

Upload weights, notebooks, sample images
Browse files
README.md
CHANGED
|
@@ -30,15 +30,15 @@ UnReflectAnything works on both natural indoor and surgical/endoscopic domain da
|
|
| 30 |
|
| 31 |
|
| 32 |
|
| 33 |
-
* **<font color="#a001e0">Encoder</font> (
|
| 34 |
|
| 35 |
-
* **<font color="#0167ff">Reflection Predictor</font> (
|
| 36 |
|
| 37 |
-
* **Masking Operation
|
| 38 |
|
| 39 |
-
* **<font color="#23ac2c">Token Inpainter</font> (
|
| 40 |
|
| 41 |
-
* **<font color="#ff7700">Decoder</font> (
|
| 42 |
|
| 43 |
---
|
| 44 |
|
|
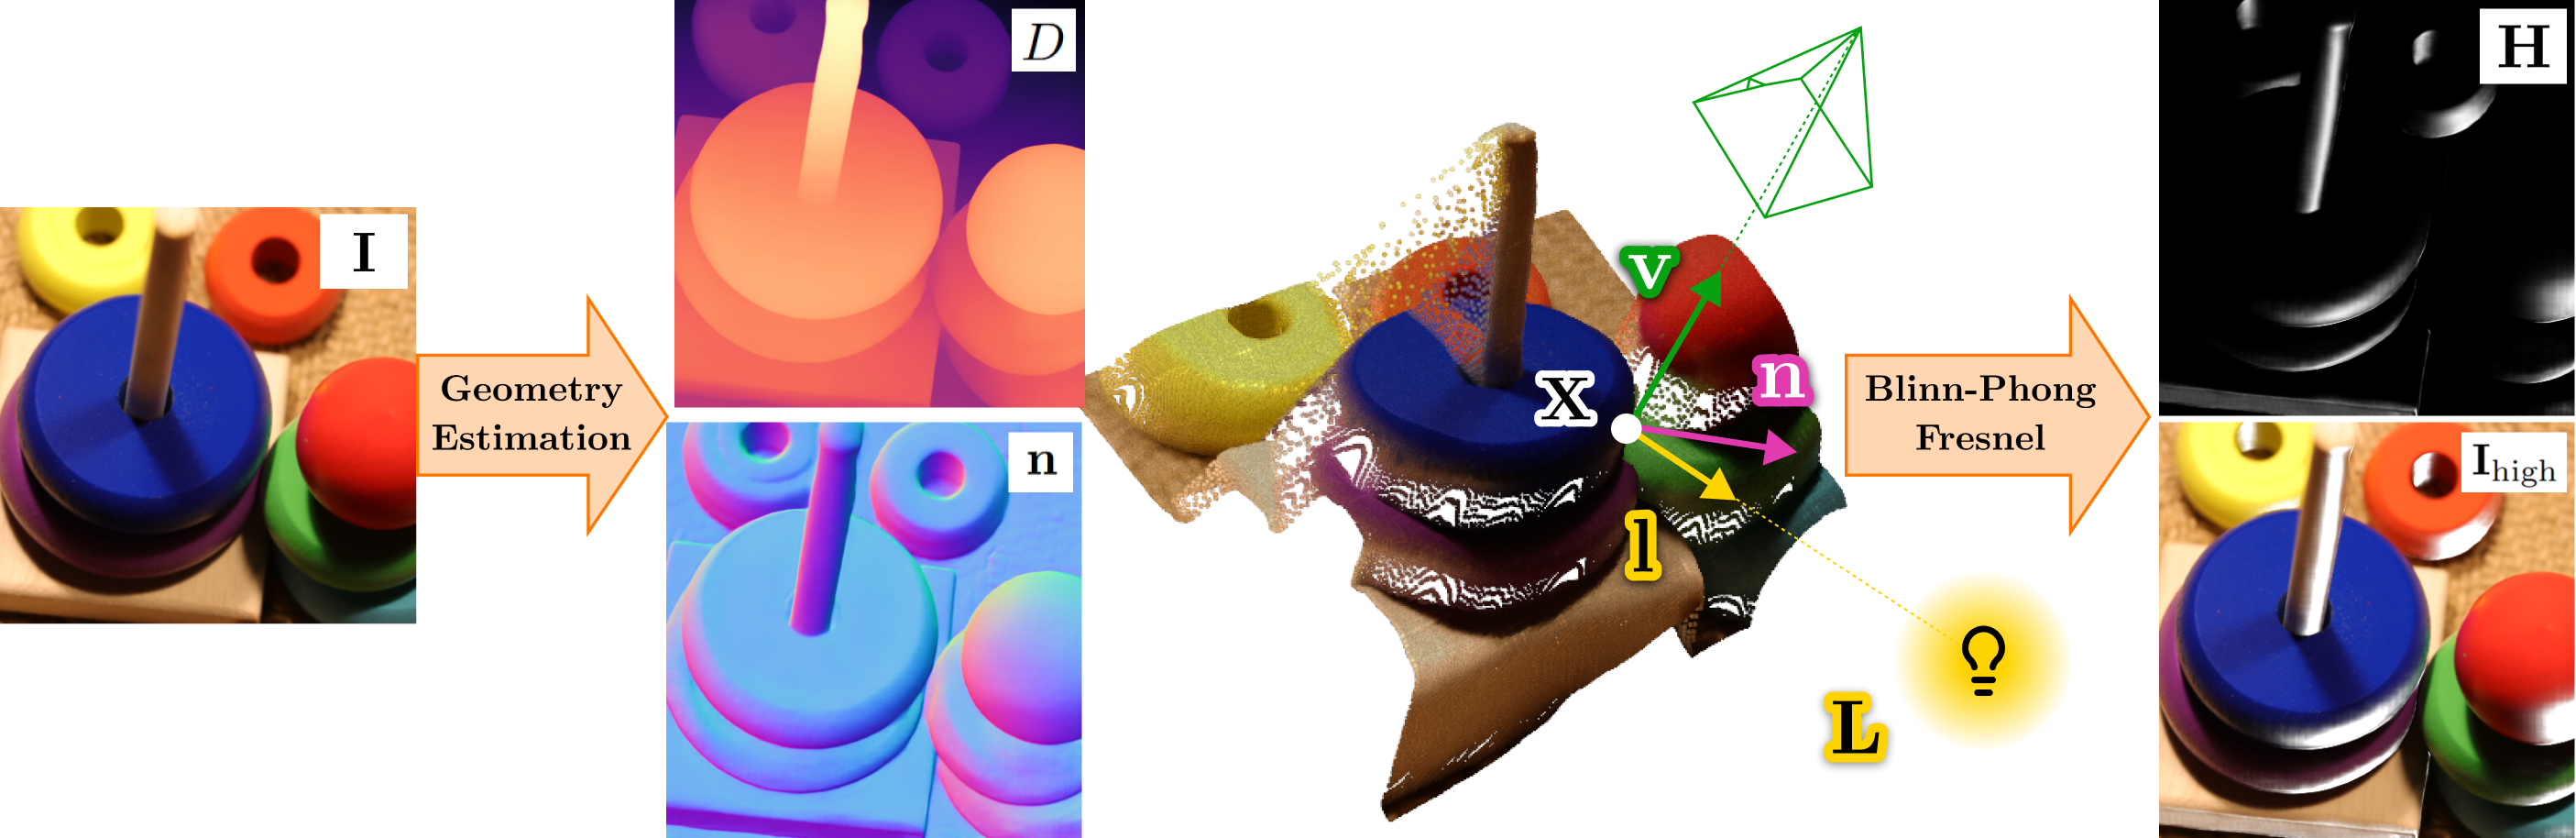
@@ -48,8 +48,8 @@ We train UnReflectAnything with **Synthetic Specular Supervision** by inferring
|
|
| 48 |
|
| 49 |
|
| 50 |
We train the model in two stages
|
| 51 |
-
1. **DPT Decoder Pre-Training**: The **<font color="#ff7700">Decoder</font>** is first pre-trained in an autoencoder configuration (
|
| 52 |
-
2. **End-to-End Refinement**: The full pipeline is then trained to predict reflection masks from
|
| 53 |
|
| 54 |
|
| 55 |
|
|
@@ -103,14 +103,13 @@ Refer to the [Wiki](https://github.com/alberto-rota/UnReflectAnything/wiki) for
|
|
| 103 |
If you use UnReflectAnything in your research or pipeline, please cite our paper:
|
| 104 |
|
| 105 |
```bibtex
|
| 106 |
-
@
|
| 107 |
-
|
| 108 |
-
|
| 109 |
-
|
| 110 |
-
|
| 111 |
-
|
| 112 |
-
|
| 113 |
-
url={[https://arxiv.org/abs/2512.09583](https://arxiv.org/abs/2512.09583)},
|
| 114 |
}
|
| 115 |
|
| 116 |
```
|
|
|
|
| 30 |
|
| 31 |
|
| 32 |
|
| 33 |
+
* **<font color="#a001e0">Encoder</font> (E)**: Processes the input image **I** to extract a rich latent representation, **F_l**. This is the off-the-shelf pretrained [DINOv3-large](https://huggingface.co/facebook/dinov3-vitl16-pretrain-lvd1689m)
|
| 34 |
|
| 35 |
+
* **<font color="#0167ff">Reflection Predictor</font> (H)**: Predicts a soft highlight mask (**H**), identifying areas of specular highlights.
|
| 36 |
|
| 37 |
+
* **Masking Operation (P)**: A binary mask **P** is derived from the prediction and applied to the feature map: `(1 - P) * F_l`. This removes features contaminated by reflections, leaving "holes" in the data.
|
| 38 |
|
| 39 |
+
* **<font color="#23ac2c">Token Inpainter</font> (T)**: Acts as a neural in-painter. It processes the masked features and uses the surrounding clean context prior and a learned mask token to synthesize the missing information in embedding space, producing the completed feature map **F_comp**.
|
| 40 |
|
| 41 |
+
* **<font color="#ff7700">Decoder</font> (D)**: Project the completed features back into the pixel space to generate the final, reflection-free image **I_diff**.
|
| 42 |
|
| 43 |
---
|
| 44 |
|
|
|
|
| 48 |

|
| 49 |
|
| 50 |
We train the model in two stages
|
| 51 |
+
1. **DPT Decoder Pre-Training**: The **<font color="#ff7700">Decoder</font>** is first pre-trained in an autoencoder configuration (minimize `L(M_θ(I), I)`) to ensure it can reconstruct realistic RGB textures from the DINOV3 latent space.
|
| 52 |
+
2. **End-to-End Refinement**: The full pipeline is then trained to predict reflection masks from **H**, and fill them using the **<font color="#38761D">Token Inpainter</font>**, ensuring the final output is both visually consistent and physically accurate. The decoder is also fine-tuned at this stage
|
| 53 |
|
| 54 |
|
| 55 |
|
|
|
|
| 103 |
If you use UnReflectAnything in your research or pipeline, please cite our paper:
|
| 104 |
|
| 105 |
```bibtex
|
| 106 |
+
@InProceedings{Rota_2026_CVPR,
|
| 107 |
+
author = {Rota, Alberto and Kiray, Mert and Karaoglu, Mert Asim and Ruhkamp, Patrick and De Momi, Elena and Navab, Nassir and Busam, Benjamin},
|
| 108 |
+
title = {UnReflectAnything: RGB-Only Highlight Removal by Rendering Synthetic Specular Supervision},
|
| 109 |
+
booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
|
| 110 |
+
month = {June},
|
| 111 |
+
year = {2026},
|
| 112 |
+
pages = {241-250}
|
|
|
|
| 113 |
}
|
| 114 |
|
| 115 |
```
|