


Commit ·
473c821
0
Parent(s):
Duplicate from google/flan-ul2
Browse filesCo-authored-by: Younes B <ybelkada@users.noreply.huggingface.co>
- .gitattributes +34 -0
- README.md +247 -0
- added_tokens.json +30 -0
- config.json +31 -0
- pytorch_model-00001-of-00008.bin +3 -0
- pytorch_model-00002-of-00008.bin +3 -0
- pytorch_model-00003-of-00008.bin +3 -0
- pytorch_model-00004-of-00008.bin +3 -0
- pytorch_model-00005-of-00008.bin +3 -0
- pytorch_model-00006-of-00008.bin +3 -0
- pytorch_model-00007-of-00008.bin +3 -0
- pytorch_model-00008-of-00008.bin +3 -0
- pytorch_model.bin.index.json +751 -0
- special_tokens_map.json +107 -0
- spiece.model +3 -0
- tokenizer.json +0 -0
- tokenizer_config.json +112 -0
.gitattributes
ADDED
|
@@ -0,0 +1,34 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 6 |
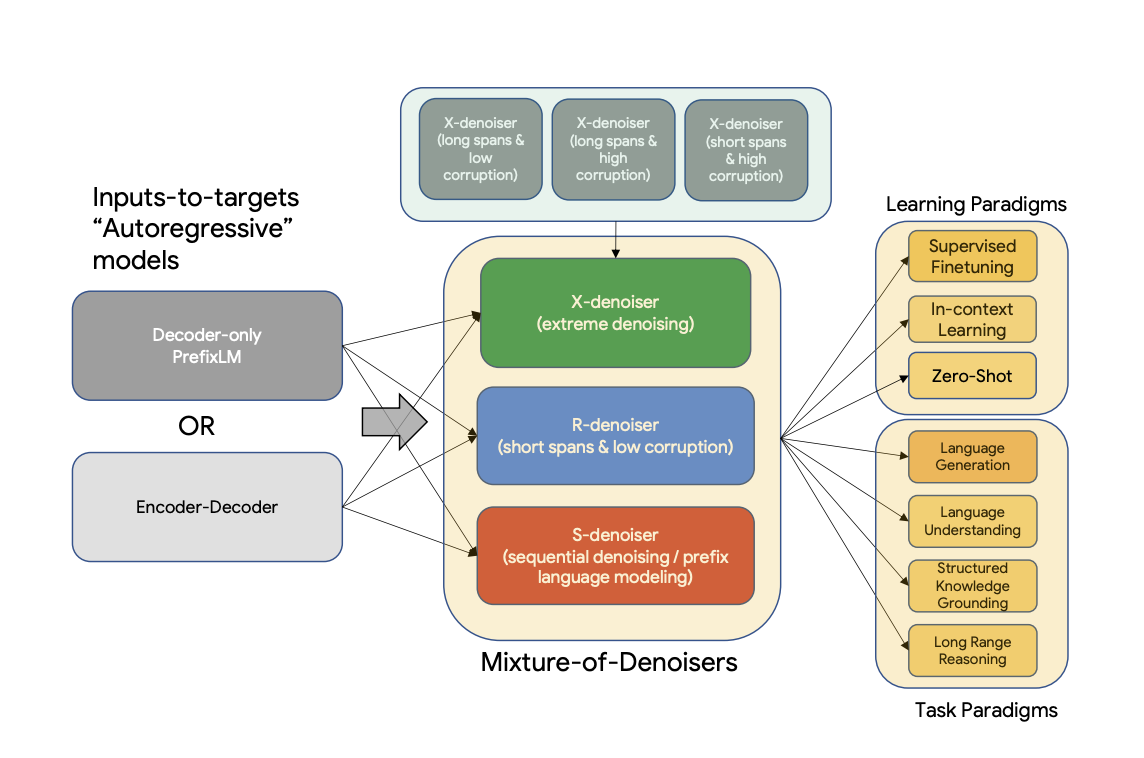
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 17 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 18 |
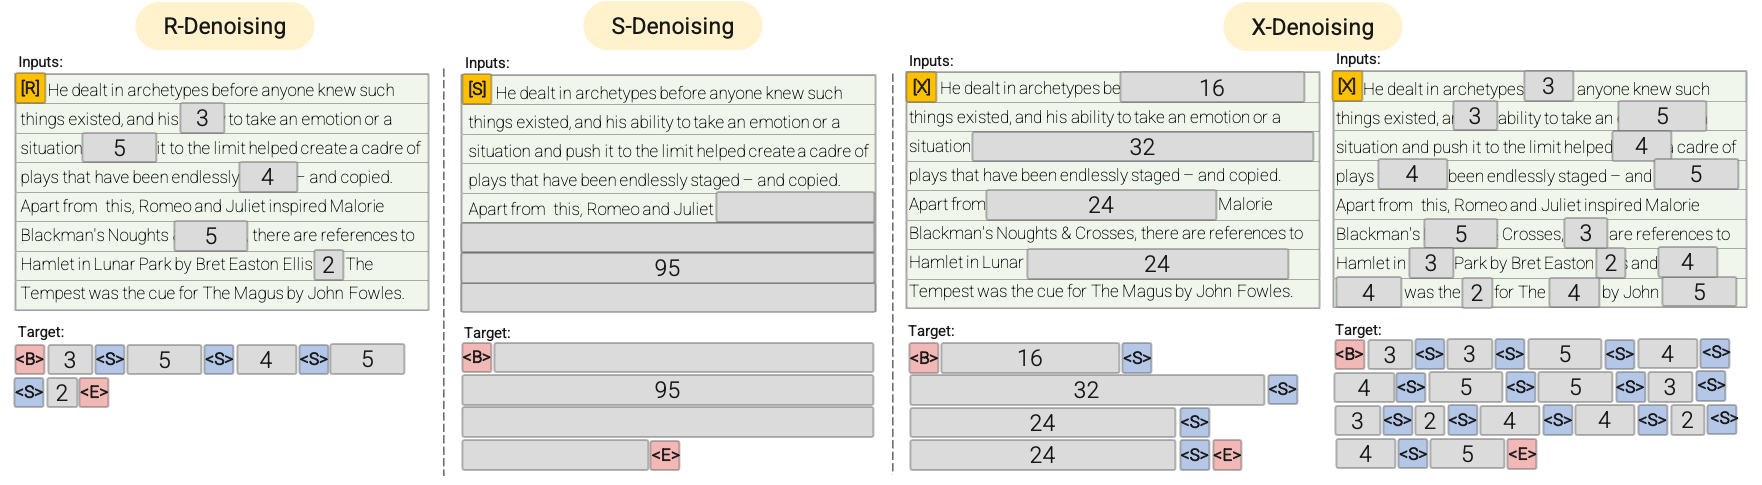
+
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 19 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 20 |
+
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 21 |
+
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 22 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 23 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 24 |
+
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 25 |
+
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 26 |
+
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 27 |
+
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 28 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 29 |
+
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 30 |
+
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 31 |
+
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 32 |
+
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 33 |
+
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 34 |
+
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
README.md
ADDED
|
@@ -0,0 +1,247 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
language:
|
| 3 |
+
- en
|
| 4 |
+
- fr
|
| 5 |
+
- ro
|
| 6 |
+
- de
|
| 7 |
+
- multilingual
|
| 8 |
+
widget:
|
| 9 |
+
- text: 'Translate to German: My name is Arthur'
|
| 10 |
+
example_title: Translation
|
| 11 |
+
- text: >-
|
| 12 |
+
Please answer to the following question. Who is going to be the next
|
| 13 |
+
Ballon d'or?
|
| 14 |
+
example_title: Question Answering
|
| 15 |
+
- text: >-
|
| 16 |
+
Q: Can Geoffrey Hinton have a conversation with George Washington? Give
|
| 17 |
+
the rationale before answering.
|
| 18 |
+
example_title: Logical reasoning
|
| 19 |
+
- text: >-
|
| 20 |
+
Please answer the following question. What is the boiling point of
|
| 21 |
+
Nitrogen?
|
| 22 |
+
example_title: Scientific knowledge
|
| 23 |
+
- text: >-
|
| 24 |
+
Answer the following yes/no question. Can you write a whole Haiku in a
|
| 25 |
+
single tweet?
|
| 26 |
+
example_title: Yes/no question
|
| 27 |
+
- text: >-
|
| 28 |
+
Answer the following yes/no question by reasoning step-by-step. Can you
|
| 29 |
+
write a whole Haiku in a single tweet?
|
| 30 |
+
example_title: Reasoning task
|
| 31 |
+
- text: 'Q: ( False or not False or False ) is? A: Let''s think step by step'
|
| 32 |
+
example_title: Boolean Expressions
|
| 33 |
+
- text: >-
|
| 34 |
+
The square root of x is the cube root of y. What is y to the power of 2,
|
| 35 |
+
if x = 4?
|
| 36 |
+
example_title: Math reasoning
|
| 37 |
+
- text: >-
|
| 38 |
+
Premise: At my age you will probably have learnt one lesson. Hypothesis:
|
| 39 |
+
It's not certain how many lessons you'll learn by your thirties. Does the
|
| 40 |
+
premise entail the hypothesis?
|
| 41 |
+
example_title: Premise and hypothesis
|
| 42 |
+
- text: >-
|
| 43 |
+
Answer the following question by reasoning step by step.
|
| 44 |
+
The cafeteria had 23 apples. If they used 20 for lunch, and bought 6 more, how many apple do they have?
|
| 45 |
+
example_title: Chain of thought
|
| 46 |
+
tags:
|
| 47 |
+
- text2text-generation
|
| 48 |
+
- flan-ul2
|
| 49 |
+
datasets:
|
| 50 |
+
- svakulenk0/qrecc
|
| 51 |
+
- taskmaster2
|
| 52 |
+
- djaym7/wiki_dialog
|
| 53 |
+
- deepmind/code_contests
|
| 54 |
+
- lambada
|
| 55 |
+
- gsm8k
|
| 56 |
+
- aqua_rat
|
| 57 |
+
- esnli
|
| 58 |
+
- quasc
|
| 59 |
+
- qed
|
| 60 |
+
- c4
|
| 61 |
+
license: apache-2.0
|
| 62 |
+
---
|
| 63 |
+
|
| 64 |
+
|
| 65 |
+
# Model card for Flan-UL2
|
| 66 |
+
|
| 67 |
+
|
| 68 |
+
|
| 69 |
+
# Table of Contents
|
| 70 |
+
|
| 71 |
+
0. [TL;DR](#TL;DR)
|
| 72 |
+
1. [Using the model](#using-the-model)
|
| 73 |
+
2. [Results](#results)
|
| 74 |
+
3. [Introduction to UL2](#introduction-to-ul2)
|
| 75 |
+
4. [Training](#training)
|
| 76 |
+
5. [Contribution](#contribution)
|
| 77 |
+
6. [Citation](#citation)
|
| 78 |
+
|
| 79 |
+
# TL;DR
|
| 80 |
+
|
| 81 |
+
Flan-UL2 is an encoder decoder model based on the `T5` architecture. It uses the same configuration as the [`UL2 model`](https://huggingface.co/google/ul2) released earlier last year. It was fine tuned using the "Flan" prompt tuning
|
| 82 |
+
and dataset collection.
|
| 83 |
+
|
| 84 |
+
According to the original [blog](https://www.yitay.net/blog/flan-ul2-20b) here are the notable improvements:
|
| 85 |
+
- The original UL2 model was only trained with receptive field of 512, which made it non-ideal for N-shot prompting where N is large.
|
| 86 |
+
- The Flan-UL2 checkpoint uses a receptive field of 2048 which makes it more usable for few-shot in-context learning.
|
| 87 |
+
- The original UL2 model also had mode switch tokens that was rather mandatory to get good performance. However, they were a little cumbersome as this requires often some changes during inference or finetuning. In this update/change, we continue training UL2 20B for an additional 100k steps (with small batch) to forget “mode tokens” before applying Flan instruction tuning. This Flan-UL2 checkpoint does not require mode tokens anymore.
|
| 88 |
+
|
| 89 |
+
# Using the model
|
| 90 |
+
|
| 91 |
+
## Converting from T5x to huggingface
|
| 92 |
+
|
| 93 |
+
You can use the [`convert_t5x_checkpoint_to_pytorch.py`](https://github.com/huggingface/transformers/blob/main/src/transformers/models/t5/convert_t5x_checkpoint_to_pytorch.py) script and pass the argument `strict = False`. The final layer norm is missing from the original dictionnary, that is why we are passing the `strict = False` argument.
|
| 94 |
+
```bash
|
| 95 |
+
python convert_t5x_checkpoint_to_pytorch.py --t5x_checkpoint_path PATH_TO_T5X_CHECKPOINTS --config_file PATH_TO_CONFIG --pytorch_dump_path PATH_TO_SAVE
|
| 96 |
+
```
|
| 97 |
+
We used the same config file as [`google/ul2`](https://huggingface.co/google/ul2/blob/main/config.json).
|
| 98 |
+
|
| 99 |
+
## Running the model
|
| 100 |
+
|
| 101 |
+
For more efficient memory usage, we advise you to load the model in `8bit` using `load_in_8bit` flag as follows (works only under GPU):
|
| 102 |
+
|
| 103 |
+
```python
|
| 104 |
+
# pip install accelerate transformers bitsandbytes
|
| 105 |
+
from transformers import T5ForConditionalGeneration, AutoTokenizer
|
| 106 |
+
import torch
|
| 107 |
+
model = T5ForConditionalGeneration.from_pretrained("google/flan-ul2", device_map="auto", load_in_8bit=True)
|
| 108 |
+
tokenizer = AutoTokenizer.from_pretrained("google/flan-ul2")
|
| 109 |
+
|
| 110 |
+
input_string = "Answer the following question by reasoning step by step. The cafeteria had 23 apples. If they used 20 for lunch, and bought 6 more, how many apple do they have?"
|
| 111 |
+
|
| 112 |
+
inputs = tokenizer(input_string, return_tensors="pt").input_ids.to("cuda")
|
| 113 |
+
outputs = model.generate(inputs, max_length=200)
|
| 114 |
+
|
| 115 |
+
print(tokenizer.decode(outputs[0]))
|
| 116 |
+
# <pad> They have 23 - 20 = 3 apples left. They have 3 + 6 = 9 apples. Therefore, the answer is 9.</s>
|
| 117 |
+
```
|
| 118 |
+
|
| 119 |
+
Otherwise, you can load and run the model in `bfloat16` as follows:
|
| 120 |
+
|
| 121 |
+
```python
|
| 122 |
+
# pip install accelerate transformers
|
| 123 |
+
from transformers import T5ForConditionalGeneration, AutoTokenizer
|
| 124 |
+
import torch
|
| 125 |
+
model = T5ForConditionalGeneration.from_pretrained("google/flan-ul2", torch_dtype=torch.bfloat16, device_map="auto")
|
| 126 |
+
tokenizer = AutoTokenizer.from_pretrained("google/flan-ul2")
|
| 127 |
+
|
| 128 |
+
input_string = "Answer the following question by reasoning step by step. The cafeteria had 23 apples. If they used 20 for lunch, and bought 6 more, how many apple do they have?"
|
| 129 |
+
|
| 130 |
+
inputs = tokenizer(input_string, return_tensors="pt").input_ids.to("cuda")
|
| 131 |
+
outputs = model.generate(inputs, max_length=200)
|
| 132 |
+
|
| 133 |
+
print(tokenizer.decode(outputs[0]))
|
| 134 |
+
# <pad> They have 23 - 20 = 3 apples left. They have 3 + 6 = 9 apples. Therefore, the answer is 9.</s>
|
| 135 |
+
```
|
| 136 |
+
|
| 137 |
+
# Results
|
| 138 |
+
|
| 139 |
+
## Performance improvment
|
| 140 |
+
|
| 141 |
+
The reported results are the following :
|
| 142 |
+
| | MMLU | BBH | MMLU-CoT | BBH-CoT | Avg |
|
| 143 |
+
| :--- | :---: | :---: | :---: | :---: | :---: |
|
| 144 |
+
| FLAN-PaLM 62B | 59.6 | 47.5 | 56.9 | 44.9 | 49.9 |
|
| 145 |
+
| FLAN-PaLM 540B | 73.5 | 57.9 | 70.9 | 66.3 | 67.2 |
|
| 146 |
+
| FLAN-T5-XXL 11B | 55.1 | 45.3 | 48.6 | 41.4 | 47.6 |
|
| 147 |
+
| FLAN-UL2 20B | 55.7(+1.1%) | 45.9(+1.3%) | 52.2(+7.4%) | 42.7(+3.1%) | 49.1(+3.2%) |
|
| 148 |
+
|
| 149 |
+
|
| 150 |
+
# Introduction to UL2
|
| 151 |
+
|
| 152 |
+
This entire section has been copied from the [`google/ul2`](https://huggingface.co/google/ul2) model card and might be subject of change with respect to `flan-ul2`.
|
| 153 |
+
|
| 154 |
+
UL2 is a unified framework for pretraining models that are universally effective across datasets and setups. UL2 uses Mixture-of-Denoisers (MoD), apre-training objective that combines diverse pre-training paradigms together. UL2 introduces a notion of mode switching, wherein downstream fine-tuning is associated with specific pre-training schemes.
|
| 155 |
+
|
| 156 |
+

|
| 157 |
+
|
| 158 |
+
**Abstract**
|
| 159 |
+
|
| 160 |
+
Existing pre-trained models are generally geared towards a particular class of problems. To date, there seems to be still no consensus on what the right architecture and pre-training setup should be. This paper presents a unified framework for pre-training models that are universally effective across datasets and setups. We begin by disentangling architectural archetypes with pre-training objectives -- two concepts that are commonly conflated. Next, we present a generalized and unified perspective for self-supervision in NLP and show how different pre-training objectives can be cast as one another and how interpolating between different objectives can be effective. We then propose Mixture-of-Denoisers (MoD), a pre-training objective that combines diverse pre-training paradigms together. We furthermore introduce a notion of mode switching, wherein downstream fine-tuning is associated with specific pre-training schemes. We conduct extensive ablative experiments to compare multiple pre-training objectives and find that our method pushes the Pareto-frontier by outperforming T5 and/or GPT-like models across multiple diverse setups. Finally, by scaling our model up to 20B parameters, we achieve SOTA performance on 50 well-established supervised NLP tasks ranging from language generation (with automated and human evaluation), language understanding, text classification, question answering, commonsense reasoning, long text reasoning, structured knowledge grounding and information retrieval. Our model also achieve strong results at in-context learning, outperforming 175B GPT-3 on zero-shot SuperGLUE and tripling the performance of T5-XXL on one-shot summarization.
|
| 161 |
+
|
| 162 |
+
For more information, please take a look at the original paper.
|
| 163 |
+
|
| 164 |
+
Paper: [Unifying Language Learning Paradigms](https://arxiv.org/abs/2205.05131v1)
|
| 165 |
+
|
| 166 |
+
Authors: *Yi Tay, Mostafa Dehghani, Vinh Q. Tran, Xavier Garcia, Dara Bahri, Tal Schuster, Huaixiu Steven Zheng, Neil Houlsby, Donald Metzler*
|
| 167 |
+
|
| 168 |
+
|
| 169 |
+
## Training
|
| 170 |
+
|
| 171 |
+
### Flan UL2
|
| 172 |
+
The Flan-UL2 model was initialized using the `UL2` checkpoints, and was then trained additionally using Flan Prompting. This means that the original training corpus is `C4`,
|
| 173 |
+
|
| 174 |
+
In “Scaling Instruction-Finetuned language models (Chung et al.)” (also referred to sometimes as the Flan2 paper), the key idea is to train a large language model on a collection of datasets. These datasets are phrased as instructions which enable generalization across diverse tasks. Flan has been primarily trained on academic tasks. In Flan2, we released a series of T5 models ranging from 200M to 11B parameters that have been instruction tuned with Flan.
|
| 175 |
+
|
| 176 |
+
The Flan datasets have also been open sourced in “The Flan Collection: Designing Data and Methods for Effective Instruction Tuning” (Longpre et al.). See Google AI Blogpost: “The Flan Collection: Advancing Open Source Methods for Instruction Tuning”.
|
| 177 |
+
|
| 178 |
+
## UL2 PreTraining
|
| 179 |
+
|
| 180 |
+
The model is pretrained on the C4 corpus. For pretraining, the model is trained on a total of 1 trillion tokens on C4 (2 million steps)
|
| 181 |
+
with a batch size of 1024. The sequence length is set to 512/512 for inputs and targets.
|
| 182 |
+
Dropout is set to 0 during pretraining. Pre-training took slightly more than one month for about 1 trillion
|
| 183 |
+
tokens. The model has 32 encoder layers and 32 decoder layers, `dmodel` of 4096 and `df` of 16384.
|
| 184 |
+
The dimension of each head is 256 for a total of 16 heads. Our model uses a model parallelism of 8.
|
| 185 |
+
The same sentencepiece tokenizer as T5 of vocab size 32000 is used (click [here](https://huggingface.co/docs/transformers/v4.20.0/en/model_doc/t5#transformers.T5Tokenizer) for more information about the T5 tokenizer).
|
| 186 |
+
|
| 187 |
+
UL-20B can be interpreted as a model that is quite similar to T5 but trained with a different objective and slightly different scaling knobs.
|
| 188 |
+
UL-20B was trained using the [Jax](https://github.com/google/jax) and [T5X](https://github.com/google-research/t5x) infrastructure.
|
| 189 |
+
|
| 190 |
+
The training objective during pretraining is a mixture of different denoising strategies that are explained in the following:
|
| 191 |
+
|
| 192 |
+
### Mixture of Denoisers
|
| 193 |
+
|
| 194 |
+
To quote the paper:
|
| 195 |
+
> We conjecture that a strong universal model has to be exposed to solving diverse set of problems
|
| 196 |
+
> during pre-training. Given that pre-training is done using self-supervision, we argue that such diversity
|
| 197 |
+
> should be injected to the objective of the model, otherwise the model might suffer from lack a certain
|
| 198 |
+
> ability, like long-coherent text generation.
|
| 199 |
+
> Motivated by this, as well as current class of objective functions, we define three main paradigms that
|
| 200 |
+
> are used during pre-training:
|
| 201 |
+
|
| 202 |
+
- **R-Denoiser**: The regular denoising is the standard span corruption introduced in [T5](https://huggingface.co/docs/transformers/v4.20.0/en/model_doc/t5)
|
| 203 |
+
that uses a range of 2 to 5 tokens as the span length, which masks about 15% of
|
| 204 |
+
input tokens. These spans are short and potentially useful to acquire knowledge instead of
|
| 205 |
+
learning to generate fluent text.
|
| 206 |
+
|
| 207 |
+
- **S-Denoiser**: A specific case of denoising where we observe a strict sequential order when
|
| 208 |
+
framing the inputs-to-targets task, i.e., prefix language modeling. To do so, we simply
|
| 209 |
+
partition the input sequence into two sub-sequences of tokens as context and target such that
|
| 210 |
+
the targets do not rely on future information. This is unlike standard span corruption where
|
| 211 |
+
there could be a target token with earlier position than a context token. Note that similar to
|
| 212 |
+
the Prefix-LM setup, the context (prefix) retains a bidirectional receptive field. We note that
|
| 213 |
+
S-Denoising with very short memory or no memory is in similar spirit to standard causal
|
| 214 |
+
language modeling.
|
| 215 |
+
|
| 216 |
+
- **X-Denoiser**: An extreme version of denoising where the model must recover a large part
|
| 217 |
+
of the input, given a small to moderate part of it. This simulates a situation where a model
|
| 218 |
+
needs to generate long target from a memory with relatively limited information. To do
|
| 219 |
+
so, we opt to include examples with aggressive denoising where approximately 50% of the
|
| 220 |
+
input sequence is masked. This is by increasing the span length and/or corruption rate. We
|
| 221 |
+
consider a pre-training task to be extreme if it has a long span (e.g., ≥ 12 tokens) or have
|
| 222 |
+
a large corruption rate (e.g., ≥ 30%). X-denoising is motivated by being an interpolation
|
| 223 |
+
between regular span corruption and language model like objectives.
|
| 224 |
+
|
| 225 |
+
See the following diagram for a more visual explanation:
|
| 226 |
+
|
| 227 |
+
|
| 228 |
+
|
| 229 |
+
**Important**: For more details, please see sections 3.1.2 of the [paper](https://arxiv.org/pdf/2205.05131v1.pdf).
|
| 230 |
+
|
| 231 |
+
## Fine-tuning
|
| 232 |
+
|
| 233 |
+
The model was continously fine-tuned after N pretraining steps where N is typically from 50k to 100k.
|
| 234 |
+
In other words, after each Nk steps of pretraining, the model is finetuned on each downstream task. See section 5.2.2 of [paper](https://arxiv.org/pdf/2205.05131v1.pdf) to get an overview of all datasets that were used for fine-tuning).
|
| 235 |
+
|
| 236 |
+
As the model is continuously finetuned, finetuning is stopped on a task once it has reached state-of-the-art to save compute.
|
| 237 |
+
In total, the model was trained for 2.65 million steps.
|
| 238 |
+
|
| 239 |
+
**Important**: For more details, please see sections 5.2.1 and 5.2.2 of the [paper](https://arxiv.org/pdf/2205.05131v1.pdf).
|
| 240 |
+
|
| 241 |
+
# Contribution
|
| 242 |
+
|
| 243 |
+
This model was originally contributed by [Yi Tay](https://www.yitay.net/?author=636616684c5e64780328eece), and added to the Hugging Face ecosystem by [Younes Belkada](https://huggingface.co/ybelkada) & [Arthur Zucker](https://huggingface.co/ArthurZ).
|
| 244 |
+
|
| 245 |
+
# Citation
|
| 246 |
+
|
| 247 |
+
If you want to cite this work, please consider citing the [blogpost](https://www.yitay.net/blog/flan-ul2-20b) announcing the release of `Flan-UL2`.
|
added_tokens.json
ADDED
|
@@ -0,0 +1,30 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"[new_id_0]": 32100,
|
| 3 |
+
"[new_id_10]": 32110,
|
| 4 |
+
"[new_id_11]": 32111,
|
| 5 |
+
"[new_id_12]": 32112,
|
| 6 |
+
"[new_id_13]": 32113,
|
| 7 |
+
"[new_id_14]": 32114,
|
| 8 |
+
"[new_id_15]": 32115,
|
| 9 |
+
"[new_id_16]": 32116,
|
| 10 |
+
"[new_id_17]": 32117,
|
| 11 |
+
"[new_id_18]": 32118,
|
| 12 |
+
"[new_id_19]": 32119,
|
| 13 |
+
"[new_id_1]": 32101,
|
| 14 |
+
"[new_id_20]": 32120,
|
| 15 |
+
"[new_id_21]": 32121,
|
| 16 |
+
"[new_id_22]": 32122,
|
| 17 |
+
"[new_id_23]": 32123,
|
| 18 |
+
"[new_id_24]": 32124,
|
| 19 |
+
"[new_id_25]": 32125,
|
| 20 |
+
"[new_id_26]": 32126,
|
| 21 |
+
"[new_id_27]": 32127,
|
| 22 |
+
"[new_id_2]": 32102,
|
| 23 |
+
"[new_id_3]": 32103,
|
| 24 |
+
"[new_id_4]": 32104,
|
| 25 |
+
"[new_id_5]": 32105,
|
| 26 |
+
"[new_id_6]": 32106,
|
| 27 |
+
"[new_id_7]": 32107,
|
| 28 |
+
"[new_id_8]": 32108,
|
| 29 |
+
"[new_id_9]": 32109
|
| 30 |
+
}
|
config.json
ADDED
|
@@ -0,0 +1,31 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_name_or_path": "/home/younes_huggingface_co/code/ul2/flan-ul2",
|
| 3 |
+
"architectures": [
|
| 4 |
+
"T5ForConditionalGeneration"
|
| 5 |
+
],
|
| 6 |
+
"d_ff": 16384,
|
| 7 |
+
"d_kv": 256,
|
| 8 |
+
"d_model": 4096,
|
| 9 |
+
"decoder_start_token_id": 0,
|
| 10 |
+
"dense_act_fn": "silu",
|
| 11 |
+
"dropout_rate": 0.1,
|
| 12 |
+
"eos_token_id": 1,
|
| 13 |
+
"feed_forward_proj": "gated-silu",
|
| 14 |
+
"initializer_factor": 1.0,
|
| 15 |
+
"is_encoder_decoder": true,
|
| 16 |
+
"is_gated_act": true,
|
| 17 |
+
"layer_norm_epsilon": 1e-06,
|
| 18 |
+
"model_type": "t5",
|
| 19 |
+
"n_positions": 512,
|
| 20 |
+
"num_decoder_layers": 32,
|
| 21 |
+
"num_heads": 16,
|
| 22 |
+
"num_layers": 32,
|
| 23 |
+
"output_past": true,
|
| 24 |
+
"pad_token_id": 0,
|
| 25 |
+
"relative_attention_max_distance": 128,
|
| 26 |
+
"relative_attention_num_buckets": 32,
|
| 27 |
+
"torch_dtype": "bfloat16",
|
| 28 |
+
"transformers_version": "4.25.0.dev0",
|
| 29 |
+
"use_cache": true,
|
| 30 |
+
"vocab_size": 32128
|
| 31 |
+
}
|
pytorch_model-00001-of-00008.bin
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:45bf24c1738fbec52a5a1eefc3b482291a351bab069829a03e775f8fa2822722
|
| 3 |
+
size 4692542996
|
pytorch_model-00002-of-00008.bin
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:88bd28a99530e6bf4798e44a5897b64a926211fbe1d1ddb908562e55793c4ede
|
| 3 |
+
size 4966229511
|
pytorch_model-00003-of-00008.bin
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:9f028a67b2a1aee2d6969a843b7be4448c89682bec5a10ed85ac03537b2a3e0e
|
| 3 |
+
size 4966229499
|
pytorch_model-00004-of-00008.bin
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:3bd08b4ba35a3eb643922118a7fc1e3a29c6163bb9539f7577e688dbe80dcc6b
|
| 3 |
+
size 4961006511
|
pytorch_model-00005-of-00008.bin
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:dc6b8ffacb7cc29f099cc0b5aec4f7aa61cea81a54e1a7a8621347002f6760f8
|
| 3 |
+
size 4999832641
|
pytorch_model-00006-of-00008.bin
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:adc1a3c4113f8168a98b19220ddc40b5fd1b0ac3fe41dfbd821d0c7129835ed8
|
| 3 |
+
size 4932714647
|
pytorch_model-00007-of-00008.bin
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6d8fb42e6386dbe3a5d14c171d4669793e27042bd6c13e1df57ee889485566f4
|
| 3 |
+
size 4999823229
|
pytorch_model-00008-of-00008.bin
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:aa22c462e65c38c2a86ead593f90687dc7e6945819d389720e6eb68097403083
|
| 3 |
+
size 4927470284
|
pytorch_model.bin.index.json
ADDED
|
@@ -0,0 +1,751 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"metadata": {
|
| 3 |
+
"total_size": 39708805120
|
| 4 |
+
},
|
| 5 |
+
"weight_map": {
|
| 6 |
+
"decoder.block.0.layer.0.SelfAttention.k.weight": "pytorch_model-00004-of-00008.bin",
|
| 7 |
+
"decoder.block.0.layer.0.SelfAttention.o.weight": "pytorch_model-00004-of-00008.bin",
|
| 8 |
+
"decoder.block.0.layer.0.SelfAttention.q.weight": "pytorch_model-00004-of-00008.bin",
|
| 9 |
+
"decoder.block.0.layer.0.SelfAttention.relative_attention_bias.weight": "pytorch_model-00004-of-00008.bin",
|
| 10 |
+
"decoder.block.0.layer.0.SelfAttention.v.weight": "pytorch_model-00004-of-00008.bin",
|
| 11 |
+
"decoder.block.0.layer.0.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 12 |
+
"decoder.block.0.layer.1.EncDecAttention.k.weight": "pytorch_model-00004-of-00008.bin",
|
| 13 |
+
"decoder.block.0.layer.1.EncDecAttention.o.weight": "pytorch_model-00004-of-00008.bin",
|
| 14 |
+
"decoder.block.0.layer.1.EncDecAttention.q.weight": "pytorch_model-00004-of-00008.bin",
|
| 15 |
+
"decoder.block.0.layer.1.EncDecAttention.v.weight": "pytorch_model-00004-of-00008.bin",
|
| 16 |
+
"decoder.block.0.layer.1.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 17 |
+
"decoder.block.0.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00004-of-00008.bin",
|
| 18 |
+
"decoder.block.0.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00004-of-00008.bin",
|
| 19 |
+
"decoder.block.0.layer.2.DenseReluDense.wo.weight": "pytorch_model-00004-of-00008.bin",
|
| 20 |
+
"decoder.block.0.layer.2.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 21 |
+
"decoder.block.1.layer.0.SelfAttention.k.weight": "pytorch_model-00004-of-00008.bin",
|
| 22 |
+
"decoder.block.1.layer.0.SelfAttention.o.weight": "pytorch_model-00004-of-00008.bin",
|
| 23 |
+
"decoder.block.1.layer.0.SelfAttention.q.weight": "pytorch_model-00004-of-00008.bin",
|
| 24 |
+
"decoder.block.1.layer.0.SelfAttention.v.weight": "pytorch_model-00004-of-00008.bin",
|
| 25 |
+
"decoder.block.1.layer.0.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 26 |
+
"decoder.block.1.layer.1.EncDecAttention.k.weight": "pytorch_model-00004-of-00008.bin",
|
| 27 |
+
"decoder.block.1.layer.1.EncDecAttention.o.weight": "pytorch_model-00004-of-00008.bin",
|
| 28 |
+
"decoder.block.1.layer.1.EncDecAttention.q.weight": "pytorch_model-00004-of-00008.bin",
|
| 29 |
+
"decoder.block.1.layer.1.EncDecAttention.v.weight": "pytorch_model-00004-of-00008.bin",
|
| 30 |
+
"decoder.block.1.layer.1.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 31 |
+
"decoder.block.1.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00004-of-00008.bin",
|
| 32 |
+
"decoder.block.1.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00004-of-00008.bin",
|
| 33 |
+
"decoder.block.1.layer.2.DenseReluDense.wo.weight": "pytorch_model-00004-of-00008.bin",
|
| 34 |
+
"decoder.block.1.layer.2.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 35 |
+
"decoder.block.10.layer.0.SelfAttention.k.weight": "pytorch_model-00005-of-00008.bin",
|
| 36 |
+
"decoder.block.10.layer.0.SelfAttention.o.weight": "pytorch_model-00005-of-00008.bin",
|
| 37 |
+
"decoder.block.10.layer.0.SelfAttention.q.weight": "pytorch_model-00005-of-00008.bin",
|
| 38 |
+
"decoder.block.10.layer.0.SelfAttention.v.weight": "pytorch_model-00005-of-00008.bin",
|
| 39 |
+
"decoder.block.10.layer.0.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 40 |
+
"decoder.block.10.layer.1.EncDecAttention.k.weight": "pytorch_model-00006-of-00008.bin",
|
| 41 |
+
"decoder.block.10.layer.1.EncDecAttention.o.weight": "pytorch_model-00006-of-00008.bin",
|
| 42 |
+
"decoder.block.10.layer.1.EncDecAttention.q.weight": "pytorch_model-00005-of-00008.bin",
|
| 43 |
+
"decoder.block.10.layer.1.EncDecAttention.v.weight": "pytorch_model-00006-of-00008.bin",
|
| 44 |
+
"decoder.block.10.layer.1.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 45 |
+
"decoder.block.10.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00006-of-00008.bin",
|
| 46 |
+
"decoder.block.10.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00006-of-00008.bin",
|
| 47 |
+
"decoder.block.10.layer.2.DenseReluDense.wo.weight": "pytorch_model-00006-of-00008.bin",
|
| 48 |
+
"decoder.block.10.layer.2.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 49 |
+
"decoder.block.11.layer.0.SelfAttention.k.weight": "pytorch_model-00006-of-00008.bin",
|
| 50 |
+
"decoder.block.11.layer.0.SelfAttention.o.weight": "pytorch_model-00006-of-00008.bin",
|
| 51 |
+
"decoder.block.11.layer.0.SelfAttention.q.weight": "pytorch_model-00006-of-00008.bin",
|
| 52 |
+
"decoder.block.11.layer.0.SelfAttention.v.weight": "pytorch_model-00006-of-00008.bin",
|
| 53 |
+
"decoder.block.11.layer.0.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 54 |
+
"decoder.block.11.layer.1.EncDecAttention.k.weight": "pytorch_model-00006-of-00008.bin",
|
| 55 |
+
"decoder.block.11.layer.1.EncDecAttention.o.weight": "pytorch_model-00006-of-00008.bin",
|
| 56 |
+
"decoder.block.11.layer.1.EncDecAttention.q.weight": "pytorch_model-00006-of-00008.bin",
|
| 57 |
+
"decoder.block.11.layer.1.EncDecAttention.v.weight": "pytorch_model-00006-of-00008.bin",
|
| 58 |
+
"decoder.block.11.layer.1.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 59 |
+
"decoder.block.11.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00006-of-00008.bin",
|
| 60 |
+
"decoder.block.11.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00006-of-00008.bin",
|
| 61 |
+
"decoder.block.11.layer.2.DenseReluDense.wo.weight": "pytorch_model-00006-of-00008.bin",
|
| 62 |
+
"decoder.block.11.layer.2.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 63 |
+
"decoder.block.12.layer.0.SelfAttention.k.weight": "pytorch_model-00006-of-00008.bin",
|
| 64 |
+
"decoder.block.12.layer.0.SelfAttention.o.weight": "pytorch_model-00006-of-00008.bin",
|
| 65 |
+
"decoder.block.12.layer.0.SelfAttention.q.weight": "pytorch_model-00006-of-00008.bin",
|
| 66 |
+
"decoder.block.12.layer.0.SelfAttention.v.weight": "pytorch_model-00006-of-00008.bin",
|
| 67 |
+
"decoder.block.12.layer.0.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 68 |
+
"decoder.block.12.layer.1.EncDecAttention.k.weight": "pytorch_model-00006-of-00008.bin",
|
| 69 |
+
"decoder.block.12.layer.1.EncDecAttention.o.weight": "pytorch_model-00006-of-00008.bin",
|
| 70 |
+
"decoder.block.12.layer.1.EncDecAttention.q.weight": "pytorch_model-00006-of-00008.bin",
|
| 71 |
+
"decoder.block.12.layer.1.EncDecAttention.v.weight": "pytorch_model-00006-of-00008.bin",
|
| 72 |
+
"decoder.block.12.layer.1.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 73 |
+
"decoder.block.12.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00006-of-00008.bin",
|
| 74 |
+
"decoder.block.12.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00006-of-00008.bin",
|
| 75 |
+
"decoder.block.12.layer.2.DenseReluDense.wo.weight": "pytorch_model-00006-of-00008.bin",
|
| 76 |
+
"decoder.block.12.layer.2.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 77 |
+
"decoder.block.13.layer.0.SelfAttention.k.weight": "pytorch_model-00006-of-00008.bin",
|
| 78 |
+
"decoder.block.13.layer.0.SelfAttention.o.weight": "pytorch_model-00006-of-00008.bin",
|
| 79 |
+
"decoder.block.13.layer.0.SelfAttention.q.weight": "pytorch_model-00006-of-00008.bin",
|
| 80 |
+
"decoder.block.13.layer.0.SelfAttention.v.weight": "pytorch_model-00006-of-00008.bin",
|
| 81 |
+
"decoder.block.13.layer.0.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 82 |
+
"decoder.block.13.layer.1.EncDecAttention.k.weight": "pytorch_model-00006-of-00008.bin",
|
| 83 |
+
"decoder.block.13.layer.1.EncDecAttention.o.weight": "pytorch_model-00006-of-00008.bin",
|
| 84 |
+
"decoder.block.13.layer.1.EncDecAttention.q.weight": "pytorch_model-00006-of-00008.bin",
|
| 85 |
+
"decoder.block.13.layer.1.EncDecAttention.v.weight": "pytorch_model-00006-of-00008.bin",
|
| 86 |
+
"decoder.block.13.layer.1.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 87 |
+
"decoder.block.13.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00006-of-00008.bin",
|
| 88 |
+
"decoder.block.13.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00006-of-00008.bin",
|
| 89 |
+
"decoder.block.13.layer.2.DenseReluDense.wo.weight": "pytorch_model-00006-of-00008.bin",
|
| 90 |
+
"decoder.block.13.layer.2.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 91 |
+
"decoder.block.14.layer.0.SelfAttention.k.weight": "pytorch_model-00006-of-00008.bin",
|
| 92 |
+
"decoder.block.14.layer.0.SelfAttention.o.weight": "pytorch_model-00006-of-00008.bin",
|
| 93 |
+
"decoder.block.14.layer.0.SelfAttention.q.weight": "pytorch_model-00006-of-00008.bin",
|
| 94 |
+
"decoder.block.14.layer.0.SelfAttention.v.weight": "pytorch_model-00006-of-00008.bin",
|
| 95 |
+
"decoder.block.14.layer.0.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 96 |
+
"decoder.block.14.layer.1.EncDecAttention.k.weight": "pytorch_model-00006-of-00008.bin",
|
| 97 |
+
"decoder.block.14.layer.1.EncDecAttention.o.weight": "pytorch_model-00006-of-00008.bin",
|
| 98 |
+
"decoder.block.14.layer.1.EncDecAttention.q.weight": "pytorch_model-00006-of-00008.bin",
|
| 99 |
+
"decoder.block.14.layer.1.EncDecAttention.v.weight": "pytorch_model-00006-of-00008.bin",
|
| 100 |
+
"decoder.block.14.layer.1.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 101 |
+
"decoder.block.14.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00006-of-00008.bin",
|
| 102 |
+
"decoder.block.14.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00006-of-00008.bin",
|
| 103 |
+
"decoder.block.14.layer.2.DenseReluDense.wo.weight": "pytorch_model-00006-of-00008.bin",
|
| 104 |
+
"decoder.block.14.layer.2.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 105 |
+
"decoder.block.15.layer.0.SelfAttention.k.weight": "pytorch_model-00006-of-00008.bin",
|
| 106 |
+
"decoder.block.15.layer.0.SelfAttention.o.weight": "pytorch_model-00006-of-00008.bin",
|
| 107 |
+
"decoder.block.15.layer.0.SelfAttention.q.weight": "pytorch_model-00006-of-00008.bin",
|
| 108 |
+
"decoder.block.15.layer.0.SelfAttention.v.weight": "pytorch_model-00006-of-00008.bin",
|
| 109 |
+
"decoder.block.15.layer.0.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 110 |
+
"decoder.block.15.layer.1.EncDecAttention.k.weight": "pytorch_model-00006-of-00008.bin",
|
| 111 |
+
"decoder.block.15.layer.1.EncDecAttention.o.weight": "pytorch_model-00006-of-00008.bin",
|
| 112 |
+
"decoder.block.15.layer.1.EncDecAttention.q.weight": "pytorch_model-00006-of-00008.bin",
|
| 113 |
+
"decoder.block.15.layer.1.EncDecAttention.v.weight": "pytorch_model-00006-of-00008.bin",
|
| 114 |
+
"decoder.block.15.layer.1.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 115 |
+
"decoder.block.15.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00006-of-00008.bin",
|
| 116 |
+
"decoder.block.15.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00006-of-00008.bin",
|
| 117 |
+
"decoder.block.15.layer.2.DenseReluDense.wo.weight": "pytorch_model-00006-of-00008.bin",
|
| 118 |
+
"decoder.block.15.layer.2.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 119 |
+
"decoder.block.16.layer.0.SelfAttention.k.weight": "pytorch_model-00006-of-00008.bin",
|
| 120 |
+
"decoder.block.16.layer.0.SelfAttention.o.weight": "pytorch_model-00006-of-00008.bin",
|
| 121 |
+
"decoder.block.16.layer.0.SelfAttention.q.weight": "pytorch_model-00006-of-00008.bin",
|
| 122 |
+
"decoder.block.16.layer.0.SelfAttention.v.weight": "pytorch_model-00006-of-00008.bin",
|
| 123 |
+
"decoder.block.16.layer.0.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 124 |
+
"decoder.block.16.layer.1.EncDecAttention.k.weight": "pytorch_model-00006-of-00008.bin",
|
| 125 |
+
"decoder.block.16.layer.1.EncDecAttention.o.weight": "pytorch_model-00006-of-00008.bin",
|
| 126 |
+
"decoder.block.16.layer.1.EncDecAttention.q.weight": "pytorch_model-00006-of-00008.bin",
|
| 127 |
+
"decoder.block.16.layer.1.EncDecAttention.v.weight": "pytorch_model-00006-of-00008.bin",
|
| 128 |
+
"decoder.block.16.layer.1.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 129 |
+
"decoder.block.16.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00006-of-00008.bin",
|
| 130 |
+
"decoder.block.16.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00006-of-00008.bin",
|
| 131 |
+
"decoder.block.16.layer.2.DenseReluDense.wo.weight": "pytorch_model-00006-of-00008.bin",
|
| 132 |
+
"decoder.block.16.layer.2.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 133 |
+
"decoder.block.17.layer.0.SelfAttention.k.weight": "pytorch_model-00006-of-00008.bin",
|
| 134 |
+
"decoder.block.17.layer.0.SelfAttention.o.weight": "pytorch_model-00006-of-00008.bin",
|
| 135 |
+
"decoder.block.17.layer.0.SelfAttention.q.weight": "pytorch_model-00006-of-00008.bin",
|
| 136 |
+
"decoder.block.17.layer.0.SelfAttention.v.weight": "pytorch_model-00006-of-00008.bin",
|
| 137 |
+
"decoder.block.17.layer.0.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 138 |
+
"decoder.block.17.layer.1.EncDecAttention.k.weight": "pytorch_model-00006-of-00008.bin",
|
| 139 |
+
"decoder.block.17.layer.1.EncDecAttention.o.weight": "pytorch_model-00006-of-00008.bin",
|
| 140 |
+
"decoder.block.17.layer.1.EncDecAttention.q.weight": "pytorch_model-00006-of-00008.bin",
|
| 141 |
+
"decoder.block.17.layer.1.EncDecAttention.v.weight": "pytorch_model-00006-of-00008.bin",
|
| 142 |
+
"decoder.block.17.layer.1.layer_norm.weight": "pytorch_model-00006-of-00008.bin",
|
| 143 |
+
"decoder.block.17.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00006-of-00008.bin",
|
| 144 |
+
"decoder.block.17.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00007-of-00008.bin",
|
| 145 |
+
"decoder.block.17.layer.2.DenseReluDense.wo.weight": "pytorch_model-00007-of-00008.bin",
|
| 146 |
+
"decoder.block.17.layer.2.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 147 |
+
"decoder.block.18.layer.0.SelfAttention.k.weight": "pytorch_model-00007-of-00008.bin",
|
| 148 |
+
"decoder.block.18.layer.0.SelfAttention.o.weight": "pytorch_model-00007-of-00008.bin",
|
| 149 |
+
"decoder.block.18.layer.0.SelfAttention.q.weight": "pytorch_model-00007-of-00008.bin",
|
| 150 |
+
"decoder.block.18.layer.0.SelfAttention.v.weight": "pytorch_model-00007-of-00008.bin",
|
| 151 |
+
"decoder.block.18.layer.0.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 152 |
+
"decoder.block.18.layer.1.EncDecAttention.k.weight": "pytorch_model-00007-of-00008.bin",
|
| 153 |
+
"decoder.block.18.layer.1.EncDecAttention.o.weight": "pytorch_model-00007-of-00008.bin",
|
| 154 |
+
"decoder.block.18.layer.1.EncDecAttention.q.weight": "pytorch_model-00007-of-00008.bin",
|
| 155 |
+
"decoder.block.18.layer.1.EncDecAttention.v.weight": "pytorch_model-00007-of-00008.bin",
|
| 156 |
+
"decoder.block.18.layer.1.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 157 |
+
"decoder.block.18.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00007-of-00008.bin",
|
| 158 |
+
"decoder.block.18.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00007-of-00008.bin",
|
| 159 |
+
"decoder.block.18.layer.2.DenseReluDense.wo.weight": "pytorch_model-00007-of-00008.bin",
|
| 160 |
+
"decoder.block.18.layer.2.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 161 |
+
"decoder.block.19.layer.0.SelfAttention.k.weight": "pytorch_model-00007-of-00008.bin",
|
| 162 |
+
"decoder.block.19.layer.0.SelfAttention.o.weight": "pytorch_model-00007-of-00008.bin",
|
| 163 |
+
"decoder.block.19.layer.0.SelfAttention.q.weight": "pytorch_model-00007-of-00008.bin",
|
| 164 |
+
"decoder.block.19.layer.0.SelfAttention.v.weight": "pytorch_model-00007-of-00008.bin",
|
| 165 |
+
"decoder.block.19.layer.0.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 166 |
+
"decoder.block.19.layer.1.EncDecAttention.k.weight": "pytorch_model-00007-of-00008.bin",
|
| 167 |
+
"decoder.block.19.layer.1.EncDecAttention.o.weight": "pytorch_model-00007-of-00008.bin",
|
| 168 |
+
"decoder.block.19.layer.1.EncDecAttention.q.weight": "pytorch_model-00007-of-00008.bin",
|
| 169 |
+
"decoder.block.19.layer.1.EncDecAttention.v.weight": "pytorch_model-00007-of-00008.bin",
|
| 170 |
+
"decoder.block.19.layer.1.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 171 |
+
"decoder.block.19.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00007-of-00008.bin",
|
| 172 |
+
"decoder.block.19.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00007-of-00008.bin",
|
| 173 |
+
"decoder.block.19.layer.2.DenseReluDense.wo.weight": "pytorch_model-00007-of-00008.bin",
|
| 174 |
+
"decoder.block.19.layer.2.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 175 |
+
"decoder.block.2.layer.0.SelfAttention.k.weight": "pytorch_model-00004-of-00008.bin",
|
| 176 |
+
"decoder.block.2.layer.0.SelfAttention.o.weight": "pytorch_model-00004-of-00008.bin",
|
| 177 |
+
"decoder.block.2.layer.0.SelfAttention.q.weight": "pytorch_model-00004-of-00008.bin",
|
| 178 |
+
"decoder.block.2.layer.0.SelfAttention.v.weight": "pytorch_model-00004-of-00008.bin",
|
| 179 |
+
"decoder.block.2.layer.0.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 180 |
+
"decoder.block.2.layer.1.EncDecAttention.k.weight": "pytorch_model-00004-of-00008.bin",
|
| 181 |
+
"decoder.block.2.layer.1.EncDecAttention.o.weight": "pytorch_model-00004-of-00008.bin",
|
| 182 |
+
"decoder.block.2.layer.1.EncDecAttention.q.weight": "pytorch_model-00004-of-00008.bin",
|
| 183 |
+
"decoder.block.2.layer.1.EncDecAttention.v.weight": "pytorch_model-00004-of-00008.bin",
|
| 184 |
+
"decoder.block.2.layer.1.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 185 |
+
"decoder.block.2.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00004-of-00008.bin",
|
| 186 |
+
"decoder.block.2.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00004-of-00008.bin",
|
| 187 |
+
"decoder.block.2.layer.2.DenseReluDense.wo.weight": "pytorch_model-00005-of-00008.bin",
|
| 188 |
+
"decoder.block.2.layer.2.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 189 |
+
"decoder.block.20.layer.0.SelfAttention.k.weight": "pytorch_model-00007-of-00008.bin",
|
| 190 |
+
"decoder.block.20.layer.0.SelfAttention.o.weight": "pytorch_model-00007-of-00008.bin",
|
| 191 |
+
"decoder.block.20.layer.0.SelfAttention.q.weight": "pytorch_model-00007-of-00008.bin",
|
| 192 |
+
"decoder.block.20.layer.0.SelfAttention.v.weight": "pytorch_model-00007-of-00008.bin",
|
| 193 |
+
"decoder.block.20.layer.0.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 194 |
+
"decoder.block.20.layer.1.EncDecAttention.k.weight": "pytorch_model-00007-of-00008.bin",
|
| 195 |
+
"decoder.block.20.layer.1.EncDecAttention.o.weight": "pytorch_model-00007-of-00008.bin",
|
| 196 |
+
"decoder.block.20.layer.1.EncDecAttention.q.weight": "pytorch_model-00007-of-00008.bin",
|
| 197 |
+
"decoder.block.20.layer.1.EncDecAttention.v.weight": "pytorch_model-00007-of-00008.bin",
|
| 198 |
+
"decoder.block.20.layer.1.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 199 |
+
"decoder.block.20.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00007-of-00008.bin",
|
| 200 |
+
"decoder.block.20.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00007-of-00008.bin",
|
| 201 |
+
"decoder.block.20.layer.2.DenseReluDense.wo.weight": "pytorch_model-00007-of-00008.bin",
|
| 202 |
+
"decoder.block.20.layer.2.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 203 |
+
"decoder.block.21.layer.0.SelfAttention.k.weight": "pytorch_model-00007-of-00008.bin",
|
| 204 |
+
"decoder.block.21.layer.0.SelfAttention.o.weight": "pytorch_model-00007-of-00008.bin",
|
| 205 |
+
"decoder.block.21.layer.0.SelfAttention.q.weight": "pytorch_model-00007-of-00008.bin",
|
| 206 |
+
"decoder.block.21.layer.0.SelfAttention.v.weight": "pytorch_model-00007-of-00008.bin",
|
| 207 |
+
"decoder.block.21.layer.0.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 208 |
+
"decoder.block.21.layer.1.EncDecAttention.k.weight": "pytorch_model-00007-of-00008.bin",
|
| 209 |
+
"decoder.block.21.layer.1.EncDecAttention.o.weight": "pytorch_model-00007-of-00008.bin",
|
| 210 |
+
"decoder.block.21.layer.1.EncDecAttention.q.weight": "pytorch_model-00007-of-00008.bin",
|
| 211 |
+
"decoder.block.21.layer.1.EncDecAttention.v.weight": "pytorch_model-00007-of-00008.bin",
|
| 212 |
+
"decoder.block.21.layer.1.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 213 |
+
"decoder.block.21.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00007-of-00008.bin",
|
| 214 |
+
"decoder.block.21.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00007-of-00008.bin",
|
| 215 |
+
"decoder.block.21.layer.2.DenseReluDense.wo.weight": "pytorch_model-00007-of-00008.bin",
|
| 216 |
+
"decoder.block.21.layer.2.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 217 |
+
"decoder.block.22.layer.0.SelfAttention.k.weight": "pytorch_model-00007-of-00008.bin",
|
| 218 |
+
"decoder.block.22.layer.0.SelfAttention.o.weight": "pytorch_model-00007-of-00008.bin",
|
| 219 |
+
"decoder.block.22.layer.0.SelfAttention.q.weight": "pytorch_model-00007-of-00008.bin",
|
| 220 |
+
"decoder.block.22.layer.0.SelfAttention.v.weight": "pytorch_model-00007-of-00008.bin",
|
| 221 |
+
"decoder.block.22.layer.0.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 222 |
+
"decoder.block.22.layer.1.EncDecAttention.k.weight": "pytorch_model-00007-of-00008.bin",
|
| 223 |
+
"decoder.block.22.layer.1.EncDecAttention.o.weight": "pytorch_model-00007-of-00008.bin",
|
| 224 |
+
"decoder.block.22.layer.1.EncDecAttention.q.weight": "pytorch_model-00007-of-00008.bin",
|
| 225 |
+
"decoder.block.22.layer.1.EncDecAttention.v.weight": "pytorch_model-00007-of-00008.bin",
|
| 226 |
+
"decoder.block.22.layer.1.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 227 |
+
"decoder.block.22.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00007-of-00008.bin",
|
| 228 |
+
"decoder.block.22.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00007-of-00008.bin",
|
| 229 |
+
"decoder.block.22.layer.2.DenseReluDense.wo.weight": "pytorch_model-00007-of-00008.bin",
|
| 230 |
+
"decoder.block.22.layer.2.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 231 |
+
"decoder.block.23.layer.0.SelfAttention.k.weight": "pytorch_model-00007-of-00008.bin",
|
| 232 |
+
"decoder.block.23.layer.0.SelfAttention.o.weight": "pytorch_model-00007-of-00008.bin",
|
| 233 |
+
"decoder.block.23.layer.0.SelfAttention.q.weight": "pytorch_model-00007-of-00008.bin",
|
| 234 |
+
"decoder.block.23.layer.0.SelfAttention.v.weight": "pytorch_model-00007-of-00008.bin",
|
| 235 |
+
"decoder.block.23.layer.0.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 236 |
+
"decoder.block.23.layer.1.EncDecAttention.k.weight": "pytorch_model-00007-of-00008.bin",
|
| 237 |
+
"decoder.block.23.layer.1.EncDecAttention.o.weight": "pytorch_model-00007-of-00008.bin",
|
| 238 |
+
"decoder.block.23.layer.1.EncDecAttention.q.weight": "pytorch_model-00007-of-00008.bin",
|
| 239 |
+
"decoder.block.23.layer.1.EncDecAttention.v.weight": "pytorch_model-00007-of-00008.bin",
|
| 240 |
+
"decoder.block.23.layer.1.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 241 |
+
"decoder.block.23.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00007-of-00008.bin",
|
| 242 |
+
"decoder.block.23.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00007-of-00008.bin",
|
| 243 |
+
"decoder.block.23.layer.2.DenseReluDense.wo.weight": "pytorch_model-00007-of-00008.bin",
|
| 244 |
+
"decoder.block.23.layer.2.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 245 |
+
"decoder.block.24.layer.0.SelfAttention.k.weight": "pytorch_model-00007-of-00008.bin",
|
| 246 |
+
"decoder.block.24.layer.0.SelfAttention.o.weight": "pytorch_model-00007-of-00008.bin",
|
| 247 |
+
"decoder.block.24.layer.0.SelfAttention.q.weight": "pytorch_model-00007-of-00008.bin",
|
| 248 |
+
"decoder.block.24.layer.0.SelfAttention.v.weight": "pytorch_model-00007-of-00008.bin",
|
| 249 |
+
"decoder.block.24.layer.0.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 250 |
+
"decoder.block.24.layer.1.EncDecAttention.k.weight": "pytorch_model-00007-of-00008.bin",
|
| 251 |
+
"decoder.block.24.layer.1.EncDecAttention.o.weight": "pytorch_model-00007-of-00008.bin",
|
| 252 |
+
"decoder.block.24.layer.1.EncDecAttention.q.weight": "pytorch_model-00007-of-00008.bin",
|
| 253 |
+
"decoder.block.24.layer.1.EncDecAttention.v.weight": "pytorch_model-00007-of-00008.bin",
|
| 254 |
+
"decoder.block.24.layer.1.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 255 |
+
"decoder.block.24.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00007-of-00008.bin",
|
| 256 |
+
"decoder.block.24.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00007-of-00008.bin",
|
| 257 |
+
"decoder.block.24.layer.2.DenseReluDense.wo.weight": "pytorch_model-00007-of-00008.bin",
|
| 258 |
+
"decoder.block.24.layer.2.layer_norm.weight": "pytorch_model-00007-of-00008.bin",
|
| 259 |
+
"decoder.block.25.layer.0.SelfAttention.k.weight": "pytorch_model-00008-of-00008.bin",
|
| 260 |
+
"decoder.block.25.layer.0.SelfAttention.o.weight": "pytorch_model-00008-of-00008.bin",
|
| 261 |
+
"decoder.block.25.layer.0.SelfAttention.q.weight": "pytorch_model-00007-of-00008.bin",
|
| 262 |
+
"decoder.block.25.layer.0.SelfAttention.v.weight": "pytorch_model-00008-of-00008.bin",
|
| 263 |
+
"decoder.block.25.layer.0.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 264 |
+
"decoder.block.25.layer.1.EncDecAttention.k.weight": "pytorch_model-00008-of-00008.bin",
|
| 265 |
+
"decoder.block.25.layer.1.EncDecAttention.o.weight": "pytorch_model-00008-of-00008.bin",
|
| 266 |
+
"decoder.block.25.layer.1.EncDecAttention.q.weight": "pytorch_model-00008-of-00008.bin",
|
| 267 |
+
"decoder.block.25.layer.1.EncDecAttention.v.weight": "pytorch_model-00008-of-00008.bin",
|
| 268 |
+
"decoder.block.25.layer.1.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 269 |
+
"decoder.block.25.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00008-of-00008.bin",
|
| 270 |
+
"decoder.block.25.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00008-of-00008.bin",
|
| 271 |
+
"decoder.block.25.layer.2.DenseReluDense.wo.weight": "pytorch_model-00008-of-00008.bin",
|
| 272 |
+
"decoder.block.25.layer.2.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 273 |
+
"decoder.block.26.layer.0.SelfAttention.k.weight": "pytorch_model-00008-of-00008.bin",
|
| 274 |
+
"decoder.block.26.layer.0.SelfAttention.o.weight": "pytorch_model-00008-of-00008.bin",
|
| 275 |
+
"decoder.block.26.layer.0.SelfAttention.q.weight": "pytorch_model-00008-of-00008.bin",
|
| 276 |
+
"decoder.block.26.layer.0.SelfAttention.v.weight": "pytorch_model-00008-of-00008.bin",
|
| 277 |
+
"decoder.block.26.layer.0.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 278 |
+
"decoder.block.26.layer.1.EncDecAttention.k.weight": "pytorch_model-00008-of-00008.bin",
|
| 279 |
+
"decoder.block.26.layer.1.EncDecAttention.o.weight": "pytorch_model-00008-of-00008.bin",
|
| 280 |
+
"decoder.block.26.layer.1.EncDecAttention.q.weight": "pytorch_model-00008-of-00008.bin",
|
| 281 |
+
"decoder.block.26.layer.1.EncDecAttention.v.weight": "pytorch_model-00008-of-00008.bin",
|
| 282 |
+
"decoder.block.26.layer.1.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 283 |
+
"decoder.block.26.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00008-of-00008.bin",
|
| 284 |
+
"decoder.block.26.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00008-of-00008.bin",
|
| 285 |
+
"decoder.block.26.layer.2.DenseReluDense.wo.weight": "pytorch_model-00008-of-00008.bin",
|
| 286 |
+
"decoder.block.26.layer.2.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 287 |
+
"decoder.block.27.layer.0.SelfAttention.k.weight": "pytorch_model-00008-of-00008.bin",
|
| 288 |
+
"decoder.block.27.layer.0.SelfAttention.o.weight": "pytorch_model-00008-of-00008.bin",
|
| 289 |
+
"decoder.block.27.layer.0.SelfAttention.q.weight": "pytorch_model-00008-of-00008.bin",
|
| 290 |
+
"decoder.block.27.layer.0.SelfAttention.v.weight": "pytorch_model-00008-of-00008.bin",
|
| 291 |
+
"decoder.block.27.layer.0.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 292 |
+
"decoder.block.27.layer.1.EncDecAttention.k.weight": "pytorch_model-00008-of-00008.bin",
|
| 293 |
+
"decoder.block.27.layer.1.EncDecAttention.o.weight": "pytorch_model-00008-of-00008.bin",
|
| 294 |
+
"decoder.block.27.layer.1.EncDecAttention.q.weight": "pytorch_model-00008-of-00008.bin",
|
| 295 |
+
"decoder.block.27.layer.1.EncDecAttention.v.weight": "pytorch_model-00008-of-00008.bin",
|
| 296 |
+
"decoder.block.27.layer.1.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 297 |
+
"decoder.block.27.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00008-of-00008.bin",
|
| 298 |
+
"decoder.block.27.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00008-of-00008.bin",
|
| 299 |
+
"decoder.block.27.layer.2.DenseReluDense.wo.weight": "pytorch_model-00008-of-00008.bin",
|
| 300 |
+
"decoder.block.27.layer.2.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 301 |
+
"decoder.block.28.layer.0.SelfAttention.k.weight": "pytorch_model-00008-of-00008.bin",
|
| 302 |
+
"decoder.block.28.layer.0.SelfAttention.o.weight": "pytorch_model-00008-of-00008.bin",
|
| 303 |
+
"decoder.block.28.layer.0.SelfAttention.q.weight": "pytorch_model-00008-of-00008.bin",
|
| 304 |
+
"decoder.block.28.layer.0.SelfAttention.v.weight": "pytorch_model-00008-of-00008.bin",
|
| 305 |
+
"decoder.block.28.layer.0.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 306 |
+
"decoder.block.28.layer.1.EncDecAttention.k.weight": "pytorch_model-00008-of-00008.bin",
|
| 307 |
+
"decoder.block.28.layer.1.EncDecAttention.o.weight": "pytorch_model-00008-of-00008.bin",
|
| 308 |
+
"decoder.block.28.layer.1.EncDecAttention.q.weight": "pytorch_model-00008-of-00008.bin",
|
| 309 |
+
"decoder.block.28.layer.1.EncDecAttention.v.weight": "pytorch_model-00008-of-00008.bin",
|
| 310 |
+
"decoder.block.28.layer.1.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 311 |
+
"decoder.block.28.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00008-of-00008.bin",
|
| 312 |
+
"decoder.block.28.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00008-of-00008.bin",
|
| 313 |
+
"decoder.block.28.layer.2.DenseReluDense.wo.weight": "pytorch_model-00008-of-00008.bin",
|
| 314 |
+
"decoder.block.28.layer.2.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 315 |
+
"decoder.block.29.layer.0.SelfAttention.k.weight": "pytorch_model-00008-of-00008.bin",
|
| 316 |
+
"decoder.block.29.layer.0.SelfAttention.o.weight": "pytorch_model-00008-of-00008.bin",
|
| 317 |
+
"decoder.block.29.layer.0.SelfAttention.q.weight": "pytorch_model-00008-of-00008.bin",
|
| 318 |
+
"decoder.block.29.layer.0.SelfAttention.v.weight": "pytorch_model-00008-of-00008.bin",
|
| 319 |
+
"decoder.block.29.layer.0.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 320 |
+
"decoder.block.29.layer.1.EncDecAttention.k.weight": "pytorch_model-00008-of-00008.bin",
|
| 321 |
+
"decoder.block.29.layer.1.EncDecAttention.o.weight": "pytorch_model-00008-of-00008.bin",
|
| 322 |
+
"decoder.block.29.layer.1.EncDecAttention.q.weight": "pytorch_model-00008-of-00008.bin",
|
| 323 |
+
"decoder.block.29.layer.1.EncDecAttention.v.weight": "pytorch_model-00008-of-00008.bin",
|
| 324 |
+
"decoder.block.29.layer.1.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 325 |
+
"decoder.block.29.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00008-of-00008.bin",
|
| 326 |
+
"decoder.block.29.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00008-of-00008.bin",
|
| 327 |
+
"decoder.block.29.layer.2.DenseReluDense.wo.weight": "pytorch_model-00008-of-00008.bin",
|
| 328 |
+
"decoder.block.29.layer.2.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 329 |
+
"decoder.block.3.layer.0.SelfAttention.k.weight": "pytorch_model-00005-of-00008.bin",
|
| 330 |
+
"decoder.block.3.layer.0.SelfAttention.o.weight": "pytorch_model-00005-of-00008.bin",
|
| 331 |
+
"decoder.block.3.layer.0.SelfAttention.q.weight": "pytorch_model-00005-of-00008.bin",
|
| 332 |
+
"decoder.block.3.layer.0.SelfAttention.v.weight": "pytorch_model-00005-of-00008.bin",
|
| 333 |
+
"decoder.block.3.layer.0.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 334 |
+
"decoder.block.3.layer.1.EncDecAttention.k.weight": "pytorch_model-00005-of-00008.bin",
|
| 335 |
+
"decoder.block.3.layer.1.EncDecAttention.o.weight": "pytorch_model-00005-of-00008.bin",
|
| 336 |
+
"decoder.block.3.layer.1.EncDecAttention.q.weight": "pytorch_model-00005-of-00008.bin",
|
| 337 |
+
"decoder.block.3.layer.1.EncDecAttention.v.weight": "pytorch_model-00005-of-00008.bin",
|
| 338 |
+
"decoder.block.3.layer.1.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 339 |
+
"decoder.block.3.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00005-of-00008.bin",
|
| 340 |
+
"decoder.block.3.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00005-of-00008.bin",
|
| 341 |
+
"decoder.block.3.layer.2.DenseReluDense.wo.weight": "pytorch_model-00005-of-00008.bin",
|
| 342 |
+
"decoder.block.3.layer.2.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 343 |
+
"decoder.block.30.layer.0.SelfAttention.k.weight": "pytorch_model-00008-of-00008.bin",
|
| 344 |
+
"decoder.block.30.layer.0.SelfAttention.o.weight": "pytorch_model-00008-of-00008.bin",
|
| 345 |
+
"decoder.block.30.layer.0.SelfAttention.q.weight": "pytorch_model-00008-of-00008.bin",
|
| 346 |
+
"decoder.block.30.layer.0.SelfAttention.v.weight": "pytorch_model-00008-of-00008.bin",
|
| 347 |
+
"decoder.block.30.layer.0.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 348 |
+
"decoder.block.30.layer.1.EncDecAttention.k.weight": "pytorch_model-00008-of-00008.bin",
|
| 349 |
+
"decoder.block.30.layer.1.EncDecAttention.o.weight": "pytorch_model-00008-of-00008.bin",
|
| 350 |
+
"decoder.block.30.layer.1.EncDecAttention.q.weight": "pytorch_model-00008-of-00008.bin",
|
| 351 |
+
"decoder.block.30.layer.1.EncDecAttention.v.weight": "pytorch_model-00008-of-00008.bin",
|
| 352 |
+
"decoder.block.30.layer.1.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 353 |
+
"decoder.block.30.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00008-of-00008.bin",
|
| 354 |
+
"decoder.block.30.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00008-of-00008.bin",
|
| 355 |
+
"decoder.block.30.layer.2.DenseReluDense.wo.weight": "pytorch_model-00008-of-00008.bin",
|
| 356 |
+
"decoder.block.30.layer.2.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 357 |
+
"decoder.block.31.layer.0.SelfAttention.k.weight": "pytorch_model-00008-of-00008.bin",
|
| 358 |
+
"decoder.block.31.layer.0.SelfAttention.o.weight": "pytorch_model-00008-of-00008.bin",
|
| 359 |
+
"decoder.block.31.layer.0.SelfAttention.q.weight": "pytorch_model-00008-of-00008.bin",
|
| 360 |
+
"decoder.block.31.layer.0.SelfAttention.v.weight": "pytorch_model-00008-of-00008.bin",
|
| 361 |
+
"decoder.block.31.layer.0.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 362 |
+
"decoder.block.31.layer.1.EncDecAttention.k.weight": "pytorch_model-00008-of-00008.bin",
|
| 363 |
+
"decoder.block.31.layer.1.EncDecAttention.o.weight": "pytorch_model-00008-of-00008.bin",
|
| 364 |
+
"decoder.block.31.layer.1.EncDecAttention.q.weight": "pytorch_model-00008-of-00008.bin",
|
| 365 |
+
"decoder.block.31.layer.1.EncDecAttention.v.weight": "pytorch_model-00008-of-00008.bin",
|
| 366 |
+
"decoder.block.31.layer.1.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 367 |
+
"decoder.block.31.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00008-of-00008.bin",
|
| 368 |
+
"decoder.block.31.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00008-of-00008.bin",
|
| 369 |
+
"decoder.block.31.layer.2.DenseReluDense.wo.weight": "pytorch_model-00008-of-00008.bin",
|
| 370 |
+
"decoder.block.31.layer.2.layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 371 |
+
"decoder.block.4.layer.0.SelfAttention.k.weight": "pytorch_model-00005-of-00008.bin",
|
| 372 |
+
"decoder.block.4.layer.0.SelfAttention.o.weight": "pytorch_model-00005-of-00008.bin",
|
| 373 |
+
"decoder.block.4.layer.0.SelfAttention.q.weight": "pytorch_model-00005-of-00008.bin",
|
| 374 |
+
"decoder.block.4.layer.0.SelfAttention.v.weight": "pytorch_model-00005-of-00008.bin",
|
| 375 |
+
"decoder.block.4.layer.0.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 376 |
+
"decoder.block.4.layer.1.EncDecAttention.k.weight": "pytorch_model-00005-of-00008.bin",
|
| 377 |
+
"decoder.block.4.layer.1.EncDecAttention.o.weight": "pytorch_model-00005-of-00008.bin",
|
| 378 |
+
"decoder.block.4.layer.1.EncDecAttention.q.weight": "pytorch_model-00005-of-00008.bin",
|
| 379 |
+
"decoder.block.4.layer.1.EncDecAttention.v.weight": "pytorch_model-00005-of-00008.bin",
|
| 380 |
+
"decoder.block.4.layer.1.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 381 |
+
"decoder.block.4.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00005-of-00008.bin",
|
| 382 |
+
"decoder.block.4.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00005-of-00008.bin",
|
| 383 |
+
"decoder.block.4.layer.2.DenseReluDense.wo.weight": "pytorch_model-00005-of-00008.bin",
|
| 384 |
+
"decoder.block.4.layer.2.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 385 |
+
"decoder.block.5.layer.0.SelfAttention.k.weight": "pytorch_model-00005-of-00008.bin",
|
| 386 |
+
"decoder.block.5.layer.0.SelfAttention.o.weight": "pytorch_model-00005-of-00008.bin",
|
| 387 |
+
"decoder.block.5.layer.0.SelfAttention.q.weight": "pytorch_model-00005-of-00008.bin",
|
| 388 |
+
"decoder.block.5.layer.0.SelfAttention.v.weight": "pytorch_model-00005-of-00008.bin",
|
| 389 |
+
"decoder.block.5.layer.0.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 390 |
+
"decoder.block.5.layer.1.EncDecAttention.k.weight": "pytorch_model-00005-of-00008.bin",
|
| 391 |
+
"decoder.block.5.layer.1.EncDecAttention.o.weight": "pytorch_model-00005-of-00008.bin",
|
| 392 |
+
"decoder.block.5.layer.1.EncDecAttention.q.weight": "pytorch_model-00005-of-00008.bin",
|
| 393 |
+
"decoder.block.5.layer.1.EncDecAttention.v.weight": "pytorch_model-00005-of-00008.bin",
|
| 394 |
+
"decoder.block.5.layer.1.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 395 |
+
"decoder.block.5.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00005-of-00008.bin",
|
| 396 |
+
"decoder.block.5.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00005-of-00008.bin",
|
| 397 |
+
"decoder.block.5.layer.2.DenseReluDense.wo.weight": "pytorch_model-00005-of-00008.bin",
|
| 398 |
+
"decoder.block.5.layer.2.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 399 |
+
"decoder.block.6.layer.0.SelfAttention.k.weight": "pytorch_model-00005-of-00008.bin",
|
| 400 |
+
"decoder.block.6.layer.0.SelfAttention.o.weight": "pytorch_model-00005-of-00008.bin",
|
| 401 |
+
"decoder.block.6.layer.0.SelfAttention.q.weight": "pytorch_model-00005-of-00008.bin",
|
| 402 |
+
"decoder.block.6.layer.0.SelfAttention.v.weight": "pytorch_model-00005-of-00008.bin",
|
| 403 |
+
"decoder.block.6.layer.0.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 404 |
+
"decoder.block.6.layer.1.EncDecAttention.k.weight": "pytorch_model-00005-of-00008.bin",
|
| 405 |
+
"decoder.block.6.layer.1.EncDecAttention.o.weight": "pytorch_model-00005-of-00008.bin",
|
| 406 |
+
"decoder.block.6.layer.1.EncDecAttention.q.weight": "pytorch_model-00005-of-00008.bin",
|
| 407 |
+
"decoder.block.6.layer.1.EncDecAttention.v.weight": "pytorch_model-00005-of-00008.bin",
|
| 408 |
+
"decoder.block.6.layer.1.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 409 |
+
"decoder.block.6.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00005-of-00008.bin",
|
| 410 |
+
"decoder.block.6.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00005-of-00008.bin",
|
| 411 |
+
"decoder.block.6.layer.2.DenseReluDense.wo.weight": "pytorch_model-00005-of-00008.bin",
|
| 412 |
+
"decoder.block.6.layer.2.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 413 |
+
"decoder.block.7.layer.0.SelfAttention.k.weight": "pytorch_model-00005-of-00008.bin",
|
| 414 |
+
"decoder.block.7.layer.0.SelfAttention.o.weight": "pytorch_model-00005-of-00008.bin",
|
| 415 |
+
"decoder.block.7.layer.0.SelfAttention.q.weight": "pytorch_model-00005-of-00008.bin",
|
| 416 |
+
"decoder.block.7.layer.0.SelfAttention.v.weight": "pytorch_model-00005-of-00008.bin",
|
| 417 |
+
"decoder.block.7.layer.0.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 418 |
+
"decoder.block.7.layer.1.EncDecAttention.k.weight": "pytorch_model-00005-of-00008.bin",
|
| 419 |
+
"decoder.block.7.layer.1.EncDecAttention.o.weight": "pytorch_model-00005-of-00008.bin",
|
| 420 |
+
"decoder.block.7.layer.1.EncDecAttention.q.weight": "pytorch_model-00005-of-00008.bin",
|
| 421 |
+
"decoder.block.7.layer.1.EncDecAttention.v.weight": "pytorch_model-00005-of-00008.bin",
|
| 422 |
+
"decoder.block.7.layer.1.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 423 |
+
"decoder.block.7.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00005-of-00008.bin",
|
| 424 |
+
"decoder.block.7.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00005-of-00008.bin",
|
| 425 |
+
"decoder.block.7.layer.2.DenseReluDense.wo.weight": "pytorch_model-00005-of-00008.bin",
|
| 426 |
+
"decoder.block.7.layer.2.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 427 |
+
"decoder.block.8.layer.0.SelfAttention.k.weight": "pytorch_model-00005-of-00008.bin",
|
| 428 |
+
"decoder.block.8.layer.0.SelfAttention.o.weight": "pytorch_model-00005-of-00008.bin",
|
| 429 |
+
"decoder.block.8.layer.0.SelfAttention.q.weight": "pytorch_model-00005-of-00008.bin",
|
| 430 |
+
"decoder.block.8.layer.0.SelfAttention.v.weight": "pytorch_model-00005-of-00008.bin",
|
| 431 |
+
"decoder.block.8.layer.0.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 432 |
+
"decoder.block.8.layer.1.EncDecAttention.k.weight": "pytorch_model-00005-of-00008.bin",
|
| 433 |
+
"decoder.block.8.layer.1.EncDecAttention.o.weight": "pytorch_model-00005-of-00008.bin",
|
| 434 |
+
"decoder.block.8.layer.1.EncDecAttention.q.weight": "pytorch_model-00005-of-00008.bin",
|
| 435 |
+
"decoder.block.8.layer.1.EncDecAttention.v.weight": "pytorch_model-00005-of-00008.bin",
|
| 436 |
+
"decoder.block.8.layer.1.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 437 |
+
"decoder.block.8.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00005-of-00008.bin",
|
| 438 |
+
"decoder.block.8.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00005-of-00008.bin",
|
| 439 |
+
"decoder.block.8.layer.2.DenseReluDense.wo.weight": "pytorch_model-00005-of-00008.bin",
|
| 440 |
+
"decoder.block.8.layer.2.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 441 |
+
"decoder.block.9.layer.0.SelfAttention.k.weight": "pytorch_model-00005-of-00008.bin",
|
| 442 |
+
"decoder.block.9.layer.0.SelfAttention.o.weight": "pytorch_model-00005-of-00008.bin",
|
| 443 |
+
"decoder.block.9.layer.0.SelfAttention.q.weight": "pytorch_model-00005-of-00008.bin",
|
| 444 |
+
"decoder.block.9.layer.0.SelfAttention.v.weight": "pytorch_model-00005-of-00008.bin",
|
| 445 |
+
"decoder.block.9.layer.0.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 446 |
+
"decoder.block.9.layer.1.EncDecAttention.k.weight": "pytorch_model-00005-of-00008.bin",
|
| 447 |
+
"decoder.block.9.layer.1.EncDecAttention.o.weight": "pytorch_model-00005-of-00008.bin",
|
| 448 |
+
"decoder.block.9.layer.1.EncDecAttention.q.weight": "pytorch_model-00005-of-00008.bin",
|
| 449 |
+
"decoder.block.9.layer.1.EncDecAttention.v.weight": "pytorch_model-00005-of-00008.bin",
|
| 450 |
+
"decoder.block.9.layer.1.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 451 |
+
"decoder.block.9.layer.2.DenseReluDense.wi_0.weight": "pytorch_model-00005-of-00008.bin",
|
| 452 |
+
"decoder.block.9.layer.2.DenseReluDense.wi_1.weight": "pytorch_model-00005-of-00008.bin",
|
| 453 |
+
"decoder.block.9.layer.2.DenseReluDense.wo.weight": "pytorch_model-00005-of-00008.bin",
|
| 454 |
+
"decoder.block.9.layer.2.layer_norm.weight": "pytorch_model-00005-of-00008.bin",
|
| 455 |
+
"decoder.embed_tokens.weight": "pytorch_model-00004-of-00008.bin",
|
| 456 |
+
"decoder.final_layer_norm.weight": "pytorch_model-00008-of-00008.bin",
|
| 457 |
+
"encoder.block.0.layer.0.SelfAttention.k.weight": "pytorch_model-00001-of-00008.bin",
|
| 458 |
+
"encoder.block.0.layer.0.SelfAttention.o.weight": "pytorch_model-00001-of-00008.bin",
|
| 459 |
+
"encoder.block.0.layer.0.SelfAttention.q.weight": "pytorch_model-00001-of-00008.bin",
|
| 460 |
+
"encoder.block.0.layer.0.SelfAttention.relative_attention_bias.weight": "pytorch_model-00001-of-00008.bin",
|
| 461 |
+
"encoder.block.0.layer.0.SelfAttention.v.weight": "pytorch_model-00001-of-00008.bin",
|
| 462 |
+
"encoder.block.0.layer.0.layer_norm.weight": "pytorch_model-00001-of-00008.bin",
|
| 463 |
+
"encoder.block.0.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00001-of-00008.bin",
|
| 464 |
+
"encoder.block.0.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00001-of-00008.bin",
|
| 465 |
+
"encoder.block.0.layer.1.DenseReluDense.wo.weight": "pytorch_model-00001-of-00008.bin",
|
| 466 |
+
"encoder.block.0.layer.1.layer_norm.weight": "pytorch_model-00001-of-00008.bin",
|
| 467 |
+
"encoder.block.1.layer.0.SelfAttention.k.weight": "pytorch_model-00001-of-00008.bin",
|
| 468 |
+
"encoder.block.1.layer.0.SelfAttention.o.weight": "pytorch_model-00001-of-00008.bin",
|
| 469 |
+
"encoder.block.1.layer.0.SelfAttention.q.weight": "pytorch_model-00001-of-00008.bin",
|
| 470 |
+
"encoder.block.1.layer.0.SelfAttention.v.weight": "pytorch_model-00001-of-00008.bin",
|
| 471 |
+
"encoder.block.1.layer.0.layer_norm.weight": "pytorch_model-00001-of-00008.bin",
|
| 472 |
+
"encoder.block.1.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00001-of-00008.bin",
|
| 473 |
+
"encoder.block.1.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00001-of-00008.bin",
|
| 474 |
+
"encoder.block.1.layer.1.DenseReluDense.wo.weight": "pytorch_model-00001-of-00008.bin",
|
| 475 |
+
"encoder.block.1.layer.1.layer_norm.weight": "pytorch_model-00001-of-00008.bin",
|
| 476 |
+
"encoder.block.10.layer.0.SelfAttention.k.weight": "pytorch_model-00002-of-00008.bin",
|
| 477 |
+
"encoder.block.10.layer.0.SelfAttention.o.weight": "pytorch_model-00002-of-00008.bin",
|
| 478 |
+
"encoder.block.10.layer.0.SelfAttention.q.weight": "pytorch_model-00002-of-00008.bin",
|
| 479 |
+
"encoder.block.10.layer.0.SelfAttention.v.weight": "pytorch_model-00002-of-00008.bin",
|
| 480 |
+
"encoder.block.10.layer.0.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 481 |
+
"encoder.block.10.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00002-of-00008.bin",
|
| 482 |
+
"encoder.block.10.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00002-of-00008.bin",
|
| 483 |
+
"encoder.block.10.layer.1.DenseReluDense.wo.weight": "pytorch_model-00002-of-00008.bin",
|
| 484 |
+
"encoder.block.10.layer.1.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 485 |
+
"encoder.block.11.layer.0.SelfAttention.k.weight": "pytorch_model-00002-of-00008.bin",
|
| 486 |
+
"encoder.block.11.layer.0.SelfAttention.o.weight": "pytorch_model-00002-of-00008.bin",
|
| 487 |
+
"encoder.block.11.layer.0.SelfAttention.q.weight": "pytorch_model-00002-of-00008.bin",
|
| 488 |
+
"encoder.block.11.layer.0.SelfAttention.v.weight": "pytorch_model-00002-of-00008.bin",
|
| 489 |
+
"encoder.block.11.layer.0.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 490 |
+
"encoder.block.11.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00002-of-00008.bin",
|
| 491 |
+
"encoder.block.11.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00002-of-00008.bin",
|
| 492 |
+
"encoder.block.11.layer.1.DenseReluDense.wo.weight": "pytorch_model-00002-of-00008.bin",
|
| 493 |
+
"encoder.block.11.layer.1.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 494 |
+
"encoder.block.12.layer.0.SelfAttention.k.weight": "pytorch_model-00002-of-00008.bin",
|
| 495 |
+
"encoder.block.12.layer.0.SelfAttention.o.weight": "pytorch_model-00002-of-00008.bin",
|
| 496 |
+
"encoder.block.12.layer.0.SelfAttention.q.weight": "pytorch_model-00002-of-00008.bin",
|
| 497 |
+
"encoder.block.12.layer.0.SelfAttention.v.weight": "pytorch_model-00002-of-00008.bin",
|
| 498 |
+
"encoder.block.12.layer.0.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 499 |
+
"encoder.block.12.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00002-of-00008.bin",
|
| 500 |
+
"encoder.block.12.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00002-of-00008.bin",
|
| 501 |
+
"encoder.block.12.layer.1.DenseReluDense.wo.weight": "pytorch_model-00002-of-00008.bin",
|
| 502 |
+
"encoder.block.12.layer.1.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 503 |
+
"encoder.block.13.layer.0.SelfAttention.k.weight": "pytorch_model-00002-of-00008.bin",
|
| 504 |
+
"encoder.block.13.layer.0.SelfAttention.o.weight": "pytorch_model-00002-of-00008.bin",
|
| 505 |
+
"encoder.block.13.layer.0.SelfAttention.q.weight": "pytorch_model-00002-of-00008.bin",
|
| 506 |
+
"encoder.block.13.layer.0.SelfAttention.v.weight": "pytorch_model-00002-of-00008.bin",
|
| 507 |
+
"encoder.block.13.layer.0.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 508 |
+
"encoder.block.13.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00002-of-00008.bin",
|
| 509 |
+
"encoder.block.13.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00002-of-00008.bin",
|
| 510 |
+
"encoder.block.13.layer.1.DenseReluDense.wo.weight": "pytorch_model-00002-of-00008.bin",
|
| 511 |
+
"encoder.block.13.layer.1.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 512 |
+
"encoder.block.14.layer.0.SelfAttention.k.weight": "pytorch_model-00002-of-00008.bin",
|
| 513 |
+
"encoder.block.14.layer.0.SelfAttention.o.weight": "pytorch_model-00002-of-00008.bin",
|
| 514 |
+
"encoder.block.14.layer.0.SelfAttention.q.weight": "pytorch_model-00002-of-00008.bin",
|
| 515 |
+
"encoder.block.14.layer.0.SelfAttention.v.weight": "pytorch_model-00002-of-00008.bin",
|
| 516 |
+
"encoder.block.14.layer.0.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 517 |
+
"encoder.block.14.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00002-of-00008.bin",
|
| 518 |
+
"encoder.block.14.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00002-of-00008.bin",
|
| 519 |
+
"encoder.block.14.layer.1.DenseReluDense.wo.weight": "pytorch_model-00002-of-00008.bin",
|
| 520 |
+
"encoder.block.14.layer.1.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 521 |
+
"encoder.block.15.layer.0.SelfAttention.k.weight": "pytorch_model-00002-of-00008.bin",
|
| 522 |
+
"encoder.block.15.layer.0.SelfAttention.o.weight": "pytorch_model-00002-of-00008.bin",
|
| 523 |
+
"encoder.block.15.layer.0.SelfAttention.q.weight": "pytorch_model-00002-of-00008.bin",
|
| 524 |
+
"encoder.block.15.layer.0.SelfAttention.v.weight": "pytorch_model-00002-of-00008.bin",
|
| 525 |
+
"encoder.block.15.layer.0.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 526 |
+
"encoder.block.15.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00002-of-00008.bin",
|
| 527 |
+
"encoder.block.15.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00002-of-00008.bin",
|
| 528 |
+
"encoder.block.15.layer.1.DenseReluDense.wo.weight": "pytorch_model-00002-of-00008.bin",
|
| 529 |
+
"encoder.block.15.layer.1.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 530 |
+
"encoder.block.16.layer.0.SelfAttention.k.weight": "pytorch_model-00002-of-00008.bin",
|
| 531 |
+
"encoder.block.16.layer.0.SelfAttention.o.weight": "pytorch_model-00002-of-00008.bin",
|
| 532 |
+
"encoder.block.16.layer.0.SelfAttention.q.weight": "pytorch_model-00002-of-00008.bin",
|
| 533 |
+
"encoder.block.16.layer.0.SelfAttention.v.weight": "pytorch_model-00002-of-00008.bin",
|
| 534 |
+
"encoder.block.16.layer.0.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 535 |
+
"encoder.block.16.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00002-of-00008.bin",
|
| 536 |
+
"encoder.block.16.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00002-of-00008.bin",
|
| 537 |
+
"encoder.block.16.layer.1.DenseReluDense.wo.weight": "pytorch_model-00002-of-00008.bin",
|
| 538 |
+
"encoder.block.16.layer.1.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 539 |
+
"encoder.block.17.layer.0.SelfAttention.k.weight": "pytorch_model-00002-of-00008.bin",
|
| 540 |
+
"encoder.block.17.layer.0.SelfAttention.o.weight": "pytorch_model-00002-of-00008.bin",
|
| 541 |
+
"encoder.block.17.layer.0.SelfAttention.q.weight": "pytorch_model-00002-of-00008.bin",
|
| 542 |
+
"encoder.block.17.layer.0.SelfAttention.v.weight": "pytorch_model-00002-of-00008.bin",
|
| 543 |
+
"encoder.block.17.layer.0.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 544 |
+
"encoder.block.17.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00002-of-00008.bin",
|
| 545 |
+
"encoder.block.17.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00003-of-00008.bin",
|
| 546 |
+
"encoder.block.17.layer.1.DenseReluDense.wo.weight": "pytorch_model-00003-of-00008.bin",
|
| 547 |
+
"encoder.block.17.layer.1.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 548 |
+
"encoder.block.18.layer.0.SelfAttention.k.weight": "pytorch_model-00003-of-00008.bin",
|
| 549 |
+
"encoder.block.18.layer.0.SelfAttention.o.weight": "pytorch_model-00003-of-00008.bin",
|
| 550 |
+
"encoder.block.18.layer.0.SelfAttention.q.weight": "pytorch_model-00003-of-00008.bin",
|
| 551 |
+
"encoder.block.18.layer.0.SelfAttention.v.weight": "pytorch_model-00003-of-00008.bin",
|
| 552 |
+
"encoder.block.18.layer.0.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 553 |
+
"encoder.block.18.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00003-of-00008.bin",
|
| 554 |
+
"encoder.block.18.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00003-of-00008.bin",
|
| 555 |
+
"encoder.block.18.layer.1.DenseReluDense.wo.weight": "pytorch_model-00003-of-00008.bin",
|
| 556 |
+
"encoder.block.18.layer.1.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 557 |
+
"encoder.block.19.layer.0.SelfAttention.k.weight": "pytorch_model-00003-of-00008.bin",
|
| 558 |
+
"encoder.block.19.layer.0.SelfAttention.o.weight": "pytorch_model-00003-of-00008.bin",
|
| 559 |
+
"encoder.block.19.layer.0.SelfAttention.q.weight": "pytorch_model-00003-of-00008.bin",
|
| 560 |
+
"encoder.block.19.layer.0.SelfAttention.v.weight": "pytorch_model-00003-of-00008.bin",
|
| 561 |
+
"encoder.block.19.layer.0.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 562 |
+
"encoder.block.19.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00003-of-00008.bin",
|
| 563 |
+
"encoder.block.19.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00003-of-00008.bin",
|
| 564 |
+
"encoder.block.19.layer.1.DenseReluDense.wo.weight": "pytorch_model-00003-of-00008.bin",
|
| 565 |
+
"encoder.block.19.layer.1.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 566 |
+
"encoder.block.2.layer.0.SelfAttention.k.weight": "pytorch_model-00001-of-00008.bin",
|
| 567 |
+
"encoder.block.2.layer.0.SelfAttention.o.weight": "pytorch_model-00001-of-00008.bin",
|
| 568 |
+
"encoder.block.2.layer.0.SelfAttention.q.weight": "pytorch_model-00001-of-00008.bin",
|
| 569 |
+
"encoder.block.2.layer.0.SelfAttention.v.weight": "pytorch_model-00001-of-00008.bin",
|
| 570 |
+
"encoder.block.2.layer.0.layer_norm.weight": "pytorch_model-00001-of-00008.bin",
|
| 571 |
+
"encoder.block.2.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00001-of-00008.bin",
|
| 572 |
+
"encoder.block.2.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00001-of-00008.bin",
|
| 573 |
+
"encoder.block.2.layer.1.DenseReluDense.wo.weight": "pytorch_model-00001-of-00008.bin",
|
| 574 |
+
"encoder.block.2.layer.1.layer_norm.weight": "pytorch_model-00001-of-00008.bin",
|
| 575 |
+
"encoder.block.20.layer.0.SelfAttention.k.weight": "pytorch_model-00003-of-00008.bin",
|
| 576 |
+
"encoder.block.20.layer.0.SelfAttention.o.weight": "pytorch_model-00003-of-00008.bin",
|
| 577 |
+
"encoder.block.20.layer.0.SelfAttention.q.weight": "pytorch_model-00003-of-00008.bin",
|
| 578 |
+
"encoder.block.20.layer.0.SelfAttention.v.weight": "pytorch_model-00003-of-00008.bin",
|
| 579 |
+
"encoder.block.20.layer.0.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 580 |
+
"encoder.block.20.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00003-of-00008.bin",
|
| 581 |
+
"encoder.block.20.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00003-of-00008.bin",
|
| 582 |
+
"encoder.block.20.layer.1.DenseReluDense.wo.weight": "pytorch_model-00003-of-00008.bin",
|
| 583 |
+
"encoder.block.20.layer.1.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 584 |
+
"encoder.block.21.layer.0.SelfAttention.k.weight": "pytorch_model-00003-of-00008.bin",
|
| 585 |
+
"encoder.block.21.layer.0.SelfAttention.o.weight": "pytorch_model-00003-of-00008.bin",
|
| 586 |
+
"encoder.block.21.layer.0.SelfAttention.q.weight": "pytorch_model-00003-of-00008.bin",
|
| 587 |
+
"encoder.block.21.layer.0.SelfAttention.v.weight": "pytorch_model-00003-of-00008.bin",
|
| 588 |
+
"encoder.block.21.layer.0.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 589 |
+
"encoder.block.21.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00003-of-00008.bin",
|
| 590 |
+
"encoder.block.21.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00003-of-00008.bin",
|
| 591 |
+
"encoder.block.21.layer.1.DenseReluDense.wo.weight": "pytorch_model-00003-of-00008.bin",
|
| 592 |
+
"encoder.block.21.layer.1.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 593 |
+
"encoder.block.22.layer.0.SelfAttention.k.weight": "pytorch_model-00003-of-00008.bin",
|
| 594 |
+
"encoder.block.22.layer.0.SelfAttention.o.weight": "pytorch_model-00003-of-00008.bin",
|
| 595 |
+
"encoder.block.22.layer.0.SelfAttention.q.weight": "pytorch_model-00003-of-00008.bin",
|
| 596 |
+
"encoder.block.22.layer.0.SelfAttention.v.weight": "pytorch_model-00003-of-00008.bin",
|
| 597 |
+
"encoder.block.22.layer.0.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 598 |
+
"encoder.block.22.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00003-of-00008.bin",
|
| 599 |
+
"encoder.block.22.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00003-of-00008.bin",
|
| 600 |
+
"encoder.block.22.layer.1.DenseReluDense.wo.weight": "pytorch_model-00003-of-00008.bin",
|
| 601 |
+
"encoder.block.22.layer.1.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 602 |
+
"encoder.block.23.layer.0.SelfAttention.k.weight": "pytorch_model-00003-of-00008.bin",
|
| 603 |
+
"encoder.block.23.layer.0.SelfAttention.o.weight": "pytorch_model-00003-of-00008.bin",
|
| 604 |
+
"encoder.block.23.layer.0.SelfAttention.q.weight": "pytorch_model-00003-of-00008.bin",
|
| 605 |
+
"encoder.block.23.layer.0.SelfAttention.v.weight": "pytorch_model-00003-of-00008.bin",
|
| 606 |
+
"encoder.block.23.layer.0.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 607 |
+
"encoder.block.23.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00003-of-00008.bin",
|
| 608 |
+
"encoder.block.23.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00003-of-00008.bin",
|
| 609 |
+
"encoder.block.23.layer.1.DenseReluDense.wo.weight": "pytorch_model-00003-of-00008.bin",
|
| 610 |
+
"encoder.block.23.layer.1.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 611 |
+
"encoder.block.24.layer.0.SelfAttention.k.weight": "pytorch_model-00003-of-00008.bin",
|
| 612 |
+
"encoder.block.24.layer.0.SelfAttention.o.weight": "pytorch_model-00003-of-00008.bin",
|
| 613 |
+
"encoder.block.24.layer.0.SelfAttention.q.weight": "pytorch_model-00003-of-00008.bin",
|
| 614 |
+
"encoder.block.24.layer.0.SelfAttention.v.weight": "pytorch_model-00003-of-00008.bin",
|
| 615 |
+
"encoder.block.24.layer.0.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 616 |
+
"encoder.block.24.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00003-of-00008.bin",
|
| 617 |
+
"encoder.block.24.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00003-of-00008.bin",
|
| 618 |
+
"encoder.block.24.layer.1.DenseReluDense.wo.weight": "pytorch_model-00003-of-00008.bin",
|
| 619 |
+
"encoder.block.24.layer.1.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 620 |
+
"encoder.block.25.layer.0.SelfAttention.k.weight": "pytorch_model-00003-of-00008.bin",
|
| 621 |
+
"encoder.block.25.layer.0.SelfAttention.o.weight": "pytorch_model-00003-of-00008.bin",
|
| 622 |
+
"encoder.block.25.layer.0.SelfAttention.q.weight": "pytorch_model-00003-of-00008.bin",
|
| 623 |
+
"encoder.block.25.layer.0.SelfAttention.v.weight": "pytorch_model-00003-of-00008.bin",
|
| 624 |
+
"encoder.block.25.layer.0.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 625 |
+
"encoder.block.25.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00003-of-00008.bin",
|
| 626 |
+
"encoder.block.25.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00003-of-00008.bin",
|
| 627 |
+
"encoder.block.25.layer.1.DenseReluDense.wo.weight": "pytorch_model-00003-of-00008.bin",
|
| 628 |
+
"encoder.block.25.layer.1.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 629 |
+
"encoder.block.26.layer.0.SelfAttention.k.weight": "pytorch_model-00003-of-00008.bin",
|
| 630 |
+
"encoder.block.26.layer.0.SelfAttention.o.weight": "pytorch_model-00003-of-00008.bin",
|
| 631 |
+
"encoder.block.26.layer.0.SelfAttention.q.weight": "pytorch_model-00003-of-00008.bin",
|
| 632 |
+
"encoder.block.26.layer.0.SelfAttention.v.weight": "pytorch_model-00003-of-00008.bin",
|
| 633 |
+
"encoder.block.26.layer.0.layer_norm.weight": "pytorch_model-00003-of-00008.bin",
|
| 634 |
+
"encoder.block.26.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00003-of-00008.bin",
|
| 635 |
+
"encoder.block.26.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00003-of-00008.bin",
|
| 636 |
+
"encoder.block.26.layer.1.DenseReluDense.wo.weight": "pytorch_model-00004-of-00008.bin",
|
| 637 |
+
"encoder.block.26.layer.1.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 638 |
+
"encoder.block.27.layer.0.SelfAttention.k.weight": "pytorch_model-00004-of-00008.bin",
|
| 639 |
+
"encoder.block.27.layer.0.SelfAttention.o.weight": "pytorch_model-00004-of-00008.bin",
|
| 640 |
+
"encoder.block.27.layer.0.SelfAttention.q.weight": "pytorch_model-00004-of-00008.bin",
|
| 641 |
+
"encoder.block.27.layer.0.SelfAttention.v.weight": "pytorch_model-00004-of-00008.bin",
|
| 642 |
+
"encoder.block.27.layer.0.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 643 |
+
"encoder.block.27.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00004-of-00008.bin",
|
| 644 |
+
"encoder.block.27.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00004-of-00008.bin",
|
| 645 |
+
"encoder.block.27.layer.1.DenseReluDense.wo.weight": "pytorch_model-00004-of-00008.bin",
|
| 646 |
+
"encoder.block.27.layer.1.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 647 |
+
"encoder.block.28.layer.0.SelfAttention.k.weight": "pytorch_model-00004-of-00008.bin",
|
| 648 |
+
"encoder.block.28.layer.0.SelfAttention.o.weight": "pytorch_model-00004-of-00008.bin",
|
| 649 |
+
"encoder.block.28.layer.0.SelfAttention.q.weight": "pytorch_model-00004-of-00008.bin",
|
| 650 |
+
"encoder.block.28.layer.0.SelfAttention.v.weight": "pytorch_model-00004-of-00008.bin",
|
| 651 |
+
"encoder.block.28.layer.0.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 652 |
+
"encoder.block.28.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00004-of-00008.bin",
|
| 653 |
+
"encoder.block.28.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00004-of-00008.bin",
|
| 654 |
+
"encoder.block.28.layer.1.DenseReluDense.wo.weight": "pytorch_model-00004-of-00008.bin",
|
| 655 |
+
"encoder.block.28.layer.1.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 656 |
+
"encoder.block.29.layer.0.SelfAttention.k.weight": "pytorch_model-00004-of-00008.bin",
|
| 657 |
+
"encoder.block.29.layer.0.SelfAttention.o.weight": "pytorch_model-00004-of-00008.bin",
|
| 658 |
+
"encoder.block.29.layer.0.SelfAttention.q.weight": "pytorch_model-00004-of-00008.bin",
|
| 659 |
+
"encoder.block.29.layer.0.SelfAttention.v.weight": "pytorch_model-00004-of-00008.bin",
|
| 660 |
+
"encoder.block.29.layer.0.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 661 |
+
"encoder.block.29.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00004-of-00008.bin",
|
| 662 |
+
"encoder.block.29.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00004-of-00008.bin",
|
| 663 |
+
"encoder.block.29.layer.1.DenseReluDense.wo.weight": "pytorch_model-00004-of-00008.bin",
|
| 664 |
+
"encoder.block.29.layer.1.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 665 |
+
"encoder.block.3.layer.0.SelfAttention.k.weight": "pytorch_model-00001-of-00008.bin",
|
| 666 |
+
"encoder.block.3.layer.0.SelfAttention.o.weight": "pytorch_model-00001-of-00008.bin",
|
| 667 |
+
"encoder.block.3.layer.0.SelfAttention.q.weight": "pytorch_model-00001-of-00008.bin",
|
| 668 |
+
"encoder.block.3.layer.0.SelfAttention.v.weight": "pytorch_model-00001-of-00008.bin",
|
| 669 |
+
"encoder.block.3.layer.0.layer_norm.weight": "pytorch_model-00001-of-00008.bin",
|
| 670 |
+
"encoder.block.3.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00001-of-00008.bin",
|
| 671 |
+
"encoder.block.3.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00001-of-00008.bin",
|
| 672 |
+
"encoder.block.3.layer.1.DenseReluDense.wo.weight": "pytorch_model-00001-of-00008.bin",
|
| 673 |
+
"encoder.block.3.layer.1.layer_norm.weight": "pytorch_model-00001-of-00008.bin",
|
| 674 |
+
"encoder.block.30.layer.0.SelfAttention.k.weight": "pytorch_model-00004-of-00008.bin",
|
| 675 |
+
"encoder.block.30.layer.0.SelfAttention.o.weight": "pytorch_model-00004-of-00008.bin",
|
| 676 |
+
"encoder.block.30.layer.0.SelfAttention.q.weight": "pytorch_model-00004-of-00008.bin",
|
| 677 |
+
"encoder.block.30.layer.0.SelfAttention.v.weight": "pytorch_model-00004-of-00008.bin",
|
| 678 |
+
"encoder.block.30.layer.0.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 679 |
+
"encoder.block.30.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00004-of-00008.bin",
|
| 680 |
+
"encoder.block.30.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00004-of-00008.bin",
|
| 681 |
+
"encoder.block.30.layer.1.DenseReluDense.wo.weight": "pytorch_model-00004-of-00008.bin",
|
| 682 |
+
"encoder.block.30.layer.1.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 683 |
+
"encoder.block.31.layer.0.SelfAttention.k.weight": "pytorch_model-00004-of-00008.bin",
|
| 684 |
+
"encoder.block.31.layer.0.SelfAttention.o.weight": "pytorch_model-00004-of-00008.bin",
|
| 685 |
+
"encoder.block.31.layer.0.SelfAttention.q.weight": "pytorch_model-00004-of-00008.bin",
|
| 686 |
+
"encoder.block.31.layer.0.SelfAttention.v.weight": "pytorch_model-00004-of-00008.bin",
|
| 687 |
+
"encoder.block.31.layer.0.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 688 |
+
"encoder.block.31.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00004-of-00008.bin",
|
| 689 |
+
"encoder.block.31.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00004-of-00008.bin",
|
| 690 |
+
"encoder.block.31.layer.1.DenseReluDense.wo.weight": "pytorch_model-00004-of-00008.bin",
|
| 691 |
+
"encoder.block.31.layer.1.layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 692 |
+
"encoder.block.4.layer.0.SelfAttention.k.weight": "pytorch_model-00001-of-00008.bin",
|
| 693 |
+
"encoder.block.4.layer.0.SelfAttention.o.weight": "pytorch_model-00001-of-00008.bin",
|
| 694 |
+
"encoder.block.4.layer.0.SelfAttention.q.weight": "pytorch_model-00001-of-00008.bin",
|
| 695 |
+
"encoder.block.4.layer.0.SelfAttention.v.weight": "pytorch_model-00001-of-00008.bin",
|
| 696 |
+
"encoder.block.4.layer.0.layer_norm.weight": "pytorch_model-00001-of-00008.bin",
|
| 697 |
+
"encoder.block.4.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00001-of-00008.bin",
|
| 698 |
+
"encoder.block.4.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00001-of-00008.bin",
|
| 699 |
+
"encoder.block.4.layer.1.DenseReluDense.wo.weight": "pytorch_model-00001-of-00008.bin",
|
| 700 |
+
"encoder.block.4.layer.1.layer_norm.weight": "pytorch_model-00001-of-00008.bin",
|
| 701 |
+
"encoder.block.5.layer.0.SelfAttention.k.weight": "pytorch_model-00001-of-00008.bin",
|
| 702 |
+
"encoder.block.5.layer.0.SelfAttention.o.weight": "pytorch_model-00001-of-00008.bin",
|
| 703 |
+
"encoder.block.5.layer.0.SelfAttention.q.weight": "pytorch_model-00001-of-00008.bin",
|
| 704 |
+
"encoder.block.5.layer.0.SelfAttention.v.weight": "pytorch_model-00001-of-00008.bin",
|
| 705 |
+
"encoder.block.5.layer.0.layer_norm.weight": "pytorch_model-00001-of-00008.bin",
|
| 706 |
+
"encoder.block.5.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00001-of-00008.bin",
|
| 707 |
+
"encoder.block.5.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00001-of-00008.bin",
|
| 708 |
+
"encoder.block.5.layer.1.DenseReluDense.wo.weight": "pytorch_model-00001-of-00008.bin",
|
| 709 |
+
"encoder.block.5.layer.1.layer_norm.weight": "pytorch_model-00001-of-00008.bin",
|
| 710 |
+
"encoder.block.6.layer.0.SelfAttention.k.weight": "pytorch_model-00001-of-00008.bin",
|
| 711 |
+
"encoder.block.6.layer.0.SelfAttention.o.weight": "pytorch_model-00001-of-00008.bin",
|
| 712 |
+
"encoder.block.6.layer.0.SelfAttention.q.weight": "pytorch_model-00001-of-00008.bin",
|
| 713 |
+
"encoder.block.6.layer.0.SelfAttention.v.weight": "pytorch_model-00001-of-00008.bin",
|
| 714 |
+
"encoder.block.6.layer.0.layer_norm.weight": "pytorch_model-00001-of-00008.bin",
|
| 715 |
+
"encoder.block.6.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00001-of-00008.bin",
|
| 716 |
+
"encoder.block.6.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00001-of-00008.bin",
|
| 717 |
+
"encoder.block.6.layer.1.DenseReluDense.wo.weight": "pytorch_model-00001-of-00008.bin",
|
| 718 |
+
"encoder.block.6.layer.1.layer_norm.weight": "pytorch_model-00001-of-00008.bin",
|
| 719 |
+
"encoder.block.7.layer.0.SelfAttention.k.weight": "pytorch_model-00001-of-00008.bin",
|
| 720 |
+
"encoder.block.7.layer.0.SelfAttention.o.weight": "pytorch_model-00001-of-00008.bin",
|
| 721 |
+
"encoder.block.7.layer.0.SelfAttention.q.weight": "pytorch_model-00001-of-00008.bin",
|
| 722 |
+
"encoder.block.7.layer.0.SelfAttention.v.weight": "pytorch_model-00001-of-00008.bin",
|
| 723 |
+
"encoder.block.7.layer.0.layer_norm.weight": "pytorch_model-00001-of-00008.bin",
|
| 724 |
+
"encoder.block.7.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00001-of-00008.bin",
|
| 725 |
+
"encoder.block.7.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00001-of-00008.bin",
|
| 726 |
+
"encoder.block.7.layer.1.DenseReluDense.wo.weight": "pytorch_model-00001-of-00008.bin",
|
| 727 |
+
"encoder.block.7.layer.1.layer_norm.weight": "pytorch_model-00001-of-00008.bin",
|
| 728 |
+
"encoder.block.8.layer.0.SelfAttention.k.weight": "pytorch_model-00001-of-00008.bin",
|
| 729 |
+
"encoder.block.8.layer.0.SelfAttention.o.weight": "pytorch_model-00001-of-00008.bin",
|
| 730 |
+
"encoder.block.8.layer.0.SelfAttention.q.weight": "pytorch_model-00001-of-00008.bin",
|
| 731 |
+
"encoder.block.8.layer.0.SelfAttention.v.weight": "pytorch_model-00001-of-00008.bin",
|
| 732 |
+
"encoder.block.8.layer.0.layer_norm.weight": "pytorch_model-00001-of-00008.bin",
|
| 733 |
+
"encoder.block.8.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00002-of-00008.bin",
|
| 734 |
+
"encoder.block.8.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00002-of-00008.bin",
|
| 735 |
+
"encoder.block.8.layer.1.DenseReluDense.wo.weight": "pytorch_model-00002-of-00008.bin",
|
| 736 |
+
"encoder.block.8.layer.1.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 737 |
+
"encoder.block.9.layer.0.SelfAttention.k.weight": "pytorch_model-00002-of-00008.bin",
|
| 738 |
+
"encoder.block.9.layer.0.SelfAttention.o.weight": "pytorch_model-00002-of-00008.bin",
|
| 739 |
+
"encoder.block.9.layer.0.SelfAttention.q.weight": "pytorch_model-00002-of-00008.bin",
|
| 740 |
+
"encoder.block.9.layer.0.SelfAttention.v.weight": "pytorch_model-00002-of-00008.bin",
|
| 741 |
+
"encoder.block.9.layer.0.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 742 |
+
"encoder.block.9.layer.1.DenseReluDense.wi_0.weight": "pytorch_model-00002-of-00008.bin",
|
| 743 |
+
"encoder.block.9.layer.1.DenseReluDense.wi_1.weight": "pytorch_model-00002-of-00008.bin",
|
| 744 |
+
"encoder.block.9.layer.1.DenseReluDense.wo.weight": "pytorch_model-00002-of-00008.bin",
|
| 745 |
+
"encoder.block.9.layer.1.layer_norm.weight": "pytorch_model-00002-of-00008.bin",
|
| 746 |
+
"encoder.embed_tokens.weight": "pytorch_model-00001-of-00008.bin",
|
| 747 |
+
"encoder.final_layer_norm.weight": "pytorch_model-00004-of-00008.bin",
|
| 748 |
+
"lm_head.weight": "pytorch_model-00008-of-00008.bin",
|
| 749 |
+
"shared.weight": "pytorch_model-00001-of-00008.bin"
|
| 750 |
+
}
|
| 751 |
+
}
|
special_tokens_map.json
ADDED
|
@@ -0,0 +1,107 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"additional_special_tokens": [
|
| 3 |
+
"<extra_id_0>",
|
| 4 |
+
"<extra_id_1>",
|
| 5 |
+
"<extra_id_2>",
|
| 6 |
+
"<extra_id_3>",
|
| 7 |
+
"<extra_id_4>",
|
| 8 |
+
"<extra_id_5>",
|
| 9 |
+
"<extra_id_6>",
|
| 10 |
+
"<extra_id_7>",
|
| 11 |
+
"<extra_id_8>",
|
| 12 |
+
"<extra_id_9>",
|
| 13 |
+
"<extra_id_10>",
|
| 14 |
+
"<extra_id_11>",
|
| 15 |
+
"<extra_id_12>",
|
| 16 |
+
"<extra_id_13>",
|
| 17 |
+
"<extra_id_14>",
|
| 18 |
+
"<extra_id_15>",
|
| 19 |
+
"<extra_id_16>",
|
| 20 |
+
"<extra_id_17>",
|
| 21 |
+
"<extra_id_18>",
|
| 22 |
+
"<extra_id_19>",
|
| 23 |
+
"<extra_id_20>",
|
| 24 |
+
"<extra_id_21>",
|
| 25 |
+
"<extra_id_22>",
|
| 26 |
+
"<extra_id_23>",
|
| 27 |
+
"<extra_id_24>",
|
| 28 |
+
"<extra_id_25>",
|
| 29 |
+
"<extra_id_26>",
|
| 30 |
+
"<extra_id_27>",
|
| 31 |
+
"<extra_id_28>",
|
| 32 |
+
"<extra_id_29>",
|
| 33 |
+
"<extra_id_30>",
|
| 34 |
+
"<extra_id_31>",
|
| 35 |
+
"<extra_id_32>",
|
| 36 |
+
"<extra_id_33>",
|
| 37 |
+
"<extra_id_34>",
|
| 38 |
+
"<extra_id_35>",
|
| 39 |
+
"<extra_id_36>",
|
| 40 |
+
"<extra_id_37>",
|
| 41 |
+
"<extra_id_38>",
|
| 42 |
+
"<extra_id_39>",
|
| 43 |
+
"<extra_id_40>",
|
| 44 |
+
"<extra_id_41>",
|
| 45 |
+
"<extra_id_42>",
|
| 46 |
+
"<extra_id_43>",
|
| 47 |
+
"<extra_id_44>",
|
| 48 |
+
"<extra_id_45>",
|
| 49 |
+
"<extra_id_46>",
|
| 50 |
+
"<extra_id_47>",
|
| 51 |
+
"<extra_id_48>",
|
| 52 |
+
"<extra_id_49>",
|
| 53 |
+
"<extra_id_50>",
|
| 54 |
+
"<extra_id_51>",
|
| 55 |
+
"<extra_id_52>",
|
| 56 |
+
"<extra_id_53>",
|
| 57 |
+
"<extra_id_54>",
|
| 58 |
+
"<extra_id_55>",
|
| 59 |
+
"<extra_id_56>",
|
| 60 |
+
"<extra_id_57>",
|
| 61 |
+
"<extra_id_58>",
|
| 62 |
+
"<extra_id_59>",
|
| 63 |
+
"<extra_id_60>",
|
| 64 |
+
"<extra_id_61>",
|
| 65 |
+
"<extra_id_62>",
|
| 66 |
+
"<extra_id_63>",
|
| 67 |
+
"<extra_id_64>",
|
| 68 |
+
"<extra_id_65>",
|
| 69 |
+
"<extra_id_66>",
|
| 70 |
+
"<extra_id_67>",
|
| 71 |
+
"<extra_id_68>",
|
| 72 |
+
"<extra_id_69>",
|
| 73 |
+
"<extra_id_70>",
|
| 74 |
+
"<extra_id_71>",
|
| 75 |
+
"<extra_id_72>",
|
| 76 |
+
"<extra_id_73>",
|
| 77 |
+
"<extra_id_74>",
|
| 78 |
+
"<extra_id_75>",
|
| 79 |
+
"<extra_id_76>",
|
| 80 |
+
"<extra_id_77>",
|
| 81 |
+
"<extra_id_78>",
|
| 82 |
+
"<extra_id_79>",
|
| 83 |
+
"<extra_id_80>",
|
| 84 |
+
"<extra_id_81>",
|
| 85 |
+
"<extra_id_82>",
|
| 86 |
+
"<extra_id_83>",
|
| 87 |
+
"<extra_id_84>",
|
| 88 |
+
"<extra_id_85>",
|
| 89 |
+
"<extra_id_86>",
|
| 90 |
+
"<extra_id_87>",
|
| 91 |
+
"<extra_id_88>",
|
| 92 |
+
"<extra_id_89>",
|
| 93 |
+
"<extra_id_90>",
|
| 94 |
+
"<extra_id_91>",
|
| 95 |
+
"<extra_id_92>",
|
| 96 |
+
"<extra_id_93>",
|
| 97 |
+
"<extra_id_94>",
|
| 98 |
+
"<extra_id_95>",
|
| 99 |
+
"<extra_id_96>",
|
| 100 |
+
"<extra_id_97>",
|
| 101 |
+
"<extra_id_98>",
|
| 102 |
+
"<extra_id_99>"
|
| 103 |
+
],
|
| 104 |
+
"eos_token": "</s>",
|
| 105 |
+
"pad_token": "<pad>",
|
| 106 |
+
"unk_token": "<unk>"
|
| 107 |
+
}
|
spiece.model
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:d60acb128cf7b7f2536e8f38a5b18a05535c9e14c7a355904270e15b0945ea86
|
| 3 |
+
size 791656
|
tokenizer.json
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
tokenizer_config.json
ADDED
|
@@ -0,0 +1,112 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"additional_special_tokens": [
|
| 3 |
+
"<extra_id_0>",
|
| 4 |
+
"<extra_id_1>",
|
| 5 |
+
"<extra_id_2>",
|
| 6 |
+
"<extra_id_3>",
|
| 7 |
+
"<extra_id_4>",
|
| 8 |
+
"<extra_id_5>",
|
| 9 |
+
"<extra_id_6>",
|
| 10 |
+
"<extra_id_7>",
|
| 11 |
+
"<extra_id_8>",
|
| 12 |
+
"<extra_id_9>",
|
| 13 |
+
"<extra_id_10>",
|
| 14 |
+
"<extra_id_11>",
|
| 15 |
+
"<extra_id_12>",
|
| 16 |
+
"<extra_id_13>",
|
| 17 |
+
"<extra_id_14>",
|
| 18 |
+
"<extra_id_15>",
|
| 19 |
+
"<extra_id_16>",
|
| 20 |
+
"<extra_id_17>",
|
| 21 |
+
"<extra_id_18>",
|
| 22 |
+
"<extra_id_19>",
|
| 23 |
+
"<extra_id_20>",
|
| 24 |
+
"<extra_id_21>",
|
| 25 |
+
"<extra_id_22>",
|
| 26 |
+
"<extra_id_23>",
|
| 27 |
+
"<extra_id_24>",
|
| 28 |
+
"<extra_id_25>",
|
| 29 |
+
"<extra_id_26>",
|
| 30 |
+
"<extra_id_27>",
|
| 31 |
+
"<extra_id_28>",
|
| 32 |
+
"<extra_id_29>",
|
| 33 |
+
"<extra_id_30>",
|
| 34 |
+
"<extra_id_31>",
|
| 35 |
+
"<extra_id_32>",
|
| 36 |
+
"<extra_id_33>",
|
| 37 |
+
"<extra_id_34>",
|
| 38 |
+
"<extra_id_35>",
|
| 39 |
+
"<extra_id_36>",
|
| 40 |
+
"<extra_id_37>",
|
| 41 |
+
"<extra_id_38>",
|
| 42 |
+
"<extra_id_39>",
|
| 43 |
+
"<extra_id_40>",
|
| 44 |
+
"<extra_id_41>",
|
| 45 |
+
"<extra_id_42>",
|
| 46 |
+
"<extra_id_43>",
|
| 47 |
+
"<extra_id_44>",
|
| 48 |
+
"<extra_id_45>",
|
| 49 |
+
"<extra_id_46>",
|
| 50 |
+
"<extra_id_47>",
|
| 51 |
+
"<extra_id_48>",
|
| 52 |
+
"<extra_id_49>",
|
| 53 |
+
"<extra_id_50>",
|
| 54 |
+
"<extra_id_51>",
|
| 55 |
+
"<extra_id_52>",
|
| 56 |
+
"<extra_id_53>",
|
| 57 |
+
"<extra_id_54>",
|
| 58 |
+
"<extra_id_55>",
|
| 59 |
+
"<extra_id_56>",
|
| 60 |
+
"<extra_id_57>",
|
| 61 |
+
"<extra_id_58>",
|
| 62 |
+
"<extra_id_59>",
|
| 63 |
+
"<extra_id_60>",
|
| 64 |
+
"<extra_id_61>",
|
| 65 |
+
"<extra_id_62>",
|
| 66 |
+
"<extra_id_63>",
|
| 67 |
+
"<extra_id_64>",
|
| 68 |
+
"<extra_id_65>",
|
| 69 |
+
"<extra_id_66>",
|
| 70 |
+
"<extra_id_67>",
|
| 71 |
+
"<extra_id_68>",
|
| 72 |
+
"<extra_id_69>",
|
| 73 |
+
"<extra_id_70>",
|
| 74 |
+
"<extra_id_71>",
|
| 75 |
+
"<extra_id_72>",
|
| 76 |
+
"<extra_id_73>",
|
| 77 |
+
"<extra_id_74>",
|
| 78 |
+
"<extra_id_75>",
|
| 79 |
+
"<extra_id_76>",
|
| 80 |
+
"<extra_id_77>",
|
| 81 |
+
"<extra_id_78>",
|
| 82 |
+
"<extra_id_79>",
|
| 83 |
+
"<extra_id_80>",
|
| 84 |
+
"<extra_id_81>",
|
| 85 |
+
"<extra_id_82>",
|
| 86 |
+
"<extra_id_83>",
|
| 87 |
+
"<extra_id_84>",
|
| 88 |
+
"<extra_id_85>",
|
| 89 |
+
"<extra_id_86>",
|
| 90 |
+
"<extra_id_87>",
|
| 91 |
+
"<extra_id_88>",
|
| 92 |
+
"<extra_id_89>",
|
| 93 |
+
"<extra_id_90>",
|
| 94 |
+
"<extra_id_91>",
|
| 95 |
+
"<extra_id_92>",
|
| 96 |
+
"<extra_id_93>",
|
| 97 |
+
"<extra_id_94>",
|
| 98 |
+
"<extra_id_95>",
|
| 99 |
+
"<extra_id_96>",
|
| 100 |
+
"<extra_id_97>",
|
| 101 |
+
"<extra_id_98>",
|
| 102 |
+
"<extra_id_99>"
|
| 103 |
+
],
|
| 104 |
+
"eos_token": "</s>",
|
| 105 |
+
"extra_ids": 100,
|
| 106 |
+
"model_max_length": 2048,
|
| 107 |
+
"name_or_path": "google/ul2",
|
| 108 |
+
"pad_token": "<pad>",
|
| 109 |
+
"special_tokens_map_file": null,
|
| 110 |
+
"tokenizer_class": "T5Tokenizer",
|
| 111 |
+
"unk_token": "<unk>"
|
| 112 |
+
}
|