


Add UniTranslator model card
Browse files
README.md
ADDED
|
@@ -0,0 +1,273 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: other
|
| 3 |
+
license_name: flux-1-dev-non-commercial-license
|
| 4 |
+
license_link: https://huggingface.co/black-forest-labs/FLUX.1-Kontext-dev/blob/main/LICENSE.md
|
| 5 |
+
library_name: transformers
|
| 6 |
+
pipeline_tag: image-to-image
|
| 7 |
+
inference: false
|
| 8 |
+
base_model:
|
| 9 |
+
- Qwen/Qwen2.5-VL-3B-Instruct
|
| 10 |
+
- black-forest-labs/FLUX.1-Kontext-dev
|
| 11 |
+
datasets:
|
| 12 |
+
- yztian/IIMT30k
|
| 13 |
+
- yztian/MTedIIMT
|
| 14 |
+
- yztian/PRIM
|
| 15 |
+
language:
|
| 16 |
+
- de
|
| 17 |
+
- en
|
| 18 |
+
- fr
|
| 19 |
+
- ro
|
| 20 |
+
- cs
|
| 21 |
+
- ru
|
| 22 |
+
tags:
|
| 23 |
+
- in-image-machine-translation
|
| 24 |
+
- image-translation
|
| 25 |
+
- image-editing
|
| 26 |
+
- multimodal
|
| 27 |
+
- qwen2.5-vl
|
| 28 |
+
- flux
|
| 29 |
+
- arxiv:2606.24333
|
| 30 |
+
---
|
| 31 |
+
|
| 32 |
+
# UniTranslator
|
| 33 |
+
|
| 34 |
+
## A Unified Multimodal Framework for End-to-End In-Image Machine Translation
|
| 35 |
+
|
| 36 |
+
<p align="center">
|
| 37 |
+
📄 <a href="https://arxiv.org/abs/2606.24333">Paper</a> ·
|
| 38 |
+
💻 <a href="https://github.com/SeerRay-Lab/Unitranslator">Code</a> ·
|
| 39 |
+
🤗 <a href="https://huggingface.co/SeerRay-Lab/Unitranslator">Model</a>
|
| 40 |
+
</p>
|
| 41 |
+
|
| 42 |
+
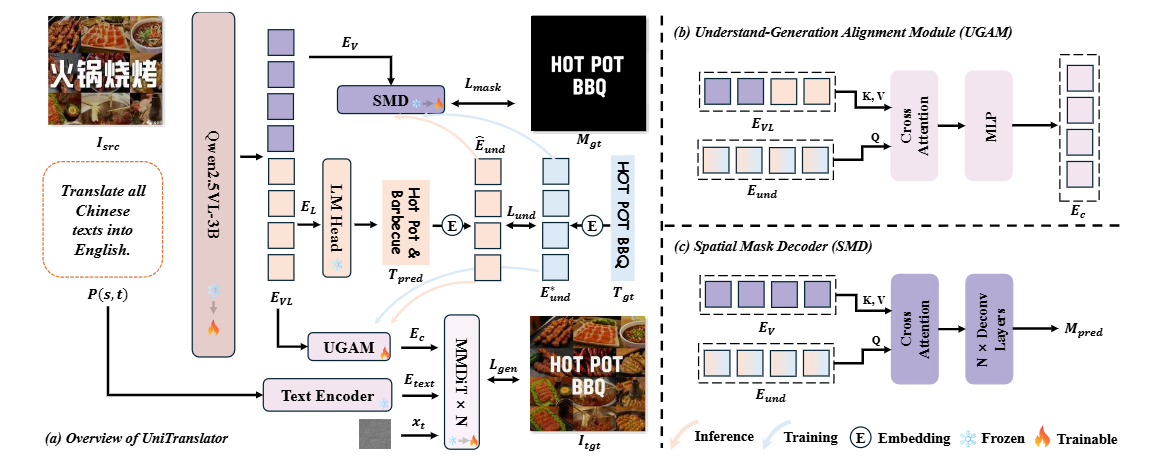
**UniTranslator**, accepted at **ECCV 2026**, is an end-to-end framework for **in-image machine translation (IIMT)**. Given an image and a translation instruction, it predicts the translated text and renders that translation back into the source text regions while preserving the surrounding scene, layout, and typography as closely as possible.
|
| 43 |
+
|
| 44 |
+
|
| 45 |
+
|
| 46 |
+
UniTranslator introduces two components:
|
| 47 |
+
|
| 48 |
+
- **Understand-Generation Alignment Module (UGAM):** aligns translation-understanding representations with the image-generation condition, reducing semantic inconsistency between predicted and rendered text.
|
| 49 |
+
- **Spatial Mask Decoder (SMD):** adds pixel-level supervision over text regions to improve localization, geometric alignment, and layout-preserving text replacement.
|
| 50 |
+
|
| 51 |
+
> This repository contains a research checkpoint that uses custom model classes from the GitHub repository. It is not directly compatible with `AutoPipeline.from_pretrained("SeerRay-Lab/Unitranslator")` or the hosted Hugging Face Inference API.
|
| 52 |
+
|
| 53 |
+
## Model details
|
| 54 |
+
|
| 55 |
+
| Property | Description |
|
| 56 |
+
|---|---|
|
| 57 |
+
| Task | End-to-end in-image machine translation |
|
| 58 |
+
| Input | Source image, source language, and target language |
|
| 59 |
+
| Output | Predicted translation text and an edited image containing the translated text |
|
| 60 |
+
| Multimodal backbone | Qwen2.5-VL-3B-based checkpoint |
|
| 61 |
+
| Image generator | FLUX.1-Kontext-dev-based denoiser |
|
| 62 |
+
| Main components | UGAM and SMD |
|
| 63 |
+
| Training | Two-stage warm-up and joint fine-tuning |
|
| 64 |
+
| Recommended precision | BF16 |
|
| 65 |
+
|
| 66 |
+
The released checkpoint combines a multimodal understanding branch, a FLUX-based generation branch, and task-specific alignment and spatial-supervision modules. Inference first autoregressively predicts the translation and then uses the resulting representation to condition image generation.
|
| 67 |
+
|
| 68 |
+
## Supported and evaluated translation directions
|
| 69 |
+
|
| 70 |
+
The paper evaluates the following directions:
|
| 71 |
+
|
| 72 |
+
- German → English (`De → En`)
|
| 73 |
+
- English → German (`En → De`)
|
| 74 |
+
- French → English (`Fr → En`)
|
| 75 |
+
- Romanian → English (`Ro → En`)
|
| 76 |
+
- English → French (`En → Fr`)
|
| 77 |
+
- English → Czech (`En → Cs`)
|
| 78 |
+
- English → Russian (`En → Ru`)
|
| 79 |
+
- English → Romanian (`En → Ro`)
|
| 80 |
+
|
| 81 |
+
Other language directions are not guaranteed to provide comparable quality.
|
| 82 |
+
|
| 83 |
+
## Checkpoint contents
|
| 84 |
+
|
| 85 |
+
| Path | Purpose |
|
| 86 |
+
|---|---|
|
| 87 |
+
| `univa/` | Final combined UniTranslator task checkpoint, including the multimodal model, denoiser, UGAM, and SMD weights |
|
| 88 |
+
| `lora/` | Rank-64 LoRA adapter used in stage-two Qwen2.5-VL fine-tuning |
|
| 89 |
+
| `denoise_projector.bin` | Standalone denoise-projector/UGAM checkpoint artifact |
|
| 90 |
+
| `pytorch_model/` | DeepSpeed training state for resuming training |
|
| 91 |
+
| `random_states_*.pkl`, `scheduler.bin`, `latest` | Training-resume metadata |
|
| 92 |
+
|
| 93 |
+
For inference, download `univa/` and `lora/`. The large DeepSpeed optimizer and random-state files are not required.
|
| 94 |
+
|
| 95 |
+
## Installation
|
| 96 |
+
|
| 97 |
+
```bash
|
| 98 |
+
git clone https://github.com/SeerRay-Lab/Unitranslator.git
|
| 99 |
+
cd Unitranslator
|
| 100 |
+
|
| 101 |
+
conda create -n univa python=3.10 -y
|
| 102 |
+
conda activate univa
|
| 103 |
+
pip install -r requirements.txt
|
| 104 |
+
pip install flash_attn --no-build-isolation
|
| 105 |
+
```
|
| 106 |
+
|
| 107 |
+
The reference environment uses PyTorch 2.7.1, Transformers 4.57.0, Diffusers 0.32.2, Accelerate 1.5.2, and PEFT 0.10.0.
|
| 108 |
+
|
| 109 |
+
## Download
|
| 110 |
+
|
| 111 |
+
Download only the files needed for inference:
|
| 112 |
+
|
| 113 |
+
```bash
|
| 114 |
+
hf download SeerRay-Lab/Unitranslator \
|
| 115 |
+
--include "univa/*" \
|
| 116 |
+
--include "lora/*" \
|
| 117 |
+
--local-dir checkpoints/Unitranslator
|
| 118 |
+
```
|
| 119 |
+
|
| 120 |
+
UniTranslator also depends on Qwen2.5-VL-3B-Instruct and FLUX.1-Kontext-dev:
|
| 121 |
+
|
| 122 |
+
```bash
|
| 123 |
+
hf download Qwen/Qwen2.5-VL-3B-Instruct \
|
| 124 |
+
--local-dir checkpoints/Qwen2.5-VL-3B-Instruct
|
| 125 |
+
|
| 126 |
+
hf download black-forest-labs/FLUX.1-Kontext-dev \
|
| 127 |
+
--local-dir checkpoints/FLUX.1-Kontext-dev
|
| 128 |
+
```
|
| 129 |
+
|
| 130 |
+
FLUX.1-Kontext-dev is gated. You must first accept its license on the [model page](https://huggingface.co/black-forest-labs/FLUX.1-Kontext-dev) and authenticate with Hugging Face.
|
| 131 |
+
|
| 132 |
+
## Inference
|
| 133 |
+
|
| 134 |
+
### 1. Construct the base hybrid checkpoint
|
| 135 |
+
|
| 136 |
+
The released inference code reconstructs the base Qwen2.5-VL + FLUX hybrid model before loading the UniTranslator task weights and LoRA adapter:
|
| 137 |
+
|
| 138 |
+
```bash
|
| 139 |
+
python scripts/make_univa_qwen2p5vl_tf.py \
|
| 140 |
+
--origin_qwenvl_ckpt_path checkpoints/Qwen2.5-VL-3B-Instruct \
|
| 141 |
+
--origin_flux_ckpt_path checkpoints/FLUX.1-Kontext-dev \
|
| 142 |
+
--save_path checkpoints/UniWorld_Kontext_3b_TF
|
| 143 |
+
```
|
| 144 |
+
|
| 145 |
+
### 2. Translate a directory of images
|
| 146 |
+
|
| 147 |
+
```bash
|
| 148 |
+
python infer_dir_tf.py \
|
| 149 |
+
--base_model_path checkpoints/UniWorld_Kontext_3b_TF \
|
| 150 |
+
--lora_adapter_path checkpoints/Unitranslator/lora \
|
| 151 |
+
--flux_finetune_path checkpoints/Unitranslator/univa \
|
| 152 |
+
--flux_base_path checkpoints/FLUX.1-Kontext-dev \
|
| 153 |
+
--input_dir path/to/input_images \
|
| 154 |
+
--output_dir results/de_to_en \
|
| 155 |
+
--gpu_id 0 \
|
| 156 |
+
--total_gpus 1 \
|
| 157 |
+
--source_language German \
|
| 158 |
+
--target_language English \
|
| 159 |
+
--dtype bf16 \
|
| 160 |
+
--height 1024 \
|
| 161 |
+
--width 1024 \
|
| 162 |
+
--num_inference_steps 50 \
|
| 163 |
+
--guidance_scale 5.0
|
| 164 |
+
```
|
| 165 |
+
|
| 166 |
+
The generated images and a JSONL file containing the predicted translations are written to `--output_dir`.
|
| 167 |
+
|
| 168 |
+
For multi-GPU directory inference, launch one process per GPU with different `--gpu_id` values and the same `--total_gpus`. Input images are assigned to processes by round-robin sharding.
|
| 169 |
+
|
| 170 |
+
The prompt format used by the inference script is:
|
| 171 |
+
|
| 172 |
+
```text
|
| 173 |
+
Translate all {source_language} texts into {target_language}.
|
| 174 |
+
```
|
| 175 |
+
|
| 176 |
+
### Hardware note
|
| 177 |
+
|
| 178 |
+
The paper reports approximately **50 GB peak GPU memory** and **9.51 seconds per image** under its evaluation setting. Actual memory use and latency depend on resolution, precision, hardware, and inference steps. A high-memory CUDA GPU is recommended.
|
| 179 |
+
|
| 180 |
+
## Training
|
| 181 |
+
|
| 182 |
+
UniTranslator uses a two-stage training strategy:
|
| 183 |
+
|
| 184 |
+
1. **Module warm-up:** freeze the pretrained Qwen2.5-VL and diffusion backbones and optimize the task-specific alignment and spatial modules.
|
| 185 |
+
2. **Joint fine-tuning:** jointly train the understanding and generation paths, including rank-64 Qwen2.5-VL LoRA adapters, UGAM, SMD, and MMDiT attention projections.
|
| 186 |
+
|
| 187 |
+
The paper reports BF16 mixed precision, AdamW, gradient checkpointing, gradient accumulation of 8, and NVIDIA H800 GPUs. See the configuration files under [`scripts/denoiser/`](https://github.com/SeerRay-Lab/Unitranslator/tree/main/scripts/denoiser) for the released training setup.
|
| 188 |
+
|
| 189 |
+
The repository provides `train_stage1.sh` and `train_stage2.sh` as reference launchers. Update their configuration paths for your environment before running them; the checked-in scripts and YAML files contain project-local paths and may require adaptation.
|
| 190 |
+
|
| 191 |
+
### Data preparation
|
| 192 |
+
|
| 193 |
+
```bash
|
| 194 |
+
# Stage-one supervision
|
| 195 |
+
python convert_en_de.py
|
| 196 |
+
|
| 197 |
+
# Stage-two mask supervision
|
| 198 |
+
python convert_transv_mask.py
|
| 199 |
+
```
|
| 200 |
+
|
| 201 |
+
Datasets used by the project include:
|
| 202 |
+
|
| 203 |
+
- [Translatotron-V](https://drive.google.com/drive/folders/12r54tAQ98Oxtp6Eb3dvaoiOKzu4lD_7h?usp=sharing)
|
| 204 |
+
- [IIMT30k](https://huggingface.co/datasets/yztian/IIMT30k)
|
| 205 |
+
- [MTedIIMT](https://huggingface.co/datasets/yztian/MTedIIMT)
|
| 206 |
+
- [PRIM](https://huggingface.co/datasets/yztian/PRIM)
|
| 207 |
+
|
| 208 |
+
Users are responsible for complying with the licenses and terms of each dataset.
|
| 209 |
+
|
| 210 |
+
## Evaluation results
|
| 211 |
+
|
| 212 |
+
All numbers below are reported in the UniTranslator paper.
|
| 213 |
+
|
| 214 |
+
### Translatotron-V
|
| 215 |
+
|
| 216 |
+
| Direction | BLEU ↑ | Structure-BLEU ↑ | SSIM ↑ |
|
| 217 |
+
|---|---:|---:|---:|
|
| 218 |
+
| De → En | **25.03** | **24.86** | **0.8184** |
|
| 219 |
+
| En → De | **13.41** | **13.36** | **0.7887** |
|
| 220 |
+
| Fr → En | **27.77** | **27.14** | **0.8060** |
|
| 221 |
+
| Ro → En | **18.45** | **18.29** | **0.8045** |
|
| 222 |
+
|
| 223 |
+
### IIMT30k test set
|
| 224 |
+
|
| 225 |
+
| Direction | BLEU ↑ | COMET ↑ | FID ↓ |
|
| 226 |
+
|---|---:|---:|---:|
|
| 227 |
+
| De → En | **14.7** | **59.8** | **8.9** |
|
| 228 |
+
| En → De | **13.0** | **45.5** | 12.5 |
|
| 229 |
+
|
| 230 |
+
### PRIM
|
| 231 |
+
|
| 232 |
+
| System | Average BLEU ↑ | Average COMET ↑ | Average FID ↓ |
|
| 233 |
+
|---|---:|---:|---:|
|
| 234 |
+
| Translatotron-V | 1.4 | 32.2 | 69.1 |
|
| 235 |
+
| VisTrans | 11.3 | 47.0 | 28.8 |
|
| 236 |
+
| **UniTranslator** | **12.8** | **50.7** | **22.9** |
|
| 237 |
+
|
| 238 |
+
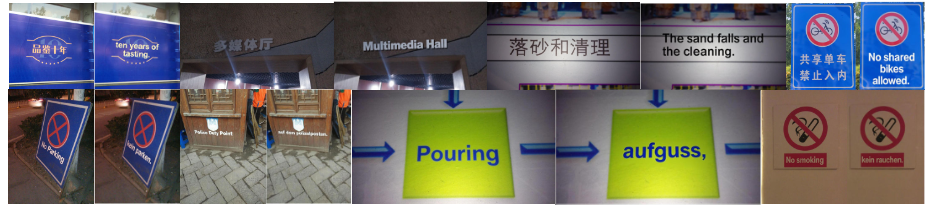
BLEU and COMET evaluate translation quality, Structure-BLEU additionally considers text-region alignment, SSIM measures source/target structural similarity, and FID evaluates generated-image distribution quality.
|
| 239 |
+
|
| 240 |
+
|
| 241 |
+
|
| 242 |
+
## Limitations and risks
|
| 243 |
+
|
| 244 |
+
- Low-resource language settings may produce missing words or incorrect character rendering.
|
| 245 |
+
- Highly stylized typography can lead to imperfect preservation of strokes, glow, erosion, or cursive deformation.
|
| 246 |
+
- Complex backgrounds may be altered outside the intended text region, including texture, color, or local appearance changes.
|
| 247 |
+
- Small, dense, curved, occluded, or low-resolution text remains challenging.
|
| 248 |
+
- Results may vary for language directions and domains not represented in the evaluated datasets.
|
| 249 |
+
- Generated translations and images should be verified before use in safety-critical, legal, medical, financial, or public-facing contexts.
|
| 250 |
+
- Input images may contain personal or copyrighted material; users are responsible for lawful processing and distribution.
|
| 251 |
+
|
| 252 |
+
## License
|
| 253 |
+
|
| 254 |
+
The source code repository is released under the [Apache 2.0 License](https://github.com/SeerRay-Lab/Unitranslator/blob/main/LICENSE).
|
| 255 |
+
|
| 256 |
+
The released model is based in part on [FLUX.1-Kontext-dev](https://huggingface.co/black-forest-labs/FLUX.1-Kontext-dev). Use of the model weights is therefore also subject to the [FLUX.1 Dev Non-Commercial License](https://huggingface.co/black-forest-labs/FLUX.1-Kontext-dev/blob/main/LICENSE.md) and its Acceptable Use Policy. Users must comply with all applicable upstream model and dataset licenses; the more restrictive terms apply where relevant.
|
| 257 |
+
|
| 258 |
+
## Citation
|
| 259 |
+
|
| 260 |
+
If you find this work useful, please cite:
|
| 261 |
+
|
| 262 |
+
```bibtex
|
| 263 |
+
@article{lyu2026unitranslator,
|
| 264 |
+
title={UniTranslator: A Unified Multi-modal Framework for End-to-end In-Image Machine Translation},
|
| 265 |
+
author={Lyu, Jiahao and Fu, Pei and Li, Zhenhang and Zhang, Shaojie and Yang, Jiahui and Ma, Can and Zhou, Yu and Luo, Zhenbo and Luan, Jian},
|
| 266 |
+
journal={arXiv preprint arXiv:2606.24333},
|
| 267 |
+
year={2026}
|
| 268 |
+
}
|
| 269 |
+
```
|
| 270 |
+
|
| 271 |
+
## Acknowledgements
|
| 272 |
+
|
| 273 |
+
This project builds on [UniWorld](https://github.com/PKU-YuanGroup/UniWorld-V1), [Qwen2.5-VL](https://huggingface.co/Qwen/Qwen2.5-VL-3B-Instruct), and [FLUX.1-Kontext-dev](https://huggingface.co/black-forest-labs/FLUX.1-Kontext-dev). See the paper and GitHub repository for the complete acknowledgements.
|