 +
+
+
+  + |
+
+  + |
+
+
+
+  +
+
+
+
+
+
+
+
+
+
+
| + Pipeline + | ++ Supported tasks + | ++ 🤗 Space + | +
|---|---|---|
| + StableDiffusion + | +text-to-image | + + |
+
| + StableDiffusionImg2Img + | +image-to-image | +
+ |
+
| + StableDiffusionInpaint + | +inpainting | +
+ |
+
| + StableDiffusionDepth2Img + | +depth-to-image | +
+ |
+
| + StableDiffusionImageVariation + | +image variation | +
+ |
+
| + StableDiffusionPipelineSafe + | +filtered text-to-image | +
+ |
+
| + StableDiffusion2 + | +text-to-image, inpainting, depth-to-image, super-resolution | +
+ |
+
| + StableDiffusionXL + | +text-to-image, image-to-image | +
+ |
+
| + StableDiffusionLatentUpscale + | +super-resolution | +
+ |
+
| + StableDiffusionUpscale + | +super-resolution | +|
| + StableDiffusionLDM3D + | +text-to-rgb, text-to-depth, text-to-pano | +
+ |
+
| + StableDiffusionUpscaleLDM3D + | +ldm3d super-resolution | +
+
+ +
+
+
+
+
+
+
+  + |
+ +  + |
+
+  + |
+
+
+
+
+
+| Project Name | +Description | +
|---|---|
| dream-textures | +Stable Diffusion built-in to Blender | +
| HiDiffusion | +Increases the resolution and speed of your diffusion model by only adding a single line of code | +
| IC-Light | +IC-Light is a project to manipulate the illumination of images | +
| InstantID | +InstantID : Zero-shot Identity-Preserving Generation in Seconds | +
| IOPaint | +Image inpainting tool powered by SOTA AI Model. Remove any unwanted object, defect, people from your pictures or erase and replace(powered by stable diffusion) any thing on your pictures. | +
| Kohya | +Gradio GUI for Kohya's Stable Diffusion trainers | +
| MagicAnimate | +MagicAnimate: Temporally Consistent Human Image Animation using Diffusion Model | +
| OOTDiffusion | +Outfitting Fusion based Latent Diffusion for Controllable Virtual Try-on | +
| SD.Next | +SD.Next: Advanced Implementation of Stable Diffusion and other Diffusion-based generative image models | +
| stable-dreamfusion | +Text-to-3D & Image-to-3D & Mesh Exportation with NeRF + Diffusion | +
| StoryDiffusion | +StoryDiffusion can create a magic story by generating consistent images and videos. | +
| StreamDiffusion | +A Pipeline-Level Solution for Real-Time Interactive Generation | +
| Stable Diffusion Server | +A server configured for Inpainting/Generation/img2img with one stable diffusion model | +
| Model Search | +Search models on Civitai and Hugging Face | +
| Skrample | +Fully modular scheduler functions with 1st class diffusers integration. | +
 +
+Whichever way you choose to contribute, we strive to be part of an open, welcoming, and kind community. Please, read our [code of conduct](https://github.com/huggingface/diffusers/blob/main/CODE_OF_CONDUCT.md) and be mindful to respect it during your interactions. We also recommend you become familiar with the [ethical guidelines](https://huggingface.co/docs/diffusers/conceptual/ethical_guidelines) that guide our project and ask you to adhere to the same principles of transparency and responsibility.
+
+We enormously value feedback from the community, so please do not be afraid to speak up if you believe you have valuable feedback that can help improve the library - every message, comment, issue, and pull request (PR) is read and considered.
+
+## Overview
+
+You can contribute in many ways ranging from answering questions on issues and discussions to adding new diffusion models to the core library.
+
+In the following, we give an overview of different ways to contribute, ranked by difficulty in ascending order. All of them are valuable to the community.
+
+* 1. Asking and answering questions on [the Diffusers discussion forum](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers) or on [Discord](https://discord.gg/G7tWnz98XR).
+* 2. Opening new issues on [the GitHub Issues tab](https://github.com/huggingface/diffusers/issues/new/choose) or new discussions on [the GitHub Discussions tab](https://github.com/huggingface/diffusers/discussions/new/choose).
+* 3. Answering issues on [the GitHub Issues tab](https://github.com/huggingface/diffusers/issues) or discussions on [the GitHub Discussions tab](https://github.com/huggingface/diffusers/discussions).
+* 4. Fix a simple issue, marked by the "Good first issue" label, see [here](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22good+first+issue%22).
+* 5. Contribute to the [documentation](https://github.com/huggingface/diffusers/tree/main/docs/source).
+* 6. Contribute a [Community Pipeline](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3Acommunity-examples).
+* 7. Contribute to the [examples](https://github.com/huggingface/diffusers/tree/main/examples).
+* 8. Fix a more difficult issue, marked by the "Good second issue" label, see [here](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22Good+second+issue%22).
+* 9. Add a new pipeline, model, or scheduler, see ["New Pipeline/Model"](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+pipeline%2Fmodel%22) and ["New scheduler"](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+scheduler%22) issues. For this contribution, please have a look at [Design Philosophy](https://github.com/huggingface/diffusers/blob/main/PHILOSOPHY.md).
+
+As said before, **all contributions are valuable to the community**.
+In the following, we will explain each contribution a bit more in detail.
+
+For all contributions 4 - 9, you will need to open a PR. It is explained in detail how to do so in [Opening a pull request](#how-to-open-a-pr).
+
+### 1. Asking and answering questions on the Diffusers discussion forum or on the Diffusers Discord
+
+Any question or comment related to the Diffusers library can be asked on the [discussion forum](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/) or on [Discord](https://discord.gg/G7tWnz98XR). Such questions and comments include (but are not limited to):
+- Reports of training or inference experiments in an attempt to share knowledge
+- Presentation of personal projects
+- Questions to non-official training examples
+- Project proposals
+- General feedback
+- Paper summaries
+- Asking for help on personal projects that build on top of the Diffusers library
+- General questions
+- Ethical questions regarding diffusion models
+- ...
+
+Every question that is asked on the forum or on Discord actively encourages the community to publicly
+share knowledge and might very well help a beginner in the future who has the same question you're
+having. Please do pose any questions you might have.
+In the same spirit, you are of immense help to the community by answering such questions because this way you are publicly documenting knowledge for everybody to learn from.
+
+**Please** keep in mind that the more effort you put into asking or answering a question, the higher
+the quality of the publicly documented knowledge. In the same way, well-posed and well-answered questions create a high-quality knowledge database accessible to everybody, while badly posed questions or answers reduce the overall quality of the public knowledge database.
+In short, a high quality question or answer is *precise*, *concise*, *relevant*, *easy-to-understand*, *accessible*, and *well-formatted/well-posed*. For more information, please have a look through the [How to write a good issue](#how-to-write-a-good-issue) section.
+
+**NOTE about channels**:
+[*The forum*](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63) is much better indexed by search engines, such as Google. Posts are ranked by popularity rather than chronologically. Hence, it's easier to look up questions and answers that we posted some time ago.
+In addition, questions and answers posted in the forum can easily be linked to.
+In contrast, *Discord* has a chat-like format that invites fast back-and-forth communication.
+While it will most likely take less time for you to get an answer to your question on Discord, your
+question won't be visible anymore over time. Also, it's much harder to find information that was posted a while back on Discord. We therefore strongly recommend using the forum for high-quality questions and answers in an attempt to create long-lasting knowledge for the community. If discussions on Discord lead to very interesting answers and conclusions, we recommend posting the results on the forum to make the information more available for future readers.
+
+### 2. Opening new issues on the GitHub issues tab
+
+The 🧨 Diffusers library is robust and reliable thanks to the users who notify us of
+the problems they encounter. So thank you for reporting an issue.
+
+Remember, GitHub issues are reserved for technical questions directly related to the Diffusers library, bug reports, feature requests, or feedback on the library design.
+
+In a nutshell, this means that everything that is **not** related to the **code of the Diffusers library** (including the documentation) should **not** be asked on GitHub, but rather on either the [forum](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63) or [Discord](https://discord.gg/G7tWnz98XR).
+
+**Please consider the following guidelines when opening a new issue**:
+- Make sure you have searched whether your issue has already been asked before (use the search bar on GitHub under Issues).
+- Please never report a new issue on another (related) issue. If another issue is highly related, please
+open a new issue nevertheless and link to the related issue.
+- Make sure your issue is written in English. Please use one of the great, free online translation services, such as [DeepL](https://www.deepl.com/translator) to translate from your native language to English if you are not comfortable in English.
+- Check whether your issue might be solved by updating to the newest Diffusers version. Before posting your issue, please make sure that `python -c "import diffusers; print(diffusers.__version__)"` is higher or matches the latest Diffusers version.
+- Remember that the more effort you put into opening a new issue, the higher the quality of your answer will be and the better the overall quality of the Diffusers issues.
+
+New issues usually include the following.
+
+#### 2.1. Reproducible, minimal bug reports
+
+A bug report should always have a reproducible code snippet and be as minimal and concise as possible.
+This means in more detail:
+- Narrow the bug down as much as you can, **do not just dump your whole code file**.
+- Format your code.
+- Do not include any external libraries except for Diffusers depending on them.
+- **Always** provide all necessary information about your environment; for this, you can run: `diffusers-cli env` in your shell and copy-paste the displayed information to the issue.
+- Explain the issue. If the reader doesn't know what the issue is and why it is an issue, (s)he cannot solve it.
+- **Always** make sure the reader can reproduce your issue with as little effort as possible. If your code snippet cannot be run because of missing libraries or undefined variables, the reader cannot help you. Make sure your reproducible code snippet is as minimal as possible and can be copy-pasted into a simple Python shell.
+- If in order to reproduce your issue a model and/or dataset is required, make sure the reader has access to that model or dataset. You can always upload your model or dataset to the [Hub](https://huggingface.co) to make it easily downloadable. Try to keep your model and dataset as small as possible, to make the reproduction of your issue as effortless as possible.
+
+For more information, please have a look through the [How to write a good issue](#how-to-write-a-good-issue) section.
+
+You can open a bug report [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=bug&projects=&template=bug-report.yml).
+
+#### 2.2. Feature requests
+
+A world-class feature request addresses the following points:
+
+1. Motivation first:
+* Is it related to a problem/frustration with the library? If so, please explain
+why. Providing a code snippet that demonstrates the problem is best.
+* Is it related to something you would need for a project? We'd love to hear
+about it!
+* Is it something you worked on and think could benefit the community?
+Awesome! Tell us what problem it solved for you.
+2. Write a *full paragraph* describing the feature;
+3. Provide a **code snippet** that demonstrates its future use;
+4. In case this is related to a paper, please attach a link;
+5. Attach any additional information (drawings, screenshots, etc.) you think may help.
+
+You can open a feature request [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feature_request.md&title=).
+
+#### 2.3 Feedback
+
+Feedback about the library design and why it is good or not good helps the core maintainers immensely to build a user-friendly library. To understand the philosophy behind the current design philosophy, please have a look [here](https://huggingface.co/docs/diffusers/conceptual/philosophy). If you feel like a certain design choice does not fit with the current design philosophy, please explain why and how it should be changed. If a certain design choice follows the design philosophy too much, hence restricting use cases, explain why and how it should be changed.
+If a certain design choice is very useful for you, please also leave a note as this is great feedback for future design decisions.
+
+You can open an issue about feedback [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feedback.md&title=).
+
+#### 2.4 Technical questions
+
+Technical questions are mainly about why certain code of the library was written in a certain way, or what a certain part of the code does. Please make sure to link to the code in question and please provide details on
+why this part of the code is difficult to understand.
+
+You can open an issue about a technical question [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=bug&template=bug-report.yml).
+
+#### 2.5 Proposal to add a new model, scheduler, or pipeline
+
+If the diffusion model community released a new model, pipeline, or scheduler that you would like to see in the Diffusers library, please provide the following information:
+
+* Short description of the diffusion pipeline, model, or scheduler and link to the paper or public release.
+* Link to any of its open-source implementation(s).
+* Link to the model weights if they are available.
+
+If you are willing to contribute to the model yourself, let us know so we can best guide you. Also, don't forget
+to tag the original author of the component (model, scheduler, pipeline, etc.) by GitHub handle if you can find it.
+
+You can open a request for a model/pipeline/scheduler [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=New+model%2Fpipeline%2Fscheduler&template=new-model-addition.yml).
+
+### 3. Answering issues on the GitHub issues tab
+
+Answering issues on GitHub might require some technical knowledge of Diffusers, but we encourage everybody to give it a try even if you are not 100% certain that your answer is correct.
+Some tips to give a high-quality answer to an issue:
+- Be as concise and minimal as possible.
+- Stay on topic. An answer to the issue should concern the issue and only the issue.
+- Provide links to code, papers, or other sources that prove or encourage your point.
+- Answer in code. If a simple code snippet is the answer to the issue or shows how the issue can be solved, please provide a fully reproducible code snippet.
+
+Also, many issues tend to be simply off-topic, duplicates of other issues, or irrelevant. It is of great
+help to the maintainers if you can answer such issues, encouraging the author of the issue to be
+more precise, provide the link to a duplicated issue or redirect them to [the forum](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63) or [Discord](https://discord.gg/G7tWnz98XR).
+
+If you have verified that the issued bug report is correct and requires a correction in the source code,
+please have a look at the next sections.
+
+For all of the following contributions, you will need to open a PR. It is explained in detail how to do so in the [Opening a pull request](#how-to-open-a-pr) section.
+
+### 4. Fixing a "Good first issue"
+
+*Good first issues* are marked by the [Good first issue](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22good+first+issue%22) label. Usually, the issue already
+explains how a potential solution should look so that it is easier to fix.
+If the issue hasn't been closed and you would like to try to fix this issue, you can just leave a message "I would like to try this issue.". There are usually three scenarios:
+- a.) The issue description already proposes a fix. In this case and if the solution makes sense to you, you can open a PR or draft PR to fix it.
+- b.) The issue description does not propose a fix. In this case, you can ask what a proposed fix could look like and someone from the Diffusers team should answer shortly. If you have a good idea of how to fix it, feel free to directly open a PR.
+- c.) There is already an open PR to fix the issue, but the issue hasn't been closed yet. If the PR has gone stale, you can simply open a new PR and link to the stale PR. PRs often go stale if the original contributor who wanted to fix the issue suddenly cannot find the time anymore to proceed. This often happens in open-source and is very normal. In this case, the community will be very happy if you give it a new try and leverage the knowledge of the existing PR. If there is already a PR and it is active, you can help the author by giving suggestions, reviewing the PR or even asking whether you can contribute to the PR.
+
+
+### 5. Contribute to the documentation
+
+A good library **always** has good documentation! The official documentation is often one of the first points of contact for new users of the library, and therefore contributing to the documentation is a **highly
+valuable contribution**.
+
+Contributing to the library can have many forms:
+
+- Correcting spelling or grammatical errors.
+- Correct incorrect formatting of the docstring. If you see that the official documentation is weirdly displayed or a link is broken, we would be very happy if you take some time to correct it.
+- Correct the shape or dimensions of a docstring input or output tensor.
+- Clarify documentation that is hard to understand or incorrect.
+- Update outdated code examples.
+- Translating the documentation to another language.
+
+Anything displayed on [the official Diffusers doc page](https://huggingface.co/docs/diffusers/index) is part of the official documentation and can be corrected, adjusted in the respective [documentation source](https://github.com/huggingface/diffusers/tree/main/docs/source).
+
+Please have a look at [this page](https://github.com/huggingface/diffusers/tree/main/docs) on how to verify changes made to the documentation locally.
+
+### 6. Contribute a community pipeline
+
+> [!TIP]
+> Read the [Community pipelines](../using-diffusers/custom_pipeline_overview#community-pipelines) guide to learn more about the difference between a GitHub and Hugging Face Hub community pipeline. If you're interested in why we have community pipelines, take a look at GitHub Issue [#841](https://github.com/huggingface/diffusers/issues/841) (basically, we can't maintain all the possible ways diffusion models can be used for inference but we also don't want to prevent the community from building them).
+
+Contributing a community pipeline is a great way to share your creativity and work with the community. It lets you build on top of the [`DiffusionPipeline`] so that anyone can load and use it by setting the `custom_pipeline` parameter. This section will walk you through how to create a simple pipeline where the UNet only does a single forward pass and calls the scheduler once (a "one-step" pipeline).
+
+1. Create a one_step_unet.py file for your community pipeline. This file can contain whatever package you want to use as long as it's installed by the user. Make sure you only have one pipeline class that inherits from [`DiffusionPipeline`] to load model weights and the scheduler configuration from the Hub. Add a UNet and scheduler to the `__init__` function.
+
+ You should also add the `register_modules` function to ensure your pipeline and its components can be saved with [`~DiffusionPipeline.save_pretrained`].
+
+```py
+from diffusers import DiffusionPipeline
+import torch
+
+class UnetSchedulerOneForwardPipeline(DiffusionPipeline):
+ def __init__(self, unet, scheduler):
+ super().__init__()
+
+ self.register_modules(unet=unet, scheduler=scheduler)
+```
+
+1. In the forward pass (which we recommend defining as `__call__`), you can add any feature you'd like. For the "one-step" pipeline, create a random image and call the UNet and scheduler once by setting `timestep=1`.
+
+```py
+ from diffusers import DiffusionPipeline
+ import torch
+
+ class UnetSchedulerOneForwardPipeline(DiffusionPipeline):
+ def __init__(self, unet, scheduler):
+ super().__init__()
+
+ self.register_modules(unet=unet, scheduler=scheduler)
+
+ def __call__(self):
+ image = torch.randn(
+ (1, self.unet.config.in_channels, self.unet.config.sample_size, self.unet.config.sample_size),
+ )
+ timestep = 1
+
+ model_output = self.unet(image, timestep).sample
+ scheduler_output = self.scheduler.step(model_output, timestep, image).prev_sample
+
+ return scheduler_output
+```
+
+Now you can run the pipeline by passing a UNet and scheduler to it or load pretrained weights if the pipeline structure is identical.
+
+```py
+from diffusers import DDPMScheduler, UNet2DModel
+
+scheduler = DDPMScheduler()
+unet = UNet2DModel()
+
+pipeline = UnetSchedulerOneForwardPipeline(unet=unet, scheduler=scheduler)
+output = pipeline()
+# load pretrained weights
+pipeline = UnetSchedulerOneForwardPipeline.from_pretrained("google/ddpm-cifar10-32", use_safetensors=True)
+output = pipeline()
+```
+
+You can either share your pipeline as a GitHub community pipeline or Hub community pipeline.
+
+
 +
+
+> [!TIP]
+> This document has now grown outdated given the emergence of existing evaluation frameworks for diffusion models for image generation. Please check
+> out works like [HEIM](https://crfm.stanford.edu/helm/heim/latest/), [T2I-Compbench](https://huggingface.co/papers/2307.06350),
+> [GenEval](https://huggingface.co/papers/2310.11513).
+
+Evaluation of generative models like [Stable Diffusion](https://huggingface.co/docs/diffusers/stable_diffusion) is subjective in nature. But as practitioners and researchers, we often have to make careful choices amongst many different possibilities. So, when working with different generative models (like GANs, Diffusion, etc.), how do we choose one over the other?
+
+Qualitative evaluation of such models can be error-prone and might incorrectly influence a decision.
+However, quantitative metrics don't necessarily correspond to image quality. So, usually, a combination
+of both qualitative and quantitative evaluations provides a stronger signal when choosing one model
+over the other.
+
+In this document, we provide a non-exhaustive overview of qualitative and quantitative methods to evaluate Diffusion models. For quantitative methods, we specifically focus on how to implement them alongside `diffusers`.
+
+The methods shown in this document can also be used to evaluate different [noise schedulers](https://huggingface.co/docs/diffusers/main/en/api/schedulers/overview) keeping the underlying generation model fixed.
+
+## Scenarios
+
+We cover Diffusion models with the following pipelines:
+
+- Text-guided image generation (such as the [`StableDiffusionPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/stable_diffusion/text2img)).
+- Text-guided image generation, additionally conditioned on an input image (such as the [`StableDiffusionImg2ImgPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/stable_diffusion/img2img) and [`StableDiffusionInstructPix2PixPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/pix2pix)).
+- Class-conditioned image generation models (such as the [`DiTPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/dit)).
+
+## Qualitative Evaluation
+
+Qualitative evaluation typically involves human assessment of generated images. Quality is measured across aspects such as compositionality, image-text alignment, and spatial relations. Common prompts provide a degree of uniformity for subjective metrics.
+DrawBench and PartiPrompts are prompt datasets used for qualitative benchmarking. DrawBench and PartiPrompts were introduced by [Imagen](https://imagen.research.google/) and [Parti](https://parti.research.google/) respectively.
+
+From the [official Parti website](https://parti.research.google/):
+
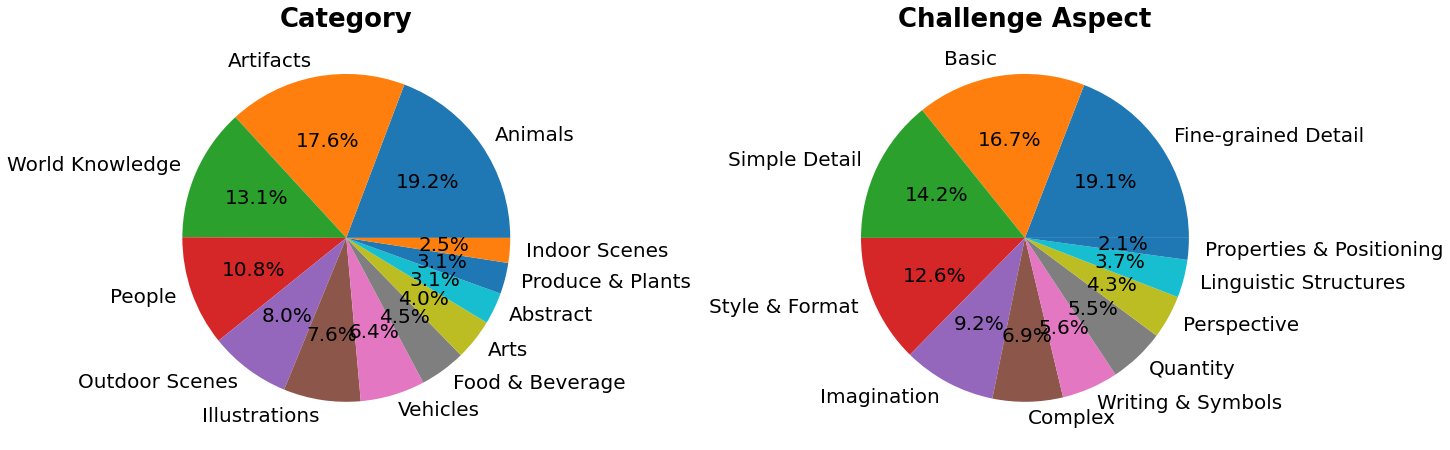
+> PartiPrompts (P2) is a rich set of over 1600 prompts in English that we release as part of this work. P2 can be used to measure model capabilities across various categories and challenge aspects.
+
+
+
+PartiPrompts has the following columns:
+
+- Prompt
+- Category of the prompt (such as “Abstract”, “World Knowledge”, etc.)
+- Challenge reflecting the difficulty (such as “Basic”, “Complex”, “Writing & Symbols”, etc.)
+
+These benchmarks allow for side-by-side human evaluation of different image generation models.
+
+For this, the 🧨 Diffusers team has built **Open Parti Prompts**, which is a community-driven qualitative benchmark based on Parti Prompts to compare state-of-the-art open-source diffusion models:
+- [Open Parti Prompts Game](https://huggingface.co/spaces/OpenGenAI/open-parti-prompts): For 10 parti prompts, 4 generated images are shown and the user selects the image that suits the prompt best.
+- [Open Parti Prompts Leaderboard](https://huggingface.co/spaces/OpenGenAI/parti-prompts-leaderboard): The leaderboard comparing the currently best open-sourced diffusion models to each other.
+
+To manually compare images, let’s see how we can use `diffusers` on a couple of PartiPrompts.
+
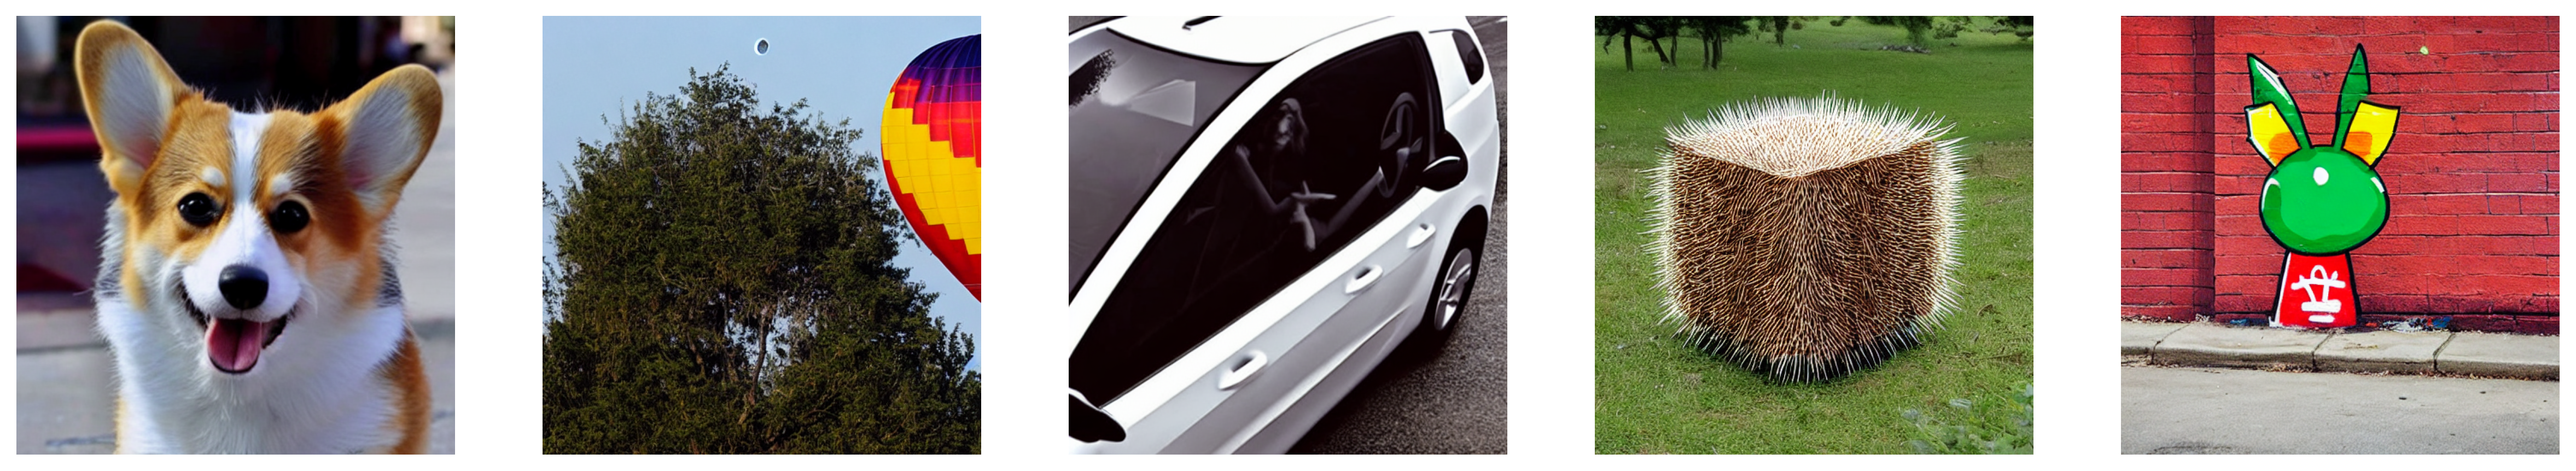
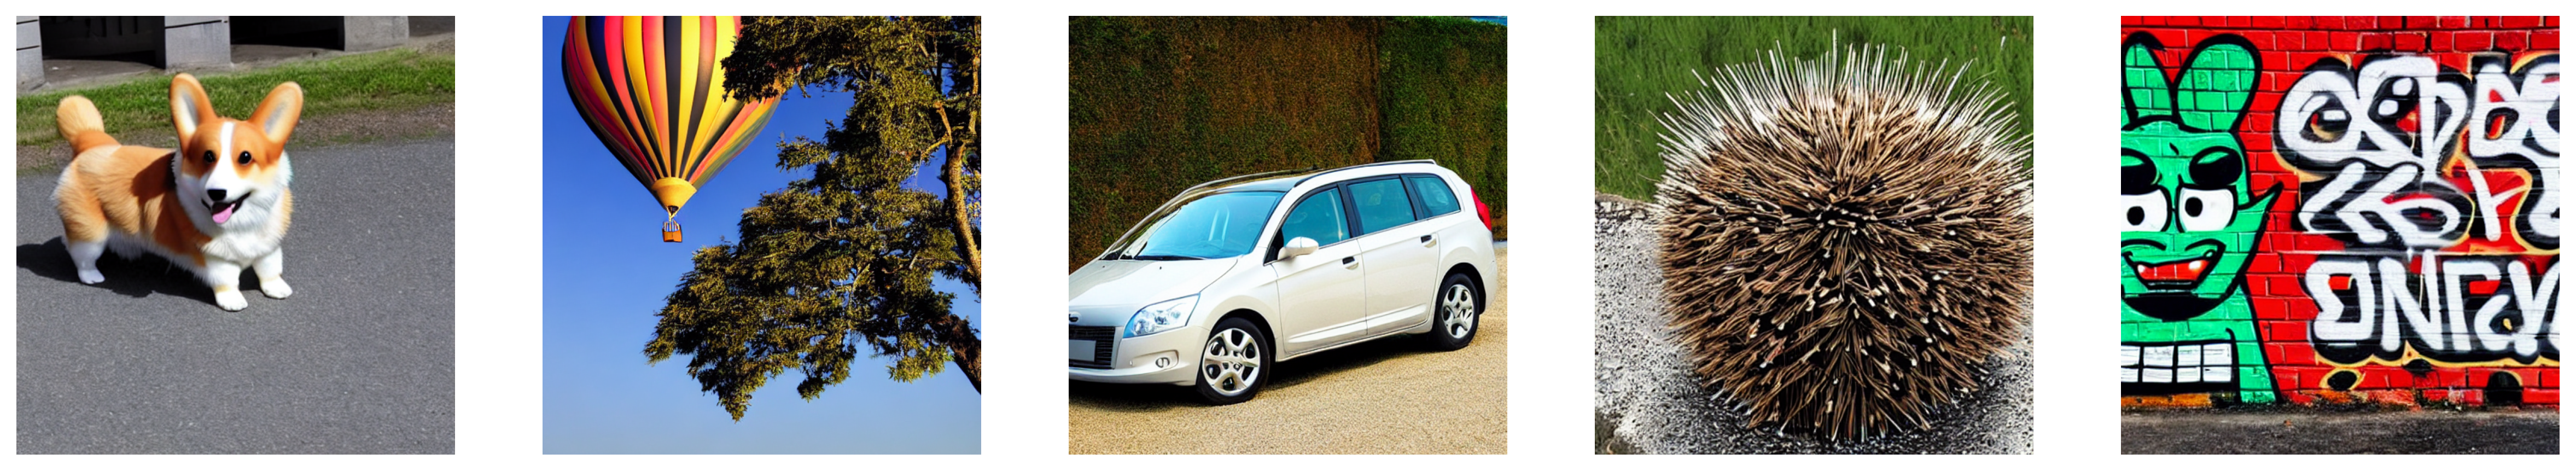
+Below we show some prompts sampled across different challenges: Basic, Complex, Linguistic Structures, Imagination, and Writing & Symbols. Here we are using PartiPrompts as a [dataset](https://huggingface.co/datasets/nateraw/parti-prompts).
+
+```python
+from datasets import load_dataset
+
+# prompts = load_dataset("nateraw/parti-prompts", split="train")
+# prompts = prompts.shuffle()
+# sample_prompts = [prompts[i]["Prompt"] for i in range(5)]
+
+# Fixing these sample prompts in the interest of reproducibility.
+sample_prompts = [
+ "a corgi",
+ "a hot air balloon with a yin-yang symbol, with the moon visible in the daytime sky",
+ "a car with no windows",
+ "a cube made of porcupine",
+ 'The saying "BE EXCELLENT TO EACH OTHER" written on a red brick wall with a graffiti image of a green alien wearing a tuxedo. A yellow fire hydrant is on a sidewalk in the foreground.',
+]
+```
+
+Now we can use these prompts to generate some images using Stable Diffusion ([v1-4 checkpoint](https://huggingface.co/CompVis/stable-diffusion-v1-4)):
+
+```python
+import torch
+
+seed = 0
+generator = torch.manual_seed(seed)
+
+images = sd_pipeline(sample_prompts, num_images_per_prompt=1, generator=generator).images
+```
+
+
+
+We can also set `num_images_per_prompt` accordingly to compare different images for the same prompt. Running the same pipeline but with a different checkpoint ([v1-5](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5)), yields:
+
+
+
+Once several images are generated from all the prompts using multiple models (under evaluation), these results are presented to human evaluators for scoring. For
+more details on the DrawBench and PartiPrompts benchmarks, refer to their respective papers.
+
+> [!TIP]
+> It is useful to look at some inference samples while a model is training to measure the
+> training progress. In our [training scripts](https://github.com/huggingface/diffusers/tree/main/examples/), we support this utility with additional support for
+> logging to TensorBoard and Weights & Biases.
+
+## Quantitative Evaluation
+
+In this section, we will walk you through how to evaluate three different diffusion pipelines using:
+
+- CLIP score
+- CLIP directional similarity
+- FID
+
+### Text-guided image generation
+
+[CLIP score](https://huggingface.co/papers/2104.08718) measures the compatibility of image-caption pairs. Higher CLIP scores imply higher compatibility 🔼. The CLIP score is a quantitative measurement of the qualitative concept "compatibility". Image-caption pair compatibility can also be thought of as the semantic similarity between the image and the caption. CLIP score was found to have high correlation with human judgement.
+
+Let's first load a [`StableDiffusionPipeline`]:
+
+```python
+from diffusers import StableDiffusionPipeline
+import torch
+
+model_ckpt = "CompVis/stable-diffusion-v1-4"
+sd_pipeline = StableDiffusionPipeline.from_pretrained(model_ckpt, torch_dtype=torch.float16).to("cuda")
+```
+
+Generate some images with multiple prompts:
+
+```python
+prompts = [
+ "a photo of an astronaut riding a horse on mars",
+ "A high tech solarpunk utopia in the Amazon rainforest",
+ "A pikachu fine dining with a view to the Eiffel Tower",
+ "A mecha robot in a favela in expressionist style",
+ "an insect robot preparing a delicious meal",
+ "A small cabin on top of a snowy mountain in the style of Disney, artstation",
+]
+
+images = sd_pipeline(prompts, num_images_per_prompt=1, output_type="np").images
+
+print(images.shape)
+# (6, 512, 512, 3)
+```
+
+And then, we calculate the CLIP score.
+
+```python
+from torchmetrics.functional.multimodal import clip_score
+from functools import partial
+
+clip_score_fn = partial(clip_score, model_name_or_path="openai/clip-vit-base-patch16")
+
+def calculate_clip_score(images, prompts):
+ images_int = (images * 255).astype("uint8")
+ clip_score = clip_score_fn(torch.from_numpy(images_int).permute(0, 3, 1, 2), prompts).detach()
+ return round(float(clip_score), 4)
+
+sd_clip_score = calculate_clip_score(images, prompts)
+print(f"CLIP score: {sd_clip_score}")
+# CLIP score: 35.7038
+```
+
+In the above example, we generated one image per prompt. If we generated multiple images per prompt, we would have to take the average score from the generated images per prompt.
+
+Now, if we wanted to compare two checkpoints compatible with the [`StableDiffusionPipeline`] we should pass a generator while calling the pipeline. First, we generate images with a
+fixed seed with the [v1-4 Stable Diffusion checkpoint](https://huggingface.co/CompVis/stable-diffusion-v1-4):
+
+```python
+seed = 0
+generator = torch.manual_seed(seed)
+
+images = sd_pipeline(prompts, num_images_per_prompt=1, generator=generator, output_type="np").images
+```
+
+Then we load the [v1-5 checkpoint](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) to generate images:
+
+```python
+model_ckpt_1_5 = "stable-diffusion-v1-5/stable-diffusion-v1-5"
+sd_pipeline_1_5 = StableDiffusionPipeline.from_pretrained(model_ckpt_1_5, torch_dtype=torch.float16).to("cuda")
+
+images_1_5 = sd_pipeline_1_5(prompts, num_images_per_prompt=1, generator=generator, output_type="np").images
+```
+
+And finally, we compare their CLIP scores:
+
+```python
+sd_clip_score_1_4 = calculate_clip_score(images, prompts)
+print(f"CLIP Score with v-1-4: {sd_clip_score_1_4}")
+# CLIP Score with v-1-4: 34.9102
+
+sd_clip_score_1_5 = calculate_clip_score(images_1_5, prompts)
+print(f"CLIP Score with v-1-5: {sd_clip_score_1_5}")
+# CLIP Score with v-1-5: 36.2137
+```
+
+It seems like the [v1-5](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) checkpoint performs better than its predecessor. Note, however, that the number of prompts we used to compute the CLIP scores is quite low. For a more practical evaluation, this number should be way higher, and the prompts should be diverse.
+
+> [!WARNING]
+> By construction, there are some limitations in this score. The captions in the training dataset
+> were crawled from the web and extracted from `alt` and similar tags associated an image on the internet.
+> They are not necessarily representative of what a human being would use to describe an image. Hence we
+> had to "engineer" some prompts here.
+
+### Image-conditioned text-to-image generation
+
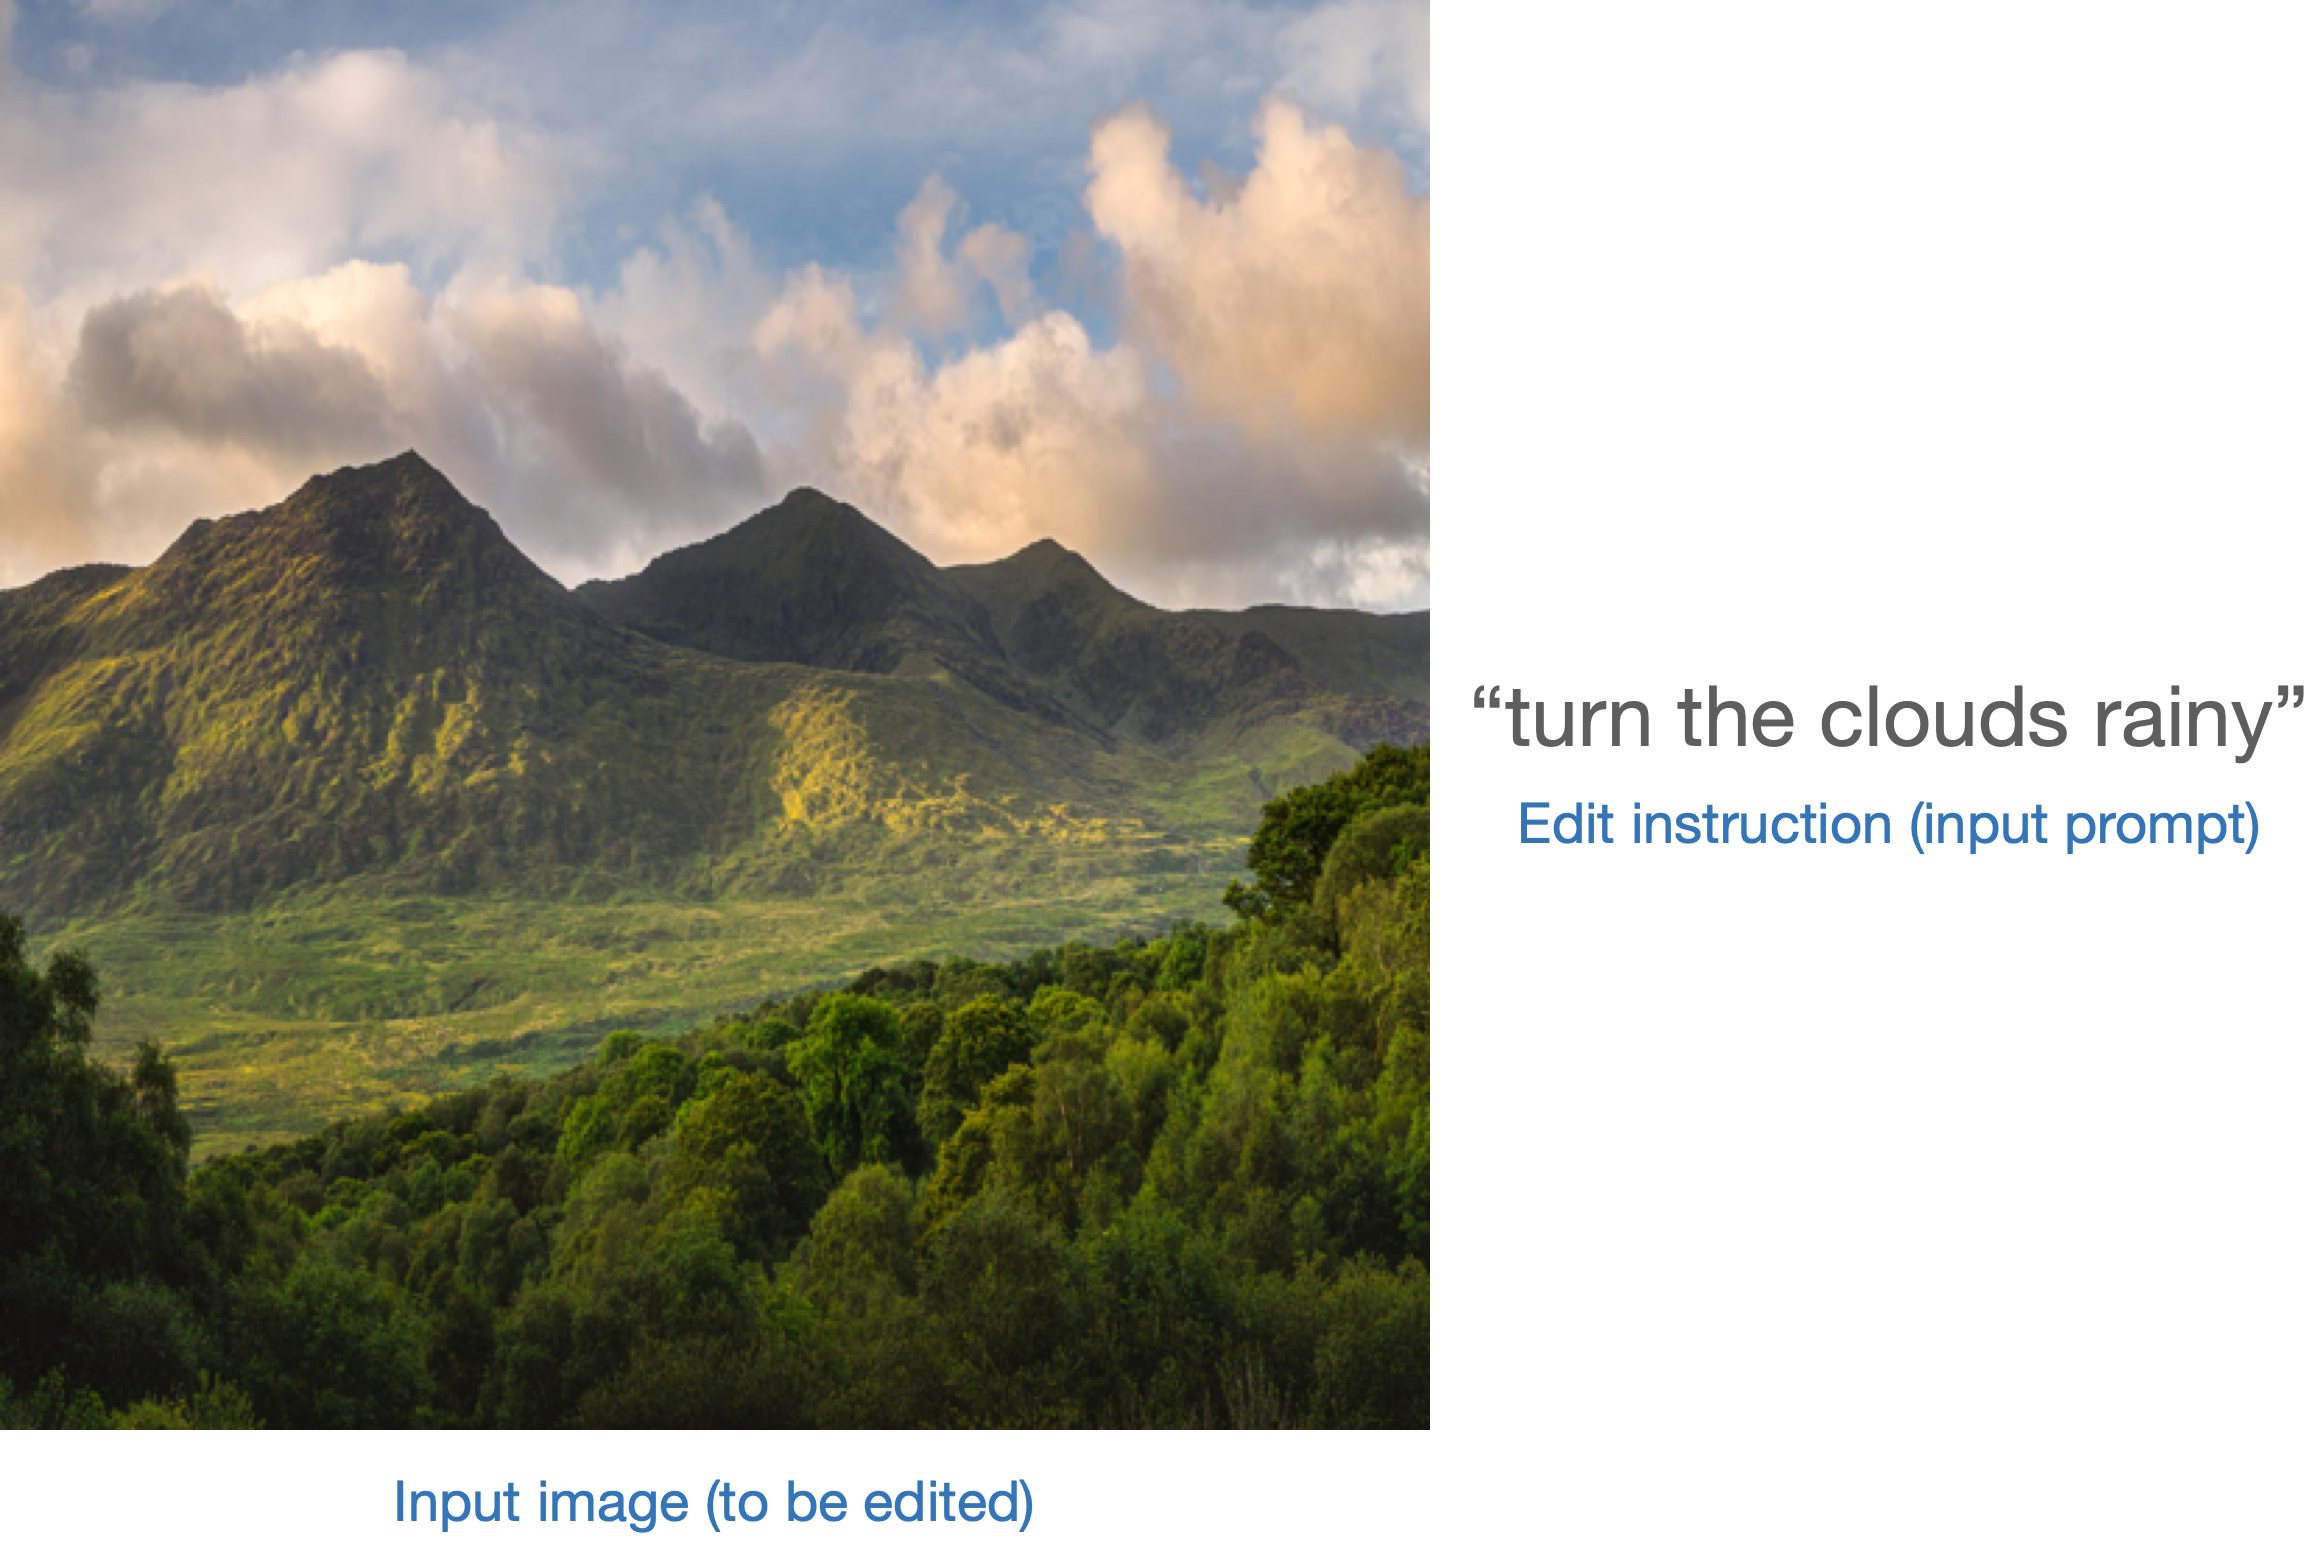
+In this case, we condition the generation pipeline with an input image as well as a text prompt. Let's take the [`StableDiffusionInstructPix2PixPipeline`], as an example. It takes an edit instruction as an input prompt and an input image to be edited.
+
+Here is one example:
+
+
+
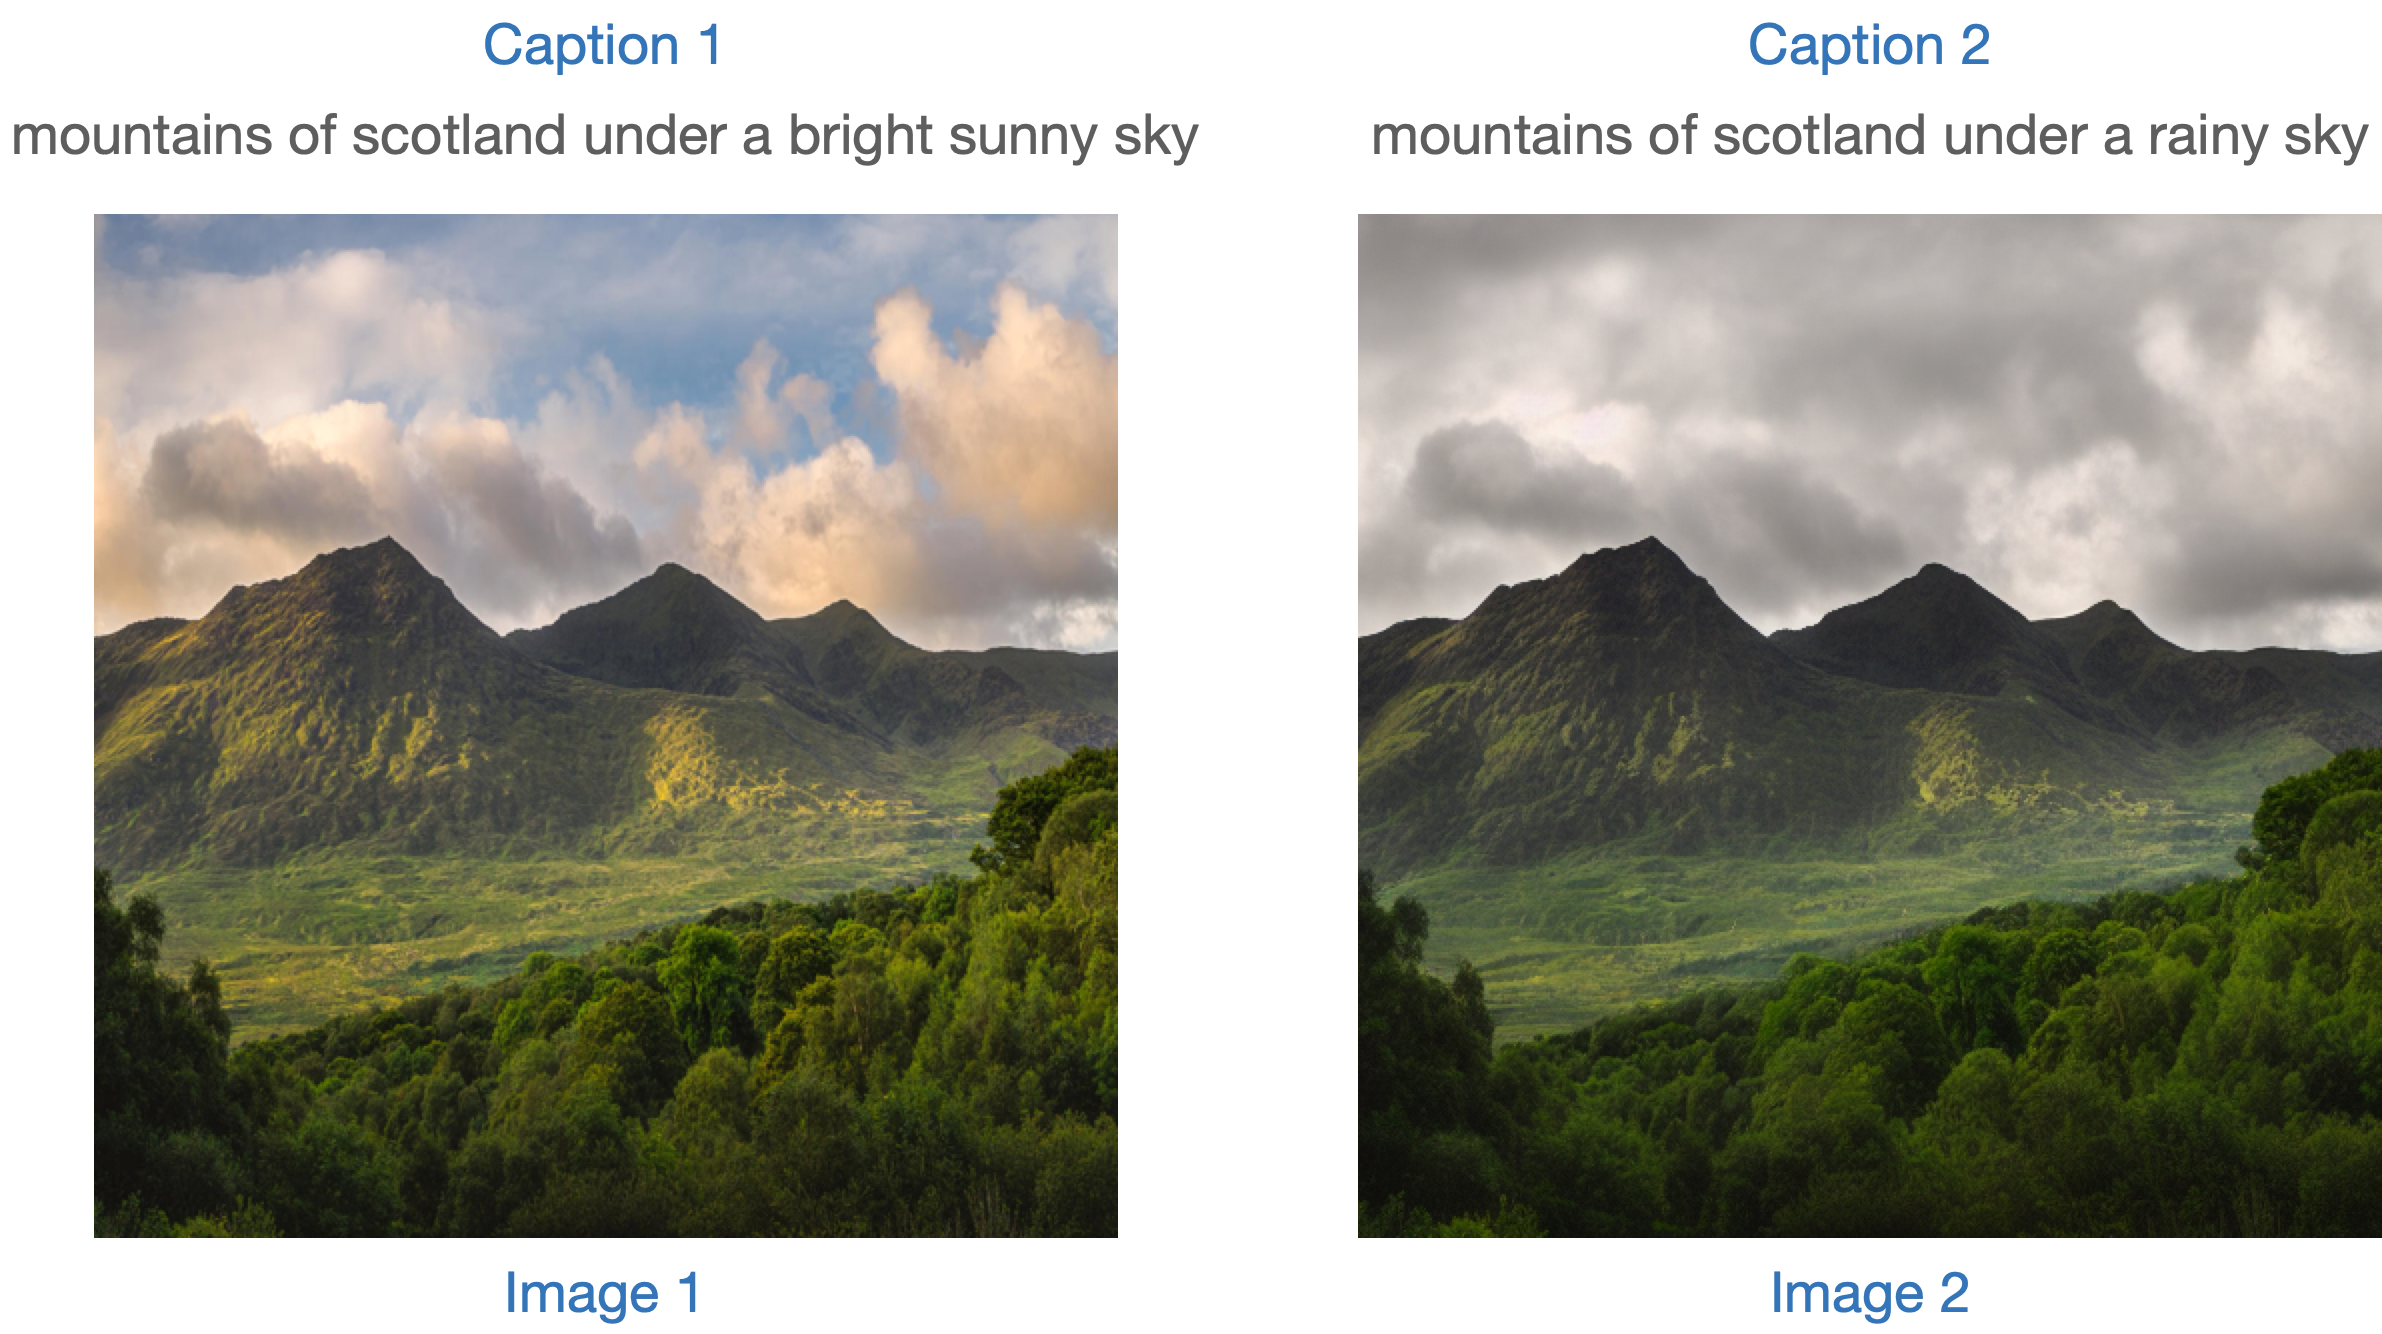
+One strategy to evaluate such a model is to measure the consistency of the change between the two images (in [CLIP](https://huggingface.co/docs/transformers/model_doc/clip) space) with the change between the two image captions (as shown in [CLIP-Guided Domain Adaptation of Image Generators](https://huggingface.co/papers/2108.00946)). This is referred to as the "**CLIP directional similarity**".
+
+- Caption 1 corresponds to the input image (image 1) that is to be edited.
+- Caption 2 corresponds to the edited image (image 2). It should reflect the edit instruction.
+
+Following is a pictorial overview:
+
+
+
+We have prepared a mini dataset to implement this metric. Let's first load the dataset.
+
+```python
+from datasets import load_dataset
+
+dataset = load_dataset("sayakpaul/instructpix2pix-demo", split="train")
+dataset.features
+```
+
+```bash
+{'input': Value(dtype='string', id=None),
+ 'edit': Value(dtype='string', id=None),
+ 'output': Value(dtype='string', id=None),
+ 'image': Image(decode=True, id=None)}
+```
+
+Here we have:
+
+- `input` is a caption corresponding to the `image`.
+- `edit` denotes the edit instruction.
+- `output` denotes the modified caption reflecting the `edit` instruction.
+
+Let's take a look at a sample.
+
+```python
+idx = 0
+print(f"Original caption: {dataset[idx]['input']}")
+print(f"Edit instruction: {dataset[idx]['edit']}")
+print(f"Modified caption: {dataset[idx]['output']}")
+```
+
+```bash
+Original caption: 2. FAROE ISLANDS: An archipelago of 18 mountainous isles in the North Atlantic Ocean between Norway and Iceland, the Faroe Islands has 'everything you could hope for', according to Big 7 Travel. It boasts 'crystal clear waterfalls, rocky cliffs that seem to jut out of nowhere and velvety green hills'
+Edit instruction: make the isles all white marble
+Modified caption: 2. WHITE MARBLE ISLANDS: An archipelago of 18 mountainous white marble isles in the North Atlantic Ocean between Norway and Iceland, the White Marble Islands has 'everything you could hope for', according to Big 7 Travel. It boasts 'crystal clear waterfalls, rocky cliffs that seem to jut out of nowhere and velvety green hills'
+```
+
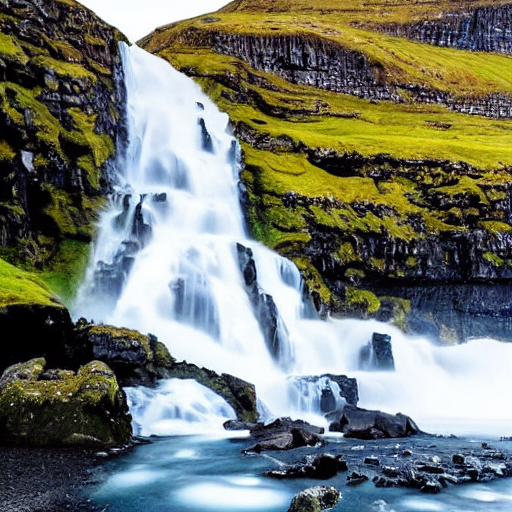
+And here is the image:
+
+```python
+dataset[idx]["image"]
+```
+
+
+
+We will first edit the images of our dataset with the edit instruction and compute the directional similarity.
+
+Let's first load the [`StableDiffusionInstructPix2PixPipeline`]:
+
+```python
+from diffusers import StableDiffusionInstructPix2PixPipeline
+
+instruct_pix2pix_pipeline = StableDiffusionInstructPix2PixPipeline.from_pretrained(
+ "timbrooks/instruct-pix2pix", torch_dtype=torch.float16
+).to("cuda")
+```
+
+Now, we perform the edits:
+
+```python
+import numpy as np
+
+
+def edit_image(input_image, instruction):
+ image = instruct_pix2pix_pipeline(
+ instruction,
+ image=input_image,
+ output_type="np",
+ generator=generator,
+ ).images[0]
+ return image
+
+input_images = []
+original_captions = []
+modified_captions = []
+edited_images = []
+
+for idx in range(len(dataset)):
+ input_image = dataset[idx]["image"]
+ edit_instruction = dataset[idx]["edit"]
+ edited_image = edit_image(input_image, edit_instruction)
+
+ input_images.append(np.array(input_image))
+ original_captions.append(dataset[idx]["input"])
+ modified_captions.append(dataset[idx]["output"])
+ edited_images.append(edited_image)
+```
+
+To measure the directional similarity, we first load CLIP's image and text encoders:
+
+```python
+from transformers import (
+ CLIPTokenizer,
+ CLIPTextModelWithProjection,
+ CLIPVisionModelWithProjection,
+ CLIPImageProcessor,
+)
+
+clip_id = "openai/clip-vit-large-patch14"
+tokenizer = CLIPTokenizer.from_pretrained(clip_id)
+text_encoder = CLIPTextModelWithProjection.from_pretrained(clip_id).to("cuda")
+image_processor = CLIPImageProcessor.from_pretrained(clip_id)
+image_encoder = CLIPVisionModelWithProjection.from_pretrained(clip_id).to("cuda")
+```
+
+Notice that we are using a particular CLIP checkpoint, i.e., `openai/clip-vit-large-patch14`. This is because the Stable Diffusion pre-training was performed with this CLIP variant. For more details, refer to the [documentation](https://huggingface.co/docs/transformers/model_doc/clip).
+
+Next, we prepare a PyTorch `nn.Module` to compute directional similarity:
+
+```python
+import torch.nn as nn
+import torch.nn.functional as F
+
+
+class DirectionalSimilarity(nn.Module):
+ def __init__(self, tokenizer, text_encoder, image_processor, image_encoder):
+ super().__init__()
+ self.tokenizer = tokenizer
+ self.text_encoder = text_encoder
+ self.image_processor = image_processor
+ self.image_encoder = image_encoder
+
+ def preprocess_image(self, image):
+ image = self.image_processor(image, return_tensors="pt")["pixel_values"]
+ return {"pixel_values": image.to("cuda")}
+
+ def tokenize_text(self, text):
+ inputs = self.tokenizer(
+ text,
+ max_length=self.tokenizer.model_max_length,
+ padding="max_length",
+ truncation=True,
+ return_tensors="pt",
+ )
+ return {"input_ids": inputs.input_ids.to("cuda")}
+
+ def encode_image(self, image):
+ preprocessed_image = self.preprocess_image(image)
+ image_features = self.image_encoder(**preprocessed_image).image_embeds
+ image_features = image_features / image_features.norm(dim=1, keepdim=True)
+ return image_features
+
+ def encode_text(self, text):
+ tokenized_text = self.tokenize_text(text)
+ text_features = self.text_encoder(**tokenized_text).text_embeds
+ text_features = text_features / text_features.norm(dim=1, keepdim=True)
+ return text_features
+
+ def compute_directional_similarity(self, img_feat_one, img_feat_two, text_feat_one, text_feat_two):
+ sim_direction = F.cosine_similarity(img_feat_two - img_feat_one, text_feat_two - text_feat_one)
+ return sim_direction
+
+ def forward(self, image_one, image_two, caption_one, caption_two):
+ img_feat_one = self.encode_image(image_one)
+ img_feat_two = self.encode_image(image_two)
+ text_feat_one = self.encode_text(caption_one)
+ text_feat_two = self.encode_text(caption_two)
+ directional_similarity = self.compute_directional_similarity(
+ img_feat_one, img_feat_two, text_feat_one, text_feat_two
+ )
+ return directional_similarity
+```
+
+Let's put `DirectionalSimilarity` to use now.
+
+```python
+dir_similarity = DirectionalSimilarity(tokenizer, text_encoder, image_processor, image_encoder)
+scores = []
+
+for i in range(len(input_images)):
+ original_image = input_images[i]
+ original_caption = original_captions[i]
+ edited_image = edited_images[i]
+ modified_caption = modified_captions[i]
+
+ similarity_score = dir_similarity(original_image, edited_image, original_caption, modified_caption)
+ scores.append(float(similarity_score.detach().cpu()))
+
+print(f"CLIP directional similarity: {np.mean(scores)}")
+# CLIP directional similarity: 0.0797976553440094
+```
+
+Like the CLIP Score, the higher the CLIP directional similarity, the better it is.
+
+It should be noted that the `StableDiffusionInstructPix2PixPipeline` exposes two arguments, namely, `image_guidance_scale` and `guidance_scale` that let you control the quality of the final edited image. We encourage you to experiment with these two arguments and see the impact of that on the directional similarity.
+
+We can extend the idea of this metric to measure how similar the original image and edited version are. To do that, we can just do `F.cosine_similarity(img_feat_two, img_feat_one)`. For these kinds of edits, we would still want the primary semantics of the images to be preserved as much as possible, i.e., a high similarity score.
+
+We can use these metrics for similar pipelines such as the [`StableDiffusionPix2PixZeroPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/pix2pix_zero#diffusers.StableDiffusionPix2PixZeroPipeline).
+
+> [!TIP]
+> Both CLIP score and CLIP direction similarity rely on the CLIP model, which can make the evaluations biased.
+
+***Extending metrics like IS, FID (discussed later), or KID can be difficult*** when the model under evaluation was pre-trained on a large image-captioning dataset (such as the [LAION-5B dataset](https://laion.ai/blog/laion-5b/)). This is because underlying these metrics is an InceptionNet (pre-trained on the ImageNet-1k dataset) used for extracting intermediate image features. The pre-training dataset of Stable Diffusion may have limited overlap with the pre-training dataset of InceptionNet, so it is not a good candidate here for feature extraction.
+
+***Using the above metrics helps evaluate models that are class-conditioned. For example, [DiT](https://huggingface.co/docs/diffusers/main/en/api/pipelines/dit). It was pre-trained being conditioned on the ImageNet-1k classes.***
+
+### Class-conditioned image generation
+
+Class-conditioned generative models are usually pre-trained on a class-labeled dataset such as [ImageNet-1k](https://huggingface.co/datasets/imagenet-1k). Popular metrics for evaluating these models include Fréchet Inception Distance (FID), Kernel Inception Distance (KID), and Inception Score (IS). In this document, we focus on FID ([Heusel et al.](https://huggingface.co/papers/1706.08500)). We show how to compute it with the [`DiTPipeline`](https://huggingface.co/docs/diffusers/api/pipelines/dit), which uses the [DiT model](https://huggingface.co/papers/2212.09748) under the hood.
+
+FID aims to measure how similar are two datasets of images. As per [this resource](https://mmgeneration.readthedocs.io/en/latest/quick_run.html#fid):
+
+> Fréchet Inception Distance is a measure of similarity between two datasets of images. It was shown to correlate well with the human judgment of visual quality and is most often used to evaluate the quality of samples of Generative Adversarial Networks. FID is calculated by computing the Fréchet distance between two Gaussians fitted to feature representations of the Inception network.
+
+These two datasets are essentially the dataset of real images and the dataset of fake images (generated images in our case). FID is usually calculated with two large datasets. However, for this document, we will work with two mini datasets.
+
+Let's first download a few images from the ImageNet-1k training set:
+
+```python
+from zipfile import ZipFile
+import requests
+
+
+def download(url, local_filepath):
+ r = requests.get(url)
+ with open(local_filepath, "wb") as f:
+ f.write(r.content)
+ return local_filepath
+
+dummy_dataset_url = "https://hf.co/datasets/sayakpaul/sample-datasets/resolve/main/sample-imagenet-images.zip"
+local_filepath = download(dummy_dataset_url, dummy_dataset_url.split("/")[-1])
+
+with ZipFile(local_filepath, "r") as zipper:
+ zipper.extractall(".")
+```
+
+```python
+from PIL import Image
+import os
+import numpy as np
+
+dataset_path = "sample-imagenet-images"
+image_paths = sorted([os.path.join(dataset_path, x) for x in os.listdir(dataset_path)])
+
+real_images = [np.array(Image.open(path).convert("RGB")) for path in image_paths]
+```
+
+These are 10 images from the following ImageNet-1k classes: "cassette_player", "chain_saw" (x2), "church", "gas_pump" (x3), "parachute" (x2), and "tench".
+
+
+ 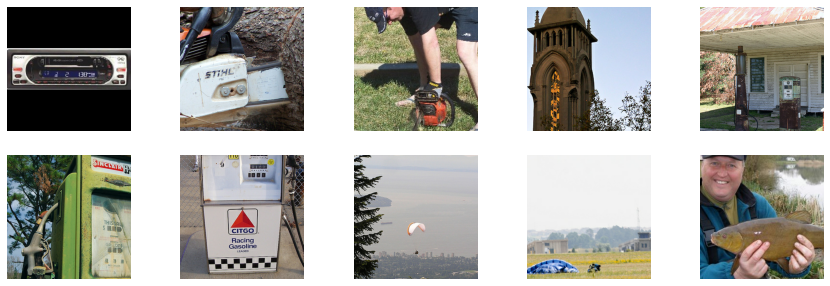
+ Real images.
+
+ 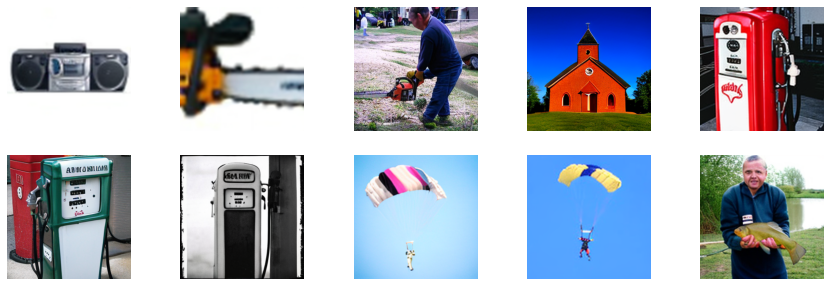
+ Fake images.
+
 +
 +
 +
 +
 +
 +
 +
+
+  +
+
 + badge indicate a model can take advantage of the MPS backend on Apple silicon devices for faster inference. Feel free to open a [Pull Request](https://github.com/huggingface/diffusers/compare) to add this badge to pipelines that are missing it.
+
+🤗 Diffusers is compatible with Apple silicon (M1/M2 chips) using the PyTorch [`mps`](https://pytorch.org/docs/stable/notes/mps.html) device, which uses the Metal framework to leverage the GPU on MacOS devices. You'll need to have:
+
+- macOS computer with Apple silicon (M1/M2) hardware
+- macOS 12.6 or later (13.0 or later recommended)
+- arm64 version of Python
+- [PyTorch 2.0](https://pytorch.org/get-started/locally/) (recommended) or 1.13 (minimum version supported for `mps`)
+
+The `mps` backend uses PyTorch's `.to()` interface to move the Stable Diffusion pipeline on to your M1 or M2 device:
+
+```python
+from diffusers import DiffusionPipeline
+
+pipe = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5")
+pipe = pipe.to("mps")
+
+# Recommended if your computer has < 64 GB of RAM
+pipe.enable_attention_slicing()
+
+prompt = "a photo of an astronaut riding a horse on mars"
+image = pipe(prompt).images[0]
+image
+```
+
+> [!WARNING]
+> The PyTorch [mps](https://pytorch.org/docs/stable/notes/mps.html) backend does not support NDArray sizes greater than `2**32`. Please open an [Issue](https://github.com/huggingface/diffusers/issues/new/choose) if you encounter this problem so we can investigate.
+
+If you're using **PyTorch 1.13**, you need to "prime" the pipeline with an additional one-time pass through it. This is a temporary workaround for an issue where the first inference pass produces slightly different results than subsequent ones. You only need to do this pass once, and after just one inference step you can discard the result.
+
+```diff
+ from diffusers import DiffusionPipeline
+
+ pipe = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5").to("mps")
+ pipe.enable_attention_slicing()
+
+ prompt = "a photo of an astronaut riding a horse on mars"
+ # First-time "warmup" pass if PyTorch version is 1.13
++ _ = pipe(prompt, num_inference_steps=1)
+
+ # Results match those from the CPU device after the warmup pass.
+ image = pipe(prompt).images[0]
+```
+
+## Troubleshoot
+
+This section lists some common issues with using the `mps` backend and how to solve them.
+
+### Attention slicing
+
+M1/M2 performance is very sensitive to memory pressure. When this occurs, the system automatically swaps if it needs to which significantly degrades performance.
+
+To prevent this from happening, we recommend *attention slicing* to reduce memory pressure during inference and prevent swapping. This is especially relevant if your computer has less than 64GB of system RAM, or if you generate images at non-standard resolutions larger than 512×512 pixels. Call the [`~DiffusionPipeline.enable_attention_slicing`] function on your pipeline:
+
+```py
+from diffusers import DiffusionPipeline
+import torch
+
+pipeline = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", torch_dtype=torch.float16, variant="fp16", use_safetensors=True).to("mps")
+pipeline.enable_attention_slicing()
+```
+
+Attention slicing performs the costly attention operation in multiple steps instead of all at once. It usually improves performance by ~20% in computers without universal memory, but we've observed *better performance* in most Apple silicon computers unless you have 64GB of RAM or more.
+
+### Batch inference
+
+Generating multiple prompts in a batch can crash or fail to work reliably. If this is the case, try iterating instead of batching.
\ No newline at end of file
diff --git a/tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/optimization/neuron.md b/tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/optimization/neuron.md
new file mode 100644
index 0000000000000000000000000000000000000000..6a45bd0563bbf7d2a6d93d3ecdb1c510334d4d6b
--- /dev/null
+++ b/tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/optimization/neuron.md
@@ -0,0 +1,58 @@
+
+
+# AWS Neuron
+
+Diffusers functionalities are available on [AWS Inf2 instances](https://aws.amazon.com/ec2/instance-types/inf2/), which are EC2 instances powered by [Neuron machine learning accelerators](https://aws.amazon.com/machine-learning/inferentia/). These instances aim to provide better compute performance (higher throughput, lower latency) with good cost-efficiency, making them good candidates for AWS users to deploy diffusion models to production.
+
+[Optimum Neuron](https://huggingface.co/docs/optimum-neuron/en/index) is the interface between Hugging Face libraries and AWS Accelerators, including AWS [Trainium](https://aws.amazon.com/machine-learning/trainium/) and AWS [Inferentia](https://aws.amazon.com/machine-learning/inferentia/). It supports many of the features in Diffusers with similar APIs, so it is easier to learn if you're already familiar with Diffusers. Once you have created an AWS Inf2 instance, install Optimum Neuron.
+
+```bash
+python -m pip install --upgrade-strategy eager optimum[neuronx]
+```
+
+> [!TIP]
+> We provide pre-built [Hugging Face Neuron Deep Learning AMI](https://aws.amazon.com/marketplace/pp/prodview-gr3e6yiscria2) (DLAMI) and Optimum Neuron containers for Amazon SageMaker. It's recommended to correctly set up your environment.
+
+The example below demonstrates how to generate images with the Stable Diffusion XL model on an inf2.8xlarge instance (you can switch to cheaper inf2.xlarge instances once the model is compiled). To generate some images, use the [`~optimum.neuron.NeuronStableDiffusionXLPipeline`] class, which is similar to the [`StableDiffusionXLPipeline`] class in Diffusers.
+
+Unlike Diffusers, you need to compile models in the pipeline to the Neuron format, `.neuron`. Launch the following command to export the model to the `.neuron` format.
+
+```bash
+optimum-cli export neuron --model stabilityai/stable-diffusion-xl-base-1.0 \
+ --batch_size 1 \
+ --height 1024 `# height in pixels of generated image, eg. 768, 1024` \
+ --width 1024 `# width in pixels of generated image, eg. 768, 1024` \
+ --num_images_per_prompt 1 `# number of images to generate per prompt, defaults to 1` \
+ --auto_cast matmul `# cast only matrix multiplication operations` \
+ --auto_cast_type bf16 `# cast operations from FP32 to BF16` \
+ sd_neuron_xl/
+```
+
+Now generate some images with the pre-compiled SDXL model.
+
+```python
+>>> from optimum.neuron import NeuronStableDiffusionXLPipeline
+
+>>> stable_diffusion_xl = NeuronStableDiffusionXLPipeline.from_pretrained("sd_neuron_xl/")
+>>> prompt = "a pig with wings flying in floating US dollar banknotes in the air, skyscrapers behind, warm color palette, muted colors, detailed, 8k"
+>>> image = stable_diffusion_xl(prompt).images[0]
+```
+
+
 +
+Feel free to check out more guides and examples on different use cases from the Optimum Neuron [documentation](https://huggingface.co/docs/optimum-neuron/en/inference_tutorials/stable_diffusion#generate-images-with-stable-diffusion-models-on-aws-inferentia)!
diff --git a/tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/optimization/onnx.md b/tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/optimization/onnx.md
new file mode 100644
index 0000000000000000000000000000000000000000..620f2af994b36266de67ea8f8b8e584142da2723
--- /dev/null
+++ b/tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/optimization/onnx.md
@@ -0,0 +1,83 @@
+
+
+# ONNX Runtime
+
+🤗 [Optimum](https://github.com/huggingface/optimum) provides a Stable Diffusion pipeline compatible with ONNX Runtime. You'll need to install 🤗 Optimum with the following command for ONNX Runtime support:
+
+```bash
+pip install -q optimum["onnxruntime"]
+```
+
+This guide will show you how to use the Stable Diffusion and Stable Diffusion XL (SDXL) pipelines with ONNX Runtime.
+
+## Stable Diffusion
+
+To load and run inference, use the [`~optimum.onnxruntime.ORTStableDiffusionPipeline`]. If you want to load a PyTorch model and convert it to the ONNX format on-the-fly, set `export=True`:
+
+```python
+from optimum.onnxruntime import ORTStableDiffusionPipeline
+
+model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5"
+pipeline = ORTStableDiffusionPipeline.from_pretrained(model_id, export=True)
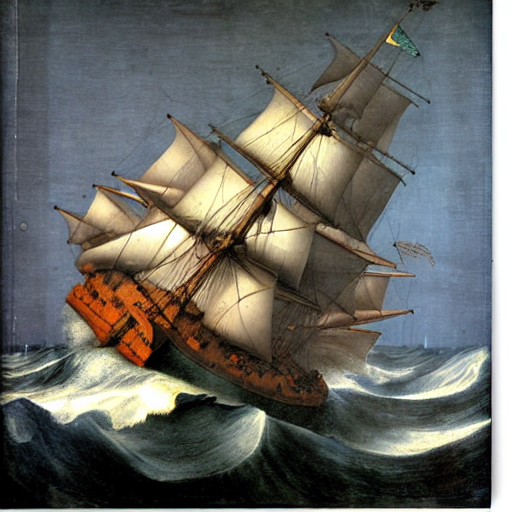
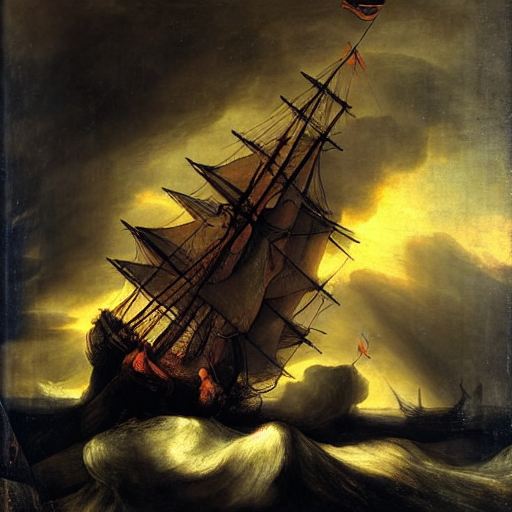
+prompt = "sailing ship in storm by Leonardo da Vinci"
+image = pipeline(prompt).images[0]
+pipeline.save_pretrained("./onnx-stable-diffusion-v1-5")
+```
+
+> [!WARNING]
+> Generating multiple prompts in a batch seems to take too much memory. While we look into it, you may need to iterate instead of batching.
+
+To export the pipeline in the ONNX format offline and use it later for inference,
+use the [`optimum-cli export`](https://huggingface.co/docs/optimum/main/en/exporters/onnx/usage_guides/export_a_model#exporting-a-model-to-onnx-using-the-cli) command:
+
+```bash
+optimum-cli export onnx --model stable-diffusion-v1-5/stable-diffusion-v1-5 sd_v15_onnx/
+```
+
+Then to perform inference (you don't have to specify `export=True` again):
+
+```python
+from optimum.onnxruntime import ORTStableDiffusionPipeline
+
+model_id = "sd_v15_onnx"
+pipeline = ORTStableDiffusionPipeline.from_pretrained(model_id)
+prompt = "sailing ship in storm by Leonardo da Vinci"
+image = pipeline(prompt).images[0]
+```
+
+
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +