 +
+**Fine-Grained Egocentric Hand-Object Segmentation: Dataset, Model, and Applications**\
+*European Conference on Computer Vision (ECCV), 2022*\
+[Lingzhi Zhang*](https://owenzlz.github.io/), [Shenghao Zhou*](https://scholar.google.com/citations?user=kWdwbUYAAAAJ&hl=en), [Simon Stent](https://scholar.google.com/citations?user=f3aij5UAAAAJ&hl=en), [Jianbo Shi](https://www.cis.upenn.edu/~jshi/) (* indicates equal contribution)
+
+Our main goal is to provide a tool for better hand-object segmentation on the in-the-wild egocentric videos.
+
+## Prerequisites
+- Linux
+- Python 3
+- NVIDIA GPU + CUDA CuDNN
+
+**Table of Contents:**
 +
+- Predict two hands, contact boundary, and interacting objects (1st and 2nd orders) sequentially.
+```bash
+cd mmsegmentation # if you are not in this directory
+bash pred_all_obj2.sh
+```
+
+
 +
+If you only want to predict only hand/contact segmentation, or want to use each module separately, see the commands below.
+
+- Predict only the left and right hands.
+```bash
+cd mmsegmentation # if you are not in this directory
+bash pred_twohands.sh
+```
+
+
 +
+- Predict the dense contact boundary.
+```bash
+cd mmsegmentation # if you are not in this directory
+bash pred_cb.sh
+```
+
+
 +
+- Predict the (1st order) interacting objects.
+```bash
+cd mmsegmentation # if you are not in this directory
+bash pred_obj1.sh
+```
+
+- Predict the (both 1st and 2nd orders) interacting objects.
+```bash
+cd mmsegmentation
+bash pred_obj2.sh
+```
+
+
 +
+ OpenMMLab website
+
+
+ HOT
+
+
+
+ OpenMMLab platform
+
+
+ TRY IT OUT
+
+
+
+ + +[](https://pypi.org/project/mmsegmentation/) +[](https://pypi.org/project/mmsegmentation) +[](https://mmsegmentation.readthedocs.io/en/latest/) +[](https://github.com/open-mmlab/mmsegmentation/actions) +[](https://codecov.io/gh/open-mmlab/mmsegmentation) +[](https://github.com/open-mmlab/mmsegmentation/blob/master/LICENSE) +[](https://github.com/open-mmlab/mmsegmentation/issues) +[](https://github.com/open-mmlab/mmsegmentation/issues) + +[📘Documentation](https://mmsegmentation.readthedocs.io/en/latest/) | +[🛠️Installation](https://mmsegmentation.readthedocs.io/en/latest/get_started.html) | +[👀Model Zoo](https://mmsegmentation.readthedocs.io/en/latest/model_zoo.html) | +[🆕Update News](https://mmsegmentation.readthedocs.io/en/latest/changelog.html) | +[🤔Reporting Issues](https://github.com/open-mmlab/mmsegmentation/issues/new/choose) + + + +
+
+English | [简体中文](README_zh-CN.md)
+
+
+
+## Introduction
+
+MMSegmentation is an open source semantic segmentation toolbox based on PyTorch.
+It is a part of the [OpenMMLab](https://openmmlab.com/) project.
+
+The master branch works with **PyTorch 1.5+**.
+
+
+
+
+
+
+## What's New
+
+v0.26.0 was released in 7/1/2022:
+
+- Update New SegFormer models on ADE20K
+- Dedicated MMSegWandbHook for MMSegmentation to use wandb visualization tool
+
+Please refer to [changelog.md](docs/en/changelog.md) for details and release history.
+
+## Installation
+
+Please refer to [get_started.md](docs/en/get_started.md#installation) for installation and [dataset_prepare.md](docs/en/dataset_prepare.md#prepare-datasets) for dataset preparation.
+
+## Get Started
+
+Please see [train.md](docs/en/train.md) and [inference.md](docs/en/inference.md) for the basic usage of MMSegmentation.
+There are also tutorials for:
+
+- [customizing dataset](docs/en/tutorials/customize_datasets.md)
+- [designing data pipeline](docs/en/tutorials/data_pipeline.md)
+- [customizing modules](docs/en/tutorials/customize_models.md)
+- [customizing runtime](docs/en/tutorials/customize_runtime.md)
+- [training tricks](docs/en/tutorials/training_tricks.md)
+- [useful tools](docs/en/useful_tools.md)
+
+A Colab tutorial is also provided. You may preview the notebook [here](demo/MMSegmentation_Tutorial.ipynb) or directly [run](https://colab.research.google.com/github/open-mmlab/mmsegmentation/blob/master/demo/MMSegmentation_Tutorial.ipynb) on Colab.
+
+## Benchmark and model zoo
+
+Results and models are available in the [model zoo](docs/en/model_zoo.md).
+
+Supported backbones:
+
+- [x] ResNet (CVPR'2016)
+- [x] ResNeXt (CVPR'2017)
+- [x] [HRNet (CVPR'2019)](configs/hrnet)
+- [x] [ResNeSt (ArXiv'2020)](configs/resnest)
+- [x] [MobileNetV2 (CVPR'2018)](configs/mobilenet_v2)
+- [x] [MobileNetV3 (ICCV'2019)](configs/mobilenet_v3)
+- [x] [Vision Transformer (ICLR'2021)](configs/vit)
+- [x] [Swin Transformer (ICCV'2021)](configs/swin)
+- [x] [Twins (NeurIPS'2021)](configs/twins)
+- [x] [BEiT (ICLR'2022)](configs/beit)
+- [x] [ConvNeXt (CVPR'2022)](configs/convnext)
+- [x] [MAE (CVPR'2022)](configs/mae)
+
+Supported methods:
+
+- [x] [FCN (CVPR'2015/TPAMI'2017)](configs/fcn)
+- [x] [ERFNet (T-ITS'2017)](configs/erfnet)
+- [x] [UNet (MICCAI'2016/Nat. Methods'2019)](configs/unet)
+- [x] [PSPNet (CVPR'2017)](configs/pspnet)
+- [x] [DeepLabV3 (ArXiv'2017)](configs/deeplabv3)
+- [x] [BiSeNetV1 (ECCV'2018)](configs/bisenetv1)
+- [x] [PSANet (ECCV'2018)](configs/psanet)
+- [x] [DeepLabV3+ (CVPR'2018)](configs/deeplabv3plus)
+- [x] [UPerNet (ECCV'2018)](configs/upernet)
+- [x] [ICNet (ECCV'2018)](configs/icnet)
+- [x] [NonLocal Net (CVPR'2018)](configs/nonlocal_net)
+- [x] [EncNet (CVPR'2018)](configs/encnet)
+- [x] [Semantic FPN (CVPR'2019)](configs/sem_fpn)
+- [x] [DANet (CVPR'2019)](configs/danet)
+- [x] [APCNet (CVPR'2019)](configs/apcnet)
+- [x] [EMANet (ICCV'2019)](configs/emanet)
+- [x] [CCNet (ICCV'2019)](configs/ccnet)
+- [x] [DMNet (ICCV'2019)](configs/dmnet)
+- [x] [ANN (ICCV'2019)](configs/ann)
+- [x] [GCNet (ICCVW'2019/TPAMI'2020)](configs/gcnet)
+- [x] [FastFCN (ArXiv'2019)](configs/fastfcn)
+- [x] [Fast-SCNN (ArXiv'2019)](configs/fastscnn)
+- [x] [ISANet (ArXiv'2019/IJCV'2021)](configs/isanet)
+- [x] [OCRNet (ECCV'2020)](configs/ocrnet)
+- [x] [DNLNet (ECCV'2020)](configs/dnlnet)
+- [x] [PointRend (CVPR'2020)](configs/point_rend)
+- [x] [CGNet (TIP'2020)](configs/cgnet)
+- [x] [BiSeNetV2 (IJCV'2021)](configs/bisenetv2)
+- [x] [STDC (CVPR'2021)](configs/stdc)
+- [x] [SETR (CVPR'2021)](configs/setr)
+- [x] [DPT (ArXiv'2021)](configs/dpt)
+- [x] [Segmenter (ICCV'2021)](configs/segmenter)
+- [x] [SegFormer (NeurIPS'2021)](configs/segformer)
+- [x] [K-Net (NeurIPS'2021)](configs/knet)
+
+Supported datasets:
+
+- [x] [Cityscapes](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/dataset_prepare.md#cityscapes)
+- [x] [PASCAL VOC](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/dataset_prepare.md#pascal-voc)
+- [x] [ADE20K](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/dataset_prepare.md#ade20k)
+- [x] [Pascal Context](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/dataset_prepare.md#pascal-context)
+- [x] [COCO-Stuff 10k](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/dataset_prepare.md#coco-stuff-10k)
+- [x] [COCO-Stuff 164k](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/dataset_prepare.md#coco-stuff-164k)
+- [x] [CHASE_DB1](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/dataset_prepare.md#chase-db1)
+- [x] [DRIVE](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/dataset_prepare.md#drive)
+- [x] [HRF](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/dataset_prepare.md#hrf)
+- [x] [STARE](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/dataset_prepare.md#stare)
+- [x] [Dark Zurich](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/dataset_prepare.md#dark-zurich)
+- [x] [Nighttime Driving](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/dataset_prepare.md#nighttime-driving)
+- [x] [LoveDA](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/dataset_prepare.md#loveda)
+- [x] [Potsdam](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/dataset_prepare.md#isprs-potsdam)
+- [x] [Vaihingen](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/dataset_prepare.md#isprs-vaihingen)
+- [x] [iSAID](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/dataset_prepare.md#isaid)
+
+## FAQ
+
+Please refer to [FAQ](docs/en/faq.md) for frequently asked questions.
+
+## Contributing
+
+We appreciate all contributions to improve MMSegmentation. Please refer to [CONTRIBUTING.md](.github/CONTRIBUTING.md) for the contributing guideline.
+
+## Acknowledgement
+
+MMSegmentation is an open source project that welcome any contribution and feedback.
+We wish that the toolbox and benchmark could serve the growing research
+community by providing a flexible as well as standardized toolkit to reimplement existing methods
+and develop their own new semantic segmentation methods.
+
+## Citation
+
+If you find this project useful in your research, please consider cite:
+
+```bibtex
+@misc{mmseg2020,
+ title={{MMSegmentation}: OpenMMLab Semantic Segmentation Toolbox and Benchmark},
+ author={MMSegmentation Contributors},
+ howpublished = {\url{https://github.com/open-mmlab/mmsegmentation}},
+ year={2020}
+}
+```
+
+## License
+
+MMSegmentation is released under the Apache 2.0 license, while some specific features in this library are with other licenses. Please refer to [LICENSES.md](LICENSES.md) for the careful check, if you are using our code for commercial matters.
+
+## Projects in OpenMMLab
+
+- [MMCV](https://github.com/open-mmlab/mmcv): OpenMMLab foundational library for computer vision.
+- [MIM](https://github.com/open-mmlab/mim): MIM installs OpenMMLab packages.
+- [MMClassification](https://github.com/open-mmlab/mmclassification): OpenMMLab image classification toolbox and benchmark.
+- [MMDetection](https://github.com/open-mmlab/mmdetection): OpenMMLab detection toolbox and benchmark.
+- [MMDetection3D](https://github.com/open-mmlab/mmdetection3d): OpenMMLab's next-generation platform for general 3D object detection.
+- [MMRotate](https://github.com/open-mmlab/mmrotate): OpenMMLab rotated object detection toolbox and benchmark.
+- [MMSegmentation](https://github.com/open-mmlab/mmsegmentation): OpenMMLab semantic segmentation toolbox and benchmark.
+- [MMOCR](https://github.com/open-mmlab/mmocr): OpenMMLab text detection, recognition, and understanding toolbox.
+- [MMPose](https://github.com/open-mmlab/mmpose): OpenMMLab pose estimation toolbox and benchmark.
+- [MMHuman3D](https://github.com/open-mmlab/mmhuman3d): OpenMMLab 3D human parametric model toolbox and benchmark.
+- [MMSelfSup](https://github.com/open-mmlab/mmselfsup): OpenMMLab self-supervised learning toolbox and benchmark.
+- [MMRazor](https://github.com/open-mmlab/mmrazor): OpenMMLab model compression toolbox and benchmark.
+- [MMFewShot](https://github.com/open-mmlab/mmfewshot): OpenMMLab fewshot learning toolbox and benchmark.
+- [MMAction2](https://github.com/open-mmlab/mmaction2): OpenMMLab's next-generation action understanding toolbox and benchmark.
+- [MMTracking](https://github.com/open-mmlab/mmtracking): OpenMMLab video perception toolbox and benchmark.
+- [MMFlow](https://github.com/open-mmlab/mmflow): OpenMMLab optical flow toolbox and benchmark.
+- [MMEditing](https://github.com/open-mmlab/mmediting): OpenMMLab image and video editing toolbox.
+- [MMGeneration](https://github.com/open-mmlab/mmgeneration): OpenMMLab image and video generative models toolbox.
+- [MMDeploy](https://github.com/open-mmlab/mmdeploy): OpenMMLab Model Deployment Framework.
diff --git a/EgoHOS/raw/script/mmsegmentation/cleanup_ckpt.py b/EgoHOS/raw/script/mmsegmentation/cleanup_ckpt.py
new file mode 100644
index 0000000000000000000000000000000000000000..2c5fa3859aa6cb3cb79704dd289b3504fd01a2fe
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/cleanup_ckpt.py
@@ -0,0 +1,19 @@
+import glob
+import pdb
+import os
+
+
+ckpt_dir = './work_dirs'
+
+for ckpt_file in glob.glob(ckpt_dir + '/**/*.pth'):
+
+ if 'best' in ckpt_file:
+ print('keep : ', ckpt_file)
+ else:
+ print('remove: ', ckpt_file)
+ os.remove(ckpt_file)
+
+
+
+
+
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..efc8b4bb20c981f3db6df7eb52b3dc0744c94cc0
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/ade20k.py
@@ -0,0 +1,54 @@
+# dataset settings
+dataset_type = 'ADE20KDataset'
+data_root = 'data/ade/ADEChallengeData2016'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (512, 512)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations', reduce_zero_label=True),
+ dict(type='Resize', img_scale=(2048, 512), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2048, 512),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=4,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/training',
+ ann_dir='annotations/training',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/validation',
+ ann_dir='annotations/validation',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/validation',
+ ann_dir='annotations/validation',
+ pipeline=test_pipeline))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/ade20k_640x640.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/ade20k_640x640.py
new file mode 100644
index 0000000000000000000000000000000000000000..14a4bb092f1db24eb871cd33fd98555cd814ef9c
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/ade20k_640x640.py
@@ -0,0 +1,54 @@
+# dataset settings
+dataset_type = 'ADE20KDataset'
+data_root = 'data/ade/ADEChallengeData2016'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (640, 640)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations', reduce_zero_label=True),
+ dict(type='Resize', img_scale=(2560, 640), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2560, 640),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=4,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/training',
+ ann_dir='annotations/training',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/validation',
+ ann_dir='annotations/validation',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/validation',
+ ann_dir='annotations/validation',
+ pipeline=test_pipeline))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/chase_db1.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/chase_db1.py
new file mode 100644
index 0000000000000000000000000000000000000000..298594ea925f87f22b37094a2ec50e370aec96a0
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/chase_db1.py
@@ -0,0 +1,59 @@
+# dataset settings
+dataset_type = 'ChaseDB1Dataset'
+data_root = 'data/CHASE_DB1'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+img_scale = (960, 999)
+crop_size = (128, 128)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=img_scale, ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg'])
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=img_scale,
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75, 2.0],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img'])
+ ])
+]
+
+data = dict(
+ samples_per_gpu=4,
+ workers_per_gpu=4,
+ train=dict(
+ type='RepeatDataset',
+ times=40000,
+ dataset=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/training',
+ ann_dir='annotations/training',
+ pipeline=train_pipeline)),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/validation',
+ ann_dir='annotations/validation',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/validation',
+ ann_dir='annotations/validation',
+ pipeline=test_pipeline))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..f21867c63e1835f6fceb61f066e802fd8fd2a735
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/cityscapes.py
@@ -0,0 +1,54 @@
+# dataset settings
+dataset_type = 'CityscapesDataset'
+data_root = 'data/cityscapes/'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (512, 1024)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=(2048, 1024), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2048, 1024),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=2,
+ workers_per_gpu=2,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='leftImg8bit/train',
+ ann_dir='gtFine/train',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='leftImg8bit/val',
+ ann_dir='gtFine/val',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='leftImg8bit/val',
+ ann_dir='gtFine/val',
+ pipeline=test_pipeline))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/cityscapes_1024x1024.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/cityscapes_1024x1024.py
new file mode 100644
index 0000000000000000000000000000000000000000..f98d929723b4539323ba6c9db867dfa4b01ffb22
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/cityscapes_1024x1024.py
@@ -0,0 +1,35 @@
+_base_ = './cityscapes.py'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (1024, 1024)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=(2048, 1024), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2048, 1024),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ train=dict(pipeline=train_pipeline),
+ val=dict(pipeline=test_pipeline),
+ test=dict(pipeline=test_pipeline))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/cityscapes_768x768.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/cityscapes_768x768.py
new file mode 100644
index 0000000000000000000000000000000000000000..fde9d7c7d8076dabff081fce0989eec6a6f5ff07
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/cityscapes_768x768.py
@@ -0,0 +1,35 @@
+_base_ = './cityscapes.py'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (768, 768)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=(2049, 1025), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2049, 1025),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ train=dict(pipeline=train_pipeline),
+ val=dict(pipeline=test_pipeline),
+ test=dict(pipeline=test_pipeline))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/cityscapes_769x769.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/cityscapes_769x769.py
new file mode 100644
index 0000000000000000000000000000000000000000..336c7b254fe392b4703039fec86a83acdbd2e1a5
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/cityscapes_769x769.py
@@ -0,0 +1,35 @@
+_base_ = './cityscapes.py'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (769, 769)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=(2049, 1025), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2049, 1025),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ train=dict(pipeline=train_pipeline),
+ val=dict(pipeline=test_pipeline),
+ test=dict(pipeline=test_pipeline))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/cityscapes_832x832.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/cityscapes_832x832.py
new file mode 100644
index 0000000000000000000000000000000000000000..b9325cc0087dffb0d3f51fe8a1ebcc45eb76b30d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/cityscapes_832x832.py
@@ -0,0 +1,35 @@
+_base_ = './cityscapes.py'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (832, 832)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=(2048, 1024), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2048, 1024),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ train=dict(pipeline=train_pipeline),
+ val=dict(pipeline=test_pipeline),
+ test=dict(pipeline=test_pipeline))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/coco-stuff10k.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/coco-stuff10k.py
new file mode 100644
index 0000000000000000000000000000000000000000..ec0496928b9464406a4013023c553cf3e7da526b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/coco-stuff10k.py
@@ -0,0 +1,57 @@
+# dataset settings
+dataset_type = 'COCOStuffDataset'
+data_root = 'data/coco_stuff10k'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (512, 512)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations', reduce_zero_label=True),
+ dict(type='Resize', img_scale=(2048, 512), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2048, 512),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=4,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ reduce_zero_label=True,
+ img_dir='images/train2014',
+ ann_dir='annotations/train2014',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ reduce_zero_label=True,
+ img_dir='images/test2014',
+ ann_dir='annotations/test2014',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ reduce_zero_label=True,
+ img_dir='images/test2014',
+ ann_dir='annotations/test2014',
+ pipeline=test_pipeline))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/coco-stuff164k.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/coco-stuff164k.py
new file mode 100644
index 0000000000000000000000000000000000000000..a6a38f2ac4d1a39d4a89bb101462d3ec805c3aff
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/coco-stuff164k.py
@@ -0,0 +1,54 @@
+# dataset settings
+dataset_type = 'COCOStuffDataset'
+data_root = 'data/coco_stuff164k'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (512, 512)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=(2048, 512), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2048, 512),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=4,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/train2017',
+ ann_dir='annotations/train2017',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/val2017',
+ ann_dir='annotations/val2017',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/val2017',
+ ann_dir='annotations/val2017',
+ pipeline=test_pipeline))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/drive.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/drive.py
new file mode 100644
index 0000000000000000000000000000000000000000..06e8ff606e0d2a4514ec8b7d2c6c436a32efcbf4
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/drive.py
@@ -0,0 +1,59 @@
+# dataset settings
+dataset_type = 'DRIVEDataset'
+data_root = 'data/DRIVE'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+img_scale = (584, 565)
+crop_size = (64, 64)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=img_scale, ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg'])
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=img_scale,
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75, 2.0],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img'])
+ ])
+]
+
+data = dict(
+ samples_per_gpu=4,
+ workers_per_gpu=4,
+ train=dict(
+ type='RepeatDataset',
+ times=40000,
+ dataset=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/training',
+ ann_dir='annotations/training',
+ pipeline=train_pipeline)),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/validation',
+ ann_dir='annotations/validation',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/validation',
+ ann_dir='annotations/validation',
+ pipeline=test_pipeline))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_cb.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_cb.py
new file mode 100644
index 0000000000000000000000000000000000000000..da2e5c3dc80af154185873925462380d2db24f87
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_cb.py
@@ -0,0 +1,59 @@
+# dataset settings
+dataset_type = 'EgoHOSDataset'
+data_root = '/mnt/session_space/home/lingzzha/EgoHOS/data'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (360, 480)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations', reduce_zero_label=False),
+ dict(type='Resize', img_scale=(360, 480), ratio_range=(1.0, 1.0)),
+ # dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=1.0),
+ dict(type='RandomFlip', prob=0.0),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(360, 480),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=16,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='train/image',
+ ann_dir='train/label_contact',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='val/image',
+ ann_dir='val/label_contact',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='test_indomain/image',
+ ann_dir='test_indomain/label_contact',
+ pipeline=test_pipeline))
+
+
+
+
+
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_cb_ccda.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_cb_ccda.py
new file mode 100644
index 0000000000000000000000000000000000000000..990768d41079011665173651e6e70aee9b8cccf7
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_cb_ccda.py
@@ -0,0 +1,59 @@
+# dataset settings
+dataset_type = 'EgoHOSDataset'
+data_root = '/mnt/session_space/home/lingzzha/EgoHOS/data'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (360, 480)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations', reduce_zero_label=False),
+ dict(type='Resize', img_scale=(360, 480), ratio_range=(1.0, 1.0)),
+ # dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=1.0),
+ dict(type='RandomFlip', prob=0.0),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(360, 480),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=16,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='train/image_ccda',
+ ann_dir='train/label_contact_ccda',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='val/image',
+ ann_dir='val/label_contact',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='test_indomain/image',
+ ann_dir='test_indomain/label_contact',
+ pipeline=test_pipeline))
+
+
+
+
+
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_handobj1.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_handobj1.py
new file mode 100644
index 0000000000000000000000000000000000000000..c15d173c48acd0c44ed8c65fc040d45f92dace64
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_handobj1.py
@@ -0,0 +1,59 @@
+# dataset settings
+dataset_type = 'EgoHOSDataset'
+data_root = '/mnt/session_space/home/lingzzha/EgoHOS/data'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (360, 480)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations', reduce_zero_label=False),
+ dict(type='Resize', img_scale=(360, 480), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(360, 480),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=16,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='train/image',
+ ann_dir='train/label_handobj1',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='test_outdomain/image',
+ ann_dir='test_outdomain/label_handobj1',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='test_indomain/image',
+ ann_dir='test_indomain/label_handobj1',
+ pipeline=test_pipeline))
+
+
+
+
+
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_handobj1_ccda.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_handobj1_ccda.py
new file mode 100644
index 0000000000000000000000000000000000000000..d930425698319d9ab8da0b7f4a5d79785e281d32
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_handobj1_ccda.py
@@ -0,0 +1,59 @@
+# dataset settings
+dataset_type = 'EgoHOSDataset'
+data_root = '/mnt/session_space/home/lingzzha/EgoHOS/data'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (360, 480)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations', reduce_zero_label=False),
+ dict(type='Resize', img_scale=(360, 480), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(360, 480),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=16,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='train/image_ccda',
+ ann_dir='train/label_handobj1_ccda',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='val/image',
+ ann_dir='val/label',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='test_indomain/image',
+ ann_dir='test_indomain/label',
+ pipeline=test_pipeline))
+
+
+
+
+
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_handobj2.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_handobj2.py
new file mode 100644
index 0000000000000000000000000000000000000000..28806b483fdede1f99acc819887ba7f3901d804c
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_handobj2.py
@@ -0,0 +1,59 @@
+# dataset settings
+dataset_type = 'EgoHOSDataset'
+data_root = '/mnt/session_space/home/lingzzha/EgoHOS/data'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (360, 480)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations', reduce_zero_label=False),
+ dict(type='Resize', img_scale=(360, 480), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(360, 480),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=16,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='train/image',
+ ann_dir='train/label',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='val/image',
+ ann_dir='val/label',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='test_indomain/image',
+ ann_dir='test_indomain/label',
+ pipeline=test_pipeline))
+
+
+
+
+
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_handobj2_ccda.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_handobj2_ccda.py
new file mode 100644
index 0000000000000000000000000000000000000000..23c23d937e61f7ac3cb26ea13f38dd20aea5dcc6
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_handobj2_ccda.py
@@ -0,0 +1,59 @@
+# dataset settings
+dataset_type = 'EgoHOSDataset'
+data_root = '/mnt/session_space/home/lingzzha/EgoHOS/data'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (360, 480)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations', reduce_zero_label=False),
+ dict(type='Resize', img_scale=(360, 480), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(360, 480),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=16,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='train/image_ccda',
+ ann_dir='train/label_handobj2_ccda',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='val/image',
+ ann_dir='val/label',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='test_indomain/image',
+ ann_dir='test_indomain/label',
+ pipeline=test_pipeline))
+
+
+
+
+
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_handobj2_subset.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_handobj2_subset.py
new file mode 100644
index 0000000000000000000000000000000000000000..f9ebfe36fd24552496a05a27616b7df793f9a6f8
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_handobj2_subset.py
@@ -0,0 +1,59 @@
+# dataset settings
+dataset_type = 'EgoHOSDataset'
+data_root = '/mnt/session_space/home/lingzzha/EgoHOS/data'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (360, 480)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations', reduce_zero_label=False),
+ dict(type='Resize', img_scale=(360, 480), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(360, 480),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=16,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='train/image_200',
+ ann_dir='train/label_200',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='val/image',
+ ann_dir='val/label',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='test_indomain/image',
+ ann_dir='test_indomain/label',
+ pipeline=test_pipeline))
+
+
+
+
+
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_obj1.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_obj1.py
new file mode 100644
index 0000000000000000000000000000000000000000..af0690d60a0fd2c5511e9d885b15ab050eedc5ce
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_obj1.py
@@ -0,0 +1,59 @@
+# dataset settings
+dataset_type = 'EgoHOSDataset'
+data_root = '/mnt/session_space/home/lingzzha/EgoHOS/data'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (360, 480)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations', reduce_zero_label=False),
+ dict(type='Resize', img_scale=(360, 480), ratio_range=(1.0, 1.0)),
+ # dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=1.0),
+ dict(type='RandomFlip', prob=0.0),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(360, 480),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=16,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='train/image',
+ ann_dir='train/label_obj1',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='val/image',
+ ann_dir='val/label_obj1',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='test_indomain/image',
+ ann_dir='test_indomain/label_obj1',
+ pipeline=test_pipeline))
+
+
+
+
+
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_obj1_ccda.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_obj1_ccda.py
new file mode 100644
index 0000000000000000000000000000000000000000..0d6eee54dbdc344581e20056d62ae8be5f4cecee
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_obj1_ccda.py
@@ -0,0 +1,59 @@
+# dataset settings
+dataset_type = 'EgoHOSDataset'
+data_root = '/mnt/session_space/home/lingzzha/EgoHOS/data'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (360, 480)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations', reduce_zero_label=False),
+ dict(type='Resize', img_scale=(360, 480), ratio_range=(1.0, 1.0)),
+ # dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=1.0),
+ dict(type='RandomFlip', prob=0.0),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(360, 480),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=16,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='train/image_ccda',
+ ann_dir='train/label_obj1_ccda',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='val/image',
+ ann_dir='val/label_obj1',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='test_indomain/image',
+ ann_dir='test_indomain/label_obj1',
+ pipeline=test_pipeline))
+
+
+
+
+
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_obj2.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_obj2.py
new file mode 100644
index 0000000000000000000000000000000000000000..a48cf2e3e6419e1d08a39f26a93e47430fb906e9
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_obj2.py
@@ -0,0 +1,59 @@
+# dataset settings
+dataset_type = 'EgoHOSDataset'
+data_root = '/mnt/session_space/home/lingzzha/EgoHOS/data'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (360, 480)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations', reduce_zero_label=False),
+ dict(type='Resize', img_scale=(360, 480), ratio_range=(1.0, 1.0)),
+ # dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=1.0),
+ dict(type='RandomFlip', prob=0.0),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(360, 480),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=16,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='train/image',
+ ann_dir='train/label_obj2',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='val/image',
+ ann_dir='val/label_obj2',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='test_indomain/image',
+ ann_dir='test_indomain/label_obj2',
+ pipeline=test_pipeline))
+
+
+
+
+
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_obj2_ccda.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_obj2_ccda.py
new file mode 100644
index 0000000000000000000000000000000000000000..7685028e0993ff39a5a5c68e207c703acd21d6a9
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_obj2_ccda.py
@@ -0,0 +1,59 @@
+# dataset settings
+dataset_type = 'EgoHOSDataset'
+data_root = '/mnt/session_space/home/lingzzha/EgoHOS/data'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (360, 480)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations', reduce_zero_label=False),
+ dict(type='Resize', img_scale=(360, 480), ratio_range=(1.0, 1.0)),
+ # dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=1.0),
+ dict(type='RandomFlip', prob=0.0),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(360, 480),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ # dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=16,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='train/image_ccda',
+ ann_dir='train/label_obj2_ccda',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='val/image',
+ ann_dir='val/label_obj2',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='test_indomain/image',
+ ann_dir='test_indomain/label_obj2',
+ pipeline=test_pipeline))
+
+
+
+
+
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_twohands.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_twohands.py
new file mode 100644
index 0000000000000000000000000000000000000000..d8a09e1a6ab14ac5e001af5f2fa0f959c9ba1f22
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_twohands.py
@@ -0,0 +1,59 @@
+# dataset settings
+dataset_type = 'EgoHOSDataset'
+data_root = '/mnt/session_space/home/lingzzha/EgoHOS/data'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (360, 480)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations', reduce_zero_label=False),
+ dict(type='Resize', img_scale=(360, 480), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(360, 480),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=16,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='train/image',
+ ann_dir='train/label_twohands',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='val/image',
+ ann_dir='val/label_twohands',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='test_indomain/image',
+ ann_dir='test_indomain/label_twohands',
+ pipeline=test_pipeline))
+
+
+
+
+
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_twohands_ccda.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_twohands_ccda.py
new file mode 100644
index 0000000000000000000000000000000000000000..756215ad74cf9929f5b20df69593fa22a59ec83c
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/egohos_twohands_ccda.py
@@ -0,0 +1,59 @@
+# dataset settings
+dataset_type = 'EgoHOSDataset'
+data_root = '/mnt/session_space/home/lingzzha/EgoHOS/data'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (360, 480)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations', reduce_zero_label=False),
+ dict(type='Resize', img_scale=(360, 480), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(360, 480),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=16,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='train/image_ccda',
+ ann_dir='train/label_twohands_ccda',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='val/image',
+ ann_dir='val/label',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='test_indomain/image',
+ ann_dir='test_indomain/label',
+ pipeline=test_pipeline))
+
+
+
+
+
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/hrf.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/hrf.py
new file mode 100644
index 0000000000000000000000000000000000000000..242d790eb1b83e75cf6b7eaa7a35c674099311ad
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/hrf.py
@@ -0,0 +1,59 @@
+# dataset settings
+dataset_type = 'HRFDataset'
+data_root = 'data/HRF'
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+img_scale = (2336, 3504)
+crop_size = (256, 256)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=img_scale, ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg'])
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=img_scale,
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75, 2.0],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img'])
+ ])
+]
+
+data = dict(
+ samples_per_gpu=4,
+ workers_per_gpu=4,
+ train=dict(
+ type='RepeatDataset',
+ times=40000,
+ dataset=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/training',
+ ann_dir='annotations/training',
+ pipeline=train_pipeline)),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/validation',
+ ann_dir='annotations/validation',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='images/validation',
+ ann_dir='annotations/validation',
+ pipeline=test_pipeline))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/isaid.py b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/isaid.py
new file mode 100644
index 0000000000000000000000000000000000000000..8e4c26abb703e07b0361eca68a862d7d869409da
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/_base_/datasets/isaid.py
@@ -0,0 +1,62 @@
+# dataset settings
+dataset_type = 'iSAIDDataset'
+data_root = 'data/iSAID'
+
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+"""
+This crop_size setting is followed by the implementation of
+`PointFlow: Flowing Semantics Through Points for Aerial Image
+Segmentation Major features
+ +- **Unified Benchmark** + + We provide a unified benchmark toolbox for various semantic segmentation methods. + +- **Modular Design** + + We decompose the semantic segmentation framework into different components and one can easily construct a customized semantic segmentation framework by combining different modules. + +- **Support of multiple methods out of box** + + The toolbox directly supports popular and contemporary semantic segmentation frameworks, *e.g.* PSPNet, DeepLabV3, PSANet, DeepLabV3+, etc. + +- **High efficiency** + + The training speed is faster than or comparable to other codebases. + +
+ +
+
+
+## Citation
+
+```bibtex
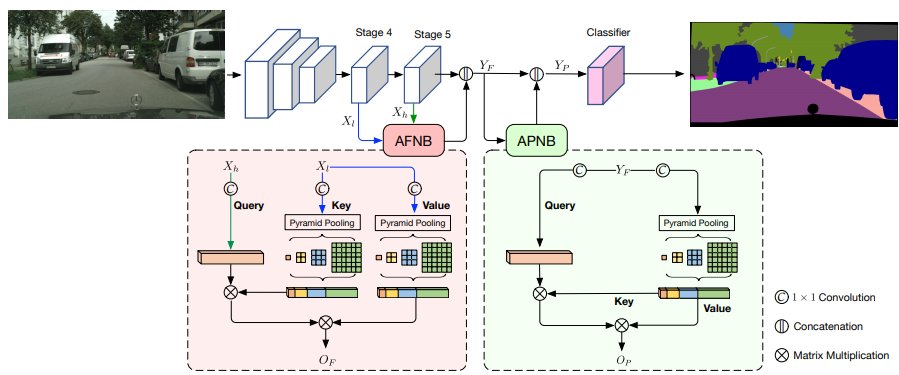
+@inproceedings{zhu2019asymmetric,
+ title={Asymmetric non-local neural networks for semantic segmentation},
+ author={Zhu, Zhen and Xu, Mengde and Bai, Song and Huang, Tengteng and Bai, Xiang},
+ booktitle={Proceedings of the IEEE/CVF International Conference on Computer Vision},
+ pages={593--602},
+ year={2019}
+}
+```
+
+
+## Results and models
+
+### Cityscapes
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| ------ | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | --------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
+| ANN | R-50-D8 | 512x1024 | 40000 | 6 | 3.71 | 77.40 | 78.57 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann/ann_r50-d8_512x1024_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x1024_40k_cityscapes/ann_r50-d8_512x1024_40k_cityscapes_20200605_095211-049fc292.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x1024_40k_cityscapes/ann_r50-d8_512x1024_40k_cityscapes_20200605_095211.log.json) |
+| ANN | R-101-D8 | 512x1024 | 40000 | 9.5 | 2.55 | 76.55 | 78.85 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann/ann_r101-d8_512x1024_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x1024_40k_cityscapes/ann_r101-d8_512x1024_40k_cityscapes_20200605_095243-adf6eece.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x1024_40k_cityscapes/ann_r101-d8_512x1024_40k_cityscapes_20200605_095243.log.json) |
+| ANN | R-50-D8 | 769x769 | 40000 | 6.8 | 1.70 | 78.89 | 80.46 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann/ann_r50-d8_769x769_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_769x769_40k_cityscapes/ann_r50-d8_769x769_40k_cityscapes_20200530_025712-2b46b04d.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_769x769_40k_cityscapes/ann_r50-d8_769x769_40k_cityscapes_20200530_025712.log.json) |
+| ANN | R-101-D8 | 769x769 | 40000 | 10.7 | 1.15 | 79.32 | 80.94 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann/ann_r101-d8_769x769_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_769x769_40k_cityscapes/ann_r101-d8_769x769_40k_cityscapes_20200530_025720-059bff28.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_769x769_40k_cityscapes/ann_r101-d8_769x769_40k_cityscapes_20200530_025720.log.json) |
+| ANN | R-50-D8 | 512x1024 | 80000 | - | - | 77.34 | 78.65 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann/ann_r50-d8_512x1024_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x1024_80k_cityscapes/ann_r50-d8_512x1024_80k_cityscapes_20200607_101911-5a9ad545.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x1024_80k_cityscapes/ann_r50-d8_512x1024_80k_cityscapes_20200607_101911.log.json) |
+| ANN | R-101-D8 | 512x1024 | 80000 | - | - | 77.14 | 78.81 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann/ann_r101-d8_512x1024_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x1024_80k_cityscapes/ann_r101-d8_512x1024_80k_cityscapes_20200607_013728-aceccc6e.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x1024_80k_cityscapes/ann_r101-d8_512x1024_80k_cityscapes_20200607_013728.log.json) |
+| ANN | R-50-D8 | 769x769 | 80000 | - | - | 78.88 | 80.57 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann/ann_r50-d8_769x769_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_769x769_80k_cityscapes/ann_r50-d8_769x769_80k_cityscapes_20200607_044426-cc7ff323.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_769x769_80k_cityscapes/ann_r50-d8_769x769_80k_cityscapes_20200607_044426.log.json) |
+| ANN | R-101-D8 | 769x769 | 80000 | - | - | 78.80 | 80.34 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann/ann_r101-d8_769x769_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_769x769_80k_cityscapes/ann_r101-d8_769x769_80k_cityscapes_20200607_013713-a9d4be8d.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_769x769_80k_cityscapes/ann_r101-d8_769x769_80k_cityscapes_20200607_013713.log.json) |
+
+### ADE20K
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| ------ | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | ----------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
+| ANN | R-50-D8 | 512x512 | 80000 | 9.1 | 21.01 | 41.01 | 42.30 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann/ann_r50-d8_512x512_80k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x512_80k_ade20k/ann_r50-d8_512x512_80k_ade20k_20200615_014818-26f75e11.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x512_80k_ade20k/ann_r50-d8_512x512_80k_ade20k_20200615_014818.log.json) |
+| ANN | R-101-D8 | 512x512 | 80000 | 12.5 | 14.12 | 42.94 | 44.18 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann/ann_r101-d8_512x512_80k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x512_80k_ade20k/ann_r101-d8_512x512_80k_ade20k_20200615_014818-c0153543.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x512_80k_ade20k/ann_r101-d8_512x512_80k_ade20k_20200615_014818.log.json) |
+| ANN | R-50-D8 | 512x512 | 160000 | - | - | 41.74 | 42.62 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann/ann_r50-d8_512x512_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x512_160k_ade20k/ann_r50-d8_512x512_160k_ade20k_20200615_231733-892247bc.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x512_160k_ade20k/ann_r50-d8_512x512_160k_ade20k_20200615_231733.log.json) |
+| ANN | R-101-D8 | 512x512 | 160000 | - | - | 42.94 | 44.06 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann/ann_r101-d8_512x512_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x512_160k_ade20k/ann_r101-d8_512x512_160k_ade20k_20200615_231733-955eb1ec.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x512_160k_ade20k/ann_r101-d8_512x512_160k_ade20k_20200615_231733.log.json) |
+
+### Pascal VOC 2012 + Aug
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| ------ | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | ------------------------------------------------------------------------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
+| ANN | R-50-D8 | 512x512 | 20000 | 6 | 20.92 | 74.86 | 76.13 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann/ann_r50-d8_512x512_20k_voc12aug.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x512_20k_voc12aug/ann_r50-d8_512x512_20k_voc12aug_20200617_222246-dfcb1c62.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x512_20k_voc12aug/ann_r50-d8_512x512_20k_voc12aug_20200617_222246.log.json) |
+| ANN | R-101-D8 | 512x512 | 20000 | 9.5 | 13.94 | 77.47 | 78.70 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann/ann_r101-d8_512x512_20k_voc12aug.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x512_20k_voc12aug/ann_r101-d8_512x512_20k_voc12aug_20200617_222246-2fad0042.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x512_20k_voc12aug/ann_r101-d8_512x512_20k_voc12aug_20200617_222246.log.json) |
+| ANN | R-50-D8 | 512x512 | 40000 | - | - | 76.56 | 77.51 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann/ann_r50-d8_512x512_40k_voc12aug.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x512_40k_voc12aug/ann_r50-d8_512x512_40k_voc12aug_20200613_231314-b5dac322.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x512_40k_voc12aug/ann_r50-d8_512x512_40k_voc12aug_20200613_231314.log.json) |
+| ANN | R-101-D8 | 512x512 | 40000 | - | - | 76.70 | 78.06 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann/ann_r101-d8_512x512_40k_voc12aug.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x512_40k_voc12aug/ann_r101-d8_512x512_40k_voc12aug_20200613_231314-bd205bbe.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x512_40k_voc12aug/ann_r101-d8_512x512_40k_voc12aug_20200613_231314.log.json) |
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ann/ann.yml b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann.yml
new file mode 100644
index 0000000000000000000000000000000000000000..ff6bea653b231ce98f79263b24d9912ca23a5eee
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann.yml
@@ -0,0 +1,305 @@
+Collections:
+- Name: ANN
+ Metadata:
+ Training Data:
+ - Cityscapes
+ - ADE20K
+ - Pascal VOC 2012 + Aug
+ Paper:
+ URL: https://arxiv.org/abs/1908.07678
+ Title: Asymmetric Non-local Neural Networks for Semantic Segmentation
+ README: configs/ann/README.md
+ Code:
+ URL: https://github.com/open-mmlab/mmsegmentation/blob/v0.17.0/mmseg/models/decode_heads/ann_head.py#L185
+ Version: v0.17.0
+ Converted From:
+ Code: https://github.com/MendelXu/ANN
+Models:
+- Name: ann_r50-d8_512x1024_40k_cityscapes
+ In Collection: ANN
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,1024)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 269.54
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,1024)
+ Training Memory (GB): 6.0
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 77.4
+ mIoU(ms+flip): 78.57
+ Config: configs/ann/ann_r50-d8_512x1024_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x1024_40k_cityscapes/ann_r50-d8_512x1024_40k_cityscapes_20200605_095211-049fc292.pth
+- Name: ann_r101-d8_512x1024_40k_cityscapes
+ In Collection: ANN
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,1024)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 392.16
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,1024)
+ Training Memory (GB): 9.5
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 76.55
+ mIoU(ms+flip): 78.85
+ Config: configs/ann/ann_r101-d8_512x1024_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x1024_40k_cityscapes/ann_r101-d8_512x1024_40k_cityscapes_20200605_095243-adf6eece.pth
+- Name: ann_r50-d8_769x769_40k_cityscapes
+ In Collection: ANN
+ Metadata:
+ backbone: R-50-D8
+ crop size: (769,769)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 588.24
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (769,769)
+ Training Memory (GB): 6.8
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 78.89
+ mIoU(ms+flip): 80.46
+ Config: configs/ann/ann_r50-d8_769x769_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_769x769_40k_cityscapes/ann_r50-d8_769x769_40k_cityscapes_20200530_025712-2b46b04d.pth
+- Name: ann_r101-d8_769x769_40k_cityscapes
+ In Collection: ANN
+ Metadata:
+ backbone: R-101-D8
+ crop size: (769,769)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 869.57
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (769,769)
+ Training Memory (GB): 10.7
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 79.32
+ mIoU(ms+flip): 80.94
+ Config: configs/ann/ann_r101-d8_769x769_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_769x769_40k_cityscapes/ann_r101-d8_769x769_40k_cityscapes_20200530_025720-059bff28.pth
+- Name: ann_r50-d8_512x1024_80k_cityscapes
+ In Collection: ANN
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,1024)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 77.34
+ mIoU(ms+flip): 78.65
+ Config: configs/ann/ann_r50-d8_512x1024_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x1024_80k_cityscapes/ann_r50-d8_512x1024_80k_cityscapes_20200607_101911-5a9ad545.pth
+- Name: ann_r101-d8_512x1024_80k_cityscapes
+ In Collection: ANN
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,1024)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 77.14
+ mIoU(ms+flip): 78.81
+ Config: configs/ann/ann_r101-d8_512x1024_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x1024_80k_cityscapes/ann_r101-d8_512x1024_80k_cityscapes_20200607_013728-aceccc6e.pth
+- Name: ann_r50-d8_769x769_80k_cityscapes
+ In Collection: ANN
+ Metadata:
+ backbone: R-50-D8
+ crop size: (769,769)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 78.88
+ mIoU(ms+flip): 80.57
+ Config: configs/ann/ann_r50-d8_769x769_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_769x769_80k_cityscapes/ann_r50-d8_769x769_80k_cityscapes_20200607_044426-cc7ff323.pth
+- Name: ann_r101-d8_769x769_80k_cityscapes
+ In Collection: ANN
+ Metadata:
+ backbone: R-101-D8
+ crop size: (769,769)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 78.8
+ mIoU(ms+flip): 80.34
+ Config: configs/ann/ann_r101-d8_769x769_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_769x769_80k_cityscapes/ann_r101-d8_769x769_80k_cityscapes_20200607_013713-a9d4be8d.pth
+- Name: ann_r50-d8_512x512_80k_ade20k
+ In Collection: ANN
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 47.6
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 9.1
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 41.01
+ mIoU(ms+flip): 42.3
+ Config: configs/ann/ann_r50-d8_512x512_80k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x512_80k_ade20k/ann_r50-d8_512x512_80k_ade20k_20200615_014818-26f75e11.pth
+- Name: ann_r101-d8_512x512_80k_ade20k
+ In Collection: ANN
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 70.82
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 12.5
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 42.94
+ mIoU(ms+flip): 44.18
+ Config: configs/ann/ann_r101-d8_512x512_80k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x512_80k_ade20k/ann_r101-d8_512x512_80k_ade20k_20200615_014818-c0153543.pth
+- Name: ann_r50-d8_512x512_160k_ade20k
+ In Collection: ANN
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 160000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 41.74
+ mIoU(ms+flip): 42.62
+ Config: configs/ann/ann_r50-d8_512x512_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x512_160k_ade20k/ann_r50-d8_512x512_160k_ade20k_20200615_231733-892247bc.pth
+- Name: ann_r101-d8_512x512_160k_ade20k
+ In Collection: ANN
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 160000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 42.94
+ mIoU(ms+flip): 44.06
+ Config: configs/ann/ann_r101-d8_512x512_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x512_160k_ade20k/ann_r101-d8_512x512_160k_ade20k_20200615_231733-955eb1ec.pth
+- Name: ann_r50-d8_512x512_20k_voc12aug
+ In Collection: ANN
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 20000
+ inference time (ms/im):
+ - value: 47.8
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 6.0
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal VOC 2012 + Aug
+ Metrics:
+ mIoU: 74.86
+ mIoU(ms+flip): 76.13
+ Config: configs/ann/ann_r50-d8_512x512_20k_voc12aug.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x512_20k_voc12aug/ann_r50-d8_512x512_20k_voc12aug_20200617_222246-dfcb1c62.pth
+- Name: ann_r101-d8_512x512_20k_voc12aug
+ In Collection: ANN
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 20000
+ inference time (ms/im):
+ - value: 71.74
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 9.5
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal VOC 2012 + Aug
+ Metrics:
+ mIoU: 77.47
+ mIoU(ms+flip): 78.7
+ Config: configs/ann/ann_r101-d8_512x512_20k_voc12aug.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x512_20k_voc12aug/ann_r101-d8_512x512_20k_voc12aug_20200617_222246-2fad0042.pth
+- Name: ann_r50-d8_512x512_40k_voc12aug
+ In Collection: ANN
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 40000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal VOC 2012 + Aug
+ Metrics:
+ mIoU: 76.56
+ mIoU(ms+flip): 77.51
+ Config: configs/ann/ann_r50-d8_512x512_40k_voc12aug.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r50-d8_512x512_40k_voc12aug/ann_r50-d8_512x512_40k_voc12aug_20200613_231314-b5dac322.pth
+- Name: ann_r101-d8_512x512_40k_voc12aug
+ In Collection: ANN
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 40000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal VOC 2012 + Aug
+ Metrics:
+ mIoU: 76.7
+ mIoU(ms+flip): 78.06
+ Config: configs/ann/ann_r101-d8_512x512_40k_voc12aug.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ann/ann_r101-d8_512x512_40k_voc12aug/ann_r101-d8_512x512_40k_voc12aug_20200613_231314-bd205bbe.pth
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x1024_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x1024_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..d494e07333217e0c6830d36d1bb58fa78b03cfb0
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x1024_40k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './ann_r50-d8_512x1024_40k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x1024_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x1024_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..1eeff0b030cf1db8c6ec9740fa65db44b2026d58
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x1024_80k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './ann_r50-d8_512x1024_80k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x512_160k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x512_160k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..9e43af541f6e3df3f36479e736bb0c03fc916970
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x512_160k_ade20k.py
@@ -0,0 +1,2 @@
+_base_ = './ann_r50-d8_512x512_160k_ade20k.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x512_20k_voc12aug.py b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x512_20k_voc12aug.py
new file mode 100644
index 0000000000000000000000000000000000000000..d854f2e4223731f443369febc500dbccdc524d9d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x512_20k_voc12aug.py
@@ -0,0 +1,2 @@
+_base_ = './ann_r50-d8_512x512_20k_voc12aug.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x512_40k_voc12aug.py b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x512_40k_voc12aug.py
new file mode 100644
index 0000000000000000000000000000000000000000..893c53b1ca4bf9788e4d94f0f53cfe92a93f48ce
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x512_40k_voc12aug.py
@@ -0,0 +1,2 @@
+_base_ = './ann_r50-d8_512x512_40k_voc12aug.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x512_80k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x512_80k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..a64dac670ed4d4632e7b9791ec5f8a334dcea78e
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_512x512_80k_ade20k.py
@@ -0,0 +1,2 @@
+_base_ = './ann_r50-d8_512x512_80k_ade20k.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_769x769_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_769x769_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..59508248490b3edbac1c46b4fcc7891f99655b9b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_769x769_40k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './ann_r50-d8_769x769_40k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_769x769_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_769x769_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..a9c712d1ccfd62ddf6f12ff01ea347ca1995013b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r101-d8_769x769_80k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './ann_r50-d8_769x769_80k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x1024_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x1024_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..00b2594ba8a1c9edc90cca7a6d7c3334fa209edc
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x1024_40k_cityscapes.py
@@ -0,0 +1,4 @@
+_base_ = [
+ '../_base_/models/ann_r50-d8.py', '../_base_/datasets/cityscapes.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_40k.py'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x1024_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x1024_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..ef7b369dd9e12b2282a30da14f99dd4547c53a7b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x1024_80k_cityscapes.py
@@ -0,0 +1,4 @@
+_base_ = [
+ '../_base_/models/ann_r50-d8.py', '../_base_/datasets/cityscapes.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_80k.py'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x512_160k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x512_160k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..ca6bb248ac867d463c274f975c884aa80a57730f
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x512_160k_ade20k.py
@@ -0,0 +1,6 @@
+_base_ = [
+ '../_base_/models/ann_r50-d8.py', '../_base_/datasets/ade20k.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_160k.py'
+]
+model = dict(
+ decode_head=dict(num_classes=150), auxiliary_head=dict(num_classes=150))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x512_20k_voc12aug.py b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x512_20k_voc12aug.py
new file mode 100644
index 0000000000000000000000000000000000000000..071f190261c4e8f4a80a5da12a88e0cfcdfef0d8
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x512_20k_voc12aug.py
@@ -0,0 +1,6 @@
+_base_ = [
+ '../_base_/models/ann_r50-d8.py', '../_base_/datasets/pascal_voc12_aug.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_20k.py'
+]
+model = dict(
+ decode_head=dict(num_classes=21), auxiliary_head=dict(num_classes=21))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x512_40k_voc12aug.py b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x512_40k_voc12aug.py
new file mode 100644
index 0000000000000000000000000000000000000000..82a1c9386c51fb0ada436e51702beb961a534b26
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x512_40k_voc12aug.py
@@ -0,0 +1,6 @@
+_base_ = [
+ '../_base_/models/ann_r50-d8.py', '../_base_/datasets/pascal_voc12_aug.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_40k.py'
+]
+model = dict(
+ decode_head=dict(num_classes=21), auxiliary_head=dict(num_classes=21))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x512_80k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x512_80k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..5e04aa7c6ac050d119e07b715e2082f692e1a1de
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_512x512_80k_ade20k.py
@@ -0,0 +1,6 @@
+_base_ = [
+ '../_base_/models/ann_r50-d8.py', '../_base_/datasets/ade20k.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_80k.py'
+]
+model = dict(
+ decode_head=dict(num_classes=150), auxiliary_head=dict(num_classes=150))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_769x769_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_769x769_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..4912bdb9fb298518ae084eb7df0ad22d3e4ff84f
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_769x769_40k_cityscapes.py
@@ -0,0 +1,9 @@
+_base_ = [
+ '../_base_/models/ann_r50-d8.py',
+ '../_base_/datasets/cityscapes_769x769.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_40k.py'
+]
+model = dict(
+ decode_head=dict(align_corners=True),
+ auxiliary_head=dict(align_corners=True),
+ test_cfg=dict(mode='slide', crop_size=(769, 769), stride=(513, 513)))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_769x769_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_769x769_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..d1cc072b152986102286f503e3d7b92999bf414c
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ann/ann_r50-d8_769x769_80k_cityscapes.py
@@ -0,0 +1,9 @@
+_base_ = [
+ '../_base_/models/ann_r50-d8.py',
+ '../_base_/datasets/cityscapes_769x769.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_80k.py'
+]
+model = dict(
+ decode_head=dict(align_corners=True),
+ auxiliary_head=dict(align_corners=True),
+ test_cfg=dict(mode='slide', crop_size=(769, 769), stride=(513, 513)))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/apcnet/README.md b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..5e1fd6b4201622df972e0cb120925a6856b0c672
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/README.md
@@ -0,0 +1,58 @@
+# APCNet
+
+[Adaptive Pyramid Context Network for Semantic Segmentation](https://openaccess.thecvf.com/content_CVPR_2019/html/He_Adaptive_Pyramid_Context_Network_for_Semantic_Segmentation_CVPR_2019_paper.html)
+
+## Introduction
+
+
+
+Official Repo
+
+Code Snippet
+
+## Abstract
+
+
+
+Recent studies witnessed that context features can significantly improve the performance of deep semantic segmentation networks. Current context based segmentation methods differ with each other in how to construct context features and perform differently in practice. This paper firstly introduces three desirable properties of context features in segmentation task. Specially, we find that Global-guided Local Affinity (GLA) can play a vital role in constructing effective context features, while this property has been largely ignored in previous works. Based on this analysis, this paper proposes Adaptive Pyramid Context Network (APCNet)for semantic segmentation. APCNet adaptively constructs multi-scale contextual representations with multiple welldesigned Adaptive Context Modules (ACMs). Specifically, each ACM leverages a global image representation as a guidance to estimate the local affinity coefficients for each sub-region, and then calculates a context vector with these affinities. We empirically evaluate our APCNet on three semantic segmentation and scene parsing datasets, including PASCAL VOC 2012, Pascal-Context, and ADE20K dataset. Experimental results show that APCNet achieves state-ofthe-art performance on all three benchmarks, and obtains a new record 84.2% on PASCAL VOC 2012 test set without MS COCO pre-trained and any post-processing.
+
+
+
+
+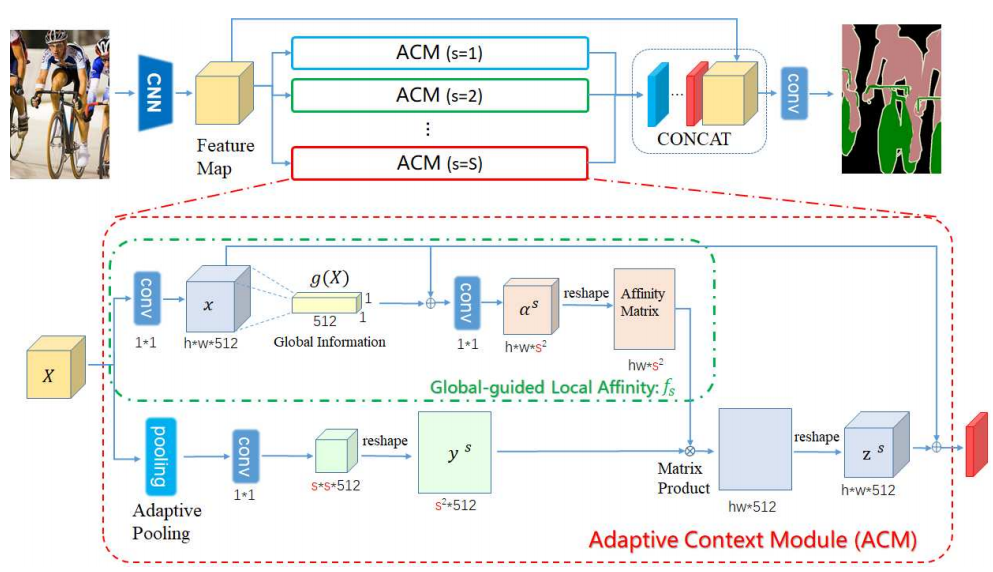 +
+
+## Citation
+
+```bibtex
+@InProceedings{He_2019_CVPR,
+author = {He, Junjun and Deng, Zhongying and Zhou, Lei and Wang, Yali and Qiao, Yu},
+title = {Adaptive Pyramid Context Network for Semantic Segmentation},
+booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
+month = {June},
+year = {2019}
+}
+```
+
+## Results and models
+
+### Cityscapes
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| ------ | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | --------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
+| APCNet | R-50-D8 | 512x1024 | 40000 | 7.7 | 3.57 | 78.02 | 79.26 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/apcnet/apcnet_r50-d8_512x1024_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_512x1024_40k_cityscapes/apcnet_r50-d8_512x1024_40k_cityscapes_20201214_115717-5e88fa33.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_512x1024_40k_cityscapes/apcnet_r50-d8_512x1024_40k_cityscapes-20201214_115717.log.json) |
+| APCNet | R-101-D8 | 512x1024 | 40000 | 11.2 | 2.15 | 79.08 | 80.34 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/apcnet/apcnet_r101-d8_512x1024_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_512x1024_40k_cityscapes/apcnet_r101-d8_512x1024_40k_cityscapes_20201214_115716-abc9d111.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_512x1024_40k_cityscapes/apcnet_r101-d8_512x1024_40k_cityscapes-20201214_115716.log.json) |
+| APCNet | R-50-D8 | 769x769 | 40000 | 8.7 | 1.52 | 77.89 | 79.75 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/apcnet/apcnet_r50-d8_769x769_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_769x769_40k_cityscapes/apcnet_r50-d8_769x769_40k_cityscapes_20201214_115717-2a2628d7.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_769x769_40k_cityscapes/apcnet_r50-d8_769x769_40k_cityscapes-20201214_115717.log.json) |
+| APCNet | R-101-D8 | 769x769 | 40000 | 12.7 | 1.03 | 77.96 | 79.24 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/apcnet/apcnet_r101-d8_769x769_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_769x769_40k_cityscapes/apcnet_r101-d8_769x769_40k_cityscapes_20201214_115718-b650de90.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_769x769_40k_cityscapes/apcnet_r101-d8_769x769_40k_cityscapes-20201214_115718.log.json) |
+| APCNet | R-50-D8 | 512x1024 | 80000 | - | - | 78.96 | 79.94 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/apcnet/apcnet_r50-d8_512x1024_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_512x1024_80k_cityscapes/apcnet_r50-d8_512x1024_80k_cityscapes_20201214_115716-987f51e3.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_512x1024_80k_cityscapes/apcnet_r50-d8_512x1024_80k_cityscapes-20201214_115716.log.json) |
+| APCNet | R-101-D8 | 512x1024 | 80000 | - | - | 79.64 | 80.61 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/apcnet/apcnet_r101-d8_512x1024_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_512x1024_80k_cityscapes/apcnet_r101-d8_512x1024_80k_cityscapes_20201214_115705-b1ff208a.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_512x1024_80k_cityscapes/apcnet_r101-d8_512x1024_80k_cityscapes-20201214_115705.log.json) |
+| APCNet | R-50-D8 | 769x769 | 80000 | - | - | 78.79 | 80.35 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/apcnet/apcnet_r50-d8_769x769_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_769x769_80k_cityscapes/apcnet_r50-d8_769x769_80k_cityscapes_20201214_115718-7ea9fa12.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_769x769_80k_cityscapes/apcnet_r50-d8_769x769_80k_cityscapes-20201214_115718.log.json) |
+| APCNet | R-101-D8 | 769x769 | 80000 | - | - | 78.45 | 79.91 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/apcnet/apcnet_r101-d8_769x769_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_769x769_80k_cityscapes/apcnet_r101-d8_769x769_80k_cityscapes_20201214_115716-a7fbc2ab.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_769x769_80k_cityscapes/apcnet_r101-d8_769x769_80k_cityscapes-20201214_115716.log.json) |
+
+### ADE20K
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| ------ | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | ----------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
+| APCNet | R-50-D8 | 512x512 | 80000 | 10.1 | 19.61 | 42.20 | 43.30 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/apcnet/apcnet_r50-d8_512x512_80k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_512x512_80k_ade20k/apcnet_r50-d8_512x512_80k_ade20k_20201214_115705-a8626293.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_512x512_80k_ade20k/apcnet_r50-d8_512x512_80k_ade20k-20201214_115705.log.json) |
+| APCNet | R-101-D8 | 512x512 | 80000 | 13.6 | 13.10 | 45.54 | 46.65 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/apcnet/apcnet_r101-d8_512x512_80k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_512x512_80k_ade20k/apcnet_r101-d8_512x512_80k_ade20k_20201214_115704-c656c3fb.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_512x512_80k_ade20k/apcnet_r101-d8_512x512_80k_ade20k-20201214_115704.log.json) |
+| APCNet | R-50-D8 | 512x512 | 160000 | - | - | 43.40 | 43.94 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/apcnet/apcnet_r50-d8_512x512_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_512x512_160k_ade20k/apcnet_r50-d8_512x512_160k_ade20k_20201214_115706-25fb92c2.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_512x512_160k_ade20k/apcnet_r50-d8_512x512_160k_ade20k-20201214_115706.log.json) |
+| APCNet | R-101-D8 | 512x512 | 160000 | - | - | 45.41 | 46.63 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/apcnet/apcnet_r101-d8_512x512_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_512x512_160k_ade20k/apcnet_r101-d8_512x512_160k_ade20k_20201214_115705-73f9a8d7.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_512x512_160k_ade20k/apcnet_r101-d8_512x512_160k_ade20k-20201214_115705.log.json) |
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet.yml b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet.yml
new file mode 100644
index 0000000000000000000000000000000000000000..7a453a36072ed7b3df6fdfbf8db884a783d055e7
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet.yml
@@ -0,0 +1,232 @@
+Collections:
+- Name: APCNet
+ Metadata:
+ Training Data:
+ - Cityscapes
+ - ADE20K
+ Paper:
+ URL: https://openaccess.thecvf.com/content_CVPR_2019/html/He_Adaptive_Pyramid_Context_Network_for_Semantic_Segmentation_CVPR_2019_paper.html
+ Title: Adaptive Pyramid Context Network for Semantic Segmentation
+ README: configs/apcnet/README.md
+ Code:
+ URL: https://github.com/open-mmlab/mmsegmentation/blob/v0.17.0/mmseg/models/decode_heads/apc_head.py#L111
+ Version: v0.17.0
+ Converted From:
+ Code: https://github.com/Junjun2016/APCNet
+Models:
+- Name: apcnet_r50-d8_512x1024_40k_cityscapes
+ In Collection: APCNet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,1024)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 280.11
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,1024)
+ Training Memory (GB): 7.7
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 78.02
+ mIoU(ms+flip): 79.26
+ Config: configs/apcnet/apcnet_r50-d8_512x1024_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_512x1024_40k_cityscapes/apcnet_r50-d8_512x1024_40k_cityscapes_20201214_115717-5e88fa33.pth
+- Name: apcnet_r101-d8_512x1024_40k_cityscapes
+ In Collection: APCNet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,1024)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 465.12
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,1024)
+ Training Memory (GB): 11.2
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 79.08
+ mIoU(ms+flip): 80.34
+ Config: configs/apcnet/apcnet_r101-d8_512x1024_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_512x1024_40k_cityscapes/apcnet_r101-d8_512x1024_40k_cityscapes_20201214_115716-abc9d111.pth
+- Name: apcnet_r50-d8_769x769_40k_cityscapes
+ In Collection: APCNet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (769,769)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 657.89
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (769,769)
+ Training Memory (GB): 8.7
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 77.89
+ mIoU(ms+flip): 79.75
+ Config: configs/apcnet/apcnet_r50-d8_769x769_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_769x769_40k_cityscapes/apcnet_r50-d8_769x769_40k_cityscapes_20201214_115717-2a2628d7.pth
+- Name: apcnet_r101-d8_769x769_40k_cityscapes
+ In Collection: APCNet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (769,769)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 970.87
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (769,769)
+ Training Memory (GB): 12.7
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 77.96
+ mIoU(ms+flip): 79.24
+ Config: configs/apcnet/apcnet_r101-d8_769x769_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_769x769_40k_cityscapes/apcnet_r101-d8_769x769_40k_cityscapes_20201214_115718-b650de90.pth
+- Name: apcnet_r50-d8_512x1024_80k_cityscapes
+ In Collection: APCNet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,1024)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 78.96
+ mIoU(ms+flip): 79.94
+ Config: configs/apcnet/apcnet_r50-d8_512x1024_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_512x1024_80k_cityscapes/apcnet_r50-d8_512x1024_80k_cityscapes_20201214_115716-987f51e3.pth
+- Name: apcnet_r101-d8_512x1024_80k_cityscapes
+ In Collection: APCNet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,1024)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 79.64
+ mIoU(ms+flip): 80.61
+ Config: configs/apcnet/apcnet_r101-d8_512x1024_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_512x1024_80k_cityscapes/apcnet_r101-d8_512x1024_80k_cityscapes_20201214_115705-b1ff208a.pth
+- Name: apcnet_r50-d8_769x769_80k_cityscapes
+ In Collection: APCNet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (769,769)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 78.79
+ mIoU(ms+flip): 80.35
+ Config: configs/apcnet/apcnet_r50-d8_769x769_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_769x769_80k_cityscapes/apcnet_r50-d8_769x769_80k_cityscapes_20201214_115718-7ea9fa12.pth
+- Name: apcnet_r101-d8_769x769_80k_cityscapes
+ In Collection: APCNet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (769,769)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 78.45
+ mIoU(ms+flip): 79.91
+ Config: configs/apcnet/apcnet_r101-d8_769x769_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_769x769_80k_cityscapes/apcnet_r101-d8_769x769_80k_cityscapes_20201214_115716-a7fbc2ab.pth
+- Name: apcnet_r50-d8_512x512_80k_ade20k
+ In Collection: APCNet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 50.99
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 10.1
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 42.2
+ mIoU(ms+flip): 43.3
+ Config: configs/apcnet/apcnet_r50-d8_512x512_80k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_512x512_80k_ade20k/apcnet_r50-d8_512x512_80k_ade20k_20201214_115705-a8626293.pth
+- Name: apcnet_r101-d8_512x512_80k_ade20k
+ In Collection: APCNet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 76.34
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 13.6
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 45.54
+ mIoU(ms+flip): 46.65
+ Config: configs/apcnet/apcnet_r101-d8_512x512_80k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_512x512_80k_ade20k/apcnet_r101-d8_512x512_80k_ade20k_20201214_115704-c656c3fb.pth
+- Name: apcnet_r50-d8_512x512_160k_ade20k
+ In Collection: APCNet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 160000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 43.4
+ mIoU(ms+flip): 43.94
+ Config: configs/apcnet/apcnet_r50-d8_512x512_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r50-d8_512x512_160k_ade20k/apcnet_r50-d8_512x512_160k_ade20k_20201214_115706-25fb92c2.pth
+- Name: apcnet_r101-d8_512x512_160k_ade20k
+ In Collection: APCNet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 160000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 45.41
+ mIoU(ms+flip): 46.63
+ Config: configs/apcnet/apcnet_r101-d8_512x512_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/apcnet/apcnet_r101-d8_512x512_160k_ade20k/apcnet_r101-d8_512x512_160k_ade20k_20201214_115705-73f9a8d7.pth
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_512x1024_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_512x1024_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..1e1cec67355abae33d518417eb96eae111f16d2b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_512x1024_40k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './apcnet_r50-d8_512x1024_40k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_512x1024_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_512x1024_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..04cb006ba146268e1d3278151bc6ea00a4fb1bfe
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_512x1024_80k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './apcnet_r50-d8_512x1024_80k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_512x512_160k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_512x512_160k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..1ce2279a0fbfd6fcc7cd20e3f552b1a39f47d943
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_512x512_160k_ade20k.py
@@ -0,0 +1,2 @@
+_base_ = './apcnet_r50-d8_512x512_160k_ade20k.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_512x512_80k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_512x512_80k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..8f10b98406c88256c66d3bbe241c149791d68feb
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_512x512_80k_ade20k.py
@@ -0,0 +1,2 @@
+_base_ = './apcnet_r50-d8_512x512_80k_ade20k.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_769x769_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_769x769_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..5c44ebcaf36075e67208c5f033d1e5f9a78dda4e
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_769x769_40k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './apcnet_r50-d8_769x769_40k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_769x769_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_769x769_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..616984575dda73a13fc5870f60ae6ffa30d6b01b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r101-d8_769x769_80k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './apcnet_r50-d8_769x769_80k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_512x1024_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_512x1024_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..99c61a942e4868315ce4a9404d113f73fed4a4ea
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_512x1024_40k_cityscapes.py
@@ -0,0 +1,4 @@
+_base_ = [
+ '../_base_/models/apcnet_r50-d8.py', '../_base_/datasets/cityscapes.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_40k.py'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_512x1024_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_512x1024_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..62a0627ae2e9bb17974068e56ee660093e944e0d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_512x1024_80k_cityscapes.py
@@ -0,0 +1,4 @@
+_base_ = [
+ '../_base_/models/apcnet_r50-d8.py', '../_base_/datasets/cityscapes.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_80k.py'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_512x512_160k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_512x512_160k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..f7821c559d2f92d23b28e07e040a54cfc425eefc
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_512x512_160k_ade20k.py
@@ -0,0 +1,6 @@
+_base_ = [
+ '../_base_/models/apcnet_r50-d8.py', '../_base_/datasets/ade20k.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_160k.py'
+]
+model = dict(
+ decode_head=dict(num_classes=150), auxiliary_head=dict(num_classes=150))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_512x512_80k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_512x512_80k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..daafa5fbc12c3ed6c10b5234d520166f774e0f94
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_512x512_80k_ade20k.py
@@ -0,0 +1,6 @@
+_base_ = [
+ '../_base_/models/apcnet_r50-d8.py', '../_base_/datasets/ade20k.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_80k.py'
+]
+model = dict(
+ decode_head=dict(num_classes=150), auxiliary_head=dict(num_classes=150))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_769x769_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_769x769_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..3db6140cb97da1d202fd464d01f793276effa629
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_769x769_40k_cityscapes.py
@@ -0,0 +1,9 @@
+_base_ = [
+ '../_base_/models/apcnet_r50-d8.py',
+ '../_base_/datasets/cityscapes_769x769.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_40k.py'
+]
+model = dict(
+ decode_head=dict(align_corners=True),
+ auxiliary_head=dict(align_corners=True),
+ test_cfg=dict(mode='slide', crop_size=(769, 769), stride=(513, 513)))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_769x769_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_769x769_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..9cac4254f37bc3755bff869a10eb3cb75db4d943
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/apcnet/apcnet_r50-d8_769x769_80k_cityscapes.py
@@ -0,0 +1,9 @@
+_base_ = [
+ '../_base_/models/apcnet_r50-d8.py',
+ '../_base_/datasets/cityscapes_769x769.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_80k.py'
+]
+model = dict(
+ decode_head=dict(align_corners=True),
+ auxiliary_head=dict(align_corners=True),
+ test_cfg=dict(mode='slide', crop_size=(769, 769), stride=(513, 513)))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/beit/README.md b/EgoHOS/raw/script/mmsegmentation/configs/beit/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..e0286f2e4b39ab3c71d80beb4665d74b98060f63
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/beit/README.md
@@ -0,0 +1,84 @@
+# BEiT
+
+[BEiT: BERT Pre-Training of Image Transformers](https://arxiv.org/abs/2106.08254)
+
+## Introduction
+
+
+
+Official Repo
+
+Code Snippet
+
+## Abstract
+
+
+
+We introduce a self-supervised vision representation model BEiT, which stands for Bidirectional Encoder representation from Image Transformers. Following BERT developed in the natural language processing area, we propose a masked image modeling task to pretrain vision Transformers. Specifically, each image has two views in our pre-training, i.e, image patches (such as 16x16 pixels), and visual tokens (i.e., discrete tokens). We first "tokenize" the original image into visual tokens. Then we randomly mask some image patches and fed them into the backbone Transformer. The pre-training objective is to recover the original visual tokens based on the corrupted image patches. After pre-training BEiT, we directly fine-tune the model parameters on downstream tasks by appending task layers upon the pretrained encoder. Experimental results on image classification and semantic segmentation show that our model achieves competitive results with previous pre-training methods. For example, base-size BEiT achieves 83.2% top-1 accuracy on ImageNet-1K, significantly outperforming from-scratch DeiT training (81.8%) with the same setup. Moreover, large-size BEiT obtains 86.3% only using ImageNet-1K, even outperforming ViT-L with supervised pre-training on ImageNet-22K (85.2%). The code and pretrained models are available at [this https URL](https://github.com/microsoft/unilm/tree/master/beit).
+
+
+
+
+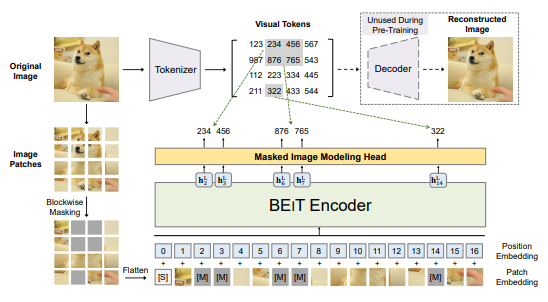 +
+
+## Citation
+
+```bibtex
+@inproceedings{beit,
+ title={{BEiT}: {BERT} Pre-Training of Image Transformers},
+ author={Hangbo Bao and Li Dong and Songhao Piao and Furu Wei},
+ booktitle={International Conference on Learning Representations},
+ year={2022},
+ url={https://openreview.net/forum?id=p-BhZSz59o4}
+}
+```
+
+## Usage
+
+To use other repositories' pre-trained models, it is necessary to convert keys.
+
+We provide a script [`beit2mmseg.py`](../../tools/model_converters/beit2mmseg.py) in the tools directory to convert the key of models from [the official repo](https://github.com/microsoft/unilm/tree/master/beit/semantic_segmentation) to MMSegmentation style.
+
+```shell
+python tools/model_converters/beit2mmseg.py ${PRETRAIN_PATH} ${STORE_PATH}
+```
+
+E.g.
+
+```shell
+python tools/model_converters/beit2mmseg.py https://conversationhub.blob.core.windows.net/beit-share-public/beit/beit_base_patch16_224_pt22k_ft22k.pth pretrain/beit_base_patch16_224_pt22k_ft22k.pth
+```
+
+This script convert model from `PRETRAIN_PATH` and store the converted model in `STORE_PATH`.
+
+In our default setting, pretrained models could be defined below:
+
+ | pretrained models | original models |
+ | ------ | -------- |
+ |BEiT_base.pth | ['BEiT_base'](https://conversationhub.blob.core.windows.net/beit-share-public/beit/beit_base_patch16_224_pt22k_ft22k.pth) |
+ |BEiT_large.pth | ['BEiT_large'](https://conversationhub.blob.core.windows.net/beit-share-public/beit/beit_large_patch16_224_pt22k_ft22k.pth) |
+
+Verify the single-scale results of the model:
+
+```shell
+sh tools/dist_test.sh \
+configs/beit/upernet_beit-large_fp16_8x1_640x640_160k_ade20k.py \
+upernet_beit-large_fp16_8x1_640x640_160k_ade20k-8fc0dd5d.pth $GPUS --eval mIoU
+```
+
+Since relative position embedding requires the input length and width to be equal, the sliding window is adopted for multi-scale inference. So we set min_size=640, that is, the shortest edge is 640. So the multi-scale inference of config is performed separately, instead of '--aug-test'. For multi-scale inference:
+
+```shell
+sh tools/dist_test.sh \
+configs/beit/upernet_beit-large_fp16_640x640_160k_ade20k_ms.py \
+upernet_beit-large_fp16_8x1_640x640_160k_ade20k-8fc0dd5d.pth $GPUS --eval mIoU
+```
+
+## Results and models
+
+### ADE20K
+
+| Method | Backbone | Crop Size | pretrain | pretrain img size | Batch Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| ------ | -------- | --------- | ---------- | ------- | -------- | --- | --- | -------------- | ----- | ------------: | -------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
+| UperNet | BEiT-B | 640x640 | ImageNet-22K | 224x224 | 16 | 160000 | 15.88 | 2.00 | 53.08 | 53.84 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/beit/upernet_beit-base_8x2_640x640_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/beit/upernet_beit-base_8x2_640x640_160k_ade20k/upernet_beit-base_8x2_640x640_160k_ade20k-eead221d.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/beit/upernet_beit-base_8x2_640x640_160k_ade20k/upernet_beit-base_8x2_640x640_160k_ade20k.log.json) |
+| UperNet | BEiT-L | 640x640 | ImageNet-22K | 224x224 | 8 | 320000 | 22.64 | 0.96 | 56.33 | 56.84 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/beit/upernet_beit-large_fp16_8x1_640x640_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/beit/upernet_beit-large_fp16_8x1_640x640_160k_ade20k/upernet_beit-large_fp16_8x1_640x640_160k_ade20k-8fc0dd5d.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/beit/upernet_beit-large_fp16_8x1_640x640_160k_ade20k/upernet_beit-large_fp16_8x1_640x640_160k_ade20k.log.json) |
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/beit/beit.yml b/EgoHOS/raw/script/mmsegmentation/configs/beit/beit.yml
new file mode 100644
index 0000000000000000000000000000000000000000..6f3cee3eddfba1b4c6582760df4cbdfae9522227
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/beit/beit.yml
@@ -0,0 +1,45 @@
+Models:
+- Name: upernet_beit-base_8x2_640x640_160k_ade20k
+ In Collection: UperNet
+ Metadata:
+ backbone: BEiT-B
+ crop size: (640,640)
+ lr schd: 160000
+ inference time (ms/im):
+ - value: 500.0
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (640,640)
+ Training Memory (GB): 15.88
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 53.08
+ mIoU(ms+flip): 53.84
+ Config: configs/beit/upernet_beit-base_8x2_640x640_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/beit/upernet_beit-base_8x2_640x640_160k_ade20k/upernet_beit-base_8x2_640x640_160k_ade20k-eead221d.pth
+- Name: upernet_beit-large_fp16_8x1_640x640_160k_ade20k
+ In Collection: UperNet
+ Metadata:
+ backbone: BEiT-L
+ crop size: (640,640)
+ lr schd: 320000
+ inference time (ms/im):
+ - value: 1041.67
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP16
+ resolution: (640,640)
+ Training Memory (GB): 22.64
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 56.33
+ mIoU(ms+flip): 56.84
+ Config: configs/beit/upernet_beit-large_fp16_8x1_640x640_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/beit/upernet_beit-large_fp16_8x1_640x640_160k_ade20k/upernet_beit-large_fp16_8x1_640x640_160k_ade20k-8fc0dd5d.pth
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/beit/upernet_beit-base_640x640_160k_ade20k_ms.py b/EgoHOS/raw/script/mmsegmentation/configs/beit/upernet_beit-base_640x640_160k_ade20k_ms.py
new file mode 100644
index 0000000000000000000000000000000000000000..f764c92c11e0bfac26fdce782287138a5676a68c
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/beit/upernet_beit-base_640x640_160k_ade20k_ms.py
@@ -0,0 +1,24 @@
+_base_ = './upernet_beit-base_8x2_640x640_160k_ade20k.py'
+
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2560, 640),
+ img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=True,
+ transforms=[
+ dict(type='Resize', keep_ratio=True, min_size=640),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ val=dict(pipeline=test_pipeline),
+ test=dict(pipeline=test_pipeline),
+ samples_per_gpu=2)
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/beit/upernet_beit-base_8x2_640x640_160k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/beit/upernet_beit-base_8x2_640x640_160k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..b36adc3c0d58a4e4ec66fbc22baad5ea570f048b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/beit/upernet_beit-base_8x2_640x640_160k_ade20k.py
@@ -0,0 +1,30 @@
+_base_ = [
+ '../_base_/models/upernet_beit.py', '../_base_/datasets/ade20k_640x640.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_160k.py'
+]
+
+model = dict(
+ pretrained='pretrain/beit_base_patch16_224_pt22k_ft22k.pth',
+ test_cfg=dict(mode='slide', crop_size=(640, 640), stride=(426, 426)))
+
+optimizer = dict(
+ _delete_=True,
+ type='AdamW',
+ lr=3e-5,
+ betas=(0.9, 0.999),
+ weight_decay=0.05,
+ constructor='LayerDecayOptimizerConstructor',
+ paramwise_cfg=dict(num_layers=12, layer_decay_rate=0.9))
+
+lr_config = dict(
+ _delete_=True,
+ policy='poly',
+ warmup='linear',
+ warmup_iters=1500,
+ warmup_ratio=1e-6,
+ power=1.0,
+ min_lr=0.0,
+ by_epoch=False)
+
+# By default, models are trained on 8 GPUs with 2 images per GPU
+data = dict(samples_per_gpu=2)
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/beit/upernet_beit-large_fp16_640x640_160k_ade20k_ms.py b/EgoHOS/raw/script/mmsegmentation/configs/beit/upernet_beit-large_fp16_640x640_160k_ade20k_ms.py
new file mode 100644
index 0000000000000000000000000000000000000000..fd4d9477d4b7b60ee7a14d10143ecac5a92527f5
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/beit/upernet_beit-large_fp16_640x640_160k_ade20k_ms.py
@@ -0,0 +1,22 @@
+_base_ = './upernet_beit-large_fp16_8x1_640x640_160k_ade20k.py'
+
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2560, 640),
+ img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=True,
+ transforms=[
+ dict(type='Resize', keep_ratio=True, min_size=640),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ val=dict(pipeline=test_pipeline), test=dict(pipeline=test_pipeline))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/beit/upernet_beit-large_fp16_8x1_640x640_160k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/beit/upernet_beit-large_fp16_8x1_640x640_160k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..e6247b7352ba0c3f428744e12abb5cd1c6ea3727
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/beit/upernet_beit-large_fp16_8x1_640x640_160k_ade20k.py
@@ -0,0 +1,47 @@
+_base_ = [
+ '../_base_/models/upernet_beit.py', '../_base_/datasets/ade20k_640x640.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_320k.py'
+]
+
+model = dict(
+ pretrained='pretrain/beit_large_patch16_224_pt22k_ft22k.pth',
+ backbone=dict(
+ type='BEiT',
+ embed_dims=1024,
+ num_layers=24,
+ num_heads=16,
+ mlp_ratio=4,
+ qv_bias=True,
+ init_values=1e-6,
+ drop_path_rate=0.2,
+ out_indices=[7, 11, 15, 23]),
+ neck=dict(embed_dim=1024, rescales=[4, 2, 1, 0.5]),
+ decode_head=dict(
+ in_channels=[1024, 1024, 1024, 1024], num_classes=150, channels=1024),
+ auxiliary_head=dict(in_channels=1024, num_classes=150),
+ test_cfg=dict(mode='slide', crop_size=(640, 640), stride=(426, 426)))
+
+optimizer = dict(
+ _delete_=True,
+ type='AdamW',
+ lr=2e-5,
+ betas=(0.9, 0.999),
+ weight_decay=0.05,
+ constructor='LayerDecayOptimizerConstructor',
+ paramwise_cfg=dict(num_layers=24, layer_decay_rate=0.95))
+
+lr_config = dict(
+ _delete_=True,
+ policy='poly',
+ warmup='linear',
+ warmup_iters=3000,
+ warmup_ratio=1e-6,
+ power=1.0,
+ min_lr=0.0,
+ by_epoch=False)
+
+data = dict(samples_per_gpu=1)
+optimizer_config = dict(
+ type='GradientCumulativeFp16OptimizerHook', cumulative_iters=2)
+
+fp16 = dict()
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/README.md b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..75ac37c1c1842be4f430126095ecf1347b9c3f61
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/README.md
@@ -0,0 +1,63 @@
+# BiSeNetV1
+
+[BiSeNet: Bilateral Segmentation Network for Real-time Semantic Segmentation](https://arxiv.org/abs/1808.00897)
+
+## Introduction
+
+
+
+Official Repo
+
+Code Snippet
+
+## Abstract
+
+
+
+Semantic segmentation requires both rich spatial information and sizeable receptive field. However, modern approaches usually compromise spatial resolution to achieve real-time inference speed, which leads to poor performance. In this paper, we address this dilemma with a novel Bilateral Segmentation Network (BiSeNet). We first design a Spatial Path with a small stride to preserve the spatial information and generate high-resolution features. Meanwhile, a Context Path with a fast downsampling strategy is employed to obtain sufficient receptive field. On top of the two paths, we introduce a new Feature Fusion Module to combine features efficiently. The proposed architecture makes a right balance between the speed and segmentation performance on Cityscapes, CamVid, and COCO-Stuff datasets. Specifically, for a 2048x1024 input, we achieve 68.4% Mean IOU on the Cityscapes test dataset with speed of 105 FPS on one NVIDIA Titan XP card, which is significantly faster than the existing methods with comparable performance.
+
+
+
+
+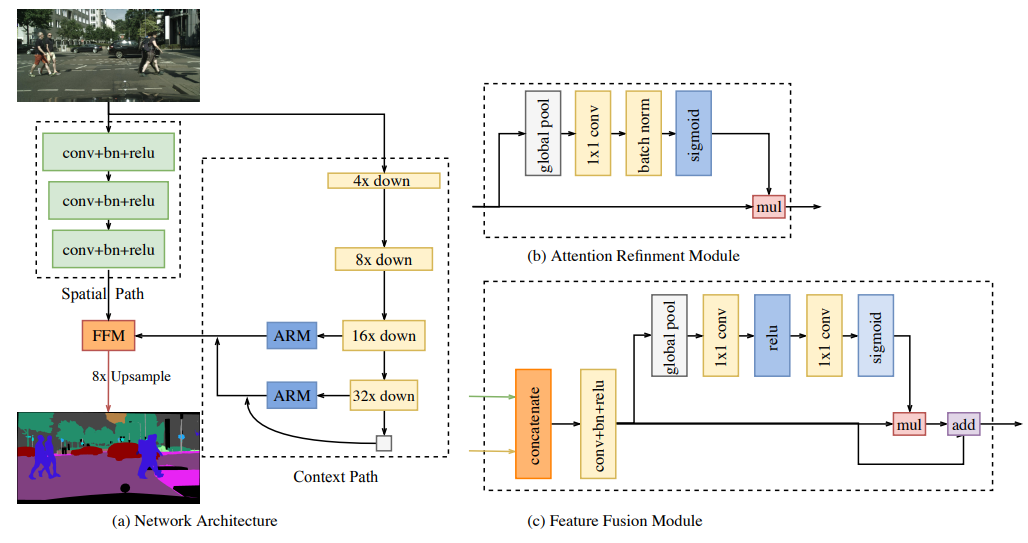 +
+
+## Citation
+
+```bibtex
+@inproceedings{yu2018bisenet,
+ title={Bisenet: Bilateral segmentation network for real-time semantic segmentation},
+ author={Yu, Changqian and Wang, Jingbo and Peng, Chao and Gao, Changxin and Yu, Gang and Sang, Nong},
+ booktitle={Proceedings of the European conference on computer vision (ECCV)},
+ pages={325--341},
+ year={2018}
+}
+```
+
+## Results and models
+
+### Cityscapes
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| --------- | --------- | --------- | ------: | -------- | -------------- | ----: | ------------- | --------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
+| BiSeNetV1 (No Pretrain) | R-18-D32 | 1024x1024 | 160000 | 5.69 | 31.77 | 74.44 | 77.05 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/bisenetv1/bisenetv1_r18-d32_4x4_1024x1024_160k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r18-d32_4x4_1024x1024_160k_cityscapes/bisenetv1_r18-d32_4x4_1024x1024_160k_cityscapes_20210922_172239-c55e78e2.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r18-d32_4x4_1024x1024_160k_cityscapes/bisenetv1_r18-d32_4x4_1024x1024_160k_cityscapes_20210922_172239.log.json) |
+| BiSeNetV1| R-18-D32 | 1024x1024 | 160000 | 5.69 | 31.77 | 74.37 | 76.91 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/bisenetv1/bisenetv1_r18-d32_in1k-pre_4x4_1024x1024_160k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r18-d32_in1k-pre_4x4_1024x1024_160k_cityscapes/bisenetv1_r18-d32_in1k-pre_4x4_1024x1024_160k_cityscapes_20210905_220251-8ba80eff.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r18-d32_in1k-pre_4x4_1024x1024_160k_cityscapes/bisenetv1_r18-d32_in1k-pre_4x4_1024x1024_160k_cityscapes_20210905_220251.log.json) |
+| BiSeNetV1 (4x8) | R-18-D32 | 1024x1024 | 160000 | 11.17 | 31.77 | 75.16 | 77.24 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/bisenetv1/bisenetv1_r18-d32_in1k-pre_4x8_1024x1024_160k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r18-d32_in1k-pre_4x8_1024x1024_160k_cityscapes/bisenetv1_r18-d32_in1k-pre_4x8_1024x1024_160k_cityscapes_20210905_220322-bb8db75f.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r18-d32_in1k-pre_4x8_1024x1024_160k_cityscapes/bisenetv1_r18-d32_in1k-pre_4x8_1024x1024_160k_cityscapes_20210905_220322.log.json) |
+| BiSeNetV1 (No Pretrain) | R-50-D32 | 1024x1024 | 160000 | 15.39 | 7.71 | 76.92 | 78.87 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/bisenetv1/bisenetv1_r50-d32_4x4_1024x1024_160k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r50-d32_4x4_1024x1024_160k_cityscapes/bisenetv1_r50-d32_4x4_1024x1024_160k_cityscapes_20210923_222639-7b28a2a6.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r50-d32_4x4_1024x1024_160k_cityscapes/bisenetv1_r50-d32_4x4_1024x1024_160k_cityscapes_20210923_222639.log.json) |
+| BiSeNetV1 | R-50-D32 | 1024x1024 | 160000 | 15.39 | 7.71 | 77.68 | 79.57 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/bisenetv1/bisenetv1_r50-d32_in1k-pre_4x4_1024x1024_160k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r50-d32_in1k-pre_4x4_1024x1024_160k_cityscapes/bisenetv1_r50-d32_in1k-pre_4x4_1024x1024_160k_cityscapes_20210917_234628-8b304447.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r50-d32_in1k-pre_4x4_1024x1024_160k_cityscapes/bisenetv1_r50-d32_in1k-pre_4x4_1024x1024_160k_cityscapes_20210917_234628.log.json) |
+
+### COCO-Stuff 164k
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| --------- | --------- | --------- | ------: | -------- | -------------- | ----: | ------------- | --------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
+| BiSeNetV1 (No Pretrain) | R-18-D32 | 512x512 | 160000 | - | - | 25.45 | 26.15 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/bisenetv1/bisenetv1_r18-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r18-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r18-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211022_054328-046aa2f2.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r18-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r18-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211022_054328.log.json) |
+| BiSeNetV1| R-18-D32 | 512x512 | 160000 | 6.33 | 74.24 | 28.55 | 29.26 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/bisenetv1/bisenetv1_r18-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r18-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r18-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211023_013100-f700dbf7.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r18-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r18-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211023_013100.log.json) |
+| BiSeNetV1 (No Pretrain) | R-50-D32 | 512x512 | 160000 | - | - | 29.82 | 30.33 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/bisenetv1/bisenetv1_r50-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r50-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r50-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211101_040616-d2bb0df4.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r50-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r50-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211101_040616.log.json) |
+| BiSeNetV1 | R-50-D32 | 512x512 | 160000 | 9.28 | 32.60 | 34.88 | 35.37 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/bisenetv1/bisenetv1_r50-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r50-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r50-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211101_181932-66747911.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r50-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r50-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211101_181932.log.json) |
+| BiSeNetV1 (No Pretrain) | R-101-D32 | 512x512 | 160000 | - | - | 31.14 | 31.76 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/bisenetv1/bisenetv1_r101-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r101-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r101-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211102_164147-c6b32c3b.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r101-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r101-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211102_164147.log.json) |
+| BiSeNetV1 | R-101-D32 | 512x512 | 160000 | 10.36 | 25.25 | 37.38 | 37.99 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/bisenetv1/bisenetv1_r101-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r101-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r101-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211101_225220-28c8f092.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r101-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r101-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211101_225220.log.json) |
+
+Note:
+
+- `4x8`: Using 4 GPUs with 8 samples per GPU in training.
+- For BiSeNetV1 on Cityscapes dataset, default setting is 4 GPUs with 4 samples per GPU in training.
+- `No Pretrain` means the model is trained from scratch.
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1.yml b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1.yml
new file mode 100644
index 0000000000000000000000000000000000000000..61f264b0568cadde5045ba3b3721ee412e68e19f
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1.yml
@@ -0,0 +1,234 @@
+Collections:
+- Name: BiSeNetV1
+ Metadata:
+ Training Data:
+ - Cityscapes
+ - COCO-Stuff 164k
+ Paper:
+ URL: https://arxiv.org/abs/1808.00897
+ Title: 'BiSeNet: Bilateral Segmentation Network for Real-time Semantic Segmentation'
+ README: configs/bisenetv1/README.md
+ Code:
+ URL: https://github.com/open-mmlab/mmsegmentation/blob/v0.18.0/mmseg/models/backbones/bisenetv1.py#L266
+ Version: v0.18.0
+ Converted From:
+ Code: https://github.com/ycszen/TorchSeg/tree/master/model/bisenet
+Models:
+- Name: bisenetv1_r18-d32_4x4_1024x1024_160k_cityscapes
+ In Collection: BiSeNetV1
+ Metadata:
+ backbone: R-18-D32
+ crop size: (1024,1024)
+ lr schd: 160000
+ inference time (ms/im):
+ - value: 31.48
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (1024,1024)
+ Training Memory (GB): 5.69
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 74.44
+ mIoU(ms+flip): 77.05
+ Config: configs/bisenetv1/bisenetv1_r18-d32_4x4_1024x1024_160k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r18-d32_4x4_1024x1024_160k_cityscapes/bisenetv1_r18-d32_4x4_1024x1024_160k_cityscapes_20210922_172239-c55e78e2.pth
+- Name: bisenetv1_r18-d32_in1k-pre_4x4_1024x1024_160k_cityscapes
+ In Collection: BiSeNetV1
+ Metadata:
+ backbone: R-18-D32
+ crop size: (1024,1024)
+ lr schd: 160000
+ inference time (ms/im):
+ - value: 31.48
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (1024,1024)
+ Training Memory (GB): 5.69
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 74.37
+ mIoU(ms+flip): 76.91
+ Config: configs/bisenetv1/bisenetv1_r18-d32_in1k-pre_4x4_1024x1024_160k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r18-d32_in1k-pre_4x4_1024x1024_160k_cityscapes/bisenetv1_r18-d32_in1k-pre_4x4_1024x1024_160k_cityscapes_20210905_220251-8ba80eff.pth
+- Name: bisenetv1_r18-d32_in1k-pre_4x8_1024x1024_160k_cityscapes
+ In Collection: BiSeNetV1
+ Metadata:
+ backbone: R-18-D32
+ crop size: (1024,1024)
+ lr schd: 160000
+ inference time (ms/im):
+ - value: 31.48
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (1024,1024)
+ Training Memory (GB): 11.17
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 75.16
+ mIoU(ms+flip): 77.24
+ Config: configs/bisenetv1/bisenetv1_r18-d32_in1k-pre_4x8_1024x1024_160k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r18-d32_in1k-pre_4x8_1024x1024_160k_cityscapes/bisenetv1_r18-d32_in1k-pre_4x8_1024x1024_160k_cityscapes_20210905_220322-bb8db75f.pth
+- Name: bisenetv1_r50-d32_4x4_1024x1024_160k_cityscapes
+ In Collection: BiSeNetV1
+ Metadata:
+ backbone: R-50-D32
+ crop size: (1024,1024)
+ lr schd: 160000
+ inference time (ms/im):
+ - value: 129.7
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (1024,1024)
+ Training Memory (GB): 15.39
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 76.92
+ mIoU(ms+flip): 78.87
+ Config: configs/bisenetv1/bisenetv1_r50-d32_4x4_1024x1024_160k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r50-d32_4x4_1024x1024_160k_cityscapes/bisenetv1_r50-d32_4x4_1024x1024_160k_cityscapes_20210923_222639-7b28a2a6.pth
+- Name: bisenetv1_r50-d32_in1k-pre_4x4_1024x1024_160k_cityscapes
+ In Collection: BiSeNetV1
+ Metadata:
+ backbone: R-50-D32
+ crop size: (1024,1024)
+ lr schd: 160000
+ inference time (ms/im):
+ - value: 129.7
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (1024,1024)
+ Training Memory (GB): 15.39
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 77.68
+ mIoU(ms+flip): 79.57
+ Config: configs/bisenetv1/bisenetv1_r50-d32_in1k-pre_4x4_1024x1024_160k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r50-d32_in1k-pre_4x4_1024x1024_160k_cityscapes/bisenetv1_r50-d32_in1k-pre_4x4_1024x1024_160k_cityscapes_20210917_234628-8b304447.pth
+- Name: bisenetv1_r18-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k
+ In Collection: BiSeNetV1
+ Metadata:
+ backbone: R-18-D32
+ crop size: (512,512)
+ lr schd: 160000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: COCO-Stuff 164k
+ Metrics:
+ mIoU: 25.45
+ mIoU(ms+flip): 26.15
+ Config: configs/bisenetv1/bisenetv1_r18-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r18-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r18-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211022_054328-046aa2f2.pth
+- Name: bisenetv1_r18-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k
+ In Collection: BiSeNetV1
+ Metadata:
+ backbone: R-18-D32
+ crop size: (512,512)
+ lr schd: 160000
+ inference time (ms/im):
+ - value: 13.47
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 6.33
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: COCO-Stuff 164k
+ Metrics:
+ mIoU: 28.55
+ mIoU(ms+flip): 29.26
+ Config: configs/bisenetv1/bisenetv1_r18-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r18-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r18-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211023_013100-f700dbf7.pth
+- Name: bisenetv1_r50-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k
+ In Collection: BiSeNetV1
+ Metadata:
+ backbone: R-50-D32
+ crop size: (512,512)
+ lr schd: 160000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: COCO-Stuff 164k
+ Metrics:
+ mIoU: 29.82
+ mIoU(ms+flip): 30.33
+ Config: configs/bisenetv1/bisenetv1_r50-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r50-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r50-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211101_040616-d2bb0df4.pth
+- Name: bisenetv1_r50-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k
+ In Collection: BiSeNetV1
+ Metadata:
+ backbone: R-50-D32
+ crop size: (512,512)
+ lr schd: 160000
+ inference time (ms/im):
+ - value: 30.67
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 9.28
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: COCO-Stuff 164k
+ Metrics:
+ mIoU: 34.88
+ mIoU(ms+flip): 35.37
+ Config: configs/bisenetv1/bisenetv1_r50-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r50-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r50-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211101_181932-66747911.pth
+- Name: bisenetv1_r101-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k
+ In Collection: BiSeNetV1
+ Metadata:
+ backbone: R-101-D32
+ crop size: (512,512)
+ lr schd: 160000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: COCO-Stuff 164k
+ Metrics:
+ mIoU: 31.14
+ mIoU(ms+flip): 31.76
+ Config: configs/bisenetv1/bisenetv1_r101-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r101-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r101-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211102_164147-c6b32c3b.pth
+- Name: bisenetv1_r101-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k
+ In Collection: BiSeNetV1
+ Metadata:
+ backbone: R-101-D32
+ crop size: (512,512)
+ lr schd: 160000
+ inference time (ms/im):
+ - value: 39.6
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 10.36
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: COCO-Stuff 164k
+ Metrics:
+ mIoU: 37.38
+ mIoU(ms+flip): 37.99
+ Config: configs/bisenetv1/bisenetv1_r101-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv1/bisenetv1_r101-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k/bisenetv1_r101-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k_20211101_225220-28c8f092.pth
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r101-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k.py b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r101-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
new file mode 100644
index 0000000000000000000000000000000000000000..c3fe21597d6dfab1d27669674926b5e761466cce
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r101-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
@@ -0,0 +1,6 @@
+_base_ = './bisenetv1_r101-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py'
+model = dict(
+ backbone=dict(
+ backbone_cfg=dict(
+ init_cfg=dict(
+ type='Pretrained', checkpoint='open-mmlab://resnet101_v1c'))))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r101-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r101-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
new file mode 100644
index 0000000000000000000000000000000000000000..b1e1c3e86363cfb187efb69006486146dabb10c9
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r101-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
@@ -0,0 +1,18 @@
+_base_ = [
+ '../_base_/models/bisenetv1_r18-d32.py',
+ '../_base_/datasets/coco-stuff164k.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_160k.py'
+]
+model = dict(
+ backbone=dict(
+ context_channels=(512, 1024, 2048),
+ spatial_channels=(256, 256, 256, 512),
+ out_channels=1024,
+ backbone_cfg=dict(type='ResNet', depth=101)),
+ decode_head=dict(in_channels=1024, channels=1024, num_classes=171),
+ auxiliary_head=[
+ dict(in_channels=512, channels=256, num_classes=171),
+ dict(in_channels=512, channels=256, num_classes=171),
+ ])
+lr_config = dict(warmup='linear', warmup_iters=1000)
+optimizer = dict(lr=0.005)
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r18-d32_4x4_1024x1024_160k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r18-d32_4x4_1024x1024_160k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..f4019e930e54e034ac4592b6b31af6a0fd391ca2
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r18-d32_4x4_1024x1024_160k_cityscapes.py
@@ -0,0 +1,11 @@
+_base_ = [
+ '../_base_/models/bisenetv1_r18-d32.py',
+ '../_base_/datasets/cityscapes_1024x1024.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_160k.py'
+]
+lr_config = dict(warmup='linear', warmup_iters=1000)
+optimizer = dict(lr=0.025)
+data = dict(
+ samples_per_gpu=4,
+ workers_per_gpu=4,
+)
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r18-d32_in1k-pre_4x4_1024x1024_160k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r18-d32_in1k-pre_4x4_1024x1024_160k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..ef061a16bde683828bb118b0540adb2814b3009d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r18-d32_in1k-pre_4x4_1024x1024_160k_cityscapes.py
@@ -0,0 +1,16 @@
+_base_ = [
+ '../_base_/models/bisenetv1_r18-d32.py',
+ '../_base_/datasets/cityscapes_1024x1024.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_160k.py'
+]
+model = dict(
+ backbone=dict(
+ backbone_cfg=dict(
+ init_cfg=dict(
+ type='Pretrained', checkpoint='open-mmlab://resnet18_v1c'))))
+lr_config = dict(warmup='linear', warmup_iters=1000)
+optimizer = dict(lr=0.025)
+data = dict(
+ samples_per_gpu=4,
+ workers_per_gpu=4,
+)
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r18-d32_in1k-pre_4x8_1024x1024_160k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r18-d32_in1k-pre_4x8_1024x1024_160k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..f4b9f6d2c9559f136bb50948e57f47a2c420d6de
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r18-d32_in1k-pre_4x8_1024x1024_160k_cityscapes.py
@@ -0,0 +1,5 @@
+_base_ = './bisenetv1_r18-d32_in1k-pre_4x4_1024x1024_160k_cityscapes.py'
+data = dict(
+ samples_per_gpu=8,
+ workers_per_gpu=4,
+)
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r18-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k.py b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r18-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
new file mode 100644
index 0000000000000000000000000000000000000000..c6d93049e28826e8038cbc16d5241a260f4714eb
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r18-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
@@ -0,0 +1,6 @@
+_base_ = './bisenetv1_r18-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py'
+model = dict(
+ backbone=dict(
+ backbone_cfg=dict(
+ init_cfg=dict(
+ type='Pretrained', checkpoint='open-mmlab://resnet18_v1c'))), )
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r18-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r18-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
new file mode 100644
index 0000000000000000000000000000000000000000..78d7fea62963e08d152477bb1309c1629572de8c
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r18-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
@@ -0,0 +1,13 @@
+_base_ = [
+ '../_base_/models/bisenetv1_r18-d32.py',
+ '../_base_/datasets/coco-stuff164k.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_160k.py'
+]
+model = dict(
+ decode_head=dict(num_classes=171),
+ auxiliary_head=[
+ dict(num_classes=171),
+ dict(num_classes=171),
+ ])
+lr_config = dict(warmup='linear', warmup_iters=1000)
+optimizer = dict(lr=0.005)
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r50-d32_4x4_1024x1024_160k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r50-d32_4x4_1024x1024_160k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..7cadd503c40639c40731e39ab0ad77745102be6a
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r50-d32_4x4_1024x1024_160k_cityscapes.py
@@ -0,0 +1,42 @@
+_base_ = [
+ '../_base_/models/bisenetv1_r18-d32.py',
+ '../_base_/datasets/cityscapes_1024x1024.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_160k.py'
+]
+norm_cfg = dict(type='SyncBN', requires_grad=True)
+model = dict(
+ type='EncoderDecoder',
+ backbone=dict(
+ type='BiSeNetV1',
+ context_channels=(512, 1024, 2048),
+ spatial_channels=(256, 256, 256, 512),
+ out_channels=1024,
+ backbone_cfg=dict(type='ResNet', depth=50)),
+ decode_head=dict(
+ type='FCNHead', in_channels=1024, in_index=0, channels=1024),
+ auxiliary_head=[
+ dict(
+ type='FCNHead',
+ in_channels=512,
+ channels=256,
+ num_convs=1,
+ num_classes=19,
+ in_index=1,
+ norm_cfg=norm_cfg,
+ concat_input=False),
+ dict(
+ type='FCNHead',
+ in_channels=512,
+ channels=256,
+ num_convs=1,
+ num_classes=19,
+ in_index=2,
+ norm_cfg=norm_cfg,
+ concat_input=False),
+ ])
+lr_config = dict(warmup='linear', warmup_iters=1000)
+optimizer = dict(lr=0.05)
+data = dict(
+ samples_per_gpu=4,
+ workers_per_gpu=4,
+)
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r50-d32_in1k-pre_4x4_1024x1024_160k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r50-d32_in1k-pre_4x4_1024x1024_160k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..5625a76c0873ca7ddb6dcfea2f273da4114c421d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r50-d32_in1k-pre_4x4_1024x1024_160k_cityscapes.py
@@ -0,0 +1,7 @@
+_base_ = './bisenetv1_r50-d32_4x4_1024x1024_160k_cityscapes.py'
+model = dict(
+ type='EncoderDecoder',
+ backbone=dict(
+ backbone_cfg=dict(
+ init_cfg=dict(
+ type='Pretrained', checkpoint='open-mmlab://resnet50_v1c'))))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r50-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k.py b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r50-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
new file mode 100644
index 0000000000000000000000000000000000000000..f0fea69f2f01c68f2df774839c650774a43e97f5
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r50-d32_in1k-pre_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
@@ -0,0 +1,7 @@
+_base_ = './bisenetv1_r50-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py'
+
+model = dict(
+ backbone=dict(
+ backbone_cfg=dict(
+ init_cfg=dict(
+ type='Pretrained', checkpoint='open-mmlab://resnet50_v1c'))))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r50-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r50-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
new file mode 100644
index 0000000000000000000000000000000000000000..dbbccc69d80923a2fe43879094d25d7221e716ab
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv1/bisenetv1_r50-d32_lr5e-3_4x4_512x512_160k_coco-stuff164k.py
@@ -0,0 +1,18 @@
+_base_ = [
+ '../_base_/models/bisenetv1_r18-d32.py',
+ '../_base_/datasets/coco-stuff164k.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_160k.py'
+]
+model = dict(
+ backbone=dict(
+ context_channels=(512, 1024, 2048),
+ spatial_channels=(256, 256, 256, 512),
+ out_channels=1024,
+ backbone_cfg=dict(type='ResNet', depth=50)),
+ decode_head=dict(in_channels=1024, channels=1024, num_classes=171),
+ auxiliary_head=[
+ dict(in_channels=512, channels=256, num_classes=171),
+ dict(in_channels=512, channels=256, num_classes=171),
+ ])
+lr_config = dict(warmup='linear', warmup_iters=1000)
+optimizer = dict(lr=0.005)
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/README.md b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..1bc74249073eb7a372af869e4c171fb8c0402b91
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/README.md
@@ -0,0 +1,53 @@
+# BiSeNetV2
+
+[Bisenet v2: Bilateral Network with Guided Aggregation for Real-time Semantic Segmentation](https://arxiv.org/abs/2004.02147)
+
+## Introduction
+
+
+
+Official Repo
+
+Code Snippet
+
+## Abstract
+
+
+
+The low-level details and high-level semantics are both essential to the semantic segmentation task. However, to speed up the model inference, current approaches almost always sacrifice the low-level details, which leads to a considerable accuracy decrease. We propose to treat these spatial details and categorical semantics separately to achieve high accuracy and high efficiency for realtime semantic segmentation. To this end, we propose an efficient and effective architecture with a good trade-off between speed and accuracy, termed Bilateral Segmentation Network (BiSeNet V2). This architecture involves: (i) a Detail Branch, with wide channels and shallow layers to capture low-level details and generate high-resolution feature representation; (ii) a Semantic Branch, with narrow channels and deep layers to obtain high-level semantic context. The Semantic Branch is lightweight due to reducing the channel capacity and a fast-downsampling strategy. Furthermore, we design a Guided Aggregation Layer to enhance mutual connections and fuse both types of feature representation. Besides, a booster training strategy is designed to improve the segmentation performance without any extra inference cost. Extensive quantitative and qualitative evaluations demonstrate that the proposed architecture performs favourably against a few state-of-the-art real-time semantic segmentation approaches. Specifically, for a 2,048x1,024 input, we achieve 72.6% Mean IoU on the Cityscapes test set with a speed of 156 FPS on one NVIDIA GeForce GTX 1080 Ti card, which is significantly faster than existing methods, yet we achieve better segmentation accuracy.
+
+
+
+
+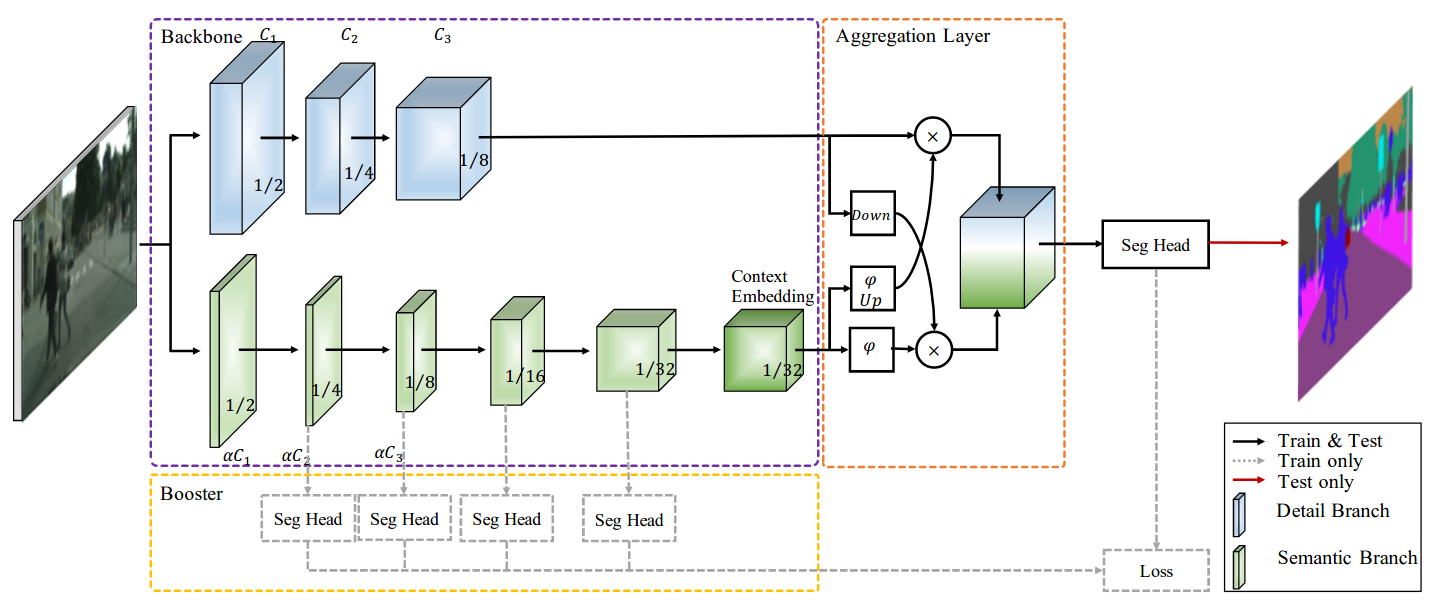 +
+
+## Citation
+
+```bibtex
+@article{yu2021bisenet,
+ title={Bisenet v2: Bilateral network with guided aggregation for real-time semantic segmentation},
+ author={Yu, Changqian and Gao, Changxin and Wang, Jingbo and Yu, Gang and Shen, Chunhua and Sang, Nong},
+ journal={International Journal of Computer Vision},
+ pages={1--18},
+ year={2021},
+ publisher={Springer}
+}
+```
+
+
+## Results and models
+
+### Cityscapes
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| ------ | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | --------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
+| BiSeNetV2 | BiSeNetV2 | 1024x1024 | 160000 | 7.64 | 31.77 | 73.21 | 75.74 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/bisenetv2/bisenetv2_fcn_4x4_1024x1024_160k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv2/bisenetv2_fcn_4x4_1024x1024_160k_cityscapes/bisenetv2_fcn_4x4_1024x1024_160k_cityscapes_20210902_015551-bcf10f09.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv2/bisenetv2_fcn_4x4_1024x1024_160k_cityscapes/bisenetv2_fcn_4x4_1024x1024_160k_cityscapes_20210902_015551.log.json) |
+| BiSeNetV2 (OHEM) | BiSeNetV2 | 1024x1024 | 160000 | 7.64 | - | 73.57 | 75.80 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/bisenetv2/bisenetv2_fcn_ohem_4x4_1024x1024_160k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv2/bisenetv2_fcn_ohem_4x4_1024x1024_160k_cityscapes/bisenetv2_fcn_ohem_4x4_1024x1024_160k_cityscapes_20210902_112947-5f8103b4.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv2/bisenetv2_fcn_ohem_4x4_1024x1024_160k_cityscapes/bisenetv2_fcn_ohem_4x4_1024x1024_160k_cityscapes_20210902_112947.log.json) |
+| BiSeNetV2 (4x8) | BiSeNetV2 | 1024x1024 | 160000 | 15.05 | - | 75.76 | 77.79 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/bisenetv2/bisenetv2_fcn_4x8_1024x1024_160k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv2/bisenetv2_fcn_4x8_1024x1024_160k_cityscapes/bisenetv2_fcn_4x8_1024x1024_160k_cityscapes_20210903_000032-e1a2eed6.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv2/bisenetv2_fcn_4x8_1024x1024_160k_cityscapes/bisenetv2_fcn_4x8_1024x1024_160k_cityscapes_20210903_000032.log.json) |
+| BiSeNetV2 (FP16) | BiSeNetV2 | 1024x1024 | 160000 | 5.77 | 36.65 | 73.07 | 75.13 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/bisenetv2/bisenetv2_fcn_fp16_4x4_1024x1024_160k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv2/bisenetv2_fcn_fp16_4x4_1024x1024_160k_cityscapes/bisenetv2_fcn_fp16_4x4_1024x1024_160k_cityscapes_20210902_045942-b979777b.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv2/bisenetv2_fcn_fp16_4x4_1024x1024_160k_cityscapes/bisenetv2_fcn_fp16_4x4_1024x1024_160k_cityscapes_20210902_045942.log.json) |
+
+Note:
+
+- `OHEM` means Online Hard Example Mining (OHEM) is adopted in training.
+- `FP16` means Mixed Precision (FP16) is adopted in training.
+- `4x8` means 4 GPUs with 8 samples per GPU in training.
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/bisenetv2.yml b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/bisenetv2.yml
new file mode 100644
index 0000000000000000000000000000000000000000..455fa6c4796d987584b07698fb2563da4a962849
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/bisenetv2.yml
@@ -0,0 +1,88 @@
+Collections:
+- Name: BiSeNetV2
+ Metadata:
+ Training Data:
+ - Cityscapes
+ Paper:
+ URL: https://arxiv.org/abs/2004.02147
+ Title: 'Bisenet v2: Bilateral Network with Guided Aggregation for Real-time Semantic
+ Segmentation'
+ README: configs/bisenetv2/README.md
+ Code:
+ URL: https://github.com/open-mmlab/mmsegmentation/blob/v0.18.0/mmseg/models/backbones/bisenetv2.py#L545
+ Version: v0.18.0
+Models:
+- Name: bisenetv2_fcn_4x4_1024x1024_160k_cityscapes
+ In Collection: BiSeNetV2
+ Metadata:
+ backbone: BiSeNetV2
+ crop size: (1024,1024)
+ lr schd: 160000
+ inference time (ms/im):
+ - value: 31.48
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (1024,1024)
+ Training Memory (GB): 7.64
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 73.21
+ mIoU(ms+flip): 75.74
+ Config: configs/bisenetv2/bisenetv2_fcn_4x4_1024x1024_160k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv2/bisenetv2_fcn_4x4_1024x1024_160k_cityscapes/bisenetv2_fcn_4x4_1024x1024_160k_cityscapes_20210902_015551-bcf10f09.pth
+- Name: bisenetv2_fcn_ohem_4x4_1024x1024_160k_cityscapes
+ In Collection: BiSeNetV2
+ Metadata:
+ backbone: BiSeNetV2
+ crop size: (1024,1024)
+ lr schd: 160000
+ Training Memory (GB): 7.64
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 73.57
+ mIoU(ms+flip): 75.8
+ Config: configs/bisenetv2/bisenetv2_fcn_ohem_4x4_1024x1024_160k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv2/bisenetv2_fcn_ohem_4x4_1024x1024_160k_cityscapes/bisenetv2_fcn_ohem_4x4_1024x1024_160k_cityscapes_20210902_112947-5f8103b4.pth
+- Name: bisenetv2_fcn_4x8_1024x1024_160k_cityscapes
+ In Collection: BiSeNetV2
+ Metadata:
+ backbone: BiSeNetV2
+ crop size: (1024,1024)
+ lr schd: 160000
+ Training Memory (GB): 15.05
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 75.76
+ mIoU(ms+flip): 77.79
+ Config: configs/bisenetv2/bisenetv2_fcn_4x8_1024x1024_160k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv2/bisenetv2_fcn_4x8_1024x1024_160k_cityscapes/bisenetv2_fcn_4x8_1024x1024_160k_cityscapes_20210903_000032-e1a2eed6.pth
+- Name: bisenetv2_fcn_fp16_4x4_1024x1024_160k_cityscapes
+ In Collection: BiSeNetV2
+ Metadata:
+ backbone: BiSeNetV2
+ crop size: (1024,1024)
+ lr schd: 160000
+ inference time (ms/im):
+ - value: 27.29
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP16
+ resolution: (1024,1024)
+ Training Memory (GB): 5.77
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 73.07
+ mIoU(ms+flip): 75.13
+ Config: configs/bisenetv2/bisenetv2_fcn_fp16_4x4_1024x1024_160k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/bisenetv2/bisenetv2_fcn_fp16_4x4_1024x1024_160k_cityscapes/bisenetv2_fcn_fp16_4x4_1024x1024_160k_cityscapes_20210902_045942-b979777b.pth
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/bisenetv2_fcn_4x4_1024x1024_160k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/bisenetv2_fcn_4x4_1024x1024_160k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..1248bd87aadd56cc41c4e9d95409a7387cb445fb
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/bisenetv2_fcn_4x4_1024x1024_160k_cityscapes.py
@@ -0,0 +1,11 @@
+_base_ = [
+ '../_base_/models/bisenetv2.py',
+ '../_base_/datasets/cityscapes_1024x1024.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_160k.py'
+]
+lr_config = dict(warmup='linear', warmup_iters=1000)
+optimizer = dict(lr=0.05)
+data = dict(
+ samples_per_gpu=4,
+ workers_per_gpu=4,
+)
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/bisenetv2_fcn_4x8_1024x1024_160k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/bisenetv2_fcn_4x8_1024x1024_160k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..5e93bea8be06bfec390ec718531b79b01b1e04bf
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/bisenetv2_fcn_4x8_1024x1024_160k_cityscapes.py
@@ -0,0 +1,11 @@
+_base_ = [
+ '../_base_/models/bisenetv2.py',
+ '../_base_/datasets/cityscapes_1024x1024.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_160k.py'
+]
+lr_config = dict(warmup='linear', warmup_iters=1000)
+optimizer = dict(lr=0.05)
+data = dict(
+ samples_per_gpu=8,
+ workers_per_gpu=4,
+)
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/bisenetv2_fcn_fp16_4x4_1024x1024_160k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/bisenetv2_fcn_fp16_4x4_1024x1024_160k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..0196214b7dfe21ad8408218d81b300c3dc7f2967
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/bisenetv2_fcn_fp16_4x4_1024x1024_160k_cityscapes.py
@@ -0,0 +1,5 @@
+_base_ = './bisenetv2_fcn_4x4_1024x1024_160k_cityscapes.py'
+# fp16 settings
+optimizer_config = dict(type='Fp16OptimizerHook', loss_scale=512.)
+# fp16 placeholder
+fp16 = dict()
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/bisenetv2_fcn_ohem_4x4_1024x1024_160k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/bisenetv2_fcn_ohem_4x4_1024x1024_160k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..f14e528130b1587db51ba8db2a5c3da4c5968866
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/bisenetv2/bisenetv2_fcn_ohem_4x4_1024x1024_160k_cityscapes.py
@@ -0,0 +1,12 @@
+_base_ = [
+ '../_base_/models/bisenetv2.py',
+ '../_base_/datasets/cityscapes_1024x1024.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_160k.py'
+]
+sampler = dict(type='OHEMPixelSampler', thresh=0.7, min_kept=10000)
+lr_config = dict(warmup='linear', warmup_iters=1000)
+optimizer = dict(lr=0.05)
+data = dict(
+ samples_per_gpu=4,
+ workers_per_gpu=4,
+)
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/README.md b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..9cefcf023e4da1a63666e3890ea0c2d0579eae2c
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/README.md
@@ -0,0 +1,67 @@
+# CCNet
+
+[CCNet: Criss-Cross Attention for Semantic Segmentation](https://arxiv.org/abs/1811.11721)
+
+## Introduction
+
+
+
+Official Repo
+
+Code Snippet
+
+## Abstract
+
+
+
+Contextual information is vital in visual understanding problems, such as semantic segmentation and object detection. We propose a Criss-Cross Network (CCNet) for obtaining full-image contextual information in a very effective and efficient way. Concretely, for each pixel, a novel criss-cross attention module harvests the contextual information of all the pixels on its criss-cross path. By taking a further recurrent operation, each pixel can finally capture the full-image dependencies. Besides, a category consistent loss is proposed to enforce the criss-cross attention module to produce more discriminative features. Overall, CCNet is with the following merits: 1) GPU memory friendly. Compared with the non-local block, the proposed recurrent criss-cross attention module requires 11x less GPU memory usage. 2) High computational efficiency. The recurrent criss-cross attention significantly reduces FLOPs by about 85% of the non-local block. 3) The state-of-the-art performance. We conduct extensive experiments on semantic segmentation benchmarks including Cityscapes, ADE20K, human parsing benchmark LIP, instance segmentation benchmark COCO, video segmentation benchmark CamVid. In particular, our CCNet achieves the mIoU scores of 81.9%, 45.76% and 55.47% on the Cityscapes test set, the ADE20K validation set and the LIP validation set respectively, which are the new state-of-the-art results. The source codes are available at [this https URL](https://github.com/speedinghzl/CCNet).
+
+
+
+
+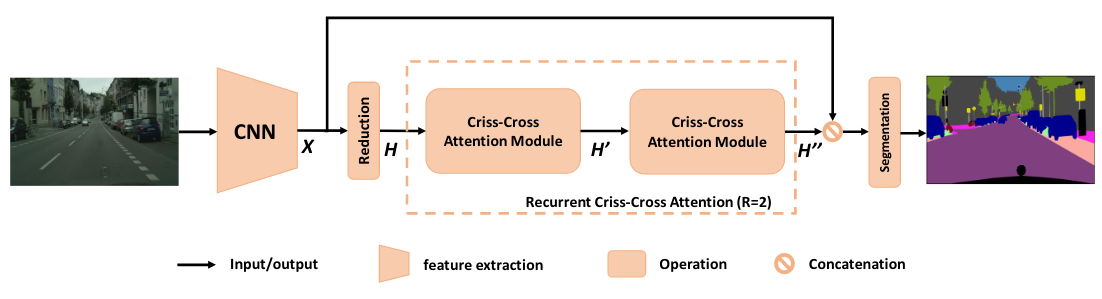 +
+
+## Citation
+
+```bibtex
+@article{huang2018ccnet,
+ title={CCNet: Criss-Cross Attention for Semantic Segmentation},
+ author={Huang, Zilong and Wang, Xinggang and Huang, Lichao and Huang, Chang and Wei, Yunchao and Liu, Wenyu},
+ booktitle={ICCV},
+ year={2019}
+}
+```
+
+
+## Results and models
+
+### Cityscapes
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| ------ | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | ------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
+| CCNet | R-50-D8 | 512x1024 | 40000 | 6 | 3.32 | 77.76 | 78.87 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet/ccnet_r50-d8_512x1024_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x1024_40k_cityscapes/ccnet_r50-d8_512x1024_40k_cityscapes_20200616_142517-4123f401.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x1024_40k_cityscapes/ccnet_r50-d8_512x1024_40k_cityscapes_20200616_142517.log.json) |
+| CCNet | R-101-D8 | 512x1024 | 40000 | 9.5 | 2.31 | 76.35 | 78.19 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet/ccnet_r101-d8_512x1024_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x1024_40k_cityscapes/ccnet_r101-d8_512x1024_40k_cityscapes_20200616_142540-a3b84ba6.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x1024_40k_cityscapes/ccnet_r101-d8_512x1024_40k_cityscapes_20200616_142540.log.json) |
+| CCNet | R-50-D8 | 769x769 | 40000 | 6.8 | 1.43 | 78.46 | 79.93 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet/ccnet_r50-d8_769x769_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_769x769_40k_cityscapes/ccnet_r50-d8_769x769_40k_cityscapes_20200616_145125-76d11884.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_769x769_40k_cityscapes/ccnet_r50-d8_769x769_40k_cityscapes_20200616_145125.log.json) |
+| CCNet | R-101-D8 | 769x769 | 40000 | 10.7 | 1.01 | 76.94 | 78.62 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet/ccnet_r101-d8_769x769_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_769x769_40k_cityscapes/ccnet_r101-d8_769x769_40k_cityscapes_20200617_101428-4f57c8d0.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_769x769_40k_cityscapes/ccnet_r101-d8_769x769_40k_cityscapes_20200617_101428.log.json) |
+| CCNet | R-50-D8 | 512x1024 | 80000 | - | - | 79.03 | 80.16 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet/ccnet_r50-d8_512x1024_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x1024_80k_cityscapes/ccnet_r50-d8_512x1024_80k_cityscapes_20200617_010421-869a3423.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x1024_80k_cityscapes/ccnet_r50-d8_512x1024_80k_cityscapes_20200617_010421.log.json) |
+| CCNet | R-101-D8 | 512x1024 | 80000 | - | - | 78.87 | 79.90 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet/ccnet_r101-d8_512x1024_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x1024_80k_cityscapes/ccnet_r101-d8_512x1024_80k_cityscapes_20200617_203935-ffae8917.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x1024_80k_cityscapes/ccnet_r101-d8_512x1024_80k_cityscapes_20200617_203935.log.json) |
+| CCNet | R-50-D8 | 769x769 | 80000 | - | - | 79.29 | 81.08 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet/ccnet_r50-d8_769x769_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_769x769_80k_cityscapes/ccnet_r50-d8_769x769_80k_cityscapes_20200617_010421-73eed8ca.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_769x769_80k_cityscapes/ccnet_r50-d8_769x769_80k_cityscapes_20200617_010421.log.json) |
+| CCNet | R-101-D8 | 769x769 | 80000 | - | - | 79.45 | 80.66 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet/ccnet_r101-d8_769x769_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_769x769_80k_cityscapes/ccnet_r101-d8_769x769_80k_cityscapes_20200618_011502-ad3cd481.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_769x769_80k_cityscapes/ccnet_r101-d8_769x769_80k_cityscapes_20200618_011502.log.json) |
+
+### ADE20K
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| ------ | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | --------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
+| CCNet | R-50-D8 | 512x512 | 80000 | 8.8 | 20.89 | 41.78 | 42.98 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet/ccnet_r50-d8_512x512_80k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x512_80k_ade20k/ccnet_r50-d8_512x512_80k_ade20k_20200615_014848-aa37f61e.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x512_80k_ade20k/ccnet_r50-d8_512x512_80k_ade20k_20200615_014848.log.json) |
+| CCNet | R-101-D8 | 512x512 | 80000 | 12.2 | 14.11 | 43.97 | 45.13 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet/ccnet_r101-d8_512x512_80k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x512_80k_ade20k/ccnet_r101-d8_512x512_80k_ade20k_20200615_014848-1f4929a3.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x512_80k_ade20k/ccnet_r101-d8_512x512_80k_ade20k_20200615_014848.log.json) |
+| CCNet | R-50-D8 | 512x512 | 160000 | - | - | 42.08 | 43.13 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet/ccnet_r50-d8_512x512_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x512_160k_ade20k/ccnet_r50-d8_512x512_160k_ade20k_20200616_084435-7c97193b.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x512_160k_ade20k/ccnet_r50-d8_512x512_160k_ade20k_20200616_084435.log.json) |
+| CCNet | R-101-D8 | 512x512 | 160000 | - | - | 43.71 | 45.04 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet/ccnet_r101-d8_512x512_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x512_160k_ade20k/ccnet_r101-d8_512x512_160k_ade20k_20200616_000644-e849e007.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x512_160k_ade20k/ccnet_r101-d8_512x512_160k_ade20k_20200616_000644.log.json) |
+
+### Pascal VOC 2012 + Aug
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| ------ | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | ---------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
+| CCNet | R-50-D8 | 512x512 | 20000 | 6 | 20.45 | 76.17 | 77.51 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet/ccnet_r50-d8_512x512_20k_voc12aug.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x512_20k_voc12aug/ccnet_r50-d8_512x512_20k_voc12aug_20200617_193212-fad81784.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x512_20k_voc12aug/ccnet_r50-d8_512x512_20k_voc12aug_20200617_193212.log.json) |
+| CCNet | R-101-D8 | 512x512 | 20000 | 9.5 | 13.64 | 77.27 | 79.02 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet/ccnet_r101-d8_512x512_20k_voc12aug.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x512_20k_voc12aug/ccnet_r101-d8_512x512_20k_voc12aug_20200617_193212-0007b61d.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x512_20k_voc12aug/ccnet_r101-d8_512x512_20k_voc12aug_20200617_193212.log.json) |
+| CCNet | R-50-D8 | 512x512 | 40000 | - | - | 75.96 | 77.04 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet/ccnet_r50-d8_512x512_40k_voc12aug.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x512_40k_voc12aug/ccnet_r50-d8_512x512_40k_voc12aug_20200613_232127-c2a15f02.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x512_40k_voc12aug/ccnet_r50-d8_512x512_40k_voc12aug_20200613_232127.log.json) |
+| CCNet | R-101-D8 | 512x512 | 40000 | - | - | 77.87 | 78.90 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet/ccnet_r101-d8_512x512_40k_voc12aug.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x512_40k_voc12aug/ccnet_r101-d8_512x512_40k_voc12aug_20200613_232127-c30da577.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x512_40k_voc12aug/ccnet_r101-d8_512x512_40k_voc12aug_20200613_232127.log.json) |
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet.yml b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet.yml
new file mode 100644
index 0000000000000000000000000000000000000000..b264f2e6c20f7eef1924ee4a63dc0d92dd3bab71
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet.yml
@@ -0,0 +1,305 @@
+Collections:
+- Name: CCNet
+ Metadata:
+ Training Data:
+ - Cityscapes
+ - ADE20K
+ - Pascal VOC 2012 + Aug
+ Paper:
+ URL: https://arxiv.org/abs/1811.11721
+ Title: 'CCNet: Criss-Cross Attention for Semantic Segmentation'
+ README: configs/ccnet/README.md
+ Code:
+ URL: https://github.com/open-mmlab/mmsegmentation/blob/v0.17.0/mmseg/models/decode_heads/apc_head.py#L111
+ Version: v0.17.0
+ Converted From:
+ Code: https://github.com/speedinghzl/CCNet
+Models:
+- Name: ccnet_r50-d8_512x1024_40k_cityscapes
+ In Collection: CCNet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,1024)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 301.2
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,1024)
+ Training Memory (GB): 6.0
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 77.76
+ mIoU(ms+flip): 78.87
+ Config: configs/ccnet/ccnet_r50-d8_512x1024_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x1024_40k_cityscapes/ccnet_r50-d8_512x1024_40k_cityscapes_20200616_142517-4123f401.pth
+- Name: ccnet_r101-d8_512x1024_40k_cityscapes
+ In Collection: CCNet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,1024)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 432.9
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,1024)
+ Training Memory (GB): 9.5
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 76.35
+ mIoU(ms+flip): 78.19
+ Config: configs/ccnet/ccnet_r101-d8_512x1024_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x1024_40k_cityscapes/ccnet_r101-d8_512x1024_40k_cityscapes_20200616_142540-a3b84ba6.pth
+- Name: ccnet_r50-d8_769x769_40k_cityscapes
+ In Collection: CCNet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (769,769)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 699.3
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (769,769)
+ Training Memory (GB): 6.8
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 78.46
+ mIoU(ms+flip): 79.93
+ Config: configs/ccnet/ccnet_r50-d8_769x769_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_769x769_40k_cityscapes/ccnet_r50-d8_769x769_40k_cityscapes_20200616_145125-76d11884.pth
+- Name: ccnet_r101-d8_769x769_40k_cityscapes
+ In Collection: CCNet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (769,769)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 990.1
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (769,769)
+ Training Memory (GB): 10.7
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 76.94
+ mIoU(ms+flip): 78.62
+ Config: configs/ccnet/ccnet_r101-d8_769x769_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_769x769_40k_cityscapes/ccnet_r101-d8_769x769_40k_cityscapes_20200617_101428-4f57c8d0.pth
+- Name: ccnet_r50-d8_512x1024_80k_cityscapes
+ In Collection: CCNet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,1024)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 79.03
+ mIoU(ms+flip): 80.16
+ Config: configs/ccnet/ccnet_r50-d8_512x1024_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x1024_80k_cityscapes/ccnet_r50-d8_512x1024_80k_cityscapes_20200617_010421-869a3423.pth
+- Name: ccnet_r101-d8_512x1024_80k_cityscapes
+ In Collection: CCNet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,1024)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 78.87
+ mIoU(ms+flip): 79.9
+ Config: configs/ccnet/ccnet_r101-d8_512x1024_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x1024_80k_cityscapes/ccnet_r101-d8_512x1024_80k_cityscapes_20200617_203935-ffae8917.pth
+- Name: ccnet_r50-d8_769x769_80k_cityscapes
+ In Collection: CCNet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (769,769)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 79.29
+ mIoU(ms+flip): 81.08
+ Config: configs/ccnet/ccnet_r50-d8_769x769_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_769x769_80k_cityscapes/ccnet_r50-d8_769x769_80k_cityscapes_20200617_010421-73eed8ca.pth
+- Name: ccnet_r101-d8_769x769_80k_cityscapes
+ In Collection: CCNet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (769,769)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 79.45
+ mIoU(ms+flip): 80.66
+ Config: configs/ccnet/ccnet_r101-d8_769x769_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_769x769_80k_cityscapes/ccnet_r101-d8_769x769_80k_cityscapes_20200618_011502-ad3cd481.pth
+- Name: ccnet_r50-d8_512x512_80k_ade20k
+ In Collection: CCNet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 47.87
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 8.8
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 41.78
+ mIoU(ms+flip): 42.98
+ Config: configs/ccnet/ccnet_r50-d8_512x512_80k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x512_80k_ade20k/ccnet_r50-d8_512x512_80k_ade20k_20200615_014848-aa37f61e.pth
+- Name: ccnet_r101-d8_512x512_80k_ade20k
+ In Collection: CCNet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 70.87
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 12.2
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 43.97
+ mIoU(ms+flip): 45.13
+ Config: configs/ccnet/ccnet_r101-d8_512x512_80k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x512_80k_ade20k/ccnet_r101-d8_512x512_80k_ade20k_20200615_014848-1f4929a3.pth
+- Name: ccnet_r50-d8_512x512_160k_ade20k
+ In Collection: CCNet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 160000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 42.08
+ mIoU(ms+flip): 43.13
+ Config: configs/ccnet/ccnet_r50-d8_512x512_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x512_160k_ade20k/ccnet_r50-d8_512x512_160k_ade20k_20200616_084435-7c97193b.pth
+- Name: ccnet_r101-d8_512x512_160k_ade20k
+ In Collection: CCNet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 160000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 43.71
+ mIoU(ms+flip): 45.04
+ Config: configs/ccnet/ccnet_r101-d8_512x512_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x512_160k_ade20k/ccnet_r101-d8_512x512_160k_ade20k_20200616_000644-e849e007.pth
+- Name: ccnet_r50-d8_512x512_20k_voc12aug
+ In Collection: CCNet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 20000
+ inference time (ms/im):
+ - value: 48.9
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 6.0
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal VOC 2012 + Aug
+ Metrics:
+ mIoU: 76.17
+ mIoU(ms+flip): 77.51
+ Config: configs/ccnet/ccnet_r50-d8_512x512_20k_voc12aug.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x512_20k_voc12aug/ccnet_r50-d8_512x512_20k_voc12aug_20200617_193212-fad81784.pth
+- Name: ccnet_r101-d8_512x512_20k_voc12aug
+ In Collection: CCNet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 20000
+ inference time (ms/im):
+ - value: 73.31
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 9.5
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal VOC 2012 + Aug
+ Metrics:
+ mIoU: 77.27
+ mIoU(ms+flip): 79.02
+ Config: configs/ccnet/ccnet_r101-d8_512x512_20k_voc12aug.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x512_20k_voc12aug/ccnet_r101-d8_512x512_20k_voc12aug_20200617_193212-0007b61d.pth
+- Name: ccnet_r50-d8_512x512_40k_voc12aug
+ In Collection: CCNet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 40000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal VOC 2012 + Aug
+ Metrics:
+ mIoU: 75.96
+ mIoU(ms+flip): 77.04
+ Config: configs/ccnet/ccnet_r50-d8_512x512_40k_voc12aug.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r50-d8_512x512_40k_voc12aug/ccnet_r50-d8_512x512_40k_voc12aug_20200613_232127-c2a15f02.pth
+- Name: ccnet_r101-d8_512x512_40k_voc12aug
+ In Collection: CCNet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 40000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal VOC 2012 + Aug
+ Metrics:
+ mIoU: 77.87
+ mIoU(ms+flip): 78.9
+ Config: configs/ccnet/ccnet_r101-d8_512x512_40k_voc12aug.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/ccnet/ccnet_r101-d8_512x512_40k_voc12aug/ccnet_r101-d8_512x512_40k_voc12aug_20200613_232127-c30da577.pth
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x1024_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x1024_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..d2bac38ca6760af6441ede5a04409ed495ef87f3
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x1024_40k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './ccnet_r50-d8_512x1024_40k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x1024_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x1024_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..989928ab7f98da86e291451040ff85669a9fbddb
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x1024_80k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './ccnet_r50-d8_512x1024_80k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x512_160k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x512_160k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..c32bf48751f0a18983bff0d99310870b71801663
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x512_160k_ade20k.py
@@ -0,0 +1,2 @@
+_base_ = './ccnet_r50-d8_512x512_160k_ade20k.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x512_20k_voc12aug.py b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x512_20k_voc12aug.py
new file mode 100644
index 0000000000000000000000000000000000000000..53eb77c0cd6690668ee7c2a666bd85b9a5f7e73b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x512_20k_voc12aug.py
@@ -0,0 +1,2 @@
+_base_ = './ccnet_r50-d8_512x512_20k_voc12aug.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x512_40k_voc12aug.py b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x512_40k_voc12aug.py
new file mode 100644
index 0000000000000000000000000000000000000000..d7eb668f39bbd22a1f42628428bc19d1645e9865
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x512_40k_voc12aug.py
@@ -0,0 +1,2 @@
+_base_ = './ccnet_r50-d8_512x512_40k_voc12aug.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x512_80k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x512_80k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..029c1d525b809b61dc8e548ebe4fb26e5c68a8be
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_512x512_80k_ade20k.py
@@ -0,0 +1,2 @@
+_base_ = './ccnet_r50-d8_512x512_80k_ade20k.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_769x769_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_769x769_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..43f05fab05ee4e20c3509a923118fe9818543cbd
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_769x769_40k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './ccnet_r50-d8_769x769_40k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_769x769_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_769x769_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..654f377b6f6152c9bd98d33824a39a41d7510c3f
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r101-d8_769x769_80k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './ccnet_r50-d8_769x769_80k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x1024_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x1024_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..6a4316dde57206fe369e72fa0d32a529fe1a1932
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x1024_40k_cityscapes.py
@@ -0,0 +1,4 @@
+_base_ = [
+ '../_base_/models/ccnet_r50-d8.py', '../_base_/datasets/cityscapes.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_40k.py'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x1024_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x1024_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..16e34356e9f8566ec73e3c25c771e281d3eeb975
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x1024_80k_cityscapes.py
@@ -0,0 +1,4 @@
+_base_ = [
+ '../_base_/models/ccnet_r50-d8.py', '../_base_/datasets/cityscapes.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_80k.py'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x512_160k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x512_160k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..1ad94d8988bb822c1571816255464126d9d5b95d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x512_160k_ade20k.py
@@ -0,0 +1,6 @@
+_base_ = [
+ '../_base_/models/ccnet_r50-d8.py', '../_base_/datasets/ade20k.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_160k.py'
+]
+model = dict(
+ decode_head=dict(num_classes=150), auxiliary_head=dict(num_classes=150))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x512_20k_voc12aug.py b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x512_20k_voc12aug.py
new file mode 100644
index 0000000000000000000000000000000000000000..bbcd29ccea8dcf9f67f1cd198dacd5dab380b265
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x512_20k_voc12aug.py
@@ -0,0 +1,7 @@
+_base_ = [
+ '../_base_/models/ccnet_r50-d8.py',
+ '../_base_/datasets/pascal_voc12_aug.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_20k.py'
+]
+model = dict(
+ decode_head=dict(num_classes=21), auxiliary_head=dict(num_classes=21))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x512_40k_voc12aug.py b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x512_40k_voc12aug.py
new file mode 100644
index 0000000000000000000000000000000000000000..947b8ac8ce1ddf7906ad39788c6992df3b506d29
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x512_40k_voc12aug.py
@@ -0,0 +1,7 @@
+_base_ = [
+ '../_base_/models/ccnet_r50-d8.py',
+ '../_base_/datasets/pascal_voc12_aug.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_40k.py'
+]
+model = dict(
+ decode_head=dict(num_classes=21), auxiliary_head=dict(num_classes=21))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x512_80k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x512_80k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..1a1f49cf6b112afdadf1841571f51b98c010ddf8
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_512x512_80k_ade20k.py
@@ -0,0 +1,6 @@
+_base_ = [
+ '../_base_/models/ccnet_r50-d8.py', '../_base_/datasets/ade20k.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_80k.py'
+]
+model = dict(
+ decode_head=dict(num_classes=150), auxiliary_head=dict(num_classes=150))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_769x769_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_769x769_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..580d59ca6995ea95a9345ef3ea574ea5b57e9cfb
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_769x769_40k_cityscapes.py
@@ -0,0 +1,9 @@
+_base_ = [
+ '../_base_/models/ccnet_r50-d8.py',
+ '../_base_/datasets/cityscapes_769x769.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_40k.py'
+]
+model = dict(
+ decode_head=dict(align_corners=True),
+ auxiliary_head=dict(align_corners=True),
+ test_cfg=dict(mode='slide', crop_size=(769, 769), stride=(513, 513)))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_769x769_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_769x769_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..c6dac64377bb3f73fdf5c836fa9c38757f75ff76
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/ccnet/ccnet_r50-d8_769x769_80k_cityscapes.py
@@ -0,0 +1,9 @@
+_base_ = [
+ '../_base_/models/ccnet_r50-d8.py',
+ '../_base_/datasets/cityscapes_769x769.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_80k.py'
+]
+model = dict(
+ decode_head=dict(align_corners=True),
+ auxiliary_head=dict(align_corners=True),
+ test_cfg=dict(mode='slide', crop_size=(769, 769), stride=(513, 513)))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/cgnet/README.md b/EgoHOS/raw/script/mmsegmentation/configs/cgnet/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..fefb291404732d03ba6c25ca0b7875e1a937d497
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/cgnet/README.md
@@ -0,0 +1,45 @@
+# CGNet
+
+[CGNet: A Light-weight Context Guided Network for Semantic Segmentation](https://arxiv.org/abs/1811.08201)
+
+## Introduction
+
+
+
+Official Repo
+
+Code Snippet
+
+## Abstract
+
+
+
+The demand of applying semantic segmentation model on mobile devices has been increasing rapidly. Current state-of-the-art networks have enormous amount of parameters hence unsuitable for mobile devices, while other small memory footprint models follow the spirit of classification network and ignore the inherent characteristic of semantic segmentation. To tackle this problem, we propose a novel Context Guided Network (CGNet), which is a light-weight and efficient network for semantic segmentation. We first propose the Context Guided (CG) block, which learns the joint feature of both local feature and surrounding context, and further improves the joint feature with the global context. Based on the CG block, we develop CGNet which captures contextual information in all stages of the network and is specially tailored for increasing segmentation accuracy. CGNet is also elaborately designed to reduce the number of parameters and save memory footprint. Under an equivalent number of parameters, the proposed CGNet significantly outperforms existing segmentation networks. Extensive experiments on Cityscapes and CamVid datasets verify the effectiveness of the proposed approach. Specifically, without any post-processing and multi-scale testing, the proposed CGNet achieves 64.8% mean IoU on Cityscapes with less than 0.5 M parameters. The source code for the complete system can be found at [this https URL](https://github.com/wutianyiRosun/CGNet).
+
+
+
+
+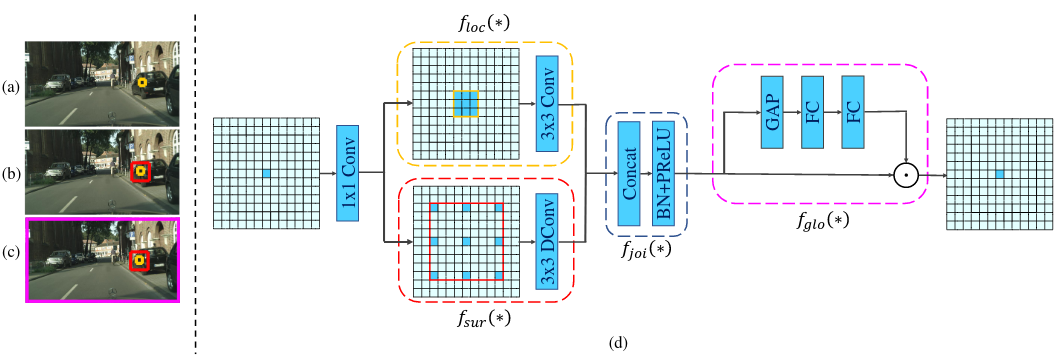 +
+
+## Citation
+
+```bibtext
+@article{wu2020cgnet,
+ title={Cgnet: A light-weight context guided network for semantic segmentation},
+ author={Wu, Tianyi and Tang, Sheng and Zhang, Rui and Cao, Juan and Zhang, Yongdong},
+ journal={IEEE Transactions on Image Processing},
+ volume={30},
+ pages={1169--1179},
+ year={2020},
+ publisher={IEEE}
+}
+```
+
+## Results and models
+
+### Cityscapes
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| ------ | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | ----------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
+| CGNet | M3N21 | 680x680 | 60000 | 7.5 | 30.51 | 65.63 | 68.04 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/cgnet/cgnet_680x680_60k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/cgnet/cgnet_680x680_60k_cityscapes/cgnet_680x680_60k_cityscapes_20201101_110253-4c0b2f2d.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/cgnet/cgnet_680x680_60k_cityscapes/cgnet_680x680_60k_cityscapes-20201101_110253.log.json) |
+| CGNet | M3N21 | 512x1024 | 60000 | 8.3 | 31.14 | 68.27 | 70.33 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/cgnet/cgnet_512x1024_60k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/cgnet/cgnet_512x1024_60k_cityscapes/cgnet_512x1024_60k_cityscapes_20201101_110254-124ea03b.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/cgnet/cgnet_512x1024_60k_cityscapes/cgnet_512x1024_60k_cityscapes-20201101_110254.log.json) |
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/cgnet/cgnet.yml b/EgoHOS/raw/script/mmsegmentation/configs/cgnet/cgnet.yml
new file mode 100644
index 0000000000000000000000000000000000000000..bcd6d89c1bdbfb63e94faa4a65f14e8373cf752c
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/cgnet/cgnet.yml
@@ -0,0 +1,59 @@
+Collections:
+- Name: CGNet
+ Metadata:
+ Training Data:
+ - Cityscapes
+ Paper:
+ URL: https://arxiv.org/abs/1811.08201
+ Title: 'CGNet: A Light-weight Context Guided Network for Semantic Segmentation'
+ README: configs/cgnet/README.md
+ Code:
+ URL: https://github.com/open-mmlab/mmsegmentation/blob/v0.17.0/mmseg/models/backbones/cgnet.py#L187
+ Version: v0.17.0
+ Converted From:
+ Code: https://github.com/wutianyiRosun/CGNet
+Models:
+- Name: cgnet_680x680_60k_cityscapes
+ In Collection: CGNet
+ Metadata:
+ backbone: M3N21
+ crop size: (680,680)
+ lr schd: 60000
+ inference time (ms/im):
+ - value: 32.78
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (680,680)
+ Training Memory (GB): 7.5
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 65.63
+ mIoU(ms+flip): 68.04
+ Config: configs/cgnet/cgnet_680x680_60k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/cgnet/cgnet_680x680_60k_cityscapes/cgnet_680x680_60k_cityscapes_20201101_110253-4c0b2f2d.pth
+- Name: cgnet_512x1024_60k_cityscapes
+ In Collection: CGNet
+ Metadata:
+ backbone: M3N21
+ crop size: (512,1024)
+ lr schd: 60000
+ inference time (ms/im):
+ - value: 32.11
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,1024)
+ Training Memory (GB): 8.3
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 68.27
+ mIoU(ms+flip): 70.33
+ Config: configs/cgnet/cgnet_512x1024_60k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/cgnet/cgnet_512x1024_60k_cityscapes/cgnet_512x1024_60k_cityscapes_20201101_110254-124ea03b.pth
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/cgnet/cgnet_512x1024_60k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/cgnet/cgnet_512x1024_60k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..6efc4cd5c8604d355bf1cd7d02c5528874b858a4
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/cgnet/cgnet_512x1024_60k_cityscapes.py
@@ -0,0 +1,66 @@
+_base_ = ['../_base_/models/cgnet.py', '../_base_/default_runtime.py']
+
+# optimizer
+optimizer = dict(type='Adam', lr=0.001, eps=1e-08, weight_decay=0.0005)
+optimizer_config = dict()
+# learning policy
+lr_config = dict(policy='poly', power=0.9, min_lr=1e-4, by_epoch=False)
+# runtime settings
+total_iters = 60000
+checkpoint_config = dict(by_epoch=False, interval=4000)
+evaluation = dict(interval=4000, metric='mIoU')
+
+# dataset settings
+dataset_type = 'CityscapesDataset'
+data_root = 'data/cityscapes/'
+img_norm_cfg = dict(
+ mean=[72.39239876, 82.90891754, 73.15835921], std=[1, 1, 1], to_rgb=True)
+crop_size = (512, 1024)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=(2048, 1024), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', flip_ratio=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2048, 1024),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=8,
+ workers_per_gpu=4,
+ train=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='leftImg8bit/train',
+ ann_dir='gtFine/train',
+ pipeline=train_pipeline),
+ val=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='leftImg8bit/val',
+ ann_dir='gtFine/val',
+ pipeline=test_pipeline),
+ test=dict(
+ type=dataset_type,
+ data_root=data_root,
+ img_dir='leftImg8bit/val',
+ ann_dir='gtFine/val',
+ pipeline=test_pipeline))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/cgnet/cgnet_680x680_60k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/cgnet/cgnet_680x680_60k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..7d4ebe136533fc35e05e0c514511d041f092cfd2
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/cgnet/cgnet_680x680_60k_cityscapes.py
@@ -0,0 +1,50 @@
+_base_ = [
+ '../_base_/models/cgnet.py', '../_base_/datasets/cityscapes.py',
+ '../_base_/default_runtime.py'
+]
+
+# optimizer
+optimizer = dict(type='Adam', lr=0.001, eps=1e-08, weight_decay=0.0005)
+optimizer_config = dict()
+# learning policy
+lr_config = dict(policy='poly', power=0.9, min_lr=1e-4, by_epoch=False)
+# runtime settings
+total_iters = 60000
+checkpoint_config = dict(by_epoch=False, interval=4000)
+evaluation = dict(interval=4000, metric='mIoU')
+
+img_norm_cfg = dict(
+ mean=[72.39239876, 82.90891754, 73.15835921], std=[1, 1, 1], to_rgb=True)
+crop_size = (680, 680)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=(2048, 1024), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size),
+ dict(type='RandomFlip', flip_ratio=0.5),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2048, 1024),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ samples_per_gpu=8,
+ workers_per_gpu=4,
+ train=dict(pipeline=train_pipeline),
+ val=dict(pipeline=test_pipeline),
+ test=dict(pipeline=test_pipeline))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/convnext/README.md b/EgoHOS/raw/script/mmsegmentation/configs/convnext/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..48c37afb049d6c0e12da22860064ec637615e335
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/convnext/README.md
@@ -0,0 +1,71 @@
+# ConvNeXt
+
+[A ConvNet for the 2020s](https://arxiv.org/abs/2201.03545)
+
+## Introduction
+
+
+
+Official Repo
+
+Code Snippet
+
+## Abstract
+
+
+
+The "Roaring 20s" of visual recognition began with the introduction of Vision Transformers (ViTs), which quickly superseded ConvNets as the state-of-the-art image classification model. A vanilla ViT, on the other hand, faces difficulties when applied to general computer vision tasks such as object detection and semantic segmentation. It is the hierarchical Transformers (e.g., Swin Transformers) that reintroduced several ConvNet priors, making Transformers practically viable as a generic vision backbone and demonstrating remarkable performance on a wide variety of vision tasks. However, the effectiveness of such hybrid approaches is still largely credited to the intrinsic superiority of Transformers, rather than the inherent inductive biases of convolutions. In this work, we reexamine the design spaces and test the limits of what a pure ConvNet can achieve. We gradually "modernize" a standard ResNet toward the design of a vision Transformer, and discover several key components that contribute to the performance difference along the way. The outcome of this exploration is a family of pure ConvNet models dubbed ConvNeXt. Constructed entirely from standard ConvNet modules, ConvNeXts compete favorably with Transformers in terms of accuracy and scalability, achieving 87.8% ImageNet top-1 accuracy and outperforming Swin Transformers on COCO detection and ADE20K segmentation, while maintaining the simplicity and efficiency of standard ConvNets.
+
+
+
+
+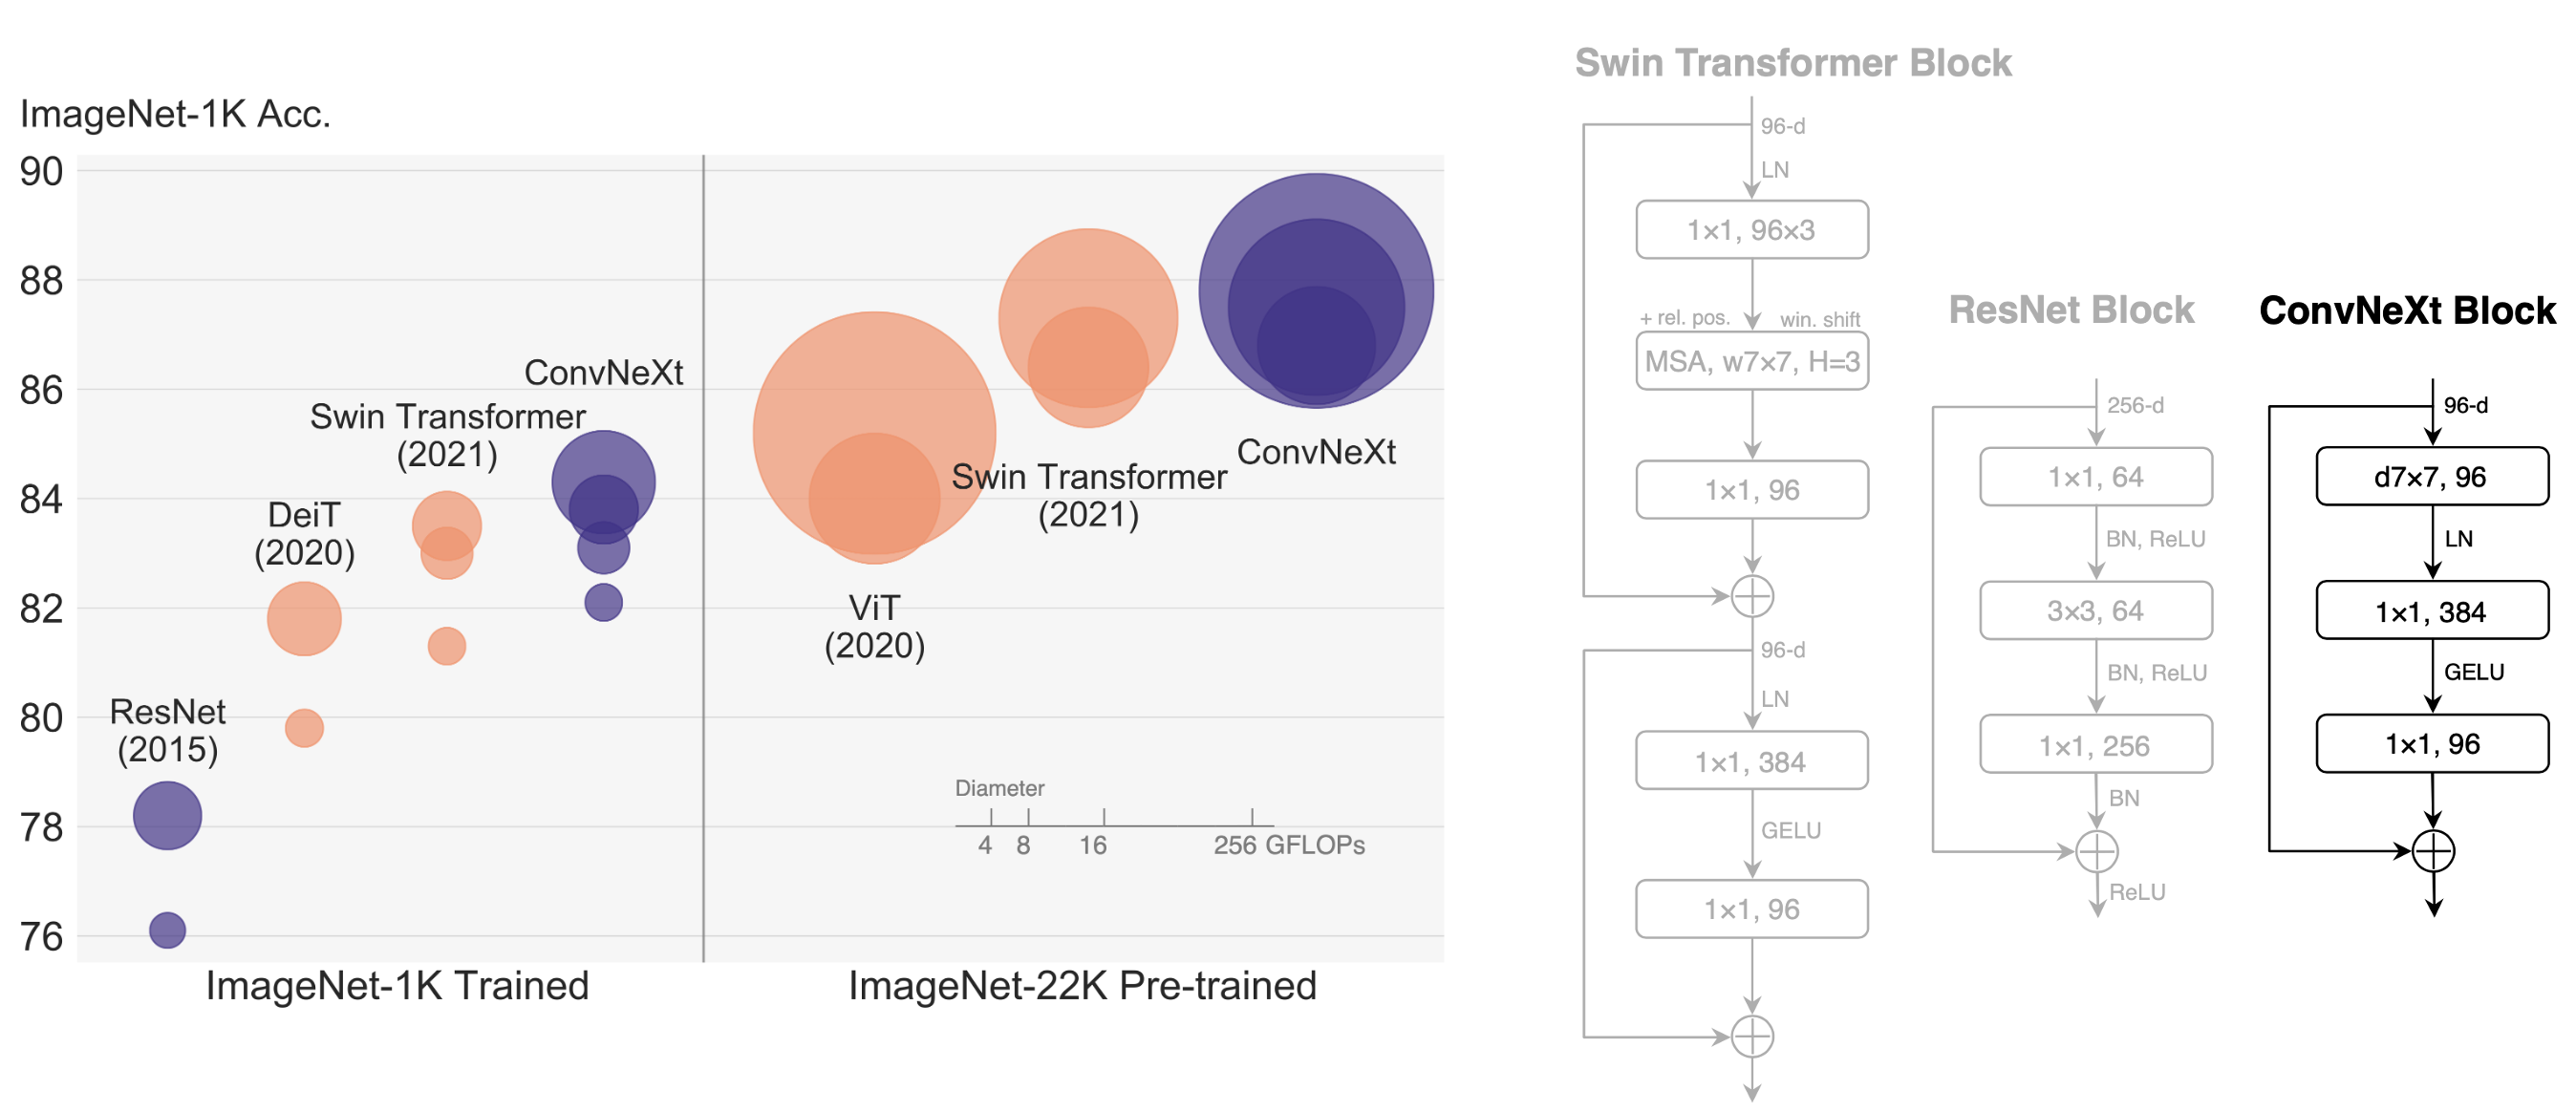 +
+
+```bibtex
+@article{liu2022convnet,
+ title={A ConvNet for the 2020s},
+ author={Liu, Zhuang and Mao, Hanzi and Wu, Chao-Yuan and Feichtenhofer, Christoph and Darrell, Trevor and Xie, Saining},
+ journal={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
+ year={2022}
+}
+```
+
+### Usage
+
+- ConvNeXt backbone needs to install [MMClassification](https://github.com/open-mmlab/mmclassification) first, which has abundant backbones for downstream tasks.
+
+```shell
+pip install mmcls>=0.20.1
+```
+
+### Pre-trained Models
+
+The pre-trained models on ImageNet-1k or ImageNet-21k are used to fine-tune on the downstream tasks.
+
+| Model | Training Data | Params(M) | Flops(G) | Download |
+|:--------------:|:-------------:|:---------:|:--------:|:--------:|
+| ConvNeXt-T\* | ImageNet-1k | 28.59 | 4.46 | [model](https://download.openmmlab.com/mmclassification/v0/convnext/downstream/convnext-tiny_3rdparty_32xb128-noema_in1k_20220301-795e9634.pth) |
+| ConvNeXt-S\* | ImageNet-1k | 50.22 | 8.69 | [model](https://download.openmmlab.com/mmclassification/v0/convnext/downstream/convnext-small_3rdparty_32xb128-noema_in1k_20220301-303e75e3.pth) |
+| ConvNeXt-B\* | ImageNet-1k | 88.59 | 15.36 | [model](https://download.openmmlab.com/mmclassification/v0/convnext/downstream/convnext-base_3rdparty_32xb128-noema_in1k_20220301-2a0ee547.pth) |
+| ConvNeXt-B\* | ImageNet-21k | 88.59 | 15.36 | [model](https://download.openmmlab.com/mmclassification/v0/convnext/downstream/convnext-base_3rdparty_in21k_20220301-262fd037.pth) |
+| ConvNeXt-L\* | ImageNet-21k | 197.77 | 34.37 | [model](https://download.openmmlab.com/mmclassification/v0/convnext/downstream/convnext-large_3rdparty_in21k_20220301-e6e0ea0a.pth) |
+| ConvNeXt-XL\* | ImageNet-21k | 350.20 | 60.93 | [model](https://download.openmmlab.com/mmclassification/v0/convnext/downstream/convnext-xlarge_3rdparty_in21k_20220301-08aa5ddc.pth) |
+
+*Models with \* are converted from the [official repo](https://github.com/facebookresearch/ConvNeXt/tree/main/semantic_segmentation#results-and-fine-tuned-models).*
+
+## Results and models
+
+### ADE20K
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| ------ | -------- | --------- | ---------- | ------- | -------- | --- | --- | -------------- | ----- |
+| UperNet | ConvNeXt-T | 512x512 | 160000 | 4.23 | 19.90 | 46.11 | 46.62 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/convnext/upernet_convnext_tiny_fp16_512x512_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_tiny_fp16_512x512_160k_ade20k/upernet_convnext_tiny_fp16_512x512_160k_ade20k_20220227_124553-cad485de.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_tiny_fp16_512x512_160k_ade20k/upernet_convnext_tiny_fp16_512x512_160k_ade20k_20220227_124553.log.json) |
+| UperNet | ConvNeXt-S | 512x512 | 160000 | 5.16 | 15.18 | 48.56 | 49.02 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/convnext/upernet_convnext_small_fp16_512x512_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_small_fp16_512x512_160k_ade20k/upernet_convnext_small_fp16_512x512_160k_ade20k_20220227_131208-1b1e394f.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_small_fp16_512x512_160k_ade20k/upernet_convnext_small_fp16_512x512_160k_ade20k_20220227_131208.log.json) |
+| UperNet | ConvNeXt-B | 512x512 | 160000 | 6.33 | 14.41 | 48.71 | 49.54 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/convnext/upernet_convnext_base_fp16_512x512_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_base_fp16_512x512_160k_ade20k/upernet_convnext_base_fp16_512x512_160k_ade20k_20220227_181227-02a24fc6.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_base_fp16_512x512_160k_ade20k/upernet_convnext_base_fp16_512x512_160k_ade20k_20220227_181227.log.json) |
+| UperNet | ConvNeXt-B |640x640 | 160000 | 8.53 | 10.88 | 52.13 | 52.66 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/convnext/upernet_convnext_base_fp16_640x640_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_base_fp16_640x640_160k_ade20k/upernet_convnext_base_fp16_640x640_160k_ade20k_20220227_182859-9280e39b.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_base_fp16_640x640_160k_ade20k/upernet_convnext_base_fp16_640x640_160k_ade20k_20220227_182859.log.json) |
+| UperNet | ConvNeXt-L |640x640 | 160000 | 12.08 | 7.69 | 53.16 | 53.38 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/convnext/upernet_convnext_large_fp16_640x640_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_large_fp16_640x640_160k_ade20k/upernet_convnext_large_fp16_640x640_160k_ade20k_20220226_040532-e57aa54d.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_large_fp16_640x640_160k_ade20k/upernet_convnext_large_fp16_640x640_160k_ade20k_20220226_040532.log.json) |
+| UperNet | ConvNeXt-XL |640x640 | 160000 | 26.16\* | 6.33 | 53.58 | 54.11 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/convnext/upernet_convnext_xlarge_fp16_640x640_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_xlarge_fp16_640x640_160k_ade20k/upernet_convnext_xlarge_fp16_640x640_160k_ade20k_20220226_080344-95fc38c2.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_xlarge_fp16_640x640_160k_ade20k/upernet_convnext_xlarge_fp16_640x640_160k_ade20k_20220226_080344.log.json) |
+
+Note:
+
+- `Mem (GB)` with \* is collected when `cudnn_benchmark=True`, and hardware is V100.
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/convnext/convnext.yml b/EgoHOS/raw/script/mmsegmentation/configs/convnext/convnext.yml
new file mode 100644
index 0000000000000000000000000000000000000000..3e521eff3e67a0dc4f4e9560bb7dfa7baf091d6b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/convnext/convnext.yml
@@ -0,0 +1,133 @@
+Models:
+- Name: upernet_convnext_tiny_fp16_512x512_160k_ade20k
+ In Collection: UperNet
+ Metadata:
+ backbone: ConvNeXt-T
+ crop size: (512,512)
+ lr schd: 160000
+ inference time (ms/im):
+ - value: 50.25
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP16
+ resolution: (512,512)
+ Training Memory (GB): 4.23
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 46.11
+ mIoU(ms+flip): 46.62
+ Config: configs/convnext/upernet_convnext_tiny_fp16_512x512_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_tiny_fp16_512x512_160k_ade20k/upernet_convnext_tiny_fp16_512x512_160k_ade20k_20220227_124553-cad485de.pth
+- Name: upernet_convnext_small_fp16_512x512_160k_ade20k
+ In Collection: UperNet
+ Metadata:
+ backbone: ConvNeXt-S
+ crop size: (512,512)
+ lr schd: 160000
+ inference time (ms/im):
+ - value: 65.88
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP16
+ resolution: (512,512)
+ Training Memory (GB): 5.16
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 48.56
+ mIoU(ms+flip): 49.02
+ Config: configs/convnext/upernet_convnext_small_fp16_512x512_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_small_fp16_512x512_160k_ade20k/upernet_convnext_small_fp16_512x512_160k_ade20k_20220227_131208-1b1e394f.pth
+- Name: upernet_convnext_base_fp16_512x512_160k_ade20k
+ In Collection: UperNet
+ Metadata:
+ backbone: ConvNeXt-B
+ crop size: (512,512)
+ lr schd: 160000
+ inference time (ms/im):
+ - value: 69.4
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP16
+ resolution: (512,512)
+ Training Memory (GB): 6.33
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 48.71
+ mIoU(ms+flip): 49.54
+ Config: configs/convnext/upernet_convnext_base_fp16_512x512_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_base_fp16_512x512_160k_ade20k/upernet_convnext_base_fp16_512x512_160k_ade20k_20220227_181227-02a24fc6.pth
+- Name: upernet_convnext_base_fp16_640x640_160k_ade20k
+ In Collection: UperNet
+ Metadata:
+ backbone: ConvNeXt-B
+ crop size: (640,640)
+ lr schd: 160000
+ inference time (ms/im):
+ - value: 91.91
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP16
+ resolution: (640,640)
+ Training Memory (GB): 8.53
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 52.13
+ mIoU(ms+flip): 52.66
+ Config: configs/convnext/upernet_convnext_base_fp16_640x640_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_base_fp16_640x640_160k_ade20k/upernet_convnext_base_fp16_640x640_160k_ade20k_20220227_182859-9280e39b.pth
+- Name: upernet_convnext_large_fp16_640x640_160k_ade20k
+ In Collection: UperNet
+ Metadata:
+ backbone: ConvNeXt-L
+ crop size: (640,640)
+ lr schd: 160000
+ inference time (ms/im):
+ - value: 130.04
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP16
+ resolution: (640,640)
+ Training Memory (GB): 12.08
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 53.16
+ mIoU(ms+flip): 53.38
+ Config: configs/convnext/upernet_convnext_large_fp16_640x640_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_large_fp16_640x640_160k_ade20k/upernet_convnext_large_fp16_640x640_160k_ade20k_20220226_040532-e57aa54d.pth
+- Name: upernet_convnext_xlarge_fp16_640x640_160k_ade20k
+ In Collection: UperNet
+ Metadata:
+ backbone: ConvNeXt-XL
+ crop size: (640,640)
+ lr schd: 160000
+ inference time (ms/im):
+ - value: 157.98
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP16
+ resolution: (640,640)
+ Training Memory (GB): 26.16
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 53.58
+ mIoU(ms+flip): 54.11
+ Config: configs/convnext/upernet_convnext_xlarge_fp16_640x640_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/convnext/upernet_convnext_xlarge_fp16_640x640_160k_ade20k/upernet_convnext_xlarge_fp16_640x640_160k_ade20k_20220226_080344-95fc38c2.pth
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_base_fp16_512x512_160k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_base_fp16_512x512_160k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..7bf35b2f1ab1b2cb2205d8ad80b4198e555bfa2a
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_base_fp16_512x512_160k_ade20k.py
@@ -0,0 +1,40 @@
+_base_ = [
+ '../_base_/models/upernet_convnext.py', '../_base_/datasets/ade20k.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_160k.py'
+]
+crop_size = (512, 512)
+model = dict(
+ decode_head=dict(in_channels=[128, 256, 512, 1024], num_classes=150),
+ auxiliary_head=dict(in_channels=512, num_classes=150),
+ test_cfg=dict(mode='slide', crop_size=crop_size, stride=(341, 341)),
+)
+
+optimizer = dict(
+ constructor='LearningRateDecayOptimizerConstructor',
+ _delete_=True,
+ type='AdamW',
+ lr=0.0001,
+ betas=(0.9, 0.999),
+ weight_decay=0.05,
+ paramwise_cfg={
+ 'decay_rate': 0.9,
+ 'decay_type': 'stage_wise',
+ 'num_layers': 12
+ })
+
+lr_config = dict(
+ _delete_=True,
+ policy='poly',
+ warmup='linear',
+ warmup_iters=1500,
+ warmup_ratio=1e-6,
+ power=1.0,
+ min_lr=0.0,
+ by_epoch=False)
+
+# By default, models are trained on 8 GPUs with 2 images per GPU
+data = dict(samples_per_gpu=2)
+# fp16 settings
+optimizer_config = dict(type='Fp16OptimizerHook', loss_scale='dynamic')
+# fp16 placeholder
+fp16 = dict()
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_base_fp16_640x640_160k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_base_fp16_640x640_160k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..8d2c0c26d014771c4e2d3126073d102138f2cd88
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_base_fp16_640x640_160k_ade20k.py
@@ -0,0 +1,55 @@
+_base_ = [
+ '../_base_/models/upernet_convnext.py',
+ '../_base_/datasets/ade20k_640x640.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_160k.py'
+]
+crop_size = (640, 640)
+checkpoint_file = 'https://download.openmmlab.com/mmclassification/v0/convnext/downstream/convnext-base_3rdparty_in21k_20220301-262fd037.pth' # noqa
+model = dict(
+ backbone=dict(
+ type='mmcls.ConvNeXt',
+ arch='base',
+ out_indices=[0, 1, 2, 3],
+ drop_path_rate=0.4,
+ layer_scale_init_value=1.0,
+ gap_before_final_norm=False,
+ init_cfg=dict(
+ type='Pretrained', checkpoint=checkpoint_file,
+ prefix='backbone.')),
+ decode_head=dict(
+ in_channels=[128, 256, 512, 1024],
+ num_classes=150,
+ ),
+ auxiliary_head=dict(in_channels=512, num_classes=150),
+ test_cfg=dict(mode='slide', crop_size=crop_size, stride=(426, 426)),
+)
+
+optimizer = dict(
+ constructor='LearningRateDecayOptimizerConstructor',
+ _delete_=True,
+ type='AdamW',
+ lr=0.0001,
+ betas=(0.9, 0.999),
+ weight_decay=0.05,
+ paramwise_cfg={
+ 'decay_rate': 0.9,
+ 'decay_type': 'stage_wise',
+ 'num_layers': 12
+ })
+
+lr_config = dict(
+ _delete_=True,
+ policy='poly',
+ warmup='linear',
+ warmup_iters=1500,
+ warmup_ratio=1e-6,
+ power=1.0,
+ min_lr=0.0,
+ by_epoch=False)
+
+# By default, models are trained on 8 GPUs with 2 images per GPU
+data = dict(samples_per_gpu=2)
+# fp16 settings
+optimizer_config = dict(type='Fp16OptimizerHook', loss_scale='dynamic')
+# fp16 placeholder
+fp16 = dict()
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_large_fp16_640x640_160k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_large_fp16_640x640_160k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..7527ed51fee3c134c7257b56bd2810fdcffd98d3
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_large_fp16_640x640_160k_ade20k.py
@@ -0,0 +1,55 @@
+_base_ = [
+ '../_base_/models/upernet_convnext.py',
+ '../_base_/datasets/ade20k_640x640.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_160k.py'
+]
+crop_size = (640, 640)
+checkpoint_file = 'https://download.openmmlab.com/mmclassification/v0/convnext/downstream/convnext-large_3rdparty_in21k_20220301-e6e0ea0a.pth' # noqa
+model = dict(
+ backbone=dict(
+ type='mmcls.ConvNeXt',
+ arch='large',
+ out_indices=[0, 1, 2, 3],
+ drop_path_rate=0.4,
+ layer_scale_init_value=1.0,
+ gap_before_final_norm=False,
+ init_cfg=dict(
+ type='Pretrained', checkpoint=checkpoint_file,
+ prefix='backbone.')),
+ decode_head=dict(
+ in_channels=[192, 384, 768, 1536],
+ num_classes=150,
+ ),
+ auxiliary_head=dict(in_channels=768, num_classes=150),
+ test_cfg=dict(mode='slide', crop_size=crop_size, stride=(426, 426)),
+)
+
+optimizer = dict(
+ constructor='LearningRateDecayOptimizerConstructor',
+ _delete_=True,
+ type='AdamW',
+ lr=0.0001,
+ betas=(0.9, 0.999),
+ weight_decay=0.05,
+ paramwise_cfg={
+ 'decay_rate': 0.9,
+ 'decay_type': 'stage_wise',
+ 'num_layers': 12
+ })
+
+lr_config = dict(
+ _delete_=True,
+ policy='poly',
+ warmup='linear',
+ warmup_iters=1500,
+ warmup_ratio=1e-6,
+ power=1.0,
+ min_lr=0.0,
+ by_epoch=False)
+
+# By default, models are trained on 8 GPUs with 2 images per GPU
+data = dict(samples_per_gpu=2)
+# fp16 settings
+optimizer_config = dict(type='Fp16OptimizerHook', loss_scale='dynamic')
+# fp16 placeholder
+fp16 = dict()
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_small_fp16_512x512_160k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_small_fp16_512x512_160k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..2e95f3af990dbc5f441dd2f6bbcbfab86517885c
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_small_fp16_512x512_160k_ade20k.py
@@ -0,0 +1,54 @@
+_base_ = [
+ '../_base_/models/upernet_convnext.py', '../_base_/datasets/ade20k.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_160k.py'
+]
+crop_size = (512, 512)
+checkpoint_file = 'https://download.openmmlab.com/mmclassification/v0/convnext/downstream/convnext-small_3rdparty_32xb128-noema_in1k_20220301-303e75e3.pth' # noqa
+model = dict(
+ backbone=dict(
+ type='mmcls.ConvNeXt',
+ arch='small',
+ out_indices=[0, 1, 2, 3],
+ drop_path_rate=0.3,
+ layer_scale_init_value=1.0,
+ gap_before_final_norm=False,
+ init_cfg=dict(
+ type='Pretrained', checkpoint=checkpoint_file,
+ prefix='backbone.')),
+ decode_head=dict(
+ in_channels=[96, 192, 384, 768],
+ num_classes=150,
+ ),
+ auxiliary_head=dict(in_channels=384, num_classes=150),
+ test_cfg=dict(mode='slide', crop_size=crop_size, stride=(341, 341)),
+)
+
+optimizer = dict(
+ constructor='LearningRateDecayOptimizerConstructor',
+ _delete_=True,
+ type='AdamW',
+ lr=0.0001,
+ betas=(0.9, 0.999),
+ weight_decay=0.05,
+ paramwise_cfg={
+ 'decay_rate': 0.9,
+ 'decay_type': 'stage_wise',
+ 'num_layers': 12
+ })
+
+lr_config = dict(
+ _delete_=True,
+ policy='poly',
+ warmup='linear',
+ warmup_iters=1500,
+ warmup_ratio=1e-6,
+ power=1.0,
+ min_lr=0.0,
+ by_epoch=False)
+
+# By default, models are trained on 8 GPUs with 2 images per GPU
+data = dict(samples_per_gpu=2)
+# fp16 settings
+optimizer_config = dict(type='Fp16OptimizerHook', loss_scale='dynamic')
+# fp16 placeholder
+fp16 = dict()
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_tiny_fp16_512x512_160k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_tiny_fp16_512x512_160k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..35c72a8d9945fb80e86a98859a90f8940cec3f67
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_tiny_fp16_512x512_160k_ade20k.py
@@ -0,0 +1,54 @@
+_base_ = [
+ '../_base_/models/upernet_convnext.py', '../_base_/datasets/ade20k.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_160k.py'
+]
+crop_size = (512, 512)
+checkpoint_file = 'https://download.openmmlab.com/mmclassification/v0/convnext/downstream/convnext-tiny_3rdparty_32xb128-noema_in1k_20220301-795e9634.pth' # noqa
+model = dict(
+ backbone=dict(
+ type='mmcls.ConvNeXt',
+ arch='tiny',
+ out_indices=[0, 1, 2, 3],
+ drop_path_rate=0.4,
+ layer_scale_init_value=1.0,
+ gap_before_final_norm=False,
+ init_cfg=dict(
+ type='Pretrained', checkpoint=checkpoint_file,
+ prefix='backbone.')),
+ decode_head=dict(
+ in_channels=[96, 192, 384, 768],
+ num_classes=150,
+ ),
+ auxiliary_head=dict(in_channels=384, num_classes=150),
+ test_cfg=dict(mode='slide', crop_size=crop_size, stride=(341, 341)),
+)
+
+optimizer = dict(
+ constructor='LearningRateDecayOptimizerConstructor',
+ _delete_=True,
+ type='AdamW',
+ lr=0.0001,
+ betas=(0.9, 0.999),
+ weight_decay=0.05,
+ paramwise_cfg={
+ 'decay_rate': 0.9,
+ 'decay_type': 'stage_wise',
+ 'num_layers': 6
+ })
+
+lr_config = dict(
+ _delete_=True,
+ policy='poly',
+ warmup='linear',
+ warmup_iters=1500,
+ warmup_ratio=1e-6,
+ power=1.0,
+ min_lr=0.0,
+ by_epoch=False)
+
+# By default, models are trained on 8 GPUs with 2 images per GPU
+data = dict(samples_per_gpu=2)
+# fp16 settings
+optimizer_config = dict(type='Fp16OptimizerHook', loss_scale='dynamic')
+# fp16 placeholder
+fp16 = dict()
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_xlarge_fp16_640x640_160k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_xlarge_fp16_640x640_160k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..0e2f38ebbd7015153c6e4a2d1fad499bc47de4a0
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/convnext/upernet_convnext_xlarge_fp16_640x640_160k_ade20k.py
@@ -0,0 +1,55 @@
+_base_ = [
+ '../_base_/models/upernet_convnext.py',
+ '../_base_/datasets/ade20k_640x640.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_160k.py'
+]
+crop_size = (640, 640)
+checkpoint_file = 'https://download.openmmlab.com/mmclassification/v0/convnext/downstream/convnext-xlarge_3rdparty_in21k_20220301-08aa5ddc.pth' # noqa
+model = dict(
+ backbone=dict(
+ type='mmcls.ConvNeXt',
+ arch='xlarge',
+ out_indices=[0, 1, 2, 3],
+ drop_path_rate=0.4,
+ layer_scale_init_value=1.0,
+ gap_before_final_norm=False,
+ init_cfg=dict(
+ type='Pretrained', checkpoint=checkpoint_file,
+ prefix='backbone.')),
+ decode_head=dict(
+ in_channels=[256, 512, 1024, 2048],
+ num_classes=150,
+ ),
+ auxiliary_head=dict(in_channels=1024, num_classes=150),
+ test_cfg=dict(mode='slide', crop_size=crop_size, stride=(426, 426)),
+)
+
+optimizer = dict(
+ constructor='LearningRateDecayOptimizerConstructor',
+ _delete_=True,
+ type='AdamW',
+ lr=0.00008,
+ betas=(0.9, 0.999),
+ weight_decay=0.05,
+ paramwise_cfg={
+ 'decay_rate': 0.9,
+ 'decay_type': 'stage_wise',
+ 'num_layers': 12
+ })
+
+lr_config = dict(
+ _delete_=True,
+ policy='poly',
+ warmup='linear',
+ warmup_iters=1500,
+ warmup_ratio=1e-6,
+ power=1.0,
+ min_lr=0.0,
+ by_epoch=False)
+
+# By default, models are trained on 8 GPUs with 2 images per GPU
+data = dict(samples_per_gpu=2)
+# fp16 settings
+optimizer_config = dict(type='Fp16OptimizerHook', loss_scale='dynamic')
+# fp16 placeholder
+fp16 = dict()
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/README.md b/EgoHOS/raw/script/mmsegmentation/configs/danet/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..411c5956212fba5c351e385a57b23942a8946eeb
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/README.md
@@ -0,0 +1,66 @@
+# DANet
+
+[Dual Attention Network for Scene Segmentation](https://arxiv.org/abs/1809.02983)
+
+## Introduction
+
+
+
+Official Repo
+
+Code Snippet
+
+## Abstract
+
+
+
+In this paper, we address the scene segmentation task by capturing rich contextual dependencies based on the selfattention mechanism. Unlike previous works that capture contexts by multi-scale features fusion, we propose a Dual Attention Networks (DANet) to adaptively integrate local features with their global dependencies. Specifically, we append two types of attention modules on top of traditional dilated FCN, which model the semantic interdependencies in spatial and channel dimensions respectively. The position attention module selectively aggregates the features at each position by a weighted sum of the features at all positions. Similar features would be related to each other regardless of their distances. Meanwhile, the channel attention module selectively emphasizes interdependent channel maps by integrating associated features among all channel maps. We sum the outputs of the two attention modules to further improve feature representation which contributes to more precise segmentation results. We achieve new state-of-the-art segmentation performance on three challenging scene segmentation datasets, i.e., Cityscapes, PASCAL Context and COCO Stuff dataset. In particular, a Mean IoU score of 81.5% on Cityscapes test set is achieved without using coarse data. We make the code and trained model publicly available at [this https URL](https://github.com/junfu1115/DANet).
+
+
+
+
+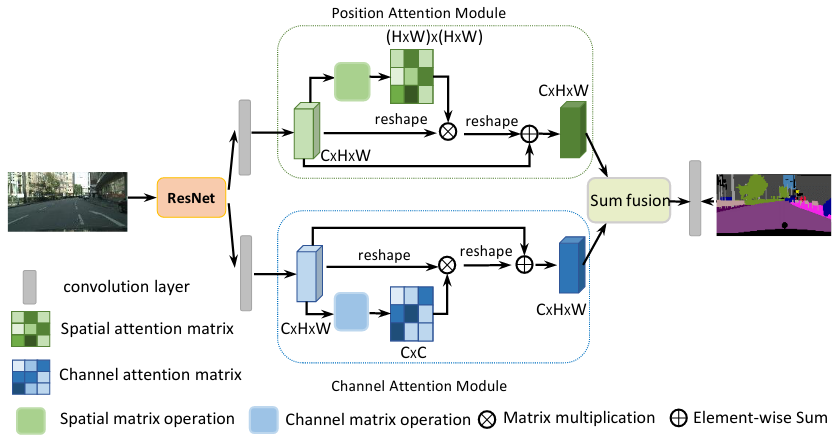 +
+
+## Citation
+
+```bibtex
+@article{fu2018dual,
+ title={Dual Attention Network for Scene Segmentation},
+ author={Jun Fu, Jing Liu, Haijie Tian, Yong Li, Yongjun Bao, Zhiwei Fang,and Hanqing Lu},
+ booktitle={The IEEE Conference on Computer Vision and Pattern Recognition (CVPR)},
+ year={2019}
+}
+```
+
+## Results and models
+
+### Cityscapes
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| ------ | -------- | --------- | ------: | -------- | -------------- | ----: | ------------- | ------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
+| DANet | R-50-D8 | 512x1024 | 40000 | 7.4 | 2.66 | 78.74 | - | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet/danet_r50-d8_512x1024_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x1024_40k_cityscapes/danet_r50-d8_512x1024_40k_cityscapes_20200605_191324-c0dbfa5f.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x1024_40k_cityscapes/danet_r50-d8_512x1024_40k_cityscapes_20200605_191324.log.json) |
+| DANet | R-101-D8 | 512x1024 | 40000 | 10.9 | 1.99 | 80.52 | - | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet/danet_r101-d8_512x1024_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x1024_40k_cityscapes/danet_r101-d8_512x1024_40k_cityscapes_20200605_200831-c57a7157.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x1024_40k_cityscapes/danet_r101-d8_512x1024_40k_cityscapes_20200605_200831.log.json) |
+| DANet | R-50-D8 | 769x769 | 40000 | 8.8 | 1.56 | 78.88 | 80.62 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet/danet_r50-d8_769x769_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_769x769_40k_cityscapes/danet_r50-d8_769x769_40k_cityscapes_20200530_025703-76681c60.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_769x769_40k_cityscapes/danet_r50-d8_769x769_40k_cityscapes_20200530_025703.log.json) |
+| DANet | R-101-D8 | 769x769 | 40000 | 12.8 | 1.07 | 79.88 | 81.47 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet/danet_r101-d8_769x769_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_769x769_40k_cityscapes/danet_r101-d8_769x769_40k_cityscapes_20200530_025717-dcb7fd4e.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_769x769_40k_cityscapes/danet_r101-d8_769x769_40k_cityscapes_20200530_025717.log.json) |
+| DANet | R-50-D8 | 512x1024 | 80000 | - | - | 79.34 | - | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet/danet_r50-d8_512x1024_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x1024_80k_cityscapes/danet_r50-d8_512x1024_80k_cityscapes_20200607_133029-2bfa2293.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x1024_80k_cityscapes/danet_r50-d8_512x1024_80k_cityscapes_20200607_133029.log.json) |
+| DANet | R-101-D8 | 512x1024 | 80000 | - | - | 80.41 | - | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet/danet_r101-d8_512x1024_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x1024_80k_cityscapes/danet_r101-d8_512x1024_80k_cityscapes_20200607_132918-955e6350.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x1024_80k_cityscapes/danet_r101-d8_512x1024_80k_cityscapes_20200607_132918.log.json) |
+| DANet | R-50-D8 | 769x769 | 80000 | - | - | 79.27 | 80.96 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet/danet_r50-d8_769x769_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_769x769_80k_cityscapes/danet_r50-d8_769x769_80k_cityscapes_20200607_132954-495689b4.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_769x769_80k_cityscapes/danet_r50-d8_769x769_80k_cityscapes_20200607_132954.log.json) |
+| DANet | R-101-D8 | 769x769 | 80000 | - | - | 80.47 | 82.02 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet/danet_r101-d8_769x769_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_769x769_80k_cityscapes/danet_r101-d8_769x769_80k_cityscapes_20200607_132918-f3a929e7.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_769x769_80k_cityscapes/danet_r101-d8_769x769_80k_cityscapes_20200607_132918.log.json) |
+
+### ADE20K
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| ------ | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | --------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
+| DANet | R-50-D8 | 512x512 | 80000 | 11.5 | 21.20 | 41.66 | 42.90 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet/danet_r50-d8_512x512_80k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x512_80k_ade20k/danet_r50-d8_512x512_80k_ade20k_20200615_015125-edb18e08.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x512_80k_ade20k/danet_r50-d8_512x512_80k_ade20k_20200615_015125.log.json) |
+| DANet | R-101-D8 | 512x512 | 80000 | 15 | 14.18 | 43.64 | 45.19 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet/danet_r101-d8_512x512_80k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x512_80k_ade20k/danet_r101-d8_512x512_80k_ade20k_20200615_015126-d0357c73.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x512_80k_ade20k/danet_r101-d8_512x512_80k_ade20k_20200615_015126.log.json) |
+| DANet | R-50-D8 | 512x512 | 160000 | - | - | 42.45 | 43.25 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet/danet_r50-d8_512x512_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x512_160k_ade20k/danet_r50-d8_512x512_160k_ade20k_20200616_082340-9cb35dcd.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x512_160k_ade20k/danet_r50-d8_512x512_160k_ade20k_20200616_082340.log.json) |
+| DANet | R-101-D8 | 512x512 | 160000 | - | - | 44.17 | 45.02 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet/danet_r101-d8_512x512_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x512_160k_ade20k/danet_r101-d8_512x512_160k_ade20k_20200616_082348-23bf12f9.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x512_160k_ade20k/danet_r101-d8_512x512_160k_ade20k_20200616_082348.log.json) |
+
+### Pascal VOC 2012 + Aug
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| ------ | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | ---------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
+| DANet | R-50-D8 | 512x512 | 20000 | 6.5 | 20.94 | 74.45 | 75.69 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet/danet_r50-d8_512x512_20k_voc12aug.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x512_20k_voc12aug/danet_r50-d8_512x512_20k_voc12aug_20200618_070026-9e9e3ab3.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x512_20k_voc12aug/danet_r50-d8_512x512_20k_voc12aug_20200618_070026.log.json) |
+| DANet | R-101-D8 | 512x512 | 20000 | 9.9 | 13.76 | 76.02 | 77.23 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet/danet_r101-d8_512x512_20k_voc12aug.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x512_20k_voc12aug/danet_r101-d8_512x512_20k_voc12aug_20200618_070026-d48d23b2.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x512_20k_voc12aug/danet_r101-d8_512x512_20k_voc12aug_20200618_070026.log.json) |
+| DANet | R-50-D8 | 512x512 | 40000 | - | - | 76.37 | 77.29 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet/danet_r50-d8_512x512_40k_voc12aug.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x512_40k_voc12aug/danet_r50-d8_512x512_40k_voc12aug_20200613_235526-426e3a64.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x512_40k_voc12aug/danet_r50-d8_512x512_40k_voc12aug_20200613_235526.log.json) |
+| DANet | R-101-D8 | 512x512 | 40000 | - | - | 76.51 | 77.32 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet/danet_r101-d8_512x512_40k_voc12aug.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x512_40k_voc12aug/danet_r101-d8_512x512_40k_voc12aug_20200613_223031-788e232a.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x512_40k_voc12aug/danet_r101-d8_512x512_40k_voc12aug_20200613_223031.log.json) |
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/danet.yml b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet.yml
new file mode 100644
index 0000000000000000000000000000000000000000..ca2d6ff982c5185cf820ed87227d282e58617f19
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet.yml
@@ -0,0 +1,301 @@
+Collections:
+- Name: DANet
+ Metadata:
+ Training Data:
+ - Cityscapes
+ - ADE20K
+ - Pascal VOC 2012 + Aug
+ Paper:
+ URL: https://arxiv.org/abs/1809.02983
+ Title: Dual Attention Network for Scene Segmentation
+ README: configs/danet/README.md
+ Code:
+ URL: https://github.com/open-mmlab/mmsegmentation/blob/v0.17.0/mmseg/models/decode_heads/da_head.py#L76
+ Version: v0.17.0
+ Converted From:
+ Code: https://github.com/junfu1115/DANet/
+Models:
+- Name: danet_r50-d8_512x1024_40k_cityscapes
+ In Collection: DANet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,1024)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 375.94
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,1024)
+ Training Memory (GB): 7.4
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 78.74
+ Config: configs/danet/danet_r50-d8_512x1024_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x1024_40k_cityscapes/danet_r50-d8_512x1024_40k_cityscapes_20200605_191324-c0dbfa5f.pth
+- Name: danet_r101-d8_512x1024_40k_cityscapes
+ In Collection: DANet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,1024)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 502.51
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,1024)
+ Training Memory (GB): 10.9
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 80.52
+ Config: configs/danet/danet_r101-d8_512x1024_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x1024_40k_cityscapes/danet_r101-d8_512x1024_40k_cityscapes_20200605_200831-c57a7157.pth
+- Name: danet_r50-d8_769x769_40k_cityscapes
+ In Collection: DANet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (769,769)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 641.03
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (769,769)
+ Training Memory (GB): 8.8
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 78.88
+ mIoU(ms+flip): 80.62
+ Config: configs/danet/danet_r50-d8_769x769_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_769x769_40k_cityscapes/danet_r50-d8_769x769_40k_cityscapes_20200530_025703-76681c60.pth
+- Name: danet_r101-d8_769x769_40k_cityscapes
+ In Collection: DANet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (769,769)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 934.58
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (769,769)
+ Training Memory (GB): 12.8
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 79.88
+ mIoU(ms+flip): 81.47
+ Config: configs/danet/danet_r101-d8_769x769_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_769x769_40k_cityscapes/danet_r101-d8_769x769_40k_cityscapes_20200530_025717-dcb7fd4e.pth
+- Name: danet_r50-d8_512x1024_80k_cityscapes
+ In Collection: DANet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,1024)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 79.34
+ Config: configs/danet/danet_r50-d8_512x1024_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x1024_80k_cityscapes/danet_r50-d8_512x1024_80k_cityscapes_20200607_133029-2bfa2293.pth
+- Name: danet_r101-d8_512x1024_80k_cityscapes
+ In Collection: DANet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,1024)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 80.41
+ Config: configs/danet/danet_r101-d8_512x1024_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x1024_80k_cityscapes/danet_r101-d8_512x1024_80k_cityscapes_20200607_132918-955e6350.pth
+- Name: danet_r50-d8_769x769_80k_cityscapes
+ In Collection: DANet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (769,769)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 79.27
+ mIoU(ms+flip): 80.96
+ Config: configs/danet/danet_r50-d8_769x769_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_769x769_80k_cityscapes/danet_r50-d8_769x769_80k_cityscapes_20200607_132954-495689b4.pth
+- Name: danet_r101-d8_769x769_80k_cityscapes
+ In Collection: DANet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (769,769)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 80.47
+ mIoU(ms+flip): 82.02
+ Config: configs/danet/danet_r101-d8_769x769_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_769x769_80k_cityscapes/danet_r101-d8_769x769_80k_cityscapes_20200607_132918-f3a929e7.pth
+- Name: danet_r50-d8_512x512_80k_ade20k
+ In Collection: DANet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 47.17
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 11.5
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 41.66
+ mIoU(ms+flip): 42.9
+ Config: configs/danet/danet_r50-d8_512x512_80k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x512_80k_ade20k/danet_r50-d8_512x512_80k_ade20k_20200615_015125-edb18e08.pth
+- Name: danet_r101-d8_512x512_80k_ade20k
+ In Collection: DANet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 70.52
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 15.0
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 43.64
+ mIoU(ms+flip): 45.19
+ Config: configs/danet/danet_r101-d8_512x512_80k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x512_80k_ade20k/danet_r101-d8_512x512_80k_ade20k_20200615_015126-d0357c73.pth
+- Name: danet_r50-d8_512x512_160k_ade20k
+ In Collection: DANet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 160000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 42.45
+ mIoU(ms+flip): 43.25
+ Config: configs/danet/danet_r50-d8_512x512_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x512_160k_ade20k/danet_r50-d8_512x512_160k_ade20k_20200616_082340-9cb35dcd.pth
+- Name: danet_r101-d8_512x512_160k_ade20k
+ In Collection: DANet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 160000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 44.17
+ mIoU(ms+flip): 45.02
+ Config: configs/danet/danet_r101-d8_512x512_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x512_160k_ade20k/danet_r101-d8_512x512_160k_ade20k_20200616_082348-23bf12f9.pth
+- Name: danet_r50-d8_512x512_20k_voc12aug
+ In Collection: DANet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 20000
+ inference time (ms/im):
+ - value: 47.76
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 6.5
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal VOC 2012 + Aug
+ Metrics:
+ mIoU: 74.45
+ mIoU(ms+flip): 75.69
+ Config: configs/danet/danet_r50-d8_512x512_20k_voc12aug.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x512_20k_voc12aug/danet_r50-d8_512x512_20k_voc12aug_20200618_070026-9e9e3ab3.pth
+- Name: danet_r101-d8_512x512_20k_voc12aug
+ In Collection: DANet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 20000
+ inference time (ms/im):
+ - value: 72.67
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 9.9
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal VOC 2012 + Aug
+ Metrics:
+ mIoU: 76.02
+ mIoU(ms+flip): 77.23
+ Config: configs/danet/danet_r101-d8_512x512_20k_voc12aug.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x512_20k_voc12aug/danet_r101-d8_512x512_20k_voc12aug_20200618_070026-d48d23b2.pth
+- Name: danet_r50-d8_512x512_40k_voc12aug
+ In Collection: DANet
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 40000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal VOC 2012 + Aug
+ Metrics:
+ mIoU: 76.37
+ mIoU(ms+flip): 77.29
+ Config: configs/danet/danet_r50-d8_512x512_40k_voc12aug.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r50-d8_512x512_40k_voc12aug/danet_r50-d8_512x512_40k_voc12aug_20200613_235526-426e3a64.pth
+- Name: danet_r101-d8_512x512_40k_voc12aug
+ In Collection: DANet
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 40000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal VOC 2012 + Aug
+ Metrics:
+ mIoU: 76.51
+ mIoU(ms+flip): 77.32
+ Config: configs/danet/danet_r101-d8_512x512_40k_voc12aug.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/danet/danet_r101-d8_512x512_40k_voc12aug/danet_r101-d8_512x512_40k_voc12aug_20200613_223031-788e232a.pth
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x1024_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x1024_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..3bfb9bdb3064275c2ac3bf2a057ef8eb79c308df
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x1024_40k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './danet_r50-d8_512x1024_40k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x1024_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x1024_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..d80b2ec160ae1c41499d45242713a99122d8adf8
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x1024_80k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './danet_r50-d8_512x1024_80k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x512_160k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x512_160k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..0f22d0fb6362252ac02f3f152a42997c68b90343
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x512_160k_ade20k.py
@@ -0,0 +1,2 @@
+_base_ = './danet_r50-d8_512x512_160k_ade20k.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x512_20k_voc12aug.py b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x512_20k_voc12aug.py
new file mode 100644
index 0000000000000000000000000000000000000000..709f93cba3e3bca6ce0635457ab1823b04123bf8
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x512_20k_voc12aug.py
@@ -0,0 +1,2 @@
+_base_ = './danet_r50-d8_512x512_20k_voc12aug.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x512_40k_voc12aug.py b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x512_40k_voc12aug.py
new file mode 100644
index 0000000000000000000000000000000000000000..5c623eb56836760694b50f3e4e66aa0f1fc069df
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x512_40k_voc12aug.py
@@ -0,0 +1,2 @@
+_base_ = './danet_r50-d8_512x512_40k_voc12aug.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x512_80k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x512_80k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..bd31bc8f283fe8c322ee4876deadb89569dc1743
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_512x512_80k_ade20k.py
@@ -0,0 +1,2 @@
+_base_ = './danet_r50-d8_512x512_80k_ade20k.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_769x769_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_769x769_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..597d76de79610780b03cd91dba5f3a4f10147bcd
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_769x769_40k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './danet_r50-d8_769x769_40k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_769x769_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_769x769_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..70f9b31966128e8d9ec37859f57a7edfd8e6d1b2
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r101-d8_769x769_80k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './danet_r50-d8_769x769_80k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x1024_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x1024_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..1b70c5b8d49f04661e23604ca4da56a82b1b99c9
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x1024_40k_cityscapes.py
@@ -0,0 +1,4 @@
+_base_ = [
+ '../_base_/models/danet_r50-d8.py', '../_base_/datasets/cityscapes.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_40k.py'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x1024_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x1024_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..03734310d7338c75d48c914cb325500961c04a79
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x1024_80k_cityscapes.py
@@ -0,0 +1,4 @@
+_base_ = [
+ '../_base_/models/danet_r50-d8.py', '../_base_/datasets/cityscapes.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_80k.py'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x512_160k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x512_160k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..22aaf857c3212d0b36b0b04e7990616025a3ef9b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x512_160k_ade20k.py
@@ -0,0 +1,6 @@
+_base_ = [
+ '../_base_/models/danet_r50-d8.py', '../_base_/datasets/ade20k.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_160k.py'
+]
+model = dict(
+ decode_head=dict(num_classes=150), auxiliary_head=dict(num_classes=150))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x512_20k_voc12aug.py b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x512_20k_voc12aug.py
new file mode 100644
index 0000000000000000000000000000000000000000..010f86f1aac1b5c827dec29f692d137dc1c399bf
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x512_20k_voc12aug.py
@@ -0,0 +1,7 @@
+_base_ = [
+ '../_base_/models/danet_r50-d8.py',
+ '../_base_/datasets/pascal_voc12_aug.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_20k.py'
+]
+model = dict(
+ decode_head=dict(num_classes=21), auxiliary_head=dict(num_classes=21))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x512_40k_voc12aug.py b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x512_40k_voc12aug.py
new file mode 100644
index 0000000000000000000000000000000000000000..0cef0f09bfa2290d14fc3a783ea500d6c3da2931
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x512_40k_voc12aug.py
@@ -0,0 +1,7 @@
+_base_ = [
+ '../_base_/models/danet_r50-d8.py',
+ '../_base_/datasets/pascal_voc12_aug.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_40k.py'
+]
+model = dict(
+ decode_head=dict(num_classes=21), auxiliary_head=dict(num_classes=21))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x512_80k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x512_80k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..154e84890ed73fe4813dddc8c321de6cd2854fc1
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_512x512_80k_ade20k.py
@@ -0,0 +1,6 @@
+_base_ = [
+ '../_base_/models/danet_r50-d8.py', '../_base_/datasets/ade20k.py',
+ '../_base_/default_runtime.py', '../_base_/schedules/schedule_80k.py'
+]
+model = dict(
+ decode_head=dict(num_classes=150), auxiliary_head=dict(num_classes=150))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_769x769_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_769x769_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..5c5b94e5a27d7f902d4bdea7ef6c4ef0b816bb99
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_769x769_40k_cityscapes.py
@@ -0,0 +1,9 @@
+_base_ = [
+ '../_base_/models/danet_r50-d8.py',
+ '../_base_/datasets/cityscapes_769x769.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_40k.py'
+]
+model = dict(
+ decode_head=dict(align_corners=True),
+ auxiliary_head=dict(align_corners=True),
+ test_cfg=dict(mode='slide', crop_size=(769, 769), stride=(513, 513)))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_769x769_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_769x769_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..c7237ae03c601204dc7c03018ca17ed363090569
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/danet/danet_r50-d8_769x769_80k_cityscapes.py
@@ -0,0 +1,9 @@
+_base_ = [
+ '../_base_/models/danet_r50-d8.py',
+ '../_base_/datasets/cityscapes_769x769.py', '../_base_/default_runtime.py',
+ '../_base_/schedules/schedule_80k.py'
+]
+model = dict(
+ decode_head=dict(align_corners=True),
+ auxiliary_head=dict(align_corners=True),
+ test_cfg=dict(mode='slide', crop_size=(769, 769), stride=(513, 513)))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/README.md b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..a5d85a5efdaf4b1f0f865ccf35d0dec868c37224
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/README.md
@@ -0,0 +1,116 @@
+# DeepLabV3
+
+[Rethinking atrous convolution for semantic image segmentation](https://arxiv.org/abs/1706.05587)
+
+## Introduction
+
+
+
+Official Repo
+
+Code Snippet
+
+## Abstract
+
+
+
+In this work, we revisit atrous convolution, a powerful tool to explicitly adjust filter's field-of-view as well as control the resolution of feature responses computed by Deep Convolutional Neural Networks, in the application of semantic image segmentation. To handle the problem of segmenting objects at multiple scales, we design modules which employ atrous convolution in cascade or in parallel to capture multi-scale context by adopting multiple atrous rates. Furthermore, we propose to augment our previously proposed Atrous Spatial Pyramid Pooling module, which probes convolutional features at multiple scales, with image-level features encoding global context and further boost performance. We also elaborate on implementation details and share our experience on training our system. The proposed `DeepLabv3' system significantly improves over our previous DeepLab versions without DenseCRF post-processing and attains comparable performance with other state-of-art models on the PASCAL VOC 2012 semantic image segmentation benchmark.
+
+
+
+
+ +
+
+## Citation
+
+```bibtext
+@article{chen2017rethinking,
+ title={Rethinking atrous convolution for semantic image segmentation},
+ author={Chen, Liang-Chieh and Papandreou, George and Schroff, Florian and Adam, Hartwig},
+ journal={arXiv preprint arXiv:1706.05587},
+ year={2017}
+}
+```
+
+## Results and models
+
+### Cityscapes
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| --------- | --------------- | --------- | ------: | -------- | -------------- | ----: | ------------: | ---------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
+| DeepLabV3 | R-50-D8 | 512x1024 | 40000 | 6.1 | 2.57 | 79.09 | 80.45 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r50-d8_512x1024_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x1024_40k_cityscapes/deeplabv3_r50-d8_512x1024_40k_cityscapes_20200605_022449-acadc2f8.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x1024_40k_cityscapes/deeplabv3_r50-d8_512x1024_40k_cityscapes_20200605_022449.log.json) |
+| DeepLabV3 | R-101-D8 | 512x1024 | 40000 | 9.6 | 1.92 | 77.12 | 79.61 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r101-d8_512x1024_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x1024_40k_cityscapes/deeplabv3_r101-d8_512x1024_40k_cityscapes_20200605_012241-7fd3f799.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x1024_40k_cityscapes/deeplabv3_r101-d8_512x1024_40k_cityscapes_20200605_012241.log.json) |
+| DeepLabV3 | R-50-D8 | 769x769 | 40000 | 6.9 | 1.11 | 78.58 | 79.89 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r50-d8_769x769_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_769x769_40k_cityscapes/deeplabv3_r50-d8_769x769_40k_cityscapes_20200606_113723-7eda553c.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_769x769_40k_cityscapes/deeplabv3_r50-d8_769x769_40k_cityscapes_20200606_113723.log.json) |
+| DeepLabV3 | R-101-D8 | 769x769 | 40000 | 10.9 | 0.83 | 79.27 | 80.11 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r101-d8_769x769_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_769x769_40k_cityscapes/deeplabv3_r101-d8_769x769_40k_cityscapes_20200606_113809-c64f889f.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_769x769_40k_cityscapes/deeplabv3_r101-d8_769x769_40k_cityscapes_20200606_113809.log.json) |
+| DeepLabV3 | R-18-D8 | 512x1024 | 80000 | 1.7 | 13.78 | 76.70 | 78.27 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r18-d8_512x1024_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r18-d8_512x1024_80k_cityscapes/deeplabv3_r18-d8_512x1024_80k_cityscapes_20201225_021506-23dffbe2.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r18-d8_512x1024_80k_cityscapes/deeplabv3_r18-d8_512x1024_80k_cityscapes-20201225_021506.log.json) |
+| DeepLabV3 | R-50-D8 | 512x1024 | 80000 | - | - | 79.32 | 80.57 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r50-d8_512x1024_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x1024_80k_cityscapes/deeplabv3_r50-d8_512x1024_80k_cityscapes_20200606_113404-b92cfdd4.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x1024_80k_cityscapes/deeplabv3_r50-d8_512x1024_80k_cityscapes_20200606_113404.log.json) |
+| DeepLabV3 | R-101-D8 | 512x1024 | 80000 | - | - | 80.20 | 81.21 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r101-d8_512x1024_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x1024_80k_cityscapes/deeplabv3_r101-d8_512x1024_80k_cityscapes_20200606_113503-9e428899.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x1024_80k_cityscapes/deeplabv3_r101-d8_512x1024_80k_cityscapes_20200606_113503.log.json) |
+| DeepLabV3 (FP16) | R-101-D8 | 512x1024 | 80000 | 5.75 | 3.86 | 80.48 | - | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r101-d8_fp16_512x1024_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_fp16_512x1024_80k_cityscapes/deeplabv3_r101-d8_fp16_512x1024_80k_cityscapes_20200717_230920-774d9cec.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_fp16_512x1024_80k_cityscapes/deeplabv3_r101-d8_fp16_512x1024_80k_cityscapes_20200717_230920.log.json) |
+| DeepLabV3 | R-18-D8 | 769x769 | 80000 | 1.9 | 5.55 | 76.60 | 78.26 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r18-d8_769x769_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r18-d8_769x769_80k_cityscapes/deeplabv3_r18-d8_769x769_80k_cityscapes_20201225_021506-6452126a.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r18-d8_769x769_80k_cityscapes/deeplabv3_r18-d8_769x769_80k_cityscapes-20201225_021506.log.json) |
+| DeepLabV3 | R-50-D8 | 769x769 | 80000 | - | - | 79.89 | 81.06 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r50-d8_769x769_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_769x769_80k_cityscapes/deeplabv3_r50-d8_769x769_80k_cityscapes_20200606_221338-788d6228.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_769x769_80k_cityscapes/deeplabv3_r50-d8_769x769_80k_cityscapes_20200606_221338.log.json) |
+| DeepLabV3 | R-101-D8 | 769x769 | 80000 | - | - | 79.67 | 80.81 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r101-d8_769x769_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_769x769_80k_cityscapes/deeplabv3_r101-d8_769x769_80k_cityscapes_20200607_013353-60e95418.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_769x769_80k_cityscapes/deeplabv3_r101-d8_769x769_80k_cityscapes_20200607_013353.log.json) |
+| DeepLabV3 | R-101-D16-MG124 | 512x1024 | 40000 | 4.7 | - 6.96 | 76.71 | 78.63 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r101-d16-mg124_512x1024_40k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d16-mg124_512x1024_40k_cityscapes/deeplabv3_r101-d16-mg124_512x1024_40k_cityscapes_20200908_005644-67b0c992.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d16-mg124_512x1024_40k_cityscapes/deeplabv3_r101-d16-mg124_512x1024_40k_cityscapes-20200908_005644.log.json) |
+| DeepLabV3 | R-101-D16-MG124 | 512x1024 | 80000 | - | - | 78.36 | 79.84 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r101-d16-mg124_512x1024_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d16-mg124_512x1024_80k_cityscapes/deeplabv3_r101-d16-mg124_512x1024_80k_cityscapes_20200908_005644-57bb8425.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d16-mg124_512x1024_80k_cityscapes/deeplabv3_r101-d16-mg124_512x1024_80k_cityscapes-20200908_005644.log.json) |
+| DeepLabV3 | R-18b-D8 | 512x1024 | 80000 | 1.6 | 13.93 | 76.26 | 77.88 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r18b-d8_512x1024_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r18b-d8_512x1024_80k_cityscapes/deeplabv3_r18b-d8_512x1024_80k_cityscapes_20201225_094144-46040cef.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r18b-d8_512x1024_80k_cityscapes/deeplabv3_r18b-d8_512x1024_80k_cityscapes-20201225_094144.log.json) |
+| DeepLabV3 | R-50b-D8 | 512x1024 | 80000 | 6.0 | 2.74 | 79.63 | 80.98 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r50b-d8_512x1024_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50b-d8_512x1024_80k_cityscapes/deeplabv3_r50b-d8_512x1024_80k_cityscapes_20201225_155148-ec368954.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50b-d8_512x1024_80k_cityscapes/deeplabv3_r50b-d8_512x1024_80k_cityscapes-20201225_155148.log.json) |
+| DeepLabV3 | R-101b-D8 | 512x1024 | 80000 | 9.5 | 1.81 | 80.01 | 81.21 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r101b-d8_512x1024_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101b-d8_512x1024_80k_cityscapes/deeplabv3_r101b-d8_512x1024_80k_cityscapes_20201226_171821-8fd49503.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101b-d8_512x1024_80k_cityscapes/deeplabv3_r101b-d8_512x1024_80k_cityscapes-20201226_171821.log.json) |
+| DeepLabV3 | R-18b-D8 | 769x769 | 80000 | 1.8 | 5.79 | 76.63 | 77.51 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r18b-d8_769x769_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r18b-d8_769x769_80k_cityscapes/deeplabv3_r18b-d8_769x769_80k_cityscapes_20201225_094144-fdc985d9.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r18b-d8_769x769_80k_cityscapes/deeplabv3_r18b-d8_769x769_80k_cityscapes-20201225_094144.log.json) |
+| DeepLabV3 | R-50b-D8 | 769x769 | 80000 | 6.8 | 1.16 | 78.80 | 80.27 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r50b-d8_769x769_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50b-d8_769x769_80k_cityscapes/deeplabv3_r50b-d8_769x769_80k_cityscapes_20201225_155404-87fb0cf4.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50b-d8_769x769_80k_cityscapes/deeplabv3_r50b-d8_769x769_80k_cityscapes-20201225_155404.log.json) |
+| DeepLabV3 | R-101b-D8 | 769x769 | 80000 | 10.7 | 0.82 | 79.41 | 80.73 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r101b-d8_769x769_80k_cityscapes.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101b-d8_769x769_80k_cityscapes/deeplabv3_r101b-d8_769x769_80k_cityscapes_20201226_190843-9142ee57.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101b-d8_769x769_80k_cityscapes/deeplabv3_r101b-d8_769x769_80k_cityscapes-20201226_190843.log.json) |
+
+### ADE20K
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| --------- | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | ----------------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
+| DeepLabV3 | R-50-D8 | 512x512 | 80000 | 8.9 | 14.76 | 42.42 | 43.28 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r50-d8_512x512_80k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_80k_ade20k/deeplabv3_r50-d8_512x512_80k_ade20k_20200614_185028-0bb3f844.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_80k_ade20k/deeplabv3_r50-d8_512x512_80k_ade20k_20200614_185028.log.json) |
+| DeepLabV3 | R-101-D8 | 512x512 | 80000 | 12.4 | 10.14 | 44.08 | 45.19 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r101-d8_512x512_80k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_80k_ade20k/deeplabv3_r101-d8_512x512_80k_ade20k_20200615_021256-d89c7fa4.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_80k_ade20k/deeplabv3_r101-d8_512x512_80k_ade20k_20200615_021256.log.json) |
+| DeepLabV3 | R-50-D8 | 512x512 | 160000 | - | - | 42.66 | 44.09 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r50-d8_512x512_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_160k_ade20k/deeplabv3_r50-d8_512x512_160k_ade20k_20200615_123227-5d0ee427.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_160k_ade20k/deeplabv3_r50-d8_512x512_160k_ade20k_20200615_123227.log.json) |
+| DeepLabV3 | R-101-D8 | 512x512 | 160000 | - | - | 45.00 | 46.66 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r101-d8_512x512_160k_ade20k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_160k_ade20k/deeplabv3_r101-d8_512x512_160k_ade20k_20200615_105816-b1f72b3b.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_160k_ade20k/deeplabv3_r101-d8_512x512_160k_ade20k_20200615_105816.log.json) |
+
+### Pascal VOC 2012 + Aug
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| --------- | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | ------------------------------------------------------------------------------------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
+| DeepLabV3 | R-50-D8 | 512x512 | 20000 | 6.1 | 13.88 | 76.17 | 77.42 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r50-d8_512x512_20k_voc12aug.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_20k_voc12aug/deeplabv3_r50-d8_512x512_20k_voc12aug_20200617_010906-596905ef.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_20k_voc12aug/deeplabv3_r50-d8_512x512_20k_voc12aug_20200617_010906.log.json) |
+| DeepLabV3 | R-101-D8 | 512x512 | 20000 | 9.6 | 9.81 | 78.70 | 79.95 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r101-d8_512x512_20k_voc12aug.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_20k_voc12aug/deeplabv3_r101-d8_512x512_20k_voc12aug_20200617_010932-8d13832f.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_20k_voc12aug/deeplabv3_r101-d8_512x512_20k_voc12aug_20200617_010932.log.json) |
+| DeepLabV3 | R-50-D8 | 512x512 | 40000 | - | - | 77.68 | 78.78 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r50-d8_512x512_40k_voc12aug.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_40k_voc12aug/deeplabv3_r50-d8_512x512_40k_voc12aug_20200613_161546-2ae96e7e.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_40k_voc12aug/deeplabv3_r50-d8_512x512_40k_voc12aug_20200613_161546.log.json) |
+| DeepLabV3 | R-101-D8 | 512x512 | 40000 | - | - | 77.92 | 79.18 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r101-d8_512x512_40k_voc12aug.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_40k_voc12aug/deeplabv3_r101-d8_512x512_40k_voc12aug_20200613_161432-0017d784.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_40k_voc12aug/deeplabv3_r101-d8_512x512_40k_voc12aug_20200613_161432.log.json) |
+
+### Pascal Context
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| --------- | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | ------------------------------------------------------------------------------------------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
+| DeepLabV3 | R-101-D8 | 480x480 | 40000 | 9.2 | 7.09 | 46.55 | 47.81 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r101-d8_480x480_40k_pascal_context.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_480x480_40k_pascal_context/deeplabv3_r101-d8_480x480_40k_pascal_context_20200911_204118-1aa27336.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_480x480_40k_pascal_context/deeplabv3_r101-d8_480x480_40k_pascal_context-20200911_204118.log.json) |
+| DeepLabV3 | R-101-D8 | 480x480 | 80000 | - | - | 46.42 | 47.53 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r101-d8_480x480_80k_pascal_context.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_480x480_80k_pascal_context/deeplabv3_r101-d8_480x480_80k_pascal_context_20200911_170155-2a21fff3.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_480x480_80k_pascal_context/deeplabv3_r101-d8_480x480_80k_pascal_context-20200911_170155.log.json) |
+
+### Pascal Context 59
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| --------- | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | ------------------------------------------------------------------------------------------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
+| DeepLabV3 | R-101-D8 | 480x480 | 40000 | - | - | 52.61 | 54.28 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r101-d8_480x480_40k_pascal_context_59.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_480x480_40k_pascal_context_59/deeplabv3_r101-d8_480x480_40k_pascal_context_59_20210416_110332-cb08ea46.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_480x480_40k_pascal_context_59/deeplabv3_r101-d8_480x480_40k_pascal_context_59-20210416_110332.log.json) |
+| DeepLabV3 | R-101-D8 | 480x480 | 80000 | - | - | 52.46 | 54.09 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3/deeplabv3_r101-d8_480x480_80k_pascal_context_59.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_480x480_80k_pascal_context_59/deeplabv3_r101-d8_480x480_80k_pascal_context_59_20210416_113002-26303993.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_480x480_80k_pascal_context_59/deeplabv3_r101-d8_480x480_80k_pascal_context_59-20210416_113002.log.json) |
+
+### COCO-Stuff 10k
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| --------- | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | ----------------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
+| DeepLabV3 | R-50-D8 | 512x512 | 20000 | 9.6 | 10.8 | 34.66 | 36.08 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3_r50-d8_512x512_4x4_20k_coco-stuff10k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_4x4_20k_coco-stuff10k/deeplabv3_r50-d8_512x512_4x4_20k_coco-stuff10k_20210821_043025-b35f789d.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_4x4_20k_coco-stuff10k/deeplabv3_r50-d8_512x512_4x4_20k_coco-stuff10k_20210821_043025.log.json) |
+| DeepLabV3 | R-101-D8 | 512x512 | 20000 | 13.2 | 8.7 | 37.30 | 38.42 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3_r101-d8_512x512_4x4_20k_coco-stuff10k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_4x4_20k_coco-stuff10k/deeplabv3_r101-d8_512x512_4x4_20k_coco-stuff10k_20210821_043025-c49752cb.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_4x4_20k_coco-stuff10k/deeplabv3_r101-d8_512x512_4x4_20k_coco-stuff10k_20210821_043025.log.json) |
+| DeepLabV3 | R-50-D8 | 512x512 | 40000 | - | - | 35.73 | 37.09 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3_r50-d8_512x512_4x4_40k_coco-stuff10k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_4x4_40k_coco-stuff10k/deeplabv3_r50-d8_512x512_4x4_40k_coco-stuff10k_20210821_043305-dc76f3ff.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_4x4_40k_coco-stuff10k/deeplabv3_r50-d8_512x512_4x4_40k_coco-stuff10k_20210821_043305.log.json) |
+| DeepLabV3 | R-101-D8 | 512x512 | 40000 | - | - | 37.81 | 38.80 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3_r101-d8_512x512_4x4_40k_coco-stuff10k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_4x4_40k_coco-stuff10k/deeplabv3_r101-d8_512x512_4x4_40k_coco-stuff10k_20210821_043305-636cb433.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_4x4_40k_coco-stuff10k/deeplabv3_r101-d8_512x512_4x4_40k_coco-stuff10k_20210821_043305.log.json) |
+
+### COCO-Stuff 164k
+
+| Method | Backbone | Crop Size | Lr schd | Mem (GB) | Inf time (fps) | mIoU | mIoU(ms+flip) | config | download |
+| --------- | -------- | --------- | ------: | -------- | -------------- | ----: | ------------: | ----------------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
+| DeepLabV3 | R-50-D8 | 512x512 | 80000 | 9.6 | 10.8 | 39.38 | 40.03 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3_r50-d8_512x512_4x4_80k_coco-stuff164k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_4x4_80k_coco-stuff164k/deeplabv3_r50-d8_512x512_4x4_80k_coco-stuff164k_20210709_163016-88675c24.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_4x4_80k_coco-stuff164k/deeplabv3_r50-d8_512x512_4x4_80k_coco-stuff164k_20210709_163016.log.json) |
+| DeepLabV3 | R-101-D8 | 512x512 | 80000 | 13.2 | 8.7 | 40.87 | 41.50 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3_r101-d8_512x512_4x4_80k_coco-stuff164k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_4x4_80k_coco-stuff164k/deeplabv3_r101-d8_512x512_4x4_80k_coco-stuff164k_20210709_201252-13600dc2.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_4x4_80k_coco-stuff164k/deeplabv3_r101-d8_512x512_4x4_80k_coco-stuff164k_20210709_201252.log.json) |
+| DeepLabV3 | R-50-D8 | 512x512 | 160000 | - | - | 41.09 | 41.69 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3_r50-d8_512x512_4x4_160k_coco-stuff164k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_4x4_160k_coco-stuff164k/deeplabv3_r50-d8_512x512_4x4_160k_coco-stuff164k_20210709_163016-49f2812b.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_4x4_160k_coco-stuff164k/deeplabv3_r50-d8_512x512_4x4_160k_coco-stuff164k_20210709_163016.log.json) |
+| DeepLabV3 | R-101-D8 | 512x512 | 160000 | - | - | 41.82 | 42.49 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3_r101-d8_512x512_4x4_160k_coco-stuff164k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_4x4_160k_coco-stuff164k/deeplabv3_r101-d8_512x512_4x4_160k_coco-stuff164k_20210709_155402-f035acfd.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_4x4_160k_coco-stuff164k/deeplabv3_r101-d8_512x512_4x4_160k_coco-stuff164k_20210709_155402.log.json) |
+| DeepLabV3 | R-50-D8 | 512x512 | 320000 | - | - | 41.37 | 42.22 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3_r50-d8_512x512_4x4_320k_coco-stuff164k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_4x4_320k_coco-stuff164k/deeplabv3_r50-d8_512x512_4x4_320k_coco-stuff164k_20210709_155403-51b21115.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_4x4_320k_coco-stuff164k/deeplabv3_r50-d8_512x512_4x4_320k_coco-stuff164k_20210709_155403.log.json) |
+| DeepLabV3 | R-101-D8 | 512x512 | 320000 | - | - | 42.61 | 43.42 | [config](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3_r101-d8_512x512_4x4_320k_coco-stuff164k.py) | [model](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_4x4_320k_coco-stuff164k/deeplabv3_r101-d8_512x512_4x4_320k_coco-stuff164k_20210709_155402-3cbca14d.pth) | [log](https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_4x4_320k_coco-stuff164k/deeplabv3_r101-d8_512x512_4x4_320k_coco-stuff164k_20210709_155402.log.json) |
+
+Note:
+
+- `D-8` here corresponding to the output stride 8 setting for DeepLab series.
+- `FP16` means Mixed Precision (FP16) is adopted in training.
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3.yml b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3.yml
new file mode 100644
index 0000000000000000000000000000000000000000..559af4f69ced5b2a8c3dcc4c68d8b5532f8fb879
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3.yml
@@ -0,0 +1,756 @@
+Collections:
+- Name: DeepLabV3
+ Metadata:
+ Training Data:
+ - Cityscapes
+ - ADE20K
+ - Pascal VOC 2012 + Aug
+ - Pascal Context
+ - Pascal Context 59
+ - COCO-Stuff 10k
+ - COCO-Stuff 164k
+ Paper:
+ URL: https://arxiv.org/abs/1706.05587
+ Title: Rethinking atrous convolution for semantic image segmentation
+ README: configs/deeplabv3/README.md
+ Code:
+ URL: https://github.com/open-mmlab/mmsegmentation/blob/v0.17.0/mmseg/models/decode_heads/aspp_head.py#L54
+ Version: v0.17.0
+ Converted From:
+ Code: https://github.com/tensorflow/models/tree/master/research/deeplab
+Models:
+- Name: deeplabv3_r50-d8_512x1024_40k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,1024)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 389.11
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,1024)
+ Training Memory (GB): 6.1
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 79.09
+ mIoU(ms+flip): 80.45
+ Config: configs/deeplabv3/deeplabv3_r50-d8_512x1024_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x1024_40k_cityscapes/deeplabv3_r50-d8_512x1024_40k_cityscapes_20200605_022449-acadc2f8.pth
+- Name: deeplabv3_r101-d8_512x1024_40k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,1024)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 520.83
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,1024)
+ Training Memory (GB): 9.6
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 77.12
+ mIoU(ms+flip): 79.61
+ Config: configs/deeplabv3/deeplabv3_r101-d8_512x1024_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x1024_40k_cityscapes/deeplabv3_r101-d8_512x1024_40k_cityscapes_20200605_012241-7fd3f799.pth
+- Name: deeplabv3_r50-d8_769x769_40k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-50-D8
+ crop size: (769,769)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 900.9
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (769,769)
+ Training Memory (GB): 6.9
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 78.58
+ mIoU(ms+flip): 79.89
+ Config: configs/deeplabv3/deeplabv3_r50-d8_769x769_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_769x769_40k_cityscapes/deeplabv3_r50-d8_769x769_40k_cityscapes_20200606_113723-7eda553c.pth
+- Name: deeplabv3_r101-d8_769x769_40k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (769,769)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 1204.82
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (769,769)
+ Training Memory (GB): 10.9
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 79.27
+ mIoU(ms+flip): 80.11
+ Config: configs/deeplabv3/deeplabv3_r101-d8_769x769_40k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_769x769_40k_cityscapes/deeplabv3_r101-d8_769x769_40k_cityscapes_20200606_113809-c64f889f.pth
+- Name: deeplabv3_r18-d8_512x1024_80k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-18-D8
+ crop size: (512,1024)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 72.57
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,1024)
+ Training Memory (GB): 1.7
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 76.7
+ mIoU(ms+flip): 78.27
+ Config: configs/deeplabv3/deeplabv3_r18-d8_512x1024_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r18-d8_512x1024_80k_cityscapes/deeplabv3_r18-d8_512x1024_80k_cityscapes_20201225_021506-23dffbe2.pth
+- Name: deeplabv3_r50-d8_512x1024_80k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,1024)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 79.32
+ mIoU(ms+flip): 80.57
+ Config: configs/deeplabv3/deeplabv3_r50-d8_512x1024_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x1024_80k_cityscapes/deeplabv3_r50-d8_512x1024_80k_cityscapes_20200606_113404-b92cfdd4.pth
+- Name: deeplabv3_r101-d8_512x1024_80k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,1024)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 80.2
+ mIoU(ms+flip): 81.21
+ Config: configs/deeplabv3/deeplabv3_r101-d8_512x1024_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x1024_80k_cityscapes/deeplabv3_r101-d8_512x1024_80k_cityscapes_20200606_113503-9e428899.pth
+- Name: deeplabv3_r101-d8_fp16_512x1024_80k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,1024)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 259.07
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP16
+ resolution: (512,1024)
+ Training Memory (GB): 5.75
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 80.48
+ Config: configs/deeplabv3/deeplabv3_r101-d8_fp16_512x1024_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_fp16_512x1024_80k_cityscapes/deeplabv3_r101-d8_fp16_512x1024_80k_cityscapes_20200717_230920-774d9cec.pth
+- Name: deeplabv3_r18-d8_769x769_80k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-18-D8
+ crop size: (769,769)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 180.18
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (769,769)
+ Training Memory (GB): 1.9
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 76.6
+ mIoU(ms+flip): 78.26
+ Config: configs/deeplabv3/deeplabv3_r18-d8_769x769_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r18-d8_769x769_80k_cityscapes/deeplabv3_r18-d8_769x769_80k_cityscapes_20201225_021506-6452126a.pth
+- Name: deeplabv3_r50-d8_769x769_80k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-50-D8
+ crop size: (769,769)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 79.89
+ mIoU(ms+flip): 81.06
+ Config: configs/deeplabv3/deeplabv3_r50-d8_769x769_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_769x769_80k_cityscapes/deeplabv3_r50-d8_769x769_80k_cityscapes_20200606_221338-788d6228.pth
+- Name: deeplabv3_r101-d8_769x769_80k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (769,769)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 79.67
+ mIoU(ms+flip): 80.81
+ Config: configs/deeplabv3/deeplabv3_r101-d8_769x769_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_769x769_80k_cityscapes/deeplabv3_r101-d8_769x769_80k_cityscapes_20200607_013353-60e95418.pth
+- Name: deeplabv3_r101-d16-mg124_512x1024_80k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D16-MG124
+ crop size: (512,1024)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 78.36
+ mIoU(ms+flip): 79.84
+ Config: configs/deeplabv3/deeplabv3_r101-d16-mg124_512x1024_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d16-mg124_512x1024_80k_cityscapes/deeplabv3_r101-d16-mg124_512x1024_80k_cityscapes_20200908_005644-57bb8425.pth
+- Name: deeplabv3_r18b-d8_512x1024_80k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-18b-D8
+ crop size: (512,1024)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 71.79
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,1024)
+ Training Memory (GB): 1.6
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 76.26
+ mIoU(ms+flip): 77.88
+ Config: configs/deeplabv3/deeplabv3_r18b-d8_512x1024_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r18b-d8_512x1024_80k_cityscapes/deeplabv3_r18b-d8_512x1024_80k_cityscapes_20201225_094144-46040cef.pth
+- Name: deeplabv3_r50b-d8_512x1024_80k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-50b-D8
+ crop size: (512,1024)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 364.96
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,1024)
+ Training Memory (GB): 6.0
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 79.63
+ mIoU(ms+flip): 80.98
+ Config: configs/deeplabv3/deeplabv3_r50b-d8_512x1024_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50b-d8_512x1024_80k_cityscapes/deeplabv3_r50b-d8_512x1024_80k_cityscapes_20201225_155148-ec368954.pth
+- Name: deeplabv3_r101b-d8_512x1024_80k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101b-D8
+ crop size: (512,1024)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 552.49
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,1024)
+ Training Memory (GB): 9.5
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 80.01
+ mIoU(ms+flip): 81.21
+ Config: configs/deeplabv3/deeplabv3_r101b-d8_512x1024_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101b-d8_512x1024_80k_cityscapes/deeplabv3_r101b-d8_512x1024_80k_cityscapes_20201226_171821-8fd49503.pth
+- Name: deeplabv3_r18b-d8_769x769_80k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-18b-D8
+ crop size: (769,769)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 172.71
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (769,769)
+ Training Memory (GB): 1.8
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 76.63
+ mIoU(ms+flip): 77.51
+ Config: configs/deeplabv3/deeplabv3_r18b-d8_769x769_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r18b-d8_769x769_80k_cityscapes/deeplabv3_r18b-d8_769x769_80k_cityscapes_20201225_094144-fdc985d9.pth
+- Name: deeplabv3_r50b-d8_769x769_80k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-50b-D8
+ crop size: (769,769)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 862.07
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (769,769)
+ Training Memory (GB): 6.8
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 78.8
+ mIoU(ms+flip): 80.27
+ Config: configs/deeplabv3/deeplabv3_r50b-d8_769x769_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50b-d8_769x769_80k_cityscapes/deeplabv3_r50b-d8_769x769_80k_cityscapes_20201225_155404-87fb0cf4.pth
+- Name: deeplabv3_r101b-d8_769x769_80k_cityscapes
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101b-D8
+ crop size: (769,769)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 1219.51
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (769,769)
+ Training Memory (GB): 10.7
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Cityscapes
+ Metrics:
+ mIoU: 79.41
+ mIoU(ms+flip): 80.73
+ Config: configs/deeplabv3/deeplabv3_r101b-d8_769x769_80k_cityscapes.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101b-d8_769x769_80k_cityscapes/deeplabv3_r101b-d8_769x769_80k_cityscapes_20201226_190843-9142ee57.pth
+- Name: deeplabv3_r50-d8_512x512_80k_ade20k
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 67.75
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 8.9
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 42.42
+ mIoU(ms+flip): 43.28
+ Config: configs/deeplabv3/deeplabv3_r50-d8_512x512_80k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_80k_ade20k/deeplabv3_r50-d8_512x512_80k_ade20k_20200614_185028-0bb3f844.pth
+- Name: deeplabv3_r101-d8_512x512_80k_ade20k
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 98.62
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 12.4
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 44.08
+ mIoU(ms+flip): 45.19
+ Config: configs/deeplabv3/deeplabv3_r101-d8_512x512_80k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_80k_ade20k/deeplabv3_r101-d8_512x512_80k_ade20k_20200615_021256-d89c7fa4.pth
+- Name: deeplabv3_r50-d8_512x512_160k_ade20k
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 160000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 42.66
+ mIoU(ms+flip): 44.09
+ Config: configs/deeplabv3/deeplabv3_r50-d8_512x512_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_160k_ade20k/deeplabv3_r50-d8_512x512_160k_ade20k_20200615_123227-5d0ee427.pth
+- Name: deeplabv3_r101-d8_512x512_160k_ade20k
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 160000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: ADE20K
+ Metrics:
+ mIoU: 45.0
+ mIoU(ms+flip): 46.66
+ Config: configs/deeplabv3/deeplabv3_r101-d8_512x512_160k_ade20k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_160k_ade20k/deeplabv3_r101-d8_512x512_160k_ade20k_20200615_105816-b1f72b3b.pth
+- Name: deeplabv3_r50-d8_512x512_20k_voc12aug
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 20000
+ inference time (ms/im):
+ - value: 72.05
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 6.1
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal VOC 2012 + Aug
+ Metrics:
+ mIoU: 76.17
+ mIoU(ms+flip): 77.42
+ Config: configs/deeplabv3/deeplabv3_r50-d8_512x512_20k_voc12aug.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_20k_voc12aug/deeplabv3_r50-d8_512x512_20k_voc12aug_20200617_010906-596905ef.pth
+- Name: deeplabv3_r101-d8_512x512_20k_voc12aug
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 20000
+ inference time (ms/im):
+ - value: 101.94
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 9.6
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal VOC 2012 + Aug
+ Metrics:
+ mIoU: 78.7
+ mIoU(ms+flip): 79.95
+ Config: configs/deeplabv3/deeplabv3_r101-d8_512x512_20k_voc12aug.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_20k_voc12aug/deeplabv3_r101-d8_512x512_20k_voc12aug_20200617_010932-8d13832f.pth
+- Name: deeplabv3_r50-d8_512x512_40k_voc12aug
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 40000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal VOC 2012 + Aug
+ Metrics:
+ mIoU: 77.68
+ mIoU(ms+flip): 78.78
+ Config: configs/deeplabv3/deeplabv3_r50-d8_512x512_40k_voc12aug.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_40k_voc12aug/deeplabv3_r50-d8_512x512_40k_voc12aug_20200613_161546-2ae96e7e.pth
+- Name: deeplabv3_r101-d8_512x512_40k_voc12aug
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 40000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal VOC 2012 + Aug
+ Metrics:
+ mIoU: 77.92
+ mIoU(ms+flip): 79.18
+ Config: configs/deeplabv3/deeplabv3_r101-d8_512x512_40k_voc12aug.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_40k_voc12aug/deeplabv3_r101-d8_512x512_40k_voc12aug_20200613_161432-0017d784.pth
+- Name: deeplabv3_r101-d8_480x480_40k_pascal_context
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (480,480)
+ lr schd: 40000
+ inference time (ms/im):
+ - value: 141.04
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (480,480)
+ Training Memory (GB): 9.2
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal Context
+ Metrics:
+ mIoU: 46.55
+ mIoU(ms+flip): 47.81
+ Config: configs/deeplabv3/deeplabv3_r101-d8_480x480_40k_pascal_context.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_480x480_40k_pascal_context/deeplabv3_r101-d8_480x480_40k_pascal_context_20200911_204118-1aa27336.pth
+- Name: deeplabv3_r101-d8_480x480_80k_pascal_context
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (480,480)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal Context
+ Metrics:
+ mIoU: 46.42
+ mIoU(ms+flip): 47.53
+ Config: configs/deeplabv3/deeplabv3_r101-d8_480x480_80k_pascal_context.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_480x480_80k_pascal_context/deeplabv3_r101-d8_480x480_80k_pascal_context_20200911_170155-2a21fff3.pth
+- Name: deeplabv3_r101-d8_480x480_40k_pascal_context_59
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (480,480)
+ lr schd: 40000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal Context 59
+ Metrics:
+ mIoU: 52.61
+ mIoU(ms+flip): 54.28
+ Config: configs/deeplabv3/deeplabv3_r101-d8_480x480_40k_pascal_context_59.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_480x480_40k_pascal_context_59/deeplabv3_r101-d8_480x480_40k_pascal_context_59_20210416_110332-cb08ea46.pth
+- Name: deeplabv3_r101-d8_480x480_80k_pascal_context_59
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (480,480)
+ lr schd: 80000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: Pascal Context 59
+ Metrics:
+ mIoU: 52.46
+ mIoU(ms+flip): 54.09
+ Config: configs/deeplabv3/deeplabv3_r101-d8_480x480_80k_pascal_context_59.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_480x480_80k_pascal_context_59/deeplabv3_r101-d8_480x480_80k_pascal_context_59_20210416_113002-26303993.pth
+- Name: deeplabv3_r50-d8_512x512_4x4_20k_coco-stuff10k
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 20000
+ inference time (ms/im):
+ - value: 92.59
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 9.6
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: COCO-Stuff 10k
+ Metrics:
+ mIoU: 34.66
+ mIoU(ms+flip): 36.08
+ Config: configs/deeplabv3/deeplabv3_r50-d8_512x512_4x4_20k_coco-stuff10k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_4x4_20k_coco-stuff10k/deeplabv3_r50-d8_512x512_4x4_20k_coco-stuff10k_20210821_043025-b35f789d.pth
+- Name: deeplabv3_r101-d8_512x512_4x4_20k_coco-stuff10k
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 20000
+ inference time (ms/im):
+ - value: 114.94
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 13.2
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: COCO-Stuff 10k
+ Metrics:
+ mIoU: 37.3
+ mIoU(ms+flip): 38.42
+ Config: configs/deeplabv3/deeplabv3_r101-d8_512x512_4x4_20k_coco-stuff10k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_4x4_20k_coco-stuff10k/deeplabv3_r101-d8_512x512_4x4_20k_coco-stuff10k_20210821_043025-c49752cb.pth
+- Name: deeplabv3_r50-d8_512x512_4x4_40k_coco-stuff10k
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 40000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: COCO-Stuff 10k
+ Metrics:
+ mIoU: 35.73
+ mIoU(ms+flip): 37.09
+ Config: configs/deeplabv3/deeplabv3_r50-d8_512x512_4x4_40k_coco-stuff10k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_4x4_40k_coco-stuff10k/deeplabv3_r50-d8_512x512_4x4_40k_coco-stuff10k_20210821_043305-dc76f3ff.pth
+- Name: deeplabv3_r101-d8_512x512_4x4_40k_coco-stuff10k
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 40000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: COCO-Stuff 10k
+ Metrics:
+ mIoU: 37.81
+ mIoU(ms+flip): 38.8
+ Config: configs/deeplabv3/deeplabv3_r101-d8_512x512_4x4_40k_coco-stuff10k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_4x4_40k_coco-stuff10k/deeplabv3_r101-d8_512x512_4x4_40k_coco-stuff10k_20210821_043305-636cb433.pth
+- Name: deeplabv3_r50-d8_512x512_4x4_80k_coco-stuff164k
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 92.59
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 9.6
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: COCO-Stuff 164k
+ Metrics:
+ mIoU: 39.38
+ mIoU(ms+flip): 40.03
+ Config: configs/deeplabv3/deeplabv3_r50-d8_512x512_4x4_80k_coco-stuff164k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_4x4_80k_coco-stuff164k/deeplabv3_r50-d8_512x512_4x4_80k_coco-stuff164k_20210709_163016-88675c24.pth
+- Name: deeplabv3_r101-d8_512x512_4x4_80k_coco-stuff164k
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 80000
+ inference time (ms/im):
+ - value: 114.94
+ hardware: V100
+ backend: PyTorch
+ batch size: 1
+ mode: FP32
+ resolution: (512,512)
+ Training Memory (GB): 13.2
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: COCO-Stuff 164k
+ Metrics:
+ mIoU: 40.87
+ mIoU(ms+flip): 41.5
+ Config: configs/deeplabv3/deeplabv3_r101-d8_512x512_4x4_80k_coco-stuff164k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_4x4_80k_coco-stuff164k/deeplabv3_r101-d8_512x512_4x4_80k_coco-stuff164k_20210709_201252-13600dc2.pth
+- Name: deeplabv3_r50-d8_512x512_4x4_160k_coco-stuff164k
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 160000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: COCO-Stuff 164k
+ Metrics:
+ mIoU: 41.09
+ mIoU(ms+flip): 41.69
+ Config: configs/deeplabv3/deeplabv3_r50-d8_512x512_4x4_160k_coco-stuff164k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_4x4_160k_coco-stuff164k/deeplabv3_r50-d8_512x512_4x4_160k_coco-stuff164k_20210709_163016-49f2812b.pth
+- Name: deeplabv3_r101-d8_512x512_4x4_160k_coco-stuff164k
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 160000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: COCO-Stuff 164k
+ Metrics:
+ mIoU: 41.82
+ mIoU(ms+flip): 42.49
+ Config: configs/deeplabv3/deeplabv3_r101-d8_512x512_4x4_160k_coco-stuff164k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_4x4_160k_coco-stuff164k/deeplabv3_r101-d8_512x512_4x4_160k_coco-stuff164k_20210709_155402-f035acfd.pth
+- Name: deeplabv3_r50-d8_512x512_4x4_320k_coco-stuff164k
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-50-D8
+ crop size: (512,512)
+ lr schd: 320000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: COCO-Stuff 164k
+ Metrics:
+ mIoU: 41.37
+ mIoU(ms+flip): 42.22
+ Config: configs/deeplabv3/deeplabv3_r50-d8_512x512_4x4_320k_coco-stuff164k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r50-d8_512x512_4x4_320k_coco-stuff164k/deeplabv3_r50-d8_512x512_4x4_320k_coco-stuff164k_20210709_155403-51b21115.pth
+- Name: deeplabv3_r101-d8_512x512_4x4_320k_coco-stuff164k
+ In Collection: DeepLabV3
+ Metadata:
+ backbone: R-101-D8
+ crop size: (512,512)
+ lr schd: 320000
+ Results:
+ - Task: Semantic Segmentation
+ Dataset: COCO-Stuff 164k
+ Metrics:
+ mIoU: 42.61
+ mIoU(ms+flip): 43.42
+ Config: configs/deeplabv3/deeplabv3_r101-d8_512x512_4x4_320k_coco-stuff164k.py
+ Weights: https://download.openmmlab.com/mmsegmentation/v0.5/deeplabv3/deeplabv3_r101-d8_512x512_4x4_320k_coco-stuff164k/deeplabv3_r101-d8_512x512_4x4_320k_coco-stuff164k_20210709_155402-3cbca14d.pth
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d16-mg124_512x1024_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d16-mg124_512x1024_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..f20f260e23a95dfee9dfdceef9badab992246f53
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d16-mg124_512x1024_40k_cityscapes.py
@@ -0,0 +1,11 @@
+_base_ = './deeplabv3_r50-d8_512x1024_40k_cityscapes.py'
+model = dict(
+ pretrained='open-mmlab://resnet101_v1c',
+ backbone=dict(
+ depth=101,
+ dilations=(1, 1, 1, 2),
+ strides=(1, 2, 2, 1),
+ multi_grid=(1, 2, 4)),
+ decode_head=dict(
+ dilations=(1, 6, 12, 18),
+ sampler=dict(type='OHEMPixelSampler', min_kept=100000)))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d16-mg124_512x1024_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d16-mg124_512x1024_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..de4a8a5e9f030f1e8a8802596885186163f23eed
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d16-mg124_512x1024_80k_cityscapes.py
@@ -0,0 +1,11 @@
+_base_ = './deeplabv3_r50-d8_512x1024_80k_cityscapes.py'
+model = dict(
+ pretrained='open-mmlab://resnet101_v1c',
+ backbone=dict(
+ depth=101,
+ dilations=(1, 1, 1, 2),
+ strides=(1, 2, 2, 1),
+ multi_grid=(1, 2, 4)),
+ decode_head=dict(
+ dilations=(1, 6, 12, 18),
+ sampler=dict(type='OHEMPixelSampler', min_kept=100000)))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_480x480_40k_pascal_context.py b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_480x480_40k_pascal_context.py
new file mode 100644
index 0000000000000000000000000000000000000000..0b5256f7b7b053cbe8d9e4ca2ec6139bb02387f6
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_480x480_40k_pascal_context.py
@@ -0,0 +1,2 @@
+_base_ = './deeplabv3_r50-d8_480x480_40k_pascal_context.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_480x480_40k_pascal_context_59.py b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_480x480_40k_pascal_context_59.py
new file mode 100644
index 0000000000000000000000000000000000000000..4874121fd01e4024bfde445f451b7368c6834511
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_480x480_40k_pascal_context_59.py
@@ -0,0 +1,2 @@
+_base_ = './deeplabv3_r50-d8_480x480_40k_pascal_context_59.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_480x480_80k_pascal_context.py b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_480x480_80k_pascal_context.py
new file mode 100644
index 0000000000000000000000000000000000000000..001b7a69c15299fc1fe5b269a5accf92c5ece032
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_480x480_80k_pascal_context.py
@@ -0,0 +1,2 @@
+_base_ = './deeplabv3_r50-d8_480x480_80k_pascal_context.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_480x480_80k_pascal_context_59.py b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_480x480_80k_pascal_context_59.py
new file mode 100644
index 0000000000000000000000000000000000000000..032dc8b6219421698c3a1bfb4bca5addfeea1ab3
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_480x480_80k_pascal_context_59.py
@@ -0,0 +1,2 @@
+_base_ = './deeplabv3_r50-d8_480x480_80k_pascal_context_59.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x1024_40k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x1024_40k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..8c707c79d659bc544d242352bcb29686eb40b004
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x1024_40k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './deeplabv3_r50-d8_512x1024_40k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x1024_80k_cityscapes.py b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x1024_80k_cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..6804a5781369d1031f179d421a3b5a160fd575d3
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x1024_80k_cityscapes.py
@@ -0,0 +1,2 @@
+_base_ = './deeplabv3_r50-d8_512x1024_80k_cityscapes.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x512_160k_ade20k.py b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x512_160k_ade20k.py
new file mode 100644
index 0000000000000000000000000000000000000000..df6f36ef7c3b71ba7979aa7a1b226b3e3ebd9bb4
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x512_160k_ade20k.py
@@ -0,0 +1,2 @@
+_base_ = './deeplabv3_r50-d8_512x512_160k_ade20k.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x512_20k_voc12aug.py b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x512_20k_voc12aug.py
new file mode 100644
index 0000000000000000000000000000000000000000..40f5f62373e59d1c6c01ca3f57777698461127c9
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x512_20k_voc12aug.py
@@ -0,0 +1,2 @@
+_base_ = './deeplabv3_r50-d8_512x512_20k_voc12aug.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x512_40k_voc12aug.py b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x512_40k_voc12aug.py
new file mode 100644
index 0000000000000000000000000000000000000000..fb2be22f8bc2e10cdfba4f58b2ad1ced913b4ea4
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x512_40k_voc12aug.py
@@ -0,0 +1,2 @@
+_base_ = './deeplabv3_r50-d8_512x512_40k_voc12aug.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
diff --git a/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x512_4x4_160k_coco-stuff164k.py b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x512_4x4_160k_coco-stuff164k.py
new file mode 100644
index 0000000000000000000000000000000000000000..76b124248e14c5dccea55ea2ea91c63409e0ffec
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/deeplabv3/deeplabv3_r101-d8_512x512_4x4_160k_coco-stuff164k.py
@@ -0,0 +1,2 @@
+_base_ = './deeplabv3_r50-d8_512x512_4x4_160k_coco-stuff164k.py'
+model = dict(pretrained='open-mmlab://resnet101_v1c', backbone=dict(depth=101))
+