diff --git a/EgoHOS/raw/script/mmsegmentation/configs/segmenter/README.md b/EgoHOS/raw/script/mmsegmentation/configs/segmenter/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..1d092a12d5ae5bf941747bd8a24e37263d201fde
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/configs/segmenter/README.md
@@ -0,0 +1,74 @@
+# Segmenter
+
+[Segmenter: Transformer for Semantic Segmentation](https://arxiv.org/abs/2105.05633)
+
+## Introduction
+
+
+
+Official Repo
+
+Code Snippet
+
+## Abstract
+
+
+
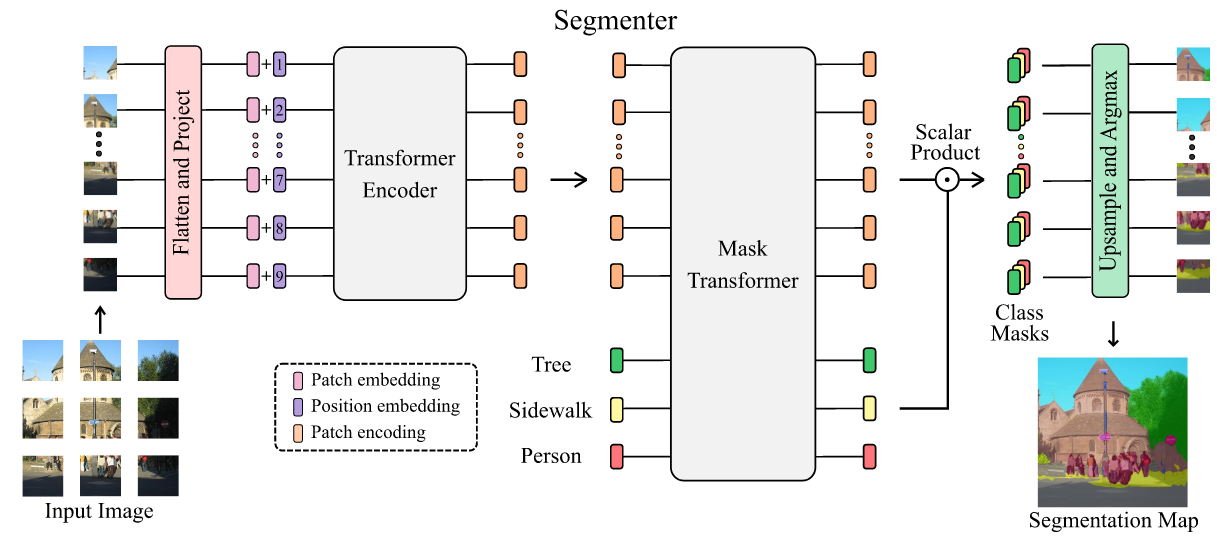
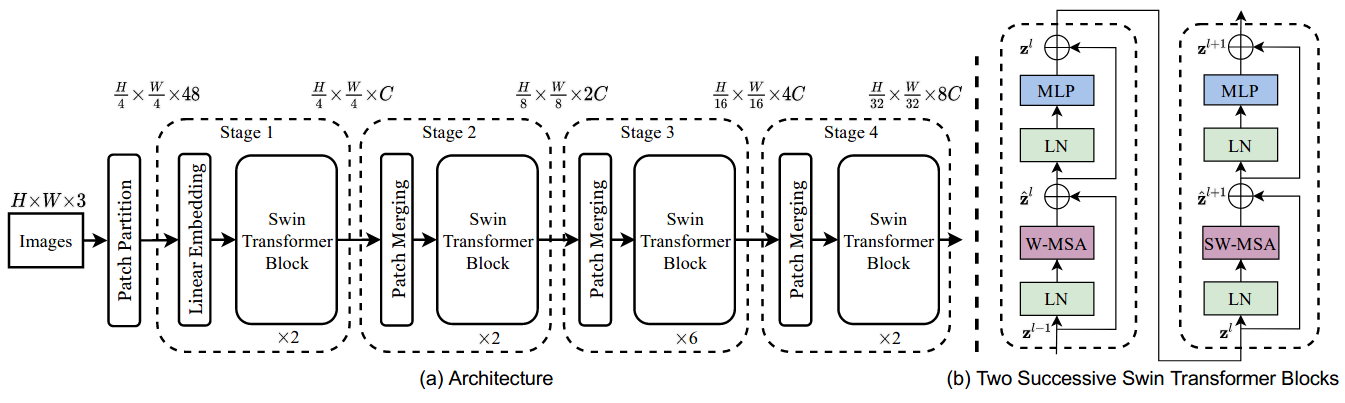
+Image segmentation is often ambiguous at the level of individual image patches and requires contextual information to reach label consensus. In this paper we introduce Segmenter, a transformer model for semantic segmentation. In contrast to convolution-based methods, our approach allows to model global context already at the first layer and throughout the network. We build on the recent Vision Transformer (ViT) and extend it to semantic segmentation. To do so, we rely on the output embeddings corresponding to image patches and obtain class labels from these embeddings with a point-wise linear decoder or a mask transformer decoder. We leverage models pre-trained for image classification and show that we can fine-tune them on moderate sized datasets available for semantic segmentation. The linear decoder allows to obtain excellent results already, but the performance can be further improved by a mask transformer generating class masks. We conduct an extensive ablation study to show the impact of the different parameters, in particular the performance is better for large models and small patch sizes. Segmenter attains excellent results for semantic segmentation. It outperforms the state of the art on both ADE20K and Pascal Context datasets and is competitive on Cityscapes.
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
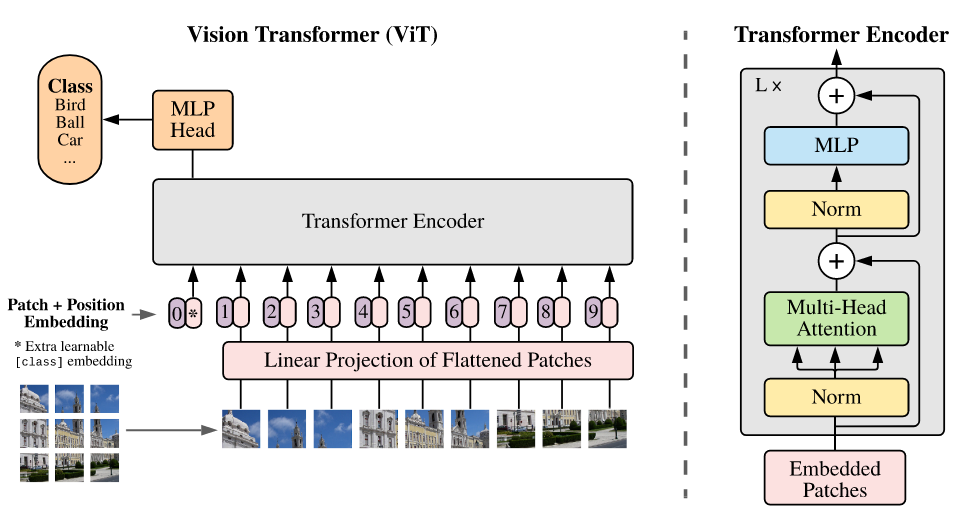
+
 "
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "id": "FVmnaxFJvsb8"
+ },
+ "source": [
+ "# MMSegmentation Tutorial\n",
+ "Welcome to MMSegmentation! \n",
+ "\n",
+ "In this tutorial, we demo\n",
+ "* How to do inference with MMSeg trained weight\n",
+ "* How to train on your own dataset and visualize the results. "
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "id": "QS8YHrEhbpas"
+ },
+ "source": [
+ "## Install MMSegmentation\n",
+ "This step may take several minutes. \n",
+ "\n",
+ "We use PyTorch 1.10 and CUDA 11.1 for this tutorial. You may install other versions by change the version number in pip install command. "
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {
+ "base_uri": "https://localhost:8080/"
+ },
+ "id": "UWyLrLYaNEaL",
+ "outputId": "32a47fe3-f10d-47a1-f6b9-b7c235abdab1"
+ },
+ "outputs": [],
+ "source": [
+ "# Check nvcc version\n",
+ "!nvcc -V\n",
+ "# Check GCC version\n",
+ "!gcc --version"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {
+ "base_uri": "https://localhost:8080/"
+ },
+ "id": "Ki3WUBjKbutg",
+ "outputId": "14bd14b0-4d8c-4fa9-e3f9-da35c0efc0d5"
+ },
+ "outputs": [],
+ "source": [
+ "# Install PyTorch\n",
+ "!conda install pytorch=1.10.0 torchvision cudatoolkit=11.1 -c pytorch\n",
+ "# Install MMCV\n",
+ "!pip install mmcv-full -f https://download.openmmlab.com/mmcv/dist/cu111/torch1.10/index.html"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {
+ "base_uri": "https://localhost:8080/"
+ },
+ "id": "nR-hHRvbNJJZ",
+ "outputId": "10c3b131-d4db-458c-fc10-b94b1c6ed546"
+ },
+ "outputs": [],
+ "source": [
+ "!rm -rf mmsegmentation\n",
+ "!git clone https://github.com/open-mmlab/mmsegmentation.git \n",
+ "%cd mmsegmentation\n",
+ "!pip install -e ."
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {
+ "base_uri": "https://localhost:8080/"
+ },
+ "id": "mAE_h7XhPT7d",
+ "outputId": "83bf0f8e-fc69-40b1-f9fe-0025724a217c"
+ },
+ "outputs": [],
+ "source": [
+ "# Check Pytorch installation\n",
+ "import torch, torchvision\n",
+ "print(torch.__version__, torch.cuda.is_available())\n",
+ "\n",
+ "# Check MMSegmentation installation\n",
+ "import mmseg\n",
+ "print(mmseg.__version__)"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "id": "eUcuC3dUv32I"
+ },
+ "source": [
+ "## Run Inference with MMSeg trained weight"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {
+ "base_uri": "https://localhost:8080/"
+ },
+ "id": "2hd41IGaiNet",
+ "outputId": "b7b2aafc-edf2-43e4-ea43-0b5dd0aa4b4a"
+ },
+ "outputs": [],
+ "source": [
+ "!mkdir checkpoints\n",
+ "!wget https://download.openmmlab.com/mmsegmentation/v0.5/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth -P checkpoints"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "id": "H8Fxg8i-wHJE"
+ },
+ "outputs": [],
+ "source": [
+ "from mmseg.apis import inference_segmentor, init_segmentor, show_result_pyplot\n",
+ "from mmseg.core.evaluation import get_palette"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "id": "umk8sJ0Xuace"
+ },
+ "outputs": [],
+ "source": [
+ "config_file = 'configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py'\n",
+ "checkpoint_file = 'checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth'"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {
+ "base_uri": "https://localhost:8080/"
+ },
+ "id": "nWlQFuTgudxu",
+ "outputId": "5e45f4f6-5bcf-4d04-bb9c-0428ee84a576"
+ },
+ "outputs": [],
+ "source": [
+ "# build the model from a config file and a checkpoint file\n",
+ "model = init_segmentor(config_file, checkpoint_file, device='cuda:0')"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "id": "izFv6pSRujk9"
+ },
+ "outputs": [],
+ "source": [
+ "# test a single image\n",
+ "img = 'demo/demo.png'\n",
+ "result = inference_segmentor(model, img)"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {
+ "base_uri": "https://localhost:8080/",
+ "height": 504
+ },
+ "id": "bDcs9udgunQK",
+ "outputId": "7c55f713-4085-47fd-fa06-720a321d0795"
+ },
+ "outputs": [],
+ "source": [
+ "# show the results\n",
+ "show_result_pyplot(model, img, result, get_palette('cityscapes'))"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "id": "Ta51clKX4cwM"
+ },
+ "source": [
+ "## Train a semantic segmentation model on a new dataset\n",
+ "\n",
+ "To train on a customized dataset, the following steps are necessary. \n",
+ "1. Add a new dataset class. \n",
+ "2. Create a config file accordingly. \n",
+ "3. Perform training and evaluation. "
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "id": "AcZg6x_K5Zs3"
+ },
+ "source": [
+ "### Add a new dataset\n",
+ "\n",
+ "Datasets in MMSegmentation require image and semantic segmentation maps to be placed in folders with the same prefix. To support a new dataset, we may need to modify the original file structure. \n",
+ "\n",
+ "In this tutorial, we give an example of converting the dataset. You may refer to [docs](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/tutorials/customize_datasets.md#customize-datasets-by-reorganizing-data) for details about dataset reorganization. \n",
+ "\n",
+ "We use [Stanford Background Dataset](http://dags.stanford.edu/projects/scenedataset.html) as an example. The dataset contains 715 images chosen from existing public datasets [LabelMe](http://labelme.csail.mit.edu), [MSRC](http://research.microsoft.com/en-us/projects/objectclassrecognition), [PASCAL VOC](http://pascallin.ecs.soton.ac.uk/challenges/VOC) and [Geometric Context](http://www.cs.illinois.edu/homes/dhoiem/). Images from these datasets are mainly outdoor scenes, each containing approximately 320-by-240 pixels. \n",
+ "In this tutorial, we use the region annotations as labels. There are 8 classes in total, i.e. sky, tree, road, grass, water, building, mountain, and foreground object. "
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {
+ "base_uri": "https://localhost:8080/"
+ },
+ "id": "TFIt7MHq5Wls",
+ "outputId": "74a126e4-c8a4-4d2f-a910-b58b71843a23"
+ },
+ "outputs": [],
+ "source": [
+ "# download and unzip\n",
+ "!wget http://dags.stanford.edu/data/iccv09Data.tar.gz -O stanford_background.tar.gz\n",
+ "!tar xf stanford_background.tar.gz"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {
+ "base_uri": "https://localhost:8080/",
+ "height": 377
+ },
+ "id": "78LIci7F9WWI",
+ "outputId": "c432ddac-5a50-47b1-daac-5a26b07afea2"
+ },
+ "outputs": [],
+ "source": [
+ "# Let's take a look at the dataset\n",
+ "import mmcv\n",
+ "import matplotlib.pyplot as plt\n",
+ "\n",
+ "img = mmcv.imread('iccv09Data/images/6000124.jpg')\n",
+ "plt.figure(figsize=(8, 6))\n",
+ "plt.imshow(mmcv.bgr2rgb(img))\n",
+ "plt.show()"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "id": "L5mNQuc2GsVE"
+ },
+ "source": [
+ "We need to convert the annotation into semantic map format as an image."
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "id": "WnGZfribFHCx"
+ },
+ "outputs": [],
+ "source": [
+ "import os.path as osp\n",
+ "import numpy as np\n",
+ "from PIL import Image\n",
+ "# convert dataset annotation to semantic segmentation map\n",
+ "data_root = 'iccv09Data'\n",
+ "img_dir = 'images'\n",
+ "ann_dir = 'labels'\n",
+ "# define class and plaette for better visualization\n",
+ "classes = ('sky', 'tree', 'road', 'grass', 'water', 'bldg', 'mntn', 'fg obj')\n",
+ "palette = [[128, 128, 128], [129, 127, 38], [120, 69, 125], [53, 125, 34], \n",
+ " [0, 11, 123], [118, 20, 12], [122, 81, 25], [241, 134, 51]]\n",
+ "for file in mmcv.scandir(osp.join(data_root, ann_dir), suffix='.regions.txt'):\n",
+ " seg_map = np.loadtxt(osp.join(data_root, ann_dir, file)).astype(np.uint8)\n",
+ " seg_img = Image.fromarray(seg_map).convert('P')\n",
+ " seg_img.putpalette(np.array(palette, dtype=np.uint8))\n",
+ " seg_img.save(osp.join(data_root, ann_dir, file.replace('.regions.txt', \n",
+ " '.png')))"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {
+ "base_uri": "https://localhost:8080/",
+ "height": 377
+ },
+ "id": "5MCSS9ABfSks",
+ "outputId": "92b9bafc-589e-48fc-c9e9-476f125d6522"
+ },
+ "outputs": [],
+ "source": [
+ "# Let's take a look at the segmentation map we got\n",
+ "import matplotlib.patches as mpatches\n",
+ "img = Image.open('iccv09Data/labels/6000124.png')\n",
+ "plt.figure(figsize=(8, 6))\n",
+ "im = plt.imshow(np.array(img.convert('RGB')))\n",
+ "\n",
+ "# create a patch (proxy artist) for every color \n",
+ "patches = [mpatches.Patch(color=np.array(palette[i])/255., \n",
+ " label=classes[i]) for i in range(8)]\n",
+ "# put those patched as legend-handles into the legend\n",
+ "plt.legend(handles=patches, bbox_to_anchor=(1.05, 1), loc=2, borderaxespad=0., \n",
+ " fontsize='large')\n",
+ "\n",
+ "plt.show()"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "id": "WbeLYCp2k5hl"
+ },
+ "outputs": [],
+ "source": [
+ "# split train/val set randomly\n",
+ "split_dir = 'splits'\n",
+ "mmcv.mkdir_or_exist(osp.join(data_root, split_dir))\n",
+ "filename_list = [osp.splitext(filename)[0] for filename in mmcv.scandir(\n",
+ " osp.join(data_root, ann_dir), suffix='.png')]\n",
+ "with open(osp.join(data_root, split_dir, 'train.txt'), 'w') as f:\n",
+ " # select first 4/5 as train set\n",
+ " train_length = int(len(filename_list)*4/5)\n",
+ " f.writelines(line + '\\n' for line in filename_list[:train_length])\n",
+ "with open(osp.join(data_root, split_dir, 'val.txt'), 'w') as f:\n",
+ " # select last 1/5 as train set\n",
+ " f.writelines(line + '\\n' for line in filename_list[train_length:])"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "id": "HchvmGYB_rrO"
+ },
+ "source": [
+ "After downloading the data, we need to implement `load_annotations` function in the new dataset class `StanfordBackgroundDataset`."
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "id": "LbsWOw62_o-X"
+ },
+ "outputs": [],
+ "source": [
+ "from mmseg.datasets.builder import DATASETS\n",
+ "from mmseg.datasets.custom import CustomDataset\n",
+ "\n",
+ "@DATASETS.register_module()\n",
+ "class StanfordBackgroundDataset(CustomDataset):\n",
+ " CLASSES = classes\n",
+ " PALETTE = palette\n",
+ " def __init__(self, split, **kwargs):\n",
+ " super().__init__(img_suffix='.jpg', seg_map_suffix='.png', \n",
+ " split=split, **kwargs)\n",
+ " assert osp.exists(self.img_dir) and self.split is not None\n",
+ "\n",
+ " "
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "id": "yUVtmn3Iq3WA"
+ },
+ "source": [
+ "### Create a config file\n",
+ "In the next step, we need to modify the config for the training. To accelerate the process, we finetune the model from trained weights."
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "id": "Wwnj9tRzqX_A"
+ },
+ "outputs": [],
+ "source": [
+ "from mmcv import Config\n",
+ "cfg = Config.fromfile('configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py')"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "id": "1y2oV5w97jQo"
+ },
+ "source": [
+ "Since the given config is used to train PSPNet on the cityscapes dataset, we need to modify it accordingly for our new dataset. "
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {
+ "base_uri": "https://localhost:8080/"
+ },
+ "id": "eyKnYC1Z7iCV",
+ "outputId": "6195217b-187f-4675-994b-ba90d8bb3078"
+ },
+ "outputs": [],
+ "source": [
+ "from mmseg.apis import set_random_seed\n",
+ "\n",
+ "# Since we use only one GPU, BN is used instead of SyncBN\n",
+ "cfg.norm_cfg = dict(type='BN', requires_grad=True)\n",
+ "cfg.model.backbone.norm_cfg = cfg.norm_cfg\n",
+ "cfg.model.decode_head.norm_cfg = cfg.norm_cfg\n",
+ "cfg.model.auxiliary_head.norm_cfg = cfg.norm_cfg\n",
+ "# modify num classes of the model in decode/auxiliary head\n",
+ "cfg.model.decode_head.num_classes = 8\n",
+ "cfg.model.auxiliary_head.num_classes = 8\n",
+ "\n",
+ "# Modify dataset type and path\n",
+ "cfg.dataset_type = 'StanfordBackgroundDataset'\n",
+ "cfg.data_root = data_root\n",
+ "\n",
+ "cfg.data.samples_per_gpu = 8\n",
+ "cfg.data.workers_per_gpu=8\n",
+ "\n",
+ "cfg.img_norm_cfg = dict(\n",
+ " mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)\n",
+ "cfg.crop_size = (256, 256)\n",
+ "cfg.train_pipeline = [\n",
+ " dict(type='LoadImageFromFile'),\n",
+ " dict(type='LoadAnnotations'),\n",
+ " dict(type='Resize', img_scale=(320, 240), ratio_range=(0.5, 2.0)),\n",
+ " dict(type='RandomCrop', crop_size=cfg.crop_size, cat_max_ratio=0.75),\n",
+ " dict(type='RandomFlip', flip_ratio=0.5),\n",
+ " dict(type='PhotoMetricDistortion'),\n",
+ " dict(type='Normalize', **cfg.img_norm_cfg),\n",
+ " dict(type='Pad', size=cfg.crop_size, pad_val=0, seg_pad_val=255),\n",
+ " dict(type='DefaultFormatBundle'),\n",
+ " dict(type='Collect', keys=['img', 'gt_semantic_seg']),\n",
+ "]\n",
+ "\n",
+ "cfg.test_pipeline = [\n",
+ " dict(type='LoadImageFromFile'),\n",
+ " dict(\n",
+ " type='MultiScaleFlipAug',\n",
+ " img_scale=(320, 240),\n",
+ " # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],\n",
+ " flip=False,\n",
+ " transforms=[\n",
+ " dict(type='Resize', keep_ratio=True),\n",
+ " dict(type='RandomFlip'),\n",
+ " dict(type='Normalize', **cfg.img_norm_cfg),\n",
+ " dict(type='ImageToTensor', keys=['img']),\n",
+ " dict(type='Collect', keys=['img']),\n",
+ " ])\n",
+ "]\n",
+ "\n",
+ "\n",
+ "cfg.data.train.type = cfg.dataset_type\n",
+ "cfg.data.train.data_root = cfg.data_root\n",
+ "cfg.data.train.img_dir = img_dir\n",
+ "cfg.data.train.ann_dir = ann_dir\n",
+ "cfg.data.train.pipeline = cfg.train_pipeline\n",
+ "cfg.data.train.split = 'splits/train.txt'\n",
+ "\n",
+ "cfg.data.val.type = cfg.dataset_type\n",
+ "cfg.data.val.data_root = cfg.data_root\n",
+ "cfg.data.val.img_dir = img_dir\n",
+ "cfg.data.val.ann_dir = ann_dir\n",
+ "cfg.data.val.pipeline = cfg.test_pipeline\n",
+ "cfg.data.val.split = 'splits/val.txt'\n",
+ "\n",
+ "cfg.data.test.type = cfg.dataset_type\n",
+ "cfg.data.test.data_root = cfg.data_root\n",
+ "cfg.data.test.img_dir = img_dir\n",
+ "cfg.data.test.ann_dir = ann_dir\n",
+ "cfg.data.test.pipeline = cfg.test_pipeline\n",
+ "cfg.data.test.split = 'splits/val.txt'\n",
+ "\n",
+ "# We can still use the pre-trained Mask RCNN model though we do not need to\n",
+ "# use the mask branch\n",
+ "cfg.load_from = 'checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth'\n",
+ "\n",
+ "# Set up working dir to save files and logs.\n",
+ "cfg.work_dir = './work_dirs/tutorial'\n",
+ "\n",
+ "cfg.runner.max_iters = 200\n",
+ "cfg.log_config.interval = 10\n",
+ "cfg.evaluation.interval = 200\n",
+ "cfg.checkpoint_config.interval = 200\n",
+ "\n",
+ "# Set seed to facitate reproducing the result\n",
+ "cfg.seed = 0\n",
+ "set_random_seed(0, deterministic=False)\n",
+ "cfg.gpu_ids = range(1)\n",
+ "\n",
+ "# Let's have a look at the final config used for training\n",
+ "print(f'Config:\\n{cfg.pretty_text}')"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "id": "QWuH14LYF2gQ"
+ },
+ "source": [
+ "### Train and Evaluation"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {
+ "base_uri": "https://localhost:8080/"
+ },
+ "id": "jYKoSfdMF12B",
+ "outputId": "422219ca-d7a5-4890-f09f-88c959942e64"
+ },
+ "outputs": [],
+ "source": [
+ "from mmseg.datasets import build_dataset\n",
+ "from mmseg.models import build_segmentor\n",
+ "from mmseg.apis import train_segmentor\n",
+ "\n",
+ "\n",
+ "# Build the dataset\n",
+ "datasets = [build_dataset(cfg.data.train)]\n",
+ "\n",
+ "# Build the detector\n",
+ "model = build_segmentor(cfg.model)\n",
+ "# Add an attribute for visualization convenience\n",
+ "model.CLASSES = datasets[0].CLASSES\n",
+ "\n",
+ "# Create work_dir\n",
+ "mmcv.mkdir_or_exist(osp.abspath(cfg.work_dir))\n",
+ "train_segmentor(model, datasets, cfg, distributed=False, validate=True, \n",
+ " meta=dict())"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "id": "DEkWOP-NMbc_"
+ },
+ "source": [
+ "Inference with trained model"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {
+ "base_uri": "https://localhost:8080/",
+ "height": 645
+ },
+ "id": "ekG__UfaH_OU",
+ "outputId": "1437419c-869a-4902-df86-d4f6f8b2597a"
+ },
+ "outputs": [],
+ "source": [
+ "img = mmcv.imread('iccv09Data/images/6000124.jpg')\n",
+ "\n",
+ "model.cfg = cfg\n",
+ "result = inference_segmentor(model, img)\n",
+ "plt.figure(figsize=(8, 6))\n",
+ "show_result_pyplot(model, img, result, palette)"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": []
+ }
+ ],
+ "metadata": {
+ "accelerator": "GPU",
+ "colab": {
+ "collapsed_sections": [],
+ "include_colab_link": true,
+ "name": "MMSegmentation Tutorial.ipynb",
+ "provenance": []
+ },
+ "kernelspec": {
+ "display_name": "Python 3",
+ "language": "python",
+ "name": "python3"
+ },
+ "language_info": {
+ "codemirror_mode": {
+ "name": "ipython",
+ "version": 3
+ },
+ "file_extension": ".py",
+ "mimetype": "text/x-python",
+ "name": "python",
+ "nbconvert_exporter": "python",
+ "pygments_lexer": "ipython3",
+ "version": "3.7.0"
+ },
+ "pycharm": {
+ "stem_cell": {
+ "cell_type": "raw",
+ "metadata": {
+ "collapsed": false
+ },
+ "source": []
+ }
+ }
+ },
+ "nbformat": 4,
+ "nbformat_minor": 2
+}
diff --git a/EgoHOS/raw/script/mmsegmentation/demo/image_demo.py b/EgoHOS/raw/script/mmsegmentation/demo/image_demo.py
new file mode 100644
index 0000000000000000000000000000000000000000..05e1a791303d85747483bc3a9deb75b99819439e
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/demo/image_demo.py
@@ -0,0 +1,40 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from argparse import ArgumentParser
+
+from mmseg.apis import inference_segmentor, init_segmentor, show_result_pyplot
+from mmseg.core.evaluation import get_palette
+
+
+def main():
+ parser = ArgumentParser()
+ parser.add_argument('img', help='Image file')
+ parser.add_argument('config', help='Config file')
+ parser.add_argument('checkpoint', help='Checkpoint file')
+ parser.add_argument(
+ '--device', default='cuda:0', help='Device used for inference')
+ parser.add_argument(
+ '--palette',
+ default='cityscapes',
+ help='Color palette used for segmentation map')
+ parser.add_argument(
+ '--opacity',
+ type=float,
+ default=0.5,
+ help='Opacity of painted segmentation map. In (0, 1] range.')
+ args = parser.parse_args()
+
+ # build the model from a config file and a checkpoint file
+ model = init_segmentor(args.config, args.checkpoint, device=args.device)
+ # test a single image
+ result = inference_segmentor(model, args.img)
+ # show the results
+ show_result_pyplot(
+ model,
+ args.img,
+ result,
+ get_palette(args.palette),
+ opacity=args.opacity)
+
+
+if __name__ == '__main__':
+ main()
diff --git a/EgoHOS/raw/script/mmsegmentation/demo/inference_demo.ipynb b/EgoHOS/raw/script/mmsegmentation/demo/inference_demo.ipynb
new file mode 100644
index 0000000000000000000000000000000000000000..66a447b766bc725b1b841139835da4f9007c2e00
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/demo/inference_demo.ipynb
@@ -0,0 +1,110 @@
+{
+ "cells": [
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "!mkdir ../checkpoints\n",
+ "!wget https://download.openmmlab.com/mmsegmentation/v0.5/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth -P ../checkpoints"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "pycharm": {
+ "is_executing": true
+ }
+ },
+ "outputs": [],
+ "source": [
+ "from mmseg.apis import init_segmentor, inference_segmentor, show_result_pyplot\n",
+ "from mmseg.core.evaluation import get_palette"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "pycharm": {
+ "is_executing": true
+ }
+ },
+ "outputs": [],
+ "source": [
+ "config_file = '../configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py'\n",
+ "checkpoint_file = '../checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth'"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "# build the model from a config file and a checkpoint file\n",
+ "model = init_segmentor(config_file, checkpoint_file, device='cuda:0')"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "# test a single image\n",
+ "img = 'demo.png'\n",
+ "result = inference_segmentor(model, img)"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "# show the results\n",
+ "show_result_pyplot(model, img, result, get_palette('cityscapes'))"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": []
+ }
+ ],
+ "metadata": {
+ "kernelspec": {
+ "display_name": "Python 3",
+ "language": "python",
+ "name": "python3"
+ },
+ "language_info": {
+ "codemirror_mode": {
+ "name": "ipython",
+ "version": 3
+ },
+ "file_extension": ".py",
+ "mimetype": "text/x-python",
+ "name": "python",
+ "nbconvert_exporter": "python",
+ "pygments_lexer": "ipython3",
+ "version": "3.7.0"
+ },
+ "pycharm": {
+ "stem_cell": {
+ "cell_type": "raw",
+ "metadata": {
+ "collapsed": false
+ },
+ "source": []
+ }
+ }
+ },
+ "nbformat": 4,
+ "nbformat_minor": 4
+}
diff --git a/EgoHOS/raw/script/mmsegmentation/demo/video_demo.py b/EgoHOS/raw/script/mmsegmentation/demo/video_demo.py
new file mode 100644
index 0000000000000000000000000000000000000000..eb4fd69943fd0a0e304dd7e779484c20508315a6
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/demo/video_demo.py
@@ -0,0 +1,112 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from argparse import ArgumentParser
+
+import cv2
+
+from mmseg.apis import inference_segmentor, init_segmentor
+from mmseg.core.evaluation import get_palette
+
+
+def main():
+ parser = ArgumentParser()
+ parser.add_argument('video', help='Video file or webcam id')
+ parser.add_argument('config', help='Config file')
+ parser.add_argument('checkpoint', help='Checkpoint file')
+ parser.add_argument(
+ '--device', default='cuda:0', help='Device used for inference')
+ parser.add_argument(
+ '--palette',
+ default='cityscapes',
+ help='Color palette used for segmentation map')
+ parser.add_argument(
+ '--show', action='store_true', help='Whether to show draw result')
+ parser.add_argument(
+ '--show-wait-time', default=1, type=int, help='Wait time after imshow')
+ parser.add_argument(
+ '--output-file', default=None, type=str, help='Output video file path')
+ parser.add_argument(
+ '--output-fourcc',
+ default='MJPG',
+ type=str,
+ help='Fourcc of the output video')
+ parser.add_argument(
+ '--output-fps', default=-1, type=int, help='FPS of the output video')
+ parser.add_argument(
+ '--output-height',
+ default=-1,
+ type=int,
+ help='Frame height of the output video')
+ parser.add_argument(
+ '--output-width',
+ default=-1,
+ type=int,
+ help='Frame width of the output video')
+ parser.add_argument(
+ '--opacity',
+ type=float,
+ default=0.5,
+ help='Opacity of painted segmentation map. In (0, 1] range.')
+ args = parser.parse_args()
+
+ assert args.show or args.output_file, \
+ 'At least one output should be enabled.'
+
+ # build the model from a config file and a checkpoint file
+ model = init_segmentor(args.config, args.checkpoint, device=args.device)
+
+ # build input video
+ cap = cv2.VideoCapture(args.video)
+ assert (cap.isOpened())
+ input_height = cap.get(cv2.CAP_PROP_FRAME_HEIGHT)
+ input_width = cap.get(cv2.CAP_PROP_FRAME_WIDTH)
+ input_fps = cap.get(cv2.CAP_PROP_FPS)
+
+ # init output video
+ writer = None
+ output_height = None
+ output_width = None
+ if args.output_file is not None:
+ fourcc = cv2.VideoWriter_fourcc(*args.output_fourcc)
+ output_fps = args.output_fps if args.output_fps > 0 else input_fps
+ output_height = args.output_height if args.output_height > 0 else int(
+ input_height)
+ output_width = args.output_width if args.output_width > 0 else int(
+ input_width)
+ writer = cv2.VideoWriter(args.output_file, fourcc, output_fps,
+ (output_width, output_height), True)
+
+ # start looping
+ try:
+ while True:
+ flag, frame = cap.read()
+ if not flag:
+ break
+
+ # test a single image
+ result = inference_segmentor(model, frame)
+
+ # blend raw image and prediction
+ draw_img = model.show_result(
+ frame,
+ result,
+ palette=get_palette(args.palette),
+ show=False,
+ opacity=args.opacity)
+
+ if args.show:
+ cv2.imshow('video_demo', draw_img)
+ cv2.waitKey(args.show_wait_time)
+ if writer:
+ if draw_img.shape[0] != output_height or draw_img.shape[
+ 1] != output_width:
+ draw_img = cv2.resize(draw_img,
+ (output_width, output_height))
+ writer.write(draw_img)
+ finally:
+ if writer:
+ writer.release()
+ cap.release()
+
+
+if __name__ == '__main__':
+ main()
diff --git a/EgoHOS/raw/script/mmsegmentation/docker/Dockerfile b/EgoHOS/raw/script/mmsegmentation/docker/Dockerfile
new file mode 100644
index 0000000000000000000000000000000000000000..64482b4725ed2c7a21cc280efb4f0f6559c82aed
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docker/Dockerfile
@@ -0,0 +1,32 @@
+ARG PYTORCH="1.11.0"
+ARG CUDA="11.3"
+ARG CUDNN="8"
+
+FROM pytorch/pytorch:${PYTORCH}-cuda${CUDA}-cudnn${CUDNN}-devel
+
+ENV TORCH_CUDA_ARCH_LIST="6.0 6.1 7.0+PTX"
+ENV TORCH_NVCC_FLAGS="-Xfatbin -compress-all"
+ENV CMAKE_PREFIX_PATH="$(dirname $(which conda))/../"
+
+# To fix GPG key error when running apt-get update
+RUN apt-key adv --fetch-keys https://developer.download.nvidia.com/compute/cuda/repos/ubuntu1804/x86_64/3bf863cc.pub
+RUN apt-key adv --fetch-keys https://developer.download.nvidia.com/compute/machine-learning/repos/ubuntu1804/x86_64/7fa2af80.pub
+
+RUN apt-get update && apt-get install -y git ninja-build libglib2.0-0 libsm6 libxrender-dev libxext6 \
+ && apt-get clean \
+ && rm -rf /var/lib/apt/lists/*
+
+RUN conda clean --all
+
+# Install MMCV
+ARG PYTORCH
+ARG CUDA
+ARG MMCV
+RUN ["/bin/bash", "-c", "pip install --no-cache-dir mmcv-full -f https://download.openmmlab.com/mmcv/dist/cu${CUDA//./}/torch${PYTORCH}/index.html"]
+
+# Install MMSegmentation
+RUN git clone https://github.com/open-mmlab/mmsegmentation.git /mmsegmentation
+WORKDIR /mmsegmentation
+ENV FORCE_CUDA="1"
+RUN pip install -r requirements.txt
+RUN pip install --no-cache-dir -e .
diff --git a/EgoHOS/raw/script/mmsegmentation/docker/serve/Dockerfile b/EgoHOS/raw/script/mmsegmentation/docker/serve/Dockerfile
new file mode 100644
index 0000000000000000000000000000000000000000..c1d154528ce7dc86d628012c765063edd93b7865
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docker/serve/Dockerfile
@@ -0,0 +1,49 @@
+ARG PYTORCH="1.11.0"
+ARG CUDA="11.3"
+ARG CUDNN="8"
+FROM pytorch/pytorch:${PYTORCH}-cuda${CUDA}-cudnn${CUDNN}-devel
+
+ARG MMCV="1.4.8"
+ARG MMSEG="0.24.1"
+
+ENV PYTHONUNBUFFERED TRUE
+
+RUN apt-get update && \
+ DEBIAN_FRONTEND=noninteractive apt-get install --no-install-recommends -y \
+ ca-certificates \
+ g++ \
+ openjdk-11-jre-headless \
+ # MMDet Requirements
+ ffmpeg libsm6 libxext6 git ninja-build libglib2.0-0 libsm6 libxrender-dev libxext6 \
+ && rm -rf /var/lib/apt/lists/*
+
+ENV PATH="/opt/conda/bin:$PATH"
+RUN export FORCE_CUDA=1
+
+# TORCHSEVER
+RUN pip install torchserve torch-model-archiver
+
+# MMLAB
+ARG PYTORCH
+ARG CUDA
+RUN ["/bin/bash", "-c", "pip install mmcv-full==${MMCV} -f https://download.openmmlab.com/mmcv/dist/cu${CUDA//./}/torch${PYTORCH}/index.html"]
+RUN pip install mmsegmentation==${MMSEG}
+
+RUN useradd -m model-server \
+ && mkdir -p /home/model-server/tmp
+
+COPY entrypoint.sh /usr/local/bin/entrypoint.sh
+
+RUN chmod +x /usr/local/bin/entrypoint.sh \
+ && chown -R model-server /home/model-server
+
+COPY config.properties /home/model-server/config.properties
+RUN mkdir /home/model-server/model-store && chown -R model-server /home/model-server/model-store
+
+EXPOSE 8080 8081 8082
+
+USER model-server
+WORKDIR /home/model-server
+ENV TEMP=/home/model-server/tmp
+ENTRYPOINT ["/usr/local/bin/entrypoint.sh"]
+CMD ["serve"]
diff --git a/EgoHOS/raw/script/mmsegmentation/docker/serve/config.properties b/EgoHOS/raw/script/mmsegmentation/docker/serve/config.properties
new file mode 100644
index 0000000000000000000000000000000000000000..efb9c47e40ab550bac765611e6c6c6f2a7152f11
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docker/serve/config.properties
@@ -0,0 +1,5 @@
+inference_address=http://0.0.0.0:8080
+management_address=http://0.0.0.0:8081
+metrics_address=http://0.0.0.0:8082
+model_store=/home/model-server/model-store
+load_models=all
diff --git a/EgoHOS/raw/script/mmsegmentation/docker/serve/entrypoint.sh b/EgoHOS/raw/script/mmsegmentation/docker/serve/entrypoint.sh
new file mode 100644
index 0000000000000000000000000000000000000000..41ba00b048aed84b45c5a8015a016ff148e97d86
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docker/serve/entrypoint.sh
@@ -0,0 +1,12 @@
+#!/bin/bash
+set -e
+
+if [[ "$1" = "serve" ]]; then
+ shift 1
+ torchserve --start --ts-config /home/model-server/config.properties
+else
+ eval "$@"
+fi
+
+# prevent docker exit
+tail -f /dev/null
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/Makefile b/EgoHOS/raw/script/mmsegmentation/docs/en/Makefile
new file mode 100644
index 0000000000000000000000000000000000000000..d4bb2cbb9eddb1bb1b4f366623044af8e4830919
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/Makefile
@@ -0,0 +1,20 @@
+# Minimal makefile for Sphinx documentation
+#
+
+# You can set these variables from the command line, and also
+# from the environment for the first two.
+SPHINXOPTS ?=
+SPHINXBUILD ?= sphinx-build
+SOURCEDIR = .
+BUILDDIR = _build
+
+# Put it first so that "make" without argument is like "make help".
+help:
+ @$(SPHINXBUILD) -M help "$(SOURCEDIR)" "$(BUILDDIR)" $(SPHINXOPTS) $(O)
+
+.PHONY: help Makefile
+
+# Catch-all target: route all unknown targets to Sphinx using the new
+# "make mode" option. $(O) is meant as a shortcut for $(SPHINXOPTS).
+%: Makefile
+ @$(SPHINXBUILD) -M $@ "$(SOURCEDIR)" "$(BUILDDIR)" $(SPHINXOPTS) $(O)
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/_static/css/readthedocs.css b/EgoHOS/raw/script/mmsegmentation/docs/en/_static/css/readthedocs.css
new file mode 100644
index 0000000000000000000000000000000000000000..2e38d0880b4dd3ffbffb38272173a30a42cf538a
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/_static/css/readthedocs.css
@@ -0,0 +1,6 @@
+.header-logo {
+ background-image: url("../images/mmsegmentation.png");
+ background-size: 201px 40px;
+ height: 40px;
+ width: 201px;
+}
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/api.rst b/EgoHOS/raw/script/mmsegmentation/docs/en/api.rst
new file mode 100644
index 0000000000000000000000000000000000000000..8285841dc69d724f32d0816a8435566bfc5bd1fc
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/api.rst
@@ -0,0 +1,58 @@
+mmseg.apis
+--------------
+.. automodule:: mmseg.apis
+ :members:
+
+mmseg.core
+--------------
+
+seg
+^^^^^^^^^^
+.. automodule:: mmseg.core.seg
+ :members:
+
+evaluation
+^^^^^^^^^^
+.. automodule:: mmseg.core.evaluation
+ :members:
+
+utils
+^^^^^^^^^^
+.. automodule:: mmseg.core.utils
+ :members:
+
+mmseg.datasets
+--------------
+
+datasets
+^^^^^^^^^^
+.. automodule:: mmseg.datasets
+ :members:
+
+pipelines
+^^^^^^^^^^
+.. automodule:: mmseg.datasets.pipelines
+ :members:
+
+mmseg.models
+--------------
+
+segmentors
+^^^^^^^^^^
+.. automodule:: mmseg.models.segmentors
+ :members:
+
+backbones
+^^^^^^^^^^
+.. automodule:: mmseg.models.backbones
+ :members:
+
+decode_heads
+^^^^^^^^^^^^
+.. automodule:: mmseg.models.decode_heads
+ :members:
+
+losses
+^^^^^^^^^^
+.. automodule:: mmseg.models.losses
+ :members:
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/changelog.md b/EgoHOS/raw/script/mmsegmentation/docs/en/changelog.md
new file mode 100644
index 0000000000000000000000000000000000000000..a9c81020e6fd65f79d95984f3109da18d50aa654
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/changelog.md
@@ -0,0 +1,721 @@
+## Changelog
+
+### V0.24.1 (5/1/2022)
+
+**Bug Fixes**
+
+- Fix `LayerDecayOptimizerConstructor` for MAE training ([#1539](https://github.com/open-mmlab/mmsegmentation/pull/1539), [#1540](https://github.com/open-mmlab/mmsegmentation/pull/1540))
+
+### V0.24.0 (4/29/2022)
+
+**Highlights**
+
+- Support MAE: Masked Autoencoders Are Scalable Vision Learners
+- Support Resnet strikes back
+
+**New Features**
+
+- Support MAE: Masked Autoencoders Are Scalable Vision Learners ([1307](https://github.com/open-mmlab/mmsegmentation/pull/1307), [1523](https://github.com/open-mmlab/mmsegmentation/pull/1523))
+- Support Resnet strikes back ([1390](https://github.com/open-mmlab/mmsegmentation/pull/1390))
+- Support extra dataloader settings in configs ([1435](https://github.com/open-mmlab/mmsegmentation/pull/1435))
+
+**Bug Fixes**
+
+- Fix input previous results for the last cascade_decode_head ([#1450](https://github.com/open-mmlab/mmsegmentation/pull/1450))
+- Fix validation loss logging ([#1494](https://github.com/open-mmlab/mmsegmentation/pull/1494))
+- Fix the bug in binary_cross_entropy ([1527](https://github.com/open-mmlab/mmsegmentation/pull/1527))
+- Support single channel prediction for Binary Cross Entropy Loss ([#1454](https://github.com/open-mmlab/mmsegmentation/pull/1454))
+- Fix potential bugs in accuracy.py ([1496](https://github.com/open-mmlab/mmsegmentation/pull/1496))
+- Avoid converting label ids twice by label map during evaluation ([1417](https://github.com/open-mmlab/mmsegmentation/pull/1417))
+- Fix bug about label_map ([1445](https://github.com/open-mmlab/mmsegmentation/pull/1445))
+- Fix image save path bug in Windows ([1423](https://github.com/open-mmlab/mmsegmentation/pull/1423))
+- Fix MMSegmentation Colab demo ([1501](https://github.com/open-mmlab/mmsegmentation/pull/1501), [1452](https://github.com/open-mmlab/mmsegmentation/pull/1452))
+- Migrate azure blob for beit checkpoints ([1503](https://github.com/open-mmlab/mmsegmentation/pull/1503))
+- Fix bug in `tools/analyse_logs.py` caused by wrong plot_iter in some cases ([1428](https://github.com/open-mmlab/mmsegmentation/pull/1428))
+
+**Improvements**
+
+- Merge BEiT and ConvNext's LR decay optimizer constructors ([#1438](https://github.com/open-mmlab/mmsegmentation/pull/1438))
+- Register optimizer constructor with mmseg ([#1456](https://github.com/open-mmlab/mmsegmentation/pull/1456))
+- Refactor transformer encode layer in ViT and BEiT backbone ([#1481](https://github.com/open-mmlab/mmsegmentation/pull/1481))
+- Add `build_pos_embed` and `build_layers` for BEiT ([1517](https://github.com/open-mmlab/mmsegmentation/pull/1517))
+- Add `with_cp` to mit and vit ([1431](https://github.com/open-mmlab/mmsegmentation/pull/1431))
+- Fix inconsistent dtype of `seg_label` in stdc decode ([1463](https://github.com/open-mmlab/mmsegmentation/pull/1463))
+- Delete random seed for training in `dist_train.sh` ([1519](https://github.com/open-mmlab/mmsegmentation/pull/1519))
+- Revise high `workers_per_gpus` in config file ([#1506](https://github.com/open-mmlab/mmsegmentation/pull/1506))
+- Add GPG keys and del mmcv version in Dockerfile ([1534](https://github.com/open-mmlab/mmsegmentation/pull/1534))
+- Update checkpoint for model in deeplabv3plus ([#1487](https://github.com/open-mmlab/mmsegmentation/pull/1487))
+- Add `DistSamplerSeedHook` to set epoch number to dataloader when runner is `EpochBasedRunner` ([1449](https://github.com/open-mmlab/mmsegmentation/pull/1449))
+- Provide URLs of Swin Transformer pretrained models ([1389](https://github.com/open-mmlab/mmsegmentation/pull/1389))
+- Updating Dockerfiles From Docker Directory and `get_started.md` to reach latest stable version of Python, PyTorch and MMCV ([1446](https://github.com/open-mmlab/mmsegmentation/pull/1446))
+
+**Documentation**
+
+- Add more clearly statement of CPU training/inference ([1518](https://github.com/open-mmlab/mmsegmentation/pull/1518))
+
+**Contributors**
+
+* @jiangyitong made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1431
+* @kahkeng made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1447
+* @Nourollah made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1446
+* @androbaza made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1452
+* @Yzichen made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1445
+* @whu-pzhang made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1423
+* @panfeng-hover made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1417
+* @Johnson-Wang made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1496
+* @jere357 made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1460
+* @mfernezir made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1494
+* @donglixp made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1503
+* @YuanLiuuuuuu made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1307
+* @Dawn-bin made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1527
+
+### V0.23.0 (4/1/2022)
+
+**Highlights**
+
+- Support BEiT: BERT Pre-Training of Image Transformers
+- Support K-Net: Towards Unified Image Segmentation
+- Add `avg_non_ignore` of CELoss to support average loss over non-ignored elements
+- Support dataset initialization with file client
+
+**New Features**
+
+- Support BEiT: BERT Pre-Training of Image Transformers ([#1404](https://github.com/open-mmlab/mmsegmentation/pull/1404))
+- Support K-Net: Towards Unified Image Segmentation ([#1289](https://github.com/open-mmlab/mmsegmentation/pull/1289))
+- Support dataset initialization with file client ([#1402](https://github.com/open-mmlab/mmsegmentation/pull/1402))
+- Add class name function for STARE datasets ([#1376](https://github.com/open-mmlab/mmsegmentation/pull/1376))
+- Support different seeds on different ranks when distributed training ([#1362](https://github.com/open-mmlab/mmsegmentation/pull/1362))
+- Add `nlc2nchw2nlc` and `nchw2nlc2nchw` to simplify tensor with different dimension operation ([#1249](https://github.com/open-mmlab/mmsegmentation/pull/1249))
+
+**Improvements**
+
+- Synchronize random seed for distributed sampler ([#1411](https://github.com/open-mmlab/mmsegmentation/pull/1411))
+- Add script and documentation for multi-machine distributed training ([#1383](https://github.com/open-mmlab/mmsegmentation/pull/1383))
+
+**Bug Fixes**
+
+- Add `avg_non_ignore` of CELoss to support average loss over non-ignored elements ([#1409](https://github.com/open-mmlab/mmsegmentation/pull/1409))
+- Fix some wrong URLs of models or logs in `./configs` ([#1336](https://github.com/open-mmlab/mmsegmentation/pull/1433))
+- Add title and color theme arguments to plot function in `tools/confusion_matrix.py` ([#1401](https://github.com/open-mmlab/mmsegmentation/pull/1401))
+- Fix outdated link in Colab demo ([#1392](https://github.com/open-mmlab/mmsegmentation/pull/1392))
+- Fix typos ([#1424](https://github.com/open-mmlab/mmsegmentation/pull/1424), [#1405](https://github.com/open-mmlab/mmsegmentation/pull/1405), [#1371](https://github.com/open-mmlab/mmsegmentation/pull/1371), [#1366](https://github.com/open-mmlab/mmsegmentation/pull/1366), [#1363](https://github.com/open-mmlab/mmsegmentation/pull/1363))
+
+**Documentation**
+
+- Add FAQ document ([#1420](https://github.com/open-mmlab/mmsegmentation/pull/1420))
+- Fix the config name style description in official docs([#1414](https://github.com/open-mmlab/mmsegmentation/pull/1414))
+
+**Contributors**
+
+* @kinglintianxia made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1371
+* @CCODING04 made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1376
+* @mob5566 made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1401
+* @xiongnemo made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1392
+* @Xiangxu-0103 made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1405
+
+### V0.22.1 (3/9/2022)
+
+**Bug Fixes**
+
+- Fix the ZeroDivisionError that all pixels in one image is ignored. ([#1336](https://github.com/open-mmlab/mmsegmentation/pull/1336))
+
+**Improvements**
+
+- Provide URLs of STDC, Segmenter and Twins pretrained models ([#1272](https://github.com/open-mmlab/mmsegmentation/pull/1357))
+
+
+### V0.22 (3/04/2022)
+
+**Highlights**
+
+- Support ConvNeXt: A ConvNet for the 2020s. Please use the latest MMClassification (0.21.0) to try it out.
+- Support iSAID aerial Dataset.
+- Officially Support inference on Windows OS.
+
+**New Features**
+
+- Support ConvNeXt: A ConvNet for the 2020s. ([#1216](https://github.com/open-mmlab/mmsegmentation/pull/1216))
+- Support iSAID aerial Dataset. ([#1115](https://github.com/open-mmlab/mmsegmentation/pull/1115)
+- Generating and plotting confusion matrix. ([#1301](https://github.com/open-mmlab/mmsegmentation/pull/1301))
+
+**Improvements**
+
+- Refactor 4 decoder heads (ASPP, FCN, PSP, UPer): Split forward function into `_forward_feature` and `cls_seg`. ([#1299](https://github.com/open-mmlab/mmsegmentation/pull/1299))
+- Add `min_size` arg in `Resize` to keep the shape after resize bigger than slide window. ([#1318](https://github.com/open-mmlab/mmsegmentation/pull/1318))
+- Revise pre-commit-hooks. ([#1315](https://github.com/open-mmlab/mmsegmentation/pull/1315))
+- Add win-ci. ([#1296](https://github.com/open-mmlab/mmsegmentation/pull/1296))
+
+**Bug Fixes**
+
+- Fix `mlp_ratio` type in Swin Transformer. ([#1274](https://github.com/open-mmlab/mmsegmentation/pull/1274))
+- Fix path errors in `./demo` . ([#1269](https://github.com/open-mmlab/mmsegmentation/pull/1269))
+- Fix bug in conversion of potsdam. ([#1279](https://github.com/open-mmlab/mmsegmentation/pull/1279))
+- Make accuracy take into account `ignore_index`. ([#1259](https://github.com/open-mmlab/mmsegmentation/pull/1259))
+- Add Pytorch HardSwish assertion in unit test. ([#1294](https://github.com/open-mmlab/mmsegmentation/pull/1294))
+- Fix wrong palette value in vaihingen. ([#1292](https://github.com/open-mmlab/mmsegmentation/pull/1292))
+- Fix the bug that SETR cannot load pretrain. ([#1293](https://github.com/open-mmlab/mmsegmentation/pull/1293))
+- Update correct `In Collection` in metafile of each configs. ([#1239](https://github.com/open-mmlab/mmsegmentation/pull/1239))
+- Upload completed STDC models. ([#1332](https://github.com/open-mmlab/mmsegmentation/pull/1332))
+- Fix `DNLHead` exports onnx inference difference type Cast error. ([#1161](https://github.com/open-mmlab/mmsegmentation/pull/1332))
+
+**Contributors**
+
+- @JiaYanhao made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1269
+- @andife made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1281
+- @SBCV made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1279
+- @HJoonKwon made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1259
+- @Tsingularity made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1290
+- @Waterman0524 made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1115
+- @MeowZheng made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1315
+- @linfangjian01 made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1318
+
+### V0.21.1 (2/9/2022)
+
+**Bug Fixes**
+
+- Fix typos in docs. ([#1263](https://github.com/open-mmlab/mmsegmentation/pull/1263))
+- Fix repeating log by `setup_multi_processes`. ([#1267](https://github.com/open-mmlab/mmsegmentation/pull/1267))
+- Upgrade isort in pre-commit hook. ([#1270](https://github.com/open-mmlab/mmsegmentation/pull/1270))
+
+**Improvements**
+
+- Use MMCV load_state_dict func in ViT/Swin. ([#1272](https://github.com/open-mmlab/mmsegmentation/pull/1272))
+- Add exception for PointRend for support CPU-only. ([#1271](https://github.com/open-mmlab/mmsegmentation/pull/1270))
+
+### V0.21 (1/29/2022)
+
+**Highlights**
+
+- Officially Support CPUs training and inference, please use the latest MMCV (1.4.4) to try it out.
+- Support Segmenter: Transformer for Semantic Segmentation (ICCV'2021).
+- Support ISPRS Potsdam and Vaihingen Dataset.
+- Add Mosaic transform and `MultiImageMixDataset` class in `dataset_wrappers`.
+
+**New Features**
+
+- Support Segmenter: Transformer for Semantic Segmentation (ICCV'2021) ([#955](https://github.com/open-mmlab/mmsegmentation/pull/955))
+- Support ISPRS Potsdam and Vaihingen Dataset ([#1097](https://github.com/open-mmlab/mmsegmentation/pull/1097), [#1171](https://github.com/open-mmlab/mmsegmentation/pull/1171))
+- Add segformer‘s benchmark on cityscapes ([#1155](https://github.com/open-mmlab/mmsegmentation/pull/1155))
+- Add auto resume ([#1172](https://github.com/open-mmlab/mmsegmentation/pull/1172))
+- Add Mosaic transform and `MultiImageMixDataset` class in `dataset_wrappers` ([#1093](https://github.com/open-mmlab/mmsegmentation/pull/1093), [#1105](https://github.com/open-mmlab/mmsegmentation/pull/1105))
+- Add log collector ([#1175](https://github.com/open-mmlab/mmsegmentation/pull/1175))
+
+**Improvements**
+
+- New-style CPU training and inference ([#1251](https://github.com/open-mmlab/mmsegmentation/pull/1251))
+- Add UNet benchmark with multiple losses supervision ([#1143](https://github.com/open-mmlab/mmsegmentation/pull/1143))
+
+**Bug Fixes**
+
+- Fix the model statistics in doc for readthedoc ([#1153](https://github.com/open-mmlab/mmsegmentation/pull/1153))
+- Set random seed for `palette` if not given ([#1152](https://github.com/open-mmlab/mmsegmentation/pull/1152))
+- Add `COCOStuffDataset` in `class_names.py` ([#1222](https://github.com/open-mmlab/mmsegmentation/pull/1222))
+- Fix bug in non-distributed multi-gpu training/testing ([#1247](https://github.com/open-mmlab/mmsegmentation/pull/1247))
+- Delete unnecessary lines of STDCHead ([#1231](https://github.com/open-mmlab/mmsegmentation/pull/1231))
+
+**Contributors**
+
+- @jbwang1997 made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1152
+- @BeaverCC made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1206
+- @Echo-minn made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1214
+- @rstrudel made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/955
+
+### V0.20.2 (12/15/2021)
+
+**Bug Fixes**
+
+- Revise --option to --options to avoid BC-breaking. ([#1140](https://github.com/open-mmlab/mmsegmentation/pull/1140))
+
+### V0.20.1 (12/14/2021)
+
+**Improvements**
+
+- Change options to cfg-options ([#1129](https://github.com/open-mmlab/mmsegmentation/pull/1129))
+
+**Bug Fixes**
+
+- Fix `` in metafile. ([#1127](https://github.com/open-mmlab/mmsegmentation/pull/1127))
+- Fix correct `num_classes` of HRNet in `LoveDA` dataset ([#1136](https://github.com/open-mmlab/mmsegmentation/pull/1136))
+
+### V0.20 (12/10/2021)
+
+**Highlights**
+
+- Support Twins ([#989](https://github.com/open-mmlab/mmsegmentation/pull/989))
+- Support a real-time segmentation model STDC ([#995](https://github.com/open-mmlab/mmsegmentation/pull/995))
+- Support a widely-used segmentation model in lane detection ERFNet ([#960](https://github.com/open-mmlab/mmsegmentation/pull/960))
+- Support A Remote Sensing Land-Cover Dataset LoveDA ([#1028](https://github.com/open-mmlab/mmsegmentation/pull/1028))
+- Support focal loss ([#1024](https://github.com/open-mmlab/mmsegmentation/pull/1024))
+
+**New Features**
+
+- Support Twins ([#989](https://github.com/open-mmlab/mmsegmentation/pull/989))
+- Support a real-time segmentation model STDC ([#995](https://github.com/open-mmlab/mmsegmentation/pull/995))
+- Support a widely-used segmentation model in lane detection ERFNet ([#960](https://github.com/open-mmlab/mmsegmentation/pull/960))
+- Add SETR cityscapes benchmark ([#1087](https://github.com/open-mmlab/mmsegmentation/pull/1087))
+- Add BiSeNetV1 COCO-Stuff 164k benchmark ([#1019](https://github.com/open-mmlab/mmsegmentation/pull/1019))
+- Support focal loss ([#1024](https://github.com/open-mmlab/mmsegmentation/pull/1024))
+- Add Cutout transform ([#1022](https://github.com/open-mmlab/mmsegmentation/pull/1022))
+
+**Improvements**
+
+- Set a random seed when the user does not set a seed ([#1039](https://github.com/open-mmlab/mmsegmentation/pull/1039))
+- Add CircleCI setup ([#1086](https://github.com/open-mmlab/mmsegmentation/pull/1086))
+- Skip CI on ignoring given paths ([#1078](https://github.com/open-mmlab/mmsegmentation/pull/1078))
+- Add abstract and image for every paper ([#1060](https://github.com/open-mmlab/mmsegmentation/pull/1060))
+- Create a symbolic link on windows ([#1090](https://github.com/open-mmlab/mmsegmentation/pull/1090))
+- Support video demo using trained model ([#1014](https://github.com/open-mmlab/mmsegmentation/pull/1014))
+
+**Bug Fixes**
+
+- Fix incorrectly loading init_cfg or pretrained models of several transformer models ([#999](https://github.com/open-mmlab/mmsegmentation/pull/999), [#1069](https://github.com/open-mmlab/mmsegmentation/pull/1069), [#1102](https://github.com/open-mmlab/mmsegmentation/pull/1102))
+- Fix EfficientMultiheadAttention in SegFormer ([#1037](https://github.com/open-mmlab/mmsegmentation/pull/1037))
+- Remove `fp16` folder in `configs` ([#1031](https://github.com/open-mmlab/mmsegmentation/pull/1031))
+- Fix several typos in .yml file (Dice Metric [#1041](https://github.com/open-mmlab/mmsegmentation/pull/1041), ADE20K dataset [#1120](https://github.com/open-mmlab/mmsegmentation/pull/1120), Training Memory (GB) [#1083](https://github.com/open-mmlab/mmsegmentation/pull/1083))
+- Fix test error when using `--show-dir` ([#1091](https://github.com/open-mmlab/mmsegmentation/pull/1091))
+- Fix dist training infinite waiting issue ([#1035](https://github.com/open-mmlab/mmsegmentation/pull/1035))
+- Change the upper version of mmcv to 1.5.0 ([#1096](https://github.com/open-mmlab/mmsegmentation/pull/1096))
+- Fix symlink failure on Windows ([#1038](https://github.com/open-mmlab/mmsegmentation/pull/1038))
+- Cancel previous runs that are not completed ([#1118](https://github.com/open-mmlab/mmsegmentation/pull/1118))
+- Unified links of readthedocs in docs ([#1119](https://github.com/open-mmlab/mmsegmentation/pull/1119))
+
+**Contributors**
+
+- @Junjue-Wang made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1028
+- @ddebby made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1066
+- @del-zhenwu made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1078
+- @KangBK0120 made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1106
+- @zergzzlun made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1091
+- @fingertap made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1035
+- @irvingzhang0512 made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1014
+- @littleSunlxy made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/989
+- @lkm2835
+- @RockeyCoss
+- @MengzhangLI
+- @Junjun2016
+- @xiexinch
+- @xvjiarui
+
+### V0.19 (11/02/2021)
+
+**Highlights**
+
+- Support TIMMBackbone wrapper ([#998](https://github.com/open-mmlab/mmsegmentation/pull/998))
+- Support custom hook ([#428](https://github.com/open-mmlab/mmsegmentation/pull/428))
+- Add codespell pre-commit hook ([#920](https://github.com/open-mmlab/mmsegmentation/pull/920))
+- Add FastFCN benchmark on ADE20K ([#972](https://github.com/open-mmlab/mmsegmentation/pull/972))
+
+**New Features**
+
+- Support TIMMBackbone wrapper ([#998](https://github.com/open-mmlab/mmsegmentation/pull/998))
+- Support custom hook ([#428](https://github.com/open-mmlab/mmsegmentation/pull/428))
+- Add FastFCN benchmark on ADE20K ([#972](https://github.com/open-mmlab/mmsegmentation/pull/972))
+- Add codespell pre-commit hook and fix typos ([#920](https://github.com/open-mmlab/mmsegmentation/pull/920))
+
+**Improvements**
+
+- Make inputs & channels smaller in unittests ([#1004](https://github.com/open-mmlab/mmsegmentation/pull/1004))
+- Change `self.loss_decode` back to `dict` in Single Loss situation ([#1002](https://github.com/open-mmlab/mmsegmentation/pull/1002))
+
+**Bug Fixes**
+
+- Fix typo in usage example ([#1003](https://github.com/open-mmlab/mmsegmentation/pull/1003))
+- Add contiguous after permutation in ViT ([#992](https://github.com/open-mmlab/mmsegmentation/pull/992))
+- Fix the invalid link ([#985](https://github.com/open-mmlab/mmsegmentation/pull/985))
+- Fix bug in CI with python 3.9 ([#994](https://github.com/open-mmlab/mmsegmentation/pull/994))
+- Fix bug when loading class name form file in custom dataset ([#923](https://github.com/open-mmlab/mmsegmentation/pull/923))
+
+**Contributors**
+
+- @ShoupingShan made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/923
+- @RockeyCoss made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/954
+- @HarborYuan made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/992
+- @lkm2835 made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/1003
+- @gszh made their first contribution in https://github.com/open-mmlab/mmsegmentation/pull/428
+- @VVsssssk
+- @MengzhangLI
+- @Junjun2016
+
+### V0.18 (10/07/2021)
+
+**Highlights**
+
+- Support three real-time segmentation models (ICNet [#884](https://github.com/open-mmlab/mmsegmentation/pull/884), BiSeNetV1 [#851](https://github.com/open-mmlab/mmsegmentation/pull/851), and BiSeNetV2 [#804](https://github.com/open-mmlab/mmsegmentation/pull/804))
+- Support one efficient segmentation model (FastFCN [#885](https://github.com/open-mmlab/mmsegmentation/pull/885))
+- Support one efficient non-local/self-attention based segmentation model (ISANet [#70](https://github.com/open-mmlab/mmsegmentation/pull/70))
+- Support COCO-Stuff 10k and 164k datasets ([#625](https://github.com/open-mmlab/mmsegmentation/pull/625))
+- Support evaluate concated dataset separately ([#833](https://github.com/open-mmlab/mmsegmentation/pull/833))
+- Support loading GT for evaluation from multi-file backend ([#867](https://github.com/open-mmlab/mmsegmentation/pull/867))
+
+**New Features**
+
+- Support three real-time segmentation models (ICNet [#884](https://github.com/open-mmlab/mmsegmentation/pull/884), BiSeNetV1 [#851](https://github.com/open-mmlab/mmsegmentation/pull/851), and BiSeNetV2 [#804](https://github.com/open-mmlab/mmsegmentation/pull/804))
+- Support one efficient segmentation model (FastFCN [#885](https://github.com/open-mmlab/mmsegmentation/pull/885))
+- Support one efficient non-local/self-attention based segmentation model (ISANet [#70](https://github.com/open-mmlab/mmsegmentation/pull/70))
+- Support COCO-Stuff 10k and 164k datasets ([#625](https://github.com/open-mmlab/mmsegmentation/pull/625))
+- Support evaluate concated dataset separately ([#833](https://github.com/open-mmlab/mmsegmentation/pull/833))
+
+**Improvements**
+
+- Support loading GT for evaluation from multi-file backend ([#867](https://github.com/open-mmlab/mmsegmentation/pull/867))
+- Auto-convert SyncBN to BN when training on DP automatly([#772](https://github.com/open-mmlab/mmsegmentation/pull/772))
+- Refactor Swin-Transformer ([#800](https://github.com/open-mmlab/mmsegmentation/pull/800))
+
+**Bug Fixes**
+
+- Update mmcv installation in dockerfile ([#860](https://github.com/open-mmlab/mmsegmentation/pull/860))
+- Fix number of iteration bug when resuming checkpoint in distributed train ([#866](https://github.com/open-mmlab/mmsegmentation/pull/866))
+- Fix parsing parse in val_step ([#906](https://github.com/open-mmlab/mmsegmentation/pull/906))
+
+### V0.17 (09/01/2021)
+
+**Highlights**
+
+- Support SegFormer
+- Support DPT
+- Support Dark Zurich and Nighttime Driving datasets
+- Support progressive evaluation
+
+**New Features**
+
+- Support SegFormer ([#599](https://github.com/open-mmlab/mmsegmentation/pull/599))
+- Support DPT ([#605](https://github.com/open-mmlab/mmsegmentation/pull/605))
+- Support Dark Zurich and Nighttime Driving datasets ([#815](https://github.com/open-mmlab/mmsegmentation/pull/815))
+- Support progressive evaluation ([#709](https://github.com/open-mmlab/mmsegmentation/pull/709))
+
+**Improvements**
+
+- Add multiscale_output interface and unittests for HRNet ([#830](https://github.com/open-mmlab/mmsegmentation/pull/830))
+- Support inherit cityscapes dataset ([#750](https://github.com/open-mmlab/mmsegmentation/pull/750))
+- Fix some typos in README.md ([#824](https://github.com/open-mmlab/mmsegmentation/pull/824))
+- Delete convert function and add instruction to ViT/Swin README.md ([#791](https://github.com/open-mmlab/mmsegmentation/pull/791))
+- Add vit/swin/mit convert weight scripts ([#783](https://github.com/open-mmlab/mmsegmentation/pull/783))
+- Add copyright files ([#796](https://github.com/open-mmlab/mmsegmentation/pull/796))
+
+**Bug Fixes**
+
+- Fix invalid checkpoint link in inference_demo.ipynb ([#814](https://github.com/open-mmlab/mmsegmentation/pull/814))
+- Ensure that items in dataset have the same order across multi machine ([#780](https://github.com/open-mmlab/mmsegmentation/pull/780))
+- Fix the log error ([#766](https://github.com/open-mmlab/mmsegmentation/pull/766))
+
+### V0.16 (08/04/2021)
+
+**Highlights**
+
+- Support PyTorch 1.9
+- Support SegFormer backbone MiT
+- Support md2yml pre-commit hook
+- Support frozen stage for HRNet
+
+**New Features**
+
+- Support SegFormer backbone MiT ([#594](https://github.com/open-mmlab/mmsegmentation/pull/594))
+- Support md2yml pre-commit hook ([#732](https://github.com/open-mmlab/mmsegmentation/pull/732))
+- Support mim ([#717](https://github.com/open-mmlab/mmsegmentation/pull/717))
+- Add mmseg2torchserve tool ([#552](https://github.com/open-mmlab/mmsegmentation/pull/552))
+
+**Improvements**
+
+- Support hrnet frozen stage ([#743](https://github.com/open-mmlab/mmsegmentation/pull/743))
+- Add template of reimplementation questions ([#741](https://github.com/open-mmlab/mmsegmentation/pull/741))
+- Output pdf and epub formats for readthedocs ([#742](https://github.com/open-mmlab/mmsegmentation/pull/742))
+- Refine the docstring of ResNet ([#723](https://github.com/open-mmlab/mmsegmentation/pull/723))
+- Replace interpolate with resize ([#731](https://github.com/open-mmlab/mmsegmentation/pull/731))
+- Update resource limit ([#700](https://github.com/open-mmlab/mmsegmentation/pull/700))
+- Update config.md ([#678](https://github.com/open-mmlab/mmsegmentation/pull/678))
+
+**Bug Fixes**
+
+- Fix ATTENTION registry ([#729](https://github.com/open-mmlab/mmsegmentation/pull/729))
+- Fix analyze log script ([#716](https://github.com/open-mmlab/mmsegmentation/pull/716))
+- Fix doc api display ([#725](https://github.com/open-mmlab/mmsegmentation/pull/725))
+- Fix patch_embed and pos_embed mismatch error ([#685](https://github.com/open-mmlab/mmsegmentation/pull/685))
+- Fix efficient test for multi-node ([#707](https://github.com/open-mmlab/mmsegmentation/pull/707))
+- Fix init_cfg in resnet backbone ([#697](https://github.com/open-mmlab/mmsegmentation/pull/697))
+- Fix efficient test bug ([#702](https://github.com/open-mmlab/mmsegmentation/pull/702))
+- Fix url error in config docs ([#680](https://github.com/open-mmlab/mmsegmentation/pull/680))
+- Fix mmcv installation ([#676](https://github.com/open-mmlab/mmsegmentation/pull/676))
+- Fix torch version ([#670](https://github.com/open-mmlab/mmsegmentation/pull/670))
+
+**Contributors**
+
+@sshuair @xiexinch @Junjun2016 @mmeendez8 @xvjiarui @sennnnn @puhsu @BIGWangYuDong @keke1u @daavoo
+
+### V0.15 (07/04/2021)
+
+**Highlights**
+
+- Support ViT, SETR, and Swin-Transformer
+- Add Chinese documentation
+- Unified parameter initialization
+
+**Bug Fixes**
+
+- Fix typo and links ([#608](https://github.com/open-mmlab/mmsegmentation/pull/608))
+- Fix Dockerfile ([#607](https://github.com/open-mmlab/mmsegmentation/pull/607))
+- Fix ViT init ([#609](https://github.com/open-mmlab/mmsegmentation/pull/609))
+- Fix mmcv version compatible table ([#658](https://github.com/open-mmlab/mmsegmentation/pull/658))
+- Fix model links of DMNEt ([#660](https://github.com/open-mmlab/mmsegmentation/pull/660))
+
+**New Features**
+
+- Support loading DeiT weights ([#538](https://github.com/open-mmlab/mmsegmentation/pull/538))
+- Support SETR ([#531](https://github.com/open-mmlab/mmsegmentation/pull/531), [#635](https://github.com/open-mmlab/mmsegmentation/pull/635))
+- Add config and models for ViT backbone with UperHead ([#520](https://github.com/open-mmlab/mmsegmentation/pull/531), [#635](https://github.com/open-mmlab/mmsegmentation/pull/520))
+- Support Swin-Transformer ([#511](https://github.com/open-mmlab/mmsegmentation/pull/511))
+- Add higher accuracy FastSCNN ([#606](https://github.com/open-mmlab/mmsegmentation/pull/606))
+- Add Chinese documentation ([#666](https://github.com/open-mmlab/mmsegmentation/pull/666))
+
+**Improvements**
+
+- Unified parameter initialization ([#567](https://github.com/open-mmlab/mmsegmentation/pull/567))
+- Separate CUDA and CPU in github action CI ([#602](https://github.com/open-mmlab/mmsegmentation/pull/602))
+- Support persistent dataloader worker ([#646](https://github.com/open-mmlab/mmsegmentation/pull/646))
+- Update meta file fields ([#661](https://github.com/open-mmlab/mmsegmentation/pull/661), [#664](https://github.com/open-mmlab/mmsegmentation/pull/664))
+
+### V0.14 (06/02/2021)
+
+**Highlights**
+
+- Support ONNX to TensorRT
+- Support MIM
+
+**Bug Fixes**
+
+- Fix ONNX to TensorRT verify ([#547](https://github.com/open-mmlab/mmsegmentation/pull/547))
+- Fix save best for EvalHook ([#575](https://github.com/open-mmlab/mmsegmentation/pull/575))
+
+**New Features**
+
+- Support loading DeiT weights ([#538](https://github.com/open-mmlab/mmsegmentation/pull/538))
+- Support ONNX to TensorRT ([#542](https://github.com/open-mmlab/mmsegmentation/pull/542))
+- Support output results for ADE20k ([#544](https://github.com/open-mmlab/mmsegmentation/pull/544))
+- Support MIM ([#549](https://github.com/open-mmlab/mmsegmentation/pull/549))
+
+**Improvements**
+
+- Add option for ViT output shape ([#530](https://github.com/open-mmlab/mmsegmentation/pull/530))
+- Infer batch size using len(result) ([#532](https://github.com/open-mmlab/mmsegmentation/pull/532))
+- Add compatible table between MMSeg and MMCV ([#558](https://github.com/open-mmlab/mmsegmentation/pull/558))
+
+### V0.13 (05/05/2021)
+
+**Highlights**
+
+- Support Pascal Context Class-59 dataset.
+- Support Visual Transformer Backbone.
+- Support mFscore metric.
+
+**Bug Fixes**
+
+- Fixed Colaboratory tutorial ([#451](https://github.com/open-mmlab/mmsegmentation/pull/451))
+- Fixed mIoU calculation range ([#471](https://github.com/open-mmlab/mmsegmentation/pull/471))
+- Fixed sem_fpn, unet README.md ([#492](https://github.com/open-mmlab/mmsegmentation/pull/492))
+- Fixed `num_classes` in FCN for Pascal Context 60-class dataset ([#488](https://github.com/open-mmlab/mmsegmentation/pull/488))
+- Fixed FP16 inference ([#497](https://github.com/open-mmlab/mmsegmentation/pull/497))
+
+**New Features**
+
+- Support dynamic export and visualize to pytorch2onnx ([#463](https://github.com/open-mmlab/mmsegmentation/pull/463))
+- Support export to torchscript ([#469](https://github.com/open-mmlab/mmsegmentation/pull/469), [#499](https://github.com/open-mmlab/mmsegmentation/pull/499))
+- Support Pascal Context Class-59 dataset ([#459](https://github.com/open-mmlab/mmsegmentation/pull/459))
+- Support Visual Transformer backbone ([#465](https://github.com/open-mmlab/mmsegmentation/pull/465))
+- Support UpSample Neck ([#512](https://github.com/open-mmlab/mmsegmentation/pull/512))
+- Support mFscore metric ([#509](https://github.com/open-mmlab/mmsegmentation/pull/509))
+
+**Improvements**
+
+- Add more CI for PyTorch ([#460](https://github.com/open-mmlab/mmsegmentation/pull/460))
+- Add print model graph args for tools/print_config.py ([#451](https://github.com/open-mmlab/mmsegmentation/pull/451))
+- Add cfg links in modelzoo README.md ([#468](https://github.com/open-mmlab/mmsegmentation/pull/469))
+- Add BaseSegmentor import to segmentors/__init__.py ([#495](https://github.com/open-mmlab/mmsegmentation/pull/495))
+- Add MMOCR, MMGeneration links ([#501](https://github.com/open-mmlab/mmsegmentation/pull/501), [#506](https://github.com/open-mmlab/mmsegmentation/pull/506))
+- Add Chinese QR code ([#506](https://github.com/open-mmlab/mmsegmentation/pull/506))
+- Use MMCV MODEL_REGISTRY ([#515](https://github.com/open-mmlab/mmsegmentation/pull/515))
+- Add ONNX testing tools ([#498](https://github.com/open-mmlab/mmsegmentation/pull/498))
+- Replace data_dict calling 'img' key to support MMDet3D ([#514](https://github.com/open-mmlab/mmsegmentation/pull/514))
+- Support reading class_weight from file in loss function ([#513](https://github.com/open-mmlab/mmsegmentation/pull/513))
+- Make tags as comment ([#505](https://github.com/open-mmlab/mmsegmentation/pull/505))
+- Use MMCV EvalHook ([#438](https://github.com/open-mmlab/mmsegmentation/pull/438))
+
+### V0.12 (04/03/2021)
+
+**Highlights**
+
+- Support FCN-Dilate 6 model.
+- Support Dice Loss.
+
+**Bug Fixes**
+
+- Fixed PhotoMetricDistortion Doc ([#388](https://github.com/open-mmlab/mmsegmentation/pull/388))
+- Fixed install scripts ([#399](https://github.com/open-mmlab/mmsegmentation/pull/399))
+- Fixed Dice Loss multi-class ([#417](https://github.com/open-mmlab/mmsegmentation/pull/417))
+
+**New Features**
+
+- Support Dice Loss ([#396](https://github.com/open-mmlab/mmsegmentation/pull/396))
+- Add plot logs tool ([#426](https://github.com/open-mmlab/mmsegmentation/pull/426))
+- Add opacity option to show_result ([#425](https://github.com/open-mmlab/mmsegmentation/pull/425))
+- Speed up mIoU metric ([#430](https://github.com/open-mmlab/mmsegmentation/pull/430))
+
+**Improvements**
+
+- Refactor unittest file structure ([#440](https://github.com/open-mmlab/mmsegmentation/pull/440))
+- Fix typos in the repo ([#449](https://github.com/open-mmlab/mmsegmentation/pull/449))
+- Include class-level metrics in the log ([#445](https://github.com/open-mmlab/mmsegmentation/pull/445))
+
+### V0.11 (02/02/2021)
+
+**Highlights**
+
+- Support memory efficient test, add more UNet models.
+
+**Bug Fixes**
+
+- Fixed TTA resize scale ([#334](https://github.com/open-mmlab/mmsegmentation/pull/334))
+- Fixed CI for pip 20.3 ([#307](https://github.com/open-mmlab/mmsegmentation/pull/307))
+- Fixed ADE20k test ([#359](https://github.com/open-mmlab/mmsegmentation/pull/359))
+
+**New Features**
+
+- Support memory efficient test ([#330](https://github.com/open-mmlab/mmsegmentation/pull/330))
+- Add more UNet benchmarks ([#324](https://github.com/open-mmlab/mmsegmentation/pull/324))
+- Support Lovasz Loss ([#351](https://github.com/open-mmlab/mmsegmentation/pull/351))
+
+**Improvements**
+
+- Move train_cfg/test_cfg inside model ([#341](https://github.com/open-mmlab/mmsegmentation/pull/341))
+
+### V0.10 (01/01/2021)
+
+**Highlights**
+
+- Support MobileNetV3, DMNet, APCNet. Add models of ResNet18V1b, ResNet18V1c, ResNet50V1b.
+
+**Bug Fixes**
+
+- Fixed CPU TTA ([#276](https://github.com/open-mmlab/mmsegmentation/pull/276))
+- Fixed CI for pip 20.3 ([#307](https://github.com/open-mmlab/mmsegmentation/pull/307))
+
+**New Features**
+
+- Add ResNet18V1b, ResNet18V1c, ResNet50V1b, ResNet101V1b models ([#316](https://github.com/open-mmlab/mmsegmentation/pull/316))
+- Support MobileNetV3 ([#268](https://github.com/open-mmlab/mmsegmentation/pull/268))
+- Add 4 retinal vessel segmentation benchmark ([#315](https://github.com/open-mmlab/mmsegmentation/pull/315))
+- Support DMNet ([#313](https://github.com/open-mmlab/mmsegmentation/pull/313))
+- Support APCNet ([#299](https://github.com/open-mmlab/mmsegmentation/pull/299))
+
+**Improvements**
+
+- Refactor Documentation page ([#311](https://github.com/open-mmlab/mmsegmentation/pull/311))
+- Support resize data augmentation according to original image size ([#291](https://github.com/open-mmlab/mmsegmentation/pull/291))
+
+### V0.9 (30/11/2020)
+
+**Highlights**
+
+- Support 4 medical dataset, UNet and CGNet.
+
+**New Features**
+
+- Support RandomRotate transform ([#215](https://github.com/open-mmlab/mmsegmentation/pull/215), [#260](https://github.com/open-mmlab/mmsegmentation/pull/260))
+- Support RGB2Gray transform ([#227](https://github.com/open-mmlab/mmsegmentation/pull/227))
+- Support Rerange transform ([#228](https://github.com/open-mmlab/mmsegmentation/pull/228))
+- Support ignore_index for BCE loss ([#210](https://github.com/open-mmlab/mmsegmentation/pull/210))
+- Add modelzoo statistics ([#263](https://github.com/open-mmlab/mmsegmentation/pull/263))
+- Support Dice evaluation metric ([#225](https://github.com/open-mmlab/mmsegmentation/pull/225))
+- Support Adjust Gamma transform ([#232](https://github.com/open-mmlab/mmsegmentation/pull/232))
+- Support CLAHE transform ([#229](https://github.com/open-mmlab/mmsegmentation/pull/229))
+
+**Bug Fixes**
+
+- Fixed detail API link ([#267](https://github.com/open-mmlab/mmsegmentation/pull/267))
+
+### V0.8 (03/11/2020)
+
+**Highlights**
+
+- Support 4 medical dataset, UNet and CGNet.
+
+**New Features**
+
+- Support customize runner ([#118](https://github.com/open-mmlab/mmsegmentation/pull/118))
+- Support UNet ([#161](https://github.com/open-mmlab/mmsegmentation/pull/162))
+- Support CHASE_DB1, DRIVE, STARE, HRD ([#203](https://github.com/open-mmlab/mmsegmentation/pull/203))
+- Support CGNet ([#223](https://github.com/open-mmlab/mmsegmentation/pull/223))
+
+### V0.7 (07/10/2020)
+
+**Highlights**
+
+- Support Pascal Context dataset and customizing class dataset.
+
+**Bug Fixes**
+
+- Fixed CPU inference ([#153](https://github.com/open-mmlab/mmsegmentation/pull/153))
+
+**New Features**
+
+- Add DeepLab OS16 models ([#154](https://github.com/open-mmlab/mmsegmentation/pull/154))
+- Support Pascal Context dataset ([#133](https://github.com/open-mmlab/mmsegmentation/pull/133))
+- Support customizing dataset classes ([#71](https://github.com/open-mmlab/mmsegmentation/pull/71))
+- Support customizing dataset palette ([#157](https://github.com/open-mmlab/mmsegmentation/pull/157))
+
+**Improvements**
+
+- Support 4D tensor output in ONNX ([#150](https://github.com/open-mmlab/mmsegmentation/pull/150))
+- Remove redundancies in ONNX export ([#160](https://github.com/open-mmlab/mmsegmentation/pull/160))
+- Migrate to MMCV DepthwiseSeparableConv ([#158](https://github.com/open-mmlab/mmsegmentation/pull/158))
+- Migrate to MMCV collect_env ([#137](https://github.com/open-mmlab/mmsegmentation/pull/137))
+- Use img_prefix and seg_prefix for loading ([#153](https://github.com/open-mmlab/mmsegmentation/pull/153))
+
+### V0.6 (10/09/2020)
+
+**Highlights**
+
+- Support new methods i.e. MobileNetV2, EMANet, DNL, PointRend, Semantic FPN, Fast-SCNN, ResNeSt.
+
+**Bug Fixes**
+
+- Fixed sliding inference ONNX export ([#90](https://github.com/open-mmlab/mmsegmentation/pull/90))
+
+**New Features**
+
+- Support MobileNet v2 ([#86](https://github.com/open-mmlab/mmsegmentation/pull/86))
+- Support EMANet ([#34](https://github.com/open-mmlab/mmsegmentation/pull/34))
+- Support DNL ([#37](https://github.com/open-mmlab/mmsegmentation/pull/37))
+- Support PointRend ([#109](https://github.com/open-mmlab/mmsegmentation/pull/109))
+- Support Semantic FPN ([#94](https://github.com/open-mmlab/mmsegmentation/pull/94))
+- Support Fast-SCNN ([#58](https://github.com/open-mmlab/mmsegmentation/pull/58))
+- Support ResNeSt backbone ([#47](https://github.com/open-mmlab/mmsegmentation/pull/47))
+- Support ONNX export (experimental) ([#12](https://github.com/open-mmlab/mmsegmentation/pull/12))
+
+**Improvements**
+
+- Support Upsample in ONNX ([#100](https://github.com/open-mmlab/mmsegmentation/pull/100))
+- Support Windows install (experimental) ([#75](https://github.com/open-mmlab/mmsegmentation/pull/75))
+- Add more OCRNet results ([#20](https://github.com/open-mmlab/mmsegmentation/pull/20))
+- Add PyTorch 1.6 CI ([#64](https://github.com/open-mmlab/mmsegmentation/pull/64))
+- Get version and githash automatically ([#55](https://github.com/open-mmlab/mmsegmentation/pull/55))
+
+### v0.5.1 (11/08/2020)
+
+**Highlights**
+
+- Support FP16 and more generalized OHEM
+
+**Bug Fixes**
+
+- Fixed Pascal VOC conversion script (#19)
+- Fixed OHEM weight assign bug (#54)
+- Fixed palette type when palette is not given (#27)
+
+**New Features**
+
+- Support FP16 (#21)
+- Generalized OHEM (#54)
+
+**Improvements**
+
+- Add load-from flag (#33)
+- Fixed training tricks doc about different learning rates of model (#26)
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/conf.py b/EgoHOS/raw/script/mmsegmentation/docs/en/conf.py
new file mode 100644
index 0000000000000000000000000000000000000000..87b16f2667494098fe2a3da1193fa778ad5904b1
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/conf.py
@@ -0,0 +1,133 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+# Configuration file for the Sphinx documentation builder.
+#
+# This file only contains a selection of the most common options. For a full
+# list see the documentation:
+# https://www.sphinx-doc.org/en/master/usage/configuration.html
+
+# -- Path setup --------------------------------------------------------------
+
+# If extensions (or modules to document with autodoc) are in another directory,
+# add these directories to sys.path here. If the directory is relative to the
+# documentation root, use os.path.abspath to make it absolute, like shown here.
+#
+import os
+import subprocess
+import sys
+
+import pytorch_sphinx_theme
+
+sys.path.insert(0, os.path.abspath('../../'))
+
+# -- Project information -----------------------------------------------------
+
+project = 'MMSegmentation'
+copyright = '2020-2021, OpenMMLab'
+author = 'MMSegmentation Authors'
+version_file = '../../mmseg/version.py'
+
+
+def get_version():
+ with open(version_file, 'r') as f:
+ exec(compile(f.read(), version_file, 'exec'))
+ return locals()['__version__']
+
+
+# The full version, including alpha/beta/rc tags
+release = get_version()
+
+# -- General configuration ---------------------------------------------------
+
+# Add any Sphinx extension module names here, as strings. They can be
+# extensions coming with Sphinx (named 'sphinx.ext.*') or your custom
+# ones.
+extensions = [
+ 'sphinx.ext.autodoc', 'sphinx.ext.napoleon', 'sphinx.ext.viewcode',
+ 'sphinx_markdown_tables', 'sphinx_copybutton', 'myst_parser'
+]
+
+autodoc_mock_imports = [
+ 'matplotlib', 'pycocotools', 'mmseg.version', 'mmcv.ops'
+]
+
+# Ignore >>> when copying code
+copybutton_prompt_text = r'>>> |\.\.\. '
+copybutton_prompt_is_regexp = True
+
+# Add any paths that contain templates here, relative to this directory.
+templates_path = ['_templates']
+
+# The suffix(es) of source filenames.
+# You can specify multiple suffix as a list of string:
+#
+source_suffix = {
+ '.rst': 'restructuredtext',
+ '.md': 'markdown',
+}
+
+# The master toctree document.
+master_doc = 'index'
+
+# List of patterns, relative to source directory, that match files and
+# directories to ignore when looking for source files.
+# This pattern also affects html_static_path and html_extra_path.
+exclude_patterns = ['_build', 'Thumbs.db', '.DS_Store']
+
+# -- Options for HTML output -------------------------------------------------
+
+# The theme to use for HTML and HTML Help pages. See the documentation for
+# a list of builtin themes.
+#
+# html_theme = 'sphinx_rtd_theme'
+html_theme = 'pytorch_sphinx_theme'
+html_theme_path = [pytorch_sphinx_theme.get_html_theme_path()]
+html_theme_options = {
+ 'logo_url':
+ 'https://mmsegmentation.readthedocs.io/en/latest/',
+ 'menu': [
+ {
+ 'name':
+ 'Tutorial',
+ 'url':
+ 'https://github.com/open-mmlab/mmsegmentation/blob/master/'
+ 'demo/MMSegmentation_Tutorial.ipynb'
+ },
+ {
+ 'name': 'GitHub',
+ 'url': 'https://github.com/open-mmlab/mmsegmentation'
+ },
+ {
+ 'name':
+ 'Upstream',
+ 'children': [
+ {
+ 'name': 'MMCV',
+ 'url': 'https://github.com/open-mmlab/mmcv',
+ 'description': 'Foundational library for computer vision'
+ },
+ ]
+ },
+ ],
+ # Specify the language of shared menu
+ 'menu_lang':
+ 'en'
+}
+
+# Add any paths that contain custom static files (such as style sheets) here,
+# relative to this directory. They are copied after the builtin static files,
+# so a file named "default.css" will overwrite the builtin "default.css".
+html_static_path = ['_static']
+html_css_files = ['css/readthedocs.css']
+
+# Enable ::: for my_st
+myst_enable_extensions = ['colon_fence']
+
+language = 'en'
+
+
+def builder_inited_handler(app):
+ subprocess.run(['./stat.py'])
+
+
+def setup(app):
+ app.connect('builder-inited', builder_inited_handler)
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/dataset_prepare.md b/EgoHOS/raw/script/mmsegmentation/docs/en/dataset_prepare.md
new file mode 100644
index 0000000000000000000000000000000000000000..c6aaad10ed9d3bf68439e530eed30eb0a9c686cc
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/dataset_prepare.md
@@ -0,0 +1,377 @@
+## Prepare datasets
+
+It is recommended to symlink the dataset root to `$MMSEGMENTATION/data`.
+If your folder structure is different, you may need to change the corresponding paths in config files.
+
+```none
+mmsegmentation
+├── mmseg
+├── tools
+├── configs
+├── data
+│ ├── cityscapes
+│ │ ├── leftImg8bit
+│ │ │ ├── train
+│ │ │ ├── val
+│ │ ├── gtFine
+│ │ │ ├── train
+│ │ │ ├── val
+│ ├── VOCdevkit
+│ │ ├── VOC2012
+│ │ │ ├── JPEGImages
+│ │ │ ├── SegmentationClass
+│ │ │ ├── ImageSets
+│ │ │ │ ├── Segmentation
+│ │ ├── VOC2010
+│ │ │ ├── JPEGImages
+│ │ │ ├── SegmentationClassContext
+│ │ │ ├── ImageSets
+│ │ │ │ ├── SegmentationContext
+│ │ │ │ │ ├── train.txt
+│ │ │ │ │ ├── val.txt
+│ │ │ ├── trainval_merged.json
+│ │ ├── VOCaug
+│ │ │ ├── dataset
+│ │ │ │ ├── cls
+│ ├── ade
+│ │ ├── ADEChallengeData2016
+│ │ │ ├── annotations
+│ │ │ │ ├── training
+│ │ │ │ ├── validation
+│ │ │ ├── images
+│ │ │ │ ├── training
+│ │ │ │ ├── validation
+│ ├── coco_stuff10k
+│ │ ├── images
+│ │ │ ├── train2014
+│ │ │ ├── test2014
+│ │ ├── annotations
+│ │ │ ├── train2014
+│ │ │ ├── test2014
+│ │ ├── imagesLists
+│ │ │ ├── train.txt
+│ │ │ ├── test.txt
+│ │ │ ├── all.txt
+│ ├── coco_stuff164k
+│ │ ├── images
+│ │ │ ├── train2017
+│ │ │ ├── val2017
+│ │ ├── annotations
+│ │ │ ├── train2017
+│ │ │ ├── val2017
+│ ├── CHASE_DB1
+│ │ ├── images
+│ │ │ ├── training
+│ │ │ ├── validation
+│ │ ├── annotations
+│ │ │ ├── training
+│ │ │ ├── validation
+│ ├── DRIVE
+│ │ ├── images
+│ │ │ ├── training
+│ │ │ ├── validation
+│ │ ├── annotations
+│ │ │ ├── training
+│ │ │ ├── validation
+│ ├── HRF
+│ │ ├── images
+│ │ │ ├── training
+│ │ │ ├── validation
+│ │ ├── annotations
+│ │ │ ├── training
+│ │ │ ├── validation
+│ ├── STARE
+│ │ ├── images
+│ │ │ ├── training
+│ │ │ ├── validation
+│ │ ├── annotations
+│ │ │ ├── training
+│ │ │ ├── validation
+| ├── dark_zurich
+| │ ├── gps
+| │ │ ├── val
+| │ │ └── val_ref
+| │ ├── gt
+| │ │ └── val
+| │ ├── LICENSE.txt
+| │ ├── lists_file_names
+| │ │ ├── val_filenames.txt
+| │ │ └── val_ref_filenames.txt
+| │ ├── README.md
+| │ └── rgb_anon
+| │ | ├── val
+| │ | └── val_ref
+| ├── NighttimeDrivingTest
+| | ├── gtCoarse_daytime_trainvaltest
+| | │ └── test
+| | │ └── night
+| | └── leftImg8bit
+| | | └── test
+| | | └── night
+│ ├── loveDA
+│ │ ├── img_dir
+│ │ │ ├── train
+│ │ │ ├── val
+│ │ │ ├── test
+│ │ ├── ann_dir
+│ │ │ ├── train
+│ │ │ ├── val
+│ ├── potsdam
+│ │ ├── img_dir
+│ │ │ ├── train
+│ │ │ ├── val
+│ │ ├── ann_dir
+│ │ │ ├── train
+│ │ │ ├── val
+│ ├── vaihingen
+│ │ ├── img_dir
+│ │ │ ├── train
+│ │ │ ├── val
+│ │ ├── ann_dir
+│ │ │ ├── train
+│ │ │ ├── val
+│ ├── iSAID
+│ │ ├── img_dir
+│ │ │ ├── train
+│ │ │ ├── val
+│ │ │ ├── test
+│ │ ├── ann_dir
+│ │ │ ├── train
+│ │ │ ├── val
+```
+
+### Cityscapes
+
+The data could be found [here](https://www.cityscapes-dataset.com/downloads/) after registration.
+
+By convention, `**labelTrainIds.png` are used for cityscapes training.
+We provided a [scripts](https://github.com/open-mmlab/mmsegmentation/blob/master/tools/convert_datasets/cityscapes.py) based on [cityscapesscripts](https://github.com/mcordts/cityscapesScripts)
+to generate `**labelTrainIds.png`.
+
+```shell
+# --nproc means 8 process for conversion, which could be omitted as well.
+python tools/convert_datasets/cityscapes.py data/cityscapes --nproc 8
+```
+
+### Pascal VOC
+
+Pascal VOC 2012 could be downloaded from [here](http://host.robots.ox.ac.uk/pascal/VOC/voc2012/VOCtrainval_11-May-2012.tar).
+Beside, most recent works on Pascal VOC dataset usually exploit extra augmentation data, which could be found [here](http://www.eecs.berkeley.edu/Research/Projects/CS/vision/grouping/semantic_contours/benchmark.tgz).
+
+If you would like to use augmented VOC dataset, please run following command to convert augmentation annotations into proper format.
+
+```shell
+# --nproc means 8 process for conversion, which could be omitted as well.
+python tools/convert_datasets/voc_aug.py data/VOCdevkit data/VOCdevkit/VOCaug --nproc 8
+```
+
+Please refer to [concat dataset](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/tutorials/customize_datasets.md#concatenate-dataset) for details about how to concatenate them and train them together.
+
+### ADE20K
+
+The training and validation set of ADE20K could be download from this [link](http://data.csail.mit.edu/places/ADEchallenge/ADEChallengeData2016.zip).
+We may also download test set from [here](http://data.csail.mit.edu/places/ADEchallenge/release_test.zip).
+
+### Pascal Context
+
+The training and validation set of Pascal Context could be download from [here](http://host.robots.ox.ac.uk/pascal/VOC/voc2010/VOCtrainval_03-May-2010.tar). You may also download test set from [here](http://host.robots.ox.ac.uk:8080/eval/downloads/VOC2010test.tar) after registration.
+
+To split the training and validation set from original dataset, you may download trainval_merged.json from [here](https://codalabuser.blob.core.windows.net/public/trainval_merged.json).
+
+If you would like to use Pascal Context dataset, please install [Detail](https://github.com/zhanghang1989/detail-api) and then run the following command to convert annotations into proper format.
+
+```shell
+python tools/convert_datasets/pascal_context.py data/VOCdevkit data/VOCdevkit/VOC2010/trainval_merged.json
+```
+
+### COCO Stuff 10k
+
+The data could be downloaded [here](http://calvin.inf.ed.ac.uk/wp-content/uploads/data/cocostuffdataset/cocostuff-10k-v1.1.zip) by wget.
+
+For COCO Stuff 10k dataset, please run the following commands to download and convert the dataset.
+
+```shell
+# download
+mkdir coco_stuff10k && cd coco_stuff10k
+wget http://calvin.inf.ed.ac.uk/wp-content/uploads/data/cocostuffdataset/cocostuff-10k-v1.1.zip
+
+# unzip
+unzip cocostuff-10k-v1.1.zip
+
+# --nproc means 8 process for conversion, which could be omitted as well.
+python tools/convert_datasets/coco_stuff10k.py /path/to/coco_stuff10k --nproc 8
+```
+
+By convention, mask labels in `/path/to/coco_stuff164k/annotations/*2014/*_labelTrainIds.png` are used for COCO Stuff 10k training and testing.
+
+### COCO Stuff 164k
+
+For COCO Stuff 164k dataset, please run the following commands to download and convert the augmented dataset.
+
+```shell
+# download
+mkdir coco_stuff164k && cd coco_stuff164k
+wget http://images.cocodataset.org/zips/train2017.zip
+wget http://images.cocodataset.org/zips/val2017.zip
+wget http://calvin.inf.ed.ac.uk/wp-content/uploads/data/cocostuffdataset/stuffthingmaps_trainval2017.zip
+
+# unzip
+unzip train2017.zip -d images/
+unzip val2017.zip -d images/
+unzip stuffthingmaps_trainval2017.zip -d annotations/
+
+# --nproc means 8 process for conversion, which could be omitted as well.
+python tools/convert_datasets/coco_stuff164k.py /path/to/coco_stuff164k --nproc 8
+```
+
+By convention, mask labels in `/path/to/coco_stuff164k/annotations/*2017/*_labelTrainIds.png` are used for COCO Stuff 164k training and testing.
+
+The details of this dataset could be found at [here](https://github.com/nightrome/cocostuff#downloads).
+
+### CHASE DB1
+
+The training and validation set of CHASE DB1 could be download from [here](https://staffnet.kingston.ac.uk/~ku15565/CHASE_DB1/assets/CHASEDB1.zip).
+
+To convert CHASE DB1 dataset to MMSegmentation format, you should run the following command:
+
+```shell
+python tools/convert_datasets/chase_db1.py /path/to/CHASEDB1.zip
+```
+
+The script will make directory structure automatically.
+
+### DRIVE
+
+The training and validation set of DRIVE could be download from [here](https://drive.grand-challenge.org/). Before that, you should register an account. Currently '1st_manual' is not provided officially.
+
+To convert DRIVE dataset to MMSegmentation format, you should run the following command:
+
+```shell
+python tools/convert_datasets/drive.py /path/to/training.zip /path/to/test.zip
+```
+
+The script will make directory structure automatically.
+
+### HRF
+
+First, download [healthy.zip](https://www5.cs.fau.de/fileadmin/research/datasets/fundus-images/healthy.zip), [glaucoma.zip](https://www5.cs.fau.de/fileadmin/research/datasets/fundus-images/glaucoma.zip), [diabetic_retinopathy.zip](https://www5.cs.fau.de/fileadmin/research/datasets/fundus-images/diabetic_retinopathy.zip), [healthy_manualsegm.zip](https://www5.cs.fau.de/fileadmin/research/datasets/fundus-images/healthy_manualsegm.zip), [glaucoma_manualsegm.zip](https://www5.cs.fau.de/fileadmin/research/datasets/fundus-images/glaucoma_manualsegm.zip) and [diabetic_retinopathy_manualsegm.zip](https://www5.cs.fau.de/fileadmin/research/datasets/fundus-images/diabetic_retinopathy_manualsegm.zip).
+
+To convert HRF dataset to MMSegmentation format, you should run the following command:
+
+```shell
+python tools/convert_datasets/hrf.py /path/to/healthy.zip /path/to/healthy_manualsegm.zip /path/to/glaucoma.zip /path/to/glaucoma_manualsegm.zip /path/to/diabetic_retinopathy.zip /path/to/diabetic_retinopathy_manualsegm.zip
+```
+
+The script will make directory structure automatically.
+
+### STARE
+
+First, download [stare-images.tar](http://cecas.clemson.edu/~ahoover/stare/probing/stare-images.tar), [labels-ah.tar](http://cecas.clemson.edu/~ahoover/stare/probing/labels-ah.tar) and [labels-vk.tar](http://cecas.clemson.edu/~ahoover/stare/probing/labels-vk.tar).
+
+To convert STARE dataset to MMSegmentation format, you should run the following command:
+
+```shell
+python tools/convert_datasets/stare.py /path/to/stare-images.tar /path/to/labels-ah.tar /path/to/labels-vk.tar
+```
+
+The script will make directory structure automatically.
+
+### Dark Zurich
+
+Since we only support test models on this dataset, you may only download [the validation set](https://data.vision.ee.ethz.ch/csakarid/shared/GCMA_UIoU/Dark_Zurich_val_anon.zip).
+
+### Nighttime Driving
+
+Since we only support test models on this dataset, you may only download [the test set](http://data.vision.ee.ethz.ch/daid/NighttimeDriving/NighttimeDrivingTest.zip).
+
+### LoveDA
+
+The data could be downloaded from Google Drive [here](https://drive.google.com/drive/folders/1ibYV0qwn4yuuh068Rnc-w4tPi0U0c-ti?usp=sharing).
+
+Or it can be downloaded from [zenodo](https://zenodo.org/record/5706578#.YZvN7SYRXdF), you should run the following command:
+
+```shell
+# Download Train.zip
+wget https://zenodo.org/record/5706578/files/Train.zip
+# Download Val.zip
+wget https://zenodo.org/record/5706578/files/Val.zip
+# Download Test.zip
+wget https://zenodo.org/record/5706578/files/Test.zip
+```
+
+For LoveDA dataset, please run the following command to download and re-organize the dataset.
+
+```shell
+python tools/convert_datasets/loveda.py /path/to/loveDA
+```
+
+Using trained model to predict test set of LoveDA and submit it to server can be found [here](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/inference.md).
+
+More details about LoveDA can be found [here](https://github.com/Junjue-Wang/LoveDA).
+
+### ISPRS Potsdam
+
+The [Potsdam](https://www2.isprs.org/commissions/comm2/wg4/benchmark/2d-sem-label-potsdam/)
+dataset is for urban semantic segmentation used in the 2D Semantic Labeling Contest - Potsdam.
+
+The dataset can be requested at the challenge [homepage](https://www2.isprs.org/commissions/comm2/wg4/benchmark/data-request-form/).
+The '2_Ortho_RGB.zip' and '5_Labels_all_noBoundary.zip' are required.
+
+For Potsdam dataset, please run the following command to download and re-organize the dataset.
+
+```shell
+python tools/convert_datasets/potsdam.py /path/to/potsdam
+```
+
+In our default setting, it will generate 3456 images for training and 2016 images for validation.
+
+### ISPRS Vaihingen
+
+The [Vaihingen](https://www2.isprs.org/commissions/comm2/wg4/benchmark/2d-sem-label-vaihingen/)
+dataset is for urban semantic segmentation used in the 2D Semantic Labeling Contest - Vaihingen.
+
+The dataset can be requested at the challenge [homepage](https://www2.isprs.org/commissions/comm2/wg4/benchmark/data-request-form/).
+The 'ISPRS_semantic_labeling_Vaihingen.zip' and 'ISPRS_semantic_labeling_Vaihingen_ground_truth_eroded_COMPLETE.zip' are required.
+
+For Vaihingen dataset, please run the following command to download and re-organize the dataset.
+
+```shell
+python tools/convert_datasets/vaihingen.py /path/to/vaihingen
+```
+
+In our default setting (`clip_size` =512, `stride_size`=256), it will generate 344 images for training and 398 images for validation.
+
+### iSAID
+The data images could be download from [DOTA-v1.0](https://captain-whu.github.io/DOTA/dataset.html) (train/val/test)
+
+The data annotations could be download from [iSAID](https://captain-whu.github.io/iSAID/dataset.html) (train/val)
+
+The dataset is a Large-scale Dataset for Instance Segmentation (also have segmantic segmentation) in Aerial Images.
+
+You may need to follow the following structure for dataset preparation after downloading iSAID dataset.
+
+```
+│ ├── iSAID
+│ │ ├── train
+│ │ │ ├── images
+│ │ │ │ ├── part1.zip
+│ │ │ │ ├── part2.zip
+│ │ │ │ ├── part3.zip
+│ │ │ ├── Semantic_masks
+│ │ │ │ ├── images.zip
+│ │ ├── val
+│ │ │ ├── images
+│ │ │ │ ├── part1.zip
+│ │ │ ├── Semantic_masks
+│ │ │ │ ├── images.zip
+│ │ ├── test
+│ │ │ ├── images
+│ │ │ │ ├── part1.zip
+│ │ │ │ ├── part2.zip
+```
+
+```shell
+python tools/convert_datasets/isaid.py /path/to/iSAID
+```
+
+In our default setting (`patch_width`=896, `patch_height`=896, `overlap_area`=384), it will generate 33978 images for training and 11644 images for validation.
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/faq.md b/EgoHOS/raw/script/mmsegmentation/docs/en/faq.md
new file mode 100644
index 0000000000000000000000000000000000000000..5a26d88fb11c689ab8470ae1ee983b81058d9410
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/faq.md
@@ -0,0 +1,8 @@
+# Frequently Asked Questions (FAQ)
+
+We list some common troubles faced by many users and their corresponding solutions here. Feel free to enrich the list if you find any frequent issues and have ways to help others to solve them. If the contents here do not cover your issue, please create an issue using the [provided templates](https://github.com/open-mmlab/mmsegmentation/blob/master/.github/ISSUE_TEMPLATE/error-report.md/) and make sure you fill in all required information in the template.
+
+## How to know the number of GPUs needed to train the model
+
+- Infer from the name of the config file of the model. You can refer to the `Config Name Style` part of [Learn about Configs](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/en/tutorials/config.md ). For example, for config file with name `segformer_mit-b0_8x1_1024x1024_160k_cityscapes.py`, `8x1` means training the model corresponding to it needs 8 GPUs, and the batch size of each GPU is 1.
+- Infer from the log file. Open the log file of the model and search `nGPU` in the file. The number of figures following `nGPU` is the number of GPUs needed to train the model. For instance, searching for `nGPU` in the log file yields the record `nGPU 0,1,2,3,4,5,6,7`, which indicates that eight GPUs are needed to train the model.
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/get_started.md b/EgoHOS/raw/script/mmsegmentation/docs/en/get_started.md
new file mode 100644
index 0000000000000000000000000000000000000000..424985b550cf54ebbefcf73599c829ad1b50e986
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/get_started.md
@@ -0,0 +1,265 @@
+## Prerequisites
+
+- Linux or macOS (Windows is in experimental support)
+- Python 3.6+
+- PyTorch 1.3+
+- CUDA 9.2+ (If you build PyTorch from source, CUDA 9.0 is also compatible)
+- GCC 5+
+- [MMCV](https://mmcv.readthedocs.io/en/latest/#installation)
+
+The compatible MMSegmentation and MMCV versions are as below. Please install the correct version of MMCV to avoid installation issues.
+
+| MMSegmentation version | MMCV version | MMClassification version |
+|:----------------------:|:--------------------------:|:------------------------:|
+| master | mmcv-full>=1.4.4, <=1.6.0 | mmcls>=0.20.1, <=1.0.0 |
+| 0.24.1 | mmcv-full>=1.4.4, <=1.6.0 | mmcls>=0.20.1, <=1.0.0 |
+| 0.23.0 | mmcv-full>=1.4.4, <=1.6.0 | mmcls>=0.20.1, <=1.0.0 |
+| 0.22.0 | mmcv-full>=1.4.4, <=1.6.0 | mmcls>=0.20.1, <=1.0.0 |
+| 0.21.1 | mmcv-full>=1.4.4, <=1.6.0 | Not required |
+| 0.20.2 | mmcv-full>=1.3.13, <=1.6.0 | Not required |
+| 0.19.0 | mmcv-full>=1.3.13, <1.3.17 | Not required |
+| 0.18.0 | mmcv-full>=1.3.13, <1.3.17 | Not required |
+| 0.17.0 | mmcv-full>=1.3.7, <1.3.17 | Not required |
+| 0.16.0 | mmcv-full>=1.3.7, <1.3.17 | Not required |
+| 0.15.0 | mmcv-full>=1.3.7, <1.3.17 | Not required |
+| 0.14.1 | mmcv-full>=1.3.7, <1.3.17 | Not required |
+| 0.14.0 | mmcv-full>=1.3.1, <1.3.2 | Not required |
+| 0.13.0 | mmcv-full>=1.3.1, <1.3.2 | Not required |
+| 0.12.0 | mmcv-full>=1.1.4, <1.3.2 | Not required |
+| 0.11.0 | mmcv-full>=1.1.4, <1.3.0 | Not required |
+| 0.10.0 | mmcv-full>=1.1.4, <1.3.0 | Not required |
+| 0.9.0 | mmcv-full>=1.1.4, <1.3.0 | Not required |
+| 0.8.0 | mmcv-full>=1.1.4, <1.2.0 | Not required |
+| 0.7.0 | mmcv-full>=1.1.2, <1.2.0 | Not required |
+| 0.6.0 | mmcv-full>=1.1.2, <1.2.0 | Not required |
+
+:::{note}
+You need to run `pip uninstall mmcv` first if you have mmcv installed.
+If mmcv and mmcv-full are both installed, there will be `ModuleNotFoundError`.
+:::
+
+## Installation
+
+a. Create a conda virtual environment and activate it.
+
+```shell
+conda create -n open-mmlab python=3.10 -y
+conda activate open-mmlab
+```
+
+b. Install PyTorch and torchvision following the [official instructions](https://pytorch.org/).
+Here we use PyTorch 1.11.0 and CUDA 11.3.
+You may also switch to other version by specifying the version number.
+
+```shell
+conda install pytorch=1.11.0 torchvision cudatoolkit=11.3 -c pytorch
+```
+
+c. Install [MMCV](https://mmcv.readthedocs.io/en/latest/) following the [official instructions](https://mmcv.readthedocs.io/en/latest/#installation).
+Either `mmcv` or `mmcv-full` is compatible with MMSegmentation, but for methods like CCNet and PSANet, CUDA ops in `mmcv-full` is required.
+
+**Install mmcv for Linux:**
+
+Install MMCV, we recommend you to install the pre-built mmcv as below.
+
+```shell
+pip install mmcv-full -f https://download.openmmlab.com/mmcv/dist/{cu_version}/{torch_version}/index.html
+```
+
+Please replace ``{cu_version}`` and ``{torch_version}`` in the url to your desired one. mmcv-full is only compiled on
+PyTorch 1.x.0 because the compatibility usually holds between 1.x.0 and 1.x.1. If your PyTorch version is 1.x.1,
+you can install mmcv-full compiled with PyTorch 1.x.0 and it usually works well.
+For example, to install the ``mmcv-full`` with ``CUDA 11.3`` and ``PyTorch 1.11.0``, use the following command:
+
+```shell
+pip install mmcv-full -f https://download.openmmlab.com/mmcv/dist/cu113/torch1.11/index.html
+```
+
+See [here](https://github.com/open-mmlab/mmcv#installation) for different versions of MMCV compatible to different PyTorch and CUDA versions.
+
+Optionally you can choose to compile mmcv from source by the following command
+
+```shell
+git clone https://github.com/open-mmlab/mmcv.git
+cd mmcv
+MMCV_WITH_OPS=1 pip install -e . # package mmcv-full, which contains cuda ops, will be installed after this step
+# OR pip install -e . # package mmcv, which contains no cuda ops, will be installed after this step
+cd ..
+```
+
+**Important:** You need to run `pip uninstall mmcv` first if you have mmcv installed. Because if `mmcv` and `mmcv-full` are both installed, there will be `ModuleNotFoundError`.
+
+
+**Install mmcv for Windows (Experimental):**
+
+For Windows, the installation of MMCV requires native C++ compilers, such as cl.exe. Please add the compiler to %PATH%.
+
+A typical path for cl.exe looks like the following if you have Windows SDK and Visual Studio installed on your computer:
+
+```shell
+C:\Program Files (x86)\Microsoft Visual Studio\2019\Professional\VC\Tools\MSVC\14.26.28801\bin\Hostx86\x64
+```
+
+Or you should download the cl compiler from web and then set up the path.
+
+Then, clone mmcv from github and install mmcv via pip:
+
+```shell
+git clone https://github.com/open-mmlab/mmcv.git
+cd mmcv
+pip install -e .
+```
+
+Or simply:
+
+```shell
+pip install mmcv
+```
+
+Currently, mmcv-full is not supported on Windows.
+
+d. Install MMSegmentation.
+
+```shell
+pip install mmsegmentation # install the latest release
+```
+
+or
+
+```shell
+pip install git+https://github.com/open-mmlab/mmsegmentation.git # install the master branch
+```
+
+Instead, if you would like to install MMSegmentation in `dev` mode, run following
+
+```shell
+git clone https://github.com/open-mmlab/mmsegmentation.git
+cd mmsegmentation
+pip install -e . # or "python setup.py develop"
+```
+
+:::{note}
+
+1. When training or testing models on Windows, please ensure that all the '\\' in paths are replaced with '/'. Add .replace('\\', '/') to your python code wherever path strings occur.
+2. The `version+git_hash` will also be saved in trained models meta, e.g. 0.5.0+c415a2e.
+3. When MMsegmentation is installed on `dev` mode, any local modifications made to the code will take effect without the need to reinstall it.
+4. If you would like to use `opencv-python-headless` instead of `opencv-python`,
+ you can install it before installing MMCV.
+5. Some dependencies are optional. Simply running `pip install -e .` will only install the minimum runtime requirements.
+ To use optional dependencies like `cityscapessripts` either install them manually with `pip install -r requirements/optional.txt` or specify desired extras when calling `pip` (e.g. `pip install -e .[optional]`). Valid keys for the extras field are: `all`, `tests`, `build`, and `optional`.
+:::
+
+### A from-scratch setup script
+
+#### Linux
+
+Here is a full script for setting up mmsegmentation with conda and link the dataset path (supposing that your dataset path is $DATA_ROOT).
+
+```shell
+conda create -n open-mmlab python=3.10 -y
+conda activate open-mmlab
+
+conda install pytorch=1.11.0 torchvision cudatoolkit=11.3 -c pytorch
+pip install mmcv-full -f https://download.openmmlab.com/mmcv/dist/cu113/torch1.11.0/index.html
+git clone https://github.com/open-mmlab/mmsegmentation.git
+cd mmsegmentation
+pip install -e . # or "python setup.py develop"
+
+mkdir data
+ln -s $DATA_ROOT data
+```
+
+#### Windows(Experimental)
+
+Here is a full script for setting up mmsegmentation with conda and link the dataset path (supposing that your dataset path is
+%DATA_ROOT%. Notice: It must be an absolute path).
+
+```shell
+conda create -n open-mmlab python=3.10 -y
+conda activate open-mmlab
+
+conda install pytorch=1.11.0 torchvision cudatoolkit=11.3 -c pytorch
+set PATH=full\path\to\your\cpp\compiler;%PATH%
+pip install mmcv
+
+git clone https://github.com/open-mmlab/mmsegmentation.git
+cd mmsegmentation
+pip install -e . # or "python setup.py develop"
+
+mklink /D data %DATA_ROOT%
+```
+
+#### Developing with multiple MMSegmentation versions
+
+The train and test scripts already modify the `PYTHONPATH` to ensure the script use the MMSegmentation in the current directory.
+
+To use the default MMSegmentation installed in the environment rather than that you are working with, you can remove the following line in those scripts
+
+```shell
+PYTHONPATH="$(dirname $0)/..":$PYTHONPATH
+```
+
+## Verification
+
+To verify whether MMSegmentation and the required environment are installed correctly, we can run sample python codes to initialize a segmentor and inference a demo image:
+
+```python
+from mmseg.apis import inference_segmentor, init_segmentor
+import mmcv
+
+config_file = 'configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py'
+checkpoint_file = 'checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth'
+
+# build the model from a config file and a checkpoint file
+model = init_segmentor(config_file, checkpoint_file, device='cuda:0')
+
+# test a single image and show the results
+img = 'test.jpg' # or img = mmcv.imread(img), which will only load it once
+result = inference_segmentor(model, img)
+# visualize the results in a new window
+model.show_result(img, result, show=True)
+# or save the visualization results to image files
+# you can change the opacity of the painted segmentation map in (0, 1].
+model.show_result(img, result, out_file='result.jpg', opacity=0.5)
+
+# test a video and show the results
+video = mmcv.VideoReader('video.mp4')
+for frame in video:
+ result = inference_segmentor(model, frame)
+ model.show_result(frame, result, wait_time=1)
+```
+
+The above code is supposed to run successfully upon you finish the installation.
+
+We also provide a demo script to test a single image.
+
+```shell
+python demo/image_demo.py ${IMAGE_FILE} ${CONFIG_FILE} ${CHECKPOINT_FILE} [--device ${DEVICE_NAME}] [--palette-thr ${PALETTE}]
+```
+
+Examples:
+
+```shell
+python demo/image_demo.py demo/demo.png configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py \
+ checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth --device cuda:0 --palette cityscapes
+```
+
+A notebook demo can be found in [demo/inference_demo.ipynb](../demo/inference_demo.ipynb).
+
+Now we also provide a demo script to test a single video.
+
+```shell
+wget -O demo/demo.mp4 https://user-images.githubusercontent.com/22089207/144212749-44411ef4-b564-4b37-96d4-04bedec629ab.mp4
+python demo/video_demo.py ${VIDEO_FILE} ${CONFIG_FILE} ${CHECKPOINT_FILE} [--device ${DEVICE_NAME}] [--palette-thr ${PALETTE}] \
+ [--show] [--show-wait-time {SHOW_WAIT_TIME}] [--output-file {OUTPUT_FILE}] [--output-fps {OUTPUT_FPS}] \
+ [--output-height {OUTPUT_HEIGHT}] [--output-width {OUTPUT_WIDTH}] [--opacity {OPACITY}]
+```
+
+Examples:
+
+```shell
+wget -O demo/demo.mp4 https://user-images.githubusercontent.com/22089207/144212749-44411ef4-b564-4b37-96d4-04bedec629ab.mp4
+python demo/video_demo.py demo/demo.mp4 configs/cgnet/cgnet_680x680_60k_cityscapes.py \
+ checkpoints/cgnet_680x680_60k_cityscapes_20201101_110253-4c0b2f2d.pth \
+ --device cuda:0 --palette cityscapes --show
+```
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/index.rst b/EgoHOS/raw/script/mmsegmentation/docs/en/index.rst
new file mode 100644
index 0000000000000000000000000000000000000000..ae009bf4411e3c81e7f9c7c5999cb6b72c8f45f6
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/index.rst
@@ -0,0 +1,63 @@
+Welcome to MMSegmentation's documentation!
+=======================================
+
+.. toctree::
+ :maxdepth: 2
+ :caption: Get Started
+
+ get_started.md
+
+.. toctree::
+ :maxdepth: 1
+ :caption: Dataset Preparation
+
+ dataset_prepare.md
+
+.. toctree::
+ :maxdepth: 1
+ :caption: Model Zoo
+
+ model_zoo.md
+ modelzoo_statistics.md
+
+.. toctree::
+ :maxdepth: 2
+ :caption: Quick Run
+
+ train.md
+ inference.md
+
+.. toctree::
+ :maxdepth: 2
+ :caption: Tutorials
+
+ tutorials/index.rst
+
+.. toctree::
+ :maxdepth: 2
+ :caption: Useful Tools and Scripts
+
+ useful_tools.md
+
+.. toctree::
+ :maxdepth: 2
+ :caption: Notes
+
+ changelog.md
+ faq.md
+
+.. toctree::
+ :caption: Switch Language
+
+ switch_language.md
+
+.. toctree::
+ :caption: API Reference
+
+ api.rst
+
+Indices and tables
+==================
+
+* :ref:`genindex`
+* :ref:`search`
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/inference.md b/EgoHOS/raw/script/mmsegmentation/docs/en/inference.md
new file mode 100644
index 0000000000000000000000000000000000000000..1fc94ef9e49709727d17dc91b43d2f02b9e28ae6
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/inference.md
@@ -0,0 +1,131 @@
+## Inference with pretrained models
+
+We provide testing scripts to evaluate a whole dataset (Cityscapes, PASCAL VOC, ADE20k, etc.),
+and also some high-level apis for easier integration to other projects.
+
+### Test a dataset
+
+- single GPU
+- CPU
+- single node multiple GPU
+- multiple node
+
+You can use the following commands to test a dataset.
+
+```shell
+# single-gpu testing
+python tools/test.py ${CONFIG_FILE} ${CHECKPOINT_FILE} [--out ${RESULT_FILE}] [--eval ${EVAL_METRICS}] [--show]
+
+# CPU: If GPU unavailable, directly running single-gpu testing command above
+# CPU: If GPU available, disable GPUs and run single-gpu testing script
+export CUDA_VISIBLE_DEVICES=-1
+python tools/test.py ${CONFIG_FILE} ${CHECKPOINT_FILE} [--out ${RESULT_FILE}] [--eval ${EVAL_METRICS}] [--show]
+
+# multi-gpu testing
+./tools/dist_test.sh ${CONFIG_FILE} ${CHECKPOINT_FILE} ${GPU_NUM} [--out ${RESULT_FILE}] [--eval ${EVAL_METRICS}]
+```
+
+Optional arguments:
+
+- `RESULT_FILE`: Filename of the output results in pickle format. If not specified, the results will not be saved to a file. (After mmseg v0.17, the output results become pre-evaluation results or format result paths)
+- `EVAL_METRICS`: Items to be evaluated on the results. Allowed values depend on the dataset, e.g., `mIoU` is available for all dataset. Cityscapes could be evaluated by `cityscapes` as well as standard `mIoU` metrics.
+- `--show`: If specified, segmentation results will be plotted on the images and shown in a new window. It is only applicable to single GPU testing and used for debugging and visualization. Please make sure that GUI is available in your environment, otherwise you may encounter the error like `cannot connect to X server`.
+- `--show-dir`: If specified, segmentation results will be plotted on the images and saved to the specified directory. It is only applicable to single GPU testing and used for debugging and visualization. You do NOT need a GUI available in your environment for using this option.
+- `--eval-options`: Optional parameters for `dataset.format_results` and `dataset.evaluate` during evaluation. When `efficient_test=True`, it will save intermediate results to local files to save CPU memory. Make sure that you have enough local storage space (more than 20GB). (`efficient_test` argument does not have effect after mmseg v0.17, we use a progressive mode to evaluation and format results which can largely save memory cost and evaluation time.)
+
+Examples:
+
+Assume that you have already downloaded the checkpoints to the directory `checkpoints/`.
+
+1. Test PSPNet and visualize the results. Press any key for the next image.
+
+ ```shell
+ python tools/test.py configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py \
+ checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth \
+ --show
+ ```
+
+2. Test PSPNet and save the painted images for latter visualization.
+
+ ```shell
+ python tools/test.py configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py \
+ checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth \
+ --show-dir psp_r50_512x1024_40ki_cityscapes_results
+ ```
+
+3. Test PSPNet on PASCAL VOC (without saving the test results) and evaluate the mIoU.
+
+ ```shell
+ python tools/test.py configs/pspnet/pspnet_r50-d8_512x1024_20k_voc12aug.py \
+ checkpoints/pspnet_r50-d8_512x1024_20k_voc12aug_20200605_003338-c57ef100.pth \
+ --eval mAP
+ ```
+
+4. Test PSPNet with 4 GPUs, and evaluate the standard mIoU and cityscapes metric.
+
+ ```shell
+ ./tools/dist_test.sh configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py \
+ checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth \
+ 4 --out results.pkl --eval mIoU cityscapes
+ ```
+
+ :::{note}
+ There is some gap (~0.1%) between cityscapes mIoU and our mIoU. The reason is that cityscapes average each class with class size by default.
+ We use the simple version without average for all datasets.
+:::
+
+5. Test PSPNet on cityscapes test split with 4 GPUs, and generate the png files to be submit to the official evaluation server.
+
+ First, add following to config file `configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py`,
+
+ ```python
+ data = dict(
+ test=dict(
+ img_dir='leftImg8bit/test',
+ ann_dir='gtFine/test'))
+ ```
+
+ Then run test.
+
+ ```shell
+ ./tools/dist_test.sh configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py \
+ checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth \
+ 4 --format-only --eval-options "imgfile_prefix=./pspnet_test_results"
+ ```
+
+ You will get png files under `./pspnet_test_results` directory.
+ You may run `zip -r results.zip pspnet_test_results/` and submit the zip file to [evaluation server](https://www.cityscapes-dataset.com/submit/).
+
+6. CPU memory efficient test DeeplabV3+ on Cityscapes (without saving the test results) and evaluate the mIoU.
+
+ ```shell
+ python tools/test.py \
+ configs/deeplabv3plus/deeplabv3plus_r18-d8_512x1024_80k_cityscapes.py \
+ deeplabv3plus_r18-d8_512x1024_80k_cityscapes_20201226_080942-cff257fe.pth \
+ --eval-options efficient_test=True \
+ --eval mIoU
+ ```
+
+ Using ```pmap``` to view CPU memory footprint, it used 2.25GB CPU memory with ```efficient_test=True``` and 11.06GB CPU memory with ```efficient_test=False``` . This optional parameter can save a lot of memory. (After mmseg v0.17, efficient_test has not effect and we use a progressive mode to evaluation and format results efficiently by default.)
+
+7. Test PSPNet on LoveDA test split with 1 GPU, and generate the png files to be submit to the official evaluation server.
+
+ First, add following to config file `configs/pspnet/pspnet_r50-d8_512x512_80k_loveda.py`,
+
+ ```python
+ data = dict(
+ test=dict(
+ img_dir='img_dir/test',
+ ann_dir='ann_dir/test'))
+ ```
+
+ Then run test.
+
+ ```shell
+ python ./tools/test.py configs/pspnet/pspnet_r50-d8_512x512_80k_loveda.py \
+ checkpoints/pspnet_r50-d8_512x512_80k_loveda_20211104_155728-88610f9f.pth \
+ --format-only --eval-options "imgfile_prefix=./pspnet_test_results"
+ ```
+
+ You will get png files under `./pspnet_test_results` directory.
+ You may run `zip -r -j Results.zip pspnet_test_results/` and submit the zip file to [evaluation server](https://codalab.lisn.upsaclay.fr/competitions/421).
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/make.bat b/EgoHOS/raw/script/mmsegmentation/docs/en/make.bat
new file mode 100644
index 0000000000000000000000000000000000000000..922152e96a04a242e6fc40f124261d74890617d8
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/make.bat
@@ -0,0 +1,35 @@
+@ECHO OFF
+
+pushd %~dp0
+
+REM Command file for Sphinx documentation
+
+if "%SPHINXBUILD%" == "" (
+ set SPHINXBUILD=sphinx-build
+)
+set SOURCEDIR=.
+set BUILDDIR=_build
+
+if "%1" == "" goto help
+
+%SPHINXBUILD% >NUL 2>NUL
+if errorlevel 9009 (
+ echo.
+ echo.The 'sphinx-build' command was not found. Make sure you have Sphinx
+ echo.installed, then set the SPHINXBUILD environment variable to point
+ echo.to the full path of the 'sphinx-build' executable. Alternatively you
+ echo.may add the Sphinx directory to PATH.
+ echo.
+ echo.If you don't have Sphinx installed, grab it from
+ echo.http://sphinx-doc.org/
+ exit /b 1
+)
+
+%SPHINXBUILD% -M %1 %SOURCEDIR% %BUILDDIR% %SPHINXOPTS% %O%
+goto end
+
+:help
+%SPHINXBUILD% -M help %SOURCEDIR% %BUILDDIR% %SPHINXOPTS% %O%
+
+:end
+popd
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/model_zoo.md b/EgoHOS/raw/script/mmsegmentation/docs/en/model_zoo.md
new file mode 100644
index 0000000000000000000000000000000000000000..e6498ad4a15920c34c92a77fc2e8295c4b0758c0
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/model_zoo.md
@@ -0,0 +1,181 @@
+# Benchmark and Model Zoo
+
+## Common settings
+
+* We use distributed training with 4 GPUs by default.
+* All pytorch-style pretrained backbones on ImageNet are train by ourselves, with the same procedure in the [paper](https://arxiv.org/pdf/1812.01187.pdf).
+ Our ResNet style backbone are based on ResNetV1c variant, where the 7x7 conv in the input stem is replaced with three 3x3 convs.
+* For the consistency across different hardwares, we report the GPU memory as the maximum value of `torch.cuda.max_memory_allocated()` for all 4 GPUs with `torch.backends.cudnn.benchmark=False`.
+ Note that this value is usually less than what `nvidia-smi` shows.
+* We report the inference time as the total time of network forwarding and post-processing, excluding the data loading time.
+ Results are obtained with the script `tools/benchmark.py` which computes the average time on 200 images with `torch.backends.cudnn.benchmark=False`.
+* There are two inference modes in this framework.
+
+ * `slide` mode: The `test_cfg` will be like `dict(mode='slide', crop_size=(769, 769), stride=(513, 513))`.
+
+ In this mode, multiple patches will be cropped from input image, passed into network individually.
+ The crop size and stride between patches are specified by `crop_size` and `stride`.
+ The overlapping area will be merged by average
+
+ * `whole` mode: The `test_cfg` will be like `dict(mode='whole')`.
+
+ In this mode, the whole imaged will be passed into network directly.
+
+ By default, we use `slide` inference for 769x769 trained model, `whole` inference for the rest.
+* For input size of 8x+1 (e.g. 769), `align_corner=True` is adopted as a traditional practice.
+ Otherwise, for input size of 8x (e.g. 512, 1024), `align_corner=False` is adopted.
+
+## Baselines
+
+### FCN
+
+Please refer to [FCN](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/fcn) for details.
+
+### PSPNet
+
+Please refer to [PSPNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/pspnet) for details.
+
+### DeepLabV3
+
+Please refer to [DeepLabV3](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3) for details.
+
+### PSANet
+
+Please refer to [PSANet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/psanet) for details.
+
+### DeepLabV3+
+
+Please refer to [DeepLabV3+](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3plus) for details.
+
+### UPerNet
+
+Please refer to [UPerNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/upernet) for details.
+
+### NonLocal Net
+
+Please refer to [NonLocal Net](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/nonlocal_net) for details.
+
+### EncNet
+
+Please refer to [EncNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/encnet) for details.
+
+### CCNet
+
+Please refer to [CCNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet) for details.
+
+### DANet
+
+Please refer to [DANet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet) for details.
+
+### APCNet
+
+Please refer to [APCNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/apcnet) for details.
+
+### HRNet
+
+Please refer to [HRNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/hrnet) for details.
+
+### GCNet
+
+Please refer to [GCNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/gcnet) for details.
+
+### DMNet
+
+Please refer to [DMNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/dmnet) for details.
+
+### ANN
+
+Please refer to [ANN](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann) for details.
+
+### OCRNet
+
+Please refer to [OCRNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ocrnet) for details.
+
+### Fast-SCNN
+
+Please refer to [Fast-SCNN](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/fastscnn) for details.
+
+### ResNeSt
+
+Please refer to [ResNeSt](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/resnest) for details.
+
+### Semantic FPN
+
+Please refer to [Semantic FPN](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/sem_fpn) for details.
+
+### PointRend
+
+Please refer to [PointRend](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/point_rend) for details.
+
+### MobileNetV2
+
+Please refer to [MobileNetV2](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/mobilenet_v2) for details.
+
+### MobileNetV3
+
+Please refer to [MobileNetV3](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/mobilenet_v3) for details.
+
+### EMANet
+
+Please refer to [EMANet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/emanet) for details.
+
+### DNLNet
+
+Please refer to [DNLNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/dnlnet) for details.
+
+### CGNet
+
+Please refer to [CGNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/cgnet) for details.
+
+### Mixed Precision (FP16) Training
+
+Please refer [Mixed Precision (FP16) Training on BiSeNetV2](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/bisenetv2/bisenetv2_fcn_fp16_4x4_1024x1024_160k_cityscapes.py) for details.
+
+### U-Net
+
+Please refer to [U-Net](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/unet/README.md) for details.
+
+### ViT
+
+Please refer to [ViT](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/vit/README.md) for details.
+
+### Swin
+
+Please refer to [Swin](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/swin/README.md) for details.
+
+### SETR
+
+Please refer to [SETR](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/setr/README.md) for details.
+
+## Speed benchmark
+
+### Hardware
+
+* 8 NVIDIA Tesla V100 (32G) GPUs
+* Intel(R) Xeon(R) Gold 6148 CPU @ 2.40GHz
+
+### Software environment
+
+* Python 3.7
+* PyTorch 1.5
+* CUDA 10.1
+* CUDNN 7.6.03
+* NCCL 2.4.08
+
+### Training speed
+
+For fair comparison, we benchmark all implementations with ResNet-101V1c.
+The input size is fixed to 1024x512 with batch size 2.
+
+The training speed is reported as followed, in terms of second per iter (s/iter). The lower, the better.
+
+| Implementation | PSPNet (s/iter) | DeepLabV3+ (s/iter) |
+|----------------|-----------------|---------------------|
+| [MMSegmentation](https://github.com/open-mmlab/mmsegmentation) | **0.83** | **0.85** |
+| [SegmenTron](https://github.com/LikeLy-Journey/SegmenTron) | 0.84 | 0.85 |
+| [CASILVision](https://github.com/CSAILVision/semantic-segmentation-pytorch) | 1.15 | N/A |
+| [vedaseg](https://github.com/Media-Smart/vedaseg) | 0.95 | 1.25 |
+
+:::{note}
+The output stride of DeepLabV3+ is 8.
+:::
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/stat.py b/EgoHOS/raw/script/mmsegmentation/docs/en/stat.py
new file mode 100644
index 0000000000000000000000000000000000000000..1398a706f3ec81c2adb0e96faa7fb7dd3f8274bb
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/stat.py
@@ -0,0 +1,65 @@
+#!/usr/bin/env python
+# Copyright (c) OpenMMLab. All rights reserved.
+import functools as func
+import glob
+import os.path as osp
+import re
+
+import numpy as np
+
+url_prefix = 'https://github.com/open-mmlab/mmsegmentation/blob/master/'
+
+files = sorted(glob.glob('../../configs/*/README.md'))
+
+stats = []
+titles = []
+num_ckpts = 0
+
+for f in files:
+ url = osp.dirname(f.replace('../../', url_prefix))
+
+ with open(f, 'r') as content_file:
+ content = content_file.read()
+
+ title = content.split('\n')[0].replace('#', '').strip()
+ ckpts = set(x.lower().strip()
+ for x in re.findall(r'https?://download.*\.pth', content)
+ if 'mmsegmentation' in x)
+ if len(ckpts) == 0:
+ continue
+
+ _papertype = [
+ x for x in re.findall(r'', content)
+ ]
+ assert len(_papertype) > 0
+ papertype = _papertype[0]
+
+ paper = set([(papertype, title)])
+
+ titles.append(title)
+ num_ckpts += len(ckpts)
+ statsmsg = f"""
+\t* [{papertype}] [{title}]({url}) ({len(ckpts)} ckpts)
+"""
+ stats.append((paper, ckpts, statsmsg))
+
+allpapers = func.reduce(lambda a, b: a.union(b), [p for p, _, _ in stats])
+msglist = '\n'.join(x for _, _, x in stats)
+
+papertypes, papercounts = np.unique([t for t, _ in allpapers],
+ return_counts=True)
+countstr = '\n'.join(
+ [f' - {t}: {c}' for t, c in zip(papertypes, papercounts)])
+
+modelzoo = f"""
+# Model Zoo Statistics
+
+* Number of papers: {len(set(titles))}
+{countstr}
+
+* Number of checkpoints: {num_ckpts}
+{msglist}
+"""
+
+with open('modelzoo_statistics.md', 'w') as f:
+ f.write(modelzoo)
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/switch_language.md b/EgoHOS/raw/script/mmsegmentation/docs/en/switch_language.md
new file mode 100644
index 0000000000000000000000000000000000000000..f58efc42be0d4c352db5d6af3c9ffef675a32e33
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/switch_language.md
@@ -0,0 +1,3 @@
+## English
+
+## 简体中文
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/train.md b/EgoHOS/raw/script/mmsegmentation/docs/en/train.md
new file mode 100644
index 0000000000000000000000000000000000000000..7c1c41184812642b560ba646723baab43011445a
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/train.md
@@ -0,0 +1,169 @@
+## Train a model
+
+MMSegmentation implements distributed training and non-distributed training,
+which uses `MMDistributedDataParallel` and `MMDataParallel` respectively.
+
+All outputs (log files and checkpoints) will be saved to the working directory,
+which is specified by `work_dir` in the config file.
+
+By default we evaluate the model on the validation set after some iterations, you can change the evaluation interval by adding the interval argument in the training config.
+
+```python
+evaluation = dict(interval=4000) # This evaluate the model per 4000 iterations.
+```
+
+**\*Important\***: The default learning rate in config files is for 4 GPUs and 2 img/gpu (batch size = 4x2 = 8).
+Equivalently, you may also use 8 GPUs and 1 imgs/gpu since all models using cross-GPU SyncBN.
+
+To trade speed with GPU memory, you may pass in `--cfg-options model.backbone.with_cp=True` to enable checkpoint in backbone.
+
+### Train on a single machine
+
+#### Train with a single GPU
+
+official support:
+
+```shell
+sh tools/dist_train.sh ${CONFIG_FILE} 1 [optional arguments]
+```
+
+experimental support (Convert SyncBN to BN):
+
+```shell
+python tools/train.py ${CONFIG_FILE} [optional arguments]
+```
+
+If you want to specify the working directory in the command, you can add an argument `--work-dir ${YOUR_WORK_DIR}`.
+
+#### Train with CPU
+
+The process of training on the CPU is consistent with single GPU training if machine does not have GPU. If it has GPUs but not wanting to use it, we just need to disable GPUs before the training process.
+
+```shell
+export CUDA_VISIBLE_DEVICES=-1
+```
+
+And then run the script [above](#train-with-a-single-gpu).
+
+```{warning}
+The process of training on the CPU is consistent with single GPU training. We just need to disable GPUs before the training process.
+```
+
+#### Train with multiple GPUs
+
+```shell
+sh tools/dist_train.sh ${CONFIG_FILE} ${GPU_NUM} [optional arguments]
+```
+
+Optional arguments are:
+
+- `--no-validate` (**not suggested**): By default, the codebase will perform evaluation at every k iterations during the training. To disable this behavior, use `--no-validate`.
+- `--work-dir ${WORK_DIR}`: Override the working directory specified in the config file.
+- `--resume-from ${CHECKPOINT_FILE}`: Resume from a previous checkpoint file (to continue the training process).
+- `--load-from ${CHECKPOINT_FILE}`: Load weights from a checkpoint file (to start finetuning for another task).
+- `--deterministic`: Switch on "deterministic" mode which slows down training but the results are reproducible.
+
+Difference between `resume-from` and `load-from`:
+
+- `resume-from` loads both the model weights and optimizer state including the iteration number.
+- `load-from` loads only the model weights, starts the training from iteration 0.
+
+An example:
+
+```shell
+# checkpoints and logs saved in WORK_DIR=work_dirs/pspnet_r50-d8_512x512_80k_ade20k/
+# If work_dir is not set, it will be generated automatically.
+sh tools/dist_train.sh configs/pspnet/pspnet_r50-d8_512x512_80k_ade20k.py 8 --work_dir work_dirs/pspnet_r50-d8_512x512_80k_ade20k/ --deterministic
+```
+
+**Note**: During training, checkpoints and logs are saved in the same folder structure as the config file under `work_dirs/`. Custom work directory is not recommended since evaluation scripts infer work directories from the config file name. If you want to save your weights somewhere else, please use symlink, for example:
+
+```shell
+ln -s ${YOUR_WORK_DIRS} ${MMSEG}/work_dirs
+```
+
+#### Launch multiple jobs on a single machine
+
+If you launch multiple jobs on a single machine, e.g., 2 jobs of 4-GPU training on a machine with 8 GPUs, you need to specify different ports (29500 by default) for each job to avoid communication conflict. Otherwise, there will be error message saying `RuntimeError: Address already in use`.
+
+If you use `dist_train.sh` to launch training jobs, you can set the port in commands with environment variable `PORT`.
+
+```shell
+CUDA_VISIBLE_DEVICES=0,1,2,3 PORT=29500 sh tools/dist_train.sh ${CONFIG_FILE} 4
+CUDA_VISIBLE_DEVICES=4,5,6,7 PORT=29501 sh tools/dist_train.sh ${CONFIG_FILE} 4
+```
+
+### Train with multiple machines
+
+If you launch with multiple machines simply connected with ethernet, you can simply run following commands:
+
+On the first machine:
+
+```shell
+NNODES=2 NODE_RANK=0 PORT=$MASTER_PORT MASTER_ADDR=$MASTER_ADDR sh tools/dist_train.sh $CONFIG $GPUS
+```
+
+On the second machine:
+
+```shell
+NNODES=2 NODE_RANK=1 PORT=$MASTER_PORT MASTER_ADDR=$MASTER_ADDR sh tools/dist_train.sh $CONFIG $GPUS
+```
+
+Usually it is slow if you do not have high speed networking like InfiniBand.
+
+### Manage jobs with Slurm
+
+Slurm is a good job scheduling system for computing clusters. On a cluster managed by Slurm, you can use slurm_train.sh to spawn training jobs. It supports both single-node and multi-node training.
+
+Train with multiple machines:
+
+```shell
+[GPUS=${GPUS}] sh tools/slurm_train.sh ${PARTITION} ${JOB_NAME} ${CONFIG_FILE} --work-dir ${WORK_DIR}
+```
+
+Here is an example of using 16 GPUs to train PSPNet on the dev partition.
+
+```shell
+GPUS=16 sh tools/slurm_train.sh dev pspr50 configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py work_dirs/pspnet_r50-d8_512x1024_40k_cityscapes/
+```
+
+When using 'slurm_train.sh' to start multiple tasks on a node, different ports need to be specified. Three settings are provided:
+
+Option 1:
+
+In `config1.py`:
+
+```python
+dist_params = dict(backend='nccl', port=29500)
+```
+
+In `config2.py`:
+
+```python
+dist_params = dict(backend='nccl', port=29501)
+```
+
+Then you can launch two jobs with config1.py and config2.py.
+
+```shell
+CUDA_VISIBLE_DEVICES=0,1,2,3 GPUS=4 sh tools/slurm_train.sh ${PARTITION} ${JOB_NAME} config1.py tmp_work_dir_1
+CUDA_VISIBLE_DEVICES=4,5,6,7 GPUS=4 sh tools/slurm_train.sh ${PARTITION} ${JOB_NAME} config2.py tmp_work_dir_2
+```
+
+Option 2:
+
+You can set different communication ports without the need to modify the configuration file, but have to set the `cfg-options` to overwrite the default port in configuration file.
+
+```shell
+CUDA_VISIBLE_DEVICES=0,1,2,3 GPUS=4 sh tools/slurm_train.sh ${PARTITION} ${JOB_NAME} config1.py tmp_work_dir_1 --cfg-options dist_params.port=29500
+CUDA_VISIBLE_DEVICES=4,5,6,7 GPUS=4 sh tools/slurm_train.sh ${PARTITION} ${JOB_NAME} config2.py tmp_work_dir_2 --cfg-options dist_params.port=29501
+```
+
+Option 3:
+
+You can set the port in the command using the environment variable 'MASTER_PORT':
+
+```shell
+CUDA_VISIBLE_DEVICES=0,1,2,3 GPUS=4 MASTER_PORT=29500 sh tools/slurm_train.sh ${PARTITION} ${JOB_NAME} config1.py tmp_work_dir_1
+CUDA_VISIBLE_DEVICES=4,5,6,7 GPUS=4 MASTER_PORT=29501 sh tools/slurm_train.sh ${PARTITION} ${JOB_NAME} config2.py tmp_work_dir_2
+```
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/config.md b/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/config.md
new file mode 100644
index 0000000000000000000000000000000000000000..2db54696091d72924840a266d26994acd404a7c4
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/config.md
@@ -0,0 +1,381 @@
+# Tutorial 1: Learn about Configs
+
+We incorporate modular and inheritance design into our config system, which is convenient to conduct various experiments.
+If you wish to inspect the config file, you may run `python tools/print_config.py /PATH/TO/CONFIG` to see the complete config.
+You may also pass `--cfg-options xxx.yyy=zzz` to see updated config.
+
+## Config File Structure
+
+There are 4 basic component types under `config/_base_`, dataset, model, schedule, default_runtime.
+Many methods could be easily constructed with one of each like DeepLabV3, PSPNet.
+The configs that are composed by components from `_base_` are called _primitive_.
+
+For all configs under the same folder, it is recommended to have only **one** _primitive_ config. All other configs should inherit from the _primitive_ config. In this way, the maximum of inheritance level is 3.
+
+For easy understanding, we recommend contributors to inherit from existing methods.
+For example, if some modification is made base on DeepLabV3, user may first inherit the basic DeepLabV3 structure by specifying `_base_ = ../deeplabv3/deeplabv3_r50_512x1024_40ki_cityscapes.py`, then modify the necessary fields in the config files.
+
+If you are building an entirely new method that does not share the structure with any of the existing methods, you may create a folder `xxxnet` under `configs`,
+
+Please refer to [mmcv](https://mmcv.readthedocs.io/en/latest/understand_mmcv/config.html) for detailed documentation.
+
+## Config Name Style
+
+We follow the below style to name config files. Contributors are advised to follow the same style.
+
+```
+{model}_{backbone}_[misc]_[gpu x batch_per_gpu]_{resolution}_{iterations}_{dataset}
+```
+
+`{xxx}` is required field and `[yyy]` is optional.
+
+- `{model}`: model type like `psp`, `deeplabv3`, etc.
+- `{backbone}`: backbone type like `r50` (ResNet-50), `x101` (ResNeXt-101).
+- `[misc]`: miscellaneous setting/plugins of model, e.g. `dconv`, `gcb`, `attention`, `mstrain`.
+- `[gpu x batch_per_gpu]`: GPUs and samples per GPU, `8x2` is used by default.
+- `{iterations}`: number of training iterations like `160k`.
+- `{dataset}`: dataset like `cityscapes`, `voc12aug`, `ade`.
+
+## An Example of PSPNet
+
+To help the users have a basic idea of a complete config and the modules in a modern semantic segmentation system,
+we make brief comments on the config of PSPNet using ResNet50V1c as the following.
+For more detailed usage and the corresponding alternative for each module, please refer to the API documentation.
+
+```python
+norm_cfg = dict(type='SyncBN', requires_grad=True) # Segmentation usually uses SyncBN
+model = dict(
+ type='EncoderDecoder', # Name of segmentor
+ pretrained='open-mmlab://resnet50_v1c', # The ImageNet pretrained backbone to be loaded
+ backbone=dict(
+ type='ResNetV1c', # The type of backbone. Please refer to mmseg/models/backbones/resnet.py for details.
+ depth=50, # Depth of backbone. Normally 50, 101 are used.
+ num_stages=4, # Number of stages of backbone.
+ out_indices=(0, 1, 2, 3), # The index of output feature maps produced in each stages.
+ dilations=(1, 1, 2, 4), # The dilation rate of each layer.
+ strides=(1, 2, 1, 1), # The stride of each layer.
+ norm_cfg=dict( # The configuration of norm layer.
+ type='SyncBN', # Type of norm layer. Usually it is SyncBN.
+ requires_grad=True), # Whether to train the gamma and beta in norm
+ norm_eval=False, # Whether to freeze the statistics in BN
+ style='pytorch', # The style of backbone, 'pytorch' means that stride 2 layers are in 3x3 conv, 'caffe' means stride 2 layers are in 1x1 convs.
+ contract_dilation=True), # When dilation > 1, whether contract first layer of dilation.
+ decode_head=dict(
+ type='PSPHead', # Type of decode head. Please refer to mmseg/models/decode_heads for available options.
+ in_channels=2048, # Input channel of decode head.
+ in_index=3, # The index of feature map to select.
+ channels=512, # The intermediate channels of decode head.
+ pool_scales=(1, 2, 3, 6), # The avg pooling scales of PSPHead. Please refer to paper for details.
+ dropout_ratio=0.1, # The dropout ratio before final classification layer.
+ num_classes=19, # Number of segmentation class. Usually 19 for cityscapes, 21 for VOC, 150 for ADE20k.
+ norm_cfg=dict(type='SyncBN', requires_grad=True), # The configuration of norm layer.
+ align_corners=False, # The align_corners argument for resize in decoding.
+ loss_decode=dict( # Config of loss function for the decode_head.
+ type='CrossEntropyLoss', # Type of loss used for segmentation.
+ use_sigmoid=False, # Whether use sigmoid activation for segmentation.
+ loss_weight=1.0)), # Loss weight of decode head.
+ auxiliary_head=dict(
+ type='FCNHead', # Type of auxiliary head. Please refer to mmseg/models/decode_heads for available options.
+ in_channels=1024, # Input channel of auxiliary head.
+ in_index=2, # The index of feature map to select.
+ channels=256, # The intermediate channels of decode head.
+ num_convs=1, # Number of convs in FCNHead. It is usually 1 in auxiliary head.
+ concat_input=False, # Whether concat output of convs with input before classification layer.
+ dropout_ratio=0.1, # The dropout ratio before final classification layer.
+ num_classes=19, # Number of segmentation class. Usually 19 for cityscapes, 21 for VOC, 150 for ADE20k.
+ norm_cfg=dict(type='SyncBN', requires_grad=True), # The configuration of norm layer.
+ align_corners=False, # The align_corners argument for resize in decoding.
+ loss_decode=dict( # Config of loss function for the decode_head.
+ type='CrossEntropyLoss', # Type of loss used for segmentation.
+ use_sigmoid=False, # Whether use sigmoid activation for segmentation.
+ loss_weight=0.4))) # Loss weight of auxiliary head, which is usually 0.4 of decode head.
+train_cfg = dict() # train_cfg is just a place holder for now.
+test_cfg = dict(mode='whole') # The test mode, options are 'whole' and 'sliding'. 'whole': whole image fully-convolutional test. 'sliding': sliding crop window on the image.
+dataset_type = 'CityscapesDataset' # Dataset type, this will be used to define the dataset.
+data_root = 'data/cityscapes/' # Root path of data.
+img_norm_cfg = dict( # Image normalization config to normalize the input images.
+ mean=[123.675, 116.28, 103.53], # Mean values used to pre-training the pre-trained backbone models.
+ std=[58.395, 57.12, 57.375], # Standard variance used to pre-training the pre-trained backbone models.
+ to_rgb=True) # The channel orders of image used to pre-training the pre-trained backbone models.
+crop_size = (512, 1024) # The crop size during training.
+train_pipeline = [ # Training pipeline.
+ dict(type='LoadImageFromFile'), # First pipeline to load images from file path.
+ dict(type='LoadAnnotations'), # Second pipeline to load annotations for current image.
+ dict(type='Resize', # Augmentation pipeline that resize the images and their annotations.
+ img_scale=(2048, 1024), # The largest scale of image.
+ ratio_range=(0.5, 2.0)), # The augmented scale range as ratio.
+ dict(type='RandomCrop', # Augmentation pipeline that randomly crop a patch from current image.
+ crop_size=(512, 1024), # The crop size of patch.
+ cat_max_ratio=0.75), # The max area ratio that could be occupied by single category.
+ dict(
+ type='RandomFlip', # Augmentation pipeline that flip the images and their annotations
+ flip_ratio=0.5), # The ratio or probability to flip
+ dict(type='PhotoMetricDistortion'), # Augmentation pipeline that distort current image with several photo metric methods.
+ dict(
+ type='Normalize', # Augmentation pipeline that normalize the input images
+ mean=[123.675, 116.28, 103.53], # These keys are the same of img_norm_cfg since the
+ std=[58.395, 57.12, 57.375], # keys of img_norm_cfg are used here as arguments
+ to_rgb=True),
+ dict(type='Pad', # Augmentation pipeline that pad the image to specified size.
+ size=(512, 1024), # The output size of padding.
+ pad_val=0, # The padding value for image.
+ seg_pad_val=255), # The padding value of 'gt_semantic_seg'.
+ dict(type='DefaultFormatBundle'), # Default format bundle to gather data in the pipeline
+ dict(type='Collect', # Pipeline that decides which keys in the data should be passed to the segmentor
+ keys=['img', 'gt_semantic_seg'])
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'), # First pipeline to load images from file path
+ dict(
+ type='MultiScaleFlipAug', # An encapsulation that encapsulates the test time augmentations
+ img_scale=(2048, 1024), # Decides the largest scale for testing, used for the Resize pipeline
+ flip=False, # Whether to flip images during testing
+ transforms=[
+ dict(type='Resize', # Use resize augmentation
+ keep_ratio=True), # Whether to keep the ratio between height and width, the img_scale set here will be suppressed by the img_scale set above.
+ dict(type='RandomFlip'), # Thought RandomFlip is added in pipeline, it is not used when flip=False
+ dict(
+ type='Normalize', # Normalization config, the values are from img_norm_cfg
+ mean=[123.675, 116.28, 103.53],
+ std=[58.395, 57.12, 57.375],
+ to_rgb=True),
+ dict(type='ImageToTensor', # Convert image to tensor
+ keys=['img']),
+ dict(type='Collect', # Collect pipeline that collect necessary keys for testing.
+ keys=['img'])
+ ])
+]
+data = dict(
+ samples_per_gpu=2, # Batch size of a single GPU
+ workers_per_gpu=2, # Worker to pre-fetch data for each single GPU
+ train=dict( # Train dataset config
+ type='CityscapesDataset', # Type of dataset, refer to mmseg/datasets/ for details.
+ data_root='data/cityscapes/', # The root of dataset.
+ img_dir='leftImg8bit/train', # The image directory of dataset.
+ ann_dir='gtFine/train', # The annotation directory of dataset.
+ pipeline=[ # pipeline, this is passed by the train_pipeline created before.
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(
+ type='Resize', img_scale=(2048, 1024), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=(512, 1024), cat_max_ratio=0.75),
+ dict(type='RandomFlip', flip_ratio=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(
+ type='Normalize',
+ mean=[123.675, 116.28, 103.53],
+ std=[58.395, 57.12, 57.375],
+ to_rgb=True),
+ dict(type='Pad', size=(512, 1024), pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg'])
+ ]),
+ val=dict( # Validation dataset config
+ type='CityscapesDataset',
+ data_root='data/cityscapes/',
+ img_dir='leftImg8bit/val',
+ ann_dir='gtFine/val',
+ pipeline=[ # Pipeline is passed by test_pipeline created before
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2048, 1024),
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(
+ type='Normalize',
+ mean=[123.675, 116.28, 103.53],
+ std=[58.395, 57.12, 57.375],
+ to_rgb=True),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img'])
+ ])
+ ]),
+ test=dict(
+ type='CityscapesDataset',
+ data_root='data/cityscapes/',
+ img_dir='leftImg8bit/val',
+ ann_dir='gtFine/val',
+ pipeline=[
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2048, 1024),
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(
+ type='Normalize',
+ mean=[123.675, 116.28, 103.53],
+ std=[58.395, 57.12, 57.375],
+ to_rgb=True),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img'])
+ ])
+ ]))
+log_config = dict( # config to register logger hook
+ interval=50, # Interval to print the log
+ hooks=[
+ # dict(type='TensorboardLoggerHook') # The Tensorboard logger is also supported
+ dict(type='TextLoggerHook', by_epoch=False)
+ ])
+dist_params = dict(backend='nccl') # Parameters to setup distributed training, the port can also be set.
+log_level = 'INFO' # The level of logging.
+load_from = None # load models as a pre-trained model from a given path. This will not resume training.
+resume_from = None # Resume checkpoints from a given path, the training will be resumed from the iteration when the checkpoint's is saved.
+workflow = [('train', 1)] # Workflow for runner. [('train', 1)] means there is only one workflow and the workflow named 'train' is executed once. The workflow trains the model by 40000 iterations according to the `runner.max_iters`.
+cudnn_benchmark = True # Whether use cudnn_benchmark to speed up, which is fast for fixed input size.
+optimizer = dict( # Config used to build optimizer, support all the optimizers in PyTorch whose arguments are also the same as those in PyTorch
+ type='SGD', # Type of optimizers, refer to https://github.com/open-mmlab/mmcv/blob/master/mmcv/runner/optimizer/default_constructor.py#L13 for more details
+ lr=0.01, # Learning rate of optimizers, see detail usages of the parameters in the documentation of PyTorch
+ momentum=0.9, # Momentum
+ weight_decay=0.0005) # Weight decay of SGD
+optimizer_config = dict() # Config used to build the optimizer hook, refer to https://github.com/open-mmlab/mmcv/blob/master/mmcv/runner/hooks/optimizer.py#L8 for implementation details.
+lr_config = dict(
+ policy='poly', # The policy of scheduler, also support Step, CosineAnnealing, Cyclic, etc. Refer to details of supported LrUpdater from https://github.com/open-mmlab/mmcv/blob/master/mmcv/runner/hooks/lr_updater.py#L9.
+ power=0.9, # The power of polynomial decay.
+ min_lr=0.0001, # The minimum learning rate to stable the training.
+ by_epoch=False) # Whether count by epoch or not.
+runner = dict(
+ type='IterBasedRunner', # Type of runner to use (i.e. IterBasedRunner or EpochBasedRunner)
+ max_iters=40000) # Total number of iterations. For EpochBasedRunner use `max_epochs`
+checkpoint_config = dict( # Config to set the checkpoint hook, Refer to https://github.com/open-mmlab/mmcv/blob/master/mmcv/runner/hooks/checkpoint.py for implementation.
+ by_epoch=False, # Whether count by epoch or not.
+ interval=4000) # The save interval.
+evaluation = dict( # The config to build the evaluation hook. Please refer to mmseg/core/evaluation/eval_hook.py for details.
+ interval=4000, # The interval of evaluation.
+ metric='mIoU') # The evaluation metric.
+
+
+```
+
+## FAQ
+
+### Ignore some fields in the base configs
+
+Sometimes, you may set `_delete_=True` to ignore some of the fields in base configs.
+You may refer to [mmcv](https://mmcv.readthedocs.io/en/latest/understand_mmcv/config.html#inherit-from-base-config-with-ignored-fields) for simple illustration.
+
+In MMSegmentation, for example, to change the backbone of PSPNet with the following config.
+
+```python
+norm_cfg = dict(type='SyncBN', requires_grad=True)
+model = dict(
+ type='MaskRCNN',
+ pretrained='torchvision://resnet50',
+ backbone=dict(
+ type='ResNetV1c',
+ depth=50,
+ num_stages=4,
+ out_indices=(0, 1, 2, 3),
+ dilations=(1, 1, 2, 4),
+ strides=(1, 2, 1, 1),
+ norm_cfg=norm_cfg,
+ norm_eval=False,
+ style='pytorch',
+ contract_dilation=True),
+ decode_head=dict(...),
+ auxiliary_head=dict(...))
+```
+
+`ResNet` and `HRNet` use different keywords to construct.
+
+```python
+_base_ = '../pspnet/psp_r50_512x1024_40ki_cityscpaes.py'
+norm_cfg = dict(type='SyncBN', requires_grad=True)
+model = dict(
+ pretrained='open-mmlab://msra/hrnetv2_w32',
+ backbone=dict(
+ _delete_=True,
+ type='HRNet',
+ norm_cfg=norm_cfg,
+ extra=dict(
+ stage1=dict(
+ num_modules=1,
+ num_branches=1,
+ block='BOTTLENECK',
+ num_blocks=(4, ),
+ num_channels=(64, )),
+ stage2=dict(
+ num_modules=1,
+ num_branches=2,
+ block='BASIC',
+ num_blocks=(4, 4),
+ num_channels=(32, 64)),
+ stage3=dict(
+ num_modules=4,
+ num_branches=3,
+ block='BASIC',
+ num_blocks=(4, 4, 4),
+ num_channels=(32, 64, 128)),
+ stage4=dict(
+ num_modules=3,
+ num_branches=4,
+ block='BASIC',
+ num_blocks=(4, 4, 4, 4),
+ num_channels=(32, 64, 128, 256)))),
+ decode_head=dict(...),
+ auxiliary_head=dict(...))
+```
+
+The `_delete_=True` would replace all old keys in `backbone` field with new keys.
+
+### Use intermediate variables in configs
+
+Some intermediate variables are used in the configs files, like `train_pipeline`/`test_pipeline` in datasets.
+It's worth noting that when modifying intermediate variables in the children configs, user need to pass the intermediate variables into corresponding fields again.
+For example, we would like to change multi scale strategy to train/test a PSPNet. `train_pipeline`/`test_pipeline` are intermediate variable we would like to modify.
+
+```python
+_base_ = '../pspnet/psp_r50_512x1024_40ki_cityscapes.py'
+crop_size = (512, 1024)
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=(2048, 1024), ratio_range=(1.0, 2.0)), # change to [1., 2.]
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', flip_ratio=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2048, 1024),
+ img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75], # change to multi scale testing
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ train=dict(pipeline=train_pipeline),
+ val=dict(pipeline=test_pipeline),
+ test=dict(pipeline=test_pipeline))
+```
+
+We first define the new `train_pipeline`/`test_pipeline` and pass them into `data`.
+
+Similarly, if we would like to switch from `SyncBN` to `BN` or `MMSyncBN`, we need to substitute every `norm_cfg` in the config.
+
+```python
+_base_ = '../pspnet/psp_r50_512x1024_40ki_cityscpaes.py'
+norm_cfg = dict(type='BN', requires_grad=True)
+model = dict(
+ backbone=dict(norm_cfg=norm_cfg),
+ decode_head=dict(norm_cfg=norm_cfg),
+ auxiliary_head=dict(norm_cfg=norm_cfg))
+```
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/customize_datasets.md b/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/customize_datasets.md
new file mode 100644
index 0000000000000000000000000000000000000000..78bdb38645d7a7ba65d7caf651bc1f070e75bff7
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/customize_datasets.md
@@ -0,0 +1,290 @@
+# Tutorial 2: Customize Datasets
+
+## Data configuration
+
+`data` in config file is the variable for data configuration, to define the arguments that are used in datasets and dataloaders.
+
+Here is an example of data configuration:
+
+```python
+data = dict(
+ samples_per_gpu=4,
+ workers_per_gpu=4,
+ train=dict(
+ type='ADE20KDataset',
+ data_root='data/ade/ADEChallengeData2016',
+ img_dir='images/training',
+ ann_dir='annotations/training',
+ pipeline=train_pipeline),
+ val=dict(
+ type='ADE20KDataset',
+ data_root='data/ade/ADEChallengeData2016',
+ img_dir='images/validation',
+ ann_dir='annotations/validation',
+ pipeline=test_pipeline),
+ test=dict(
+ type='ADE20KDataset',
+ data_root='data/ade/ADEChallengeData2016',
+ img_dir='images/validation',
+ ann_dir='annotations/validation',
+ pipeline=test_pipeline))
+```
+
+- `train`, `val` and `test`: The [`config`](https://github.com/open-mmlab/mmcv/blob/master/docs/en/understand_mmcv/config.md)s to build dataset instances for model training, validation and testing by
+using [`build and registry`](https://github.com/open-mmlab/mmcv/blob/master/docs/en/understand_mmcv/registry.md) mechanism.
+
+- `samples_per_gpu`: How many samples per batch and per gpu to load during model training, and the `batch_size` of training is equal to `samples_per_gpu` times gpu number, e.g. when using 8 gpus for distributed data parallel trainig and `samples_per_gpu=4`, the `batch_size` is `8*4=16`.
+If you would like to define `batch_size` for testing and validation, please use `test_dataloaser` and
+`val_dataloader` with mmseg >=0.24.1.
+
+- `workers_per_gpu`: How many subprocesses per gpu to use for data loading. `0` means that the data will be loaded in the main process.
+
+**Note:** `samples_per_gpu` only works for model training, and the default setting of `samples_per_gpu` is 1 in mmseg when model testing and validation (DO NOT support batch inference yet).
+
+**Note:** before v0.24.1, except `train`, `val` `test`, `samples_per_gpu` and `workers_per_gpu`, the other keys in `data` must be the
+input keyword arguments for `dataloader` in pytorch, and the dataloaders used for model training, validation and testing have the same input arguments.
+In v0.24.1, mmseg supports to use `train_dataloader`, `test_dataloaser` and `val_dataloader` to specify different keyword arguments, and still supports the overall arguments definition but the specific dataloader setting has a higher priority.
+
+Here is an example for specific dataloader:
+
+```python
+data = dict(
+ samples_per_gpu=4,
+ workers_per_gpu=4,
+ shuffle=True,
+ train=dict(type='xxx', ...),
+ val=dict(type='xxx', ...),
+ test=dict(type='xxx', ...),
+ # Use different batch size during validation and testing.
+ val_dataloader=dict(samples_per_gpu=1, workers_per_gpu=4, shuffle=False),
+ test_dataloader=dict(samples_per_gpu=1, workers_per_gpu=4, shuffle=False))
+```
+
+Assume only one gpu used for model training and testing, as the priority of the overall arguments definition is low, the batch_size
+for training is `4` and dataset will be shuffled, and batch_size for testing and validation is `1`, and dataset will not be shuffled.
+
+To make data configuration much clearer, we recommend use specific dataloader setting instead of overall dataloader setting after v0.24.1, just like:
+
+```python
+data = dict(
+ train=dict(type='xxx', ...),
+ val=dict(type='xxx', ...),
+ test=dict(type='xxx', ...),
+ # Use specific dataloader setting
+ train_dataloader=dict(samples_per_gpu=4, workers_per_gpu=4, shuffle=True),
+ val_dataloader=dict(samples_per_gpu=1, workers_per_gpu=4, shuffle=False),
+ test_dataloader=dict(samples_per_gpu=1, workers_per_gpu=4, shuffle=False))
+```
+
+**Note:** in model training, default values in the script of mmseg for dataloader are `shuffle=True, and drop_last=True`,
+in model validation and testing, default values are `shuffle=False, and drop_last=False`
+
+## Customize datasets by reorganizing data
+
+The simplest way is to convert your dataset to organize your data into folders.
+
+An example of file structure is as followed.
+
+```none
+├── data
+│ ├── my_dataset
+│ │ ├── img_dir
+│ │ │ ├── train
+│ │ │ │ ├── xxx{img_suffix}
+│ │ │ │ ├── yyy{img_suffix}
+│ │ │ │ ├── zzz{img_suffix}
+│ │ │ ├── val
+│ │ ├── ann_dir
+│ │ │ ├── train
+│ │ │ │ ├── xxx{seg_map_suffix}
+│ │ │ │ ├── yyy{seg_map_suffix}
+│ │ │ │ ├── zzz{seg_map_suffix}
+│ │ │ ├── val
+
+```
+
+A training pair will consist of the files with same suffix in img_dir/ann_dir.
+
+If `split` argument is given, only part of the files in img_dir/ann_dir will be loaded.
+We may specify the prefix of files we would like to be included in the split txt.
+
+More specifically, for a split txt like following,
+
+```none
+xxx
+zzz
+```
+
+Only
+`data/my_dataset/img_dir/train/xxx{img_suffix}`,
+`data/my_dataset/img_dir/train/zzz{img_suffix}`,
+`data/my_dataset/ann_dir/train/xxx{seg_map_suffix}`,
+`data/my_dataset/ann_dir/train/zzz{seg_map_suffix}` will be loaded.
+
+:::{note}
+The annotations are images of shape (H, W), the value pixel should fall in range `[0, num_classes - 1]`.
+You may use `'P'` mode of [pillow](https://pillow.readthedocs.io/en/stable/handbook/concepts.html#palette) to create your annotation image with color.
+:::
+
+## Customize datasets by mixing dataset
+
+MMSegmentation also supports to mix dataset for training.
+Currently it supports to concat, repeat and multi-image mix datasets.
+
+### Repeat dataset
+
+We use `RepeatDataset` as wrapper to repeat the dataset.
+For example, suppose the original dataset is `Dataset_A`, to repeat it, the config looks like the following
+
+```python
+dataset_A_train = dict(
+ type='RepeatDataset',
+ times=N,
+ dataset=dict( # This is the original config of Dataset_A
+ type='Dataset_A',
+ ...
+ pipeline=train_pipeline
+ )
+ )
+```
+
+### Concatenate dataset
+
+There 2 ways to concatenate the dataset.
+
+1. If the datasets you want to concatenate are in the same type with different annotation files,
+ you can concatenate the dataset configs like the following.
+
+ 1. You may concatenate two `ann_dir`.
+
+ ```python
+ dataset_A_train = dict(
+ type='Dataset_A',
+ img_dir = 'img_dir',
+ ann_dir = ['anno_dir_1', 'anno_dir_2'],
+ pipeline=train_pipeline
+ )
+ ```
+
+ 2. You may concatenate two `split`.
+
+ ```python
+ dataset_A_train = dict(
+ type='Dataset_A',
+ img_dir = 'img_dir',
+ ann_dir = 'anno_dir',
+ split = ['split_1.txt', 'split_2.txt'],
+ pipeline=train_pipeline
+ )
+ ```
+
+ 3. You may concatenate two `ann_dir` and `split` simultaneously.
+
+ ```python
+ dataset_A_train = dict(
+ type='Dataset_A',
+ img_dir = 'img_dir',
+ ann_dir = ['anno_dir_1', 'anno_dir_2'],
+ split = ['split_1.txt', 'split_2.txt'],
+ pipeline=train_pipeline
+ )
+ ```
+
+ In this case, `ann_dir_1` and `ann_dir_2` are corresponding to `split_1.txt` and `split_2.txt`.
+
+2. In case the dataset you want to concatenate is different, you can concatenate the dataset configs like the following.
+
+ ```python
+ dataset_A_train = dict()
+ dataset_B_train = dict()
+
+ data = dict(
+ imgs_per_gpu=2,
+ workers_per_gpu=2,
+ train = [
+ dataset_A_train,
+ dataset_B_train
+ ],
+ val = dataset_A_val,
+ test = dataset_A_test
+ )
+ ```
+
+A more complex example that repeats `Dataset_A` and `Dataset_B` by N and M times, respectively, and then concatenates the repeated datasets is as the following.
+
+```python
+dataset_A_train = dict(
+ type='RepeatDataset',
+ times=N,
+ dataset=dict(
+ type='Dataset_A',
+ ...
+ pipeline=train_pipeline
+ )
+)
+dataset_A_val = dict(
+ ...
+ pipeline=test_pipeline
+)
+dataset_A_test = dict(
+ ...
+ pipeline=test_pipeline
+)
+dataset_B_train = dict(
+ type='RepeatDataset',
+ times=M,
+ dataset=dict(
+ type='Dataset_B',
+ ...
+ pipeline=train_pipeline
+ )
+)
+data = dict(
+ imgs_per_gpu=2,
+ workers_per_gpu=2,
+ train = [
+ dataset_A_train,
+ dataset_B_train
+ ],
+ val = dataset_A_val,
+ test = dataset_A_test
+)
+
+```
+
+### Multi-image Mix Dataset
+
+We use `MultiImageMixDataset` as a wrapper to mix images from multiple datasets.
+`MultiImageMixDataset` can be used by multiple images mixed data augmentation
+like mosaic and mixup.
+
+An example of using `MultiImageMixDataset` with `Mosaic` data augmentation:
+
+```python
+train_pipeline = [
+ dict(type='RandomMosaic', prob=1),
+ dict(type='Resize', img_scale=(1024, 512), keep_ratio=True),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+
+train_dataset = dict(
+ type='MultiImageMixDataset',
+ dataset=dict(
+ classes=classes,
+ palette=palette,
+ type=dataset_type,
+ reduce_zero_label=False,
+ img_dir=data_root + "images/train",
+ ann_dir=data_root + "annotations/train",
+ pipeline=[
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ ]
+ ),
+ pipeline=train_pipeline
+)
+
+```
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/customize_models.md b/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/customize_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..f637fd6f0431ea0de748e39806be51d1b4849c8e
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/customize_models.md
@@ -0,0 +1,234 @@
+# Tutorial 4: Customize Models
+
+## Customize optimizer
+
+Assume you want to add a optimizer named as `MyOptimizer`, which has arguments `a`, `b`, and `c`.
+You need to first implement the new optimizer in a file, e.g., in `mmseg/core/optimizer/my_optimizer.py`:
+
+```python
+from mmcv.runner import OPTIMIZERS
+from torch.optim import Optimizer
+
+
+@OPTIMIZERS.register_module
+class MyOptimizer(Optimizer):
+
+ def __init__(self, a, b, c)
+
+```
+
+Then add this module in `mmseg/core/optimizer/__init__.py` thus the registry will
+find the new module and add it:
+
+```python
+from .my_optimizer import MyOptimizer
+```
+
+Then you can use `MyOptimizer` in `optimizer` field of config files.
+In the configs, the optimizers are defined by the field `optimizer` like the following:
+
+```python
+optimizer = dict(type='SGD', lr=0.02, momentum=0.9, weight_decay=0.0001)
+```
+
+To use your own optimizer, the field can be changed as
+
+```python
+optimizer = dict(type='MyOptimizer', a=a_value, b=b_value, c=c_value)
+```
+
+We already support to use all the optimizers implemented by PyTorch, and the only modification is to change the `optimizer` field of config files.
+For example, if you want to use `ADAM`, though the performance will drop a lot, the modification could be as the following.
+
+```python
+optimizer = dict(type='Adam', lr=0.0003, weight_decay=0.0001)
+```
+
+The users can directly set arguments following the [API doc](https://pytorch.org/docs/stable/optim.html?highlight=optim#module-torch.optim) of PyTorch.
+
+## Customize optimizer constructor
+
+Some models may have some parameter-specific settings for optimization, e.g. weight decay for BatchNoarm layers.
+The users can do those fine-grained parameter tuning through customizing optimizer constructor.
+
+```
+from mmcv.utils import build_from_cfg
+
+from mmcv.runner import OPTIMIZER_BUILDERS
+from .cocktail_optimizer import CocktailOptimizer
+
+
+@OPTIMIZER_BUILDERS.register_module
+class CocktailOptimizerConstructor(object):
+
+ def __init__(self, optimizer_cfg, paramwise_cfg=None):
+
+ def __call__(self, model):
+
+ return my_optimizer
+
+```
+
+## Develop new components
+
+There are mainly 2 types of components in MMSegmentation.
+
+- backbone: usually stacks of convolutional network to extract feature maps, e.g., ResNet, HRNet.
+- head: the component for semantic segmentation map decoding.
+
+### Add new backbones
+
+Here we show how to develop new components with an example of MobileNet.
+
+1. Create a new file `mmseg/models/backbones/mobilenet.py`.
+
+```python
+import torch.nn as nn
+
+from ..registry import BACKBONES
+
+
+@BACKBONES.register_module
+class MobileNet(nn.Module):
+
+ def __init__(self, arg1, arg2):
+ pass
+
+ def forward(self, x): # should return a tuple
+ pass
+
+ def init_weights(self, pretrained=None):
+ pass
+```
+
+2. Import the module in `mmseg/models/backbones/__init__.py`.
+
+```python
+from .mobilenet import MobileNet
+```
+
+3. Use it in your config file.
+
+```python
+model = dict(
+ ...
+ backbone=dict(
+ type='MobileNet',
+ arg1=xxx,
+ arg2=xxx),
+ ...
+```
+
+### Add new heads
+
+In MMSegmentation, we provide a base [BaseDecodeHead](https://github.com/open-mmlab/mmsegmentation/blob/master/mmseg/models/decode_heads/decode_head.py) for all segmentation head.
+All newly implemented decode heads should be derived from it.
+Here we show how to develop a new head with the example of [PSPNet](https://arxiv.org/abs/1612.01105) as the following.
+
+First, add a new decode head in `mmseg/models/decode_heads/psp_head.py`.
+PSPNet implements a decode head for segmentation decode.
+To implement a decode head, basically we need to implement three functions of the new module as the following.
+
+```python
+@HEADS.register_module()
+class PSPHead(BaseDecodeHead):
+
+ def __init__(self, pool_scales=(1, 2, 3, 6), **kwargs):
+ super(PSPHead, self).__init__(**kwargs)
+
+ def init_weights(self):
+
+ def forward(self, inputs):
+
+```
+
+Next, the users need to add the module in the `mmseg/models/decode_heads/__init__.py` thus the corresponding registry could find and load them.
+
+To config file of PSPNet is as the following
+
+```python
+norm_cfg = dict(type='SyncBN', requires_grad=True)
+model = dict(
+ type='EncoderDecoder',
+ pretrained='pretrain_model/resnet50_v1c_trick-2cccc1ad.pth',
+ backbone=dict(
+ type='ResNetV1c',
+ depth=50,
+ num_stages=4,
+ out_indices=(0, 1, 2, 3),
+ dilations=(1, 1, 2, 4),
+ strides=(1, 2, 1, 1),
+ norm_cfg=norm_cfg,
+ norm_eval=False,
+ style='pytorch',
+ contract_dilation=True),
+ decode_head=dict(
+ type='PSPHead',
+ in_channels=2048,
+ in_index=3,
+ channels=512,
+ pool_scales=(1, 2, 3, 6),
+ dropout_ratio=0.1,
+ num_classes=19,
+ norm_cfg=norm_cfg,
+ align_corners=False,
+ loss_decode=dict(
+ type='CrossEntropyLoss', use_sigmoid=False, loss_weight=1.0)))
+
+```
+
+### Add new loss
+
+Assume you want to add a new loss as `MyLoss` for segmentation decode.
+To add a new loss function, the users need implement it in `mmseg/models/losses/my_loss.py`.
+The decorator `weighted_loss` enable the loss to be weighted for each element.
+
+```python
+import torch
+import torch.nn as nn
+
+from ..builder import LOSSES
+from .utils import weighted_loss
+
+@weighted_loss
+def my_loss(pred, target):
+ assert pred.size() == target.size() and target.numel() > 0
+ loss = torch.abs(pred - target)
+ return loss
+
+@LOSSES.register_module
+class MyLoss(nn.Module):
+
+ def __init__(self, reduction='mean', loss_weight=1.0):
+ super(MyLoss, self).__init__()
+ self.reduction = reduction
+ self.loss_weight = loss_weight
+
+ def forward(self,
+ pred,
+ target,
+ weight=None,
+ avg_factor=None,
+ reduction_override=None):
+ assert reduction_override in (None, 'none', 'mean', 'sum')
+ reduction = (
+ reduction_override if reduction_override else self.reduction)
+ loss = self.loss_weight * my_loss(
+ pred, target, weight, reduction=reduction, avg_factor=avg_factor)
+ return loss
+```
+
+Then the users need to add it in the `mmseg/models/losses/__init__.py`.
+
+```python
+from .my_loss import MyLoss, my_loss
+
+```
+
+To use it, modify the `loss_xxx` field.
+Then you need to modify the `loss_decode` field in the head.
+`loss_weight` could be used to balance multiple losses.
+
+```python
+loss_decode=dict(type='MyLoss', loss_weight=1.0))
+```
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/customize_runtime.md b/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/customize_runtime.md
new file mode 100644
index 0000000000000000000000000000000000000000..dba0edc4a4944d9fe4bb78751e06469c64c1cba4
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/customize_runtime.md
@@ -0,0 +1,245 @@
+# Tutorial 6: Customize Runtime Settings
+
+## Customize optimization settings
+
+### Customize optimizer supported by Pytorch
+
+We already support to use all the optimizers implemented by PyTorch, and the only modification is to change the `optimizer` field of config files.
+For example, if you want to use `ADAM` (note that the performance could drop a lot), the modification could be as the following.
+
+```python
+optimizer = dict(type='Adam', lr=0.0003, weight_decay=0.0001)
+```
+
+To modify the learning rate of the model, the users only need to modify the `lr` in the config of optimizer. The users can directly set arguments following the [API doc](https://pytorch.org/docs/stable/optim.html?highlight=optim#module-torch.optim) of PyTorch.
+
+### Customize self-implemented optimizer
+
+#### 1. Define a new optimizer
+
+A customized optimizer could be defined as following.
+
+Assume you want to add a optimizer named `MyOptimizer`, which has arguments `a`, `b`, and `c`.
+You need to create a new directory named `mmseg/core/optimizer`.
+And then implement the new optimizer in a file, e.g., in `mmseg/core/optimizer/my_optimizer.py`:
+
+```python
+from .registry import OPTIMIZERS
+from torch.optim import Optimizer
+
+
+@OPTIMIZERS.register_module()
+class MyOptimizer(Optimizer):
+
+ def __init__(self, a, b, c)
+
+```
+
+#### 2. Add the optimizer to registry
+
+To find the above module defined above, this module should be imported into the main namespace at first. There are two options to achieve it.
+
+- Modify `mmseg/core/optimizer/__init__.py` to import it.
+
+ The newly defined module should be imported in `mmseg/core/optimizer/__init__.py` so that the registry will
+ find the new module and add it:
+
+```python
+from .my_optimizer import MyOptimizer
+```
+
+- Use `custom_imports` in the config to manually import it
+
+```python
+custom_imports = dict(imports=['mmseg.core.optimizer.my_optimizer'], allow_failed_imports=False)
+```
+
+The module `mmseg.core.optimizer.my_optimizer` will be imported at the beginning of the program and the class `MyOptimizer` is then automatically registered.
+Note that only the package containing the class `MyOptimizer` should be imported.
+`mmseg.core.optimizer.my_optimizer.MyOptimizer` **cannot** be imported directly.
+
+Actually users can use a totally different file directory structure using this importing method, as long as the module root can be located in `PYTHONPATH`.
+
+#### 3. Specify the optimizer in the config file
+
+Then you can use `MyOptimizer` in `optimizer` field of config files.
+In the configs, the optimizers are defined by the field `optimizer` like the following:
+
+```python
+optimizer = dict(type='SGD', lr=0.02, momentum=0.9, weight_decay=0.0001)
+```
+
+To use your own optimizer, the field can be changed to
+
+```python
+optimizer = dict(type='MyOptimizer', a=a_value, b=b_value, c=c_value)
+```
+
+### Customize optimizer constructor
+
+Some models may have some parameter-specific settings for optimization, e.g. weight decay for BatchNorm layers.
+The users can do those fine-grained parameter tuning through customizing optimizer constructor.
+
+```python
+from mmcv.utils import build_from_cfg
+
+from mmcv.runner.optimizer import OPTIMIZER_BUILDERS, OPTIMIZERS
+from mmseg.utils import get_root_logger
+from .my_optimizer import MyOptimizer
+
+
+@OPTIMIZER_BUILDERS.register_module()
+class MyOptimizerConstructor(object):
+
+ def __init__(self, optimizer_cfg, paramwise_cfg=None):
+
+ def __call__(self, model):
+
+ return my_optimizer
+
+```
+
+The default optimizer constructor is implemented [here](https://github.com/open-mmlab/mmcv/blob/9ecd6b0d5ff9d2172c49a182eaa669e9f27bb8e7/mmcv/runner/optimizer/default_constructor.py#L11), which could also serve as a template for new optimizer constructor.
+
+### Additional settings
+
+Tricks not implemented by the optimizer should be implemented through optimizer constructor (e.g., set parameter-wise learning rates) or hooks. We list some common settings that could stabilize the training or accelerate the training. Feel free to create PR, issue for more settings.
+
+- __Use gradient clip to stabilize training__:
+ Some models need gradient clip to clip the gradients to stabilize the training process. An example is as below:
+
+ ```python
+ optimizer_config = dict(
+ _delete_=True, grad_clip=dict(max_norm=35, norm_type=2))
+ ```
+
+ If your config inherits the base config which already sets the `optimizer_config`, you might need `_delete_=True` to override the unnecessary settings. See the [config documentation](https://mmsegmentation.readthedocs.io/en/latest/config.html) for more details.
+
+- __Use momentum schedule to accelerate model convergence__:
+ We support momentum scheduler to modify model's momentum according to learning rate, which could make the model converge in a faster way.
+ Momentum scheduler is usually used with LR scheduler, for example, the following config is used in 3D detection to accelerate convergence.
+ For more details, please refer to the implementation of [CyclicLrUpdater](https://github.com/open-mmlab/mmcv/blob/f48241a65aebfe07db122e9db320c31b685dc674/mmcv/runner/hooks/lr_updater.py#L327) and [CyclicMomentumUpdater](https://github.com/open-mmlab/mmcv/blob/f48241a65aebfe07db122e9db320c31b685dc674/mmcv/runner/hooks/momentum_updater.py#L130).
+
+ ```python
+ lr_config = dict(
+ policy='cyclic',
+ target_ratio=(10, 1e-4),
+ cyclic_times=1,
+ step_ratio_up=0.4,
+ )
+ momentum_config = dict(
+ policy='cyclic',
+ target_ratio=(0.85 / 0.95, 1),
+ cyclic_times=1,
+ step_ratio_up=0.4,
+ )
+ ```
+
+## Customize training schedules
+
+By default we use step learning rate with 40k/80k schedule, this calls [`PolyLrUpdaterHook`](https://github.com/open-mmlab/mmcv/blob/826d3a7b68596c824fa1e2cb89b6ac274f52179c/mmcv/runner/hooks/lr_updater.py#L196) in MMCV.
+We support many other learning rate schedule [here](https://github.com/open-mmlab/mmcv/blob/master/mmcv/runner/hooks/lr_updater.py), such as `CosineAnnealing` and `Poly` schedule. Here are some examples
+
+- Step schedule:
+
+ ```python
+ lr_config = dict(policy='step', step=[9, 10])
+ ```
+
+- ConsineAnnealing schedule:
+
+ ```python
+ lr_config = dict(
+ policy='CosineAnnealing',
+ warmup='linear',
+ warmup_iters=1000,
+ warmup_ratio=1.0 / 10,
+ min_lr_ratio=1e-5)
+ ```
+
+## Customize workflow
+
+Workflow is a list of (phase, epochs) to specify the running order and epochs.
+By default it is set to be
+
+```python
+workflow = [('train', 1)]
+```
+
+which means running 1 epoch for training.
+Sometimes user may want to check some metrics (e.g. loss, accuracy) about the model on the validate set.
+In such case, we can set the workflow as
+
+```python
+[('train', 1), ('val', 1)]
+```
+
+so that 1 epoch for training and 1 epoch for validation will be run iteratively.
+
+:::{note}
+
+1. The parameters of model will not be updated during val epoch.
+2. Keyword `total_epochs` in the config only controls the number of training epochs and will not affect the validation workflow.
+3. Workflows `[('train', 1), ('val', 1)]` and `[('train', 1)]` will not change the behavior of `EvalHook` because `EvalHook` is called by `after_train_epoch` and validation workflow only affect hooks that are called through `after_val_epoch`. Therefore, the only difference between `[('train', 1), ('val', 1)]` and `[('train', 1)]` is that the runner will calculate losses on validation set after each training epoch.
+
+:::
+
+## Customize hooks
+
+### Use hooks implemented in MMCV
+
+If the hook is already implemented in MMCV, you can directly modify the config to use the hook as below
+
+```python
+custom_hooks = [
+ dict(type='MyHook', a=a_value, b=b_value, priority='NORMAL')
+]
+```
+
+### Modify default runtime hooks
+
+There are some common hooks that are not registered through `custom_hooks`, they are
+
+- log_config
+- checkpoint_config
+- evaluation
+- lr_config
+- optimizer_config
+- momentum_config
+
+In those hooks, only the logger hook has the `VERY_LOW` priority, others' priority are `NORMAL`.
+The above-mentioned tutorials already covers how to modify `optimizer_config`, `momentum_config`, and `lr_config`.
+Here we reveals how what we can do with `log_config`, `checkpoint_config`, and `evaluation`.
+
+#### Checkpoint config
+
+The MMCV runner will use `checkpoint_config` to initialize [`CheckpointHook`](https://github.com/open-mmlab/mmcv/blob/9ecd6b0d5ff9d2172c49a182eaa669e9f27bb8e7/mmcv/runner/hooks/checkpoint.py#L9).
+
+```python
+checkpoint_config = dict(interval=1)
+```
+
+The users could set `max_keep_ckpts` to only save only small number of checkpoints or decide whether to store state dict of optimizer by `save_optimizer`. More details of the arguments are [here](https://mmcv.readthedocs.io/en/latest/api.html#mmcv.runner.CheckpointHook)
+
+#### Log config
+
+The `log_config` wraps multiple logger hooks and enables to set intervals. Now MMCV supports `WandbLoggerHook`, `MlflowLoggerHook`, and `TensorboardLoggerHook`.
+The detail usages can be found in the [doc](https://mmcv.readthedocs.io/en/latest/api.html#mmcv.runner.LoggerHook).
+
+```python
+log_config = dict(
+ interval=50,
+ hooks=[
+ dict(type='TextLoggerHook'),
+ dict(type='TensorboardLoggerHook')
+ ])
+```
+
+#### Evaluation config
+
+The config of `evaluation` will be used to initialize the [`EvalHook`](https://github.com/open-mmlab/mmsegmentation/blob/e3f6f655d69b777341aec2fe8829871cc0beadcb/mmseg/core/evaluation/eval_hooks.py#L7).
+Except the key `interval`, other arguments such as `metric` will be passed to the `dataset.evaluate()`
+
+```python
+evaluation = dict(interval=1, metric='mIoU')
+```
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/data_pipeline.md b/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/data_pipeline.md
new file mode 100644
index 0000000000000000000000000000000000000000..1eecfe91d433ca897ae47a5ae9b8c5f406a3fe2b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/data_pipeline.md
@@ -0,0 +1,171 @@
+# Tutorial 3: Customize Data Pipelines
+
+## Design of Data pipelines
+
+Following typical conventions, we use `Dataset` and `DataLoader` for data loading
+with multiple workers. `Dataset` returns a dict of data items corresponding
+the arguments of models' forward method.
+Since the data in semantic segmentation may not be the same size,
+we introduce a new `DataContainer` type in MMCV to help collect and distribute
+data of different size.
+See [here](https://github.com/open-mmlab/mmcv/blob/master/mmcv/parallel/data_container.py) for more details.
+
+The data preparation pipeline and the dataset is decomposed. Usually a dataset
+defines how to process the annotations and a data pipeline defines all the steps to prepare a data dict.
+A pipeline consists of a sequence of operations. Each operation takes a dict as input and also output a dict for the next transform.
+
+The operations are categorized into data loading, pre-processing, formatting and test-time augmentation.
+
+Here is an pipeline example for PSPNet.
+
+```python
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (512, 1024)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=(2048, 1024), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', flip_ratio=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2048, 1024),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+```
+
+For each operation, we list the related dict fields that are added/updated/removed.
+
+### Data loading
+
+`LoadImageFromFile`
+
+- add: img, img_shape, ori_shape
+
+`LoadAnnotations`
+
+- add: gt_semantic_seg, seg_fields
+
+### Pre-processing
+
+`Resize`
+
+- add: scale, scale_idx, pad_shape, scale_factor, keep_ratio
+- update: img, img_shape, *seg_fields
+
+`RandomFlip`
+
+- add: flip
+- update: img, *seg_fields
+
+`Pad`
+
+- add: pad_fixed_size, pad_size_divisor
+- update: img, pad_shape, *seg_fields
+
+`RandomCrop`
+
+- update: img, pad_shape, *seg_fields
+
+`Normalize`
+
+- add: img_norm_cfg
+- update: img
+
+`SegRescale`
+
+- update: gt_semantic_seg
+
+`PhotoMetricDistortion`
+
+- update: img
+
+### Formatting
+
+`ToTensor`
+
+- update: specified by `keys`.
+
+`ImageToTensor`
+
+- update: specified by `keys`.
+
+`Transpose`
+
+- update: specified by `keys`.
+
+`ToDataContainer`
+
+- update: specified by `fields`.
+
+`DefaultFormatBundle`
+
+- update: img, gt_semantic_seg
+
+`Collect`
+
+- add: img_meta (the keys of img_meta is specified by `meta_keys`)
+- remove: all other keys except for those specified by `keys`
+
+### Test time augmentation
+
+`MultiScaleFlipAug`
+
+## Extend and use custom pipelines
+
+1. Write a new pipeline in any file, e.g., `my_pipeline.py`. It takes a dict as input and return a dict.
+
+ ```python
+ from mmseg.datasets import PIPELINES
+
+ @PIPELINES.register_module()
+ class MyTransform:
+
+ def __call__(self, results):
+ results['dummy'] = True
+ return results
+ ```
+
+2. Import the new class.
+
+ ```python
+ from .my_pipeline import MyTransform
+ ```
+
+3. Use it in config files.
+
+ ```python
+ img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+ crop_size = (512, 1024)
+ train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=(2048, 1024), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', flip_ratio=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='MyTransform'),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+ ]
+ ```
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/index.rst b/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/index.rst
new file mode 100644
index 0000000000000000000000000000000000000000..e1a67a8b44a9ac3c2bbee59304c2043467ac3f30
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/index.rst
@@ -0,0 +1,9 @@
+.. toctree::
+ :maxdepth: 2
+
+ config.md
+ customize_datasets.md
+ data_pipeline.md
+ customize_models.md
+ training_tricks.md
+ customize_runtime.md
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/training_tricks.md b/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/training_tricks.md
new file mode 100644
index 0000000000000000000000000000000000000000..6ff2c4249da792e4c0e460427a420ffbecb58d10
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/tutorials/training_tricks.md
@@ -0,0 +1,90 @@
+# Tutorial 5: Training Tricks
+
+MMSegmentation support following training tricks out of box.
+
+## Different Learning Rate(LR) for Backbone and Heads
+
+In semantic segmentation, some methods make the LR of heads larger than backbone to achieve better performance or faster convergence.
+
+In MMSegmentation, you may add following lines to config to make the LR of heads 10 times of backbone.
+
+```python
+optimizer=dict(
+ paramwise_cfg = dict(
+ custom_keys={
+ 'head': dict(lr_mult=10.)}))
+```
+
+With this modification, the LR of any parameter group with `'head'` in name will be multiplied by 10.
+You may refer to [MMCV doc](https://mmcv.readthedocs.io/en/latest/api.html#mmcv.runner.DefaultOptimizerConstructor) for further details.
+
+## Online Hard Example Mining (OHEM)
+
+We implement pixel sampler [here](https://github.com/open-mmlab/mmsegmentation/tree/master/mmseg/core/seg/sampler) for training sampling.
+Here is an example config of training PSPNet with OHEM enabled.
+
+```python
+_base_ = './pspnet_r50-d8_512x1024_40k_cityscapes.py'
+model=dict(
+ decode_head=dict(
+ sampler=dict(type='OHEMPixelSampler', thresh=0.7, min_kept=100000)) )
+```
+
+In this way, only pixels with confidence score under 0.7 are used to train. And we keep at least 100000 pixels during training. If `thresh` is not specified, pixels of top ``min_kept`` loss will be selected.
+
+## Class Balanced Loss
+
+For dataset that is not balanced in classes distribution, you may change the loss weight of each class.
+Here is an example for cityscapes dataset.
+
+```python
+_base_ = './pspnet_r50-d8_512x1024_40k_cityscapes.py'
+model=dict(
+ decode_head=dict(
+ loss_decode=dict(
+ type='CrossEntropyLoss', use_sigmoid=False, loss_weight=1.0,
+ # DeepLab used this class weight for cityscapes
+ class_weight=[0.8373, 0.9180, 0.8660, 1.0345, 1.0166, 0.9969, 0.9754,
+ 1.0489, 0.8786, 1.0023, 0.9539, 0.9843, 1.1116, 0.9037,
+ 1.0865, 1.0955, 1.0865, 1.1529, 1.0507])))
+```
+
+`class_weight` will be passed into `CrossEntropyLoss` as `weight` argument. Please refer to [PyTorch Doc](https://pytorch.org/docs/stable/nn.html?highlight=crossentropy#torch.nn.CrossEntropyLoss) for details.
+
+## Multiple Losses
+
+For loss calculation, we support multiple losses training concurrently. Here is an example config of training `unet` on `DRIVE` dataset, whose loss function is `1:3` weighted sum of `CrossEntropyLoss` and `DiceLoss`:
+
+```python
+_base_ = './fcn_unet_s5-d16_64x64_40k_drive.py'
+model = dict(
+ decode_head=dict(loss_decode=[dict(type='CrossEntropyLoss', loss_name='loss_ce', loss_weight=1.0),
+ dict(type='DiceLoss', loss_name='loss_dice', loss_weight=3.0)]),
+ auxiliary_head=dict(loss_decode=[dict(type='CrossEntropyLoss', loss_name='loss_ce',loss_weight=1.0),
+ dict(type='DiceLoss', loss_name='loss_dice', loss_weight=3.0)]),
+ )
+```
+
+In this way, `loss_weight` and `loss_name` will be weight and name in training log of corresponding loss, respectively.
+
+Note: If you want this loss item to be included into the backward graph, `loss_` must be the prefix of the name.
+
+## Ignore specified label index in loss calculation
+
+In default setting, `avg_non_ignore=False` which means each pixel counts for loss calculation although some of them belong to ignore-index labels.
+
+For loss calculation, we support ignore index of certain label by `avg_non_ignore` and `ignore_index`. In this way, the average loss would only be calculated in non-ignored labels which may achieve better performance, and here is the [reference](https://github.com/open-mmlab/mmsegmentation/pull/1409). Here is an example config of training `unet` on `Cityscapes` dataset: in loss calculation it would ignore label 0 which is background and loss average is only calculated on non-ignore labels:
+
+```python
+_base_ = './fcn_unet_s5-d16_4x4_512x1024_160k_cityscapes.py'
+model = dict(
+ decode_head=dict(
+ ignore_index=0,
+ loss_decode=dict(
+ type='CrossEntropyLoss', use_sigmoid=False, loss_weight=1.0, avg_non_ignore=True),
+ auxiliary_head=dict(
+ ignore_index=0,
+ loss_decode=dict(
+ type='CrossEntropyLoss', use_sigmoid=False, loss_weight=1.0, avg_non_ignore=True)),
+ ))
+```
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/en/useful_tools.md b/EgoHOS/raw/script/mmsegmentation/docs/en/useful_tools.md
new file mode 100644
index 0000000000000000000000000000000000000000..56710c54f11fe0ca29d51f5072a272f43d7800e2
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/en/useful_tools.md
@@ -0,0 +1,426 @@
+## Useful tools
+
+Apart from training/testing scripts, We provide lots of useful tools under the
+ `tools/` directory.
+
+### Get the FLOPs and params (experimental)
+
+We provide a script adapted from [flops-counter.pytorch](https://github.com/sovrasov/flops-counter.pytorch) to compute the FLOPs and params of a given model.
+
+```shell
+python tools/get_flops.py ${CONFIG_FILE} [--shape ${INPUT_SHAPE}]
+```
+
+You will get the result like this.
+
+```none
+==============================
+Input shape: (3, 2048, 1024)
+Flops: 1429.68 GMac
+Params: 48.98 M
+==============================
+```
+
+:::{note}
+This tool is still experimental and we do not guarantee that the number is correct. You may well use the result for simple comparisons, but double check it before you adopt it in technical reports or papers.
+:::
+
+(1) FLOPs are related to the input shape while parameters are not. The default input shape is (1, 3, 1280, 800).
+(2) Some operators are not counted into FLOPs like GN and custom operators.
+
+### Publish a model
+
+Before you upload a model to AWS, you may want to
+(1) convert model weights to CPU tensors, (2) delete the optimizer states and
+(3) compute the hash of the checkpoint file and append the hash id to the filename.
+
+```shell
+python tools/publish_model.py ${INPUT_FILENAME} ${OUTPUT_FILENAME}
+```
+
+E.g.,
+
+```shell
+python tools/publish_model.py work_dirs/pspnet/latest.pth psp_r50_hszhao_200ep.pth
+```
+
+The final output filename will be `psp_r50_512x1024_40ki_cityscapes-{hash id}.pth`.
+
+### Convert to ONNX (experimental)
+
+We provide a script to convert model to [ONNX](https://github.com/onnx/onnx) format. The converted model could be visualized by tools like [Netron](https://github.com/lutzroeder/netron). Besides, we also support comparing the output results between PyTorch and ONNX model.
+
+```bash
+python tools/pytorch2onnx.py \
+ ${CONFIG_FILE} \
+ --checkpoint ${CHECKPOINT_FILE} \
+ --output-file ${ONNX_FILE} \
+ --input-img ${INPUT_IMG} \
+ --shape ${INPUT_SHAPE} \
+ --rescale-shape ${RESCALE_SHAPE} \
+ --show \
+ --verify \
+ --dynamic-export \
+ --cfg-options \
+ model.test_cfg.mode="whole"
+```
+
+Description of arguments:
+
+- `config` : The path of a model config file.
+- `--checkpoint` : The path of a model checkpoint file.
+- `--output-file`: The path of output ONNX model. If not specified, it will be set to `tmp.onnx`.
+- `--input-img` : The path of an input image for conversion and visualize.
+- `--shape`: The height and width of input tensor to the model. If not specified, it will be set to img_scale of test_pipeline.
+- `--rescale-shape`: rescale shape of output, set this value to avoid OOM, only work on `slide` mode.
+- `--show`: Determines whether to print the architecture of the exported model. If not specified, it will be set to `False`.
+- `--verify`: Determines whether to verify the correctness of an exported model. If not specified, it will be set to `False`.
+- `--dynamic-export`: Determines whether to export ONNX model with dynamic input and output shapes. If not specified, it will be set to `False`.
+- `--cfg-options`:Update config options.
+
+:::{note}
+This tool is still experimental. Some customized operators are not supported for now.
+:::
+
+### Evaluate ONNX model
+
+We provide `tools/deploy_test.py` to evaluate ONNX model with different backend.
+
+#### Prerequisite
+
+- Install onnx and onnxruntime-gpu
+
+ ```shell
+ pip install onnx onnxruntime-gpu
+ ```
+
+- Install TensorRT following [how-to-build-tensorrt-plugins-in-mmcv](https://mmcv.readthedocs.io/en/latest/tensorrt_plugin.html#how-to-build-tensorrt-plugins-in-mmcv)(optional)
+
+#### Usage
+
+```bash
+python tools/deploy_test.py \
+ ${CONFIG_FILE} \
+ ${MODEL_FILE} \
+ ${BACKEND} \
+ --out ${OUTPUT_FILE} \
+ --eval ${EVALUATION_METRICS} \
+ --show \
+ --show-dir ${SHOW_DIRECTORY} \
+ --cfg-options ${CFG_OPTIONS} \
+ --eval-options ${EVALUATION_OPTIONS} \
+ --opacity ${OPACITY} \
+```
+
+Description of all arguments
+
+- `config`: The path of a model config file.
+- `model`: The path of a converted model file.
+- `backend`: Backend of the inference, options: `onnxruntime`, `tensorrt`.
+- `--out`: The path of output result file in pickle format.
+- `--format-only` : Format the output results without perform evaluation. It is useful when you want to format the result to a specific format and submit it to the test server. If not specified, it will be set to `False`. Note that this argument is **mutually exclusive** with `--eval`.
+- `--eval`: Evaluation metrics, which depends on the dataset, e.g., "mIoU" for generic datasets, and "cityscapes" for Cityscapes. Note that this argument is **mutually exclusive** with `--format-only`.
+- `--show`: Show results flag.
+- `--show-dir`: Directory where painted images will be saved
+- `--cfg-options`: Override some settings in the used config file, the key-value pair in `xxx=yyy` format will be merged into config file.
+- `--eval-options`: Custom options for evaluation, the key-value pair in `xxx=yyy` format will be kwargs for `dataset.evaluate()` function
+- `--opacity`: Opacity of painted segmentation map. In (0, 1] range.
+
+#### Results and Models
+
+| Model | Config | Dataset | Metric | PyTorch | ONNXRuntime | TensorRT-fp32 | TensorRT-fp16 |
+| :--------: | :---------------------------------------------: | :--------: | :----: | :-----: | :---------: | :-----------: | :-----------: |
+| FCN | fcn_r50-d8_512x1024_40k_cityscapes.py | cityscapes | mIoU | 72.2 | 72.2 | 72.2 | 72.2 |
+| PSPNet | pspnet_r50-d8_512x1024_40k_cityscapes.py | cityscapes | mIoU | 77.8 | 77.8 | 77.8 | 77.8 |
+| deeplabv3 | deeplabv3_r50-d8_512x1024_40k_cityscapes.py | cityscapes | mIoU | 79.0 | 79.0 | 79.0 | 79.0 |
+| deeplabv3+ | deeplabv3plus_r50-d8_512x1024_40k_cityscapes.py | cityscapes | mIoU | 79.6 | 79.5 | 79.5 | 79.5 |
+| PSPNet | pspnet_r50-d8_769x769_40k_cityscapes.py | cityscapes | mIoU | 78.2 | 78.1 | | |
+| deeplabv3 | deeplabv3_r50-d8_769x769_40k_cityscapes.py | cityscapes | mIoU | 78.5 | 78.3 | | |
+| deeplabv3+ | deeplabv3plus_r50-d8_769x769_40k_cityscapes.py | cityscapes | mIoU | 78.9 | 78.7 | | |
+
+:::{note}
+TensorRT is only available on configs with `whole mode`.
+:::
+
+### Convert to TorchScript (experimental)
+
+We also provide a script to convert model to [TorchScript](https://pytorch.org/docs/stable/jit.html) format. You can use the pytorch C++ API [LibTorch](https://pytorch.org/docs/stable/cpp_index.html) inference the trained model. The converted model could be visualized by tools like [Netron](https://github.com/lutzroeder/netron). Besides, we also support comparing the output results between PyTorch and TorchScript model.
+
+```shell
+python tools/pytorch2torchscript.py \
+ ${CONFIG_FILE} \
+ --checkpoint ${CHECKPOINT_FILE} \
+ --output-file ${ONNX_FILE}
+ --shape ${INPUT_SHAPE}
+ --verify \
+ --show
+```
+
+Description of arguments:
+
+- `config` : The path of a pytorch model config file.
+- `--checkpoint` : The path of a pytorch model checkpoint file.
+- `--output-file`: The path of output TorchScript model. If not specified, it will be set to `tmp.pt`.
+- `--input-img` : The path of an input image for conversion and visualize.
+- `--shape`: The height and width of input tensor to the model. If not specified, it will be set to `512 512`.
+- `--show`: Determines whether to print the traced graph of the exported model. If not specified, it will be set to `False`.
+- `--verify`: Determines whether to verify the correctness of an exported model. If not specified, it will be set to `False`.
+
+:::{note}
+It's only support PyTorch>=1.8.0 for now.
+:::
+
+:::{note}
+This tool is still experimental. Some customized operators are not supported for now.
+:::
+
+Examples:
+
+- Convert the cityscapes PSPNet pytorch model.
+
+ ```shell
+ python tools/pytorch2torchscript.py configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py \
+ --checkpoint checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth \
+ --output-file checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pt \
+ --shape 512 1024
+ ```
+
+### Convert to TensorRT (experimental)
+
+A script to convert [ONNX](https://github.com/onnx/onnx) model to [TensorRT](https://developer.nvidia.com/tensorrt) format.
+
+Prerequisite
+
+- install `mmcv-full` with ONNXRuntime custom ops and TensorRT plugins follow [ONNXRuntime in mmcv](https://mmcv.readthedocs.io/en/latest/deployment/onnxruntime_op.html) and [TensorRT plugin in mmcv](https://github.com/open-mmlab/mmcv/blob/master/docs/en/deployment/tensorrt_plugin.md).
+- Use [pytorch2onnx](#convert-to-onnx-experimental) to convert the model from PyTorch to ONNX.
+
+Usage
+
+```bash
+python ${MMSEG_PATH}/tools/onnx2tensorrt.py \
+ ${CFG_PATH} \
+ ${ONNX_PATH} \
+ --trt-file ${OUTPUT_TRT_PATH} \
+ --min-shape ${MIN_SHAPE} \
+ --max-shape ${MAX_SHAPE} \
+ --input-img ${INPUT_IMG} \
+ --show \
+ --verify
+```
+
+Description of all arguments
+
+- `config` : Config file of the model.
+- `model` : Path to the input ONNX model.
+- `--trt-file` : Path to the output TensorRT engine.
+- `--max-shape` : Maximum shape of model input.
+- `--min-shape` : Minimum shape of model input.
+- `--fp16` : Enable fp16 model conversion.
+- `--workspace-size` : Max workspace size in GiB.
+- `--input-img` : Image for visualize.
+- `--show` : Enable result visualize.
+- `--dataset` : Palette provider, `CityscapesDataset` as default.
+- `--verify` : Verify the outputs of ONNXRuntime and TensorRT.
+- `--verbose` : Whether to verbose logging messages while creating TensorRT engine. Defaults to False.
+
+:::{note}
+Only tested on whole mode.
+:::
+
+## Miscellaneous
+
+### Print the entire config
+
+`tools/print_config.py` prints the whole config verbatim, expanding all its
+ imports.
+
+```shell
+python tools/print_config.py \
+ ${CONFIG} \
+ --graph \
+ --cfg-options ${OPTIONS [OPTIONS...]} \
+```
+
+Description of arguments:
+
+- `config` : The path of a pytorch model config file.
+- `--graph` : Determines whether to print the models graph.
+- `--cfg-options`: Custom options to replace the config file.
+
+### Plot training logs
+
+`tools/analyze_logs.py` plots loss/mIoU curves given a training log file. `pip install seaborn` first to install the dependency.
+
+```shell
+python tools/analyze_logs.py xxx.log.json [--keys ${KEYS}] [--legend ${LEGEND}] [--backend ${BACKEND}] [--style ${STYLE}] [--out ${OUT_FILE}]
+```
+
+Examples:
+
+- Plot the mIoU, mAcc, aAcc metrics.
+
+ ```shell
+ python tools/analyze_logs.py log.json --keys mIoU mAcc aAcc --legend mIoU mAcc aAcc
+ ```
+
+- Plot loss metric.
+
+ ```shell
+ python tools/analyze_logs.py log.json --keys loss --legend loss
+ ```
+
+### Model conversion
+
+`tools/model_converters/` provide several scripts to convert pretrain models released by other repos to MMSegmentation style.
+
+#### ViT Swin MiT Transformer Models
+
+- ViT
+
+ `tools/model_converters/vit2mmseg.py` convert keys in timm pretrained vit models to MMSegmentation style.
+
+ ```shell
+ python tools/model_converters/vit2mmseg.py ${SRC} ${DST}
+ ```
+
+- Swin
+
+ `tools/model_converters/swin2mmseg.py` convert keys in official pretrained swin models to MMSegmentation style.
+
+ ```shell
+ python tools/model_converters/swin2mmseg.py ${SRC} ${DST}
+ ```
+
+- SegFormer
+
+ `tools/model_converters/mit2mmseg.py` convert keys in official pretrained mit models to MMSegmentation style.
+
+ ```shell
+ python tools/model_converters/mit2mmseg.py ${SRC} ${DST}
+ ```
+
+## Model Serving
+
+In order to serve an `MMSegmentation` model with [`TorchServe`](https://pytorch.org/serve/), you can follow the steps:
+
+### 1. Convert model from MMSegmentation to TorchServe
+
+```shell
+python tools/torchserve/mmseg2torchserve.py ${CONFIG_FILE} ${CHECKPOINT_FILE} \
+--output-folder ${MODEL_STORE} \
+--model-name ${MODEL_NAME}
+```
+
+:::{note}
+${MODEL_STORE} needs to be an absolute path to a folder.
+:::
+
+### 2. Build `mmseg-serve` docker image
+
+```shell
+docker build -t mmseg-serve:latest docker/serve/
+```
+
+### 3. Run `mmseg-serve`
+
+Check the official docs for [running TorchServe with docker](https://github.com/pytorch/serve/blob/master/docker/README.md#running-torchserve-in-a-production-docker-environment).
+
+In order to run in GPU, you need to install [nvidia-docker](https://docs.nvidia.com/datacenter/cloud-native/container-toolkit/install-guide.html). You can omit the `--gpus` argument in order to run in CPU.
+
+Example:
+
+```shell
+docker run --rm \
+--cpus 8 \
+--gpus device=0 \
+-p8080:8080 -p8081:8081 -p8082:8082 \
+--mount type=bind,source=$MODEL_STORE,target=/home/model-server/model-store \
+mmseg-serve:latest
+```
+
+[Read the docs](https://github.com/pytorch/serve/blob/072f5d088cce9bb64b2a18af065886c9b01b317b/docs/rest_api.md) about the Inference (8080), Management (8081) and Metrics (8082) APIs
+
+### 4. Test deployment
+
+```shell
+curl -O https://raw.githubusercontent.com/open-mmlab/mmsegmentation/master/resources/3dogs.jpg
+curl http://127.0.0.1:8080/predictions/${MODEL_NAME} -T 3dogs.jpg -o 3dogs_mask.png
+```
+
+The response will be a ".png" mask.
+
+You can visualize the output as follows:
+
+```python
+import matplotlib.pyplot as plt
+import mmcv
+plt.imshow(mmcv.imread("3dogs_mask.png", "grayscale"))
+plt.show()
+```
+
+You should see something similar to:
+
+
+
+And you can use `test_torchserve.py` to compare result of torchserve and pytorch, and visualize them.
+
+```shell
+python tools/torchserve/test_torchserve.py ${IMAGE_FILE} ${CONFIG_FILE} ${CHECKPOINT_FILE} ${MODEL_NAME}
+[--inference-addr ${INFERENCE_ADDR}] [--result-image ${RESULT_IMAGE}] [--device ${DEVICE}]
+```
+
+Example:
+
+```shell
+python tools/torchserve/test_torchserve.py \
+demo/demo.png \
+configs/fcn/fcn_r50-d8_512x1024_40k_cityscapes.py \
+checkpoint/fcn_r50-d8_512x1024_40k_cityscapes_20200604_192608-efe53f0d.pth \
+fcn
+```
+
+## Confusion Matrix
+
+In order to generate and plot a ```nxn``` confusion matrix where ```n``` is the number of classes, you can follow the steps:
+
+### 1.Generate a prediction result in pkl format using `test.py`
+
+```shell
+python tools/test.py ${CONFIG_FILE} ${CHECKPOINT_FILE} [--out ${PATH_TO_RESULT_FILE}]
+```
+
+Note that the argument for ```--eval``` should be ```None``` so that the result file contains numpy type of prediction results. The usage for distribution test is just the same.
+
+Example:
+
+```shell
+python tools/test.py \
+configs/fcn/fcn_r50-d8_512x1024_40k_cityscapes.py \
+checkpoint/fcn_r50-d8_512x1024_40k_cityscapes_20200604_192608-efe53f0d.pth \
+--out result/pred_result.pkl
+```
+
+### 2. Use ```confusion_matrix.py``` to generate and plot a confusion matrix
+
+```shell
+python tools/confusion_matrix.py ${CONFIG_FILE} ${PATH_TO_RESULT_FILE} ${SAVE_DIR} --show
+```
+
+Description of arguments:
+
+- `config`: Path to the test config file.
+- `prediction_path`: Path to the prediction .pkl result.
+- `save_dir`: Directory where confusion matrix will be saved.
+- `--show`: Enable result visualize.
+- `--color-theme`: Theme of the matrix color map.
+- `--cfg_options`: Custom options to replace the config file.
+
+Example:
+
+```shell
+python tools/confusion_matrix.py \
+configs/fcn/fcn_r50-d8_512x1024_40k_cityscapes.py \
+result/pred_result.pkl \
+result/confusion_matrix \
+--show
+```
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/Makefile b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/Makefile
new file mode 100644
index 0000000000000000000000000000000000000000..d4bb2cbb9eddb1bb1b4f366623044af8e4830919
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/Makefile
@@ -0,0 +1,20 @@
+# Minimal makefile for Sphinx documentation
+#
+
+# You can set these variables from the command line, and also
+# from the environment for the first two.
+SPHINXOPTS ?=
+SPHINXBUILD ?= sphinx-build
+SOURCEDIR = .
+BUILDDIR = _build
+
+# Put it first so that "make" without argument is like "make help".
+help:
+ @$(SPHINXBUILD) -M help "$(SOURCEDIR)" "$(BUILDDIR)" $(SPHINXOPTS) $(O)
+
+.PHONY: help Makefile
+
+# Catch-all target: route all unknown targets to Sphinx using the new
+# "make mode" option. $(O) is meant as a shortcut for $(SPHINXOPTS).
+%: Makefile
+ @$(SPHINXBUILD) -M $@ "$(SOURCEDIR)" "$(BUILDDIR)" $(SPHINXOPTS) $(O)
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/_static/css/readthedocs.css b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/_static/css/readthedocs.css
new file mode 100644
index 0000000000000000000000000000000000000000..2e38d0880b4dd3ffbffb38272173a30a42cf538a
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/_static/css/readthedocs.css
@@ -0,0 +1,6 @@
+.header-logo {
+ background-image: url("../images/mmsegmentation.png");
+ background-size: 201px 40px;
+ height: 40px;
+ width: 201px;
+}
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/api.rst b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/api.rst
new file mode 100644
index 0000000000000000000000000000000000000000..8285841dc69d724f32d0816a8435566bfc5bd1fc
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/api.rst
@@ -0,0 +1,58 @@
+mmseg.apis
+--------------
+.. automodule:: mmseg.apis
+ :members:
+
+mmseg.core
+--------------
+
+seg
+^^^^^^^^^^
+.. automodule:: mmseg.core.seg
+ :members:
+
+evaluation
+^^^^^^^^^^
+.. automodule:: mmseg.core.evaluation
+ :members:
+
+utils
+^^^^^^^^^^
+.. automodule:: mmseg.core.utils
+ :members:
+
+mmseg.datasets
+--------------
+
+datasets
+^^^^^^^^^^
+.. automodule:: mmseg.datasets
+ :members:
+
+pipelines
+^^^^^^^^^^
+.. automodule:: mmseg.datasets.pipelines
+ :members:
+
+mmseg.models
+--------------
+
+segmentors
+^^^^^^^^^^
+.. automodule:: mmseg.models.segmentors
+ :members:
+
+backbones
+^^^^^^^^^^
+.. automodule:: mmseg.models.backbones
+ :members:
+
+decode_heads
+^^^^^^^^^^^^
+.. automodule:: mmseg.models.decode_heads
+ :members:
+
+losses
+^^^^^^^^^^
+.. automodule:: mmseg.models.losses
+ :members:
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/conf.py b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/conf.py
new file mode 100644
index 0000000000000000000000000000000000000000..353b0bc725d351bbd11cec2412c49d798bbeb4af
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/conf.py
@@ -0,0 +1,133 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+# Configuration file for the Sphinx documentation builder.
+#
+# This file only contains a selection of the most common options. For a full
+# list see the documentation:
+# https://www.sphinx-doc.org/en/master/usage/configuration.html
+
+# -- Path setup --------------------------------------------------------------
+
+# If extensions (or modules to document with autodoc) are in another directory,
+# add these directories to sys.path here. If the directory is relative to the
+# documentation root, use os.path.abspath to make it absolute, like shown here.
+#
+import os
+import subprocess
+import sys
+
+import pytorch_sphinx_theme
+
+sys.path.insert(0, os.path.abspath('../../'))
+
+# -- Project information -----------------------------------------------------
+
+project = 'MMSegmentation'
+copyright = '2020-2021, OpenMMLab'
+author = 'MMSegmentation Authors'
+version_file = '../../mmseg/version.py'
+
+
+def get_version():
+ with open(version_file, 'r') as f:
+ exec(compile(f.read(), version_file, 'exec'))
+ return locals()['__version__']
+
+
+# The full version, including alpha/beta/rc tags
+release = get_version()
+
+# -- General configuration ---------------------------------------------------
+
+# Add any Sphinx extension module names here, as strings. They can be
+# extensions coming with Sphinx (named 'sphinx.ext.*') or your custom
+# ones.
+extensions = [
+ 'sphinx.ext.autodoc', 'sphinx.ext.napoleon', 'sphinx.ext.viewcode',
+ 'sphinx_markdown_tables', 'sphinx_copybutton', 'myst_parser'
+]
+
+autodoc_mock_imports = [
+ 'matplotlib', 'pycocotools', 'mmseg.version', 'mmcv.ops'
+]
+
+# Ignore >>> when copying code
+copybutton_prompt_text = r'>>> |\.\.\. '
+copybutton_prompt_is_regexp = True
+
+# Add any paths that contain templates here, relative to this directory.
+templates_path = ['_templates']
+
+# The suffix(es) of source filenames.
+# You can specify multiple suffix as a list of string:
+#
+source_suffix = {
+ '.rst': 'restructuredtext',
+ '.md': 'markdown',
+}
+
+# The master toctree document.
+master_doc = 'index'
+
+# List of patterns, relative to source directory, that match files and
+# directories to ignore when looking for source files.
+# This pattern also affects html_static_path and html_extra_path.
+exclude_patterns = ['_build', 'Thumbs.db', '.DS_Store']
+
+# -- Options for HTML output -------------------------------------------------
+
+# The theme to use for HTML and HTML Help pages. See the documentation for
+# a list of builtin themes.
+#
+# html_theme = 'sphinx_rtd_theme'
+html_theme = 'pytorch_sphinx_theme'
+html_theme_path = [pytorch_sphinx_theme.get_html_theme_path()]
+html_theme_options = {
+ 'logo_url':
+ 'https://mmsegmentation.readthedocs.io/zh-CN/latest/',
+ 'menu': [
+ {
+ 'name':
+ '教程',
+ 'url':
+ 'https://github.com/open-mmlab/mmsegmentation/blob/master/'
+ 'demo/MMSegmentation_Tutorial.ipynb'
+ },
+ {
+ 'name': 'GitHub',
+ 'url': 'https://github.com/open-mmlab/mmsegmentation'
+ },
+ {
+ 'name':
+ '上游库',
+ 'children': [
+ {
+ 'name': 'MMCV',
+ 'url': 'https://github.com/open-mmlab/mmcv',
+ 'description': '基础视觉库'
+ },
+ ]
+ },
+ ],
+ # Specify the language of shared menu
+ 'menu_lang':
+ 'cn',
+}
+
+# Add any paths that contain custom static files (such as style sheets) here,
+# relative to this directory. They are copied after the builtin static files,
+# so a file named "default.css" will overwrite the builtin "default.css".
+html_static_path = ['_static']
+html_css_files = ['css/readthedocs.css']
+
+# Enable ::: for my_st
+myst_enable_extensions = ['colon_fence']
+
+language = 'zh-CN'
+
+
+def builder_inited_handler(app):
+ subprocess.run(['./stat.py'])
+
+
+def setup(app):
+ app.connect('builder-inited', builder_inited_handler)
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/dataset_prepare.md b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/dataset_prepare.md
new file mode 100644
index 0000000000000000000000000000000000000000..5df5881603000f7760c7d0e0820b13a3b37db1ee
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/dataset_prepare.md
@@ -0,0 +1,318 @@
+## 准备数据集
+
+推荐用软链接,将数据集根目录链接到 `$MMSEGMENTATION/data` 里。如果您的文件夹结构是不同的,您也许可以试着修改配置文件里对应的路径。
+
+```none
+mmsegmentation
+├── mmseg
+├── tools
+├── configs
+├── data
+│ ├── cityscapes
+│ │ ├── leftImg8bit
+│ │ │ ├── train
+│ │ │ ├── val
+│ │ ├── gtFine
+│ │ │ ├── train
+│ │ │ ├── val
+│ ├── VOCdevkit
+│ │ ├── VOC2012
+│ │ │ ├── JPEGImages
+│ │ │ ├── SegmentationClass
+│ │ │ ├── ImageSets
+│ │ │ │ ├── Segmentation
+│ │ ├── VOC2010
+│ │ │ ├── JPEGImages
+│ │ │ ├── SegmentationClassContext
+│ │ │ ├── ImageSets
+│ │ │ │ ├── SegmentationContext
+│ │ │ │ │ ├── train.txt
+│ │ │ │ │ ├── val.txt
+│ │ │ ├── trainval_merged.json
+│ │ ├── VOCaug
+│ │ │ ├── dataset
+│ │ │ │ ├── cls
+│ ├── ade
+│ │ ├── ADEChallengeData2016
+│ │ │ ├── annotations
+│ │ │ │ ├── training
+│ │ │ │ ├── validation
+│ │ │ ├── images
+│ │ │ │ ├── training
+│ │ │ │ ├── validation
+│ ├── CHASE_DB1
+│ │ ├── images
+│ │ │ ├── training
+│ │ │ ├── validation
+│ │ ├── annotations
+│ │ │ ├── training
+│ │ │ ├── validation
+│ ├── DRIVE
+│ │ ├── images
+│ │ │ ├── training
+│ │ │ ├── validation
+│ │ ├── annotations
+│ │ │ ├── training
+│ │ │ ├── validation
+│ ├── HRF
+│ │ ├── images
+│ │ │ ├── training
+│ │ │ ├── validation
+│ │ ├── annotations
+│ │ │ ├── training
+│ │ │ ├── validation
+│ ├── STARE
+│ │ ├── images
+│ │ │ ├── training
+│ │ │ ├── validation
+│ │ ├── annotations
+│ │ │ ├── training
+│ │ │ ├── validation
+| ├── dark_zurich
+| │ ├── gps
+| │ │ ├── val
+| │ │ └── val_ref
+| │ ├── gt
+| │ │ └── val
+| │ ├── LICENSE.txt
+| │ ├── lists_file_names
+| │ │ ├── val_filenames.txt
+| │ │ └── val_ref_filenames.txt
+| │ ├── README.md
+| │ └── rgb_anon
+| │ | ├── val
+| │ | └── val_ref
+| ├── NighttimeDrivingTest
+| | ├── gtCoarse_daytime_trainvaltest
+| | │ └── test
+| | │ └── night
+| | └── leftImg8bit
+| | | └── test
+| | | └── night
+│ ├── loveDA
+│ │ ├── img_dir
+│ │ │ ├── train
+│ │ │ ├── val
+│ │ │ ├── test
+│ │ ├── ann_dir
+│ │ │ ├── train
+│ │ │ ├── val
+│ ├── potsdam
+│ │ ├── img_dir
+│ │ │ ├── train
+│ │ │ ├── val
+│ │ ├── ann_dir
+│ │ │ ├── train
+│ │ │ ├── val
+│ ├── vaihingen
+│ │ ├── img_dir
+│ │ │ ├── train
+│ │ │ ├── val
+│ │ ├── ann_dir
+│ │ │ ├── train
+│ │ │ ├── val
+│ ├── iSAID
+│ │ ├── img_dir
+│ │ │ ├── train
+│ │ │ ├── val
+│ │ │ ├── test
+│ │ ├── ann_dir
+│ │ │ ├── train
+│ │ │ ├── val
+```
+
+### Cityscapes
+
+注册成功后,数据集可以在 [这里](https://www.cityscapes-dataset.com/downloads/) 下载。
+
+通常情况下,`**labelTrainIds.png` 被用来训练 cityscapes。
+基于 [cityscapesscripts](https://github.com/mcordts/cityscapesScripts),
+我们提供了一个 [脚本](https://github.com/open-mmlab/mmsegmentation/blob/master/tools/convert_datasets/cityscapes.py),
+去生成 `**labelTrainIds.png`。
+
+```shell
+# --nproc 8 意味着有 8 个进程用来转换,它也可以被忽略。
+python tools/convert_datasets/cityscapes.py data/cityscapes --nproc 8
+```
+
+### Pascal VOC
+
+Pascal VOC 2012 可以在 [这里](http://host.robots.ox.ac.uk/pascal/VOC/voc2012/VOCtrainval_11-May-2012.tar) 下载。
+此外,许多最近在 Pascal VOC 数据集上的工作都会利用增广的数据,它们可以在 [这里](http://www.eecs.berkeley.edu/Research/Projects/CS/vision/grouping/semantic_contours/benchmark.tgz) 找到。
+
+如果您想使用增广后的 VOC 数据集,请运行下面的命令来将数据增广的标注转成正确的格式。
+
+```shell
+# --nproc 8 意味着有 8 个进程用来转换,它也可以被忽略。
+python tools/convert_datasets/voc_aug.py data/VOCdevkit data/VOCdevkit/VOCaug --nproc 8
+```
+
+关于如何拼接数据集 (concatenate) 并一起训练它们,更多细节请参考 [拼接连接数据集](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/zh_cn/tutorials/customize_datasets.md#%E6%8B%BC%E6%8E%A5%E6%95%B0%E6%8D%AE%E9%9B%86) 。
+
+### ADE20K
+
+ADE20K 的训练集和验证集可以在 [这里](http://data.csail.mit.edu/places/ADEchallenge/ADEChallengeData2016.zip) 下载。
+您还可以在 [这里](http://data.csail.mit.edu/places/ADEchallenge/release_test.zip) 下载验证集。
+
+### Pascal Context
+
+Pascal Context 的训练集和验证集可以在 [这里](http://host.robots.ox.ac.uk/pascal/VOC/voc2010/VOCtrainval_03-May-2010.tar) 下载。
+注册成功后,您还可以在 [这里](http://host.robots.ox.ac.uk:8080/eval/downloads/VOC2010test.tar) 下载验证集。
+
+为了从原始数据集里切分训练集和验证集, 您可以在 [这里](https://codalabuser.blob.core.windows.net/public/trainval_merged.json)
+下载 trainval_merged.json。
+
+如果您想使用 Pascal Context 数据集,
+请安装 [细节](https://github.com/zhanghang1989/detail-api) 然后再运行如下命令来把标注转换成正确的格式。
+
+```shell
+python tools/convert_datasets/pascal_context.py data/VOCdevkit data/VOCdevkit/VOC2010/trainval_merged.json
+```
+
+### CHASE DB1
+
+CHASE DB1 的训练集和验证集可以在 [这里](https://staffnet.kingston.ac.uk/~ku15565/CHASE_DB1/assets/CHASEDB1.zip) 下载。
+
+为了将 CHASE DB1 数据集转换成 MMSegmentation 的格式,您需要运行如下命令:
+
+```shell
+python tools/convert_datasets/chase_db1.py /path/to/CHASEDB1.zip
+```
+
+这个脚本将自动生成正确的文件夹结构。
+
+### DRIVE
+
+DRIVE 的训练集和验证集可以在 [这里](https://drive.grand-challenge.org/) 下载。
+在此之前,您需要注册一个账号,当前 '1st_manual' 并未被官方提供,因此需要您从其他地方获取。
+
+为了将 DRIVE 数据集转换成 MMSegmentation 格式,您需要运行如下命令:
+
+```shell
+python tools/convert_datasets/drive.py /path/to/training.zip /path/to/test.zip
+```
+
+这个脚本将自动生成正确的文件夹结构。
+
+### HRF
+
+首先,下载 [healthy.zip](https://www5.cs.fau.de/fileadmin/research/datasets/fundus-images/healthy.zip) [glaucoma.zip](https://www5.cs.fau.de/fileadmin/research/datasets/fundus-images/glaucoma.zip), [diabetic_retinopathy.zip](https://www5.cs.fau.de/fileadmin/research/datasets/fundus-images/diabetic_retinopathy.zip), [healthy_manualsegm.zip](https://www5.cs.fau.de/fileadmin/research/datasets/fundus-images/healthy_manualsegm.zip), [glaucoma_manualsegm.zip](https://www5.cs.fau.de/fileadmin/research/datasets/fundus-images/glaucoma_manualsegm.zip) 以及 [diabetic_retinopathy_manualsegm.zip](https://www5.cs.fau.de/fileadmin/research/datasets/fundus-images/diabetic_retinopathy_manualsegm.zip) 。
+
+为了将 HRF 数据集转换成 MMSegmentation 格式,您需要运行如下命令:
+
+```shell
+python tools/convert_datasets/hrf.py /path/to/healthy.zip /path/to/healthy_manualsegm.zip /path/to/glaucoma.zip /path/to/glaucoma_manualsegm.zip /path/to/diabetic_retinopathy.zip /path/to/diabetic_retinopathy_manualsegm.zip
+```
+
+这个脚本将自动生成正确的文件夹结构。
+
+### STARE
+
+首先,下载 [stare-images.tar](http://cecas.clemson.edu/~ahoover/stare/probing/stare-images.tar), [labels-ah.tar](http://cecas.clemson.edu/~ahoover/stare/probing/labels-ah.tar) 和 [labels-vk.tar](http://cecas.clemson.edu/~ahoover/stare/probing/labels-vk.tar) 。
+
+为了将 STARE 数据集转换成 MMSegmentation 格式,您需要运行如下命令:
+
+```shell
+python tools/convert_datasets/stare.py /path/to/stare-images.tar /path/to/labels-ah.tar /path/to/labels-vk.tar
+```
+
+这个脚本将自动生成正确的文件夹结构。
+
+### Dark Zurich
+
+因为我们只支持在此数据集上测试模型,所以您只需下载[验证集](https://data.vision.ee.ethz.ch/csakarid/shared/GCMA_UIoU/Dark_Zurich_val_anon.zip) 。
+
+### Nighttime Driving
+
+因为我们只支持在此数据集上测试模型,所以您只需下载[测试集](http://data.vision.ee.ethz.ch/daid/NighttimeDriving/NighttimeDrivingTest.zip) 。
+
+### LoveDA
+
+可以从 Google Drive 里下载 [LoveDA数据集](https://drive.google.com/drive/folders/1ibYV0qwn4yuuh068Rnc-w4tPi0U0c-ti?usp=sharing) 。
+
+或者它还可以从 [zenodo](https://zenodo.org/record/5706578#.YZvN7SYRXdF) 下载, 您需要运行如下命令:
+
+```shell
+# Download Train.zip
+wget https://zenodo.org/record/5706578/files/Train.zip
+# Download Val.zip
+wget https://zenodo.org/record/5706578/files/Val.zip
+# Download Test.zip
+wget https://zenodo.org/record/5706578/files/Test.zip
+```
+
+对于 LoveDA 数据集,请运行以下命令下载并重新组织数据集
+
+```shell
+python tools/convert_datasets/loveda.py /path/to/loveDA
+```
+
+请参照 [这里](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/zh_cn/inference.md) 来使用训练好的模型去预测 LoveDA 测试集并且提交到官网。
+
+关于 LoveDA 的更多细节可以在[这里](https://github.com/Junjue-Wang/LoveDA) 找到。
+
+### ISPRS Potsdam
+
+[Potsdam](https://www2.isprs.org/commissions/comm2/wg4/benchmark/2d-sem-label-potsdam/)
+数据集是一个有着2D 语义分割内容标注的城市遥感数据集。
+数据集可以从挑战[主页](https://www2.isprs.org/commissions/comm2/wg4/benchmark/data-request-form/) 获得。
+需要其中的 '2_Ortho_RGB.zip' 和 '5_Labels_all_noBoundary.zip'。
+
+对于 Potsdam 数据集,请运行以下命令下载并重新组织数据集
+
+```shell
+python tools/convert_datasets/potsdam.py /path/to/potsdam
+```
+
+使用我们默认的配置, 将生成 3456 张图片的训练集和 2016 张图片的验证集。
+
+### ISPRS Vaihingen
+
+[Vaihingen](https://www2.isprs.org/commissions/comm2/wg4/benchmark/2d-sem-label-vaihingen/)
+数据集是一个有着2D 语义分割内容标注的城市遥感数据集。
+
+数据集可以从挑战 [主页](https://www2.isprs.org/commissions/comm2/wg4/benchmark/data-request-form/).
+需要其中的 'ISPRS_semantic_labeling_Vaihingen.zip' 和 'ISPRS_semantic_labeling_Vaihingen_ground_truth_eroded_COMPLETE.zip'。
+
+对于 Vaihingen 数据集,请运行以下命令下载并重新组织数据集
+
+```shell
+python tools/convert_datasets/vaihingen.py /path/to/vaihingen
+```
+
+使用我们默认的配置 (`clip_size`=512, `stride_size`=256), 将生成 344 张图片的训练集和 398 张图片的验证集。
+
+### iSAID
+iSAID 数据集(训练集/验证集/测试集)的图像可以从 [DOTA-v1.0](https://captain-whu.github.io/DOTA/dataset.html) 下载.
+
+iSAID 数据集(训练集/验证集)的注释可以从 [iSAID](https://captain-whu.github.io/iSAID/dataset.html) 下载.
+
+该数据集是一个大规模的实例分割(也可以用于语义分割)的遥感数据集.
+
+下载后,在数据集转换前,您需要将数据集文件夹调整成如下格式.
+
+```
+│ ├── iSAID
+│ │ ├── train
+│ │ │ ├── images
+│ │ │ │ ├── part1.zip
+│ │ │ │ ├── part2.zip
+│ │ │ │ ├── part3.zip
+│ │ │ ├── Semantic_masks
+│ │ │ │ ├── images.zip
+│ │ ├── val
+│ │ │ ├── images
+│ │ │ │ ├── part1.zip
+│ │ │ ├── Semantic_masks
+│ │ │ │ ├── images.zip
+│ │ ├── test
+│ │ │ ├── images
+│ │ │ │ ├── part1.zip
+│ │ │ │ ├── part2.zip
+```
+
+```shell
+python tools/convert_datasets/isaid.py /path/to/iSAID
+```
+
+使用我们默认的配置 (`patch_width`=896, `patch_height`=896, `overlap_area`=384), 将生成 33978 张图片的训练集和 11644 张图片的验证集。
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/faq.md b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/faq.md
new file mode 100644
index 0000000000000000000000000000000000000000..7272f5909a28bc1730ba9bcb0f313a01f6b0f62b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/faq.md
@@ -0,0 +1,8 @@
+# 常见问题解答(FAQ)
+
+我们在这里列出了使用时的一些常见问题及其相应的解决方案。 如果您发现有一些问题被遗漏,请随时提 PR 丰富这个列表。 如果您无法在此获得帮助,请使用 [issue模板](https://github.com/open-mmlab/mmsegmentation/blob/master/.github/ISSUE_TEMPLATE/error-report.md/ )创建问题,但是请在模板中填写所有必填信息,这有助于我们更快定位问题。
+
+## 如何获知模型训练时需要的显卡数量
+
+- 看模型的config文件的命名。可以参考[学习配置文件](https://github.com/open-mmlab/mmsegmentation/blob/master/docs/zh_cn/tutorials/config.md )中的`配置文件命名风格`部分。比如,对于名字为`segformer_mit-b0_8x1_1024x1024_160k_cityscapes.py`的config文件,`8x1`代表训练其对应的模型需要的卡数为8,每张卡中的batch size为1。
+- 看模型的log文件。点开该模型的log文件,并在其中搜索`nGPU`,在`nGPU`后的数字个数即训练时所需的卡数。比如,在log文件中搜索`nGPU`得到`nGPU 0,1,2,3,4,5,6,7`的记录,则说明训练该模型需要使用八张卡。
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/get_started.md b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/get_started.md
new file mode 100644
index 0000000000000000000000000000000000000000..5c82152839602c79eb2dfef2c050f379f65b4d60
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/get_started.md
@@ -0,0 +1,247 @@
+## 依赖
+
+- Linux or macOS (Windows下支持需要 mmcv-full,但运行时可能会有一些问题。)
+- Python 3.6+
+- PyTorch 1.3+
+- CUDA 9.2+ (如果您基于源文件编译 PyTorch, CUDA 9.0也可以使用)
+- GCC 5+
+- [MMCV](https://mmcv.readthedocs.io/en/latest/#installation)
+
+可编译的 MMSegmentation 和 MMCV 版本如下所示,请对照对应版本安装以避免安装问题。
+
+| MMSegmentation 版本 | MMCV 版本 | MMClassification 版本 |
+|:-----------------:|:--------------------------:|:------------------------:|
+| master | mmcv-full>=1.4.4, <=1.6.0 | mmcls>=0.20.1, <=1.0.0 |
+| 0.24.1 | mmcv-full>=1.4.4, <=1.6.0 | mmcls>=0.20.1, <=1.0.0 |
+| 0.23.0 | mmcv-full>=1.4.4, <=1.6.0 | mmcls>=0.20.1, <=1.0.0 |
+| 0.22.0 | mmcv-full>=1.4.4, <=1.6.0 | mmcls>=0.20.1, <=1.0.0 |
+| 0.21.1 | mmcv-full>=1.4.4, <=1.6.0 | Not required |
+| 0.20.2 | mmcv-full>=1.3.13, <=1.6.0 | Not required |
+| 0.19.0 | mmcv-full>=1.3.13, <1.3.17 | Not required |
+| 0.18.0 | mmcv-full>=1.3.13, <1.3.17 | Not required |
+| 0.17.0 | mmcv-full>=1.3.7, <1.3.17 | Not required |
+| 0.16.0 | mmcv-full>=1.3.7, <1.3.17 | Not required |
+| 0.15.0 | mmcv-full>=1.3.7, <1.3.17 | Not required |
+| 0.14.1 | mmcv-full>=1.3.7, <1.3.17 | Not required |
+| 0.14.0 | mmcv-full>=1.3.1, <1.3.2 | Not required |
+| 0.13.0 | mmcv-full>=1.3.1, <1.3.2 | Not required |
+| 0.12.0 | mmcv-full>=1.1.4, <1.3.2 | Not required |
+| 0.11.0 | mmcv-full>=1.1.4, <1.3.0 | Not required |
+| 0.10.0 | mmcv-full>=1.1.4, <1.3.0 | Not required |
+| 0.9.0 | mmcv-full>=1.1.4, <1.3.0 | Not required |
+| 0.8.0 | mmcv-full>=1.1.4, <1.2.0 | Not required |
+| 0.7.0 | mmcv-full>=1.1.2, <1.2.0 | Not required |
+| 0.6.0 | mmcv-full>=1.1.2, <1.2.0 | Not required |
+
+注意: 如果您已经安装好 mmcv, 您首先需要运行 `pip uninstall mmcv`。
+如果 mmcv 和 mmcv-full 同时被安装,会报错 `ModuleNotFoundError`。
+
+## 安装
+
+a. 创建一个 conda 虚拟环境并激活它
+
+```shell
+conda create -n open-mmlab python=3.10 -y
+conda activate open-mmlab
+
+```
+
+b. 按照[官方教程](https://pytorch.org/) 安装 PyTorch 和 totchvision,
+这里我们使用 PyTorch1.11.0 和 CUDA11.3,
+您也可以切换至其他版本
+
+```shell
+conda install pytorch=1.11.0 torchvision cudatoolkit=11.3 -c pytorch
+```
+
+c. 按照 [官方教程](https://mmcv.readthedocs.io/en/latest/#installation)
+安装 [MMCV](https://mmcv.readthedocs.io/en/latest/) ,
+`mmcv` 或 `mmcv-full` 和 MMSegmentation 均兼容,但对于 CCNet 和 PSANet,`mmcv-full` 里的 CUDA 运算是必须的
+
+**在 Linux 下安装 mmcv:**
+
+为了安装 MMCV, 我们推荐使用下面的这种预编译好的 MMCV.
+
+```shell
+pip install mmcv-full -f https://download.openmmlab.com/mmcv/dist/{cu_version}/{torch_version}/index.html
+```
+
+请替换 url 里面的 ``{cu_version}`` 和 ``{torch_version}`` 为您想要使用的版本. mmcv-full 仅在
+PyTorch 1.x.0 上面编译, 因为在 1.x.0 和 1.x.1 之间通常是兼容的. 如果您的 PyTorch 版本是 1.x.1,
+您可以安装用 PyTorch 1.x.0 编译的 mmcv-full 而它通常是可以正常使用的.
+例如, 用 ``CUDA 11.1`` and ``PyTorch 1.11.0`` 安装使用 ``mmcv-full``, 使用如下命令:
+
+```shell
+pip install mmcv-full -f https://download.openmmlab.com/mmcv/dist/cu113/torch1.11/index.html
+```
+
+请查看 [这里](https://github.com/open-mmlab/mmcv#installation) 来找到适配不同 PyTorch 和 CUDA 版本的 MMCV.
+
+您也可以采用下面的命令来从源码编译 MMCV (可选)
+
+```shell
+git clone https://github.com/open-mmlab/mmcv.git
+cd mmcv
+MMCV_WITH_OPS=1 pip install -e . # package mmcv-full, which contains cuda ops, will be installed after this step
+# OR pip install -e . # package mmcv, which contains no cuda ops, will be installed after this step
+cd ..
+```
+
+**重点:** 如果您已经安装了 MMCV, 您需要先运行 `pip uninstall mmcv`. 因为如果 `mmcv` 和 `mmcv-full` 被同时安装, 将会报错 `ModuleNotFoundError`.
+
+
+**在 Windows 下安装 mmcv (有风险):**
+
+对于 Windows, MMCV 的安装需要本地 C++ 编译工具, 例如 cl.exe。 请添加编译工具至 %PATH%。
+
+如果您已经在电脑上安装好Windows SDK 和 Visual Studio,cl.exe 的一个典型路径看起来如下:
+
+```shell
+C:\Program Files (x86)\Microsoft Visual Studio\2019\Professional\VC\Tools\MSVC\14.26.28801\bin\Hostx86\x64
+```
+
+或者您需要从网上下载 cl 编译工具并安装至路径。
+
+随后,从 github 克隆 mmcv 并通过 pip 安装:
+
+```shell
+git clone https://github.com/open-mmlab/mmcv.git
+cd mmcv
+pip install -e .
+```
+
+或直接:
+
+```shell
+pip install mmcv
+```
+
+当前,mmcv-full 并不完全在 windows 上支持。
+
+d. 安装 MMSegmentation
+
+```shell
+pip install mmsegmentation # 安装最新版本
+```
+
+或者
+
+```shell
+pip install git+https://github.com/open-mmlab/mmsegmentation.git # 安装 master 分支
+```
+
+此外,如果您想安装 `dev` 模式的 MMSegmentation, 运行如下命令:
+
+```shell
+git clone https://github.com/open-mmlab/mmsegmentation.git
+cd mmsegmentation
+pip install -e . # 或者 "python setup.py develop"
+```
+
+注意:
+
+1. 当在 windows 下训练和测试模型时,请确保路径下所有的'\\' 被替换成 '/',
+ 在 python 代码里可以使用`.replace('\\', '/')`处理路径的字符串
+2. `version+git_hash` 也将被保存进 meta 训练模型里,即0.5.0+c415a2e
+3. 当 MMsegmentation 以 `dev` 模式被安装时,本地对代码的修改将不需要重新安装即可产生作用
+4. 如果您想使用 `opencv-python-headless` 替换 `opencv-python`,您可以在安装 MMCV 前安装它
+5. 一些依赖项是可选的。简单的运行 `pip install -e .` 将仅安装最必要的一些依赖。为了使用可选的依赖项如`cityscapessripts`,
+ 要么手动使用 `pip install -r requirements/optional.txt` 安装,要么专门从pip下安装(即 `pip install -e .[optional]`,
+ 其中选项可设置为 `all`, `tests`, `build`, 和 `optional`)
+
+### 完整的安装脚本
+
+#### Linux
+
+这里便是一个完整安装 MMSegmentation 的脚本,使用 conda 并链接了数据集的路径(以您的数据集路径为 $DATA_ROOT 来安装)。
+
+```shell
+conda create -n open-mmlab python=3.10 -y
+conda activate open-mmlab
+
+conda install pytorch=1.11.0 torchvision cudatoolkit=11.3 -c pytorch
+pip install mmcv-full -f https://download.openmmlab.com/mmcv/dist/cu113/torch1.11.0/index.html
+git clone https://github.com/open-mmlab/mmsegmentation.git
+cd mmsegmentation
+pip install -e . # 或者 "python setup.py develop"
+
+mkdir data
+ln -s $DATA_ROOT data
+```
+
+#### Windows (有风险)
+
+这里便是一个完整安装 MMSegmentation 的脚本,使用 conda 并链接了数据集的路径(以您的数据集路径为 %DATA_ROOT% 来安装)。
+注意:它必须是一个绝对路径。
+
+```shell
+conda create -n open-mmlab python=3.10 -y
+conda activate open-mmlab
+
+conda install pytorch=1.11.0 torchvision cudatoolkit=11.3 -c pytorch
+set PATH=full\path\to\your\cpp\compiler;%PATH%
+pip install mmcv
+
+git clone https://github.com/open-mmlab/mmsegmentation.git
+cd mmsegmentation
+pip install -e . # 或者 "python setup.py develop"
+
+mklink /D data %DATA_ROOT%
+```
+
+#### 使用多版本 MMSegmentation 进行开发
+
+训练和测试脚本已经修改了 `PYTHONPATH` 来确保使用当前路径的MMSegmentation。
+
+为了使用当前环境默认安装的 MMSegmentation 而不是正在工作的 MMSegmentation,您可以在那些脚本里移除下面的内容:
+
+```shell
+PYTHONPATH="$(dirname $0)/..":$PYTHONPATH
+```
+
+## 验证
+
+为了验证 MMSegmentation 和它所需要的环境是否正确安装,我们可以使用样例 python 代码来初始化一个 segmentor 并推理一张 demo 图像。
+
+```python
+from mmseg.apis import inference_segmentor, init_segmentor
+import mmcv
+
+config_file = 'configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py'
+checkpoint_file = 'checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth'
+
+# 从一个 config 配置文件和 checkpoint 文件里创建分割模型
+model = init_segmentor(config_file, checkpoint_file, device='cuda:0')
+
+# 测试一张样例图片并得到结果
+img = 'test.jpg' # 或者 img = mmcv.imread(img), 这将只加载图像一次.
+result = inference_segmentor(model, img)
+# 在新的窗口里可视化结果
+model.show_result(img, result, show=True)
+# 或者保存图片文件的可视化结果
+# 您可以改变 segmentation map 的不透明度(opacity),在(0, 1]之间。
+model.show_result(img, result, out_file='result.jpg', opacity=0.5)
+
+# 测试一个视频并得到分割结果
+video = mmcv.VideoReader('video.mp4')
+for frame in video:
+ result = inference_segmentor(model, frame)
+ model.show_result(frame, result, wait_time=1)
+```
+
+当您完成 MMSegmentation 的安装时,上述代码应该可以成功运行。
+
+我们还提供一个 demo 脚本去可视化单张图片。
+
+```shell
+python demo/image_demo.py ${IMAGE_FILE} ${CONFIG_FILE} ${CHECKPOINT_FILE} [--device ${DEVICE_NAME}] [--palette-thr ${PALETTE}]
+```
+
+样例:
+
+```shell
+python demo/image_demo.py demo/demo.jpg configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py \
+ checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth --device cuda:0 --palette cityscapes
+```
+
+推理的 demo 文档可在此查询:[demo/inference_demo.ipynb](../demo/inference_demo.ipynb) 。
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/index.rst b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/index.rst
new file mode 100644
index 0000000000000000000000000000000000000000..4ac9211b62a258b5167ff98eea229ea4e4ec09ce
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/index.rst
@@ -0,0 +1,63 @@
+欢迎来到 MMSegmentation 的文档!
+=======================================
+
+.. toctree::
+ :maxdepth: 2
+ :caption: 开始你的第一步
+
+ get_started.md
+
+.. toctree::
+ :maxdepth: 1
+ :caption: 数据集准备
+
+ dataset_prepare.md
+
+.. toctree::
+ :maxdepth: 1
+ :caption: 模型库
+
+ model_zoo.md
+ modelzoo_statistics.md
+
+.. toctree::
+ :maxdepth: 2
+ :caption: 快速启动
+
+ train.md
+ inference.md
+
+.. toctree::
+ :maxdepth: 2
+ :caption: 教程
+
+ tutorials/index.rst
+
+.. toctree::
+ :maxdepth: 2
+ :caption: 实用工具与脚本
+
+ useful_tools.md
+
+.. toctree::
+ :maxdepth: 2
+ :caption: 说明
+
+ changelog.md
+ faq.md
+
+.. toctree::
+ :caption: 语言切换
+
+ switch_language.md
+
+.. toctree::
+ :caption: 接口文档(英文)
+
+ api.rst
+
+Indices and tables
+==================
+
+* :ref:`genindex`
+* :ref:`search`
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/inference.md b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/inference.md
new file mode 100644
index 0000000000000000000000000000000000000000..835872be92b0da55cb75e4190ab334ed24fad5a8
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/inference.md
@@ -0,0 +1,127 @@
+## 使用预训练模型推理
+
+我们提供测试脚本来评估完整数据集(Cityscapes, PASCAL VOC, ADE20k 等)上的结果,同时为了使其他项目的整合更容易,也提供一些高级 API。
+
+### 测试一个数据集
+
+- 单卡 GPU
+- CPU
+- 单节点多卡 GPU
+- 多节点
+
+您可以使用以下命令来测试一个数据集。
+
+```shell
+# 单卡 GPU 测试
+python tools/test.py ${配置文件} ${检查点文件} [--out ${结果文件}] [--eval ${评估指标}] [--show]
+
+# CPU: 如果机器没有 GPU, 则跟上述单卡 GPU 测试一致
+# CPU: 如果机器有 GPU, 那么先禁用 GPU 再运行单 GPU 测试脚本
+export CUDA_VISIBLE_DEVICES=-1 # 禁用 GPU
+python tools/test.py ${配置文件} ${检查点文件} [--out ${结果文件}] [--eval ${评估指标}] [--show]
+
+# 多卡GPU 测试
+./tools/dist_test.sh ${配置文件} ${检查点文件} ${GPU数目} [--out ${结果文件}] [--eval ${评估指标}]
+```
+
+可选参数:
+
+- `RESULT_FILE`: pickle 格式的输出结果的文件名,如果不专门指定,结果将不会被专门保存成文件。(MMseg v0.17 之后,args.out 将只会保存评估时的中间结果或者是分割图的保存路径。)
+- `EVAL_METRICS`: 在结果里将被评估的指标。这主要取决于数据集, `mIoU` 对于所有数据集都可获得,像 Cityscapes 数据集可以通过 `cityscapes` 命令来专门评估,就像标准的 `mIoU`一样。
+- `--show`: 如果被指定,分割结果将会在一张图像里画出来并且在另一个窗口展示。它仅仅是用来调试与可视化,并且仅针对单卡 GPU 测试。请确认 GUI 在您的环境里可用,否则您也许会遇到报错 `cannot connect to X server`
+- `--show-dir`: 如果被指定,分割结果将会在一张图像里画出来并且保存在指定文件夹里。它仅仅是用来调试与可视化,并且仅针对单卡GPU测试。使用该参数时,您的环境不需要 GUI。
+- `--eval-options`: 评估时的可选参数,当设置 `efficient_test=True` 时,它将会保存中间结果至本地文件里以节约 CPU 内存。请确认您本地硬盘有足够的存储空间(大于20GB)。(MMseg v0.17 之后,`efficient_test` 不再生效,我们重构了 test api,通过使用一种渐近式的方式来提升评估和保存结果的效率。)
+
+例子:
+
+假设您已经下载检查点文件至文件夹 `checkpoints/` 里。
+
+1. 测试 PSPNet 并可视化结果。按下任何键会进行到下一张图
+
+ ```shell
+ python tools/test.py configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py \
+ checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth \
+ --show
+ ```
+
+2. 测试 PSPNet 并保存画出的图以便于之后的可视化
+
+ ```shell
+ python tools/test.py configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py \
+ checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth \
+ --show-dir psp_r50_512x1024_40ki_cityscapes_results
+ ```
+
+3. 在数据集 PASCAL VOC (不保存测试结果) 上测试 PSPNet 并评估 mIoU
+
+ ```shell
+ python tools/test.py configs/pspnet/pspnet_r50-d8_512x1024_20k_voc12aug.py \
+ checkpoints/pspnet_r50-d8_512x1024_20k_voc12aug_20200605_003338-c57ef100.pth \
+ --eval mAP
+ ```
+
+4. 使用4卡 GPU 测试 PSPNet,并且在标准 mIoU 和 cityscapes 指标里评估模型
+
+ ```shell
+ ./tools/dist_test.sh configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py \
+ checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth \
+ 4 --out results.pkl --eval mIoU cityscapes
+ ```
+
+ 注意:在 cityscapes mIoU 和我们的 mIoU 指标会有一些差异 (~0.1%) 。因为 cityscapes 默认是根据类别样本数的多少进行加权平均,而我们对所有的数据集都是采取直接平均的方法来得到 mIoU。
+
+5. 在 cityscapes 数据集上4卡 GPU 测试 PSPNet, 并生成 png 文件以便提交给官方评估服务器
+
+ 首先,在配置文件里添加内容: `configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py`,
+
+ ```python
+ data = dict(
+ test=dict(
+ img_dir='leftImg8bit/test',
+ ann_dir='gtFine/test'))
+ ```
+
+ 随后,进行测试。
+
+ ```shell
+ ./tools/dist_test.sh configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py \
+ checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth \
+ 4 --format-only --eval-options "imgfile_prefix=./pspnet_test_results"
+ ```
+
+ 您会在文件夹 `./pspnet_test_results` 里得到生成的 png 文件。
+ 您也许可以运行 `zip -r results.zip pspnet_test_results/` 并提交 zip 文件给 [evaluation server](https://www.cityscapes-dataset.com/submit/) 。
+
+6. 在 Cityscapes 数据集上使用 CPU 高效内存选项来测试 DeeplabV3+ `mIoU` 指标 (没有保存测试结果)
+
+ ```shell
+ python tools/test.py \
+ configs/deeplabv3plus/deeplabv3plus_r18-d8_512x1024_80k_cityscapes.py \
+ deeplabv3plus_r18-d8_512x1024_80k_cityscapes_20201226_080942-cff257fe.pth \
+ --eval-options efficient_test=True \
+ --eval mIoU
+ ```
+
+ 使用 ```pmap``` 可查看 CPU 内存情况, ```efficient_test=True``` 会使用约 2.25GB 的 CPU 内存, ```efficient_test=False``` 会使用约 11.06GB 的 CPU 内存。 这个可选参数可以节约很多 CPU 内存。(MMseg v0.17 之后, `efficient_test` 参数将不再生效, 我们使用了一种渐近的方式来更加有效快速地评估和保存结果。)
+
+7. 在 LoveDA 数据集上1卡 GPU 测试 PSPNet, 并生成 png 文件以便提交给官方评估服务器
+
+ 首先,在配置文件里添加内容: `configs/pspnet/pspnet_r50-d8_512x512_80k_loveda.py`,
+
+ ```python
+ data = dict(
+ test=dict(
+ img_dir='img_dir/test',
+ ann_dir='ann_dir/test'))
+ ```
+
+ 随后,进行测试。
+
+ ```shell
+ python ./tools/test.py configs/pspnet/pspnet_r50-d8_512x512_80k_loveda.py \
+ checkpoints/pspnet_r50-d8_512x512_80k_loveda_20211104_155728-88610f9f.pth \
+ --format-only --eval-options "imgfile_prefix=./pspnet_test_results"
+ ```
+
+ 您会在文件夹 `./pspnet_test_results` 里得到生成的 png 文件。
+ 您也许可以运行 `zip -r -j Results.zip pspnet_test_results/` 并提交 zip 文件给 [evaluation server](https://codalab.lisn.upsaclay.fr/competitions/421) 。
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/make.bat b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/make.bat
new file mode 100644
index 0000000000000000000000000000000000000000..922152e96a04a242e6fc40f124261d74890617d8
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/make.bat
@@ -0,0 +1,35 @@
+@ECHO OFF
+
+pushd %~dp0
+
+REM Command file for Sphinx documentation
+
+if "%SPHINXBUILD%" == "" (
+ set SPHINXBUILD=sphinx-build
+)
+set SOURCEDIR=.
+set BUILDDIR=_build
+
+if "%1" == "" goto help
+
+%SPHINXBUILD% >NUL 2>NUL
+if errorlevel 9009 (
+ echo.
+ echo.The 'sphinx-build' command was not found. Make sure you have Sphinx
+ echo.installed, then set the SPHINXBUILD environment variable to point
+ echo.to the full path of the 'sphinx-build' executable. Alternatively you
+ echo.may add the Sphinx directory to PATH.
+ echo.
+ echo.If you don't have Sphinx installed, grab it from
+ echo.http://sphinx-doc.org/
+ exit /b 1
+)
+
+%SPHINXBUILD% -M %1 %SOURCEDIR% %BUILDDIR% %SPHINXOPTS% %O%
+goto end
+
+:help
+%SPHINXBUILD% -M help %SOURCEDIR% %BUILDDIR% %SPHINXOPTS% %O%
+
+:end
+popd
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/model_zoo.md b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/model_zoo.md
new file mode 100644
index 0000000000000000000000000000000000000000..bfcc4c15beb8eec0b3dd688ddd3cbcbcb67c7b64
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/model_zoo.md
@@ -0,0 +1,152 @@
+# 标准与模型库
+
+## 共同设定
+
+* 我们默认使用 4 卡分布式训练
+* 所有 PyTorch 风格的 ImageNet 预训练网络由我们自己训练,和 [论文](https://arxiv.org/pdf/1812.01187.pdf) 保持一致。
+ 我们的 ResNet 网络是基于 ResNetV1c 的变种,在这里输入层的 7x7 卷积被 3个 3x3 取代
+* 为了在不同的硬件上保持一致,我们以 `torch.cuda.max_memory_allocated()` 的最大值作为 GPU 占用率,同时设置 `torch.backends.cudnn.benchmark=False`。
+ 注意,这通常比 `nvidia-smi` 显示的要少
+* 我们以网络 forward 和后处理的时间加和作为推理时间,除去数据加载时间。我们使用脚本 `tools/benchmark.py` 来获取推理时间,它在 `torch.backends.cudnn.benchmark=False` 的设定下,计算 200 张图片的平均推理时间
+* 在框架中,有两种推理模式
+ * `slide` 模式(滑动模式):测试的配置文件字段 `test_cfg` 会是 `dict(mode='slide', crop_size=(769, 769), stride=(513, 513))`.
+ 在这个模式下,从原图中裁剪多个小图分别输入网络中进行推理。小图的大小和小图之间的距离由 `crop_size` 和 `stride` 决定,重合区域会进行平均
+ * `whole` 模式 (全图模式):测试的配置文件字段 `test_cfg` 会是 `dict(mode='whole')`. 在这个模式下,全图会被直接输入到网络中进行推理。
+ 对于 769x769 下训练的模型,我们默认使用 `slide` 进行推理,其余模型用 `whole` 进行推理
+* 对于输入大小为 8x+1 (比如769),我们使用 `align_corners=True`。其余情况,对于输入大小为 8x (比如 512,1024),我们使用 `align_corners=False`
+
+## 基线
+
+### FCN
+
+请参考 [FCN](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/fcn) 获得详细信息。
+
+### PSPNet
+
+请参考 [PSPNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/pspnet) 获得详细信息。
+
+### DeepLabV3
+
+请参考 [DeepLabV3](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3) 获得详细信息。
+
+### PSANet
+
+请参考 [PSANet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/psanet) 获得详细信息。
+
+### DeepLabV3+
+
+请参考 [DeepLabV3+](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/deeplabv3plus) 获得详细信息。
+
+### UPerNet
+
+请参考 [UPerNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/upernet) 获得详细信息。
+
+### NonLocal Net
+
+请参考 [NonLocal Net](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/nlnet) 获得详细信息。
+
+### EncNet
+
+请参考 [EncNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/encnet) 获得详细信息。
+
+### CCNet
+
+请参考 [CCNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ccnet) 获得详细信息。
+
+### DANet
+
+请参考 [DANet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/danet) 获得详细信息。
+
+### APCNet
+
+请参考 [APCNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/apcnet) 获得详细信息。
+
+### HRNet
+
+请参考 [HRNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/hrnet) 获得详细信息。
+
+### GCNet
+
+请参考 [GCNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/gcnet) 获得详细信息。
+
+### DMNet
+
+请参考 [DMNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/dmnet) 获得详细信息。
+
+### ANN
+
+请参考 [ANN](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ann) 获得详细信息。
+
+### OCRNet
+
+请参考 [OCRNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/ocrnet) 获得详细信息。
+
+### Fast-SCNN
+
+请参考 [Fast-SCNN](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/fastscnn) 获得详细信息。
+
+### ResNeSt
+
+请参考 [ResNeSt](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/resnest) 获得详细信息。
+
+### Semantic FPN
+
+请参考 [Semantic FPN](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/semfpn) 获得详细信息。
+
+### PointRend
+
+请参考 [PointRend](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/point_rend) 获得详细信息。
+
+### MobileNetV2
+
+请参考 [MobileNetV2](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/mobilenet_v2) 获得详细信息。
+
+### MobileNetV3
+
+请参考 [MobileNetV3](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/mobilenet_v3) 获得详细信息。
+
+### EMANet
+
+请参考 [EMANet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/emanet) 获得详细信息。
+
+### DNLNet
+
+请参考 [DNLNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/dnlnet) 获得详细信息。
+
+### CGNet
+
+请参考 [CGNet](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/cgnet) 获得详细信息。
+
+### Mixed Precision (FP16) Training
+
+请参考 [Mixed Precision (FP16) Training 在 BiSeNetV2 训练的样例](https://github.com/open-mmlab/mmsegmentation/blob/master/configs/bisenetv2/bisenetv2_fcn_fp16_4x4_1024x1024_160k_cityscapes.py) 获得详细信息。
+
+## 速度标定
+
+### 硬件
+
+* 8 NVIDIA Tesla V100 (32G) GPUs
+* Intel(R) Xeon(R) Gold 6148 CPU @ 2.40GHz
+
+### 软件环境
+
+* Python 3.7
+* PyTorch 1.5
+* CUDA 10.1
+* CUDNN 7.6.03
+* NCCL 2.4.08
+
+### 训练速度
+
+为了公平比较,我们全部使用 ResNet-101V1c 进行标定。输入大小为 1024x512,批量样本数为 2。
+
+训练速度如下表,指标为每次迭代的时间,以秒为单位,越低越快。
+
+| Implementation | PSPNet (s/iter) | DeepLabV3+ (s/iter) |
+|----------------|-----------------|---------------------|
+| [MMSegmentation](https://github.com/open-mmlab/mmsegmentation) | **0.83** | **0.85** |
+| [SegmenTron](https://github.com/LikeLy-Journey/SegmenTron) | 0.84 | 0.85 |
+| [CASILVision](https://github.com/CSAILVision/semantic-segmentation-pytorch) | 1.15 | N/A |
+| [vedaseg](https://github.com/Media-Smart/vedaseg) | 0.95 | 1.25 |
+
+注意:DeepLabV3+ 的输出步长为 8。
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/stat.py b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/stat.py
new file mode 100644
index 0000000000000000000000000000000000000000..b3a1d730693fdf218d10417fdeec227e38294b24
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/stat.py
@@ -0,0 +1,65 @@
+#!/usr/bin/env python
+# Copyright (c) OpenMMLab. All rights reserved.
+import functools as func
+import glob
+import os.path as osp
+import re
+
+import numpy as np
+
+url_prefix = 'https://github.com/open-mmlab/mmsegmentation/blob/master/'
+
+files = sorted(glob.glob('../../configs/*/README.md'))
+
+stats = []
+titles = []
+num_ckpts = 0
+
+for f in files:
+ url = osp.dirname(f.replace('../../', url_prefix))
+
+ with open(f, 'r') as content_file:
+ content = content_file.read()
+
+ title = content.split('\n')[0].replace('#', '').strip()
+ ckpts = set(x.lower().strip()
+ for x in re.findall(r'https?://download.*\.pth', content)
+ if 'mmsegmentation' in x)
+ if len(ckpts) == 0:
+ continue
+
+ _papertype = [
+ x for x in re.findall(r'', content)
+ ]
+ assert len(_papertype) > 0
+ papertype = _papertype[0]
+
+ paper = set([(papertype, title)])
+
+ titles.append(title)
+ num_ckpts += len(ckpts)
+ statsmsg = f"""
+\t* [{papertype}] [{title}]({url}) ({len(ckpts)} ckpts)
+"""
+ stats.append((paper, ckpts, statsmsg))
+
+allpapers = func.reduce(lambda a, b: a.union(b), [p for p, _, _ in stats])
+msglist = '\n'.join(x for _, _, x in stats)
+
+papertypes, papercounts = np.unique([t for t, _ in allpapers],
+ return_counts=True)
+countstr = '\n'.join(
+ [f' - {t}: {c}' for t, c in zip(papertypes, papercounts)])
+
+modelzoo = f"""
+# 模型库统计数据
+
+* 论文数量: {len(set(titles))}
+{countstr}
+
+* 模型数量: {num_ckpts}
+{msglist}
+"""
+
+with open('modelzoo_statistics.md', 'w') as f:
+ f.write(modelzoo)
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/switch_language.md b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/switch_language.md
new file mode 100644
index 0000000000000000000000000000000000000000..f58efc42be0d4c352db5d6af3c9ffef675a32e33
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/switch_language.md
@@ -0,0 +1,3 @@
+## English
+
+## 简体中文
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/train.md b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/train.md
new file mode 100644
index 0000000000000000000000000000000000000000..a54f28f03f97be7185f3d2c2c2bb965de114c4a2
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/train.md
@@ -0,0 +1,159 @@
+## 训练一个模型
+
+MMSegmentation 可以执行分布式训练和非分布式训练,分别使用 `MMDistributedDataParallel` 和 `MMDataParallel` 命令。
+
+所有的输出(日志 log 和检查点 checkpoints )将被保存到工作路径文件夹里,它可以通过配置文件里的 `work_dir` 指定。
+
+在一定迭代轮次后,我们默认在验证集上评估模型表现。您可以在训练配置文件中添加间隔参数来改变评估间隔。
+
+```python
+evaluation = dict(interval=4000) # 每4000 iterations 评估一次模型的性能
+```
+
+**\*重要提示\***: 在配置文件里的默认学习率是针对4卡 GPU 和2张图/GPU (此时 batchsize = 4x2 = 8)来设置的。
+同样,您也可以使用8卡 GPU 和 1张图/GPU 的设置,因为所有的模型均使用 cross-GPU 的 SyncBN 模式。
+
+我们可以在训练速度和 GPU 显存之间做平衡。当模型或者 Batch Size 比较大的时,可以传递`--cfg-options model.backbone.with_cp=True` ,使用 `with_cp` 来节省显存,但是速度会更慢,因为原先使用 `with_cp` 时,是逐层反向传播(Back Propagation, BP),不会保存所有的梯度。
+
+### 使用单台机器训练
+
+#### 使用单卡 GPU 训练
+
+```shell
+python tools/train.py ${CONFIG_FILE} [可选参数]
+```
+
+如果您想在命令里定义工作文件夹路径,您可以添加一个参数`--work-dir ${工作路径}`。
+
+#### 使用 CPU 训练
+
+如果计算机没有 GPU,那么使用 CPU 训练的流程和使用单 GPU 训练的流程一致。如果计算机有 GPU 但是想使用 CPU,我们仅需要在训练流程开始前禁用 GPU。
+
+```shell
+export CUDA_VISIBLE_DEVICES=-1
+```
+
+之后运行单 GPU 训练脚本即可。
+
+```{warning}
+我们不推荐用户使用 CPU 进行训练,这太过缓慢。我们支持这个功能是为了方便用户在没有 GPU 的机器上进行调试。
+```
+
+#### 使用多卡 GPU 训练
+
+```shell
+sh tools/dist_train.sh ${CONFIG_FILE} ${GPUS} [可选参数]
+```
+
+可选参数可以为:
+
+- `--no-validate` (**不推荐**): 训练时代码库默认会在每 k 轮迭代后在验证集上进行评估,如果不需评估使用命令 `--no-validate`
+- `--work-dir ${工作路径}`: 在配置文件里重写工作路径文件夹
+- `--resume-from ${检查点文件}`: 继续使用先前的检查点 (checkpoint) 文件(可以继续训练过程)
+- `--load-from ${检查点文件}`: 从一个检查点 (checkpoint) 文件里加载权重(对另一个任务进行精调)
+- `--deterministic`: 选择此模式会减慢训练速度,但结果易于复现
+
+`resume-from` 和 `load-from` 的区别:
+
+- `resume-from` 加载出模型权重和优化器状态包括迭代轮数等
+- `load-from` 仅加载模型权重,从第0轮开始训练
+
+示例:
+
+```shell
+# 模型的权重和日志将会存储在这个路径下: WORK_DIR=work_dirs/pspnet_r50-d8_512x512_80k_ade20k/
+# 如果work_dir没有被设定,它将会被自动生成
+sh tools/dist_train.sh configs/pspnet/pspnet_r50-d8_512x512_80k_ade20k.py 8 --work_dir work_dirs/pspnet_r50-d8_512x512_80k_ade20k/ --deterministic
+```
+
+**注意**: 在训练时,模型的和日志保存在“work_dirs/”下的配置文件的相同文件夹结构中。不建议使用自定义的“work_dirs/”,因为验证脚本可以从配置文件名中推断工作目录。如果你想在其他地方保存模型的权重,请使用符号链接,例如:
+
+```shell
+ln -s ${YOUR_WORK_DIRS} ${MMSEG}/work_dirs
+```
+
+#### 在单个机器上启动多个任务
+
+如果您在单个机器上启动多个任务,例如在8卡 GPU 的一个机器上有2个4卡 GPU 的训练任务,您需要特别对每个任务指定不同的端口(默认为29500)来避免通讯冲突。否则,将会有报错信息 `RuntimeError: Address already in use`。
+
+如果您使用命令 `dist_train.sh` 来启动一个训练任务,您可以在命令行的用环境变量 `PORT` 设置端口:
+
+```shell
+CUDA_VISIBLE_DEVICES=0,1,2,3 PORT=29500 sh tools/dist_train.sh ${CONFIG_FILE} 4
+CUDA_VISIBLE_DEVICES=4,5,6,7 PORT=29501 sh tools/dist_train.sh ${CONFIG_FILE} 4
+```
+
+### 使用多台机器训练
+
+如果您想使用由 ethernet 连接起来的多台机器, 您可以使用以下命令:
+
+在第一台机器上:
+
+```shell
+NNODES=2 NODE_RANK=0 PORT=$MASTER_PORT MASTER_ADDR=$MASTER_ADDR sh tools/dist_train.sh $CONFIG $GPUS
+```
+
+在第二台机器上:
+
+```shell
+NNODES=2 NODE_RANK=1 PORT=$MASTER_PORT MASTER_ADDR=$MASTER_ADDR sh tools/dist_train.sh $CONFIG $GPUS
+```
+
+但是,如果您不使用高速网路连接这几台机器的话,训练将会非常慢。
+
+### 使用slurm管理任务
+
+Slurm是一个很好的计算集群作业调度系统。在由Slurm管理的集群中,可以使用slurm_train.sh来进行训练。它同时支持单节点和多节点训练。
+
+在多台机器上训练:
+
+```shell
+[GPUS=${GPUS}] sh tools/slurm_train.sh ${PARTITION} ${JOB_NAME} ${CONFIG_FILE} --work-dir ${WORK_DIR}
+```
+
+这里有一个在dev分区上使用16块GPUs来训练PSPNet的例子:
+
+```shell
+GPUS=16 sh tools/slurm_train.sh dev pspr50 configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py work_dirs/pspnet_r50-d8_512x1024_40k_cityscapes/
+```
+
+当使用 `slurm_train.sh` 在一个节点上启动多个任务时,需要指定不同的端口号,这里提供了三种设置:
+
+方式1:
+
+在`config1.py`中设置:
+
+```python
+dist_params = dict(backend='nccl', port=29500)
+```
+
+在`config2.py`中设置:
+
+```python
+dist_params = dict(backend='nccl', port=29501)
+```
+
+然后就可以使用config1.py和config2.py启动两个作业:
+
+```shell
+CUDA_VISIBLE_DEVICES=0,1,2,3 GPUS=4 sh tools/slurm_train.sh ${PARTITION} ${JOB_NAME} config1.py tmp_work_dir_1
+CUDA_VISIBLE_DEVICES=4,5,6,7 GPUS=4 sh tools/slurm_train.sh ${PARTITION} ${JOB_NAME} config2.py tmp_work_dir_2
+```
+
+方式2:
+
+您可以设置不同的通信端口,而不需要修改配置文件,但必须设置“cfg-options”,以覆盖配置文件中的默认端口。
+
+```shell
+CUDA_VISIBLE_DEVICES=0,1,2,3 GPUS=4 sh tools/slurm_train.sh ${PARTITION} ${JOB_NAME} config1.py tmp_work_dir_1 --cfg-options dist_params.port=29500
+CUDA_VISIBLE_DEVICES=4,5,6,7 GPUS=4 sh tools/slurm_train.sh ${PARTITION} ${JOB_NAME} config2.py tmp_work_dir_2 --cfg-options dist_params.port=29501
+```
+
+方式3:
+
+您可以使用环境变量’ MASTER_PORT ‘在命令中设置端口:
+
+```shell
+CUDA_VISIBLE_DEVICES=0,1,2,3 GPUS=4 MASTER_PORT=29500 sh tools/slurm_train.sh ${PARTITION} ${JOB_NAME} config1.py tmp_work_dir_1
+CUDA_VISIBLE_DEVICES=4,5,6,7 GPUS=4 MASTER_PORT=29501 sh tools/slurm_train.sh ${PARTITION} ${JOB_NAME} config2.py tmp_work_dir_2
+```
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/config.md b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/config.md
new file mode 100644
index 0000000000000000000000000000000000000000..7cee6112698159800bacc0928efd98fc60e9c4b3
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/config.md
@@ -0,0 +1,377 @@
+# 教程 1: 学习配置文件
+
+我们整合了模块和继承设计到我们的配置里,这便于做很多实验。如果您想查看配置文件,您可以运行 `python tools/print_config.py /PATH/TO/CONFIG` 去查看完整的配置文件。您还可以传递参数
+`--cfg-options xxx.yyy=zzz` 去查看更新的配置。
+
+## 配置文件的结构
+
+在 `config/_base_` 文件夹下面有4种基本组件类型: 数据集(dataset),模型(model),训练策略(schedule)和运行时的默认设置(default runtime)。许多方法都可以方便地通过组合这些组件进行实现。
+这样,像 DeepLabV3, PSPNet 这样的模型可以容易地被构造。被来自 `_base_` 下的组件来构建的配置叫做 _原始配置 (primitive)_。
+
+对于所有在同一个文件夹下的配置文件,推荐**只有一个**对应的**原始配置**文件。所有其他的配置文件都应该继承自这个**原始配置**文件。这样就能保证配置文件的最大继承深度为 3。
+
+为了便于理解,我们推荐社区贡献者继承已有的方法配置文件。
+例如,如果一些修改是基于 DeepLabV3,使用者首先首先应该通过指定 `_base_ = ../deeplabv3/deeplabv3_r50_512x1024_40ki_cityscapes.py`来继承基础 DeepLabV3 结构,再去修改配置文件里其他内容以完成继承。
+
+如果您正在构建一个完整的新模型,它完全没有和已有的方法共享一些结构,您可能需要在 `configs` 下面创建一个文件夹 `xxxnet`。
+更详细的文档,请参照 [mmcv](https://mmcv.readthedocs.io/en/latest/understand_mmcv/config.html) 。
+
+## 配置文件命名风格
+
+我们按照下面的风格去命名配置文件,社区贡献者被建议使用同样的风格。
+
+```
+{model}_{backbone}_[misc]_[gpu x batch_per_gpu]_{resolution}_{iterations}_{dataset}
+```
+
+`{xxx}` 是被要求的文件 `[yyy]` 是可选的。
+
+- `{model}`: 模型种类,例如 `psp`, `deeplabv3` 等等
+- `{backbone}`: 主干网络种类,例如 `r50` (ResNet-50), `x101` (ResNeXt-101)
+- `[misc]`: 模型中各式各样的设置/插件,例如 `dconv`, `gcb`, `attention`, `mstrain`
+- `[gpu x batch_per_gpu]`: GPU数目 和每个 GPU 的样本数, 默认为 `8x2`
+- `{iterations}`: 训练迭代轮数,如`160k`
+- `{dataset}`: 数据集,如 `cityscapes`, `voc12aug`, `ade`
+
+## PSPNet 的一个例子
+
+为了帮助使用者熟悉这个流行的语义分割框架的完整配置文件和模块,我们在下面对使用 ResNet50V1c 的 PSPNet 的配置文件做了详细的注释说明。
+更多的详细使用和其他模块的替代项请参考 API 文档。
+
+```python
+norm_cfg = dict(type='SyncBN', requires_grad=True) # 分割框架通常使用 SyncBN
+model = dict(
+ type='EncoderDecoder', # 分割器(segmentor)的名字
+ pretrained='open-mmlab://resnet50_v1c', # 将被加载的 ImageNet 预训练主干网络
+ backbone=dict(
+ type='ResNetV1c', # 主干网络的类别。 可用选项请参考 mmseg/models/backbones/resnet.py
+ depth=50, # 主干网络的深度。通常为 50 和 101。
+ num_stages=4, # 主干网络状态(stages)的数目,这些状态产生的特征图作为后续的 head 的输入。
+ out_indices=(0, 1, 2, 3), # 每个状态产生的特征图输出的索引。
+ dilations=(1, 1, 2, 4), # 每一层(layer)的空心率(dilation rate)。
+ strides=(1, 2, 1, 1), # 每一层(layer)的步长(stride)。
+ norm_cfg=dict( # 归一化层(norm layer)的配置项。
+ type='SyncBN', # 归一化层的类别。通常是 SyncBN。
+ requires_grad=True), # 是否训练归一化里的 gamma 和 beta。
+ norm_eval=False, # 是否冻结 BN 里的统计项。
+ style='pytorch', # 主干网络的风格,'pytorch' 意思是步长为2的层为 3x3 卷积, 'caffe' 意思是步长为2的层为 1x1 卷积。
+ contract_dilation=True), # 当空洞 > 1, 是否压缩第一个空洞层。
+ decode_head=dict(
+ type='PSPHead', # 解码头(decode head)的类别。 可用选项请参考 mmseg/models/decode_heads。
+ in_channels=2048, # 解码头的输入通道数。
+ in_index=3, # 被选择的特征图(feature map)的索引。
+ channels=512, # 解码头中间态(intermediate)的通道数。
+ pool_scales=(1, 2, 3, 6), # PSPHead 平均池化(avg pooling)的规模(scales)。 细节请参考文章内容。
+ dropout_ratio=0.1, # 进入最后分类层(classification layer)之前的 dropout 比例。
+ num_classes=19, # 分割前景的种类数目。 通常情况下,cityscapes 为19,VOC为21,ADE20k 为150。
+ norm_cfg=dict(type='SyncBN', requires_grad=True), # 归一化层的配置项。
+ align_corners=False, # 解码里调整大小(resize)的 align_corners 参数。
+ loss_decode=dict( # 解码头(decode_head)里的损失函数的配置项。
+ type='CrossEntropyLoss', # 在分割里使用的损失函数的类别。
+ use_sigmoid=False, # 在分割里是否使用 sigmoid 激活。
+ loss_weight=1.0)), # 解码头里损失的权重。
+ auxiliary_head=dict(
+ type='FCNHead', # 辅助头(auxiliary head)的种类。可用选项请参考 mmseg/models/decode_heads。
+ in_channels=1024, # 辅助头的输入通道数。
+ in_index=2, # 被选择的特征图(feature map)的索引。
+ channels=256, # 辅助头中间态(intermediate)的通道数。
+ num_convs=1, # FCNHead 里卷积(convs)的数目. 辅助头里通常为1。
+ concat_input=False, # 在分类层(classification layer)之前是否连接(concat)输入和卷积的输出。
+ dropout_ratio=0.1, # 进入最后分类层(classification layer)之前的 dropout 比例。
+ num_classes=19, # 分割前景的种类数目。 通常情况下,cityscapes 为19,VOC为21,ADE20k 为150。
+ norm_cfg=dict(type='SyncBN', requires_grad=True), # 归一化层的配置项。
+ align_corners=False, # 解码里调整大小(resize)的 align_corners 参数。
+ loss_decode=dict( # 辅助头(auxiliary head)里的损失函数的配置项。
+ type='CrossEntropyLoss', # 在分割里使用的损失函数的类别。
+ use_sigmoid=False, # 在分割里是否使用 sigmoid 激活。
+ loss_weight=0.4))) # 辅助头里损失的权重。默认设置为0.4。
+train_cfg = dict() # train_cfg 当前仅是一个占位符。
+test_cfg = dict(mode='whole') # 测试模式, 选项是 'whole' 和 'sliding'. 'whole': 整张图像全卷积(fully-convolutional)测试。 'sliding': 图像上做滑动裁剪窗口(sliding crop window)。
+dataset_type = 'CityscapesDataset' # 数据集类型,这将被用来定义数据集。
+data_root = 'data/cityscapes/' # 数据的根路径。
+img_norm_cfg = dict( # 图像归一化配置,用来归一化输入的图像。
+ mean=[123.675, 116.28, 103.53], # 预训练里用于预训练主干网络模型的平均值。
+ std=[58.395, 57.12, 57.375], # 预训练里用于预训练主干网络模型的标准差。
+ to_rgb=True) # 预训练里用于预训练主干网络的图像的通道顺序。
+crop_size = (512, 1024) # 训练时的裁剪大小
+train_pipeline = [ #训练流程
+ dict(type='LoadImageFromFile'), # 第1个流程,从文件路径里加载图像。
+ dict(type='LoadAnnotations'), # 第2个流程,对于当前图像,加载它的注释信息。
+ dict(type='Resize', # 变化图像和其注释大小的数据增广的流程。
+ img_scale=(2048, 1024), # 图像的最大规模。
+ ratio_range=(0.5, 2.0)), # 数据增广的比例范围。
+ dict(type='RandomCrop', # 随机裁剪当前图像和其注释大小的数据增广的流程。
+ crop_size=(512, 1024), # 随机裁剪图像生成 patch 的大小。
+ cat_max_ratio=0.75), # 单个类别可以填充的最大区域的比例。
+ dict(
+ type='RandomFlip', # 翻转图像和其注释大小的数据增广的流程。
+ flip_ratio=0.5), # 翻转图像的概率
+ dict(type='PhotoMetricDistortion'), # 光学上使用一些方法扭曲当前图像和其注释的数据增广的流程。
+ dict(
+ type='Normalize', # 归一化当前图像的数据增广的流程。
+ mean=[123.675, 116.28, 103.53], # 这些键与 img_norm_cfg 一致,因为 img_norm_cfg 被
+ std=[58.395, 57.12, 57.375], # 用作参数。
+ to_rgb=True),
+ dict(type='Pad', # 填充当前图像到指定大小的数据增广的流程。
+ size=(512, 1024), # 填充的图像大小。
+ pad_val=0, # 图像的填充值。
+ seg_pad_val=255), # 'gt_semantic_seg'的填充值。
+ dict(type='DefaultFormatBundle'), # 流程里收集数据的默认格式捆。
+ dict(type='Collect', # 决定数据里哪些键被传递到分割器里的流程。
+ keys=['img', 'gt_semantic_seg'])
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'), # 第1个流程,从文件路径里加载图像。
+ dict(
+ type='MultiScaleFlipAug', # 封装测试时数据增广(test time augmentations)。
+ img_scale=(2048, 1024), # 决定测试时可改变图像的最大规模。用于改变图像大小的流程。
+ flip=False, # 测试时是否翻转图像。
+ transforms=[
+ dict(type='Resize', # 使用改变图像大小的数据增广。
+ keep_ratio=True), # 是否保持宽和高的比例,这里的图像比例设置将覆盖上面的图像规模大小的设置。
+ dict(type='RandomFlip'), # 考虑到 RandomFlip 已经被添加到流程里,当 flip=False 时它将不被使用。
+ dict(
+ type='Normalize', # 归一化配置项,值来自 img_norm_cfg。
+ mean=[123.675, 116.28, 103.53],
+ std=[58.395, 57.12, 57.375],
+ to_rgb=True),
+ dict(type='ImageToTensor', # 将图像转为张量
+ keys=['img']),
+ dict(type='Collect', # 收集测试时必须的键的收集流程。
+ keys=['img'])
+ ])
+]
+data = dict(
+ samples_per_gpu=2, # 单个 GPU 的 Batch size
+ workers_per_gpu=2, # 单个 GPU 分配的数据加载线程数
+ train=dict( # 训练数据集配置
+ type='CityscapesDataset', # 数据集的类别, 细节参考自 mmseg/datasets/。
+ data_root='data/cityscapes/', # 数据集的根目录。
+ img_dir='leftImg8bit/train', # 数据集图像的文件夹。
+ ann_dir='gtFine/train', # 数据集注释的文件夹。
+ pipeline=[ # 流程, 由之前创建的 train_pipeline 传递进来。
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(
+ type='Resize', img_scale=(2048, 1024), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=(512, 1024), cat_max_ratio=0.75),
+ dict(type='RandomFlip', flip_ratio=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(
+ type='Normalize',
+ mean=[123.675, 116.28, 103.53],
+ std=[58.395, 57.12, 57.375],
+ to_rgb=True),
+ dict(type='Pad', size=(512, 1024), pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg'])
+ ]),
+ val=dict( # 验证数据集的配置
+ type='CityscapesDataset',
+ data_root='data/cityscapes/',
+ img_dir='leftImg8bit/val',
+ ann_dir='gtFine/val',
+ pipeline=[ # 由之前创建的 test_pipeline 传递的流程。
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2048, 1024),
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(
+ type='Normalize',
+ mean=[123.675, 116.28, 103.53],
+ std=[58.395, 57.12, 57.375],
+ to_rgb=True),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img'])
+ ])
+ ]),
+ test=dict(
+ type='CityscapesDataset',
+ data_root='data/cityscapes/',
+ img_dir='leftImg8bit/val',
+ ann_dir='gtFine/val',
+ pipeline=[
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2048, 1024),
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(
+ type='Normalize',
+ mean=[123.675, 116.28, 103.53],
+ std=[58.395, 57.12, 57.375],
+ to_rgb=True),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img'])
+ ])
+ ]))
+log_config = dict( # 注册日志钩 (register logger hook) 的配置文件。
+ interval=50, # 打印日志的间隔
+ hooks=[
+ # dict(type='TensorboardLoggerHook') # 同样支持 Tensorboard 日志
+ dict(type='TextLoggerHook', by_epoch=False)
+ ])
+dist_params = dict(backend='nccl') # 用于设置分布式训练的参数,端口也同样可被设置。
+log_level = 'INFO' # 日志的级别。
+load_from = None # 从一个给定路径里加载模型作为预训练模型,它并不会消耗训练时间。
+resume_from = None # 从给定路径里恢复检查点(checkpoints),训练模式将从检查点保存的轮次开始恢复训练。
+workflow = [('train', 1)] # runner 的工作流程。 [('train', 1)] 意思是只有一个工作流程而且工作流程 'train' 仅执行一次。根据 `runner.max_iters` 工作流程训练模型的迭代轮数为40000次。
+cudnn_benchmark = True # 是否是使用 cudnn_benchmark 去加速,它对于固定输入大小的可以提高训练速度。
+optimizer = dict( # 用于构建优化器的配置文件。支持 PyTorch 中的所有优化器,同时它们的参数与PyTorch里的优化器参数一致。
+ type='SGD', # 优化器种类,更多细节可参考 https://github.com/open-mmlab/mmcv/blob/master/mmcv/runner/optimizer/default_constructor.py#L13。
+ lr=0.01, # 优化器的学习率,参数的使用细节请参照对应的 PyTorch 文档。
+ momentum=0.9, # 动量 (Momentum)
+ weight_decay=0.0005) # SGD 的衰减权重 (weight decay)。
+optimizer_config = dict() # 用于构建优化器钩 (optimizer hook) 的配置文件,执行细节请参考 https://github.com/open-mmlab/mmcv/blob/master/mmcv/runner/hooks/optimizer.py#L8。
+lr_config = dict(
+ policy='poly', # 调度流程的策略,同样支持 Step, CosineAnnealing, Cyclic 等. 请从 https://github.com/open-mmlab/mmcv/blob/master/mmcv/runner/hooks/lr_updater.py#L9 参考 LrUpdater 的细节。
+ power=0.9, # 多项式衰减 (polynomial decay) 的幂。
+ min_lr=0.0001, # 用来稳定训练的最小学习率。
+ by_epoch=False) # 是否按照每个 epoch 去算学习率。
+runner = dict(
+ type='IterBasedRunner', # 将使用的 runner 的类别 (例如 IterBasedRunner 或 EpochBasedRunner)。
+ max_iters=40000) # 全部迭代轮数大小,对于 EpochBasedRunner 使用 `max_epochs` 。
+checkpoint_config = dict( # 设置检查点钩子 (checkpoint hook) 的配置文件。执行时请参考 https://github.com/open-mmlab/mmcv/blob/master/mmcv/runner/hooks/checkpoint.py。
+ by_epoch=False, # 是否按照每个 epoch 去算 runner。
+ interval=4000) # 保存的间隔
+evaluation = dict( # 构建评估钩 (evaluation hook) 的配置文件。细节请参考 mmseg/core/evaluation/eval_hook.py。
+ interval=4000, # 评估的间歇点
+ metric='mIoU') # 评估的指标
+
+
+```
+
+## FAQ
+
+### 忽略基础配置文件里的一些域内容。
+
+有时,您也许会设置 `_delete_=True` 去忽略基础配置文件里的一些域内容。
+您也许可以参照 [mmcv](https://mmcv.readthedocs.io/en/latest/understand_mmcv/config.html#inherit-from-base-config-with-ignored-fields) 来获得一些简单的指导。
+
+在 MMSegmentation 里,例如为了改变 PSPNet 的主干网络的某些内容:
+
+```python
+norm_cfg = dict(type='SyncBN', requires_grad=True)
+model = dict(
+ type='MaskRCNN',
+ pretrained='torchvision://resnet50',
+ backbone=dict(
+ type='ResNetV1c',
+ depth=50,
+ num_stages=4,
+ out_indices=(0, 1, 2, 3),
+ dilations=(1, 1, 2, 4),
+ strides=(1, 2, 1, 1),
+ norm_cfg=norm_cfg,
+ norm_eval=False,
+ style='pytorch',
+ contract_dilation=True),
+ decode_head=dict(...),
+ auxiliary_head=dict(...))
+```
+
+`ResNet` 和 `HRNet` 使用不同的关键词去构建。
+
+```python
+_base_ = '../pspnet/psp_r50_512x1024_40ki_cityscpaes.py'
+norm_cfg = dict(type='SyncBN', requires_grad=True)
+model = dict(
+ pretrained='open-mmlab://msra/hrnetv2_w32',
+ backbone=dict(
+ _delete_=True,
+ type='HRNet',
+ norm_cfg=norm_cfg,
+ extra=dict(
+ stage1=dict(
+ num_modules=1,
+ num_branches=1,
+ block='BOTTLENECK',
+ num_blocks=(4, ),
+ num_channels=(64, )),
+ stage2=dict(
+ num_modules=1,
+ num_branches=2,
+ block='BASIC',
+ num_blocks=(4, 4),
+ num_channels=(32, 64)),
+ stage3=dict(
+ num_modules=4,
+ num_branches=3,
+ block='BASIC',
+ num_blocks=(4, 4, 4),
+ num_channels=(32, 64, 128)),
+ stage4=dict(
+ num_modules=3,
+ num_branches=4,
+ block='BASIC',
+ num_blocks=(4, 4, 4, 4),
+ num_channels=(32, 64, 128, 256)))),
+ decode_head=dict(...),
+ auxiliary_head=dict(...))
+```
+
+`_delete_=True` 将用新的键去替换 `backbone` 域内所有老的键。
+
+### 使用配置文件里的中间变量
+
+配置文件里会使用一些中间变量,例如数据集里的 `train_pipeline`/`test_pipeline`。
+需要注意的是,在子配置文件里修改中间变量时,使用者需要再次传递这些变量给对应的域。
+例如,我们想改变在训练或测试时,PSPNet 的多尺度策略 (multi scale strategy),`train_pipeline`/`test_pipeline` 是我们想要修改的中间变量。
+
+```python
+_base_ = '../pspnet/psp_r50_512x1024_40ki_cityscapes.py'
+crop_size = (512, 1024)
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=(2048, 1024), ratio_range=(1.0, 2.0)), # 改成 [1., 2.]
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', flip_ratio=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2048, 1024),
+ img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75], # 改成多尺度测试 (multi scale testing)。
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+data = dict(
+ train=dict(pipeline=train_pipeline),
+ val=dict(pipeline=test_pipeline),
+ test=dict(pipeline=test_pipeline))
+```
+
+我们首先定义新的 `train_pipeline`/`test_pipeline` 然后传递到 `data` 里。
+
+同样的,如果我们想从 `SyncBN` 切换到 `BN` 或者 `MMSyncBN`,我们需要配置文件里的每一个 `norm_cfg`。
+
+```python
+_base_ = '../pspnet/psp_r50_512x1024_40ki_cityscpaes.py'
+norm_cfg = dict(type='BN', requires_grad=True)
+model = dict(
+ backbone=dict(norm_cfg=norm_cfg),
+ decode_head=dict(norm_cfg=norm_cfg),
+ auxiliary_head=dict(norm_cfg=norm_cfg))
+```
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/customize_datasets.md b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/customize_datasets.md
new file mode 100644
index 0000000000000000000000000000000000000000..c579a8f3994d2978cde2e5ed62b737addf1d42b5
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/customize_datasets.md
@@ -0,0 +1,209 @@
+# 教程 2: 自定义数据集
+
+## 通过重新组织数据来定制数据集
+
+最简单的方法是将您的数据集进行转化,并组织成文件夹的形式。
+
+如下的文件结构就是一个例子。
+
+```none
+├── data
+│ ├── my_dataset
+│ │ ├── img_dir
+│ │ │ ├── train
+│ │ │ │ ├── xxx{img_suffix}
+│ │ │ │ ├── yyy{img_suffix}
+│ │ │ │ ├── zzz{img_suffix}
+│ │ │ ├── val
+│ │ ├── ann_dir
+│ │ │ ├── train
+│ │ │ │ ├── xxx{seg_map_suffix}
+│ │ │ │ ├── yyy{seg_map_suffix}
+│ │ │ │ ├── zzz{seg_map_suffix}
+│ │ │ ├── val
+
+```
+
+一个训练对将由 img_dir/ann_dir 里同样首缀的文件组成。
+
+如果给定 `split` 参数,只有部分在 img_dir/ann_dir 里的文件会被加载。
+我们可以对被包括在 split 文本里的文件指定前缀。
+
+除此以外,一个 split 文本如下所示:
+
+```none
+xxx
+zzz
+```
+
+只有
+
+`data/my_dataset/img_dir/train/xxx{img_suffix}`,
+`data/my_dataset/img_dir/train/zzz{img_suffix}`,
+`data/my_dataset/ann_dir/train/xxx{seg_map_suffix}`,
+`data/my_dataset/ann_dir/train/zzz{seg_map_suffix}` 将被加载。
+
+注意:标注是跟图像同样的形状 (H, W),其中的像素值的范围是 `[0, num_classes - 1]`。
+您也可以使用 [pillow](https://pillow.readthedocs.io/en/stable/handbook/concepts.html#palette) 的 `'P'` 模式去创建包含颜色的标注。
+
+## 通过混合数据去定制数据集
+
+MMSegmentation 同样支持混合数据集去训练。
+当前它支持拼接 (concat), 重复 (repeat) 和多图混合 (multi-image mix)数据集。
+
+### 重复数据集
+
+我们使用 `RepeatDataset` 作为包装 (wrapper) 去重复数据集。
+例如,假设原始数据集是 `Dataset_A`,为了重复它,配置文件如下:
+
+```python
+dataset_A_train = dict(
+ type='RepeatDataset',
+ times=N,
+ dataset=dict( # 这是 Dataset_A 数据集的原始配置
+ type='Dataset_A',
+ ...
+ pipeline=train_pipeline
+ )
+ )
+```
+
+### 拼接数据集
+
+有2种方式去拼接数据集。
+
+1. 如果您想拼接的数据集是同样的类型,但有不同的标注文件,
+ 您可以按如下操作去拼接数据集的配置文件:
+
+ 1. 您也许可以拼接两个标注文件夹 `ann_dir`
+
+ ```python
+ dataset_A_train = dict(
+ type='Dataset_A',
+ img_dir = 'img_dir',
+ ann_dir = ['anno_dir_1', 'anno_dir_2'],
+ pipeline=train_pipeline
+ )
+ ```
+
+ 2. 您也可以去拼接两个 `split` 文件列表
+
+ ```python
+ dataset_A_train = dict(
+ type='Dataset_A',
+ img_dir = 'img_dir',
+ ann_dir = 'anno_dir',
+ split = ['split_1.txt', 'split_2.txt'],
+ pipeline=train_pipeline
+ )
+ ```
+
+ 3. 您也可以同时拼接 `ann_dir` 文件夹和 `split` 文件列表
+
+ ```python
+ dataset_A_train = dict(
+ type='Dataset_A',
+ img_dir = 'img_dir',
+ ann_dir = ['anno_dir_1', 'anno_dir_2'],
+ split = ['split_1.txt', 'split_2.txt'],
+ pipeline=train_pipeline
+ )
+ ```
+
+ 在这样的情况下, `ann_dir_1` 和 `ann_dir_2` 分别对应于 `split_1.txt` 和 `split_2.txt`
+
+2. 如果您想拼接不同的数据集,您可以如下去拼接数据集的配置文件:
+
+ ```python
+ dataset_A_train = dict()
+ dataset_B_train = dict()
+
+ data = dict(
+ imgs_per_gpu=2,
+ workers_per_gpu=2,
+ train = [
+ dataset_A_train,
+ dataset_B_train
+ ],
+ val = dataset_A_val,
+ test = dataset_A_test
+ )
+ ```
+
+一个更复杂的例子如下:分别重复 `Dataset_A` 和 `Dataset_B` N 次和 M 次,然后再去拼接重复后的数据集
+
+```python
+dataset_A_train = dict(
+ type='RepeatDataset',
+ times=N,
+ dataset=dict(
+ type='Dataset_A',
+ ...
+ pipeline=train_pipeline
+ )
+)
+dataset_A_val = dict(
+ ...
+ pipeline=test_pipeline
+)
+dataset_A_test = dict(
+ ...
+ pipeline=test_pipeline
+)
+dataset_B_train = dict(
+ type='RepeatDataset',
+ times=M,
+ dataset=dict(
+ type='Dataset_B',
+ ...
+ pipeline=train_pipeline
+ )
+)
+data = dict(
+ imgs_per_gpu=2,
+ workers_per_gpu=2,
+ train = [
+ dataset_A_train,
+ dataset_B_train
+ ],
+ val = dataset_A_val,
+ test = dataset_A_test
+)
+
+```
+
+### 多图混合集
+
+我们使用 `MultiImageMixDataset` 作为包装(wrapper)去混合多个数据集的图片。
+`MultiImageMixDataset`可以被类似mosaic和mixup的多图混合数据増广使用。
+
+`MultiImageMixDataset`与`Mosaic`数据増广一起使用的例子:
+
+```python
+train_pipeline = [
+ dict(type='RandomMosaic', prob=1),
+ dict(type='Resize', img_scale=(1024, 512), keep_ratio=True),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+
+train_dataset = dict(
+ type='MultiImageMixDataset',
+ dataset=dict(
+ classes=classes,
+ palette=palette,
+ type=dataset_type,
+ reduce_zero_label=False,
+ img_dir=data_root + "images/train",
+ ann_dir=data_root + "annotations/train",
+ pipeline=[
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ ]
+ ),
+ pipeline=train_pipeline
+)
+
+```
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/customize_models.md b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/customize_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..c92d7db238e8e08863d228bab8cb41f2ea754275
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/customize_models.md
@@ -0,0 +1,230 @@
+# 教程 4: 自定义模型
+
+## 自定义优化器 (optimizer)
+
+假设您想增加一个新的叫 `MyOptimizer` 的优化器,它的参数分别为 `a`, `b`, 和 `c`。
+您首先需要在一个文件里实现这个新的优化器,例如在 `mmseg/core/optimizer/my_optimizer.py` 里面:
+
+```python
+from mmcv.runner import OPTIMIZERS
+from torch.optim import Optimizer
+
+
+@OPTIMIZERS.register_module
+class MyOptimizer(Optimizer):
+
+ def __init__(self, a, b, c)
+
+```
+
+然后增加这个模块到 `mmseg/core/optimizer/__init__.py` 里面,这样注册器 (registry) 将会发现这个新的模块并添加它:
+
+```python
+from .my_optimizer import MyOptimizer
+```
+
+之后您可以在配置文件的 `optimizer` 域里使用 `MyOptimizer`,
+如下所示,在配置文件里,优化器被 `optimizer` 域所定义:
+
+```python
+optimizer = dict(type='SGD', lr=0.02, momentum=0.9, weight_decay=0.0001)
+```
+
+为了使用您自己的优化器,域可以被修改为:
+
+```python
+optimizer = dict(type='MyOptimizer', a=a_value, b=b_value, c=c_value)
+```
+
+我们已经支持了 PyTorch 自带的全部优化器,唯一修改的地方是在配置文件里的 `optimizer` 域。例如,如果您想使用 `ADAM`,尽管数值表现会掉点,还是可以如下修改:
+
+```python
+optimizer = dict(type='Adam', lr=0.0003, weight_decay=0.0001)
+```
+
+使用者可以直接按照 PyTorch [文档教程](https://pytorch.org/docs/stable/optim.html?highlight=optim#module-torch.optim) 去设置参数。
+
+## 定制优化器的构造器 (optimizer constructor)
+
+对于优化,一些模型可能会有一些特别定义的参数,例如批归一化 (BatchNorm) 层里面的权重衰减 (weight decay)。
+使用者可以通过定制优化器的构造器来微调这些细粒度的优化器参数。
+
+```python
+from mmcv.utils import build_from_cfg
+
+from mmcv.runner import OPTIMIZER_BUILDERS
+from .cocktail_optimizer import CocktailOptimizer
+
+
+@OPTIMIZER_BUILDERS.register_module
+class CocktailOptimizerConstructor(object):
+
+ def __init__(self, optimizer_cfg, paramwise_cfg=None):
+
+ def __call__(self, model):
+
+ return my_optimizer
+
+```
+
+## 开发和增加新的组件(Module)
+
+MMSegmentation 里主要有2种组件:
+
+- 主干网络 (backbone): 通常是卷积网络的堆叠,来做特征提取,例如 ResNet, HRNet
+- 解码头 (decoder head): 用于语义分割图的解码的组件(得到分割结果)
+
+### 添加新的主干网络
+
+这里我们以 MobileNet 为例,展示如何增加新的主干组件:
+
+1. 创建一个新的文件 `mmseg/models/backbones/mobilenet.py`
+
+```python
+import torch.nn as nn
+
+from ..registry import BACKBONES
+
+
+@BACKBONES.register_module
+class MobileNet(nn.Module):
+
+ def __init__(self, arg1, arg2):
+ pass
+
+ def forward(self, x): # should return a tuple
+ pass
+
+ def init_weights(self, pretrained=None):
+ pass
+```
+
+2. 在 `mmseg/models/backbones/__init__.py` 里面导入模块
+
+```python
+from .mobilenet import MobileNet
+```
+
+3. 在您的配置文件里使用它
+
+```python
+model = dict(
+ ...
+ backbone=dict(
+ type='MobileNet',
+ arg1=xxx,
+ arg2=xxx),
+ ...
+```
+
+### 增加新的解码头 (decoder head)组件
+
+在 MMSegmentation 里面,对于所有的分割头,我们提供一个基类解码头 [BaseDecodeHead](https://github.com/open-mmlab/mmsegmentation/blob/master/mmseg/models/decode_heads/decode_head.py) 。
+所有新建的解码头都应该继承它。这里我们以 [PSPNet](https://arxiv.org/abs/1612.01105) 为例,
+展示如何开发和增加一个新的解码头组件:
+
+首先,在 `mmseg/models/decode_heads/psp_head.py` 里添加一个新的解码头。
+PSPNet 中实现了一个语义分割的解码头。为了实现一个解码头,我们只需要在新构造的解码头中实现如下的3个函数:
+
+```python
+@HEADS.register_module()
+class PSPHead(BaseDecodeHead):
+
+ def __init__(self, pool_scales=(1, 2, 3, 6), **kwargs):
+ super(PSPHead, self).__init__(**kwargs)
+
+ def init_weights(self):
+
+ def forward(self, inputs):
+
+```
+
+接着,使用者需要在 `mmseg/models/decode_heads/__init__.py` 里面添加这个模块,这样对应的注册器 (registry) 可以查找并加载它们。
+
+PSPNet的配置文件如下所示:
+
+```python
+norm_cfg = dict(type='SyncBN', requires_grad=True)
+model = dict(
+ type='EncoderDecoder',
+ pretrained='pretrain_model/resnet50_v1c_trick-2cccc1ad.pth',
+ backbone=dict(
+ type='ResNetV1c',
+ depth=50,
+ num_stages=4,
+ out_indices=(0, 1, 2, 3),
+ dilations=(1, 1, 2, 4),
+ strides=(1, 2, 1, 1),
+ norm_cfg=norm_cfg,
+ norm_eval=False,
+ style='pytorch',
+ contract_dilation=True),
+ decode_head=dict(
+ type='PSPHead',
+ in_channels=2048,
+ in_index=3,
+ channels=512,
+ pool_scales=(1, 2, 3, 6),
+ dropout_ratio=0.1,
+ num_classes=19,
+ norm_cfg=norm_cfg,
+ align_corners=False,
+ loss_decode=dict(
+ type='CrossEntropyLoss', use_sigmoid=False, loss_weight=1.0)))
+
+```
+
+### 增加新的损失函数
+
+假设您想添加一个新的损失函数 `MyLoss` 到语义分割解码器里。
+为了添加一个新的损失函数,使用者需要在 `mmseg/models/losses/my_loss.py` 里面去实现它。
+`weighted_loss` 可以对计算损失时的每个样本做加权。
+
+```python
+import torch
+import torch.nn as nn
+
+from ..builder import LOSSES
+from .utils import weighted_loss
+
+@weighted_loss
+def my_loss(pred, target):
+ assert pred.size() == target.size() and target.numel() > 0
+ loss = torch.abs(pred - target)
+ return loss
+
+@LOSSES.register_module
+class MyLoss(nn.Module):
+
+ def __init__(self, reduction='mean', loss_weight=1.0):
+ super(MyLoss, self).__init__()
+ self.reduction = reduction
+ self.loss_weight = loss_weight
+
+ def forward(self,
+ pred,
+ target,
+ weight=None,
+ avg_factor=None,
+ reduction_override=None):
+ assert reduction_override in (None, 'none', 'mean', 'sum')
+ reduction = (
+ reduction_override if reduction_override else self.reduction)
+ loss = self.loss_weight * my_loss(
+ pred, target, weight, reduction=reduction, avg_factor=avg_factor)
+ return loss
+```
+
+然后使用者需要在 `mmseg/models/losses/__init__.py` 里面添加它:
+
+```python
+from .my_loss import MyLoss, my_loss
+
+```
+
+为了使用它,修改 `loss_xxx` 域。之后您需要在解码头组件里修改 `loss_decode` 域。
+`loss_weight` 可以被用来对不同的损失函数做加权。
+
+```python
+loss_decode=dict(type='MyLoss', loss_weight=1.0))
+```
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/customize_runtime.md b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/customize_runtime.md
new file mode 100644
index 0000000000000000000000000000000000000000..6331789397c67e11589ce8c8b1cdf9c31c542860
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/customize_runtime.md
@@ -0,0 +1,248 @@
+# 教程 6: 自定义运行设定
+
+## 自定义优化设定
+
+### 自定义 PyTorch 支持的优化器
+
+我们已经支持 PyTorch 自带的所有优化器,唯一需要修改的地方是在配置文件里的 `optimizer` 域里面。
+例如,如果您想使用 `ADAM` (注意如下操作可能会让模型表现下降),可以使用如下修改:
+
+```python
+optimizer = dict(type='Adam', lr=0.0003, weight_decay=0.0001)
+```
+
+为了修改模型的学习率,使用者仅需要修改配置文件里 optimizer 的 `lr` 即可。
+使用者可以参照 PyTorch 的 [API 文档](https://pytorch.org/docs/stable/optim.html?highlight=optim#module-torch.optim)
+直接设置参数。
+
+### 自定义自己实现的优化器
+
+#### 1. 定义一个新的优化器
+
+一个自定义的优化器可以按照如下去定义:
+
+假如您想增加一个叫做 `MyOptimizer` 的优化器,它的参数分别有 `a`, `b`, 和 `c`。
+您需要创建一个叫 `mmseg/core/optimizer` 的新文件夹。
+然后再在文件,即 `mmseg/core/optimizer/my_optimizer.py` 里面去实现这个新优化器:
+
+```python
+from .registry import OPTIMIZERS
+from torch.optim import Optimizer
+
+
+@OPTIMIZERS.register_module()
+class MyOptimizer(Optimizer):
+
+ def __init__(self, a, b, c)
+
+```
+
+#### 2. 增加优化器到注册表 (registry)
+
+为了让上述定义的模块被框架发现,首先这个模块应该被导入到主命名空间 (main namespace) 里。
+有两种方式可以实现它。
+
+- 修改 `mmseg/core/optimizer/__init__.py` 来导入它
+
+ 新的被定义的模块应该被导入到 `mmseg/core/optimizer/__init__.py` 这样注册表将会发现新的模块并添加它
+
+```python
+from .my_optimizer import MyOptimizer
+```
+
+- 在配置文件里使用 `custom_imports` 去手动导入它
+
+```python
+custom_imports = dict(imports=['mmseg.core.optimizer.my_optimizer'], allow_failed_imports=False)
+```
+
+`mmseg.core.optimizer.my_optimizer` 模块将会在程序运行的开始被导入,并且 `MyOptimizer` 类将会自动注册。
+需要注意只有包含 `MyOptimizer` 类的包 (package) 应当被导入。
+而 `mmseg.core.optimizer.my_optimizer.MyOptimizer` **不能** 被直接导入。
+
+事实上,使用者完全可以用另一个按这样导入方法的文件夹结构,只要模块的根路径已经被添加到 `PYTHONPATH` 里面。
+
+#### 3. 在配置文件里定义优化器
+
+之后您可以在配置文件的 `optimizer` 域里面使用 `MyOptimizer`
+在配置文件里,优化器被定义在 `optimizer` 域里,如下所示:
+
+```python
+optimizer = dict(type='SGD', lr=0.02, momentum=0.9, weight_decay=0.0001)
+```
+
+为了使用您自己的优化器,这个域可以被改成:
+
+```python
+optimizer = dict(type='MyOptimizer', a=a_value, b=b_value, c=c_value)
+```
+
+### 自定义优化器的构造器 (constructor)
+
+有些模型可能需要在优化器里有一些特别参数的设置,例如 批归一化层 (BatchNorm layers) 的 权重衰减 (weight decay)。
+使用者可以通过自定义优化器的构造器去微调这些细粒度参数。
+
+```python
+from mmcv.utils import build_from_cfg
+
+from mmcv.runner.optimizer import OPTIMIZER_BUILDERS, OPTIMIZERS
+from mmseg.utils import get_root_logger
+from .my_optimizer import MyOptimizer
+
+
+@OPTIMIZER_BUILDERS.register_module()
+class MyOptimizerConstructor(object):
+
+ def __init__(self, optimizer_cfg, paramwise_cfg=None):
+
+ def __call__(self, model):
+
+ return my_optimizer
+
+```
+
+默认的优化器构造器的实现可以参照 [这里](https://github.com/open-mmlab/mmcv/blob/9ecd6b0d5ff9d2172c49a182eaa669e9f27bb8e7/mmcv/runner/optimizer/default_constructor.py#L11) ,它也可以被用作新的优化器构造器的模板。
+
+### 额外的设置
+
+优化器没有实现的一些技巧应该通过优化器构造器 (optimizer constructor) 或者钩子 (hook) 去实现,如设置基于参数的学习率 (parameter-wise learning rates)。我们列出一些常见的设置,它们可以稳定或加速模型的训练。
+如果您有更多的设置,欢迎在 PR 和 issue 里面提交。
+
+- __使用梯度截断 (gradient clip) 去稳定训练__:
+
+ 一些模型需要梯度截断去稳定训练过程,如下所示
+
+ ```python
+ optimizer_config = dict(
+ _delete_=True, grad_clip=dict(max_norm=35, norm_type=2))
+ ```
+
+ 如果您的配置继承自已经设置了 `optimizer_config` 的基础配置 (base config),您可能需要 `_delete_=True` 来重写那些不需要的设置。更多细节请参照 [配置文件文档](https://mmsegmentation.readthedocs.io/en/latest/config.html) 。
+
+- __使用动量计划表 (momentum schedule) 去加速模型收敛__:
+
+ 我们支持动量计划表去让模型基于学习率修改动量,这样可能让模型收敛地更快。
+ 动量计划表经常和学习率计划表 (LR scheduler) 一起使用,例如如下配置文件就在 3D 检测里经常使用以加速收敛。
+ 更多细节请参考 [CyclicLrUpdater](https://github.com/open-mmlab/mmcv/blob/f48241a65aebfe07db122e9db320c31b685dc674/mmcv/runner/hooks/lr_updater.py#L327) 和 [CyclicMomentumUpdater](https://github.com/open-mmlab/mmcv/blob/f48241a65aebfe07db122e9db320c31b685dc674/mmcv/runner/hooks/momentum_updater.py#L130) 的实现。
+
+ ```python
+ lr_config = dict(
+ policy='cyclic',
+ target_ratio=(10, 1e-4),
+ cyclic_times=1,
+ step_ratio_up=0.4,
+ )
+ momentum_config = dict(
+ policy='cyclic',
+ target_ratio=(0.85 / 0.95, 1),
+ cyclic_times=1,
+ step_ratio_up=0.4,
+ )
+ ```
+
+## 自定义训练计划表
+
+我们根据默认的训练迭代步数 40k/80k 来设置学习率,这在 MMCV 里叫做 [`PolyLrUpdaterHook`](https://github.com/open-mmlab/mmcv/blob/826d3a7b68596c824fa1e2cb89b6ac274f52179c/mmcv/runner/hooks/lr_updater.py#L196) 。
+我们也支持许多其他的学习率计划表:[这里](https://github.com/open-mmlab/mmcv/blob/master/mmcv/runner/hooks/lr_updater.py) ,例如 `CosineAnnealing` 和 `Poly` 计划表。下面是一些例子:
+
+- 步计划表 Step schedule:
+
+ ```python
+ lr_config = dict(policy='step', step=[9, 10])
+ ```
+
+- 余弦退火计划表 ConsineAnnealing schedule:
+
+ ```python
+ lr_config = dict(
+ policy='CosineAnnealing',
+ warmup='linear',
+ warmup_iters=1000,
+ warmup_ratio=1.0 / 10,
+ min_lr_ratio=1e-5)
+ ```
+
+## 自定义工作流 (workflow)
+
+工作流是一个专门定义运行顺序和轮数 (running order and epochs) 的列表 (phase, epochs)。
+默认情况下它设置成:
+
+```python
+workflow = [('train', 1)]
+```
+
+意思是训练是跑 1 个 epoch。有时候使用者可能想检查模型在验证集上的一些指标(如 损失 loss,精确性 accuracy),我们可以这样设置工作流:
+
+```python
+[('train', 1), ('val', 1)]
+```
+
+于是 1 个 epoch 训练,1 个 epoch 验证将交替运行。
+
+**注意**:
+
+1. 模型的参数在验证的阶段不会被自动更新
+2. 配置文件里的关键词 `total_epochs` 仅控制训练的 epochs 数目,而不会影响验证时的工作流
+3. 工作流 `[('train', 1), ('val', 1)]` 和 `[('train', 1)]` 将不会改变 `EvalHook` 的行为,因为 `EvalHook` 被 `after_train_epoch`
+ 调用而且验证的工作流仅仅影响通过调用 `after_val_epoch` 的钩子 (hooks)。因此, `[('train', 1), ('val', 1)]` 和 `[('train', 1)]`
+ 的区别仅在于 runner 将在每次训练 epoch 结束后计算在验证集上的损失
+
+## 自定义钩 (hooks)
+
+### 使用 MMCV 实现的钩子 (hooks)
+
+如果钩子已经在 MMCV 里被实现,如下所示,您可以直接修改配置文件来使用钩子:
+
+```python
+custom_hooks = [
+ dict(type='MyHook', a=a_value, b=b_value, priority='NORMAL')
+]
+```
+
+### 修改默认的运行时间钩子 (runtime hooks)
+
+以下的常用的钩子没有被 `custom_hooks` 注册:
+
+- log_config
+- checkpoint_config
+- evaluation
+- lr_config
+- optimizer_config
+- momentum_config
+
+在这些钩子里,只有 logger hook 有 `VERY_LOW` 优先级,其他的优先级都是 `NORMAL`。
+上述提及的教程已经包括了如何修改 `optimizer_config`,`momentum_config` 和 `lr_config`。
+这里我们展示我们如何处理 `log_config`, `checkpoint_config` 和 `evaluation`。
+
+#### 检查点配置文件 (Checkpoint config)
+
+MMCV runner 将使用 `checkpoint_config` 去初始化 [`CheckpointHook`](https://github.com/open-mmlab/mmcv/blob/9ecd6b0d5ff9d2172c49a182eaa669e9f27bb8e7/mmcv/runner/hooks/checkpoint.py#L9).
+
+```python
+checkpoint_config = dict(interval=1)
+```
+
+使用者可以设置 `max_keep_ckpts` 来仅保存一小部分检查点或者通过 `save_optimizer` 来决定是否保存优化器的状态字典 (state dict of optimizer)。 更多使用参数的细节请参考 [这里](https://mmcv.readthedocs.io/en/latest/api.html#mmcv.runner.CheckpointHook) 。
+
+#### 日志配置文件 (Log config)
+
+`log_config` 包裹了许多日志钩 (logger hooks) 而且能去设置间隔 (intervals)。现在 MMCV 支持 `WandbLoggerHook`, `MlflowLoggerHook` 和 `TensorboardLoggerHook`。
+详细的使用请参照 [文档](https://mmcv.readthedocs.io/en/latest/api.html#mmcv.runner.LoggerHook) 。
+
+```python
+log_config = dict(
+ interval=50,
+ hooks=[
+ dict(type='TextLoggerHook'),
+ dict(type='TensorboardLoggerHook')
+ ])
+```
+
+#### 评估配置文件 (Evaluation config)
+
+`evaluation` 的配置文件将被用来初始化 [`EvalHook`](https://github.com/open-mmlab/mmsegmentation/blob/e3f6f655d69b777341aec2fe8829871cc0beadcb/mmseg/core/evaluation/eval_hooks.py#L7) 。
+除了 `interval` 键,其他的像 `metric` 这样的参数将被传递给 `dataset.evaluate()` 。
+
+```python
+evaluation = dict(interval=1, metric='mIoU')
+```
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/data_pipeline.md b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/data_pipeline.md
new file mode 100644
index 0000000000000000000000000000000000000000..f3dfcd832a12995ef28aa415206087558e2494c4
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/data_pipeline.md
@@ -0,0 +1,166 @@
+# 教程 3: 自定义数据流程
+
+## 数据流程的设计
+
+按照通常的惯例,我们使用 `Dataset` 和 `DataLoader` 做多线程的数据加载。`Dataset` 返回一个数据内容的字典,里面对应于模型前传方法的各个参数。
+因为在语义分割中,输入的图像数据具有不同的大小,我们在 MMCV 里引入一个新的 `DataContainer` 类别去帮助收集和分发不同大小的输入数据。
+
+更多细节,请查看[这里](https://github.com/open-mmlab/mmcv/blob/master/mmcv/parallel/data_container.py) 。
+
+数据的准备流程和数据集是解耦的。通常一个数据集定义了如何处理标注数据(annotations)信息,而一个数据流程定义了准备一个数据字典的所有步骤。一个流程包括了一系列操作,每个操作里都把一个字典作为输入,然后再输出一个新的字典给下一个变换操作。
+
+这些操作可分为数据加载 (data loading),预处理 (pre-processing),格式变化 (formatting) 和测试时数据增强 (test-time augmentation)。
+
+下面的例子就是 PSPNet 的一个流程:
+
+```python
+img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+crop_size = (512, 1024)
+train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=(2048, 1024), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', flip_ratio=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+]
+test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(2048, 1024),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+]
+```
+
+对于每个操作,我们列出它添加、更新、移除的相关字典域 (dict fields):
+
+### 数据加载 Data loading
+
+`LoadImageFromFile`
+
+- 增加: img, img_shape, ori_shape
+
+`LoadAnnotations`
+
+- 增加: gt_semantic_seg, seg_fields
+
+### 预处理 Pre-processing
+
+`Resize`
+
+- 增加: scale, scale_idx, pad_shape, scale_factor, keep_ratio
+- 更新: img, img_shape, *seg_fields
+
+`RandomFlip`
+
+- 增加: flip
+- 更新: img, *seg_fields
+
+`Pad`
+
+- 增加: pad_fixed_size, pad_size_divisor
+- 更新: img, pad_shape, *seg_fields
+
+`RandomCrop`
+
+- 更新: img, pad_shape, *seg_fields
+
+`Normalize`
+
+- 增加: img_norm_cfg
+- 更新: img
+
+`SegRescale`
+
+- 更新: gt_semantic_seg
+
+`PhotoMetricDistortion`
+
+- 更新: img
+
+### 格式 Formatting
+
+`ToTensor`
+
+- 更新: 由 `keys` 指定
+
+`ImageToTensor`
+
+- 更新: 由 `keys` 指定
+
+`Transpose`
+
+- 更新: 由 `keys` 指定
+
+`ToDataContainer`
+
+- 更新: 由 `keys` 指定
+
+`DefaultFormatBundle`
+
+- 更新: img, gt_semantic_seg
+
+`Collect`
+
+- 增加: img_meta (the keys of img_meta is specified by `meta_keys`)
+- 移除: all other keys except for those specified by `keys`
+
+### 测试时数据增强 Test time augmentation
+
+`MultiScaleFlipAug`
+
+## 拓展和使用自定义的流程
+
+1. 在任何一个文件里写一个新的流程,例如 `my_pipeline.py`,它以一个字典作为输入并且输出一个字典
+
+ ```python
+ from mmseg.datasets import PIPELINES
+
+ @PIPELINES.register_module()
+ class MyTransform:
+
+ def __call__(self, results):
+ results['dummy'] = True
+ return results
+ ```
+
+2. 导入一个新类
+
+ ```python
+ from .my_pipeline import MyTransform
+ ```
+
+3. 在配置文件里使用它
+
+ ```python
+ img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53], std=[58.395, 57.12, 57.375], to_rgb=True)
+ crop_size = (512, 1024)
+ train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=(2048, 1024), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', flip_ratio=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='MyTransform'),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+ ]
+ ```
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/index.rst b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/index.rst
new file mode 100644
index 0000000000000000000000000000000000000000..e1a67a8b44a9ac3c2bbee59304c2043467ac3f30
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/index.rst
@@ -0,0 +1,9 @@
+.. toctree::
+ :maxdepth: 2
+
+ config.md
+ customize_datasets.md
+ data_pipeline.md
+ customize_models.md
+ training_tricks.md
+ customize_runtime.md
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/training_tricks.md b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/training_tricks.md
new file mode 100644
index 0000000000000000000000000000000000000000..2efbdf177c0a07657e5f034096307aea98e79d31
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/tutorials/training_tricks.md
@@ -0,0 +1,95 @@
+# 教程 5: 训练技巧
+
+MMSegmentation 支持如下训练技巧:
+
+## 主干网络和解码头组件使用不同的学习率 (Learning Rate, LR)
+
+在语义分割里,一些方法会让解码头组件的学习率大于主干网络的学习率,这样可以获得更好的表现或更快的收敛。
+
+在 MMSegmentation 里面,您也可以在配置文件里添加如下行来让解码头组件的学习率是主干组件的10倍。
+
+```python
+optimizer=dict(
+ paramwise_cfg = dict(
+ custom_keys={
+ 'head': dict(lr_mult=10.)}))
+```
+
+通过这种修改,任何被分组到 `'head'` 的参数的学习率都将乘以10。您也可以参照 [MMCV 文档](https://mmcv.readthedocs.io/en/latest/api.html#mmcv.runner.DefaultOptimizerConstructor) 获取更详细的信息。
+
+## 在线难样本挖掘 (Online Hard Example Mining, OHEM)
+
+对于训练时采样,我们在 [这里](https://github.com/open-mmlab/mmsegmentation/tree/master/mmseg/core/seg/sampler) 做了像素采样器。
+如下例子是使用 PSPNet 训练并采用 OHEM 策略的配置:
+
+```python
+_base_ = './pspnet_r50-d8_512x1024_40k_cityscapes.py'
+model=dict(
+ decode_head=dict(
+ sampler=dict(type='OHEMPixelSampler', thresh=0.7, min_kept=100000)) )
+```
+
+通过这种方式,只有置信分数在0.7以下的像素值点会被拿来训练。在训练时我们至少要保留100000个像素值点。如果 `thresh` 并未被指定,前 ``min_kept``
+个损失的像素值点才会被选择。
+
+## 类别平衡损失 (Class Balanced Loss)
+
+对于不平衡类别分布的数据集,您也许可以改变每个类别的损失权重。这里以 cityscapes 数据集为例:
+
+```python
+_base_ = './pspnet_r50-d8_512x1024_40k_cityscapes.py'
+model=dict(
+ decode_head=dict(
+ loss_decode=dict(
+ type='CrossEntropyLoss', use_sigmoid=False, loss_weight=1.0,
+ # DeepLab 对 cityscapes 使用这种权重
+ class_weight=[0.8373, 0.9180, 0.8660, 1.0345, 1.0166, 0.9969, 0.9754,
+ 1.0489, 0.8786, 1.0023, 0.9539, 0.9843, 1.1116, 0.9037,
+ 1.0865, 1.0955, 1.0865, 1.1529, 1.0507])))
+```
+
+`class_weight` 将被作为 `weight` 参数,传递给 `CrossEntropyLoss`。详细信息请参照 [PyTorch 文档](https://pytorch.org/docs/stable/nn.html?highlight=crossentropy#torch.nn.CrossEntropyLoss) 。
+
+## 同时使用多种损失函数 (Multiple Losses)
+
+对于训练时损失函数的计算,我们目前支持多个损失函数同时使用。 以 `unet` 使用 `DRIVE` 数据集训练为例,
+使用 `CrossEntropyLoss` 和 `DiceLoss` 的 `1:3` 的加权和作为损失函数。配置文件写为:
+
+```python
+_base_ = './fcn_unet_s5-d16_64x64_40k_drive.py'
+model = dict(
+ decode_head=dict(loss_decode=[dict(type='CrossEntropyLoss', loss_name='loss_ce', loss_weight=1.0),
+ dict(type='DiceLoss', loss_name='loss_dice', loss_weight=3.0)]),
+ auxiliary_head=dict(loss_decode=[dict(type='CrossEntropyLoss', loss_name='loss_ce',loss_weight=1.0),
+ dict(type='DiceLoss', loss_name='loss_dice', loss_weight=3.0)]),
+ )
+```
+
+通过这种方式,确定训练过程中损失函数的权重 `loss_weight` 和在训练日志里的名字 `loss_name`。
+
+注意: `loss_name` 的名字必须带有 `loss_` 前缀,这样它才能被包括在反传的图里。
+
+## 在损失函数中忽略特定的 label 类别
+
+默认设置 `avg_non_ignore=False`, 即每个像素都用来计算损失函数。尽管其中的一些像素属于需要被忽略的类别。
+
+对于训练时损失函数的计算,我们目前支持使用 `avg_non_ignore` 和 `ignore_index` 来忽略 label 特定的类别。 这样损失函数将只在非忽略类别像素中求平均值,会获得更好的表现。这里是[相关 PR](https://github.com/open-mmlab/mmsegmentation/pull/1409)。以 `unet` 使用 `Cityscapes` 数据集训练为例,
+在计算损失函数时,忽略 label 为0的背景,并且仅在不被忽略的像素上计算均值。配置文件写为:
+
+```python
+_base_ = './fcn_unet_s5-d16_4x4_512x1024_160k_cityscapes.py'
+model = dict(
+ decode_head=dict(
+ ignore_index=0,
+ loss_decode=dict(
+ type='CrossEntropyLoss', use_sigmoid=False, loss_weight=1.0, avg_non_ignore=True),
+ auxiliary_head=dict(
+ ignore_index=0,
+ loss_decode=dict(
+ type='CrossEntropyLoss', use_sigmoid=False, loss_weight=1.0, avg_non_ignore=True)),
+ ))
+```
+
+通过这种方式,确定训练过程中损失函数的权重 `loss_weight` 和在训练日志里的名字 `loss_name`。
+
+注意: `loss_name` 的名字必须带有 `loss_` 前缀,这样它才能被包括在反传的图里。
diff --git a/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/useful_tools.md b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/useful_tools.md
new file mode 100644
index 0000000000000000000000000000000000000000..bdf2740b68e0917d016c96475819f24c7c5cac06
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/docs/zh_cn/useful_tools.md
@@ -0,0 +1,368 @@
+## 常用工具
+
+除了训练和测试的脚本,我们在 `tools/` 文件夹路径下还提供许多有用的工具。
+
+### 计算参数量(params)和计算量( FLOPs) (试验性)
+
+我们基于 [flops-counter.pytorch](https://github.com/sovrasov/flops-counter.pytorch)
+提供了一个用于计算给定模型参数量和计算量的脚本。
+
+```shell
+python tools/get_flops.py ${CONFIG_FILE} [--shape ${INPUT_SHAPE}]
+```
+
+您将得到如下的结果:
+
+```none
+==============================
+Input shape: (3, 2048, 1024)
+Flops: 1429.68 GMac
+Params: 48.98 M
+==============================
+```
+
+**注意**: 这个工具仍然是试验性的,我们无法保证数字是正确的。您可以拿这些结果做简单的实验的对照,在写技术文档报告或者论文前您需要再次确认一下。
+
+(1) 计算量与输入的形状有关,而参数量与输入的形状无关,默认的输入形状是 (1, 3, 1280, 800);
+(2) 一些运算操作,如 GN 和其他定制的运算操作没有加入到计算量的计算中。
+
+### 发布模型
+
+在您上传一个模型到云服务器之前,您需要做以下几步:
+(1) 将模型权重转成 CPU 张量;
+(2) 删除记录优化器状态 (optimizer states)的相关信息;
+(3) 计算检查点文件 (checkpoint file) 的哈希编码(hash id)并且将哈希编码加到文件名中。
+
+```shell
+python tools/publish_model.py ${INPUT_FILENAME} ${OUTPUT_FILENAME}
+```
+
+例如,
+
+```shell
+python tools/publish_model.py work_dirs/pspnet/latest.pth psp_r50_hszhao_200ep.pth
+```
+
+最终输出文件将是 `psp_r50_512x1024_40ki_cityscapes-{hash id}.pth`。
+
+### 导出 ONNX (试验性)
+
+我们提供了一个脚本来导出模型到 [ONNX](https://github.com/onnx/onnx) 格式。被转换的模型可以通过工具 [Netron](https://github.com/lutzroeder/netron)
+来可视化。除此以外,我们同样支持对 PyTorch 和 ONNX 模型的输出结果做对比。
+
+```bash
+python tools/pytorch2onnx.py \
+ ${CONFIG_FILE} \
+ --checkpoint ${CHECKPOINT_FILE} \
+ --output-file ${ONNX_FILE} \
+ --input-img ${INPUT_IMG} \
+ --shape ${INPUT_SHAPE} \
+ --rescale-shape ${RESCALE_SHAPE} \
+ --show \
+ --verify \
+ --dynamic-export \
+ --cfg-options \
+ model.test_cfg.mode="whole"
+```
+
+各个参数的描述:
+
+- `config` : 模型配置文件的路径
+- `--checkpoint` : 模型检查点文件的路径
+- `--output-file`: 输出的 ONNX 模型的路径。如果没有专门指定,它默认是 `tmp.onnx`
+- `--input-img` : 用来转换和可视化的一张输入图像的路径
+- `--shape`: 模型的输入张量的高和宽。如果没有专门指定,它将被设置成 `test_pipeline` 的 `img_scale`
+- `--rescale-shape`: 改变输出的形状。设置这个值来避免 OOM,它仅在 `slide` 模式下可以用
+- `--show`: 是否打印输出模型的结构。如果没有被专门指定,它将被设置成 `False`
+- `--verify`: 是否验证一个输出模型的正确性 (correctness)。如果没有被专门指定,它将被设置成 `False`
+- `--dynamic-export`: 是否导出形状变化的输入与输出的 ONNX 模型。如果没有被专门指定,它将被设置成 `False`
+- `--cfg-options`: 更新配置选项
+
+**注意**: 这个工具仍然是试验性的,目前一些自定义操作还没有被支持
+
+### 评估 ONNX 模型
+
+我们提供 `tools/deploy_test.py` 去评估不同后端的 ONNX 模型。
+
+#### 先决条件
+
+- 安装 onnx 和 onnxruntime-gpu
+
+ ```shell
+ pip install onnx onnxruntime-gpu
+ ```
+
+- 参考 [如何在 MMCV 里构建 tensorrt 插件](https://mmcv.readthedocs.io/en/latest/tensorrt_plugin.html#how-to-build-tensorrt-plugins-in-mmcv) 安装TensorRT (可选)
+
+#### 使用方法
+
+```bash
+python tools/deploy_test.py \
+ ${CONFIG_FILE} \
+ ${MODEL_FILE} \
+ ${BACKEND} \
+ --out ${OUTPUT_FILE} \
+ --eval ${EVALUATION_METRICS} \
+ --show \
+ --show-dir ${SHOW_DIRECTORY} \
+ --cfg-options ${CFG_OPTIONS} \
+ --eval-options ${EVALUATION_OPTIONS} \
+ --opacity ${OPACITY} \
+```
+
+各个参数的描述:
+
+- `config`: 模型配置文件的路径
+- `model`: 被转换的模型文件的路径
+- `backend`: 推理的后端,可选项:`onnxruntime`, `tensorrt`
+- `--out`: 输出结果成 pickle 格式文件的路径
+- `--format-only` : 不评估直接给输出结果的格式。通常用在当您想把结果输出成一些测试服务器需要的特定格式时。如果没有被专门指定,它将被设置成 `False`。 注意这个参数是用 `--eval` 来 **手动添加**
+- `--eval`: 评估指标,取决于每个数据集的要求,例如 "mIoU" 是大多数据集的指标而 "cityscapes" 仅针对 Cityscapes 数据集。注意这个参数是用 `--format-only` 来 **手动添加**
+- `--show`: 是否展示结果
+- `--show-dir`: 涂上结果的图像被保存的文件夹的路径
+- `--cfg-options`: 重写配置文件里的一些设置,`xxx=yyy` 格式的键值对将被覆盖到配置文件里
+- `--eval-options`: 自定义的评估的选项, `xxx=yyy` 格式的键值对将成为 `dataset.evaluate()` 函数的参数变量
+- `--opacity`: 涂上结果的分割图的透明度,范围在 (0, 1] 之间
+
+#### 结果和模型
+
+| 模型 | 配置文件 | 数据集 | 评价指标 | PyTorch | ONNXRuntime | TensorRT-fp32 | TensorRT-fp16 |
+| :--------: | :---------------------------------------------: | :--------: | :----: | :-----: | :---------: | :-----------: | :-----------: |
+| FCN | fcn_r50-d8_512x1024_40k_cityscapes.py | cityscapes | mIoU | 72.2 | 72.2 | 72.2 | 72.2 |
+| PSPNet | pspnet_r50-d8_512x1024_40k_cityscapes.py | cityscapes | mIoU | 77.8 | 77.8 | 77.8 | 77.8 |
+| deeplabv3 | deeplabv3_r50-d8_512x1024_40k_cityscapes.py | cityscapes | mIoU | 79.0 | 79.0 | 79.0 | 79.0 |
+| deeplabv3+ | deeplabv3plus_r50-d8_512x1024_40k_cityscapes.py | cityscapes | mIoU | 79.6 | 79.5 | 79.5 | 79.5 |
+| PSPNet | pspnet_r50-d8_769x769_40k_cityscapes.py | cityscapes | mIoU | 78.2 | 78.1 | | |
+| deeplabv3 | deeplabv3_r50-d8_769x769_40k_cityscapes.py | cityscapes | mIoU | 78.5 | 78.3 | | |
+| deeplabv3+ | deeplabv3plus_r50-d8_769x769_40k_cityscapes.py | cityscapes | mIoU | 78.9 | 78.7 | | |
+
+**注意**: TensorRT 仅在使用 `whole mode` 测试模式时的配置文件里可用。
+
+### 导出 TorchScript (试验性)
+
+我们同样提供一个脚本去把模型导出成 [TorchScript](https://pytorch.org/docs/stable/jit.html) 格式。您可以使用 pytorch C++ API [LibTorch](https://pytorch.org/docs/stable/cpp_index.html) 去推理训练好的模型。
+被转换的模型能被像 [Netron](https://github.com/lutzroeder/netron) 的工具来可视化。此外,我们还支持 PyTorch 和 TorchScript 模型的输出结果的比较。
+
+```shell
+python tools/pytorch2torchscript.py \
+ ${CONFIG_FILE} \
+ --checkpoint ${CHECKPOINT_FILE} \
+ --output-file ${ONNX_FILE}
+ --shape ${INPUT_SHAPE}
+ --verify \
+ --show
+```
+
+各个参数的描述:
+
+- `config` : pytorch 模型的配置文件的路径
+- `--checkpoint` : pytorch 模型的检查点文件的路径
+- `--output-file`: TorchScript 模型输出的路径,如果没有被专门指定,它将被设置成 `tmp.pt`
+- `--input-img` : 用来转换和可视化的输入图像的路径
+- `--shape`: 模型的输入张量的宽和高。如果没有被专门指定,它将被设置成 `512 512`
+- `--show`: 是否打印输出模型的追踪图 (traced graph),如果没有被专门指定,它将被设置成 `False`
+- `--verify`: 是否验证一个输出模型的正确性 (correctness),如果没有被专门指定,它将被设置成 `False`
+
+**注意**: 目前仅支持 PyTorch>=1.8.0 版本
+
+**注意**: 这个工具仍然是试验性的,一些自定义操作符目前还不被支持
+
+例子:
+
+- 导出 PSPNet 在 cityscapes 数据集上的 pytorch 模型
+
+ ```shell
+ python tools/pytorch2torchscript.py configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py \
+ --checkpoint checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pth \
+ --output-file checkpoints/pspnet_r50-d8_512x1024_40k_cityscapes_20200605_003338-2966598c.pt \
+ --shape 512 1024
+ ```
+
+### 导出 TensorRT (试验性)
+
+一个导出 [ONNX](https://github.com/onnx/onnx) 模型成 [TensorRT](https://developer.nvidia.com/tensorrt) 格式的脚本
+
+先决条件
+
+- 按照 [ONNXRuntime in mmcv](https://mmcv.readthedocs.io/en/latest/deployment/onnxruntime_op.html) 和 [TensorRT plugin in mmcv](https://github.com/open-mmlab/mmcv/blob/master/docs/en/deployment/tensorrt_plugin.md) ,用 ONNXRuntime 自定义运算 (custom ops) 和 TensorRT 插件安装 `mmcv-full`
+- 使用 [pytorch2onnx](#convert-to-onnx-experimental) 将模型从 PyTorch 转成 ONNX
+
+使用方法
+
+```bash
+python ${MMSEG_PATH}/tools/onnx2tensorrt.py \
+ ${CFG_PATH} \
+ ${ONNX_PATH} \
+ --trt-file ${OUTPUT_TRT_PATH} \
+ --min-shape ${MIN_SHAPE} \
+ --max-shape ${MAX_SHAPE} \
+ --input-img ${INPUT_IMG} \
+ --show \
+ --verify
+```
+
+各个参数的描述:
+
+- `config` : 模型的配置文件
+- `model` : 输入的 ONNX 模型的路径
+- `--trt-file` : 输出的 TensorRT 引擎的路径
+- `--max-shape` : 模型的输入的最大形状
+- `--min-shape` : 模型的输入的最小形状
+- `--fp16` : 做 fp16 模型转换
+- `--workspace-size` : 在 GiB 里的最大工作空间大小 (Max workspace size)
+- `--input-img` : 用来可视化的图像
+- `--show` : 做结果的可视化
+- `--dataset` : Palette provider, 默认为 `CityscapesDataset`
+- `--verify` : 验证 ONNXRuntime 和 TensorRT 的输出
+- `--verbose` : 当创建 TensorRT 引擎时,是否详细做信息日志。默认为 False
+
+**注意**: 仅在全图测试模式 (whole mode) 下测试过
+
+## 其他内容
+
+### 打印完整的配置文件
+
+`tools/print_config.py` 会逐字逐句的打印整个配置文件,展开所有的导入。
+
+```shell
+python tools/print_config.py \
+ ${CONFIG} \
+ --graph \
+ --cfg-options ${OPTIONS [OPTIONS...]} \
+```
+
+各个参数的描述:
+
+- `config` : pytorch 模型的配置文件的路径
+- `--graph` : 是否打印模型的图 (models graph)
+- `--cfg-options`: 自定义替换配置文件的选项
+
+### 对训练日志 (training logs) 画图
+
+`tools/analyze_logs.py` 会画出给定的训练日志文件的 loss/mIoU 曲线,首先需要 `pip install seaborn` 安装依赖包。
+
+```shell
+python tools/analyze_logs.py xxx.log.json [--keys ${KEYS}] [--legend ${LEGEND}] [--backend ${BACKEND}] [--style ${STYLE}] [--out ${OUT_FILE}]
+```
+
+示例:
+
+- 对 mIoU, mAcc, aAcc 指标画图
+
+ ```shell
+ python tools/analyze_logs.py log.json --keys mIoU mAcc aAcc --legend mIoU mAcc aAcc
+ ```
+
+- 对 loss 指标画图
+
+ ```shell
+ python tools/analyze_logs.py log.json --keys loss --legend loss
+ ```
+
+### 转换其他仓库的权重
+
+`tools/model_converters/` 提供了若干个预训练权重转换脚本,支持将其他仓库的预训练权重的 key 转换为与 MMSegmentation 相匹配的 key。
+
+#### ViT Swin MiT Transformer 模型
+
+- ViT
+
+`tools/model_converters/vit2mmseg.py` 将 timm 预训练模型转换到 MMSegmentation。
+
+ ```shell
+ python tools/model_converters/vit2mmseg.py ${SRC} ${DST}
+ ```
+
+- Swin
+
+ `tools/model_converters/swin2mmseg.py` 将官方预训练模型转换到 MMSegmentation。
+
+ ```shell
+ python tools/model_converters/swin2mmseg.py ${SRC} ${DST}
+ ```
+
+- SegFormer
+
+ `tools/model_converters/mit2mmseg.py` 将官方预训练模型转换到 MMSegmentation。
+
+ ```shell
+ python tools/model_converters/mit2mmseg.py ${SRC} ${DST}
+ ```
+
+## 模型服务
+
+为了用 [`TorchServe`](https://pytorch.org/serve/) 服务 `MMSegmentation` 的模型 , 您可以遵循如下流程:
+
+### 1. 将 model 从 MMSegmentation 转换到 TorchServe
+
+```shell
+python tools/mmseg2torchserve.py ${CONFIG_FILE} ${CHECKPOINT_FILE} \
+--output-folder ${MODEL_STORE} \
+--model-name ${MODEL_NAME}
+```
+
+**注意**: ${MODEL_STORE} 需要设置为某个文件夹的绝对路径
+
+### 2. 构建 `mmseg-serve` 容器镜像 (docker image)
+
+```shell
+docker build -t mmseg-serve:latest docker/serve/
+```
+
+### 3. 运行 `mmseg-serve`
+
+请查阅官方文档: [使用容器运行 TorchServe](https://github.com/pytorch/serve/blob/master/docker/README.md#running-torchserve-in-a-production-docker-environment)
+
+为了在 GPU 环境下使用, 您需要安装 [nvidia-docker](https://docs.nvidia.com/datacenter/cloud-native/container-toolkit/install-guide.html). 若在 CPU 环境下使用,您可以忽略添加 `--gpus` 参数。
+
+示例:
+
+```shell
+docker run --rm \
+--cpus 8 \
+--gpus device=0 \
+-p8080:8080 -p8081:8081 -p8082:8082 \
+--mount type=bind,source=$MODEL_STORE,target=/home/model-server/model-store \
+mmseg-serve:latest
+```
+
+阅读关于推理 (8080), 管理 (8081) 和指标 (8082) APIs 的 [文档](https://github.com/pytorch/serve/blob/072f5d088cce9bb64b2a18af065886c9b01b317b/docs/rest_api.md) 。
+
+### 4. 测试部署
+
+```shell
+curl -O https://raw.githubusercontent.com/open-mmlab/mmsegmentation/master/resources/3dogs.jpg
+curl http://127.0.0.1:8080/predictions/${MODEL_NAME} -T 3dogs.jpg -o 3dogs_mask.png
+```
+
+得到的响应将是一个 ".png" 的分割掩码.
+
+您可以按照如下方法可视化输出:
+
+```python
+import matplotlib.pyplot as plt
+import mmcv
+plt.imshow(mmcv.imread("3dogs_mask.png", "grayscale"))
+plt.show()
+```
+
+看到的东西将会和下图类似:
+
+
+
+然后您可以使用 `test_torchserve.py` 比较 torchserve 和 pytorch 的结果,并将它们可视化。
+
+```shell
+python tools/torchserve/test_torchserve.py ${IMAGE_FILE} ${CONFIG_FILE} ${CHECKPOINT_FILE} ${MODEL_NAME}
+[--inference-addr ${INFERENCE_ADDR}] [--result-image ${RESULT_IMAGE}] [--device ${DEVICE}]
+```
+
+示例:
+
+```shell
+python tools/torchserve/test_torchserve.py \
+demo/demo.png \
+configs/fcn/fcn_r50-d8_512x1024_40k_cityscapes.py \
+checkpoint/fcn_r50-d8_512x1024_40k_cityscapes_20200604_192608-efe53f0d.pth \
+fcn
+```
diff --git a/EgoHOS/raw/script/mmsegmentation/eval.sh b/EgoHOS/raw/script/mmsegmentation/eval.sh
new file mode 100644
index 0000000000000000000000000000000000000000..3375fa380bdf988dde6b397d531e1e34adb6c589
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/eval.sh
@@ -0,0 +1,14 @@
+# python tools/test.py \
+# /mnt/session_space/home/lingzzha/EgoHOS/mmsegmentation/work_dirs/twohands_cb_to_obj1/twohands_cb_to_obj1.py \
+# /mnt/session_space/home/lingzzha/EgoHOS/mmsegmentation/work_dirs/twohands_cb_to_obj1/best_mIoU_iter_22000.pth \
+# --eval mIoU
+
+# python tools/test.py \
+# /mnt/session_space/home/lingzzha/EgoHOS/mmsegmentation/work_dirs/seg_twohands/seg_twohands.py \
+# /mnt/session_space/home/lingzzha/EgoHOS/mmsegmentation/work_dirs/seg_twohands/best_mIoU_iter_64000.pth \
+# --eval mIoU
+
+python tools/test.py \
+ /mnt/session_space/home/lingzzha/EgoHOS/mmsegmentation/work_dirs/seg_handobj1/seg_handobj1.py \
+ /mnt/session_space/home/lingzzha/EgoHOS/mmsegmentation/work_dirs/seg_handobj1/best_mIoU_iter_96000.pth \
+ --eval mIoU
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..360abfc85761f3144de88422a45c858d602f38d2
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/__init__.py
@@ -0,0 +1,62 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import warnings
+
+import mmcv
+from packaging.version import parse
+
+from .version import __version__, version_info
+
+MMCV_MIN = '1.3.13'
+MMCV_MAX = '1.6.0'
+
+
+def digit_version(version_str: str, length: int = 4):
+ """Convert a version string into a tuple of integers.
+
+ This method is usually used for comparing two versions. For pre-release
+ versions: alpha < beta < rc.
+
+ Args:
+ version_str (str): The version string.
+ length (int): The maximum number of version levels. Default: 4.
+
+ Returns:
+ tuple[int]: The version info in digits (integers).
+ """
+ version = parse(version_str)
+ assert version.release, f'failed to parse version {version_str}'
+ release = list(version.release)
+ release = release[:length]
+ if len(release) < length:
+ release = release + [0] * (length - len(release))
+ if version.is_prerelease:
+ mapping = {'a': -3, 'b': -2, 'rc': -1}
+ val = -4
+ # version.pre can be None
+ if version.pre:
+ if version.pre[0] not in mapping:
+ warnings.warn(f'unknown prerelease version {version.pre[0]}, '
+ 'version checking may go wrong')
+ else:
+ val = mapping[version.pre[0]]
+ release.extend([val, version.pre[-1]])
+ else:
+ release.extend([val, 0])
+
+ elif version.is_postrelease:
+ release.extend([1, version.post])
+ else:
+ release.extend([0, 0])
+ return tuple(release)
+
+
+mmcv_min_version = digit_version(MMCV_MIN)
+mmcv_max_version = digit_version(MMCV_MAX)
+mmcv_version = digit_version(mmcv.__version__)
+
+
+assert (mmcv_min_version <= mmcv_version <= mmcv_max_version), \
+ f'MMCV=={mmcv.__version__} is used but incompatible. ' \
+ f'Please install mmcv>={mmcv_min_version}, <={mmcv_max_version}.'
+
+__all__ = ['__version__', 'version_info', 'digit_version']
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/apis/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/apis/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..c6881805330b61eecc632ac7e93d94cf83dab6cc
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/apis/__init__.py
@@ -0,0 +1,11 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .inference import inference_segmentor, init_segmentor, show_result_pyplot
+from .test import multi_gpu_test, single_gpu_test
+from .train import (get_root_logger, init_random_seed, set_random_seed,
+ train_segmentor)
+
+__all__ = [
+ 'get_root_logger', 'set_random_seed', 'train_segmentor', 'init_segmentor',
+ 'inference_segmentor', 'multi_gpu_test', 'single_gpu_test',
+ 'show_result_pyplot', 'init_random_seed'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/apis/inference.py b/EgoHOS/raw/script/mmsegmentation/mmseg/apis/inference.py
new file mode 100644
index 0000000000000000000000000000000000000000..5e0fa6f3c6ce776d718450d0ec8e08de448fc420
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/apis/inference.py
@@ -0,0 +1,143 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import matplotlib.pyplot as plt
+import mmcv
+import torch
+from mmcv.parallel import collate, scatter
+from mmcv.runner import load_checkpoint
+from mmseg.datasets.pipelines import Compose
+from mmseg.models import build_segmentor
+
+
+def init_segmentor(config, checkpoint=None, device='cuda:0'):
+ """Initialize a segmentor from config file.
+
+ Args:
+ config (str or :obj:`mmcv.Config`): Config file path or the config
+ object.
+ checkpoint (str, optional): Checkpoint path. If left as None, the model
+ will not load any weights.
+ device (str, optional) CPU/CUDA device option. Default 'cuda:0'.
+ Use 'cpu' for loading model on CPU.
+ Returns:
+ nn.Module: The constructed segmentor.
+ """
+ if isinstance(config, str):
+ config = mmcv.Config.fromfile(config)
+ elif not isinstance(config, mmcv.Config):
+ raise TypeError('config must be a filename or Config object, '
+ 'but got {}'.format(type(config)))
+ config.model.pretrained = None
+ config.model.train_cfg = None
+ # import pdb; pdb.set_trace()
+ model = build_segmentor(config.model, test_cfg=config.get('test_cfg'))
+ if checkpoint is not None:
+ checkpoint = load_checkpoint(model, checkpoint, map_location='cpu')
+ model.CLASSES = checkpoint['meta']['CLASSES']
+ model.PALETTE = checkpoint['meta']['PALETTE']
+ model.cfg = config # save the config in the model for convenience
+ model.to(device)
+ model.eval()
+ return model
+
+
+class LoadImage:
+ """A simple pipeline to load image."""
+
+ def __call__(self, results):
+ """Call function to load images into results.
+
+ Args:
+ results (dict): A result dict contains the file name
+ of the image to be read.
+
+ Returns:
+ dict: ``results`` will be returned containing loaded image.
+ """
+
+ if isinstance(results['img'], str):
+ results['filename'] = results['img']
+ results['ori_filename'] = results['img']
+ else:
+ results['filename'] = None
+ results['ori_filename'] = None
+ img = mmcv.imread(results['img'])
+ results['img'] = img
+ results['img_shape'] = img.shape
+ results['ori_shape'] = img.shape
+ return results
+
+
+def inference_segmentor(model, img):
+ """Inference image(s) with the segmentor.
+
+ Args:
+ model (nn.Module): The loaded segmentor.
+ imgs (str/ndarray or list[str/ndarray]): Either image files or loaded
+ images.
+
+ Returns:
+ (list[Tensor]): The segmentation result.
+ """
+ cfg = model.cfg
+ device = next(model.parameters()).device # model device
+ # build the data pipeline
+ test_pipeline = [LoadImage()] + cfg.data.test.pipeline[1:]
+ test_pipeline = Compose(test_pipeline)
+ # prepare data
+ data = dict(img=img)
+ data = test_pipeline(data)
+ data = collate([data], samples_per_gpu=1)
+ if next(model.parameters()).is_cuda:
+ # scatter to specified GPU
+ data = scatter(data, [device])[0]
+ else:
+ data['img_metas'] = [i.data[0] for i in data['img_metas']]
+
+ if 'additional_channel' in cfg.keys():
+ data['img_metas'][0][0]['additional_channel'] = cfg['additional_channel']
+ if 'twohands_dir' in cfg.keys():
+ data['img_metas'][0][0]['twohands_dir'] = cfg['twohands_dir']
+ if 'cb_dir' in cfg.keys():
+ data['img_metas'][0][0]['cb_dir'] = cfg['cb_dir']
+
+ # forward the model
+ with torch.no_grad():
+ result = model(return_loss=False, rescale=True, **data)
+ return result
+
+
+def show_result_pyplot(model,
+ img,
+ result,
+ palette=None,
+ fig_size=(15, 10),
+ opacity=0.5,
+ title='',
+ block=True):
+ """Visualize the segmentation results on the image.
+
+ Args:
+ model (nn.Module): The loaded segmentor.
+ img (str or np.ndarray): Image filename or loaded image.
+ result (list): The segmentation result.
+ palette (list[list[int]]] | None): The palette of segmentation
+ map. If None is given, random palette will be generated.
+ Default: None
+ fig_size (tuple): Figure size of the pyplot figure.
+ opacity(float): Opacity of painted segmentation map.
+ Default 0.5.
+ Must be in (0, 1] range.
+ title (str): The title of pyplot figure.
+ Default is ''.
+ block (bool): Whether to block the pyplot figure.
+ Default is True.
+ """
+ if hasattr(model, 'module'):
+ model = model.module
+ img = model.show_result(
+ img, result, palette=palette, show=False, opacity=opacity)
+ plt.figure(figsize=fig_size)
+ plt.imshow(mmcv.bgr2rgb(img))
+ plt.title(title)
+ plt.tight_layout()
+ plt.show(block=block)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/apis/test.py b/EgoHOS/raw/script/mmsegmentation/mmseg/apis/test.py
new file mode 100644
index 0000000000000000000000000000000000000000..cc4fcc97975741697b7c99c32f66c47b6206f1a6
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/apis/test.py
@@ -0,0 +1,233 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import os.path as osp
+import tempfile
+import warnings
+
+import mmcv
+import numpy as np
+import torch
+from mmcv.engine import collect_results_cpu, collect_results_gpu
+from mmcv.image import tensor2imgs
+from mmcv.runner import get_dist_info
+
+
+def np2tmp(array, temp_file_name=None, tmpdir=None):
+ """Save ndarray to local numpy file.
+
+ Args:
+ array (ndarray): Ndarray to save.
+ temp_file_name (str): Numpy file name. If 'temp_file_name=None', this
+ function will generate a file name with tempfile.NamedTemporaryFile
+ to save ndarray. Default: None.
+ tmpdir (str): Temporary directory to save Ndarray files. Default: None.
+ Returns:
+ str: The numpy file name.
+ """
+
+ if temp_file_name is None:
+ temp_file_name = tempfile.NamedTemporaryFile(
+ suffix='.npy', delete=False, dir=tmpdir).name
+ np.save(temp_file_name, array)
+ return temp_file_name
+
+
+def single_gpu_test(model,
+ data_loader,
+ show=False,
+ out_dir=None,
+ efficient_test=False,
+ opacity=0.5,
+ pre_eval=False,
+ format_only=False,
+ format_args={}):
+ """Test with single GPU by progressive mode.
+
+ Args:
+ model (nn.Module): Model to be tested.
+ data_loader (utils.data.Dataloader): Pytorch data loader.
+ show (bool): Whether show results during inference. Default: False.
+ out_dir (str, optional): If specified, the results will be dumped into
+ the directory to save output results.
+ efficient_test (bool): Whether save the results as local numpy files to
+ save CPU memory during evaluation. Mutually exclusive with
+ pre_eval and format_results. Default: False.
+ opacity(float): Opacity of painted segmentation map.
+ Default 0.5.
+ Must be in (0, 1] range.
+ pre_eval (bool): Use dataset.pre_eval() function to generate
+ pre_results for metric evaluation. Mutually exclusive with
+ efficient_test and format_results. Default: False.
+ format_only (bool): Only format result for results commit.
+ Mutually exclusive with pre_eval and efficient_test.
+ Default: False.
+ format_args (dict): The args for format_results. Default: {}.
+ Returns:
+ list: list of evaluation pre-results or list of save file names.
+ """
+ if efficient_test:
+ warnings.warn(
+ 'DeprecationWarning: ``efficient_test`` will be deprecated, the '
+ 'evaluation is CPU memory friendly with pre_eval=True')
+ mmcv.mkdir_or_exist('.efficient_test')
+ # when none of them is set true, return segmentation results as
+ # a list of np.array.
+ assert [efficient_test, pre_eval, format_only].count(True) <= 1, \
+ '``efficient_test``, ``pre_eval`` and ``format_only`` are mutually ' \
+ 'exclusive, only one of them could be true .'
+
+ model.eval()
+ results = []
+ dataset = data_loader.dataset
+ prog_bar = mmcv.ProgressBar(len(dataset))
+ # The pipeline about how the data_loader retrieval samples from dataset:
+ # sampler -> batch_sampler -> indices
+ # The indices are passed to dataset_fetcher to get data from dataset.
+ # data_fetcher -> collate_fn(dataset[index]) -> data_sample
+ # we use batch_sampler to get correct data idx
+ loader_indices = data_loader.batch_sampler
+
+ for batch_indices, data in zip(loader_indices, data_loader):
+ with torch.no_grad():
+ result = model(return_loss=False, **data)
+
+ if show or out_dir:
+ img_tensor = data['img'][0]
+ img_metas = data['img_metas'][0].data[0]
+ imgs = tensor2imgs(img_tensor, **img_metas[0]['img_norm_cfg'])
+ assert len(imgs) == len(img_metas)
+
+ for img, img_meta in zip(imgs, img_metas):
+ h, w, _ = img_meta['img_shape']
+ img_show = img[:h, :w, :]
+
+ ori_h, ori_w = img_meta['ori_shape'][:-1]
+ img_show = mmcv.imresize(img_show, (ori_w, ori_h))
+
+ if out_dir:
+ out_file = osp.join(out_dir, img_meta['ori_filename'])
+ else:
+ out_file = None
+
+ model.module.show_result(
+ img_show,
+ result,
+ palette=dataset.PALETTE,
+ show=show,
+ out_file=out_file,
+ opacity=opacity)
+
+ if efficient_test:
+ result = [np2tmp(_, tmpdir='.efficient_test') for _ in result]
+
+ if format_only:
+ result = dataset.format_results(
+ result, indices=batch_indices, **format_args)
+ if pre_eval:
+ # TODO: adapt samples_per_gpu > 1.
+ # only samples_per_gpu=1 valid now
+ result = dataset.pre_eval(result, indices=batch_indices)
+ results.extend(result)
+ else:
+ results.extend(result)
+
+ batch_size = len(result)
+ for _ in range(batch_size):
+ prog_bar.update()
+
+ return results
+
+
+def multi_gpu_test(model,
+ data_loader,
+ tmpdir=None,
+ gpu_collect=False,
+ efficient_test=False,
+ pre_eval=False,
+ format_only=False,
+ format_args={}):
+ """Test model with multiple gpus by progressive mode.
+
+ This method tests model with multiple gpus and collects the results
+ under two different modes: gpu and cpu modes. By setting 'gpu_collect=True'
+ it encodes results to gpu tensors and use gpu communication for results
+ collection. On cpu mode it saves the results on different gpus to 'tmpdir'
+ and collects them by the rank 0 worker.
+
+ Args:
+ model (nn.Module): Model to be tested.
+ data_loader (utils.data.Dataloader): Pytorch data loader.
+ tmpdir (str): Path of directory to save the temporary results from
+ different gpus under cpu mode. The same path is used for efficient
+ test. Default: None.
+ gpu_collect (bool): Option to use either gpu or cpu to collect results.
+ Default: False.
+ efficient_test (bool): Whether save the results as local numpy files to
+ save CPU memory during evaluation. Mutually exclusive with
+ pre_eval and format_results. Default: False.
+ pre_eval (bool): Use dataset.pre_eval() function to generate
+ pre_results for metric evaluation. Mutually exclusive with
+ efficient_test and format_results. Default: False.
+ format_only (bool): Only format result for results commit.
+ Mutually exclusive with pre_eval and efficient_test.
+ Default: False.
+ format_args (dict): The args for format_results. Default: {}.
+
+ Returns:
+ list: list of evaluation pre-results or list of save file names.
+ """
+ if efficient_test:
+ warnings.warn(
+ 'DeprecationWarning: ``efficient_test`` will be deprecated, the '
+ 'evaluation is CPU memory friendly with pre_eval=True')
+ mmcv.mkdir_or_exist('.efficient_test')
+ # when none of them is set true, return segmentation results as
+ # a list of np.array.
+ assert [efficient_test, pre_eval, format_only].count(True) <= 1, \
+ '``efficient_test``, ``pre_eval`` and ``format_only`` are mutually ' \
+ 'exclusive, only one of them could be true .'
+
+ model.eval()
+ results = []
+ dataset = data_loader.dataset
+ # The pipeline about how the data_loader retrieval samples from dataset:
+ # sampler -> batch_sampler -> indices
+ # The indices are passed to dataset_fetcher to get data from dataset.
+ # data_fetcher -> collate_fn(dataset[index]) -> data_sample
+ # we use batch_sampler to get correct data idx
+
+ # batch_sampler based on DistributedSampler, the indices only point to data
+ # samples of related machine.
+ loader_indices = data_loader.batch_sampler
+
+ rank, world_size = get_dist_info()
+ if rank == 0:
+ prog_bar = mmcv.ProgressBar(len(dataset))
+
+ for batch_indices, data in zip(loader_indices, data_loader):
+ with torch.no_grad():
+ result = model(return_loss=False, rescale=True, **data)
+
+ if efficient_test:
+ result = [np2tmp(_, tmpdir='.efficient_test') for _ in result]
+
+ if format_only:
+ result = dataset.format_results(
+ result, indices=batch_indices, **format_args)
+ if pre_eval:
+ # TODO: adapt samples_per_gpu > 1.
+ # only samples_per_gpu=1 valid now
+ result = dataset.pre_eval(result, indices=batch_indices)
+
+ results.extend(result)
+
+ if rank == 0:
+ batch_size = len(result) * world_size
+ for _ in range(batch_size):
+ prog_bar.update()
+
+ # collect results from all ranks
+ if gpu_collect:
+ results = collect_results_gpu(results, len(dataset))
+ else:
+ results = collect_results_cpu(results, len(dataset), tmpdir)
+ return results
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/apis/train.py b/EgoHOS/raw/script/mmsegmentation/mmseg/apis/train.py
new file mode 100644
index 0000000000000000000000000000000000000000..3563e3620396594fa346ff9555d6e07b74f61c39
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/apis/train.py
@@ -0,0 +1,191 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import random
+import warnings
+
+import mmcv
+import numpy as np
+import torch
+import torch.distributed as dist
+from mmcv.parallel import MMDataParallel, MMDistributedDataParallel
+from mmcv.runner import (HOOKS, DistSamplerSeedHook, EpochBasedRunner,
+ build_runner, get_dist_info)
+from mmcv.utils import build_from_cfg
+
+from mmseg import digit_version
+from mmseg.core import DistEvalHook, EvalHook, build_optimizer
+from mmseg.datasets import build_dataloader, build_dataset
+from mmseg.utils import find_latest_checkpoint, get_root_logger
+
+
+def init_random_seed(seed=None, device='cuda'):
+ """Initialize random seed.
+
+ If the seed is not set, the seed will be automatically randomized,
+ and then broadcast to all processes to prevent some potential bugs.
+ Args:
+ seed (int, Optional): The seed. Default to None.
+ device (str): The device where the seed will be put on.
+ Default to 'cuda'.
+ Returns:
+ int: Seed to be used.
+ """
+ if seed is not None:
+ return seed
+
+ # Make sure all ranks share the same random seed to prevent
+ # some potential bugs. Please refer to
+ # https://github.com/open-mmlab/mmdetection/issues/6339
+ rank, world_size = get_dist_info()
+ seed = np.random.randint(2**31)
+ if world_size == 1:
+ return seed
+
+ if rank == 0:
+ random_num = torch.tensor(seed, dtype=torch.int32, device=device)
+ else:
+ random_num = torch.tensor(0, dtype=torch.int32, device=device)
+ dist.broadcast(random_num, src=0)
+ return random_num.item()
+
+
+def set_random_seed(seed, deterministic=False):
+ """Set random seed.
+
+ Args:
+ seed (int): Seed to be used.
+ deterministic (bool): Whether to set the deterministic option for
+ CUDNN backend, i.e., set `torch.backends.cudnn.deterministic`
+ to True and `torch.backends.cudnn.benchmark` to False.
+ Default: False.
+ """
+ random.seed(seed)
+ np.random.seed(seed)
+ torch.manual_seed(seed)
+ torch.cuda.manual_seed_all(seed)
+ if deterministic:
+ torch.backends.cudnn.deterministic = True
+ torch.backends.cudnn.benchmark = False
+
+
+def train_segmentor(model,
+ dataset,
+ cfg,
+ distributed=False,
+ validate=False,
+ timestamp=None,
+ meta=None):
+ """Launch segmentor training."""
+ logger = get_root_logger(cfg.log_level)
+
+ # prepare data loaders
+ dataset = dataset if isinstance(dataset, (list, tuple)) else [dataset]
+ # The default loader config
+ loader_cfg = dict(
+ # cfg.gpus will be ignored if distributed
+ num_gpus=len(cfg.gpu_ids),
+ dist=distributed,
+ seed=cfg.seed,
+ drop_last=True)
+ # The overall dataloader settings
+ loader_cfg.update({
+ k: v
+ for k, v in cfg.data.items() if k not in [
+ 'train', 'val', 'test', 'train_dataloader', 'val_dataloader',
+ 'test_dataloader'
+ ]
+ })
+
+ # The specific dataloader settings
+ train_loader_cfg = {**loader_cfg, **cfg.data.get('train_dataloader', {})}
+ data_loaders = [build_dataloader(ds, **train_loader_cfg) for ds in dataset]
+
+ # put model on gpus
+ if distributed:
+ find_unused_parameters = cfg.get('find_unused_parameters', False)
+ # Sets the `find_unused_parameters` parameter in
+ # torch.nn.parallel.DistributedDataParallel
+ model = MMDistributedDataParallel(
+ model.cuda(),
+ device_ids=[torch.cuda.current_device()],
+ broadcast_buffers=False,
+ find_unused_parameters=find_unused_parameters)
+ else:
+ if not torch.cuda.is_available():
+ assert digit_version(mmcv.__version__) >= digit_version('1.4.4'), \
+ 'Please use MMCV >= 1.4.4 for CPU training!'
+ model = MMDataParallel(model, device_ids=cfg.gpu_ids)
+ # build runner
+ optimizer = build_optimizer(model, cfg.optimizer)
+
+ if cfg.get('runner') is None:
+ cfg.runner = {'type': 'IterBasedRunner', 'max_iters': cfg.total_iters}
+ warnings.warn(
+ 'config is now expected to have a `runner` section, '
+ 'please set `runner` in your config.', UserWarning)
+
+ runner = build_runner(
+ cfg.runner,
+ default_args=dict(
+ model=model,
+ batch_processor=None,
+ optimizer=optimizer,
+ work_dir=cfg.work_dir,
+ logger=logger,
+ meta=meta))
+
+ # register hooks
+ runner.register_training_hooks(cfg.lr_config, cfg.optimizer_config,
+ cfg.checkpoint_config, cfg.log_config,
+ cfg.get('momentum_config', None))
+ if distributed:
+ # when distributed training by epoch, using`DistSamplerSeedHook` to set
+ # the different seed to distributed sampler for each epoch, it will
+ # shuffle dataset at each epoch and avoid overfitting.
+ if isinstance(runner, EpochBasedRunner):
+ runner.register_hook(DistSamplerSeedHook())
+
+ # an ugly walkaround to make the .log and .log.json filenames the same
+ runner.timestamp = timestamp
+
+ # register eval hooks
+ if validate:
+ val_dataset = build_dataset(cfg.data.val, dict(test_mode=True))
+ # The specific dataloader settings
+ val_loader_cfg = {
+ **loader_cfg,
+ 'samples_per_gpu': 1,
+ 'shuffle': False, # Not shuffle by default
+ **cfg.data.get('val_dataloader', {}),
+ }
+ val_dataloader = build_dataloader(val_dataset, **val_loader_cfg)
+ eval_cfg = cfg.get('evaluation', {})
+ eval_cfg['by_epoch'] = cfg.runner['type'] != 'IterBasedRunner'
+ eval_hook = DistEvalHook if distributed else EvalHook
+ # In this PR (https://github.com/open-mmlab/mmcv/pull/1193), the
+ # priority of IterTimerHook has been modified from 'NORMAL' to 'LOW'.
+ runner.register_hook(
+ eval_hook(val_dataloader, **eval_cfg), priority='LOW')
+
+ # user-defined hooks
+ if cfg.get('custom_hooks', None):
+ custom_hooks = cfg.custom_hooks
+ assert isinstance(custom_hooks, list), \
+ f'custom_hooks expect list type, but got {type(custom_hooks)}'
+ for hook_cfg in cfg.custom_hooks:
+ assert isinstance(hook_cfg, dict), \
+ 'Each item in custom_hooks expects dict type, but got ' \
+ f'{type(hook_cfg)}'
+ hook_cfg = hook_cfg.copy()
+ priority = hook_cfg.pop('priority', 'NORMAL')
+ hook = build_from_cfg(hook_cfg, HOOKS)
+ runner.register_hook(hook, priority=priority)
+
+ if cfg.resume_from is None and cfg.get('auto_resume'):
+ resume_from = find_latest_checkpoint(cfg.work_dir)
+ if resume_from is not None:
+ cfg.resume_from = resume_from
+ if cfg.resume_from:
+ runner.resume(cfg.resume_from)
+ elif cfg.load_from:
+ runner.load_checkpoint(cfg.load_from)
+ runner.run(data_loaders, cfg.workflow)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/core/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/core/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..1a077d2f1fd8889b8f60851cb7940ec8abc28567
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/core/__init__.py
@@ -0,0 +1,11 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .builder import (OPTIMIZER_BUILDERS, build_optimizer,
+ build_optimizer_constructor)
+from .evaluation import * # noqa: F401, F403
+from .optimizers import * # noqa: F401, F403
+from .seg import * # noqa: F401, F403
+from .utils import * # noqa: F401, F403
+
+__all__ = [
+ 'OPTIMIZER_BUILDERS', 'build_optimizer', 'build_optimizer_constructor'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/core/builder.py b/EgoHOS/raw/script/mmsegmentation/mmseg/core/builder.py
new file mode 100644
index 0000000000000000000000000000000000000000..406dd9b4b7027e9c2254b0d18cf0c80a7161912b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/core/builder.py
@@ -0,0 +1,33 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import copy
+
+from mmcv.runner.optimizer import OPTIMIZER_BUILDERS as MMCV_OPTIMIZER_BUILDERS
+from mmcv.utils import Registry, build_from_cfg
+
+OPTIMIZER_BUILDERS = Registry(
+ 'optimizer builder', parent=MMCV_OPTIMIZER_BUILDERS)
+
+
+def build_optimizer_constructor(cfg):
+ constructor_type = cfg.get('type')
+ if constructor_type in OPTIMIZER_BUILDERS:
+ return build_from_cfg(cfg, OPTIMIZER_BUILDERS)
+ elif constructor_type in MMCV_OPTIMIZER_BUILDERS:
+ return build_from_cfg(cfg, MMCV_OPTIMIZER_BUILDERS)
+ else:
+ raise KeyError(f'{constructor_type} is not registered '
+ 'in the optimizer builder registry.')
+
+
+def build_optimizer(model, cfg):
+ optimizer_cfg = copy.deepcopy(cfg)
+ constructor_type = optimizer_cfg.pop('constructor',
+ 'DefaultOptimizerConstructor')
+ paramwise_cfg = optimizer_cfg.pop('paramwise_cfg', None)
+ optim_constructor = build_optimizer_constructor(
+ dict(
+ type=constructor_type,
+ optimizer_cfg=optimizer_cfg,
+ paramwise_cfg=paramwise_cfg))
+ optimizer = optim_constructor(model)
+ return optimizer
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/core/evaluation/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/core/evaluation/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..3d16d17e54222f006e32cd6b9e6ca323e3738f03
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/core/evaluation/__init__.py
@@ -0,0 +1,11 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .class_names import get_classes, get_palette
+from .eval_hooks import DistEvalHook, EvalHook
+from .metrics import (eval_metrics, intersect_and_union, mean_dice,
+ mean_fscore, mean_iou, pre_eval_to_metrics)
+
+__all__ = [
+ 'EvalHook', 'DistEvalHook', 'mean_dice', 'mean_iou', 'mean_fscore',
+ 'eval_metrics', 'get_classes', 'get_palette', 'pre_eval_to_metrics',
+ 'intersect_and_union'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/core/evaluation/class_names.py b/EgoHOS/raw/script/mmsegmentation/mmseg/core/evaluation/class_names.py
new file mode 100644
index 0000000000000000000000000000000000000000..e3bff6231435412852d87b22f5b897207c1f56af
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/core/evaluation/class_names.py
@@ -0,0 +1,316 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import mmcv
+
+
+def cityscapes_classes():
+ """Cityscapes class names for external use."""
+ return [
+ 'road', 'sidewalk', 'building', 'wall', 'fence', 'pole',
+ 'traffic light', 'traffic sign', 'vegetation', 'terrain', 'sky',
+ 'person', 'rider', 'car', 'truck', 'bus', 'train', 'motorcycle',
+ 'bicycle'
+ ]
+
+
+def ade_classes():
+ """ADE20K class names for external use."""
+ return [
+ 'wall', 'building', 'sky', 'floor', 'tree', 'ceiling', 'road', 'bed ',
+ 'windowpane', 'grass', 'cabinet', 'sidewalk', 'person', 'earth',
+ 'door', 'table', 'mountain', 'plant', 'curtain', 'chair', 'car',
+ 'water', 'painting', 'sofa', 'shelf', 'house', 'sea', 'mirror', 'rug',
+ 'field', 'armchair', 'seat', 'fence', 'desk', 'rock', 'wardrobe',
+ 'lamp', 'bathtub', 'railing', 'cushion', 'base', 'box', 'column',
+ 'signboard', 'chest of drawers', 'counter', 'sand', 'sink',
+ 'skyscraper', 'fireplace', 'refrigerator', 'grandstand', 'path',
+ 'stairs', 'runway', 'case', 'pool table', 'pillow', 'screen door',
+ 'stairway', 'river', 'bridge', 'bookcase', 'blind', 'coffee table',
+ 'toilet', 'flower', 'book', 'hill', 'bench', 'countertop', 'stove',
+ 'palm', 'kitchen island', 'computer', 'swivel chair', 'boat', 'bar',
+ 'arcade machine', 'hovel', 'bus', 'towel', 'light', 'truck', 'tower',
+ 'chandelier', 'awning', 'streetlight', 'booth', 'television receiver',
+ 'airplane', 'dirt track', 'apparel', 'pole', 'land', 'bannister',
+ 'escalator', 'ottoman', 'bottle', 'buffet', 'poster', 'stage', 'van',
+ 'ship', 'fountain', 'conveyer belt', 'canopy', 'washer', 'plaything',
+ 'swimming pool', 'stool', 'barrel', 'basket', 'waterfall', 'tent',
+ 'bag', 'minibike', 'cradle', 'oven', 'ball', 'food', 'step', 'tank',
+ 'trade name', 'microwave', 'pot', 'animal', 'bicycle', 'lake',
+ 'dishwasher', 'screen', 'blanket', 'sculpture', 'hood', 'sconce',
+ 'vase', 'traffic light', 'tray', 'ashcan', 'fan', 'pier', 'crt screen',
+ 'plate', 'monitor', 'bulletin board', 'shower', 'radiator', 'glass',
+ 'clock', 'flag'
+ ]
+
+
+def voc_classes():
+ """Pascal VOC class names for external use."""
+ return [
+ 'background', 'aeroplane', 'bicycle', 'bird', 'boat', 'bottle', 'bus',
+ 'car', 'cat', 'chair', 'cow', 'diningtable', 'dog', 'horse',
+ 'motorbike', 'person', 'pottedplant', 'sheep', 'sofa', 'train',
+ 'tvmonitor'
+ ]
+
+
+def cocostuff_classes():
+ """CocoStuff class names for external use."""
+ return [
+ 'person', 'bicycle', 'car', 'motorcycle', 'airplane', 'bus', 'train',
+ 'truck', 'boat', 'traffic light', 'fire hydrant', 'stop sign',
+ 'parking meter', 'bench', 'bird', 'cat', 'dog', 'horse', 'sheep',
+ 'cow', 'elephant', 'bear', 'zebra', 'giraffe', 'backpack', 'umbrella',
+ 'handbag', 'tie', 'suitcase', 'frisbee', 'skis', 'snowboard',
+ 'sports ball', 'kite', 'baseball bat', 'baseball glove', 'skateboard',
+ 'surfboard', 'tennis racket', 'bottle', 'wine glass', 'cup', 'fork',
+ 'knife', 'spoon', 'bowl', 'banana', 'apple', 'sandwich', 'orange',
+ 'broccoli', 'carrot', 'hot dog', 'pizza', 'donut', 'cake', 'chair',
+ 'couch', 'potted plant', 'bed', 'dining table', 'toilet', 'tv',
+ 'laptop', 'mouse', 'remote', 'keyboard', 'cell phone', 'microwave',
+ 'oven', 'toaster', 'sink', 'refrigerator', 'book', 'clock', 'vase',
+ 'scissors', 'teddy bear', 'hair drier', 'toothbrush', 'banner',
+ 'blanket', 'branch', 'bridge', 'building-other', 'bush', 'cabinet',
+ 'cage', 'cardboard', 'carpet', 'ceiling-other', 'ceiling-tile',
+ 'cloth', 'clothes', 'clouds', 'counter', 'cupboard', 'curtain',
+ 'desk-stuff', 'dirt', 'door-stuff', 'fence', 'floor-marble',
+ 'floor-other', 'floor-stone', 'floor-tile', 'floor-wood', 'flower',
+ 'fog', 'food-other', 'fruit', 'furniture-other', 'grass', 'gravel',
+ 'ground-other', 'hill', 'house', 'leaves', 'light', 'mat', 'metal',
+ 'mirror-stuff', 'moss', 'mountain', 'mud', 'napkin', 'net', 'paper',
+ 'pavement', 'pillow', 'plant-other', 'plastic', 'platform',
+ 'playingfield', 'railing', 'railroad', 'river', 'road', 'rock', 'roof',
+ 'rug', 'salad', 'sand', 'sea', 'shelf', 'sky-other', 'skyscraper',
+ 'snow', 'solid-other', 'stairs', 'stone', 'straw', 'structural-other',
+ 'table', 'tent', 'textile-other', 'towel', 'tree', 'vegetable',
+ 'wall-brick', 'wall-concrete', 'wall-other', 'wall-panel',
+ 'wall-stone', 'wall-tile', 'wall-wood', 'water-other', 'waterdrops',
+ 'window-blind', 'window-other', 'wood'
+ ]
+
+
+def loveda_classes():
+ """LoveDA class names for external use."""
+ return [
+ 'background', 'building', 'road', 'water', 'barren', 'forest',
+ 'agricultural'
+ ]
+
+
+def potsdam_classes():
+ """Potsdam class names for external use."""
+ return [
+ 'impervious_surface', 'building', 'low_vegetation', 'tree', 'car',
+ 'clutter'
+ ]
+
+
+def vaihingen_classes():
+ """Vaihingen class names for external use."""
+ return [
+ 'impervious_surface', 'building', 'low_vegetation', 'tree', 'car',
+ 'clutter'
+ ]
+
+
+def isaid_classes():
+ """iSAID class names for external use."""
+ return [
+ 'background', 'ship', 'store_tank', 'baseball_diamond', 'tennis_court',
+ 'basketball_court', 'Ground_Track_Field', 'Bridge', 'Large_Vehicle',
+ 'Small_Vehicle', 'Helicopter', 'Swimming_pool', 'Roundabout',
+ 'Soccer_ball_field', 'plane', 'Harbor'
+ ]
+
+
+def stare_classes():
+ """stare class names for external use."""
+ return ['background', 'vessel']
+
+
+def cityscapes_palette():
+ """Cityscapes palette for external use."""
+ return [[128, 64, 128], [244, 35, 232], [70, 70, 70], [102, 102, 156],
+ [190, 153, 153], [153, 153, 153], [250, 170, 30], [220, 220, 0],
+ [107, 142, 35], [152, 251, 152], [70, 130, 180], [220, 20, 60],
+ [255, 0, 0], [0, 0, 142], [0, 0, 70], [0, 60, 100], [0, 80, 100],
+ [0, 0, 230], [119, 11, 32]]
+
+
+def ade_palette():
+ """ADE20K palette for external use."""
+ return [[120, 120, 120], [180, 120, 120], [6, 230, 230], [80, 50, 50],
+ [4, 200, 3], [120, 120, 80], [140, 140, 140], [204, 5, 255],
+ [230, 230, 230], [4, 250, 7], [224, 5, 255], [235, 255, 7],
+ [150, 5, 61], [120, 120, 70], [8, 255, 51], [255, 6, 82],
+ [143, 255, 140], [204, 255, 4], [255, 51, 7], [204, 70, 3],
+ [0, 102, 200], [61, 230, 250], [255, 6, 51], [11, 102, 255],
+ [255, 7, 71], [255, 9, 224], [9, 7, 230], [220, 220, 220],
+ [255, 9, 92], [112, 9, 255], [8, 255, 214], [7, 255, 224],
+ [255, 184, 6], [10, 255, 71], [255, 41, 10], [7, 255, 255],
+ [224, 255, 8], [102, 8, 255], [255, 61, 6], [255, 194, 7],
+ [255, 122, 8], [0, 255, 20], [255, 8, 41], [255, 5, 153],
+ [6, 51, 255], [235, 12, 255], [160, 150, 20], [0, 163, 255],
+ [140, 140, 140], [250, 10, 15], [20, 255, 0], [31, 255, 0],
+ [255, 31, 0], [255, 224, 0], [153, 255, 0], [0, 0, 255],
+ [255, 71, 0], [0, 235, 255], [0, 173, 255], [31, 0, 255],
+ [11, 200, 200], [255, 82, 0], [0, 255, 245], [0, 61, 255],
+ [0, 255, 112], [0, 255, 133], [255, 0, 0], [255, 163, 0],
+ [255, 102, 0], [194, 255, 0], [0, 143, 255], [51, 255, 0],
+ [0, 82, 255], [0, 255, 41], [0, 255, 173], [10, 0, 255],
+ [173, 255, 0], [0, 255, 153], [255, 92, 0], [255, 0, 255],
+ [255, 0, 245], [255, 0, 102], [255, 173, 0], [255, 0, 20],
+ [255, 184, 184], [0, 31, 255], [0, 255, 61], [0, 71, 255],
+ [255, 0, 204], [0, 255, 194], [0, 255, 82], [0, 10, 255],
+ [0, 112, 255], [51, 0, 255], [0, 194, 255], [0, 122, 255],
+ [0, 255, 163], [255, 153, 0], [0, 255, 10], [255, 112, 0],
+ [143, 255, 0], [82, 0, 255], [163, 255, 0], [255, 235, 0],
+ [8, 184, 170], [133, 0, 255], [0, 255, 92], [184, 0, 255],
+ [255, 0, 31], [0, 184, 255], [0, 214, 255], [255, 0, 112],
+ [92, 255, 0], [0, 224, 255], [112, 224, 255], [70, 184, 160],
+ [163, 0, 255], [153, 0, 255], [71, 255, 0], [255, 0, 163],
+ [255, 204, 0], [255, 0, 143], [0, 255, 235], [133, 255, 0],
+ [255, 0, 235], [245, 0, 255], [255, 0, 122], [255, 245, 0],
+ [10, 190, 212], [214, 255, 0], [0, 204, 255], [20, 0, 255],
+ [255, 255, 0], [0, 153, 255], [0, 41, 255], [0, 255, 204],
+ [41, 0, 255], [41, 255, 0], [173, 0, 255], [0, 245, 255],
+ [71, 0, 255], [122, 0, 255], [0, 255, 184], [0, 92, 255],
+ [184, 255, 0], [0, 133, 255], [255, 214, 0], [25, 194, 194],
+ [102, 255, 0], [92, 0, 255]]
+
+
+def voc_palette():
+ """Pascal VOC palette for external use."""
+ return [[0, 0, 0], [128, 0, 0], [0, 128, 0], [128, 128, 0], [0, 0, 128],
+ [128, 0, 128], [0, 128, 128], [128, 128, 128], [64, 0, 0],
+ [192, 0, 0], [64, 128, 0], [192, 128, 0], [64, 0, 128],
+ [192, 0, 128], [64, 128, 128], [192, 128, 128], [0, 64, 0],
+ [128, 64, 0], [0, 192, 0], [128, 192, 0], [0, 64, 128]]
+
+
+def cocostuff_palette():
+ """CocoStuff palette for external use."""
+ return [[0, 192, 64], [0, 192, 64], [0, 64, 96], [128, 192, 192],
+ [0, 64, 64], [0, 192, 224], [0, 192, 192], [128, 192, 64],
+ [0, 192, 96], [128, 192, 64], [128, 32, 192], [0, 0, 224],
+ [0, 0, 64], [0, 160, 192], [128, 0, 96], [128, 0, 192],
+ [0, 32, 192], [128, 128, 224], [0, 0, 192], [128, 160, 192],
+ [128, 128, 0], [128, 0, 32], [128, 32, 0], [128, 0, 128],
+ [64, 128, 32], [0, 160, 0], [0, 0, 0], [192, 128, 160], [0, 32, 0],
+ [0, 128, 128], [64, 128, 160], [128, 160, 0], [0, 128, 0],
+ [192, 128, 32], [128, 96, 128], [0, 0, 128], [64, 0, 32],
+ [0, 224, 128], [128, 0, 0], [192, 0, 160], [0, 96, 128],
+ [128, 128, 128], [64, 0, 160], [128, 224, 128], [128, 128, 64],
+ [192, 0, 32], [128, 96, 0], [128, 0, 192], [0, 128, 32],
+ [64, 224, 0], [0, 0, 64], [128, 128, 160], [64, 96, 0],
+ [0, 128, 192], [0, 128, 160], [192, 224, 0], [0, 128, 64],
+ [128, 128, 32], [192, 32, 128], [0, 64, 192], [0, 0, 32],
+ [64, 160, 128], [128, 64, 64], [128, 0, 160], [64, 32, 128],
+ [128, 192, 192], [0, 0, 160], [192, 160, 128], [128, 192, 0],
+ [128, 0, 96], [192, 32, 0], [128, 64, 128], [64, 128, 96],
+ [64, 160, 0], [0, 64, 0], [192, 128, 224], [64, 32, 0],
+ [0, 192, 128], [64, 128, 224], [192, 160, 0], [0, 192, 0],
+ [192, 128, 96], [192, 96, 128], [0, 64, 128], [64, 0, 96],
+ [64, 224, 128], [128, 64, 0], [192, 0, 224], [64, 96, 128],
+ [128, 192, 128], [64, 0, 224], [192, 224, 128], [128, 192, 64],
+ [192, 0, 96], [192, 96, 0], [128, 64, 192], [0, 128, 96],
+ [0, 224, 0], [64, 64, 64], [128, 128, 224], [0, 96, 0],
+ [64, 192, 192], [0, 128, 224], [128, 224, 0], [64, 192, 64],
+ [128, 128, 96], [128, 32, 128], [64, 0, 192], [0, 64, 96],
+ [0, 160, 128], [192, 0, 64], [128, 64, 224], [0, 32, 128],
+ [192, 128, 192], [0, 64, 224], [128, 160, 128], [192, 128, 0],
+ [128, 64, 32], [128, 32, 64], [192, 0, 128], [64, 192, 32],
+ [0, 160, 64], [64, 0, 0], [192, 192, 160], [0, 32, 64],
+ [64, 128, 128], [64, 192, 160], [128, 160, 64], [64, 128, 0],
+ [192, 192, 32], [128, 96, 192], [64, 0, 128], [64, 64, 32],
+ [0, 224, 192], [192, 0, 0], [192, 64, 160], [0, 96, 192],
+ [192, 128, 128], [64, 64, 160], [128, 224, 192], [192, 128, 64],
+ [192, 64, 32], [128, 96, 64], [192, 0, 192], [0, 192, 32],
+ [64, 224, 64], [64, 0, 64], [128, 192, 160], [64, 96, 64],
+ [64, 128, 192], [0, 192, 160], [192, 224, 64], [64, 128, 64],
+ [128, 192, 32], [192, 32, 192], [64, 64, 192], [0, 64, 32],
+ [64, 160, 192], [192, 64, 64], [128, 64, 160], [64, 32, 192],
+ [192, 192, 192], [0, 64, 160], [192, 160, 192], [192, 192, 0],
+ [128, 64, 96], [192, 32, 64], [192, 64, 128], [64, 192, 96],
+ [64, 160, 64], [64, 64, 0]]
+
+
+def loveda_palette():
+ """LoveDA palette for external use."""
+ return [[255, 255, 255], [255, 0, 0], [255, 255, 0], [0, 0, 255],
+ [159, 129, 183], [0, 255, 0], [255, 195, 128]]
+
+
+def potsdam_palette():
+ """Potsdam palette for external use."""
+ return [[255, 255, 255], [0, 0, 255], [0, 255, 255], [0, 255, 0],
+ [255, 255, 0], [255, 0, 0]]
+
+
+def vaihingen_palette():
+ """Vaihingen palette for external use."""
+ return [[255, 255, 255], [0, 0, 255], [0, 255, 255], [0, 255, 0],
+ [255, 255, 0], [255, 0, 0]]
+
+
+def isaid_palette():
+ """iSAID palette for external use."""
+ return [[0, 0, 0], [0, 0, 63], [0, 63, 63], [0, 63, 0], [0, 63, 127],
+ [0, 63, 191], [0, 63, 255], [0, 127, 63], [0, 127,
+ 127], [0, 0, 127],
+ [0, 0, 191], [0, 0, 255], [0, 191, 127], [0, 127, 191],
+ [0, 127, 255], [0, 100, 155]]
+
+
+def stare_palette():
+ """STARE palette for external use."""
+ return [[120, 120, 120], [6, 230, 230]]
+
+
+dataset_aliases = {
+ 'cityscapes': ['cityscapes'],
+ 'ade': ['ade', 'ade20k'],
+ 'voc': ['voc', 'pascal_voc', 'voc12', 'voc12aug'],
+ 'loveda': ['loveda'],
+ 'potsdam': ['potsdam'],
+ 'vaihingen': ['vaihingen'],
+ 'cocostuff': [
+ 'cocostuff', 'cocostuff10k', 'cocostuff164k', 'coco-stuff',
+ 'coco-stuff10k', 'coco-stuff164k', 'coco_stuff', 'coco_stuff10k',
+ 'coco_stuff164k'
+ ],
+ 'isaid': ['isaid', 'iSAID'],
+ 'stare': ['stare', 'STARE']
+}
+
+
+def get_classes(dataset):
+ """Get class names of a dataset."""
+ alias2name = {}
+ for name, aliases in dataset_aliases.items():
+ for alias in aliases:
+ alias2name[alias] = name
+
+ if mmcv.is_str(dataset):
+ if dataset in alias2name:
+ labels = eval(alias2name[dataset] + '_classes()')
+ else:
+ raise ValueError(f'Unrecognized dataset: {dataset}')
+ else:
+ raise TypeError(f'dataset must a str, but got {type(dataset)}')
+ return labels
+
+
+def get_palette(dataset):
+ """Get class palette (RGB) of a dataset."""
+ alias2name = {}
+ for name, aliases in dataset_aliases.items():
+ for alias in aliases:
+ alias2name[alias] = name
+
+ if mmcv.is_str(dataset):
+ if dataset in alias2name:
+ labels = eval(alias2name[dataset] + '_palette()')
+ else:
+ raise ValueError(f'Unrecognized dataset: {dataset}')
+ else:
+ raise TypeError(f'dataset must a str, but got {type(dataset)}')
+ return labels
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/core/evaluation/eval_hooks.py b/EgoHOS/raw/script/mmsegmentation/mmseg/core/evaluation/eval_hooks.py
new file mode 100644
index 0000000000000000000000000000000000000000..952db3b0b410ecbe1999435c3ca8722034381ef7
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/core/evaluation/eval_hooks.py
@@ -0,0 +1,128 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import os.path as osp
+import warnings
+
+import torch.distributed as dist
+from mmcv.runner import DistEvalHook as _DistEvalHook
+from mmcv.runner import EvalHook as _EvalHook
+from torch.nn.modules.batchnorm import _BatchNorm
+
+
+class EvalHook(_EvalHook):
+ """Single GPU EvalHook, with efficient test support.
+
+ Args:
+ by_epoch (bool): Determine perform evaluation by epoch or by iteration.
+ If set to True, it will perform by epoch. Otherwise, by iteration.
+ Default: False.
+ efficient_test (bool): Whether save the results as local numpy files to
+ save CPU memory during evaluation. Default: False.
+ pre_eval (bool): Whether to use progressive mode to evaluate model.
+ Default: False.
+ Returns:
+ list: The prediction results.
+ """
+
+ greater_keys = ['mIoU', 'mAcc', 'aAcc']
+
+ def __init__(self,
+ *args,
+ by_epoch=False,
+ efficient_test=False,
+ pre_eval=False,
+ **kwargs):
+ super().__init__(*args, by_epoch=by_epoch, **kwargs)
+ self.pre_eval = pre_eval
+ if efficient_test:
+ warnings.warn(
+ 'DeprecationWarning: ``efficient_test`` for evaluation hook '
+ 'is deprecated, the evaluation hook is CPU memory friendly '
+ 'with ``pre_eval=True`` as argument for ``single_gpu_test()`` '
+ 'function')
+
+ def _do_evaluate(self, runner):
+ """perform evaluation and save ckpt."""
+ if not self._should_evaluate(runner):
+ return
+
+ from mmseg.apis import single_gpu_test
+ results = single_gpu_test(
+ runner.model, self.dataloader, show=False, pre_eval=self.pre_eval)
+ runner.log_buffer.clear()
+ runner.log_buffer.output['eval_iter_num'] = len(self.dataloader)
+ key_score = self.evaluate(runner, results)
+ if self.save_best:
+ self._save_ckpt(runner, key_score)
+
+
+class DistEvalHook(_DistEvalHook):
+ """Distributed EvalHook, with efficient test support.
+
+ Args:
+ by_epoch (bool): Determine perform evaluation by epoch or by iteration.
+ If set to True, it will perform by epoch. Otherwise, by iteration.
+ Default: False.
+ efficient_test (bool): Whether save the results as local numpy files to
+ save CPU memory during evaluation. Default: False.
+ pre_eval (bool): Whether to use progressive mode to evaluate model.
+ Default: False.
+ Returns:
+ list: The prediction results.
+ """
+
+ greater_keys = ['mIoU', 'mAcc', 'aAcc']
+
+ def __init__(self,
+ *args,
+ by_epoch=False,
+ efficient_test=False,
+ pre_eval=False,
+ **kwargs):
+ super().__init__(*args, by_epoch=by_epoch, **kwargs)
+ self.pre_eval = pre_eval
+ if efficient_test:
+ warnings.warn(
+ 'DeprecationWarning: ``efficient_test`` for evaluation hook '
+ 'is deprecated, the evaluation hook is CPU memory friendly '
+ 'with ``pre_eval=True`` as argument for ``multi_gpu_test()`` '
+ 'function')
+
+ def _do_evaluate(self, runner):
+ """perform evaluation and save ckpt."""
+ # Synchronization of BatchNorm's buffer (running_mean
+ # and running_var) is not supported in the DDP of pytorch,
+ # which may cause the inconsistent performance of models in
+ # different ranks, so we broadcast BatchNorm's buffers
+ # of rank 0 to other ranks to avoid this.
+ if self.broadcast_bn_buffer:
+ model = runner.model
+ for name, module in model.named_modules():
+ if isinstance(module,
+ _BatchNorm) and module.track_running_stats:
+ dist.broadcast(module.running_var, 0)
+ dist.broadcast(module.running_mean, 0)
+
+ if not self._should_evaluate(runner):
+ return
+
+ tmpdir = self.tmpdir
+ if tmpdir is None:
+ tmpdir = osp.join(runner.work_dir, '.eval_hook')
+
+ from mmseg.apis import multi_gpu_test
+ results = multi_gpu_test(
+ runner.model,
+ self.dataloader,
+ tmpdir=tmpdir,
+ gpu_collect=self.gpu_collect,
+ pre_eval=self.pre_eval)
+
+ runner.log_buffer.clear()
+
+ if runner.rank == 0:
+ print('\n')
+ runner.log_buffer.output['eval_iter_num'] = len(self.dataloader)
+ key_score = self.evaluate(runner, results)
+
+ if self.save_best:
+ self._save_ckpt(runner, key_score)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/core/evaluation/metrics.py b/EgoHOS/raw/script/mmsegmentation/mmseg/core/evaluation/metrics.py
new file mode 100644
index 0000000000000000000000000000000000000000..a1c0908e155cf06f51c72f4cec27ad15a482d4eb
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/core/evaluation/metrics.py
@@ -0,0 +1,395 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from collections import OrderedDict
+
+import mmcv
+import numpy as np
+import torch
+
+
+def f_score(precision, recall, beta=1):
+ """calculate the f-score value.
+
+ Args:
+ precision (float | torch.Tensor): The precision value.
+ recall (float | torch.Tensor): The recall value.
+ beta (int): Determines the weight of recall in the combined score.
+ Default: False.
+
+ Returns:
+ [torch.tensor]: The f-score value.
+ """
+ score = (1 + beta**2) * (precision * recall) / (
+ (beta**2 * precision) + recall)
+ return score
+
+
+def intersect_and_union(pred_label,
+ label,
+ num_classes,
+ ignore_index,
+ label_map=dict(),
+ reduce_zero_label=False):
+ """Calculate intersection and Union.
+
+ Args:
+ pred_label (ndarray | str): Prediction segmentation map
+ or predict result filename.
+ label (ndarray | str): Ground truth segmentation map
+ or label filename.
+ num_classes (int): Number of categories.
+ ignore_index (int): Index that will be ignored in evaluation.
+ label_map (dict): Mapping old labels to new labels. The parameter will
+ work only when label is str. Default: dict().
+ reduce_zero_label (bool): Whether ignore zero label. The parameter will
+ work only when label is str. Default: False.
+
+ Returns:
+ torch.Tensor: The intersection of prediction and ground truth
+ histogram on all classes.
+ torch.Tensor: The union of prediction and ground truth histogram on
+ all classes.
+ torch.Tensor: The prediction histogram on all classes.
+ torch.Tensor: The ground truth histogram on all classes.
+ """
+
+ if isinstance(pred_label, str):
+ pred_label = torch.from_numpy(np.load(pred_label))
+ else:
+ pred_label = torch.from_numpy((pred_label))
+
+ if isinstance(label, str):
+ label = torch.from_numpy(
+ mmcv.imread(label, flag='unchanged', backend='pillow'))
+ else:
+ label = torch.from_numpy(label)
+
+ if label_map is not None:
+ for old_id, new_id in label_map.items():
+ label[label == old_id] = new_id
+ if reduce_zero_label:
+ label[label == 0] = 255
+ label = label - 1
+ label[label == 254] = 255
+
+ mask = (label != ignore_index)
+ pred_label = pred_label[mask]
+ label = label[mask]
+
+ intersect = pred_label[pred_label == label]
+ area_intersect = torch.histc(
+ intersect.float(), bins=(num_classes), min=0, max=num_classes - 1)
+ area_pred_label = torch.histc(
+ pred_label.float(), bins=(num_classes), min=0, max=num_classes - 1)
+ area_label = torch.histc(
+ label.float(), bins=(num_classes), min=0, max=num_classes - 1)
+ area_union = area_pred_label + area_label - area_intersect
+ return area_intersect, area_union, area_pred_label, area_label
+
+
+def total_intersect_and_union(results,
+ gt_seg_maps,
+ num_classes,
+ ignore_index,
+ label_map=dict(),
+ reduce_zero_label=False):
+ """Calculate Total Intersection and Union.
+
+ Args:
+ results (list[ndarray] | list[str]): List of prediction segmentation
+ maps or list of prediction result filenames.
+ gt_seg_maps (list[ndarray] | list[str] | Iterables): list of ground
+ truth segmentation maps or list of label filenames.
+ num_classes (int): Number of categories.
+ ignore_index (int): Index that will be ignored in evaluation.
+ label_map (dict): Mapping old labels to new labels. Default: dict().
+ reduce_zero_label (bool): Whether ignore zero label. Default: False.
+
+ Returns:
+ ndarray: The intersection of prediction and ground truth histogram
+ on all classes.
+ ndarray: The union of prediction and ground truth histogram on all
+ classes.
+ ndarray: The prediction histogram on all classes.
+ ndarray: The ground truth histogram on all classes.
+ """
+ total_area_intersect = torch.zeros((num_classes, ), dtype=torch.float64)
+ total_area_union = torch.zeros((num_classes, ), dtype=torch.float64)
+ total_area_pred_label = torch.zeros((num_classes, ), dtype=torch.float64)
+ total_area_label = torch.zeros((num_classes, ), dtype=torch.float64)
+ for result, gt_seg_map in zip(results, gt_seg_maps):
+ area_intersect, area_union, area_pred_label, area_label = \
+ intersect_and_union(
+ result, gt_seg_map, num_classes, ignore_index,
+ label_map, reduce_zero_label)
+ total_area_intersect += area_intersect
+ total_area_union += area_union
+ total_area_pred_label += area_pred_label
+ total_area_label += area_label
+ return total_area_intersect, total_area_union, total_area_pred_label, \
+ total_area_label
+
+
+def mean_iou(results,
+ gt_seg_maps,
+ num_classes,
+ ignore_index,
+ nan_to_num=None,
+ label_map=dict(),
+ reduce_zero_label=False):
+ """Calculate Mean Intersection and Union (mIoU)
+
+ Args:
+ results (list[ndarray] | list[str]): List of prediction segmentation
+ maps or list of prediction result filenames.
+ gt_seg_maps (list[ndarray] | list[str]): list of ground truth
+ segmentation maps or list of label filenames.
+ num_classes (int): Number of categories.
+ ignore_index (int): Index that will be ignored in evaluation.
+ nan_to_num (int, optional): If specified, NaN values will be replaced
+ by the numbers defined by the user. Default: None.
+ label_map (dict): Mapping old labels to new labels. Default: dict().
+ reduce_zero_label (bool): Whether ignore zero label. Default: False.
+
+ Returns:
+ dict[str, float | ndarray]:
+ float: Overall accuracy on all images.
+ ndarray: Per category accuracy, shape (num_classes, ).
+ ndarray: Per category IoU, shape (num_classes, ).
+ """
+ iou_result = eval_metrics(
+ results=results,
+ gt_seg_maps=gt_seg_maps,
+ num_classes=num_classes,
+ ignore_index=ignore_index,
+ metrics=['mIoU'],
+ nan_to_num=nan_to_num,
+ label_map=label_map,
+ reduce_zero_label=reduce_zero_label)
+ return iou_result
+
+
+def mean_dice(results,
+ gt_seg_maps,
+ num_classes,
+ ignore_index,
+ nan_to_num=None,
+ label_map=dict(),
+ reduce_zero_label=False):
+ """Calculate Mean Dice (mDice)
+
+ Args:
+ results (list[ndarray] | list[str]): List of prediction segmentation
+ maps or list of prediction result filenames.
+ gt_seg_maps (list[ndarray] | list[str]): list of ground truth
+ segmentation maps or list of label filenames.
+ num_classes (int): Number of categories.
+ ignore_index (int): Index that will be ignored in evaluation.
+ nan_to_num (int, optional): If specified, NaN values will be replaced
+ by the numbers defined by the user. Default: None.
+ label_map (dict): Mapping old labels to new labels. Default: dict().
+ reduce_zero_label (bool): Whether ignore zero label. Default: False.
+
+ Returns:
+ dict[str, float | ndarray]: Default metrics.
+ float: Overall accuracy on all images.
+ ndarray: Per category accuracy, shape (num_classes, ).
+ ndarray: Per category dice, shape (num_classes, ).
+ """
+
+ dice_result = eval_metrics(
+ results=results,
+ gt_seg_maps=gt_seg_maps,
+ num_classes=num_classes,
+ ignore_index=ignore_index,
+ metrics=['mDice'],
+ nan_to_num=nan_to_num,
+ label_map=label_map,
+ reduce_zero_label=reduce_zero_label)
+ return dice_result
+
+
+def mean_fscore(results,
+ gt_seg_maps,
+ num_classes,
+ ignore_index,
+ nan_to_num=None,
+ label_map=dict(),
+ reduce_zero_label=False,
+ beta=1):
+ """Calculate Mean Intersection and Union (mIoU)
+
+ Args:
+ results (list[ndarray] | list[str]): List of prediction segmentation
+ maps or list of prediction result filenames.
+ gt_seg_maps (list[ndarray] | list[str]): list of ground truth
+ segmentation maps or list of label filenames.
+ num_classes (int): Number of categories.
+ ignore_index (int): Index that will be ignored in evaluation.
+ nan_to_num (int, optional): If specified, NaN values will be replaced
+ by the numbers defined by the user. Default: None.
+ label_map (dict): Mapping old labels to new labels. Default: dict().
+ reduce_zero_label (bool): Whether ignore zero label. Default: False.
+ beta (int): Determines the weight of recall in the combined score.
+ Default: False.
+
+
+ Returns:
+ dict[str, float | ndarray]: Default metrics.
+ float: Overall accuracy on all images.
+ ndarray: Per category recall, shape (num_classes, ).
+ ndarray: Per category precision, shape (num_classes, ).
+ ndarray: Per category f-score, shape (num_classes, ).
+ """
+ fscore_result = eval_metrics(
+ results=results,
+ gt_seg_maps=gt_seg_maps,
+ num_classes=num_classes,
+ ignore_index=ignore_index,
+ metrics=['mFscore'],
+ nan_to_num=nan_to_num,
+ label_map=label_map,
+ reduce_zero_label=reduce_zero_label,
+ beta=beta)
+ return fscore_result
+
+
+def eval_metrics(results,
+ gt_seg_maps,
+ num_classes,
+ ignore_index,
+ metrics=['mIoU'],
+ nan_to_num=None,
+ label_map=dict(),
+ reduce_zero_label=False,
+ beta=1):
+ """Calculate evaluation metrics
+ Args:
+ results (list[ndarray] | list[str]): List of prediction segmentation
+ maps or list of prediction result filenames.
+ gt_seg_maps (list[ndarray] | list[str] | Iterables): list of ground
+ truth segmentation maps or list of label filenames.
+ num_classes (int): Number of categories.
+ ignore_index (int): Index that will be ignored in evaluation.
+ metrics (list[str] | str): Metrics to be evaluated, 'mIoU' and 'mDice'.
+ nan_to_num (int, optional): If specified, NaN values will be replaced
+ by the numbers defined by the user. Default: None.
+ label_map (dict): Mapping old labels to new labels. Default: dict().
+ reduce_zero_label (bool): Whether ignore zero label. Default: False.
+ Returns:
+ float: Overall accuracy on all images.
+ ndarray: Per category accuracy, shape (num_classes, ).
+ ndarray: Per category evaluation metrics, shape (num_classes, ).
+ """
+
+ total_area_intersect, total_area_union, total_area_pred_label, \
+ total_area_label = total_intersect_and_union(
+ results, gt_seg_maps, num_classes, ignore_index, label_map,
+ reduce_zero_label)
+ ret_metrics = total_area_to_metrics(total_area_intersect, total_area_union,
+ total_area_pred_label,
+ total_area_label, metrics, nan_to_num,
+ beta)
+
+ return ret_metrics
+
+
+def pre_eval_to_metrics(pre_eval_results,
+ metrics=['mIoU'],
+ nan_to_num=None,
+ beta=1):
+ """Convert pre-eval results to metrics.
+
+ Args:
+ pre_eval_results (list[tuple[torch.Tensor]]): per image eval results
+ for computing evaluation metric
+ metrics (list[str] | str): Metrics to be evaluated, 'mIoU' and 'mDice'.
+ nan_to_num (int, optional): If specified, NaN values will be replaced
+ by the numbers defined by the user. Default: None.
+ Returns:
+ float: Overall accuracy on all images.
+ ndarray: Per category accuracy, shape (num_classes, ).
+ ndarray: Per category evaluation metrics, shape (num_classes, ).
+ """
+
+ # convert list of tuples to tuple of lists, e.g.
+ # [(A_1, B_1, C_1, D_1), ..., (A_n, B_n, C_n, D_n)] to
+ # ([A_1, ..., A_n], ..., [D_1, ..., D_n])
+ pre_eval_results = tuple(zip(*pre_eval_results))
+ assert len(pre_eval_results) == 4
+
+ total_area_intersect = sum(pre_eval_results[0])
+ total_area_union = sum(pre_eval_results[1])
+ total_area_pred_label = sum(pre_eval_results[2])
+ total_area_label = sum(pre_eval_results[3])
+
+ ret_metrics = total_area_to_metrics(total_area_intersect, total_area_union,
+ total_area_pred_label,
+ total_area_label, metrics, nan_to_num,
+ beta)
+
+ return ret_metrics
+
+
+def total_area_to_metrics(total_area_intersect,
+ total_area_union,
+ total_area_pred_label,
+ total_area_label,
+ metrics=['mIoU'],
+ nan_to_num=None,
+ beta=1):
+ """Calculate evaluation metrics
+ Args:
+ total_area_intersect (ndarray): The intersection of prediction and
+ ground truth histogram on all classes.
+ total_area_union (ndarray): The union of prediction and ground truth
+ histogram on all classes.
+ total_area_pred_label (ndarray): The prediction histogram on all
+ classes.
+ total_area_label (ndarray): The ground truth histogram on all classes.
+ metrics (list[str] | str): Metrics to be evaluated, 'mIoU' and 'mDice'.
+ nan_to_num (int, optional): If specified, NaN values will be replaced
+ by the numbers defined by the user. Default: None.
+ Returns:
+ float: Overall accuracy on all images.
+ ndarray: Per category accuracy, shape (num_classes, ).
+ ndarray: Per category evaluation metrics, shape (num_classes, ).
+ """
+ if isinstance(metrics, str):
+ metrics = [metrics]
+ allowed_metrics = ['mIoU', 'mDice', 'mFscore']
+ if not set(metrics).issubset(set(allowed_metrics)):
+ raise KeyError('metrics {} is not supported'.format(metrics))
+
+ all_acc = total_area_intersect.sum() / total_area_label.sum()
+ ret_metrics = OrderedDict({'aAcc': all_acc})
+ for metric in metrics:
+ if metric == 'mIoU':
+ iou = total_area_intersect / total_area_union
+ acc = total_area_intersect / total_area_label
+ ret_metrics['IoU'] = iou
+ ret_metrics['Acc'] = acc
+ elif metric == 'mDice':
+ dice = 2 * total_area_intersect / (
+ total_area_pred_label + total_area_label)
+ acc = total_area_intersect / total_area_label
+ ret_metrics['Dice'] = dice
+ ret_metrics['Acc'] = acc
+ elif metric == 'mFscore':
+ precision = total_area_intersect / total_area_pred_label
+ recall = total_area_intersect / total_area_label
+ f_value = torch.tensor(
+ [f_score(x[0], x[1], beta) for x in zip(precision, recall)])
+ ret_metrics['Fscore'] = f_value
+ ret_metrics['Precision'] = precision
+ ret_metrics['Recall'] = recall
+
+ ret_metrics = {
+ metric: value.numpy()
+ for metric, value in ret_metrics.items()
+ }
+ if nan_to_num is not None:
+ ret_metrics = OrderedDict({
+ metric: np.nan_to_num(metric_value, nan=nan_to_num)
+ for metric, metric_value in ret_metrics.items()
+ })
+ return ret_metrics
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/core/optimizers/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/core/optimizers/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..4fbf4ecfcd4d1f0834322e2964b55d9637c844ba
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/core/optimizers/__init__.py
@@ -0,0 +1,7 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .layer_decay_optimizer_constructor import (
+ LayerDecayOptimizerConstructor, LearningRateDecayOptimizerConstructor)
+
+__all__ = [
+ 'LearningRateDecayOptimizerConstructor', 'LayerDecayOptimizerConstructor'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/core/optimizers/layer_decay_optimizer_constructor.py b/EgoHOS/raw/script/mmsegmentation/mmseg/core/optimizers/layer_decay_optimizer_constructor.py
new file mode 100644
index 0000000000000000000000000000000000000000..2b6b8ff9c97f4c65ac713bde8031454f3ba7c074
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/core/optimizers/layer_decay_optimizer_constructor.py
@@ -0,0 +1,208 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import json
+import warnings
+
+from mmcv.runner import DefaultOptimizerConstructor, get_dist_info
+
+from mmseg.utils import get_root_logger
+from ..builder import OPTIMIZER_BUILDERS
+
+
+def get_layer_id_for_convnext(var_name, max_layer_id):
+ """Get the layer id to set the different learning rates in ``layer_wise``
+ decay_type.
+
+ Args:
+ var_name (str): The key of the model.
+ max_layer_id (int): Maximum number of backbone layers.
+
+ Returns:
+ int: The id number corresponding to different learning rate in
+ ``LearningRateDecayOptimizerConstructor``.
+ """
+
+ if var_name in ('backbone.cls_token', 'backbone.mask_token',
+ 'backbone.pos_embed'):
+ return 0
+ elif var_name.startswith('backbone.downsample_layers'):
+ stage_id = int(var_name.split('.')[2])
+ if stage_id == 0:
+ layer_id = 0
+ elif stage_id == 1:
+ layer_id = 2
+ elif stage_id == 2:
+ layer_id = 3
+ elif stage_id == 3:
+ layer_id = max_layer_id
+ return layer_id
+ elif var_name.startswith('backbone.stages'):
+ stage_id = int(var_name.split('.')[2])
+ block_id = int(var_name.split('.')[3])
+ if stage_id == 0:
+ layer_id = 1
+ elif stage_id == 1:
+ layer_id = 2
+ elif stage_id == 2:
+ layer_id = 3 + block_id // 3
+ elif stage_id == 3:
+ layer_id = max_layer_id
+ return layer_id
+ else:
+ return max_layer_id + 1
+
+
+def get_stage_id_for_convnext(var_name, max_stage_id):
+ """Get the stage id to set the different learning rates in ``stage_wise``
+ decay_type.
+
+ Args:
+ var_name (str): The key of the model.
+ max_stage_id (int): Maximum number of backbone layers.
+
+ Returns:
+ int: The id number corresponding to different learning rate in
+ ``LearningRateDecayOptimizerConstructor``.
+ """
+
+ if var_name in ('backbone.cls_token', 'backbone.mask_token',
+ 'backbone.pos_embed'):
+ return 0
+ elif var_name.startswith('backbone.downsample_layers'):
+ return 0
+ elif var_name.startswith('backbone.stages'):
+ stage_id = int(var_name.split('.')[2])
+ return stage_id + 1
+ else:
+ return max_stage_id - 1
+
+
+def get_layer_id_for_vit(var_name, max_layer_id):
+ """Get the layer id to set the different learning rates.
+
+ Args:
+ var_name (str): The key of the model.
+ num_max_layer (int): Maximum number of backbone layers.
+
+ Returns:
+ int: Returns the layer id of the key.
+ """
+
+ if var_name in ('backbone.cls_token', 'backbone.mask_token',
+ 'backbone.pos_embed'):
+ return 0
+ elif var_name.startswith('backbone.patch_embed'):
+ return 0
+ elif var_name.startswith('backbone.layers'):
+ layer_id = int(var_name.split('.')[2])
+ return layer_id + 1
+ else:
+ return max_layer_id - 1
+
+
+@OPTIMIZER_BUILDERS.register_module()
+class LearningRateDecayOptimizerConstructor(DefaultOptimizerConstructor):
+ """Different learning rates are set for different layers of backbone.
+
+ Note: Currently, this optimizer constructor is built for ConvNeXt,
+ BEiT and MAE.
+ """
+
+ def add_params(self, params, module, **kwargs):
+ """Add all parameters of module to the params list.
+
+ The parameters of the given module will be added to the list of param
+ groups, with specific rules defined by paramwise_cfg.
+
+ Args:
+ params (list[dict]): A list of param groups, it will be modified
+ in place.
+ module (nn.Module): The module to be added.
+ """
+ logger = get_root_logger()
+
+ parameter_groups = {}
+ logger.info(f'self.paramwise_cfg is {self.paramwise_cfg}')
+ num_layers = self.paramwise_cfg.get('num_layers') + 2
+ decay_rate = self.paramwise_cfg.get('decay_rate')
+ decay_type = self.paramwise_cfg.get('decay_type', 'layer_wise')
+ logger.info('Build LearningRateDecayOptimizerConstructor '
+ f'{decay_type} {decay_rate} - {num_layers}')
+ weight_decay = self.base_wd
+ for name, param in module.named_parameters():
+ if not param.requires_grad:
+ continue # frozen weights
+ if len(param.shape) == 1 or name.endswith('.bias') or name in (
+ 'pos_embed', 'cls_token'):
+ group_name = 'no_decay'
+ this_weight_decay = 0.
+ else:
+ group_name = 'decay'
+ this_weight_decay = weight_decay
+ if 'layer_wise' in decay_type:
+ if 'ConvNeXt' in module.backbone.__class__.__name__:
+ layer_id = get_layer_id_for_convnext(
+ name, self.paramwise_cfg.get('num_layers'))
+ logger.info(f'set param {name} as id {layer_id}')
+ elif 'BEiT' in module.backbone.__class__.__name__ or \
+ 'MAE' in module.backbone.__class__.__name__:
+ layer_id = get_layer_id_for_vit(name, num_layers)
+ logger.info(f'set param {name} as id {layer_id}')
+ else:
+ raise NotImplementedError()
+ elif decay_type == 'stage_wise':
+ if 'ConvNeXt' in module.backbone.__class__.__name__:
+ layer_id = get_stage_id_for_convnext(name, num_layers)
+ logger.info(f'set param {name} as id {layer_id}')
+ else:
+ raise NotImplementedError()
+ group_name = f'layer_{layer_id}_{group_name}'
+
+ if group_name not in parameter_groups:
+ scale = decay_rate**(num_layers - layer_id - 1)
+
+ parameter_groups[group_name] = {
+ 'weight_decay': this_weight_decay,
+ 'params': [],
+ 'param_names': [],
+ 'lr_scale': scale,
+ 'group_name': group_name,
+ 'lr': scale * self.base_lr,
+ }
+
+ parameter_groups[group_name]['params'].append(param)
+ parameter_groups[group_name]['param_names'].append(name)
+ rank, _ = get_dist_info()
+ if rank == 0:
+ to_display = {}
+ for key in parameter_groups:
+ to_display[key] = {
+ 'param_names': parameter_groups[key]['param_names'],
+ 'lr_scale': parameter_groups[key]['lr_scale'],
+ 'lr': parameter_groups[key]['lr'],
+ 'weight_decay': parameter_groups[key]['weight_decay'],
+ }
+ logger.info(f'Param groups = {json.dumps(to_display, indent=2)}')
+ params.extend(parameter_groups.values())
+
+
+@OPTIMIZER_BUILDERS.register_module()
+class LayerDecayOptimizerConstructor(LearningRateDecayOptimizerConstructor):
+ """Different learning rates are set for different layers of backbone.
+
+ Note: Currently, this optimizer constructor is built for BEiT,
+ and it will be deprecated.
+ Please use ``LearningRateDecayOptimizerConstructor`` instead.
+ """
+
+ def __init__(self, optimizer_cfg, paramwise_cfg):
+ warnings.warn('DeprecationWarning: Original '
+ 'LayerDecayOptimizerConstructor of BEiT '
+ 'will be deprecated. Please use '
+ 'LearningRateDecayOptimizerConstructor instead, '
+ 'and set decay_type = layer_wise_vit in paramwise_cfg.')
+ paramwise_cfg.update({'decay_type': 'layer_wise_vit'})
+ warnings.warn('DeprecationWarning: Layer_decay_rate will '
+ 'be deleted, please use decay_rate instead.')
+ paramwise_cfg['decay_rate'] = paramwise_cfg.pop('layer_decay_rate')
+ super(LayerDecayOptimizerConstructor,
+ self).__init__(optimizer_cfg, paramwise_cfg)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/core/seg/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/core/seg/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..5206b96be6f87e99e8ae820bdd788444f4d255d9
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/core/seg/__init__.py
@@ -0,0 +1,5 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .builder import build_pixel_sampler
+from .sampler import BasePixelSampler, OHEMPixelSampler
+
+__all__ = ['build_pixel_sampler', 'BasePixelSampler', 'OHEMPixelSampler']
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/core/seg/builder.py b/EgoHOS/raw/script/mmsegmentation/mmseg/core/seg/builder.py
new file mode 100644
index 0000000000000000000000000000000000000000..1cecd347bffb6ab289f27e0f9bbab91c3a5d4bd8
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/core/seg/builder.py
@@ -0,0 +1,9 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from mmcv.utils import Registry, build_from_cfg
+
+PIXEL_SAMPLERS = Registry('pixel sampler')
+
+
+def build_pixel_sampler(cfg, **default_args):
+ """Build pixel sampler for segmentation map."""
+ return build_from_cfg(cfg, PIXEL_SAMPLERS, default_args)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/core/seg/sampler/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/core/seg/sampler/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..5a7648564adbfcdb3e66f640e4f9c61de6e215e1
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/core/seg/sampler/__init__.py
@@ -0,0 +1,5 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .base_pixel_sampler import BasePixelSampler
+from .ohem_pixel_sampler import OHEMPixelSampler
+
+__all__ = ['BasePixelSampler', 'OHEMPixelSampler']
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/core/seg/sampler/base_pixel_sampler.py b/EgoHOS/raw/script/mmsegmentation/mmseg/core/seg/sampler/base_pixel_sampler.py
new file mode 100644
index 0000000000000000000000000000000000000000..03672cd478a2e464cc734ae92686c86f219da0a9
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/core/seg/sampler/base_pixel_sampler.py
@@ -0,0 +1,13 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from abc import ABCMeta, abstractmethod
+
+
+class BasePixelSampler(metaclass=ABCMeta):
+ """Base class of pixel sampler."""
+
+ def __init__(self, **kwargs):
+ pass
+
+ @abstractmethod
+ def sample(self, seg_logit, seg_label):
+ """Placeholder for sample function."""
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/core/seg/sampler/ohem_pixel_sampler.py b/EgoHOS/raw/script/mmsegmentation/mmseg/core/seg/sampler/ohem_pixel_sampler.py
new file mode 100644
index 0000000000000000000000000000000000000000..833a28768cd0bfddfc7ab59d3ba3cbe892b2fbb5
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/core/seg/sampler/ohem_pixel_sampler.py
@@ -0,0 +1,85 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+
+from ..builder import PIXEL_SAMPLERS
+from .base_pixel_sampler import BasePixelSampler
+
+
+@PIXEL_SAMPLERS.register_module()
+class OHEMPixelSampler(BasePixelSampler):
+ """Online Hard Example Mining Sampler for segmentation.
+
+ Args:
+ context (nn.Module): The context of sampler, subclass of
+ :obj:`BaseDecodeHead`.
+ thresh (float, optional): The threshold for hard example selection.
+ Below which, are prediction with low confidence. If not
+ specified, the hard examples will be pixels of top ``min_kept``
+ loss. Default: None.
+ min_kept (int, optional): The minimum number of predictions to keep.
+ Default: 100000.
+ """
+
+ def __init__(self, context, thresh=None, min_kept=100000):
+ super(OHEMPixelSampler, self).__init__()
+ self.context = context
+ assert min_kept > 1
+ self.thresh = thresh
+ self.min_kept = min_kept
+
+ def sample(self, seg_logit, seg_label):
+ """Sample pixels that have high loss or with low prediction confidence.
+
+ Args:
+ seg_logit (torch.Tensor): segmentation logits, shape (N, C, H, W)
+ seg_label (torch.Tensor): segmentation label, shape (N, 1, H, W)
+
+ Returns:
+ torch.Tensor: segmentation weight, shape (N, H, W)
+ """
+ with torch.no_grad():
+ assert seg_logit.shape[2:] == seg_label.shape[2:]
+ assert seg_label.shape[1] == 1
+ seg_label = seg_label.squeeze(1).long()
+ batch_kept = self.min_kept * seg_label.size(0)
+ valid_mask = seg_label != self.context.ignore_index
+ seg_weight = seg_logit.new_zeros(size=seg_label.size())
+ valid_seg_weight = seg_weight[valid_mask]
+ if self.thresh is not None:
+ seg_prob = F.softmax(seg_logit, dim=1)
+
+ tmp_seg_label = seg_label.clone().unsqueeze(1)
+ tmp_seg_label[tmp_seg_label == self.context.ignore_index] = 0
+ seg_prob = seg_prob.gather(1, tmp_seg_label).squeeze(1)
+ sort_prob, sort_indices = seg_prob[valid_mask].sort()
+
+ if sort_prob.numel() > 0:
+ min_threshold = sort_prob[min(batch_kept,
+ sort_prob.numel() - 1)]
+ else:
+ min_threshold = 0.0
+ threshold = max(min_threshold, self.thresh)
+ valid_seg_weight[seg_prob[valid_mask] < threshold] = 1.
+ else:
+ if not isinstance(self.context.loss_decode, nn.ModuleList):
+ losses_decode = [self.context.loss_decode]
+ else:
+ losses_decode = self.context.loss_decode
+ losses = 0.0
+ for loss_module in losses_decode:
+ losses += loss_module(
+ seg_logit,
+ seg_label,
+ weight=None,
+ ignore_index=self.context.ignore_index,
+ reduction_override='none')
+
+ # faster than topk according to https://github.com/pytorch/pytorch/issues/22812 # noqa
+ _, sort_indices = losses[valid_mask].sort(descending=True)
+ valid_seg_weight[sort_indices[:batch_kept]] = 1.
+
+ seg_weight[valid_mask] = valid_seg_weight
+
+ return seg_weight
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/core/utils/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/core/utils/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..28882893a53a78dcb7063e51b07273d30dd1c19f
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/core/utils/__init__.py
@@ -0,0 +1,5 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .dist_util import check_dist_init, sync_random_seed
+from .misc import add_prefix
+
+__all__ = ['add_prefix', 'check_dist_init', 'sync_random_seed']
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/core/utils/dist_util.py b/EgoHOS/raw/script/mmsegmentation/mmseg/core/utils/dist_util.py
new file mode 100644
index 0000000000000000000000000000000000000000..b3288519d0a8785db12c00da9d48e51de5ce3ba1
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/core/utils/dist_util.py
@@ -0,0 +1,46 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import numpy as np
+import torch
+import torch.distributed as dist
+from mmcv.runner import get_dist_info
+
+
+def check_dist_init():
+ return dist.is_available() and dist.is_initialized()
+
+
+def sync_random_seed(seed=None, device='cuda'):
+ """Make sure different ranks share the same seed. All workers must call
+ this function, otherwise it will deadlock. This method is generally used in
+ `DistributedSampler`, because the seed should be identical across all
+ processes in the distributed group.
+
+ In distributed sampling, different ranks should sample non-overlapped
+ data in the dataset. Therefore, this function is used to make sure that
+ each rank shuffles the data indices in the same order based
+ on the same seed. Then different ranks could use different indices
+ to select non-overlapped data from the same data list.
+
+ Args:
+ seed (int, Optional): The seed. Default to None.
+ device (str): The device where the seed will be put on.
+ Default to 'cuda'.
+ Returns:
+ int: Seed to be used.
+ """
+
+ if seed is None:
+ seed = np.random.randint(2**31)
+ assert isinstance(seed, int)
+
+ rank, world_size = get_dist_info()
+
+ if world_size == 1:
+ return seed
+
+ if rank == 0:
+ random_num = torch.tensor(seed, dtype=torch.int32, device=device)
+ else:
+ random_num = torch.tensor(0, dtype=torch.int32, device=device)
+ dist.broadcast(random_num, src=0)
+ return random_num.item()
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/core/utils/misc.py b/EgoHOS/raw/script/mmsegmentation/mmseg/core/utils/misc.py
new file mode 100644
index 0000000000000000000000000000000000000000..282bb8d9698ebd19876d849f1e3fc2ee23e2d40d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/core/utils/misc.py
@@ -0,0 +1,18 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+def add_prefix(inputs, prefix):
+ """Add prefix for dict.
+
+ Args:
+ inputs (dict): The input dict with str keys.
+ prefix (str): The prefix to add.
+
+ Returns:
+
+ dict: The dict with keys updated with ``prefix``.
+ """
+
+ outputs = dict()
+ for name, value in inputs.items():
+ outputs[f'{prefix}.{name}'] = value
+
+ return outputs
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..7c2a5076f8dfc7886318018ac9a126a3c0dcb1ee
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/__init__.py
@@ -0,0 +1,31 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .ade import ADE20KDataset
+from .builder import DATASETS, PIPELINES, build_dataloader, build_dataset
+from .chase_db1 import ChaseDB1Dataset
+from .cityscapes import CityscapesDataset
+from .coco_stuff import COCOStuffDataset
+from .custom import CustomDataset
+from .dark_zurich import DarkZurichDataset
+from .dataset_wrappers import (ConcatDataset, MultiImageMixDataset,
+ RepeatDataset)
+from .drive import DRIVEDataset
+from .hrf import HRFDataset
+from .isaid import iSAIDDataset
+from .isprs import ISPRSDataset
+from .loveda import LoveDADataset
+from .night_driving import NightDrivingDataset
+from .pascal_context import PascalContextDataset, PascalContextDataset59
+from .potsdam import PotsdamDataset
+from .stare import STAREDataset
+from .voc import PascalVOCDataset
+from .egohos import EgoHOSDataset
+
+__all__ = [
+ 'CustomDataset', 'build_dataloader', 'ConcatDataset', 'RepeatDataset',
+ 'DATASETS', 'build_dataset', 'PIPELINES', 'CityscapesDataset',
+ 'PascalVOCDataset', 'ADE20KDataset', 'PascalContextDataset',
+ 'PascalContextDataset59', 'ChaseDB1Dataset', 'DRIVEDataset', 'HRFDataset',
+ 'STAREDataset', 'DarkZurichDataset', 'NightDrivingDataset',
+ 'COCOStuffDataset', 'LoveDADataset', 'MultiImageMixDataset',
+ 'iSAIDDataset', 'ISPRSDataset', 'PotsdamDataset', 'EgoHOSDataset'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/ade.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/ade.py
new file mode 100644
index 0000000000000000000000000000000000000000..db94cebd3bbaed1dfee0f9a80f5a164a862de84f
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/ade.py
@@ -0,0 +1,167 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import os.path as osp
+
+import mmcv
+import numpy as np
+from PIL import Image
+
+from .builder import DATASETS
+from .custom import CustomDataset
+
+
+@DATASETS.register_module()
+class ADE20KDataset(CustomDataset):
+ """ADE20K dataset.
+
+ In segmentation map annotation for ADE20K, 0 stands for background, which
+ is not included in 150 categories. ``reduce_zero_label`` is fixed to True.
+ The ``img_suffix`` is fixed to '.jpg' and ``seg_map_suffix`` is fixed to
+ '.png'.
+ """
+ CLASSES = (
+ 'wall', 'building', 'sky', 'floor', 'tree', 'ceiling', 'road', 'bed ',
+ 'windowpane', 'grass', 'cabinet', 'sidewalk', 'person', 'earth',
+ 'door', 'table', 'mountain', 'plant', 'curtain', 'chair', 'car',
+ 'water', 'painting', 'sofa', 'shelf', 'house', 'sea', 'mirror', 'rug',
+ 'field', 'armchair', 'seat', 'fence', 'desk', 'rock', 'wardrobe',
+ 'lamp', 'bathtub', 'railing', 'cushion', 'base', 'box', 'column',
+ 'signboard', 'chest of drawers', 'counter', 'sand', 'sink',
+ 'skyscraper', 'fireplace', 'refrigerator', 'grandstand', 'path',
+ 'stairs', 'runway', 'case', 'pool table', 'pillow', 'screen door',
+ 'stairway', 'river', 'bridge', 'bookcase', 'blind', 'coffee table',
+ 'toilet', 'flower', 'book', 'hill', 'bench', 'countertop', 'stove',
+ 'palm', 'kitchen island', 'computer', 'swivel chair', 'boat', 'bar',
+ 'arcade machine', 'hovel', 'bus', 'towel', 'light', 'truck', 'tower',
+ 'chandelier', 'awning', 'streetlight', 'booth', 'television receiver',
+ 'airplane', 'dirt track', 'apparel', 'pole', 'land', 'bannister',
+ 'escalator', 'ottoman', 'bottle', 'buffet', 'poster', 'stage', 'van',
+ 'ship', 'fountain', 'conveyer belt', 'canopy', 'washer', 'plaything',
+ 'swimming pool', 'stool', 'barrel', 'basket', 'waterfall', 'tent',
+ 'bag', 'minibike', 'cradle', 'oven', 'ball', 'food', 'step', 'tank',
+ 'trade name', 'microwave', 'pot', 'animal', 'bicycle', 'lake',
+ 'dishwasher', 'screen', 'blanket', 'sculpture', 'hood', 'sconce',
+ 'vase', 'traffic light', 'tray', 'ashcan', 'fan', 'pier', 'crt screen',
+ 'plate', 'monitor', 'bulletin board', 'shower', 'radiator', 'glass',
+ 'clock', 'flag')
+
+ PALETTE = [[120, 120, 120], [180, 120, 120], [6, 230, 230], [80, 50, 50],
+ [4, 200, 3], [120, 120, 80], [140, 140, 140], [204, 5, 255],
+ [230, 230, 230], [4, 250, 7], [224, 5, 255], [235, 255, 7],
+ [150, 5, 61], [120, 120, 70], [8, 255, 51], [255, 6, 82],
+ [143, 255, 140], [204, 255, 4], [255, 51, 7], [204, 70, 3],
+ [0, 102, 200], [61, 230, 250], [255, 6, 51], [11, 102, 255],
+ [255, 7, 71], [255, 9, 224], [9, 7, 230], [220, 220, 220],
+ [255, 9, 92], [112, 9, 255], [8, 255, 214], [7, 255, 224],
+ [255, 184, 6], [10, 255, 71], [255, 41, 10], [7, 255, 255],
+ [224, 255, 8], [102, 8, 255], [255, 61, 6], [255, 194, 7],
+ [255, 122, 8], [0, 255, 20], [255, 8, 41], [255, 5, 153],
+ [6, 51, 255], [235, 12, 255], [160, 150, 20], [0, 163, 255],
+ [140, 140, 140], [250, 10, 15], [20, 255, 0], [31, 255, 0],
+ [255, 31, 0], [255, 224, 0], [153, 255, 0], [0, 0, 255],
+ [255, 71, 0], [0, 235, 255], [0, 173, 255], [31, 0, 255],
+ [11, 200, 200], [255, 82, 0], [0, 255, 245], [0, 61, 255],
+ [0, 255, 112], [0, 255, 133], [255, 0, 0], [255, 163, 0],
+ [255, 102, 0], [194, 255, 0], [0, 143, 255], [51, 255, 0],
+ [0, 82, 255], [0, 255, 41], [0, 255, 173], [10, 0, 255],
+ [173, 255, 0], [0, 255, 153], [255, 92, 0], [255, 0, 255],
+ [255, 0, 245], [255, 0, 102], [255, 173, 0], [255, 0, 20],
+ [255, 184, 184], [0, 31, 255], [0, 255, 61], [0, 71, 255],
+ [255, 0, 204], [0, 255, 194], [0, 255, 82], [0, 10, 255],
+ [0, 112, 255], [51, 0, 255], [0, 194, 255], [0, 122, 255],
+ [0, 255, 163], [255, 153, 0], [0, 255, 10], [255, 112, 0],
+ [143, 255, 0], [82, 0, 255], [163, 255, 0], [255, 235, 0],
+ [8, 184, 170], [133, 0, 255], [0, 255, 92], [184, 0, 255],
+ [255, 0, 31], [0, 184, 255], [0, 214, 255], [255, 0, 112],
+ [92, 255, 0], [0, 224, 255], [112, 224, 255], [70, 184, 160],
+ [163, 0, 255], [153, 0, 255], [71, 255, 0], [255, 0, 163],
+ [255, 204, 0], [255, 0, 143], [0, 255, 235], [133, 255, 0],
+ [255, 0, 235], [245, 0, 255], [255, 0, 122], [255, 245, 0],
+ [10, 190, 212], [214, 255, 0], [0, 204, 255], [20, 0, 255],
+ [255, 255, 0], [0, 153, 255], [0, 41, 255], [0, 255, 204],
+ [41, 0, 255], [41, 255, 0], [173, 0, 255], [0, 245, 255],
+ [71, 0, 255], [122, 0, 255], [0, 255, 184], [0, 92, 255],
+ [184, 255, 0], [0, 133, 255], [255, 214, 0], [25, 194, 194],
+ [102, 255, 0], [92, 0, 255]]
+
+ def __init__(self, **kwargs):
+ super(ADE20KDataset, self).__init__(
+ img_suffix='.jpg',
+ seg_map_suffix='.png',
+ reduce_zero_label=True,
+ **kwargs)
+
+ def results2img(self, results, imgfile_prefix, to_label_id, indices=None):
+ """Write the segmentation results to images.
+
+ Args:
+ results (list[ndarray]): Testing results of the
+ dataset.
+ imgfile_prefix (str): The filename prefix of the png files.
+ If the prefix is "somepath/xxx",
+ the png files will be named "somepath/xxx.png".
+ to_label_id (bool): whether convert output to label_id for
+ submission.
+ indices (list[int], optional): Indices of input results, if not
+ set, all the indices of the dataset will be used.
+ Default: None.
+
+ Returns:
+ list[str: str]: result txt files which contains corresponding
+ semantic segmentation images.
+ """
+ if indices is None:
+ indices = list(range(len(self)))
+
+ mmcv.mkdir_or_exist(imgfile_prefix)
+ result_files = []
+ for result, idx in zip(results, indices):
+
+ filename = self.img_infos[idx]['filename']
+ basename = osp.splitext(osp.basename(filename))[0]
+
+ png_filename = osp.join(imgfile_prefix, f'{basename}.png')
+
+ # The index range of official requirement is from 0 to 150.
+ # But the index range of output is from 0 to 149.
+ # That is because we set reduce_zero_label=True.
+ result = result + 1
+
+ output = Image.fromarray(result.astype(np.uint8))
+ output.save(png_filename)
+ result_files.append(png_filename)
+
+ return result_files
+
+ def format_results(self,
+ results,
+ imgfile_prefix,
+ to_label_id=True,
+ indices=None):
+ """Format the results into dir (standard format for ade20k evaluation).
+
+ Args:
+ results (list): Testing results of the dataset.
+ imgfile_prefix (str | None): The prefix of images files. It
+ includes the file path and the prefix of filename, e.g.,
+ "a/b/prefix".
+ to_label_id (bool): whether convert output to label_id for
+ submission. Default: False
+ indices (list[int], optional): Indices of input results, if not
+ set, all the indices of the dataset will be used.
+ Default: None.
+
+ Returns:
+ tuple: (result_files, tmp_dir), result_files is a list containing
+ the image paths, tmp_dir is the temporal directory created
+ for saving json/png files when img_prefix is not specified.
+ """
+
+ if indices is None:
+ indices = list(range(len(self)))
+
+ assert isinstance(results, list), 'results must be a list.'
+ assert isinstance(indices, list), 'indices must be a list.'
+
+ result_files = self.results2img(results, imgfile_prefix, to_label_id,
+ indices)
+ return result_files
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/builder.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/builder.py
new file mode 100644
index 0000000000000000000000000000000000000000..4d852d3653ca4df4fbe2495c096775e6a42c7ac6
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/builder.py
@@ -0,0 +1,191 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import copy
+import platform
+import random
+from functools import partial
+
+import numpy as np
+import torch
+from mmcv.parallel import collate
+from mmcv.runner import get_dist_info
+from mmcv.utils import Registry, build_from_cfg, digit_version
+from torch.utils.data import DataLoader
+
+from .samplers import DistributedSampler
+
+if platform.system() != 'Windows':
+ # https://github.com/pytorch/pytorch/issues/973
+ import resource
+ rlimit = resource.getrlimit(resource.RLIMIT_NOFILE)
+ base_soft_limit = rlimit[0]
+ hard_limit = rlimit[1]
+ soft_limit = min(max(4096, base_soft_limit), hard_limit)
+ resource.setrlimit(resource.RLIMIT_NOFILE, (soft_limit, hard_limit))
+
+DATASETS = Registry('dataset')
+PIPELINES = Registry('pipeline')
+
+
+def _concat_dataset(cfg, default_args=None):
+ """Build :obj:`ConcatDataset by."""
+ from .dataset_wrappers import ConcatDataset
+ img_dir = cfg['img_dir']
+ ann_dir = cfg.get('ann_dir', None)
+ split = cfg.get('split', None)
+ # pop 'separate_eval' since it is not a valid key for common datasets.
+ separate_eval = cfg.pop('separate_eval', True)
+ num_img_dir = len(img_dir) if isinstance(img_dir, (list, tuple)) else 1
+ if ann_dir is not None:
+ num_ann_dir = len(ann_dir) if isinstance(ann_dir, (list, tuple)) else 1
+ else:
+ num_ann_dir = 0
+ if split is not None:
+ num_split = len(split) if isinstance(split, (list, tuple)) else 1
+ else:
+ num_split = 0
+ if num_img_dir > 1:
+ assert num_img_dir == num_ann_dir or num_ann_dir == 0
+ assert num_img_dir == num_split or num_split == 0
+ else:
+ assert num_split == num_ann_dir or num_ann_dir <= 1
+ num_dset = max(num_split, num_img_dir)
+
+ datasets = []
+ for i in range(num_dset):
+ data_cfg = copy.deepcopy(cfg)
+ if isinstance(img_dir, (list, tuple)):
+ data_cfg['img_dir'] = img_dir[i]
+ if isinstance(ann_dir, (list, tuple)):
+ data_cfg['ann_dir'] = ann_dir[i]
+ if isinstance(split, (list, tuple)):
+ data_cfg['split'] = split[i]
+ datasets.append(build_dataset(data_cfg, default_args))
+
+ return ConcatDataset(datasets, separate_eval)
+
+
+def build_dataset(cfg, default_args=None):
+ """Build datasets."""
+ from .dataset_wrappers import (ConcatDataset, MultiImageMixDataset,
+ RepeatDataset)
+ if isinstance(cfg, (list, tuple)):
+ dataset = ConcatDataset([build_dataset(c, default_args) for c in cfg])
+ elif cfg['type'] == 'RepeatDataset':
+ dataset = RepeatDataset(
+ build_dataset(cfg['dataset'], default_args), cfg['times'])
+ elif cfg['type'] == 'MultiImageMixDataset':
+ cp_cfg = copy.deepcopy(cfg)
+ cp_cfg['dataset'] = build_dataset(cp_cfg['dataset'])
+ cp_cfg.pop('type')
+ dataset = MultiImageMixDataset(**cp_cfg)
+ elif isinstance(cfg.get('img_dir'), (list, tuple)) or isinstance(
+ cfg.get('split', None), (list, tuple)):
+ dataset = _concat_dataset(cfg, default_args)
+ else:
+ dataset = build_from_cfg(cfg, DATASETS, default_args)
+
+ return dataset
+
+
+def build_dataloader(dataset,
+ samples_per_gpu,
+ workers_per_gpu,
+ num_gpus=1,
+ dist=True,
+ shuffle=True,
+ seed=None,
+ drop_last=False,
+ pin_memory=True,
+ persistent_workers=True,
+ **kwargs):
+ """Build PyTorch DataLoader.
+
+ In distributed training, each GPU/process has a dataloader.
+ In non-distributed training, there is only one dataloader for all GPUs.
+
+ Args:
+ dataset (Dataset): A PyTorch dataset.
+ samples_per_gpu (int): Number of training samples on each GPU, i.e.,
+ batch size of each GPU.
+ workers_per_gpu (int): How many subprocesses to use for data loading
+ for each GPU.
+ num_gpus (int): Number of GPUs. Only used in non-distributed training.
+ dist (bool): Distributed training/test or not. Default: True.
+ shuffle (bool): Whether to shuffle the data at every epoch.
+ Default: True.
+ seed (int | None): Seed to be used. Default: None.
+ drop_last (bool): Whether to drop the last incomplete batch in epoch.
+ Default: False
+ pin_memory (bool): Whether to use pin_memory in DataLoader.
+ Default: True
+ persistent_workers (bool): If True, the data loader will not shutdown
+ the worker processes after a dataset has been consumed once.
+ This allows to maintain the workers Dataset instances alive.
+ The argument also has effect in PyTorch>=1.7.0.
+ Default: True
+ kwargs: any keyword argument to be used to initialize DataLoader
+
+ Returns:
+ DataLoader: A PyTorch dataloader.
+ """
+ rank, world_size = get_dist_info()
+ if dist:
+ sampler = DistributedSampler(
+ dataset, world_size, rank, shuffle=shuffle, seed=seed)
+ shuffle = False
+ batch_size = samples_per_gpu
+ num_workers = workers_per_gpu
+ else:
+ sampler = None
+ batch_size = num_gpus * samples_per_gpu
+ num_workers = num_gpus * workers_per_gpu
+
+ init_fn = partial(
+ worker_init_fn, num_workers=num_workers, rank=rank,
+ seed=seed) if seed is not None else None
+
+ if digit_version(torch.__version__) >= digit_version('1.8.0'):
+ data_loader = DataLoader(
+ dataset,
+ batch_size=batch_size,
+ sampler=sampler,
+ num_workers=num_workers,
+ collate_fn=partial(collate, samples_per_gpu=samples_per_gpu),
+ pin_memory=pin_memory,
+ shuffle=shuffle,
+ worker_init_fn=init_fn,
+ drop_last=drop_last,
+ persistent_workers=persistent_workers,
+ **kwargs)
+ else:
+ data_loader = DataLoader(
+ dataset,
+ batch_size=batch_size,
+ sampler=sampler,
+ num_workers=num_workers,
+ collate_fn=partial(collate, samples_per_gpu=samples_per_gpu),
+ pin_memory=pin_memory,
+ shuffle=shuffle,
+ worker_init_fn=init_fn,
+ drop_last=drop_last,
+ **kwargs)
+
+ return data_loader
+
+
+def worker_init_fn(worker_id, num_workers, rank, seed):
+ """Worker init func for dataloader.
+
+ The seed of each worker equals to num_worker * rank + worker_id + user_seed
+
+ Args:
+ worker_id (int): Worker id.
+ num_workers (int): Number of workers.
+ rank (int): The rank of current process.
+ seed (int): The random seed to use.
+ """
+
+ worker_seed = num_workers * rank + worker_id + seed
+ np.random.seed(worker_seed)
+ random.seed(worker_seed)
+ torch.manual_seed(worker_seed)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/chase_db1.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/chase_db1.py
new file mode 100644
index 0000000000000000000000000000000000000000..5cdc8d8d41c6869876fb13d83c1de0d51d4c6e7c
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/chase_db1.py
@@ -0,0 +1,27 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+
+from .builder import DATASETS
+from .custom import CustomDataset
+
+
+@DATASETS.register_module()
+class ChaseDB1Dataset(CustomDataset):
+ """Chase_db1 dataset.
+
+ In segmentation map annotation for Chase_db1, 0 stands for background,
+ which is included in 2 categories. ``reduce_zero_label`` is fixed to False.
+ The ``img_suffix`` is fixed to '.png' and ``seg_map_suffix`` is fixed to
+ '_1stHO.png'.
+ """
+
+ CLASSES = ('background', 'vessel')
+
+ PALETTE = [[120, 120, 120], [6, 230, 230]]
+
+ def __init__(self, **kwargs):
+ super(ChaseDB1Dataset, self).__init__(
+ img_suffix='.png',
+ seg_map_suffix='_1stHO.png',
+ reduce_zero_label=False,
+ **kwargs)
+ assert self.file_client.exists(self.img_dir)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/cityscapes.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/cityscapes.py
new file mode 100644
index 0000000000000000000000000000000000000000..ed633d00db33789541284df0d2ec3187d4dd01a3
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/cityscapes.py
@@ -0,0 +1,214 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import os.path as osp
+
+import mmcv
+import numpy as np
+from mmcv.utils import print_log
+from PIL import Image
+
+from .builder import DATASETS
+from .custom import CustomDataset
+
+
+@DATASETS.register_module()
+class CityscapesDataset(CustomDataset):
+ """Cityscapes dataset.
+
+ The ``img_suffix`` is fixed to '_leftImg8bit.png' and ``seg_map_suffix`` is
+ fixed to '_gtFine_labelTrainIds.png' for Cityscapes dataset.
+ """
+
+ CLASSES = ('road', 'sidewalk', 'building', 'wall', 'fence', 'pole',
+ 'traffic light', 'traffic sign', 'vegetation', 'terrain', 'sky',
+ 'person', 'rider', 'car', 'truck', 'bus', 'train', 'motorcycle',
+ 'bicycle')
+
+ PALETTE = [[128, 64, 128], [244, 35, 232], [70, 70, 70], [102, 102, 156],
+ [190, 153, 153], [153, 153, 153], [250, 170, 30], [220, 220, 0],
+ [107, 142, 35], [152, 251, 152], [70, 130, 180], [220, 20, 60],
+ [255, 0, 0], [0, 0, 142], [0, 0, 70], [0, 60, 100],
+ [0, 80, 100], [0, 0, 230], [119, 11, 32]]
+
+ def __init__(self,
+ img_suffix='_leftImg8bit.png',
+ seg_map_suffix='_gtFine_labelTrainIds.png',
+ **kwargs):
+ super(CityscapesDataset, self).__init__(
+ img_suffix=img_suffix, seg_map_suffix=seg_map_suffix, **kwargs)
+
+ @staticmethod
+ def _convert_to_label_id(result):
+ """Convert trainId to id for cityscapes."""
+ if isinstance(result, str):
+ result = np.load(result)
+ import cityscapesscripts.helpers.labels as CSLabels
+ result_copy = result.copy()
+ for trainId, label in CSLabels.trainId2label.items():
+ result_copy[result == trainId] = label.id
+
+ return result_copy
+
+ def results2img(self, results, imgfile_prefix, to_label_id, indices=None):
+ """Write the segmentation results to images.
+
+ Args:
+ results (list[ndarray]): Testing results of the
+ dataset.
+ imgfile_prefix (str): The filename prefix of the png files.
+ If the prefix is "somepath/xxx",
+ the png files will be named "somepath/xxx.png".
+ to_label_id (bool): whether convert output to label_id for
+ submission.
+ indices (list[int], optional): Indices of input results,
+ if not set, all the indices of the dataset will be used.
+ Default: None.
+
+ Returns:
+ list[str: str]: result txt files which contains corresponding
+ semantic segmentation images.
+ """
+ if indices is None:
+ indices = list(range(len(self)))
+
+ mmcv.mkdir_or_exist(imgfile_prefix)
+ result_files = []
+ for result, idx in zip(results, indices):
+ if to_label_id:
+ result = self._convert_to_label_id(result)
+ filename = self.img_infos[idx]['filename']
+ basename = osp.splitext(osp.basename(filename))[0]
+
+ png_filename = osp.join(imgfile_prefix, f'{basename}.png')
+
+ output = Image.fromarray(result.astype(np.uint8)).convert('P')
+ import cityscapesscripts.helpers.labels as CSLabels
+ palette = np.zeros((len(CSLabels.id2label), 3), dtype=np.uint8)
+ for label_id, label in CSLabels.id2label.items():
+ palette[label_id] = label.color
+
+ output.putpalette(palette)
+ output.save(png_filename)
+ result_files.append(png_filename)
+
+ return result_files
+
+ def format_results(self,
+ results,
+ imgfile_prefix,
+ to_label_id=True,
+ indices=None):
+ """Format the results into dir (standard format for Cityscapes
+ evaluation).
+
+ Args:
+ results (list): Testing results of the dataset.
+ imgfile_prefix (str): The prefix of images files. It
+ includes the file path and the prefix of filename, e.g.,
+ "a/b/prefix".
+ to_label_id (bool): whether convert output to label_id for
+ submission. Default: False
+ indices (list[int], optional): Indices of input results,
+ if not set, all the indices of the dataset will be used.
+ Default: None.
+
+ Returns:
+ tuple: (result_files, tmp_dir), result_files is a list containing
+ the image paths, tmp_dir is the temporal directory created
+ for saving json/png files when img_prefix is not specified.
+ """
+ if indices is None:
+ indices = list(range(len(self)))
+
+ assert isinstance(results, list), 'results must be a list.'
+ assert isinstance(indices, list), 'indices must be a list.'
+
+ result_files = self.results2img(results, imgfile_prefix, to_label_id,
+ indices)
+
+ return result_files
+
+ def evaluate(self,
+ results,
+ metric='mIoU',
+ logger=None,
+ imgfile_prefix=None):
+ """Evaluation in Cityscapes/default protocol.
+
+ Args:
+ results (list): Testing results of the dataset.
+ metric (str | list[str]): Metrics to be evaluated.
+ logger (logging.Logger | None | str): Logger used for printing
+ related information during evaluation. Default: None.
+ imgfile_prefix (str | None): The prefix of output image file,
+ for cityscapes evaluation only. It includes the file path and
+ the prefix of filename, e.g., "a/b/prefix".
+ If results are evaluated with cityscapes protocol, it would be
+ the prefix of output png files. The output files would be
+ png images under folder "a/b/prefix/xxx.png", where "xxx" is
+ the image name of cityscapes. If not specified, a temp file
+ will be created for evaluation.
+ Default: None.
+
+ Returns:
+ dict[str, float]: Cityscapes/default metrics.
+ """
+
+ eval_results = dict()
+ metrics = metric.copy() if isinstance(metric, list) else [metric]
+ if 'cityscapes' in metrics:
+ eval_results.update(
+ self._evaluate_cityscapes(results, logger, imgfile_prefix))
+ metrics.remove('cityscapes')
+ if len(metrics) > 0:
+ eval_results.update(
+ super(CityscapesDataset,
+ self).evaluate(results, metrics, logger))
+
+ return eval_results
+
+ def _evaluate_cityscapes(self, results, logger, imgfile_prefix):
+ """Evaluation in Cityscapes protocol.
+
+ Args:
+ results (list): Testing results of the dataset.
+ logger (logging.Logger | str | None): Logger used for printing
+ related information during evaluation. Default: None.
+ imgfile_prefix (str | None): The prefix of output image file
+
+ Returns:
+ dict[str: float]: Cityscapes evaluation results.
+ """
+ try:
+ import cityscapesscripts.evaluation.evalPixelLevelSemanticLabeling as CSEval # noqa
+ except ImportError:
+ raise ImportError('Please run "pip install cityscapesscripts" to '
+ 'install cityscapesscripts first.')
+ msg = 'Evaluating in Cityscapes style'
+ if logger is None:
+ msg = '\n' + msg
+ print_log(msg, logger=logger)
+
+ result_dir = imgfile_prefix
+
+ eval_results = dict()
+ print_log(f'Evaluating results under {result_dir} ...', logger=logger)
+
+ CSEval.args.evalInstLevelScore = True
+ CSEval.args.predictionPath = osp.abspath(result_dir)
+ CSEval.args.evalPixelAccuracy = True
+ CSEval.args.JSONOutput = False
+
+ seg_map_list = []
+ pred_list = []
+
+ # when evaluating with official cityscapesscripts,
+ # **_gtFine_labelIds.png is used
+ for seg_map in mmcv.scandir(
+ self.ann_dir, 'gtFine_labelIds.png', recursive=True):
+ seg_map_list.append(osp.join(self.ann_dir, seg_map))
+ pred_list.append(CSEval.getPrediction(CSEval.args, seg_map))
+
+ eval_results.update(
+ CSEval.evaluateImgLists(pred_list, seg_map_list, CSEval.args))
+
+ return eval_results
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/coco_stuff.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/coco_stuff.py
new file mode 100644
index 0000000000000000000000000000000000000000..24d089556599a5696c50fd0115077fbc83413061
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/coco_stuff.py
@@ -0,0 +1,94 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .builder import DATASETS
+from .custom import CustomDataset
+
+
+@DATASETS.register_module()
+class COCOStuffDataset(CustomDataset):
+ """COCO-Stuff dataset.
+
+ In segmentation map annotation for COCO-Stuff, Train-IDs of the 10k version
+ are from 1 to 171, where 0 is the ignore index, and Train-ID of COCO Stuff
+ 164k is from 0 to 170, where 255 is the ignore index. So, they are all 171
+ semantic categories. ``reduce_zero_label`` is set to True and False for the
+ 10k and 164k versions, respectively. The ``img_suffix`` is fixed to '.jpg',
+ and ``seg_map_suffix`` is fixed to '.png'.
+ """
+ CLASSES = (
+ 'person', 'bicycle', 'car', 'motorcycle', 'airplane', 'bus', 'train',
+ 'truck', 'boat', 'traffic light', 'fire hydrant', 'stop sign',
+ 'parking meter', 'bench', 'bird', 'cat', 'dog', 'horse', 'sheep',
+ 'cow', 'elephant', 'bear', 'zebra', 'giraffe', 'backpack', 'umbrella',
+ 'handbag', 'tie', 'suitcase', 'frisbee', 'skis', 'snowboard',
+ 'sports ball', 'kite', 'baseball bat', 'baseball glove', 'skateboard',
+ 'surfboard', 'tennis racket', 'bottle', 'wine glass', 'cup', 'fork',
+ 'knife', 'spoon', 'bowl', 'banana', 'apple', 'sandwich', 'orange',
+ 'broccoli', 'carrot', 'hot dog', 'pizza', 'donut', 'cake', 'chair',
+ 'couch', 'potted plant', 'bed', 'dining table', 'toilet', 'tv',
+ 'laptop', 'mouse', 'remote', 'keyboard', 'cell phone', 'microwave',
+ 'oven', 'toaster', 'sink', 'refrigerator', 'book', 'clock', 'vase',
+ 'scissors', 'teddy bear', 'hair drier', 'toothbrush', 'banner',
+ 'blanket', 'branch', 'bridge', 'building-other', 'bush', 'cabinet',
+ 'cage', 'cardboard', 'carpet', 'ceiling-other', 'ceiling-tile',
+ 'cloth', 'clothes', 'clouds', 'counter', 'cupboard', 'curtain',
+ 'desk-stuff', 'dirt', 'door-stuff', 'fence', 'floor-marble',
+ 'floor-other', 'floor-stone', 'floor-tile', 'floor-wood',
+ 'flower', 'fog', 'food-other', 'fruit', 'furniture-other', 'grass',
+ 'gravel', 'ground-other', 'hill', 'house', 'leaves', 'light', 'mat',
+ 'metal', 'mirror-stuff', 'moss', 'mountain', 'mud', 'napkin', 'net',
+ 'paper', 'pavement', 'pillow', 'plant-other', 'plastic', 'platform',
+ 'playingfield', 'railing', 'railroad', 'river', 'road', 'rock', 'roof',
+ 'rug', 'salad', 'sand', 'sea', 'shelf', 'sky-other', 'skyscraper',
+ 'snow', 'solid-other', 'stairs', 'stone', 'straw', 'structural-other',
+ 'table', 'tent', 'textile-other', 'towel', 'tree', 'vegetable',
+ 'wall-brick', 'wall-concrete', 'wall-other', 'wall-panel',
+ 'wall-stone', 'wall-tile', 'wall-wood', 'water-other', 'waterdrops',
+ 'window-blind', 'window-other', 'wood')
+
+ PALETTE = [[0, 192, 64], [0, 192, 64], [0, 64, 96], [128, 192, 192],
+ [0, 64, 64], [0, 192, 224], [0, 192, 192], [128, 192, 64],
+ [0, 192, 96], [128, 192, 64], [128, 32, 192], [0, 0, 224],
+ [0, 0, 64], [0, 160, 192], [128, 0, 96], [128, 0, 192],
+ [0, 32, 192], [128, 128, 224], [0, 0, 192], [128, 160, 192],
+ [128, 128, 0], [128, 0, 32], [128, 32, 0], [128, 0, 128],
+ [64, 128, 32], [0, 160, 0], [0, 0, 0], [192, 128, 160],
+ [0, 32, 0], [0, 128, 128], [64, 128, 160], [128, 160, 0],
+ [0, 128, 0], [192, 128, 32], [128, 96, 128], [0, 0, 128],
+ [64, 0, 32], [0, 224, 128], [128, 0, 0], [192, 0, 160],
+ [0, 96, 128], [128, 128, 128], [64, 0, 160], [128, 224, 128],
+ [128, 128, 64], [192, 0, 32], [128, 96, 0], [128, 0, 192],
+ [0, 128, 32], [64, 224, 0], [0, 0, 64], [128, 128, 160],
+ [64, 96, 0], [0, 128, 192], [0, 128, 160], [192, 224, 0],
+ [0, 128, 64], [128, 128, 32], [192, 32, 128], [0, 64, 192],
+ [0, 0, 32], [64, 160, 128], [128, 64, 64], [128, 0, 160],
+ [64, 32, 128], [128, 192, 192], [0, 0, 160], [192, 160, 128],
+ [128, 192, 0], [128, 0, 96], [192, 32, 0], [128, 64, 128],
+ [64, 128, 96], [64, 160, 0], [0, 64, 0], [192, 128, 224],
+ [64, 32, 0], [0, 192, 128], [64, 128, 224], [192, 160, 0],
+ [0, 192, 0], [192, 128, 96], [192, 96, 128], [0, 64, 128],
+ [64, 0, 96], [64, 224, 128], [128, 64, 0], [192, 0, 224],
+ [64, 96, 128], [128, 192, 128], [64, 0, 224], [192, 224, 128],
+ [128, 192, 64], [192, 0, 96], [192, 96, 0], [128, 64, 192],
+ [0, 128, 96], [0, 224, 0], [64, 64, 64], [128, 128, 224],
+ [0, 96, 0], [64, 192, 192], [0, 128, 224], [128, 224, 0],
+ [64, 192, 64], [128, 128, 96], [128, 32, 128], [64, 0, 192],
+ [0, 64, 96], [0, 160, 128], [192, 0, 64], [128, 64, 224],
+ [0, 32, 128], [192, 128, 192], [0, 64, 224], [128, 160, 128],
+ [192, 128, 0], [128, 64, 32], [128, 32, 64], [192, 0, 128],
+ [64, 192, 32], [0, 160, 64], [64, 0, 0], [192, 192, 160],
+ [0, 32, 64], [64, 128, 128], [64, 192, 160], [128, 160, 64],
+ [64, 128, 0], [192, 192, 32], [128, 96, 192], [64, 0, 128],
+ [64, 64, 32], [0, 224, 192], [192, 0, 0], [192, 64, 160],
+ [0, 96, 192], [192, 128, 128], [64, 64, 160], [128, 224, 192],
+ [192, 128, 64], [192, 64, 32], [128, 96, 64], [192, 0, 192],
+ [0, 192, 32], [64, 224, 64], [64, 0, 64], [128, 192, 160],
+ [64, 96, 64], [64, 128, 192], [0, 192, 160], [192, 224, 64],
+ [64, 128, 64], [128, 192, 32], [192, 32, 192], [64, 64, 192],
+ [0, 64, 32], [64, 160, 192], [192, 64, 64], [128, 64, 160],
+ [64, 32, 192], [192, 192, 192], [0, 64, 160], [192, 160, 192],
+ [192, 192, 0], [128, 64, 96], [192, 32, 64], [192, 64, 128],
+ [64, 192, 96], [64, 160, 64], [64, 64, 0]]
+
+ def __init__(self, **kwargs):
+ super(COCOStuffDataset, self).__init__(
+ img_suffix='.jpg', seg_map_suffix='_labelTrainIds.png', **kwargs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/custom.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/custom.py
new file mode 100644
index 0000000000000000000000000000000000000000..4615d4114ec0a1ff8a2771999ef8c08fd95c9743
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/custom.py
@@ -0,0 +1,487 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import os.path as osp
+import warnings
+from collections import OrderedDict
+
+import mmcv
+import numpy as np
+from mmcv.utils import print_log
+from prettytable import PrettyTable
+from torch.utils.data import Dataset
+
+from mmseg.core import eval_metrics, intersect_and_union, pre_eval_to_metrics
+from mmseg.utils import get_root_logger
+from .builder import DATASETS
+from .pipelines import Compose, LoadAnnotations
+
+
+@DATASETS.register_module()
+class CustomDataset(Dataset):
+ """Custom dataset for semantic segmentation. An example of file structure
+ is as followed.
+
+ .. code-block:: none
+
+ ├── data
+ │ ├── my_dataset
+ │ │ ├── img_dir
+ │ │ │ ├── train
+ │ │ │ │ ├── xxx{img_suffix}
+ │ │ │ │ ├── yyy{img_suffix}
+ │ │ │ │ ├── zzz{img_suffix}
+ │ │ │ ├── val
+ │ │ ├── ann_dir
+ │ │ │ ├── train
+ │ │ │ │ ├── xxx{seg_map_suffix}
+ │ │ │ │ ├── yyy{seg_map_suffix}
+ │ │ │ │ ├── zzz{seg_map_suffix}
+ │ │ │ ├── val
+
+ The img/gt_semantic_seg pair of CustomDataset should be of the same
+ except suffix. A valid img/gt_semantic_seg filename pair should be like
+ ``xxx{img_suffix}`` and ``xxx{seg_map_suffix}`` (extension is also included
+ in the suffix). If split is given, then ``xxx`` is specified in txt file.
+ Otherwise, all files in ``img_dir/``and ``ann_dir`` will be loaded.
+ Please refer to ``docs/en/tutorials/new_dataset.md`` for more details.
+
+
+ Args:
+ pipeline (list[dict]): Processing pipeline
+ img_dir (str): Path to image directory
+ img_suffix (str): Suffix of images. Default: '.jpg'
+ ann_dir (str, optional): Path to annotation directory. Default: None
+ seg_map_suffix (str): Suffix of segmentation maps. Default: '.png'
+ split (str, optional): Split txt file. If split is specified, only
+ file with suffix in the splits will be loaded. Otherwise, all
+ images in img_dir/ann_dir will be loaded. Default: None
+ data_root (str, optional): Data root for img_dir/ann_dir. Default:
+ None.
+ test_mode (bool): If test_mode=True, gt wouldn't be loaded.
+ ignore_index (int): The label index to be ignored. Default: 255
+ reduce_zero_label (bool): Whether to mark label zero as ignored.
+ Default: False
+ classes (str | Sequence[str], optional): Specify classes to load.
+ If is None, ``cls.CLASSES`` will be used. Default: None.
+ palette (Sequence[Sequence[int]]] | np.ndarray | None):
+ The palette of segmentation map. If None is given, and
+ self.PALETTE is None, random palette will be generated.
+ Default: None
+ gt_seg_map_loader_cfg (dict, optional): build LoadAnnotations to
+ load gt for evaluation, load from disk by default. Default: None.
+ file_client_args (dict): Arguments to instantiate a FileClient.
+ See :class:`mmcv.fileio.FileClient` for details.
+ Defaults to ``dict(backend='disk')``.
+ """
+
+ CLASSES = None
+
+ PALETTE = None
+
+ def __init__(self,
+ pipeline,
+ img_dir,
+ img_suffix='.jpg',
+ ann_dir=None,
+ seg_map_suffix='.png',
+ split=None,
+ data_root=None,
+ test_mode=False,
+ ignore_index=255,
+ reduce_zero_label=False,
+ classes=None,
+ palette=None,
+ gt_seg_map_loader_cfg=None,
+ file_client_args=dict(backend='disk')):
+ self.pipeline = Compose(pipeline)
+ self.img_dir = img_dir
+ self.img_suffix = img_suffix
+ self.ann_dir = ann_dir
+ self.seg_map_suffix = seg_map_suffix
+ self.split = split
+ self.data_root = data_root
+ self.test_mode = test_mode
+ self.ignore_index = ignore_index
+ self.reduce_zero_label = reduce_zero_label
+ self.label_map = None
+ self.CLASSES, self.PALETTE = self.get_classes_and_palette(
+ classes, palette)
+ self.gt_seg_map_loader = LoadAnnotations(
+ ) if gt_seg_map_loader_cfg is None else LoadAnnotations(
+ **gt_seg_map_loader_cfg)
+
+ self.file_client_args = file_client_args
+ self.file_client = mmcv.FileClient.infer_client(self.file_client_args)
+
+ if test_mode:
+ assert self.CLASSES is not None, \
+ '`cls.CLASSES` or `classes` should be specified when testing'
+
+ # join paths if data_root is specified
+ if self.data_root is not None:
+ if not osp.isabs(self.img_dir):
+ self.img_dir = osp.join(self.data_root, self.img_dir)
+ if not (self.ann_dir is None or osp.isabs(self.ann_dir)):
+ self.ann_dir = osp.join(self.data_root, self.ann_dir)
+ if not (self.split is None or osp.isabs(self.split)):
+ self.split = osp.join(self.data_root, self.split)
+
+ # load annotations
+ self.img_infos = self.load_annotations(self.img_dir, self.img_suffix,
+ self.ann_dir,
+ self.seg_map_suffix, self.split)
+
+ def __len__(self):
+ """Total number of samples of data."""
+ return len(self.img_infos)
+
+ def load_annotations(self, img_dir, img_suffix, ann_dir, seg_map_suffix,
+ split):
+ """Load annotation from directory.
+
+ Args:
+ img_dir (str): Path to image directory
+ img_suffix (str): Suffix of images.
+ ann_dir (str|None): Path to annotation directory.
+ seg_map_suffix (str|None): Suffix of segmentation maps.
+ split (str|None): Split txt file. If split is specified, only file
+ with suffix in the splits will be loaded. Otherwise, all images
+ in img_dir/ann_dir will be loaded. Default: None
+
+ Returns:
+ list[dict]: All image info of dataset.
+ """
+
+ img_infos = []
+ if split is not None:
+ lines = mmcv.list_from_file(
+ split, file_client_args=self.file_client_args)
+ for line in lines:
+ img_name = line.strip()
+ img_info = dict(filename=img_name + img_suffix)
+ if ann_dir is not None:
+ seg_map = img_name + seg_map_suffix
+ img_info['ann'] = dict(seg_map=seg_map)
+ img_infos.append(img_info)
+ else:
+ for img in self.file_client.list_dir_or_file(
+ dir_path=img_dir,
+ list_dir=False,
+ suffix=img_suffix,
+ recursive=True):
+ img_info = dict(filename=img)
+ if ann_dir is not None:
+ seg_map = img.replace(img_suffix, seg_map_suffix)
+ img_info['ann'] = dict(seg_map=seg_map)
+ img_infos.append(img_info)
+ img_infos = sorted(img_infos, key=lambda x: x['filename'])
+
+ print_log(f'Loaded {len(img_infos)} images', logger=get_root_logger())
+ return img_infos
+
+ def get_ann_info(self, idx):
+ """Get annotation by index.
+
+ Args:
+ idx (int): Index of data.
+
+ Returns:
+ dict: Annotation info of specified index.
+ """
+
+ return self.img_infos[idx]['ann']
+
+ def pre_pipeline(self, results):
+ """Prepare results dict for pipeline."""
+ results['seg_fields'] = []
+ results['img_prefix'] = self.img_dir
+ results['seg_prefix'] = self.ann_dir
+ if self.custom_classes:
+ results['label_map'] = self.label_map
+
+ def __getitem__(self, idx):
+ """Get training/test data after pipeline.
+
+ Args:
+ idx (int): Index of data.
+
+ Returns:
+ dict: Training/test data (with annotation if `test_mode` is set
+ False).
+ """
+
+ if self.test_mode:
+ return self.prepare_test_img(idx)
+ else:
+ return self.prepare_train_img(idx)
+
+ def prepare_train_img(self, idx):
+ """Get training data and annotations after pipeline.
+
+ Args:
+ idx (int): Index of data.
+
+ Returns:
+ dict: Training data and annotation after pipeline with new keys
+ introduced by pipeline.
+ """
+
+ img_info = self.img_infos[idx]
+ ann_info = self.get_ann_info(idx)
+ results = dict(img_info=img_info, ann_info=ann_info)
+ self.pre_pipeline(results)
+ return self.pipeline(results)
+
+ def prepare_test_img(self, idx):
+ """Get testing data after pipeline.
+
+ Args:
+ idx (int): Index of data.
+
+ Returns:
+ dict: Testing data after pipeline with new keys introduced by
+ pipeline.
+ """
+
+ img_info = self.img_infos[idx]
+ results = dict(img_info=img_info)
+ self.pre_pipeline(results)
+ return self.pipeline(results)
+
+ def format_results(self, results, imgfile_prefix, indices=None, **kwargs):
+ """Place holder to format result to dataset specific output."""
+ raise NotImplementedError
+
+ def get_gt_seg_map_by_idx(self, index):
+ """Get one ground truth segmentation map for evaluation."""
+ ann_info = self.get_ann_info(index)
+ results = dict(ann_info=ann_info)
+ self.pre_pipeline(results)
+ self.gt_seg_map_loader(results)
+ return results['gt_semantic_seg']
+
+ def get_gt_seg_maps(self, efficient_test=None):
+ """Get ground truth segmentation maps for evaluation."""
+ if efficient_test is not None:
+ warnings.warn(
+ 'DeprecationWarning: ``efficient_test`` has been deprecated '
+ 'since MMSeg v0.16, the ``get_gt_seg_maps()`` is CPU memory '
+ 'friendly by default. ')
+
+ for idx in range(len(self)):
+ ann_info = self.get_ann_info(idx)
+ results = dict(ann_info=ann_info)
+ self.pre_pipeline(results)
+ self.gt_seg_map_loader(results)
+ yield results['gt_semantic_seg']
+
+ def pre_eval(self, preds, indices):
+ """Collect eval result from each iteration.
+
+ Args:
+ preds (list[torch.Tensor] | torch.Tensor): the segmentation logit
+ after argmax, shape (N, H, W).
+ indices (list[int] | int): the prediction related ground truth
+ indices.
+
+ Returns:
+ list[torch.Tensor]: (area_intersect, area_union, area_prediction,
+ area_ground_truth).
+ """
+ # In order to compat with batch inference
+ if not isinstance(indices, list):
+ indices = [indices]
+ if not isinstance(preds, list):
+ preds = [preds]
+
+ pre_eval_results = []
+
+ for pred, index in zip(preds, indices):
+ seg_map = self.get_gt_seg_map_by_idx(index)
+ pre_eval_results.append(
+ intersect_and_union(
+ pred,
+ seg_map,
+ len(self.CLASSES),
+ self.ignore_index,
+ # as the labels has been converted when dataset initialized
+ # in `get_palette_for_custom_classes ` this `label_map`
+ # should be `dict()`, see
+ # https://github.com/open-mmlab/mmsegmentation/issues/1415
+ # for more ditails
+ label_map=dict(),
+ reduce_zero_label=self.reduce_zero_label))
+
+ return pre_eval_results
+
+ def get_classes_and_palette(self, classes=None, palette=None):
+ """Get class names of current dataset.
+
+ Args:
+ classes (Sequence[str] | str | None): If classes is None, use
+ default CLASSES defined by builtin dataset. If classes is a
+ string, take it as a file name. The file contains the name of
+ classes where each line contains one class name. If classes is
+ a tuple or list, override the CLASSES defined by the dataset.
+ palette (Sequence[Sequence[int]]] | np.ndarray | None):
+ The palette of segmentation map. If None is given, random
+ palette will be generated. Default: None
+ """
+ if classes is None:
+ self.custom_classes = False
+ return self.CLASSES, self.PALETTE
+
+ self.custom_classes = True
+ if isinstance(classes, str):
+ # take it as a file path
+ class_names = mmcv.list_from_file(classes)
+ elif isinstance(classes, (tuple, list)):
+ class_names = classes
+ else:
+ raise ValueError(f'Unsupported type {type(classes)} of classes.')
+
+ if self.CLASSES:
+ if not set(class_names).issubset(self.CLASSES):
+ raise ValueError('classes is not a subset of CLASSES.')
+
+ # dictionary, its keys are the old label ids and its values
+ # are the new label ids.
+ # used for changing pixel labels in load_annotations.
+ self.label_map = {}
+ for i, c in enumerate(self.CLASSES):
+ if c not in class_names:
+ self.label_map[i] = -1
+ else:
+ self.label_map[i] = class_names.index(c)
+
+ palette = self.get_palette_for_custom_classes(class_names, palette)
+
+ return class_names, palette
+
+ def get_palette_for_custom_classes(self, class_names, palette=None):
+
+ if self.label_map is not None:
+ # return subset of palette
+ palette = []
+ for old_id, new_id in sorted(
+ self.label_map.items(), key=lambda x: x[1]):
+ if new_id != -1:
+ palette.append(self.PALETTE[old_id])
+ palette = type(self.PALETTE)(palette)
+
+ elif palette is None:
+ if self.PALETTE is None:
+ # Get random state before set seed, and restore
+ # random state later.
+ # It will prevent loss of randomness, as the palette
+ # may be different in each iteration if not specified.
+ # See: https://github.com/open-mmlab/mmdetection/issues/5844
+ state = np.random.get_state()
+ np.random.seed(42)
+ # random palette
+ palette = np.random.randint(0, 255, size=(len(class_names), 3))
+ np.random.set_state(state)
+ else:
+ palette = self.PALETTE
+
+ return palette
+
+ def evaluate(self,
+ results,
+ metric='mIoU',
+ logger=None,
+ gt_seg_maps=None,
+ **kwargs):
+ """Evaluate the dataset.
+
+ Args:
+ results (list[tuple[torch.Tensor]] | list[str]): per image pre_eval
+ results or predict segmentation map for computing evaluation
+ metric.
+ metric (str | list[str]): Metrics to be evaluated. 'mIoU',
+ 'mDice' and 'mFscore' are supported.
+ logger (logging.Logger | None | str): Logger used for printing
+ related information during evaluation. Default: None.
+ gt_seg_maps (generator[ndarray]): Custom gt seg maps as input,
+ used in ConcatDataset
+
+ Returns:
+ dict[str, float]: Default metrics.
+ """
+ if isinstance(metric, str):
+ metric = [metric]
+ allowed_metrics = ['mIoU', 'mDice', 'mFscore']
+ if not set(metric).issubset(set(allowed_metrics)):
+ raise KeyError('metric {} is not supported'.format(metric))
+
+ eval_results = {}
+ # test a list of files
+ if mmcv.is_list_of(results, np.ndarray) or mmcv.is_list_of(
+ results, str):
+ if gt_seg_maps is None:
+ gt_seg_maps = self.get_gt_seg_maps()
+ num_classes = len(self.CLASSES)
+ ret_metrics = eval_metrics(
+ results,
+ gt_seg_maps,
+ num_classes,
+ self.ignore_index,
+ metric,
+ label_map=dict(),
+ reduce_zero_label=self.reduce_zero_label)
+ # test a list of pre_eval_results
+ else:
+ ret_metrics = pre_eval_to_metrics(results, metric)
+
+ # Because dataset.CLASSES is required for per-eval.
+ if self.CLASSES is None:
+ class_names = tuple(range(num_classes))
+ else:
+ class_names = self.CLASSES
+
+ # summary table
+ ret_metrics_summary = OrderedDict({
+ ret_metric: np.round(np.nanmean(ret_metric_value) * 100, 2)
+ for ret_metric, ret_metric_value in ret_metrics.items()
+ })
+
+ # each class table
+ ret_metrics.pop('aAcc', None)
+ ret_metrics_class = OrderedDict({
+ ret_metric: np.round(ret_metric_value * 100, 2)
+ for ret_metric, ret_metric_value in ret_metrics.items()
+ })
+ ret_metrics_class.update({'Class': class_names})
+ ret_metrics_class.move_to_end('Class', last=False)
+
+ # for logger
+ class_table_data = PrettyTable()
+ for key, val in ret_metrics_class.items():
+ class_table_data.add_column(key, val)
+
+ summary_table_data = PrettyTable()
+ for key, val in ret_metrics_summary.items():
+ if key == 'aAcc':
+ summary_table_data.add_column(key, [val])
+ else:
+ summary_table_data.add_column('m' + key, [val])
+
+ print_log('per class results:', logger)
+ print_log('\n' + class_table_data.get_string(), logger=logger)
+ print_log('Summary:', logger)
+ print_log('\n' + summary_table_data.get_string(), logger=logger)
+
+ # each metric dict
+ for key, value in ret_metrics_summary.items():
+ if key == 'aAcc':
+ eval_results[key] = value / 100.0
+ else:
+ eval_results['m' + key] = value / 100.0
+
+ ret_metrics_class.pop('Class', None)
+ for key, value in ret_metrics_class.items():
+ eval_results.update({
+ key + '.' + str(name): value[idx] / 100.0
+ for idx, name in enumerate(class_names)
+ })
+
+ return eval_results
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/dark_zurich.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/dark_zurich.py
new file mode 100644
index 0000000000000000000000000000000000000000..0b6fda6e9e27d9ccb1b6fb2e22aa4340e635a4da
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/dark_zurich.py
@@ -0,0 +1,14 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .builder import DATASETS
+from .cityscapes import CityscapesDataset
+
+
+@DATASETS.register_module()
+class DarkZurichDataset(CityscapesDataset):
+ """DarkZurichDataset dataset."""
+
+ def __init__(self, **kwargs):
+ super().__init__(
+ img_suffix='_rgb_anon.png',
+ seg_map_suffix='_gt_labelTrainIds.png',
+ **kwargs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/dataset_wrappers.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/dataset_wrappers.py
new file mode 100644
index 0000000000000000000000000000000000000000..1fb089f9f287f841d0a99f67ab840f28175c87ec
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/dataset_wrappers.py
@@ -0,0 +1,277 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import bisect
+import collections
+import copy
+from itertools import chain
+
+import mmcv
+import numpy as np
+from mmcv.utils import build_from_cfg, print_log
+from torch.utils.data.dataset import ConcatDataset as _ConcatDataset
+
+from .builder import DATASETS, PIPELINES
+from .cityscapes import CityscapesDataset
+
+
+@DATASETS.register_module()
+class ConcatDataset(_ConcatDataset):
+ """A wrapper of concatenated dataset.
+
+ Same as :obj:`torch.utils.data.dataset.ConcatDataset`, but
+ support evaluation and formatting results
+
+ Args:
+ datasets (list[:obj:`Dataset`]): A list of datasets.
+ separate_eval (bool): Whether to evaluate the concatenated
+ dataset results separately, Defaults to True.
+ """
+
+ def __init__(self, datasets, separate_eval=True):
+ super(ConcatDataset, self).__init__(datasets)
+ self.CLASSES = datasets[0].CLASSES
+ self.PALETTE = datasets[0].PALETTE
+ self.separate_eval = separate_eval
+ assert separate_eval in [True, False], \
+ f'separate_eval can only be True or False,' \
+ f'but get {separate_eval}'
+ if any([isinstance(ds, CityscapesDataset) for ds in datasets]):
+ raise NotImplementedError(
+ 'Evaluating ConcatDataset containing CityscapesDataset'
+ 'is not supported!')
+
+ def evaluate(self, results, logger=None, **kwargs):
+ """Evaluate the results.
+
+ Args:
+ results (list[tuple[torch.Tensor]] | list[str]]): per image
+ pre_eval results or predict segmentation map for
+ computing evaluation metric.
+ logger (logging.Logger | str | None): Logger used for printing
+ related information during evaluation. Default: None.
+
+ Returns:
+ dict[str: float]: evaluate results of the total dataset
+ or each separate
+ dataset if `self.separate_eval=True`.
+ """
+ assert len(results) == self.cumulative_sizes[-1], \
+ ('Dataset and results have different sizes: '
+ f'{self.cumulative_sizes[-1]} v.s. {len(results)}')
+
+ # Check whether all the datasets support evaluation
+ for dataset in self.datasets:
+ assert hasattr(dataset, 'evaluate'), \
+ f'{type(dataset)} does not implement evaluate function'
+
+ if self.separate_eval:
+ dataset_idx = -1
+ total_eval_results = dict()
+ for size, dataset in zip(self.cumulative_sizes, self.datasets):
+ start_idx = 0 if dataset_idx == -1 else \
+ self.cumulative_sizes[dataset_idx]
+ end_idx = self.cumulative_sizes[dataset_idx + 1]
+
+ results_per_dataset = results[start_idx:end_idx]
+ print_log(
+ f'\nEvaluateing {dataset.img_dir} with '
+ f'{len(results_per_dataset)} images now',
+ logger=logger)
+
+ eval_results_per_dataset = dataset.evaluate(
+ results_per_dataset, logger=logger, **kwargs)
+ dataset_idx += 1
+ for k, v in eval_results_per_dataset.items():
+ total_eval_results.update({f'{dataset_idx}_{k}': v})
+
+ return total_eval_results
+
+ if len(set([type(ds) for ds in self.datasets])) != 1:
+ raise NotImplementedError(
+ 'All the datasets should have same types when '
+ 'self.separate_eval=False')
+ else:
+ if mmcv.is_list_of(results, np.ndarray) or mmcv.is_list_of(
+ results, str):
+ # merge the generators of gt_seg_maps
+ gt_seg_maps = chain(
+ *[dataset.get_gt_seg_maps() for dataset in self.datasets])
+ else:
+ # if the results are `pre_eval` results,
+ # we do not need gt_seg_maps to evaluate
+ gt_seg_maps = None
+ eval_results = self.datasets[0].evaluate(
+ results, gt_seg_maps=gt_seg_maps, logger=logger, **kwargs)
+ return eval_results
+
+ def get_dataset_idx_and_sample_idx(self, indice):
+ """Return dataset and sample index when given an indice of
+ ConcatDataset.
+
+ Args:
+ indice (int): indice of sample in ConcatDataset
+
+ Returns:
+ int: the index of sub dataset the sample belong to
+ int: the index of sample in its corresponding subset
+ """
+ if indice < 0:
+ if -indice > len(self):
+ raise ValueError(
+ 'absolute value of index should not exceed dataset length')
+ indice = len(self) + indice
+ dataset_idx = bisect.bisect_right(self.cumulative_sizes, indice)
+ if dataset_idx == 0:
+ sample_idx = indice
+ else:
+ sample_idx = indice - self.cumulative_sizes[dataset_idx - 1]
+ return dataset_idx, sample_idx
+
+ def format_results(self, results, imgfile_prefix, indices=None, **kwargs):
+ """format result for every sample of ConcatDataset."""
+ if indices is None:
+ indices = list(range(len(self)))
+
+ assert isinstance(results, list), 'results must be a list.'
+ assert isinstance(indices, list), 'indices must be a list.'
+
+ ret_res = []
+ for i, indice in enumerate(indices):
+ dataset_idx, sample_idx = self.get_dataset_idx_and_sample_idx(
+ indice)
+ res = self.datasets[dataset_idx].format_results(
+ [results[i]],
+ imgfile_prefix + f'/{dataset_idx}',
+ indices=[sample_idx],
+ **kwargs)
+ ret_res.append(res)
+ return sum(ret_res, [])
+
+ def pre_eval(self, preds, indices):
+ """do pre eval for every sample of ConcatDataset."""
+ # In order to compat with batch inference
+ if not isinstance(indices, list):
+ indices = [indices]
+ if not isinstance(preds, list):
+ preds = [preds]
+ ret_res = []
+ for i, indice in enumerate(indices):
+ dataset_idx, sample_idx = self.get_dataset_idx_and_sample_idx(
+ indice)
+ res = self.datasets[dataset_idx].pre_eval(preds[i], sample_idx)
+ ret_res.append(res)
+ return sum(ret_res, [])
+
+
+@DATASETS.register_module()
+class RepeatDataset(object):
+ """A wrapper of repeated dataset.
+
+ The length of repeated dataset will be `times` larger than the original
+ dataset. This is useful when the data loading time is long but the dataset
+ is small. Using RepeatDataset can reduce the data loading time between
+ epochs.
+
+ Args:
+ dataset (:obj:`Dataset`): The dataset to be repeated.
+ times (int): Repeat times.
+ """
+
+ def __init__(self, dataset, times):
+ self.dataset = dataset
+ self.times = times
+ self.CLASSES = dataset.CLASSES
+ self.PALETTE = dataset.PALETTE
+ self._ori_len = len(self.dataset)
+
+ def __getitem__(self, idx):
+ """Get item from original dataset."""
+ return self.dataset[idx % self._ori_len]
+
+ def __len__(self):
+ """The length is multiplied by ``times``"""
+ return self.times * self._ori_len
+
+
+@DATASETS.register_module()
+class MultiImageMixDataset:
+ """A wrapper of multiple images mixed dataset.
+
+ Suitable for training on multiple images mixed data augmentation like
+ mosaic and mixup. For the augmentation pipeline of mixed image data,
+ the `get_indexes` method needs to be provided to obtain the image
+ indexes, and you can set `skip_flags` to change the pipeline running
+ process.
+
+
+ Args:
+ dataset (:obj:`CustomDataset`): The dataset to be mixed.
+ pipeline (Sequence[dict]): Sequence of transform object or
+ config dict to be composed.
+ skip_type_keys (list[str], optional): Sequence of type string to
+ be skip pipeline. Default to None.
+ """
+
+ def __init__(self, dataset, pipeline, skip_type_keys=None):
+ assert isinstance(pipeline, collections.abc.Sequence)
+ if skip_type_keys is not None:
+ assert all([
+ isinstance(skip_type_key, str)
+ for skip_type_key in skip_type_keys
+ ])
+ self._skip_type_keys = skip_type_keys
+
+ self.pipeline = []
+ self.pipeline_types = []
+ for transform in pipeline:
+ if isinstance(transform, dict):
+ self.pipeline_types.append(transform['type'])
+ transform = build_from_cfg(transform, PIPELINES)
+ self.pipeline.append(transform)
+ else:
+ raise TypeError('pipeline must be a dict')
+
+ self.dataset = dataset
+ self.CLASSES = dataset.CLASSES
+ self.PALETTE = dataset.PALETTE
+ self.num_samples = len(dataset)
+
+ def __len__(self):
+ return self.num_samples
+
+ def __getitem__(self, idx):
+ results = copy.deepcopy(self.dataset[idx])
+ for (transform, transform_type) in zip(self.pipeline,
+ self.pipeline_types):
+ if self._skip_type_keys is not None and \
+ transform_type in self._skip_type_keys:
+ continue
+
+ if hasattr(transform, 'get_indexes'):
+ indexes = transform.get_indexes(self.dataset)
+ if not isinstance(indexes, collections.abc.Sequence):
+ indexes = [indexes]
+ mix_results = [
+ copy.deepcopy(self.dataset[index]) for index in indexes
+ ]
+ results['mix_results'] = mix_results
+
+ results = transform(results)
+
+ if 'mix_results' in results:
+ results.pop('mix_results')
+
+ return results
+
+ def update_skip_type_keys(self, skip_type_keys):
+ """Update skip_type_keys.
+
+ It is called by an external hook.
+
+ Args:
+ skip_type_keys (list[str], optional): Sequence of type
+ string to be skip pipeline.
+ """
+ assert all([
+ isinstance(skip_type_key, str) for skip_type_key in skip_type_keys
+ ])
+ self._skip_type_keys = skip_type_keys
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/drive.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/drive.py
new file mode 100644
index 0000000000000000000000000000000000000000..d44fb0da7123eeed7a8e0b932d12e41305a33f22
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/drive.py
@@ -0,0 +1,27 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+
+from .builder import DATASETS
+from .custom import CustomDataset
+
+
+@DATASETS.register_module()
+class DRIVEDataset(CustomDataset):
+ """DRIVE dataset.
+
+ In segmentation map annotation for DRIVE, 0 stands for background, which is
+ included in 2 categories. ``reduce_zero_label`` is fixed to False. The
+ ``img_suffix`` is fixed to '.png' and ``seg_map_suffix`` is fixed to
+ '_manual1.png'.
+ """
+
+ CLASSES = ('background', 'vessel')
+
+ PALETTE = [[120, 120, 120], [6, 230, 230]]
+
+ def __init__(self, **kwargs):
+ super(DRIVEDataset, self).__init__(
+ img_suffix='.png',
+ seg_map_suffix='_manual1.png',
+ reduce_zero_label=False,
+ **kwargs)
+ assert self.file_client.exists(self.img_dir)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/egohos.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/egohos.py
new file mode 100644
index 0000000000000000000000000000000000000000..4f59f829cf596b410d75a3f815c78ad89457b7bd
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/egohos.py
@@ -0,0 +1,34 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import os.path as osp
+
+from .builder import DATASETS
+from .custom import CustomDataset
+
+
+@DATASETS.register_module()
+class EgoHOSDataset(CustomDataset):
+ """EgoHOS dataset.
+
+ Args:
+ split (str): Split txt file for EgoHOS.
+ """
+
+ # CLASSES = ('background', 'aeroplane')
+
+ # PALETTE = [[0, 0, 0], [128, 0, 0], [0, 128, 0], [128, 128, 0], [0, 0, 128],
+ # [128, 0, 128]]
+
+ CLASSES = ('background', 'Left_Hand', 'Right_Hand', \
+ 'Left_Object1', 'Right_Object1', 'Two_Object1', \
+ 'Left_Object2', 'Right_Object2', 'Two_Object2')
+
+ PALETTE = [[0, 0, 0], [255, 0, 0], [0, 0, 255], \
+ [255, 0, 255], [0, 255, 255], [0, 255, 0], \
+ [255, 204, 255], [204, 255, 255], [204, 255, 204]]
+
+ def __init__(self, **kwargs):
+ super(EgoHOSDataset, self).__init__(
+ img_suffix='.jpg', seg_map_suffix='.png', **kwargs)
+
+
+
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/hrf.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/hrf.py
new file mode 100644
index 0000000000000000000000000000000000000000..cf3ea8d79c2a62dd4e9a2e84af35ec4ea1879091
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/hrf.py
@@ -0,0 +1,27 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+
+from .builder import DATASETS
+from .custom import CustomDataset
+
+
+@DATASETS.register_module()
+class HRFDataset(CustomDataset):
+ """HRF dataset.
+
+ In segmentation map annotation for HRF, 0 stands for background, which is
+ included in 2 categories. ``reduce_zero_label`` is fixed to False. The
+ ``img_suffix`` is fixed to '.png' and ``seg_map_suffix`` is fixed to
+ '.png'.
+ """
+
+ CLASSES = ('background', 'vessel')
+
+ PALETTE = [[120, 120, 120], [6, 230, 230]]
+
+ def __init__(self, **kwargs):
+ super(HRFDataset, self).__init__(
+ img_suffix='.png',
+ seg_map_suffix='.png',
+ reduce_zero_label=False,
+ **kwargs)
+ assert self.file_client.exists(self.img_dir)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/isaid.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/isaid.py
new file mode 100644
index 0000000000000000000000000000000000000000..db24f937650634066b69eb2288c506faf6479078
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/isaid.py
@@ -0,0 +1,82 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+
+import mmcv
+from mmcv.utils import print_log
+
+from ..utils import get_root_logger
+from .builder import DATASETS
+from .custom import CustomDataset
+
+
+@DATASETS.register_module()
+class iSAIDDataset(CustomDataset):
+ """ iSAID: A Large-scale Dataset for Instance Segmentation in Aerial Images
+ In segmentation map annotation for iSAID dataset, which is included
+ in 16 categories. ``reduce_zero_label`` is fixed to False. The
+ ``img_suffix`` is fixed to '.png' and ``seg_map_suffix`` is fixed to
+ '_manual1.png'.
+ """
+
+ CLASSES = ('background', 'ship', 'store_tank', 'baseball_diamond',
+ 'tennis_court', 'basketball_court', 'Ground_Track_Field',
+ 'Bridge', 'Large_Vehicle', 'Small_Vehicle', 'Helicopter',
+ 'Swimming_pool', 'Roundabout', 'Soccer_ball_field', 'plane',
+ 'Harbor')
+
+ PALETTE = [[0, 0, 0], [0, 0, 63], [0, 63, 63], [0, 63, 0], [0, 63, 127],
+ [0, 63, 191], [0, 63, 255], [0, 127, 63], [0, 127, 127],
+ [0, 0, 127], [0, 0, 191], [0, 0, 255], [0, 191, 127],
+ [0, 127, 191], [0, 127, 255], [0, 100, 155]]
+
+ def __init__(self, **kwargs):
+ super(iSAIDDataset, self).__init__(
+ img_suffix='.png',
+ seg_map_suffix='.png',
+ ignore_index=255,
+ **kwargs)
+ assert self.file_client.exists(self.img_dir)
+
+ def load_annotations(self,
+ img_dir,
+ img_suffix,
+ ann_dir,
+ seg_map_suffix=None,
+ split=None):
+ """Load annotation from directory.
+
+ Args:
+ img_dir (str): Path to image directory
+ img_suffix (str): Suffix of images.
+ ann_dir (str|None): Path to annotation directory.
+ seg_map_suffix (str|None): Suffix of segmentation maps.
+ split (str|None): Split txt file. If split is specified, only file
+ with suffix in the splits will be loaded. Otherwise, all images
+ in img_dir/ann_dir will be loaded. Default: None
+
+ Returns:
+ list[dict]: All image info of dataset.
+ """
+
+ img_infos = []
+ if split is not None:
+ with open(split) as f:
+ for line in f:
+ name = line.strip()
+ img_info = dict(filename=name + img_suffix)
+ if ann_dir is not None:
+ ann_name = name + '_instance_color_RGB'
+ seg_map = ann_name + seg_map_suffix
+ img_info['ann'] = dict(seg_map=seg_map)
+ img_infos.append(img_info)
+ else:
+ for img in mmcv.scandir(img_dir, img_suffix, recursive=True):
+ img_info = dict(filename=img)
+ if ann_dir is not None:
+ seg_img = img
+ seg_map = seg_img.replace(
+ img_suffix, '_instance_color_RGB' + seg_map_suffix)
+ img_info['ann'] = dict(seg_map=seg_map)
+ img_infos.append(img_info)
+
+ print_log(f'Loaded {len(img_infos)} images', logger=get_root_logger())
+ return img_infos
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/isprs.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/isprs.py
new file mode 100644
index 0000000000000000000000000000000000000000..5f23e1a9b61942361ed0811052700f85e5d0a1a0
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/isprs.py
@@ -0,0 +1,25 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .builder import DATASETS
+from .custom import CustomDataset
+
+
+@DATASETS.register_module()
+class ISPRSDataset(CustomDataset):
+ """ISPRS dataset.
+
+ In segmentation map annotation for LoveDA, 0 is the ignore index.
+ ``reduce_zero_label`` should be set to True. The ``img_suffix`` and
+ ``seg_map_suffix`` are both fixed to '.png'.
+ """
+ CLASSES = ('impervious_surface', 'building', 'low_vegetation', 'tree',
+ 'car', 'clutter')
+
+ PALETTE = [[255, 255, 255], [0, 0, 255], [0, 255, 255], [0, 255, 0],
+ [255, 255, 0], [255, 0, 0]]
+
+ def __init__(self, **kwargs):
+ super(ISPRSDataset, self).__init__(
+ img_suffix='.png',
+ seg_map_suffix='.png',
+ reduce_zero_label=True,
+ **kwargs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/loveda.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/loveda.py
new file mode 100644
index 0000000000000000000000000000000000000000..90d654f625a0e5ea381c0fdb1ebb4cc6c921498f
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/loveda.py
@@ -0,0 +1,92 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import os.path as osp
+
+import mmcv
+import numpy as np
+from PIL import Image
+
+from .builder import DATASETS
+from .custom import CustomDataset
+
+
+@DATASETS.register_module()
+class LoveDADataset(CustomDataset):
+ """LoveDA dataset.
+
+ In segmentation map annotation for LoveDA, 0 is the ignore index.
+ ``reduce_zero_label`` should be set to True. The ``img_suffix`` and
+ ``seg_map_suffix`` are both fixed to '.png'.
+ """
+ CLASSES = ('background', 'building', 'road', 'water', 'barren', 'forest',
+ 'agricultural')
+
+ PALETTE = [[255, 255, 255], [255, 0, 0], [255, 255, 0], [0, 0, 255],
+ [159, 129, 183], [0, 255, 0], [255, 195, 128]]
+
+ def __init__(self, **kwargs):
+ super(LoveDADataset, self).__init__(
+ img_suffix='.png',
+ seg_map_suffix='.png',
+ reduce_zero_label=True,
+ **kwargs)
+
+ def results2img(self, results, imgfile_prefix, indices=None):
+ """Write the segmentation results to images.
+
+ Args:
+ results (list[ndarray]): Testing results of the
+ dataset.
+ imgfile_prefix (str): The filename prefix of the png files.
+ If the prefix is "somepath/xxx",
+ the png files will be named "somepath/xxx.png".
+ indices (list[int], optional): Indices of input results, if not
+ set, all the indices of the dataset will be used.
+ Default: None.
+
+ Returns:
+ list[str: str]: result txt files which contains corresponding
+ semantic segmentation images.
+ """
+
+ mmcv.mkdir_or_exist(imgfile_prefix)
+ result_files = []
+ for result, idx in zip(results, indices):
+
+ filename = self.img_infos[idx]['filename']
+ basename = osp.splitext(osp.basename(filename))[0]
+
+ png_filename = osp.join(imgfile_prefix, f'{basename}.png')
+
+ # The index range of official requirement is from 0 to 6.
+ output = Image.fromarray(result.astype(np.uint8))
+ output.save(png_filename)
+ result_files.append(png_filename)
+
+ return result_files
+
+ def format_results(self, results, imgfile_prefix, indices=None):
+ """Format the results into dir (standard format for LoveDA evaluation).
+
+ Args:
+ results (list): Testing results of the dataset.
+ imgfile_prefix (str): The prefix of images files. It
+ includes the file path and the prefix of filename, e.g.,
+ "a/b/prefix".
+ indices (list[int], optional): Indices of input results,
+ if not set, all the indices of the dataset will be used.
+ Default: None.
+
+ Returns:
+ tuple: (result_files, tmp_dir), result_files is a list containing
+ the image paths, tmp_dir is the temporal directory created
+ for saving json/png files when img_prefix is not specified.
+ """
+ if indices is None:
+ indices = list(range(len(self)))
+
+ assert isinstance(results, list), 'results must be a list.'
+ assert isinstance(indices, list), 'indices must be a list.'
+
+ result_files = self.results2img(results, imgfile_prefix, indices)
+
+ return result_files
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/night_driving.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/night_driving.py
new file mode 100644
index 0000000000000000000000000000000000000000..6620586e3f11f56690982568c7761dfa7b3dbf50
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/night_driving.py
@@ -0,0 +1,14 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .builder import DATASETS
+from .cityscapes import CityscapesDataset
+
+
+@DATASETS.register_module()
+class NightDrivingDataset(CityscapesDataset):
+ """NightDrivingDataset dataset."""
+
+ def __init__(self, **kwargs):
+ super().__init__(
+ img_suffix='_leftImg8bit.png',
+ seg_map_suffix='_gtCoarse_labelTrainIds.png',
+ **kwargs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pascal_context.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pascal_context.py
new file mode 100644
index 0000000000000000000000000000000000000000..efacee0f3fb856f10c6d589346316342a1f20c5e
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pascal_context.py
@@ -0,0 +1,103 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+
+from .builder import DATASETS
+from .custom import CustomDataset
+
+
+@DATASETS.register_module()
+class PascalContextDataset(CustomDataset):
+ """PascalContext dataset.
+
+ In segmentation map annotation for PascalContext, 0 stands for background,
+ which is included in 60 categories. ``reduce_zero_label`` is fixed to
+ False. The ``img_suffix`` is fixed to '.jpg' and ``seg_map_suffix`` is
+ fixed to '.png'.
+
+ Args:
+ split (str): Split txt file for PascalContext.
+ """
+
+ CLASSES = ('background', 'aeroplane', 'bag', 'bed', 'bedclothes', 'bench',
+ 'bicycle', 'bird', 'boat', 'book', 'bottle', 'building', 'bus',
+ 'cabinet', 'car', 'cat', 'ceiling', 'chair', 'cloth',
+ 'computer', 'cow', 'cup', 'curtain', 'dog', 'door', 'fence',
+ 'floor', 'flower', 'food', 'grass', 'ground', 'horse',
+ 'keyboard', 'light', 'motorbike', 'mountain', 'mouse', 'person',
+ 'plate', 'platform', 'pottedplant', 'road', 'rock', 'sheep',
+ 'shelves', 'sidewalk', 'sign', 'sky', 'snow', 'sofa', 'table',
+ 'track', 'train', 'tree', 'truck', 'tvmonitor', 'wall', 'water',
+ 'window', 'wood')
+
+ PALETTE = [[120, 120, 120], [180, 120, 120], [6, 230, 230], [80, 50, 50],
+ [4, 200, 3], [120, 120, 80], [140, 140, 140], [204, 5, 255],
+ [230, 230, 230], [4, 250, 7], [224, 5, 255], [235, 255, 7],
+ [150, 5, 61], [120, 120, 70], [8, 255, 51], [255, 6, 82],
+ [143, 255, 140], [204, 255, 4], [255, 51, 7], [204, 70, 3],
+ [0, 102, 200], [61, 230, 250], [255, 6, 51], [11, 102, 255],
+ [255, 7, 71], [255, 9, 224], [9, 7, 230], [220, 220, 220],
+ [255, 9, 92], [112, 9, 255], [8, 255, 214], [7, 255, 224],
+ [255, 184, 6], [10, 255, 71], [255, 41, 10], [7, 255, 255],
+ [224, 255, 8], [102, 8, 255], [255, 61, 6], [255, 194, 7],
+ [255, 122, 8], [0, 255, 20], [255, 8, 41], [255, 5, 153],
+ [6, 51, 255], [235, 12, 255], [160, 150, 20], [0, 163, 255],
+ [140, 140, 140], [250, 10, 15], [20, 255, 0], [31, 255, 0],
+ [255, 31, 0], [255, 224, 0], [153, 255, 0], [0, 0, 255],
+ [255, 71, 0], [0, 235, 255], [0, 173, 255], [31, 0, 255]]
+
+ def __init__(self, split, **kwargs):
+ super(PascalContextDataset, self).__init__(
+ img_suffix='.jpg',
+ seg_map_suffix='.png',
+ split=split,
+ reduce_zero_label=False,
+ **kwargs)
+ assert self.file_client.exists(self.img_dir) and self.split is not None
+
+
+@DATASETS.register_module()
+class PascalContextDataset59(CustomDataset):
+ """PascalContext dataset.
+
+ In segmentation map annotation for PascalContext, 0 stands for background,
+ which is included in 60 categories. ``reduce_zero_label`` is fixed to
+ False. The ``img_suffix`` is fixed to '.jpg' and ``seg_map_suffix`` is
+ fixed to '.png'.
+
+ Args:
+ split (str): Split txt file for PascalContext.
+ """
+
+ CLASSES = ('aeroplane', 'bag', 'bed', 'bedclothes', 'bench', 'bicycle',
+ 'bird', 'boat', 'book', 'bottle', 'building', 'bus', 'cabinet',
+ 'car', 'cat', 'ceiling', 'chair', 'cloth', 'computer', 'cow',
+ 'cup', 'curtain', 'dog', 'door', 'fence', 'floor', 'flower',
+ 'food', 'grass', 'ground', 'horse', 'keyboard', 'light',
+ 'motorbike', 'mountain', 'mouse', 'person', 'plate', 'platform',
+ 'pottedplant', 'road', 'rock', 'sheep', 'shelves', 'sidewalk',
+ 'sign', 'sky', 'snow', 'sofa', 'table', 'track', 'train',
+ 'tree', 'truck', 'tvmonitor', 'wall', 'water', 'window', 'wood')
+
+ PALETTE = [[180, 120, 120], [6, 230, 230], [80, 50, 50], [4, 200, 3],
+ [120, 120, 80], [140, 140, 140], [204, 5, 255], [230, 230, 230],
+ [4, 250, 7], [224, 5, 255], [235, 255, 7], [150, 5, 61],
+ [120, 120, 70], [8, 255, 51], [255, 6, 82], [143, 255, 140],
+ [204, 255, 4], [255, 51, 7], [204, 70, 3], [0, 102, 200],
+ [61, 230, 250], [255, 6, 51], [11, 102, 255], [255, 7, 71],
+ [255, 9, 224], [9, 7, 230], [220, 220, 220], [255, 9, 92],
+ [112, 9, 255], [8, 255, 214], [7, 255, 224], [255, 184, 6],
+ [10, 255, 71], [255, 41, 10], [7, 255, 255], [224, 255, 8],
+ [102, 8, 255], [255, 61, 6], [255, 194, 7], [255, 122, 8],
+ [0, 255, 20], [255, 8, 41], [255, 5, 153], [6, 51, 255],
+ [235, 12, 255], [160, 150, 20], [0, 163, 255], [140, 140, 140],
+ [250, 10, 15], [20, 255, 0], [31, 255, 0], [255, 31, 0],
+ [255, 224, 0], [153, 255, 0], [0, 0, 255], [255, 71, 0],
+ [0, 235, 255], [0, 173, 255], [31, 0, 255]]
+
+ def __init__(self, split, **kwargs):
+ super(PascalContextDataset59, self).__init__(
+ img_suffix='.jpg',
+ seg_map_suffix='.png',
+ split=split,
+ reduce_zero_label=True,
+ **kwargs)
+ assert self.file_client.exists(self.img_dir) and self.split is not None
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..8256a6fe2f03a381ee62a0271411d5102caf8c43
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/__init__.py
@@ -0,0 +1,19 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .compose import Compose
+from .formatting import (Collect, ImageToTensor, ToDataContainer, ToTensor,
+ Transpose, to_tensor)
+from .loading import LoadAnnotations, LoadImageFromFile
+from .test_time_aug import MultiScaleFlipAug
+from .transforms import (CLAHE, AdjustGamma, Normalize, Pad,
+ PhotoMetricDistortion, RandomCrop, RandomCutOut,
+ RandomFlip, RandomMosaic, RandomRotate, Rerange,
+ Resize, RGB2Gray, SegRescale)
+
+__all__ = [
+ 'Compose', 'to_tensor', 'ToTensor', 'ImageToTensor', 'ToDataContainer',
+ 'Transpose', 'Collect', 'LoadAnnotations', 'LoadImageFromFile',
+ 'MultiScaleFlipAug', 'Resize', 'RandomFlip', 'Pad', 'RandomCrop',
+ 'Normalize', 'SegRescale', 'PhotoMetricDistortion', 'RandomRotate',
+ 'AdjustGamma', 'CLAHE', 'Rerange', 'RGB2Gray', 'RandomCutOut',
+ 'RandomMosaic'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/compose.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/compose.py
new file mode 100644
index 0000000000000000000000000000000000000000..30280c1332abc253434ae4e88271d73de2690ecb
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/compose.py
@@ -0,0 +1,52 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import collections
+
+from mmcv.utils import build_from_cfg
+
+from ..builder import PIPELINES
+
+
+@PIPELINES.register_module()
+class Compose(object):
+ """Compose multiple transforms sequentially.
+
+ Args:
+ transforms (Sequence[dict | callable]): Sequence of transform object or
+ config dict to be composed.
+ """
+
+ def __init__(self, transforms):
+ assert isinstance(transforms, collections.abc.Sequence)
+ self.transforms = []
+ for transform in transforms:
+ if isinstance(transform, dict):
+ transform = build_from_cfg(transform, PIPELINES)
+ self.transforms.append(transform)
+ elif callable(transform):
+ self.transforms.append(transform)
+ else:
+ raise TypeError('transform must be callable or a dict')
+
+ def __call__(self, data):
+ """Call function to apply transforms sequentially.
+
+ Args:
+ data (dict): A result dict contains the data to transform.
+
+ Returns:
+ dict: Transformed data.
+ """
+
+ for t in self.transforms:
+ data = t(data)
+ if data is None:
+ return None
+ return data
+
+ def __repr__(self):
+ format_string = self.__class__.__name__ + '('
+ for t in self.transforms:
+ format_string += '\n'
+ format_string += f' {t}'
+ format_string += '\n)'
+ return format_string
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/formating.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/formating.py
new file mode 100644
index 0000000000000000000000000000000000000000..f6e53bfebe3e76412600361da01c36cb440bafd8
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/formating.py
@@ -0,0 +1,9 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+# flake8: noqa
+import warnings
+
+from .formatting import *
+
+warnings.warn('DeprecationWarning: mmseg.datasets.pipelines.formating will be '
+ 'deprecated in 2021, please replace it with '
+ 'mmseg.datasets.pipelines.formatting.')
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/formatting.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/formatting.py
new file mode 100644
index 0000000000000000000000000000000000000000..4e057c1b8161148166d17cf339b4c04e3f31bc5f
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/formatting.py
@@ -0,0 +1,289 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from collections.abc import Sequence
+
+import mmcv
+import numpy as np
+import torch
+from mmcv.parallel import DataContainer as DC
+
+from ..builder import PIPELINES
+
+
+def to_tensor(data):
+ """Convert objects of various python types to :obj:`torch.Tensor`.
+
+ Supported types are: :class:`numpy.ndarray`, :class:`torch.Tensor`,
+ :class:`Sequence`, :class:`int` and :class:`float`.
+
+ Args:
+ data (torch.Tensor | numpy.ndarray | Sequence | int | float): Data to
+ be converted.
+ """
+
+ if isinstance(data, torch.Tensor):
+ return data
+ elif isinstance(data, np.ndarray):
+ return torch.from_numpy(data)
+ elif isinstance(data, Sequence) and not mmcv.is_str(data):
+ return torch.tensor(data)
+ elif isinstance(data, int):
+ return torch.LongTensor([data])
+ elif isinstance(data, float):
+ return torch.FloatTensor([data])
+ else:
+ raise TypeError(f'type {type(data)} cannot be converted to tensor.')
+
+
+@PIPELINES.register_module()
+class ToTensor(object):
+ """Convert some results to :obj:`torch.Tensor` by given keys.
+
+ Args:
+ keys (Sequence[str]): Keys that need to be converted to Tensor.
+ """
+
+ def __init__(self, keys):
+ self.keys = keys
+
+ def __call__(self, results):
+ """Call function to convert data in results to :obj:`torch.Tensor`.
+
+ Args:
+ results (dict): Result dict contains the data to convert.
+
+ Returns:
+ dict: The result dict contains the data converted
+ to :obj:`torch.Tensor`.
+ """
+
+ for key in self.keys:
+ results[key] = to_tensor(results[key])
+ return results
+
+ def __repr__(self):
+ return self.__class__.__name__ + f'(keys={self.keys})'
+
+
+@PIPELINES.register_module()
+class ImageToTensor(object):
+ """Convert image to :obj:`torch.Tensor` by given keys.
+
+ The dimension order of input image is (H, W, C). The pipeline will convert
+ it to (C, H, W). If only 2 dimension (H, W) is given, the output would be
+ (1, H, W).
+
+ Args:
+ keys (Sequence[str]): Key of images to be converted to Tensor.
+ """
+
+ def __init__(self, keys):
+ self.keys = keys
+
+ def __call__(self, results):
+ """Call function to convert image in results to :obj:`torch.Tensor` and
+ transpose the channel order.
+
+ Args:
+ results (dict): Result dict contains the image data to convert.
+
+ Returns:
+ dict: The result dict contains the image converted
+ to :obj:`torch.Tensor` and transposed to (C, H, W) order.
+ """
+
+ for key in self.keys:
+ img = results[key]
+ if len(img.shape) < 3:
+ img = np.expand_dims(img, -1)
+ results[key] = to_tensor(img.transpose(2, 0, 1))
+ return results
+
+ def __repr__(self):
+ return self.__class__.__name__ + f'(keys={self.keys})'
+
+
+@PIPELINES.register_module()
+class Transpose(object):
+ """Transpose some results by given keys.
+
+ Args:
+ keys (Sequence[str]): Keys of results to be transposed.
+ order (Sequence[int]): Order of transpose.
+ """
+
+ def __init__(self, keys, order):
+ self.keys = keys
+ self.order = order
+
+ def __call__(self, results):
+ """Call function to convert image in results to :obj:`torch.Tensor` and
+ transpose the channel order.
+
+ Args:
+ results (dict): Result dict contains the image data to convert.
+
+ Returns:
+ dict: The result dict contains the image converted
+ to :obj:`torch.Tensor` and transposed to (C, H, W) order.
+ """
+
+ for key in self.keys:
+ results[key] = results[key].transpose(self.order)
+ return results
+
+ def __repr__(self):
+ return self.__class__.__name__ + \
+ f'(keys={self.keys}, order={self.order})'
+
+
+@PIPELINES.register_module()
+class ToDataContainer(object):
+ """Convert results to :obj:`mmcv.DataContainer` by given fields.
+
+ Args:
+ fields (Sequence[dict]): Each field is a dict like
+ ``dict(key='xxx', **kwargs)``. The ``key`` in result will
+ be converted to :obj:`mmcv.DataContainer` with ``**kwargs``.
+ Default: ``(dict(key='img', stack=True),
+ dict(key='gt_semantic_seg'))``.
+ """
+
+ def __init__(self,
+ fields=(dict(key='img',
+ stack=True), dict(key='gt_semantic_seg'))):
+ self.fields = fields
+
+ def __call__(self, results):
+ """Call function to convert data in results to
+ :obj:`mmcv.DataContainer`.
+
+ Args:
+ results (dict): Result dict contains the data to convert.
+
+ Returns:
+ dict: The result dict contains the data converted to
+ :obj:`mmcv.DataContainer`.
+ """
+
+ for field in self.fields:
+ field = field.copy()
+ key = field.pop('key')
+ results[key] = DC(results[key], **field)
+ return results
+
+ def __repr__(self):
+ return self.__class__.__name__ + f'(fields={self.fields})'
+
+
+@PIPELINES.register_module()
+class DefaultFormatBundle(object):
+ """Default formatting bundle.
+
+ It simplifies the pipeline of formatting common fields, including "img"
+ and "gt_semantic_seg". These fields are formatted as follows.
+
+ - img: (1)transpose, (2)to tensor, (3)to DataContainer (stack=True)
+ - gt_semantic_seg: (1)unsqueeze dim-0 (2)to tensor,
+ (3)to DataContainer (stack=True)
+ """
+
+ def __call__(self, results):
+ """Call function to transform and format common fields in results.
+
+ Args:
+ results (dict): Result dict contains the data to convert.
+
+ Returns:
+ dict: The result dict contains the data that is formatted with
+ default bundle.
+ """
+
+ if 'img' in results:
+ img = results['img']
+ if len(img.shape) < 3:
+ img = np.expand_dims(img, -1)
+ img = np.ascontiguousarray(img.transpose(2, 0, 1))
+ results['img'] = DC(to_tensor(img), stack=True)
+ if 'gt_semantic_seg' in results:
+ # convert to long
+ results['gt_semantic_seg'] = DC(
+ to_tensor(results['gt_semantic_seg'][None,
+ ...].astype(np.int64)),
+ stack=True)
+ return results
+
+ def __repr__(self):
+ return self.__class__.__name__
+
+
+@PIPELINES.register_module()
+class Collect(object):
+ """Collect data from the loader relevant to the specific task.
+
+ This is usually the last stage of the data loader pipeline. Typically keys
+ is set to some subset of "img", "gt_semantic_seg".
+
+ The "img_meta" item is always populated. The contents of the "img_meta"
+ dictionary depends on "meta_keys". By default this includes:
+
+ - "img_shape": shape of the image input to the network as a tuple
+ (h, w, c). Note that images may be zero padded on the bottom/right
+ if the batch tensor is larger than this shape.
+
+ - "scale_factor": a float indicating the preprocessing scale
+
+ - "flip": a boolean indicating if image flip transform was used
+
+ - "filename": path to the image file
+
+ - "ori_shape": original shape of the image as a tuple (h, w, c)
+
+ - "pad_shape": image shape after padding
+
+ - "img_norm_cfg": a dict of normalization information:
+ - mean - per channel mean subtraction
+ - std - per channel std divisor
+ - to_rgb - bool indicating if bgr was converted to rgb
+
+ Args:
+ keys (Sequence[str]): Keys of results to be collected in ``data``.
+ meta_keys (Sequence[str], optional): Meta keys to be converted to
+ ``mmcv.DataContainer`` and collected in ``data[img_metas]``.
+ Default: (``filename``, ``ori_filename``, ``ori_shape``,
+ ``img_shape``, ``pad_shape``, ``scale_factor``, ``flip``,
+ ``flip_direction``, ``img_norm_cfg``)
+ """
+
+ def __init__(self,
+ keys,
+ meta_keys=('filename', 'ori_filename', 'ori_shape',
+ 'img_shape', 'pad_shape', 'scale_factor', 'flip',
+ 'flip_direction', 'img_norm_cfg')):
+ self.keys = keys
+ self.meta_keys = meta_keys
+
+ def __call__(self, results):
+ """Call function to collect keys in results. The keys in ``meta_keys``
+ will be converted to :obj:mmcv.DataContainer.
+
+ Args:
+ results (dict): Result dict contains the data to collect.
+
+ Returns:
+ dict: The result dict contains the following keys
+ - keys in``self.keys``
+ - ``img_metas``
+ """
+
+ data = {}
+ img_meta = {}
+ for key in self.meta_keys:
+ img_meta[key] = results[key]
+ data['img_metas'] = DC(img_meta, cpu_only=True)
+ for key in self.keys:
+ data[key] = results[key]
+ return data
+
+ def __repr__(self):
+ return self.__class__.__name__ + \
+ f'(keys={self.keys}, meta_keys={self.meta_keys})'
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/loading.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/loading.py
new file mode 100644
index 0000000000000000000000000000000000000000..572e43431832454b31fb8ed0305c995b404328c4
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/loading.py
@@ -0,0 +1,158 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import os.path as osp
+
+import mmcv
+import numpy as np
+
+from ..builder import PIPELINES
+
+
+@PIPELINES.register_module()
+class LoadImageFromFile(object):
+ """Load an image from file.
+
+ Required keys are "img_prefix" and "img_info" (a dict that must contain the
+ key "filename"). Added or updated keys are "filename", "img", "img_shape",
+ "ori_shape" (same as `img_shape`), "pad_shape" (same as `img_shape`),
+ "scale_factor" (1.0) and "img_norm_cfg" (means=0 and stds=1).
+
+ Args:
+ to_float32 (bool): Whether to convert the loaded image to a float32
+ numpy array. If set to False, the loaded image is an uint8 array.
+ Defaults to False.
+ color_type (str): The flag argument for :func:`mmcv.imfrombytes`.
+ Defaults to 'color'.
+ file_client_args (dict): Arguments to instantiate a FileClient.
+ See :class:`mmcv.fileio.FileClient` for details.
+ Defaults to ``dict(backend='disk')``.
+ imdecode_backend (str): Backend for :func:`mmcv.imdecode`. Default:
+ 'cv2'
+ """
+
+ def __init__(self,
+ to_float32=False,
+ color_type='color',
+ file_client_args=dict(backend='disk'),
+ imdecode_backend='cv2'):
+ self.to_float32 = to_float32
+ self.color_type = color_type
+ self.file_client_args = file_client_args.copy()
+ self.file_client = None
+ self.imdecode_backend = imdecode_backend
+
+ def __call__(self, results):
+ """Call functions to load image and get image meta information.
+
+ Args:
+ results (dict): Result dict from :obj:`mmseg.CustomDataset`.
+
+ Returns:
+ dict: The dict contains loaded image and meta information.
+ """
+
+ if self.file_client is None:
+ self.file_client = mmcv.FileClient(**self.file_client_args)
+
+ if results.get('img_prefix') is not None:
+ filename = osp.join(results['img_prefix'],
+ results['img_info']['filename'])
+ else:
+ filename = results['img_info']['filename']
+ img_bytes = self.file_client.get(filename)
+ img = mmcv.imfrombytes(
+ img_bytes, flag=self.color_type, backend=self.imdecode_backend)
+ if self.to_float32:
+ img = img.astype(np.float32)
+
+ results['filename'] = filename
+ results['ori_filename'] = results['img_info']['filename']
+ results['img'] = img
+ results['img_shape'] = img.shape
+ results['ori_shape'] = img.shape
+ # Set initial values for default meta_keys
+ results['pad_shape'] = img.shape
+ results['scale_factor'] = 1.0
+ num_channels = 1 if len(img.shape) < 3 else img.shape[2]
+ results['img_norm_cfg'] = dict(
+ mean=np.zeros(num_channels, dtype=np.float32),
+ std=np.ones(num_channels, dtype=np.float32),
+ to_rgb=False)
+ return results
+
+ def __repr__(self):
+ repr_str = self.__class__.__name__
+ repr_str += f'(to_float32={self.to_float32},'
+ repr_str += f"color_type='{self.color_type}',"
+ repr_str += f"imdecode_backend='{self.imdecode_backend}')"
+ return repr_str
+
+
+@PIPELINES.register_module()
+class LoadAnnotations(object):
+ """Load annotations for semantic segmentation.
+
+ Args:
+ reduce_zero_label (bool): Whether reduce all label value by 1.
+ Usually used for datasets where 0 is background label.
+ Default: False.
+ file_client_args (dict): Arguments to instantiate a FileClient.
+ See :class:`mmcv.fileio.FileClient` for details.
+ Defaults to ``dict(backend='disk')``.
+ imdecode_backend (str): Backend for :func:`mmcv.imdecode`. Default:
+ 'pillow'
+ """
+
+ def __init__(self,
+ reduce_zero_label=False,
+ file_client_args=dict(backend='disk'),
+ imdecode_backend='pillow'):
+ self.reduce_zero_label = reduce_zero_label
+ self.file_client_args = file_client_args.copy()
+ self.file_client = None
+ self.imdecode_backend = imdecode_backend
+
+ def __call__(self, results):
+ """Call function to load multiple types annotations.
+
+ Args:
+ results (dict): Result dict from :obj:`mmseg.CustomDataset`.
+
+ Returns:
+ dict: The dict contains loaded semantic segmentation annotations.
+ """
+
+ if self.file_client is None:
+ self.file_client = mmcv.FileClient(**self.file_client_args)
+
+ if results.get('seg_prefix', None) is not None:
+ filename = osp.join(results['seg_prefix'],
+ results['ann_info']['seg_map'])
+ else:
+ filename = results['ann_info']['seg_map']
+ img_bytes = self.file_client.get(filename)
+ gt_semantic_seg = mmcv.imfrombytes(
+ img_bytes, flag='unchanged',
+ backend=self.imdecode_backend).squeeze().astype(np.uint8)
+ # modify if custom classes
+ if results.get('label_map', None) is not None:
+ # Add deep copy to solve bug of repeatedly
+ # replace `gt_semantic_seg`, which is reported in
+ # https://github.com/open-mmlab/mmsegmentation/pull/1445/
+ gt_semantic_seg_copy = gt_semantic_seg.copy()
+ for old_id, new_id in results['label_map'].items():
+ gt_semantic_seg[gt_semantic_seg_copy == old_id] = new_id
+ # reduce zero_label
+ if self.reduce_zero_label:
+ # avoid using underflow conversion
+ gt_semantic_seg[gt_semantic_seg == 0] = 255
+ gt_semantic_seg = gt_semantic_seg - 1
+ gt_semantic_seg[gt_semantic_seg == 254] = 255
+ results['gt_semantic_seg'] = gt_semantic_seg
+ results['seg_fields'].append('gt_semantic_seg')
+ return results
+
+ def __repr__(self):
+ repr_str = self.__class__.__name__
+ repr_str += f'(reduce_zero_label={self.reduce_zero_label},'
+ repr_str += f"imdecode_backend='{self.imdecode_backend}')"
+ return repr_str
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/test_time_aug.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/test_time_aug.py
new file mode 100644
index 0000000000000000000000000000000000000000..5c17cbbba11fe99976f4d929215343ca403da688
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/test_time_aug.py
@@ -0,0 +1,134 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import warnings
+
+import mmcv
+
+from ..builder import PIPELINES
+from .compose import Compose
+
+
+@PIPELINES.register_module()
+class MultiScaleFlipAug(object):
+ """Test-time augmentation with multiple scales and flipping.
+
+ An example configuration is as followed:
+
+ .. code-block::
+
+ img_scale=(2048, 1024),
+ img_ratios=[0.5, 1.0],
+ flip=True,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size_divisor=32),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ]
+
+ After MultiScaleFLipAug with above configuration, the results are wrapped
+ into lists of the same length as followed:
+
+ .. code-block::
+
+ dict(
+ img=[...],
+ img_shape=[...],
+ scale=[(1024, 512), (1024, 512), (2048, 1024), (2048, 1024)]
+ flip=[False, True, False, True]
+ ...
+ )
+
+ Args:
+ transforms (list[dict]): Transforms to apply in each augmentation.
+ img_scale (None | tuple | list[tuple]): Images scales for resizing.
+ img_ratios (float | list[float]): Image ratios for resizing
+ flip (bool): Whether apply flip augmentation. Default: False.
+ flip_direction (str | list[str]): Flip augmentation directions,
+ options are "horizontal" and "vertical". If flip_direction is list,
+ multiple flip augmentations will be applied.
+ It has no effect when flip == False. Default: "horizontal".
+ """
+
+ def __init__(self,
+ transforms,
+ img_scale,
+ img_ratios=None,
+ flip=False,
+ flip_direction='horizontal'):
+ self.transforms = Compose(transforms)
+ if img_ratios is not None:
+ img_ratios = img_ratios if isinstance(img_ratios,
+ list) else [img_ratios]
+ assert mmcv.is_list_of(img_ratios, float)
+ if img_scale is None:
+ # mode 1: given img_scale=None and a range of image ratio
+ self.img_scale = None
+ assert mmcv.is_list_of(img_ratios, float)
+ elif isinstance(img_scale, tuple) and mmcv.is_list_of(
+ img_ratios, float):
+ assert len(img_scale) == 2
+ # mode 2: given a scale and a range of image ratio
+ self.img_scale = [(int(img_scale[0] * ratio),
+ int(img_scale[1] * ratio))
+ for ratio in img_ratios]
+ else:
+ # mode 3: given multiple scales
+ self.img_scale = img_scale if isinstance(img_scale,
+ list) else [img_scale]
+ assert mmcv.is_list_of(self.img_scale, tuple) or self.img_scale is None
+ self.flip = flip
+ self.img_ratios = img_ratios
+ self.flip_direction = flip_direction if isinstance(
+ flip_direction, list) else [flip_direction]
+ assert mmcv.is_list_of(self.flip_direction, str)
+ if not self.flip and self.flip_direction != ['horizontal']:
+ warnings.warn(
+ 'flip_direction has no effect when flip is set to False')
+ if (self.flip
+ and not any([t['type'] == 'RandomFlip' for t in transforms])):
+ warnings.warn(
+ 'flip has no effect when RandomFlip is not in transforms')
+
+ def __call__(self, results):
+ """Call function to apply test time augment transforms on results.
+
+ Args:
+ results (dict): Result dict contains the data to transform.
+
+ Returns:
+ dict[str: list]: The augmented data, where each value is wrapped
+ into a list.
+ """
+
+ aug_data = []
+ if self.img_scale is None and mmcv.is_list_of(self.img_ratios, float):
+ h, w = results['img'].shape[:2]
+ img_scale = [(int(w * ratio), int(h * ratio))
+ for ratio in self.img_ratios]
+ else:
+ img_scale = self.img_scale
+ flip_aug = [False, True] if self.flip else [False]
+ for scale in img_scale:
+ for flip in flip_aug:
+ for direction in self.flip_direction:
+ _results = results.copy()
+ _results['scale'] = scale
+ _results['flip'] = flip
+ _results['flip_direction'] = direction
+ data = self.transforms(_results)
+ aug_data.append(data)
+ # list of dict to dict of list
+ aug_data_dict = {key: [] for key in aug_data[0]}
+ for data in aug_data:
+ for key, val in data.items():
+ aug_data_dict[key].append(val)
+ return aug_data_dict
+
+ def __repr__(self):
+ repr_str = self.__class__.__name__
+ repr_str += f'(transforms={self.transforms}, '
+ repr_str += f'img_scale={self.img_scale}, flip={self.flip})'
+ repr_str += f'flip_direction={self.flip_direction}'
+ return repr_str
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/transforms.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/transforms.py
new file mode 100644
index 0000000000000000000000000000000000000000..5673b646fa654bcba39ea897d37a4e7371b5c77f
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/pipelines/transforms.py
@@ -0,0 +1,1335 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import copy
+
+import mmcv
+import numpy as np
+from mmcv.utils import deprecated_api_warning, is_tuple_of
+from numpy import random
+
+from ..builder import PIPELINES
+
+
+@PIPELINES.register_module()
+class ResizeToMultiple(object):
+ """Resize images & seg to multiple of divisor.
+
+ Args:
+ size_divisor (int): images and gt seg maps need to resize to multiple
+ of size_divisor. Default: 32.
+ interpolation (str, optional): The interpolation mode of image resize.
+ Default: None
+ """
+
+ def __init__(self, size_divisor=32, interpolation=None):
+ self.size_divisor = size_divisor
+ self.interpolation = interpolation
+
+ def __call__(self, results):
+ """Call function to resize images, semantic segmentation map to
+ multiple of size divisor.
+
+ Args:
+ results (dict): Result dict from loading pipeline.
+
+ Returns:
+ dict: Resized results, 'img_shape', 'pad_shape' keys are updated.
+ """
+ # Align image to multiple of size divisor.
+ img = results['img']
+ img = mmcv.imresize_to_multiple(
+ img,
+ self.size_divisor,
+ scale_factor=1,
+ interpolation=self.interpolation
+ if self.interpolation else 'bilinear')
+
+ results['img'] = img
+ results['img_shape'] = img.shape
+ results['pad_shape'] = img.shape
+
+ # Align segmentation map to multiple of size divisor.
+ for key in results.get('seg_fields', []):
+ gt_seg = results[key]
+ gt_seg = mmcv.imresize_to_multiple(
+ gt_seg,
+ self.size_divisor,
+ scale_factor=1,
+ interpolation='nearest')
+ results[key] = gt_seg
+
+ return results
+
+ def __repr__(self):
+ repr_str = self.__class__.__name__
+ repr_str += (f'(size_divisor={self.size_divisor}, '
+ f'interpolation={self.interpolation})')
+ return repr_str
+
+
+@PIPELINES.register_module()
+class Resize(object):
+ """Resize images & seg.
+
+ This transform resizes the input image to some scale. If the input dict
+ contains the key "scale", then the scale in the input dict is used,
+ otherwise the specified scale in the init method is used.
+
+ ``img_scale`` can be None, a tuple (single-scale) or a list of tuple
+ (multi-scale). There are 4 multiscale modes:
+
+ - ``ratio_range is not None``:
+ 1. When img_scale is None, img_scale is the shape of image in results
+ (img_scale = results['img'].shape[:2]) and the image is resized based
+ on the original size. (mode 1)
+ 2. When img_scale is a tuple (single-scale), randomly sample a ratio from
+ the ratio range and multiply it with the image scale. (mode 2)
+
+ - ``ratio_range is None and multiscale_mode == "range"``: randomly sample a
+ scale from the a range. (mode 3)
+
+ - ``ratio_range is None and multiscale_mode == "value"``: randomly sample a
+ scale from multiple scales. (mode 4)
+
+ Args:
+ img_scale (tuple or list[tuple]): Images scales for resizing.
+ Default:None.
+ multiscale_mode (str): Either "range" or "value".
+ Default: 'range'
+ ratio_range (tuple[float]): (min_ratio, max_ratio).
+ Default: None
+ keep_ratio (bool): Whether to keep the aspect ratio when resizing the
+ image. Default: True
+ min_size (int, optional): The minimum size for input and the shape
+ of the image and seg map will not be less than ``min_size``.
+ As the shape of model input is fixed like 'SETR' and 'BEiT'.
+ Following the setting in these models, resized images must be
+ bigger than the crop size in ``slide_inference``. Default: None
+ """
+
+ def __init__(self,
+ img_scale=None,
+ multiscale_mode='range',
+ ratio_range=None,
+ keep_ratio=True,
+ min_size=None):
+ if img_scale is None:
+ self.img_scale = None
+ else:
+ if isinstance(img_scale, list):
+ self.img_scale = img_scale
+ else:
+ self.img_scale = [img_scale]
+ assert mmcv.is_list_of(self.img_scale, tuple)
+
+ if ratio_range is not None:
+ # mode 1: given img_scale=None and a range of image ratio
+ # mode 2: given a scale and a range of image ratio
+ assert self.img_scale is None or len(self.img_scale) == 1
+ else:
+ # mode 3 and 4: given multiple scales or a range of scales
+ assert multiscale_mode in ['value', 'range']
+
+ self.multiscale_mode = multiscale_mode
+ self.ratio_range = ratio_range
+ self.keep_ratio = keep_ratio
+ self.min_size = min_size
+
+ @staticmethod
+ def random_select(img_scales):
+ """Randomly select an img_scale from given candidates.
+
+ Args:
+ img_scales (list[tuple]): Images scales for selection.
+
+ Returns:
+ (tuple, int): Returns a tuple ``(img_scale, scale_dix)``,
+ where ``img_scale`` is the selected image scale and
+ ``scale_idx`` is the selected index in the given candidates.
+ """
+
+ assert mmcv.is_list_of(img_scales, tuple)
+ scale_idx = np.random.randint(len(img_scales))
+ img_scale = img_scales[scale_idx]
+ return img_scale, scale_idx
+
+ @staticmethod
+ def random_sample(img_scales):
+ """Randomly sample an img_scale when ``multiscale_mode=='range'``.
+
+ Args:
+ img_scales (list[tuple]): Images scale range for sampling.
+ There must be two tuples in img_scales, which specify the lower
+ and upper bound of image scales.
+
+ Returns:
+ (tuple, None): Returns a tuple ``(img_scale, None)``, where
+ ``img_scale`` is sampled scale and None is just a placeholder
+ to be consistent with :func:`random_select`.
+ """
+
+ assert mmcv.is_list_of(img_scales, tuple) and len(img_scales) == 2
+ img_scale_long = [max(s) for s in img_scales]
+ img_scale_short = [min(s) for s in img_scales]
+ long_edge = np.random.randint(
+ min(img_scale_long),
+ max(img_scale_long) + 1)
+ short_edge = np.random.randint(
+ min(img_scale_short),
+ max(img_scale_short) + 1)
+ img_scale = (long_edge, short_edge)
+ return img_scale, None
+
+ @staticmethod
+ def random_sample_ratio(img_scale, ratio_range):
+ """Randomly sample an img_scale when ``ratio_range`` is specified.
+
+ A ratio will be randomly sampled from the range specified by
+ ``ratio_range``. Then it would be multiplied with ``img_scale`` to
+ generate sampled scale.
+
+ Args:
+ img_scale (tuple): Images scale base to multiply with ratio.
+ ratio_range (tuple[float]): The minimum and maximum ratio to scale
+ the ``img_scale``.
+
+ Returns:
+ (tuple, None): Returns a tuple ``(scale, None)``, where
+ ``scale`` is sampled ratio multiplied with ``img_scale`` and
+ None is just a placeholder to be consistent with
+ :func:`random_select`.
+ """
+
+ assert isinstance(img_scale, tuple) and len(img_scale) == 2
+ min_ratio, max_ratio = ratio_range
+ assert min_ratio <= max_ratio
+ ratio = np.random.random_sample() * (max_ratio - min_ratio) + min_ratio
+ scale = int(img_scale[0] * ratio), int(img_scale[1] * ratio)
+ return scale, None
+
+ def _random_scale(self, results):
+ """Randomly sample an img_scale according to ``ratio_range`` and
+ ``multiscale_mode``.
+
+ If ``ratio_range`` is specified, a ratio will be sampled and be
+ multiplied with ``img_scale``.
+ If multiple scales are specified by ``img_scale``, a scale will be
+ sampled according to ``multiscale_mode``.
+ Otherwise, single scale will be used.
+
+ Args:
+ results (dict): Result dict from :obj:`dataset`.
+
+ Returns:
+ dict: Two new keys 'scale` and 'scale_idx` are added into
+ ``results``, which would be used by subsequent pipelines.
+ """
+
+ if self.ratio_range is not None:
+ if self.img_scale is None:
+ h, w = results['img'].shape[:2]
+ scale, scale_idx = self.random_sample_ratio((w, h),
+ self.ratio_range)
+ else:
+ scale, scale_idx = self.random_sample_ratio(
+ self.img_scale[0], self.ratio_range)
+ elif len(self.img_scale) == 1:
+ scale, scale_idx = self.img_scale[0], 0
+ elif self.multiscale_mode == 'range':
+ scale, scale_idx = self.random_sample(self.img_scale)
+ elif self.multiscale_mode == 'value':
+ scale, scale_idx = self.random_select(self.img_scale)
+ else:
+ raise NotImplementedError
+
+ results['scale'] = scale
+ results['scale_idx'] = scale_idx
+
+ def _resize_img(self, results):
+ """Resize images with ``results['scale']``."""
+ if self.keep_ratio:
+ if self.min_size is not None:
+ # TODO: Now 'min_size' is an 'int' which means the minimum
+ # shape of images is (min_size, min_size, 3). 'min_size'
+ # with tuple type will be supported, i.e. the width and
+ # height are not equal.
+ if min(results['scale']) < self.min_size:
+ new_short = self.min_size
+ else:
+ new_short = min(results['scale'])
+
+ h, w = results['img'].shape[:2]
+ if h > w:
+ new_h, new_w = new_short * h / w, new_short
+ else:
+ new_h, new_w = new_short, new_short * w / h
+ results['scale'] = (new_h, new_w)
+
+ img, scale_factor = mmcv.imrescale(
+ results['img'], results['scale'], return_scale=True)
+ # the w_scale and h_scale has minor difference
+ # a real fix should be done in the mmcv.imrescale in the future
+ new_h, new_w = img.shape[:2]
+ h, w = results['img'].shape[:2]
+ w_scale = new_w / w
+ h_scale = new_h / h
+ else:
+ img, w_scale, h_scale = mmcv.imresize(
+ results['img'], results['scale'], return_scale=True)
+ scale_factor = np.array([w_scale, h_scale, w_scale, h_scale],
+ dtype=np.float32)
+ results['img'] = img
+ results['img_shape'] = img.shape
+ results['pad_shape'] = img.shape # in case that there is no padding
+ results['scale_factor'] = scale_factor
+ results['keep_ratio'] = self.keep_ratio
+
+ def _resize_seg(self, results):
+ """Resize semantic segmentation map with ``results['scale']``."""
+ for key in results.get('seg_fields', []):
+ if self.keep_ratio:
+ gt_seg = mmcv.imrescale(
+ results[key], results['scale'], interpolation='nearest')
+ else:
+ gt_seg = mmcv.imresize(
+ results[key], results['scale'], interpolation='nearest')
+ results[key] = gt_seg
+
+ def __call__(self, results):
+ """Call function to resize images, bounding boxes, masks, semantic
+ segmentation map.
+
+ Args:
+ results (dict): Result dict from loading pipeline.
+
+ Returns:
+ dict: Resized results, 'img_shape', 'pad_shape', 'scale_factor',
+ 'keep_ratio' keys are added into result dict.
+ """
+
+ if 'scale' not in results:
+ self._random_scale(results)
+ self._resize_img(results)
+ self._resize_seg(results)
+ return results
+
+ def __repr__(self):
+ repr_str = self.__class__.__name__
+ repr_str += (f'(img_scale={self.img_scale}, '
+ f'multiscale_mode={self.multiscale_mode}, '
+ f'ratio_range={self.ratio_range}, '
+ f'keep_ratio={self.keep_ratio})')
+ return repr_str
+
+
+@PIPELINES.register_module()
+class RandomFlip(object):
+ """Flip the image & seg.
+
+ If the input dict contains the key "flip", then the flag will be used,
+ otherwise it will be randomly decided by a ratio specified in the init
+ method.
+
+ Args:
+ prob (float, optional): The flipping probability. Default: None.
+ direction(str, optional): The flipping direction. Options are
+ 'horizontal' and 'vertical'. Default: 'horizontal'.
+ """
+
+ @deprecated_api_warning({'flip_ratio': 'prob'}, cls_name='RandomFlip')
+ def __init__(self, prob=None, direction='horizontal'):
+ self.prob = prob
+ self.direction = direction
+ if prob is not None:
+ assert prob >= 0 and prob <= 1
+ assert direction in ['horizontal', 'vertical']
+
+ def __call__(self, results):
+ """Call function to flip bounding boxes, masks, semantic segmentation
+ maps.
+
+ Args:
+ results (dict): Result dict from loading pipeline.
+
+ Returns:
+ dict: Flipped results, 'flip', 'flip_direction' keys are added into
+ result dict.
+ """
+
+ if 'flip' not in results:
+ flip = True if np.random.rand() < self.prob else False
+ results['flip'] = flip
+ if 'flip_direction' not in results:
+ results['flip_direction'] = self.direction
+ if results['flip']:
+ # flip image
+ results['img'] = mmcv.imflip(
+ results['img'], direction=results['flip_direction'])
+
+ # flip segs
+ for key in results.get('seg_fields', []):
+ # use copy() to make numpy stride positive
+ results[key] = mmcv.imflip(
+ results[key], direction=results['flip_direction']).copy()
+ return results
+
+ def __repr__(self):
+ return self.__class__.__name__ + f'(prob={self.prob})'
+
+
+@PIPELINES.register_module()
+class Pad(object):
+ """Pad the image & mask.
+
+ There are two padding modes: (1) pad to a fixed size and (2) pad to the
+ minimum size that is divisible by some number.
+ Added keys are "pad_shape", "pad_fixed_size", "pad_size_divisor",
+
+ Args:
+ size (tuple, optional): Fixed padding size.
+ size_divisor (int, optional): The divisor of padded size.
+ pad_val (float, optional): Padding value. Default: 0.
+ seg_pad_val (float, optional): Padding value of segmentation map.
+ Default: 255.
+ """
+
+ def __init__(self,
+ size=None,
+ size_divisor=None,
+ pad_val=0,
+ seg_pad_val=255):
+ self.size = size
+ self.size_divisor = size_divisor
+ self.pad_val = pad_val
+ self.seg_pad_val = seg_pad_val
+ # only one of size and size_divisor should be valid
+ assert size is not None or size_divisor is not None
+ assert size is None or size_divisor is None
+
+ def _pad_img(self, results):
+ """Pad images according to ``self.size``."""
+ if self.size is not None:
+ padded_img = mmcv.impad(
+ results['img'], shape=self.size, pad_val=self.pad_val)
+ elif self.size_divisor is not None:
+ padded_img = mmcv.impad_to_multiple(
+ results['img'], self.size_divisor, pad_val=self.pad_val)
+ results['img'] = padded_img
+ results['pad_shape'] = padded_img.shape
+ results['pad_fixed_size'] = self.size
+ results['pad_size_divisor'] = self.size_divisor
+
+ def _pad_seg(self, results):
+ """Pad masks according to ``results['pad_shape']``."""
+ for key in results.get('seg_fields', []):
+ results[key] = mmcv.impad(
+ results[key],
+ shape=results['pad_shape'][:2],
+ pad_val=self.seg_pad_val)
+
+ def __call__(self, results):
+ """Call function to pad images, masks, semantic segmentation maps.
+
+ Args:
+ results (dict): Result dict from loading pipeline.
+
+ Returns:
+ dict: Updated result dict.
+ """
+
+ self._pad_img(results)
+ self._pad_seg(results)
+ return results
+
+ def __repr__(self):
+ repr_str = self.__class__.__name__
+ repr_str += f'(size={self.size}, size_divisor={self.size_divisor}, ' \
+ f'pad_val={self.pad_val})'
+ return repr_str
+
+
+@PIPELINES.register_module()
+class Normalize(object):
+ """Normalize the image.
+
+ Added key is "img_norm_cfg".
+
+ Args:
+ mean (sequence): Mean values of 3 channels.
+ std (sequence): Std values of 3 channels.
+ to_rgb (bool): Whether to convert the image from BGR to RGB,
+ default is true.
+ """
+
+ def __init__(self, mean, std, to_rgb=True):
+ self.mean = np.array(mean, dtype=np.float32)
+ self.std = np.array(std, dtype=np.float32)
+ self.to_rgb = to_rgb
+
+ def __call__(self, results):
+ """Call function to normalize images.
+
+ Args:
+ results (dict): Result dict from loading pipeline.
+
+ Returns:
+ dict: Normalized results, 'img_norm_cfg' key is added into
+ result dict.
+ """
+
+ results['img'] = mmcv.imnormalize(results['img'], self.mean, self.std,
+ self.to_rgb)
+ results['img_norm_cfg'] = dict(
+ mean=self.mean, std=self.std, to_rgb=self.to_rgb)
+ return results
+
+ def __repr__(self):
+ repr_str = self.__class__.__name__
+ repr_str += f'(mean={self.mean}, std={self.std}, to_rgb=' \
+ f'{self.to_rgb})'
+ return repr_str
+
+
+@PIPELINES.register_module()
+class Rerange(object):
+ """Rerange the image pixel value.
+
+ Args:
+ min_value (float or int): Minimum value of the reranged image.
+ Default: 0.
+ max_value (float or int): Maximum value of the reranged image.
+ Default: 255.
+ """
+
+ def __init__(self, min_value=0, max_value=255):
+ assert isinstance(min_value, float) or isinstance(min_value, int)
+ assert isinstance(max_value, float) or isinstance(max_value, int)
+ assert min_value < max_value
+ self.min_value = min_value
+ self.max_value = max_value
+
+ def __call__(self, results):
+ """Call function to rerange images.
+
+ Args:
+ results (dict): Result dict from loading pipeline.
+ Returns:
+ dict: Reranged results.
+ """
+
+ img = results['img']
+ img_min_value = np.min(img)
+ img_max_value = np.max(img)
+
+ assert img_min_value < img_max_value
+ # rerange to [0, 1]
+ img = (img - img_min_value) / (img_max_value - img_min_value)
+ # rerange to [min_value, max_value]
+ img = img * (self.max_value - self.min_value) + self.min_value
+ results['img'] = img
+
+ return results
+
+ def __repr__(self):
+ repr_str = self.__class__.__name__
+ repr_str += f'(min_value={self.min_value}, max_value={self.max_value})'
+ return repr_str
+
+
+@PIPELINES.register_module()
+class CLAHE(object):
+ """Use CLAHE method to process the image.
+
+ See `ZUIDERVELD,K. Contrast Limited Adaptive Histogram Equalization[J].
+ Graphics Gems, 1994:474-485.` for more information.
+
+ Args:
+ clip_limit (float): Threshold for contrast limiting. Default: 40.0.
+ tile_grid_size (tuple[int]): Size of grid for histogram equalization.
+ Input image will be divided into equally sized rectangular tiles.
+ It defines the number of tiles in row and column. Default: (8, 8).
+ """
+
+ def __init__(self, clip_limit=40.0, tile_grid_size=(8, 8)):
+ assert isinstance(clip_limit, (float, int))
+ self.clip_limit = clip_limit
+ assert is_tuple_of(tile_grid_size, int)
+ assert len(tile_grid_size) == 2
+ self.tile_grid_size = tile_grid_size
+
+ def __call__(self, results):
+ """Call function to Use CLAHE method process images.
+
+ Args:
+ results (dict): Result dict from loading pipeline.
+
+ Returns:
+ dict: Processed results.
+ """
+
+ for i in range(results['img'].shape[2]):
+ results['img'][:, :, i] = mmcv.clahe(
+ np.array(results['img'][:, :, i], dtype=np.uint8),
+ self.clip_limit, self.tile_grid_size)
+
+ return results
+
+ def __repr__(self):
+ repr_str = self.__class__.__name__
+ repr_str += f'(clip_limit={self.clip_limit}, '\
+ f'tile_grid_size={self.tile_grid_size})'
+ return repr_str
+
+
+@PIPELINES.register_module()
+class RandomCrop(object):
+ """Random crop the image & seg.
+
+ Args:
+ crop_size (tuple): Expected size after cropping, (h, w).
+ cat_max_ratio (float): The maximum ratio that single category could
+ occupy.
+ """
+
+ def __init__(self, crop_size, cat_max_ratio=1., ignore_index=255):
+ assert crop_size[0] > 0 and crop_size[1] > 0
+ self.crop_size = crop_size
+ self.cat_max_ratio = cat_max_ratio
+ self.ignore_index = ignore_index
+
+ def get_crop_bbox(self, img):
+ """Randomly get a crop bounding box."""
+ margin_h = max(img.shape[0] - self.crop_size[0], 0)
+ margin_w = max(img.shape[1] - self.crop_size[1], 0)
+ offset_h = np.random.randint(0, margin_h + 1)
+ offset_w = np.random.randint(0, margin_w + 1)
+ crop_y1, crop_y2 = offset_h, offset_h + self.crop_size[0]
+ crop_x1, crop_x2 = offset_w, offset_w + self.crop_size[1]
+
+ return crop_y1, crop_y2, crop_x1, crop_x2
+
+ def crop(self, img, crop_bbox):
+ """Crop from ``img``"""
+ crop_y1, crop_y2, crop_x1, crop_x2 = crop_bbox
+ img = img[crop_y1:crop_y2, crop_x1:crop_x2, ...]
+ return img
+
+ def __call__(self, results):
+ """Call function to randomly crop images, semantic segmentation maps.
+
+ Args:
+ results (dict): Result dict from loading pipeline.
+
+ Returns:
+ dict: Randomly cropped results, 'img_shape' key in result dict is
+ updated according to crop size.
+ """
+
+ img = results['img']
+ crop_bbox = self.get_crop_bbox(img)
+ if self.cat_max_ratio < 1.:
+ # Repeat 10 times
+ for _ in range(10):
+ seg_temp = self.crop(results['gt_semantic_seg'], crop_bbox)
+ labels, cnt = np.unique(seg_temp, return_counts=True)
+ cnt = cnt[labels != self.ignore_index]
+ if len(cnt) > 1 and np.max(cnt) / np.sum(
+ cnt) < self.cat_max_ratio:
+ break
+ crop_bbox = self.get_crop_bbox(img)
+
+ # crop the image
+ img = self.crop(img, crop_bbox)
+ img_shape = img.shape
+ results['img'] = img
+ results['img_shape'] = img_shape
+
+ # crop semantic seg
+ for key in results.get('seg_fields', []):
+ results[key] = self.crop(results[key], crop_bbox)
+
+ return results
+
+ def __repr__(self):
+ return self.__class__.__name__ + f'(crop_size={self.crop_size})'
+
+
+@PIPELINES.register_module()
+class RandomRotate(object):
+ """Rotate the image & seg.
+
+ Args:
+ prob (float): The rotation probability.
+ degree (float, tuple[float]): Range of degrees to select from. If
+ degree is a number instead of tuple like (min, max),
+ the range of degree will be (``-degree``, ``+degree``)
+ pad_val (float, optional): Padding value of image. Default: 0.
+ seg_pad_val (float, optional): Padding value of segmentation map.
+ Default: 255.
+ center (tuple[float], optional): Center point (w, h) of the rotation in
+ the source image. If not specified, the center of the image will be
+ used. Default: None.
+ auto_bound (bool): Whether to adjust the image size to cover the whole
+ rotated image. Default: False
+ """
+
+ def __init__(self,
+ prob,
+ degree,
+ pad_val=0,
+ seg_pad_val=255,
+ center=None,
+ auto_bound=False):
+ self.prob = prob
+ assert prob >= 0 and prob <= 1
+ if isinstance(degree, (float, int)):
+ assert degree > 0, f'degree {degree} should be positive'
+ self.degree = (-degree, degree)
+ else:
+ self.degree = degree
+ assert len(self.degree) == 2, f'degree {self.degree} should be a ' \
+ f'tuple of (min, max)'
+ self.pal_val = pad_val
+ self.seg_pad_val = seg_pad_val
+ self.center = center
+ self.auto_bound = auto_bound
+
+ def __call__(self, results):
+ """Call function to rotate image, semantic segmentation maps.
+
+ Args:
+ results (dict): Result dict from loading pipeline.
+
+ Returns:
+ dict: Rotated results.
+ """
+
+ rotate = True if np.random.rand() < self.prob else False
+ degree = np.random.uniform(min(*self.degree), max(*self.degree))
+ if rotate:
+ # rotate image
+ results['img'] = mmcv.imrotate(
+ results['img'],
+ angle=degree,
+ border_value=self.pal_val,
+ center=self.center,
+ auto_bound=self.auto_bound)
+
+ # rotate segs
+ for key in results.get('seg_fields', []):
+ results[key] = mmcv.imrotate(
+ results[key],
+ angle=degree,
+ border_value=self.seg_pad_val,
+ center=self.center,
+ auto_bound=self.auto_bound,
+ interpolation='nearest')
+ return results
+
+ def __repr__(self):
+ repr_str = self.__class__.__name__
+ repr_str += f'(prob={self.prob}, ' \
+ f'degree={self.degree}, ' \
+ f'pad_val={self.pal_val}, ' \
+ f'seg_pad_val={self.seg_pad_val}, ' \
+ f'center={self.center}, ' \
+ f'auto_bound={self.auto_bound})'
+ return repr_str
+
+
+@PIPELINES.register_module()
+class RGB2Gray(object):
+ """Convert RGB image to grayscale image.
+
+ This transform calculate the weighted mean of input image channels with
+ ``weights`` and then expand the channels to ``out_channels``. When
+ ``out_channels`` is None, the number of output channels is the same as
+ input channels.
+
+ Args:
+ out_channels (int): Expected number of output channels after
+ transforming. Default: None.
+ weights (tuple[float]): The weights to calculate the weighted mean.
+ Default: (0.299, 0.587, 0.114).
+ """
+
+ def __init__(self, out_channels=None, weights=(0.299, 0.587, 0.114)):
+ assert out_channels is None or out_channels > 0
+ self.out_channels = out_channels
+ assert isinstance(weights, tuple)
+ for item in weights:
+ assert isinstance(item, (float, int))
+ self.weights = weights
+
+ def __call__(self, results):
+ """Call function to convert RGB image to grayscale image.
+
+ Args:
+ results (dict): Result dict from loading pipeline.
+
+ Returns:
+ dict: Result dict with grayscale image.
+ """
+ img = results['img']
+ assert len(img.shape) == 3
+ assert img.shape[2] == len(self.weights)
+ weights = np.array(self.weights).reshape((1, 1, -1))
+ img = (img * weights).sum(2, keepdims=True)
+ if self.out_channels is None:
+ img = img.repeat(weights.shape[2], axis=2)
+ else:
+ img = img.repeat(self.out_channels, axis=2)
+
+ results['img'] = img
+ results['img_shape'] = img.shape
+
+ return results
+
+ def __repr__(self):
+ repr_str = self.__class__.__name__
+ repr_str += f'(out_channels={self.out_channels}, ' \
+ f'weights={self.weights})'
+ return repr_str
+
+
+@PIPELINES.register_module()
+class AdjustGamma(object):
+ """Using gamma correction to process the image.
+
+ Args:
+ gamma (float or int): Gamma value used in gamma correction.
+ Default: 1.0.
+ """
+
+ def __init__(self, gamma=1.0):
+ assert isinstance(gamma, float) or isinstance(gamma, int)
+ assert gamma > 0
+ self.gamma = gamma
+ inv_gamma = 1.0 / gamma
+ self.table = np.array([(i / 255.0)**inv_gamma * 255
+ for i in np.arange(256)]).astype('uint8')
+
+ def __call__(self, results):
+ """Call function to process the image with gamma correction.
+
+ Args:
+ results (dict): Result dict from loading pipeline.
+
+ Returns:
+ dict: Processed results.
+ """
+
+ results['img'] = mmcv.lut_transform(
+ np.array(results['img'], dtype=np.uint8), self.table)
+
+ return results
+
+ def __repr__(self):
+ return self.__class__.__name__ + f'(gamma={self.gamma})'
+
+
+@PIPELINES.register_module()
+class SegRescale(object):
+ """Rescale semantic segmentation maps.
+
+ Args:
+ scale_factor (float): The scale factor of the final output.
+ """
+
+ def __init__(self, scale_factor=1):
+ self.scale_factor = scale_factor
+
+ def __call__(self, results):
+ """Call function to scale the semantic segmentation map.
+
+ Args:
+ results (dict): Result dict from loading pipeline.
+
+ Returns:
+ dict: Result dict with semantic segmentation map scaled.
+ """
+ for key in results.get('seg_fields', []):
+ if self.scale_factor != 1:
+ results[key] = mmcv.imrescale(
+ results[key], self.scale_factor, interpolation='nearest')
+ return results
+
+ def __repr__(self):
+ return self.__class__.__name__ + f'(scale_factor={self.scale_factor})'
+
+
+@PIPELINES.register_module()
+class PhotoMetricDistortion(object):
+ """Apply photometric distortion to image sequentially, every transformation
+ is applied with a probability of 0.5. The position of random contrast is in
+ second or second to last.
+
+ 1. random brightness
+ 2. random contrast (mode 0)
+ 3. convert color from BGR to HSV
+ 4. random saturation
+ 5. random hue
+ 6. convert color from HSV to BGR
+ 7. random contrast (mode 1)
+
+ Args:
+ brightness_delta (int): delta of brightness.
+ contrast_range (tuple): range of contrast.
+ saturation_range (tuple): range of saturation.
+ hue_delta (int): delta of hue.
+ """
+
+ def __init__(self,
+ brightness_delta=32,
+ contrast_range=(0.5, 1.5),
+ saturation_range=(0.5, 1.5),
+ hue_delta=18):
+ self.brightness_delta = brightness_delta
+ self.contrast_lower, self.contrast_upper = contrast_range
+ self.saturation_lower, self.saturation_upper = saturation_range
+ self.hue_delta = hue_delta
+
+ def convert(self, img, alpha=1, beta=0):
+ """Multiple with alpha and add beat with clip."""
+ img = img.astype(np.float32) * alpha + beta
+ img = np.clip(img, 0, 255)
+ return img.astype(np.uint8)
+
+ def brightness(self, img):
+ """Brightness distortion."""
+ if random.randint(2):
+ return self.convert(
+ img,
+ beta=random.uniform(-self.brightness_delta,
+ self.brightness_delta))
+ return img
+
+ def contrast(self, img):
+ """Contrast distortion."""
+ if random.randint(2):
+ return self.convert(
+ img,
+ alpha=random.uniform(self.contrast_lower, self.contrast_upper))
+ return img
+
+ def saturation(self, img):
+ """Saturation distortion."""
+ if random.randint(2):
+ img = mmcv.bgr2hsv(img)
+ img[:, :, 1] = self.convert(
+ img[:, :, 1],
+ alpha=random.uniform(self.saturation_lower,
+ self.saturation_upper))
+ img = mmcv.hsv2bgr(img)
+ return img
+
+ def hue(self, img):
+ """Hue distortion."""
+ if random.randint(2):
+ img = mmcv.bgr2hsv(img)
+ img[:, :,
+ 0] = (img[:, :, 0].astype(int) +
+ random.randint(-self.hue_delta, self.hue_delta)) % 180
+ img = mmcv.hsv2bgr(img)
+ return img
+
+ def __call__(self, results):
+ """Call function to perform photometric distortion on images.
+
+ Args:
+ results (dict): Result dict from loading pipeline.
+
+ Returns:
+ dict: Result dict with images distorted.
+ """
+
+ img = results['img']
+ # random brightness
+ img = self.brightness(img)
+
+ # mode == 0 --> do random contrast first
+ # mode == 1 --> do random contrast last
+ mode = random.randint(2)
+ if mode == 1:
+ img = self.contrast(img)
+
+ # random saturation
+ img = self.saturation(img)
+
+ # random hue
+ img = self.hue(img)
+
+ # random contrast
+ if mode == 0:
+ img = self.contrast(img)
+
+ results['img'] = img
+ return results
+
+ def __repr__(self):
+ repr_str = self.__class__.__name__
+ repr_str += (f'(brightness_delta={self.brightness_delta}, '
+ f'contrast_range=({self.contrast_lower}, '
+ f'{self.contrast_upper}), '
+ f'saturation_range=({self.saturation_lower}, '
+ f'{self.saturation_upper}), '
+ f'hue_delta={self.hue_delta})')
+ return repr_str
+
+
+@PIPELINES.register_module()
+class RandomCutOut(object):
+ """CutOut operation.
+
+ Randomly drop some regions of image used in
+ `Cutout `_.
+ Args:
+ prob (float): cutout probability.
+ n_holes (int | tuple[int, int]): Number of regions to be dropped.
+ If it is given as a list, number of holes will be randomly
+ selected from the closed interval [`n_holes[0]`, `n_holes[1]`].
+ cutout_shape (tuple[int, int] | list[tuple[int, int]]): The candidate
+ shape of dropped regions. It can be `tuple[int, int]` to use a
+ fixed cutout shape, or `list[tuple[int, int]]` to randomly choose
+ shape from the list.
+ cutout_ratio (tuple[float, float] | list[tuple[float, float]]): The
+ candidate ratio of dropped regions. It can be `tuple[float, float]`
+ to use a fixed ratio or `list[tuple[float, float]]` to randomly
+ choose ratio from the list. Please note that `cutout_shape`
+ and `cutout_ratio` cannot be both given at the same time.
+ fill_in (tuple[float, float, float] | tuple[int, int, int]): The value
+ of pixel to fill in the dropped regions. Default: (0, 0, 0).
+ seg_fill_in (int): The labels of pixel to fill in the dropped regions.
+ If seg_fill_in is None, skip. Default: None.
+ """
+
+ def __init__(self,
+ prob,
+ n_holes,
+ cutout_shape=None,
+ cutout_ratio=None,
+ fill_in=(0, 0, 0),
+ seg_fill_in=None):
+
+ assert 0 <= prob and prob <= 1
+ assert (cutout_shape is None) ^ (cutout_ratio is None), \
+ 'Either cutout_shape or cutout_ratio should be specified.'
+ assert (isinstance(cutout_shape, (list, tuple))
+ or isinstance(cutout_ratio, (list, tuple)))
+ if isinstance(n_holes, tuple):
+ assert len(n_holes) == 2 and 0 <= n_holes[0] < n_holes[1]
+ else:
+ n_holes = (n_holes, n_holes)
+ if seg_fill_in is not None:
+ assert (isinstance(seg_fill_in, int) and 0 <= seg_fill_in
+ and seg_fill_in <= 255)
+ self.prob = prob
+ self.n_holes = n_holes
+ self.fill_in = fill_in
+ self.seg_fill_in = seg_fill_in
+ self.with_ratio = cutout_ratio is not None
+ self.candidates = cutout_ratio if self.with_ratio else cutout_shape
+ if not isinstance(self.candidates, list):
+ self.candidates = [self.candidates]
+
+ def __call__(self, results):
+ """Call function to drop some regions of image."""
+ cutout = True if np.random.rand() < self.prob else False
+ if cutout:
+ h, w, c = results['img'].shape
+ n_holes = np.random.randint(self.n_holes[0], self.n_holes[1] + 1)
+ for _ in range(n_holes):
+ x1 = np.random.randint(0, w)
+ y1 = np.random.randint(0, h)
+ index = np.random.randint(0, len(self.candidates))
+ if not self.with_ratio:
+ cutout_w, cutout_h = self.candidates[index]
+ else:
+ cutout_w = int(self.candidates[index][0] * w)
+ cutout_h = int(self.candidates[index][1] * h)
+
+ x2 = np.clip(x1 + cutout_w, 0, w)
+ y2 = np.clip(y1 + cutout_h, 0, h)
+ results['img'][y1:y2, x1:x2, :] = self.fill_in
+
+ if self.seg_fill_in is not None:
+ for key in results.get('seg_fields', []):
+ results[key][y1:y2, x1:x2] = self.seg_fill_in
+
+ return results
+
+ def __repr__(self):
+ repr_str = self.__class__.__name__
+ repr_str += f'(prob={self.prob}, '
+ repr_str += f'n_holes={self.n_holes}, '
+ repr_str += (f'cutout_ratio={self.candidates}, ' if self.with_ratio
+ else f'cutout_shape={self.candidates}, ')
+ repr_str += f'fill_in={self.fill_in}, '
+ repr_str += f'seg_fill_in={self.seg_fill_in})'
+ return repr_str
+
+
+@PIPELINES.register_module()
+class RandomMosaic(object):
+ """Mosaic augmentation. Given 4 images, mosaic transform combines them into
+ one output image. The output image is composed of the parts from each sub-
+ image.
+
+ .. code:: text
+
+ mosaic transform
+ center_x
+ +------------------------------+
+ | pad | pad |
+ | +-----------+ |
+ | | | |
+ | | image1 |--------+ |
+ | | | | |
+ | | | image2 | |
+ center_y |----+-------------+-----------|
+ | | cropped | |
+ |pad | image3 | image4 |
+ | | | |
+ +----|-------------+-----------+
+ | |
+ +-------------+
+
+ The mosaic transform steps are as follows:
+ 1. Choose the mosaic center as the intersections of 4 images
+ 2. Get the left top image according to the index, and randomly
+ sample another 3 images from the custom dataset.
+ 3. Sub image will be cropped if image is larger than mosaic patch
+
+ Args:
+ prob (float): mosaic probability.
+ img_scale (Sequence[int]): Image size after mosaic pipeline of
+ a single image. The size of the output image is four times
+ that of a single image. The output image comprises 4 single images.
+ Default: (640, 640).
+ center_ratio_range (Sequence[float]): Center ratio range of mosaic
+ output. Default: (0.5, 1.5).
+ pad_val (int): Pad value. Default: 0.
+ seg_pad_val (int): Pad value of segmentation map. Default: 255.
+ """
+
+ def __init__(self,
+ prob,
+ img_scale=(640, 640),
+ center_ratio_range=(0.5, 1.5),
+ pad_val=0,
+ seg_pad_val=255):
+ assert 0 <= prob and prob <= 1
+ assert isinstance(img_scale, tuple)
+ self.prob = prob
+ self.img_scale = img_scale
+ self.center_ratio_range = center_ratio_range
+ self.pad_val = pad_val
+ self.seg_pad_val = seg_pad_val
+
+ def __call__(self, results):
+ """Call function to make a mosaic of image.
+
+ Args:
+ results (dict): Result dict.
+
+ Returns:
+ dict: Result dict with mosaic transformed.
+ """
+ mosaic = True if np.random.rand() < self.prob else False
+ if mosaic:
+ results = self._mosaic_transform_img(results)
+ results = self._mosaic_transform_seg(results)
+ return results
+
+ def get_indexes(self, dataset):
+ """Call function to collect indexes.
+
+ Args:
+ dataset (:obj:`MultiImageMixDataset`): The dataset.
+
+ Returns:
+ list: indexes.
+ """
+
+ indexes = [random.randint(0, len(dataset)) for _ in range(3)]
+ return indexes
+
+ def _mosaic_transform_img(self, results):
+ """Mosaic transform function.
+
+ Args:
+ results (dict): Result dict.
+
+ Returns:
+ dict: Updated result dict.
+ """
+
+ assert 'mix_results' in results
+ if len(results['img'].shape) == 3:
+ mosaic_img = np.full(
+ (int(self.img_scale[0] * 2), int(self.img_scale[1] * 2), 3),
+ self.pad_val,
+ dtype=results['img'].dtype)
+ else:
+ mosaic_img = np.full(
+ (int(self.img_scale[0] * 2), int(self.img_scale[1] * 2)),
+ self.pad_val,
+ dtype=results['img'].dtype)
+
+ # mosaic center x, y
+ self.center_x = int(
+ random.uniform(*self.center_ratio_range) * self.img_scale[1])
+ self.center_y = int(
+ random.uniform(*self.center_ratio_range) * self.img_scale[0])
+ center_position = (self.center_x, self.center_y)
+
+ loc_strs = ('top_left', 'top_right', 'bottom_left', 'bottom_right')
+ for i, loc in enumerate(loc_strs):
+ if loc == 'top_left':
+ result_patch = copy.deepcopy(results)
+ else:
+ result_patch = copy.deepcopy(results['mix_results'][i - 1])
+
+ img_i = result_patch['img']
+ h_i, w_i = img_i.shape[:2]
+ # keep_ratio resize
+ scale_ratio_i = min(self.img_scale[0] / h_i,
+ self.img_scale[1] / w_i)
+ img_i = mmcv.imresize(
+ img_i, (int(w_i * scale_ratio_i), int(h_i * scale_ratio_i)))
+
+ # compute the combine parameters
+ paste_coord, crop_coord = self._mosaic_combine(
+ loc, center_position, img_i.shape[:2][::-1])
+ x1_p, y1_p, x2_p, y2_p = paste_coord
+ x1_c, y1_c, x2_c, y2_c = crop_coord
+
+ # crop and paste image
+ mosaic_img[y1_p:y2_p, x1_p:x2_p] = img_i[y1_c:y2_c, x1_c:x2_c]
+
+ results['img'] = mosaic_img
+ results['img_shape'] = mosaic_img.shape
+ results['ori_shape'] = mosaic_img.shape
+
+ return results
+
+ def _mosaic_transform_seg(self, results):
+ """Mosaic transform function for label annotations.
+
+ Args:
+ results (dict): Result dict.
+
+ Returns:
+ dict: Updated result dict.
+ """
+
+ assert 'mix_results' in results
+ for key in results.get('seg_fields', []):
+ mosaic_seg = np.full(
+ (int(self.img_scale[0] * 2), int(self.img_scale[1] * 2)),
+ self.seg_pad_val,
+ dtype=results[key].dtype)
+
+ # mosaic center x, y
+ center_position = (self.center_x, self.center_y)
+
+ loc_strs = ('top_left', 'top_right', 'bottom_left', 'bottom_right')
+ for i, loc in enumerate(loc_strs):
+ if loc == 'top_left':
+ result_patch = copy.deepcopy(results)
+ else:
+ result_patch = copy.deepcopy(results['mix_results'][i - 1])
+
+ gt_seg_i = result_patch[key]
+ h_i, w_i = gt_seg_i.shape[:2]
+ # keep_ratio resize
+ scale_ratio_i = min(self.img_scale[0] / h_i,
+ self.img_scale[1] / w_i)
+ gt_seg_i = mmcv.imresize(
+ gt_seg_i,
+ (int(w_i * scale_ratio_i), int(h_i * scale_ratio_i)),
+ interpolation='nearest')
+
+ # compute the combine parameters
+ paste_coord, crop_coord = self._mosaic_combine(
+ loc, center_position, gt_seg_i.shape[:2][::-1])
+ x1_p, y1_p, x2_p, y2_p = paste_coord
+ x1_c, y1_c, x2_c, y2_c = crop_coord
+
+ # crop and paste image
+ mosaic_seg[y1_p:y2_p, x1_p:x2_p] = gt_seg_i[y1_c:y2_c,
+ x1_c:x2_c]
+
+ results[key] = mosaic_seg
+
+ return results
+
+ def _mosaic_combine(self, loc, center_position_xy, img_shape_wh):
+ """Calculate global coordinate of mosaic image and local coordinate of
+ cropped sub-image.
+
+ Args:
+ loc (str): Index for the sub-image, loc in ('top_left',
+ 'top_right', 'bottom_left', 'bottom_right').
+ center_position_xy (Sequence[float]): Mixing center for 4 images,
+ (x, y).
+ img_shape_wh (Sequence[int]): Width and height of sub-image
+
+ Returns:
+ tuple[tuple[float]]: Corresponding coordinate of pasting and
+ cropping
+ - paste_coord (tuple): paste corner coordinate in mosaic image.
+ - crop_coord (tuple): crop corner coordinate in mosaic image.
+ """
+
+ assert loc in ('top_left', 'top_right', 'bottom_left', 'bottom_right')
+ if loc == 'top_left':
+ # index0 to top left part of image
+ x1, y1, x2, y2 = max(center_position_xy[0] - img_shape_wh[0], 0), \
+ max(center_position_xy[1] - img_shape_wh[1], 0), \
+ center_position_xy[0], \
+ center_position_xy[1]
+ crop_coord = img_shape_wh[0] - (x2 - x1), img_shape_wh[1] - (
+ y2 - y1), img_shape_wh[0], img_shape_wh[1]
+
+ elif loc == 'top_right':
+ # index1 to top right part of image
+ x1, y1, x2, y2 = center_position_xy[0], \
+ max(center_position_xy[1] - img_shape_wh[1], 0), \
+ min(center_position_xy[0] + img_shape_wh[0],
+ self.img_scale[1] * 2), \
+ center_position_xy[1]
+ crop_coord = 0, img_shape_wh[1] - (y2 - y1), min(
+ img_shape_wh[0], x2 - x1), img_shape_wh[1]
+
+ elif loc == 'bottom_left':
+ # index2 to bottom left part of image
+ x1, y1, x2, y2 = max(center_position_xy[0] - img_shape_wh[0], 0), \
+ center_position_xy[1], \
+ center_position_xy[0], \
+ min(self.img_scale[0] * 2, center_position_xy[1] +
+ img_shape_wh[1])
+ crop_coord = img_shape_wh[0] - (x2 - x1), 0, img_shape_wh[0], min(
+ y2 - y1, img_shape_wh[1])
+
+ else:
+ # index3 to bottom right part of image
+ x1, y1, x2, y2 = center_position_xy[0], \
+ center_position_xy[1], \
+ min(center_position_xy[0] + img_shape_wh[0],
+ self.img_scale[1] * 2), \
+ min(self.img_scale[0] * 2, center_position_xy[1] +
+ img_shape_wh[1])
+ crop_coord = 0, 0, min(img_shape_wh[0],
+ x2 - x1), min(y2 - y1, img_shape_wh[1])
+
+ paste_coord = x1, y1, x2, y2
+ return paste_coord, crop_coord
+
+ def __repr__(self):
+ repr_str = self.__class__.__name__
+ repr_str += f'(prob={self.prob}, '
+ repr_str += f'img_scale={self.img_scale}, '
+ repr_str += f'center_ratio_range={self.center_ratio_range}, '
+ repr_str += f'pad_val={self.pad_val}, '
+ repr_str += f'seg_pad_val={self.pad_val})'
+ return repr_str
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/potsdam.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/potsdam.py
new file mode 100644
index 0000000000000000000000000000000000000000..2986b8faa02f9633295879a791ed6202e2f29919
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/potsdam.py
@@ -0,0 +1,25 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .builder import DATASETS
+from .custom import CustomDataset
+
+
+@DATASETS.register_module()
+class PotsdamDataset(CustomDataset):
+ """ISPRS Potsdam dataset.
+
+ In segmentation map annotation for Potsdam dataset, 0 is the ignore index.
+ ``reduce_zero_label`` should be set to True. The ``img_suffix`` and
+ ``seg_map_suffix`` are both fixed to '.png'.
+ """
+ CLASSES = ('impervious_surface', 'building', 'low_vegetation', 'tree',
+ 'car', 'clutter')
+
+ PALETTE = [[255, 255, 255], [0, 0, 255], [0, 255, 255], [0, 255, 0],
+ [255, 255, 0], [255, 0, 0]]
+
+ def __init__(self, **kwargs):
+ super(PotsdamDataset, self).__init__(
+ img_suffix='.png',
+ seg_map_suffix='.png',
+ reduce_zero_label=True,
+ **kwargs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/samplers/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/samplers/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..da09effaf20fefe1a102277672b98db7d884f002
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/samplers/__init__.py
@@ -0,0 +1,4 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .distributed_sampler import DistributedSampler
+
+__all__ = ['DistributedSampler']
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/samplers/distributed_sampler.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/samplers/distributed_sampler.py
new file mode 100644
index 0000000000000000000000000000000000000000..d1a13c7162b060ac3047a8a4b5b215ab63ef6454
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/samplers/distributed_sampler.py
@@ -0,0 +1,71 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from __future__ import division
+from typing import Iterator, Optional
+
+import torch
+from torch.utils.data import Dataset
+from torch.utils.data import DistributedSampler as _DistributedSampler
+
+from mmseg.core.utils import sync_random_seed
+
+
+class DistributedSampler(_DistributedSampler):
+ """DistributedSampler inheriting from
+ `torch.utils.data.DistributedSampler`.
+
+ Args:
+ datasets (Dataset): the dataset will be loaded.
+ num_replicas (int, optional): Number of processes participating in
+ distributed training. By default, world_size is retrieved from the
+ current distributed group.
+ rank (int, optional): Rank of the current process within num_replicas.
+ By default, rank is retrieved from the current distributed group.
+ shuffle (bool): If True (default), sampler will shuffle the indices.
+ seed (int): random seed used to shuffle the sampler if
+ :attr:`shuffle=True`. This number should be identical across all
+ processes in the distributed group. Default: ``0``.
+ """
+
+ def __init__(self,
+ dataset: Dataset,
+ num_replicas: Optional[int] = None,
+ rank: Optional[int] = None,
+ shuffle: bool = True,
+ seed=0) -> None:
+ super().__init__(
+ dataset, num_replicas=num_replicas, rank=rank, shuffle=shuffle)
+
+ # In distributed sampling, different ranks should sample
+ # non-overlapped data in the dataset. Therefore, this function
+ # is used to make sure that each rank shuffles the data indices
+ # in the same order based on the same seed. Then different ranks
+ # could use different indices to select non-overlapped data from the
+ # same data list.
+ self.seed = sync_random_seed(seed)
+
+ def __iter__(self) -> Iterator:
+ """
+ Yields:
+ Iterator: iterator of indices for rank.
+ """
+ # deterministically shuffle based on epoch
+ if self.shuffle:
+ g = torch.Generator()
+ # When :attr:`shuffle=True`, this ensures all replicas
+ # use a different random ordering for each epoch.
+ # Otherwise, the next iteration of this sampler will
+ # yield the same ordering.
+ g.manual_seed(self.epoch + self.seed)
+ indices = torch.randperm(len(self.dataset), generator=g).tolist()
+ else:
+ indices = torch.arange(len(self.dataset)).tolist()
+
+ # add extra samples to make it evenly divisible
+ indices += indices[:(self.total_size - len(indices))]
+ assert len(indices) == self.total_size
+
+ # subsample
+ indices = indices[self.rank:self.total_size:self.num_replicas]
+ assert len(indices) == self.num_samples
+
+ return iter(indices)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/stare.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/stare.py
new file mode 100644
index 0000000000000000000000000000000000000000..a24d1d9570b710e70e3437f4c33a1c84299c6313
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/stare.py
@@ -0,0 +1,28 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import os.path as osp
+
+from .builder import DATASETS
+from .custom import CustomDataset
+
+
+@DATASETS.register_module()
+class STAREDataset(CustomDataset):
+ """STARE dataset.
+
+ In segmentation map annotation for STARE, 0 stands for background, which is
+ included in 2 categories. ``reduce_zero_label`` is fixed to False. The
+ ``img_suffix`` is fixed to '.png' and ``seg_map_suffix`` is fixed to
+ '.ah.png'.
+ """
+
+ CLASSES = ('background', 'vessel')
+
+ PALETTE = [[120, 120, 120], [6, 230, 230]]
+
+ def __init__(self, **kwargs):
+ super(STAREDataset, self).__init__(
+ img_suffix='.png',
+ seg_map_suffix='.ah.png',
+ reduce_zero_label=False,
+ **kwargs)
+ assert osp.exists(self.img_dir)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/voc.py b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/voc.py
new file mode 100644
index 0000000000000000000000000000000000000000..3cec9e3505e5931868869ccebf43263e8883d660
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/datasets/voc.py
@@ -0,0 +1,30 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import os.path as osp
+
+from .builder import DATASETS
+from .custom import CustomDataset
+
+
+@DATASETS.register_module()
+class PascalVOCDataset(CustomDataset):
+ """Pascal VOC dataset.
+
+ Args:
+ split (str): Split txt file for Pascal VOC.
+ """
+
+ CLASSES = ('background', 'aeroplane', 'bicycle', 'bird', 'boat', 'bottle',
+ 'bus', 'car', 'cat', 'chair', 'cow', 'diningtable', 'dog',
+ 'horse', 'motorbike', 'person', 'pottedplant', 'sheep', 'sofa',
+ 'train', 'tvmonitor')
+
+ PALETTE = [[0, 0, 0], [128, 0, 0], [0, 128, 0], [128, 128, 0], [0, 0, 128],
+ [128, 0, 128], [0, 128, 128], [128, 128, 128], [64, 0, 0],
+ [192, 0, 0], [64, 128, 0], [192, 128, 0], [64, 0, 128],
+ [192, 0, 128], [64, 128, 128], [192, 128, 128], [0, 64, 0],
+ [128, 64, 0], [0, 192, 0], [128, 192, 0], [0, 64, 128]]
+
+ def __init__(self, split, **kwargs):
+ super(PascalVOCDataset, self).__init__(
+ img_suffix='.jpg', seg_map_suffix='.png', split=split, **kwargs)
+ assert osp.exists(self.img_dir) and self.split is not None
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..87d8108e3f1977bf4830fa83ad7498081d2a9a51
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/__init__.py
@@ -0,0 +1,13 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .backbones import * # noqa: F401,F403
+from .builder import (BACKBONES, HEADS, LOSSES, SEGMENTORS, build_backbone,
+ build_head, build_loss, build_segmentor)
+from .decode_heads import * # noqa: F401,F403
+from .losses import * # noqa: F401,F403
+from .necks import * # noqa: F401,F403
+from .segmentors import * # noqa: F401,F403
+
+__all__ = [
+ 'BACKBONES', 'HEADS', 'LOSSES', 'SEGMENTORS', 'build_backbone',
+ 'build_head', 'build_loss', 'build_segmentor'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..bda42bb69297ce616e60492aa78fd72ce10a8e21
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/__init__.py
@@ -0,0 +1,30 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .beit import BEiT
+from .bisenetv1 import BiSeNetV1
+from .bisenetv2 import BiSeNetV2
+from .cgnet import CGNet
+from .erfnet import ERFNet
+from .fast_scnn import FastSCNN
+from .hrnet import HRNet
+from .icnet import ICNet
+from .mae import MAE
+from .mit import MixVisionTransformer
+from .mobilenet_v2 import MobileNetV2
+from .mobilenet_v3 import MobileNetV3
+from .resnest import ResNeSt
+from .resnet import ResNet, ResNetV1c, ResNetV1d
+from .resnext import ResNeXt
+from .stdc import STDCContextPathNet, STDCNet
+from .swin import SwinTransformer
+from .timm_backbone import TIMMBackbone
+from .twins import PCPVT, SVT
+from .unet import UNet
+from .vit import VisionTransformer
+
+__all__ = [
+ 'ResNet', 'ResNetV1c', 'ResNetV1d', 'ResNeXt', 'HRNet', 'FastSCNN',
+ 'ResNeSt', 'MobileNetV2', 'UNet', 'CGNet', 'MobileNetV3',
+ 'VisionTransformer', 'SwinTransformer', 'MixVisionTransformer',
+ 'BiSeNetV1', 'BiSeNetV2', 'ICNet', 'TIMMBackbone', 'ERFNet', 'PCPVT',
+ 'SVT', 'STDCNet', 'STDCContextPathNet', 'BEiT', 'MAE'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/beit.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/beit.py
new file mode 100644
index 0000000000000000000000000000000000000000..fade60137dff4a5ab7f16d2d10b829b78232e656
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/beit.py
@@ -0,0 +1,559 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import warnings
+
+import numpy as np
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+from mmcv.cnn import build_norm_layer
+from mmcv.cnn.bricks.drop import build_dropout
+from mmcv.cnn.utils.weight_init import (constant_init, kaiming_init,
+ trunc_normal_)
+from mmcv.runner import BaseModule, ModuleList, _load_checkpoint
+from torch.nn.modules.batchnorm import _BatchNorm
+from torch.nn.modules.utils import _pair as to_2tuple
+
+from mmseg.utils import get_root_logger
+from ..builder import BACKBONES
+from ..utils import PatchEmbed
+from .vit import TransformerEncoderLayer as VisionTransformerEncoderLayer
+
+try:
+ from scipy import interpolate
+except ImportError:
+ interpolate = None
+
+
+class BEiTAttention(BaseModule):
+ """Window based multi-head self-attention (W-MSA) module with relative
+ position bias.
+
+ Args:
+ embed_dims (int): Number of input channels.
+ num_heads (int): Number of attention heads.
+ window_size (tuple[int]): The height and width of the window.
+ bias (bool): The option to add leanable bias for q, k, v. If bias is
+ True, it will add leanable bias. If bias is 'qv_bias', it will only
+ add leanable bias for q, v. If bias is False, it will not add bias
+ for q, k, v. Default to 'qv_bias'.
+ qk_scale (float | None, optional): Override default qk scale of
+ head_dim ** -0.5 if set. Default: None.
+ attn_drop_rate (float): Dropout ratio of attention weight.
+ Default: 0.0
+ proj_drop_rate (float): Dropout ratio of output. Default: 0.
+ init_cfg (dict | None, optional): The Config for initialization.
+ Default: None.
+ """
+
+ def __init__(self,
+ embed_dims,
+ num_heads,
+ window_size,
+ bias='qv_bias',
+ qk_scale=None,
+ attn_drop_rate=0.,
+ proj_drop_rate=0.,
+ init_cfg=None,
+ **kwargs):
+ super().__init__(init_cfg=init_cfg)
+ self.embed_dims = embed_dims
+ self.num_heads = num_heads
+ head_embed_dims = embed_dims // num_heads
+ self.bias = bias
+ self.scale = qk_scale or head_embed_dims**-0.5
+
+ qkv_bias = bias
+ if bias == 'qv_bias':
+ self._init_qv_bias()
+ qkv_bias = False
+
+ self.window_size = window_size
+ self._init_rel_pos_embedding()
+
+ self.qkv = nn.Linear(embed_dims, embed_dims * 3, bias=qkv_bias)
+ self.attn_drop = nn.Dropout(attn_drop_rate)
+ self.proj = nn.Linear(embed_dims, embed_dims)
+ self.proj_drop = nn.Dropout(proj_drop_rate)
+
+ def _init_qv_bias(self):
+ self.q_bias = nn.Parameter(torch.zeros(self.embed_dims))
+ self.v_bias = nn.Parameter(torch.zeros(self.embed_dims))
+
+ def _init_rel_pos_embedding(self):
+ Wh, Ww = self.window_size
+ # cls to token & token 2 cls & cls to cls
+ self.num_relative_distance = (2 * Wh - 1) * (2 * Ww - 1) + 3
+ # relative_position_bias_table shape is (2*Wh-1 * 2*Ww-1 + 3, nH)
+ self.relative_position_bias_table = nn.Parameter(
+ torch.zeros(self.num_relative_distance, self.num_heads))
+
+ # get pair-wise relative position index for
+ # each token inside the window
+ coords_h = torch.arange(Wh)
+ coords_w = torch.arange(Ww)
+ # coords shape is (2, Wh, Ww)
+ coords = torch.stack(torch.meshgrid([coords_h, coords_w]))
+ # coords_flatten shape is (2, Wh*Ww)
+ coords_flatten = torch.flatten(coords, 1)
+ relative_coords = (
+ coords_flatten[:, :, None] - coords_flatten[:, None, :])
+ # relative_coords shape is (Wh*Ww, Wh*Ww, 2)
+ relative_coords = relative_coords.permute(1, 2, 0).contiguous()
+ # shift to start from 0
+ relative_coords[:, :, 0] += Wh - 1
+ relative_coords[:, :, 1] += Ww - 1
+ relative_coords[:, :, 0] *= 2 * Ww - 1
+ relative_position_index = torch.zeros(
+ size=(Wh * Ww + 1, ) * 2, dtype=relative_coords.dtype)
+ # relative_position_index shape is (Wh*Ww, Wh*Ww)
+ relative_position_index[1:, 1:] = relative_coords.sum(-1)
+ relative_position_index[0, 0:] = self.num_relative_distance - 3
+ relative_position_index[0:, 0] = self.num_relative_distance - 2
+ relative_position_index[0, 0] = self.num_relative_distance - 1
+
+ self.register_buffer('relative_position_index',
+ relative_position_index)
+
+ def init_weights(self):
+ trunc_normal_(self.relative_position_bias_table, std=0.02)
+
+ def forward(self, x):
+ """
+ Args:
+ x (tensor): input features with shape of (num_windows*B, N, C).
+ """
+ B, N, C = x.shape
+
+ if self.bias == 'qv_bias':
+ k_bias = torch.zeros_like(self.v_bias, requires_grad=False)
+ qkv_bias = torch.cat((self.q_bias, k_bias, self.v_bias))
+ qkv = F.linear(input=x, weight=self.qkv.weight, bias=qkv_bias)
+ else:
+ qkv = self.qkv(x)
+
+ qkv = qkv.reshape(B, N, 3, self.num_heads, -1).permute(2, 0, 3, 1, 4)
+ q, k, v = qkv[0], qkv[1], qkv[2]
+ q = q * self.scale
+ attn = (q @ k.transpose(-2, -1))
+ if self.relative_position_bias_table is not None:
+ Wh = self.window_size[0]
+ Ww = self.window_size[1]
+ relative_position_bias = self.relative_position_bias_table[
+ self.relative_position_index.view(-1)].view(
+ Wh * Ww + 1, Wh * Ww + 1, -1)
+ relative_position_bias = relative_position_bias.permute(
+ 2, 0, 1).contiguous() # nH, Wh*Ww, Wh*Ww
+ attn = attn + relative_position_bias.unsqueeze(0)
+ attn = attn.softmax(dim=-1)
+ attn = self.attn_drop(attn)
+ x = (attn @ v).transpose(1, 2).reshape(B, N, C)
+ x = self.proj(x)
+ x = self.proj_drop(x)
+ return x
+
+
+class BEiTTransformerEncoderLayer(VisionTransformerEncoderLayer):
+ """Implements one encoder layer in Vision Transformer.
+
+ Args:
+ embed_dims (int): The feature dimension.
+ num_heads (int): Parallel attention heads.
+ feedforward_channels (int): The hidden dimension for FFNs.
+ attn_drop_rate (float): The drop out rate for attention layer.
+ Default: 0.0.
+ drop_path_rate (float): Stochastic depth rate. Default 0.0.
+ num_fcs (int): The number of fully-connected layers for FFNs.
+ Default: 2.
+ bias (bool): The option to add leanable bias for q, k, v. If bias is
+ True, it will add leanable bias. If bias is 'qv_bias', it will only
+ add leanable bias for q, v. If bias is False, it will not add bias
+ for q, k, v. Default to 'qv_bias'.
+ act_cfg (dict): The activation config for FFNs.
+ Default: dict(type='GELU').
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='LN').
+ window_size (tuple[int], optional): The height and width of the window.
+ Default: None.
+ init_values (float, optional): Initialize the values of BEiTAttention
+ and FFN with learnable scaling. Default: None.
+ """
+
+ def __init__(self,
+ embed_dims,
+ num_heads,
+ feedforward_channels,
+ attn_drop_rate=0.,
+ drop_path_rate=0.,
+ num_fcs=2,
+ bias='qv_bias',
+ act_cfg=dict(type='GELU'),
+ norm_cfg=dict(type='LN'),
+ window_size=None,
+ attn_cfg=dict(),
+ ffn_cfg=dict(add_identity=False),
+ init_values=None):
+ attn_cfg.update(dict(window_size=window_size, qk_scale=None))
+
+ super(BEiTTransformerEncoderLayer, self).__init__(
+ embed_dims=embed_dims,
+ num_heads=num_heads,
+ feedforward_channels=feedforward_channels,
+ attn_drop_rate=attn_drop_rate,
+ drop_path_rate=0.,
+ drop_rate=0.,
+ num_fcs=num_fcs,
+ qkv_bias=bias,
+ act_cfg=act_cfg,
+ norm_cfg=norm_cfg,
+ attn_cfg=attn_cfg,
+ ffn_cfg=ffn_cfg)
+
+ # NOTE: drop path for stochastic depth, we shall see if
+ # this is better than dropout here
+ dropout_layer = dict(type='DropPath', drop_prob=drop_path_rate)
+ self.drop_path = build_dropout(
+ dropout_layer) if dropout_layer else nn.Identity()
+ self.gamma_1 = nn.Parameter(
+ init_values * torch.ones((embed_dims)), requires_grad=True)
+ self.gamma_2 = nn.Parameter(
+ init_values * torch.ones((embed_dims)), requires_grad=True)
+
+ def build_attn(self, attn_cfg):
+ self.attn = BEiTAttention(**attn_cfg)
+
+ def forward(self, x):
+ x = x + self.drop_path(self.gamma_1 * self.attn(self.norm1(x)))
+ x = x + self.drop_path(self.gamma_2 * self.ffn(self.norm2(x)))
+ return x
+
+
+@BACKBONES.register_module()
+class BEiT(BaseModule):
+ """BERT Pre-Training of Image Transformers.
+
+ Args:
+ img_size (int | tuple): Input image size. Default: 224.
+ patch_size (int): The patch size. Default: 16.
+ in_channels (int): Number of input channels. Default: 3.
+ embed_dims (int): Embedding dimension. Default: 768.
+ num_layers (int): Depth of transformer. Default: 12.
+ num_heads (int): Number of attention heads. Default: 12.
+ mlp_ratio (int): Ratio of mlp hidden dim to embedding dim.
+ Default: 4.
+ out_indices (list | tuple | int): Output from which stages.
+ Default: -1.
+ qv_bias (bool): Enable bias for qv if True. Default: True.
+ attn_drop_rate (float): The drop out rate for attention layer.
+ Default 0.0
+ drop_path_rate (float): Stochastic depth rate. Default 0.0.
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='LN')
+ act_cfg (dict): The activation config for FFNs.
+ Default: dict(type='GELU').
+ patch_norm (bool): Whether to add a norm in PatchEmbed Block.
+ Default: False.
+ final_norm (bool): Whether to add a additional layer to normalize
+ final feature map. Default: False.
+ num_fcs (int): The number of fully-connected layers for FFNs.
+ Default: 2.
+ norm_eval (bool): Whether to set norm layers to eval mode, namely,
+ freeze running stats (mean and var). Note: Effect on Batch Norm
+ and its variants only. Default: False.
+ pretrained (str, optional): Model pretrained path. Default: None.
+ init_values (float): Initialize the values of BEiTAttention and FFN
+ with learnable scaling.
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ """
+
+ def __init__(self,
+ img_size=224,
+ patch_size=16,
+ in_channels=3,
+ embed_dims=768,
+ num_layers=12,
+ num_heads=12,
+ mlp_ratio=4,
+ out_indices=-1,
+ qv_bias=True,
+ attn_drop_rate=0.,
+ drop_path_rate=0.,
+ norm_cfg=dict(type='LN'),
+ act_cfg=dict(type='GELU'),
+ patch_norm=False,
+ final_norm=False,
+ num_fcs=2,
+ norm_eval=False,
+ pretrained=None,
+ init_values=0.1,
+ init_cfg=None):
+ super(BEiT, self).__init__(init_cfg=init_cfg)
+ if isinstance(img_size, int):
+ img_size = to_2tuple(img_size)
+ elif isinstance(img_size, tuple):
+ if len(img_size) == 1:
+ img_size = to_2tuple(img_size[0])
+ assert len(img_size) == 2, \
+ f'The size of image should have length 1 or 2, ' \
+ f'but got {len(img_size)}'
+
+ assert not (init_cfg and pretrained), \
+ 'init_cfg and pretrained cannot be set at the same time'
+ if isinstance(pretrained, str):
+ warnings.warn('DeprecationWarning: pretrained is deprecated, '
+ 'please use "init_cfg" instead')
+ self.init_cfg = dict(type='Pretrained', checkpoint=pretrained)
+ elif pretrained is not None:
+ raise TypeError('pretrained must be a str or None')
+
+ self.in_channels = in_channels
+ self.img_size = img_size
+ self.patch_size = patch_size
+ self.norm_eval = norm_eval
+ self.pretrained = pretrained
+ self.num_layers = num_layers
+ self.embed_dims = embed_dims
+ self.num_heads = num_heads
+ self.mlp_ratio = mlp_ratio
+ self.attn_drop_rate = attn_drop_rate
+ self.drop_path_rate = drop_path_rate
+ self.num_fcs = num_fcs
+ self.qv_bias = qv_bias
+ self.act_cfg = act_cfg
+ self.norm_cfg = norm_cfg
+ self.patch_norm = patch_norm
+ self.init_values = init_values
+ self.window_size = (img_size[0] // patch_size,
+ img_size[1] // patch_size)
+ self.patch_shape = self.window_size
+ self.cls_token = nn.Parameter(torch.zeros(1, 1, embed_dims))
+
+ self._build_patch_embedding()
+ self._build_layers()
+
+ if isinstance(out_indices, int):
+ if out_indices == -1:
+ out_indices = num_layers - 1
+ self.out_indices = [out_indices]
+ elif isinstance(out_indices, list) or isinstance(out_indices, tuple):
+ self.out_indices = out_indices
+ else:
+ raise TypeError('out_indices must be type of int, list or tuple')
+
+ self.final_norm = final_norm
+ if final_norm:
+ self.norm1_name, norm1 = build_norm_layer(
+ norm_cfg, embed_dims, postfix=1)
+ self.add_module(self.norm1_name, norm1)
+
+ def _build_patch_embedding(self):
+ """Build patch embedding layer."""
+ self.patch_embed = PatchEmbed(
+ in_channels=self.in_channels,
+ embed_dims=self.embed_dims,
+ conv_type='Conv2d',
+ kernel_size=self.patch_size,
+ stride=self.patch_size,
+ padding=0,
+ norm_cfg=self.norm_cfg if self.patch_norm else None,
+ init_cfg=None)
+
+ def _build_layers(self):
+ """Build transformer encoding layers."""
+
+ dpr = [
+ x.item()
+ for x in torch.linspace(0, self.drop_path_rate, self.num_layers)
+ ]
+ self.layers = ModuleList()
+ for i in range(self.num_layers):
+ self.layers.append(
+ BEiTTransformerEncoderLayer(
+ embed_dims=self.embed_dims,
+ num_heads=self.num_heads,
+ feedforward_channels=self.mlp_ratio * self.embed_dims,
+ attn_drop_rate=self.attn_drop_rate,
+ drop_path_rate=dpr[i],
+ num_fcs=self.num_fcs,
+ bias='qv_bias' if self.qv_bias else False,
+ act_cfg=self.act_cfg,
+ norm_cfg=self.norm_cfg,
+ window_size=self.window_size,
+ init_values=self.init_values))
+
+ @property
+ def norm1(self):
+ return getattr(self, self.norm1_name)
+
+ def _geometric_sequence_interpolation(self, src_size, dst_size, sequence,
+ num):
+ """Get new sequence via geometric sequence interpolation.
+
+ Args:
+ src_size (int): Pos_embedding size in pre-trained model.
+ dst_size (int): Pos_embedding size in the current model.
+ sequence (tensor): The relative position bias of the pretrain
+ model after removing the extra tokens.
+ num (int): Number of attention heads.
+ Returns:
+ new_sequence (tensor): Geometric sequence interpolate the
+ pre-trained relative position bias to the size of
+ the current model.
+ """
+
+ def geometric_progression(a, r, n):
+ return a * (1.0 - r**n) / (1.0 - r)
+
+ # Here is a binary function.
+ left, right = 1.01, 1.5
+ while right - left > 1e-6:
+ q = (left + right) / 2.0
+ gp = geometric_progression(1, q, src_size // 2)
+ if gp > dst_size // 2:
+ right = q
+ else:
+ left = q
+ # The position of each interpolated point is determined
+ # by the ratio obtained by dichotomy.
+ dis = []
+ cur = 1
+ for i in range(src_size // 2):
+ dis.append(cur)
+ cur += q**(i + 1)
+ r_ids = [-_ for _ in reversed(dis)]
+ x = r_ids + [0] + dis
+ y = r_ids + [0] + dis
+ t = dst_size // 2.0
+ dx = np.arange(-t, t + 0.1, 1.0)
+ dy = np.arange(-t, t + 0.1, 1.0)
+ # Interpolation functions are being executed and called.
+ new_sequence = []
+ for i in range(num):
+ z = sequence[:, i].view(src_size, src_size).float().numpy()
+ f = interpolate.interp2d(x, y, z, kind='cubic')
+ new_sequence.append(
+ torch.Tensor(f(dx, dy)).contiguous().view(-1, 1).to(sequence))
+ new_sequence = torch.cat(new_sequence, dim=-1)
+ return new_sequence
+
+ def resize_rel_pos_embed(self, checkpoint):
+ """Resize relative pos_embed weights.
+
+ This function is modified from
+ https://github.com/microsoft/unilm/blob/master/beit/semantic_segmentation/mmcv_custom/checkpoint.py. # noqa: E501
+ Copyright (c) Microsoft Corporation
+ Licensed under the MIT License
+ Args:
+ checkpoint (dict): Key and value of the pretrain model.
+ Returns:
+ state_dict (dict): Interpolate the relative pos_embed weights
+ in the pre-train model to the current model size.
+ """
+ if 'state_dict' in checkpoint:
+ state_dict = checkpoint['state_dict']
+ else:
+ state_dict = checkpoint
+
+ all_keys = list(state_dict.keys())
+ for key in all_keys:
+ if 'relative_position_index' in key:
+ state_dict.pop(key)
+ # In order to keep the center of pos_bias as consistent as
+ # possible after interpolation, and vice versa in the edge
+ # area, the geometric sequence interpolation method is adopted.
+ if 'relative_position_bias_table' in key:
+ rel_pos_bias = state_dict[key]
+ src_num_pos, num_attn_heads = rel_pos_bias.size()
+ dst_num_pos, _ = self.state_dict()[key].size()
+ dst_patch_shape = self.patch_shape
+ if dst_patch_shape[0] != dst_patch_shape[1]:
+ raise NotImplementedError()
+ # Count the number of extra tokens.
+ num_extra_tokens = dst_num_pos - (
+ dst_patch_shape[0] * 2 - 1) * (
+ dst_patch_shape[1] * 2 - 1)
+ src_size = int((src_num_pos - num_extra_tokens)**0.5)
+ dst_size = int((dst_num_pos - num_extra_tokens)**0.5)
+ if src_size != dst_size:
+ extra_tokens = rel_pos_bias[-num_extra_tokens:, :]
+ rel_pos_bias = rel_pos_bias[:-num_extra_tokens, :]
+ new_rel_pos_bias = self._geometric_sequence_interpolation(
+ src_size, dst_size, rel_pos_bias, num_attn_heads)
+ new_rel_pos_bias = torch.cat(
+ (new_rel_pos_bias, extra_tokens), dim=0)
+ state_dict[key] = new_rel_pos_bias
+
+ return state_dict
+
+ def init_weights(self):
+
+ def _init_weights(m):
+ if isinstance(m, nn.Linear):
+ trunc_normal_(m.weight, std=.02)
+ if isinstance(m, nn.Linear) and m.bias is not None:
+ nn.init.constant_(m.bias, 0)
+ elif isinstance(m, nn.LayerNorm):
+ nn.init.constant_(m.bias, 0)
+ nn.init.constant_(m.weight, 1.0)
+
+ self.apply(_init_weights)
+
+ if (isinstance(self.init_cfg, dict)
+ and self.init_cfg.get('type') == 'Pretrained'):
+ logger = get_root_logger()
+ checkpoint = _load_checkpoint(
+ self.init_cfg['checkpoint'], logger=logger, map_location='cpu')
+ state_dict = self.resize_rel_pos_embed(checkpoint)
+ self.load_state_dict(state_dict, False)
+ elif self.init_cfg is not None:
+ super(BEiT, self).init_weights()
+ else:
+ # We only implement the 'jax_impl' initialization implemented at
+ # https://github.com/rwightman/pytorch-image-models/blob/master/timm/models/vision_transformer.py#L353 # noqa: E501
+ # Copyright 2019 Ross Wightman
+ # Licensed under the Apache License, Version 2.0 (the "License")
+ trunc_normal_(self.cls_token, std=.02)
+ for n, m in self.named_modules():
+ if isinstance(m, nn.Linear):
+ trunc_normal_(m.weight, std=.02)
+ if m.bias is not None:
+ if 'ffn' in n:
+ nn.init.normal_(m.bias, mean=0., std=1e-6)
+ else:
+ nn.init.constant_(m.bias, 0)
+ elif isinstance(m, nn.Conv2d):
+ kaiming_init(m, mode='fan_in', bias=0.)
+ elif isinstance(m, (_BatchNorm, nn.GroupNorm, nn.LayerNorm)):
+ constant_init(m, val=1.0, bias=0.)
+
+ def forward(self, inputs):
+ B = inputs.shape[0]
+
+ x, hw_shape = self.patch_embed(inputs)
+
+ # stole cls_tokens impl from Phil Wang, thanks
+ cls_tokens = self.cls_token.expand(B, -1, -1)
+ x = torch.cat((cls_tokens, x), dim=1)
+
+ outs = []
+ for i, layer in enumerate(self.layers):
+ x = layer(x)
+ if i == len(self.layers) - 1:
+ if self.final_norm:
+ x = self.norm1(x)
+ if i in self.out_indices:
+ # Remove class token and reshape token for decoder head
+ out = x[:, 1:]
+ B, _, C = out.shape
+ out = out.reshape(B, hw_shape[0], hw_shape[1],
+ C).permute(0, 3, 1, 2).contiguous()
+ outs.append(out)
+
+ return tuple(outs)
+
+ def train(self, mode=True):
+ super(BEiT, self).train(mode)
+ if mode and self.norm_eval:
+ for m in self.modules():
+ if isinstance(m, nn.LayerNorm):
+ m.eval()
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/bisenetv1.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/bisenetv1.py
new file mode 100644
index 0000000000000000000000000000000000000000..4beb7b394d307bf34abab44507ecb92c9bb6cdb1
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/bisenetv1.py
@@ -0,0 +1,332 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+from mmcv.cnn import ConvModule
+from mmcv.runner import BaseModule
+
+from mmseg.ops import resize
+from ..builder import BACKBONES, build_backbone
+
+
+class SpatialPath(BaseModule):
+ """Spatial Path to preserve the spatial size of the original input image
+ and encode affluent spatial information.
+
+ Args:
+ in_channels(int): The number of channels of input
+ image. Default: 3.
+ num_channels (Tuple[int]): The number of channels of
+ each layers in Spatial Path.
+ Default: (64, 64, 64, 128).
+ Returns:
+ x (torch.Tensor): Feature map for Feature Fusion Module.
+ """
+
+ def __init__(self,
+ in_channels=3,
+ num_channels=(64, 64, 64, 128),
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ init_cfg=None):
+ super(SpatialPath, self).__init__(init_cfg=init_cfg)
+ assert len(num_channels) == 4, 'Length of input channels \
+ of Spatial Path must be 4!'
+
+ self.layers = []
+ for i in range(len(num_channels)):
+ layer_name = f'layer{i + 1}'
+ self.layers.append(layer_name)
+ if i == 0:
+ self.add_module(
+ layer_name,
+ ConvModule(
+ in_channels=in_channels,
+ out_channels=num_channels[i],
+ kernel_size=7,
+ stride=2,
+ padding=3,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg))
+ elif i == len(num_channels) - 1:
+ self.add_module(
+ layer_name,
+ ConvModule(
+ in_channels=num_channels[i - 1],
+ out_channels=num_channels[i],
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg))
+ else:
+ self.add_module(
+ layer_name,
+ ConvModule(
+ in_channels=num_channels[i - 1],
+ out_channels=num_channels[i],
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg))
+
+ def forward(self, x):
+ for i, layer_name in enumerate(self.layers):
+ layer_stage = getattr(self, layer_name)
+ x = layer_stage(x)
+ return x
+
+
+class AttentionRefinementModule(BaseModule):
+ """Attention Refinement Module (ARM) to refine the features of each stage.
+
+ Args:
+ in_channels (int): The number of input channels.
+ out_channels (int): The number of output channels.
+ Returns:
+ x_out (torch.Tensor): Feature map of Attention Refinement Module.
+ """
+
+ def __init__(self,
+ in_channels,
+ out_channel,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ init_cfg=None):
+ super(AttentionRefinementModule, self).__init__(init_cfg=init_cfg)
+ self.conv_layer = ConvModule(
+ in_channels=in_channels,
+ out_channels=out_channel,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ self.atten_conv_layer = nn.Sequential(
+ nn.AdaptiveAvgPool2d((1, 1)),
+ ConvModule(
+ in_channels=out_channel,
+ out_channels=out_channel,
+ kernel_size=1,
+ bias=False,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=None), nn.Sigmoid())
+
+ def forward(self, x):
+ x = self.conv_layer(x)
+ x_atten = self.atten_conv_layer(x)
+ x_out = x * x_atten
+ return x_out
+
+
+class ContextPath(BaseModule):
+ """Context Path to provide sufficient receptive field.
+
+ Args:
+ backbone_cfg:(dict): Config of backbone of
+ Context Path.
+ context_channels (Tuple[int]): The number of channel numbers
+ of various modules in Context Path.
+ Default: (128, 256, 512).
+ align_corners (bool, optional): The align_corners argument of
+ resize operation. Default: False.
+ Returns:
+ x_16_up, x_32_up (torch.Tensor, torch.Tensor): Two feature maps
+ undergoing upsampling from 1/16 and 1/32 downsampling
+ feature maps. These two feature maps are used for Feature
+ Fusion Module and Auxiliary Head.
+ """
+
+ def __init__(self,
+ backbone_cfg,
+ context_channels=(128, 256, 512),
+ align_corners=False,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ init_cfg=None):
+ super(ContextPath, self).__init__(init_cfg=init_cfg)
+ assert len(context_channels) == 3, 'Length of input channels \
+ of Context Path must be 3!'
+
+ self.backbone = build_backbone(backbone_cfg)
+
+ self.align_corners = align_corners
+ self.arm16 = AttentionRefinementModule(context_channels[1],
+ context_channels[0])
+ self.arm32 = AttentionRefinementModule(context_channels[2],
+ context_channels[0])
+ self.conv_head32 = ConvModule(
+ in_channels=context_channels[0],
+ out_channels=context_channels[0],
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ self.conv_head16 = ConvModule(
+ in_channels=context_channels[0],
+ out_channels=context_channels[0],
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ self.gap_conv = nn.Sequential(
+ nn.AdaptiveAvgPool2d((1, 1)),
+ ConvModule(
+ in_channels=context_channels[2],
+ out_channels=context_channels[0],
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg))
+
+ def forward(self, x):
+ x_4, x_8, x_16, x_32 = self.backbone(x)
+ x_gap = self.gap_conv(x_32)
+
+ x_32_arm = self.arm32(x_32)
+ x_32_sum = x_32_arm + x_gap
+ x_32_up = resize(input=x_32_sum, size=x_16.shape[2:], mode='nearest')
+ x_32_up = self.conv_head32(x_32_up)
+
+ x_16_arm = self.arm16(x_16)
+ x_16_sum = x_16_arm + x_32_up
+ x_16_up = resize(input=x_16_sum, size=x_8.shape[2:], mode='nearest')
+ x_16_up = self.conv_head16(x_16_up)
+
+ return x_16_up, x_32_up
+
+
+class FeatureFusionModule(BaseModule):
+ """Feature Fusion Module to fuse low level output feature of Spatial Path
+ and high level output feature of Context Path.
+
+ Args:
+ in_channels (int): The number of input channels.
+ out_channels (int): The number of output channels.
+ Returns:
+ x_out (torch.Tensor): Feature map of Feature Fusion Module.
+ """
+
+ def __init__(self,
+ in_channels,
+ out_channels,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ init_cfg=None):
+ super(FeatureFusionModule, self).__init__(init_cfg=init_cfg)
+ self.conv1 = ConvModule(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ self.gap = nn.AdaptiveAvgPool2d((1, 1))
+ self.conv_atten = nn.Sequential(
+ ConvModule(
+ in_channels=out_channels,
+ out_channels=out_channels,
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ bias=False,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg), nn.Sigmoid())
+
+ def forward(self, x_sp, x_cp):
+ x_concat = torch.cat([x_sp, x_cp], dim=1)
+ x_fuse = self.conv1(x_concat)
+ x_atten = self.gap(x_fuse)
+ # Note: No BN and more 1x1 conv in paper.
+ x_atten = self.conv_atten(x_atten)
+ x_atten = x_fuse * x_atten
+ x_out = x_atten + x_fuse
+ return x_out
+
+
+@BACKBONES.register_module()
+class BiSeNetV1(BaseModule):
+ """BiSeNetV1 backbone.
+
+ This backbone is the implementation of `BiSeNet: Bilateral
+ Segmentation Network for Real-time Semantic
+ Segmentation `_.
+
+ Args:
+ backbone_cfg:(dict): Config of backbone of
+ Context Path.
+ in_channels (int): The number of channels of input
+ image. Default: 3.
+ spatial_channels (Tuple[int]): Size of channel numbers of
+ various layers in Spatial Path.
+ Default: (64, 64, 64, 128).
+ context_channels (Tuple[int]): Size of channel numbers of
+ various modules in Context Path.
+ Default: (128, 256, 512).
+ out_indices (Tuple[int] | int, optional): Output from which stages.
+ Default: (0, 1, 2).
+ align_corners (bool, optional): The align_corners argument of
+ resize operation in Bilateral Guided Aggregation Layer.
+ Default: False.
+ out_channels(int): The number of channels of output.
+ It must be the same with `in_channels` of decode_head.
+ Default: 256.
+ """
+
+ def __init__(self,
+ backbone_cfg,
+ in_channels=3,
+ spatial_channels=(64, 64, 64, 128),
+ context_channels=(128, 256, 512),
+ out_indices=(0, 1, 2),
+ align_corners=False,
+ out_channels=256,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN', requires_grad=True),
+ act_cfg=dict(type='ReLU'),
+ init_cfg=None):
+
+ super(BiSeNetV1, self).__init__(init_cfg=init_cfg)
+ assert len(spatial_channels) == 4, 'Length of input channels \
+ of Spatial Path must be 4!'
+
+ assert len(context_channels) == 3, 'Length of input channels \
+ of Context Path must be 3!'
+
+ self.out_indices = out_indices
+ self.align_corners = align_corners
+ self.context_path = ContextPath(backbone_cfg, context_channels,
+ self.align_corners)
+ self.spatial_path = SpatialPath(in_channels, spatial_channels)
+ self.ffm = FeatureFusionModule(context_channels[1], out_channels)
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+
+ def forward(self, x):
+ # stole refactoring code from Coin Cheung, thanks
+ x_context8, x_context16 = self.context_path(x)
+ x_spatial = self.spatial_path(x)
+ x_fuse = self.ffm(x_spatial, x_context8)
+
+ outs = [x_fuse, x_context8, x_context16]
+ outs = [outs[i] for i in self.out_indices]
+ return tuple(outs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/bisenetv2.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/bisenetv2.py
new file mode 100644
index 0000000000000000000000000000000000000000..d908b321caa4acacd71c997f16b6ac99b4256434
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/bisenetv2.py
@@ -0,0 +1,622 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+from mmcv.cnn import (ConvModule, DepthwiseSeparableConvModule,
+ build_activation_layer, build_norm_layer)
+from mmcv.runner import BaseModule
+
+from mmseg.ops import resize
+from ..builder import BACKBONES
+
+
+class DetailBranch(BaseModule):
+ """Detail Branch with wide channels and shallow layers to capture low-level
+ details and generate high-resolution feature representation.
+
+ Args:
+ detail_channels (Tuple[int]): Size of channel numbers of each stage
+ in Detail Branch, in paper it has 3 stages.
+ Default: (64, 64, 128).
+ in_channels (int): Number of channels of input image. Default: 3.
+ conv_cfg (dict | None): Config of conv layers.
+ Default: None.
+ norm_cfg (dict | None): Config of norm layers.
+ Default: dict(type='BN').
+ act_cfg (dict): Config of activation layers.
+ Default: dict(type='ReLU').
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ Returns:
+ x (torch.Tensor): Feature map of Detail Branch.
+ """
+
+ def __init__(self,
+ detail_channels=(64, 64, 128),
+ in_channels=3,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ init_cfg=None):
+ super(DetailBranch, self).__init__(init_cfg=init_cfg)
+ detail_branch = []
+ for i in range(len(detail_channels)):
+ if i == 0:
+ detail_branch.append(
+ nn.Sequential(
+ ConvModule(
+ in_channels=in_channels,
+ out_channels=detail_channels[i],
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg),
+ ConvModule(
+ in_channels=detail_channels[i],
+ out_channels=detail_channels[i],
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)))
+ else:
+ detail_branch.append(
+ nn.Sequential(
+ ConvModule(
+ in_channels=detail_channels[i - 1],
+ out_channels=detail_channels[i],
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg),
+ ConvModule(
+ in_channels=detail_channels[i],
+ out_channels=detail_channels[i],
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg),
+ ConvModule(
+ in_channels=detail_channels[i],
+ out_channels=detail_channels[i],
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)))
+ self.detail_branch = nn.ModuleList(detail_branch)
+
+ def forward(self, x):
+ for stage in self.detail_branch:
+ x = stage(x)
+ return x
+
+
+class StemBlock(BaseModule):
+ """Stem Block at the beginning of Semantic Branch.
+
+ Args:
+ in_channels (int): Number of input channels.
+ Default: 3.
+ out_channels (int): Number of output channels.
+ Default: 16.
+ conv_cfg (dict | None): Config of conv layers.
+ Default: None.
+ norm_cfg (dict | None): Config of norm layers.
+ Default: dict(type='BN').
+ act_cfg (dict): Config of activation layers.
+ Default: dict(type='ReLU').
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ Returns:
+ x (torch.Tensor): First feature map in Semantic Branch.
+ """
+
+ def __init__(self,
+ in_channels=3,
+ out_channels=16,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ init_cfg=None):
+ super(StemBlock, self).__init__(init_cfg=init_cfg)
+
+ self.conv_first = ConvModule(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ self.convs = nn.Sequential(
+ ConvModule(
+ in_channels=out_channels,
+ out_channels=out_channels // 2,
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg),
+ ConvModule(
+ in_channels=out_channels // 2,
+ out_channels=out_channels,
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg))
+ self.pool = nn.MaxPool2d(
+ kernel_size=3, stride=2, padding=1, ceil_mode=False)
+ self.fuse_last = ConvModule(
+ in_channels=out_channels * 2,
+ out_channels=out_channels,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+
+ def forward(self, x):
+ x = self.conv_first(x)
+ x_left = self.convs(x)
+ x_right = self.pool(x)
+ x = self.fuse_last(torch.cat([x_left, x_right], dim=1))
+ return x
+
+
+class GELayer(BaseModule):
+ """Gather-and-Expansion Layer.
+
+ Args:
+ in_channels (int): Number of input channels.
+ out_channels (int): Number of output channels.
+ exp_ratio (int): Expansion ratio for middle channels.
+ Default: 6.
+ stride (int): Stride of GELayer. Default: 1
+ conv_cfg (dict | None): Config of conv layers.
+ Default: None.
+ norm_cfg (dict | None): Config of norm layers.
+ Default: dict(type='BN').
+ act_cfg (dict): Config of activation layers.
+ Default: dict(type='ReLU').
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ Returns:
+ x (torch.Tensor): Intermediate feature map in
+ Semantic Branch.
+ """
+
+ def __init__(self,
+ in_channels,
+ out_channels,
+ exp_ratio=6,
+ stride=1,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ init_cfg=None):
+ super(GELayer, self).__init__(init_cfg=init_cfg)
+ mid_channel = in_channels * exp_ratio
+ self.conv1 = ConvModule(
+ in_channels=in_channels,
+ out_channels=in_channels,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ if stride == 1:
+ self.dwconv = nn.Sequential(
+ # ReLU in ConvModule not shown in paper
+ ConvModule(
+ in_channels=in_channels,
+ out_channels=mid_channel,
+ kernel_size=3,
+ stride=stride,
+ padding=1,
+ groups=in_channels,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg))
+ self.shortcut = None
+ else:
+ self.dwconv = nn.Sequential(
+ ConvModule(
+ in_channels=in_channels,
+ out_channels=mid_channel,
+ kernel_size=3,
+ stride=stride,
+ padding=1,
+ groups=in_channels,
+ bias=False,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=None),
+ # ReLU in ConvModule not shown in paper
+ ConvModule(
+ in_channels=mid_channel,
+ out_channels=mid_channel,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ groups=mid_channel,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg),
+ )
+ self.shortcut = nn.Sequential(
+ DepthwiseSeparableConvModule(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ kernel_size=3,
+ stride=stride,
+ padding=1,
+ dw_norm_cfg=norm_cfg,
+ dw_act_cfg=None,
+ pw_norm_cfg=norm_cfg,
+ pw_act_cfg=None,
+ ))
+
+ self.conv2 = nn.Sequential(
+ ConvModule(
+ in_channels=mid_channel,
+ out_channels=out_channels,
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ bias=False,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=None,
+ ))
+
+ self.act = build_activation_layer(act_cfg)
+
+ def forward(self, x):
+ identity = x
+ x = self.conv1(x)
+ x = self.dwconv(x)
+ x = self.conv2(x)
+ if self.shortcut is not None:
+ shortcut = self.shortcut(identity)
+ x = x + shortcut
+ else:
+ x = x + identity
+ x = self.act(x)
+ return x
+
+
+class CEBlock(BaseModule):
+ """Context Embedding Block for large receptive filed in Semantic Branch.
+
+ Args:
+ in_channels (int): Number of input channels.
+ Default: 3.
+ out_channels (int): Number of output channels.
+ Default: 16.
+ conv_cfg (dict | None): Config of conv layers.
+ Default: None.
+ norm_cfg (dict | None): Config of norm layers.
+ Default: dict(type='BN').
+ act_cfg (dict): Config of activation layers.
+ Default: dict(type='ReLU').
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ Returns:
+ x (torch.Tensor): Last feature map in Semantic Branch.
+ """
+
+ def __init__(self,
+ in_channels=3,
+ out_channels=16,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ init_cfg=None):
+ super(CEBlock, self).__init__(init_cfg=init_cfg)
+ self.in_channels = in_channels
+ self.out_channels = out_channels
+ self.gap = nn.Sequential(
+ nn.AdaptiveAvgPool2d((1, 1)),
+ build_norm_layer(norm_cfg, self.in_channels)[1])
+ self.conv_gap = ConvModule(
+ in_channels=self.in_channels,
+ out_channels=self.out_channels,
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ # Note: in paper here is naive conv2d, no bn-relu
+ self.conv_last = ConvModule(
+ in_channels=self.out_channels,
+ out_channels=self.out_channels,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+
+ def forward(self, x):
+ identity = x
+ x = self.gap(x)
+ x = self.conv_gap(x)
+ x = identity + x
+ x = self.conv_last(x)
+ return x
+
+
+class SemanticBranch(BaseModule):
+ """Semantic Branch which is lightweight with narrow channels and deep
+ layers to obtain high-level semantic context.
+
+ Args:
+ semantic_channels(Tuple[int]): Size of channel numbers of
+ various stages in Semantic Branch.
+ Default: (16, 32, 64, 128).
+ in_channels (int): Number of channels of input image. Default: 3.
+ exp_ratio (int): Expansion ratio for middle channels.
+ Default: 6.
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ Returns:
+ semantic_outs (List[torch.Tensor]): List of several feature maps
+ for auxiliary heads (Booster) and Bilateral
+ Guided Aggregation Layer.
+ """
+
+ def __init__(self,
+ semantic_channels=(16, 32, 64, 128),
+ in_channels=3,
+ exp_ratio=6,
+ init_cfg=None):
+ super(SemanticBranch, self).__init__(init_cfg=init_cfg)
+ self.in_channels = in_channels
+ self.semantic_channels = semantic_channels
+ self.semantic_stages = []
+ for i in range(len(semantic_channels)):
+ stage_name = f'stage{i + 1}'
+ self.semantic_stages.append(stage_name)
+ if i == 0:
+ self.add_module(
+ stage_name,
+ StemBlock(self.in_channels, semantic_channels[i]))
+ elif i == (len(semantic_channels) - 1):
+ self.add_module(
+ stage_name,
+ nn.Sequential(
+ GELayer(semantic_channels[i - 1], semantic_channels[i],
+ exp_ratio, 2),
+ GELayer(semantic_channels[i], semantic_channels[i],
+ exp_ratio, 1),
+ GELayer(semantic_channels[i], semantic_channels[i],
+ exp_ratio, 1),
+ GELayer(semantic_channels[i], semantic_channels[i],
+ exp_ratio, 1)))
+ else:
+ self.add_module(
+ stage_name,
+ nn.Sequential(
+ GELayer(semantic_channels[i - 1], semantic_channels[i],
+ exp_ratio, 2),
+ GELayer(semantic_channels[i], semantic_channels[i],
+ exp_ratio, 1)))
+
+ self.add_module(f'stage{len(semantic_channels)}_CEBlock',
+ CEBlock(semantic_channels[-1], semantic_channels[-1]))
+ self.semantic_stages.append(f'stage{len(semantic_channels)}_CEBlock')
+
+ def forward(self, x):
+ semantic_outs = []
+ for stage_name in self.semantic_stages:
+ semantic_stage = getattr(self, stage_name)
+ x = semantic_stage(x)
+ semantic_outs.append(x)
+ return semantic_outs
+
+
+class BGALayer(BaseModule):
+ """Bilateral Guided Aggregation Layer to fuse the complementary information
+ from both Detail Branch and Semantic Branch.
+
+ Args:
+ out_channels (int): Number of output channels.
+ Default: 128.
+ align_corners (bool): align_corners argument of F.interpolate.
+ Default: False.
+ conv_cfg (dict | None): Config of conv layers.
+ Default: None.
+ norm_cfg (dict | None): Config of norm layers.
+ Default: dict(type='BN').
+ act_cfg (dict): Config of activation layers.
+ Default: dict(type='ReLU').
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ Returns:
+ output (torch.Tensor): Output feature map for Segment heads.
+ """
+
+ def __init__(self,
+ out_channels=128,
+ align_corners=False,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ init_cfg=None):
+ super(BGALayer, self).__init__(init_cfg=init_cfg)
+ self.out_channels = out_channels
+ self.align_corners = align_corners
+ self.detail_dwconv = nn.Sequential(
+ DepthwiseSeparableConvModule(
+ in_channels=self.out_channels,
+ out_channels=self.out_channels,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ dw_norm_cfg=norm_cfg,
+ dw_act_cfg=None,
+ pw_norm_cfg=None,
+ pw_act_cfg=None,
+ ))
+ self.detail_down = nn.Sequential(
+ ConvModule(
+ in_channels=self.out_channels,
+ out_channels=self.out_channels,
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ bias=False,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=None),
+ nn.AvgPool2d(kernel_size=3, stride=2, padding=1, ceil_mode=False))
+ self.semantic_conv = nn.Sequential(
+ ConvModule(
+ in_channels=self.out_channels,
+ out_channels=self.out_channels,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ bias=False,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=None))
+ self.semantic_dwconv = nn.Sequential(
+ DepthwiseSeparableConvModule(
+ in_channels=self.out_channels,
+ out_channels=self.out_channels,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ dw_norm_cfg=norm_cfg,
+ dw_act_cfg=None,
+ pw_norm_cfg=None,
+ pw_act_cfg=None,
+ ))
+ self.conv = ConvModule(
+ in_channels=self.out_channels,
+ out_channels=self.out_channels,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ inplace=True,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg,
+ )
+
+ def forward(self, x_d, x_s):
+ detail_dwconv = self.detail_dwconv(x_d)
+ detail_down = self.detail_down(x_d)
+ semantic_conv = self.semantic_conv(x_s)
+ semantic_dwconv = self.semantic_dwconv(x_s)
+ semantic_conv = resize(
+ input=semantic_conv,
+ size=detail_dwconv.shape[2:],
+ mode='bilinear',
+ align_corners=self.align_corners)
+ fuse_1 = detail_dwconv * torch.sigmoid(semantic_conv)
+ fuse_2 = detail_down * torch.sigmoid(semantic_dwconv)
+ fuse_2 = resize(
+ input=fuse_2,
+ size=fuse_1.shape[2:],
+ mode='bilinear',
+ align_corners=self.align_corners)
+ output = self.conv(fuse_1 + fuse_2)
+ return output
+
+
+@BACKBONES.register_module()
+class BiSeNetV2(BaseModule):
+ """BiSeNetV2: Bilateral Network with Guided Aggregation for
+ Real-time Semantic Segmentation.
+
+ This backbone is the implementation of
+ `BiSeNetV2 `_.
+
+ Args:
+ in_channels (int): Number of channel of input image. Default: 3.
+ detail_channels (Tuple[int], optional): Channels of each stage
+ in Detail Branch. Default: (64, 64, 128).
+ semantic_channels (Tuple[int], optional): Channels of each stage
+ in Semantic Branch. Default: (16, 32, 64, 128).
+ See Table 1 and Figure 3 of paper for more details.
+ semantic_expansion_ratio (int, optional): The expansion factor
+ expanding channel number of middle channels in Semantic Branch.
+ Default: 6.
+ bga_channels (int, optional): Number of middle channels in
+ Bilateral Guided Aggregation Layer. Default: 128.
+ out_indices (Tuple[int] | int, optional): Output from which stages.
+ Default: (0, 1, 2, 3, 4).
+ align_corners (bool, optional): The align_corners argument of
+ resize operation in Bilateral Guided Aggregation Layer.
+ Default: False.
+ conv_cfg (dict | None): Config of conv layers.
+ Default: None.
+ norm_cfg (dict | None): Config of norm layers.
+ Default: dict(type='BN').
+ act_cfg (dict): Config of activation layers.
+ Default: dict(type='ReLU').
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ """
+
+ def __init__(self,
+ in_channels=3,
+ detail_channels=(64, 64, 128),
+ semantic_channels=(16, 32, 64, 128),
+ semantic_expansion_ratio=6,
+ bga_channels=128,
+ out_indices=(0, 1, 2, 3, 4),
+ align_corners=False,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ init_cfg=None):
+ if init_cfg is None:
+ init_cfg = [
+ dict(type='Kaiming', layer='Conv2d'),
+ dict(
+ type='Constant', val=1, layer=['_BatchNorm', 'GroupNorm'])
+ ]
+ super(BiSeNetV2, self).__init__(init_cfg=init_cfg)
+ self.in_channels = in_channels
+ self.out_indices = out_indices
+ self.detail_channels = detail_channels
+ self.semantic_channels = semantic_channels
+ self.semantic_expansion_ratio = semantic_expansion_ratio
+ self.bga_channels = bga_channels
+ self.align_corners = align_corners
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+
+ self.detail = DetailBranch(self.detail_channels, self.in_channels)
+ self.semantic = SemanticBranch(self.semantic_channels,
+ self.in_channels,
+ self.semantic_expansion_ratio)
+ self.bga = BGALayer(self.bga_channels, self.align_corners)
+
+ def forward(self, x):
+ # stole refactoring code from Coin Cheung, thanks
+ x_detail = self.detail(x)
+ x_semantic_lst = self.semantic(x)
+ x_head = self.bga(x_detail, x_semantic_lst[-1])
+ outs = [x_head] + x_semantic_lst[:-1]
+ outs = [outs[i] for i in self.out_indices]
+ return tuple(outs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/cgnet.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/cgnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..168194c106ed19fd46891de7ee8214a4db88f3c7
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/cgnet.py
@@ -0,0 +1,372 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import warnings
+
+import torch
+import torch.nn as nn
+import torch.utils.checkpoint as cp
+from mmcv.cnn import ConvModule, build_conv_layer, build_norm_layer
+from mmcv.runner import BaseModule
+from mmcv.utils.parrots_wrapper import _BatchNorm
+
+from ..builder import BACKBONES
+
+
+class GlobalContextExtractor(nn.Module):
+ """Global Context Extractor for CGNet.
+
+ This class is employed to refine the joint feature of both local feature
+ and surrounding context.
+
+ Args:
+ channel (int): Number of input feature channels.
+ reduction (int): Reductions for global context extractor. Default: 16.
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save some
+ memory while slowing down the training speed. Default: False.
+ """
+
+ def __init__(self, channel, reduction=16, with_cp=False):
+ super(GlobalContextExtractor, self).__init__()
+ self.channel = channel
+ self.reduction = reduction
+ assert reduction >= 1 and channel >= reduction
+ self.with_cp = with_cp
+ self.avg_pool = nn.AdaptiveAvgPool2d(1)
+ self.fc = nn.Sequential(
+ nn.Linear(channel, channel // reduction), nn.ReLU(inplace=True),
+ nn.Linear(channel // reduction, channel), nn.Sigmoid())
+
+ def forward(self, x):
+
+ def _inner_forward(x):
+ num_batch, num_channel = x.size()[:2]
+ y = self.avg_pool(x).view(num_batch, num_channel)
+ y = self.fc(y).view(num_batch, num_channel, 1, 1)
+ return x * y
+
+ if self.with_cp and x.requires_grad:
+ out = cp.checkpoint(_inner_forward, x)
+ else:
+ out = _inner_forward(x)
+
+ return out
+
+
+class ContextGuidedBlock(nn.Module):
+ """Context Guided Block for CGNet.
+
+ This class consists of four components: local feature extractor,
+ surrounding feature extractor, joint feature extractor and global
+ context extractor.
+
+ Args:
+ in_channels (int): Number of input feature channels.
+ out_channels (int): Number of output feature channels.
+ dilation (int): Dilation rate for surrounding context extractor.
+ Default: 2.
+ reduction (int): Reduction for global context extractor. Default: 16.
+ skip_connect (bool): Add input to output or not. Default: True.
+ downsample (bool): Downsample the input to 1/2 or not. Default: False.
+ conv_cfg (dict): Config dict for convolution layer.
+ Default: None, which means using conv2d.
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='BN', requires_grad=True).
+ act_cfg (dict): Config dict for activation layer.
+ Default: dict(type='PReLU').
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save some
+ memory while slowing down the training speed. Default: False.
+ """
+
+ def __init__(self,
+ in_channels,
+ out_channels,
+ dilation=2,
+ reduction=16,
+ skip_connect=True,
+ downsample=False,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN', requires_grad=True),
+ act_cfg=dict(type='PReLU'),
+ with_cp=False):
+ super(ContextGuidedBlock, self).__init__()
+ self.with_cp = with_cp
+ self.downsample = downsample
+
+ channels = out_channels if downsample else out_channels // 2
+ if 'type' in act_cfg and act_cfg['type'] == 'PReLU':
+ act_cfg['num_parameters'] = channels
+ kernel_size = 3 if downsample else 1
+ stride = 2 if downsample else 1
+ padding = (kernel_size - 1) // 2
+
+ self.conv1x1 = ConvModule(
+ in_channels,
+ channels,
+ kernel_size,
+ stride,
+ padding,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+
+ self.f_loc = build_conv_layer(
+ conv_cfg,
+ channels,
+ channels,
+ kernel_size=3,
+ padding=1,
+ groups=channels,
+ bias=False)
+ self.f_sur = build_conv_layer(
+ conv_cfg,
+ channels,
+ channels,
+ kernel_size=3,
+ padding=dilation,
+ groups=channels,
+ dilation=dilation,
+ bias=False)
+
+ self.bn = build_norm_layer(norm_cfg, 2 * channels)[1]
+ self.activate = nn.PReLU(2 * channels)
+
+ if downsample:
+ self.bottleneck = build_conv_layer(
+ conv_cfg,
+ 2 * channels,
+ out_channels,
+ kernel_size=1,
+ bias=False)
+
+ self.skip_connect = skip_connect and not downsample
+ self.f_glo = GlobalContextExtractor(out_channels, reduction, with_cp)
+
+ def forward(self, x):
+
+ def _inner_forward(x):
+ out = self.conv1x1(x)
+ loc = self.f_loc(out)
+ sur = self.f_sur(out)
+
+ joi_feat = torch.cat([loc, sur], 1) # the joint feature
+ joi_feat = self.bn(joi_feat)
+ joi_feat = self.activate(joi_feat)
+ if self.downsample:
+ joi_feat = self.bottleneck(joi_feat) # channel = out_channels
+ # f_glo is employed to refine the joint feature
+ out = self.f_glo(joi_feat)
+
+ if self.skip_connect:
+ return x + out
+ else:
+ return out
+
+ if self.with_cp and x.requires_grad:
+ out = cp.checkpoint(_inner_forward, x)
+ else:
+ out = _inner_forward(x)
+
+ return out
+
+
+class InputInjection(nn.Module):
+ """Downsampling module for CGNet."""
+
+ def __init__(self, num_downsampling):
+ super(InputInjection, self).__init__()
+ self.pool = nn.ModuleList()
+ for i in range(num_downsampling):
+ self.pool.append(nn.AvgPool2d(3, stride=2, padding=1))
+
+ def forward(self, x):
+ for pool in self.pool:
+ x = pool(x)
+ return x
+
+
+@BACKBONES.register_module()
+class CGNet(BaseModule):
+ """CGNet backbone.
+
+ This backbone is the implementation of `A Light-weight Context Guided
+ Network for Semantic Segmentation `_.
+
+ Args:
+ in_channels (int): Number of input image channels. Normally 3.
+ num_channels (tuple[int]): Numbers of feature channels at each stages.
+ Default: (32, 64, 128).
+ num_blocks (tuple[int]): Numbers of CG blocks at stage 1 and stage 2.
+ Default: (3, 21).
+ dilations (tuple[int]): Dilation rate for surrounding context
+ extractors at stage 1 and stage 2. Default: (2, 4).
+ reductions (tuple[int]): Reductions for global context extractors at
+ stage 1 and stage 2. Default: (8, 16).
+ conv_cfg (dict): Config dict for convolution layer.
+ Default: None, which means using conv2d.
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='BN', requires_grad=True).
+ act_cfg (dict): Config dict for activation layer.
+ Default: dict(type='PReLU').
+ norm_eval (bool): Whether to set norm layers to eval mode, namely,
+ freeze running stats (mean and var). Note: Effect on Batch Norm
+ and its variants only. Default: False.
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save some
+ memory while slowing down the training speed. Default: False.
+ pretrained (str, optional): model pretrained path. Default: None
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None
+ """
+
+ def __init__(self,
+ in_channels=3,
+ num_channels=(32, 64, 128),
+ num_blocks=(3, 21),
+ dilations=(2, 4),
+ reductions=(8, 16),
+ conv_cfg=None,
+ norm_cfg=dict(type='BN', requires_grad=True),
+ act_cfg=dict(type='PReLU'),
+ norm_eval=False,
+ with_cp=False,
+ pretrained=None,
+ init_cfg=None):
+
+ super(CGNet, self).__init__(init_cfg)
+
+ assert not (init_cfg and pretrained), \
+ 'init_cfg and pretrained cannot be setting at the same time'
+ if isinstance(pretrained, str):
+ warnings.warn('DeprecationWarning: pretrained is a deprecated, '
+ 'please use "init_cfg" instead')
+ self.init_cfg = dict(type='Pretrained', checkpoint=pretrained)
+ elif pretrained is None:
+ if init_cfg is None:
+ self.init_cfg = [
+ dict(type='Kaiming', layer=['Conv2d', 'Linear']),
+ dict(
+ type='Constant',
+ val=1,
+ layer=['_BatchNorm', 'GroupNorm']),
+ dict(type='Constant', val=0, layer='PReLU')
+ ]
+ else:
+ raise TypeError('pretrained must be a str or None')
+
+ self.in_channels = in_channels
+ self.num_channels = num_channels
+ assert isinstance(self.num_channels, tuple) and len(
+ self.num_channels) == 3
+ self.num_blocks = num_blocks
+ assert isinstance(self.num_blocks, tuple) and len(self.num_blocks) == 2
+ self.dilations = dilations
+ assert isinstance(self.dilations, tuple) and len(self.dilations) == 2
+ self.reductions = reductions
+ assert isinstance(self.reductions, tuple) and len(self.reductions) == 2
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+ if 'type' in self.act_cfg and self.act_cfg['type'] == 'PReLU':
+ self.act_cfg['num_parameters'] = num_channels[0]
+ self.norm_eval = norm_eval
+ self.with_cp = with_cp
+
+ cur_channels = in_channels
+ self.stem = nn.ModuleList()
+ for i in range(3):
+ self.stem.append(
+ ConvModule(
+ cur_channels,
+ num_channels[0],
+ 3,
+ 2 if i == 0 else 1,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg))
+ cur_channels = num_channels[0]
+
+ self.inject_2x = InputInjection(1) # down-sample for Input, factor=2
+ self.inject_4x = InputInjection(2) # down-sample for Input, factor=4
+
+ cur_channels += in_channels
+ self.norm_prelu_0 = nn.Sequential(
+ build_norm_layer(norm_cfg, cur_channels)[1],
+ nn.PReLU(cur_channels))
+
+ # stage 1
+ self.level1 = nn.ModuleList()
+ for i in range(num_blocks[0]):
+ self.level1.append(
+ ContextGuidedBlock(
+ cur_channels if i == 0 else num_channels[1],
+ num_channels[1],
+ dilations[0],
+ reductions[0],
+ downsample=(i == 0),
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg,
+ with_cp=with_cp)) # CG block
+
+ cur_channels = 2 * num_channels[1] + in_channels
+ self.norm_prelu_1 = nn.Sequential(
+ build_norm_layer(norm_cfg, cur_channels)[1],
+ nn.PReLU(cur_channels))
+
+ # stage 2
+ self.level2 = nn.ModuleList()
+ for i in range(num_blocks[1]):
+ self.level2.append(
+ ContextGuidedBlock(
+ cur_channels if i == 0 else num_channels[2],
+ num_channels[2],
+ dilations[1],
+ reductions[1],
+ downsample=(i == 0),
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg,
+ with_cp=with_cp)) # CG block
+
+ cur_channels = 2 * num_channels[2]
+ self.norm_prelu_2 = nn.Sequential(
+ build_norm_layer(norm_cfg, cur_channels)[1],
+ nn.PReLU(cur_channels))
+
+ def forward(self, x):
+ output = []
+
+ # stage 0
+ inp_2x = self.inject_2x(x)
+ inp_4x = self.inject_4x(x)
+ for layer in self.stem:
+ x = layer(x)
+ x = self.norm_prelu_0(torch.cat([x, inp_2x], 1))
+ output.append(x)
+
+ # stage 1
+ for i, layer in enumerate(self.level1):
+ x = layer(x)
+ if i == 0:
+ down1 = x
+ x = self.norm_prelu_1(torch.cat([x, down1, inp_4x], 1))
+ output.append(x)
+
+ # stage 2
+ for i, layer in enumerate(self.level2):
+ x = layer(x)
+ if i == 0:
+ down2 = x
+ x = self.norm_prelu_2(torch.cat([down2, x], 1))
+ output.append(x)
+
+ return output
+
+ def train(self, mode=True):
+ """Convert the model into training mode will keeping the normalization
+ layer freezed."""
+ super(CGNet, self).train(mode)
+ if mode and self.norm_eval:
+ for m in self.modules():
+ # trick: eval have effect on BatchNorm only
+ if isinstance(m, _BatchNorm):
+ m.eval()
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/erfnet.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/erfnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..8921c18f3cc30bf8104ae31f53fb70470e12d30b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/erfnet.py
@@ -0,0 +1,329 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+from mmcv.cnn import build_activation_layer, build_conv_layer, build_norm_layer
+from mmcv.runner import BaseModule
+
+from mmseg.ops import resize
+from ..builder import BACKBONES
+
+
+class DownsamplerBlock(BaseModule):
+ """Downsampler block of ERFNet.
+
+ This module is a little different from basical ConvModule.
+ The features from Conv and MaxPool layers are
+ concatenated before BatchNorm.
+
+ Args:
+ in_channels (int): Number of input channels.
+ out_channels (int): Number of output channels.
+ conv_cfg (dict | None): Config of conv layers.
+ Default: None.
+ norm_cfg (dict | None): Config of norm layers.
+ Default: dict(type='BN').
+ act_cfg (dict): Config of activation layers.
+ Default: dict(type='ReLU').
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ """
+
+ def __init__(self,
+ in_channels,
+ out_channels,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN', eps=1e-3),
+ act_cfg=dict(type='ReLU'),
+ init_cfg=None):
+ super(DownsamplerBlock, self).__init__(init_cfg=init_cfg)
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+
+ self.conv = build_conv_layer(
+ self.conv_cfg,
+ in_channels,
+ out_channels - in_channels,
+ kernel_size=3,
+ stride=2,
+ padding=1)
+ self.pool = nn.MaxPool2d(kernel_size=2, stride=2)
+ self.bn = build_norm_layer(self.norm_cfg, out_channels)[1]
+ self.act = build_activation_layer(self.act_cfg)
+
+ def forward(self, input):
+ conv_out = self.conv(input)
+ pool_out = self.pool(input)
+ pool_out = resize(
+ input=pool_out,
+ size=conv_out.size()[2:],
+ mode='bilinear',
+ align_corners=False)
+ output = torch.cat([conv_out, pool_out], 1)
+ output = self.bn(output)
+ output = self.act(output)
+ return output
+
+
+class NonBottleneck1d(BaseModule):
+ """Non-bottleneck block of ERFNet.
+
+ Args:
+ channels (int): Number of channels in Non-bottleneck block.
+ drop_rate (float): Probability of an element to be zeroed.
+ Default 0.
+ dilation (int): Dilation rate for last two conv layers.
+ Default 1.
+ num_conv_layer (int): Number of 3x1 and 1x3 convolution layers.
+ Default 2.
+ conv_cfg (dict | None): Config of conv layers.
+ Default: None.
+ norm_cfg (dict | None): Config of norm layers.
+ Default: dict(type='BN').
+ act_cfg (dict): Config of activation layers.
+ Default: dict(type='ReLU').
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ """
+
+ def __init__(self,
+ channels,
+ drop_rate=0,
+ dilation=1,
+ num_conv_layer=2,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN', eps=1e-3),
+ act_cfg=dict(type='ReLU'),
+ init_cfg=None):
+ super(NonBottleneck1d, self).__init__(init_cfg=init_cfg)
+
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+ self.act = build_activation_layer(self.act_cfg)
+
+ self.convs_layers = nn.ModuleList()
+ for conv_layer in range(num_conv_layer):
+ first_conv_padding = (1, 0) if conv_layer == 0 else (dilation, 0)
+ first_conv_dilation = 1 if conv_layer == 0 else (dilation, 1)
+ second_conv_padding = (0, 1) if conv_layer == 0 else (0, dilation)
+ second_conv_dilation = 1 if conv_layer == 0 else (1, dilation)
+
+ self.convs_layers.append(
+ build_conv_layer(
+ self.conv_cfg,
+ channels,
+ channels,
+ kernel_size=(3, 1),
+ stride=1,
+ padding=first_conv_padding,
+ bias=True,
+ dilation=first_conv_dilation))
+ self.convs_layers.append(self.act)
+ self.convs_layers.append(
+ build_conv_layer(
+ self.conv_cfg,
+ channels,
+ channels,
+ kernel_size=(1, 3),
+ stride=1,
+ padding=second_conv_padding,
+ bias=True,
+ dilation=second_conv_dilation))
+ self.convs_layers.append(
+ build_norm_layer(self.norm_cfg, channels)[1])
+ if conv_layer == 0:
+ self.convs_layers.append(self.act)
+ else:
+ self.convs_layers.append(nn.Dropout(p=drop_rate))
+
+ def forward(self, input):
+ output = input
+ for conv in self.convs_layers:
+ output = conv(output)
+ output = self.act(output + input)
+ return output
+
+
+class UpsamplerBlock(BaseModule):
+ """Upsampler block of ERFNet.
+
+ Args:
+ in_channels (int): Number of input channels.
+ out_channels (int): Number of output channels.
+ conv_cfg (dict | None): Config of conv layers.
+ Default: None.
+ norm_cfg (dict | None): Config of norm layers.
+ Default: dict(type='BN').
+ act_cfg (dict): Config of activation layers.
+ Default: dict(type='ReLU').
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ """
+
+ def __init__(self,
+ in_channels,
+ out_channels,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN', eps=1e-3),
+ act_cfg=dict(type='ReLU'),
+ init_cfg=None):
+ super(UpsamplerBlock, self).__init__(init_cfg=init_cfg)
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+
+ self.conv = nn.ConvTranspose2d(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ output_padding=1,
+ bias=True)
+ self.bn = build_norm_layer(self.norm_cfg, out_channels)[1]
+ self.act = build_activation_layer(self.act_cfg)
+
+ def forward(self, input):
+ output = self.conv(input)
+ output = self.bn(output)
+ output = self.act(output)
+ return output
+
+
+@BACKBONES.register_module()
+class ERFNet(BaseModule):
+ """ERFNet backbone.
+
+ This backbone is the implementation of `ERFNet: Efficient Residual
+ Factorized ConvNet for Real-time SemanticSegmentation
+ `_.
+
+ Args:
+ in_channels (int): The number of channels of input
+ image. Default: 3.
+ enc_downsample_channels (Tuple[int]): Size of channel
+ numbers of various Downsampler block in encoder.
+ Default: (16, 64, 128).
+ enc_stage_non_bottlenecks (Tuple[int]): Number of stages of
+ Non-bottleneck block in encoder.
+ Default: (5, 8).
+ enc_non_bottleneck_dilations (Tuple[int]): Dilation rate of each
+ stage of Non-bottleneck block of encoder.
+ Default: (2, 4, 8, 16).
+ enc_non_bottleneck_channels (Tuple[int]): Size of channel
+ numbers of various Non-bottleneck block in encoder.
+ Default: (64, 128).
+ dec_upsample_channels (Tuple[int]): Size of channel numbers of
+ various Deconvolution block in decoder.
+ Default: (64, 16).
+ dec_stages_non_bottleneck (Tuple[int]): Number of stages of
+ Non-bottleneck block in decoder.
+ Default: (2, 2).
+ dec_non_bottleneck_channels (Tuple[int]): Size of channel
+ numbers of various Non-bottleneck block in decoder.
+ Default: (64, 16).
+ drop_rate (float): Probability of an element to be zeroed.
+ Default 0.1.
+ """
+
+ def __init__(self,
+ in_channels=3,
+ enc_downsample_channels=(16, 64, 128),
+ enc_stage_non_bottlenecks=(5, 8),
+ enc_non_bottleneck_dilations=(2, 4, 8, 16),
+ enc_non_bottleneck_channels=(64, 128),
+ dec_upsample_channels=(64, 16),
+ dec_stages_non_bottleneck=(2, 2),
+ dec_non_bottleneck_channels=(64, 16),
+ dropout_ratio=0.1,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN', requires_grad=True),
+ act_cfg=dict(type='ReLU'),
+ init_cfg=None):
+
+ super(ERFNet, self).__init__(init_cfg=init_cfg)
+ assert len(enc_downsample_channels) \
+ == len(dec_upsample_channels)+1, 'Number of downsample\
+ block of encoder does not \
+ match number of upsample block of decoder!'
+ assert len(enc_downsample_channels) \
+ == len(enc_stage_non_bottlenecks)+1, 'Number of \
+ downsample block of encoder does not match \
+ number of Non-bottleneck block of encoder!'
+ assert len(enc_downsample_channels) \
+ == len(enc_non_bottleneck_channels)+1, 'Number of \
+ downsample block of encoder does not match \
+ number of channels of Non-bottleneck block of encoder!'
+ assert enc_stage_non_bottlenecks[-1] \
+ % len(enc_non_bottleneck_dilations) == 0, 'Number of \
+ Non-bottleneck block of encoder does not match \
+ number of Non-bottleneck block of encoder!'
+ assert len(dec_upsample_channels) \
+ == len(dec_stages_non_bottleneck), 'Number of \
+ upsample block of decoder does not match \
+ number of Non-bottleneck block of decoder!'
+ assert len(dec_stages_non_bottleneck) \
+ == len(dec_non_bottleneck_channels), 'Number of \
+ Non-bottleneck block of decoder does not match \
+ number of channels of Non-bottleneck block of decoder!'
+
+ self.in_channels = in_channels
+ self.enc_downsample_channels = enc_downsample_channels
+ self.enc_stage_non_bottlenecks = enc_stage_non_bottlenecks
+ self.enc_non_bottleneck_dilations = enc_non_bottleneck_dilations
+ self.enc_non_bottleneck_channels = enc_non_bottleneck_channels
+ self.dec_upsample_channels = dec_upsample_channels
+ self.dec_stages_non_bottleneck = dec_stages_non_bottleneck
+ self.dec_non_bottleneck_channels = dec_non_bottleneck_channels
+ self.dropout_ratio = dropout_ratio
+
+ self.encoder = nn.ModuleList()
+ self.decoder = nn.ModuleList()
+
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+
+ self.encoder.append(
+ DownsamplerBlock(self.in_channels, enc_downsample_channels[0]))
+
+ for i in range(len(enc_downsample_channels) - 1):
+ self.encoder.append(
+ DownsamplerBlock(enc_downsample_channels[i],
+ enc_downsample_channels[i + 1]))
+ # Last part of encoder is some dilated NonBottleneck1d blocks.
+ if i == len(enc_downsample_channels) - 2:
+ iteration_times = int(enc_stage_non_bottlenecks[-1] /
+ len(enc_non_bottleneck_dilations))
+ for j in range(iteration_times):
+ for k in range(len(enc_non_bottleneck_dilations)):
+ self.encoder.append(
+ NonBottleneck1d(enc_downsample_channels[-1],
+ self.dropout_ratio,
+ enc_non_bottleneck_dilations[k]))
+ else:
+ for j in range(enc_stage_non_bottlenecks[i]):
+ self.encoder.append(
+ NonBottleneck1d(enc_downsample_channels[i + 1],
+ self.dropout_ratio))
+
+ for i in range(len(dec_upsample_channels)):
+ if i == 0:
+ self.decoder.append(
+ UpsamplerBlock(enc_downsample_channels[-1],
+ dec_non_bottleneck_channels[i]))
+ else:
+ self.decoder.append(
+ UpsamplerBlock(dec_non_bottleneck_channels[i - 1],
+ dec_non_bottleneck_channels[i]))
+ for j in range(dec_stages_non_bottleneck[i]):
+ self.decoder.append(
+ NonBottleneck1d(dec_non_bottleneck_channels[i]))
+
+ def forward(self, x):
+ for enc in self.encoder:
+ x = enc(x)
+ for dec in self.decoder:
+ x = dec(x)
+ return [x]
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/fast_scnn.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/fast_scnn.py
new file mode 100644
index 0000000000000000000000000000000000000000..cbfbcaf4f3bf508098a281cffa87f94bd1bdd47c
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/fast_scnn.py
@@ -0,0 +1,409 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+from mmcv.cnn import ConvModule, DepthwiseSeparableConvModule
+from mmcv.runner import BaseModule
+
+from mmseg.models.decode_heads.psp_head import PPM
+from mmseg.ops import resize
+from ..builder import BACKBONES
+from ..utils import InvertedResidual
+
+
+class LearningToDownsample(nn.Module):
+ """Learning to downsample module.
+
+ Args:
+ in_channels (int): Number of input channels.
+ dw_channels (tuple[int]): Number of output channels of the first and
+ the second depthwise conv (dwconv) layers.
+ out_channels (int): Number of output channels of the whole
+ 'learning to downsample' module.
+ conv_cfg (dict | None): Config of conv layers. Default: None
+ norm_cfg (dict | None): Config of norm layers. Default:
+ dict(type='BN')
+ act_cfg (dict): Config of activation layers. Default:
+ dict(type='ReLU')
+ dw_act_cfg (dict): In DepthwiseSeparableConvModule, activation config
+ of depthwise ConvModule. If it is 'default', it will be the same
+ as `act_cfg`. Default: None.
+ """
+
+ def __init__(self,
+ in_channels,
+ dw_channels,
+ out_channels,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ dw_act_cfg=None):
+ super(LearningToDownsample, self).__init__()
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+ self.dw_act_cfg = dw_act_cfg
+ dw_channels1 = dw_channels[0]
+ dw_channels2 = dw_channels[1]
+
+ self.conv = ConvModule(
+ in_channels,
+ dw_channels1,
+ 3,
+ stride=2,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ self.dsconv1 = DepthwiseSeparableConvModule(
+ dw_channels1,
+ dw_channels2,
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ norm_cfg=self.norm_cfg,
+ dw_act_cfg=self.dw_act_cfg)
+
+ self.dsconv2 = DepthwiseSeparableConvModule(
+ dw_channels2,
+ out_channels,
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ norm_cfg=self.norm_cfg,
+ dw_act_cfg=self.dw_act_cfg)
+
+ def forward(self, x):
+ x = self.conv(x)
+ x = self.dsconv1(x)
+ x = self.dsconv2(x)
+ return x
+
+
+class GlobalFeatureExtractor(nn.Module):
+ """Global feature extractor module.
+
+ Args:
+ in_channels (int): Number of input channels of the GFE module.
+ Default: 64
+ block_channels (tuple[int]): Tuple of ints. Each int specifies the
+ number of output channels of each Inverted Residual module.
+ Default: (64, 96, 128)
+ out_channels(int): Number of output channels of the GFE module.
+ Default: 128
+ expand_ratio (int): Adjusts number of channels of the hidden layer
+ in InvertedResidual by this amount.
+ Default: 6
+ num_blocks (tuple[int]): Tuple of ints. Each int specifies the
+ number of times each Inverted Residual module is repeated.
+ The repeated Inverted Residual modules are called a 'group'.
+ Default: (3, 3, 3)
+ strides (tuple[int]): Tuple of ints. Each int specifies
+ the downsampling factor of each 'group'.
+ Default: (2, 2, 1)
+ pool_scales (tuple[int]): Tuple of ints. Each int specifies
+ the parameter required in 'global average pooling' within PPM.
+ Default: (1, 2, 3, 6)
+ conv_cfg (dict | None): Config of conv layers. Default: None
+ norm_cfg (dict | None): Config of norm layers. Default:
+ dict(type='BN')
+ act_cfg (dict): Config of activation layers. Default:
+ dict(type='ReLU')
+ align_corners (bool): align_corners argument of F.interpolate.
+ Default: False
+ """
+
+ def __init__(self,
+ in_channels=64,
+ block_channels=(64, 96, 128),
+ out_channels=128,
+ expand_ratio=6,
+ num_blocks=(3, 3, 3),
+ strides=(2, 2, 1),
+ pool_scales=(1, 2, 3, 6),
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ align_corners=False):
+ super(GlobalFeatureExtractor, self).__init__()
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+ assert len(block_channels) == len(num_blocks) == 3
+ self.bottleneck1 = self._make_layer(in_channels, block_channels[0],
+ num_blocks[0], strides[0],
+ expand_ratio)
+ self.bottleneck2 = self._make_layer(block_channels[0],
+ block_channels[1], num_blocks[1],
+ strides[1], expand_ratio)
+ self.bottleneck3 = self._make_layer(block_channels[1],
+ block_channels[2], num_blocks[2],
+ strides[2], expand_ratio)
+ self.ppm = PPM(
+ pool_scales,
+ block_channels[2],
+ block_channels[2] // 4,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg,
+ align_corners=align_corners)
+
+ self.out = ConvModule(
+ block_channels[2] * 2,
+ out_channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ def _make_layer(self,
+ in_channels,
+ out_channels,
+ blocks,
+ stride=1,
+ expand_ratio=6):
+ layers = [
+ InvertedResidual(
+ in_channels,
+ out_channels,
+ stride,
+ expand_ratio,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ ]
+ for i in range(1, blocks):
+ layers.append(
+ InvertedResidual(
+ out_channels,
+ out_channels,
+ 1,
+ expand_ratio,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg))
+ return nn.Sequential(*layers)
+
+ def forward(self, x):
+ x = self.bottleneck1(x)
+ x = self.bottleneck2(x)
+ x = self.bottleneck3(x)
+ x = torch.cat([x, *self.ppm(x)], dim=1)
+ x = self.out(x)
+ return x
+
+
+class FeatureFusionModule(nn.Module):
+ """Feature fusion module.
+
+ Args:
+ higher_in_channels (int): Number of input channels of the
+ higher-resolution branch.
+ lower_in_channels (int): Number of input channels of the
+ lower-resolution branch.
+ out_channels (int): Number of output channels.
+ conv_cfg (dict | None): Config of conv layers. Default: None
+ norm_cfg (dict | None): Config of norm layers. Default:
+ dict(type='BN')
+ dwconv_act_cfg (dict): Config of activation layers in 3x3 conv.
+ Default: dict(type='ReLU').
+ conv_act_cfg (dict): Config of activation layers in the two 1x1 conv.
+ Default: None.
+ align_corners (bool): align_corners argument of F.interpolate.
+ Default: False.
+ """
+
+ def __init__(self,
+ higher_in_channels,
+ lower_in_channels,
+ out_channels,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ dwconv_act_cfg=dict(type='ReLU'),
+ conv_act_cfg=None,
+ align_corners=False):
+ super(FeatureFusionModule, self).__init__()
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.dwconv_act_cfg = dwconv_act_cfg
+ self.conv_act_cfg = conv_act_cfg
+ self.align_corners = align_corners
+ self.dwconv = ConvModule(
+ lower_in_channels,
+ out_channels,
+ 3,
+ padding=1,
+ groups=out_channels,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.dwconv_act_cfg)
+ self.conv_lower_res = ConvModule(
+ out_channels,
+ out_channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.conv_act_cfg)
+
+ self.conv_higher_res = ConvModule(
+ higher_in_channels,
+ out_channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.conv_act_cfg)
+
+ self.relu = nn.ReLU(True)
+
+ def forward(self, higher_res_feature, lower_res_feature):
+ lower_res_feature = resize(
+ lower_res_feature,
+ size=higher_res_feature.size()[2:],
+ mode='bilinear',
+ align_corners=self.align_corners)
+ lower_res_feature = self.dwconv(lower_res_feature)
+ lower_res_feature = self.conv_lower_res(lower_res_feature)
+
+ higher_res_feature = self.conv_higher_res(higher_res_feature)
+ out = higher_res_feature + lower_res_feature
+ return self.relu(out)
+
+
+@BACKBONES.register_module()
+class FastSCNN(BaseModule):
+ """Fast-SCNN Backbone.
+
+ This backbone is the implementation of `Fast-SCNN: Fast Semantic
+ Segmentation Network `_.
+
+ Args:
+ in_channels (int): Number of input image channels. Default: 3.
+ downsample_dw_channels (tuple[int]): Number of output channels after
+ the first conv layer & the second conv layer in
+ Learning-To-Downsample (LTD) module.
+ Default: (32, 48).
+ global_in_channels (int): Number of input channels of
+ Global Feature Extractor(GFE).
+ Equal to number of output channels of LTD.
+ Default: 64.
+ global_block_channels (tuple[int]): Tuple of integers that describe
+ the output channels for each of the MobileNet-v2 bottleneck
+ residual blocks in GFE.
+ Default: (64, 96, 128).
+ global_block_strides (tuple[int]): Tuple of integers
+ that describe the strides (downsampling factors) for each of the
+ MobileNet-v2 bottleneck residual blocks in GFE.
+ Default: (2, 2, 1).
+ global_out_channels (int): Number of output channels of GFE.
+ Default: 128.
+ higher_in_channels (int): Number of input channels of the higher
+ resolution branch in FFM.
+ Equal to global_in_channels.
+ Default: 64.
+ lower_in_channels (int): Number of input channels of the lower
+ resolution branch in FFM.
+ Equal to global_out_channels.
+ Default: 128.
+ fusion_out_channels (int): Number of output channels of FFM.
+ Default: 128.
+ out_indices (tuple): Tuple of indices of list
+ [higher_res_features, lower_res_features, fusion_output].
+ Often set to (0,1,2) to enable aux. heads.
+ Default: (0, 1, 2).
+ conv_cfg (dict | None): Config of conv layers. Default: None
+ norm_cfg (dict | None): Config of norm layers. Default:
+ dict(type='BN')
+ act_cfg (dict): Config of activation layers. Default:
+ dict(type='ReLU')
+ align_corners (bool): align_corners argument of F.interpolate.
+ Default: False
+ dw_act_cfg (dict): In DepthwiseSeparableConvModule, activation config
+ of depthwise ConvModule. If it is 'default', it will be the same
+ as `act_cfg`. Default: None.
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None
+ """
+
+ def __init__(self,
+ in_channels=3,
+ downsample_dw_channels=(32, 48),
+ global_in_channels=64,
+ global_block_channels=(64, 96, 128),
+ global_block_strides=(2, 2, 1),
+ global_out_channels=128,
+ higher_in_channels=64,
+ lower_in_channels=128,
+ fusion_out_channels=128,
+ out_indices=(0, 1, 2),
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ align_corners=False,
+ dw_act_cfg=None,
+ init_cfg=None):
+
+ super(FastSCNN, self).__init__(init_cfg)
+
+ if init_cfg is None:
+ self.init_cfg = [
+ dict(type='Kaiming', layer='Conv2d'),
+ dict(
+ type='Constant', val=1, layer=['_BatchNorm', 'GroupNorm'])
+ ]
+
+ if global_in_channels != higher_in_channels:
+ raise AssertionError('Global Input Channels must be the same \
+ with Higher Input Channels!')
+ elif global_out_channels != lower_in_channels:
+ raise AssertionError('Global Output Channels must be the same \
+ with Lower Input Channels!')
+
+ self.in_channels = in_channels
+ self.downsample_dw_channels1 = downsample_dw_channels[0]
+ self.downsample_dw_channels2 = downsample_dw_channels[1]
+ self.global_in_channels = global_in_channels
+ self.global_block_channels = global_block_channels
+ self.global_block_strides = global_block_strides
+ self.global_out_channels = global_out_channels
+ self.higher_in_channels = higher_in_channels
+ self.lower_in_channels = lower_in_channels
+ self.fusion_out_channels = fusion_out_channels
+ self.out_indices = out_indices
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+ self.align_corners = align_corners
+ self.learning_to_downsample = LearningToDownsample(
+ in_channels,
+ downsample_dw_channels,
+ global_in_channels,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg,
+ dw_act_cfg=dw_act_cfg)
+ self.global_feature_extractor = GlobalFeatureExtractor(
+ global_in_channels,
+ global_block_channels,
+ global_out_channels,
+ strides=self.global_block_strides,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg,
+ align_corners=self.align_corners)
+ self.feature_fusion = FeatureFusionModule(
+ higher_in_channels,
+ lower_in_channels,
+ fusion_out_channels,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ dwconv_act_cfg=self.act_cfg,
+ align_corners=self.align_corners)
+
+ def forward(self, x):
+ higher_res_features = self.learning_to_downsample(x)
+ lower_res_features = self.global_feature_extractor(higher_res_features)
+ fusion_output = self.feature_fusion(higher_res_features,
+ lower_res_features)
+
+ outs = [higher_res_features, lower_res_features, fusion_output]
+ outs = [outs[i] for i in self.out_indices]
+ return tuple(outs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/hrnet.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/hrnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..90feadcf62798f7b7a5e9fdddd0e2202687cc113
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/hrnet.py
@@ -0,0 +1,642 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import warnings
+
+import torch.nn as nn
+from mmcv.cnn import build_conv_layer, build_norm_layer
+from mmcv.runner import BaseModule, ModuleList, Sequential
+from mmcv.utils.parrots_wrapper import _BatchNorm
+
+from mmseg.ops import Upsample, resize
+from ..builder import BACKBONES
+from .resnet import BasicBlock, Bottleneck
+
+
+class HRModule(BaseModule):
+ """High-Resolution Module for HRNet.
+
+ In this module, every branch has 4 BasicBlocks/Bottlenecks. Fusion/Exchange
+ is in this module.
+ """
+
+ def __init__(self,
+ num_branches,
+ blocks,
+ num_blocks,
+ in_channels,
+ num_channels,
+ multiscale_output=True,
+ with_cp=False,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN', requires_grad=True),
+ block_init_cfg=None,
+ init_cfg=None):
+ super(HRModule, self).__init__(init_cfg)
+ self.block_init_cfg = block_init_cfg
+ self._check_branches(num_branches, num_blocks, in_channels,
+ num_channels)
+
+ self.in_channels = in_channels
+ self.num_branches = num_branches
+
+ self.multiscale_output = multiscale_output
+ self.norm_cfg = norm_cfg
+ self.conv_cfg = conv_cfg
+ self.with_cp = with_cp
+ self.branches = self._make_branches(num_branches, blocks, num_blocks,
+ num_channels)
+ self.fuse_layers = self._make_fuse_layers()
+ self.relu = nn.ReLU(inplace=False)
+
+ def _check_branches(self, num_branches, num_blocks, in_channels,
+ num_channels):
+ """Check branches configuration."""
+ if num_branches != len(num_blocks):
+ error_msg = f'NUM_BRANCHES({num_branches}) <> NUM_BLOCKS(' \
+ f'{len(num_blocks)})'
+ raise ValueError(error_msg)
+
+ if num_branches != len(num_channels):
+ error_msg = f'NUM_BRANCHES({num_branches}) <> NUM_CHANNELS(' \
+ f'{len(num_channels)})'
+ raise ValueError(error_msg)
+
+ if num_branches != len(in_channels):
+ error_msg = f'NUM_BRANCHES({num_branches}) <> NUM_INCHANNELS(' \
+ f'{len(in_channels)})'
+ raise ValueError(error_msg)
+
+ def _make_one_branch(self,
+ branch_index,
+ block,
+ num_blocks,
+ num_channels,
+ stride=1):
+ """Build one branch."""
+ downsample = None
+ if stride != 1 or \
+ self.in_channels[branch_index] != \
+ num_channels[branch_index] * block.expansion:
+ downsample = nn.Sequential(
+ build_conv_layer(
+ self.conv_cfg,
+ self.in_channels[branch_index],
+ num_channels[branch_index] * block.expansion,
+ kernel_size=1,
+ stride=stride,
+ bias=False),
+ build_norm_layer(self.norm_cfg, num_channels[branch_index] *
+ block.expansion)[1])
+
+ layers = []
+ layers.append(
+ block(
+ self.in_channels[branch_index],
+ num_channels[branch_index],
+ stride,
+ downsample=downsample,
+ with_cp=self.with_cp,
+ norm_cfg=self.norm_cfg,
+ conv_cfg=self.conv_cfg,
+ init_cfg=self.block_init_cfg))
+ self.in_channels[branch_index] = \
+ num_channels[branch_index] * block.expansion
+ for i in range(1, num_blocks[branch_index]):
+ layers.append(
+ block(
+ self.in_channels[branch_index],
+ num_channels[branch_index],
+ with_cp=self.with_cp,
+ norm_cfg=self.norm_cfg,
+ conv_cfg=self.conv_cfg,
+ init_cfg=self.block_init_cfg))
+
+ return Sequential(*layers)
+
+ def _make_branches(self, num_branches, block, num_blocks, num_channels):
+ """Build multiple branch."""
+ branches = []
+
+ for i in range(num_branches):
+ branches.append(
+ self._make_one_branch(i, block, num_blocks, num_channels))
+
+ return ModuleList(branches)
+
+ def _make_fuse_layers(self):
+ """Build fuse layer."""
+ if self.num_branches == 1:
+ return None
+
+ num_branches = self.num_branches
+ in_channels = self.in_channels
+ fuse_layers = []
+ num_out_branches = num_branches if self.multiscale_output else 1
+ for i in range(num_out_branches):
+ fuse_layer = []
+ for j in range(num_branches):
+ if j > i:
+ fuse_layer.append(
+ nn.Sequential(
+ build_conv_layer(
+ self.conv_cfg,
+ in_channels[j],
+ in_channels[i],
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ bias=False),
+ build_norm_layer(self.norm_cfg, in_channels[i])[1],
+ # we set align_corners=False for HRNet
+ Upsample(
+ scale_factor=2**(j - i),
+ mode='bilinear',
+ align_corners=False)))
+ elif j == i:
+ fuse_layer.append(None)
+ else:
+ conv_downsamples = []
+ for k in range(i - j):
+ if k == i - j - 1:
+ conv_downsamples.append(
+ nn.Sequential(
+ build_conv_layer(
+ self.conv_cfg,
+ in_channels[j],
+ in_channels[i],
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ bias=False),
+ build_norm_layer(self.norm_cfg,
+ in_channels[i])[1]))
+ else:
+ conv_downsamples.append(
+ nn.Sequential(
+ build_conv_layer(
+ self.conv_cfg,
+ in_channels[j],
+ in_channels[j],
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ bias=False),
+ build_norm_layer(self.norm_cfg,
+ in_channels[j])[1],
+ nn.ReLU(inplace=False)))
+ fuse_layer.append(nn.Sequential(*conv_downsamples))
+ fuse_layers.append(nn.ModuleList(fuse_layer))
+
+ return nn.ModuleList(fuse_layers)
+
+ def forward(self, x):
+ """Forward function."""
+ if self.num_branches == 1:
+ return [self.branches[0](x[0])]
+
+ for i in range(self.num_branches):
+ x[i] = self.branches[i](x[i])
+
+ x_fuse = []
+ for i in range(len(self.fuse_layers)):
+ y = 0
+ for j in range(self.num_branches):
+ if i == j:
+ y += x[j]
+ elif j > i:
+ y = y + resize(
+ self.fuse_layers[i][j](x[j]),
+ size=x[i].shape[2:],
+ mode='bilinear',
+ align_corners=False)
+ else:
+ y += self.fuse_layers[i][j](x[j])
+ x_fuse.append(self.relu(y))
+ return x_fuse
+
+
+@BACKBONES.register_module()
+class HRNet(BaseModule):
+ """HRNet backbone.
+
+ This backbone is the implementation of `High-Resolution Representations
+ for Labeling Pixels and Regions `_.
+
+ Args:
+ extra (dict): Detailed configuration for each stage of HRNet.
+ There must be 4 stages, the configuration for each stage must have
+ 5 keys:
+
+ - num_modules (int): The number of HRModule in this stage.
+ - num_branches (int): The number of branches in the HRModule.
+ - block (str): The type of convolution block.
+ - num_blocks (tuple): The number of blocks in each branch.
+ The length must be equal to num_branches.
+ - num_channels (tuple): The number of channels in each branch.
+ The length must be equal to num_branches.
+ in_channels (int): Number of input image channels. Normally 3.
+ conv_cfg (dict): Dictionary to construct and config conv layer.
+ Default: None.
+ norm_cfg (dict): Dictionary to construct and config norm layer.
+ Use `BN` by default.
+ norm_eval (bool): Whether to set norm layers to eval mode, namely,
+ freeze running stats (mean and var). Note: Effect on Batch Norm
+ and its variants only. Default: False.
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save some
+ memory while slowing down the training speed. Default: False.
+ frozen_stages (int): Stages to be frozen (stop grad and set eval mode).
+ -1 means not freezing any parameters. Default: -1.
+ zero_init_residual (bool): Whether to use zero init for last norm layer
+ in resblocks to let them behave as identity. Default: False.
+ multiscale_output (bool): Whether to output multi-level features
+ produced by multiple branches. If False, only the first level
+ feature will be output. Default: True.
+ pretrained (str, optional): Model pretrained path. Default: None.
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+
+ Example:
+ >>> from mmseg.models import HRNet
+ >>> import torch
+ >>> extra = dict(
+ >>> stage1=dict(
+ >>> num_modules=1,
+ >>> num_branches=1,
+ >>> block='BOTTLENECK',
+ >>> num_blocks=(4, ),
+ >>> num_channels=(64, )),
+ >>> stage2=dict(
+ >>> num_modules=1,
+ >>> num_branches=2,
+ >>> block='BASIC',
+ >>> num_blocks=(4, 4),
+ >>> num_channels=(32, 64)),
+ >>> stage3=dict(
+ >>> num_modules=4,
+ >>> num_branches=3,
+ >>> block='BASIC',
+ >>> num_blocks=(4, 4, 4),
+ >>> num_channels=(32, 64, 128)),
+ >>> stage4=dict(
+ >>> num_modules=3,
+ >>> num_branches=4,
+ >>> block='BASIC',
+ >>> num_blocks=(4, 4, 4, 4),
+ >>> num_channels=(32, 64, 128, 256)))
+ >>> self = HRNet(extra, in_channels=1)
+ >>> self.eval()
+ >>> inputs = torch.rand(1, 1, 32, 32)
+ >>> level_outputs = self.forward(inputs)
+ >>> for level_out in level_outputs:
+ ... print(tuple(level_out.shape))
+ (1, 32, 8, 8)
+ (1, 64, 4, 4)
+ (1, 128, 2, 2)
+ (1, 256, 1, 1)
+ """
+
+ blocks_dict = {'BASIC': BasicBlock, 'BOTTLENECK': Bottleneck}
+
+ def __init__(self,
+ extra,
+ in_channels=3,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN', requires_grad=True),
+ norm_eval=False,
+ with_cp=False,
+ frozen_stages=-1,
+ zero_init_residual=False,
+ multiscale_output=True,
+ pretrained=None,
+ init_cfg=None):
+ super(HRNet, self).__init__(init_cfg)
+
+ self.pretrained = pretrained
+ self.zero_init_residual = zero_init_residual
+ assert not (init_cfg and pretrained), \
+ 'init_cfg and pretrained cannot be setting at the same time'
+ if isinstance(pretrained, str):
+ warnings.warn('DeprecationWarning: pretrained is deprecated, '
+ 'please use "init_cfg" instead')
+ self.init_cfg = dict(type='Pretrained', checkpoint=pretrained)
+ elif pretrained is None:
+ if init_cfg is None:
+ self.init_cfg = [
+ dict(type='Kaiming', layer='Conv2d'),
+ dict(
+ type='Constant',
+ val=1,
+ layer=['_BatchNorm', 'GroupNorm'])
+ ]
+ else:
+ raise TypeError('pretrained must be a str or None')
+
+ # Assert configurations of 4 stages are in extra
+ assert 'stage1' in extra and 'stage2' in extra \
+ and 'stage3' in extra and 'stage4' in extra
+ # Assert whether the length of `num_blocks` and `num_channels` are
+ # equal to `num_branches`
+ for i in range(4):
+ cfg = extra[f'stage{i + 1}']
+ assert len(cfg['num_blocks']) == cfg['num_branches'] and \
+ len(cfg['num_channels']) == cfg['num_branches']
+
+ self.extra = extra
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.norm_eval = norm_eval
+ self.with_cp = with_cp
+ self.frozen_stages = frozen_stages
+
+ # stem net
+ self.norm1_name, norm1 = build_norm_layer(self.norm_cfg, 64, postfix=1)
+ self.norm2_name, norm2 = build_norm_layer(self.norm_cfg, 64, postfix=2)
+
+ self.conv1 = build_conv_layer(
+ self.conv_cfg,
+ in_channels,
+ 64,
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ bias=False)
+
+ self.add_module(self.norm1_name, norm1)
+ self.conv2 = build_conv_layer(
+ self.conv_cfg,
+ 64,
+ 64,
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ bias=False)
+
+ self.add_module(self.norm2_name, norm2)
+ self.relu = nn.ReLU(inplace=True)
+
+ # stage 1
+ self.stage1_cfg = self.extra['stage1']
+ num_channels = self.stage1_cfg['num_channels'][0]
+ block_type = self.stage1_cfg['block']
+ num_blocks = self.stage1_cfg['num_blocks'][0]
+
+ block = self.blocks_dict[block_type]
+ stage1_out_channels = num_channels * block.expansion
+ self.layer1 = self._make_layer(block, 64, num_channels, num_blocks)
+
+ # stage 2
+ self.stage2_cfg = self.extra['stage2']
+ num_channels = self.stage2_cfg['num_channels']
+ block_type = self.stage2_cfg['block']
+
+ block = self.blocks_dict[block_type]
+ num_channels = [channel * block.expansion for channel in num_channels]
+ self.transition1 = self._make_transition_layer([stage1_out_channels],
+ num_channels)
+ self.stage2, pre_stage_channels = self._make_stage(
+ self.stage2_cfg, num_channels)
+
+ # stage 3
+ self.stage3_cfg = self.extra['stage3']
+ num_channels = self.stage3_cfg['num_channels']
+ block_type = self.stage3_cfg['block']
+
+ block = self.blocks_dict[block_type]
+ num_channels = [channel * block.expansion for channel in num_channels]
+ self.transition2 = self._make_transition_layer(pre_stage_channels,
+ num_channels)
+ self.stage3, pre_stage_channels = self._make_stage(
+ self.stage3_cfg, num_channels)
+
+ # stage 4
+ self.stage4_cfg = self.extra['stage4']
+ num_channels = self.stage4_cfg['num_channels']
+ block_type = self.stage4_cfg['block']
+
+ block = self.blocks_dict[block_type]
+ num_channels = [channel * block.expansion for channel in num_channels]
+ self.transition3 = self._make_transition_layer(pre_stage_channels,
+ num_channels)
+ self.stage4, pre_stage_channels = self._make_stage(
+ self.stage4_cfg, num_channels, multiscale_output=multiscale_output)
+
+ self._freeze_stages()
+
+ @property
+ def norm1(self):
+ """nn.Module: the normalization layer named "norm1" """
+ return getattr(self, self.norm1_name)
+
+ @property
+ def norm2(self):
+ """nn.Module: the normalization layer named "norm2" """
+ return getattr(self, self.norm2_name)
+
+ def _make_transition_layer(self, num_channels_pre_layer,
+ num_channels_cur_layer):
+ """Make transition layer."""
+ num_branches_cur = len(num_channels_cur_layer)
+ num_branches_pre = len(num_channels_pre_layer)
+
+ transition_layers = []
+ for i in range(num_branches_cur):
+ if i < num_branches_pre:
+ if num_channels_cur_layer[i] != num_channels_pre_layer[i]:
+ transition_layers.append(
+ nn.Sequential(
+ build_conv_layer(
+ self.conv_cfg,
+ num_channels_pre_layer[i],
+ num_channels_cur_layer[i],
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ bias=False),
+ build_norm_layer(self.norm_cfg,
+ num_channels_cur_layer[i])[1],
+ nn.ReLU(inplace=True)))
+ else:
+ transition_layers.append(None)
+ else:
+ conv_downsamples = []
+ for j in range(i + 1 - num_branches_pre):
+ in_channels = num_channels_pre_layer[-1]
+ out_channels = num_channels_cur_layer[i] \
+ if j == i - num_branches_pre else in_channels
+ conv_downsamples.append(
+ nn.Sequential(
+ build_conv_layer(
+ self.conv_cfg,
+ in_channels,
+ out_channels,
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ bias=False),
+ build_norm_layer(self.norm_cfg, out_channels)[1],
+ nn.ReLU(inplace=True)))
+ transition_layers.append(nn.Sequential(*conv_downsamples))
+
+ return nn.ModuleList(transition_layers)
+
+ def _make_layer(self, block, inplanes, planes, blocks, stride=1):
+ """Make each layer."""
+ downsample = None
+ if stride != 1 or inplanes != planes * block.expansion:
+ downsample = nn.Sequential(
+ build_conv_layer(
+ self.conv_cfg,
+ inplanes,
+ planes * block.expansion,
+ kernel_size=1,
+ stride=stride,
+ bias=False),
+ build_norm_layer(self.norm_cfg, planes * block.expansion)[1])
+
+ layers = []
+ block_init_cfg = None
+ if self.pretrained is None and not hasattr(
+ self, 'init_cfg') and self.zero_init_residual:
+ if block is BasicBlock:
+ block_init_cfg = dict(
+ type='Constant', val=0, override=dict(name='norm2'))
+ elif block is Bottleneck:
+ block_init_cfg = dict(
+ type='Constant', val=0, override=dict(name='norm3'))
+
+ layers.append(
+ block(
+ inplanes,
+ planes,
+ stride,
+ downsample=downsample,
+ with_cp=self.with_cp,
+ norm_cfg=self.norm_cfg,
+ conv_cfg=self.conv_cfg,
+ init_cfg=block_init_cfg))
+ inplanes = planes * block.expansion
+ for i in range(1, blocks):
+ layers.append(
+ block(
+ inplanes,
+ planes,
+ with_cp=self.with_cp,
+ norm_cfg=self.norm_cfg,
+ conv_cfg=self.conv_cfg,
+ init_cfg=block_init_cfg))
+
+ return Sequential(*layers)
+
+ def _make_stage(self, layer_config, in_channels, multiscale_output=True):
+ """Make each stage."""
+ num_modules = layer_config['num_modules']
+ num_branches = layer_config['num_branches']
+ num_blocks = layer_config['num_blocks']
+ num_channels = layer_config['num_channels']
+ block = self.blocks_dict[layer_config['block']]
+
+ hr_modules = []
+ block_init_cfg = None
+ if self.pretrained is None and not hasattr(
+ self, 'init_cfg') and self.zero_init_residual:
+ if block is BasicBlock:
+ block_init_cfg = dict(
+ type='Constant', val=0, override=dict(name='norm2'))
+ elif block is Bottleneck:
+ block_init_cfg = dict(
+ type='Constant', val=0, override=dict(name='norm3'))
+
+ for i in range(num_modules):
+ # multi_scale_output is only used for the last module
+ if not multiscale_output and i == num_modules - 1:
+ reset_multiscale_output = False
+ else:
+ reset_multiscale_output = True
+
+ hr_modules.append(
+ HRModule(
+ num_branches,
+ block,
+ num_blocks,
+ in_channels,
+ num_channels,
+ reset_multiscale_output,
+ with_cp=self.with_cp,
+ norm_cfg=self.norm_cfg,
+ conv_cfg=self.conv_cfg,
+ block_init_cfg=block_init_cfg))
+
+ return Sequential(*hr_modules), in_channels
+
+ def _freeze_stages(self):
+ """Freeze stages param and norm stats."""
+ if self.frozen_stages >= 0:
+
+ self.norm1.eval()
+ self.norm2.eval()
+ for m in [self.conv1, self.norm1, self.conv2, self.norm2]:
+ for param in m.parameters():
+ param.requires_grad = False
+
+ for i in range(1, self.frozen_stages + 1):
+ if i == 1:
+ m = getattr(self, f'layer{i}')
+ t = getattr(self, f'transition{i}')
+ elif i == 4:
+ m = getattr(self, f'stage{i}')
+ else:
+ m = getattr(self, f'stage{i}')
+ t = getattr(self, f'transition{i}')
+ m.eval()
+ for param in m.parameters():
+ param.requires_grad = False
+ t.eval()
+ for param in t.parameters():
+ param.requires_grad = False
+
+ def forward(self, x):
+ """Forward function."""
+
+ x = self.conv1(x)
+ x = self.norm1(x)
+ x = self.relu(x)
+ x = self.conv2(x)
+ x = self.norm2(x)
+ x = self.relu(x)
+ x = self.layer1(x)
+
+ x_list = []
+ for i in range(self.stage2_cfg['num_branches']):
+ if self.transition1[i] is not None:
+ x_list.append(self.transition1[i](x))
+ else:
+ x_list.append(x)
+ y_list = self.stage2(x_list)
+
+ x_list = []
+ for i in range(self.stage3_cfg['num_branches']):
+ if self.transition2[i] is not None:
+ x_list.append(self.transition2[i](y_list[-1]))
+ else:
+ x_list.append(y_list[i])
+ y_list = self.stage3(x_list)
+
+ x_list = []
+ for i in range(self.stage4_cfg['num_branches']):
+ if self.transition3[i] is not None:
+ x_list.append(self.transition3[i](y_list[-1]))
+ else:
+ x_list.append(y_list[i])
+ y_list = self.stage4(x_list)
+
+ return y_list
+
+ def train(self, mode=True):
+ """Convert the model into training mode will keeping the normalization
+ layer freezed."""
+ super(HRNet, self).train(mode)
+ self._freeze_stages()
+ if mode and self.norm_eval:
+ for m in self.modules():
+ # trick: eval have effect on BatchNorm only
+ if isinstance(m, _BatchNorm):
+ m.eval()
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/icnet.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/icnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..6faaeab01c26eca979ad47a29c07dd935124da2d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/icnet.py
@@ -0,0 +1,166 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+from mmcv.cnn import ConvModule
+from mmcv.runner import BaseModule
+
+from mmseg.ops import resize
+from ..builder import BACKBONES, build_backbone
+from ..decode_heads.psp_head import PPM
+
+
+@BACKBONES.register_module()
+class ICNet(BaseModule):
+ """ICNet for Real-Time Semantic Segmentation on High-Resolution Images.
+
+ This backbone is the implementation of
+ `ICNet `_.
+
+ Args:
+ backbone_cfg (dict): Config dict to build backbone. Usually it is
+ ResNet but it can also be other backbones.
+ in_channels (int): The number of input image channels. Default: 3.
+ layer_channels (Sequence[int]): The numbers of feature channels at
+ layer 2 and layer 4 in ResNet. It can also be other backbones.
+ Default: (512, 2048).
+ light_branch_middle_channels (int): The number of channels of the
+ middle layer in light branch. Default: 32.
+ psp_out_channels (int): The number of channels of the output of PSP
+ module. Default: 512.
+ out_channels (Sequence[int]): The numbers of output feature channels
+ at each branches. Default: (64, 256, 256).
+ pool_scales (tuple[int]): Pooling scales used in Pooling Pyramid
+ Module. Default: (1, 2, 3, 6).
+ conv_cfg (dict): Dictionary to construct and config conv layer.
+ Default: None.
+ norm_cfg (dict): Dictionary to construct and config norm layer.
+ Default: dict(type='BN').
+ act_cfg (dict): Dictionary to construct and config act layer.
+ Default: dict(type='ReLU').
+ align_corners (bool): align_corners argument of F.interpolate.
+ Default: False.
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ """
+
+ def __init__(self,
+ backbone_cfg,
+ in_channels=3,
+ layer_channels=(512, 2048),
+ light_branch_middle_channels=32,
+ psp_out_channels=512,
+ out_channels=(64, 256, 256),
+ pool_scales=(1, 2, 3, 6),
+ conv_cfg=None,
+ norm_cfg=dict(type='BN', requires_grad=True),
+ act_cfg=dict(type='ReLU'),
+ align_corners=False,
+ init_cfg=None):
+ if backbone_cfg is None:
+ raise TypeError('backbone_cfg must be passed from config file!')
+ if init_cfg is None:
+ init_cfg = [
+ dict(type='Kaiming', mode='fan_out', layer='Conv2d'),
+ dict(type='Constant', val=1, layer='_BatchNorm'),
+ dict(type='Normal', mean=0.01, layer='Linear')
+ ]
+ super(ICNet, self).__init__(init_cfg=init_cfg)
+ self.align_corners = align_corners
+ self.backbone = build_backbone(backbone_cfg)
+
+ # Note: Default `ceil_mode` is false in nn.MaxPool2d, set
+ # `ceil_mode=True` to keep information in the corner of feature map.
+ self.backbone.maxpool = nn.MaxPool2d(
+ kernel_size=3, stride=2, padding=1, ceil_mode=True)
+
+ self.psp_modules = PPM(
+ pool_scales=pool_scales,
+ in_channels=layer_channels[1],
+ channels=psp_out_channels,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg,
+ align_corners=align_corners)
+
+ self.psp_bottleneck = ConvModule(
+ layer_channels[1] + len(pool_scales) * psp_out_channels,
+ psp_out_channels,
+ 3,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+
+ self.conv_sub1 = nn.Sequential(
+ ConvModule(
+ in_channels=in_channels,
+ out_channels=light_branch_middle_channels,
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg),
+ ConvModule(
+ in_channels=light_branch_middle_channels,
+ out_channels=light_branch_middle_channels,
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg),
+ ConvModule(
+ in_channels=light_branch_middle_channels,
+ out_channels=out_channels[0],
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg))
+
+ self.conv_sub2 = ConvModule(
+ layer_channels[0],
+ out_channels[1],
+ 1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg)
+
+ self.conv_sub4 = ConvModule(
+ psp_out_channels,
+ out_channels[2],
+ 1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg)
+
+ def forward(self, x):
+ output = []
+
+ # sub 1
+ output.append(self.conv_sub1(x))
+
+ # sub 2
+ x = resize(
+ x,
+ scale_factor=0.5,
+ mode='bilinear',
+ align_corners=self.align_corners)
+ x = self.backbone.stem(x)
+ x = self.backbone.maxpool(x)
+ x = self.backbone.layer1(x)
+ x = self.backbone.layer2(x)
+ output.append(self.conv_sub2(x))
+
+ # sub 4
+ x = resize(
+ x,
+ scale_factor=0.5,
+ mode='bilinear',
+ align_corners=self.align_corners)
+ x = self.backbone.layer3(x)
+ x = self.backbone.layer4(x)
+ psp_outs = self.psp_modules(x) + [x]
+ psp_outs = torch.cat(psp_outs, dim=1)
+ x = self.psp_bottleneck(psp_outs)
+
+ output.append(self.conv_sub4(x))
+
+ return output
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/mae.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/mae.py
new file mode 100644
index 0000000000000000000000000000000000000000..d3e8754bd2bb187529d5d28ac0c6d9e66b9afb5c
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/mae.py
@@ -0,0 +1,261 @@
+# Copyright (c) OpenMMLab. All rights reserved.import math
+import math
+
+import torch
+import torch.nn as nn
+from mmcv.cnn.utils.weight_init import (constant_init, kaiming_init,
+ trunc_normal_)
+from mmcv.runner import ModuleList, _load_checkpoint
+from torch.nn.modules.batchnorm import _BatchNorm
+
+from mmseg.utils import get_root_logger
+from ..builder import BACKBONES
+from .beit import BEiT, BEiTAttention, BEiTTransformerEncoderLayer
+
+
+class MAEAttention(BEiTAttention):
+ """Multi-head self-attention with relative position bias used in MAE.
+
+ This module is different from ``BEiTAttention`` by initializing the
+ relative bias table with zeros.
+ """
+
+ def init_weights(self):
+ """Initialize relative position bias with zeros."""
+
+ # As MAE initializes relative position bias as zeros and this class
+ # inherited from BEiT which initializes relative position bias
+ # with `trunc_normal`, `init_weights` here does
+ # nothing and just passes directly
+
+ pass
+
+
+class MAETransformerEncoderLayer(BEiTTransformerEncoderLayer):
+ """Implements one encoder layer in Vision Transformer.
+
+ This module is different from ``BEiTTransformerEncoderLayer`` by replacing
+ ``BEiTAttention`` with ``MAEAttention``.
+ """
+
+ def build_attn(self, attn_cfg):
+ self.attn = MAEAttention(**attn_cfg)
+
+
+@BACKBONES.register_module()
+class MAE(BEiT):
+ """VisionTransformer with support for patch.
+
+ Args:
+ img_size (int | tuple): Input image size. Default: 224.
+ patch_size (int): The patch size. Default: 16.
+ in_channels (int): Number of input channels. Default: 3.
+ embed_dims (int): embedding dimension. Default: 768.
+ num_layers (int): depth of transformer. Default: 12.
+ num_heads (int): number of attention heads. Default: 12.
+ mlp_ratio (int): ratio of mlp hidden dim to embedding dim.
+ Default: 4.
+ out_indices (list | tuple | int): Output from which stages.
+ Default: -1.
+ attn_drop_rate (float): The drop out rate for attention layer.
+ Default 0.0
+ drop_path_rate (float): stochastic depth rate. Default 0.0.
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='LN')
+ act_cfg (dict): The activation config for FFNs.
+ Default: dict(type='GELU').
+ patch_norm (bool): Whether to add a norm in PatchEmbed Block.
+ Default: False.
+ final_norm (bool): Whether to add a additional layer to normalize
+ final feature map. Default: False.
+ num_fcs (int): The number of fully-connected layers for FFNs.
+ Default: 2.
+ norm_eval (bool): Whether to set norm layers to eval mode, namely,
+ freeze running stats (mean and var). Note: Effect on Batch Norm
+ and its variants only. Default: False.
+ pretrained (str, optional): model pretrained path. Default: None.
+ init_values (float): Initialize the values of Attention and FFN
+ with learnable scaling. Defaults to 0.1.
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ """
+
+ def __init__(self,
+ img_size=224,
+ patch_size=16,
+ in_channels=3,
+ embed_dims=768,
+ num_layers=12,
+ num_heads=12,
+ mlp_ratio=4,
+ out_indices=-1,
+ attn_drop_rate=0.,
+ drop_path_rate=0.,
+ norm_cfg=dict(type='LN'),
+ act_cfg=dict(type='GELU'),
+ patch_norm=False,
+ final_norm=False,
+ num_fcs=2,
+ norm_eval=False,
+ pretrained=None,
+ init_values=0.1,
+ init_cfg=None):
+ super(MAE, self).__init__(
+ img_size=img_size,
+ patch_size=patch_size,
+ in_channels=in_channels,
+ embed_dims=embed_dims,
+ num_layers=num_layers,
+ num_heads=num_heads,
+ mlp_ratio=mlp_ratio,
+ out_indices=out_indices,
+ qv_bias=False,
+ attn_drop_rate=attn_drop_rate,
+ drop_path_rate=drop_path_rate,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg,
+ patch_norm=patch_norm,
+ final_norm=final_norm,
+ num_fcs=num_fcs,
+ norm_eval=norm_eval,
+ pretrained=pretrained,
+ init_values=init_values,
+ init_cfg=init_cfg)
+
+ self.cls_token = nn.Parameter(torch.zeros(1, 1, embed_dims))
+
+ self.num_patches = self.patch_shape[0] * self.patch_shape[1]
+ self.pos_embed = nn.Parameter(
+ torch.zeros(1, self.num_patches + 1, embed_dims))
+
+ def _build_layers(self):
+ dpr = [
+ x.item()
+ for x in torch.linspace(0, self.drop_path_rate, self.num_layers)
+ ]
+ self.layers = ModuleList()
+ for i in range(self.num_layers):
+ self.layers.append(
+ MAETransformerEncoderLayer(
+ embed_dims=self.embed_dims,
+ num_heads=self.num_heads,
+ feedforward_channels=self.mlp_ratio * self.embed_dims,
+ attn_drop_rate=self.attn_drop_rate,
+ drop_path_rate=dpr[i],
+ num_fcs=self.num_fcs,
+ bias=True,
+ act_cfg=self.act_cfg,
+ norm_cfg=self.norm_cfg,
+ window_size=self.patch_shape,
+ init_values=self.init_values))
+
+ def fix_init_weight(self):
+ """Rescale the initialization according to layer id.
+
+ This function is copied from https://github.com/microsoft/unilm/blob/master/beit/modeling_pretrain.py. # noqa: E501
+ Copyright (c) Microsoft Corporation
+ Licensed under the MIT License
+ """
+
+ def rescale(param, layer_id):
+ param.div_(math.sqrt(2.0 * layer_id))
+
+ for layer_id, layer in enumerate(self.layers):
+ rescale(layer.attn.proj.weight.data, layer_id + 1)
+ rescale(layer.ffn.layers[1].weight.data, layer_id + 1)
+
+ def init_weights(self):
+
+ def _init_weights(m):
+ if isinstance(m, nn.Linear):
+ trunc_normal_(m.weight, std=.02)
+ if isinstance(m, nn.Linear) and m.bias is not None:
+ nn.init.constant_(m.bias, 0)
+ elif isinstance(m, nn.LayerNorm):
+ nn.init.constant_(m.bias, 0)
+ nn.init.constant_(m.weight, 1.0)
+
+ self.apply(_init_weights)
+ self.fix_init_weight()
+
+ if (isinstance(self.init_cfg, dict)
+ and self.init_cfg.get('type') == 'Pretrained'):
+ logger = get_root_logger()
+ checkpoint = _load_checkpoint(
+ self.init_cfg['checkpoint'], logger=logger, map_location='cpu')
+ state_dict = self.resize_rel_pos_embed(checkpoint)
+ state_dict = self.resize_abs_pos_embed(state_dict)
+ self.load_state_dict(state_dict, False)
+ elif self.init_cfg is not None:
+ super(MAE, self).init_weights()
+ else:
+ # We only implement the 'jax_impl' initialization implemented at
+ # https://github.com/rwightman/pytorch-image-models/blob/master/timm/models/vision_transformer.py#L353 # noqa: E501
+ # Copyright 2019 Ross Wightman
+ # Licensed under the Apache License, Version 2.0 (the "License")
+ trunc_normal_(self.cls_token, std=.02)
+ for n, m in self.named_modules():
+ if isinstance(m, nn.Linear):
+ trunc_normal_(m.weight, std=.02)
+ if m.bias is not None:
+ if 'ffn' in n:
+ nn.init.normal_(m.bias, mean=0., std=1e-6)
+ else:
+ nn.init.constant_(m.bias, 0)
+ elif isinstance(m, nn.Conv2d):
+ kaiming_init(m, mode='fan_in', bias=0.)
+ elif isinstance(m, (_BatchNorm, nn.GroupNorm, nn.LayerNorm)):
+ constant_init(m, val=1.0, bias=0.)
+
+ def resize_abs_pos_embed(self, state_dict):
+ if 'pos_embed' in state_dict:
+ pos_embed_checkpoint = state_dict['pos_embed']
+ embedding_size = pos_embed_checkpoint.shape[-1]
+ num_extra_tokens = self.pos_embed.shape[-2] - self.num_patches
+ # height (== width) for the checkpoint position embedding
+ orig_size = int(
+ (pos_embed_checkpoint.shape[-2] - num_extra_tokens)**0.5)
+ # height (== width) for the new position embedding
+ new_size = int(self.num_patches**0.5)
+ # class_token and dist_token are kept unchanged
+ if orig_size != new_size:
+ extra_tokens = pos_embed_checkpoint[:, :num_extra_tokens]
+ # only the position tokens are interpolated
+ pos_tokens = pos_embed_checkpoint[:, num_extra_tokens:]
+ pos_tokens = pos_tokens.reshape(-1, orig_size, orig_size,
+ embedding_size).permute(
+ 0, 3, 1, 2)
+ pos_tokens = torch.nn.functional.interpolate(
+ pos_tokens,
+ size=(new_size, new_size),
+ mode='bicubic',
+ align_corners=False)
+ pos_tokens = pos_tokens.permute(0, 2, 3, 1).flatten(1, 2)
+ new_pos_embed = torch.cat((extra_tokens, pos_tokens), dim=1)
+ state_dict['pos_embed'] = new_pos_embed
+ return state_dict
+
+ def forward(self, inputs):
+ B = inputs.shape[0]
+
+ x, hw_shape = self.patch_embed(inputs)
+
+ # stole cls_tokens impl from Phil Wang, thanks
+ cls_tokens = self.cls_token.expand(B, -1, -1)
+ x = torch.cat((cls_tokens, x), dim=1)
+ x = x + self.pos_embed
+
+ outs = []
+ for i, layer in enumerate(self.layers):
+ x = layer(x)
+ if i == len(self.layers) - 1:
+ if self.final_norm:
+ x = self.norm1(x)
+ if i in self.out_indices:
+ out = x[:, 1:]
+ B, _, C = out.shape
+ out = out.reshape(B, hw_shape[0], hw_shape[1],
+ C).permute(0, 3, 1, 2).contiguous()
+ outs.append(out)
+
+ return tuple(outs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/mit.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/mit.py
new file mode 100644
index 0000000000000000000000000000000000000000..4417cf113383c8576ee11c56d908d2fd2b639219
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/mit.py
@@ -0,0 +1,450 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import math
+import warnings
+
+import torch
+import torch.nn as nn
+import torch.utils.checkpoint as cp
+from mmcv.cnn import Conv2d, build_activation_layer, build_norm_layer
+from mmcv.cnn.bricks.drop import build_dropout
+from mmcv.cnn.bricks.transformer import MultiheadAttention
+from mmcv.cnn.utils.weight_init import (constant_init, normal_init,
+ trunc_normal_init)
+from mmcv.runner import BaseModule, ModuleList, Sequential
+
+from ..builder import BACKBONES
+from ..utils import PatchEmbed, nchw_to_nlc, nlc_to_nchw
+
+
+class MixFFN(BaseModule):
+ """An implementation of MixFFN of Segformer.
+
+ The differences between MixFFN & FFN:
+ 1. Use 1X1 Conv to replace Linear layer.
+ 2. Introduce 3X3 Conv to encode positional information.
+ Args:
+ embed_dims (int): The feature dimension. Same as
+ `MultiheadAttention`. Defaults: 256.
+ feedforward_channels (int): The hidden dimension of FFNs.
+ Defaults: 1024.
+ act_cfg (dict, optional): The activation config for FFNs.
+ Default: dict(type='ReLU')
+ ffn_drop (float, optional): Probability of an element to be
+ zeroed in FFN. Default 0.0.
+ dropout_layer (obj:`ConfigDict`): The dropout_layer used
+ when adding the shortcut.
+ init_cfg (obj:`mmcv.ConfigDict`): The Config for initialization.
+ Default: None.
+ """
+
+ def __init__(self,
+ embed_dims,
+ feedforward_channels,
+ act_cfg=dict(type='GELU'),
+ ffn_drop=0.,
+ dropout_layer=None,
+ init_cfg=None):
+ super(MixFFN, self).__init__(init_cfg)
+
+ self.embed_dims = embed_dims
+ self.feedforward_channels = feedforward_channels
+ self.act_cfg = act_cfg
+ self.activate = build_activation_layer(act_cfg)
+
+ in_channels = embed_dims
+ fc1 = Conv2d(
+ in_channels=in_channels,
+ out_channels=feedforward_channels,
+ kernel_size=1,
+ stride=1,
+ bias=True)
+ # 3x3 depth wise conv to provide positional encode information
+ pe_conv = Conv2d(
+ in_channels=feedforward_channels,
+ out_channels=feedforward_channels,
+ kernel_size=3,
+ stride=1,
+ padding=(3 - 1) // 2,
+ bias=True,
+ groups=feedforward_channels)
+ fc2 = Conv2d(
+ in_channels=feedforward_channels,
+ out_channels=in_channels,
+ kernel_size=1,
+ stride=1,
+ bias=True)
+ drop = nn.Dropout(ffn_drop)
+ layers = [fc1, pe_conv, self.activate, drop, fc2, drop]
+ self.layers = Sequential(*layers)
+ self.dropout_layer = build_dropout(
+ dropout_layer) if dropout_layer else torch.nn.Identity()
+
+ def forward(self, x, hw_shape, identity=None):
+ out = nlc_to_nchw(x, hw_shape)
+ out = self.layers(out)
+ out = nchw_to_nlc(out)
+ if identity is None:
+ identity = x
+ return identity + self.dropout_layer(out)
+
+
+class EfficientMultiheadAttention(MultiheadAttention):
+ """An implementation of Efficient Multi-head Attention of Segformer.
+
+ This module is modified from MultiheadAttention which is a module from
+ mmcv.cnn.bricks.transformer.
+ Args:
+ embed_dims (int): The embedding dimension.
+ num_heads (int): Parallel attention heads.
+ attn_drop (float): A Dropout layer on attn_output_weights.
+ Default: 0.0.
+ proj_drop (float): A Dropout layer after `nn.MultiheadAttention`.
+ Default: 0.0.
+ dropout_layer (obj:`ConfigDict`): The dropout_layer used
+ when adding the shortcut. Default: None.
+ init_cfg (obj:`mmcv.ConfigDict`): The Config for initialization.
+ Default: None.
+ batch_first (bool): Key, Query and Value are shape of
+ (batch, n, embed_dim)
+ or (n, batch, embed_dim). Default: False.
+ qkv_bias (bool): enable bias for qkv if True. Default True.
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='LN').
+ sr_ratio (int): The ratio of spatial reduction of Efficient Multi-head
+ Attention of Segformer. Default: 1.
+ """
+
+ def __init__(self,
+ embed_dims,
+ num_heads,
+ attn_drop=0.,
+ proj_drop=0.,
+ dropout_layer=None,
+ init_cfg=None,
+ batch_first=True,
+ qkv_bias=False,
+ norm_cfg=dict(type='LN'),
+ sr_ratio=1):
+ super().__init__(
+ embed_dims,
+ num_heads,
+ attn_drop,
+ proj_drop,
+ dropout_layer=dropout_layer,
+ init_cfg=init_cfg,
+ batch_first=batch_first,
+ bias=qkv_bias)
+
+ self.sr_ratio = sr_ratio
+ if sr_ratio > 1:
+ self.sr = Conv2d(
+ in_channels=embed_dims,
+ out_channels=embed_dims,
+ kernel_size=sr_ratio,
+ stride=sr_ratio)
+ # The ret[0] of build_norm_layer is norm name.
+ self.norm = build_norm_layer(norm_cfg, embed_dims)[1]
+
+ # handle the BC-breaking from https://github.com/open-mmlab/mmcv/pull/1418 # noqa
+ from mmseg import digit_version, mmcv_version
+ if mmcv_version < digit_version('1.3.17'):
+ warnings.warn('The legacy version of forward function in'
+ 'EfficientMultiheadAttention is deprecated in'
+ 'mmcv>=1.3.17 and will no longer support in the'
+ 'future. Please upgrade your mmcv.')
+ self.forward = self.legacy_forward
+
+ def forward(self, x, hw_shape, identity=None):
+
+ x_q = x
+ if self.sr_ratio > 1:
+ x_kv = nlc_to_nchw(x, hw_shape)
+ x_kv = self.sr(x_kv)
+ x_kv = nchw_to_nlc(x_kv)
+ x_kv = self.norm(x_kv)
+ else:
+ x_kv = x
+
+ if identity is None:
+ identity = x_q
+
+ # Because the dataflow('key', 'query', 'value') of
+ # ``torch.nn.MultiheadAttention`` is (num_query, batch,
+ # embed_dims), We should adjust the shape of dataflow from
+ # batch_first (batch, num_query, embed_dims) to num_query_first
+ # (num_query ,batch, embed_dims), and recover ``attn_output``
+ # from num_query_first to batch_first.
+ if self.batch_first:
+ x_q = x_q.transpose(0, 1)
+ x_kv = x_kv.transpose(0, 1)
+
+ out = self.attn(query=x_q, key=x_kv, value=x_kv)[0]
+
+ if self.batch_first:
+ out = out.transpose(0, 1)
+
+ return identity + self.dropout_layer(self.proj_drop(out))
+
+ def legacy_forward(self, x, hw_shape, identity=None):
+ """multi head attention forward in mmcv version < 1.3.17."""
+
+ x_q = x
+ if self.sr_ratio > 1:
+ x_kv = nlc_to_nchw(x, hw_shape)
+ x_kv = self.sr(x_kv)
+ x_kv = nchw_to_nlc(x_kv)
+ x_kv = self.norm(x_kv)
+ else:
+ x_kv = x
+
+ if identity is None:
+ identity = x_q
+
+ # `need_weights=True` will let nn.MultiHeadAttention
+ # `return attn_output, attn_output_weights.sum(dim=1) / num_heads`
+ # The `attn_output_weights.sum(dim=1)` may cause cuda error. So, we set
+ # `need_weights=False` to ignore `attn_output_weights.sum(dim=1)`.
+ # This issue - `https://github.com/pytorch/pytorch/issues/37583` report
+ # the error that large scale tensor sum operation may cause cuda error.
+ out = self.attn(query=x_q, key=x_kv, value=x_kv, need_weights=False)[0]
+
+ return identity + self.dropout_layer(self.proj_drop(out))
+
+
+class TransformerEncoderLayer(BaseModule):
+ """Implements one encoder layer in Segformer.
+
+ Args:
+ embed_dims (int): The feature dimension.
+ num_heads (int): Parallel attention heads.
+ feedforward_channels (int): The hidden dimension for FFNs.
+ drop_rate (float): Probability of an element to be zeroed.
+ after the feed forward layer. Default 0.0.
+ attn_drop_rate (float): The drop out rate for attention layer.
+ Default 0.0.
+ drop_path_rate (float): stochastic depth rate. Default 0.0.
+ qkv_bias (bool): enable bias for qkv if True.
+ Default: True.
+ act_cfg (dict): The activation config for FFNs.
+ Default: dict(type='GELU').
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='LN').
+ batch_first (bool): Key, Query and Value are shape of
+ (batch, n, embed_dim)
+ or (n, batch, embed_dim). Default: False.
+ init_cfg (dict, optional): Initialization config dict.
+ Default:None.
+ sr_ratio (int): The ratio of spatial reduction of Efficient Multi-head
+ Attention of Segformer. Default: 1.
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save
+ some memory while slowing down the training speed. Default: False.
+ """
+
+ def __init__(self,
+ embed_dims,
+ num_heads,
+ feedforward_channels,
+ drop_rate=0.,
+ attn_drop_rate=0.,
+ drop_path_rate=0.,
+ qkv_bias=True,
+ act_cfg=dict(type='GELU'),
+ norm_cfg=dict(type='LN'),
+ batch_first=True,
+ sr_ratio=1,
+ with_cp=False):
+ super(TransformerEncoderLayer, self).__init__()
+
+ # The ret[0] of build_norm_layer is norm name.
+ self.norm1 = build_norm_layer(norm_cfg, embed_dims)[1]
+
+ self.attn = EfficientMultiheadAttention(
+ embed_dims=embed_dims,
+ num_heads=num_heads,
+ attn_drop=attn_drop_rate,
+ proj_drop=drop_rate,
+ dropout_layer=dict(type='DropPath', drop_prob=drop_path_rate),
+ batch_first=batch_first,
+ qkv_bias=qkv_bias,
+ norm_cfg=norm_cfg,
+ sr_ratio=sr_ratio)
+
+ # The ret[0] of build_norm_layer is norm name.
+ self.norm2 = build_norm_layer(norm_cfg, embed_dims)[1]
+
+ self.ffn = MixFFN(
+ embed_dims=embed_dims,
+ feedforward_channels=feedforward_channels,
+ ffn_drop=drop_rate,
+ dropout_layer=dict(type='DropPath', drop_prob=drop_path_rate),
+ act_cfg=act_cfg)
+
+ self.with_cp = with_cp
+
+ def forward(self, x, hw_shape):
+
+ def _inner_forward(x):
+ x = self.attn(self.norm1(x), hw_shape, identity=x)
+ x = self.ffn(self.norm2(x), hw_shape, identity=x)
+ return x
+
+ if self.with_cp and x.requires_grad:
+ x = cp.checkpoint(_inner_forward, x)
+ else:
+ x = _inner_forward(x)
+ return x
+
+
+@BACKBONES.register_module()
+class MixVisionTransformer(BaseModule):
+ """The backbone of Segformer.
+
+ This backbone is the implementation of `SegFormer: Simple and
+ Efficient Design for Semantic Segmentation with
+ Transformers `_.
+ Args:
+ in_channels (int): Number of input channels. Default: 3.
+ embed_dims (int): Embedding dimension. Default: 768.
+ num_stags (int): The num of stages. Default: 4.
+ num_layers (Sequence[int]): The layer number of each transformer encode
+ layer. Default: [3, 4, 6, 3].
+ num_heads (Sequence[int]): The attention heads of each transformer
+ encode layer. Default: [1, 2, 4, 8].
+ patch_sizes (Sequence[int]): The patch_size of each overlapped patch
+ embedding. Default: [7, 3, 3, 3].
+ strides (Sequence[int]): The stride of each overlapped patch embedding.
+ Default: [4, 2, 2, 2].
+ sr_ratios (Sequence[int]): The spatial reduction rate of each
+ transformer encode layer. Default: [8, 4, 2, 1].
+ out_indices (Sequence[int] | int): Output from which stages.
+ Default: (0, 1, 2, 3).
+ mlp_ratio (int): ratio of mlp hidden dim to embedding dim.
+ Default: 4.
+ qkv_bias (bool): Enable bias for qkv if True. Default: True.
+ drop_rate (float): Probability of an element to be zeroed.
+ Default 0.0
+ attn_drop_rate (float): The drop out rate for attention layer.
+ Default 0.0
+ drop_path_rate (float): stochastic depth rate. Default 0.0
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='LN')
+ act_cfg (dict): The activation config for FFNs.
+ Default: dict(type='GELU').
+ pretrained (str, optional): model pretrained path. Default: None.
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save
+ some memory while slowing down the training speed. Default: False.
+ """
+
+ def __init__(self,
+ in_channels=3,
+ embed_dims=64,
+ num_stages=4,
+ num_layers=[3, 4, 6, 3],
+ num_heads=[1, 2, 4, 8],
+ patch_sizes=[7, 3, 3, 3],
+ strides=[4, 2, 2, 2],
+ sr_ratios=[8, 4, 2, 1],
+ out_indices=(0, 1, 2, 3),
+ mlp_ratio=4,
+ qkv_bias=True,
+ drop_rate=0.,
+ attn_drop_rate=0.,
+ drop_path_rate=0.,
+ act_cfg=dict(type='GELU'),
+ norm_cfg=dict(type='LN', eps=1e-6),
+ pretrained=None,
+ init_cfg=None,
+ with_cp=False):
+ super(MixVisionTransformer, self).__init__(init_cfg=init_cfg)
+
+ assert not (init_cfg and pretrained), \
+ 'init_cfg and pretrained cannot be set at the same time'
+ if isinstance(pretrained, str):
+ warnings.warn('DeprecationWarning: pretrained is deprecated, '
+ 'please use "init_cfg" instead')
+ self.init_cfg = dict(type='Pretrained', checkpoint=pretrained)
+ elif pretrained is not None:
+ raise TypeError('pretrained must be a str or None')
+
+ self.embed_dims = embed_dims
+ self.num_stages = num_stages
+ self.num_layers = num_layers
+ self.num_heads = num_heads
+ self.patch_sizes = patch_sizes
+ self.strides = strides
+ self.sr_ratios = sr_ratios
+ self.with_cp = with_cp
+ assert num_stages == len(num_layers) == len(num_heads) \
+ == len(patch_sizes) == len(strides) == len(sr_ratios)
+
+ self.out_indices = out_indices
+ assert max(out_indices) < self.num_stages
+
+ # transformer encoder
+ dpr = [
+ x.item()
+ for x in torch.linspace(0, drop_path_rate, sum(num_layers))
+ ] # stochastic num_layer decay rule
+
+ cur = 0
+ self.layers = ModuleList()
+ for i, num_layer in enumerate(num_layers):
+ embed_dims_i = embed_dims * num_heads[i]
+ patch_embed = PatchEmbed(
+ in_channels=in_channels,
+ embed_dims=embed_dims_i,
+ kernel_size=patch_sizes[i],
+ stride=strides[i],
+ padding=patch_sizes[i] // 2,
+ norm_cfg=norm_cfg)
+ layer = ModuleList([
+ TransformerEncoderLayer(
+ embed_dims=embed_dims_i,
+ num_heads=num_heads[i],
+ feedforward_channels=mlp_ratio * embed_dims_i,
+ drop_rate=drop_rate,
+ attn_drop_rate=attn_drop_rate,
+ drop_path_rate=dpr[cur + idx],
+ qkv_bias=qkv_bias,
+ act_cfg=act_cfg,
+ norm_cfg=norm_cfg,
+ with_cp=with_cp,
+ sr_ratio=sr_ratios[i]) for idx in range(num_layer)
+ ])
+ in_channels = embed_dims_i
+ # The ret[0] of build_norm_layer is norm name.
+ norm = build_norm_layer(norm_cfg, embed_dims_i)[1]
+ self.layers.append(ModuleList([patch_embed, layer, norm]))
+ cur += num_layer
+
+ def init_weights(self):
+ if self.init_cfg is None:
+ for m in self.modules():
+ if isinstance(m, nn.Linear):
+ trunc_normal_init(m, std=.02, bias=0.)
+ elif isinstance(m, nn.LayerNorm):
+ constant_init(m, val=1.0, bias=0.)
+ elif isinstance(m, nn.Conv2d):
+ fan_out = m.kernel_size[0] * m.kernel_size[
+ 1] * m.out_channels
+ fan_out //= m.groups
+ normal_init(
+ m, mean=0, std=math.sqrt(2.0 / fan_out), bias=0)
+ else:
+ super(MixVisionTransformer, self).init_weights()
+
+ def forward(self, x):
+ outs = []
+
+ for i, layer in enumerate(self.layers):
+ x, hw_shape = layer[0](x)
+ for block in layer[1]:
+ x = block(x, hw_shape)
+ x = layer[2](x)
+ x = nlc_to_nchw(x, hw_shape)
+ if i in self.out_indices:
+ outs.append(x)
+
+ return outs
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/mobilenet_v2.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/mobilenet_v2.py
new file mode 100644
index 0000000000000000000000000000000000000000..cbb9c6cd01fb83b330a6067415a0519bcb448e1c
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/mobilenet_v2.py
@@ -0,0 +1,197 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import warnings
+
+import torch.nn as nn
+from mmcv.cnn import ConvModule
+from mmcv.runner import BaseModule
+from torch.nn.modules.batchnorm import _BatchNorm
+
+from ..builder import BACKBONES
+from ..utils import InvertedResidual, make_divisible
+
+
+@BACKBONES.register_module()
+class MobileNetV2(BaseModule):
+ """MobileNetV2 backbone.
+
+ This backbone is the implementation of
+ `MobileNetV2: Inverted Residuals and Linear Bottlenecks
+ `_.
+
+ Args:
+ widen_factor (float): Width multiplier, multiply number of
+ channels in each layer by this amount. Default: 1.0.
+ strides (Sequence[int], optional): Strides of the first block of each
+ layer. If not specified, default config in ``arch_setting`` will
+ be used.
+ dilations (Sequence[int]): Dilation of each layer.
+ out_indices (None or Sequence[int]): Output from which stages.
+ Default: (7, ).
+ frozen_stages (int): Stages to be frozen (all param fixed).
+ Default: -1, which means not freezing any parameters.
+ conv_cfg (dict): Config dict for convolution layer.
+ Default: None, which means using conv2d.
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='BN').
+ act_cfg (dict): Config dict for activation layer.
+ Default: dict(type='ReLU6').
+ norm_eval (bool): Whether to set norm layers to eval mode, namely,
+ freeze running stats (mean and var). Note: Effect on Batch Norm
+ and its variants only. Default: False.
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save some
+ memory while slowing down the training speed. Default: False.
+ pretrained (str, optional): model pretrained path. Default: None
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None
+ """
+
+ # Parameters to build layers. 3 parameters are needed to construct a
+ # layer, from left to right: expand_ratio, channel, num_blocks.
+ arch_settings = [[1, 16, 1], [6, 24, 2], [6, 32, 3], [6, 64, 4],
+ [6, 96, 3], [6, 160, 3], [6, 320, 1]]
+
+ def __init__(self,
+ widen_factor=1.,
+ strides=(1, 2, 2, 2, 1, 2, 1),
+ dilations=(1, 1, 1, 1, 1, 1, 1),
+ out_indices=(1, 2, 4, 6),
+ frozen_stages=-1,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU6'),
+ norm_eval=False,
+ with_cp=False,
+ pretrained=None,
+ init_cfg=None):
+ super(MobileNetV2, self).__init__(init_cfg)
+
+ self.pretrained = pretrained
+ assert not (init_cfg and pretrained), \
+ 'init_cfg and pretrained cannot be setting at the same time'
+ if isinstance(pretrained, str):
+ warnings.warn('DeprecationWarning: pretrained is a deprecated, '
+ 'please use "init_cfg" instead')
+ self.init_cfg = dict(type='Pretrained', checkpoint=pretrained)
+ elif pretrained is None:
+ if init_cfg is None:
+ self.init_cfg = [
+ dict(type='Kaiming', layer='Conv2d'),
+ dict(
+ type='Constant',
+ val=1,
+ layer=['_BatchNorm', 'GroupNorm'])
+ ]
+ else:
+ raise TypeError('pretrained must be a str or None')
+
+ self.widen_factor = widen_factor
+ self.strides = strides
+ self.dilations = dilations
+ assert len(strides) == len(dilations) == len(self.arch_settings)
+ self.out_indices = out_indices
+ for index in out_indices:
+ if index not in range(0, 7):
+ raise ValueError('the item in out_indices must in '
+ f'range(0, 7). But received {index}')
+
+ if frozen_stages not in range(-1, 7):
+ raise ValueError('frozen_stages must be in range(-1, 7). '
+ f'But received {frozen_stages}')
+ self.out_indices = out_indices
+ self.frozen_stages = frozen_stages
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+ self.norm_eval = norm_eval
+ self.with_cp = with_cp
+
+ self.in_channels = make_divisible(32 * widen_factor, 8)
+
+ self.conv1 = ConvModule(
+ in_channels=3,
+ out_channels=self.in_channels,
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ self.layers = []
+
+ for i, layer_cfg in enumerate(self.arch_settings):
+ expand_ratio, channel, num_blocks = layer_cfg
+ stride = self.strides[i]
+ dilation = self.dilations[i]
+ out_channels = make_divisible(channel * widen_factor, 8)
+ inverted_res_layer = self.make_layer(
+ out_channels=out_channels,
+ num_blocks=num_blocks,
+ stride=stride,
+ dilation=dilation,
+ expand_ratio=expand_ratio)
+ layer_name = f'layer{i + 1}'
+ self.add_module(layer_name, inverted_res_layer)
+ self.layers.append(layer_name)
+
+ def make_layer(self, out_channels, num_blocks, stride, dilation,
+ expand_ratio):
+ """Stack InvertedResidual blocks to build a layer for MobileNetV2.
+
+ Args:
+ out_channels (int): out_channels of block.
+ num_blocks (int): Number of blocks.
+ stride (int): Stride of the first block.
+ dilation (int): Dilation of the first block.
+ expand_ratio (int): Expand the number of channels of the
+ hidden layer in InvertedResidual by this ratio.
+ """
+ layers = []
+ for i in range(num_blocks):
+ layers.append(
+ InvertedResidual(
+ self.in_channels,
+ out_channels,
+ stride if i == 0 else 1,
+ expand_ratio=expand_ratio,
+ dilation=dilation if i == 0 else 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg,
+ with_cp=self.with_cp))
+ self.in_channels = out_channels
+
+ return nn.Sequential(*layers)
+
+ def forward(self, x):
+ x = self.conv1(x)
+
+ outs = []
+ for i, layer_name in enumerate(self.layers):
+ layer = getattr(self, layer_name)
+ x = layer(x)
+ if i in self.out_indices:
+ outs.append(x)
+
+ if len(outs) == 1:
+ return outs[0]
+ else:
+ return tuple(outs)
+
+ def _freeze_stages(self):
+ if self.frozen_stages >= 0:
+ for param in self.conv1.parameters():
+ param.requires_grad = False
+ for i in range(1, self.frozen_stages + 1):
+ layer = getattr(self, f'layer{i}')
+ layer.eval()
+ for param in layer.parameters():
+ param.requires_grad = False
+
+ def train(self, mode=True):
+ super(MobileNetV2, self).train(mode)
+ self._freeze_stages()
+ if mode and self.norm_eval:
+ for m in self.modules():
+ if isinstance(m, _BatchNorm):
+ m.eval()
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/mobilenet_v3.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/mobilenet_v3.py
new file mode 100644
index 0000000000000000000000000000000000000000..dd3d6eb176bbd8c77d25730744daeef6c02435bc
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/mobilenet_v3.py
@@ -0,0 +1,267 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import warnings
+
+import mmcv
+from mmcv.cnn import ConvModule
+from mmcv.cnn.bricks import Conv2dAdaptivePadding
+from mmcv.runner import BaseModule
+from torch.nn.modules.batchnorm import _BatchNorm
+
+from ..builder import BACKBONES
+from ..utils import InvertedResidualV3 as InvertedResidual
+
+
+@BACKBONES.register_module()
+class MobileNetV3(BaseModule):
+ """MobileNetV3 backbone.
+
+ This backbone is the improved implementation of `Searching for MobileNetV3
+ `_.
+
+ Args:
+ arch (str): Architecture of mobilnetv3, from {'small', 'large'}.
+ Default: 'small'.
+ conv_cfg (dict): Config dict for convolution layer.
+ Default: None, which means using conv2d.
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='BN').
+ out_indices (tuple[int]): Output from which layer.
+ Default: (0, 1, 12).
+ frozen_stages (int): Stages to be frozen (all param fixed).
+ Default: -1, which means not freezing any parameters.
+ norm_eval (bool): Whether to set norm layers to eval mode, namely,
+ freeze running stats (mean and var). Note: Effect on Batch Norm
+ and its variants only. Default: False.
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save
+ some memory while slowing down the training speed.
+ Default: False.
+ pretrained (str, optional): model pretrained path. Default: None
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None
+ """
+ # Parameters to build each block:
+ # [kernel size, mid channels, out channels, with_se, act type, stride]
+ arch_settings = {
+ 'small': [[3, 16, 16, True, 'ReLU', 2], # block0 layer1 os=4
+ [3, 72, 24, False, 'ReLU', 2], # block1 layer2 os=8
+ [3, 88, 24, False, 'ReLU', 1],
+ [5, 96, 40, True, 'HSwish', 2], # block2 layer4 os=16
+ [5, 240, 40, True, 'HSwish', 1],
+ [5, 240, 40, True, 'HSwish', 1],
+ [5, 120, 48, True, 'HSwish', 1], # block3 layer7 os=16
+ [5, 144, 48, True, 'HSwish', 1],
+ [5, 288, 96, True, 'HSwish', 2], # block4 layer9 os=32
+ [5, 576, 96, True, 'HSwish', 1],
+ [5, 576, 96, True, 'HSwish', 1]],
+ 'large': [[3, 16, 16, False, 'ReLU', 1], # block0 layer1 os=2
+ [3, 64, 24, False, 'ReLU', 2], # block1 layer2 os=4
+ [3, 72, 24, False, 'ReLU', 1],
+ [5, 72, 40, True, 'ReLU', 2], # block2 layer4 os=8
+ [5, 120, 40, True, 'ReLU', 1],
+ [5, 120, 40, True, 'ReLU', 1],
+ [3, 240, 80, False, 'HSwish', 2], # block3 layer7 os=16
+ [3, 200, 80, False, 'HSwish', 1],
+ [3, 184, 80, False, 'HSwish', 1],
+ [3, 184, 80, False, 'HSwish', 1],
+ [3, 480, 112, True, 'HSwish', 1], # block4 layer11 os=16
+ [3, 672, 112, True, 'HSwish', 1],
+ [5, 672, 160, True, 'HSwish', 2], # block5 layer13 os=32
+ [5, 960, 160, True, 'HSwish', 1],
+ [5, 960, 160, True, 'HSwish', 1]]
+ } # yapf: disable
+
+ def __init__(self,
+ arch='small',
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ out_indices=(0, 1, 12),
+ frozen_stages=-1,
+ reduction_factor=1,
+ norm_eval=False,
+ with_cp=False,
+ pretrained=None,
+ init_cfg=None):
+ super(MobileNetV3, self).__init__(init_cfg)
+
+ self.pretrained = pretrained
+ assert not (init_cfg and pretrained), \
+ 'init_cfg and pretrained cannot be setting at the same time'
+ if isinstance(pretrained, str):
+ warnings.warn('DeprecationWarning: pretrained is a deprecated, '
+ 'please use "init_cfg" instead')
+ self.init_cfg = dict(type='Pretrained', checkpoint=pretrained)
+ elif pretrained is None:
+ if init_cfg is None:
+ self.init_cfg = [
+ dict(type='Kaiming', layer='Conv2d'),
+ dict(
+ type='Constant',
+ val=1,
+ layer=['_BatchNorm', 'GroupNorm'])
+ ]
+ else:
+ raise TypeError('pretrained must be a str or None')
+
+ assert arch in self.arch_settings
+ assert isinstance(reduction_factor, int) and reduction_factor > 0
+ assert mmcv.is_tuple_of(out_indices, int)
+ for index in out_indices:
+ if index not in range(0, len(self.arch_settings[arch]) + 2):
+ raise ValueError(
+ 'the item in out_indices must in '
+ f'range(0, {len(self.arch_settings[arch])+2}). '
+ f'But received {index}')
+
+ if frozen_stages not in range(-1, len(self.arch_settings[arch]) + 2):
+ raise ValueError('frozen_stages must be in range(-1, '
+ f'{len(self.arch_settings[arch])+2}). '
+ f'But received {frozen_stages}')
+ self.arch = arch
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.out_indices = out_indices
+ self.frozen_stages = frozen_stages
+ self.reduction_factor = reduction_factor
+ self.norm_eval = norm_eval
+ self.with_cp = with_cp
+ self.layers = self._make_layer()
+
+ def _make_layer(self):
+ layers = []
+
+ # build the first layer (layer0)
+ in_channels = 16
+ layer = ConvModule(
+ in_channels=3,
+ out_channels=in_channels,
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ conv_cfg=dict(type='Conv2dAdaptivePadding'),
+ norm_cfg=self.norm_cfg,
+ act_cfg=dict(type='HSwish'))
+ self.add_module('layer0', layer)
+ layers.append('layer0')
+
+ layer_setting = self.arch_settings[self.arch]
+ for i, params in enumerate(layer_setting):
+ (kernel_size, mid_channels, out_channels, with_se, act,
+ stride) = params
+
+ if self.arch == 'large' and i >= 12 or self.arch == 'small' and \
+ i >= 8:
+ mid_channels = mid_channels // self.reduction_factor
+ out_channels = out_channels // self.reduction_factor
+
+ if with_se:
+ se_cfg = dict(
+ channels=mid_channels,
+ ratio=4,
+ act_cfg=(dict(type='ReLU'),
+ dict(type='HSigmoid', bias=3.0, divisor=6.0)))
+ else:
+ se_cfg = None
+
+ layer = InvertedResidual(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ mid_channels=mid_channels,
+ kernel_size=kernel_size,
+ stride=stride,
+ se_cfg=se_cfg,
+ with_expand_conv=(in_channels != mid_channels),
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=dict(type=act),
+ with_cp=self.with_cp)
+ in_channels = out_channels
+ layer_name = 'layer{}'.format(i + 1)
+ self.add_module(layer_name, layer)
+ layers.append(layer_name)
+
+ # build the last layer
+ # block5 layer12 os=32 for small model
+ # block6 layer16 os=32 for large model
+ layer = ConvModule(
+ in_channels=in_channels,
+ out_channels=576 if self.arch == 'small' else 960,
+ kernel_size=1,
+ stride=1,
+ dilation=4,
+ padding=0,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=dict(type='HSwish'))
+ layer_name = 'layer{}'.format(len(layer_setting) + 1)
+ self.add_module(layer_name, layer)
+ layers.append(layer_name)
+
+ # next, convert backbone MobileNetV3 to a semantic segmentation version
+ if self.arch == 'small':
+ self.layer4.depthwise_conv.conv.stride = (1, 1)
+ self.layer9.depthwise_conv.conv.stride = (1, 1)
+ for i in range(4, len(layers)):
+ layer = getattr(self, layers[i])
+ if isinstance(layer, InvertedResidual):
+ modified_module = layer.depthwise_conv.conv
+ else:
+ modified_module = layer.conv
+
+ if i < 9:
+ modified_module.dilation = (2, 2)
+ pad = 2
+ else:
+ modified_module.dilation = (4, 4)
+ pad = 4
+
+ if not isinstance(modified_module, Conv2dAdaptivePadding):
+ # Adjust padding
+ pad *= (modified_module.kernel_size[0] - 1) // 2
+ modified_module.padding = (pad, pad)
+ else:
+ self.layer7.depthwise_conv.conv.stride = (1, 1)
+ self.layer13.depthwise_conv.conv.stride = (1, 1)
+ for i in range(7, len(layers)):
+ layer = getattr(self, layers[i])
+ if isinstance(layer, InvertedResidual):
+ modified_module = layer.depthwise_conv.conv
+ else:
+ modified_module = layer.conv
+
+ if i < 13:
+ modified_module.dilation = (2, 2)
+ pad = 2
+ else:
+ modified_module.dilation = (4, 4)
+ pad = 4
+
+ if not isinstance(modified_module, Conv2dAdaptivePadding):
+ # Adjust padding
+ pad *= (modified_module.kernel_size[0] - 1) // 2
+ modified_module.padding = (pad, pad)
+
+ return layers
+
+ def forward(self, x):
+ outs = []
+ for i, layer_name in enumerate(self.layers):
+ layer = getattr(self, layer_name)
+ x = layer(x)
+ if i in self.out_indices:
+ outs.append(x)
+ return outs
+
+ def _freeze_stages(self):
+ for i in range(self.frozen_stages + 1):
+ layer = getattr(self, f'layer{i}')
+ layer.eval()
+ for param in layer.parameters():
+ param.requires_grad = False
+
+ def train(self, mode=True):
+ super(MobileNetV3, self).train(mode)
+ self._freeze_stages()
+ if mode and self.norm_eval:
+ for m in self.modules():
+ if isinstance(m, _BatchNorm):
+ m.eval()
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/resnest.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/resnest.py
new file mode 100644
index 0000000000000000000000000000000000000000..91952c2caf37c1ca5c72ed845030d219d064b290
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/resnest.py
@@ -0,0 +1,318 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import math
+
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+import torch.utils.checkpoint as cp
+from mmcv.cnn import build_conv_layer, build_norm_layer
+
+from ..builder import BACKBONES
+from ..utils import ResLayer
+from .resnet import Bottleneck as _Bottleneck
+from .resnet import ResNetV1d
+
+
+class RSoftmax(nn.Module):
+ """Radix Softmax module in ``SplitAttentionConv2d``.
+
+ Args:
+ radix (int): Radix of input.
+ groups (int): Groups of input.
+ """
+
+ def __init__(self, radix, groups):
+ super().__init__()
+ self.radix = radix
+ self.groups = groups
+
+ def forward(self, x):
+ batch = x.size(0)
+ if self.radix > 1:
+ x = x.view(batch, self.groups, self.radix, -1).transpose(1, 2)
+ x = F.softmax(x, dim=1)
+ x = x.reshape(batch, -1)
+ else:
+ x = torch.sigmoid(x)
+ return x
+
+
+class SplitAttentionConv2d(nn.Module):
+ """Split-Attention Conv2d in ResNeSt.
+
+ Args:
+ in_channels (int): Same as nn.Conv2d.
+ out_channels (int): Same as nn.Conv2d.
+ kernel_size (int | tuple[int]): Same as nn.Conv2d.
+ stride (int | tuple[int]): Same as nn.Conv2d.
+ padding (int | tuple[int]): Same as nn.Conv2d.
+ dilation (int | tuple[int]): Same as nn.Conv2d.
+ groups (int): Same as nn.Conv2d.
+ radix (int): Radix of SpltAtConv2d. Default: 2
+ reduction_factor (int): Reduction factor of inter_channels. Default: 4.
+ conv_cfg (dict): Config dict for convolution layer. Default: None,
+ which means using conv2d.
+ norm_cfg (dict): Config dict for normalization layer. Default: None.
+ dcn (dict): Config dict for DCN. Default: None.
+ """
+
+ def __init__(self,
+ in_channels,
+ channels,
+ kernel_size,
+ stride=1,
+ padding=0,
+ dilation=1,
+ groups=1,
+ radix=2,
+ reduction_factor=4,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ dcn=None):
+ super(SplitAttentionConv2d, self).__init__()
+ inter_channels = max(in_channels * radix // reduction_factor, 32)
+ self.radix = radix
+ self.groups = groups
+ self.channels = channels
+ self.with_dcn = dcn is not None
+ self.dcn = dcn
+ fallback_on_stride = False
+ if self.with_dcn:
+ fallback_on_stride = self.dcn.pop('fallback_on_stride', False)
+ if self.with_dcn and not fallback_on_stride:
+ assert conv_cfg is None, 'conv_cfg must be None for DCN'
+ conv_cfg = dcn
+ self.conv = build_conv_layer(
+ conv_cfg,
+ in_channels,
+ channels * radix,
+ kernel_size,
+ stride=stride,
+ padding=padding,
+ dilation=dilation,
+ groups=groups * radix,
+ bias=False)
+ self.norm0_name, norm0 = build_norm_layer(
+ norm_cfg, channels * radix, postfix=0)
+ self.add_module(self.norm0_name, norm0)
+ self.relu = nn.ReLU(inplace=True)
+ self.fc1 = build_conv_layer(
+ None, channels, inter_channels, 1, groups=self.groups)
+ self.norm1_name, norm1 = build_norm_layer(
+ norm_cfg, inter_channels, postfix=1)
+ self.add_module(self.norm1_name, norm1)
+ self.fc2 = build_conv_layer(
+ None, inter_channels, channels * radix, 1, groups=self.groups)
+ self.rsoftmax = RSoftmax(radix, groups)
+
+ @property
+ def norm0(self):
+ """nn.Module: the normalization layer named "norm0" """
+ return getattr(self, self.norm0_name)
+
+ @property
+ def norm1(self):
+ """nn.Module: the normalization layer named "norm1" """
+ return getattr(self, self.norm1_name)
+
+ def forward(self, x):
+ x = self.conv(x)
+ x = self.norm0(x)
+ x = self.relu(x)
+
+ batch, rchannel = x.shape[:2]
+ batch = x.size(0)
+ if self.radix > 1:
+ splits = x.view(batch, self.radix, -1, *x.shape[2:])
+ gap = splits.sum(dim=1)
+ else:
+ gap = x
+ gap = F.adaptive_avg_pool2d(gap, 1)
+ gap = self.fc1(gap)
+
+ gap = self.norm1(gap)
+ gap = self.relu(gap)
+
+ atten = self.fc2(gap)
+ atten = self.rsoftmax(atten).view(batch, -1, 1, 1)
+
+ if self.radix > 1:
+ attens = atten.view(batch, self.radix, -1, *atten.shape[2:])
+ out = torch.sum(attens * splits, dim=1)
+ else:
+ out = atten * x
+ return out.contiguous()
+
+
+class Bottleneck(_Bottleneck):
+ """Bottleneck block for ResNeSt.
+
+ Args:
+ inplane (int): Input planes of this block.
+ planes (int): Middle planes of this block.
+ groups (int): Groups of conv2.
+ width_per_group (int): Width per group of conv2. 64x4d indicates
+ ``groups=64, width_per_group=4`` and 32x8d indicates
+ ``groups=32, width_per_group=8``.
+ radix (int): Radix of SpltAtConv2d. Default: 2
+ reduction_factor (int): Reduction factor of inter_channels in
+ SplitAttentionConv2d. Default: 4.
+ avg_down_stride (bool): Whether to use average pool for stride in
+ Bottleneck. Default: True.
+ kwargs (dict): Key word arguments for base class.
+ """
+ expansion = 4
+
+ def __init__(self,
+ inplanes,
+ planes,
+ groups=1,
+ base_width=4,
+ base_channels=64,
+ radix=2,
+ reduction_factor=4,
+ avg_down_stride=True,
+ **kwargs):
+ """Bottleneck block for ResNeSt."""
+ super(Bottleneck, self).__init__(inplanes, planes, **kwargs)
+
+ if groups == 1:
+ width = self.planes
+ else:
+ width = math.floor(self.planes *
+ (base_width / base_channels)) * groups
+
+ self.avg_down_stride = avg_down_stride and self.conv2_stride > 1
+
+ self.norm1_name, norm1 = build_norm_layer(
+ self.norm_cfg, width, postfix=1)
+ self.norm3_name, norm3 = build_norm_layer(
+ self.norm_cfg, self.planes * self.expansion, postfix=3)
+
+ self.conv1 = build_conv_layer(
+ self.conv_cfg,
+ self.inplanes,
+ width,
+ kernel_size=1,
+ stride=self.conv1_stride,
+ bias=False)
+ self.add_module(self.norm1_name, norm1)
+ self.with_modulated_dcn = False
+ self.conv2 = SplitAttentionConv2d(
+ width,
+ width,
+ kernel_size=3,
+ stride=1 if self.avg_down_stride else self.conv2_stride,
+ padding=self.dilation,
+ dilation=self.dilation,
+ groups=groups,
+ radix=radix,
+ reduction_factor=reduction_factor,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ dcn=self.dcn)
+ delattr(self, self.norm2_name)
+
+ if self.avg_down_stride:
+ self.avd_layer = nn.AvgPool2d(3, self.conv2_stride, padding=1)
+
+ self.conv3 = build_conv_layer(
+ self.conv_cfg,
+ width,
+ self.planes * self.expansion,
+ kernel_size=1,
+ bias=False)
+ self.add_module(self.norm3_name, norm3)
+
+ def forward(self, x):
+
+ def _inner_forward(x):
+ identity = x
+
+ out = self.conv1(x)
+ out = self.norm1(out)
+ out = self.relu(out)
+
+ if self.with_plugins:
+ out = self.forward_plugin(out, self.after_conv1_plugin_names)
+
+ out = self.conv2(out)
+
+ if self.avg_down_stride:
+ out = self.avd_layer(out)
+
+ if self.with_plugins:
+ out = self.forward_plugin(out, self.after_conv2_plugin_names)
+
+ out = self.conv3(out)
+ out = self.norm3(out)
+
+ if self.with_plugins:
+ out = self.forward_plugin(out, self.after_conv3_plugin_names)
+
+ if self.downsample is not None:
+ identity = self.downsample(x)
+
+ out += identity
+
+ return out
+
+ if self.with_cp and x.requires_grad:
+ out = cp.checkpoint(_inner_forward, x)
+ else:
+ out = _inner_forward(x)
+
+ out = self.relu(out)
+
+ return out
+
+
+@BACKBONES.register_module()
+class ResNeSt(ResNetV1d):
+ """ResNeSt backbone.
+
+ This backbone is the implementation of `ResNeSt:
+ Split-Attention Networks `_.
+
+ Args:
+ groups (int): Number of groups of Bottleneck. Default: 1
+ base_width (int): Base width of Bottleneck. Default: 4
+ radix (int): Radix of SpltAtConv2d. Default: 2
+ reduction_factor (int): Reduction factor of inter_channels in
+ SplitAttentionConv2d. Default: 4.
+ avg_down_stride (bool): Whether to use average pool for stride in
+ Bottleneck. Default: True.
+ kwargs (dict): Keyword arguments for ResNet.
+ """
+
+ arch_settings = {
+ 50: (Bottleneck, (3, 4, 6, 3)),
+ 101: (Bottleneck, (3, 4, 23, 3)),
+ 152: (Bottleneck, (3, 8, 36, 3)),
+ 200: (Bottleneck, (3, 24, 36, 3))
+ }
+
+ def __init__(self,
+ groups=1,
+ base_width=4,
+ radix=2,
+ reduction_factor=4,
+ avg_down_stride=True,
+ **kwargs):
+ self.groups = groups
+ self.base_width = base_width
+ self.radix = radix
+ self.reduction_factor = reduction_factor
+ self.avg_down_stride = avg_down_stride
+ super(ResNeSt, self).__init__(**kwargs)
+
+ def make_res_layer(self, **kwargs):
+ """Pack all blocks in a stage into a ``ResLayer``."""
+ return ResLayer(
+ groups=self.groups,
+ base_width=self.base_width,
+ base_channels=self.base_channels,
+ radix=self.radix,
+ reduction_factor=self.reduction_factor,
+ avg_down_stride=self.avg_down_stride,
+ **kwargs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/resnet.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/resnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..e8b961d5faed3a25eb09576b1339e5ce18ca9627
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/resnet.py
@@ -0,0 +1,714 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import warnings
+
+import torch.nn as nn
+import torch.utils.checkpoint as cp
+from mmcv.cnn import build_conv_layer, build_norm_layer, build_plugin_layer
+from mmcv.runner import BaseModule
+from mmcv.utils.parrots_wrapper import _BatchNorm
+
+from ..builder import BACKBONES
+from ..utils import ResLayer
+
+
+class BasicBlock(BaseModule):
+ """Basic block for ResNet."""
+
+ expansion = 1
+
+ def __init__(self,
+ inplanes,
+ planes,
+ stride=1,
+ dilation=1,
+ downsample=None,
+ style='pytorch',
+ with_cp=False,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ dcn=None,
+ plugins=None,
+ init_cfg=None):
+ super(BasicBlock, self).__init__(init_cfg)
+ assert dcn is None, 'Not implemented yet.'
+ assert plugins is None, 'Not implemented yet.'
+
+ self.norm1_name, norm1 = build_norm_layer(norm_cfg, planes, postfix=1)
+ self.norm2_name, norm2 = build_norm_layer(norm_cfg, planes, postfix=2)
+
+ self.conv1 = build_conv_layer(
+ conv_cfg,
+ inplanes,
+ planes,
+ 3,
+ stride=stride,
+ padding=dilation,
+ dilation=dilation,
+ bias=False)
+ self.add_module(self.norm1_name, norm1)
+ self.conv2 = build_conv_layer(
+ conv_cfg, planes, planes, 3, padding=1, bias=False)
+ self.add_module(self.norm2_name, norm2)
+
+ self.relu = nn.ReLU(inplace=True)
+ self.downsample = downsample
+ self.stride = stride
+ self.dilation = dilation
+ self.with_cp = with_cp
+
+ @property
+ def norm1(self):
+ """nn.Module: normalization layer after the first convolution layer"""
+ return getattr(self, self.norm1_name)
+
+ @property
+ def norm2(self):
+ """nn.Module: normalization layer after the second convolution layer"""
+ return getattr(self, self.norm2_name)
+
+ def forward(self, x):
+ """Forward function."""
+
+ def _inner_forward(x):
+ identity = x
+
+ out = self.conv1(x)
+ out = self.norm1(out)
+ out = self.relu(out)
+
+ out = self.conv2(out)
+ out = self.norm2(out)
+
+ if self.downsample is not None:
+ identity = self.downsample(x)
+
+ out += identity
+
+ return out
+
+ if self.with_cp and x.requires_grad:
+ out = cp.checkpoint(_inner_forward, x)
+ else:
+ out = _inner_forward(x)
+
+ out = self.relu(out)
+
+ return out
+
+
+class Bottleneck(BaseModule):
+ """Bottleneck block for ResNet.
+
+ If style is "pytorch", the stride-two layer is the 3x3 conv layer, if it is
+ "caffe", the stride-two layer is the first 1x1 conv layer.
+ """
+
+ expansion = 4
+
+ def __init__(self,
+ inplanes,
+ planes,
+ stride=1,
+ dilation=1,
+ downsample=None,
+ style='pytorch',
+ with_cp=False,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ dcn=None,
+ plugins=None,
+ init_cfg=None):
+ super(Bottleneck, self).__init__(init_cfg)
+ assert style in ['pytorch', 'caffe']
+ assert dcn is None or isinstance(dcn, dict)
+ assert plugins is None or isinstance(plugins, list)
+ if plugins is not None:
+ allowed_position = ['after_conv1', 'after_conv2', 'after_conv3']
+ assert all(p['position'] in allowed_position for p in plugins)
+
+ self.inplanes = inplanes
+ self.planes = planes
+ self.stride = stride
+ self.dilation = dilation
+ self.style = style
+ self.with_cp = with_cp
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.dcn = dcn
+ self.with_dcn = dcn is not None
+ self.plugins = plugins
+ self.with_plugins = plugins is not None
+
+ if self.with_plugins:
+ # collect plugins for conv1/conv2/conv3
+ self.after_conv1_plugins = [
+ plugin['cfg'] for plugin in plugins
+ if plugin['position'] == 'after_conv1'
+ ]
+ self.after_conv2_plugins = [
+ plugin['cfg'] for plugin in plugins
+ if plugin['position'] == 'after_conv2'
+ ]
+ self.after_conv3_plugins = [
+ plugin['cfg'] for plugin in plugins
+ if plugin['position'] == 'after_conv3'
+ ]
+
+ if self.style == 'pytorch':
+ self.conv1_stride = 1
+ self.conv2_stride = stride
+ else:
+ self.conv1_stride = stride
+ self.conv2_stride = 1
+
+ self.norm1_name, norm1 = build_norm_layer(norm_cfg, planes, postfix=1)
+ self.norm2_name, norm2 = build_norm_layer(norm_cfg, planes, postfix=2)
+ self.norm3_name, norm3 = build_norm_layer(
+ norm_cfg, planes * self.expansion, postfix=3)
+
+ self.conv1 = build_conv_layer(
+ conv_cfg,
+ inplanes,
+ planes,
+ kernel_size=1,
+ stride=self.conv1_stride,
+ bias=False)
+ self.add_module(self.norm1_name, norm1)
+ fallback_on_stride = False
+ if self.with_dcn:
+ fallback_on_stride = dcn.pop('fallback_on_stride', False)
+ if not self.with_dcn or fallback_on_stride:
+ self.conv2 = build_conv_layer(
+ conv_cfg,
+ planes,
+ planes,
+ kernel_size=3,
+ stride=self.conv2_stride,
+ padding=dilation,
+ dilation=dilation,
+ bias=False)
+ else:
+ assert self.conv_cfg is None, 'conv_cfg must be None for DCN'
+ self.conv2 = build_conv_layer(
+ dcn,
+ planes,
+ planes,
+ kernel_size=3,
+ stride=self.conv2_stride,
+ padding=dilation,
+ dilation=dilation,
+ bias=False)
+
+ self.add_module(self.norm2_name, norm2)
+ self.conv3 = build_conv_layer(
+ conv_cfg,
+ planes,
+ planes * self.expansion,
+ kernel_size=1,
+ bias=False)
+ self.add_module(self.norm3_name, norm3)
+
+ self.relu = nn.ReLU(inplace=True)
+ self.downsample = downsample
+
+ if self.with_plugins:
+ self.after_conv1_plugin_names = self.make_block_plugins(
+ planes, self.after_conv1_plugins)
+ self.after_conv2_plugin_names = self.make_block_plugins(
+ planes, self.after_conv2_plugins)
+ self.after_conv3_plugin_names = self.make_block_plugins(
+ planes * self.expansion, self.after_conv3_plugins)
+
+ def make_block_plugins(self, in_channels, plugins):
+ """make plugins for block.
+
+ Args:
+ in_channels (int): Input channels of plugin.
+ plugins (list[dict]): List of plugins cfg to build.
+
+ Returns:
+ list[str]: List of the names of plugin.
+ """
+ assert isinstance(plugins, list)
+ plugin_names = []
+ for plugin in plugins:
+ plugin = plugin.copy()
+ name, layer = build_plugin_layer(
+ plugin,
+ in_channels=in_channels,
+ postfix=plugin.pop('postfix', ''))
+ assert not hasattr(self, name), f'duplicate plugin {name}'
+ self.add_module(name, layer)
+ plugin_names.append(name)
+ return plugin_names
+
+ def forward_plugin(self, x, plugin_names):
+ """Forward function for plugins."""
+ out = x
+ for name in plugin_names:
+ out = getattr(self, name)(x)
+ return out
+
+ @property
+ def norm1(self):
+ """nn.Module: normalization layer after the first convolution layer"""
+ return getattr(self, self.norm1_name)
+
+ @property
+ def norm2(self):
+ """nn.Module: normalization layer after the second convolution layer"""
+ return getattr(self, self.norm2_name)
+
+ @property
+ def norm3(self):
+ """nn.Module: normalization layer after the third convolution layer"""
+ return getattr(self, self.norm3_name)
+
+ def forward(self, x):
+ """Forward function."""
+
+ def _inner_forward(x):
+ identity = x
+
+ out = self.conv1(x)
+ out = self.norm1(out)
+ out = self.relu(out)
+
+ if self.with_plugins:
+ out = self.forward_plugin(out, self.after_conv1_plugin_names)
+
+ out = self.conv2(out)
+ out = self.norm2(out)
+ out = self.relu(out)
+
+ if self.with_plugins:
+ out = self.forward_plugin(out, self.after_conv2_plugin_names)
+
+ out = self.conv3(out)
+ out = self.norm3(out)
+
+ if self.with_plugins:
+ out = self.forward_plugin(out, self.after_conv3_plugin_names)
+
+ if self.downsample is not None:
+ identity = self.downsample(x)
+
+ out += identity
+
+ return out
+
+ if self.with_cp and x.requires_grad:
+ out = cp.checkpoint(_inner_forward, x)
+ else:
+ out = _inner_forward(x)
+
+ out = self.relu(out)
+
+ return out
+
+
+@BACKBONES.register_module()
+class ResNet(BaseModule):
+ """ResNet backbone.
+
+ This backbone is the improved implementation of `Deep Residual Learning
+ for Image Recognition `_.
+
+ Args:
+ depth (int): Depth of resnet, from {18, 34, 50, 101, 152}.
+ in_channels (int): Number of input image channels. Default: 3.
+ stem_channels (int): Number of stem channels. Default: 64.
+ base_channels (int): Number of base channels of res layer. Default: 64.
+ num_stages (int): Resnet stages, normally 4. Default: 4.
+ strides (Sequence[int]): Strides of the first block of each stage.
+ Default: (1, 2, 2, 2).
+ dilations (Sequence[int]): Dilation of each stage.
+ Default: (1, 1, 1, 1).
+ out_indices (Sequence[int]): Output from which stages.
+ Default: (0, 1, 2, 3).
+ style (str): `pytorch` or `caffe`. If set to "pytorch", the stride-two
+ layer is the 3x3 conv layer, otherwise the stride-two layer is
+ the first 1x1 conv layer. Default: 'pytorch'.
+ deep_stem (bool): Replace 7x7 conv in input stem with 3 3x3 conv.
+ Default: False.
+ avg_down (bool): Use AvgPool instead of stride conv when
+ downsampling in the bottleneck. Default: False.
+ frozen_stages (int): Stages to be frozen (stop grad and set eval mode).
+ -1 means not freezing any parameters. Default: -1.
+ conv_cfg (dict | None): Dictionary to construct and config conv layer.
+ When conv_cfg is None, cfg will be set to dict(type='Conv2d').
+ Default: None.
+ norm_cfg (dict): Dictionary to construct and config norm layer.
+ Default: dict(type='BN', requires_grad=True).
+ norm_eval (bool): Whether to set norm layers to eval mode, namely,
+ freeze running stats (mean and var). Note: Effect on Batch Norm
+ and its variants only. Default: False.
+ dcn (dict | None): Dictionary to construct and config DCN conv layer.
+ When dcn is not None, conv_cfg must be None. Default: None.
+ stage_with_dcn (Sequence[bool]): Whether to set DCN conv for each
+ stage. The length of stage_with_dcn is equal to num_stages.
+ Default: (False, False, False, False).
+ plugins (list[dict]): List of plugins for stages, each dict contains:
+
+ - cfg (dict, required): Cfg dict to build plugin.
+
+ - position (str, required): Position inside block to insert plugin,
+ options: 'after_conv1', 'after_conv2', 'after_conv3'.
+
+ - stages (tuple[bool], optional): Stages to apply plugin, length
+ should be same as 'num_stages'.
+ Default: None.
+ multi_grid (Sequence[int]|None): Multi grid dilation rates of last
+ stage. Default: None.
+ contract_dilation (bool): Whether contract first dilation of each layer
+ Default: False.
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save some
+ memory while slowing down the training speed. Default: False.
+ zero_init_residual (bool): Whether to use zero init for last norm layer
+ in resblocks to let them behave as identity. Default: True.
+ pretrained (str, optional): model pretrained path. Default: None.
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+
+ Example:
+ >>> from mmseg.models import ResNet
+ >>> import torch
+ >>> self = ResNet(depth=18)
+ >>> self.eval()
+ >>> inputs = torch.rand(1, 3, 32, 32)
+ >>> level_outputs = self.forward(inputs)
+ >>> for level_out in level_outputs:
+ ... print(tuple(level_out.shape))
+ (1, 64, 8, 8)
+ (1, 128, 4, 4)
+ (1, 256, 2, 2)
+ (1, 512, 1, 1)
+ """
+
+ arch_settings = {
+ 18: (BasicBlock, (2, 2, 2, 2)),
+ 34: (BasicBlock, (3, 4, 6, 3)),
+ 50: (Bottleneck, (3, 4, 6, 3)),
+ 101: (Bottleneck, (3, 4, 23, 3)),
+ 152: (Bottleneck, (3, 8, 36, 3))
+ }
+
+ def __init__(self,
+ depth,
+ in_channels=3,
+ stem_channels=64,
+ base_channels=64,
+ num_stages=4,
+ strides=(1, 2, 2, 2),
+ dilations=(1, 1, 1, 1),
+ out_indices=(0, 1, 2, 3),
+ style='pytorch',
+ deep_stem=False,
+ avg_down=False,
+ frozen_stages=-1,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN', requires_grad=True),
+ norm_eval=False,
+ dcn=None,
+ stage_with_dcn=(False, False, False, False),
+ plugins=None,
+ multi_grid=None,
+ contract_dilation=False,
+ with_cp=False,
+ zero_init_residual=True,
+ pretrained=None,
+ init_cfg=None):
+ super(ResNet, self).__init__(init_cfg)
+ if depth not in self.arch_settings:
+ raise KeyError(f'invalid depth {depth} for resnet')
+
+ self.pretrained = pretrained
+ self.zero_init_residual = zero_init_residual
+ block_init_cfg = None
+ assert not (init_cfg and pretrained), \
+ 'init_cfg and pretrained cannot be setting at the same time'
+ if isinstance(pretrained, str):
+ warnings.warn('DeprecationWarning: pretrained is a deprecated, '
+ 'please use "init_cfg" instead')
+ self.init_cfg = dict(type='Pretrained', checkpoint=pretrained)
+ elif pretrained is None:
+ if init_cfg is None:
+ self.init_cfg = [
+ dict(type='Kaiming', layer='Conv2d'),
+ dict(
+ type='Constant',
+ val=1,
+ layer=['_BatchNorm', 'GroupNorm'])
+ ]
+ block = self.arch_settings[depth][0]
+ if self.zero_init_residual:
+ if block is BasicBlock:
+ block_init_cfg = dict(
+ type='Constant',
+ val=0,
+ override=dict(name='norm2'))
+ elif block is Bottleneck:
+ block_init_cfg = dict(
+ type='Constant',
+ val=0,
+ override=dict(name='norm3'))
+ else:
+ raise TypeError('pretrained must be a str or None')
+
+ self.depth = depth
+ self.stem_channels = stem_channels
+ self.base_channels = base_channels
+ self.num_stages = num_stages
+ assert num_stages >= 1 and num_stages <= 4
+ self.strides = strides
+ self.dilations = dilations
+ assert len(strides) == len(dilations) == num_stages
+ self.out_indices = out_indices
+ assert max(out_indices) < num_stages
+ self.style = style
+ self.deep_stem = deep_stem
+ self.avg_down = avg_down
+ self.frozen_stages = frozen_stages
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.with_cp = with_cp
+ self.norm_eval = norm_eval
+ self.dcn = dcn
+ self.stage_with_dcn = stage_with_dcn
+ if dcn is not None:
+ assert len(stage_with_dcn) == num_stages
+ self.plugins = plugins
+ self.multi_grid = multi_grid
+ self.contract_dilation = contract_dilation
+ self.block, stage_blocks = self.arch_settings[depth]
+ self.stage_blocks = stage_blocks[:num_stages]
+ self.inplanes = stem_channels
+
+ self._make_stem_layer(in_channels, stem_channels)
+
+ self.res_layers = []
+ for i, num_blocks in enumerate(self.stage_blocks):
+ stride = strides[i]
+ dilation = dilations[i]
+ dcn = self.dcn if self.stage_with_dcn[i] else None
+ if plugins is not None:
+ stage_plugins = self.make_stage_plugins(plugins, i)
+ else:
+ stage_plugins = None
+ # multi grid is applied to last layer only
+ stage_multi_grid = multi_grid if i == len(
+ self.stage_blocks) - 1 else None
+ planes = base_channels * 2**i
+ res_layer = self.make_res_layer(
+ block=self.block,
+ inplanes=self.inplanes,
+ planes=planes,
+ num_blocks=num_blocks,
+ stride=stride,
+ dilation=dilation,
+ style=self.style,
+ avg_down=self.avg_down,
+ with_cp=with_cp,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ dcn=dcn,
+ plugins=stage_plugins,
+ multi_grid=stage_multi_grid,
+ contract_dilation=contract_dilation,
+ init_cfg=block_init_cfg)
+ self.inplanes = planes * self.block.expansion
+ layer_name = f'layer{i+1}'
+ self.add_module(layer_name, res_layer)
+ self.res_layers.append(layer_name)
+
+ self._freeze_stages()
+
+ self.feat_dim = self.block.expansion * base_channels * 2**(
+ len(self.stage_blocks) - 1)
+
+ def make_stage_plugins(self, plugins, stage_idx):
+ """make plugins for ResNet 'stage_idx'th stage .
+
+ Currently we support to insert 'context_block',
+ 'empirical_attention_block', 'nonlocal_block' into the backbone like
+ ResNet/ResNeXt. They could be inserted after conv1/conv2/conv3 of
+ Bottleneck.
+
+ An example of plugins format could be :
+ >>> plugins=[
+ ... dict(cfg=dict(type='xxx', arg1='xxx'),
+ ... stages=(False, True, True, True),
+ ... position='after_conv2'),
+ ... dict(cfg=dict(type='yyy'),
+ ... stages=(True, True, True, True),
+ ... position='after_conv3'),
+ ... dict(cfg=dict(type='zzz', postfix='1'),
+ ... stages=(True, True, True, True),
+ ... position='after_conv3'),
+ ... dict(cfg=dict(type='zzz', postfix='2'),
+ ... stages=(True, True, True, True),
+ ... position='after_conv3')
+ ... ]
+ >>> self = ResNet(depth=18)
+ >>> stage_plugins = self.make_stage_plugins(plugins, 0)
+ >>> assert len(stage_plugins) == 3
+
+ Suppose 'stage_idx=0', the structure of blocks in the stage would be:
+ conv1-> conv2->conv3->yyy->zzz1->zzz2
+ Suppose 'stage_idx=1', the structure of blocks in the stage would be:
+ conv1-> conv2->xxx->conv3->yyy->zzz1->zzz2
+
+ If stages is missing, the plugin would be applied to all stages.
+
+ Args:
+ plugins (list[dict]): List of plugins cfg to build. The postfix is
+ required if multiple same type plugins are inserted.
+ stage_idx (int): Index of stage to build
+
+ Returns:
+ list[dict]: Plugins for current stage
+ """
+ stage_plugins = []
+ for plugin in plugins:
+ plugin = plugin.copy()
+ stages = plugin.pop('stages', None)
+ assert stages is None or len(stages) == self.num_stages
+ # whether to insert plugin into current stage
+ if stages is None or stages[stage_idx]:
+ stage_plugins.append(plugin)
+
+ return stage_plugins
+
+ def make_res_layer(self, **kwargs):
+ """Pack all blocks in a stage into a ``ResLayer``."""
+ return ResLayer(**kwargs)
+
+ @property
+ def norm1(self):
+ """nn.Module: the normalization layer named "norm1" """
+ return getattr(self, self.norm1_name)
+
+ def _make_stem_layer(self, in_channels, stem_channels):
+ """Make stem layer for ResNet."""
+ if self.deep_stem:
+ self.stem = nn.Sequential(
+ build_conv_layer(
+ self.conv_cfg,
+ in_channels,
+ stem_channels // 2,
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ bias=False),
+ build_norm_layer(self.norm_cfg, stem_channels // 2)[1],
+ nn.ReLU(inplace=True),
+ build_conv_layer(
+ self.conv_cfg,
+ stem_channels // 2,
+ stem_channels // 2,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ bias=False),
+ build_norm_layer(self.norm_cfg, stem_channels // 2)[1],
+ nn.ReLU(inplace=True),
+ build_conv_layer(
+ self.conv_cfg,
+ stem_channels // 2,
+ stem_channels,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ bias=False),
+ build_norm_layer(self.norm_cfg, stem_channels)[1],
+ nn.ReLU(inplace=True))
+ else:
+ self.conv1 = build_conv_layer(
+ self.conv_cfg,
+ in_channels,
+ stem_channels,
+ kernel_size=7,
+ stride=2,
+ padding=3,
+ bias=False)
+ self.norm1_name, norm1 = build_norm_layer(
+ self.norm_cfg, stem_channels, postfix=1)
+ self.add_module(self.norm1_name, norm1)
+ self.relu = nn.ReLU(inplace=True)
+ self.maxpool = nn.MaxPool2d(kernel_size=3, stride=2, padding=1)
+
+ def _freeze_stages(self):
+ """Freeze stages param and norm stats."""
+ if self.frozen_stages >= 0:
+ if self.deep_stem:
+ self.stem.eval()
+ for param in self.stem.parameters():
+ param.requires_grad = False
+ else:
+ self.norm1.eval()
+ for m in [self.conv1, self.norm1]:
+ for param in m.parameters():
+ param.requires_grad = False
+
+ for i in range(1, self.frozen_stages + 1):
+ m = getattr(self, f'layer{i}')
+ m.eval()
+ for param in m.parameters():
+ param.requires_grad = False
+
+ def forward(self, x):
+ """Forward function."""
+ if self.deep_stem:
+ x = self.stem(x)
+ else:
+ x = self.conv1(x)
+ x = self.norm1(x)
+ x = self.relu(x)
+ x = self.maxpool(x)
+ outs = []
+ for i, layer_name in enumerate(self.res_layers):
+ res_layer = getattr(self, layer_name)
+ x = res_layer(x)
+ if i in self.out_indices:
+ outs.append(x)
+ return tuple(outs)
+
+ def train(self, mode=True):
+ """Convert the model into training mode while keep normalization layer
+ freezed."""
+ super(ResNet, self).train(mode)
+ self._freeze_stages()
+ if mode and self.norm_eval:
+ for m in self.modules():
+ # trick: eval have effect on BatchNorm only
+ if isinstance(m, _BatchNorm):
+ m.eval()
+
+
+@BACKBONES.register_module()
+class ResNetV1c(ResNet):
+ """ResNetV1c variant described in [1]_.
+
+ Compared with default ResNet(ResNetV1b), ResNetV1c replaces the 7x7 conv in
+ the input stem with three 3x3 convs. For more details please refer to `Bag
+ of Tricks for Image Classification with Convolutional Neural Networks
+ `_.
+ """
+
+ def __init__(self, **kwargs):
+ super(ResNetV1c, self).__init__(
+ deep_stem=True, avg_down=False, **kwargs)
+
+
+@BACKBONES.register_module()
+class ResNetV1d(ResNet):
+ """ResNetV1d variant described in [1]_.
+
+ Compared with default ResNet(ResNetV1b), ResNetV1d replaces the 7x7 conv in
+ the input stem with three 3x3 convs. And in the downsampling block, a 2x2
+ avg_pool with stride 2 is added before conv, whose stride is changed to 1.
+ """
+
+ def __init__(self, **kwargs):
+ super(ResNetV1d, self).__init__(
+ deep_stem=True, avg_down=True, **kwargs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/resnext.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/resnext.py
new file mode 100644
index 0000000000000000000000000000000000000000..805c27bf332b365a0c374cfeb5a1ea6ea268ec43
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/resnext.py
@@ -0,0 +1,150 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import math
+
+from mmcv.cnn import build_conv_layer, build_norm_layer
+
+from ..builder import BACKBONES
+from ..utils import ResLayer
+from .resnet import Bottleneck as _Bottleneck
+from .resnet import ResNet
+
+
+class Bottleneck(_Bottleneck):
+ """Bottleneck block for ResNeXt.
+
+ If style is "pytorch", the stride-two layer is the 3x3 conv layer, if it is
+ "caffe", the stride-two layer is the first 1x1 conv layer.
+ """
+
+ def __init__(self,
+ inplanes,
+ planes,
+ groups=1,
+ base_width=4,
+ base_channels=64,
+ **kwargs):
+ super(Bottleneck, self).__init__(inplanes, planes, **kwargs)
+
+ if groups == 1:
+ width = self.planes
+ else:
+ width = math.floor(self.planes *
+ (base_width / base_channels)) * groups
+
+ self.norm1_name, norm1 = build_norm_layer(
+ self.norm_cfg, width, postfix=1)
+ self.norm2_name, norm2 = build_norm_layer(
+ self.norm_cfg, width, postfix=2)
+ self.norm3_name, norm3 = build_norm_layer(
+ self.norm_cfg, self.planes * self.expansion, postfix=3)
+
+ self.conv1 = build_conv_layer(
+ self.conv_cfg,
+ self.inplanes,
+ width,
+ kernel_size=1,
+ stride=self.conv1_stride,
+ bias=False)
+ self.add_module(self.norm1_name, norm1)
+ fallback_on_stride = False
+ self.with_modulated_dcn = False
+ if self.with_dcn:
+ fallback_on_stride = self.dcn.pop('fallback_on_stride', False)
+ if not self.with_dcn or fallback_on_stride:
+ self.conv2 = build_conv_layer(
+ self.conv_cfg,
+ width,
+ width,
+ kernel_size=3,
+ stride=self.conv2_stride,
+ padding=self.dilation,
+ dilation=self.dilation,
+ groups=groups,
+ bias=False)
+ else:
+ assert self.conv_cfg is None, 'conv_cfg must be None for DCN'
+ self.conv2 = build_conv_layer(
+ self.dcn,
+ width,
+ width,
+ kernel_size=3,
+ stride=self.conv2_stride,
+ padding=self.dilation,
+ dilation=self.dilation,
+ groups=groups,
+ bias=False)
+
+ self.add_module(self.norm2_name, norm2)
+ self.conv3 = build_conv_layer(
+ self.conv_cfg,
+ width,
+ self.planes * self.expansion,
+ kernel_size=1,
+ bias=False)
+ self.add_module(self.norm3_name, norm3)
+
+
+@BACKBONES.register_module()
+class ResNeXt(ResNet):
+ """ResNeXt backbone.
+
+ This backbone is the implementation of `Aggregated
+ Residual Transformations for Deep Neural
+ Networks `_.
+
+ Args:
+ depth (int): Depth of resnet, from {18, 34, 50, 101, 152}.
+ in_channels (int): Number of input image channels. Normally 3.
+ num_stages (int): Resnet stages, normally 4.
+ groups (int): Group of resnext.
+ base_width (int): Base width of resnext.
+ strides (Sequence[int]): Strides of the first block of each stage.
+ dilations (Sequence[int]): Dilation of each stage.
+ out_indices (Sequence[int]): Output from which stages.
+ style (str): `pytorch` or `caffe`. If set to "pytorch", the stride-two
+ layer is the 3x3 conv layer, otherwise the stride-two layer is
+ the first 1x1 conv layer.
+ frozen_stages (int): Stages to be frozen (all param fixed). -1 means
+ not freezing any parameters.
+ norm_cfg (dict): dictionary to construct and config norm layer.
+ norm_eval (bool): Whether to set norm layers to eval mode, namely,
+ freeze running stats (mean and var). Note: Effect on Batch Norm
+ and its variants only.
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save some
+ memory while slowing down the training speed.
+ zero_init_residual (bool): whether to use zero init for last norm layer
+ in resblocks to let them behave as identity.
+
+ Example:
+ >>> from mmseg.models import ResNeXt
+ >>> import torch
+ >>> self = ResNeXt(depth=50)
+ >>> self.eval()
+ >>> inputs = torch.rand(1, 3, 32, 32)
+ >>> level_outputs = self.forward(inputs)
+ >>> for level_out in level_outputs:
+ ... print(tuple(level_out.shape))
+ (1, 256, 8, 8)
+ (1, 512, 4, 4)
+ (1, 1024, 2, 2)
+ (1, 2048, 1, 1)
+ """
+
+ arch_settings = {
+ 50: (Bottleneck, (3, 4, 6, 3)),
+ 101: (Bottleneck, (3, 4, 23, 3)),
+ 152: (Bottleneck, (3, 8, 36, 3))
+ }
+
+ def __init__(self, groups=1, base_width=4, **kwargs):
+ self.groups = groups
+ self.base_width = base_width
+ super(ResNeXt, self).__init__(**kwargs)
+
+ def make_res_layer(self, **kwargs):
+ """Pack all blocks in a stage into a ``ResLayer``"""
+ return ResLayer(
+ groups=self.groups,
+ base_width=self.base_width,
+ base_channels=self.base_channels,
+ **kwargs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/stdc.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/stdc.py
new file mode 100644
index 0000000000000000000000000000000000000000..04f2f7a2a7574633b1878e0d10c0bb6371fdaffa
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/stdc.py
@@ -0,0 +1,422 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+"""Modified from https://github.com/MichaelFan01/STDC-Seg."""
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+from mmcv.cnn import ConvModule
+from mmcv.runner.base_module import BaseModule, ModuleList, Sequential
+
+from mmseg.ops import resize
+from ..builder import BACKBONES, build_backbone
+from .bisenetv1 import AttentionRefinementModule
+
+
+class STDCModule(BaseModule):
+ """STDCModule.
+
+ Args:
+ in_channels (int): The number of input channels.
+ out_channels (int): The number of output channels before scaling.
+ stride (int): The number of stride for the first conv layer.
+ norm_cfg (dict): Config dict for normalization layer. Default: None.
+ act_cfg (dict): The activation config for conv layers.
+ num_convs (int): Numbers of conv layers.
+ fusion_type (str): Type of fusion operation. Default: 'add'.
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ """
+
+ def __init__(self,
+ in_channels,
+ out_channels,
+ stride,
+ norm_cfg=None,
+ act_cfg=None,
+ num_convs=4,
+ fusion_type='add',
+ init_cfg=None):
+ super(STDCModule, self).__init__(init_cfg=init_cfg)
+ assert num_convs > 1
+ assert fusion_type in ['add', 'cat']
+ self.stride = stride
+ self.with_downsample = True if self.stride == 2 else False
+ self.fusion_type = fusion_type
+
+ self.layers = ModuleList()
+ conv_0 = ConvModule(
+ in_channels, out_channels // 2, kernel_size=1, norm_cfg=norm_cfg)
+
+ if self.with_downsample:
+ self.downsample = ConvModule(
+ out_channels // 2,
+ out_channels // 2,
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ groups=out_channels // 2,
+ norm_cfg=norm_cfg,
+ act_cfg=None)
+
+ if self.fusion_type == 'add':
+ self.layers.append(nn.Sequential(conv_0, self.downsample))
+ self.skip = Sequential(
+ ConvModule(
+ in_channels,
+ in_channels,
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ groups=in_channels,
+ norm_cfg=norm_cfg,
+ act_cfg=None),
+ ConvModule(
+ in_channels,
+ out_channels,
+ 1,
+ norm_cfg=norm_cfg,
+ act_cfg=None))
+ else:
+ self.layers.append(conv_0)
+ self.skip = nn.AvgPool2d(kernel_size=3, stride=2, padding=1)
+ else:
+ self.layers.append(conv_0)
+
+ for i in range(1, num_convs):
+ out_factor = 2**(i + 1) if i != num_convs - 1 else 2**i
+ self.layers.append(
+ ConvModule(
+ out_channels // 2**i,
+ out_channels // out_factor,
+ kernel_size=3,
+ stride=1,
+ padding=1,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg))
+
+ def forward(self, inputs):
+ if self.fusion_type == 'add':
+ out = self.forward_add(inputs)
+ else:
+ out = self.forward_cat(inputs)
+ return out
+
+ def forward_add(self, inputs):
+ layer_outputs = []
+ x = inputs.clone()
+ for layer in self.layers:
+ x = layer(x)
+ layer_outputs.append(x)
+ if self.with_downsample:
+ inputs = self.skip(inputs)
+
+ return torch.cat(layer_outputs, dim=1) + inputs
+
+ def forward_cat(self, inputs):
+ x0 = self.layers[0](inputs)
+ layer_outputs = [x0]
+ for i, layer in enumerate(self.layers[1:]):
+ if i == 0:
+ if self.with_downsample:
+ x = layer(self.downsample(x0))
+ else:
+ x = layer(x0)
+ else:
+ x = layer(x)
+ layer_outputs.append(x)
+ if self.with_downsample:
+ layer_outputs[0] = self.skip(x0)
+ return torch.cat(layer_outputs, dim=1)
+
+
+class FeatureFusionModule(BaseModule):
+ """Feature Fusion Module. This module is different from FeatureFusionModule
+ in BiSeNetV1. It uses two ConvModules in `self.attention` whose inter
+ channel number is calculated by given `scale_factor`, while
+ FeatureFusionModule in BiSeNetV1 only uses one ConvModule in
+ `self.conv_atten`.
+
+ Args:
+ in_channels (int): The number of input channels.
+ out_channels (int): The number of output channels.
+ scale_factor (int): The number of channel scale factor.
+ Default: 4.
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='BN').
+ act_cfg (dict): The activation config for conv layers.
+ Default: dict(type='ReLU').
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ """
+
+ def __init__(self,
+ in_channels,
+ out_channels,
+ scale_factor=4,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ init_cfg=None):
+ super(FeatureFusionModule, self).__init__(init_cfg=init_cfg)
+ channels = out_channels // scale_factor
+ self.conv0 = ConvModule(
+ in_channels, out_channels, 1, norm_cfg=norm_cfg, act_cfg=act_cfg)
+ self.attention = nn.Sequential(
+ nn.AdaptiveAvgPool2d((1, 1)),
+ ConvModule(
+ out_channels,
+ channels,
+ 1,
+ norm_cfg=None,
+ bias=False,
+ act_cfg=act_cfg),
+ ConvModule(
+ channels,
+ out_channels,
+ 1,
+ norm_cfg=None,
+ bias=False,
+ act_cfg=None), nn.Sigmoid())
+
+ def forward(self, spatial_inputs, context_inputs):
+ inputs = torch.cat([spatial_inputs, context_inputs], dim=1)
+ x = self.conv0(inputs)
+ attn = self.attention(x)
+ x_attn = x * attn
+ return x_attn + x
+
+
+@BACKBONES.register_module()
+class STDCNet(BaseModule):
+ """This backbone is the implementation of `Rethinking BiSeNet For Real-time
+ Semantic Segmentation `_.
+
+ Args:
+ stdc_type (int): The type of backbone structure,
+ `STDCNet1` and`STDCNet2` denotes two main backbones in paper,
+ whose FLOPs is 813M and 1446M, respectively.
+ in_channels (int): The num of input_channels.
+ channels (tuple[int]): The output channels for each stage.
+ bottleneck_type (str): The type of STDC Module type, the value must
+ be 'add' or 'cat'.
+ norm_cfg (dict): Config dict for normalization layer.
+ act_cfg (dict): The activation config for conv layers.
+ num_convs (int): Numbers of conv layer at each STDC Module.
+ Default: 4.
+ with_final_conv (bool): Whether add a conv layer at the Module output.
+ Default: True.
+ pretrained (str, optional): Model pretrained path. Default: None.
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+
+ Example:
+ >>> import torch
+ >>> stdc_type = 'STDCNet1'
+ >>> in_channels = 3
+ >>> channels = (32, 64, 256, 512, 1024)
+ >>> bottleneck_type = 'cat'
+ >>> inputs = torch.rand(1, 3, 1024, 2048)
+ >>> self = STDCNet(stdc_type, in_channels,
+ ... channels, bottleneck_type).eval()
+ >>> outputs = self.forward(inputs)
+ >>> for i in range(len(outputs)):
+ ... print(f'outputs[{i}].shape = {outputs[i].shape}')
+ outputs[0].shape = torch.Size([1, 256, 128, 256])
+ outputs[1].shape = torch.Size([1, 512, 64, 128])
+ outputs[2].shape = torch.Size([1, 1024, 32, 64])
+ """
+
+ arch_settings = {
+ 'STDCNet1': [(2, 1), (2, 1), (2, 1)],
+ 'STDCNet2': [(2, 1, 1, 1), (2, 1, 1, 1, 1), (2, 1, 1)]
+ }
+
+ def __init__(self,
+ stdc_type,
+ in_channels,
+ channels,
+ bottleneck_type,
+ norm_cfg,
+ act_cfg,
+ num_convs=4,
+ with_final_conv=False,
+ pretrained=None,
+ init_cfg=None):
+ super(STDCNet, self).__init__(init_cfg=init_cfg)
+ assert stdc_type in self.arch_settings, \
+ f'invalid structure {stdc_type} for STDCNet.'
+ assert bottleneck_type in ['add', 'cat'],\
+ f'bottleneck_type must be `add` or `cat`, got {bottleneck_type}'
+
+ assert len(channels) == 5,\
+ f'invalid channels length {len(channels)} for STDCNet.'
+
+ self.in_channels = in_channels
+ self.channels = channels
+ self.stage_strides = self.arch_settings[stdc_type]
+ self.prtrained = pretrained
+ self.num_convs = num_convs
+ self.with_final_conv = with_final_conv
+
+ self.stages = ModuleList([
+ ConvModule(
+ self.in_channels,
+ self.channels[0],
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg),
+ ConvModule(
+ self.channels[0],
+ self.channels[1],
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ ])
+ # `self.num_shallow_features` is the number of shallow modules in
+ # `STDCNet`, which is noted as `Stage1` and `Stage2` in original paper.
+ # They are both not used for following modules like Attention
+ # Refinement Module and Feature Fusion Module.
+ # Thus they would be cut from `outs`. Please refer to Figure 4
+ # of original paper for more details.
+ self.num_shallow_features = len(self.stages)
+
+ for strides in self.stage_strides:
+ idx = len(self.stages) - 1
+ self.stages.append(
+ self._make_stage(self.channels[idx], self.channels[idx + 1],
+ strides, norm_cfg, act_cfg, bottleneck_type))
+ # After appending, `self.stages` is a ModuleList including several
+ # shallow modules and STDCModules.
+ # (len(self.stages) ==
+ # self.num_shallow_features + len(self.stage_strides))
+ if self.with_final_conv:
+ self.final_conv = ConvModule(
+ self.channels[-1],
+ max(1024, self.channels[-1]),
+ 1,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+
+ def _make_stage(self, in_channels, out_channels, strides, norm_cfg,
+ act_cfg, bottleneck_type):
+ layers = []
+ for i, stride in enumerate(strides):
+ layers.append(
+ STDCModule(
+ in_channels if i == 0 else out_channels,
+ out_channels,
+ stride,
+ norm_cfg,
+ act_cfg,
+ num_convs=self.num_convs,
+ fusion_type=bottleneck_type))
+ return Sequential(*layers)
+
+ def forward(self, x):
+ outs = []
+ for stage in self.stages:
+ x = stage(x)
+ outs.append(x)
+ if self.with_final_conv:
+ outs[-1] = self.final_conv(outs[-1])
+ outs = outs[self.num_shallow_features:]
+ return tuple(outs)
+
+
+@BACKBONES.register_module()
+class STDCContextPathNet(BaseModule):
+ """STDCNet with Context Path. The `outs` below is a list of three feature
+ maps from deep to shallow, whose height and width is from small to big,
+ respectively. The biggest feature map of `outs` is outputted for
+ `STDCHead`, where Detail Loss would be calculated by Detail Ground-truth.
+ The other two feature maps are used for Attention Refinement Module,
+ respectively. Besides, the biggest feature map of `outs` and the last
+ output of Attention Refinement Module are concatenated for Feature Fusion
+ Module. Then, this fusion feature map `feat_fuse` would be outputted for
+ `decode_head`. More details please refer to Figure 4 of original paper.
+
+ Args:
+ backbone_cfg (dict): Config dict for stdc backbone.
+ last_in_channels (tuple(int)), The number of channels of last
+ two feature maps from stdc backbone. Default: (1024, 512).
+ out_channels (int): The channels of output feature maps.
+ Default: 128.
+ ffm_cfg (dict): Config dict for Feature Fusion Module. Default:
+ `dict(in_channels=512, out_channels=256, scale_factor=4)`.
+ upsample_mode (str): Algorithm used for upsampling:
+ ``'nearest'`` | ``'linear'`` | ``'bilinear'`` | ``'bicubic'`` |
+ ``'trilinear'``. Default: ``'nearest'``.
+ align_corners (str): align_corners argument of F.interpolate. It
+ must be `None` if upsample_mode is ``'nearest'``. Default: None.
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='BN').
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+
+ Return:
+ outputs (tuple): The tuple of list of output feature map for
+ auxiliary heads and decoder head.
+ """
+
+ def __init__(self,
+ backbone_cfg,
+ last_in_channels=(1024, 512),
+ out_channels=128,
+ ffm_cfg=dict(
+ in_channels=512, out_channels=256, scale_factor=4),
+ upsample_mode='nearest',
+ align_corners=None,
+ norm_cfg=dict(type='BN'),
+ init_cfg=None):
+ super(STDCContextPathNet, self).__init__(init_cfg=init_cfg)
+ self.backbone = build_backbone(backbone_cfg)
+ self.arms = ModuleList()
+ self.convs = ModuleList()
+ for channels in last_in_channels:
+ self.arms.append(AttentionRefinementModule(channels, out_channels))
+ self.convs.append(
+ ConvModule(
+ out_channels,
+ out_channels,
+ 3,
+ padding=1,
+ norm_cfg=norm_cfg))
+ self.conv_avg = ConvModule(
+ last_in_channels[0], out_channels, 1, norm_cfg=norm_cfg)
+
+ self.ffm = FeatureFusionModule(**ffm_cfg)
+
+ self.upsample_mode = upsample_mode
+ self.align_corners = align_corners
+
+ def forward(self, x):
+ outs = list(self.backbone(x))
+ avg = F.adaptive_avg_pool2d(outs[-1], 1)
+ avg_feat = self.conv_avg(avg)
+
+ feature_up = resize(
+ avg_feat,
+ size=outs[-1].shape[2:],
+ mode=self.upsample_mode,
+ align_corners=self.align_corners)
+ arms_out = []
+ for i in range(len(self.arms)):
+ x_arm = self.arms[i](outs[len(outs) - 1 - i]) + feature_up
+ feature_up = resize(
+ x_arm,
+ size=outs[len(outs) - 1 - i - 1].shape[2:],
+ mode=self.upsample_mode,
+ align_corners=self.align_corners)
+ feature_up = self.convs[i](feature_up)
+ arms_out.append(feature_up)
+
+ feat_fuse = self.ffm(outs[0], arms_out[1])
+
+ # The `outputs` has four feature maps.
+ # `outs[0]` is outputted for `STDCHead` auxiliary head.
+ # Two feature maps of `arms_out` are outputted for auxiliary head.
+ # `feat_fuse` is outputted for decoder head.
+ outputs = [outs[0]] + list(arms_out) + [feat_fuse]
+ return tuple(outputs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/swin.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/swin.py
new file mode 100644
index 0000000000000000000000000000000000000000..cbf13288aff055b2e87dfe08849c6b4b4831424d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/swin.py
@@ -0,0 +1,756 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import warnings
+from collections import OrderedDict
+from copy import deepcopy
+
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+import torch.utils.checkpoint as cp
+from mmcv.cnn import build_norm_layer
+from mmcv.cnn.bricks.transformer import FFN, build_dropout
+from mmcv.cnn.utils.weight_init import (constant_init, trunc_normal_,
+ trunc_normal_init)
+from mmcv.runner import (BaseModule, CheckpointLoader, ModuleList,
+ load_state_dict)
+from mmcv.utils import to_2tuple
+
+from ...utils import get_root_logger
+from ..builder import BACKBONES
+from ..utils.embed import PatchEmbed, PatchMerging
+
+
+class WindowMSA(BaseModule):
+ """Window based multi-head self-attention (W-MSA) module with relative
+ position bias.
+
+ Args:
+ embed_dims (int): Number of input channels.
+ num_heads (int): Number of attention heads.
+ window_size (tuple[int]): The height and width of the window.
+ qkv_bias (bool, optional): If True, add a learnable bias to q, k, v.
+ Default: True.
+ qk_scale (float | None, optional): Override default qk scale of
+ head_dim ** -0.5 if set. Default: None.
+ attn_drop_rate (float, optional): Dropout ratio of attention weight.
+ Default: 0.0
+ proj_drop_rate (float, optional): Dropout ratio of output. Default: 0.
+ init_cfg (dict | None, optional): The Config for initialization.
+ Default: None.
+ """
+
+ def __init__(self,
+ embed_dims,
+ num_heads,
+ window_size,
+ qkv_bias=True,
+ qk_scale=None,
+ attn_drop_rate=0.,
+ proj_drop_rate=0.,
+ init_cfg=None):
+
+ super().__init__(init_cfg=init_cfg)
+ self.embed_dims = embed_dims
+ self.window_size = window_size # Wh, Ww
+ self.num_heads = num_heads
+ head_embed_dims = embed_dims // num_heads
+ self.scale = qk_scale or head_embed_dims**-0.5
+
+ # define a parameter table of relative position bias
+ self.relative_position_bias_table = nn.Parameter(
+ torch.zeros((2 * window_size[0] - 1) * (2 * window_size[1] - 1),
+ num_heads)) # 2*Wh-1 * 2*Ww-1, nH
+
+ # About 2x faster than original impl
+ Wh, Ww = self.window_size
+ rel_index_coords = self.double_step_seq(2 * Ww - 1, Wh, 1, Ww)
+ rel_position_index = rel_index_coords + rel_index_coords.T
+ rel_position_index = rel_position_index.flip(1).contiguous()
+ self.register_buffer('relative_position_index', rel_position_index)
+
+ self.qkv = nn.Linear(embed_dims, embed_dims * 3, bias=qkv_bias)
+ self.attn_drop = nn.Dropout(attn_drop_rate)
+ self.proj = nn.Linear(embed_dims, embed_dims)
+ self.proj_drop = nn.Dropout(proj_drop_rate)
+
+ self.softmax = nn.Softmax(dim=-1)
+
+ def init_weights(self):
+ trunc_normal_(self.relative_position_bias_table, std=0.02)
+
+ def forward(self, x, mask=None):
+ """
+ Args:
+
+ x (tensor): input features with shape of (num_windows*B, N, C)
+ mask (tensor | None, Optional): mask with shape of (num_windows,
+ Wh*Ww, Wh*Ww), value should be between (-inf, 0].
+ """
+ B, N, C = x.shape
+ qkv = self.qkv(x).reshape(B, N, 3, self.num_heads,
+ C // self.num_heads).permute(2, 0, 3, 1, 4)
+ # make torchscript happy (cannot use tensor as tuple)
+ q, k, v = qkv[0], qkv[1], qkv[2]
+
+ q = q * self.scale
+ attn = (q @ k.transpose(-2, -1))
+
+ relative_position_bias = self.relative_position_bias_table[
+ self.relative_position_index.view(-1)].view(
+ self.window_size[0] * self.window_size[1],
+ self.window_size[0] * self.window_size[1],
+ -1) # Wh*Ww,Wh*Ww,nH
+ relative_position_bias = relative_position_bias.permute(
+ 2, 0, 1).contiguous() # nH, Wh*Ww, Wh*Ww
+ attn = attn + relative_position_bias.unsqueeze(0)
+
+ if mask is not None:
+ nW = mask.shape[0]
+ attn = attn.view(B // nW, nW, self.num_heads, N,
+ N) + mask.unsqueeze(1).unsqueeze(0)
+ attn = attn.view(-1, self.num_heads, N, N)
+ attn = self.softmax(attn)
+
+ attn = self.attn_drop(attn)
+
+ x = (attn @ v).transpose(1, 2).reshape(B, N, C)
+ x = self.proj(x)
+ x = self.proj_drop(x)
+ return x
+
+ @staticmethod
+ def double_step_seq(step1, len1, step2, len2):
+ seq1 = torch.arange(0, step1 * len1, step1)
+ seq2 = torch.arange(0, step2 * len2, step2)
+ return (seq1[:, None] + seq2[None, :]).reshape(1, -1)
+
+
+class ShiftWindowMSA(BaseModule):
+ """Shifted Window Multihead Self-Attention Module.
+
+ Args:
+ embed_dims (int): Number of input channels.
+ num_heads (int): Number of attention heads.
+ window_size (int): The height and width of the window.
+ shift_size (int, optional): The shift step of each window towards
+ right-bottom. If zero, act as regular window-msa. Defaults to 0.
+ qkv_bias (bool, optional): If True, add a learnable bias to q, k, v.
+ Default: True
+ qk_scale (float | None, optional): Override default qk scale of
+ head_dim ** -0.5 if set. Defaults: None.
+ attn_drop_rate (float, optional): Dropout ratio of attention weight.
+ Defaults: 0.
+ proj_drop_rate (float, optional): Dropout ratio of output.
+ Defaults: 0.
+ dropout_layer (dict, optional): The dropout_layer used before output.
+ Defaults: dict(type='DropPath', drop_prob=0.).
+ init_cfg (dict, optional): The extra config for initialization.
+ Default: None.
+ """
+
+ def __init__(self,
+ embed_dims,
+ num_heads,
+ window_size,
+ shift_size=0,
+ qkv_bias=True,
+ qk_scale=None,
+ attn_drop_rate=0,
+ proj_drop_rate=0,
+ dropout_layer=dict(type='DropPath', drop_prob=0.),
+ init_cfg=None):
+ super().__init__(init_cfg=init_cfg)
+
+ self.window_size = window_size
+ self.shift_size = shift_size
+ assert 0 <= self.shift_size < self.window_size
+
+ self.w_msa = WindowMSA(
+ embed_dims=embed_dims,
+ num_heads=num_heads,
+ window_size=to_2tuple(window_size),
+ qkv_bias=qkv_bias,
+ qk_scale=qk_scale,
+ attn_drop_rate=attn_drop_rate,
+ proj_drop_rate=proj_drop_rate,
+ init_cfg=None)
+
+ self.drop = build_dropout(dropout_layer)
+
+ def forward(self, query, hw_shape):
+ B, L, C = query.shape
+ H, W = hw_shape
+ assert L == H * W, 'input feature has wrong size'
+ query = query.view(B, H, W, C)
+
+ # pad feature maps to multiples of window size
+ pad_r = (self.window_size - W % self.window_size) % self.window_size
+ pad_b = (self.window_size - H % self.window_size) % self.window_size
+ query = F.pad(query, (0, 0, 0, pad_r, 0, pad_b))
+ H_pad, W_pad = query.shape[1], query.shape[2]
+
+ # cyclic shift
+ if self.shift_size > 0:
+ shifted_query = torch.roll(
+ query,
+ shifts=(-self.shift_size, -self.shift_size),
+ dims=(1, 2))
+
+ # calculate attention mask for SW-MSA
+ img_mask = torch.zeros((1, H_pad, W_pad, 1), device=query.device)
+ h_slices = (slice(0, -self.window_size),
+ slice(-self.window_size,
+ -self.shift_size), slice(-self.shift_size, None))
+ w_slices = (slice(0, -self.window_size),
+ slice(-self.window_size,
+ -self.shift_size), slice(-self.shift_size, None))
+ cnt = 0
+ for h in h_slices:
+ for w in w_slices:
+ img_mask[:, h, w, :] = cnt
+ cnt += 1
+
+ # nW, window_size, window_size, 1
+ mask_windows = self.window_partition(img_mask)
+ mask_windows = mask_windows.view(
+ -1, self.window_size * self.window_size)
+ attn_mask = mask_windows.unsqueeze(1) - mask_windows.unsqueeze(2)
+ attn_mask = attn_mask.masked_fill(attn_mask != 0,
+ float(-100.0)).masked_fill(
+ attn_mask == 0, float(0.0))
+ else:
+ shifted_query = query
+ attn_mask = None
+
+ # nW*B, window_size, window_size, C
+ query_windows = self.window_partition(shifted_query)
+ # nW*B, window_size*window_size, C
+ query_windows = query_windows.view(-1, self.window_size**2, C)
+
+ # W-MSA/SW-MSA (nW*B, window_size*window_size, C)
+ attn_windows = self.w_msa(query_windows, mask=attn_mask)
+
+ # merge windows
+ attn_windows = attn_windows.view(-1, self.window_size,
+ self.window_size, C)
+
+ # B H' W' C
+ shifted_x = self.window_reverse(attn_windows, H_pad, W_pad)
+ # reverse cyclic shift
+ if self.shift_size > 0:
+ x = torch.roll(
+ shifted_x,
+ shifts=(self.shift_size, self.shift_size),
+ dims=(1, 2))
+ else:
+ x = shifted_x
+
+ if pad_r > 0 or pad_b:
+ x = x[:, :H, :W, :].contiguous()
+
+ x = x.view(B, H * W, C)
+
+ x = self.drop(x)
+ return x
+
+ def window_reverse(self, windows, H, W):
+ """
+ Args:
+ windows: (num_windows*B, window_size, window_size, C)
+ H (int): Height of image
+ W (int): Width of image
+ Returns:
+ x: (B, H, W, C)
+ """
+ window_size = self.window_size
+ B = int(windows.shape[0] / (H * W / window_size / window_size))
+ x = windows.view(B, H // window_size, W // window_size, window_size,
+ window_size, -1)
+ x = x.permute(0, 1, 3, 2, 4, 5).contiguous().view(B, H, W, -1)
+ return x
+
+ def window_partition(self, x):
+ """
+ Args:
+ x: (B, H, W, C)
+ Returns:
+ windows: (num_windows*B, window_size, window_size, C)
+ """
+ B, H, W, C = x.shape
+ window_size = self.window_size
+ x = x.view(B, H // window_size, window_size, W // window_size,
+ window_size, C)
+ windows = x.permute(0, 1, 3, 2, 4, 5).contiguous()
+ windows = windows.view(-1, window_size, window_size, C)
+ return windows
+
+
+class SwinBlock(BaseModule):
+ """"
+ Args:
+ embed_dims (int): The feature dimension.
+ num_heads (int): Parallel attention heads.
+ feedforward_channels (int): The hidden dimension for FFNs.
+ window_size (int, optional): The local window scale. Default: 7.
+ shift (bool, optional): whether to shift window or not. Default False.
+ qkv_bias (bool, optional): enable bias for qkv if True. Default: True.
+ qk_scale (float | None, optional): Override default qk scale of
+ head_dim ** -0.5 if set. Default: None.
+ drop_rate (float, optional): Dropout rate. Default: 0.
+ attn_drop_rate (float, optional): Attention dropout rate. Default: 0.
+ drop_path_rate (float, optional): Stochastic depth rate. Default: 0.
+ act_cfg (dict, optional): The config dict of activation function.
+ Default: dict(type='GELU').
+ norm_cfg (dict, optional): The config dict of normalization.
+ Default: dict(type='LN').
+ with_cp (bool, optional): Use checkpoint or not. Using checkpoint
+ will save some memory while slowing down the training speed.
+ Default: False.
+ init_cfg (dict | list | None, optional): The init config.
+ Default: None.
+ """
+
+ def __init__(self,
+ embed_dims,
+ num_heads,
+ feedforward_channels,
+ window_size=7,
+ shift=False,
+ qkv_bias=True,
+ qk_scale=None,
+ drop_rate=0.,
+ attn_drop_rate=0.,
+ drop_path_rate=0.,
+ act_cfg=dict(type='GELU'),
+ norm_cfg=dict(type='LN'),
+ with_cp=False,
+ init_cfg=None):
+
+ super(SwinBlock, self).__init__(init_cfg=init_cfg)
+
+ self.with_cp = with_cp
+
+ self.norm1 = build_norm_layer(norm_cfg, embed_dims)[1]
+ self.attn = ShiftWindowMSA(
+ embed_dims=embed_dims,
+ num_heads=num_heads,
+ window_size=window_size,
+ shift_size=window_size // 2 if shift else 0,
+ qkv_bias=qkv_bias,
+ qk_scale=qk_scale,
+ attn_drop_rate=attn_drop_rate,
+ proj_drop_rate=drop_rate,
+ dropout_layer=dict(type='DropPath', drop_prob=drop_path_rate),
+ init_cfg=None)
+
+ self.norm2 = build_norm_layer(norm_cfg, embed_dims)[1]
+ self.ffn = FFN(
+ embed_dims=embed_dims,
+ feedforward_channels=feedforward_channels,
+ num_fcs=2,
+ ffn_drop=drop_rate,
+ dropout_layer=dict(type='DropPath', drop_prob=drop_path_rate),
+ act_cfg=act_cfg,
+ add_identity=True,
+ init_cfg=None)
+
+ def forward(self, x, hw_shape):
+
+ def _inner_forward(x):
+ identity = x
+ x = self.norm1(x)
+ x = self.attn(x, hw_shape)
+
+ x = x + identity
+
+ identity = x
+ x = self.norm2(x)
+ x = self.ffn(x, identity=identity)
+
+ return x
+
+ if self.with_cp and x.requires_grad:
+ x = cp.checkpoint(_inner_forward, x)
+ else:
+ x = _inner_forward(x)
+
+ return x
+
+
+class SwinBlockSequence(BaseModule):
+ """Implements one stage in Swin Transformer.
+
+ Args:
+ embed_dims (int): The feature dimension.
+ num_heads (int): Parallel attention heads.
+ feedforward_channels (int): The hidden dimension for FFNs.
+ depth (int): The number of blocks in this stage.
+ window_size (int, optional): The local window scale. Default: 7.
+ qkv_bias (bool, optional): enable bias for qkv if True. Default: True.
+ qk_scale (float | None, optional): Override default qk scale of
+ head_dim ** -0.5 if set. Default: None.
+ drop_rate (float, optional): Dropout rate. Default: 0.
+ attn_drop_rate (float, optional): Attention dropout rate. Default: 0.
+ drop_path_rate (float | list[float], optional): Stochastic depth
+ rate. Default: 0.
+ downsample (BaseModule | None, optional): The downsample operation
+ module. Default: None.
+ act_cfg (dict, optional): The config dict of activation function.
+ Default: dict(type='GELU').
+ norm_cfg (dict, optional): The config dict of normalization.
+ Default: dict(type='LN').
+ with_cp (bool, optional): Use checkpoint or not. Using checkpoint
+ will save some memory while slowing down the training speed.
+ Default: False.
+ init_cfg (dict | list | None, optional): The init config.
+ Default: None.
+ """
+
+ def __init__(self,
+ embed_dims,
+ num_heads,
+ feedforward_channels,
+ depth,
+ window_size=7,
+ qkv_bias=True,
+ qk_scale=None,
+ drop_rate=0.,
+ attn_drop_rate=0.,
+ drop_path_rate=0.,
+ downsample=None,
+ act_cfg=dict(type='GELU'),
+ norm_cfg=dict(type='LN'),
+ with_cp=False,
+ init_cfg=None):
+ super().__init__(init_cfg=init_cfg)
+
+ if isinstance(drop_path_rate, list):
+ drop_path_rates = drop_path_rate
+ assert len(drop_path_rates) == depth
+ else:
+ drop_path_rates = [deepcopy(drop_path_rate) for _ in range(depth)]
+
+ self.blocks = ModuleList()
+ for i in range(depth):
+ block = SwinBlock(
+ embed_dims=embed_dims,
+ num_heads=num_heads,
+ feedforward_channels=feedforward_channels,
+ window_size=window_size,
+ shift=False if i % 2 == 0 else True,
+ qkv_bias=qkv_bias,
+ qk_scale=qk_scale,
+ drop_rate=drop_rate,
+ attn_drop_rate=attn_drop_rate,
+ drop_path_rate=drop_path_rates[i],
+ act_cfg=act_cfg,
+ norm_cfg=norm_cfg,
+ with_cp=with_cp,
+ init_cfg=None)
+ self.blocks.append(block)
+
+ self.downsample = downsample
+
+ def forward(self, x, hw_shape):
+ for block in self.blocks:
+ x = block(x, hw_shape)
+
+ if self.downsample:
+ x_down, down_hw_shape = self.downsample(x, hw_shape)
+ return x_down, down_hw_shape, x, hw_shape
+ else:
+ return x, hw_shape, x, hw_shape
+
+
+@BACKBONES.register_module()
+class SwinTransformer(BaseModule):
+ """Swin Transformer backbone.
+
+ This backbone is the implementation of `Swin Transformer:
+ Hierarchical Vision Transformer using Shifted
+ Windows `_.
+ Inspiration from https://github.com/microsoft/Swin-Transformer.
+
+ Args:
+ pretrain_img_size (int | tuple[int]): The size of input image when
+ pretrain. Defaults: 224.
+ in_channels (int): The num of input channels.
+ Defaults: 3.
+ embed_dims (int): The feature dimension. Default: 96.
+ patch_size (int | tuple[int]): Patch size. Default: 4.
+ window_size (int): Window size. Default: 7.
+ mlp_ratio (int | float): Ratio of mlp hidden dim to embedding dim.
+ Default: 4.
+ depths (tuple[int]): Depths of each Swin Transformer stage.
+ Default: (2, 2, 6, 2).
+ num_heads (tuple[int]): Parallel attention heads of each Swin
+ Transformer stage. Default: (3, 6, 12, 24).
+ strides (tuple[int]): The patch merging or patch embedding stride of
+ each Swin Transformer stage. (In swin, we set kernel size equal to
+ stride.) Default: (4, 2, 2, 2).
+ out_indices (tuple[int]): Output from which stages.
+ Default: (0, 1, 2, 3).
+ qkv_bias (bool, optional): If True, add a learnable bias to query, key,
+ value. Default: True
+ qk_scale (float | None, optional): Override default qk scale of
+ head_dim ** -0.5 if set. Default: None.
+ patch_norm (bool): If add a norm layer for patch embed and patch
+ merging. Default: True.
+ drop_rate (float): Dropout rate. Defaults: 0.
+ attn_drop_rate (float): Attention dropout rate. Default: 0.
+ drop_path_rate (float): Stochastic depth rate. Defaults: 0.1.
+ use_abs_pos_embed (bool): If True, add absolute position embedding to
+ the patch embedding. Defaults: False.
+ act_cfg (dict): Config dict for activation layer.
+ Default: dict(type='LN').
+ norm_cfg (dict): Config dict for normalization layer at
+ output of backone. Defaults: dict(type='LN').
+ with_cp (bool, optional): Use checkpoint or not. Using checkpoint
+ will save some memory while slowing down the training speed.
+ Default: False.
+ pretrained (str, optional): model pretrained path. Default: None.
+ frozen_stages (int): Stages to be frozen (stop grad and set eval mode).
+ -1 means not freezing any parameters.
+ init_cfg (dict, optional): The Config for initialization.
+ Defaults to None.
+ """
+
+ def __init__(self,
+ pretrain_img_size=224,
+ in_channels=3,
+ embed_dims=96,
+ patch_size=4,
+ window_size=7,
+ mlp_ratio=4,
+ depths=(2, 2, 6, 2),
+ num_heads=(3, 6, 12, 24),
+ strides=(4, 2, 2, 2),
+ out_indices=(0, 1, 2, 3),
+ qkv_bias=True,
+ qk_scale=None,
+ patch_norm=True,
+ drop_rate=0.,
+ attn_drop_rate=0.,
+ drop_path_rate=0.1,
+ use_abs_pos_embed=False,
+ act_cfg=dict(type='GELU'),
+ norm_cfg=dict(type='LN'),
+ with_cp=False,
+ pretrained=None,
+ frozen_stages=-1,
+ init_cfg=None):
+ self.frozen_stages = frozen_stages
+
+ if isinstance(pretrain_img_size, int):
+ pretrain_img_size = to_2tuple(pretrain_img_size)
+ elif isinstance(pretrain_img_size, tuple):
+ if len(pretrain_img_size) == 1:
+ pretrain_img_size = to_2tuple(pretrain_img_size[0])
+ assert len(pretrain_img_size) == 2, \
+ f'The size of image should have length 1 or 2, ' \
+ f'but got {len(pretrain_img_size)}'
+
+ assert not (init_cfg and pretrained), \
+ 'init_cfg and pretrained cannot be specified at the same time'
+ if isinstance(pretrained, str):
+ warnings.warn('DeprecationWarning: pretrained is deprecated, '
+ 'please use "init_cfg" instead')
+ init_cfg = dict(type='Pretrained', checkpoint=pretrained)
+ elif pretrained is None:
+ init_cfg = init_cfg
+ else:
+ raise TypeError('pretrained must be a str or None')
+
+ super(SwinTransformer, self).__init__(init_cfg=init_cfg)
+
+ num_layers = len(depths)
+ self.out_indices = out_indices
+ self.use_abs_pos_embed = use_abs_pos_embed
+
+ assert strides[0] == patch_size, 'Use non-overlapping patch embed.'
+
+ self.patch_embed = PatchEmbed(
+ in_channels=in_channels,
+ embed_dims=embed_dims,
+ conv_type='Conv2d',
+ kernel_size=patch_size,
+ stride=strides[0],
+ padding='corner',
+ norm_cfg=norm_cfg if patch_norm else None,
+ init_cfg=None)
+
+ if self.use_abs_pos_embed:
+ patch_row = pretrain_img_size[0] // patch_size
+ patch_col = pretrain_img_size[1] // patch_size
+ num_patches = patch_row * patch_col
+ self.absolute_pos_embed = nn.Parameter(
+ torch.zeros((1, num_patches, embed_dims)))
+
+ self.drop_after_pos = nn.Dropout(p=drop_rate)
+
+ # set stochastic depth decay rule
+ total_depth = sum(depths)
+ dpr = [
+ x.item() for x in torch.linspace(0, drop_path_rate, total_depth)
+ ]
+
+ self.stages = ModuleList()
+ in_channels = embed_dims
+ for i in range(num_layers):
+ if i < num_layers - 1:
+ downsample = PatchMerging(
+ in_channels=in_channels,
+ out_channels=2 * in_channels,
+ stride=strides[i + 1],
+ norm_cfg=norm_cfg if patch_norm else None,
+ init_cfg=None)
+ else:
+ downsample = None
+
+ stage = SwinBlockSequence(
+ embed_dims=in_channels,
+ num_heads=num_heads[i],
+ feedforward_channels=int(mlp_ratio * in_channels),
+ depth=depths[i],
+ window_size=window_size,
+ qkv_bias=qkv_bias,
+ qk_scale=qk_scale,
+ drop_rate=drop_rate,
+ attn_drop_rate=attn_drop_rate,
+ drop_path_rate=dpr[sum(depths[:i]):sum(depths[:i + 1])],
+ downsample=downsample,
+ act_cfg=act_cfg,
+ norm_cfg=norm_cfg,
+ with_cp=with_cp,
+ init_cfg=None)
+ self.stages.append(stage)
+ if downsample:
+ in_channels = downsample.out_channels
+
+ self.num_features = [int(embed_dims * 2**i) for i in range(num_layers)]
+ # Add a norm layer for each output
+ for i in out_indices:
+ layer = build_norm_layer(norm_cfg, self.num_features[i])[1]
+ layer_name = f'norm{i}'
+ self.add_module(layer_name, layer)
+
+ def train(self, mode=True):
+ """Convert the model into training mode while keep layers freezed."""
+ super(SwinTransformer, self).train(mode)
+ self._freeze_stages()
+
+ def _freeze_stages(self):
+ if self.frozen_stages >= 0:
+ self.patch_embed.eval()
+ for param in self.patch_embed.parameters():
+ param.requires_grad = False
+ if self.use_abs_pos_embed:
+ self.absolute_pos_embed.requires_grad = False
+ self.drop_after_pos.eval()
+
+ for i in range(1, self.frozen_stages + 1):
+
+ if (i - 1) in self.out_indices:
+ norm_layer = getattr(self, f'norm{i-1}')
+ norm_layer.eval()
+ for param in norm_layer.parameters():
+ param.requires_grad = False
+
+ m = self.stages[i - 1]
+ m.eval()
+ for param in m.parameters():
+ param.requires_grad = False
+
+ def init_weights(self):
+ logger = get_root_logger()
+ if self.init_cfg is None:
+ logger.warn(f'No pre-trained weights for '
+ f'{self.__class__.__name__}, '
+ f'training start from scratch')
+ if self.use_abs_pos_embed:
+ trunc_normal_(self.absolute_pos_embed, std=0.02)
+ for m in self.modules():
+ if isinstance(m, nn.Linear):
+ trunc_normal_init(m, std=.02, bias=0.)
+ elif isinstance(m, nn.LayerNorm):
+ constant_init(m, val=1.0, bias=0.)
+ else:
+ assert 'checkpoint' in self.init_cfg, f'Only support ' \
+ f'specify `Pretrained` in ' \
+ f'`init_cfg` in ' \
+ f'{self.__class__.__name__} '
+ ckpt = CheckpointLoader.load_checkpoint(
+ self.init_cfg['checkpoint'], logger=logger, map_location='cpu')
+ if 'state_dict' in ckpt:
+ _state_dict = ckpt['state_dict']
+ elif 'model' in ckpt:
+ _state_dict = ckpt['model']
+ else:
+ _state_dict = ckpt
+
+ state_dict = OrderedDict()
+ for k, v in _state_dict.items():
+ if k.startswith('backbone.'):
+ state_dict[k[9:]] = v
+ else:
+ state_dict[k] = v
+
+ # strip prefix of state_dict
+ if list(state_dict.keys())[0].startswith('module.'):
+ state_dict = {k[7:]: v for k, v in state_dict.items()}
+
+ # reshape absolute position embedding
+ if state_dict.get('absolute_pos_embed') is not None:
+ absolute_pos_embed = state_dict['absolute_pos_embed']
+ N1, L, C1 = absolute_pos_embed.size()
+ N2, C2, H, W = self.absolute_pos_embed.size()
+ if N1 != N2 or C1 != C2 or L != H * W:
+ logger.warning('Error in loading absolute_pos_embed, pass')
+ else:
+ state_dict['absolute_pos_embed'] = absolute_pos_embed.view(
+ N2, H, W, C2).permute(0, 3, 1, 2).contiguous()
+
+ # interpolate position bias table if needed
+ relative_position_bias_table_keys = [
+ k for k in state_dict.keys()
+ if 'relative_position_bias_table' in k
+ ]
+ for table_key in relative_position_bias_table_keys:
+ table_pretrained = state_dict[table_key]
+ table_current = self.state_dict()[table_key]
+ L1, nH1 = table_pretrained.size()
+ L2, nH2 = table_current.size()
+ if nH1 != nH2:
+ logger.warning(f'Error in loading {table_key}, pass')
+ elif L1 != L2:
+ S1 = int(L1**0.5)
+ S2 = int(L2**0.5)
+ table_pretrained_resized = F.interpolate(
+ table_pretrained.permute(1, 0).reshape(1, nH1, S1, S1),
+ size=(S2, S2),
+ mode='bicubic')
+ state_dict[table_key] = table_pretrained_resized.view(
+ nH2, L2).permute(1, 0).contiguous()
+
+ # load state_dict
+ load_state_dict(self, state_dict, strict=False, logger=logger)
+
+ def forward(self, x):
+ x, hw_shape = self.patch_embed(x)
+
+ if self.use_abs_pos_embed:
+ x = x + self.absolute_pos_embed
+ x = self.drop_after_pos(x)
+
+ outs = []
+ for i, stage in enumerate(self.stages):
+ x, hw_shape, out, out_hw_shape = stage(x, hw_shape)
+ if i in self.out_indices:
+ norm_layer = getattr(self, f'norm{i}')
+ out = norm_layer(out)
+ out = out.view(-1, *out_hw_shape,
+ self.num_features[i]).permute(0, 3, 1,
+ 2).contiguous()
+ outs.append(out)
+
+ return outs
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/timm_backbone.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/timm_backbone.py
new file mode 100644
index 0000000000000000000000000000000000000000..01b29fc5ed9f8f0cfbfc25aca8f8628e1f2670d6
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/timm_backbone.py
@@ -0,0 +1,63 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+try:
+ import timm
+except ImportError:
+ timm = None
+
+from mmcv.cnn.bricks.registry import NORM_LAYERS
+from mmcv.runner import BaseModule
+
+from ..builder import BACKBONES
+
+
+@BACKBONES.register_module()
+class TIMMBackbone(BaseModule):
+ """Wrapper to use backbones from timm library. More details can be found in
+ `timm `_ .
+
+ Args:
+ model_name (str): Name of timm model to instantiate.
+ pretrained (bool): Load pretrained weights if True.
+ checkpoint_path (str): Path of checkpoint to load after
+ model is initialized.
+ in_channels (int): Number of input image channels. Default: 3.
+ init_cfg (dict, optional): Initialization config dict
+ **kwargs: Other timm & model specific arguments.
+ """
+
+ def __init__(
+ self,
+ model_name,
+ features_only=True,
+ pretrained=True,
+ checkpoint_path='',
+ in_channels=3,
+ init_cfg=None,
+ **kwargs,
+ ):
+ if timm is None:
+ raise RuntimeError('timm is not installed')
+ super(TIMMBackbone, self).__init__(init_cfg)
+ if 'norm_layer' in kwargs:
+ kwargs['norm_layer'] = NORM_LAYERS.get(kwargs['norm_layer'])
+ self.timm_model = timm.create_model(
+ model_name=model_name,
+ features_only=features_only,
+ pretrained=pretrained,
+ in_chans=in_channels,
+ checkpoint_path=checkpoint_path,
+ **kwargs,
+ )
+
+ # Make unused parameters None
+ self.timm_model.global_pool = None
+ self.timm_model.fc = None
+ self.timm_model.classifier = None
+
+ # Hack to use pretrained weights from timm
+ if pretrained or checkpoint_path:
+ self._is_init = True
+
+ def forward(self, x):
+ features = self.timm_model(x)
+ return features
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/twins.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/twins.py
new file mode 100644
index 0000000000000000000000000000000000000000..6bd9469118ca76a0fe87e04e8a52dd8144791a43
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/twins.py
@@ -0,0 +1,588 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import math
+import warnings
+
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+from mmcv.cnn import build_norm_layer
+from mmcv.cnn.bricks.drop import build_dropout
+from mmcv.cnn.bricks.transformer import FFN
+from mmcv.cnn.utils.weight_init import (constant_init, normal_init,
+ trunc_normal_init)
+from mmcv.runner import BaseModule, ModuleList
+from torch.nn.modules.batchnorm import _BatchNorm
+
+from mmseg.models.backbones.mit import EfficientMultiheadAttention
+from mmseg.models.builder import BACKBONES
+from ..utils.embed import PatchEmbed
+
+
+class GlobalSubsampledAttention(EfficientMultiheadAttention):
+ """Global Sub-sampled Attention (Spatial Reduction Attention)
+
+ This module is modified from EfficientMultiheadAttention,
+ which is a module from mmseg.models.backbones.mit.py.
+ Specifically, there is no difference between
+ `GlobalSubsampledAttention` and `EfficientMultiheadAttention`,
+ `GlobalSubsampledAttention` is built as a brand new class
+ because it is renamed as `Global sub-sampled attention (GSA)`
+ in paper.
+
+
+ Args:
+ embed_dims (int): The embedding dimension.
+ num_heads (int): Parallel attention heads.
+ attn_drop (float): A Dropout layer on attn_output_weights.
+ Default: 0.0.
+ proj_drop (float): A Dropout layer after `nn.MultiheadAttention`.
+ Default: 0.0.
+ dropout_layer (obj:`ConfigDict`): The dropout_layer used
+ when adding the shortcut. Default: None.
+ batch_first (bool): Key, Query and Value are shape of
+ (batch, n, embed_dims)
+ or (n, batch, embed_dims). Default: False.
+ qkv_bias (bool): enable bias for qkv if True. Default: True.
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='LN').
+ sr_ratio (int): The ratio of spatial reduction of GSA of PCPVT.
+ Default: 1.
+ init_cfg (dict, optional): The Config for initialization.
+ Defaults to None.
+ """
+
+ def __init__(self,
+ embed_dims,
+ num_heads,
+ attn_drop=0.,
+ proj_drop=0.,
+ dropout_layer=None,
+ batch_first=True,
+ qkv_bias=True,
+ norm_cfg=dict(type='LN'),
+ sr_ratio=1,
+ init_cfg=None):
+ super(GlobalSubsampledAttention, self).__init__(
+ embed_dims,
+ num_heads,
+ attn_drop=attn_drop,
+ proj_drop=proj_drop,
+ dropout_layer=dropout_layer,
+ batch_first=batch_first,
+ qkv_bias=qkv_bias,
+ norm_cfg=norm_cfg,
+ sr_ratio=sr_ratio,
+ init_cfg=init_cfg)
+
+
+class GSAEncoderLayer(BaseModule):
+ """Implements one encoder layer with GSA.
+
+ Args:
+ embed_dims (int): The feature dimension.
+ num_heads (int): Parallel attention heads.
+ feedforward_channels (int): The hidden dimension for FFNs.
+ drop_rate (float): Probability of an element to be zeroed
+ after the feed forward layer. Default: 0.0.
+ attn_drop_rate (float): The drop out rate for attention layer.
+ Default: 0.0.
+ drop_path_rate (float): Stochastic depth rate. Default 0.0.
+ num_fcs (int): The number of fully-connected layers for FFNs.
+ Default: 2.
+ qkv_bias (bool): Enable bias for qkv if True. Default: True
+ act_cfg (dict): The activation config for FFNs.
+ Default: dict(type='GELU').
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='LN').
+ sr_ratio (float): Kernel_size of conv in Attention modules. Default: 1.
+ init_cfg (dict, optional): The Config for initialization.
+ Defaults to None.
+ """
+
+ def __init__(self,
+ embed_dims,
+ num_heads,
+ feedforward_channels,
+ drop_rate=0.,
+ attn_drop_rate=0.,
+ drop_path_rate=0.,
+ num_fcs=2,
+ qkv_bias=True,
+ act_cfg=dict(type='GELU'),
+ norm_cfg=dict(type='LN'),
+ sr_ratio=1.,
+ init_cfg=None):
+ super(GSAEncoderLayer, self).__init__(init_cfg=init_cfg)
+
+ self.norm1 = build_norm_layer(norm_cfg, embed_dims, postfix=1)[1]
+ self.attn = GlobalSubsampledAttention(
+ embed_dims=embed_dims,
+ num_heads=num_heads,
+ attn_drop=attn_drop_rate,
+ proj_drop=drop_rate,
+ dropout_layer=dict(type='DropPath', drop_prob=drop_path_rate),
+ qkv_bias=qkv_bias,
+ norm_cfg=norm_cfg,
+ sr_ratio=sr_ratio)
+
+ self.norm2 = build_norm_layer(norm_cfg, embed_dims, postfix=2)[1]
+ self.ffn = FFN(
+ embed_dims=embed_dims,
+ feedforward_channels=feedforward_channels,
+ num_fcs=num_fcs,
+ ffn_drop=drop_rate,
+ dropout_layer=dict(type='DropPath', drop_prob=drop_path_rate),
+ act_cfg=act_cfg,
+ add_identity=False)
+
+ self.drop_path = build_dropout(
+ dict(type='DropPath', drop_prob=drop_path_rate)
+ ) if drop_path_rate > 0. else nn.Identity()
+
+ def forward(self, x, hw_shape):
+ x = x + self.drop_path(self.attn(self.norm1(x), hw_shape, identity=0.))
+ x = x + self.drop_path(self.ffn(self.norm2(x)))
+ return x
+
+
+class LocallyGroupedSelfAttention(BaseModule):
+ """Locally-grouped Self Attention (LSA) module.
+
+ Args:
+ embed_dims (int): Number of input channels.
+ num_heads (int): Number of attention heads. Default: 8
+ qkv_bias (bool, optional): If True, add a learnable bias to q, k, v.
+ Default: False.
+ qk_scale (float | None, optional): Override default qk scale of
+ head_dim ** -0.5 if set. Default: None.
+ attn_drop_rate (float, optional): Dropout ratio of attention weight.
+ Default: 0.0
+ proj_drop_rate (float, optional): Dropout ratio of output. Default: 0.
+ window_size(int): Window size of LSA. Default: 1.
+ init_cfg (dict, optional): The Config for initialization.
+ Defaults to None.
+ """
+
+ def __init__(self,
+ embed_dims,
+ num_heads=8,
+ qkv_bias=False,
+ qk_scale=None,
+ attn_drop_rate=0.,
+ proj_drop_rate=0.,
+ window_size=1,
+ init_cfg=None):
+ super(LocallyGroupedSelfAttention, self).__init__(init_cfg=init_cfg)
+
+ assert embed_dims % num_heads == 0, f'dim {embed_dims} should be ' \
+ f'divided by num_heads ' \
+ f'{num_heads}.'
+ self.embed_dims = embed_dims
+ self.num_heads = num_heads
+ head_dim = embed_dims // num_heads
+ self.scale = qk_scale or head_dim**-0.5
+
+ self.qkv = nn.Linear(embed_dims, embed_dims * 3, bias=qkv_bias)
+ self.attn_drop = nn.Dropout(attn_drop_rate)
+ self.proj = nn.Linear(embed_dims, embed_dims)
+ self.proj_drop = nn.Dropout(proj_drop_rate)
+ self.window_size = window_size
+
+ def forward(self, x, hw_shape):
+ b, n, c = x.shape
+ h, w = hw_shape
+ x = x.view(b, h, w, c)
+
+ # pad feature maps to multiples of Local-groups
+ pad_l = pad_t = 0
+ pad_r = (self.window_size - w % self.window_size) % self.window_size
+ pad_b = (self.window_size - h % self.window_size) % self.window_size
+ x = F.pad(x, (0, 0, pad_l, pad_r, pad_t, pad_b))
+
+ # calculate attention mask for LSA
+ Hp, Wp = x.shape[1:-1]
+ _h, _w = Hp // self.window_size, Wp // self.window_size
+ mask = torch.zeros((1, Hp, Wp), device=x.device)
+ mask[:, -pad_b:, :].fill_(1)
+ mask[:, :, -pad_r:].fill_(1)
+
+ # [B, _h, _w, window_size, window_size, C]
+ x = x.reshape(b, _h, self.window_size, _w, self.window_size,
+ c).transpose(2, 3)
+ mask = mask.reshape(1, _h, self.window_size, _w,
+ self.window_size).transpose(2, 3).reshape(
+ 1, _h * _w,
+ self.window_size * self.window_size)
+ # [1, _h*_w, window_size*window_size, window_size*window_size]
+ attn_mask = mask.unsqueeze(2) - mask.unsqueeze(3)
+ attn_mask = attn_mask.masked_fill(attn_mask != 0,
+ float(-1000.0)).masked_fill(
+ attn_mask == 0, float(0.0))
+
+ # [3, B, _w*_h, nhead, window_size*window_size, dim]
+ qkv = self.qkv(x).reshape(b, _h * _w,
+ self.window_size * self.window_size, 3,
+ self.num_heads, c // self.num_heads).permute(
+ 3, 0, 1, 4, 2, 5)
+ q, k, v = qkv[0], qkv[1], qkv[2]
+ # [B, _h*_w, n_head, window_size*window_size, window_size*window_size]
+ attn = (q @ k.transpose(-2, -1)) * self.scale
+ attn = attn + attn_mask.unsqueeze(2)
+ attn = attn.softmax(dim=-1)
+ attn = self.attn_drop(attn)
+ attn = (attn @ v).transpose(2, 3).reshape(b, _h, _w, self.window_size,
+ self.window_size, c)
+ x = attn.transpose(2, 3).reshape(b, _h * self.window_size,
+ _w * self.window_size, c)
+ if pad_r > 0 or pad_b > 0:
+ x = x[:, :h, :w, :].contiguous()
+
+ x = x.reshape(b, n, c)
+ x = self.proj(x)
+ x = self.proj_drop(x)
+ return x
+
+
+class LSAEncoderLayer(BaseModule):
+ """Implements one encoder layer in Twins-SVT.
+
+ Args:
+ embed_dims (int): The feature dimension.
+ num_heads (int): Parallel attention heads.
+ feedforward_channels (int): The hidden dimension for FFNs.
+ drop_rate (float): Probability of an element to be zeroed
+ after the feed forward layer. Default: 0.0.
+ attn_drop_rate (float, optional): Dropout ratio of attention weight.
+ Default: 0.0
+ drop_path_rate (float): Stochastic depth rate. Default 0.0.
+ num_fcs (int): The number of fully-connected layers for FFNs.
+ Default: 2.
+ qkv_bias (bool): Enable bias for qkv if True. Default: True
+ qk_scale (float | None, optional): Override default qk scale of
+ head_dim ** -0.5 if set. Default: None.
+ act_cfg (dict): The activation config for FFNs.
+ Default: dict(type='GELU').
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='LN').
+ window_size (int): Window size of LSA. Default: 1.
+ init_cfg (dict, optional): The Config for initialization.
+ Defaults to None.
+ """
+
+ def __init__(self,
+ embed_dims,
+ num_heads,
+ feedforward_channels,
+ drop_rate=0.,
+ attn_drop_rate=0.,
+ drop_path_rate=0.,
+ num_fcs=2,
+ qkv_bias=True,
+ qk_scale=None,
+ act_cfg=dict(type='GELU'),
+ norm_cfg=dict(type='LN'),
+ window_size=1,
+ init_cfg=None):
+
+ super(LSAEncoderLayer, self).__init__(init_cfg=init_cfg)
+
+ self.norm1 = build_norm_layer(norm_cfg, embed_dims, postfix=1)[1]
+ self.attn = LocallyGroupedSelfAttention(embed_dims, num_heads,
+ qkv_bias, qk_scale,
+ attn_drop_rate, drop_rate,
+ window_size)
+
+ self.norm2 = build_norm_layer(norm_cfg, embed_dims, postfix=2)[1]
+ self.ffn = FFN(
+ embed_dims=embed_dims,
+ feedforward_channels=feedforward_channels,
+ num_fcs=num_fcs,
+ ffn_drop=drop_rate,
+ dropout_layer=dict(type='DropPath', drop_prob=drop_path_rate),
+ act_cfg=act_cfg,
+ add_identity=False)
+
+ self.drop_path = build_dropout(
+ dict(type='DropPath', drop_prob=drop_path_rate)
+ ) if drop_path_rate > 0. else nn.Identity()
+
+ def forward(self, x, hw_shape):
+ x = x + self.drop_path(self.attn(self.norm1(x), hw_shape))
+ x = x + self.drop_path(self.ffn(self.norm2(x)))
+ return x
+
+
+class ConditionalPositionEncoding(BaseModule):
+ """The Conditional Position Encoding (CPE) module.
+
+ The CPE is the implementation of 'Conditional Positional Encodings
+ for Vision Transformers '_.
+
+ Args:
+ in_channels (int): Number of input channels.
+ embed_dims (int): The feature dimension. Default: 768.
+ stride (int): Stride of conv layer. Default: 1.
+ """
+
+ def __init__(self, in_channels, embed_dims=768, stride=1, init_cfg=None):
+ super(ConditionalPositionEncoding, self).__init__(init_cfg=init_cfg)
+ self.proj = nn.Conv2d(
+ in_channels,
+ embed_dims,
+ kernel_size=3,
+ stride=stride,
+ padding=1,
+ bias=True,
+ groups=embed_dims)
+ self.stride = stride
+
+ def forward(self, x, hw_shape):
+ b, n, c = x.shape
+ h, w = hw_shape
+ feat_token = x
+ cnn_feat = feat_token.transpose(1, 2).view(b, c, h, w)
+ if self.stride == 1:
+ x = self.proj(cnn_feat) + cnn_feat
+ else:
+ x = self.proj(cnn_feat)
+ x = x.flatten(2).transpose(1, 2)
+ return x
+
+
+@BACKBONES.register_module()
+class PCPVT(BaseModule):
+ """The backbone of Twins-PCPVT.
+
+ This backbone is the implementation of `Twins: Revisiting the Design
+ of Spatial Attention in Vision Transformers
+ `_.
+
+ Args:
+ in_channels (int): Number of input channels. Default: 3.
+ embed_dims (list): Embedding dimension. Default: [64, 128, 256, 512].
+ patch_sizes (list): The patch sizes. Default: [4, 2, 2, 2].
+ strides (list): The strides. Default: [4, 2, 2, 2].
+ num_heads (int): Number of attention heads. Default: [1, 2, 4, 8].
+ mlp_ratios (int): Ratio of mlp hidden dim to embedding dim.
+ Default: [4, 4, 4, 4].
+ out_indices (tuple[int]): Output from which stages.
+ Default: (0, 1, 2, 3).
+ qkv_bias (bool): Enable bias for qkv if True. Default: False.
+ drop_rate (float): Probability of an element to be zeroed.
+ Default 0.
+ attn_drop_rate (float): The drop out rate for attention layer.
+ Default 0.0
+ drop_path_rate (float): Stochastic depth rate. Default 0.0
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='LN')
+ depths (list): Depths of each stage. Default [3, 4, 6, 3]
+ sr_ratios (list): Kernel_size of conv in each Attn module in
+ Transformer encoder layer. Default: [8, 4, 2, 1].
+ norm_after_stage(bool): Add extra norm. Default False.
+ init_cfg (dict, optional): The Config for initialization.
+ Defaults to None.
+ """
+
+ def __init__(self,
+ in_channels=3,
+ embed_dims=[64, 128, 256, 512],
+ patch_sizes=[4, 2, 2, 2],
+ strides=[4, 2, 2, 2],
+ num_heads=[1, 2, 4, 8],
+ mlp_ratios=[4, 4, 4, 4],
+ out_indices=(0, 1, 2, 3),
+ qkv_bias=False,
+ drop_rate=0.,
+ attn_drop_rate=0.,
+ drop_path_rate=0.,
+ norm_cfg=dict(type='LN'),
+ depths=[3, 4, 6, 3],
+ sr_ratios=[8, 4, 2, 1],
+ norm_after_stage=False,
+ pretrained=None,
+ init_cfg=None):
+ super(PCPVT, self).__init__(init_cfg=init_cfg)
+ assert not (init_cfg and pretrained), \
+ 'init_cfg and pretrained cannot be set at the same time'
+ if isinstance(pretrained, str):
+ warnings.warn('DeprecationWarning: pretrained is deprecated, '
+ 'please use "init_cfg" instead')
+ self.init_cfg = dict(type='Pretrained', checkpoint=pretrained)
+ elif pretrained is not None:
+ raise TypeError('pretrained must be a str or None')
+ self.depths = depths
+
+ # patch_embed
+ self.patch_embeds = ModuleList()
+ self.position_encoding_drops = ModuleList()
+ self.layers = ModuleList()
+
+ for i in range(len(depths)):
+ self.patch_embeds.append(
+ PatchEmbed(
+ in_channels=in_channels if i == 0 else embed_dims[i - 1],
+ embed_dims=embed_dims[i],
+ conv_type='Conv2d',
+ kernel_size=patch_sizes[i],
+ stride=strides[i],
+ padding='corner',
+ norm_cfg=norm_cfg))
+
+ self.position_encoding_drops.append(nn.Dropout(p=drop_rate))
+
+ self.position_encodings = ModuleList([
+ ConditionalPositionEncoding(embed_dim, embed_dim)
+ for embed_dim in embed_dims
+ ])
+
+ # transformer encoder
+ dpr = [
+ x.item() for x in torch.linspace(0, drop_path_rate, sum(depths))
+ ] # stochastic depth decay rule
+ cur = 0
+
+ for k in range(len(depths)):
+ _block = ModuleList([
+ GSAEncoderLayer(
+ embed_dims=embed_dims[k],
+ num_heads=num_heads[k],
+ feedforward_channels=mlp_ratios[k] * embed_dims[k],
+ attn_drop_rate=attn_drop_rate,
+ drop_rate=drop_rate,
+ drop_path_rate=dpr[cur + i],
+ num_fcs=2,
+ qkv_bias=qkv_bias,
+ act_cfg=dict(type='GELU'),
+ norm_cfg=dict(type='LN'),
+ sr_ratio=sr_ratios[k]) for i in range(depths[k])
+ ])
+ self.layers.append(_block)
+ cur += depths[k]
+
+ self.norm_name, norm = build_norm_layer(
+ norm_cfg, embed_dims[-1], postfix=1)
+
+ self.out_indices = out_indices
+ self.norm_after_stage = norm_after_stage
+ if self.norm_after_stage:
+ self.norm_list = ModuleList()
+ for dim in embed_dims:
+ self.norm_list.append(build_norm_layer(norm_cfg, dim)[1])
+
+ def init_weights(self):
+ if self.init_cfg is not None:
+ super(PCPVT, self).init_weights()
+ else:
+ for m in self.modules():
+ if isinstance(m, nn.Linear):
+ trunc_normal_init(m, std=.02, bias=0.)
+ elif isinstance(m, (_BatchNorm, nn.GroupNorm, nn.LayerNorm)):
+ constant_init(m, val=1.0, bias=0.)
+ elif isinstance(m, nn.Conv2d):
+ fan_out = m.kernel_size[0] * m.kernel_size[
+ 1] * m.out_channels
+ fan_out //= m.groups
+ normal_init(
+ m, mean=0, std=math.sqrt(2.0 / fan_out), bias=0)
+
+ def forward(self, x):
+ outputs = list()
+
+ b = x.shape[0]
+
+ for i in range(len(self.depths)):
+ x, hw_shape = self.patch_embeds[i](x)
+ h, w = hw_shape
+ x = self.position_encoding_drops[i](x)
+ for j, blk in enumerate(self.layers[i]):
+ x = blk(x, hw_shape)
+ if j == 0:
+ x = self.position_encodings[i](x, hw_shape)
+ if self.norm_after_stage:
+ x = self.norm_list[i](x)
+ x = x.reshape(b, h, w, -1).permute(0, 3, 1, 2).contiguous()
+
+ if i in self.out_indices:
+ outputs.append(x)
+
+ return tuple(outputs)
+
+
+@BACKBONES.register_module()
+class SVT(PCPVT):
+ """The backbone of Twins-SVT.
+
+ This backbone is the implementation of `Twins: Revisiting the Design
+ of Spatial Attention in Vision Transformers
+ `_.
+
+ Args:
+ in_channels (int): Number of input channels. Default: 3.
+ embed_dims (list): Embedding dimension. Default: [64, 128, 256, 512].
+ patch_sizes (list): The patch sizes. Default: [4, 2, 2, 2].
+ strides (list): The strides. Default: [4, 2, 2, 2].
+ num_heads (int): Number of attention heads. Default: [1, 2, 4].
+ mlp_ratios (int): Ratio of mlp hidden dim to embedding dim.
+ Default: [4, 4, 4].
+ out_indices (tuple[int]): Output from which stages.
+ Default: (0, 1, 2, 3).
+ qkv_bias (bool): Enable bias for qkv if True. Default: False.
+ drop_rate (float): Dropout rate. Default 0.
+ attn_drop_rate (float): Dropout ratio of attention weight.
+ Default 0.0
+ drop_path_rate (float): Stochastic depth rate. Default 0.2.
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='LN')
+ depths (list): Depths of each stage. Default [4, 4, 4].
+ sr_ratios (list): Kernel_size of conv in each Attn module in
+ Transformer encoder layer. Default: [4, 2, 1].
+ windiow_sizes (list): Window size of LSA. Default: [7, 7, 7],
+ input_features_slice(bool): Input features need slice. Default: False.
+ norm_after_stage(bool): Add extra norm. Default False.
+ strides (list): Strides in patch-Embedding modules. Default: (2, 2, 2)
+ init_cfg (dict, optional): The Config for initialization.
+ Defaults to None.
+ """
+
+ def __init__(self,
+ in_channels=3,
+ embed_dims=[64, 128, 256],
+ patch_sizes=[4, 2, 2, 2],
+ strides=[4, 2, 2, 2],
+ num_heads=[1, 2, 4],
+ mlp_ratios=[4, 4, 4],
+ out_indices=(0, 1, 2, 3),
+ qkv_bias=False,
+ drop_rate=0.,
+ attn_drop_rate=0.,
+ drop_path_rate=0.2,
+ norm_cfg=dict(type='LN'),
+ depths=[4, 4, 4],
+ sr_ratios=[4, 2, 1],
+ windiow_sizes=[7, 7, 7],
+ norm_after_stage=True,
+ pretrained=None,
+ init_cfg=None):
+ super(SVT, self).__init__(in_channels, embed_dims, patch_sizes,
+ strides, num_heads, mlp_ratios, out_indices,
+ qkv_bias, drop_rate, attn_drop_rate,
+ drop_path_rate, norm_cfg, depths, sr_ratios,
+ norm_after_stage, pretrained, init_cfg)
+ # transformer encoder
+ dpr = [
+ x.item() for x in torch.linspace(0, drop_path_rate, sum(depths))
+ ] # stochastic depth decay rule
+
+ for k in range(len(depths)):
+ for i in range(depths[k]):
+ if i % 2 == 0:
+ self.layers[k][i] = \
+ LSAEncoderLayer(
+ embed_dims=embed_dims[k],
+ num_heads=num_heads[k],
+ feedforward_channels=mlp_ratios[k] * embed_dims[k],
+ drop_rate=drop_rate,
+ attn_drop_rate=attn_drop_rate,
+ drop_path_rate=dpr[sum(depths[:k])+i],
+ qkv_bias=qkv_bias,
+ window_size=windiow_sizes[k])
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/unet.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/unet.py
new file mode 100644
index 0000000000000000000000000000000000000000..c2d33667f88fbdbea574c12b750cb540f79da387
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/unet.py
@@ -0,0 +1,438 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import warnings
+
+import torch.nn as nn
+import torch.utils.checkpoint as cp
+from mmcv.cnn import (UPSAMPLE_LAYERS, ConvModule, build_activation_layer,
+ build_norm_layer)
+from mmcv.runner import BaseModule
+from mmcv.utils.parrots_wrapper import _BatchNorm
+
+from mmseg.ops import Upsample
+from ..builder import BACKBONES
+from ..utils import UpConvBlock
+
+
+class BasicConvBlock(nn.Module):
+ """Basic convolutional block for UNet.
+
+ This module consists of several plain convolutional layers.
+
+ Args:
+ in_channels (int): Number of input channels.
+ out_channels (int): Number of output channels.
+ num_convs (int): Number of convolutional layers. Default: 2.
+ stride (int): Whether use stride convolution to downsample
+ the input feature map. If stride=2, it only uses stride convolution
+ in the first convolutional layer to downsample the input feature
+ map. Options are 1 or 2. Default: 1.
+ dilation (int): Whether use dilated convolution to expand the
+ receptive field. Set dilation rate of each convolutional layer and
+ the dilation rate of the first convolutional layer is always 1.
+ Default: 1.
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save some
+ memory while slowing down the training speed. Default: False.
+ conv_cfg (dict | None): Config dict for convolution layer.
+ Default: None.
+ norm_cfg (dict | None): Config dict for normalization layer.
+ Default: dict(type='BN').
+ act_cfg (dict | None): Config dict for activation layer in ConvModule.
+ Default: dict(type='ReLU').
+ dcn (bool): Use deformable convolution in convolutional layer or not.
+ Default: None.
+ plugins (dict): plugins for convolutional layers. Default: None.
+ """
+
+ def __init__(self,
+ in_channels,
+ out_channels,
+ num_convs=2,
+ stride=1,
+ dilation=1,
+ with_cp=False,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ dcn=None,
+ plugins=None):
+ super(BasicConvBlock, self).__init__()
+ assert dcn is None, 'Not implemented yet.'
+ assert plugins is None, 'Not implemented yet.'
+
+ self.with_cp = with_cp
+ convs = []
+ for i in range(num_convs):
+ convs.append(
+ ConvModule(
+ in_channels=in_channels if i == 0 else out_channels,
+ out_channels=out_channels,
+ kernel_size=3,
+ stride=stride if i == 0 else 1,
+ dilation=1 if i == 0 else dilation,
+ padding=1 if i == 0 else dilation,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg))
+
+ self.convs = nn.Sequential(*convs)
+
+ def forward(self, x):
+ """Forward function."""
+
+ if self.with_cp and x.requires_grad:
+ out = cp.checkpoint(self.convs, x)
+ else:
+ out = self.convs(x)
+ return out
+
+
+@UPSAMPLE_LAYERS.register_module()
+class DeconvModule(nn.Module):
+ """Deconvolution upsample module in decoder for UNet (2X upsample).
+
+ This module uses deconvolution to upsample feature map in the decoder
+ of UNet.
+
+ Args:
+ in_channels (int): Number of input channels.
+ out_channels (int): Number of output channels.
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save some
+ memory while slowing down the training speed. Default: False.
+ norm_cfg (dict | None): Config dict for normalization layer.
+ Default: dict(type='BN').
+ act_cfg (dict | None): Config dict for activation layer in ConvModule.
+ Default: dict(type='ReLU').
+ kernel_size (int): Kernel size of the convolutional layer. Default: 4.
+ """
+
+ def __init__(self,
+ in_channels,
+ out_channels,
+ with_cp=False,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ *,
+ kernel_size=4,
+ scale_factor=2):
+ super(DeconvModule, self).__init__()
+
+ assert (kernel_size - scale_factor >= 0) and\
+ (kernel_size - scale_factor) % 2 == 0,\
+ f'kernel_size should be greater than or equal to scale_factor '\
+ f'and (kernel_size - scale_factor) should be even numbers, '\
+ f'while the kernel size is {kernel_size} and scale_factor is '\
+ f'{scale_factor}.'
+
+ stride = scale_factor
+ padding = (kernel_size - scale_factor) // 2
+ self.with_cp = with_cp
+ deconv = nn.ConvTranspose2d(
+ in_channels,
+ out_channels,
+ kernel_size=kernel_size,
+ stride=stride,
+ padding=padding)
+
+ norm_name, norm = build_norm_layer(norm_cfg, out_channels)
+ activate = build_activation_layer(act_cfg)
+ self.deconv_upsamping = nn.Sequential(deconv, norm, activate)
+
+ def forward(self, x):
+ """Forward function."""
+
+ if self.with_cp and x.requires_grad:
+ out = cp.checkpoint(self.deconv_upsamping, x)
+ else:
+ out = self.deconv_upsamping(x)
+ return out
+
+
+@UPSAMPLE_LAYERS.register_module()
+class InterpConv(nn.Module):
+ """Interpolation upsample module in decoder for UNet.
+
+ This module uses interpolation to upsample feature map in the decoder
+ of UNet. It consists of one interpolation upsample layer and one
+ convolutional layer. It can be one interpolation upsample layer followed
+ by one convolutional layer (conv_first=False) or one convolutional layer
+ followed by one interpolation upsample layer (conv_first=True).
+
+ Args:
+ in_channels (int): Number of input channels.
+ out_channels (int): Number of output channels.
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save some
+ memory while slowing down the training speed. Default: False.
+ norm_cfg (dict | None): Config dict for normalization layer.
+ Default: dict(type='BN').
+ act_cfg (dict | None): Config dict for activation layer in ConvModule.
+ Default: dict(type='ReLU').
+ conv_cfg (dict | None): Config dict for convolution layer.
+ Default: None.
+ conv_first (bool): Whether convolutional layer or interpolation
+ upsample layer first. Default: False. It means interpolation
+ upsample layer followed by one convolutional layer.
+ kernel_size (int): Kernel size of the convolutional layer. Default: 1.
+ stride (int): Stride of the convolutional layer. Default: 1.
+ padding (int): Padding of the convolutional layer. Default: 1.
+ upsample_cfg (dict): Interpolation config of the upsample layer.
+ Default: dict(
+ scale_factor=2, mode='bilinear', align_corners=False).
+ """
+
+ def __init__(self,
+ in_channels,
+ out_channels,
+ with_cp=False,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ *,
+ conv_cfg=None,
+ conv_first=False,
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ upsample_cfg=dict(
+ scale_factor=2, mode='bilinear', align_corners=False)):
+ super(InterpConv, self).__init__()
+
+ self.with_cp = with_cp
+ conv = ConvModule(
+ in_channels,
+ out_channels,
+ kernel_size=kernel_size,
+ stride=stride,
+ padding=padding,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ upsample = Upsample(**upsample_cfg)
+ if conv_first:
+ self.interp_upsample = nn.Sequential(conv, upsample)
+ else:
+ self.interp_upsample = nn.Sequential(upsample, conv)
+
+ def forward(self, x):
+ """Forward function."""
+
+ if self.with_cp and x.requires_grad:
+ out = cp.checkpoint(self.interp_upsample, x)
+ else:
+ out = self.interp_upsample(x)
+ return out
+
+
+@BACKBONES.register_module()
+class UNet(BaseModule):
+ """UNet backbone.
+
+ This backbone is the implementation of `U-Net: Convolutional Networks
+ for Biomedical Image Segmentation `_.
+
+ Args:
+ in_channels (int): Number of input image channels. Default" 3.
+ base_channels (int): Number of base channels of each stage.
+ The output channels of the first stage. Default: 64.
+ num_stages (int): Number of stages in encoder, normally 5. Default: 5.
+ strides (Sequence[int 1 | 2]): Strides of each stage in encoder.
+ len(strides) is equal to num_stages. Normally the stride of the
+ first stage in encoder is 1. If strides[i]=2, it uses stride
+ convolution to downsample in the correspondence encoder stage.
+ Default: (1, 1, 1, 1, 1).
+ enc_num_convs (Sequence[int]): Number of convolutional layers in the
+ convolution block of the correspondence encoder stage.
+ Default: (2, 2, 2, 2, 2).
+ dec_num_convs (Sequence[int]): Number of convolutional layers in the
+ convolution block of the correspondence decoder stage.
+ Default: (2, 2, 2, 2).
+ downsamples (Sequence[int]): Whether use MaxPool to downsample the
+ feature map after the first stage of encoder
+ (stages: [1, num_stages)). If the correspondence encoder stage use
+ stride convolution (strides[i]=2), it will never use MaxPool to
+ downsample, even downsamples[i-1]=True.
+ Default: (True, True, True, True).
+ enc_dilations (Sequence[int]): Dilation rate of each stage in encoder.
+ Default: (1, 1, 1, 1, 1).
+ dec_dilations (Sequence[int]): Dilation rate of each stage in decoder.
+ Default: (1, 1, 1, 1).
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save some
+ memory while slowing down the training speed. Default: False.
+ conv_cfg (dict | None): Config dict for convolution layer.
+ Default: None.
+ norm_cfg (dict | None): Config dict for normalization layer.
+ Default: dict(type='BN').
+ act_cfg (dict | None): Config dict for activation layer in ConvModule.
+ Default: dict(type='ReLU').
+ upsample_cfg (dict): The upsample config of the upsample module in
+ decoder. Default: dict(type='InterpConv').
+ norm_eval (bool): Whether to set norm layers to eval mode, namely,
+ freeze running stats (mean and var). Note: Effect on Batch Norm
+ and its variants only. Default: False.
+ dcn (bool): Use deformable convolution in convolutional layer or not.
+ Default: None.
+ plugins (dict): plugins for convolutional layers. Default: None.
+ pretrained (str, optional): model pretrained path. Default: None
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None
+
+ Notice:
+ The input image size should be divisible by the whole downsample rate
+ of the encoder. More detail of the whole downsample rate can be found
+ in UNet._check_input_divisible.
+ """
+
+ def __init__(self,
+ in_channels=3,
+ base_channels=64,
+ num_stages=5,
+ strides=(1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True, True),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1),
+ with_cp=False,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ upsample_cfg=dict(type='InterpConv'),
+ norm_eval=False,
+ dcn=None,
+ plugins=None,
+ pretrained=None,
+ init_cfg=None):
+ super(UNet, self).__init__(init_cfg)
+
+ self.pretrained = pretrained
+ assert not (init_cfg and pretrained), \
+ 'init_cfg and pretrained cannot be setting at the same time'
+ if isinstance(pretrained, str):
+ warnings.warn('DeprecationWarning: pretrained is a deprecated, '
+ 'please use "init_cfg" instead')
+ self.init_cfg = dict(type='Pretrained', checkpoint=pretrained)
+ elif pretrained is None:
+ if init_cfg is None:
+ self.init_cfg = [
+ dict(type='Kaiming', layer='Conv2d'),
+ dict(
+ type='Constant',
+ val=1,
+ layer=['_BatchNorm', 'GroupNorm'])
+ ]
+ else:
+ raise TypeError('pretrained must be a str or None')
+
+ assert dcn is None, 'Not implemented yet.'
+ assert plugins is None, 'Not implemented yet.'
+ assert len(strides) == num_stages, \
+ 'The length of strides should be equal to num_stages, '\
+ f'while the strides is {strides}, the length of '\
+ f'strides is {len(strides)}, and the num_stages is '\
+ f'{num_stages}.'
+ assert len(enc_num_convs) == num_stages, \
+ 'The length of enc_num_convs should be equal to num_stages, '\
+ f'while the enc_num_convs is {enc_num_convs}, the length of '\
+ f'enc_num_convs is {len(enc_num_convs)}, and the num_stages is '\
+ f'{num_stages}.'
+ assert len(dec_num_convs) == (num_stages-1), \
+ 'The length of dec_num_convs should be equal to (num_stages-1), '\
+ f'while the dec_num_convs is {dec_num_convs}, the length of '\
+ f'dec_num_convs is {len(dec_num_convs)}, and the num_stages is '\
+ f'{num_stages}.'
+ assert len(downsamples) == (num_stages-1), \
+ 'The length of downsamples should be equal to (num_stages-1), '\
+ f'while the downsamples is {downsamples}, the length of '\
+ f'downsamples is {len(downsamples)}, and the num_stages is '\
+ f'{num_stages}.'
+ assert len(enc_dilations) == num_stages, \
+ 'The length of enc_dilations should be equal to num_stages, '\
+ f'while the enc_dilations is {enc_dilations}, the length of '\
+ f'enc_dilations is {len(enc_dilations)}, and the num_stages is '\
+ f'{num_stages}.'
+ assert len(dec_dilations) == (num_stages-1), \
+ 'The length of dec_dilations should be equal to (num_stages-1), '\
+ f'while the dec_dilations is {dec_dilations}, the length of '\
+ f'dec_dilations is {len(dec_dilations)}, and the num_stages is '\
+ f'{num_stages}.'
+ self.num_stages = num_stages
+ self.strides = strides
+ self.downsamples = downsamples
+ self.norm_eval = norm_eval
+ self.base_channels = base_channels
+
+ self.encoder = nn.ModuleList()
+ self.decoder = nn.ModuleList()
+
+ for i in range(num_stages):
+ enc_conv_block = []
+ if i != 0:
+ if strides[i] == 1 and downsamples[i - 1]:
+ enc_conv_block.append(nn.MaxPool2d(kernel_size=2))
+ upsample = (strides[i] != 1 or downsamples[i - 1])
+ self.decoder.append(
+ UpConvBlock(
+ conv_block=BasicConvBlock,
+ in_channels=base_channels * 2**i,
+ skip_channels=base_channels * 2**(i - 1),
+ out_channels=base_channels * 2**(i - 1),
+ num_convs=dec_num_convs[i - 1],
+ stride=1,
+ dilation=dec_dilations[i - 1],
+ with_cp=with_cp,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg,
+ upsample_cfg=upsample_cfg if upsample else None,
+ dcn=None,
+ plugins=None))
+
+ enc_conv_block.append(
+ BasicConvBlock(
+ in_channels=in_channels,
+ out_channels=base_channels * 2**i,
+ num_convs=enc_num_convs[i],
+ stride=strides[i],
+ dilation=enc_dilations[i],
+ with_cp=with_cp,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg,
+ dcn=None,
+ plugins=None))
+ self.encoder.append((nn.Sequential(*enc_conv_block)))
+ in_channels = base_channels * 2**i
+
+ def forward(self, x):
+ self._check_input_divisible(x)
+ enc_outs = []
+ for enc in self.encoder:
+ x = enc(x)
+ enc_outs.append(x)
+ dec_outs = [x]
+ for i in reversed(range(len(self.decoder))):
+ x = self.decoder[i](enc_outs[i], x)
+ dec_outs.append(x)
+
+ return dec_outs
+
+ def train(self, mode=True):
+ """Convert the model into training mode while keep normalization layer
+ freezed."""
+ super(UNet, self).train(mode)
+ if mode and self.norm_eval:
+ for m in self.modules():
+ # trick: eval have effect on BatchNorm only
+ if isinstance(m, _BatchNorm):
+ m.eval()
+
+ def _check_input_divisible(self, x):
+ h, w = x.shape[-2:]
+ whole_downsample_rate = 1
+ for i in range(1, self.num_stages):
+ if self.strides[i] == 2 or self.downsamples[i - 1]:
+ whole_downsample_rate *= 2
+ assert (h % whole_downsample_rate == 0) \
+ and (w % whole_downsample_rate == 0),\
+ f'The input image size {(h, w)} should be divisible by the whole '\
+ f'downsample rate {whole_downsample_rate}, when num_stages is '\
+ f'{self.num_stages}, strides is {self.strides}, and downsamples '\
+ f'is {self.downsamples}.'
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/vit.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/vit.py
new file mode 100644
index 0000000000000000000000000000000000000000..94ea5eacb8801ec43f548eb601a9d32c81dfa960
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/backbones/vit.py
@@ -0,0 +1,440 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import math
+import warnings
+
+import torch
+import torch.nn as nn
+import torch.utils.checkpoint as cp
+from mmcv.cnn import build_norm_layer
+from mmcv.cnn.bricks.transformer import FFN, MultiheadAttention
+from mmcv.cnn.utils.weight_init import (constant_init, kaiming_init,
+ trunc_normal_)
+from mmcv.runner import (BaseModule, CheckpointLoader, ModuleList,
+ load_state_dict)
+from torch.nn.modules.batchnorm import _BatchNorm
+from torch.nn.modules.utils import _pair as to_2tuple
+
+from mmseg.ops import resize
+from mmseg.utils import get_root_logger
+from ..builder import BACKBONES
+from ..utils import PatchEmbed
+
+
+class TransformerEncoderLayer(BaseModule):
+ """Implements one encoder layer in Vision Transformer.
+
+ Args:
+ embed_dims (int): The feature dimension.
+ num_heads (int): Parallel attention heads.
+ feedforward_channels (int): The hidden dimension for FFNs.
+ drop_rate (float): Probability of an element to be zeroed
+ after the feed forward layer. Default: 0.0.
+ attn_drop_rate (float): The drop out rate for attention layer.
+ Default: 0.0.
+ drop_path_rate (float): stochastic depth rate. Default 0.0.
+ num_fcs (int): The number of fully-connected layers for FFNs.
+ Default: 2.
+ qkv_bias (bool): enable bias for qkv if True. Default: True
+ act_cfg (dict): The activation config for FFNs.
+ Default: dict(type='GELU').
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='LN').
+ batch_first (bool): Key, Query and Value are shape of
+ (batch, n, embed_dim)
+ or (n, batch, embed_dim). Default: True.
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save
+ some memory while slowing down the training speed. Default: False.
+ """
+
+ def __init__(self,
+ embed_dims,
+ num_heads,
+ feedforward_channels,
+ drop_rate=0.,
+ attn_drop_rate=0.,
+ drop_path_rate=0.,
+ num_fcs=2,
+ qkv_bias=True,
+ act_cfg=dict(type='GELU'),
+ norm_cfg=dict(type='LN'),
+ batch_first=True,
+ attn_cfg=dict(),
+ ffn_cfg=dict(),
+ with_cp=False):
+ super(TransformerEncoderLayer, self).__init__()
+
+ self.norm1_name, norm1 = build_norm_layer(
+ norm_cfg, embed_dims, postfix=1)
+ self.add_module(self.norm1_name, norm1)
+
+ attn_cfg.update(
+ dict(
+ embed_dims=embed_dims,
+ num_heads=num_heads,
+ attn_drop=attn_drop_rate,
+ proj_drop=drop_rate,
+ batch_first=batch_first,
+ bias=qkv_bias))
+
+ self.build_attn(attn_cfg)
+
+ self.norm2_name, norm2 = build_norm_layer(
+ norm_cfg, embed_dims, postfix=2)
+ self.add_module(self.norm2_name, norm2)
+
+ ffn_cfg.update(
+ dict(
+ embed_dims=embed_dims,
+ feedforward_channels=feedforward_channels,
+ num_fcs=num_fcs,
+ ffn_drop=drop_rate,
+ dropout_layer=dict(type='DropPath', drop_prob=drop_path_rate)
+ if drop_path_rate > 0 else None,
+ act_cfg=act_cfg))
+ self.build_ffn(ffn_cfg)
+ self.with_cp = with_cp
+
+ def build_attn(self, attn_cfg):
+ self.attn = MultiheadAttention(**attn_cfg)
+
+ def build_ffn(self, ffn_cfg):
+ self.ffn = FFN(**ffn_cfg)
+
+ @property
+ def norm1(self):
+ return getattr(self, self.norm1_name)
+
+ @property
+ def norm2(self):
+ return getattr(self, self.norm2_name)
+
+ def forward(self, x):
+
+ def _inner_forward(x):
+ x = self.attn(self.norm1(x), identity=x)
+ x = self.ffn(self.norm2(x), identity=x)
+ return x
+
+ if self.with_cp and x.requires_grad:
+ x = cp.checkpoint(_inner_forward, x)
+ else:
+ x = _inner_forward(x)
+ return x
+
+
+@BACKBONES.register_module()
+class VisionTransformer(BaseModule):
+ """Vision Transformer.
+
+ This backbone is the implementation of `An Image is Worth 16x16 Words:
+ Transformers for Image Recognition at
+ Scale `_.
+
+ Args:
+ img_size (int | tuple): Input image size. Default: 224.
+ patch_size (int): The patch size. Default: 16.
+ in_channels (int): Number of input channels. Default: 3.
+ embed_dims (int): embedding dimension. Default: 768.
+ num_layers (int): depth of transformer. Default: 12.
+ num_heads (int): number of attention heads. Default: 12.
+ mlp_ratio (int): ratio of mlp hidden dim to embedding dim.
+ Default: 4.
+ out_indices (list | tuple | int): Output from which stages.
+ Default: -1.
+ qkv_bias (bool): enable bias for qkv if True. Default: True.
+ drop_rate (float): Probability of an element to be zeroed.
+ Default 0.0
+ attn_drop_rate (float): The drop out rate for attention layer.
+ Default 0.0
+ drop_path_rate (float): stochastic depth rate. Default 0.0
+ with_cls_token (bool): Whether concatenating class token into image
+ tokens as transformer input. Default: True.
+ output_cls_token (bool): Whether output the cls_token. If set True,
+ `with_cls_token` must be True. Default: False.
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='LN')
+ act_cfg (dict): The activation config for FFNs.
+ Default: dict(type='GELU').
+ patch_norm (bool): Whether to add a norm in PatchEmbed Block.
+ Default: False.
+ final_norm (bool): Whether to add a additional layer to normalize
+ final feature map. Default: False.
+ interpolate_mode (str): Select the interpolate mode for position
+ embeding vector resize. Default: bicubic.
+ num_fcs (int): The number of fully-connected layers for FFNs.
+ Default: 2.
+ norm_eval (bool): Whether to set norm layers to eval mode, namely,
+ freeze running stats (mean and var). Note: Effect on Batch Norm
+ and its variants only. Default: False.
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save
+ some memory while slowing down the training speed. Default: False.
+ pretrained (str, optional): model pretrained path. Default: None.
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ """
+
+ def __init__(self,
+ img_size=224,
+ patch_size=16,
+ in_channels=3,
+ embed_dims=768,
+ num_layers=12,
+ num_heads=12,
+ mlp_ratio=4,
+ out_indices=-1,
+ qkv_bias=True,
+ drop_rate=0.,
+ attn_drop_rate=0.,
+ drop_path_rate=0.,
+ with_cls_token=True,
+ output_cls_token=False,
+ norm_cfg=dict(type='LN'),
+ act_cfg=dict(type='GELU'),
+ patch_norm=False,
+ final_norm=False,
+ interpolate_mode='bicubic',
+ num_fcs=2,
+ norm_eval=False,
+ with_cp=False,
+ pretrained=None,
+ init_cfg=None):
+ super(VisionTransformer, self).__init__(init_cfg=init_cfg)
+
+ if isinstance(img_size, int):
+ img_size = to_2tuple(img_size)
+ elif isinstance(img_size, tuple):
+ if len(img_size) == 1:
+ img_size = to_2tuple(img_size[0])
+ assert len(img_size) == 2, \
+ f'The size of image should have length 1 or 2, ' \
+ f'but got {len(img_size)}'
+
+ if output_cls_token:
+ assert with_cls_token is True, f'with_cls_token must be True if' \
+ f'set output_cls_token to True, but got {with_cls_token}'
+
+ assert not (init_cfg and pretrained), \
+ 'init_cfg and pretrained cannot be set at the same time'
+ if isinstance(pretrained, str):
+ warnings.warn('DeprecationWarning: pretrained is deprecated, '
+ 'please use "init_cfg" instead')
+ self.init_cfg = dict(type='Pretrained', checkpoint=pretrained)
+ elif pretrained is not None:
+ raise TypeError('pretrained must be a str or None')
+
+ self.img_size = img_size
+ self.patch_size = patch_size
+ self.interpolate_mode = interpolate_mode
+ self.norm_eval = norm_eval
+ self.with_cp = with_cp
+ self.pretrained = pretrained
+
+ self.patch_embed = PatchEmbed(
+ in_channels=in_channels,
+ embed_dims=embed_dims,
+ conv_type='Conv2d',
+ kernel_size=patch_size,
+ stride=patch_size,
+ padding='corner',
+ norm_cfg=norm_cfg if patch_norm else None,
+ init_cfg=None,
+ )
+
+ num_patches = (img_size[0] // patch_size) * \
+ (img_size[1] // patch_size)
+
+ self.with_cls_token = with_cls_token
+ self.output_cls_token = output_cls_token
+ self.cls_token = nn.Parameter(torch.zeros(1, 1, embed_dims))
+ self.pos_embed = nn.Parameter(
+ torch.zeros(1, num_patches + 1, embed_dims))
+ self.drop_after_pos = nn.Dropout(p=drop_rate)
+
+ if isinstance(out_indices, int):
+ if out_indices == -1:
+ out_indices = num_layers - 1
+ self.out_indices = [out_indices]
+ elif isinstance(out_indices, list) or isinstance(out_indices, tuple):
+ self.out_indices = out_indices
+ else:
+ raise TypeError('out_indices must be type of int, list or tuple')
+
+ dpr = [
+ x.item() for x in torch.linspace(0, drop_path_rate, num_layers)
+ ] # stochastic depth decay rule
+
+ self.layers = ModuleList()
+ for i in range(num_layers):
+ self.layers.append(
+ TransformerEncoderLayer(
+ embed_dims=embed_dims,
+ num_heads=num_heads,
+ feedforward_channels=mlp_ratio * embed_dims,
+ attn_drop_rate=attn_drop_rate,
+ drop_rate=drop_rate,
+ drop_path_rate=dpr[i],
+ num_fcs=num_fcs,
+ qkv_bias=qkv_bias,
+ act_cfg=act_cfg,
+ norm_cfg=norm_cfg,
+ with_cp=with_cp,
+ batch_first=True))
+
+ self.final_norm = final_norm
+ if final_norm:
+ self.norm1_name, norm1 = build_norm_layer(
+ norm_cfg, embed_dims, postfix=1)
+ self.add_module(self.norm1_name, norm1)
+
+ @property
+ def norm1(self):
+ return getattr(self, self.norm1_name)
+
+ def init_weights(self):
+ if (isinstance(self.init_cfg, dict)
+ and self.init_cfg.get('type') == 'Pretrained'):
+ logger = get_root_logger()
+ checkpoint = CheckpointLoader.load_checkpoint(
+ self.init_cfg['checkpoint'], logger=logger, map_location='cpu')
+
+ if 'state_dict' in checkpoint:
+ state_dict = checkpoint['state_dict']
+ else:
+ state_dict = checkpoint
+
+ if 'pos_embed' in state_dict.keys():
+ if self.pos_embed.shape != state_dict['pos_embed'].shape:
+ logger.info(msg=f'Resize the pos_embed shape from '
+ f'{state_dict["pos_embed"].shape} to '
+ f'{self.pos_embed.shape}')
+ h, w = self.img_size
+ pos_size = int(
+ math.sqrt(state_dict['pos_embed'].shape[1] - 1))
+ state_dict['pos_embed'] = self.resize_pos_embed(
+ state_dict['pos_embed'],
+ (h // self.patch_size, w // self.patch_size),
+ (pos_size, pos_size), self.interpolate_mode)
+
+ load_state_dict(self, state_dict, strict=False, logger=logger)
+ elif self.init_cfg is not None:
+ super(VisionTransformer, self).init_weights()
+ else:
+ # We only implement the 'jax_impl' initialization implemented at
+ # https://github.com/rwightman/pytorch-image-models/blob/master/timm/models/vision_transformer.py#L353 # noqa: E501
+ trunc_normal_(self.pos_embed, std=.02)
+ trunc_normal_(self.cls_token, std=.02)
+ for n, m in self.named_modules():
+ if isinstance(m, nn.Linear):
+ trunc_normal_(m.weight, std=.02)
+ if m.bias is not None:
+ if 'ffn' in n:
+ nn.init.normal_(m.bias, mean=0., std=1e-6)
+ else:
+ nn.init.constant_(m.bias, 0)
+ elif isinstance(m, nn.Conv2d):
+ kaiming_init(m, mode='fan_in', bias=0.)
+ elif isinstance(m, (_BatchNorm, nn.GroupNorm, nn.LayerNorm)):
+ constant_init(m, val=1.0, bias=0.)
+
+ def _pos_embeding(self, patched_img, hw_shape, pos_embed):
+ """Positiong embeding method.
+
+ Resize the pos_embed, if the input image size doesn't match
+ the training size.
+ Args:
+ patched_img (torch.Tensor): The patched image, it should be
+ shape of [B, L1, C].
+ hw_shape (tuple): The downsampled image resolution.
+ pos_embed (torch.Tensor): The pos_embed weighs, it should be
+ shape of [B, L2, c].
+ Return:
+ torch.Tensor: The pos encoded image feature.
+ """
+ assert patched_img.ndim == 3 and pos_embed.ndim == 3, \
+ 'the shapes of patched_img and pos_embed must be [B, L, C]'
+ x_len, pos_len = patched_img.shape[1], pos_embed.shape[1]
+ if x_len != pos_len:
+ if pos_len == (self.img_size[0] // self.patch_size) * (
+ self.img_size[1] // self.patch_size) + 1:
+ pos_h = self.img_size[0] // self.patch_size
+ pos_w = self.img_size[1] // self.patch_size
+ else:
+ raise ValueError(
+ 'Unexpected shape of pos_embed, got {}.'.format(
+ pos_embed.shape))
+ pos_embed = self.resize_pos_embed(pos_embed, hw_shape,
+ (pos_h, pos_w),
+ self.interpolate_mode)
+ return self.drop_after_pos(patched_img + pos_embed)
+
+ @staticmethod
+ def resize_pos_embed(pos_embed, input_shpae, pos_shape, mode):
+ """Resize pos_embed weights.
+
+ Resize pos_embed using bicubic interpolate method.
+ Args:
+ pos_embed (torch.Tensor): Position embedding weights.
+ input_shpae (tuple): Tuple for (downsampled input image height,
+ downsampled input image width).
+ pos_shape (tuple): The resolution of downsampled origin training
+ image.
+ mode (str): Algorithm used for upsampling:
+ ``'nearest'`` | ``'linear'`` | ``'bilinear'`` | ``'bicubic'`` |
+ ``'trilinear'``. Default: ``'nearest'``
+ Return:
+ torch.Tensor: The resized pos_embed of shape [B, L_new, C]
+ """
+ assert pos_embed.ndim == 3, 'shape of pos_embed must be [B, L, C]'
+ pos_h, pos_w = pos_shape
+ cls_token_weight = pos_embed[:, 0]
+ pos_embed_weight = pos_embed[:, (-1 * pos_h * pos_w):]
+ pos_embed_weight = pos_embed_weight.reshape(
+ 1, pos_h, pos_w, pos_embed.shape[2]).permute(0, 3, 1, 2)
+ pos_embed_weight = resize(
+ pos_embed_weight, size=input_shpae, align_corners=False, mode=mode)
+ cls_token_weight = cls_token_weight.unsqueeze(1)
+ pos_embed_weight = torch.flatten(pos_embed_weight, 2).transpose(1, 2)
+ pos_embed = torch.cat((cls_token_weight, pos_embed_weight), dim=1)
+ return pos_embed
+
+ def forward(self, inputs):
+ B = inputs.shape[0]
+
+ x, hw_shape = self.patch_embed(inputs)
+
+ # stole cls_tokens impl from Phil Wang, thanks
+ cls_tokens = self.cls_token.expand(B, -1, -1)
+ x = torch.cat((cls_tokens, x), dim=1)
+ x = self._pos_embeding(x, hw_shape, self.pos_embed)
+
+ if not self.with_cls_token:
+ # Remove class token for transformer encoder input
+ x = x[:, 1:]
+
+ outs = []
+ for i, layer in enumerate(self.layers):
+ x = layer(x)
+ if i == len(self.layers) - 1:
+ if self.final_norm:
+ x = self.norm1(x)
+ if i in self.out_indices:
+ if self.with_cls_token:
+ # Remove class token and reshape token for decoder head
+ out = x[:, 1:]
+ else:
+ out = x
+ B, _, C = out.shape
+ out = out.reshape(B, hw_shape[0], hw_shape[1],
+ C).permute(0, 3, 1, 2).contiguous()
+ if self.output_cls_token:
+ out = [out, x[:, 0]]
+ outs.append(out)
+
+ return tuple(outs)
+
+ def train(self, mode=True):
+ super(VisionTransformer, self).train(mode)
+ if mode and self.norm_eval:
+ for m in self.modules():
+ if isinstance(m, nn.LayerNorm):
+ m.eval()
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/builder.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/builder.py
new file mode 100644
index 0000000000000000000000000000000000000000..5e18e4e6430a80434d7cd2a3eed55ea343fccab6
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/builder.py
@@ -0,0 +1,49 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import warnings
+
+from mmcv.cnn import MODELS as MMCV_MODELS
+from mmcv.cnn.bricks.registry import ATTENTION as MMCV_ATTENTION
+from mmcv.utils import Registry
+
+MODELS = Registry('models', parent=MMCV_MODELS)
+ATTENTION = Registry('attention', parent=MMCV_ATTENTION)
+
+BACKBONES = MODELS
+NECKS = MODELS
+HEADS = MODELS
+LOSSES = MODELS
+SEGMENTORS = MODELS
+
+
+def build_backbone(cfg):
+ """Build backbone."""
+ return BACKBONES.build(cfg)
+
+
+def build_neck(cfg):
+ """Build neck."""
+ return NECKS.build(cfg)
+
+
+def build_head(cfg):
+ """Build head."""
+ return HEADS.build(cfg)
+
+
+def build_loss(cfg):
+ """Build loss."""
+ return LOSSES.build(cfg)
+
+
+def build_segmentor(cfg, train_cfg=None, test_cfg=None):
+ """Build segmentor."""
+ if train_cfg is not None or test_cfg is not None:
+ warnings.warn(
+ 'train_cfg and test_cfg is deprecated, '
+ 'please specify them in model', UserWarning)
+ assert cfg.get('train_cfg') is None or train_cfg is None, \
+ 'train_cfg specified in both outer field and model field '
+ assert cfg.get('test_cfg') is None or test_cfg is None, \
+ 'test_cfg specified in both outer field and model field '
+ return SEGMENTORS.build(
+ cfg, default_args=dict(train_cfg=train_cfg, test_cfg=test_cfg))
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..8add7615c2f267984e8dd6ee7be7f9584bf23293
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/__init__.py
@@ -0,0 +1,40 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .ann_head import ANNHead
+from .apc_head import APCHead
+from .aspp_head import ASPPHead
+from .cc_head import CCHead
+from .da_head import DAHead
+from .dm_head import DMHead
+from .dnl_head import DNLHead
+from .dpt_head import DPTHead
+from .ema_head import EMAHead
+from .enc_head import EncHead
+from .fcn_head import FCNHead
+from .fpn_head import FPNHead
+from .gc_head import GCHead
+from .isa_head import ISAHead
+from .knet_head import IterativeDecodeHead, KernelUpdateHead, KernelUpdator
+from .lraspp_head import LRASPPHead
+from .nl_head import NLHead
+from .ocr_head import OCRHead
+from .point_head import PointHead
+from .psa_head import PSAHead
+from .psp_head import PSPHead
+from .segformer_head import SegformerHead
+from .segmenter_mask_head import SegmenterMaskTransformerHead
+from .sep_aspp_head import DepthwiseSeparableASPPHead
+from .sep_fcn_head import DepthwiseSeparableFCNHead
+from .setr_mla_head import SETRMLAHead
+from .setr_up_head import SETRUPHead
+from .stdc_head import STDCHead
+from .uper_head import UPerHead
+
+__all__ = [
+ 'FCNHead', 'PSPHead', 'ASPPHead', 'PSAHead', 'NLHead', 'GCHead', 'CCHead',
+ 'UPerHead', 'DepthwiseSeparableASPPHead', 'ANNHead', 'DAHead', 'OCRHead',
+ 'EncHead', 'DepthwiseSeparableFCNHead', 'FPNHead', 'EMAHead', 'DNLHead',
+ 'PointHead', 'APCHead', 'DMHead', 'LRASPPHead', 'SETRUPHead',
+ 'SETRMLAHead', 'DPTHead', 'SETRMLAHead', 'SegmenterMaskTransformerHead',
+ 'SegformerHead', 'ISAHead', 'STDCHead', 'IterativeDecodeHead',
+ 'KernelUpdateHead', 'KernelUpdator'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/ann_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/ann_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..c8d882e31963f09b9d250f0ce0bfde63f97d368d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/ann_head.py
@@ -0,0 +1,246 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+from mmcv.cnn import ConvModule
+
+from ..builder import HEADS
+from ..utils import SelfAttentionBlock as _SelfAttentionBlock
+from .decode_head import BaseDecodeHead
+
+
+class PPMConcat(nn.ModuleList):
+ """Pyramid Pooling Module that only concat the features of each layer.
+
+ Args:
+ pool_scales (tuple[int]): Pooling scales used in Pooling Pyramid
+ Module.
+ """
+
+ def __init__(self, pool_scales=(1, 3, 6, 8)):
+ super(PPMConcat, self).__init__(
+ [nn.AdaptiveAvgPool2d(pool_scale) for pool_scale in pool_scales])
+
+ def forward(self, feats):
+ """Forward function."""
+ ppm_outs = []
+ for ppm in self:
+ ppm_out = ppm(feats)
+ ppm_outs.append(ppm_out.view(*feats.shape[:2], -1))
+ concat_outs = torch.cat(ppm_outs, dim=2)
+ return concat_outs
+
+
+class SelfAttentionBlock(_SelfAttentionBlock):
+ """Make a ANN used SelfAttentionBlock.
+
+ Args:
+ low_in_channels (int): Input channels of lower level feature,
+ which is the key feature for self-attention.
+ high_in_channels (int): Input channels of higher level feature,
+ which is the query feature for self-attention.
+ channels (int): Output channels of key/query transform.
+ out_channels (int): Output channels.
+ share_key_query (bool): Whether share projection weight between key
+ and query projection.
+ query_scale (int): The scale of query feature map.
+ key_pool_scales (tuple[int]): Pooling scales used in Pooling Pyramid
+ Module of key feature.
+ conv_cfg (dict|None): Config of conv layers.
+ norm_cfg (dict|None): Config of norm layers.
+ act_cfg (dict|None): Config of activation layers.
+ """
+
+ def __init__(self, low_in_channels, high_in_channels, channels,
+ out_channels, share_key_query, query_scale, key_pool_scales,
+ conv_cfg, norm_cfg, act_cfg):
+ key_psp = PPMConcat(key_pool_scales)
+ if query_scale > 1:
+ query_downsample = nn.MaxPool2d(kernel_size=query_scale)
+ else:
+ query_downsample = None
+ super(SelfAttentionBlock, self).__init__(
+ key_in_channels=low_in_channels,
+ query_in_channels=high_in_channels,
+ channels=channels,
+ out_channels=out_channels,
+ share_key_query=share_key_query,
+ query_downsample=query_downsample,
+ key_downsample=key_psp,
+ key_query_num_convs=1,
+ key_query_norm=True,
+ value_out_num_convs=1,
+ value_out_norm=False,
+ matmul_norm=True,
+ with_out=True,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+
+
+class AFNB(nn.Module):
+ """Asymmetric Fusion Non-local Block(AFNB)
+
+ Args:
+ low_in_channels (int): Input channels of lower level feature,
+ which is the key feature for self-attention.
+ high_in_channels (int): Input channels of higher level feature,
+ which is the query feature for self-attention.
+ channels (int): Output channels of key/query transform.
+ out_channels (int): Output channels.
+ and query projection.
+ query_scales (tuple[int]): The scales of query feature map.
+ Default: (1,)
+ key_pool_scales (tuple[int]): Pooling scales used in Pooling Pyramid
+ Module of key feature.
+ conv_cfg (dict|None): Config of conv layers.
+ norm_cfg (dict|None): Config of norm layers.
+ act_cfg (dict|None): Config of activation layers.
+ """
+
+ def __init__(self, low_in_channels, high_in_channels, channels,
+ out_channels, query_scales, key_pool_scales, conv_cfg,
+ norm_cfg, act_cfg):
+ super(AFNB, self).__init__()
+ self.stages = nn.ModuleList()
+ for query_scale in query_scales:
+ self.stages.append(
+ SelfAttentionBlock(
+ low_in_channels=low_in_channels,
+ high_in_channels=high_in_channels,
+ channels=channels,
+ out_channels=out_channels,
+ share_key_query=False,
+ query_scale=query_scale,
+ key_pool_scales=key_pool_scales,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg))
+ self.bottleneck = ConvModule(
+ out_channels + high_in_channels,
+ out_channels,
+ 1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=None)
+
+ def forward(self, low_feats, high_feats):
+ """Forward function."""
+ priors = [stage(high_feats, low_feats) for stage in self.stages]
+ context = torch.stack(priors, dim=0).sum(dim=0)
+ output = self.bottleneck(torch.cat([context, high_feats], 1))
+ return output
+
+
+class APNB(nn.Module):
+ """Asymmetric Pyramid Non-local Block (APNB)
+
+ Args:
+ in_channels (int): Input channels of key/query feature,
+ which is the key feature for self-attention.
+ channels (int): Output channels of key/query transform.
+ out_channels (int): Output channels.
+ query_scales (tuple[int]): The scales of query feature map.
+ Default: (1,)
+ key_pool_scales (tuple[int]): Pooling scales used in Pooling Pyramid
+ Module of key feature.
+ conv_cfg (dict|None): Config of conv layers.
+ norm_cfg (dict|None): Config of norm layers.
+ act_cfg (dict|None): Config of activation layers.
+ """
+
+ def __init__(self, in_channels, channels, out_channels, query_scales,
+ key_pool_scales, conv_cfg, norm_cfg, act_cfg):
+ super(APNB, self).__init__()
+ self.stages = nn.ModuleList()
+ for query_scale in query_scales:
+ self.stages.append(
+ SelfAttentionBlock(
+ low_in_channels=in_channels,
+ high_in_channels=in_channels,
+ channels=channels,
+ out_channels=out_channels,
+ share_key_query=True,
+ query_scale=query_scale,
+ key_pool_scales=key_pool_scales,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg))
+ self.bottleneck = ConvModule(
+ 2 * in_channels,
+ out_channels,
+ 1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+
+ def forward(self, feats):
+ """Forward function."""
+ priors = [stage(feats, feats) for stage in self.stages]
+ context = torch.stack(priors, dim=0).sum(dim=0)
+ output = self.bottleneck(torch.cat([context, feats], 1))
+ return output
+
+
+@HEADS.register_module()
+class ANNHead(BaseDecodeHead):
+ """Asymmetric Non-local Neural Networks for Semantic Segmentation.
+
+ This head is the implementation of `ANNNet
+ `_.
+
+ Args:
+ project_channels (int): Projection channels for Nonlocal.
+ query_scales (tuple[int]): The scales of query feature map.
+ Default: (1,)
+ key_pool_scales (tuple[int]): The pooling scales of key feature map.
+ Default: (1, 3, 6, 8).
+ """
+
+ def __init__(self,
+ project_channels,
+ query_scales=(1, ),
+ key_pool_scales=(1, 3, 6, 8),
+ **kwargs):
+ super(ANNHead, self).__init__(
+ input_transform='multiple_select', **kwargs)
+ assert len(self.in_channels) == 2
+ low_in_channels, high_in_channels = self.in_channels
+ self.project_channels = project_channels
+ self.fusion = AFNB(
+ low_in_channels=low_in_channels,
+ high_in_channels=high_in_channels,
+ out_channels=high_in_channels,
+ channels=project_channels,
+ query_scales=query_scales,
+ key_pool_scales=key_pool_scales,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ self.bottleneck = ConvModule(
+ high_in_channels,
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ self.context = APNB(
+ in_channels=self.channels,
+ out_channels=self.channels,
+ channels=project_channels,
+ query_scales=query_scales,
+ key_pool_scales=key_pool_scales,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ def forward(self, inputs):
+ """Forward function."""
+ low_feats, high_feats = self._transform_inputs(inputs)
+ output = self.fusion(low_feats, high_feats)
+ output = self.dropout(output)
+ output = self.bottleneck(output)
+ output = self.context(output)
+ output = self.cls_seg(output)
+
+ return output
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/apc_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/apc_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..3198fd18817fe0a3698de42352073ba2d8ca4b5e
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/apc_head.py
@@ -0,0 +1,159 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+from mmcv.cnn import ConvModule
+
+from mmseg.ops import resize
+from ..builder import HEADS
+from .decode_head import BaseDecodeHead
+
+
+class ACM(nn.Module):
+ """Adaptive Context Module used in APCNet.
+
+ Args:
+ pool_scale (int): Pooling scale used in Adaptive Context
+ Module to extract region features.
+ fusion (bool): Add one conv to fuse residual feature.
+ in_channels (int): Input channels.
+ channels (int): Channels after modules, before conv_seg.
+ conv_cfg (dict | None): Config of conv layers.
+ norm_cfg (dict | None): Config of norm layers.
+ act_cfg (dict): Config of activation layers.
+ """
+
+ def __init__(self, pool_scale, fusion, in_channels, channels, conv_cfg,
+ norm_cfg, act_cfg):
+ super(ACM, self).__init__()
+ self.pool_scale = pool_scale
+ self.fusion = fusion
+ self.in_channels = in_channels
+ self.channels = channels
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+ self.pooled_redu_conv = ConvModule(
+ self.in_channels,
+ self.channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ self.input_redu_conv = ConvModule(
+ self.in_channels,
+ self.channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ self.global_info = ConvModule(
+ self.channels,
+ self.channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ self.gla = nn.Conv2d(self.channels, self.pool_scale**2, 1, 1, 0)
+
+ self.residual_conv = ConvModule(
+ self.channels,
+ self.channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ if self.fusion:
+ self.fusion_conv = ConvModule(
+ self.channels,
+ self.channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ def forward(self, x):
+ """Forward function."""
+ pooled_x = F.adaptive_avg_pool2d(x, self.pool_scale)
+ # [batch_size, channels, h, w]
+ x = self.input_redu_conv(x)
+ # [batch_size, channels, pool_scale, pool_scale]
+ pooled_x = self.pooled_redu_conv(pooled_x)
+ batch_size = x.size(0)
+ # [batch_size, pool_scale * pool_scale, channels]
+ pooled_x = pooled_x.view(batch_size, self.channels,
+ -1).permute(0, 2, 1).contiguous()
+ # [batch_size, h * w, pool_scale * pool_scale]
+ affinity_matrix = self.gla(x + resize(
+ self.global_info(F.adaptive_avg_pool2d(x, 1)), size=x.shape[2:])
+ ).permute(0, 2, 3, 1).reshape(
+ batch_size, -1, self.pool_scale**2)
+ affinity_matrix = F.sigmoid(affinity_matrix)
+ # [batch_size, h * w, channels]
+ z_out = torch.matmul(affinity_matrix, pooled_x)
+ # [batch_size, channels, h * w]
+ z_out = z_out.permute(0, 2, 1).contiguous()
+ # [batch_size, channels, h, w]
+ z_out = z_out.view(batch_size, self.channels, x.size(2), x.size(3))
+ z_out = self.residual_conv(z_out)
+ z_out = F.relu(z_out + x)
+ if self.fusion:
+ z_out = self.fusion_conv(z_out)
+
+ return z_out
+
+
+@HEADS.register_module()
+class APCHead(BaseDecodeHead):
+ """Adaptive Pyramid Context Network for Semantic Segmentation.
+
+ This head is the implementation of
+ `APCNet `_.
+
+ Args:
+ pool_scales (tuple[int]): Pooling scales used in Adaptive Context
+ Module. Default: (1, 2, 3, 6).
+ fusion (bool): Add one conv to fuse residual feature.
+ """
+
+ def __init__(self, pool_scales=(1, 2, 3, 6), fusion=True, **kwargs):
+ super(APCHead, self).__init__(**kwargs)
+ assert isinstance(pool_scales, (list, tuple))
+ self.pool_scales = pool_scales
+ self.fusion = fusion
+ acm_modules = []
+ for pool_scale in self.pool_scales:
+ acm_modules.append(
+ ACM(pool_scale,
+ self.fusion,
+ self.in_channels,
+ self.channels,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg))
+ self.acm_modules = nn.ModuleList(acm_modules)
+ self.bottleneck = ConvModule(
+ self.in_channels + len(pool_scales) * self.channels,
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ def forward(self, inputs):
+ """Forward function."""
+ x = self._transform_inputs(inputs)
+ acm_outs = [x]
+ for acm_module in self.acm_modules:
+ acm_outs.append(acm_module(x))
+ acm_outs = torch.cat(acm_outs, dim=1)
+ output = self.bottleneck(acm_outs)
+ output = self.cls_seg(output)
+ return output
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/aspp_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/aspp_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..7059aee961183952ec60ca4d6ccea5d3f9ae3f79
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/aspp_head.py
@@ -0,0 +1,122 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+from mmcv.cnn import ConvModule
+
+from mmseg.ops import resize
+from ..builder import HEADS
+from .decode_head import BaseDecodeHead
+
+
+class ASPPModule(nn.ModuleList):
+ """Atrous Spatial Pyramid Pooling (ASPP) Module.
+
+ Args:
+ dilations (tuple[int]): Dilation rate of each layer.
+ in_channels (int): Input channels.
+ channels (int): Channels after modules, before conv_seg.
+ conv_cfg (dict|None): Config of conv layers.
+ norm_cfg (dict|None): Config of norm layers.
+ act_cfg (dict): Config of activation layers.
+ """
+
+ def __init__(self, dilations, in_channels, channels, conv_cfg, norm_cfg,
+ act_cfg):
+ super(ASPPModule, self).__init__()
+ self.dilations = dilations
+ self.in_channels = in_channels
+ self.channels = channels
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+ for dilation in dilations:
+ self.append(
+ ConvModule(
+ self.in_channels,
+ self.channels,
+ 1 if dilation == 1 else 3,
+ dilation=dilation,
+ padding=0 if dilation == 1 else dilation,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg))
+
+ def forward(self, x):
+ """Forward function."""
+ aspp_outs = []
+ for aspp_module in self:
+ aspp_outs.append(aspp_module(x))
+
+ return aspp_outs
+
+
+@HEADS.register_module()
+class ASPPHead(BaseDecodeHead):
+ """Rethinking Atrous Convolution for Semantic Image Segmentation.
+
+ This head is the implementation of `DeepLabV3
+ `_.
+
+ Args:
+ dilations (tuple[int]): Dilation rates for ASPP module.
+ Default: (1, 6, 12, 18).
+ """
+
+ def __init__(self, dilations=(1, 6, 12, 18), **kwargs):
+ super(ASPPHead, self).__init__(**kwargs)
+ assert isinstance(dilations, (list, tuple))
+ self.dilations = dilations
+ self.image_pool = nn.Sequential(
+ nn.AdaptiveAvgPool2d(1),
+ ConvModule(
+ self.in_channels,
+ self.channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg))
+ self.aspp_modules = ASPPModule(
+ dilations,
+ self.in_channels,
+ self.channels,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ self.bottleneck = ConvModule(
+ (len(dilations) + 1) * self.channels,
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ def _forward_feature(self, inputs):
+ """Forward function for feature maps before classifying each pixel with
+ ``self.cls_seg`` fc.
+
+ Args:
+ inputs (list[Tensor]): List of multi-level img features.
+
+ Returns:
+ feats (Tensor): A tensor of shape (batch_size, self.channels,
+ H, W) which is feature map for last layer of decoder head.
+ """
+ x = self._transform_inputs(inputs)
+ aspp_outs = [
+ resize(
+ self.image_pool(x),
+ size=x.size()[2:],
+ mode='bilinear',
+ align_corners=self.align_corners)
+ ]
+ aspp_outs.extend(self.aspp_modules(x))
+ aspp_outs = torch.cat(aspp_outs, dim=1)
+ feats = self.bottleneck(aspp_outs)
+ return feats
+
+ def forward(self, inputs):
+ """Forward function."""
+ output = self._forward_feature(inputs)
+ output = self.cls_seg(output)
+ return output
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/cascade_decode_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/cascade_decode_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..f7c3da0d67f920af01cad802461ce74d44404d7d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/cascade_decode_head.py
@@ -0,0 +1,58 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from abc import ABCMeta, abstractmethod
+
+from .decode_head import BaseDecodeHead
+
+
+class BaseCascadeDecodeHead(BaseDecodeHead, metaclass=ABCMeta):
+ """Base class for cascade decode head used in
+ :class:`CascadeEncoderDecoder."""
+
+ def __init__(self, *args, **kwargs):
+ super(BaseCascadeDecodeHead, self).__init__(*args, **kwargs)
+
+ @abstractmethod
+ def forward(self, inputs, prev_output):
+ """Placeholder of forward function."""
+ pass
+
+ def forward_train(self, inputs, prev_output, img_metas, gt_semantic_seg,
+ train_cfg):
+ """Forward function for training.
+ Args:
+ inputs (list[Tensor]): List of multi-level img features.
+ prev_output (Tensor): The output of previous decode head.
+ img_metas (list[dict]): List of image info dict where each dict
+ has: 'img_shape', 'scale_factor', 'flip', and may also contain
+ 'filename', 'ori_shape', 'pad_shape', and 'img_norm_cfg'.
+ For details on the values of these keys see
+ `mmseg/datasets/pipelines/formatting.py:Collect`.
+ gt_semantic_seg (Tensor): Semantic segmentation masks
+ used if the architecture supports semantic segmentation task.
+ train_cfg (dict): The training config.
+
+ Returns:
+ dict[str, Tensor]: a dictionary of loss components
+ """
+ seg_logits = self.forward(inputs, prev_output)
+ losses = self.losses(seg_logits, gt_semantic_seg)
+
+ return losses
+
+ def forward_test(self, inputs, prev_output, img_metas, test_cfg):
+ """Forward function for testing.
+
+ Args:
+ inputs (list[Tensor]): List of multi-level img features.
+ prev_output (Tensor): The output of previous decode head.
+ img_metas (list[dict]): List of image info dict where each dict
+ has: 'img_shape', 'scale_factor', 'flip', and may also contain
+ 'filename', 'ori_shape', 'pad_shape', and 'img_norm_cfg'.
+ For details on the values of these keys see
+ `mmseg/datasets/pipelines/formatting.py:Collect`.
+ test_cfg (dict): The testing config.
+
+ Returns:
+ Tensor: Output segmentation map.
+ """
+ return self.forward(inputs, prev_output)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/cc_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/cc_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..ed19eb46d123fa8da5b61cf98a6a3f78abf8a494
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/cc_head.py
@@ -0,0 +1,43 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+
+from ..builder import HEADS
+from .fcn_head import FCNHead
+
+try:
+ from mmcv.ops import CrissCrossAttention
+except ModuleNotFoundError:
+ CrissCrossAttention = None
+
+
+@HEADS.register_module()
+class CCHead(FCNHead):
+ """CCNet: Criss-Cross Attention for Semantic Segmentation.
+
+ This head is the implementation of `CCNet
+ `_.
+
+ Args:
+ recurrence (int): Number of recurrence of Criss Cross Attention
+ module. Default: 2.
+ """
+
+ def __init__(self, recurrence=2, **kwargs):
+ if CrissCrossAttention is None:
+ raise RuntimeError('Please install mmcv-full for '
+ 'CrissCrossAttention ops')
+ super(CCHead, self).__init__(num_convs=2, **kwargs)
+ self.recurrence = recurrence
+ self.cca = CrissCrossAttention(self.channels)
+
+ def forward(self, inputs):
+ """Forward function."""
+ x = self._transform_inputs(inputs)
+ output = self.convs[0](x)
+ for _ in range(self.recurrence):
+ output = self.cca(output)
+ output = self.convs[1](output)
+ if self.concat_input:
+ output = self.conv_cat(torch.cat([x, output], dim=1))
+ output = self.cls_seg(output)
+ return output
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/da_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/da_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..77fd6639c00bd4cad4cfa8f0da13a3f38dccf840
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/da_head.py
@@ -0,0 +1,179 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn.functional as F
+from mmcv.cnn import ConvModule, Scale
+from torch import nn
+
+from mmseg.core import add_prefix
+from ..builder import HEADS
+from ..utils import SelfAttentionBlock as _SelfAttentionBlock
+from .decode_head import BaseDecodeHead
+
+
+class PAM(_SelfAttentionBlock):
+ """Position Attention Module (PAM)
+
+ Args:
+ in_channels (int): Input channels of key/query feature.
+ channels (int): Output channels of key/query transform.
+ """
+
+ def __init__(self, in_channels, channels):
+ super(PAM, self).__init__(
+ key_in_channels=in_channels,
+ query_in_channels=in_channels,
+ channels=channels,
+ out_channels=in_channels,
+ share_key_query=False,
+ query_downsample=None,
+ key_downsample=None,
+ key_query_num_convs=1,
+ key_query_norm=False,
+ value_out_num_convs=1,
+ value_out_norm=False,
+ matmul_norm=False,
+ with_out=False,
+ conv_cfg=None,
+ norm_cfg=None,
+ act_cfg=None)
+
+ self.gamma = Scale(0)
+
+ def forward(self, x):
+ """Forward function."""
+ out = super(PAM, self).forward(x, x)
+
+ out = self.gamma(out) + x
+ return out
+
+
+class CAM(nn.Module):
+ """Channel Attention Module (CAM)"""
+
+ def __init__(self):
+ super(CAM, self).__init__()
+ self.gamma = Scale(0)
+
+ def forward(self, x):
+ """Forward function."""
+ batch_size, channels, height, width = x.size()
+ proj_query = x.view(batch_size, channels, -1)
+ proj_key = x.view(batch_size, channels, -1).permute(0, 2, 1)
+ energy = torch.bmm(proj_query, proj_key)
+ energy_new = torch.max(
+ energy, -1, keepdim=True)[0].expand_as(energy) - energy
+ attention = F.softmax(energy_new, dim=-1)
+ proj_value = x.view(batch_size, channels, -1)
+
+ out = torch.bmm(attention, proj_value)
+ out = out.view(batch_size, channels, height, width)
+
+ out = self.gamma(out) + x
+ return out
+
+
+@HEADS.register_module()
+class DAHead(BaseDecodeHead):
+ """Dual Attention Network for Scene Segmentation.
+
+ This head is the implementation of `DANet
+ `_.
+
+ Args:
+ pam_channels (int): The channels of Position Attention Module(PAM).
+ """
+
+ def __init__(self, pam_channels, **kwargs):
+ super(DAHead, self).__init__(**kwargs)
+ self.pam_channels = pam_channels
+ self.pam_in_conv = ConvModule(
+ self.in_channels,
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ self.pam = PAM(self.channels, pam_channels)
+ self.pam_out_conv = ConvModule(
+ self.channels,
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ self.pam_conv_seg = nn.Conv2d(
+ self.channels, self.num_classes, kernel_size=1)
+
+ self.cam_in_conv = ConvModule(
+ self.in_channels,
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ self.cam = CAM()
+ self.cam_out_conv = ConvModule(
+ self.channels,
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ self.cam_conv_seg = nn.Conv2d(
+ self.channels, self.num_classes, kernel_size=1)
+
+ def pam_cls_seg(self, feat):
+ """PAM feature classification."""
+ if self.dropout is not None:
+ feat = self.dropout(feat)
+ output = self.pam_conv_seg(feat)
+ return output
+
+ def cam_cls_seg(self, feat):
+ """CAM feature classification."""
+ if self.dropout is not None:
+ feat = self.dropout(feat)
+ output = self.cam_conv_seg(feat)
+ return output
+
+ def forward(self, inputs):
+ """Forward function."""
+ x = self._transform_inputs(inputs)
+ pam_feat = self.pam_in_conv(x)
+ pam_feat = self.pam(pam_feat)
+ pam_feat = self.pam_out_conv(pam_feat)
+ pam_out = self.pam_cls_seg(pam_feat)
+
+ cam_feat = self.cam_in_conv(x)
+ cam_feat = self.cam(cam_feat)
+ cam_feat = self.cam_out_conv(cam_feat)
+ cam_out = self.cam_cls_seg(cam_feat)
+
+ feat_sum = pam_feat + cam_feat
+ pam_cam_out = self.cls_seg(feat_sum)
+
+ return pam_cam_out, pam_out, cam_out
+
+ def forward_test(self, inputs, img_metas, test_cfg):
+ """Forward function for testing, only ``pam_cam`` is used."""
+ return self.forward(inputs)[0]
+
+ def losses(self, seg_logit, seg_label):
+ """Compute ``pam_cam``, ``pam``, ``cam`` loss."""
+ pam_cam_seg_logit, pam_seg_logit, cam_seg_logit = seg_logit
+ loss = dict()
+ loss.update(
+ add_prefix(
+ super(DAHead, self).losses(pam_cam_seg_logit, seg_label),
+ 'pam_cam'))
+ loss.update(
+ add_prefix(
+ super(DAHead, self).losses(pam_seg_logit, seg_label), 'pam'))
+ loss.update(
+ add_prefix(
+ super(DAHead, self).losses(cam_seg_logit, seg_label), 'cam'))
+ return loss
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/decode_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/decode_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..d08b1d0b6067604c5e3ef8d4fbbea8bbda02f6db
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/decode_head.py
@@ -0,0 +1,266 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from abc import ABCMeta, abstractmethod
+
+import torch
+import torch.nn as nn
+from mmcv.runner import BaseModule, auto_fp16, force_fp32
+
+from mmseg.core import build_pixel_sampler
+from mmseg.ops import resize
+from ..builder import build_loss
+from ..losses import accuracy
+
+
+class BaseDecodeHead(BaseModule, metaclass=ABCMeta):
+ """Base class for BaseDecodeHead.
+
+ Args:
+ in_channels (int|Sequence[int]): Input channels.
+ channels (int): Channels after modules, before conv_seg.
+ num_classes (int): Number of classes.
+ dropout_ratio (float): Ratio of dropout layer. Default: 0.1.
+ conv_cfg (dict|None): Config of conv layers. Default: None.
+ norm_cfg (dict|None): Config of norm layers. Default: None.
+ act_cfg (dict): Config of activation layers.
+ Default: dict(type='ReLU')
+ in_index (int|Sequence[int]): Input feature index. Default: -1
+ input_transform (str|None): Transformation type of input features.
+ Options: 'resize_concat', 'multiple_select', None.
+ 'resize_concat': Multiple feature maps will be resize to the
+ same size as first one and than concat together.
+ Usually used in FCN head of HRNet.
+ 'multiple_select': Multiple feature maps will be bundle into
+ a list and passed into decode head.
+ None: Only one select feature map is allowed.
+ Default: None.
+ loss_decode (dict | Sequence[dict]): Config of decode loss.
+ The `loss_name` is property of corresponding loss function which
+ could be shown in training log. If you want this loss
+ item to be included into the backward graph, `loss_` must be the
+ prefix of the name. Defaults to 'loss_ce'.
+ e.g. dict(type='CrossEntropyLoss'),
+ [dict(type='CrossEntropyLoss', loss_name='loss_ce'),
+ dict(type='DiceLoss', loss_name='loss_dice')]
+ Default: dict(type='CrossEntropyLoss').
+ ignore_index (int | None): The label index to be ignored. When using
+ masked BCE loss, ignore_index should be set to None. Default: 255.
+ sampler (dict|None): The config of segmentation map sampler.
+ Default: None.
+ align_corners (bool): align_corners argument of F.interpolate.
+ Default: False.
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ """
+
+ def __init__(self,
+ in_channels,
+ channels,
+ *,
+ num_classes,
+ dropout_ratio=0.1,
+ conv_cfg=None,
+ norm_cfg=None,
+ act_cfg=dict(type='ReLU'),
+ in_index=-1,
+ input_transform=None,
+ loss_decode=dict(
+ type='CrossEntropyLoss',
+ use_sigmoid=False,
+ loss_weight=1.0),
+ ignore_index=255,
+ sampler=None,
+ align_corners=False,
+ init_cfg=dict(
+ type='Normal', std=0.01, override=dict(name='conv_seg'))):
+ super(BaseDecodeHead, self).__init__(init_cfg)
+ self._init_inputs(in_channels, in_index, input_transform)
+ self.channels = channels
+ self.num_classes = num_classes
+ self.dropout_ratio = dropout_ratio
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+ self.in_index = in_index
+
+ self.ignore_index = ignore_index
+ self.align_corners = align_corners
+
+ if isinstance(loss_decode, dict):
+ self.loss_decode = build_loss(loss_decode)
+ elif isinstance(loss_decode, (list, tuple)):
+ self.loss_decode = nn.ModuleList()
+ for loss in loss_decode:
+ self.loss_decode.append(build_loss(loss))
+ else:
+ raise TypeError(f'loss_decode must be a dict or sequence of dict,\
+ but got {type(loss_decode)}')
+
+ if sampler is not None:
+ self.sampler = build_pixel_sampler(sampler, context=self)
+ else:
+ self.sampler = None
+
+ self.conv_seg = nn.Conv2d(channels, num_classes, kernel_size=1)
+ if dropout_ratio > 0:
+ self.dropout = nn.Dropout2d(dropout_ratio)
+ else:
+ self.dropout = None
+ self.fp16_enabled = False
+
+ def extra_repr(self):
+ """Extra repr."""
+ s = f'input_transform={self.input_transform}, ' \
+ f'ignore_index={self.ignore_index}, ' \
+ f'align_corners={self.align_corners}'
+ return s
+
+ def _init_inputs(self, in_channels, in_index, input_transform):
+ """Check and initialize input transforms.
+
+ The in_channels, in_index and input_transform must match.
+ Specifically, when input_transform is None, only single feature map
+ will be selected. So in_channels and in_index must be of type int.
+ When input_transform
+
+ Args:
+ in_channels (int|Sequence[int]): Input channels.
+ in_index (int|Sequence[int]): Input feature index.
+ input_transform (str|None): Transformation type of input features.
+ Options: 'resize_concat', 'multiple_select', None.
+ 'resize_concat': Multiple feature maps will be resize to the
+ same size as first one and than concat together.
+ Usually used in FCN head of HRNet.
+ 'multiple_select': Multiple feature maps will be bundle into
+ a list and passed into decode head.
+ None: Only one select feature map is allowed.
+ """
+
+ if input_transform is not None:
+ assert input_transform in ['resize_concat', 'multiple_select']
+ self.input_transform = input_transform
+ self.in_index = in_index
+ if input_transform is not None:
+ assert isinstance(in_channels, (list, tuple))
+ assert isinstance(in_index, (list, tuple))
+ assert len(in_channels) == len(in_index)
+ if input_transform == 'resize_concat':
+ self.in_channels = sum(in_channels)
+ else:
+ self.in_channels = in_channels
+ else:
+ assert isinstance(in_channels, int)
+ assert isinstance(in_index, int)
+ self.in_channels = in_channels
+
+ def _transform_inputs(self, inputs):
+ """Transform inputs for decoder.
+
+ Args:
+ inputs (list[Tensor]): List of multi-level img features.
+
+ Returns:
+ Tensor: The transformed inputs
+ """
+
+ if self.input_transform == 'resize_concat':
+ inputs = [inputs[i] for i in self.in_index]
+ upsampled_inputs = [
+ resize(
+ input=x,
+ size=inputs[0].shape[2:],
+ mode='bilinear',
+ align_corners=self.align_corners) for x in inputs
+ ]
+ inputs = torch.cat(upsampled_inputs, dim=1)
+ elif self.input_transform == 'multiple_select':
+ inputs = [inputs[i] for i in self.in_index]
+ else:
+ inputs = inputs[self.in_index]
+
+ return inputs
+
+ @auto_fp16()
+ @abstractmethod
+ def forward(self, inputs):
+ """Placeholder of forward function."""
+ pass
+
+ def forward_train(self, inputs, img_metas, gt_semantic_seg, train_cfg):
+ """Forward function for training.
+ Args:
+ inputs (list[Tensor]): List of multi-level img features.
+ img_metas (list[dict]): List of image info dict where each dict
+ has: 'img_shape', 'scale_factor', 'flip', and may also contain
+ 'filename', 'ori_shape', 'pad_shape', and 'img_norm_cfg'.
+ For details on the values of these keys see
+ `mmseg/datasets/pipelines/formatting.py:Collect`.
+ gt_semantic_seg (Tensor): Semantic segmentation masks
+ used if the architecture supports semantic segmentation task.
+ train_cfg (dict): The training config.
+
+ Returns:
+ dict[str, Tensor]: a dictionary of loss components
+ """
+ seg_logits = self.forward(inputs)
+ losses = self.losses(seg_logits, gt_semantic_seg)
+ return losses
+
+ def forward_test(self, inputs, img_metas, test_cfg):
+ """Forward function for testing.
+
+ Args:
+ inputs (list[Tensor]): List of multi-level img features.
+ img_metas (list[dict]): List of image info dict where each dict
+ has: 'img_shape', 'scale_factor', 'flip', and may also contain
+ 'filename', 'ori_shape', 'pad_shape', and 'img_norm_cfg'.
+ For details on the values of these keys see
+ `mmseg/datasets/pipelines/formatting.py:Collect`.
+ test_cfg (dict): The testing config.
+
+ Returns:
+ Tensor: Output segmentation map.
+ """
+ return self.forward(inputs)
+
+ def cls_seg(self, feat):
+ """Classify each pixel."""
+ if self.dropout is not None:
+ feat = self.dropout(feat)
+ output = self.conv_seg(feat)
+ return output
+
+ @force_fp32(apply_to=('seg_logit', ))
+ def losses(self, seg_logit, seg_label):
+ """Compute segmentation loss."""
+ loss = dict()
+ seg_logit = resize(
+ input=seg_logit,
+ size=seg_label.shape[2:],
+ mode='bilinear',
+ align_corners=self.align_corners)
+ if self.sampler is not None:
+ seg_weight = self.sampler.sample(seg_logit, seg_label)
+ else:
+ seg_weight = None
+ seg_label = seg_label.squeeze(1)
+
+ if not isinstance(self.loss_decode, nn.ModuleList):
+ losses_decode = [self.loss_decode]
+ else:
+ losses_decode = self.loss_decode
+ for loss_decode in losses_decode:
+ if loss_decode.loss_name not in loss:
+ loss[loss_decode.loss_name] = loss_decode(
+ seg_logit,
+ seg_label,
+ weight=seg_weight,
+ ignore_index=self.ignore_index)
+ else:
+ loss[loss_decode.loss_name] += loss_decode(
+ seg_logit,
+ seg_label,
+ weight=seg_weight,
+ ignore_index=self.ignore_index)
+
+ loss['acc_seg'] = accuracy(
+ seg_logit, seg_label, ignore_index=self.ignore_index)
+ return loss
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/dm_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/dm_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..ffaa870ab3a6f10afec7d07d395e8f405eda936f
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/dm_head.py
@@ -0,0 +1,141 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+from mmcv.cnn import ConvModule, build_activation_layer, build_norm_layer
+
+from ..builder import HEADS
+from .decode_head import BaseDecodeHead
+
+
+class DCM(nn.Module):
+ """Dynamic Convolutional Module used in DMNet.
+
+ Args:
+ filter_size (int): The filter size of generated convolution kernel
+ used in Dynamic Convolutional Module.
+ fusion (bool): Add one conv to fuse DCM output feature.
+ in_channels (int): Input channels.
+ channels (int): Channels after modules, before conv_seg.
+ conv_cfg (dict | None): Config of conv layers.
+ norm_cfg (dict | None): Config of norm layers.
+ act_cfg (dict): Config of activation layers.
+ """
+
+ def __init__(self, filter_size, fusion, in_channels, channels, conv_cfg,
+ norm_cfg, act_cfg):
+ super(DCM, self).__init__()
+ self.filter_size = filter_size
+ self.fusion = fusion
+ self.in_channels = in_channels
+ self.channels = channels
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+ self.filter_gen_conv = nn.Conv2d(self.in_channels, self.channels, 1, 1,
+ 0)
+
+ self.input_redu_conv = ConvModule(
+ self.in_channels,
+ self.channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ if self.norm_cfg is not None:
+ self.norm = build_norm_layer(self.norm_cfg, self.channels)[1]
+ else:
+ self.norm = None
+ self.activate = build_activation_layer(self.act_cfg)
+
+ if self.fusion:
+ self.fusion_conv = ConvModule(
+ self.channels,
+ self.channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ def forward(self, x):
+ """Forward function."""
+ generated_filter = self.filter_gen_conv(
+ F.adaptive_avg_pool2d(x, self.filter_size))
+ x = self.input_redu_conv(x)
+ b, c, h, w = x.shape
+ # [1, b * c, h, w], c = self.channels
+ x = x.view(1, b * c, h, w)
+ # [b * c, 1, filter_size, filter_size]
+ generated_filter = generated_filter.view(b * c, 1, self.filter_size,
+ self.filter_size)
+ pad = (self.filter_size - 1) // 2
+ if (self.filter_size - 1) % 2 == 0:
+ p2d = (pad, pad, pad, pad)
+ else:
+ p2d = (pad + 1, pad, pad + 1, pad)
+ x = F.pad(input=x, pad=p2d, mode='constant', value=0)
+ # [1, b * c, h, w]
+ output = F.conv2d(input=x, weight=generated_filter, groups=b * c)
+ # [b, c, h, w]
+ output = output.view(b, c, h, w)
+ if self.norm is not None:
+ output = self.norm(output)
+ output = self.activate(output)
+
+ if self.fusion:
+ output = self.fusion_conv(output)
+
+ return output
+
+
+@HEADS.register_module()
+class DMHead(BaseDecodeHead):
+ """Dynamic Multi-scale Filters for Semantic Segmentation.
+
+ This head is the implementation of
+ `DMNet `_.
+
+ Args:
+ filter_sizes (tuple[int]): The size of generated convolutional filters
+ used in Dynamic Convolutional Module. Default: (1, 3, 5, 7).
+ fusion (bool): Add one conv to fuse DCM output feature.
+ """
+
+ def __init__(self, filter_sizes=(1, 3, 5, 7), fusion=False, **kwargs):
+ super(DMHead, self).__init__(**kwargs)
+ assert isinstance(filter_sizes, (list, tuple))
+ self.filter_sizes = filter_sizes
+ self.fusion = fusion
+ dcm_modules = []
+ for filter_size in self.filter_sizes:
+ dcm_modules.append(
+ DCM(filter_size,
+ self.fusion,
+ self.in_channels,
+ self.channels,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg))
+ self.dcm_modules = nn.ModuleList(dcm_modules)
+ self.bottleneck = ConvModule(
+ self.in_channels + len(filter_sizes) * self.channels,
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ def forward(self, inputs):
+ """Forward function."""
+ x = self._transform_inputs(inputs)
+ dcm_outs = [x]
+ for dcm_module in self.dcm_modules:
+ dcm_outs.append(dcm_module(x))
+ dcm_outs = torch.cat(dcm_outs, dim=1)
+ output = self.bottleneck(dcm_outs)
+ output = self.cls_seg(output)
+ return output
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/dnl_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/dnl_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..dabf1542148d3dafa419fdb2884b006144742e5a
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/dnl_head.py
@@ -0,0 +1,137 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+from mmcv.cnn import NonLocal2d
+from torch import nn
+
+from ..builder import HEADS
+from .fcn_head import FCNHead
+
+
+class DisentangledNonLocal2d(NonLocal2d):
+ """Disentangled Non-Local Blocks.
+
+ Args:
+ temperature (float): Temperature to adjust attention. Default: 0.05
+ """
+
+ def __init__(self, *arg, temperature, **kwargs):
+ super().__init__(*arg, **kwargs)
+ self.temperature = temperature
+ self.conv_mask = nn.Conv2d(self.in_channels, 1, kernel_size=1)
+
+ def embedded_gaussian(self, theta_x, phi_x):
+ """Embedded gaussian with temperature."""
+
+ # NonLocal2d pairwise_weight: [N, HxW, HxW]
+ pairwise_weight = torch.matmul(theta_x, phi_x)
+ if self.use_scale:
+ # theta_x.shape[-1] is `self.inter_channels`
+ pairwise_weight /= torch.tensor(
+ theta_x.shape[-1],
+ dtype=torch.float,
+ device=pairwise_weight.device)**torch.tensor(
+ 0.5, device=pairwise_weight.device)
+ pairwise_weight /= torch.tensor(
+ self.temperature, device=pairwise_weight.device)
+ pairwise_weight = pairwise_weight.softmax(dim=-1)
+ return pairwise_weight
+
+ def forward(self, x):
+ # x: [N, C, H, W]
+ n = x.size(0)
+
+ # g_x: [N, HxW, C]
+ g_x = self.g(x).view(n, self.inter_channels, -1)
+ g_x = g_x.permute(0, 2, 1)
+
+ # theta_x: [N, HxW, C], phi_x: [N, C, HxW]
+ if self.mode == 'gaussian':
+ theta_x = x.view(n, self.in_channels, -1)
+ theta_x = theta_x.permute(0, 2, 1)
+ if self.sub_sample:
+ phi_x = self.phi(x).view(n, self.in_channels, -1)
+ else:
+ phi_x = x.view(n, self.in_channels, -1)
+ elif self.mode == 'concatenation':
+ theta_x = self.theta(x).view(n, self.inter_channels, -1, 1)
+ phi_x = self.phi(x).view(n, self.inter_channels, 1, -1)
+ else:
+ theta_x = self.theta(x).view(n, self.inter_channels, -1)
+ theta_x = theta_x.permute(0, 2, 1)
+ phi_x = self.phi(x).view(n, self.inter_channels, -1)
+
+ # subtract mean
+ theta_x -= theta_x.mean(dim=-2, keepdim=True)
+ phi_x -= phi_x.mean(dim=-1, keepdim=True)
+
+ pairwise_func = getattr(self, self.mode)
+ # pairwise_weight: [N, HxW, HxW]
+ pairwise_weight = pairwise_func(theta_x, phi_x)
+
+ # y: [N, HxW, C]
+ y = torch.matmul(pairwise_weight, g_x)
+ # y: [N, C, H, W]
+ y = y.permute(0, 2, 1).contiguous().reshape(n, self.inter_channels,
+ *x.size()[2:])
+
+ # unary_mask: [N, 1, HxW]
+ unary_mask = self.conv_mask(x)
+ unary_mask = unary_mask.view(n, 1, -1)
+ unary_mask = unary_mask.softmax(dim=-1)
+ # unary_x: [N, 1, C]
+ unary_x = torch.matmul(unary_mask, g_x)
+ # unary_x: [N, C, 1, 1]
+ unary_x = unary_x.permute(0, 2, 1).contiguous().reshape(
+ n, self.inter_channels, 1, 1)
+
+ output = x + self.conv_out(y + unary_x)
+
+ return output
+
+
+@HEADS.register_module()
+class DNLHead(FCNHead):
+ """Disentangled Non-Local Neural Networks.
+
+ This head is the implementation of `DNLNet
+ `_.
+
+ Args:
+ reduction (int): Reduction factor of projection transform. Default: 2.
+ use_scale (bool): Whether to scale pairwise_weight by
+ sqrt(1/inter_channels). Default: False.
+ mode (str): The nonlocal mode. Options are 'embedded_gaussian',
+ 'dot_product'. Default: 'embedded_gaussian.'.
+ temperature (float): Temperature to adjust attention. Default: 0.05
+ """
+
+ def __init__(self,
+ reduction=2,
+ use_scale=True,
+ mode='embedded_gaussian',
+ temperature=0.05,
+ **kwargs):
+ super(DNLHead, self).__init__(num_convs=2, **kwargs)
+ self.reduction = reduction
+ self.use_scale = use_scale
+ self.mode = mode
+ self.temperature = temperature
+ self.dnl_block = DisentangledNonLocal2d(
+ in_channels=self.channels,
+ reduction=self.reduction,
+ use_scale=self.use_scale,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ mode=self.mode,
+ temperature=self.temperature)
+
+ def forward(self, inputs):
+ """Forward function."""
+ x = self._transform_inputs(inputs)
+ output = self.convs[0](x)
+ output = self.dnl_block(output)
+ output = self.convs[1](output)
+ if self.concat_input:
+ output = self.conv_cat(torch.cat([x, output], dim=1))
+ output = self.cls_seg(output)
+ return output
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/dpt_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/dpt_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..6c895d02dfc06c369de878e919ae5ccd5073d819
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/dpt_head.py
@@ -0,0 +1,294 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import math
+
+import torch
+import torch.nn as nn
+from mmcv.cnn import ConvModule, Linear, build_activation_layer
+from mmcv.runner import BaseModule
+
+from mmseg.ops import resize
+from ..builder import HEADS
+from .decode_head import BaseDecodeHead
+
+
+class ReassembleBlocks(BaseModule):
+ """ViTPostProcessBlock, process cls_token in ViT backbone output and
+ rearrange the feature vector to feature map.
+
+ Args:
+ in_channels (int): ViT feature channels. Default: 768.
+ out_channels (List): output channels of each stage.
+ Default: [96, 192, 384, 768].
+ readout_type (str): Type of readout operation. Default: 'ignore'.
+ patch_size (int): The patch size. Default: 16.
+ init_cfg (dict, optional): Initialization config dict. Default: None.
+ """
+
+ def __init__(self,
+ in_channels=768,
+ out_channels=[96, 192, 384, 768],
+ readout_type='ignore',
+ patch_size=16,
+ init_cfg=None):
+ super(ReassembleBlocks, self).__init__(init_cfg)
+
+ assert readout_type in ['ignore', 'add', 'project']
+ self.readout_type = readout_type
+ self.patch_size = patch_size
+
+ self.projects = nn.ModuleList([
+ ConvModule(
+ in_channels=in_channels,
+ out_channels=out_channel,
+ kernel_size=1,
+ act_cfg=None,
+ ) for out_channel in out_channels
+ ])
+
+ self.resize_layers = nn.ModuleList([
+ nn.ConvTranspose2d(
+ in_channels=out_channels[0],
+ out_channels=out_channels[0],
+ kernel_size=4,
+ stride=4,
+ padding=0),
+ nn.ConvTranspose2d(
+ in_channels=out_channels[1],
+ out_channels=out_channels[1],
+ kernel_size=2,
+ stride=2,
+ padding=0),
+ nn.Identity(),
+ nn.Conv2d(
+ in_channels=out_channels[3],
+ out_channels=out_channels[3],
+ kernel_size=3,
+ stride=2,
+ padding=1)
+ ])
+ if self.readout_type == 'project':
+ self.readout_projects = nn.ModuleList()
+ for _ in range(len(self.projects)):
+ self.readout_projects.append(
+ nn.Sequential(
+ Linear(2 * in_channels, in_channels),
+ build_activation_layer(dict(type='GELU'))))
+
+ def forward(self, inputs):
+ assert isinstance(inputs, list)
+ out = []
+ for i, x in enumerate(inputs):
+ assert len(x) == 2
+ x, cls_token = x[0], x[1]
+ feature_shape = x.shape
+ if self.readout_type == 'project':
+ x = x.flatten(2).permute((0, 2, 1))
+ readout = cls_token.unsqueeze(1).expand_as(x)
+ x = self.readout_projects[i](torch.cat((x, readout), -1))
+ x = x.permute(0, 2, 1).reshape(feature_shape)
+ elif self.readout_type == 'add':
+ x = x.flatten(2) + cls_token.unsqueeze(-1)
+ x = x.reshape(feature_shape)
+ else:
+ pass
+ x = self.projects[i](x)
+ x = self.resize_layers[i](x)
+ out.append(x)
+ return out
+
+
+class PreActResidualConvUnit(BaseModule):
+ """ResidualConvUnit, pre-activate residual unit.
+
+ Args:
+ in_channels (int): number of channels in the input feature map.
+ act_cfg (dict): dictionary to construct and config activation layer.
+ norm_cfg (dict): dictionary to construct and config norm layer.
+ stride (int): stride of the first block. Default: 1
+ dilation (int): dilation rate for convs layers. Default: 1.
+ init_cfg (dict, optional): Initialization config dict. Default: None.
+ """
+
+ def __init__(self,
+ in_channels,
+ act_cfg,
+ norm_cfg,
+ stride=1,
+ dilation=1,
+ init_cfg=None):
+ super(PreActResidualConvUnit, self).__init__(init_cfg)
+
+ self.conv1 = ConvModule(
+ in_channels,
+ in_channels,
+ 3,
+ stride=stride,
+ padding=dilation,
+ dilation=dilation,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg,
+ bias=False,
+ order=('act', 'conv', 'norm'))
+
+ self.conv2 = ConvModule(
+ in_channels,
+ in_channels,
+ 3,
+ padding=1,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg,
+ bias=False,
+ order=('act', 'conv', 'norm'))
+
+ def forward(self, inputs):
+ inputs_ = inputs.clone()
+ x = self.conv1(inputs)
+ x = self.conv2(x)
+ return x + inputs_
+
+
+class FeatureFusionBlock(BaseModule):
+ """FeatureFusionBlock, merge feature map from different stages.
+
+ Args:
+ in_channels (int): Input channels.
+ act_cfg (dict): The activation config for ResidualConvUnit.
+ norm_cfg (dict): Config dict for normalization layer.
+ expand (bool): Whether expand the channels in post process block.
+ Default: False.
+ align_corners (bool): align_corner setting for bilinear upsample.
+ Default: True.
+ init_cfg (dict, optional): Initialization config dict. Default: None.
+ """
+
+ def __init__(self,
+ in_channels,
+ act_cfg,
+ norm_cfg,
+ expand=False,
+ align_corners=True,
+ init_cfg=None):
+ super(FeatureFusionBlock, self).__init__(init_cfg)
+
+ self.in_channels = in_channels
+ self.expand = expand
+ self.align_corners = align_corners
+
+ self.out_channels = in_channels
+ if self.expand:
+ self.out_channels = in_channels // 2
+
+ self.project = ConvModule(
+ self.in_channels,
+ self.out_channels,
+ kernel_size=1,
+ act_cfg=None,
+ bias=True)
+
+ self.res_conv_unit1 = PreActResidualConvUnit(
+ in_channels=self.in_channels, act_cfg=act_cfg, norm_cfg=norm_cfg)
+ self.res_conv_unit2 = PreActResidualConvUnit(
+ in_channels=self.in_channels, act_cfg=act_cfg, norm_cfg=norm_cfg)
+
+ def forward(self, *inputs):
+ x = inputs[0]
+ if len(inputs) == 2:
+ if x.shape != inputs[1].shape:
+ res = resize(
+ inputs[1],
+ size=(x.shape[2], x.shape[3]),
+ mode='bilinear',
+ align_corners=False)
+ else:
+ res = inputs[1]
+ x = x + self.res_conv_unit1(res)
+ x = self.res_conv_unit2(x)
+ x = resize(
+ x,
+ scale_factor=2,
+ mode='bilinear',
+ align_corners=self.align_corners)
+ x = self.project(x)
+ return x
+
+
+@HEADS.register_module()
+class DPTHead(BaseDecodeHead):
+ """Vision Transformers for Dense Prediction.
+
+ This head is implemented of `DPT `_.
+
+ Args:
+ embed_dims (int): The embed dimension of the ViT backbone.
+ Default: 768.
+ post_process_channels (List): Out channels of post process conv
+ layers. Default: [96, 192, 384, 768].
+ readout_type (str): Type of readout operation. Default: 'ignore'.
+ patch_size (int): The patch size. Default: 16.
+ expand_channels (bool): Whether expand the channels in post process
+ block. Default: False.
+ act_cfg (dict): The activation config for residual conv unit.
+ Default dict(type='ReLU').
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='BN').
+ """
+
+ def __init__(self,
+ embed_dims=768,
+ post_process_channels=[96, 192, 384, 768],
+ readout_type='ignore',
+ patch_size=16,
+ expand_channels=False,
+ act_cfg=dict(type='ReLU'),
+ norm_cfg=dict(type='BN'),
+ **kwargs):
+ super(DPTHead, self).__init__(**kwargs)
+
+ self.in_channels = self.in_channels
+ self.expand_channels = expand_channels
+ self.reassemble_blocks = ReassembleBlocks(embed_dims,
+ post_process_channels,
+ readout_type, patch_size)
+
+ self.post_process_channels = [
+ channel * math.pow(2, i) if expand_channels else channel
+ for i, channel in enumerate(post_process_channels)
+ ]
+ self.convs = nn.ModuleList()
+ for channel in self.post_process_channels:
+ self.convs.append(
+ ConvModule(
+ channel,
+ self.channels,
+ kernel_size=3,
+ padding=1,
+ act_cfg=None,
+ bias=False))
+ self.fusion_blocks = nn.ModuleList()
+ for _ in range(len(self.convs)):
+ self.fusion_blocks.append(
+ FeatureFusionBlock(self.channels, act_cfg, norm_cfg))
+ self.fusion_blocks[0].res_conv_unit1 = None
+ self.project = ConvModule(
+ self.channels,
+ self.channels,
+ kernel_size=3,
+ padding=1,
+ norm_cfg=norm_cfg)
+ self.num_fusion_blocks = len(self.fusion_blocks)
+ self.num_reassemble_blocks = len(self.reassemble_blocks.resize_layers)
+ self.num_post_process_channels = len(self.post_process_channels)
+ assert self.num_fusion_blocks == self.num_reassemble_blocks
+ assert self.num_reassemble_blocks == self.num_post_process_channels
+
+ def forward(self, inputs):
+ assert len(inputs) == self.num_reassemble_blocks
+ x = self._transform_inputs(inputs)
+ x = self.reassemble_blocks(x)
+ x = [self.convs[i](feature) for i, feature in enumerate(x)]
+ out = self.fusion_blocks[0](x[-1])
+ for i in range(1, len(self.fusion_blocks)):
+ out = self.fusion_blocks[i](out, x[-(i + 1)])
+ out = self.project(out)
+ out = self.cls_seg(out)
+ return out
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/ema_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/ema_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..f6de16711187c6235d7b2e594e5d71ac0ab66b99
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/ema_head.py
@@ -0,0 +1,169 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import math
+
+import torch
+import torch.distributed as dist
+import torch.nn as nn
+import torch.nn.functional as F
+from mmcv.cnn import ConvModule
+
+from ..builder import HEADS
+from .decode_head import BaseDecodeHead
+
+
+def reduce_mean(tensor):
+ """Reduce mean when distributed training."""
+ if not (dist.is_available() and dist.is_initialized()):
+ return tensor
+ tensor = tensor.clone()
+ dist.all_reduce(tensor.div_(dist.get_world_size()), op=dist.ReduceOp.SUM)
+ return tensor
+
+
+class EMAModule(nn.Module):
+ """Expectation Maximization Attention Module used in EMANet.
+
+ Args:
+ channels (int): Channels of the whole module.
+ num_bases (int): Number of bases.
+ num_stages (int): Number of the EM iterations.
+ """
+
+ def __init__(self, channels, num_bases, num_stages, momentum):
+ super(EMAModule, self).__init__()
+ assert num_stages >= 1, 'num_stages must be at least 1!'
+ self.num_bases = num_bases
+ self.num_stages = num_stages
+ self.momentum = momentum
+
+ bases = torch.zeros(1, channels, self.num_bases)
+ bases.normal_(0, math.sqrt(2. / self.num_bases))
+ # [1, channels, num_bases]
+ bases = F.normalize(bases, dim=1, p=2)
+ self.register_buffer('bases', bases)
+
+ def forward(self, feats):
+ """Forward function."""
+ batch_size, channels, height, width = feats.size()
+ # [batch_size, channels, height*width]
+ feats = feats.view(batch_size, channels, height * width)
+ # [batch_size, channels, num_bases]
+ bases = self.bases.repeat(batch_size, 1, 1)
+
+ with torch.no_grad():
+ for i in range(self.num_stages):
+ # [batch_size, height*width, num_bases]
+ attention = torch.einsum('bcn,bck->bnk', feats, bases)
+ attention = F.softmax(attention, dim=2)
+ # l1 norm
+ attention_normed = F.normalize(attention, dim=1, p=1)
+ # [batch_size, channels, num_bases]
+ bases = torch.einsum('bcn,bnk->bck', feats, attention_normed)
+ # l2 norm
+ bases = F.normalize(bases, dim=1, p=2)
+
+ feats_recon = torch.einsum('bck,bnk->bcn', bases, attention)
+ feats_recon = feats_recon.view(batch_size, channels, height, width)
+
+ if self.training:
+ bases = bases.mean(dim=0, keepdim=True)
+ bases = reduce_mean(bases)
+ # l2 norm
+ bases = F.normalize(bases, dim=1, p=2)
+ self.bases = (1 -
+ self.momentum) * self.bases + self.momentum * bases
+
+ return feats_recon
+
+
+@HEADS.register_module()
+class EMAHead(BaseDecodeHead):
+ """Expectation Maximization Attention Networks for Semantic Segmentation.
+
+ This head is the implementation of `EMANet
+ `_.
+
+ Args:
+ ema_channels (int): EMA module channels
+ num_bases (int): Number of bases.
+ num_stages (int): Number of the EM iterations.
+ concat_input (bool): Whether concat the input and output of convs
+ before classification layer. Default: True
+ momentum (float): Momentum to update the base. Default: 0.1.
+ """
+
+ def __init__(self,
+ ema_channels,
+ num_bases,
+ num_stages,
+ concat_input=True,
+ momentum=0.1,
+ **kwargs):
+ super(EMAHead, self).__init__(**kwargs)
+ self.ema_channels = ema_channels
+ self.num_bases = num_bases
+ self.num_stages = num_stages
+ self.concat_input = concat_input
+ self.momentum = momentum
+ self.ema_module = EMAModule(self.ema_channels, self.num_bases,
+ self.num_stages, self.momentum)
+
+ self.ema_in_conv = ConvModule(
+ self.in_channels,
+ self.ema_channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ # project (0, inf) -> (-inf, inf)
+ self.ema_mid_conv = ConvModule(
+ self.ema_channels,
+ self.ema_channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=None,
+ act_cfg=None)
+ for param in self.ema_mid_conv.parameters():
+ param.requires_grad = False
+
+ self.ema_out_conv = ConvModule(
+ self.ema_channels,
+ self.ema_channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=None)
+ self.bottleneck = ConvModule(
+ self.ema_channels,
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ if self.concat_input:
+ self.conv_cat = ConvModule(
+ self.in_channels + self.channels,
+ self.channels,
+ kernel_size=3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ def forward(self, inputs):
+ """Forward function."""
+ x = self._transform_inputs(inputs)
+ feats = self.ema_in_conv(x)
+ identity = feats
+ feats = self.ema_mid_conv(feats)
+ recon = self.ema_module(feats)
+ recon = F.relu(recon, inplace=True)
+ recon = self.ema_out_conv(recon)
+ output = F.relu(identity + recon, inplace=True)
+ output = self.bottleneck(output)
+ if self.concat_input:
+ output = self.conv_cat(torch.cat([x, output], dim=1))
+ output = self.cls_seg(output)
+ return output
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/enc_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/enc_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..648c8906b91254658dd71acd6471f09e87e7a720
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/enc_head.py
@@ -0,0 +1,188 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+from mmcv.cnn import ConvModule, build_norm_layer
+
+from mmseg.ops import Encoding, resize
+from ..builder import HEADS, build_loss
+from .decode_head import BaseDecodeHead
+
+
+class EncModule(nn.Module):
+ """Encoding Module used in EncNet.
+
+ Args:
+ in_channels (int): Input channels.
+ num_codes (int): Number of code words.
+ conv_cfg (dict|None): Config of conv layers.
+ norm_cfg (dict|None): Config of norm layers.
+ act_cfg (dict): Config of activation layers.
+ """
+
+ def __init__(self, in_channels, num_codes, conv_cfg, norm_cfg, act_cfg):
+ super(EncModule, self).__init__()
+ self.encoding_project = ConvModule(
+ in_channels,
+ in_channels,
+ 1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ # TODO: resolve this hack
+ # change to 1d
+ if norm_cfg is not None:
+ encoding_norm_cfg = norm_cfg.copy()
+ if encoding_norm_cfg['type'] in ['BN', 'IN']:
+ encoding_norm_cfg['type'] += '1d'
+ else:
+ encoding_norm_cfg['type'] = encoding_norm_cfg['type'].replace(
+ '2d', '1d')
+ else:
+ # fallback to BN1d
+ encoding_norm_cfg = dict(type='BN1d')
+ self.encoding = nn.Sequential(
+ Encoding(channels=in_channels, num_codes=num_codes),
+ build_norm_layer(encoding_norm_cfg, num_codes)[1],
+ nn.ReLU(inplace=True))
+ self.fc = nn.Sequential(
+ nn.Linear(in_channels, in_channels), nn.Sigmoid())
+
+ def forward(self, x):
+ """Forward function."""
+ encoding_projection = self.encoding_project(x)
+ encoding_feat = self.encoding(encoding_projection).mean(dim=1)
+ batch_size, channels, _, _ = x.size()
+ gamma = self.fc(encoding_feat)
+ y = gamma.view(batch_size, channels, 1, 1)
+ output = F.relu_(x + x * y)
+ return encoding_feat, output
+
+
+@HEADS.register_module()
+class EncHead(BaseDecodeHead):
+ """Context Encoding for Semantic Segmentation.
+
+ This head is the implementation of `EncNet
+ `_.
+
+ Args:
+ num_codes (int): Number of code words. Default: 32.
+ use_se_loss (bool): Whether use Semantic Encoding Loss (SE-loss) to
+ regularize the training. Default: True.
+ add_lateral (bool): Whether use lateral connection to fuse features.
+ Default: False.
+ loss_se_decode (dict): Config of decode loss.
+ Default: dict(type='CrossEntropyLoss', use_sigmoid=True).
+ """
+
+ def __init__(self,
+ num_codes=32,
+ use_se_loss=True,
+ add_lateral=False,
+ loss_se_decode=dict(
+ type='CrossEntropyLoss',
+ use_sigmoid=True,
+ loss_weight=0.2),
+ **kwargs):
+ super(EncHead, self).__init__(
+ input_transform='multiple_select', **kwargs)
+ self.use_se_loss = use_se_loss
+ self.add_lateral = add_lateral
+ self.num_codes = num_codes
+ self.bottleneck = ConvModule(
+ self.in_channels[-1],
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ if add_lateral:
+ self.lateral_convs = nn.ModuleList()
+ for in_channels in self.in_channels[:-1]: # skip the last one
+ self.lateral_convs.append(
+ ConvModule(
+ in_channels,
+ self.channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg))
+ self.fusion = ConvModule(
+ len(self.in_channels) * self.channels,
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ self.enc_module = EncModule(
+ self.channels,
+ num_codes=num_codes,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ if self.use_se_loss:
+ self.loss_se_decode = build_loss(loss_se_decode)
+ self.se_layer = nn.Linear(self.channels, self.num_classes)
+
+ def forward(self, inputs):
+ """Forward function."""
+ inputs = self._transform_inputs(inputs)
+ feat = self.bottleneck(inputs[-1])
+ if self.add_lateral:
+ laterals = [
+ resize(
+ lateral_conv(inputs[i]),
+ size=feat.shape[2:],
+ mode='bilinear',
+ align_corners=self.align_corners)
+ for i, lateral_conv in enumerate(self.lateral_convs)
+ ]
+ feat = self.fusion(torch.cat([feat, *laterals], 1))
+ encode_feat, output = self.enc_module(feat)
+ output = self.cls_seg(output)
+ if self.use_se_loss:
+ se_output = self.se_layer(encode_feat)
+ return output, se_output
+ else:
+ return output
+
+ def forward_test(self, inputs, img_metas, test_cfg):
+ """Forward function for testing, ignore se_loss."""
+ if self.use_se_loss:
+ return self.forward(inputs)[0]
+ else:
+ return self.forward(inputs)
+
+ @staticmethod
+ def _convert_to_onehot_labels(seg_label, num_classes):
+ """Convert segmentation label to onehot.
+
+ Args:
+ seg_label (Tensor): Segmentation label of shape (N, H, W).
+ num_classes (int): Number of classes.
+
+ Returns:
+ Tensor: Onehot labels of shape (N, num_classes).
+ """
+
+ batch_size = seg_label.size(0)
+ onehot_labels = seg_label.new_zeros((batch_size, num_classes))
+ for i in range(batch_size):
+ hist = seg_label[i].float().histc(
+ bins=num_classes, min=0, max=num_classes - 1)
+ onehot_labels[i] = hist > 0
+ return onehot_labels
+
+ def losses(self, seg_logit, seg_label):
+ """Compute segmentation and semantic encoding loss."""
+ seg_logit, se_seg_logit = seg_logit
+ loss = dict()
+ loss.update(super(EncHead, self).losses(seg_logit, seg_label))
+ se_loss = self.loss_se_decode(
+ se_seg_logit,
+ self._convert_to_onehot_labels(seg_label, self.num_classes))
+ loss['loss_se'] = se_loss
+ return loss
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/fcn_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/fcn_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..fb79a0d7c71d76e7ebb06d26d0f96f3e129a6adb
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/fcn_head.py
@@ -0,0 +1,96 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+from mmcv.cnn import ConvModule
+
+from ..builder import HEADS
+from .decode_head import BaseDecodeHead
+
+
+@HEADS.register_module()
+class FCNHead(BaseDecodeHead):
+ """Fully Convolution Networks for Semantic Segmentation.
+
+ This head is implemented of `FCNNet `_.
+
+ Args:
+ num_convs (int): Number of convs in the head. Default: 2.
+ kernel_size (int): The kernel size for convs in the head. Default: 3.
+ concat_input (bool): Whether concat the input and output of convs
+ before classification layer.
+ dilation (int): The dilation rate for convs in the head. Default: 1.
+ """
+
+ def __init__(self,
+ num_convs=2,
+ kernel_size=3,
+ concat_input=True,
+ dilation=1,
+ **kwargs):
+ assert num_convs >= 0 and dilation > 0 and isinstance(dilation, int)
+ self.num_convs = num_convs
+ self.concat_input = concat_input
+ self.kernel_size = kernel_size
+ super(FCNHead, self).__init__(**kwargs)
+ if num_convs == 0:
+ assert self.in_channels == self.channels
+
+ conv_padding = (kernel_size // 2) * dilation
+ convs = []
+ convs.append(
+ ConvModule(
+ self.in_channels,
+ self.channels,
+ kernel_size=kernel_size,
+ padding=conv_padding,
+ dilation=dilation,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg))
+ for i in range(num_convs - 1):
+ convs.append(
+ ConvModule(
+ self.channels,
+ self.channels,
+ kernel_size=kernel_size,
+ padding=conv_padding,
+ dilation=dilation,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg))
+ if num_convs == 0:
+ self.convs = nn.Identity()
+ else:
+ self.convs = nn.Sequential(*convs)
+ if self.concat_input:
+ self.conv_cat = ConvModule(
+ self.in_channels + self.channels,
+ self.channels,
+ kernel_size=kernel_size,
+ padding=kernel_size // 2,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ def _forward_feature(self, inputs):
+ """Forward function for feature maps before classifying each pixel with
+ ``self.cls_seg`` fc.
+
+ Args:
+ inputs (list[Tensor]): List of multi-level img features.
+
+ Returns:
+ feats (Tensor): A tensor of shape (batch_size, self.channels,
+ H, W) which is feature map for last layer of decoder head.
+ """
+ x = self._transform_inputs(inputs)
+ feats = self.convs(x)
+ if self.concat_input:
+ feats = self.conv_cat(torch.cat([x, feats], dim=1))
+ return feats
+
+ def forward(self, inputs):
+ """Forward function."""
+ output = self._forward_feature(inputs)
+ output = self.cls_seg(output)
+ return output
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/fpn_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/fpn_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..e41f324cca471fe1d8fe7d95c8f5a8514d18f255
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/fpn_head.py
@@ -0,0 +1,69 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import numpy as np
+import torch.nn as nn
+from mmcv.cnn import ConvModule
+
+from mmseg.ops import Upsample, resize
+from ..builder import HEADS
+from .decode_head import BaseDecodeHead
+
+
+@HEADS.register_module()
+class FPNHead(BaseDecodeHead):
+ """Panoptic Feature Pyramid Networks.
+
+ This head is the implementation of `Semantic FPN
+ `_.
+
+ Args:
+ feature_strides (tuple[int]): The strides for input feature maps.
+ stack_lateral. All strides suppose to be power of 2. The first
+ one is of largest resolution.
+ """
+
+ def __init__(self, feature_strides, **kwargs):
+ super(FPNHead, self).__init__(
+ input_transform='multiple_select', **kwargs)
+ assert len(feature_strides) == len(self.in_channels)
+ assert min(feature_strides) == feature_strides[0]
+ self.feature_strides = feature_strides
+
+ self.scale_heads = nn.ModuleList()
+ for i in range(len(feature_strides)):
+ head_length = max(
+ 1,
+ int(np.log2(feature_strides[i]) - np.log2(feature_strides[0])))
+ scale_head = []
+ for k in range(head_length):
+ scale_head.append(
+ ConvModule(
+ self.in_channels[i] if k == 0 else self.channels,
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg))
+ if feature_strides[i] != feature_strides[0]:
+ scale_head.append(
+ Upsample(
+ scale_factor=2,
+ mode='bilinear',
+ align_corners=self.align_corners))
+ self.scale_heads.append(nn.Sequential(*scale_head))
+
+ def forward(self, inputs):
+
+ x = self._transform_inputs(inputs)
+
+ output = self.scale_heads[0](x[0])
+ for i in range(1, len(self.feature_strides)):
+ # non inplace
+ output = output + resize(
+ self.scale_heads[i](x[i]),
+ size=output.shape[2:],
+ mode='bilinear',
+ align_corners=self.align_corners)
+
+ output = self.cls_seg(output)
+ return output
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/gc_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/gc_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..eed50742514d4d6cd3d861583f8ee85575e51373
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/gc_head.py
@@ -0,0 +1,48 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+from mmcv.cnn import ContextBlock
+
+from ..builder import HEADS
+from .fcn_head import FCNHead
+
+
+@HEADS.register_module()
+class GCHead(FCNHead):
+ """GCNet: Non-local Networks Meet Squeeze-Excitation Networks and Beyond.
+
+ This head is the implementation of `GCNet
+ `_.
+
+ Args:
+ ratio (float): Multiplier of channels ratio. Default: 1/4.
+ pooling_type (str): The pooling type of context aggregation.
+ Options are 'att', 'avg'. Default: 'avg'.
+ fusion_types (tuple[str]): The fusion type for feature fusion.
+ Options are 'channel_add', 'channel_mul'. Default: ('channel_add',)
+ """
+
+ def __init__(self,
+ ratio=1 / 4.,
+ pooling_type='att',
+ fusion_types=('channel_add', ),
+ **kwargs):
+ super(GCHead, self).__init__(num_convs=2, **kwargs)
+ self.ratio = ratio
+ self.pooling_type = pooling_type
+ self.fusion_types = fusion_types
+ self.gc_block = ContextBlock(
+ in_channels=self.channels,
+ ratio=self.ratio,
+ pooling_type=self.pooling_type,
+ fusion_types=self.fusion_types)
+
+ def forward(self, inputs):
+ """Forward function."""
+ x = self._transform_inputs(inputs)
+ output = self.convs[0](x)
+ output = self.gc_block(output)
+ output = self.convs[1](output)
+ if self.concat_input:
+ output = self.conv_cat(torch.cat([x, output], dim=1))
+ output = self.cls_seg(output)
+ return output
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/isa_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/isa_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..0bf3455571e315c9f50279e57b04549a6f1f3af8
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/isa_head.py
@@ -0,0 +1,143 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import math
+
+import torch
+import torch.nn.functional as F
+from mmcv.cnn import ConvModule
+
+from ..builder import HEADS
+from ..utils import SelfAttentionBlock as _SelfAttentionBlock
+from .decode_head import BaseDecodeHead
+
+
+class SelfAttentionBlock(_SelfAttentionBlock):
+ """Self-Attention Module.
+
+ Args:
+ in_channels (int): Input channels of key/query feature.
+ channels (int): Output channels of key/query transform.
+ conv_cfg (dict | None): Config of conv layers.
+ norm_cfg (dict | None): Config of norm layers.
+ act_cfg (dict | None): Config of activation layers.
+ """
+
+ def __init__(self, in_channels, channels, conv_cfg, norm_cfg, act_cfg):
+ super(SelfAttentionBlock, self).__init__(
+ key_in_channels=in_channels,
+ query_in_channels=in_channels,
+ channels=channels,
+ out_channels=in_channels,
+ share_key_query=False,
+ query_downsample=None,
+ key_downsample=None,
+ key_query_num_convs=2,
+ key_query_norm=True,
+ value_out_num_convs=1,
+ value_out_norm=False,
+ matmul_norm=True,
+ with_out=False,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+
+ self.output_project = self.build_project(
+ in_channels,
+ in_channels,
+ num_convs=1,
+ use_conv_module=True,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+
+ def forward(self, x):
+ """Forward function."""
+ context = super(SelfAttentionBlock, self).forward(x, x)
+ return self.output_project(context)
+
+
+@HEADS.register_module()
+class ISAHead(BaseDecodeHead):
+ """Interlaced Sparse Self-Attention for Semantic Segmentation.
+
+ This head is the implementation of `ISA
+ `_.
+
+ Args:
+ isa_channels (int): The channels of ISA Module.
+ down_factor (tuple[int]): The local group size of ISA.
+ """
+
+ def __init__(self, isa_channels, down_factor=(8, 8), **kwargs):
+ super(ISAHead, self).__init__(**kwargs)
+ self.down_factor = down_factor
+
+ self.in_conv = ConvModule(
+ self.in_channels,
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ self.global_relation = SelfAttentionBlock(
+ self.channels,
+ isa_channels,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ self.local_relation = SelfAttentionBlock(
+ self.channels,
+ isa_channels,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ self.out_conv = ConvModule(
+ self.channels * 2,
+ self.channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ def forward(self, inputs):
+ """Forward function."""
+ x_ = self._transform_inputs(inputs)
+ x = self.in_conv(x_)
+ residual = x
+
+ n, c, h, w = x.size()
+ loc_h, loc_w = self.down_factor # size of local group in H- and W-axes
+ glb_h, glb_w = math.ceil(h / loc_h), math.ceil(w / loc_w)
+ pad_h, pad_w = glb_h * loc_h - h, glb_w * loc_w - w
+ if pad_h > 0 or pad_w > 0: # pad if the size is not divisible
+ padding = (pad_w // 2, pad_w - pad_w // 2, pad_h // 2,
+ pad_h - pad_h // 2)
+ x = F.pad(x, padding)
+
+ # global relation
+ x = x.view(n, c, glb_h, loc_h, glb_w, loc_w)
+ # do permutation to gather global group
+ x = x.permute(0, 3, 5, 1, 2, 4) # (n, loc_h, loc_w, c, glb_h, glb_w)
+ x = x.reshape(-1, c, glb_h, glb_w)
+ # apply attention within each global group
+ x = self.global_relation(x) # (n * loc_h * loc_w, c, glb_h, glb_w)
+
+ # local relation
+ x = x.view(n, loc_h, loc_w, c, glb_h, glb_w)
+ # do permutation to gather local group
+ x = x.permute(0, 4, 5, 3, 1, 2) # (n, glb_h, glb_w, c, loc_h, loc_w)
+ x = x.reshape(-1, c, loc_h, loc_w)
+ # apply attention within each local group
+ x = self.local_relation(x) # (n * glb_h * glb_w, c, loc_h, loc_w)
+
+ # permute each pixel back to its original position
+ x = x.view(n, glb_h, glb_w, c, loc_h, loc_w)
+ x = x.permute(0, 3, 1, 4, 2, 5) # (n, c, glb_h, loc_h, glb_w, loc_w)
+ x = x.reshape(n, c, glb_h * loc_h, glb_w * loc_w)
+ if pad_h > 0 or pad_w > 0: # remove padding
+ x = x[:, :, pad_h // 2:pad_h // 2 + h, pad_w // 2:pad_w // 2 + w]
+
+ x = self.out_conv(torch.cat([x, residual], dim=1))
+ out = self.cls_seg(x)
+
+ return out
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/knet_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/knet_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..f73daccb645210cdbd0b3f1890cb813ecec2676b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/knet_head.py
@@ -0,0 +1,453 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+from mmcv.cnn import ConvModule, build_activation_layer, build_norm_layer
+from mmcv.cnn.bricks.transformer import (FFN, TRANSFORMER_LAYER,
+ MultiheadAttention,
+ build_transformer_layer)
+
+from mmseg.models.builder import HEADS, build_head
+from mmseg.models.decode_heads.decode_head import BaseDecodeHead
+from mmseg.utils import get_root_logger
+
+
+@TRANSFORMER_LAYER.register_module()
+class KernelUpdator(nn.Module):
+ """Dynamic Kernel Updator in Kernel Update Head.
+
+ Args:
+ in_channels (int): The number of channels of input feature map.
+ Default: 256.
+ feat_channels (int): The number of middle-stage channels in
+ the kernel updator. Default: 64.
+ out_channels (int): The number of output channels.
+ gate_sigmoid (bool): Whether use sigmoid function in gate
+ mechanism. Default: True.
+ gate_norm_act (bool): Whether add normalization and activation
+ layer in gate mechanism. Default: False.
+ activate_out: Whether add activation after gate mechanism.
+ Default: False.
+ norm_cfg (dict | None): Config of norm layers.
+ Default: dict(type='LN').
+ act_cfg (dict): Config of activation layers.
+ Default: dict(type='ReLU').
+ """
+
+ def __init__(
+ self,
+ in_channels=256,
+ feat_channels=64,
+ out_channels=None,
+ gate_sigmoid=True,
+ gate_norm_act=False,
+ activate_out=False,
+ norm_cfg=dict(type='LN'),
+ act_cfg=dict(type='ReLU', inplace=True),
+ ):
+ super(KernelUpdator, self).__init__()
+ self.in_channels = in_channels
+ self.feat_channels = feat_channels
+ self.out_channels_raw = out_channels
+ self.gate_sigmoid = gate_sigmoid
+ self.gate_norm_act = gate_norm_act
+ self.activate_out = activate_out
+ self.act_cfg = act_cfg
+ self.norm_cfg = norm_cfg
+ self.out_channels = out_channels if out_channels else in_channels
+
+ self.num_params_in = self.feat_channels
+ self.num_params_out = self.feat_channels
+ self.dynamic_layer = nn.Linear(
+ self.in_channels, self.num_params_in + self.num_params_out)
+ self.input_layer = nn.Linear(self.in_channels,
+ self.num_params_in + self.num_params_out,
+ 1)
+ self.input_gate = nn.Linear(self.in_channels, self.feat_channels, 1)
+ self.update_gate = nn.Linear(self.in_channels, self.feat_channels, 1)
+ if self.gate_norm_act:
+ self.gate_norm = build_norm_layer(norm_cfg, self.feat_channels)[1]
+
+ self.norm_in = build_norm_layer(norm_cfg, self.feat_channels)[1]
+ self.norm_out = build_norm_layer(norm_cfg, self.feat_channels)[1]
+ self.input_norm_in = build_norm_layer(norm_cfg, self.feat_channels)[1]
+ self.input_norm_out = build_norm_layer(norm_cfg, self.feat_channels)[1]
+
+ self.activation = build_activation_layer(act_cfg)
+
+ self.fc_layer = nn.Linear(self.feat_channels, self.out_channels, 1)
+ self.fc_norm = build_norm_layer(norm_cfg, self.out_channels)[1]
+
+ def forward(self, update_feature, input_feature):
+ """Forward function of KernelUpdator.
+
+ Args:
+ update_feature (torch.Tensor): Feature map assembled from
+ each group. It would be reshaped with last dimension
+ shape: `self.in_channels`.
+ input_feature (torch.Tensor): Intermediate feature
+ with shape: (N, num_classes, conv_kernel_size**2, channels).
+ Returns:
+ Tensor: The output tensor of shape (N*C1/C2, K*K, C2), where N is
+ the number of classes, C1 and C2 are the feature map channels of
+ KernelUpdateHead and KernelUpdator, respectively.
+ """
+
+ update_feature = update_feature.reshape(-1, self.in_channels)
+ num_proposals = update_feature.size(0)
+ # dynamic_layer works for
+ # phi_1 and psi_3 in Eq.(4) and (5) of K-Net paper
+ parameters = self.dynamic_layer(update_feature)
+ param_in = parameters[:, :self.num_params_in].view(
+ -1, self.feat_channels)
+ param_out = parameters[:, -self.num_params_out:].view(
+ -1, self.feat_channels)
+
+ # input_layer works for
+ # phi_2 and psi_4 in Eq.(4) and (5) of K-Net paper
+ input_feats = self.input_layer(
+ input_feature.reshape(num_proposals, -1, self.feat_channels))
+ input_in = input_feats[..., :self.num_params_in]
+ input_out = input_feats[..., -self.num_params_out:]
+
+ # `gate_feats` is F^G in K-Net paper
+ gate_feats = input_in * param_in.unsqueeze(-2)
+ if self.gate_norm_act:
+ gate_feats = self.activation(self.gate_norm(gate_feats))
+
+ input_gate = self.input_norm_in(self.input_gate(gate_feats))
+ update_gate = self.norm_in(self.update_gate(gate_feats))
+ if self.gate_sigmoid:
+ input_gate = input_gate.sigmoid()
+ update_gate = update_gate.sigmoid()
+ param_out = self.norm_out(param_out)
+ input_out = self.input_norm_out(input_out)
+
+ if self.activate_out:
+ param_out = self.activation(param_out)
+ input_out = self.activation(input_out)
+
+ # Gate mechanism. Eq.(5) in original paper.
+ # param_out has shape (batch_size, feat_channels, out_channels)
+ features = update_gate * param_out.unsqueeze(
+ -2) + input_gate * input_out
+
+ features = self.fc_layer(features)
+ features = self.fc_norm(features)
+ features = self.activation(features)
+
+ return features
+
+
+@HEADS.register_module()
+class KernelUpdateHead(nn.Module):
+ """Kernel Update Head in K-Net.
+
+ Args:
+ num_classes (int): Number of classes. Default: 150.
+ num_ffn_fcs (int): The number of fully-connected layers in
+ FFNs. Default: 2.
+ num_heads (int): The number of parallel attention heads.
+ Default: 8.
+ num_mask_fcs (int): The number of fully connected layers for
+ mask prediction. Default: 3.
+ feedforward_channels (int): The hidden dimension of FFNs.
+ Defaults: 2048.
+ in_channels (int): The number of channels of input feature map.
+ Default: 256.
+ out_channels (int): The number of output channels.
+ Default: 256.
+ dropout (float): The Probability of an element to be
+ zeroed in MultiheadAttention and FFN. Default 0.0.
+ act_cfg (dict): Config of activation layers.
+ Default: dict(type='ReLU').
+ ffn_act_cfg (dict): Config of activation layers in FFN.
+ Default: dict(type='ReLU').
+ conv_kernel_size (int): The kernel size of convolution in
+ Kernel Update Head for dynamic kernel updation.
+ Default: 1.
+ feat_transform_cfg (dict | None): Config of feature transform.
+ Default: None.
+ kernel_init (bool): Whether initiate mask kernel in mask head.
+ Default: False.
+ with_ffn (bool): Whether add FFN in kernel update head.
+ Default: True.
+ feat_gather_stride (int): Stride of convolution in feature transform.
+ Default: 1.
+ mask_transform_stride (int): Stride of mask transform.
+ Default: 1.
+ kernel_updator_cfg (dict): Config of kernel updator.
+ Default: dict(
+ type='DynamicConv',
+ in_channels=256,
+ feat_channels=64,
+ out_channels=256,
+ act_cfg=dict(type='ReLU', inplace=True),
+ norm_cfg=dict(type='LN')).
+ """
+
+ def __init__(self,
+ num_classes=150,
+ num_ffn_fcs=2,
+ num_heads=8,
+ num_mask_fcs=3,
+ feedforward_channels=2048,
+ in_channels=256,
+ out_channels=256,
+ dropout=0.0,
+ act_cfg=dict(type='ReLU', inplace=True),
+ ffn_act_cfg=dict(type='ReLU', inplace=True),
+ conv_kernel_size=1,
+ feat_transform_cfg=None,
+ kernel_init=False,
+ with_ffn=True,
+ feat_gather_stride=1,
+ mask_transform_stride=1,
+ kernel_updator_cfg=dict(
+ type='DynamicConv',
+ in_channels=256,
+ feat_channels=64,
+ out_channels=256,
+ act_cfg=dict(type='ReLU', inplace=True),
+ norm_cfg=dict(type='LN'))):
+ super(KernelUpdateHead, self).__init__()
+ self.num_classes = num_classes
+ self.in_channels = in_channels
+ self.out_channels = out_channels
+ self.fp16_enabled = False
+ self.dropout = dropout
+ self.num_heads = num_heads
+ self.kernel_init = kernel_init
+ self.with_ffn = with_ffn
+ self.conv_kernel_size = conv_kernel_size
+ self.feat_gather_stride = feat_gather_stride
+ self.mask_transform_stride = mask_transform_stride
+
+ self.attention = MultiheadAttention(in_channels * conv_kernel_size**2,
+ num_heads, dropout)
+ self.attention_norm = build_norm_layer(
+ dict(type='LN'), in_channels * conv_kernel_size**2)[1]
+ self.kernel_update_conv = build_transformer_layer(kernel_updator_cfg)
+
+ if feat_transform_cfg is not None:
+ kernel_size = feat_transform_cfg.pop('kernel_size', 1)
+ transform_channels = in_channels
+ self.feat_transform = ConvModule(
+ transform_channels,
+ in_channels,
+ kernel_size,
+ stride=feat_gather_stride,
+ padding=int(feat_gather_stride // 2),
+ **feat_transform_cfg)
+ else:
+ self.feat_transform = None
+
+ if self.with_ffn:
+ self.ffn = FFN(
+ in_channels,
+ feedforward_channels,
+ num_ffn_fcs,
+ act_cfg=ffn_act_cfg,
+ dropout=dropout)
+ self.ffn_norm = build_norm_layer(dict(type='LN'), in_channels)[1]
+
+ self.mask_fcs = nn.ModuleList()
+ for _ in range(num_mask_fcs):
+ self.mask_fcs.append(
+ nn.Linear(in_channels, in_channels, bias=False))
+ self.mask_fcs.append(
+ build_norm_layer(dict(type='LN'), in_channels)[1])
+ self.mask_fcs.append(build_activation_layer(act_cfg))
+
+ self.fc_mask = nn.Linear(in_channels, out_channels)
+
+ def init_weights(self):
+ """Use xavier initialization for all weight parameter and set
+ classification head bias as a specific value when use focal loss."""
+ for p in self.parameters():
+ if p.dim() > 1:
+ nn.init.xavier_uniform_(p)
+ else:
+ # adopt the default initialization for
+ # the weight and bias of the layer norm
+ pass
+ if self.kernel_init:
+ logger = get_root_logger()
+ logger.info(
+ 'mask kernel in mask head is normal initialized by std 0.01')
+ nn.init.normal_(self.fc_mask.weight, mean=0, std=0.01)
+
+ def forward(self, x, proposal_feat, mask_preds, mask_shape=None):
+ """Forward function of Dynamic Instance Interactive Head.
+
+ Args:
+ x (Tensor): Feature map from FPN with shape
+ (batch_size, feature_dimensions, H , W).
+ proposal_feat (Tensor): Intermediate feature get from
+ diihead in last stage, has shape
+ (batch_size, num_proposals, feature_dimensions)
+ mask_preds (Tensor): mask prediction from the former stage in shape
+ (batch_size, num_proposals, H, W).
+
+ Returns:
+ Tuple: The first tensor is predicted mask with shape
+ (N, num_classes, H, W), the second tensor is dynamic kernel
+ with shape (N, num_classes, channels, K, K).
+ """
+ N, num_proposals = proposal_feat.shape[:2]
+ if self.feat_transform is not None:
+ x = self.feat_transform(x)
+
+ C, H, W = x.shape[-3:]
+
+ mask_h, mask_w = mask_preds.shape[-2:]
+ if mask_h != H or mask_w != W:
+ gather_mask = F.interpolate(
+ mask_preds, (H, W), align_corners=False, mode='bilinear')
+ else:
+ gather_mask = mask_preds
+
+ sigmoid_masks = gather_mask.softmax(dim=1)
+
+ # Group Feature Assembling. Eq.(3) in original paper.
+ # einsum is faster than bmm by 30%
+ x_feat = torch.einsum('bnhw,bchw->bnc', sigmoid_masks, x)
+
+ # obj_feat in shape [B, N, C, K, K] -> [B, N, C, K*K] -> [B, N, K*K, C]
+ proposal_feat = proposal_feat.reshape(N, num_proposals,
+ self.in_channels,
+ -1).permute(0, 1, 3, 2)
+ obj_feat = self.kernel_update_conv(x_feat, proposal_feat)
+
+ # [B, N, K*K, C] -> [B, N, K*K*C] -> [N, B, K*K*C]
+ obj_feat = obj_feat.reshape(N, num_proposals, -1).permute(1, 0, 2)
+ obj_feat = self.attention_norm(self.attention(obj_feat))
+ # [N, B, K*K*C] -> [B, N, K*K*C]
+ obj_feat = obj_feat.permute(1, 0, 2)
+
+ # obj_feat in shape [B, N, K*K*C] -> [B, N, K*K, C]
+ obj_feat = obj_feat.reshape(N, num_proposals, -1, self.in_channels)
+
+ # FFN
+ if self.with_ffn:
+ obj_feat = self.ffn_norm(self.ffn(obj_feat))
+
+ mask_feat = obj_feat
+
+ for reg_layer in self.mask_fcs:
+ mask_feat = reg_layer(mask_feat)
+
+ # [B, N, K*K, C] -> [B, N, C, K*K]
+ mask_feat = self.fc_mask(mask_feat).permute(0, 1, 3, 2)
+
+ if (self.mask_transform_stride == 2 and self.feat_gather_stride == 1):
+ mask_x = F.interpolate(
+ x, scale_factor=0.5, mode='bilinear', align_corners=False)
+ H, W = mask_x.shape[-2:]
+ else:
+ mask_x = x
+ # group conv is 5x faster than unfold and uses about 1/5 memory
+ # Group conv vs. unfold vs. concat batch, 2.9ms :13.5ms :3.8ms
+ # Group conv vs. unfold vs. concat batch, 278 : 1420 : 369
+ # but in real training group conv is slower than concat batch
+ # so we keep using concat batch.
+ # fold_x = F.unfold(
+ # mask_x,
+ # self.conv_kernel_size,
+ # padding=int(self.conv_kernel_size // 2))
+ # mask_feat = mask_feat.reshape(N, num_proposals, -1)
+ # new_mask_preds = torch.einsum('bnc,bcl->bnl', mask_feat, fold_x)
+ # [B, N, C, K*K] -> [B*N, C, K, K]
+ mask_feat = mask_feat.reshape(N, num_proposals, C,
+ self.conv_kernel_size,
+ self.conv_kernel_size)
+ # [B, C, H, W] -> [1, B*C, H, W]
+ new_mask_preds = []
+ for i in range(N):
+ new_mask_preds.append(
+ F.conv2d(
+ mask_x[i:i + 1],
+ mask_feat[i],
+ padding=int(self.conv_kernel_size // 2)))
+
+ new_mask_preds = torch.cat(new_mask_preds, dim=0)
+ new_mask_preds = new_mask_preds.reshape(N, num_proposals, H, W)
+ if self.mask_transform_stride == 2:
+ new_mask_preds = F.interpolate(
+ new_mask_preds,
+ scale_factor=2,
+ mode='bilinear',
+ align_corners=False)
+
+ if mask_shape is not None and mask_shape[0] != H:
+ new_mask_preds = F.interpolate(
+ new_mask_preds,
+ mask_shape,
+ align_corners=False,
+ mode='bilinear')
+
+ return new_mask_preds, obj_feat.permute(0, 1, 3, 2).reshape(
+ N, num_proposals, self.in_channels, self.conv_kernel_size,
+ self.conv_kernel_size)
+
+
+@HEADS.register_module()
+class IterativeDecodeHead(BaseDecodeHead):
+ """K-Net: Towards Unified Image Segmentation.
+
+ This head is the implementation of
+ `K-Net: `_.
+
+ Args:
+ num_stages (int): The number of stages (kernel update heads)
+ in IterativeDecodeHead. Default: 3.
+ kernel_generate_head:(dict): Config of kernel generate head which
+ generate mask predictions, dynamic kernels and class predictions
+ for next kernel update heads.
+ kernel_update_head (dict): Config of kernel update head which refine
+ dynamic kernels and class predictions iteratively.
+
+ """
+
+ def __init__(self, num_stages, kernel_generate_head, kernel_update_head,
+ **kwargs):
+ super(BaseDecodeHead, self).__init__(**kwargs)
+ assert num_stages == len(kernel_update_head)
+ self.num_stages = num_stages
+ self.kernel_generate_head = build_head(kernel_generate_head)
+ self.kernel_update_head = nn.ModuleList()
+ self.align_corners = self.kernel_generate_head.align_corners
+ self.num_classes = self.kernel_generate_head.num_classes
+ self.input_transform = self.kernel_generate_head.input_transform
+ self.ignore_index = self.kernel_generate_head.ignore_index
+
+ for head_cfg in kernel_update_head:
+ self.kernel_update_head.append(build_head(head_cfg))
+
+ def forward(self, inputs):
+ """Forward function."""
+ feats = self.kernel_generate_head._forward_feature(inputs)
+ sem_seg = self.kernel_generate_head.cls_seg(feats)
+ seg_kernels = self.kernel_generate_head.conv_seg.weight.clone()
+ seg_kernels = seg_kernels[None].expand(
+ feats.size(0), *seg_kernels.size())
+
+ stage_segs = [sem_seg]
+ for i in range(self.num_stages):
+ sem_seg, seg_kernels = self.kernel_update_head[i](feats,
+ seg_kernels,
+ sem_seg)
+ stage_segs.append(sem_seg)
+ if self.training:
+ return stage_segs
+ # only return the prediction of the last stage during testing
+ return stage_segs[-1]
+
+ def losses(self, seg_logit, seg_label):
+ losses = dict()
+ for i, logit in enumerate(seg_logit):
+ loss = self.kernel_generate_head.losses(logit, seg_label)
+ for k, v in loss.items():
+ losses[f'{k}.s{i}'] = v
+
+ return losses
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/lraspp_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/lraspp_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..c10ff0d822fa29d4dfa1c8a1e047e4540b1d5064
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/lraspp_head.py
@@ -0,0 +1,91 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+from mmcv import is_tuple_of
+from mmcv.cnn import ConvModule
+
+from mmseg.ops import resize
+from ..builder import HEADS
+from .decode_head import BaseDecodeHead
+
+
+@HEADS.register_module()
+class LRASPPHead(BaseDecodeHead):
+ """Lite R-ASPP (LRASPP) head is proposed in Searching for MobileNetV3.
+
+ This head is the improved implementation of `Searching for MobileNetV3
+ `_.
+
+ Args:
+ branch_channels (tuple[int]): The number of output channels in every
+ each branch. Default: (32, 64).
+ """
+
+ def __init__(self, branch_channels=(32, 64), **kwargs):
+ super(LRASPPHead, self).__init__(**kwargs)
+ if self.input_transform != 'multiple_select':
+ raise ValueError('in Lite R-ASPP (LRASPP) head, input_transform '
+ f'must be \'multiple_select\'. But received '
+ f'\'{self.input_transform}\'')
+ assert is_tuple_of(branch_channels, int)
+ assert len(branch_channels) == len(self.in_channels) - 1
+ self.branch_channels = branch_channels
+
+ self.convs = nn.Sequential()
+ self.conv_ups = nn.Sequential()
+ for i in range(len(branch_channels)):
+ self.convs.add_module(
+ f'conv{i}',
+ nn.Conv2d(
+ self.in_channels[i], branch_channels[i], 1, bias=False))
+ self.conv_ups.add_module(
+ f'conv_up{i}',
+ ConvModule(
+ self.channels + branch_channels[i],
+ self.channels,
+ 1,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg,
+ bias=False))
+
+ self.conv_up_input = nn.Conv2d(self.channels, self.channels, 1)
+
+ self.aspp_conv = ConvModule(
+ self.in_channels[-1],
+ self.channels,
+ 1,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg,
+ bias=False)
+ self.image_pool = nn.Sequential(
+ nn.AvgPool2d(kernel_size=49, stride=(16, 20)),
+ ConvModule(
+ self.in_channels[2],
+ self.channels,
+ 1,
+ act_cfg=dict(type='Sigmoid'),
+ bias=False))
+
+ def forward(self, inputs):
+ """Forward function."""
+ inputs = self._transform_inputs(inputs)
+
+ x = inputs[-1]
+
+ x = self.aspp_conv(x) * resize(
+ self.image_pool(x),
+ size=x.size()[2:],
+ mode='bilinear',
+ align_corners=self.align_corners)
+ x = self.conv_up_input(x)
+
+ for i in range(len(self.branch_channels) - 1, -1, -1):
+ x = resize(
+ x,
+ size=inputs[i].size()[2:],
+ mode='bilinear',
+ align_corners=self.align_corners)
+ x = torch.cat([x, self.convs[i](inputs[i])], 1)
+ x = self.conv_ups[i](x)
+
+ return self.cls_seg(x)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/nl_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/nl_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..637517e7a0e634f733049c6c4c2001cd844b22c1
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/nl_head.py
@@ -0,0 +1,50 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+from mmcv.cnn import NonLocal2d
+
+from ..builder import HEADS
+from .fcn_head import FCNHead
+
+
+@HEADS.register_module()
+class NLHead(FCNHead):
+ """Non-local Neural Networks.
+
+ This head is the implementation of `NLNet
+ `_.
+
+ Args:
+ reduction (int): Reduction factor of projection transform. Default: 2.
+ use_scale (bool): Whether to scale pairwise_weight by
+ sqrt(1/inter_channels). Default: True.
+ mode (str): The nonlocal mode. Options are 'embedded_gaussian',
+ 'dot_product'. Default: 'embedded_gaussian.'.
+ """
+
+ def __init__(self,
+ reduction=2,
+ use_scale=True,
+ mode='embedded_gaussian',
+ **kwargs):
+ super(NLHead, self).__init__(num_convs=2, **kwargs)
+ self.reduction = reduction
+ self.use_scale = use_scale
+ self.mode = mode
+ self.nl_block = NonLocal2d(
+ in_channels=self.channels,
+ reduction=self.reduction,
+ use_scale=self.use_scale,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ mode=self.mode)
+
+ def forward(self, inputs):
+ """Forward function."""
+ x = self._transform_inputs(inputs)
+ output = self.convs[0](x)
+ output = self.nl_block(output)
+ output = self.convs[1](output)
+ if self.concat_input:
+ output = self.conv_cat(torch.cat([x, output], dim=1))
+ output = self.cls_seg(output)
+ return output
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/ocr_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/ocr_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..09eadfb1a6a61b752ab1ece5233617a0cb3a3a2b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/ocr_head.py
@@ -0,0 +1,128 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+from mmcv.cnn import ConvModule
+
+from mmseg.ops import resize
+from ..builder import HEADS
+from ..utils import SelfAttentionBlock as _SelfAttentionBlock
+from .cascade_decode_head import BaseCascadeDecodeHead
+
+
+class SpatialGatherModule(nn.Module):
+ """Aggregate the context features according to the initial predicted
+ probability distribution.
+
+ Employ the soft-weighted method to aggregate the context.
+ """
+
+ def __init__(self, scale):
+ super(SpatialGatherModule, self).__init__()
+ self.scale = scale
+
+ def forward(self, feats, probs):
+ """Forward function."""
+ batch_size, num_classes, height, width = probs.size()
+ channels = feats.size(1)
+ probs = probs.view(batch_size, num_classes, -1)
+ feats = feats.view(batch_size, channels, -1)
+ # [batch_size, height*width, num_classes]
+ feats = feats.permute(0, 2, 1)
+ # [batch_size, channels, height*width]
+ probs = F.softmax(self.scale * probs, dim=2)
+ # [batch_size, channels, num_classes]
+ ocr_context = torch.matmul(probs, feats)
+ ocr_context = ocr_context.permute(0, 2, 1).contiguous().unsqueeze(3)
+ return ocr_context
+
+
+class ObjectAttentionBlock(_SelfAttentionBlock):
+ """Make a OCR used SelfAttentionBlock."""
+
+ def __init__(self, in_channels, channels, scale, conv_cfg, norm_cfg,
+ act_cfg):
+ if scale > 1:
+ query_downsample = nn.MaxPool2d(kernel_size=scale)
+ else:
+ query_downsample = None
+ super(ObjectAttentionBlock, self).__init__(
+ key_in_channels=in_channels,
+ query_in_channels=in_channels,
+ channels=channels,
+ out_channels=in_channels,
+ share_key_query=False,
+ query_downsample=query_downsample,
+ key_downsample=None,
+ key_query_num_convs=2,
+ key_query_norm=True,
+ value_out_num_convs=1,
+ value_out_norm=True,
+ matmul_norm=True,
+ with_out=True,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ self.bottleneck = ConvModule(
+ in_channels * 2,
+ in_channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ def forward(self, query_feats, key_feats):
+ """Forward function."""
+ context = super(ObjectAttentionBlock,
+ self).forward(query_feats, key_feats)
+ output = self.bottleneck(torch.cat([context, query_feats], dim=1))
+ if self.query_downsample is not None:
+ output = resize(query_feats)
+
+ return output
+
+
+@HEADS.register_module()
+class OCRHead(BaseCascadeDecodeHead):
+ """Object-Contextual Representations for Semantic Segmentation.
+
+ This head is the implementation of `OCRNet
+ `_.
+
+ Args:
+ ocr_channels (int): The intermediate channels of OCR block.
+ scale (int): The scale of probability map in SpatialGatherModule in
+ Default: 1.
+ """
+
+ def __init__(self, ocr_channels, scale=1, **kwargs):
+ super(OCRHead, self).__init__(**kwargs)
+ self.ocr_channels = ocr_channels
+ self.scale = scale
+ self.object_context_block = ObjectAttentionBlock(
+ self.channels,
+ self.ocr_channels,
+ self.scale,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ self.spatial_gather_module = SpatialGatherModule(self.scale)
+
+ self.bottleneck = ConvModule(
+ self.in_channels,
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ def forward(self, inputs, prev_output):
+ """Forward function."""
+ x = self._transform_inputs(inputs)
+ feats = self.bottleneck(x)
+ context = self.spatial_gather_module(feats, prev_output)
+ object_context = self.object_context_block(feats, context)
+ output = self.cls_seg(object_context)
+
+ return output
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/point_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/point_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..5e605271c79f402f12093eae66d90425a9406825
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/point_head.py
@@ -0,0 +1,364 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+# Modified from https://github.com/facebookresearch/detectron2/tree/master/projects/PointRend/point_head/point_head.py # noqa
+
+import torch
+import torch.nn as nn
+from mmcv.cnn import ConvModule
+
+try:
+ from mmcv.ops import point_sample
+except ModuleNotFoundError:
+ point_sample = None
+
+from mmseg.models.builder import HEADS
+from mmseg.ops import resize
+from ..losses import accuracy
+from .cascade_decode_head import BaseCascadeDecodeHead
+
+
+def calculate_uncertainty(seg_logits):
+ """Estimate uncertainty based on seg logits.
+
+ For each location of the prediction ``seg_logits`` we estimate
+ uncertainty as the difference between top first and top second
+ predicted logits.
+
+ Args:
+ seg_logits (Tensor): Semantic segmentation logits,
+ shape (batch_size, num_classes, height, width).
+
+ Returns:
+ scores (Tensor): T uncertainty scores with the most uncertain
+ locations having the highest uncertainty score, shape (
+ batch_size, 1, height, width)
+ """
+ top2_scores = torch.topk(seg_logits, k=2, dim=1)[0]
+ return (top2_scores[:, 1] - top2_scores[:, 0]).unsqueeze(1)
+
+
+@HEADS.register_module()
+class PointHead(BaseCascadeDecodeHead):
+ """A mask point head use in PointRend.
+
+ This head is implemented of `PointRend: Image Segmentation as
+ Rendering `_.
+ ``PointHead`` use shared multi-layer perceptron (equivalent to
+ nn.Conv1d) to predict the logit of input points. The fine-grained feature
+ and coarse feature will be concatenate together for predication.
+
+ Args:
+ num_fcs (int): Number of fc layers in the head. Default: 3.
+ in_channels (int): Number of input channels. Default: 256.
+ fc_channels (int): Number of fc channels. Default: 256.
+ num_classes (int): Number of classes for logits. Default: 80.
+ class_agnostic (bool): Whether use class agnostic classification.
+ If so, the output channels of logits will be 1. Default: False.
+ coarse_pred_each_layer (bool): Whether concatenate coarse feature with
+ the output of each fc layer. Default: True.
+ conv_cfg (dict|None): Dictionary to construct and config conv layer.
+ Default: dict(type='Conv1d'))
+ norm_cfg (dict|None): Dictionary to construct and config norm layer.
+ Default: None.
+ loss_point (dict): Dictionary to construct and config loss layer of
+ point head. Default: dict(type='CrossEntropyLoss', use_mask=True,
+ loss_weight=1.0).
+ """
+
+ def __init__(self,
+ num_fcs=3,
+ coarse_pred_each_layer=True,
+ conv_cfg=dict(type='Conv1d'),
+ norm_cfg=None,
+ act_cfg=dict(type='ReLU', inplace=False),
+ **kwargs):
+ super(PointHead, self).__init__(
+ input_transform='multiple_select',
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg,
+ init_cfg=dict(
+ type='Normal', std=0.01, override=dict(name='fc_seg')),
+ **kwargs)
+ if point_sample is None:
+ raise RuntimeError('Please install mmcv-full for '
+ 'point_sample ops')
+
+ self.num_fcs = num_fcs
+ self.coarse_pred_each_layer = coarse_pred_each_layer
+
+ fc_in_channels = sum(self.in_channels) + self.num_classes
+ fc_channels = self.channels
+ self.fcs = nn.ModuleList()
+ for k in range(num_fcs):
+ fc = ConvModule(
+ fc_in_channels,
+ fc_channels,
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ self.fcs.append(fc)
+ fc_in_channels = fc_channels
+ fc_in_channels += self.num_classes if self.coarse_pred_each_layer \
+ else 0
+ self.fc_seg = nn.Conv1d(
+ fc_in_channels,
+ self.num_classes,
+ kernel_size=1,
+ stride=1,
+ padding=0)
+ if self.dropout_ratio > 0:
+ self.dropout = nn.Dropout(self.dropout_ratio)
+ delattr(self, 'conv_seg')
+
+ def cls_seg(self, feat):
+ """Classify each pixel with fc."""
+ if self.dropout is not None:
+ feat = self.dropout(feat)
+ output = self.fc_seg(feat)
+ return output
+
+ def forward(self, fine_grained_point_feats, coarse_point_feats):
+ x = torch.cat([fine_grained_point_feats, coarse_point_feats], dim=1)
+ for fc in self.fcs:
+ x = fc(x)
+ if self.coarse_pred_each_layer:
+ x = torch.cat((x, coarse_point_feats), dim=1)
+ return self.cls_seg(x)
+
+ def _get_fine_grained_point_feats(self, x, points):
+ """Sample from fine grained features.
+
+ Args:
+ x (list[Tensor]): Feature pyramid from by neck or backbone.
+ points (Tensor): Point coordinates, shape (batch_size,
+ num_points, 2).
+
+ Returns:
+ fine_grained_feats (Tensor): Sampled fine grained feature,
+ shape (batch_size, sum(channels of x), num_points).
+ """
+
+ fine_grained_feats_list = [
+ point_sample(_, points, align_corners=self.align_corners)
+ for _ in x
+ ]
+ if len(fine_grained_feats_list) > 1:
+ fine_grained_feats = torch.cat(fine_grained_feats_list, dim=1)
+ else:
+ fine_grained_feats = fine_grained_feats_list[0]
+
+ return fine_grained_feats
+
+ def _get_coarse_point_feats(self, prev_output, points):
+ """Sample from fine grained features.
+
+ Args:
+ prev_output (list[Tensor]): Prediction of previous decode head.
+ points (Tensor): Point coordinates, shape (batch_size,
+ num_points, 2).
+
+ Returns:
+ coarse_feats (Tensor): Sampled coarse feature, shape (batch_size,
+ num_classes, num_points).
+ """
+
+ coarse_feats = point_sample(
+ prev_output, points, align_corners=self.align_corners)
+
+ return coarse_feats
+
+ def forward_train(self, inputs, prev_output, img_metas, gt_semantic_seg,
+ train_cfg):
+ """Forward function for training.
+ Args:
+ inputs (list[Tensor]): List of multi-level img features.
+ prev_output (Tensor): The output of previous decode head.
+ img_metas (list[dict]): List of image info dict where each dict
+ has: 'img_shape', 'scale_factor', 'flip', and may also contain
+ 'filename', 'ori_shape', 'pad_shape', and 'img_norm_cfg'.
+ For details on the values of these keys see
+ `mmseg/datasets/pipelines/formatting.py:Collect`.
+ gt_semantic_seg (Tensor): Semantic segmentation masks
+ used if the architecture supports semantic segmentation task.
+ train_cfg (dict): The training config.
+
+ Returns:
+ dict[str, Tensor]: a dictionary of loss components
+ """
+ x = self._transform_inputs(inputs)
+ with torch.no_grad():
+ points = self.get_points_train(
+ prev_output, calculate_uncertainty, cfg=train_cfg)
+ fine_grained_point_feats = self._get_fine_grained_point_feats(
+ x, points)
+ coarse_point_feats = self._get_coarse_point_feats(prev_output, points)
+ point_logits = self.forward(fine_grained_point_feats,
+ coarse_point_feats)
+ point_label = point_sample(
+ gt_semantic_seg.float(),
+ points,
+ mode='nearest',
+ align_corners=self.align_corners)
+ point_label = point_label.squeeze(1).long()
+
+ losses = self.losses(point_logits, point_label)
+
+ return losses
+
+ def forward_test(self, inputs, prev_output, img_metas, test_cfg):
+ """Forward function for testing.
+
+ Args:
+ inputs (list[Tensor]): List of multi-level img features.
+ prev_output (Tensor): The output of previous decode head.
+ img_metas (list[dict]): List of image info dict where each dict
+ has: 'img_shape', 'scale_factor', 'flip', and may also contain
+ 'filename', 'ori_shape', 'pad_shape', and 'img_norm_cfg'.
+ For details on the values of these keys see
+ `mmseg/datasets/pipelines/formatting.py:Collect`.
+ test_cfg (dict): The testing config.
+
+ Returns:
+ Tensor: Output segmentation map.
+ """
+
+ x = self._transform_inputs(inputs)
+ refined_seg_logits = prev_output.clone()
+ for _ in range(test_cfg.subdivision_steps):
+ refined_seg_logits = resize(
+ refined_seg_logits,
+ scale_factor=test_cfg.scale_factor,
+ mode='bilinear',
+ align_corners=self.align_corners)
+ batch_size, channels, height, width = refined_seg_logits.shape
+ point_indices, points = self.get_points_test(
+ refined_seg_logits, calculate_uncertainty, cfg=test_cfg)
+ fine_grained_point_feats = self._get_fine_grained_point_feats(
+ x, points)
+ coarse_point_feats = self._get_coarse_point_feats(
+ prev_output, points)
+ point_logits = self.forward(fine_grained_point_feats,
+ coarse_point_feats)
+
+ point_indices = point_indices.unsqueeze(1).expand(-1, channels, -1)
+ refined_seg_logits = refined_seg_logits.reshape(
+ batch_size, channels, height * width)
+ refined_seg_logits = refined_seg_logits.scatter_(
+ 2, point_indices, point_logits)
+ refined_seg_logits = refined_seg_logits.view(
+ batch_size, channels, height, width)
+
+ return refined_seg_logits
+
+ def losses(self, point_logits, point_label):
+ """Compute segmentation loss."""
+ loss = dict()
+ if not isinstance(self.loss_decode, nn.ModuleList):
+ losses_decode = [self.loss_decode]
+ else:
+ losses_decode = self.loss_decode
+ for loss_module in losses_decode:
+ loss['point' + loss_module.loss_name] = loss_module(
+ point_logits, point_label, ignore_index=self.ignore_index)
+
+ loss['acc_point'] = accuracy(
+ point_logits, point_label, ignore_index=self.ignore_index)
+ return loss
+
+ def get_points_train(self, seg_logits, uncertainty_func, cfg):
+ """Sample points for training.
+
+ Sample points in [0, 1] x [0, 1] coordinate space based on their
+ uncertainty. The uncertainties are calculated for each point using
+ 'uncertainty_func' function that takes point's logit prediction as
+ input.
+
+ Args:
+ seg_logits (Tensor): Semantic segmentation logits, shape (
+ batch_size, num_classes, height, width).
+ uncertainty_func (func): uncertainty calculation function.
+ cfg (dict): Training config of point head.
+
+ Returns:
+ point_coords (Tensor): A tensor of shape (batch_size, num_points,
+ 2) that contains the coordinates of ``num_points`` sampled
+ points.
+ """
+ num_points = cfg.num_points
+ oversample_ratio = cfg.oversample_ratio
+ importance_sample_ratio = cfg.importance_sample_ratio
+ assert oversample_ratio >= 1
+ assert 0 <= importance_sample_ratio <= 1
+ batch_size = seg_logits.shape[0]
+ num_sampled = int(num_points * oversample_ratio)
+ point_coords = torch.rand(
+ batch_size, num_sampled, 2, device=seg_logits.device)
+ point_logits = point_sample(seg_logits, point_coords)
+ # It is crucial to calculate uncertainty based on the sampled
+ # prediction value for the points. Calculating uncertainties of the
+ # coarse predictions first and sampling them for points leads to
+ # incorrect results. To illustrate this: assume uncertainty func(
+ # logits)=-abs(logits), a sampled point between two coarse
+ # predictions with -1 and 1 logits has 0 logits, and therefore 0
+ # uncertainty value. However, if we calculate uncertainties for the
+ # coarse predictions first, both will have -1 uncertainty,
+ # and sampled point will get -1 uncertainty.
+ point_uncertainties = uncertainty_func(point_logits)
+ num_uncertain_points = int(importance_sample_ratio * num_points)
+ num_random_points = num_points - num_uncertain_points
+ idx = torch.topk(
+ point_uncertainties[:, 0, :], k=num_uncertain_points, dim=1)[1]
+ shift = num_sampled * torch.arange(
+ batch_size, dtype=torch.long, device=seg_logits.device)
+ idx += shift[:, None]
+ point_coords = point_coords.view(-1, 2)[idx.view(-1), :].view(
+ batch_size, num_uncertain_points, 2)
+ if num_random_points > 0:
+ rand_point_coords = torch.rand(
+ batch_size, num_random_points, 2, device=seg_logits.device)
+ point_coords = torch.cat((point_coords, rand_point_coords), dim=1)
+ return point_coords
+
+ def get_points_test(self, seg_logits, uncertainty_func, cfg):
+ """Sample points for testing.
+
+ Find ``num_points`` most uncertain points from ``uncertainty_map``.
+
+ Args:
+ seg_logits (Tensor): A tensor of shape (batch_size, num_classes,
+ height, width) for class-specific or class-agnostic prediction.
+ uncertainty_func (func): uncertainty calculation function.
+ cfg (dict): Testing config of point head.
+
+ Returns:
+ point_indices (Tensor): A tensor of shape (batch_size, num_points)
+ that contains indices from [0, height x width) of the most
+ uncertain points.
+ point_coords (Tensor): A tensor of shape (batch_size, num_points,
+ 2) that contains [0, 1] x [0, 1] normalized coordinates of the
+ most uncertain points from the ``height x width`` grid .
+ """
+
+ num_points = cfg.subdivision_num_points
+ uncertainty_map = uncertainty_func(seg_logits)
+ batch_size, _, height, width = uncertainty_map.shape
+ h_step = 1.0 / height
+ w_step = 1.0 / width
+
+ uncertainty_map = uncertainty_map.view(batch_size, height * width)
+ num_points = min(height * width, num_points)
+ point_indices = uncertainty_map.topk(num_points, dim=1)[1]
+ point_coords = torch.zeros(
+ batch_size,
+ num_points,
+ 2,
+ dtype=torch.float,
+ device=seg_logits.device)
+ point_coords[:, :, 0] = w_step / 2.0 + (point_indices %
+ width).float() * w_step
+ point_coords[:, :, 1] = h_step / 2.0 + (point_indices //
+ width).float() * h_step
+ return point_indices, point_coords
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/psa_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/psa_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..df7593cbcbd3c0de30d6a1cc7f5f1e0b8aa9e965
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/psa_head.py
@@ -0,0 +1,197 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+from mmcv.cnn import ConvModule
+
+from mmseg.ops import resize
+from ..builder import HEADS
+from .decode_head import BaseDecodeHead
+
+try:
+ from mmcv.ops import PSAMask
+except ModuleNotFoundError:
+ PSAMask = None
+
+
+@HEADS.register_module()
+class PSAHead(BaseDecodeHead):
+ """Point-wise Spatial Attention Network for Scene Parsing.
+
+ This head is the implementation of `PSANet
+ `_.
+
+ Args:
+ mask_size (tuple[int]): The PSA mask size. It usually equals input
+ size.
+ psa_type (str): The type of psa module. Options are 'collect',
+ 'distribute', 'bi-direction'. Default: 'bi-direction'
+ compact (bool): Whether use compact map for 'collect' mode.
+ Default: True.
+ shrink_factor (int): The downsample factors of psa mask. Default: 2.
+ normalization_factor (float): The normalize factor of attention.
+ psa_softmax (bool): Whether use softmax for attention.
+ """
+
+ def __init__(self,
+ mask_size,
+ psa_type='bi-direction',
+ compact=False,
+ shrink_factor=2,
+ normalization_factor=1.0,
+ psa_softmax=True,
+ **kwargs):
+ if PSAMask is None:
+ raise RuntimeError('Please install mmcv-full for PSAMask ops')
+ super(PSAHead, self).__init__(**kwargs)
+ assert psa_type in ['collect', 'distribute', 'bi-direction']
+ self.psa_type = psa_type
+ self.compact = compact
+ self.shrink_factor = shrink_factor
+ self.mask_size = mask_size
+ mask_h, mask_w = mask_size
+ self.psa_softmax = psa_softmax
+ if normalization_factor is None:
+ normalization_factor = mask_h * mask_w
+ self.normalization_factor = normalization_factor
+
+ self.reduce = ConvModule(
+ self.in_channels,
+ self.channels,
+ kernel_size=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ self.attention = nn.Sequential(
+ ConvModule(
+ self.channels,
+ self.channels,
+ kernel_size=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg),
+ nn.Conv2d(
+ self.channels, mask_h * mask_w, kernel_size=1, bias=False))
+ if psa_type == 'bi-direction':
+ self.reduce_p = ConvModule(
+ self.in_channels,
+ self.channels,
+ kernel_size=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ self.attention_p = nn.Sequential(
+ ConvModule(
+ self.channels,
+ self.channels,
+ kernel_size=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg),
+ nn.Conv2d(
+ self.channels, mask_h * mask_w, kernel_size=1, bias=False))
+ self.psamask_collect = PSAMask('collect', mask_size)
+ self.psamask_distribute = PSAMask('distribute', mask_size)
+ else:
+ self.psamask = PSAMask(psa_type, mask_size)
+ self.proj = ConvModule(
+ self.channels * (2 if psa_type == 'bi-direction' else 1),
+ self.in_channels,
+ kernel_size=1,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ self.bottleneck = ConvModule(
+ self.in_channels * 2,
+ self.channels,
+ kernel_size=3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ def forward(self, inputs):
+ """Forward function."""
+ x = self._transform_inputs(inputs)
+ identity = x
+ align_corners = self.align_corners
+ if self.psa_type in ['collect', 'distribute']:
+ out = self.reduce(x)
+ n, c, h, w = out.size()
+ if self.shrink_factor != 1:
+ if h % self.shrink_factor and w % self.shrink_factor:
+ h = (h - 1) // self.shrink_factor + 1
+ w = (w - 1) // self.shrink_factor + 1
+ align_corners = True
+ else:
+ h = h // self.shrink_factor
+ w = w // self.shrink_factor
+ align_corners = False
+ out = resize(
+ out,
+ size=(h, w),
+ mode='bilinear',
+ align_corners=align_corners)
+ y = self.attention(out)
+ if self.compact:
+ if self.psa_type == 'collect':
+ y = y.view(n, h * w,
+ h * w).transpose(1, 2).view(n, h * w, h, w)
+ else:
+ y = self.psamask(y)
+ if self.psa_softmax:
+ y = F.softmax(y, dim=1)
+ out = torch.bmm(
+ out.view(n, c, h * w), y.view(n, h * w, h * w)).view(
+ n, c, h, w) * (1.0 / self.normalization_factor)
+ else:
+ x_col = self.reduce(x)
+ x_dis = self.reduce_p(x)
+ n, c, h, w = x_col.size()
+ if self.shrink_factor != 1:
+ if h % self.shrink_factor and w % self.shrink_factor:
+ h = (h - 1) // self.shrink_factor + 1
+ w = (w - 1) // self.shrink_factor + 1
+ align_corners = True
+ else:
+ h = h // self.shrink_factor
+ w = w // self.shrink_factor
+ align_corners = False
+ x_col = resize(
+ x_col,
+ size=(h, w),
+ mode='bilinear',
+ align_corners=align_corners)
+ x_dis = resize(
+ x_dis,
+ size=(h, w),
+ mode='bilinear',
+ align_corners=align_corners)
+ y_col = self.attention(x_col)
+ y_dis = self.attention_p(x_dis)
+ if self.compact:
+ y_dis = y_dis.view(n, h * w,
+ h * w).transpose(1, 2).view(n, h * w, h, w)
+ else:
+ y_col = self.psamask_collect(y_col)
+ y_dis = self.psamask_distribute(y_dis)
+ if self.psa_softmax:
+ y_col = F.softmax(y_col, dim=1)
+ y_dis = F.softmax(y_dis, dim=1)
+ x_col = torch.bmm(
+ x_col.view(n, c, h * w), y_col.view(n, h * w, h * w)).view(
+ n, c, h, w) * (1.0 / self.normalization_factor)
+ x_dis = torch.bmm(
+ x_dis.view(n, c, h * w), y_dis.view(n, h * w, h * w)).view(
+ n, c, h, w) * (1.0 / self.normalization_factor)
+ out = torch.cat([x_col, x_dis], 1)
+ out = self.proj(out)
+ out = resize(
+ out,
+ size=identity.shape[2:],
+ mode='bilinear',
+ align_corners=align_corners)
+ out = self.bottleneck(torch.cat((identity, out), dim=1))
+ out = self.cls_seg(out)
+ return out
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/psp_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/psp_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..6990676ff24fbf7c6ff1f677efc665f778e9f13b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/psp_head.py
@@ -0,0 +1,117 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+from mmcv.cnn import ConvModule
+
+from mmseg.ops import resize
+from ..builder import HEADS
+from .decode_head import BaseDecodeHead
+
+
+class PPM(nn.ModuleList):
+ """Pooling Pyramid Module used in PSPNet.
+
+ Args:
+ pool_scales (tuple[int]): Pooling scales used in Pooling Pyramid
+ Module.
+ in_channels (int): Input channels.
+ channels (int): Channels after modules, before conv_seg.
+ conv_cfg (dict|None): Config of conv layers.
+ norm_cfg (dict|None): Config of norm layers.
+ act_cfg (dict): Config of activation layers.
+ align_corners (bool): align_corners argument of F.interpolate.
+ """
+
+ def __init__(self, pool_scales, in_channels, channels, conv_cfg, norm_cfg,
+ act_cfg, align_corners, **kwargs):
+ super(PPM, self).__init__()
+ self.pool_scales = pool_scales
+ self.align_corners = align_corners
+ self.in_channels = in_channels
+ self.channels = channels
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+ for pool_scale in pool_scales:
+ self.append(
+ nn.Sequential(
+ nn.AdaptiveAvgPool2d(pool_scale),
+ ConvModule(
+ self.in_channels,
+ self.channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg,
+ **kwargs)))
+
+ def forward(self, x):
+ """Forward function."""
+ ppm_outs = []
+ for ppm in self:
+ ppm_out = ppm(x)
+ upsampled_ppm_out = resize(
+ ppm_out,
+ size=x.size()[2:],
+ mode='bilinear',
+ align_corners=self.align_corners)
+ ppm_outs.append(upsampled_ppm_out)
+ return ppm_outs
+
+
+@HEADS.register_module()
+class PSPHead(BaseDecodeHead):
+ """Pyramid Scene Parsing Network.
+
+ This head is the implementation of
+ `PSPNet `_.
+
+ Args:
+ pool_scales (tuple[int]): Pooling scales used in Pooling Pyramid
+ Module. Default: (1, 2, 3, 6).
+ """
+
+ def __init__(self, pool_scales=(1, 2, 3, 6), **kwargs):
+ super(PSPHead, self).__init__(**kwargs)
+ assert isinstance(pool_scales, (list, tuple))
+ self.pool_scales = pool_scales
+ self.psp_modules = PPM(
+ self.pool_scales,
+ self.in_channels,
+ self.channels,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg,
+ align_corners=self.align_corners)
+ self.bottleneck = ConvModule(
+ self.in_channels + len(pool_scales) * self.channels,
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ def _forward_feature(self, inputs):
+ """Forward function for feature maps before classifying each pixel with
+ ``self.cls_seg`` fc.
+
+ Args:
+ inputs (list[Tensor]): List of multi-level img features.
+
+ Returns:
+ feats (Tensor): A tensor of shape (batch_size, self.channels,
+ H, W) which is feature map for last layer of decoder head.
+ """
+ x = self._transform_inputs(inputs)
+ psp_outs = [x]
+ psp_outs.extend(self.psp_modules(x))
+ psp_outs = torch.cat(psp_outs, dim=1)
+ feats = self.bottleneck(psp_outs)
+ return feats
+
+ def forward(self, inputs):
+ """Forward function."""
+ output = self._forward_feature(inputs)
+ output = self.cls_seg(output)
+ return output
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/segformer_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/segformer_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..2e75d5069b35788176a56887f3a29488e7315cd5
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/segformer_head.py
@@ -0,0 +1,66 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+from mmcv.cnn import ConvModule
+
+from mmseg.models.builder import HEADS
+from mmseg.models.decode_heads.decode_head import BaseDecodeHead
+from mmseg.ops import resize
+
+
+@HEADS.register_module()
+class SegformerHead(BaseDecodeHead):
+ """The all mlp Head of segformer.
+
+ This head is the implementation of
+ `Segformer ` _.
+
+ Args:
+ interpolate_mode: The interpolate mode of MLP head upsample operation.
+ Default: 'bilinear'.
+ """
+
+ def __init__(self, interpolate_mode='bilinear', **kwargs):
+ super().__init__(input_transform='multiple_select', **kwargs)
+
+ self.interpolate_mode = interpolate_mode
+ num_inputs = len(self.in_channels)
+
+ assert num_inputs == len(self.in_index)
+
+ self.convs = nn.ModuleList()
+ for i in range(num_inputs):
+ self.convs.append(
+ ConvModule(
+ in_channels=self.in_channels[i],
+ out_channels=self.channels,
+ kernel_size=1,
+ stride=1,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg))
+
+ self.fusion_conv = ConvModule(
+ in_channels=self.channels * num_inputs,
+ out_channels=self.channels,
+ kernel_size=1,
+ norm_cfg=self.norm_cfg)
+
+ def forward(self, inputs):
+ # Receive 4 stage backbone feature map: 1/4, 1/8, 1/16, 1/32
+ inputs = self._transform_inputs(inputs)
+ outs = []
+ for idx in range(len(inputs)):
+ x = inputs[idx]
+ conv = self.convs[idx]
+ outs.append(
+ resize(
+ input=conv(x),
+ size=inputs[0].shape[2:],
+ mode=self.interpolate_mode,
+ align_corners=self.align_corners))
+
+ out = self.fusion_conv(torch.cat(outs, dim=1))
+
+ out = self.cls_seg(out)
+
+ return out
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/segmenter_mask_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/segmenter_mask_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..6a9b3d47ec5de0543e01aeb3df8092e6dbd5a7ea
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/segmenter_mask_head.py
@@ -0,0 +1,133 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+from mmcv.cnn import build_norm_layer
+from mmcv.cnn.utils.weight_init import (constant_init, trunc_normal_,
+ trunc_normal_init)
+from mmcv.runner import ModuleList
+
+from mmseg.models.backbones.vit import TransformerEncoderLayer
+from ..builder import HEADS
+from .decode_head import BaseDecodeHead
+
+
+@HEADS.register_module()
+class SegmenterMaskTransformerHead(BaseDecodeHead):
+ """Segmenter: Transformer for Semantic Segmentation.
+
+ This head is the implementation of
+ `Segmenter: `_.
+
+ Args:
+ backbone_cfg:(dict): Config of backbone of
+ Context Path.
+ in_channels (int): The number of channels of input image.
+ num_layers (int): The depth of transformer.
+ num_heads (int): The number of attention heads.
+ embed_dims (int): The number of embedding dimension.
+ mlp_ratio (int): ratio of mlp hidden dim to embedding dim.
+ Default: 4.
+ drop_path_rate (float): stochastic depth rate. Default 0.1.
+ drop_rate (float): Probability of an element to be zeroed.
+ Default 0.0
+ attn_drop_rate (float): The drop out rate for attention layer.
+ Default 0.0
+ num_fcs (int): The number of fully-connected layers for FFNs.
+ Default: 2.
+ qkv_bias (bool): Enable bias for qkv if True. Default: True.
+ act_cfg (dict): The activation config for FFNs.
+ Default: dict(type='GELU').
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='LN')
+ init_std (float): The value of std in weight initialization.
+ Default: 0.02.
+ """
+
+ def __init__(
+ self,
+ in_channels,
+ num_layers,
+ num_heads,
+ embed_dims,
+ mlp_ratio=4,
+ drop_path_rate=0.1,
+ drop_rate=0.0,
+ attn_drop_rate=0.0,
+ num_fcs=2,
+ qkv_bias=True,
+ act_cfg=dict(type='GELU'),
+ norm_cfg=dict(type='LN'),
+ init_std=0.02,
+ **kwargs,
+ ):
+ super(SegmenterMaskTransformerHead, self).__init__(
+ in_channels=in_channels, **kwargs)
+
+ dpr = [x.item() for x in torch.linspace(0, drop_path_rate, num_layers)]
+ self.layers = ModuleList()
+ for i in range(num_layers):
+ self.layers.append(
+ TransformerEncoderLayer(
+ embed_dims=embed_dims,
+ num_heads=num_heads,
+ feedforward_channels=mlp_ratio * embed_dims,
+ attn_drop_rate=attn_drop_rate,
+ drop_rate=drop_rate,
+ drop_path_rate=dpr[i],
+ num_fcs=num_fcs,
+ qkv_bias=qkv_bias,
+ act_cfg=act_cfg,
+ norm_cfg=norm_cfg,
+ batch_first=True,
+ ))
+
+ self.dec_proj = nn.Linear(in_channels, embed_dims)
+
+ self.cls_emb = nn.Parameter(
+ torch.randn(1, self.num_classes, embed_dims))
+ self.patch_proj = nn.Linear(embed_dims, embed_dims, bias=False)
+ self.classes_proj = nn.Linear(embed_dims, embed_dims, bias=False)
+
+ self.decoder_norm = build_norm_layer(
+ norm_cfg, embed_dims, postfix=1)[1]
+ self.mask_norm = build_norm_layer(
+ norm_cfg, self.num_classes, postfix=2)[1]
+
+ self.init_std = init_std
+
+ delattr(self, 'conv_seg')
+
+ def init_weights(self):
+ trunc_normal_(self.cls_emb, std=self.init_std)
+ trunc_normal_init(self.patch_proj, std=self.init_std)
+ trunc_normal_init(self.classes_proj, std=self.init_std)
+ for n, m in self.named_modules():
+ if isinstance(m, nn.Linear):
+ trunc_normal_init(m, std=self.init_std, bias=0)
+ elif isinstance(m, nn.LayerNorm):
+ constant_init(m, val=1.0, bias=0.0)
+
+ def forward(self, inputs):
+ x = self._transform_inputs(inputs)
+ b, c, h, w = x.shape
+ x = x.permute(0, 2, 3, 1).contiguous().view(b, -1, c)
+
+ x = self.dec_proj(x)
+ cls_emb = self.cls_emb.expand(x.size(0), -1, -1)
+ x = torch.cat((x, cls_emb), 1)
+ for layer in self.layers:
+ x = layer(x)
+ x = self.decoder_norm(x)
+
+ patches = self.patch_proj(x[:, :-self.num_classes])
+ cls_seg_feat = self.classes_proj(x[:, -self.num_classes:])
+
+ patches = F.normalize(patches, dim=2, p=2)
+ cls_seg_feat = F.normalize(cls_seg_feat, dim=2, p=2)
+
+ masks = patches @ cls_seg_feat.transpose(1, 2)
+ masks = self.mask_norm(masks)
+ masks = masks.permute(0, 2, 1).contiguous().view(b, -1, h, w)
+
+ return masks
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/sep_aspp_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/sep_aspp_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..4e894e28e3b192ce59d83ef09ec3105ed1436ae8
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/sep_aspp_head.py
@@ -0,0 +1,102 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+from mmcv.cnn import ConvModule, DepthwiseSeparableConvModule
+
+from mmseg.ops import resize
+from ..builder import HEADS
+from .aspp_head import ASPPHead, ASPPModule
+
+
+class DepthwiseSeparableASPPModule(ASPPModule):
+ """Atrous Spatial Pyramid Pooling (ASPP) Module with depthwise separable
+ conv."""
+
+ def __init__(self, **kwargs):
+ super(DepthwiseSeparableASPPModule, self).__init__(**kwargs)
+ for i, dilation in enumerate(self.dilations):
+ if dilation > 1:
+ self[i] = DepthwiseSeparableConvModule(
+ self.in_channels,
+ self.channels,
+ 3,
+ dilation=dilation,
+ padding=dilation,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+
+@HEADS.register_module()
+class DepthwiseSeparableASPPHead(ASPPHead):
+ """Encoder-Decoder with Atrous Separable Convolution for Semantic Image
+ Segmentation.
+
+ This head is the implementation of `DeepLabV3+
+ `_.
+
+ Args:
+ c1_in_channels (int): The input channels of c1 decoder. If is 0,
+ the no decoder will be used.
+ c1_channels (int): The intermediate channels of c1 decoder.
+ """
+
+ def __init__(self, c1_in_channels, c1_channels, **kwargs):
+ super(DepthwiseSeparableASPPHead, self).__init__(**kwargs)
+ assert c1_in_channels >= 0
+ self.aspp_modules = DepthwiseSeparableASPPModule(
+ dilations=self.dilations,
+ in_channels=self.in_channels,
+ channels=self.channels,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ if c1_in_channels > 0:
+ self.c1_bottleneck = ConvModule(
+ c1_in_channels,
+ c1_channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ else:
+ self.c1_bottleneck = None
+ self.sep_bottleneck = nn.Sequential(
+ DepthwiseSeparableConvModule(
+ self.channels + c1_channels,
+ self.channels,
+ 3,
+ padding=1,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg),
+ DepthwiseSeparableConvModule(
+ self.channels,
+ self.channels,
+ 3,
+ padding=1,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg))
+
+ def forward(self, inputs):
+ """Forward function."""
+ x = self._transform_inputs(inputs)
+ aspp_outs = [
+ resize(
+ self.image_pool(x),
+ size=x.size()[2:],
+ mode='bilinear',
+ align_corners=self.align_corners)
+ ]
+ aspp_outs.extend(self.aspp_modules(x))
+ aspp_outs = torch.cat(aspp_outs, dim=1)
+ output = self.bottleneck(aspp_outs)
+ if self.c1_bottleneck is not None:
+ c1_output = self.c1_bottleneck(inputs[0])
+ output = resize(
+ input=output,
+ size=c1_output.shape[2:],
+ mode='bilinear',
+ align_corners=self.align_corners)
+ output = torch.cat([output, c1_output], dim=1)
+ output = self.sep_bottleneck(output)
+ output = self.cls_seg(output)
+ return output
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/sep_fcn_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/sep_fcn_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..7f9658e08fbf3cd38e7c573acf3501e131d94198
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/sep_fcn_head.py
@@ -0,0 +1,60 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from mmcv.cnn import DepthwiseSeparableConvModule
+
+from ..builder import HEADS
+from .fcn_head import FCNHead
+
+
+@HEADS.register_module()
+class DepthwiseSeparableFCNHead(FCNHead):
+ """Depthwise-Separable Fully Convolutional Network for Semantic
+ Segmentation.
+
+ This head is implemented according to `Fast-SCNN: Fast Semantic
+ Segmentation Network `_.
+
+ Args:
+ in_channels(int): Number of output channels of FFM.
+ channels(int): Number of middle-stage channels in the decode head.
+ concat_input(bool): Whether to concatenate original decode input into
+ the result of several consecutive convolution layers.
+ Default: True.
+ num_classes(int): Used to determine the dimension of
+ final prediction tensor.
+ in_index(int): Correspond with 'out_indices' in FastSCNN backbone.
+ norm_cfg (dict | None): Config of norm layers.
+ align_corners (bool): align_corners argument of F.interpolate.
+ Default: False.
+ loss_decode(dict): Config of loss type and some
+ relevant additional options.
+ dw_act_cfg (dict):Activation config of depthwise ConvModule. If it is
+ 'default', it will be the same as `act_cfg`. Default: None.
+ """
+
+ def __init__(self, dw_act_cfg=None, **kwargs):
+ super(DepthwiseSeparableFCNHead, self).__init__(**kwargs)
+ self.convs[0] = DepthwiseSeparableConvModule(
+ self.in_channels,
+ self.channels,
+ kernel_size=self.kernel_size,
+ padding=self.kernel_size // 2,
+ norm_cfg=self.norm_cfg,
+ dw_act_cfg=dw_act_cfg)
+
+ for i in range(1, self.num_convs):
+ self.convs[i] = DepthwiseSeparableConvModule(
+ self.channels,
+ self.channels,
+ kernel_size=self.kernel_size,
+ padding=self.kernel_size // 2,
+ norm_cfg=self.norm_cfg,
+ dw_act_cfg=dw_act_cfg)
+
+ if self.concat_input:
+ self.conv_cat = DepthwiseSeparableConvModule(
+ self.in_channels + self.channels,
+ self.channels,
+ kernel_size=self.kernel_size,
+ padding=self.kernel_size // 2,
+ norm_cfg=self.norm_cfg,
+ dw_act_cfg=dw_act_cfg)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/setr_mla_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/setr_mla_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..6bb94ae33007aa29923680fd2e558c15320bec95
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/setr_mla_head.py
@@ -0,0 +1,63 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+from mmcv.cnn import ConvModule
+
+from mmseg.ops import Upsample
+from ..builder import HEADS
+from .decode_head import BaseDecodeHead
+
+
+@HEADS.register_module()
+class SETRMLAHead(BaseDecodeHead):
+ """Multi level feature aggretation head of SETR.
+
+ MLA head of `SETR `_.
+
+ Args:
+ mlahead_channels (int): Channels of conv-conv-4x of multi-level feature
+ aggregation. Default: 128.
+ up_scale (int): The scale factor of interpolate. Default:4.
+ """
+
+ def __init__(self, mla_channels=128, up_scale=4, **kwargs):
+ super(SETRMLAHead, self).__init__(
+ input_transform='multiple_select', **kwargs)
+ self.mla_channels = mla_channels
+
+ num_inputs = len(self.in_channels)
+
+ # Refer to self.cls_seg settings of BaseDecodeHead
+ assert self.channels == num_inputs * mla_channels
+
+ self.up_convs = nn.ModuleList()
+ for i in range(num_inputs):
+ self.up_convs.append(
+ nn.Sequential(
+ ConvModule(
+ in_channels=self.in_channels[i],
+ out_channels=mla_channels,
+ kernel_size=3,
+ padding=1,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg),
+ ConvModule(
+ in_channels=mla_channels,
+ out_channels=mla_channels,
+ kernel_size=3,
+ padding=1,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg),
+ Upsample(
+ scale_factor=up_scale,
+ mode='bilinear',
+ align_corners=self.align_corners)))
+
+ def forward(self, inputs):
+ inputs = self._transform_inputs(inputs)
+ outs = []
+ for x, up_conv in zip(inputs, self.up_convs):
+ outs.append(up_conv(x))
+ out = torch.cat(outs, dim=1)
+ out = self.cls_seg(out)
+ return out
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/setr_up_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/setr_up_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..87e7ea7faa5228e22847f5739055e17dc5415f32
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/setr_up_head.py
@@ -0,0 +1,81 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch.nn as nn
+from mmcv.cnn import ConvModule, build_norm_layer
+
+from mmseg.ops import Upsample
+from ..builder import HEADS
+from .decode_head import BaseDecodeHead
+
+
+@HEADS.register_module()
+class SETRUPHead(BaseDecodeHead):
+ """Naive upsampling head and Progressive upsampling head of SETR.
+
+ Naive or PUP head of `SETR `_.
+
+ Args:
+ norm_layer (dict): Config dict for input normalization.
+ Default: norm_layer=dict(type='LN', eps=1e-6, requires_grad=True).
+ num_convs (int): Number of decoder convolutions. Default: 1.
+ up_scale (int): The scale factor of interpolate. Default:4.
+ kernel_size (int): The kernel size of convolution when decoding
+ feature information from backbone. Default: 3.
+ init_cfg (dict | list[dict] | None): Initialization config dict.
+ Default: dict(
+ type='Constant', val=1.0, bias=0, layer='LayerNorm').
+ """
+
+ def __init__(self,
+ norm_layer=dict(type='LN', eps=1e-6, requires_grad=True),
+ num_convs=1,
+ up_scale=4,
+ kernel_size=3,
+ init_cfg=[
+ dict(type='Constant', val=1.0, bias=0, layer='LayerNorm'),
+ dict(
+ type='Normal',
+ std=0.01,
+ override=dict(name='conv_seg'))
+ ],
+ **kwargs):
+
+ assert kernel_size in [1, 3], 'kernel_size must be 1 or 3.'
+
+ super(SETRUPHead, self).__init__(init_cfg=init_cfg, **kwargs)
+
+ assert isinstance(self.in_channels, int)
+
+ _, self.norm = build_norm_layer(norm_layer, self.in_channels)
+
+ self.up_convs = nn.ModuleList()
+ in_channels = self.in_channels
+ out_channels = self.channels
+ for _ in range(num_convs):
+ self.up_convs.append(
+ nn.Sequential(
+ ConvModule(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ kernel_size=kernel_size,
+ stride=1,
+ padding=int(kernel_size - 1) // 2,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg),
+ Upsample(
+ scale_factor=up_scale,
+ mode='bilinear',
+ align_corners=self.align_corners)))
+ in_channels = out_channels
+
+ def forward(self, x):
+ x = self._transform_inputs(x)
+
+ n, c, h, w = x.shape
+ x = x.reshape(n, c, h * w).transpose(2, 1).contiguous()
+ x = self.norm(x)
+ x = x.transpose(1, 2).reshape(n, c, h, w).contiguous()
+
+ for up_conv in self.up_convs:
+ x = up_conv(x)
+ out = self.cls_seg(x)
+ return out
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/stdc_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/stdc_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..1cf3732ceb2e555ab1822663199532184b06ede1
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/stdc_head.py
@@ -0,0 +1,85 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn.functional as F
+
+from ..builder import HEADS
+from .fcn_head import FCNHead
+
+
+@HEADS.register_module()
+class STDCHead(FCNHead):
+ """This head is the implementation of `Rethinking BiSeNet For Real-time
+ Semantic Segmentation `_.
+
+ Args:
+ boundary_threshold (float): The threshold of calculating boundary.
+ Default: 0.1.
+ """
+
+ def __init__(self, boundary_threshold=0.1, **kwargs):
+ super(STDCHead, self).__init__(**kwargs)
+ self.boundary_threshold = boundary_threshold
+ # Using register buffer to make laplacian kernel on the same
+ # device of `seg_label`.
+ self.register_buffer(
+ 'laplacian_kernel',
+ torch.tensor([-1, -1, -1, -1, 8, -1, -1, -1, -1],
+ dtype=torch.float32,
+ requires_grad=False).reshape((1, 1, 3, 3)))
+ self.fusion_kernel = torch.nn.Parameter(
+ torch.tensor([[6. / 10], [3. / 10], [1. / 10]],
+ dtype=torch.float32).reshape(1, 3, 1, 1),
+ requires_grad=False)
+
+ def losses(self, seg_logit, seg_label):
+ """Compute Detail Aggregation Loss."""
+ # Note: The paper claims `fusion_kernel` is a trainable 1x1 conv
+ # parameters. However, it is a constant in original repo and other
+ # codebase because it would not be added into computation graph
+ # after threshold operation.
+ seg_label = seg_label.to(self.laplacian_kernel)
+ boundary_targets = F.conv2d(
+ seg_label, self.laplacian_kernel, padding=1)
+ boundary_targets = boundary_targets.clamp(min=0)
+ boundary_targets[boundary_targets > self.boundary_threshold] = 1
+ boundary_targets[boundary_targets <= self.boundary_threshold] = 0
+
+ boundary_targets_x2 = F.conv2d(
+ seg_label, self.laplacian_kernel, stride=2, padding=1)
+ boundary_targets_x2 = boundary_targets_x2.clamp(min=0)
+
+ boundary_targets_x4 = F.conv2d(
+ seg_label, self.laplacian_kernel, stride=4, padding=1)
+ boundary_targets_x4 = boundary_targets_x4.clamp(min=0)
+
+ boundary_targets_x4_up = F.interpolate(
+ boundary_targets_x4, boundary_targets.shape[2:], mode='nearest')
+ boundary_targets_x2_up = F.interpolate(
+ boundary_targets_x2, boundary_targets.shape[2:], mode='nearest')
+
+ boundary_targets_x2_up[
+ boundary_targets_x2_up > self.boundary_threshold] = 1
+ boundary_targets_x2_up[
+ boundary_targets_x2_up <= self.boundary_threshold] = 0
+
+ boundary_targets_x4_up[
+ boundary_targets_x4_up > self.boundary_threshold] = 1
+ boundary_targets_x4_up[
+ boundary_targets_x4_up <= self.boundary_threshold] = 0
+
+ boudary_targets_pyramids = torch.stack(
+ (boundary_targets, boundary_targets_x2_up, boundary_targets_x4_up),
+ dim=1)
+
+ boudary_targets_pyramids = boudary_targets_pyramids.squeeze(2)
+ boudary_targets_pyramid = F.conv2d(boudary_targets_pyramids,
+ self.fusion_kernel)
+
+ boudary_targets_pyramid[
+ boudary_targets_pyramid > self.boundary_threshold] = 1
+ boudary_targets_pyramid[
+ boudary_targets_pyramid <= self.boundary_threshold] = 0
+
+ loss = super(STDCHead, self).losses(seg_logit,
+ boudary_targets_pyramid.long())
+ return loss
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/uper_head.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/uper_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..06b152a3f02d431cf7f7398dd996a1453a46100e
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/decode_heads/uper_head.py
@@ -0,0 +1,140 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+from mmcv.cnn import ConvModule
+
+from mmseg.ops import resize
+from ..builder import HEADS
+from .decode_head import BaseDecodeHead
+from .psp_head import PPM
+
+
+@HEADS.register_module()
+class UPerHead(BaseDecodeHead):
+ """Unified Perceptual Parsing for Scene Understanding.
+
+ This head is the implementation of `UPerNet
+ `_.
+
+ Args:
+ pool_scales (tuple[int]): Pooling scales used in Pooling Pyramid
+ Module applied on the last feature. Default: (1, 2, 3, 6).
+ """
+
+ def __init__(self, pool_scales=(1, 2, 3, 6), **kwargs):
+ super(UPerHead, self).__init__(
+ input_transform='multiple_select', **kwargs)
+ # PSP Module
+ self.psp_modules = PPM(
+ pool_scales,
+ self.in_channels[-1],
+ self.channels,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg,
+ align_corners=self.align_corners)
+ self.bottleneck = ConvModule(
+ self.in_channels[-1] + len(pool_scales) * self.channels,
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+ # FPN Module
+ self.lateral_convs = nn.ModuleList()
+ self.fpn_convs = nn.ModuleList()
+ for in_channels in self.in_channels[:-1]: # skip the top layer
+ l_conv = ConvModule(
+ in_channels,
+ self.channels,
+ 1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg,
+ inplace=False)
+ fpn_conv = ConvModule(
+ self.channels,
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg,
+ inplace=False)
+ self.lateral_convs.append(l_conv)
+ self.fpn_convs.append(fpn_conv)
+
+ self.fpn_bottleneck = ConvModule(
+ len(self.in_channels) * self.channels,
+ self.channels,
+ 3,
+ padding=1,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg)
+
+ def psp_forward(self, inputs):
+ """Forward function of PSP module."""
+ x = inputs[-1]
+ psp_outs = [x]
+ psp_outs.extend(self.psp_modules(x))
+ psp_outs = torch.cat(psp_outs, dim=1)
+ output = self.bottleneck(psp_outs)
+
+ return output
+
+ def _forward_feature(self, inputs):
+ """Forward function for feature maps before classifying each pixel with
+ ``self.cls_seg`` fc.
+
+ Args:
+ inputs (list[Tensor]): List of multi-level img features.
+
+ Returns:
+ feats (Tensor): A tensor of shape (batch_size, self.channels,
+ H, W) which is feature map for last layer of decoder head.
+ """
+ inputs = self._transform_inputs(inputs)
+
+ # build laterals
+ laterals = [
+ lateral_conv(inputs[i])
+ for i, lateral_conv in enumerate(self.lateral_convs)
+ ]
+
+ laterals.append(self.psp_forward(inputs))
+
+ # build top-down path
+ used_backbone_levels = len(laterals)
+ for i in range(used_backbone_levels - 1, 0, -1):
+ prev_shape = laterals[i - 1].shape[2:]
+ laterals[i - 1] = laterals[i - 1] + resize(
+ laterals[i],
+ size=prev_shape,
+ mode='bilinear',
+ align_corners=self.align_corners)
+
+ # build outputs
+ fpn_outs = [
+ self.fpn_convs[i](laterals[i])
+ for i in range(used_backbone_levels - 1)
+ ]
+ # append psp feature
+ fpn_outs.append(laterals[-1])
+
+ for i in range(used_backbone_levels - 1, 0, -1):
+ fpn_outs[i] = resize(
+ fpn_outs[i],
+ size=fpn_outs[0].shape[2:],
+ mode='bilinear',
+ align_corners=self.align_corners)
+ fpn_outs = torch.cat(fpn_outs, dim=1)
+ feats = self.fpn_bottleneck(fpn_outs)
+ return feats
+
+ def forward(self, inputs):
+ """Forward function."""
+ output = self._forward_feature(inputs)
+ output = self.cls_seg(output)
+ return output
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..fbc5b2d1b9d4425f3a1938cbf8aa3b50a1a41d31
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/__init__.py
@@ -0,0 +1,15 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .accuracy import Accuracy, accuracy
+from .cross_entropy_loss import (CrossEntropyLoss, binary_cross_entropy,
+ cross_entropy, mask_cross_entropy)
+from .dice_loss import DiceLoss
+from .focal_loss import FocalLoss
+from .lovasz_loss import LovaszLoss
+from .utils import reduce_loss, weight_reduce_loss, weighted_loss
+
+__all__ = [
+ 'accuracy', 'Accuracy', 'cross_entropy', 'binary_cross_entropy',
+ 'mask_cross_entropy', 'CrossEntropyLoss', 'reduce_loss',
+ 'weight_reduce_loss', 'weighted_loss', 'LovaszLoss', 'DiceLoss',
+ 'FocalLoss'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/accuracy.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/accuracy.py
new file mode 100644
index 0000000000000000000000000000000000000000..1d9e2d7701088adadd5b6bb71c718c986b87a066
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/accuracy.py
@@ -0,0 +1,92 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+
+
+def accuracy(pred, target, topk=1, thresh=None, ignore_index=None):
+ """Calculate accuracy according to the prediction and target.
+
+ Args:
+ pred (torch.Tensor): The model prediction, shape (N, num_class, ...)
+ target (torch.Tensor): The target of each prediction, shape (N, , ...)
+ ignore_index (int | None): The label index to be ignored. Default: None
+ topk (int | tuple[int], optional): If the predictions in ``topk``
+ matches the target, the predictions will be regarded as
+ correct ones. Defaults to 1.
+ thresh (float, optional): If not None, predictions with scores under
+ this threshold are considered incorrect. Default to None.
+
+ Returns:
+ float | tuple[float]: If the input ``topk`` is a single integer,
+ the function will return a single float as accuracy. If
+ ``topk`` is a tuple containing multiple integers, the
+ function will return a tuple containing accuracies of
+ each ``topk`` number.
+ """
+ assert isinstance(topk, (int, tuple))
+ if isinstance(topk, int):
+ topk = (topk, )
+ return_single = True
+ else:
+ return_single = False
+
+ maxk = max(topk)
+ if pred.size(0) == 0:
+ accu = [pred.new_tensor(0.) for i in range(len(topk))]
+ return accu[0] if return_single else accu
+ assert pred.ndim == target.ndim + 1
+ assert pred.size(0) == target.size(0)
+ assert maxk <= pred.size(1), \
+ f'maxk {maxk} exceeds pred dimension {pred.size(1)}'
+ pred_value, pred_label = pred.topk(maxk, dim=1)
+ # transpose to shape (maxk, N, ...)
+ pred_label = pred_label.transpose(0, 1)
+ correct = pred_label.eq(target.unsqueeze(0).expand_as(pred_label))
+ if thresh is not None:
+ # Only prediction values larger than thresh are counted as correct
+ correct = correct & (pred_value > thresh).t()
+ if ignore_index is not None:
+ correct = correct[:, target != ignore_index]
+ res = []
+ eps = torch.finfo(torch.float32).eps
+ for k in topk:
+ # Avoid causing ZeroDivisionError when all pixels
+ # of an image are ignored
+ correct_k = correct[:k].reshape(-1).float().sum(0, keepdim=True) + eps
+ if ignore_index is not None:
+ total_num = target[target != ignore_index].numel() + eps
+ else:
+ total_num = target.numel() + eps
+ res.append(correct_k.mul_(100.0 / total_num))
+ return res[0] if return_single else res
+
+
+class Accuracy(nn.Module):
+ """Accuracy calculation module."""
+
+ def __init__(self, topk=(1, ), thresh=None, ignore_index=None):
+ """Module to calculate the accuracy.
+
+ Args:
+ topk (tuple, optional): The criterion used to calculate the
+ accuracy. Defaults to (1,).
+ thresh (float, optional): If not None, predictions with scores
+ under this threshold are considered incorrect. Default to None.
+ """
+ super().__init__()
+ self.topk = topk
+ self.thresh = thresh
+ self.ignore_index = ignore_index
+
+ def forward(self, pred, target):
+ """Forward function to calculate accuracy.
+
+ Args:
+ pred (torch.Tensor): Prediction of models.
+ target (torch.Tensor): Target for each prediction.
+
+ Returns:
+ tuple[float]: The accuracies under different topk criterions.
+ """
+ return accuracy(pred, target, self.topk, self.thresh,
+ self.ignore_index)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/cross_entropy_loss.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/cross_entropy_loss.py
new file mode 100644
index 0000000000000000000000000000000000000000..623fd58dbc7d909962f00d85517720ec732c6ff2
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/cross_entropy_loss.py
@@ -0,0 +1,296 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import warnings
+
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+
+from ..builder import LOSSES
+from .utils import get_class_weight, weight_reduce_loss
+
+
+def cross_entropy(pred,
+ label,
+ weight=None,
+ class_weight=None,
+ reduction='mean',
+ avg_factor=None,
+ ignore_index=-100,
+ avg_non_ignore=False):
+ """cross_entropy. The wrapper function for :func:`F.cross_entropy`
+
+ Args:
+ pred (torch.Tensor): The prediction with shape (N, 1).
+ label (torch.Tensor): The learning label of the prediction.
+ weight (torch.Tensor, optional): Sample-wise loss weight.
+ Default: None.
+ class_weight (list[float], optional): The weight for each class.
+ Default: None.
+ reduction (str, optional): The method used to reduce the loss.
+ Options are 'none', 'mean' and 'sum'. Default: 'mean'.
+ avg_factor (int, optional): Average factor that is used to average
+ the loss. Default: None.
+ ignore_index (int): Specifies a target value that is ignored and
+ does not contribute to the input gradients. When
+ ``avg_non_ignore `` is ``True``, and the ``reduction`` is
+ ``''mean''``, the loss is averaged over non-ignored targets.
+ Defaults: -100.
+ avg_non_ignore (bool): The flag decides to whether the loss is
+ only averaged over non-ignored targets. Default: False.
+ `New in version 0.23.0.`
+ """
+
+ # class_weight is a manual rescaling weight given to each class.
+ # If given, has to be a Tensor of size C element-wise losses
+ loss = F.cross_entropy(
+ pred,
+ label,
+ weight=class_weight,
+ reduction='none',
+ ignore_index=ignore_index)
+
+ # apply weights and do the reduction
+ # average loss over non-ignored elements
+ # pytorch's official cross_entropy average loss over non-ignored elements
+ # refer to https://github.com/pytorch/pytorch/blob/56b43f4fec1f76953f15a627694d4bba34588969/torch/nn/functional.py#L2660 # noqa
+ if (avg_factor is None) and avg_non_ignore and reduction == 'mean':
+ avg_factor = label.numel() - (label == ignore_index).sum().item()
+ if weight is not None:
+ weight = weight.float()
+ loss = weight_reduce_loss(
+ loss, weight=weight, reduction=reduction, avg_factor=avg_factor)
+
+ return loss
+
+
+def _expand_onehot_labels(labels, label_weights, target_shape, ignore_index):
+ """Expand onehot labels to match the size of prediction."""
+ bin_labels = labels.new_zeros(target_shape)
+ valid_mask = (labels >= 0) & (labels != ignore_index)
+ inds = torch.nonzero(valid_mask, as_tuple=True)
+
+ if inds[0].numel() > 0:
+ if labels.dim() == 3:
+ bin_labels[inds[0], labels[valid_mask], inds[1], inds[2]] = 1
+ else:
+ bin_labels[inds[0], labels[valid_mask]] = 1
+
+ valid_mask = valid_mask.unsqueeze(1).expand(target_shape).float()
+
+ if label_weights is None:
+ bin_label_weights = valid_mask
+ else:
+ bin_label_weights = label_weights.unsqueeze(1).expand(target_shape)
+ bin_label_weights = bin_label_weights * valid_mask
+
+ return bin_labels, bin_label_weights, valid_mask
+
+
+def binary_cross_entropy(pred,
+ label,
+ weight=None,
+ reduction='mean',
+ avg_factor=None,
+ class_weight=None,
+ ignore_index=-100,
+ avg_non_ignore=False,
+ **kwargs):
+ """Calculate the binary CrossEntropy loss.
+
+ Args:
+ pred (torch.Tensor): The prediction with shape (N, 1).
+ label (torch.Tensor): The learning label of the prediction.
+ Note: In bce loss, label < 0 is invalid.
+ weight (torch.Tensor, optional): Sample-wise loss weight.
+ reduction (str, optional): The method used to reduce the loss.
+ Options are "none", "mean" and "sum".
+ avg_factor (int, optional): Average factor that is used to average
+ the loss. Defaults to None.
+ class_weight (list[float], optional): The weight for each class.
+ ignore_index (int): The label index to be ignored. Default: -100.
+ avg_non_ignore (bool): The flag decides to whether the loss is
+ only averaged over non-ignored targets. Default: False.
+ `New in version 0.23.0.`
+
+ Returns:
+ torch.Tensor: The calculated loss
+ """
+ if pred.size(1) == 1:
+ # For binary class segmentation, the shape of pred is
+ # [N, 1, H, W] and that of label is [N, H, W].
+ # As the ignore_index often set as 255, so the
+ # binary class label check should mask out
+ # ignore_index
+ assert label[label != ignore_index].max() <= 1, \
+ 'For pred with shape [N, 1, H, W], its label must have at ' \
+ 'most 2 classes'
+ pred = pred.squeeze()
+ if pred.dim() != label.dim():
+ assert (pred.dim() == 2 and label.dim() == 1) or (
+ pred.dim() == 4 and label.dim() == 3), \
+ 'Only pred shape [N, C], label shape [N] or pred shape [N, C, ' \
+ 'H, W], label shape [N, H, W] are supported'
+ # `weight` returned from `_expand_onehot_labels`
+ # has been treated for valid (non-ignore) pixels
+ label, weight, valid_mask = _expand_onehot_labels(
+ label, weight, pred.shape, ignore_index)
+ else:
+ # should mask out the ignored elements
+ valid_mask = ((label >= 0) & (label != ignore_index)).float()
+ if weight is not None:
+ weight = weight * valid_mask
+ else:
+ weight = valid_mask
+ # average loss over non-ignored and valid elements
+ if reduction == 'mean' and avg_factor is None and avg_non_ignore:
+ avg_factor = valid_mask.sum().item()
+
+ loss = F.binary_cross_entropy_with_logits(
+ pred, label.float(), pos_weight=class_weight, reduction='none')
+ # do the reduction for the weighted loss
+ loss = weight_reduce_loss(
+ loss, weight, reduction=reduction, avg_factor=avg_factor)
+
+ return loss
+
+
+def mask_cross_entropy(pred,
+ target,
+ label,
+ reduction='mean',
+ avg_factor=None,
+ class_weight=None,
+ ignore_index=None,
+ **kwargs):
+ """Calculate the CrossEntropy loss for masks.
+
+ Args:
+ pred (torch.Tensor): The prediction with shape (N, C), C is the number
+ of classes.
+ target (torch.Tensor): The learning label of the prediction.
+ label (torch.Tensor): ``label`` indicates the class label of the mask'
+ corresponding object. This will be used to select the mask in the
+ of the class which the object belongs to when the mask prediction
+ if not class-agnostic.
+ reduction (str, optional): The method used to reduce the loss.
+ Options are "none", "mean" and "sum".
+ avg_factor (int, optional): Average factor that is used to average
+ the loss. Defaults to None.
+ class_weight (list[float], optional): The weight for each class.
+ ignore_index (None): Placeholder, to be consistent with other loss.
+ Default: None.
+
+ Returns:
+ torch.Tensor: The calculated loss
+ """
+ assert ignore_index is None, 'BCE loss does not support ignore_index'
+ # TODO: handle these two reserved arguments
+ assert reduction == 'mean' and avg_factor is None
+ num_rois = pred.size()[0]
+ inds = torch.arange(0, num_rois, dtype=torch.long, device=pred.device)
+ pred_slice = pred[inds, label].squeeze(1)
+ return F.binary_cross_entropy_with_logits(
+ pred_slice, target, weight=class_weight, reduction='mean')[None]
+
+
+@LOSSES.register_module()
+class CrossEntropyLoss(nn.Module):
+ """CrossEntropyLoss.
+
+ Args:
+ use_sigmoid (bool, optional): Whether the prediction uses sigmoid
+ of softmax. Defaults to False.
+ use_mask (bool, optional): Whether to use mask cross entropy loss.
+ Defaults to False.
+ reduction (str, optional): . Defaults to 'mean'.
+ Options are "none", "mean" and "sum".
+ class_weight (list[float] | str, optional): Weight of each class. If in
+ str format, read them from a file. Defaults to None.
+ loss_weight (float, optional): Weight of the loss. Defaults to 1.0.
+ loss_name (str, optional): Name of the loss item. If you want this loss
+ item to be included into the backward graph, `loss_` must be the
+ prefix of the name. Defaults to 'loss_ce'.
+ avg_non_ignore (bool): The flag decides to whether the loss is
+ only averaged over non-ignored targets. Default: False.
+ `New in version 0.23.0.`
+ """
+
+ def __init__(self,
+ use_sigmoid=False,
+ use_mask=False,
+ reduction='mean',
+ class_weight=None,
+ loss_weight=1.0,
+ loss_name='loss_ce',
+ avg_non_ignore=False):
+ super(CrossEntropyLoss, self).__init__()
+ assert (use_sigmoid is False) or (use_mask is False)
+ self.use_sigmoid = use_sigmoid
+ self.use_mask = use_mask
+ self.reduction = reduction
+ self.loss_weight = loss_weight
+ self.class_weight = get_class_weight(class_weight)
+ self.avg_non_ignore = avg_non_ignore
+ if not self.avg_non_ignore and self.reduction == 'mean':
+ warnings.warn(
+ 'Default ``avg_non_ignore`` is False, if you would like to '
+ 'ignore the certain label and average loss over non-ignore '
+ 'labels, which is the same with PyTorch official '
+ 'cross_entropy, set ``avg_non_ignore=True``.')
+
+ if self.use_sigmoid:
+ self.cls_criterion = binary_cross_entropy
+ elif self.use_mask:
+ self.cls_criterion = mask_cross_entropy
+ else:
+ self.cls_criterion = cross_entropy
+ self._loss_name = loss_name
+
+ def extra_repr(self):
+ """Extra repr."""
+ s = f'avg_non_ignore={self.avg_non_ignore}'
+ return s
+
+ def forward(self,
+ cls_score,
+ label,
+ weight=None,
+ avg_factor=None,
+ reduction_override=None,
+ ignore_index=-100,
+ **kwargs):
+ """Forward function."""
+ assert reduction_override in (None, 'none', 'mean', 'sum')
+ reduction = (
+ reduction_override if reduction_override else self.reduction)
+ if self.class_weight is not None:
+ class_weight = cls_score.new_tensor(self.class_weight)
+ else:
+ class_weight = None
+ # Note: for BCE loss, label < 0 is invalid.
+ loss_cls = self.loss_weight * self.cls_criterion(
+ cls_score,
+ label,
+ weight,
+ class_weight=class_weight,
+ reduction=reduction,
+ avg_factor=avg_factor,
+ avg_non_ignore=self.avg_non_ignore,
+ ignore_index=ignore_index,
+ **kwargs)
+ return loss_cls
+
+ @property
+ def loss_name(self):
+ """Loss Name.
+
+ This function must be implemented and will return the name of this
+ loss function. This name will be used to combine different loss items
+ by simple sum operation. In addition, if you want this loss item to be
+ included into the backward graph, `loss_` must be the prefix of the
+ name.
+
+ Returns:
+ str: The name of this loss item.
+ """
+ return self._loss_name
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/dice_loss.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/dice_loss.py
new file mode 100644
index 0000000000000000000000000000000000000000..79a3abfc2f633042b065987975a94edc64be06b1
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/dice_loss.py
@@ -0,0 +1,137 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+"""Modified from https://github.com/LikeLy-Journey/SegmenTron/blob/master/
+segmentron/solver/loss.py (Apache-2.0 License)"""
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+
+from ..builder import LOSSES
+from .utils import get_class_weight, weighted_loss
+
+
+@weighted_loss
+def dice_loss(pred,
+ target,
+ valid_mask,
+ smooth=1,
+ exponent=2,
+ class_weight=None,
+ ignore_index=255):
+ assert pred.shape[0] == target.shape[0]
+ total_loss = 0
+ num_classes = pred.shape[1]
+ for i in range(num_classes):
+ if i != ignore_index:
+ dice_loss = binary_dice_loss(
+ pred[:, i],
+ target[..., i],
+ valid_mask=valid_mask,
+ smooth=smooth,
+ exponent=exponent)
+ if class_weight is not None:
+ dice_loss *= class_weight[i]
+ total_loss += dice_loss
+ return total_loss / num_classes
+
+
+@weighted_loss
+def binary_dice_loss(pred, target, valid_mask, smooth=1, exponent=2, **kwards):
+ assert pred.shape[0] == target.shape[0]
+ pred = pred.reshape(pred.shape[0], -1)
+ target = target.reshape(target.shape[0], -1)
+ valid_mask = valid_mask.reshape(valid_mask.shape[0], -1)
+
+ num = torch.sum(torch.mul(pred, target) * valid_mask, dim=1) * 2 + smooth
+ den = torch.sum(pred.pow(exponent) + target.pow(exponent), dim=1) + smooth
+
+ return 1 - num / den
+
+
+@LOSSES.register_module()
+class DiceLoss(nn.Module):
+ """DiceLoss.
+
+ This loss is proposed in `V-Net: Fully Convolutional Neural Networks for
+ Volumetric Medical Image Segmentation `_.
+
+ Args:
+ smooth (float): A float number to smooth loss, and avoid NaN error.
+ Default: 1
+ exponent (float): An float number to calculate denominator
+ value: \\sum{x^exponent} + \\sum{y^exponent}. Default: 2.
+ reduction (str, optional): The method used to reduce the loss. Options
+ are "none", "mean" and "sum". This parameter only works when
+ per_image is True. Default: 'mean'.
+ class_weight (list[float] | str, optional): Weight of each class. If in
+ str format, read them from a file. Defaults to None.
+ loss_weight (float, optional): Weight of the loss. Default to 1.0.
+ ignore_index (int | None): The label index to be ignored. Default: 255.
+ loss_name (str, optional): Name of the loss item. If you want this loss
+ item to be included into the backward graph, `loss_` must be the
+ prefix of the name. Defaults to 'loss_dice'.
+ """
+
+ def __init__(self,
+ smooth=1,
+ exponent=2,
+ reduction='mean',
+ class_weight=None,
+ loss_weight=1.0,
+ ignore_index=255,
+ loss_name='loss_dice',
+ **kwards):
+ super(DiceLoss, self).__init__()
+ self.smooth = smooth
+ self.exponent = exponent
+ self.reduction = reduction
+ self.class_weight = get_class_weight(class_weight)
+ self.loss_weight = loss_weight
+ self.ignore_index = ignore_index
+ self._loss_name = loss_name
+
+ def forward(self,
+ pred,
+ target,
+ avg_factor=None,
+ reduction_override=None,
+ **kwards):
+ assert reduction_override in (None, 'none', 'mean', 'sum')
+ reduction = (
+ reduction_override if reduction_override else self.reduction)
+ if self.class_weight is not None:
+ class_weight = pred.new_tensor(self.class_weight)
+ else:
+ class_weight = None
+
+ pred = F.softmax(pred, dim=1)
+ num_classes = pred.shape[1]
+ one_hot_target = F.one_hot(
+ torch.clamp(target.long(), 0, num_classes - 1),
+ num_classes=num_classes)
+ valid_mask = (target != self.ignore_index).long()
+
+ loss = self.loss_weight * dice_loss(
+ pred,
+ one_hot_target,
+ valid_mask=valid_mask,
+ reduction=reduction,
+ avg_factor=avg_factor,
+ smooth=self.smooth,
+ exponent=self.exponent,
+ class_weight=class_weight,
+ ignore_index=self.ignore_index)
+ return loss
+
+ @property
+ def loss_name(self):
+ """Loss Name.
+
+ This function must be implemented and will return the name of this
+ loss function. This name will be used to combine different loss items
+ by simple sum operation. In addition, if you want this loss item to be
+ included into the backward graph, `loss_` must be the prefix of the
+ name.
+ Returns:
+ str: The name of this loss item.
+ """
+ return self._loss_name
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/focal_loss.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/focal_loss.py
new file mode 100644
index 0000000000000000000000000000000000000000..af1c711dfbce65907e77d37e7a8f0aa9bd2e5e3a
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/focal_loss.py
@@ -0,0 +1,327 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+# Modified from https://github.com/open-mmlab/mmdetection
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+from mmcv.ops import sigmoid_focal_loss as _sigmoid_focal_loss
+
+from ..builder import LOSSES
+from .utils import weight_reduce_loss
+
+
+# This method is used when cuda is not available
+def py_sigmoid_focal_loss(pred,
+ target,
+ one_hot_target=None,
+ weight=None,
+ gamma=2.0,
+ alpha=0.5,
+ class_weight=None,
+ valid_mask=None,
+ reduction='mean',
+ avg_factor=None):
+ """PyTorch version of `Focal Loss `_.
+
+ Args:
+ pred (torch.Tensor): The prediction with shape (N, C), C is the
+ number of classes
+ target (torch.Tensor): The learning label of the prediction with
+ shape (N, C)
+ one_hot_target (None): Placeholder. It should be None.
+ weight (torch.Tensor, optional): Sample-wise loss weight.
+ gamma (float, optional): The gamma for calculating the modulating
+ factor. Defaults to 2.0.
+ alpha (float | list[float], optional): A balanced form for Focal Loss.
+ Defaults to 0.5.
+ class_weight (list[float], optional): Weight of each class.
+ Defaults to None.
+ valid_mask (torch.Tensor, optional): A mask uses 1 to mark the valid
+ samples and uses 0 to mark the ignored samples. Default: None.
+ reduction (str, optional): The method used to reduce the loss into
+ a scalar. Defaults to 'mean'.
+ avg_factor (int, optional): Average factor that is used to average
+ the loss. Defaults to None.
+ """
+ if isinstance(alpha, list):
+ alpha = pred.new_tensor(alpha)
+ pred_sigmoid = pred.sigmoid()
+ target = target.type_as(pred)
+ one_minus_pt = (1 - pred_sigmoid) * target + pred_sigmoid * (1 - target)
+ focal_weight = (alpha * target + (1 - alpha) *
+ (1 - target)) * one_minus_pt.pow(gamma)
+
+ loss = F.binary_cross_entropy_with_logits(
+ pred, target, reduction='none') * focal_weight
+ final_weight = torch.ones(1, pred.size(1)).type_as(loss)
+ if weight is not None:
+ if weight.shape != loss.shape and weight.size(0) == loss.size(0):
+ # For most cases, weight is of shape (N, ),
+ # which means it does not have the second axis num_class
+ weight = weight.view(-1, 1)
+ assert weight.dim() == loss.dim()
+ final_weight = final_weight * weight
+ if class_weight is not None:
+ final_weight = final_weight * pred.new_tensor(class_weight)
+ if valid_mask is not None:
+ final_weight = final_weight * valid_mask
+ loss = weight_reduce_loss(loss, final_weight, reduction, avg_factor)
+ return loss
+
+
+def sigmoid_focal_loss(pred,
+ target,
+ one_hot_target,
+ weight=None,
+ gamma=2.0,
+ alpha=0.5,
+ class_weight=None,
+ valid_mask=None,
+ reduction='mean',
+ avg_factor=None):
+ r"""A warpper of cuda version `Focal Loss
+ `_.
+ Args:
+ pred (torch.Tensor): The prediction with shape (N, C), C is the number
+ of classes.
+ target (torch.Tensor): The learning label of the prediction. It's shape
+ should be (N, )
+ one_hot_target (torch.Tensor): The learning label with shape (N, C)
+ weight (torch.Tensor, optional): Sample-wise loss weight.
+ gamma (float, optional): The gamma for calculating the modulating
+ factor. Defaults to 2.0.
+ alpha (float | list[float], optional): A balanced form for Focal Loss.
+ Defaults to 0.5.
+ class_weight (list[float], optional): Weight of each class.
+ Defaults to None.
+ valid_mask (torch.Tensor, optional): A mask uses 1 to mark the valid
+ samples and uses 0 to mark the ignored samples. Default: None.
+ reduction (str, optional): The method used to reduce the loss into
+ a scalar. Defaults to 'mean'. Options are "none", "mean" and "sum".
+ avg_factor (int, optional): Average factor that is used to average
+ the loss. Defaults to None.
+ """
+ # Function.apply does not accept keyword arguments, so the decorator
+ # "weighted_loss" is not applicable
+ final_weight = torch.ones(1, pred.size(1)).type_as(pred)
+ if isinstance(alpha, list):
+ # _sigmoid_focal_loss doesn't accept alpha of list type. Therefore, if
+ # a list is given, we set the input alpha as 0.5. This means setting
+ # equal weight for foreground class and background class. By
+ # multiplying the loss by 2, the effect of setting alpha as 0.5 is
+ # undone. The alpha of type list is used to regulate the loss in the
+ # post-processing process.
+ loss = _sigmoid_focal_loss(pred.contiguous(), target.contiguous(),
+ gamma, 0.5, None, 'none') * 2
+ alpha = pred.new_tensor(alpha)
+ final_weight = final_weight * (
+ alpha * one_hot_target + (1 - alpha) * (1 - one_hot_target))
+ else:
+ loss = _sigmoid_focal_loss(pred.contiguous(), target.contiguous(),
+ gamma, alpha, None, 'none')
+ if weight is not None:
+ if weight.shape != loss.shape and weight.size(0) == loss.size(0):
+ # For most cases, weight is of shape (N, ),
+ # which means it does not have the second axis num_class
+ weight = weight.view(-1, 1)
+ assert weight.dim() == loss.dim()
+ final_weight = final_weight * weight
+ if class_weight is not None:
+ final_weight = final_weight * pred.new_tensor(class_weight)
+ if valid_mask is not None:
+ final_weight = final_weight * valid_mask
+ loss = weight_reduce_loss(loss, final_weight, reduction, avg_factor)
+ return loss
+
+
+@LOSSES.register_module()
+class FocalLoss(nn.Module):
+
+ def __init__(self,
+ use_sigmoid=True,
+ gamma=2.0,
+ alpha=0.5,
+ reduction='mean',
+ class_weight=None,
+ loss_weight=1.0,
+ loss_name='loss_focal'):
+ """`Focal Loss `_
+ Args:
+ use_sigmoid (bool, optional): Whether to the prediction is
+ used for sigmoid or softmax. Defaults to True.
+ gamma (float, optional): The gamma for calculating the modulating
+ factor. Defaults to 2.0.
+ alpha (float | list[float], optional): A balanced form for Focal
+ Loss. Defaults to 0.5. When a list is provided, the length
+ of the list should be equal to the number of classes.
+ Please be careful that this parameter is not the
+ class-wise weight but the weight of a binary classification
+ problem. This binary classification problem regards the
+ pixels which belong to one class as the foreground
+ and the other pixels as the background, each element in
+ the list is the weight of the corresponding foreground class.
+ The value of alpha or each element of alpha should be a float
+ in the interval [0, 1]. If you want to specify the class-wise
+ weight, please use `class_weight` parameter.
+ reduction (str, optional): The method used to reduce the loss into
+ a scalar. Defaults to 'mean'. Options are "none", "mean" and
+ "sum".
+ class_weight (list[float], optional): Weight of each class.
+ Defaults to None.
+ loss_weight (float, optional): Weight of loss. Defaults to 1.0.
+ loss_name (str, optional): Name of the loss item. If you want this
+ loss item to be included into the backward graph, `loss_` must
+ be the prefix of the name. Defaults to 'loss_focal'.
+ """
+ super(FocalLoss, self).__init__()
+ assert use_sigmoid is True, \
+ 'AssertionError: Only sigmoid focal loss supported now.'
+ assert reduction in ('none', 'mean', 'sum'), \
+ "AssertionError: reduction should be 'none', 'mean' or " \
+ "'sum'"
+ assert isinstance(alpha, (float, list)), \
+ 'AssertionError: alpha should be of type float'
+ assert isinstance(gamma, float), \
+ 'AssertionError: gamma should be of type float'
+ assert isinstance(loss_weight, float), \
+ 'AssertionError: loss_weight should be of type float'
+ assert isinstance(loss_name, str), \
+ 'AssertionError: loss_name should be of type str'
+ assert isinstance(class_weight, list) or class_weight is None, \
+ 'AssertionError: class_weight must be None or of type list'
+ self.use_sigmoid = use_sigmoid
+ self.gamma = gamma
+ self.alpha = alpha
+ self.reduction = reduction
+ self.class_weight = class_weight
+ self.loss_weight = loss_weight
+ self._loss_name = loss_name
+
+ def forward(self,
+ pred,
+ target,
+ weight=None,
+ avg_factor=None,
+ reduction_override=None,
+ ignore_index=255,
+ **kwargs):
+ """Forward function.
+
+ Args:
+ pred (torch.Tensor): The prediction with shape
+ (N, C) where C = number of classes, or
+ (N, C, d_1, d_2, ..., d_K) with K≥1 in the
+ case of K-dimensional loss.
+ target (torch.Tensor): The ground truth. If containing class
+ indices, shape (N) where each value is 0≤targets[i]≤C−1,
+ or (N, d_1, d_2, ..., d_K) with K≥1 in the case of
+ K-dimensional loss. If containing class probabilities,
+ same shape as the input.
+ weight (torch.Tensor, optional): The weight of loss for each
+ prediction. Defaults to None.
+ avg_factor (int, optional): Average factor that is used to
+ average the loss. Defaults to None.
+ reduction_override (str, optional): The reduction method used
+ to override the original reduction method of the loss.
+ Options are "none", "mean" and "sum".
+ ignore_index (int, optional): The label index to be ignored.
+ Default: 255
+ Returns:
+ torch.Tensor: The calculated loss
+ """
+ assert isinstance(ignore_index, int), \
+ 'ignore_index must be of type int'
+ assert reduction_override in (None, 'none', 'mean', 'sum'), \
+ "AssertionError: reduction should be 'none', 'mean' or " \
+ "'sum'"
+ assert pred.shape == target.shape or \
+ (pred.size(0) == target.size(0) and
+ pred.shape[2:] == target.shape[1:]), \
+ "The shape of pred doesn't match the shape of target"
+
+ original_shape = pred.shape
+
+ # [B, C, d_1, d_2, ..., d_k] -> [C, B, d_1, d_2, ..., d_k]
+ pred = pred.transpose(0, 1)
+ # [C, B, d_1, d_2, ..., d_k] -> [C, N]
+ pred = pred.reshape(pred.size(0), -1)
+ # [C, N] -> [N, C]
+ pred = pred.transpose(0, 1).contiguous()
+
+ if original_shape == target.shape:
+ # target with shape [B, C, d_1, d_2, ...]
+ # transform it's shape into [N, C]
+ # [B, C, d_1, d_2, ...] -> [C, B, d_1, d_2, ..., d_k]
+ target = target.transpose(0, 1)
+ # [C, B, d_1, d_2, ..., d_k] -> [C, N]
+ target = target.reshape(target.size(0), -1)
+ # [C, N] -> [N, C]
+ target = target.transpose(0, 1).contiguous()
+ else:
+ # target with shape [B, d_1, d_2, ...]
+ # transform it's shape into [N, ]
+ target = target.view(-1).contiguous()
+ valid_mask = (target != ignore_index).view(-1, 1)
+ # avoid raising error when using F.one_hot()
+ target = torch.where(target == ignore_index, target.new_tensor(0),
+ target)
+
+ reduction = (
+ reduction_override if reduction_override else self.reduction)
+ if self.use_sigmoid:
+ num_classes = pred.size(1)
+ if torch.cuda.is_available() and pred.is_cuda:
+ if target.dim() == 1:
+ one_hot_target = F.one_hot(target, num_classes=num_classes)
+ else:
+ one_hot_target = target
+ target = target.argmax(dim=1)
+ valid_mask = (target != ignore_index).view(-1, 1)
+ calculate_loss_func = sigmoid_focal_loss
+ else:
+ one_hot_target = None
+ if target.dim() == 1:
+ target = F.one_hot(target, num_classes=num_classes)
+ else:
+ valid_mask = (target.argmax(dim=1) != ignore_index).view(
+ -1, 1)
+ calculate_loss_func = py_sigmoid_focal_loss
+
+ loss_cls = self.loss_weight * calculate_loss_func(
+ pred,
+ target,
+ one_hot_target,
+ weight,
+ gamma=self.gamma,
+ alpha=self.alpha,
+ class_weight=self.class_weight,
+ valid_mask=valid_mask,
+ reduction=reduction,
+ avg_factor=avg_factor)
+
+ if reduction == 'none':
+ # [N, C] -> [C, N]
+ loss_cls = loss_cls.transpose(0, 1)
+ # [C, N] -> [C, B, d1, d2, ...]
+ # original_shape: [B, C, d1, d2, ...]
+ loss_cls = loss_cls.reshape(original_shape[1],
+ original_shape[0],
+ *original_shape[2:])
+ # [C, B, d1, d2, ...] -> [B, C, d1, d2, ...]
+ loss_cls = loss_cls.transpose(0, 1).contiguous()
+ else:
+ raise NotImplementedError
+ return loss_cls
+
+ @property
+ def loss_name(self):
+ """Loss Name.
+
+ This function must be implemented and will return the name of this
+ loss function. This name will be used to combine different loss items
+ by simple sum operation. In addition, if you want this loss item to be
+ included into the backward graph, `loss_` must be the prefix of the
+ name.
+ Returns:
+ str: The name of this loss item.
+ """
+ return self._loss_name
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/lovasz_loss.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/lovasz_loss.py
new file mode 100644
index 0000000000000000000000000000000000000000..2bb0fad3931ea7d6140beca8b32a09379fbd7670
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/lovasz_loss.py
@@ -0,0 +1,323 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+"""Modified from https://github.com/bermanmaxim/LovaszSoftmax/blob/master/pytor
+ch/lovasz_losses.py Lovasz-Softmax and Jaccard hinge loss in PyTorch Maxim
+Berman 2018 ESAT-PSI KU Leuven (MIT License)"""
+
+import mmcv
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+
+from ..builder import LOSSES
+from .utils import get_class_weight, weight_reduce_loss
+
+
+def lovasz_grad(gt_sorted):
+ """Computes gradient of the Lovasz extension w.r.t sorted errors.
+
+ See Alg. 1 in paper.
+ """
+ p = len(gt_sorted)
+ gts = gt_sorted.sum()
+ intersection = gts - gt_sorted.float().cumsum(0)
+ union = gts + (1 - gt_sorted).float().cumsum(0)
+ jaccard = 1. - intersection / union
+ if p > 1: # cover 1-pixel case
+ jaccard[1:p] = jaccard[1:p] - jaccard[0:-1]
+ return jaccard
+
+
+def flatten_binary_logits(logits, labels, ignore_index=None):
+ """Flattens predictions in the batch (binary case) Remove labels equal to
+ 'ignore_index'."""
+ logits = logits.view(-1)
+ labels = labels.view(-1)
+ if ignore_index is None:
+ return logits, labels
+ valid = (labels != ignore_index)
+ vlogits = logits[valid]
+ vlabels = labels[valid]
+ return vlogits, vlabels
+
+
+def flatten_probs(probs, labels, ignore_index=None):
+ """Flattens predictions in the batch."""
+ if probs.dim() == 3:
+ # assumes output of a sigmoid layer
+ B, H, W = probs.size()
+ probs = probs.view(B, 1, H, W)
+ B, C, H, W = probs.size()
+ probs = probs.permute(0, 2, 3, 1).contiguous().view(-1, C) # B*H*W, C=P,C
+ labels = labels.view(-1)
+ if ignore_index is None:
+ return probs, labels
+ valid = (labels != ignore_index)
+ vprobs = probs[valid.nonzero().squeeze()]
+ vlabels = labels[valid]
+ return vprobs, vlabels
+
+
+def lovasz_hinge_flat(logits, labels):
+ """Binary Lovasz hinge loss.
+
+ Args:
+ logits (torch.Tensor): [P], logits at each prediction
+ (between -infty and +infty).
+ labels (torch.Tensor): [P], binary ground truth labels (0 or 1).
+
+ Returns:
+ torch.Tensor: The calculated loss.
+ """
+ if len(labels) == 0:
+ # only void pixels, the gradients should be 0
+ return logits.sum() * 0.
+ signs = 2. * labels.float() - 1.
+ errors = (1. - logits * signs)
+ errors_sorted, perm = torch.sort(errors, dim=0, descending=True)
+ perm = perm.data
+ gt_sorted = labels[perm]
+ grad = lovasz_grad(gt_sorted)
+ loss = torch.dot(F.relu(errors_sorted), grad)
+ return loss
+
+
+def lovasz_hinge(logits,
+ labels,
+ classes='present',
+ per_image=False,
+ class_weight=None,
+ reduction='mean',
+ avg_factor=None,
+ ignore_index=255):
+ """Binary Lovasz hinge loss.
+
+ Args:
+ logits (torch.Tensor): [B, H, W], logits at each pixel
+ (between -infty and +infty).
+ labels (torch.Tensor): [B, H, W], binary ground truth masks (0 or 1).
+ classes (str | list[int], optional): Placeholder, to be consistent with
+ other loss. Default: None.
+ per_image (bool, optional): If per_image is True, compute the loss per
+ image instead of per batch. Default: False.
+ class_weight (list[float], optional): Placeholder, to be consistent
+ with other loss. Default: None.
+ reduction (str, optional): The method used to reduce the loss. Options
+ are "none", "mean" and "sum". This parameter only works when
+ per_image is True. Default: 'mean'.
+ avg_factor (int, optional): Average factor that is used to average
+ the loss. This parameter only works when per_image is True.
+ Default: None.
+ ignore_index (int | None): The label index to be ignored. Default: 255.
+
+ Returns:
+ torch.Tensor: The calculated loss.
+ """
+ if per_image:
+ loss = [
+ lovasz_hinge_flat(*flatten_binary_logits(
+ logit.unsqueeze(0), label.unsqueeze(0), ignore_index))
+ for logit, label in zip(logits, labels)
+ ]
+ loss = weight_reduce_loss(
+ torch.stack(loss), None, reduction, avg_factor)
+ else:
+ loss = lovasz_hinge_flat(
+ *flatten_binary_logits(logits, labels, ignore_index))
+ return loss
+
+
+def lovasz_softmax_flat(probs, labels, classes='present', class_weight=None):
+ """Multi-class Lovasz-Softmax loss.
+
+ Args:
+ probs (torch.Tensor): [P, C], class probabilities at each prediction
+ (between 0 and 1).
+ labels (torch.Tensor): [P], ground truth labels (between 0 and C - 1).
+ classes (str | list[int], optional): Classes chosen to calculate loss.
+ 'all' for all classes, 'present' for classes present in labels, or
+ a list of classes to average. Default: 'present'.
+ class_weight (list[float], optional): The weight for each class.
+ Default: None.
+
+ Returns:
+ torch.Tensor: The calculated loss.
+ """
+ if probs.numel() == 0:
+ # only void pixels, the gradients should be 0
+ return probs * 0.
+ C = probs.size(1)
+ losses = []
+ class_to_sum = list(range(C)) if classes in ['all', 'present'] else classes
+ for c in class_to_sum:
+ fg = (labels == c).float() # foreground for class c
+ if (classes == 'present' and fg.sum() == 0):
+ continue
+ if C == 1:
+ if len(classes) > 1:
+ raise ValueError('Sigmoid output possible only with 1 class')
+ class_pred = probs[:, 0]
+ else:
+ class_pred = probs[:, c]
+ errors = (fg - class_pred).abs()
+ errors_sorted, perm = torch.sort(errors, 0, descending=True)
+ perm = perm.data
+ fg_sorted = fg[perm]
+ loss = torch.dot(errors_sorted, lovasz_grad(fg_sorted))
+ if class_weight is not None:
+ loss *= class_weight[c]
+ losses.append(loss)
+ return torch.stack(losses).mean()
+
+
+def lovasz_softmax(probs,
+ labels,
+ classes='present',
+ per_image=False,
+ class_weight=None,
+ reduction='mean',
+ avg_factor=None,
+ ignore_index=255):
+ """Multi-class Lovasz-Softmax loss.
+
+ Args:
+ probs (torch.Tensor): [B, C, H, W], class probabilities at each
+ prediction (between 0 and 1).
+ labels (torch.Tensor): [B, H, W], ground truth labels (between 0 and
+ C - 1).
+ classes (str | list[int], optional): Classes chosen to calculate loss.
+ 'all' for all classes, 'present' for classes present in labels, or
+ a list of classes to average. Default: 'present'.
+ per_image (bool, optional): If per_image is True, compute the loss per
+ image instead of per batch. Default: False.
+ class_weight (list[float], optional): The weight for each class.
+ Default: None.
+ reduction (str, optional): The method used to reduce the loss. Options
+ are "none", "mean" and "sum". This parameter only works when
+ per_image is True. Default: 'mean'.
+ avg_factor (int, optional): Average factor that is used to average
+ the loss. This parameter only works when per_image is True.
+ Default: None.
+ ignore_index (int | None): The label index to be ignored. Default: 255.
+
+ Returns:
+ torch.Tensor: The calculated loss.
+ """
+
+ if per_image:
+ loss = [
+ lovasz_softmax_flat(
+ *flatten_probs(
+ prob.unsqueeze(0), label.unsqueeze(0), ignore_index),
+ classes=classes,
+ class_weight=class_weight)
+ for prob, label in zip(probs, labels)
+ ]
+ loss = weight_reduce_loss(
+ torch.stack(loss), None, reduction, avg_factor)
+ else:
+ loss = lovasz_softmax_flat(
+ *flatten_probs(probs, labels, ignore_index),
+ classes=classes,
+ class_weight=class_weight)
+ return loss
+
+
+@LOSSES.register_module()
+class LovaszLoss(nn.Module):
+ """LovaszLoss.
+
+ This loss is proposed in `The Lovasz-Softmax loss: A tractable surrogate
+ for the optimization of the intersection-over-union measure in neural
+ networks `_.
+
+ Args:
+ loss_type (str, optional): Binary or multi-class loss.
+ Default: 'multi_class'. Options are "binary" and "multi_class".
+ classes (str | list[int], optional): Classes chosen to calculate loss.
+ 'all' for all classes, 'present' for classes present in labels, or
+ a list of classes to average. Default: 'present'.
+ per_image (bool, optional): If per_image is True, compute the loss per
+ image instead of per batch. Default: False.
+ reduction (str, optional): The method used to reduce the loss. Options
+ are "none", "mean" and "sum". This parameter only works when
+ per_image is True. Default: 'mean'.
+ class_weight (list[float] | str, optional): Weight of each class. If in
+ str format, read them from a file. Defaults to None.
+ loss_weight (float, optional): Weight of the loss. Defaults to 1.0.
+ loss_name (str, optional): Name of the loss item. If you want this loss
+ item to be included into the backward graph, `loss_` must be the
+ prefix of the name. Defaults to 'loss_lovasz'.
+ """
+
+ def __init__(self,
+ loss_type='multi_class',
+ classes='present',
+ per_image=False,
+ reduction='mean',
+ class_weight=None,
+ loss_weight=1.0,
+ loss_name='loss_lovasz'):
+ super(LovaszLoss, self).__init__()
+ assert loss_type in ('binary', 'multi_class'), "loss_type should be \
+ 'binary' or 'multi_class'."
+
+ if loss_type == 'binary':
+ self.cls_criterion = lovasz_hinge
+ else:
+ self.cls_criterion = lovasz_softmax
+ assert classes in ('all', 'present') or mmcv.is_list_of(classes, int)
+ if not per_image:
+ assert reduction == 'none', "reduction should be 'none' when \
+ per_image is False."
+
+ self.classes = classes
+ self.per_image = per_image
+ self.reduction = reduction
+ self.loss_weight = loss_weight
+ self.class_weight = get_class_weight(class_weight)
+ self._loss_name = loss_name
+
+ def forward(self,
+ cls_score,
+ label,
+ weight=None,
+ avg_factor=None,
+ reduction_override=None,
+ **kwargs):
+ """Forward function."""
+ assert reduction_override in (None, 'none', 'mean', 'sum')
+ reduction = (
+ reduction_override if reduction_override else self.reduction)
+ if self.class_weight is not None:
+ class_weight = cls_score.new_tensor(self.class_weight)
+ else:
+ class_weight = None
+
+ # if multi-class loss, transform logits to probs
+ if self.cls_criterion == lovasz_softmax:
+ cls_score = F.softmax(cls_score, dim=1)
+
+ loss_cls = self.loss_weight * self.cls_criterion(
+ cls_score,
+ label,
+ self.classes,
+ self.per_image,
+ class_weight=class_weight,
+ reduction=reduction,
+ avg_factor=avg_factor,
+ **kwargs)
+ return loss_cls
+
+ @property
+ def loss_name(self):
+ """Loss Name.
+
+ This function must be implemented and will return the name of this
+ loss function. This name will be used to combine different loss items
+ by simple sum operation. In addition, if you want this loss item to be
+ included into the backward graph, `loss_` must be the prefix of the
+ name.
+ Returns:
+ str: The name of this loss item.
+ """
+ return self._loss_name
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/utils.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..621f57c746c4de0abc3ad7a3c2ad35ef65c2fe32
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/losses/utils.py
@@ -0,0 +1,126 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import functools
+
+import mmcv
+import numpy as np
+import torch
+import torch.nn.functional as F
+
+
+def get_class_weight(class_weight):
+ """Get class weight for loss function.
+
+ Args:
+ class_weight (list[float] | str | None): If class_weight is a str,
+ take it as a file name and read from it.
+ """
+ if isinstance(class_weight, str):
+ # take it as a file path
+ if class_weight.endswith('.npy'):
+ class_weight = np.load(class_weight)
+ else:
+ # pkl, json or yaml
+ class_weight = mmcv.load(class_weight)
+
+ return class_weight
+
+
+def reduce_loss(loss, reduction):
+ """Reduce loss as specified.
+
+ Args:
+ loss (Tensor): Elementwise loss tensor.
+ reduction (str): Options are "none", "mean" and "sum".
+
+ Return:
+ Tensor: Reduced loss tensor.
+ """
+ reduction_enum = F._Reduction.get_enum(reduction)
+ # none: 0, elementwise_mean:1, sum: 2
+ if reduction_enum == 0:
+ return loss
+ elif reduction_enum == 1:
+ return loss.mean()
+ elif reduction_enum == 2:
+ return loss.sum()
+
+
+def weight_reduce_loss(loss, weight=None, reduction='mean', avg_factor=None):
+ """Apply element-wise weight and reduce loss.
+
+ Args:
+ loss (Tensor): Element-wise loss.
+ weight (Tensor): Element-wise weights.
+ reduction (str): Same as built-in losses of PyTorch.
+ avg_factor (float): Average factor when computing the mean of losses.
+
+ Returns:
+ Tensor: Processed loss values.
+ """
+ # if weight is specified, apply element-wise weight
+ if weight is not None:
+ assert weight.dim() == loss.dim()
+ if weight.dim() > 1:
+ assert weight.size(1) == 1 or weight.size(1) == loss.size(1)
+ loss = loss * weight
+
+ # if avg_factor is not specified, just reduce the loss
+ if avg_factor is None:
+ loss = reduce_loss(loss, reduction)
+ else:
+ # if reduction is mean, then average the loss by avg_factor
+ if reduction == 'mean':
+ # Avoid causing ZeroDivisionError when avg_factor is 0.0,
+ # i.e., all labels of an image belong to ignore index.
+ eps = torch.finfo(torch.float32).eps
+ loss = loss.sum() / (avg_factor + eps)
+ # if reduction is 'none', then do nothing, otherwise raise an error
+ elif reduction != 'none':
+ raise ValueError('avg_factor can not be used with reduction="sum"')
+ return loss
+
+
+def weighted_loss(loss_func):
+ """Create a weighted version of a given loss function.
+
+ To use this decorator, the loss function must have the signature like
+ `loss_func(pred, target, **kwargs)`. The function only needs to compute
+ element-wise loss without any reduction. This decorator will add weight
+ and reduction arguments to the function. The decorated function will have
+ the signature like `loss_func(pred, target, weight=None, reduction='mean',
+ avg_factor=None, **kwargs)`.
+
+ :Example:
+
+ >>> import torch
+ >>> @weighted_loss
+ >>> def l1_loss(pred, target):
+ >>> return (pred - target).abs()
+
+ >>> pred = torch.Tensor([0, 2, 3])
+ >>> target = torch.Tensor([1, 1, 1])
+ >>> weight = torch.Tensor([1, 0, 1])
+
+ >>> l1_loss(pred, target)
+ tensor(1.3333)
+ >>> l1_loss(pred, target, weight)
+ tensor(1.)
+ >>> l1_loss(pred, target, reduction='none')
+ tensor([1., 1., 2.])
+ >>> l1_loss(pred, target, weight, avg_factor=2)
+ tensor(1.5000)
+ """
+
+ @functools.wraps(loss_func)
+ def wrapper(pred,
+ target,
+ weight=None,
+ reduction='mean',
+ avg_factor=None,
+ **kwargs):
+ # get element-wise loss
+ loss = loss_func(pred, target, **kwargs)
+ loss = weight_reduce_loss(loss, weight, reduction, avg_factor)
+ return loss
+
+ return wrapper
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..ff03186a92b78f942e79cff9eec9f5e2784c359a
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/__init__.py
@@ -0,0 +1,11 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .featurepyramid import Feature2Pyramid
+from .fpn import FPN
+from .ic_neck import ICNeck
+from .jpu import JPU
+from .mla_neck import MLANeck
+from .multilevel_neck import MultiLevelNeck
+
+__all__ = [
+ 'FPN', 'MultiLevelNeck', 'MLANeck', 'ICNeck', 'JPU', 'Feature2Pyramid'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/featurepyramid.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/featurepyramid.py
new file mode 100644
index 0000000000000000000000000000000000000000..82a00ceb1c4fa792538143f7af86b957822cce4d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/featurepyramid.py
@@ -0,0 +1,67 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch.nn as nn
+from mmcv.cnn import build_norm_layer
+
+from ..builder import NECKS
+
+
+@NECKS.register_module()
+class Feature2Pyramid(nn.Module):
+ """Feature2Pyramid.
+
+ A neck structure connect ViT backbone and decoder_heads.
+
+ Args:
+ embed_dims (int): Embedding dimension.
+ rescales (list[float]): Different sampling multiples were
+ used to obtain pyramid features. Default: [4, 2, 1, 0.5].
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='SyncBN', requires_grad=True).
+ """
+
+ def __init__(self,
+ embed_dim,
+ rescales=[4, 2, 1, 0.5],
+ norm_cfg=dict(type='SyncBN', requires_grad=True)):
+ super(Feature2Pyramid, self).__init__()
+ self.rescales = rescales
+ self.upsample_4x = None
+ for k in self.rescales:
+ if k == 4:
+ self.upsample_4x = nn.Sequential(
+ nn.ConvTranspose2d(
+ embed_dim, embed_dim, kernel_size=2, stride=2),
+ build_norm_layer(norm_cfg, embed_dim)[1],
+ nn.GELU(),
+ nn.ConvTranspose2d(
+ embed_dim, embed_dim, kernel_size=2, stride=2),
+ )
+ elif k == 2:
+ self.upsample_2x = nn.Sequential(
+ nn.ConvTranspose2d(
+ embed_dim, embed_dim, kernel_size=2, stride=2))
+ elif k == 1:
+ self.identity = nn.Identity()
+ elif k == 0.5:
+ self.downsample_2x = nn.MaxPool2d(kernel_size=2, stride=2)
+ elif k == 0.25:
+ self.downsample_4x = nn.MaxPool2d(kernel_size=4, stride=4)
+ else:
+ raise KeyError(f'invalid {k} for feature2pyramid')
+
+ def forward(self, inputs):
+ assert len(inputs) == len(self.rescales)
+ outputs = []
+ if self.upsample_4x is not None:
+ ops = [
+ self.upsample_4x, self.upsample_2x, self.identity,
+ self.downsample_2x
+ ]
+ else:
+ ops = [
+ self.upsample_2x, self.identity, self.downsample_2x,
+ self.downsample_4x
+ ]
+ for i in range(len(inputs)):
+ outputs.append(ops[i](inputs[i]))
+ return tuple(outputs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/fpn.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/fpn.py
new file mode 100644
index 0000000000000000000000000000000000000000..6997de9d4428a0625241b55c6d509afd8e2b515a
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/fpn.py
@@ -0,0 +1,213 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch.nn as nn
+import torch.nn.functional as F
+from mmcv.cnn import ConvModule
+from mmcv.runner import BaseModule, auto_fp16
+
+from mmseg.ops import resize
+from ..builder import NECKS
+
+
+@NECKS.register_module()
+class FPN(BaseModule):
+ """Feature Pyramid Network.
+
+ This neck is the implementation of `Feature Pyramid Networks for Object
+ Detection `_.
+
+ Args:
+ in_channels (list[int]): Number of input channels per scale.
+ out_channels (int): Number of output channels (used at each scale).
+ num_outs (int): Number of output scales.
+ start_level (int): Index of the start input backbone level used to
+ build the feature pyramid. Default: 0.
+ end_level (int): Index of the end input backbone level (exclusive) to
+ build the feature pyramid. Default: -1, which means the last level.
+ add_extra_convs (bool | str): If bool, it decides whether to add conv
+ layers on top of the original feature maps. Default to False.
+ If True, its actual mode is specified by `extra_convs_on_inputs`.
+ If str, it specifies the source feature map of the extra convs.
+ Only the following options are allowed
+
+ - 'on_input': Last feat map of neck inputs (i.e. backbone feature).
+ - 'on_lateral': Last feature map after lateral convs.
+ - 'on_output': The last output feature map after fpn convs.
+ extra_convs_on_inputs (bool, deprecated): Whether to apply extra convs
+ on the original feature from the backbone. If True,
+ it is equivalent to `add_extra_convs='on_input'`. If False, it is
+ equivalent to set `add_extra_convs='on_output'`. Default to True.
+ relu_before_extra_convs (bool): Whether to apply relu before the extra
+ conv. Default: False.
+ no_norm_on_lateral (bool): Whether to apply norm on lateral.
+ Default: False.
+ conv_cfg (dict): Config dict for convolution layer. Default: None.
+ norm_cfg (dict): Config dict for normalization layer. Default: None.
+ act_cfg (dict): Config dict for activation layer in ConvModule.
+ Default: None.
+ upsample_cfg (dict): Config dict for interpolate layer.
+ Default: dict(mode='nearest').
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+
+ Example:
+ >>> import torch
+ >>> in_channels = [2, 3, 5, 7]
+ >>> scales = [340, 170, 84, 43]
+ >>> inputs = [torch.rand(1, c, s, s)
+ ... for c, s in zip(in_channels, scales)]
+ >>> self = FPN(in_channels, 11, len(in_channels)).eval()
+ >>> outputs = self.forward(inputs)
+ >>> for i in range(len(outputs)):
+ ... print(f'outputs[{i}].shape = {outputs[i].shape}')
+ outputs[0].shape = torch.Size([1, 11, 340, 340])
+ outputs[1].shape = torch.Size([1, 11, 170, 170])
+ outputs[2].shape = torch.Size([1, 11, 84, 84])
+ outputs[3].shape = torch.Size([1, 11, 43, 43])
+ """
+
+ def __init__(self,
+ in_channels,
+ out_channels,
+ num_outs,
+ start_level=0,
+ end_level=-1,
+ add_extra_convs=False,
+ extra_convs_on_inputs=False,
+ relu_before_extra_convs=False,
+ no_norm_on_lateral=False,
+ conv_cfg=None,
+ norm_cfg=None,
+ act_cfg=None,
+ upsample_cfg=dict(mode='nearest'),
+ init_cfg=dict(
+ type='Xavier', layer='Conv2d', distribution='uniform')):
+ super(FPN, self).__init__(init_cfg)
+ assert isinstance(in_channels, list)
+ self.in_channels = in_channels
+ self.out_channels = out_channels
+ self.num_ins = len(in_channels)
+ self.num_outs = num_outs
+ self.relu_before_extra_convs = relu_before_extra_convs
+ self.no_norm_on_lateral = no_norm_on_lateral
+ self.fp16_enabled = False
+ self.upsample_cfg = upsample_cfg.copy()
+
+ if end_level == -1:
+ self.backbone_end_level = self.num_ins
+ assert num_outs >= self.num_ins - start_level
+ else:
+ # if end_level < inputs, no extra level is allowed
+ self.backbone_end_level = end_level
+ assert end_level <= len(in_channels)
+ assert num_outs == end_level - start_level
+ self.start_level = start_level
+ self.end_level = end_level
+ self.add_extra_convs = add_extra_convs
+ assert isinstance(add_extra_convs, (str, bool))
+ if isinstance(add_extra_convs, str):
+ # Extra_convs_source choices: 'on_input', 'on_lateral', 'on_output'
+ assert add_extra_convs in ('on_input', 'on_lateral', 'on_output')
+ elif add_extra_convs: # True
+ if extra_convs_on_inputs:
+ # For compatibility with previous release
+ # TODO: deprecate `extra_convs_on_inputs`
+ self.add_extra_convs = 'on_input'
+ else:
+ self.add_extra_convs = 'on_output'
+
+ self.lateral_convs = nn.ModuleList()
+ self.fpn_convs = nn.ModuleList()
+
+ for i in range(self.start_level, self.backbone_end_level):
+ l_conv = ConvModule(
+ in_channels[i],
+ out_channels,
+ 1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg if not self.no_norm_on_lateral else None,
+ act_cfg=act_cfg,
+ inplace=False)
+ fpn_conv = ConvModule(
+ out_channels,
+ out_channels,
+ 3,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg,
+ inplace=False)
+
+ self.lateral_convs.append(l_conv)
+ self.fpn_convs.append(fpn_conv)
+
+ # add extra conv layers (e.g., RetinaNet)
+ extra_levels = num_outs - self.backbone_end_level + self.start_level
+ if self.add_extra_convs and extra_levels >= 1:
+ for i in range(extra_levels):
+ if i == 0 and self.add_extra_convs == 'on_input':
+ in_channels = self.in_channels[self.backbone_end_level - 1]
+ else:
+ in_channels = out_channels
+ extra_fpn_conv = ConvModule(
+ in_channels,
+ out_channels,
+ 3,
+ stride=2,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg,
+ inplace=False)
+ self.fpn_convs.append(extra_fpn_conv)
+
+ @auto_fp16()
+ def forward(self, inputs):
+ assert len(inputs) == len(self.in_channels)
+
+ # build laterals
+ laterals = [
+ lateral_conv(inputs[i + self.start_level])
+ for i, lateral_conv in enumerate(self.lateral_convs)
+ ]
+
+ # build top-down path
+ used_backbone_levels = len(laterals)
+ for i in range(used_backbone_levels - 1, 0, -1):
+ # In some cases, fixing `scale factor` (e.g. 2) is preferred, but
+ # it cannot co-exist with `size` in `F.interpolate`.
+ if 'scale_factor' in self.upsample_cfg:
+ laterals[i - 1] = laterals[i - 1] + resize(
+ laterals[i], **self.upsample_cfg)
+ else:
+ prev_shape = laterals[i - 1].shape[2:]
+ laterals[i - 1] = laterals[i - 1] + resize(
+ laterals[i], size=prev_shape, **self.upsample_cfg)
+
+ # build outputs
+ # part 1: from original levels
+ outs = [
+ self.fpn_convs[i](laterals[i]) for i in range(used_backbone_levels)
+ ]
+ # part 2: add extra levels
+ if self.num_outs > len(outs):
+ # use max pool to get more levels on top of outputs
+ # (e.g., Faster R-CNN, Mask R-CNN)
+ if not self.add_extra_convs:
+ for i in range(self.num_outs - used_backbone_levels):
+ outs.append(F.max_pool2d(outs[-1], 1, stride=2))
+ # add conv layers on top of original feature maps (RetinaNet)
+ else:
+ if self.add_extra_convs == 'on_input':
+ extra_source = inputs[self.backbone_end_level - 1]
+ elif self.add_extra_convs == 'on_lateral':
+ extra_source = laterals[-1]
+ elif self.add_extra_convs == 'on_output':
+ extra_source = outs[-1]
+ else:
+ raise NotImplementedError
+ outs.append(self.fpn_convs[used_backbone_levels](extra_source))
+ for i in range(used_backbone_levels + 1, self.num_outs):
+ if self.relu_before_extra_convs:
+ outs.append(self.fpn_convs[i](F.relu(outs[-1])))
+ else:
+ outs.append(self.fpn_convs[i](outs[-1]))
+ return tuple(outs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/ic_neck.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/ic_neck.py
new file mode 100644
index 0000000000000000000000000000000000000000..a5d81cef8e16bd82f11c5ed35c04564a702b667d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/ic_neck.py
@@ -0,0 +1,148 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch.nn.functional as F
+from mmcv.cnn import ConvModule
+from mmcv.runner import BaseModule
+
+from mmseg.ops import resize
+from ..builder import NECKS
+
+
+class CascadeFeatureFusion(BaseModule):
+ """Cascade Feature Fusion Unit in ICNet.
+
+ Args:
+ low_channels (int): The number of input channels for
+ low resolution feature map.
+ high_channels (int): The number of input channels for
+ high resolution feature map.
+ out_channels (int): The number of output channels.
+ conv_cfg (dict): Dictionary to construct and config conv layer.
+ Default: None.
+ norm_cfg (dict): Dictionary to construct and config norm layer.
+ Default: dict(type='BN').
+ act_cfg (dict): Dictionary to construct and config act layer.
+ Default: dict(type='ReLU').
+ align_corners (bool): align_corners argument of F.interpolate.
+ Default: False.
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+
+ Returns:
+ x (Tensor): The output tensor of shape (N, out_channels, H, W).
+ x_low (Tensor): The output tensor of shape (N, out_channels, H, W)
+ for Cascade Label Guidance in auxiliary heads.
+ """
+
+ def __init__(self,
+ low_channels,
+ high_channels,
+ out_channels,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ align_corners=False,
+ init_cfg=None):
+ super(CascadeFeatureFusion, self).__init__(init_cfg=init_cfg)
+ self.align_corners = align_corners
+ self.conv_low = ConvModule(
+ low_channels,
+ out_channels,
+ 3,
+ padding=2,
+ dilation=2,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ self.conv_high = ConvModule(
+ high_channels,
+ out_channels,
+ 1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+
+ def forward(self, x_low, x_high):
+ x_low = resize(
+ x_low,
+ size=x_high.size()[2:],
+ mode='bilinear',
+ align_corners=self.align_corners)
+ # Note: Different from original paper, `x_low` is underwent
+ # `self.conv_low` rather than another 1x1 conv classifier
+ # before being used for auxiliary head.
+ x_low = self.conv_low(x_low)
+ x_high = self.conv_high(x_high)
+ x = x_low + x_high
+ x = F.relu(x, inplace=True)
+ return x, x_low
+
+
+@NECKS.register_module()
+class ICNeck(BaseModule):
+ """ICNet for Real-Time Semantic Segmentation on High-Resolution Images.
+
+ This head is the implementation of `ICHead
+ `_.
+
+ Args:
+ in_channels (int): The number of input image channels. Default: 3.
+ out_channels (int): The numbers of output feature channels.
+ Default: 128.
+ conv_cfg (dict): Dictionary to construct and config conv layer.
+ Default: None.
+ norm_cfg (dict): Dictionary to construct and config norm layer.
+ Default: dict(type='BN').
+ act_cfg (dict): Dictionary to construct and config act layer.
+ Default: dict(type='ReLU').
+ align_corners (bool): align_corners argument of F.interpolate.
+ Default: False.
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ """
+
+ def __init__(self,
+ in_channels=(64, 256, 256),
+ out_channels=128,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ align_corners=False,
+ init_cfg=None):
+ super(ICNeck, self).__init__(init_cfg=init_cfg)
+ assert len(in_channels) == 3, 'Length of input channels \
+ must be 3!'
+
+ self.in_channels = in_channels
+ self.out_channels = out_channels
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+ self.align_corners = align_corners
+ self.cff_24 = CascadeFeatureFusion(
+ self.in_channels[2],
+ self.in_channels[1],
+ self.out_channels,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg,
+ align_corners=self.align_corners)
+
+ self.cff_12 = CascadeFeatureFusion(
+ self.out_channels,
+ self.in_channels[0],
+ self.out_channels,
+ conv_cfg=self.conv_cfg,
+ norm_cfg=self.norm_cfg,
+ act_cfg=self.act_cfg,
+ align_corners=self.align_corners)
+
+ def forward(self, inputs):
+ assert len(inputs) == 3, 'Length of input feature \
+ maps must be 3!'
+
+ x_sub1, x_sub2, x_sub4 = inputs
+ x_cff_24, x_24 = self.cff_24(x_sub4, x_sub2)
+ x_cff_12, x_12 = self.cff_12(x_cff_24, x_sub1)
+ # Note: `x_cff_12` is used for decode_head,
+ # `x_24` and `x_12` are used for auxiliary head.
+ return x_24, x_12, x_cff_12
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/jpu.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/jpu.py
new file mode 100644
index 0000000000000000000000000000000000000000..3cc6b9f428911a48a7fe3f1f2913812e45e4737e
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/jpu.py
@@ -0,0 +1,131 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+from mmcv.cnn import ConvModule, DepthwiseSeparableConvModule
+from mmcv.runner import BaseModule
+
+from mmseg.ops import resize
+from ..builder import NECKS
+
+
+@NECKS.register_module()
+class JPU(BaseModule):
+ """FastFCN: Rethinking Dilated Convolution in the Backbone
+ for Semantic Segmentation.
+
+ This Joint Pyramid Upsampling (JPU) neck is the implementation of
+ `FastFCN `_.
+
+ Args:
+ in_channels (Tuple[int], optional): The number of input channels
+ for each convolution operations before upsampling.
+ Default: (512, 1024, 2048).
+ mid_channels (int): The number of output channels of JPU.
+ Default: 512.
+ start_level (int): Index of the start input backbone level used to
+ build the feature pyramid. Default: 0.
+ end_level (int): Index of the end input backbone level (exclusive) to
+ build the feature pyramid. Default: -1, which means the last level.
+ dilations (tuple[int]): Dilation rate of each Depthwise
+ Separable ConvModule. Default: (1, 2, 4, 8).
+ align_corners (bool, optional): The align_corners argument of
+ resize operation. Default: False.
+ conv_cfg (dict | None): Config of conv layers.
+ Default: None.
+ norm_cfg (dict | None): Config of norm layers.
+ Default: dict(type='BN').
+ act_cfg (dict): Config of activation layers.
+ Default: dict(type='ReLU').
+ init_cfg (dict or list[dict], optional): Initialization config dict.
+ Default: None.
+ """
+
+ def __init__(self,
+ in_channels=(512, 1024, 2048),
+ mid_channels=512,
+ start_level=0,
+ end_level=-1,
+ dilations=(1, 2, 4, 8),
+ align_corners=False,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ init_cfg=None):
+ super(JPU, self).__init__(init_cfg=init_cfg)
+ assert isinstance(in_channels, tuple)
+ assert isinstance(dilations, tuple)
+ self.in_channels = in_channels
+ self.mid_channels = mid_channels
+ self.start_level = start_level
+ self.num_ins = len(in_channels)
+ if end_level == -1:
+ self.backbone_end_level = self.num_ins
+ else:
+ self.backbone_end_level = end_level
+ assert end_level <= len(in_channels)
+
+ self.dilations = dilations
+ self.align_corners = align_corners
+
+ self.conv_layers = nn.ModuleList()
+ self.dilation_layers = nn.ModuleList()
+ for i in range(self.start_level, self.backbone_end_level):
+ conv_layer = nn.Sequential(
+ ConvModule(
+ self.in_channels[i],
+ self.mid_channels,
+ kernel_size=3,
+ padding=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg))
+ self.conv_layers.append(conv_layer)
+ for i in range(len(dilations)):
+ dilation_layer = nn.Sequential(
+ DepthwiseSeparableConvModule(
+ in_channels=(self.backbone_end_level - self.start_level) *
+ self.mid_channels,
+ out_channels=self.mid_channels,
+ kernel_size=3,
+ stride=1,
+ padding=dilations[i],
+ dilation=dilations[i],
+ dw_norm_cfg=norm_cfg,
+ dw_act_cfg=None,
+ pw_norm_cfg=norm_cfg,
+ pw_act_cfg=act_cfg))
+ self.dilation_layers.append(dilation_layer)
+
+ def forward(self, inputs):
+ """Forward function."""
+ assert len(inputs) == len(self.in_channels), 'Length of inputs must \
+ be the same with self.in_channels!'
+
+ feats = [
+ self.conv_layers[i - self.start_level](inputs[i])
+ for i in range(self.start_level, self.backbone_end_level)
+ ]
+
+ h, w = feats[0].shape[2:]
+ for i in range(1, len(feats)):
+ feats[i] = resize(
+ feats[i],
+ size=(h, w),
+ mode='bilinear',
+ align_corners=self.align_corners)
+
+ feat = torch.cat(feats, dim=1)
+ concat_feat = torch.cat([
+ self.dilation_layers[i](feat) for i in range(len(self.dilations))
+ ],
+ dim=1)
+
+ outs = []
+
+ # Default: outs[2] is the output of JPU for decoder head, outs[1] is
+ # the feature map from backbone for auxiliary head. Additionally,
+ # outs[0] can also be used for auxiliary head.
+ for i in range(self.start_level, self.backbone_end_level - 1):
+ outs.append(inputs[i])
+ outs.append(concat_feat)
+ return tuple(outs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/mla_neck.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/mla_neck.py
new file mode 100644
index 0000000000000000000000000000000000000000..1513e296daaedf83bea23ab2c168fb63482bed23
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/mla_neck.py
@@ -0,0 +1,118 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch.nn as nn
+from mmcv.cnn import ConvModule, build_norm_layer
+
+from ..builder import NECKS
+
+
+class MLAModule(nn.Module):
+
+ def __init__(self,
+ in_channels=[1024, 1024, 1024, 1024],
+ out_channels=256,
+ norm_cfg=None,
+ act_cfg=None):
+ super(MLAModule, self).__init__()
+ self.channel_proj = nn.ModuleList()
+ for i in range(len(in_channels)):
+ self.channel_proj.append(
+ ConvModule(
+ in_channels=in_channels[i],
+ out_channels=out_channels,
+ kernel_size=1,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg))
+ self.feat_extract = nn.ModuleList()
+ for i in range(len(in_channels)):
+ self.feat_extract.append(
+ ConvModule(
+ in_channels=out_channels,
+ out_channels=out_channels,
+ kernel_size=3,
+ padding=1,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg))
+
+ def forward(self, inputs):
+
+ # feat_list -> [p2, p3, p4, p5]
+ feat_list = []
+ for x, conv in zip(inputs, self.channel_proj):
+ feat_list.append(conv(x))
+
+ # feat_list -> [p5, p4, p3, p2]
+ # mid_list -> [m5, m4, m3, m2]
+ feat_list = feat_list[::-1]
+ mid_list = []
+ for feat in feat_list:
+ if len(mid_list) == 0:
+ mid_list.append(feat)
+ else:
+ mid_list.append(mid_list[-1] + feat)
+
+ # mid_list -> [m5, m4, m3, m2]
+ # out_list -> [o2, o3, o4, o5]
+ out_list = []
+ for mid, conv in zip(mid_list, self.feat_extract):
+ out_list.append(conv(mid))
+
+ return tuple(out_list)
+
+
+@NECKS.register_module()
+class MLANeck(nn.Module):
+ """Multi-level Feature Aggregation.
+
+ This neck is `The Multi-level Feature Aggregation construction of
+ SETR `_.
+
+
+ Args:
+ in_channels (List[int]): Number of input channels per scale.
+ out_channels (int): Number of output channels (used at each scale).
+ norm_layer (dict): Config dict for input normalization.
+ Default: norm_layer=dict(type='LN', eps=1e-6, requires_grad=True).
+ norm_cfg (dict): Config dict for normalization layer. Default: None.
+ act_cfg (dict): Config dict for activation layer in ConvModule.
+ Default: None.
+ """
+
+ def __init__(self,
+ in_channels,
+ out_channels,
+ norm_layer=dict(type='LN', eps=1e-6, requires_grad=True),
+ norm_cfg=None,
+ act_cfg=None):
+ super(MLANeck, self).__init__()
+ assert isinstance(in_channels, list)
+ self.in_channels = in_channels
+ self.out_channels = out_channels
+
+ # In order to build general vision transformer backbone, we have to
+ # move MLA to neck.
+ self.norm = nn.ModuleList([
+ build_norm_layer(norm_layer, in_channels[i])[1]
+ for i in range(len(in_channels))
+ ])
+
+ self.mla = MLAModule(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+
+ def forward(self, inputs):
+ assert len(inputs) == len(self.in_channels)
+
+ # Convert from nchw to nlc
+ outs = []
+ for i in range(len(inputs)):
+ x = inputs[i]
+ n, c, h, w = x.shape
+ x = x.reshape(n, c, h * w).transpose(2, 1).contiguous()
+ x = self.norm[i](x)
+ x = x.transpose(1, 2).reshape(n, c, h, w).contiguous()
+ outs.append(x)
+
+ outs = self.mla(outs)
+ return tuple(outs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/multilevel_neck.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/multilevel_neck.py
new file mode 100644
index 0000000000000000000000000000000000000000..5151f8762de46ae3e41da8f9683ee8df6f70711e
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/necks/multilevel_neck.py
@@ -0,0 +1,78 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch.nn as nn
+from mmcv.cnn import ConvModule, xavier_init
+
+from mmseg.ops import resize
+from ..builder import NECKS
+
+
+@NECKS.register_module()
+class MultiLevelNeck(nn.Module):
+ """MultiLevelNeck.
+
+ A neck structure connect vit backbone and decoder_heads.
+
+ Args:
+ in_channels (List[int]): Number of input channels per scale.
+ out_channels (int): Number of output channels (used at each scale).
+ scales (List[float]): Scale factors for each input feature map.
+ Default: [0.5, 1, 2, 4]
+ norm_cfg (dict): Config dict for normalization layer. Default: None.
+ act_cfg (dict): Config dict for activation layer in ConvModule.
+ Default: None.
+ """
+
+ def __init__(self,
+ in_channels,
+ out_channels,
+ scales=[0.5, 1, 2, 4],
+ norm_cfg=None,
+ act_cfg=None):
+ super(MultiLevelNeck, self).__init__()
+ assert isinstance(in_channels, list)
+ self.in_channels = in_channels
+ self.out_channels = out_channels
+ self.scales = scales
+ self.num_outs = len(scales)
+ self.lateral_convs = nn.ModuleList()
+ self.convs = nn.ModuleList()
+ for in_channel in in_channels:
+ self.lateral_convs.append(
+ ConvModule(
+ in_channel,
+ out_channels,
+ kernel_size=1,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg))
+ for _ in range(self.num_outs):
+ self.convs.append(
+ ConvModule(
+ out_channels,
+ out_channels,
+ kernel_size=3,
+ padding=1,
+ stride=1,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg))
+
+ # default init_weights for conv(msra) and norm in ConvModule
+ def init_weights(self):
+ for m in self.modules():
+ if isinstance(m, nn.Conv2d):
+ xavier_init(m, distribution='uniform')
+
+ def forward(self, inputs):
+ assert len(inputs) == len(self.in_channels)
+ inputs = [
+ lateral_conv(inputs[i])
+ for i, lateral_conv in enumerate(self.lateral_convs)
+ ]
+ # for len(inputs) not equal to self.num_outs
+ if len(inputs) == 1:
+ inputs = [inputs[0] for _ in range(self.num_outs)]
+ outs = []
+ for i in range(self.num_outs):
+ x_resize = resize(
+ inputs[i], scale_factor=self.scales[i], mode='bilinear')
+ outs.append(self.convs[i](x_resize))
+ return tuple(outs)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/segmentors/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/segmentors/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..387c858bd7a4e1e222db0fe99d85f4728ff48f21
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/segmentors/__init__.py
@@ -0,0 +1,6 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .base import BaseSegmentor
+from .cascade_encoder_decoder import CascadeEncoderDecoder
+from .encoder_decoder import EncoderDecoder
+
+__all__ = ['BaseSegmentor', 'EncoderDecoder', 'CascadeEncoderDecoder']
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/segmentors/base.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/segmentors/base.py
new file mode 100644
index 0000000000000000000000000000000000000000..76dc8f075a848d3df9e0d8d4f123ca458fb93aa4
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/segmentors/base.py
@@ -0,0 +1,291 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import warnings
+from abc import ABCMeta, abstractmethod
+from collections import OrderedDict
+
+import mmcv
+import numpy as np
+import torch
+import torch.distributed as dist
+from mmcv.runner import BaseModule, auto_fp16
+
+
+class BaseSegmentor(BaseModule, metaclass=ABCMeta):
+ """Base class for segmentors."""
+
+ def __init__(self, init_cfg=None):
+ super(BaseSegmentor, self).__init__(init_cfg)
+ self.fp16_enabled = False
+
+ @property
+ def with_neck(self):
+ """bool: whether the segmentor has neck"""
+ return hasattr(self, 'neck') and self.neck is not None
+
+ @property
+ def with_auxiliary_head(self):
+ """bool: whether the segmentor has auxiliary head"""
+ return hasattr(self,
+ 'auxiliary_head') and self.auxiliary_head is not None
+
+ @property
+ def with_decode_head(self):
+ """bool: whether the segmentor has decode head"""
+ return hasattr(self, 'decode_head') and self.decode_head is not None
+
+ @abstractmethod
+ def extract_feat(self, imgs):
+ """Placeholder for extract features from images."""
+ pass
+
+ @abstractmethod
+ def encode_decode(self, img, img_metas):
+ """Placeholder for encode images with backbone and decode into a
+ semantic segmentation map of the same size as input."""
+ pass
+
+ @abstractmethod
+ def forward_train(self, imgs, img_metas, **kwargs):
+ """Placeholder for Forward function for training."""
+ pass
+
+ @abstractmethod
+ def simple_test(self, img, img_meta, **kwargs):
+ """Placeholder for single image test."""
+ pass
+
+ @abstractmethod
+ def aug_test(self, imgs, img_metas, **kwargs):
+ """Placeholder for augmentation test."""
+ pass
+
+ def forward_test(self, imgs, img_metas, **kwargs):
+ """
+ Args:
+ imgs (List[Tensor]): the outer list indicates test-time
+ augmentations and inner Tensor should have a shape NxCxHxW,
+ which contains all images in the batch.
+ img_metas (List[List[dict]]): the outer list indicates test-time
+ augs (multiscale, flip, etc.) and the inner list indicates
+ images in a batch.
+ """
+ for var, name in [(imgs, 'imgs'), (img_metas, 'img_metas')]:
+ if not isinstance(var, list):
+ raise TypeError(f'{name} must be a list, but got '
+ f'{type(var)}')
+
+ num_augs = len(imgs)
+ if num_augs != len(img_metas):
+ raise ValueError(f'num of augmentations ({len(imgs)}) != '
+ f'num of image meta ({len(img_metas)})')
+ # all images in the same aug batch all of the same ori_shape and pad
+ # shape
+ for img_meta in img_metas:
+ ori_shapes = [_['ori_shape'] for _ in img_meta]
+ assert all(shape == ori_shapes[0] for shape in ori_shapes)
+ img_shapes = [_['img_shape'] for _ in img_meta]
+ assert all(shape == img_shapes[0] for shape in img_shapes)
+ pad_shapes = [_['pad_shape'] for _ in img_meta]
+ assert all(shape == pad_shapes[0] for shape in pad_shapes)
+
+ if num_augs == 1:
+ return self.simple_test(imgs[0], img_metas[0], **kwargs)
+ else:
+ return self.aug_test(imgs, img_metas, **kwargs)
+
+ @auto_fp16(apply_to=('img', ))
+ def forward(self, img, img_metas, return_loss=True, **kwargs):
+ """Calls either :func:`forward_train` or :func:`forward_test` depending
+ on whether ``return_loss`` is ``True``.
+
+ Note this setting will change the expected inputs. When
+ ``return_loss=True``, img and img_meta are single-nested (i.e. Tensor
+ and List[dict]), and when ``resturn_loss=False``, img and img_meta
+ should be double nested (i.e. List[Tensor], List[List[dict]]), with
+ the outer list indicating test time augmentations.
+ """
+ if return_loss:
+ return self.forward_train(img, img_metas, **kwargs)
+ else:
+ return self.forward_test(img, img_metas, **kwargs)
+
+ def train_step(self, data_batch, optimizer, **kwargs):
+ """The iteration step during training.
+
+ This method defines an iteration step during training, except for the
+ back propagation and optimizer updating, which are done in an optimizer
+ hook. Note that in some complicated cases or models, the whole process
+ including back propagation and optimizer updating is also defined in
+ this method, such as GAN.
+
+ Args:
+ data (dict): The output of dataloader.
+ optimizer (:obj:`torch.optim.Optimizer` | dict): The optimizer of
+ runner is passed to ``train_step()``. This argument is unused
+ and reserved.
+
+ Returns:
+ dict: It should contain at least 3 keys: ``loss``, ``log_vars``,
+ ``num_samples``.
+ ``loss`` is a tensor for back propagation, which can be a
+ weighted sum of multiple losses.
+ ``log_vars`` contains all the variables to be sent to the
+ logger.
+ ``num_samples`` indicates the batch size (when the model is
+ DDP, it means the batch size on each GPU), which is used for
+ averaging the logs.
+ """
+ losses = self(**data_batch)
+ loss, log_vars = self._parse_losses(losses)
+
+ outputs = dict(
+ loss=loss,
+ log_vars=log_vars,
+ num_samples=len(data_batch['img_metas']))
+
+ return outputs
+
+ def val_step(self, data_batch, optimizer=None, **kwargs):
+ """The iteration step during validation.
+
+ This method shares the same signature as :func:`train_step`, but used
+ during val epochs. Note that the evaluation after training epochs is
+ not implemented with this method, but an evaluation hook.
+ """
+ losses = self(**data_batch)
+ loss, log_vars = self._parse_losses(losses)
+
+ log_vars_ = dict()
+ for loss_name, loss_value in log_vars.items():
+ k = loss_name + '_val'
+ log_vars_[k] = loss_value
+
+ outputs = dict(
+ loss=loss,
+ log_vars=log_vars_,
+ num_samples=len(data_batch['img_metas']))
+
+ return outputs
+
+ @staticmethod
+ def _parse_losses(losses):
+ """Parse the raw outputs (losses) of the network.
+
+ Args:
+ losses (dict): Raw output of the network, which usually contain
+ losses and other necessary information.
+
+ Returns:
+ tuple[Tensor, dict]: (loss, log_vars), loss is the loss tensor
+ which may be a weighted sum of all losses, log_vars contains
+ all the variables to be sent to the logger.
+ """
+ log_vars = OrderedDict()
+ for loss_name, loss_value in losses.items():
+ if isinstance(loss_value, torch.Tensor):
+ log_vars[loss_name] = loss_value.mean()
+ elif isinstance(loss_value, list):
+ log_vars[loss_name] = sum(_loss.mean() for _loss in loss_value)
+ else:
+ raise TypeError(
+ f'{loss_name} is not a tensor or list of tensors')
+
+ loss = sum(_value for _key, _value in log_vars.items()
+ if 'loss' in _key)
+
+ # If the loss_vars has different length, raise assertion error
+ # to prevent GPUs from infinite waiting.
+ if dist.is_available() and dist.is_initialized():
+ log_var_length = torch.tensor(len(log_vars), device=loss.device)
+ dist.all_reduce(log_var_length)
+ message = (f'rank {dist.get_rank()}' +
+ f' len(log_vars): {len(log_vars)}' + ' keys: ' +
+ ','.join(log_vars.keys()) + '\n')
+ assert log_var_length == len(log_vars) * dist.get_world_size(), \
+ 'loss log variables are different across GPUs!\n' + message
+
+ log_vars['loss'] = loss
+ for loss_name, loss_value in log_vars.items():
+ # reduce loss when distributed training
+ if dist.is_available() and dist.is_initialized():
+ loss_value = loss_value.data.clone()
+ dist.all_reduce(loss_value.div_(dist.get_world_size()))
+ log_vars[loss_name] = loss_value.item()
+
+ return loss, log_vars
+
+ def show_result(self,
+ img,
+ result,
+ palette=None,
+ win_name='',
+ show=False,
+ wait_time=0,
+ out_file=None,
+ opacity=0.5):
+ """Draw `result` over `img`.
+
+ Args:
+ img (str or Tensor): The image to be displayed.
+ result (Tensor): The semantic segmentation results to draw over
+ `img`.
+ palette (list[list[int]]] | np.ndarray | None): The palette of
+ segmentation map. If None is given, random palette will be
+ generated. Default: None
+ win_name (str): The window name.
+ wait_time (int): Value of waitKey param.
+ Default: 0.
+ show (bool): Whether to show the image.
+ Default: False.
+ out_file (str or None): The filename to write the image.
+ Default: None.
+ opacity(float): Opacity of painted segmentation map.
+ Default 0.5.
+ Must be in (0, 1] range.
+ Returns:
+ img (Tensor): Only if not `show` or `out_file`
+ """
+ img = mmcv.imread(img)
+ img = img.copy()
+ seg = result[0]
+ if palette is None:
+ if self.PALETTE is None:
+ # Get random state before set seed,
+ # and restore random state later.
+ # It will prevent loss of randomness, as the palette
+ # may be different in each iteration if not specified.
+ # See: https://github.com/open-mmlab/mmdetection/issues/5844
+ state = np.random.get_state()
+ np.random.seed(42)
+ # random palette
+ palette = np.random.randint(
+ 0, 255, size=(len(self.CLASSES), 3))
+ np.random.set_state(state)
+ else:
+ palette = self.PALETTE
+ palette = np.array(palette)
+ assert palette.shape[0] == len(self.CLASSES)
+ assert palette.shape[1] == 3
+ assert len(palette.shape) == 2
+ assert 0 < opacity <= 1.0
+ color_seg = np.zeros((seg.shape[0], seg.shape[1], 3), dtype=np.uint8)
+ for label, color in enumerate(palette):
+ color_seg[seg == label, :] = color
+ # convert to BGR
+ color_seg = color_seg[..., ::-1]
+
+ img = img * (1 - opacity) + color_seg * opacity
+ img = img.astype(np.uint8)
+ # if out_file specified, do not show image in window
+ if out_file is not None:
+ show = False
+
+ if show:
+ mmcv.imshow(img, win_name, wait_time)
+ if out_file is not None:
+ mmcv.imwrite(img, out_file)
+
+ if not (show or out_file):
+ warnings.warn('show==False and out_file is not specified, only '
+ 'result image will be returned')
+ return img
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/segmentors/cascade_encoder_decoder.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/segmentors/cascade_encoder_decoder.py
new file mode 100644
index 0000000000000000000000000000000000000000..1913a22e204bd77d0d98fc4f9e9ebaf9723d3ffe
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/segmentors/cascade_encoder_decoder.py
@@ -0,0 +1,88 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from torch import nn
+
+from mmseg.core import add_prefix
+from mmseg.ops import resize
+from .. import builder
+from ..builder import SEGMENTORS
+from .encoder_decoder import EncoderDecoder
+
+
+@SEGMENTORS.register_module()
+class CascadeEncoderDecoder(EncoderDecoder):
+ """Cascade Encoder Decoder segmentors.
+
+ CascadeEncoderDecoder almost the same as EncoderDecoder, while decoders of
+ CascadeEncoderDecoder are cascaded. The output of previous decoder_head
+ will be the input of next decoder_head.
+ """
+
+ def __init__(self,
+ num_stages,
+ backbone,
+ decode_head,
+ neck=None,
+ auxiliary_head=None,
+ train_cfg=None,
+ test_cfg=None,
+ pretrained=None,
+ init_cfg=None):
+ self.num_stages = num_stages
+ super(CascadeEncoderDecoder, self).__init__(
+ backbone=backbone,
+ decode_head=decode_head,
+ neck=neck,
+ auxiliary_head=auxiliary_head,
+ train_cfg=train_cfg,
+ test_cfg=test_cfg,
+ pretrained=pretrained,
+ init_cfg=init_cfg)
+
+ def _init_decode_head(self, decode_head):
+ """Initialize ``decode_head``"""
+ assert isinstance(decode_head, list)
+ assert len(decode_head) == self.num_stages
+ self.decode_head = nn.ModuleList()
+ for i in range(self.num_stages):
+ self.decode_head.append(builder.build_head(decode_head[i]))
+ self.align_corners = self.decode_head[-1].align_corners
+ self.num_classes = self.decode_head[-1].num_classes
+
+ def encode_decode(self, img, img_metas):
+ """Encode images with backbone and decode into a semantic segmentation
+ map of the same size as input."""
+ x = self.extract_feat(img)
+ out = self.decode_head[0].forward_test(x, img_metas, self.test_cfg)
+ for i in range(1, self.num_stages):
+ out = self.decode_head[i].forward_test(x, out, img_metas,
+ self.test_cfg)
+ out = resize(
+ input=out,
+ size=img.shape[2:],
+ mode='bilinear',
+ align_corners=self.align_corners)
+ return out
+
+ def _decode_head_forward_train(self, x, img_metas, gt_semantic_seg):
+ """Run forward function and calculate loss for decode head in
+ training."""
+ losses = dict()
+
+ loss_decode = self.decode_head[0].forward_train(
+ x, img_metas, gt_semantic_seg, self.train_cfg)
+
+ losses.update(add_prefix(loss_decode, 'decode_0'))
+
+ for i in range(1, self.num_stages):
+ # forward test again, maybe unnecessary for most methods.
+ if i == 1:
+ prev_outputs = self.decode_head[0].forward_test(
+ x, img_metas, self.test_cfg)
+ else:
+ prev_outputs = self.decode_head[i - 1].forward_test(
+ x, prev_outputs, img_metas, self.test_cfg)
+ loss_decode = self.decode_head[i].forward_train(
+ x, prev_outputs, img_metas, gt_semantic_seg, self.train_cfg)
+ losses.update(add_prefix(loss_decode, f'decode_{i}'))
+
+ return losses
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/segmentors/encoder_decoder.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/segmentors/encoder_decoder.py
new file mode 100644
index 0000000000000000000000000000000000000000..88e6ca90b9fb80fea29aafb0490b3acdd5d094bc
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/segmentors/encoder_decoder.py
@@ -0,0 +1,500 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+
+from mmseg.core import add_prefix
+from mmseg.ops import resize
+from .. import builder
+from ..builder import SEGMENTORS
+from .base import BaseSegmentor
+
+import os
+import pdb
+import random
+from PIL import Image, ImageOps
+import numpy as np
+from torchvision.transforms.functional import to_tensor
+from torchvision.utils import save_image
+
+additional_channel = 'twohands_cb'
+use_ccda = True
+
+@SEGMENTORS.register_module()
+class EncoderDecoder(BaseSegmentor):
+ """Encoder Decoder segmentors.
+
+ EncoderDecoder typically consists of backbone, decode_head, auxiliary_head.
+ Note that auxiliary_head is only used for deep supervision during training,
+ which could be dumped during inference.
+ """
+
+ def __init__(self,
+ backbone,
+ decode_head,
+ neck=None,
+ auxiliary_head=None,
+ train_cfg=None,
+ test_cfg=None,
+ pretrained=None,
+ init_cfg=None):
+ super(EncoderDecoder, self).__init__(init_cfg)
+ if pretrained is not None:
+ assert backbone.get('pretrained') is None, \
+ 'both backbone and segmentor set pretrained weight'
+ backbone.pretrained = pretrained
+ self.backbone = builder.build_backbone(backbone)
+ if neck is not None:
+ self.neck = builder.build_neck(neck)
+ self._init_decode_head(decode_head)
+ self._init_auxiliary_head(auxiliary_head)
+
+ self.train_cfg = train_cfg
+ self.test_cfg = test_cfg
+
+ # pdb.set_trace()
+
+ assert self.with_decode_head
+
+ def _init_decode_head(self, decode_head):
+ """Initialize ``decode_head``"""
+ self.decode_head = builder.build_head(decode_head)
+ self.align_corners = self.decode_head.align_corners
+ self.num_classes = self.decode_head.num_classes
+
+ def _init_auxiliary_head(self, auxiliary_head):
+ """Initialize ``auxiliary_head``"""
+ if auxiliary_head is not None:
+ if isinstance(auxiliary_head, list):
+ self.auxiliary_head = nn.ModuleList()
+ for head_cfg in auxiliary_head:
+ self.auxiliary_head.append(builder.build_head(head_cfg))
+ else:
+ self.auxiliary_head = builder.build_head(auxiliary_head)
+
+ def extract_feat(self, img):
+ """Extract features from images."""
+ x = self.backbone(img)
+ if self.with_neck:
+ x = self.neck(x)
+ return x
+
+ def encode_decode(self, img, img_metas):
+ """Encode images with backbone and decode into a semantic segmentation
+ map of the same size as input."""
+
+ if img_metas[0]['additional_channel'] == 'twohands':
+
+ img_h, img_w = img.shape[2], img.shape[3]; target_aspect_ratio = img_h / img_w
+ aux_list = torch.zeros((img.shape[0], 1, img.shape[2], img.shape[3])).to(img.device)
+ for i in range(img.shape[0]):
+ img_file = img_metas[i]['filename']
+ # path = img_metas[i]['twohands_dir']
+ path = os.path.join(os.path.dirname(os.path.dirname(img_file)), 'pred_twohands')
+ fname = os.path.basename(img_file).split('.')[0] + '.png'
+ aux_file = os.path.join(path, fname)
+
+ aux = Image.open(aux_file); aux_w, aux_h = aux.size[0], aux.size[1]
+ if aux_h / aux_w < target_aspect_ratio:
+ new_aux_h = int(target_aspect_ratio * aux_w)
+ aux = ImageOps.pad(aux, (aux_w, new_aux_h), centering=(0,0))
+ else:
+ new_aux_w = int(aux_h / target_aspect_ratio)
+ aux = ImageOps.pad(aux, (new_aux_w, aux_h), centering=(0,0))
+
+ aux = torch.from_numpy(np.array(aux.resize((img_w, img_h)))).unsqueeze(0).to(img[i].device).float()
+ aux_list[i] = aux
+
+ cat_input = torch.cat([img, aux_list], dim = 1)
+ x = self.extract_feat(cat_input)
+
+ elif img_metas[0]['additional_channel'] == 'twohands_cb':
+
+ img_h, img_w = img.shape[2], img.shape[3]; target_aspect_ratio = img_h / img_w
+ aux_list = torch.zeros((img.shape[0], 1, img.shape[2], img.shape[3])).to(img.device)
+ cb_list = torch.zeros((img.shape[0], 1, img.shape[2], img.shape[3])).to(img.device)
+ for i in range(img.shape[0]):
+ img_file = img_metas[i]['filename']
+ # aux_path = img_metas[i]['twohands_dir']
+ aux_path = os.path.join(os.path.dirname(os.path.dirname(img_file)), 'pred_twohands')
+ # cb_path = img_metas[i]['cb_dir']
+ cb_path = os.path.join(os.path.dirname(os.path.dirname(img_file)), 'pred_cb')
+ fname = os.path.basename(img_file).split('.')[0] + '.png'
+ aux_file = os.path.join(aux_path, fname)
+ cb_file = os.path.join(cb_path, fname)
+
+ aux = Image.open(aux_file); aux_w, aux_h = aux.size[0], aux.size[1]
+ cb = Image.open(cb_file); cb_w, cb_h = cb.size[0], cb.size[1]
+ if aux_h / aux_w < target_aspect_ratio:
+ new_aux_h = int(target_aspect_ratio * aux_w)
+ aux = ImageOps.pad(aux, (aux_w, new_aux_h), centering=(0,0))
+ cb = ImageOps.pad(cb, (aux_w, new_aux_h), centering=(0,0))
+ else:
+ new_aux_w = int(aux_h / target_aspect_ratio)
+ aux = ImageOps.pad(aux, (new_aux_w, aux_h), centering=(0,0))
+ cb = ImageOps.pad(cb, (new_aux_w, aux_h), centering=(0,0))
+
+ aux = torch.from_numpy(np.array(aux.resize((img_w, img_h)))).unsqueeze(0).to(img[i].device).float()
+ aux_list[i] = aux
+ cb = torch.from_numpy(np.array(cb.resize((img_w, img_h)))).unsqueeze(0).to(img[i].device).float()
+ cb_list[i] = cb
+
+ # print('pdb @ encoder_decoder.py 144'); import pdb; pdb.set_trace()
+
+ cat_input = torch.cat([img, aux_list, cb_list], dim = 1)
+ x = self.extract_feat(cat_input)
+
+ else:
+
+ x = self.extract_feat(img)
+
+
+
+ # if additional_channel == 'twohands':
+
+ # img_h, img_w = img.shape[2], img.shape[3]; target_aspect_ratio = img_h / img_w
+ # aux_list = torch.zeros((img.shape[0], 1, img.shape[2], img.shape[3])).to(img.device)
+ # for i in range(img.shape[0]):
+ # img_file = img_metas[i]['filename']
+ # if use_ccda:
+ # path = os.path.join(os.path.dirname(os.path.dirname(img_file)), 'pred_twohands_ccda')
+ # else:
+ # path = os.path.join(os.path.dirname(os.path.dirname(img_file)), 'pred_twohands')
+ # fname = os.path.basename(img_file).split('.')[0] + '.png'
+ # aux_file = os.path.join(path, fname)
+
+ # aux = Image.open(aux_file); aux_w, aux_h = aux.size[0], aux.size[1]
+ # if aux_h / aux_w < target_aspect_ratio:
+ # new_aux_h = int(target_aspect_ratio * aux_w)
+ # aux = ImageOps.pad(aux, (aux_w, new_aux_h), centering=(0,0))
+ # else:
+ # new_aux_w = int(aux_h / target_aspect_ratio)
+ # aux = ImageOps.pad(aux, (new_aux_w, aux_h), centering=(0,0))
+
+ # aux = torch.from_numpy(np.array(aux.resize((img_w, img_h)))).unsqueeze(0).to(img[i].device).float()
+ # aux_list[i] = aux
+
+ # cat_input = torch.cat([img, aux_list], dim = 1)
+ # x = self.extract_feat(cat_input)
+
+ # elif additional_channel == 'twohands_cb':
+
+ # img_h, img_w = img.shape[2], img.shape[3]; target_aspect_ratio = img_h / img_w
+ # aux_list = torch.zeros((img.shape[0], 1, img.shape[2], img.shape[3])).to(img.device)
+ # cb_list = torch.zeros((img.shape[0], 1, img.shape[2], img.shape[3])).to(img.device)
+ # for i in range(img.shape[0]):
+ # img_file = img_metas[i]['filename']
+ # if use_ccda:
+ # aux_path = os.path.join(os.path.dirname(os.path.dirname(img_file)), 'pred_twohands_ccda')
+ # cb_path = os.path.join(os.path.dirname(os.path.dirname(img_file)), 'pred_cb_ccda')
+ # else:
+ # aux_path = os.path.join(os.path.dirname(os.path.dirname(img_file)), 'pred_twohands')
+ # cb_path = os.path.join(os.path.dirname(os.path.dirname(img_file)), 'pred_cb')
+ # fname = os.path.basename(img_file).split('.')[0] + '.png'
+ # aux_file = os.path.join(aux_path, fname)
+ # cb_file = os.path.join(cb_path, fname)
+
+ # aux = Image.open(aux_file); aux_w, aux_h = aux.size[0], aux.size[1]
+ # cb = Image.open(cb_file); cb_w, cb_h = cb.size[0], cb.size[1]
+ # if aux_h / aux_w < target_aspect_ratio:
+ # new_aux_h = int(target_aspect_ratio * aux_w)
+ # aux = ImageOps.pad(aux, (aux_w, new_aux_h), centering=(0,0))
+ # cb = ImageOps.pad(cb, (aux_w, new_aux_h), centering=(0,0))
+ # else:
+ # new_aux_w = int(aux_h / target_aspect_ratio)
+ # aux = ImageOps.pad(aux, (new_aux_w, aux_h), centering=(0,0))
+ # cb = ImageOps.pad(cb, (new_aux_w, aux_h), centering=(0,0))
+
+ # aux = torch.from_numpy(np.array(aux.resize((img_w, img_h)))).unsqueeze(0).to(img[i].device).float()
+ # aux_list[i] = aux
+ # cb = torch.from_numpy(np.array(cb.resize((img_w, img_h)))).unsqueeze(0).to(img[i].device).float()
+ # cb_list[i] = cb
+
+ # cat_input = torch.cat([img, aux_list, cb_list], dim = 1)
+ # x = self.extract_feat(cat_input)
+
+ # else:
+
+ # x = self.extract_feat(img)
+
+
+
+ out = self._decode_head_forward_test(x, img_metas)
+ out = resize(
+ input=out,
+ size=img.shape[2:],
+ mode='bilinear',
+ align_corners=self.align_corners)
+ return out
+
+ def _decode_head_forward_train(self, x, img_metas, gt_semantic_seg):
+ """Run forward function and calculate loss for decode head in
+ training."""
+
+ losses = dict()
+ loss_decode = self.decode_head.forward_train(x, img_metas,
+ gt_semantic_seg,
+ self.train_cfg)
+
+ losses.update(add_prefix(loss_decode, 'decode'))
+ return losses
+
+ def _decode_head_forward_test(self, x, img_metas):
+ """Run forward function and calculate loss for decode head in
+ inference."""
+ seg_logits = self.decode_head.forward_test(x, img_metas, self.test_cfg)
+ return seg_logits
+
+ def _auxiliary_head_forward_train(self, x, img_metas, gt_semantic_seg):
+ """Run forward function and calculate loss for auxiliary head in
+ training."""
+ losses = dict()
+ if isinstance(self.auxiliary_head, nn.ModuleList):
+ for idx, aux_head in enumerate(self.auxiliary_head):
+ loss_aux = aux_head.forward_train(x, img_metas,
+ gt_semantic_seg,
+ self.train_cfg)
+ losses.update(add_prefix(loss_aux, f'aux_{idx}'))
+ else:
+ loss_aux = self.auxiliary_head.forward_train(
+ x, img_metas, gt_semantic_seg, self.train_cfg)
+ losses.update(add_prefix(loss_aux, 'aux'))
+
+ return losses
+
+ def forward_dummy(self, img):
+ """Dummy forward function."""
+ seg_logit = self.encode_decode(img, None)
+
+ return seg_logit
+
+ def forward_train(self, img, img_metas, gt_semantic_seg):
+ """Forward function for training.
+
+ Args:
+ img (Tensor): Input images.
+ img_metas (list[dict]): List of image info dict where each dict
+ has: 'img_shape', 'scale_factor', 'flip', and may also contain
+ 'filename', 'ori_shape', 'pad_shape', and 'img_norm_cfg'.
+ For details on the values of these keys see
+ `mmseg/datasets/pipelines/formatting.py:Collect`.
+ gt_semantic_seg (Tensor): Semantic segmentation masks
+ used if the architecture supports semantic segmentation task.
+
+ Returns:
+ dict[str, Tensor]: a dictionary of loss components
+ """
+
+
+ if additional_channel == 'twohands':
+
+ img_h, img_w = img.shape[2], img.shape[3]; target_aspect_ratio = img_h / img_w
+ aux_list = torch.zeros((img.shape[0], 1, img.shape[2], img.shape[3])).to(img.device)
+ for i in range(img.shape[0]):
+ img_file = img_metas[i]['filename']
+ if use_ccda:
+ path = os.path.join(os.path.dirname(os.path.dirname(img_file)), 'pred_twohands_ccda')
+ else:
+ path = os.path.join(os.path.dirname(os.path.dirname(img_file)), 'pred_twohands')
+ fname = os.path.basename(img_file).split('.')[0] + '.png'
+ aux_file = os.path.join(path, fname)
+
+ aux = Image.open(aux_file); aux_w, aux_h = aux.size[0], aux.size[1]
+ if aux_h / aux_w < target_aspect_ratio:
+ new_aux_h = int(target_aspect_ratio * aux_w)
+ aux = ImageOps.pad(aux, (aux_w, new_aux_h), centering=(0,0))
+ else:
+ new_aux_w = int(aux_h / target_aspect_ratio)
+ aux = ImageOps.pad(aux, (new_aux_w, aux_h), centering=(0,0))
+
+ aux = torch.from_numpy(np.array(aux.resize((img_w, img_h)))).unsqueeze(0).to(img[i].device).float()
+ aux_list[i] = aux
+
+ cat_input = torch.cat([img, aux_list], dim = 1)
+ x = self.extract_feat(cat_input)
+
+ elif additional_channel == 'twohands_cb':
+
+ img_h, img_w = img.shape[2], img.shape[3]; target_aspect_ratio = img_h / img_w
+ aux_list = torch.zeros((img.shape[0], 1, img.shape[2], img.shape[3])).to(img.device)
+ cb_list = torch.zeros((img.shape[0], 1, img.shape[2], img.shape[3])).to(img.device)
+ for i in range(img.shape[0]):
+ img_file = img_metas[i]['filename']
+ if use_ccda:
+ aux_path = os.path.join(os.path.dirname(os.path.dirname(img_file)), 'pred_twohands_ccda')
+ cb_path = os.path.join(os.path.dirname(os.path.dirname(img_file)), 'pred_cb_ccda')
+ else:
+ aux_path = os.path.join(os.path.dirname(os.path.dirname(img_file)), 'pred_twohands')
+ cb_path = os.path.join(os.path.dirname(os.path.dirname(img_file)), 'pred_cb')
+ fname = os.path.basename(img_file).split('.')[0] + '.png'
+ aux_file = os.path.join(aux_path, fname)
+ cb_file = os.path.join(cb_path, fname)
+
+ aux = Image.open(aux_file); aux_w, aux_h = aux.size[0], aux.size[1]
+ cb = Image.open(cb_file); cb_w, cb_h = cb.size[0], cb.size[1]
+ if aux_h / aux_w < target_aspect_ratio:
+ new_aux_h = int(target_aspect_ratio * aux_w)
+ aux = ImageOps.pad(aux, (aux_w, new_aux_h), centering=(0,0))
+ cb = ImageOps.pad(cb, (aux_w, new_aux_h), centering=(0,0))
+ else:
+ new_aux_w = int(aux_h / target_aspect_ratio)
+ aux = ImageOps.pad(aux, (new_aux_w, aux_h), centering=(0,0))
+ cb = ImageOps.pad(cb, (new_aux_w, aux_h), centering=(0,0))
+
+ aux = torch.from_numpy(np.array(aux.resize((img_w, img_h)))).unsqueeze(0).to(img[i].device).float()
+ aux_list[i] = aux
+ cb = torch.from_numpy(np.array(cb.resize((img_w, img_h)))).unsqueeze(0).to(img[i].device).float()
+ cb_list[i] = cb
+
+ # pdb.set_trace()
+ cat_input = torch.cat([img, aux_list, cb_list], dim = 1)
+ x = self.extract_feat(cat_input)
+
+ else:
+
+ x = self.extract_feat(img)
+
+ losses = dict()
+
+ loss_decode = self._decode_head_forward_train(x, img_metas,
+ gt_semantic_seg)
+ losses.update(loss_decode)
+
+ if self.with_auxiliary_head:
+ loss_aux = self._auxiliary_head_forward_train(
+ x, img_metas, gt_semantic_seg)
+ losses.update(loss_aux)
+
+ return losses
+
+ # TODO refactor
+ def slide_inference(self, img, img_meta, rescale):
+ """Inference by sliding-window with overlap.
+
+ If h_crop > h_img or w_crop > w_img, the small patch will be used to
+ decode without padding.
+ """
+
+ h_stride, w_stride = self.test_cfg.stride
+ h_crop, w_crop = self.test_cfg.crop_size
+ batch_size, _, h_img, w_img = img.size()
+ num_classes = self.num_classes
+ h_grids = max(h_img - h_crop + h_stride - 1, 0) // h_stride + 1
+ w_grids = max(w_img - w_crop + w_stride - 1, 0) // w_stride + 1
+ preds = img.new_zeros((batch_size, num_classes, h_img, w_img))
+ count_mat = img.new_zeros((batch_size, 1, h_img, w_img))
+ for h_idx in range(h_grids):
+ for w_idx in range(w_grids):
+ y1 = h_idx * h_stride
+ x1 = w_idx * w_stride
+ y2 = min(y1 + h_crop, h_img)
+ x2 = min(x1 + w_crop, w_img)
+ y1 = max(y2 - h_crop, 0)
+ x1 = max(x2 - w_crop, 0)
+ crop_img = img[:, :, y1:y2, x1:x2]
+ crop_seg_logit = self.encode_decode(crop_img, img_meta)
+ preds += F.pad(crop_seg_logit,
+ (int(x1), int(preds.shape[3] - x2), int(y1),
+ int(preds.shape[2] - y2)))
+
+ count_mat[:, :, y1:y2, x1:x2] += 1
+ assert (count_mat == 0).sum() == 0
+ if torch.onnx.is_in_onnx_export():
+ # cast count_mat to constant while exporting to ONNX
+ count_mat = torch.from_numpy(
+ count_mat.cpu().detach().numpy()).to(device=img.device)
+ preds = preds / count_mat
+ if rescale:
+ preds = resize(
+ preds,
+ size=img_meta[0]['ori_shape'][:2],
+ mode='bilinear',
+ align_corners=self.align_corners,
+ warning=False)
+ return preds
+
+ def whole_inference(self, img, img_meta, rescale):
+ """Inference with full image."""
+
+ seg_logit = self.encode_decode(img, img_meta)
+ if rescale:
+ # support dynamic shape for onnx
+ if torch.onnx.is_in_onnx_export():
+ size = img.shape[2:]
+ else:
+ size = img_meta[0]['ori_shape'][:2]
+ seg_logit = resize(
+ seg_logit,
+ size=size,
+ mode='bilinear',
+ align_corners=self.align_corners,
+ warning=False)
+
+ return seg_logit
+
+ def inference(self, img, img_meta, rescale):
+ """Inference with slide/whole style.
+
+ Args:
+ img (Tensor): The input image of shape (N, 3, H, W).
+ img_meta (dict): Image info dict where each dict has: 'img_shape',
+ 'scale_factor', 'flip', and may also contain
+ 'filename', 'ori_shape', 'pad_shape', and 'img_norm_cfg'.
+ For details on the values of these keys see
+ `mmseg/datasets/pipelines/formatting.py:Collect`.
+ rescale (bool): Whether rescale back to original shape.
+
+ Returns:
+ Tensor: The output segmentation map.
+ """
+
+ assert self.test_cfg.mode in ['slide', 'whole']
+ ori_shape = img_meta[0]['ori_shape']
+ assert all(_['ori_shape'] == ori_shape for _ in img_meta)
+ if self.test_cfg.mode == 'slide':
+ seg_logit = self.slide_inference(img, img_meta, rescale)
+ else:
+ seg_logit = self.whole_inference(img, img_meta, rescale)
+ output = F.softmax(seg_logit, dim=1)
+ flip = img_meta[0]['flip']
+ if flip:
+ flip_direction = img_meta[0]['flip_direction']
+ assert flip_direction in ['horizontal', 'vertical']
+ if flip_direction == 'horizontal':
+ output = output.flip(dims=(3, ))
+ elif flip_direction == 'vertical':
+ output = output.flip(dims=(2, ))
+
+ return output
+
+ def simple_test(self, img, img_meta, rescale=True):
+ """Simple test with single image."""
+ seg_logit = self.inference(img, img_meta, rescale)
+ seg_pred = seg_logit.argmax(dim=1)
+ if torch.onnx.is_in_onnx_export():
+ # our inference backend only support 4D output
+ seg_pred = seg_pred.unsqueeze(0)
+ return seg_pred
+ seg_pred = seg_pred.cpu().numpy()
+ # unravel batch dim
+ seg_pred = list(seg_pred)
+ return seg_pred
+
+ def aug_test(self, imgs, img_metas, rescale=True):
+ """Test with augmentations.
+
+ Only rescale=True is supported.
+ """
+ # aug_test rescale all imgs back to ori_shape for now
+ assert rescale
+ # to save memory, we get augmented seg logit inplace
+ seg_logit = self.inference(imgs[0], img_metas[0], rescale)
+ for i in range(1, len(imgs)):
+ cur_seg_logit = self.inference(imgs[i], img_metas[i], rescale)
+ seg_logit += cur_seg_logit
+ seg_logit /= len(imgs)
+ seg_pred = seg_logit.argmax(dim=1)
+ seg_pred = seg_pred.cpu().numpy()
+ # unravel batch dim
+ seg_pred = list(seg_pred)
+ return seg_pred
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..6d8329021bc45dffb076751351bb0b44f56464f0
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/__init__.py
@@ -0,0 +1,16 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .embed import PatchEmbed
+from .inverted_residual import InvertedResidual, InvertedResidualV3
+from .make_divisible import make_divisible
+from .res_layer import ResLayer
+from .se_layer import SELayer
+from .self_attention_block import SelfAttentionBlock
+from .shape_convert import (nchw2nlc2nchw, nchw_to_nlc, nlc2nchw2nlc,
+ nlc_to_nchw)
+from .up_conv_block import UpConvBlock
+
+__all__ = [
+ 'ResLayer', 'SelfAttentionBlock', 'make_divisible', 'InvertedResidual',
+ 'UpConvBlock', 'InvertedResidualV3', 'SELayer', 'PatchEmbed',
+ 'nchw_to_nlc', 'nlc_to_nchw', 'nchw2nlc2nchw', 'nlc2nchw2nlc'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/embed.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/embed.py
new file mode 100644
index 0000000000000000000000000000000000000000..1515675e1eeec92ca1b6d417c5e202ce8aecc35f
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/embed.py
@@ -0,0 +1,330 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import math
+from typing import Sequence
+
+import torch.nn as nn
+import torch.nn.functional as F
+from mmcv.cnn import build_conv_layer, build_norm_layer
+from mmcv.runner.base_module import BaseModule
+from mmcv.utils import to_2tuple
+
+
+class AdaptivePadding(nn.Module):
+ """Applies padding to input (if needed) so that input can get fully covered
+ by filter you specified. It support two modes "same" and "corner". The
+ "same" mode is same with "SAME" padding mode in TensorFlow, pad zero around
+ input. The "corner" mode would pad zero to bottom right.
+
+ Args:
+ kernel_size (int | tuple): Size of the kernel:
+ stride (int | tuple): Stride of the filter. Default: 1:
+ dilation (int | tuple): Spacing between kernel elements.
+ Default: 1.
+ padding (str): Support "same" and "corner", "corner" mode
+ would pad zero to bottom right, and "same" mode would
+ pad zero around input. Default: "corner".
+ Example:
+ >>> kernel_size = 16
+ >>> stride = 16
+ >>> dilation = 1
+ >>> input = torch.rand(1, 1, 15, 17)
+ >>> adap_pad = AdaptivePadding(
+ >>> kernel_size=kernel_size,
+ >>> stride=stride,
+ >>> dilation=dilation,
+ >>> padding="corner")
+ >>> out = adap_pad(input)
+ >>> assert (out.shape[2], out.shape[3]) == (16, 32)
+ >>> input = torch.rand(1, 1, 16, 17)
+ >>> out = adap_pad(input)
+ >>> assert (out.shape[2], out.shape[3]) == (16, 32)
+ """
+
+ def __init__(self, kernel_size=1, stride=1, dilation=1, padding='corner'):
+
+ super(AdaptivePadding, self).__init__()
+
+ assert padding in ('same', 'corner')
+
+ kernel_size = to_2tuple(kernel_size)
+ stride = to_2tuple(stride)
+ dilation = to_2tuple(dilation)
+
+ self.padding = padding
+ self.kernel_size = kernel_size
+ self.stride = stride
+ self.dilation = dilation
+
+ def get_pad_shape(self, input_shape):
+ input_h, input_w = input_shape
+ kernel_h, kernel_w = self.kernel_size
+ stride_h, stride_w = self.stride
+ output_h = math.ceil(input_h / stride_h)
+ output_w = math.ceil(input_w / stride_w)
+ pad_h = max((output_h - 1) * stride_h +
+ (kernel_h - 1) * self.dilation[0] + 1 - input_h, 0)
+ pad_w = max((output_w - 1) * stride_w +
+ (kernel_w - 1) * self.dilation[1] + 1 - input_w, 0)
+ return pad_h, pad_w
+
+ def forward(self, x):
+ pad_h, pad_w = self.get_pad_shape(x.size()[-2:])
+ if pad_h > 0 or pad_w > 0:
+ if self.padding == 'corner':
+ x = F.pad(x, [0, pad_w, 0, pad_h])
+ elif self.padding == 'same':
+ x = F.pad(x, [
+ pad_w // 2, pad_w - pad_w // 2, pad_h // 2,
+ pad_h - pad_h // 2
+ ])
+ return x
+
+
+class PatchEmbed(BaseModule):
+ """Image to Patch Embedding.
+
+ We use a conv layer to implement PatchEmbed.
+
+ Args:
+ in_channels (int): The num of input channels. Default: 3
+ embed_dims (int): The dimensions of embedding. Default: 768
+ conv_type (str): The config dict for embedding
+ conv layer type selection. Default: "Conv2d".
+ kernel_size (int): The kernel_size of embedding conv. Default: 16.
+ stride (int, optional): The slide stride of embedding conv.
+ Default: None (Would be set as `kernel_size`).
+ padding (int | tuple | string ): The padding length of
+ embedding conv. When it is a string, it means the mode
+ of adaptive padding, support "same" and "corner" now.
+ Default: "corner".
+ dilation (int): The dilation rate of embedding conv. Default: 1.
+ bias (bool): Bias of embed conv. Default: True.
+ norm_cfg (dict, optional): Config dict for normalization layer.
+ Default: None.
+ input_size (int | tuple | None): The size of input, which will be
+ used to calculate the out size. Only work when `dynamic_size`
+ is False. Default: None.
+ init_cfg (`mmcv.ConfigDict`, optional): The Config for initialization.
+ Default: None.
+ """
+
+ def __init__(self,
+ in_channels=3,
+ embed_dims=768,
+ conv_type='Conv2d',
+ kernel_size=16,
+ stride=None,
+ padding='corner',
+ dilation=1,
+ bias=True,
+ norm_cfg=None,
+ input_size=None,
+ init_cfg=None):
+ super(PatchEmbed, self).__init__(init_cfg=init_cfg)
+
+ self.embed_dims = embed_dims
+ if stride is None:
+ stride = kernel_size
+
+ kernel_size = to_2tuple(kernel_size)
+ stride = to_2tuple(stride)
+ dilation = to_2tuple(dilation)
+
+ if isinstance(padding, str):
+ self.adap_padding = AdaptivePadding(
+ kernel_size=kernel_size,
+ stride=stride,
+ dilation=dilation,
+ padding=padding)
+ # disable the padding of conv
+ padding = 0
+ else:
+ self.adap_padding = None
+ padding = to_2tuple(padding)
+
+ self.projection = build_conv_layer(
+ dict(type=conv_type),
+ in_channels=in_channels,
+ out_channels=embed_dims,
+ kernel_size=kernel_size,
+ stride=stride,
+ padding=padding,
+ dilation=dilation,
+ bias=bias)
+
+ if norm_cfg is not None:
+ self.norm = build_norm_layer(norm_cfg, embed_dims)[1]
+ else:
+ self.norm = None
+
+ if input_size:
+ input_size = to_2tuple(input_size)
+ # `init_out_size` would be used outside to
+ # calculate the num_patches
+ # when `use_abs_pos_embed` outside
+ self.init_input_size = input_size
+ if self.adap_padding:
+ pad_h, pad_w = self.adap_padding.get_pad_shape(input_size)
+ input_h, input_w = input_size
+ input_h = input_h + pad_h
+ input_w = input_w + pad_w
+ input_size = (input_h, input_w)
+
+ # https://pytorch.org/docs/stable/generated/torch.nn.Conv2d.html
+ h_out = (input_size[0] + 2 * padding[0] - dilation[0] *
+ (kernel_size[0] - 1) - 1) // stride[0] + 1
+ w_out = (input_size[1] + 2 * padding[1] - dilation[1] *
+ (kernel_size[1] - 1) - 1) // stride[1] + 1
+ self.init_out_size = (h_out, w_out)
+ else:
+ self.init_input_size = None
+ self.init_out_size = None
+
+ def forward(self, x):
+ """
+ Args:
+ x (Tensor): Has shape (B, C, H, W). In most case, C is 3.
+
+ Returns:
+ tuple: Contains merged results and its spatial shape.
+
+ - x (Tensor): Has shape (B, out_h * out_w, embed_dims)
+ - out_size (tuple[int]): Spatial shape of x, arrange as
+ (out_h, out_w).
+ """
+
+ if self.adap_padding:
+ x = self.adap_padding(x)
+
+ x = self.projection(x)
+ out_size = (x.shape[2], x.shape[3])
+ x = x.flatten(2).transpose(1, 2)
+ if self.norm is not None:
+ x = self.norm(x)
+ return x, out_size
+
+
+class PatchMerging(BaseModule):
+ """Merge patch feature map.
+
+ This layer groups feature map by kernel_size, and applies norm and linear
+ layers to the grouped feature map. Our implementation uses `nn.Unfold` to
+ merge patch, which is about 25% faster than original implementation.
+ Instead, we need to modify pretrained models for compatibility.
+
+ Args:
+ in_channels (int): The num of input channels.
+ out_channels (int): The num of output channels.
+ kernel_size (int | tuple, optional): the kernel size in the unfold
+ layer. Defaults to 2.
+ stride (int | tuple, optional): the stride of the sliding blocks in the
+ unfold layer. Default: None. (Would be set as `kernel_size`)
+ padding (int | tuple | string ): The padding length of
+ embedding conv. When it is a string, it means the mode
+ of adaptive padding, support "same" and "corner" now.
+ Default: "corner".
+ dilation (int | tuple, optional): dilation parameter in the unfold
+ layer. Default: 1.
+ bias (bool, optional): Whether to add bias in linear layer or not.
+ Defaults: False.
+ norm_cfg (dict, optional): Config dict for normalization layer.
+ Default: dict(type='LN').
+ init_cfg (dict, optional): The extra config for initialization.
+ Default: None.
+ """
+
+ def __init__(self,
+ in_channels,
+ out_channels,
+ kernel_size=2,
+ stride=None,
+ padding='corner',
+ dilation=1,
+ bias=False,
+ norm_cfg=dict(type='LN'),
+ init_cfg=None):
+ super().__init__(init_cfg=init_cfg)
+ self.in_channels = in_channels
+ self.out_channels = out_channels
+ if stride:
+ stride = stride
+ else:
+ stride = kernel_size
+
+ kernel_size = to_2tuple(kernel_size)
+ stride = to_2tuple(stride)
+ dilation = to_2tuple(dilation)
+
+ if isinstance(padding, str):
+ self.adap_padding = AdaptivePadding(
+ kernel_size=kernel_size,
+ stride=stride,
+ dilation=dilation,
+ padding=padding)
+ # disable the padding of unfold
+ padding = 0
+ else:
+ self.adap_padding = None
+
+ padding = to_2tuple(padding)
+ self.sampler = nn.Unfold(
+ kernel_size=kernel_size,
+ dilation=dilation,
+ padding=padding,
+ stride=stride)
+
+ sample_dim = kernel_size[0] * kernel_size[1] * in_channels
+
+ if norm_cfg is not None:
+ self.norm = build_norm_layer(norm_cfg, sample_dim)[1]
+ else:
+ self.norm = None
+
+ self.reduction = nn.Linear(sample_dim, out_channels, bias=bias)
+
+ def forward(self, x, input_size):
+ """
+ Args:
+ x (Tensor): Has shape (B, H*W, C_in).
+ input_size (tuple[int]): The spatial shape of x, arrange as (H, W).
+ Default: None.
+
+ Returns:
+ tuple: Contains merged results and its spatial shape.
+
+ - x (Tensor): Has shape (B, Merged_H * Merged_W, C_out)
+ - out_size (tuple[int]): Spatial shape of x, arrange as
+ (Merged_H, Merged_W).
+ """
+ B, L, C = x.shape
+ assert isinstance(input_size, Sequence), f'Expect ' \
+ f'input_size is ' \
+ f'`Sequence` ' \
+ f'but get {input_size}'
+
+ H, W = input_size
+ assert L == H * W, 'input feature has wrong size'
+
+ x = x.view(B, H, W, C).permute([0, 3, 1, 2]) # B, C, H, W
+ # Use nn.Unfold to merge patch. About 25% faster than original method,
+ # but need to modify pretrained model for compatibility
+
+ if self.adap_padding:
+ x = self.adap_padding(x)
+ H, W = x.shape[-2:]
+
+ x = self.sampler(x)
+ # if kernel_size=2 and stride=2, x should has shape (B, 4*C, H/2*W/2)
+
+ out_h = (H + 2 * self.sampler.padding[0] - self.sampler.dilation[0] *
+ (self.sampler.kernel_size[0] - 1) -
+ 1) // self.sampler.stride[0] + 1
+ out_w = (W + 2 * self.sampler.padding[1] - self.sampler.dilation[1] *
+ (self.sampler.kernel_size[1] - 1) -
+ 1) // self.sampler.stride[1] + 1
+
+ output_size = (out_h, out_w)
+ x = x.transpose(1, 2) # B, H/2*W/2, 4*C
+ x = self.norm(x) if self.norm else x
+ x = self.reduction(x)
+ return x, output_size
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/inverted_residual.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/inverted_residual.py
new file mode 100644
index 0000000000000000000000000000000000000000..c9cda76822a45baa0cbd27c98f1e7196e1e26e9a
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/inverted_residual.py
@@ -0,0 +1,213 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from mmcv.cnn import ConvModule
+from torch import nn
+from torch.utils import checkpoint as cp
+
+from .se_layer import SELayer
+
+
+class InvertedResidual(nn.Module):
+ """InvertedResidual block for MobileNetV2.
+
+ Args:
+ in_channels (int): The input channels of the InvertedResidual block.
+ out_channels (int): The output channels of the InvertedResidual block.
+ stride (int): Stride of the middle (first) 3x3 convolution.
+ expand_ratio (int): Adjusts number of channels of the hidden layer
+ in InvertedResidual by this amount.
+ dilation (int): Dilation rate of depthwise conv. Default: 1
+ conv_cfg (dict): Config dict for convolution layer.
+ Default: None, which means using conv2d.
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='BN').
+ act_cfg (dict): Config dict for activation layer.
+ Default: dict(type='ReLU6').
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save some
+ memory while slowing down the training speed. Default: False.
+
+ Returns:
+ Tensor: The output tensor.
+ """
+
+ def __init__(self,
+ in_channels,
+ out_channels,
+ stride,
+ expand_ratio,
+ dilation=1,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU6'),
+ with_cp=False,
+ **kwargs):
+ super(InvertedResidual, self).__init__()
+ self.stride = stride
+ assert stride in [1, 2], f'stride must in [1, 2]. ' \
+ f'But received {stride}.'
+ self.with_cp = with_cp
+ self.use_res_connect = self.stride == 1 and in_channels == out_channels
+ hidden_dim = int(round(in_channels * expand_ratio))
+
+ layers = []
+ if expand_ratio != 1:
+ layers.append(
+ ConvModule(
+ in_channels=in_channels,
+ out_channels=hidden_dim,
+ kernel_size=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg,
+ **kwargs))
+ layers.extend([
+ ConvModule(
+ in_channels=hidden_dim,
+ out_channels=hidden_dim,
+ kernel_size=3,
+ stride=stride,
+ padding=dilation,
+ dilation=dilation,
+ groups=hidden_dim,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg,
+ **kwargs),
+ ConvModule(
+ in_channels=hidden_dim,
+ out_channels=out_channels,
+ kernel_size=1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=None,
+ **kwargs)
+ ])
+ self.conv = nn.Sequential(*layers)
+
+ def forward(self, x):
+
+ def _inner_forward(x):
+ if self.use_res_connect:
+ return x + self.conv(x)
+ else:
+ return self.conv(x)
+
+ if self.with_cp and x.requires_grad:
+ out = cp.checkpoint(_inner_forward, x)
+ else:
+ out = _inner_forward(x)
+
+ return out
+
+
+class InvertedResidualV3(nn.Module):
+ """Inverted Residual Block for MobileNetV3.
+
+ Args:
+ in_channels (int): The input channels of this Module.
+ out_channels (int): The output channels of this Module.
+ mid_channels (int): The input channels of the depthwise convolution.
+ kernel_size (int): The kernel size of the depthwise convolution.
+ Default: 3.
+ stride (int): The stride of the depthwise convolution. Default: 1.
+ se_cfg (dict): Config dict for se layer. Default: None, which means no
+ se layer.
+ with_expand_conv (bool): Use expand conv or not. If set False,
+ mid_channels must be the same with in_channels. Default: True.
+ conv_cfg (dict): Config dict for convolution layer. Default: None,
+ which means using conv2d.
+ norm_cfg (dict): Config dict for normalization layer.
+ Default: dict(type='BN').
+ act_cfg (dict): Config dict for activation layer.
+ Default: dict(type='ReLU').
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save some
+ memory while slowing down the training speed. Default: False.
+
+ Returns:
+ Tensor: The output tensor.
+ """
+
+ def __init__(self,
+ in_channels,
+ out_channels,
+ mid_channels,
+ kernel_size=3,
+ stride=1,
+ se_cfg=None,
+ with_expand_conv=True,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ with_cp=False):
+ super(InvertedResidualV3, self).__init__()
+ self.with_res_shortcut = (stride == 1 and in_channels == out_channels)
+ assert stride in [1, 2]
+ self.with_cp = with_cp
+ self.with_se = se_cfg is not None
+ self.with_expand_conv = with_expand_conv
+
+ if self.with_se:
+ assert isinstance(se_cfg, dict)
+ if not self.with_expand_conv:
+ assert mid_channels == in_channels
+
+ if self.with_expand_conv:
+ self.expand_conv = ConvModule(
+ in_channels=in_channels,
+ out_channels=mid_channels,
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ self.depthwise_conv = ConvModule(
+ in_channels=mid_channels,
+ out_channels=mid_channels,
+ kernel_size=kernel_size,
+ stride=stride,
+ padding=kernel_size // 2,
+ groups=mid_channels,
+ conv_cfg=dict(
+ type='Conv2dAdaptivePadding') if stride == 2 else conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+
+ if self.with_se:
+ self.se = SELayer(**se_cfg)
+
+ self.linear_conv = ConvModule(
+ in_channels=mid_channels,
+ out_channels=out_channels,
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=None)
+
+ def forward(self, x):
+
+ def _inner_forward(x):
+ out = x
+
+ if self.with_expand_conv:
+ out = self.expand_conv(out)
+
+ out = self.depthwise_conv(out)
+
+ if self.with_se:
+ out = self.se(out)
+
+ out = self.linear_conv(out)
+
+ if self.with_res_shortcut:
+ return x + out
+ else:
+ return out
+
+ if self.with_cp and x.requires_grad:
+ out = cp.checkpoint(_inner_forward, x)
+ else:
+ out = _inner_forward(x)
+
+ return out
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/make_divisible.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/make_divisible.py
new file mode 100644
index 0000000000000000000000000000000000000000..ed42c2eeea2a6aed03a0be5516b8d1ef1139e486
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/make_divisible.py
@@ -0,0 +1,28 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+def make_divisible(value, divisor, min_value=None, min_ratio=0.9):
+ """Make divisible function.
+
+ This function rounds the channel number to the nearest value that can be
+ divisible by the divisor. It is taken from the original tf repo. It ensures
+ that all layers have a channel number that is divisible by divisor. It can
+ be seen here: https://github.com/tensorflow/models/blob/master/research/slim/nets/mobilenet/mobilenet.py # noqa
+
+ Args:
+ value (int): The original channel number.
+ divisor (int): The divisor to fully divide the channel number.
+ min_value (int): The minimum value of the output channel.
+ Default: None, means that the minimum value equal to the divisor.
+ min_ratio (float): The minimum ratio of the rounded channel number to
+ the original channel number. Default: 0.9.
+
+ Returns:
+ int: The modified output channel number.
+ """
+
+ if min_value is None:
+ min_value = divisor
+ new_value = max(min_value, int(value + divisor / 2) // divisor * divisor)
+ # Make sure that round down does not go down by more than (1-min_ratio).
+ if new_value < min_ratio * value:
+ new_value += divisor
+ return new_value
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/res_layer.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/res_layer.py
new file mode 100644
index 0000000000000000000000000000000000000000..190a0c5d5a63846c9a42c6622635cf2456bd6635
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/res_layer.py
@@ -0,0 +1,96 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from mmcv.cnn import build_conv_layer, build_norm_layer
+from mmcv.runner import Sequential
+from torch import nn as nn
+
+
+class ResLayer(Sequential):
+ """ResLayer to build ResNet style backbone.
+
+ Args:
+ block (nn.Module): block used to build ResLayer.
+ inplanes (int): inplanes of block.
+ planes (int): planes of block.
+ num_blocks (int): number of blocks.
+ stride (int): stride of the first block. Default: 1
+ avg_down (bool): Use AvgPool instead of stride conv when
+ downsampling in the bottleneck. Default: False
+ conv_cfg (dict): dictionary to construct and config conv layer.
+ Default: None
+ norm_cfg (dict): dictionary to construct and config norm layer.
+ Default: dict(type='BN')
+ multi_grid (int | None): Multi grid dilation rates of last
+ stage. Default: None
+ contract_dilation (bool): Whether contract first dilation of each layer
+ Default: False
+ """
+
+ def __init__(self,
+ block,
+ inplanes,
+ planes,
+ num_blocks,
+ stride=1,
+ dilation=1,
+ avg_down=False,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ multi_grid=None,
+ contract_dilation=False,
+ **kwargs):
+ self.block = block
+
+ downsample = None
+ if stride != 1 or inplanes != planes * block.expansion:
+ downsample = []
+ conv_stride = stride
+ if avg_down:
+ conv_stride = 1
+ downsample.append(
+ nn.AvgPool2d(
+ kernel_size=stride,
+ stride=stride,
+ ceil_mode=True,
+ count_include_pad=False))
+ downsample.extend([
+ build_conv_layer(
+ conv_cfg,
+ inplanes,
+ planes * block.expansion,
+ kernel_size=1,
+ stride=conv_stride,
+ bias=False),
+ build_norm_layer(norm_cfg, planes * block.expansion)[1]
+ ])
+ downsample = nn.Sequential(*downsample)
+
+ layers = []
+ if multi_grid is None:
+ if dilation > 1 and contract_dilation:
+ first_dilation = dilation // 2
+ else:
+ first_dilation = dilation
+ else:
+ first_dilation = multi_grid[0]
+ layers.append(
+ block(
+ inplanes=inplanes,
+ planes=planes,
+ stride=stride,
+ dilation=first_dilation,
+ downsample=downsample,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ **kwargs))
+ inplanes = planes * block.expansion
+ for i in range(1, num_blocks):
+ layers.append(
+ block(
+ inplanes=inplanes,
+ planes=planes,
+ stride=1,
+ dilation=dilation if multi_grid is None else multi_grid[i],
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ **kwargs))
+ super(ResLayer, self).__init__(*layers)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/se_layer.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/se_layer.py
new file mode 100644
index 0000000000000000000000000000000000000000..16f52aa5c03b982c0d5f9ab9f145f48515a7ffa2
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/se_layer.py
@@ -0,0 +1,58 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import mmcv
+import torch.nn as nn
+from mmcv.cnn import ConvModule
+
+from .make_divisible import make_divisible
+
+
+class SELayer(nn.Module):
+ """Squeeze-and-Excitation Module.
+
+ Args:
+ channels (int): The input (and output) channels of the SE layer.
+ ratio (int): Squeeze ratio in SELayer, the intermediate channel will be
+ ``int(channels/ratio)``. Default: 16.
+ conv_cfg (None or dict): Config dict for convolution layer.
+ Default: None, which means using conv2d.
+ act_cfg (dict or Sequence[dict]): Config dict for activation layer.
+ If act_cfg is a dict, two activation layers will be configured
+ by this dict. If act_cfg is a sequence of dicts, the first
+ activation layer will be configured by the first dict and the
+ second activation layer will be configured by the second dict.
+ Default: (dict(type='ReLU'), dict(type='HSigmoid', bias=3.0,
+ divisor=6.0)).
+ """
+
+ def __init__(self,
+ channels,
+ ratio=16,
+ conv_cfg=None,
+ act_cfg=(dict(type='ReLU'),
+ dict(type='HSigmoid', bias=3.0, divisor=6.0))):
+ super(SELayer, self).__init__()
+ if isinstance(act_cfg, dict):
+ act_cfg = (act_cfg, act_cfg)
+ assert len(act_cfg) == 2
+ assert mmcv.is_tuple_of(act_cfg, dict)
+ self.global_avgpool = nn.AdaptiveAvgPool2d(1)
+ self.conv1 = ConvModule(
+ in_channels=channels,
+ out_channels=make_divisible(channels // ratio, 8),
+ kernel_size=1,
+ stride=1,
+ conv_cfg=conv_cfg,
+ act_cfg=act_cfg[0])
+ self.conv2 = ConvModule(
+ in_channels=make_divisible(channels // ratio, 8),
+ out_channels=channels,
+ kernel_size=1,
+ stride=1,
+ conv_cfg=conv_cfg,
+ act_cfg=act_cfg[1])
+
+ def forward(self, x):
+ out = self.global_avgpool(x)
+ out = self.conv1(out)
+ out = self.conv2(out)
+ return x * out
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/self_attention_block.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/self_attention_block.py
new file mode 100644
index 0000000000000000000000000000000000000000..c945fa7168208fff513c4d397ad2c9a7ac4383ad
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/self_attention_block.py
@@ -0,0 +1,160 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+from mmcv.cnn import ConvModule, constant_init
+from torch import nn as nn
+from torch.nn import functional as F
+
+
+class SelfAttentionBlock(nn.Module):
+ """General self-attention block/non-local block.
+
+ Please refer to https://arxiv.org/abs/1706.03762 for details about key,
+ query and value.
+
+ Args:
+ key_in_channels (int): Input channels of key feature.
+ query_in_channels (int): Input channels of query feature.
+ channels (int): Output channels of key/query transform.
+ out_channels (int): Output channels.
+ share_key_query (bool): Whether share projection weight between key
+ and query projection.
+ query_downsample (nn.Module): Query downsample module.
+ key_downsample (nn.Module): Key downsample module.
+ key_query_num_convs (int): Number of convs for key/query projection.
+ value_num_convs (int): Number of convs for value projection.
+ matmul_norm (bool): Whether normalize attention map with sqrt of
+ channels
+ with_out (bool): Whether use out projection.
+ conv_cfg (dict|None): Config of conv layers.
+ norm_cfg (dict|None): Config of norm layers.
+ act_cfg (dict|None): Config of activation layers.
+ """
+
+ def __init__(self, key_in_channels, query_in_channels, channels,
+ out_channels, share_key_query, query_downsample,
+ key_downsample, key_query_num_convs, value_out_num_convs,
+ key_query_norm, value_out_norm, matmul_norm, with_out,
+ conv_cfg, norm_cfg, act_cfg):
+ super(SelfAttentionBlock, self).__init__()
+ if share_key_query:
+ assert key_in_channels == query_in_channels
+ self.key_in_channels = key_in_channels
+ self.query_in_channels = query_in_channels
+ self.out_channels = out_channels
+ self.channels = channels
+ self.share_key_query = share_key_query
+ self.conv_cfg = conv_cfg
+ self.norm_cfg = norm_cfg
+ self.act_cfg = act_cfg
+ self.key_project = self.build_project(
+ key_in_channels,
+ channels,
+ num_convs=key_query_num_convs,
+ use_conv_module=key_query_norm,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ if share_key_query:
+ self.query_project = self.key_project
+ else:
+ self.query_project = self.build_project(
+ query_in_channels,
+ channels,
+ num_convs=key_query_num_convs,
+ use_conv_module=key_query_norm,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ self.value_project = self.build_project(
+ key_in_channels,
+ channels if with_out else out_channels,
+ num_convs=value_out_num_convs,
+ use_conv_module=value_out_norm,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ if with_out:
+ self.out_project = self.build_project(
+ channels,
+ out_channels,
+ num_convs=value_out_num_convs,
+ use_conv_module=value_out_norm,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ else:
+ self.out_project = None
+
+ self.query_downsample = query_downsample
+ self.key_downsample = key_downsample
+ self.matmul_norm = matmul_norm
+
+ self.init_weights()
+
+ def init_weights(self):
+ """Initialize weight of later layer."""
+ if self.out_project is not None:
+ if not isinstance(self.out_project, ConvModule):
+ constant_init(self.out_project, 0)
+
+ def build_project(self, in_channels, channels, num_convs, use_conv_module,
+ conv_cfg, norm_cfg, act_cfg):
+ """Build projection layer for key/query/value/out."""
+ if use_conv_module:
+ convs = [
+ ConvModule(
+ in_channels,
+ channels,
+ 1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ ]
+ for _ in range(num_convs - 1):
+ convs.append(
+ ConvModule(
+ channels,
+ channels,
+ 1,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg))
+ else:
+ convs = [nn.Conv2d(in_channels, channels, 1)]
+ for _ in range(num_convs - 1):
+ convs.append(nn.Conv2d(channels, channels, 1))
+ if len(convs) > 1:
+ convs = nn.Sequential(*convs)
+ else:
+ convs = convs[0]
+ return convs
+
+ def forward(self, query_feats, key_feats):
+ """Forward function."""
+ batch_size = query_feats.size(0)
+ query = self.query_project(query_feats)
+ if self.query_downsample is not None:
+ query = self.query_downsample(query)
+ query = query.reshape(*query.shape[:2], -1)
+ query = query.permute(0, 2, 1).contiguous()
+
+ key = self.key_project(key_feats)
+ value = self.value_project(key_feats)
+ if self.key_downsample is not None:
+ key = self.key_downsample(key)
+ value = self.key_downsample(value)
+ key = key.reshape(*key.shape[:2], -1)
+ value = value.reshape(*value.shape[:2], -1)
+ value = value.permute(0, 2, 1).contiguous()
+
+ sim_map = torch.matmul(query, key)
+ if self.matmul_norm:
+ sim_map = (self.channels**-.5) * sim_map
+ sim_map = F.softmax(sim_map, dim=-1)
+
+ context = torch.matmul(sim_map, value)
+ context = context.permute(0, 2, 1).contiguous()
+ context = context.reshape(batch_size, -1, *query_feats.shape[2:])
+ if self.out_project is not None:
+ context = self.out_project(context)
+ return context
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/shape_convert.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/shape_convert.py
new file mode 100644
index 0000000000000000000000000000000000000000..cce1e220b645d4b02df1ec2d9ed3137c8acba707
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/shape_convert.py
@@ -0,0 +1,107 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+def nlc_to_nchw(x, hw_shape):
+ """Convert [N, L, C] shape tensor to [N, C, H, W] shape tensor.
+
+ Args:
+ x (Tensor): The input tensor of shape [N, L, C] before conversion.
+ hw_shape (Sequence[int]): The height and width of output feature map.
+
+ Returns:
+ Tensor: The output tensor of shape [N, C, H, W] after conversion.
+ """
+ H, W = hw_shape
+ assert len(x.shape) == 3
+ B, L, C = x.shape
+ assert L == H * W, 'The seq_len doesn\'t match H, W'
+ return x.transpose(1, 2).reshape(B, C, H, W)
+
+
+def nchw_to_nlc(x):
+ """Flatten [N, C, H, W] shape tensor to [N, L, C] shape tensor.
+
+ Args:
+ x (Tensor): The input tensor of shape [N, C, H, W] before conversion.
+
+ Returns:
+ Tensor: The output tensor of shape [N, L, C] after conversion.
+ """
+ assert len(x.shape) == 4
+ return x.flatten(2).transpose(1, 2).contiguous()
+
+
+def nchw2nlc2nchw(module, x, contiguous=False, **kwargs):
+ """Flatten [N, C, H, W] shape tensor `x` to [N, L, C] shape tensor. Use the
+ reshaped tensor as the input of `module`, and the convert the output of
+ `module`, whose shape is.
+
+ [N, L, C], to [N, C, H, W].
+
+ Args:
+ module (Callable): A callable object the takes a tensor
+ with shape [N, L, C] as input.
+ x (Tensor): The input tensor of shape [N, C, H, W].
+ contiguous:
+ contiguous (Bool): Whether to make the tensor contiguous
+ after each shape transform.
+
+ Returns:
+ Tensor: The output tensor of shape [N, C, H, W].
+
+ Example:
+ >>> import torch
+ >>> import torch.nn as nn
+ >>> norm = nn.LayerNorm(4)
+ >>> feature_map = torch.rand(4, 4, 5, 5)
+ >>> output = nchw2nlc2nchw(norm, feature_map)
+ """
+ B, C, H, W = x.shape
+ if not contiguous:
+ x = x.flatten(2).transpose(1, 2)
+ x = module(x, **kwargs)
+ x = x.transpose(1, 2).reshape(B, C, H, W)
+ else:
+ x = x.flatten(2).transpose(1, 2).contiguous()
+ x = module(x, **kwargs)
+ x = x.transpose(1, 2).reshape(B, C, H, W).contiguous()
+ return x
+
+
+def nlc2nchw2nlc(module, x, hw_shape, contiguous=False, **kwargs):
+ """Convert [N, L, C] shape tensor `x` to [N, C, H, W] shape tensor. Use the
+ reshaped tensor as the input of `module`, and convert the output of
+ `module`, whose shape is.
+
+ [N, C, H, W], to [N, L, C].
+
+ Args:
+ module (Callable): A callable object the takes a tensor
+ with shape [N, C, H, W] as input.
+ x (Tensor): The input tensor of shape [N, L, C].
+ hw_shape: (Sequence[int]): The height and width of the
+ feature map with shape [N, C, H, W].
+ contiguous (Bool): Whether to make the tensor contiguous
+ after each shape transform.
+
+ Returns:
+ Tensor: The output tensor of shape [N, L, C].
+
+ Example:
+ >>> import torch
+ >>> import torch.nn as nn
+ >>> conv = nn.Conv2d(16, 16, 3, 1, 1)
+ >>> feature_map = torch.rand(4, 25, 16)
+ >>> output = nlc2nchw2nlc(conv, feature_map, (5, 5))
+ """
+ H, W = hw_shape
+ assert len(x.shape) == 3
+ B, L, C = x.shape
+ assert L == H * W, 'The seq_len doesn\'t match H, W'
+ if not contiguous:
+ x = x.transpose(1, 2).reshape(B, C, H, W)
+ x = module(x, **kwargs)
+ x = x.flatten(2).transpose(1, 2)
+ else:
+ x = x.transpose(1, 2).reshape(B, C, H, W).contiguous()
+ x = module(x, **kwargs)
+ x = x.flatten(2).transpose(1, 2).contiguous()
+ return x
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/up_conv_block.py b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/up_conv_block.py
new file mode 100644
index 0000000000000000000000000000000000000000..d8396d9c2cc77135946ae4b43620e7b583915421
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/models/utils/up_conv_block.py
@@ -0,0 +1,102 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+import torch.nn as nn
+from mmcv.cnn import ConvModule, build_upsample_layer
+
+
+class UpConvBlock(nn.Module):
+ """Upsample convolution block in decoder for UNet.
+
+ This upsample convolution block consists of one upsample module
+ followed by one convolution block. The upsample module expands the
+ high-level low-resolution feature map and the convolution block fuses
+ the upsampled high-level low-resolution feature map and the low-level
+ high-resolution feature map from encoder.
+
+ Args:
+ conv_block (nn.Sequential): Sequential of convolutional layers.
+ in_channels (int): Number of input channels of the high-level
+ skip_channels (int): Number of input channels of the low-level
+ high-resolution feature map from encoder.
+ out_channels (int): Number of output channels.
+ num_convs (int): Number of convolutional layers in the conv_block.
+ Default: 2.
+ stride (int): Stride of convolutional layer in conv_block. Default: 1.
+ dilation (int): Dilation rate of convolutional layer in conv_block.
+ Default: 1.
+ with_cp (bool): Use checkpoint or not. Using checkpoint will save some
+ memory while slowing down the training speed. Default: False.
+ conv_cfg (dict | None): Config dict for convolution layer.
+ Default: None.
+ norm_cfg (dict | None): Config dict for normalization layer.
+ Default: dict(type='BN').
+ act_cfg (dict | None): Config dict for activation layer in ConvModule.
+ Default: dict(type='ReLU').
+ upsample_cfg (dict): The upsample config of the upsample module in
+ decoder. Default: dict(type='InterpConv'). If the size of
+ high-level feature map is the same as that of skip feature map
+ (low-level feature map from encoder), it does not need upsample the
+ high-level feature map and the upsample_cfg is None.
+ dcn (bool): Use deformable convolution in convolutional layer or not.
+ Default: None.
+ plugins (dict): plugins for convolutional layers. Default: None.
+ """
+
+ def __init__(self,
+ conv_block,
+ in_channels,
+ skip_channels,
+ out_channels,
+ num_convs=2,
+ stride=1,
+ dilation=1,
+ with_cp=False,
+ conv_cfg=None,
+ norm_cfg=dict(type='BN'),
+ act_cfg=dict(type='ReLU'),
+ upsample_cfg=dict(type='InterpConv'),
+ dcn=None,
+ plugins=None):
+ super(UpConvBlock, self).__init__()
+ assert dcn is None, 'Not implemented yet.'
+ assert plugins is None, 'Not implemented yet.'
+
+ self.conv_block = conv_block(
+ in_channels=2 * skip_channels,
+ out_channels=out_channels,
+ num_convs=num_convs,
+ stride=stride,
+ dilation=dilation,
+ with_cp=with_cp,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg,
+ dcn=None,
+ plugins=None)
+ if upsample_cfg is not None:
+ self.upsample = build_upsample_layer(
+ cfg=upsample_cfg,
+ in_channels=in_channels,
+ out_channels=skip_channels,
+ with_cp=with_cp,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+ else:
+ self.upsample = ConvModule(
+ in_channels,
+ skip_channels,
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ conv_cfg=conv_cfg,
+ norm_cfg=norm_cfg,
+ act_cfg=act_cfg)
+
+ def forward(self, skip, x):
+ """Forward function."""
+
+ x = self.upsample(x)
+ out = torch.cat([skip, x], dim=1)
+ out = self.conv_block(out)
+
+ return out
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/ops/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/ops/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..bc075cd4eb7af7a8d2ad146233d9d5973e7f036d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/ops/__init__.py
@@ -0,0 +1,5 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .encoding import Encoding
+from .wrappers import Upsample, resize
+
+__all__ = ['Upsample', 'resize', 'Encoding']
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/ops/encoding.py b/EgoHOS/raw/script/mmsegmentation/mmseg/ops/encoding.py
new file mode 100644
index 0000000000000000000000000000000000000000..f397cc54e84feb6a9979c767d8602601d5613542
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/ops/encoding.py
@@ -0,0 +1,75 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+from torch import nn
+from torch.nn import functional as F
+
+
+class Encoding(nn.Module):
+ """Encoding Layer: a learnable residual encoder.
+
+ Input is of shape (batch_size, channels, height, width).
+ Output is of shape (batch_size, num_codes, channels).
+
+ Args:
+ channels: dimension of the features or feature channels
+ num_codes: number of code words
+ """
+
+ def __init__(self, channels, num_codes):
+ super(Encoding, self).__init__()
+ # init codewords and smoothing factor
+ self.channels, self.num_codes = channels, num_codes
+ std = 1. / ((num_codes * channels)**0.5)
+ # [num_codes, channels]
+ self.codewords = nn.Parameter(
+ torch.empty(num_codes, channels,
+ dtype=torch.float).uniform_(-std, std),
+ requires_grad=True)
+ # [num_codes]
+ self.scale = nn.Parameter(
+ torch.empty(num_codes, dtype=torch.float).uniform_(-1, 0),
+ requires_grad=True)
+
+ @staticmethod
+ def scaled_l2(x, codewords, scale):
+ num_codes, channels = codewords.size()
+ batch_size = x.size(0)
+ reshaped_scale = scale.view((1, 1, num_codes))
+ expanded_x = x.unsqueeze(2).expand(
+ (batch_size, x.size(1), num_codes, channels))
+ reshaped_codewords = codewords.view((1, 1, num_codes, channels))
+
+ scaled_l2_norm = reshaped_scale * (
+ expanded_x - reshaped_codewords).pow(2).sum(dim=3)
+ return scaled_l2_norm
+
+ @staticmethod
+ def aggregate(assignment_weights, x, codewords):
+ num_codes, channels = codewords.size()
+ reshaped_codewords = codewords.view((1, 1, num_codes, channels))
+ batch_size = x.size(0)
+
+ expanded_x = x.unsqueeze(2).expand(
+ (batch_size, x.size(1), num_codes, channels))
+ encoded_feat = (assignment_weights.unsqueeze(3) *
+ (expanded_x - reshaped_codewords)).sum(dim=1)
+ return encoded_feat
+
+ def forward(self, x):
+ assert x.dim() == 4 and x.size(1) == self.channels
+ # [batch_size, channels, height, width]
+ batch_size = x.size(0)
+ # [batch_size, height x width, channels]
+ x = x.view(batch_size, self.channels, -1).transpose(1, 2).contiguous()
+ # assignment_weights: [batch_size, channels, num_codes]
+ assignment_weights = F.softmax(
+ self.scaled_l2(x, self.codewords, self.scale), dim=2)
+ # aggregate
+ encoded_feat = self.aggregate(assignment_weights, x, self.codewords)
+ return encoded_feat
+
+ def __repr__(self):
+ repr_str = self.__class__.__name__
+ repr_str += f'(Nx{self.channels}xHxW =>Nx{self.num_codes}' \
+ f'x{self.channels})'
+ return repr_str
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/ops/wrappers.py b/EgoHOS/raw/script/mmsegmentation/mmseg/ops/wrappers.py
new file mode 100644
index 0000000000000000000000000000000000000000..ce67e4bebe1ed463072858f97dd950e596ca6a28
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/ops/wrappers.py
@@ -0,0 +1,51 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import warnings
+
+import torch.nn as nn
+import torch.nn.functional as F
+
+
+def resize(input,
+ size=None,
+ scale_factor=None,
+ mode='nearest',
+ align_corners=None,
+ warning=True):
+ if warning:
+ if size is not None and align_corners:
+ input_h, input_w = tuple(int(x) for x in input.shape[2:])
+ output_h, output_w = tuple(int(x) for x in size)
+ if output_h > input_h or output_w > output_h:
+ if ((output_h > 1 and output_w > 1 and input_h > 1
+ and input_w > 1) and (output_h - 1) % (input_h - 1)
+ and (output_w - 1) % (input_w - 1)):
+ warnings.warn(
+ f'When align_corners={align_corners}, '
+ 'the output would more aligned if '
+ f'input size {(input_h, input_w)} is `x+1` and '
+ f'out size {(output_h, output_w)} is `nx+1`')
+ return F.interpolate(input, size, scale_factor, mode, align_corners)
+
+
+class Upsample(nn.Module):
+
+ def __init__(self,
+ size=None,
+ scale_factor=None,
+ mode='nearest',
+ align_corners=None):
+ super(Upsample, self).__init__()
+ self.size = size
+ if isinstance(scale_factor, tuple):
+ self.scale_factor = tuple(float(factor) for factor in scale_factor)
+ else:
+ self.scale_factor = float(scale_factor) if scale_factor else None
+ self.mode = mode
+ self.align_corners = align_corners
+
+ def forward(self, x):
+ if not self.size:
+ size = [int(t * self.scale_factor) for t in x.shape[-2:]]
+ else:
+ size = self.size
+ return resize(x, size, None, self.mode, self.align_corners)
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/utils/__init__.py b/EgoHOS/raw/script/mmsegmentation/mmseg/utils/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..ed002c7de4436bd95947a762a5916cd44ff67128
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/utils/__init__.py
@@ -0,0 +1,10 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .collect_env import collect_env
+from .logger import get_root_logger
+from .misc import find_latest_checkpoint
+from .set_env import setup_multi_processes
+
+__all__ = [
+ 'get_root_logger', 'collect_env', 'find_latest_checkpoint',
+ 'setup_multi_processes'
+]
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/utils/collect_env.py b/EgoHOS/raw/script/mmsegmentation/mmseg/utils/collect_env.py
new file mode 100644
index 0000000000000000000000000000000000000000..3379ecb06bb059f2694c7ce9e1f10fa6c4f938b9
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/utils/collect_env.py
@@ -0,0 +1,18 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from mmcv.utils import collect_env as collect_base_env
+from mmcv.utils import get_git_hash
+
+import mmseg
+
+
+def collect_env():
+ """Collect the information of the running environments."""
+ env_info = collect_base_env()
+ env_info['MMSegmentation'] = f'{mmseg.__version__}+{get_git_hash()[:7]}'
+
+ return env_info
+
+
+if __name__ == '__main__':
+ for name, val in collect_env().items():
+ print('{}: {}'.format(name, val))
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/utils/logger.py b/EgoHOS/raw/script/mmsegmentation/mmseg/utils/logger.py
new file mode 100644
index 0000000000000000000000000000000000000000..0cb3c78d6da0d6c850a4603a255ecdea93b15d2b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/utils/logger.py
@@ -0,0 +1,28 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import logging
+
+from mmcv.utils import get_logger
+
+
+def get_root_logger(log_file=None, log_level=logging.INFO):
+ """Get the root logger.
+
+ The logger will be initialized if it has not been initialized. By default a
+ StreamHandler will be added. If `log_file` is specified, a FileHandler will
+ also be added. The name of the root logger is the top-level package name,
+ e.g., "mmseg".
+
+ Args:
+ log_file (str | None): The log filename. If specified, a FileHandler
+ will be added to the root logger.
+ log_level (int): The root logger level. Note that only the process of
+ rank 0 is affected, while other processes will set the level to
+ "Error" and be silent most of the time.
+
+ Returns:
+ logging.Logger: The root logger.
+ """
+
+ logger = get_logger(name='mmseg', log_file=log_file, log_level=log_level)
+
+ return logger
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/utils/misc.py b/EgoHOS/raw/script/mmsegmentation/mmseg/utils/misc.py
new file mode 100644
index 0000000000000000000000000000000000000000..bd1b6b163c21ed8ef071a97f42b7fd8997e78215
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/utils/misc.py
@@ -0,0 +1,41 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import glob
+import os.path as osp
+import warnings
+
+
+def find_latest_checkpoint(path, suffix='pth'):
+ """This function is for finding the latest checkpoint.
+
+ It will be used when automatically resume, modified from
+ https://github.com/open-mmlab/mmdetection/blob/dev-v2.20.0/mmdet/utils/misc.py
+
+ Args:
+ path (str): The path to find checkpoints.
+ suffix (str): File extension for the checkpoint. Defaults to pth.
+
+ Returns:
+ latest_path(str | None): File path of the latest checkpoint.
+ """
+ if not osp.exists(path):
+ warnings.warn("The path of the checkpoints doesn't exist.")
+ return None
+ if osp.exists(osp.join(path, f'latest.{suffix}')):
+ return osp.join(path, f'latest.{suffix}')
+
+ checkpoints = glob.glob(osp.join(path, f'*.{suffix}'))
+ if len(checkpoints) == 0:
+ warnings.warn('The are no checkpoints in the path')
+ return None
+ latest = -1
+ latest_path = ''
+ for checkpoint in checkpoints:
+ if len(checkpoint) < len(latest_path):
+ continue
+ # `count` is iteration number, as checkpoints are saved as
+ # 'iter_xx.pth' or 'epoch_xx.pth' and xx is iteration number.
+ count = int(osp.basename(checkpoint).split('_')[-1].split('.')[0])
+ if count > latest:
+ latest = count
+ latest_path = checkpoint
+ return latest_path
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/utils/set_env.py b/EgoHOS/raw/script/mmsegmentation/mmseg/utils/set_env.py
new file mode 100644
index 0000000000000000000000000000000000000000..b2d3aaf14b2f9706a561fb1af3129126a9647592
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/utils/set_env.py
@@ -0,0 +1,55 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import os
+import platform
+
+import cv2
+import torch.multiprocessing as mp
+
+from ..utils import get_root_logger
+
+
+def setup_multi_processes(cfg):
+ """Setup multi-processing environment variables."""
+ logger = get_root_logger()
+
+ # set multi-process start method
+ if platform.system() != 'Windows':
+ mp_start_method = cfg.get('mp_start_method', None)
+ current_method = mp.get_start_method(allow_none=True)
+ if mp_start_method in ('fork', 'spawn', 'forkserver'):
+ logger.info(
+ f'Multi-processing start method `{mp_start_method}` is '
+ f'different from the previous setting `{current_method}`.'
+ f'It will be force set to `{mp_start_method}`.')
+ mp.set_start_method(mp_start_method, force=True)
+ else:
+ logger.info(
+ f'Multi-processing start method is `{mp_start_method}`')
+
+ # disable opencv multithreading to avoid system being overloaded
+ opencv_num_threads = cfg.get('opencv_num_threads', None)
+ if isinstance(opencv_num_threads, int):
+ logger.info(f'OpenCV num_threads is `{opencv_num_threads}`')
+ cv2.setNumThreads(opencv_num_threads)
+ else:
+ logger.info(f'OpenCV num_threads is `{cv2.getNumThreads}')
+
+ if cfg.data.workers_per_gpu > 1:
+ # setup OMP threads
+ # This code is referred from https://github.com/pytorch/pytorch/blob/master/torch/distributed/run.py # noqa
+ omp_num_threads = cfg.get('omp_num_threads', None)
+ if 'OMP_NUM_THREADS' not in os.environ:
+ if isinstance(omp_num_threads, int):
+ logger.info(f'OMP num threads is {omp_num_threads}')
+ os.environ['OMP_NUM_THREADS'] = str(omp_num_threads)
+ else:
+ logger.info(f'OMP num threads is {os.environ["OMP_NUM_THREADS"] }')
+
+ # setup MKL threads
+ if 'MKL_NUM_THREADS' not in os.environ:
+ mkl_num_threads = cfg.get('mkl_num_threads', None)
+ if isinstance(mkl_num_threads, int):
+ logger.info(f'MKL num threads is {mkl_num_threads}')
+ os.environ['MKL_NUM_THREADS'] = str(mkl_num_threads)
+ else:
+ logger.info(f'MKL num threads is {os.environ["MKL_NUM_THREADS"]}')
diff --git a/EgoHOS/raw/script/mmsegmentation/mmseg/version.py b/EgoHOS/raw/script/mmsegmentation/mmseg/version.py
new file mode 100644
index 0000000000000000000000000000000000000000..e05146f0a07709d5f51efed652b4cb9af900c0d2
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/mmseg/version.py
@@ -0,0 +1,18 @@
+# Copyright (c) Open-MMLab. All rights reserved.
+
+__version__ = '0.24.1'
+
+
+def parse_version_info(version_str):
+ version_info = []
+ for x in version_str.split('.'):
+ if x.isdigit():
+ version_info.append(int(x))
+ elif x.find('rc') != -1:
+ patch_version = x.split('rc')
+ version_info.append(int(patch_version[0]))
+ version_info.append(f'rc{patch_version[1]}')
+ return tuple(version_info)
+
+
+version_info = parse_version_info(__version__)
diff --git a/EgoHOS/raw/script/mmsegmentation/model-index.yml b/EgoHOS/raw/script/mmsegmentation/model-index.yml
new file mode 100644
index 0000000000000000000000000000000000000000..2053fd04966a708d0a9dfcac989fa577d24fac27
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/model-index.yml
@@ -0,0 +1,45 @@
+Import:
+- configs/ann/ann.yml
+- configs/apcnet/apcnet.yml
+- configs/beit/beit.yml
+- configs/bisenetv1/bisenetv1.yml
+- configs/bisenetv2/bisenetv2.yml
+- configs/ccnet/ccnet.yml
+- configs/cgnet/cgnet.yml
+- configs/convnext/convnext.yml
+- configs/danet/danet.yml
+- configs/deeplabv3/deeplabv3.yml
+- configs/deeplabv3plus/deeplabv3plus.yml
+- configs/dmnet/dmnet.yml
+- configs/dnlnet/dnlnet.yml
+- configs/dpt/dpt.yml
+- configs/emanet/emanet.yml
+- configs/encnet/encnet.yml
+- configs/erfnet/erfnet.yml
+- configs/fastfcn/fastfcn.yml
+- configs/fastscnn/fastscnn.yml
+- configs/fcn/fcn.yml
+- configs/gcnet/gcnet.yml
+- configs/hrnet/hrnet.yml
+- configs/icnet/icnet.yml
+- configs/isanet/isanet.yml
+- configs/knet/knet.yml
+- configs/mae/mae.yml
+- configs/mobilenet_v2/mobilenet_v2.yml
+- configs/mobilenet_v3/mobilenet_v3.yml
+- configs/nonlocal_net/nonlocal_net.yml
+- configs/ocrnet/ocrnet.yml
+- configs/point_rend/point_rend.yml
+- configs/psanet/psanet.yml
+- configs/pspnet/pspnet.yml
+- configs/resnest/resnest.yml
+- configs/segformer/segformer.yml
+- configs/segmenter/segmenter.yml
+- configs/sem_fpn/sem_fpn.yml
+- configs/setr/setr.yml
+- configs/stdc/stdc.yml
+- configs/swin/swin.yml
+- configs/twins/twins.yml
+- configs/unet/unet.yml
+- configs/upernet/upernet.yml
+- configs/vit/vit.yml
diff --git a/EgoHOS/raw/script/mmsegmentation/pred_all_obj1.sh b/EgoHOS/raw/script/mmsegmentation/pred_all_obj1.sh
new file mode 100644
index 0000000000000000000000000000000000000000..92c4c2ae329d182504f7d822ee075b0cf52303fe
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/pred_all_obj1.sh
@@ -0,0 +1,39 @@
+# inference
+python predict_image.py \
+ --config_file ./work_dirs/seg_twohands_ccda/seg_twohands_ccda.py \
+ --checkpoint_file ./work_dirs/seg_twohands_ccda/best_mIoU_iter_56000.pth \
+ --img_dir ../testimages/images \
+ --pred_seg_dir ../testimages/pred_twohands \
+
+python predict_image.py \
+ --config_file ./work_dirs/twohands_to_cb_ccda/twohands_to_cb_ccda.py \
+ --checkpoint_file ./work_dirs/twohands_to_cb_ccda/best_mIoU_iter_76000.pth \
+ --img_dir ../testimages/images \
+ --pred_seg_dir ../testimages/pred_cb
+
+python predict_image.py \
+ --config_file ./work_dirs/twohands_cb_to_obj1_ccda/twohands_cb_to_obj1_ccda.py \
+ --checkpoint_file ./work_dirs/twohands_cb_to_obj1_ccda/best_mIoU_iter_34000.pth \
+ --img_dir ../testimages/images \
+ --pred_seg_dir ../testimages/pred_obj1
+
+# visualize
+python visualize.py \
+ --mode twohands \
+ --img_dir ../testimages/images \
+ --twohands_dir ../testimages/pred_twohands \
+ --vis_dir ../testimages/pred_twohands_vis
+
+python visualize.py \
+ --mode cb \
+ --img_dir ../testimages/images \
+ --cb_dir ../testimages/pred_cb \
+ --vis_dir ../testimages/pred_cb_vis
+
+python visualize.py \
+ --mode twohands_obj1 \
+ --img_dir ../testimages/images \
+ --twohands_dir ../testimages/pred_twohands \
+ --obj1_dir ../testimages/pred_obj1 \
+ --vis_dir ../testimages/pred_obj1_vis
+
diff --git a/EgoHOS/raw/script/mmsegmentation/pred_all_obj2.sh b/EgoHOS/raw/script/mmsegmentation/pred_all_obj2.sh
new file mode 100644
index 0000000000000000000000000000000000000000..66920d191f4a714e5c5e32451b1de09e127cd5a6
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/pred_all_obj2.sh
@@ -0,0 +1,39 @@
+# inference
+python predict_image.py \
+ --config_file ./work_dirs/seg_twohands_ccda/seg_twohands_ccda.py \
+ --checkpoint_file ./work_dirs/seg_twohands_ccda/best_mIoU_iter_56000.pth \
+ --img_dir ../testimages/images \
+ --pred_seg_dir ../testimages/pred_twohands \
+
+python predict_image.py \
+ --config_file ./work_dirs/twohands_to_cb_ccda/twohands_to_cb_ccda.py \
+ --checkpoint_file ./work_dirs/twohands_to_cb_ccda/best_mIoU_iter_76000.pth \
+ --img_dir ../testimages/images \
+ --pred_seg_dir ../testimages/pred_cb
+
+python predict_image.py \
+ --config_file ./work_dirs/twohands_cb_to_obj2_ccda/twohands_cb_to_obj2_ccda.py \
+ --checkpoint_file ./work_dirs/twohands_cb_to_obj2_ccda/best_mIoU_iter_32000.pth \
+ --img_dir ../testimages/images \
+ --pred_seg_dir ../testimages/pred_obj2
+
+# visualize
+python visualize.py \
+ --mode twohands \
+ --img_dir ../testimages/images \
+ --twohands_dir ../testimages/pred_twohands \
+ --vis_dir ../testimages/pred_twohands_vis
+
+python visualize.py \
+ --mode cb \
+ --img_dir ../testimages/images \
+ --cb_dir ../testimages/pred_cb \
+ --vis_dir ../testimages/pred_cb_vis
+
+python visualize.py \
+ --mode twohands_obj2 \
+ --img_dir ../testimages/images \
+ --twohands_dir ../testimages/pred_twohands \
+ --obj2_dir ../testimages/pred_obj2 \
+ --vis_dir ../testimages/pred_obj2_vis
+
diff --git a/EgoHOS/raw/script/mmsegmentation/pred_cb.sh b/EgoHOS/raw/script/mmsegmentation/pred_cb.sh
new file mode 100644
index 0000000000000000000000000000000000000000..df864748297154b280d18bb9a9a04fabf1840011
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/pred_cb.sh
@@ -0,0 +1,15 @@
+# inference
+python predict_image.py \
+ --config_file ./work_dirs/twohands_to_cb_ccda/twohands_to_cb_ccda.py \
+ --checkpoint_file ./work_dirs/twohands_to_cb_ccda/best_mIoU_iter_76000.pth \
+ --img_dir ../testimages/images \
+ --pred_seg_dir ../testimages/pred_cb
+
+# visualize
+python visualize.py \
+ --mode cb \
+ --img_dir ../testimages/images \
+ --cb_dir ../testimages/pred_cb \
+ --vis_dir ../testimages/pred_cb_vis
+
+
\ No newline at end of file
diff --git a/EgoHOS/raw/script/mmsegmentation/pred_obj1.sh b/EgoHOS/raw/script/mmsegmentation/pred_obj1.sh
new file mode 100644
index 0000000000000000000000000000000000000000..26c9417a90c016ea890614b566cb62be22299ccf
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/pred_obj1.sh
@@ -0,0 +1,14 @@
+# inference
+python predict_image.py \
+ --config_file ./work_dirs/twohands_cb_to_obj1_ccda/twohands_cb_to_obj1_ccda.py \
+ --checkpoint_file ./work_dirs/twohands_cb_to_obj1_ccda/best_mIoU_iter_34000.pth \
+ --img_dir ../testimages/images \
+ --pred_seg_dir ../testimages/pred_obj1
+
+# visualize
+python visualize.py \
+ --mode twohands_obj1 \
+ --img_dir ../testimages/images \
+ --twohands_dir ../testimages/pred_twohands \
+ --obj1_dir ../testimages/pred_obj1 \
+ --vis_dir ../testimages/pred_obj1_vis
diff --git a/EgoHOS/raw/script/mmsegmentation/pred_obj1_video.sh b/EgoHOS/raw/script/mmsegmentation/pred_obj1_video.sh
new file mode 100644
index 0000000000000000000000000000000000000000..814d36567a1d73a1fca80e5f3694b94646ddf8fa
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/pred_obj1_video.sh
@@ -0,0 +1,5 @@
+python predict_video.py \
+ --mode obj1 \
+ --input_video_file ../testvideos/testvideo1_short.mp4 \
+ --output_video_file ../testvideos/testvideo1_short_result.mp4 \
+ --remove_intermediate_images True # True: save only the processed video; False: save all intermediate segmentation image results
diff --git a/EgoHOS/raw/script/mmsegmentation/pred_obj2.sh b/EgoHOS/raw/script/mmsegmentation/pred_obj2.sh
new file mode 100644
index 0000000000000000000000000000000000000000..aa32f8e2176a15842f1dd62256698baf56588177
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/pred_obj2.sh
@@ -0,0 +1,14 @@
+# inference
+python predict_image.py \
+ --config_file ./work_dirs/twohands_cb_to_obj2_ccda/twohands_cb_to_obj2_ccda.py \
+ --checkpoint_file ./work_dirs/twohands_cb_to_obj2_ccda/best_mIoU_iter_32000.pth \
+ --img_dir ../testimages/images \
+ --pred_seg_dir ../testimages/pred_obj2
+
+# visualize
+python visualize.py \
+ --mode twohands_obj2 \
+ --img_dir ../testimages/images \
+ --twohands_dir ../testimages/pred_twohands \
+ --obj2_dir ../testimages/pred_obj2 \
+ --vis_dir ../testimages/pred_obj2_vis
diff --git a/EgoHOS/raw/script/mmsegmentation/pred_obj2_video.sh b/EgoHOS/raw/script/mmsegmentation/pred_obj2_video.sh
new file mode 100644
index 0000000000000000000000000000000000000000..0993ec892ee2d13511e759a8b642672b74f98bef
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/pred_obj2_video.sh
@@ -0,0 +1,5 @@
+python predict_video.py \
+ --mode obj2 \
+ --input_video_file ../testvideos/testvideo2_short.mp4 \
+ --output_video_file ../testvideos/testvideo2_short_result.mp4 \
+ --remove_intermediate_images True # True: save only the processed video; False: save all intermediate segmentation image results
\ No newline at end of file
diff --git a/EgoHOS/raw/script/mmsegmentation/pred_twohands.sh b/EgoHOS/raw/script/mmsegmentation/pred_twohands.sh
new file mode 100644
index 0000000000000000000000000000000000000000..00f27f1e7eab7850ac06b078c3094a4214af6b78
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/pred_twohands.sh
@@ -0,0 +1,14 @@
+# inference
+python predict_image.py \
+ --config_file ./work_dirs/seg_twohands_ccda/seg_twohands_ccda.py \
+ --checkpoint_file ./work_dirs/seg_twohands_ccda/best_mIoU_iter_56000.pth \
+ --img_dir ../testimages/images \
+ --pred_seg_dir ../testimages/pred_twohands \
+
+# visualize
+python visualize.py \
+ --mode twohands \
+ --img_dir ../testimages/images \
+ --twohands_dir ../testimages/pred_twohands \
+ --vis_dir ../testimages/pred_twohands_vis
+
diff --git a/EgoHOS/raw/script/mmsegmentation/predict_image.py b/EgoHOS/raw/script/mmsegmentation/predict_image.py
new file mode 100644
index 0000000000000000000000000000000000000000..6733b769a0682617fc2bf7abe24535ebee043367
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/predict_image.py
@@ -0,0 +1,34 @@
+from mmseg.apis import inference_segmentor, init_segmentor
+import mmcv
+import glob
+import os
+from tqdm import tqdm
+import argparse
+from PIL import Image
+import numpy as np
+from skimage.io import imsave
+import pdb
+
+
+
+parser = argparse.ArgumentParser(description="")
+parser.add_argument("--config_file", default='./work_dirs/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_pretrain_480x360_22K/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_pretrain_480x360_22K.py', type=str)
+parser.add_argument("--checkpoint_file", default='./work_dirs/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_pretrain_480x360_22K/best_mIoU_iter_42000.pth', type=str)
+parser.add_argument("--img_dir", default='../data/train/image', type=str)
+parser.add_argument("--pred_seg_dir", default='./work_dirs/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_pretrain_480x360_22K/outputs/train_seg', type=str)
+args = parser.parse_args()
+
+os.makedirs(args.pred_seg_dir, exist_ok = True)
+
+# build the model from a config file and a checkpoint file
+model = init_segmentor(args.config_file, args.checkpoint_file, device='cuda:0')
+
+alpha = 0.5
+for file in tqdm(glob.glob(args.img_dir + '/*')):
+ fname = os.path.basename(file).split('.')[0]
+ img = np.array(Image.open(os.path.join(args.img_dir, fname + '.jpg')))
+ seg_result = inference_segmentor(model, file)[0]
+ imsave(os.path.join(args.pred_seg_dir, fname + '.png'), seg_result.astype(np.uint8))
+
+
+
diff --git a/EgoHOS/raw/script/mmsegmentation/predict_video.py b/EgoHOS/raw/script/mmsegmentation/predict_video.py
new file mode 100644
index 0000000000000000000000000000000000000000..ba2081ebb3b1d92a8d276e1a10d9f40a59fa9cb3
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/predict_video.py
@@ -0,0 +1,134 @@
+from mmseg.apis import inference_segmentor, init_segmentor
+import mmcv
+import glob
+import os
+from tqdm import tqdm
+import argparse
+from PIL import Image
+import numpy as np
+from skimage.io import imsave
+import pdb
+import imageio
+from visualize import visualize_twohands_obj1, visualize_twohands_obj2
+
+
+
+parser = argparse.ArgumentParser(description="")
+parser.add_argument("--mode", default='obj1', type=str, help='options: obj1, obj2')
+parser.add_argument("--input_video_file", default='../testvideos/testvideo1_short.mp4', type=str)
+parser.add_argument("--output_video_file", default='../testvideos/testvideo1_short_result.mp4', type=str)
+parser.add_argument("--twohands_config_file", default='./work_dirs/seg_twohands_ccda/seg_twohands_ccda.py', type=str)
+parser.add_argument("--twohands_checkpoint_file", default='./work_dirs/seg_twohands_ccda/best_mIoU_iter_56000.pth', type=str)
+parser.add_argument("--cb_config_file", default='./work_dirs/twohands_to_cb_ccda/twohands_to_cb_ccda.py', type=str)
+parser.add_argument("--cb_checkpoint_file", default='./work_dirs/twohands_to_cb_ccda/best_mIoU_iter_76000.pth', type=str)
+parser.add_argument("--obj1_config_file", default='./work_dirs/twohands_cb_to_obj1_ccda/twohands_cb_to_obj1_ccda.py', type=str)
+parser.add_argument("--obj1_checkpoint_file", default='./work_dirs/twohands_cb_to_obj1_ccda/best_mIoU_iter_34000.pth', type=str)
+parser.add_argument("--obj2_config_file", default='./work_dirs/twohands_cb_to_obj2_ccda/twohands_cb_to_obj2_ccda.py', type=str)
+parser.add_argument("--obj2_checkpoint_file", default='./work_dirs/twohands_cb_to_obj2_ccda/best_mIoU_iter_32000.pth', type=str)
+parser.add_argument("--remove_intermediate_images", default=False, type=bool)
+args = parser.parse_args()
+
+video_dir = args.input_video_file.split('.mp4')[0]; os.makedirs(video_dir, exist_ok = True)
+video_image_dir = os.path.join(video_dir, 'images'); os.makedirs(video_image_dir, exist_ok = True)
+video_twohands_dir = os.path.join(video_dir, 'pred_twohands'); os.makedirs(video_twohands_dir, exist_ok = True)
+video_cb_dir = os.path.join(video_dir, 'pred_cb'); os.makedirs(video_cb_dir, exist_ok = True)
+video_obj1_dir = os.path.join(video_dir, 'pred_obj1'); os.makedirs(video_obj1_dir, exist_ok = True)
+video_obj2_dir = os.path.join(video_dir, 'pred_obj2'); os.makedirs(video_obj2_dir, exist_ok = True)
+
+
+# # extract video frames and save them into a directory
+print('Reading and extracting video frames......')
+reader = imageio.get_reader(args.input_video_file, 'ffmpeg')
+fps = reader.get_meta_data()['fps']
+for num, image in enumerate(reader):
+ save_img_file = os.path.join(video_image_dir, str(num).zfill(8)+'.jpg')
+ imsave(save_img_file, image)
+
+# predict twohands
+cmd_pred_twohands = 'python predict_image.py \
+ --config_file %s \
+ --checkpoint_file %s \
+ --img_dir %s \
+ --pred_seg_dir %s' % (args.twohands_config_file, args.twohands_checkpoint_file, video_image_dir, video_twohands_dir)
+
+print('Predicting twohands......')
+print(cmd_pred_twohands)
+os.system(cmd_pred_twohands)
+
+# predict cb
+cmd_pred_cb = 'python predict_image.py \
+ --config_file %s \
+ --checkpoint_file %s \
+ --img_dir %s \
+ --pred_seg_dir %s' % (args.cb_config_file, args.cb_checkpoint_file, video_image_dir, video_cb_dir)
+
+print('Predicting contact boundary......')
+print(cmd_pred_cb)
+os.system(cmd_pred_cb)
+
+if args.mode == 'obj1':
+ # predict obj1
+ cmd_pred_obj1 = 'python predict_image.py \
+ --config_file %s \
+ --checkpoint_file %s \
+ --img_dir %s \
+ --pred_seg_dir %s' % (args.obj1_config_file, args.obj1_checkpoint_file, video_image_dir, video_obj1_dir)
+
+ print('Predicting 1st order interacting objects......')
+ print(cmd_pred_obj1)
+ os.system(cmd_pred_obj1)
+elif args.mode == 'obj2':
+ # predict obj2
+ cmd_pred_obj2 = 'python predict_image.py \
+ --config_file %s \
+ --checkpoint_file %s \
+ --img_dir %s \
+ --pred_seg_dir %s' % (args.obj2_config_file, args.obj2_checkpoint_file, video_image_dir, video_obj2_dir)
+
+ print('Predicting 2nd order interacting objects......')
+ print(cmd_pred_obj2)
+ os.system(cmd_pred_obj2)
+else:
+ raise notimplementederror
+
+# stitch prediction into a video
+print('stitch prediction into a video......')
+writer = imageio.get_writer(args.output_video_file, fps = fps)
+for img_file in tqdm(sorted(glob.glob(video_image_dir + '/*'))):
+ fname = os.path.basename(img_file).split('.')[0]
+ twohands_file = os.path.join(video_twohands_dir, fname + '.png')
+
+ if args.mode == 'obj1':
+ obj1_file = os.path.join(video_obj1_dir, fname + '.png')
+ img = np.array(Image.open(img_file))
+ twohands = np.array(Image.open(twohands_file))
+ obj1 = np.array(Image.open(obj1_file))
+ twohands_obj1 = twohands.copy()
+ twohands_obj1[obj1 == 1] = 3
+ twohands_obj1[obj1 == 2] = 4
+ twohands_obj1[obj1 == 3] = 5
+ twohands_obj1_vis = visualize_twohands_obj1(img, twohands_obj1)
+ writer.append_data(twohands_obj1_vis)
+ elif args.mode == 'obj2':
+ obj2_file = os.path.join(video_obj2_dir, fname + '.png')
+ img = np.array(Image.open(img_file))
+ twohands = np.array(Image.open(twohands_file))
+ obj2 = np.array(Image.open(obj2_file))
+ twohands_obj2 = twohands.copy()
+ twohands_obj2[obj2 == 1] = 3
+ twohands_obj2[obj2 == 2] = 4
+ twohands_obj2[obj2 == 3] = 5
+ twohands_obj2[obj2 == 4] = 6
+ twohands_obj2[obj2 == 5] = 7
+ twohands_obj2[obj2 == 6] = 8
+ twohands_obj2_vis = visualize_twohands_obj2(img, twohands_obj2)
+ writer.append_data(twohands_obj2_vis)
+ else:
+ raise notimplementederror
+
+writer.close()
+
+# remove all folders
+if args.remove_intermediate_images:
+ os.system('rm -rf ' + video_dir)
+
diff --git a/EgoHOS/raw/script/mmsegmentation/pytest.ini b/EgoHOS/raw/script/mmsegmentation/pytest.ini
new file mode 100644
index 0000000000000000000000000000000000000000..9796e871e70c7c67345b1d6bcf708c0c82377a98
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/pytest.ini
@@ -0,0 +1,7 @@
+[pytest]
+addopts = --xdoctest --xdoctest-style=auto
+norecursedirs = .git ignore build __pycache__ data docker docs .eggs
+
+filterwarnings= default
+ ignore:.*No cfgstr given in Cacher constructor or call.*:Warning
+ ignore:.*Define the __nice__ method for.*:Warning
diff --git a/EgoHOS/raw/script/mmsegmentation/requirements.txt b/EgoHOS/raw/script/mmsegmentation/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..6da5adea757ffc79ac35e544d4afe85c5f44a90d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/requirements.txt
@@ -0,0 +1,3 @@
+-r requirements/optional.txt
+-r requirements/runtime.txt
+-r requirements/tests.txt
diff --git a/EgoHOS/raw/script/mmsegmentation/requirements/docs.txt b/EgoHOS/raw/script/mmsegmentation/requirements/docs.txt
new file mode 100644
index 0000000000000000000000000000000000000000..20170845c44eefcb139ee2baa1a3d375b71c34ec
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/requirements/docs.txt
@@ -0,0 +1,6 @@
+docutils==0.16.0
+myst-parser
+-e git+https://github.com/gaotongxiao/pytorch_sphinx_theme.git#egg=pytorch_sphinx_theme
+sphinx==4.0.2
+sphinx_copybutton
+sphinx_markdown_tables
diff --git a/EgoHOS/raw/script/mmsegmentation/requirements/mminstall.txt b/EgoHOS/raw/script/mmsegmentation/requirements/mminstall.txt
new file mode 100644
index 0000000000000000000000000000000000000000..bd43faf87e177562f7b45fc0c6c3dbbf694794e8
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/requirements/mminstall.txt
@@ -0,0 +1,2 @@
+mmcls>=0.20.1
+mmcv-full>=1.4.4,<=1.6.0
diff --git a/EgoHOS/raw/script/mmsegmentation/requirements/optional.txt b/EgoHOS/raw/script/mmsegmentation/requirements/optional.txt
new file mode 100644
index 0000000000000000000000000000000000000000..47fa5933159eb068640f6b45281d36ab4af294cb
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/requirements/optional.txt
@@ -0,0 +1 @@
+cityscapesscripts
diff --git a/EgoHOS/raw/script/mmsegmentation/requirements/readthedocs.txt b/EgoHOS/raw/script/mmsegmentation/requirements/readthedocs.txt
new file mode 100644
index 0000000000000000000000000000000000000000..22a894bd71d3454aa5e8c0dc6331afd8b53433d1
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/requirements/readthedocs.txt
@@ -0,0 +1,4 @@
+mmcv
+prettytable
+torch
+torchvision
diff --git a/EgoHOS/raw/script/mmsegmentation/requirements/runtime.txt b/EgoHOS/raw/script/mmsegmentation/requirements/runtime.txt
new file mode 100644
index 0000000000000000000000000000000000000000..520408fe8b322c0cb288160014e4e996ffa8f457
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/requirements/runtime.txt
@@ -0,0 +1,5 @@
+matplotlib
+mmcls>=0.20.1
+numpy
+packaging
+prettytable
diff --git a/EgoHOS/raw/script/mmsegmentation/requirements/tests.txt b/EgoHOS/raw/script/mmsegmentation/requirements/tests.txt
new file mode 100644
index 0000000000000000000000000000000000000000..74fc76146d8bbce7416a45c6f23d67e5336e50eb
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/requirements/tests.txt
@@ -0,0 +1,6 @@
+codecov
+flake8
+interrogate
+pytest
+xdoctest>=0.10.0
+yapf
diff --git a/EgoHOS/raw/script/mmsegmentation/resources/seg_demo.gif b/EgoHOS/raw/script/mmsegmentation/resources/seg_demo.gif
new file mode 100644
index 0000000000000000000000000000000000000000..dc795384233f3b13e582fd680a3c1af983627240
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/resources/seg_demo.gif
@@ -0,0 +1,3 @@
+version https://git-lfs.github.com/spec/v1
+oid sha256:b15135137aa5182b4ec5bdea50e59b86b00873deb4cc925ca2e6a2e39808b5f4
+size 951973
diff --git a/EgoHOS/raw/script/mmsegmentation/setup.cfg b/EgoHOS/raw/script/mmsegmentation/setup.cfg
new file mode 100644
index 0000000000000000000000000000000000000000..23cb09e6989fe840298951e1dd4c324a22fea802
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/setup.cfg
@@ -0,0 +1,19 @@
+[yapf]
+based_on_style = pep8
+blank_line_before_nested_class_or_def = true
+split_before_expression_after_opening_paren = true
+
+[isort]
+line_length = 79
+multi_line_output = 0
+extra_standard_library = setuptools
+known_first_party = mmseg
+known_third_party = PIL,cityscapesscripts,cv2,detail,matplotlib,mmcv,numpy,onnxruntime,packaging,prettytable,pytest,pytorch_sphinx_theme,requests,scipy,seaborn,torch,ts
+no_lines_before = STDLIB,LOCALFOLDER
+default_section = THIRDPARTY
+
+[codespell]
+skip = *.po,*.ts,*.ipynb
+count =
+quiet-level = 3
+ignore-words-list = formating,sur,hist,dota
diff --git a/EgoHOS/raw/script/mmsegmentation/setup.py b/EgoHOS/raw/script/mmsegmentation/setup.py
new file mode 100644
index 0000000000000000000000000000000000000000..91afefb6ed990422ed0c056f11c4dd498d2b4780
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/setup.py
@@ -0,0 +1,200 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import os
+import os.path as osp
+import platform
+import shutil
+import sys
+import warnings
+from setuptools import find_packages, setup
+
+
+def readme():
+ with open('README.md', encoding='utf-8') as f:
+ content = f.read()
+ return content
+
+
+version_file = 'mmseg/version.py'
+
+
+def get_version():
+ with open(version_file, 'r') as f:
+ exec(compile(f.read(), version_file, 'exec'))
+ return locals()['__version__']
+
+
+def parse_requirements(fname='requirements.txt', with_version=True):
+ """Parse the package dependencies listed in a requirements file but strips
+ specific versioning information.
+
+ Args:
+ fname (str): path to requirements file
+ with_version (bool, default=False): if True include version specs
+
+ Returns:
+ List[str]: list of requirements items
+
+ CommandLine:
+ python -c "import setup; print(setup.parse_requirements())"
+ """
+ import re
+ import sys
+ from os.path import exists
+ require_fpath = fname
+
+ def parse_line(line):
+ """Parse information from a line in a requirements text file."""
+ if line.startswith('-r '):
+ # Allow specifying requirements in other files
+ target = line.split(' ')[1]
+ for info in parse_require_file(target):
+ yield info
+ else:
+ info = {'line': line}
+ if line.startswith('-e '):
+ info['package'] = line.split('#egg=')[1]
+ else:
+ # Remove versioning from the package
+ pat = '(' + '|'.join(['>=', '==', '>']) + ')'
+ parts = re.split(pat, line, maxsplit=1)
+ parts = [p.strip() for p in parts]
+
+ info['package'] = parts[0]
+ if len(parts) > 1:
+ op, rest = parts[1:]
+ if ';' in rest:
+ # Handle platform specific dependencies
+ # http://setuptools.readthedocs.io/en/latest/setuptools.html#declaring-platform-specific-dependencies
+ version, platform_deps = map(str.strip,
+ rest.split(';'))
+ info['platform_deps'] = platform_deps
+ else:
+ version = rest # NOQA
+ info['version'] = (op, version)
+ yield info
+
+ def parse_require_file(fpath):
+ with open(fpath, 'r') as f:
+ for line in f.readlines():
+ line = line.strip()
+ if line and not line.startswith('#'):
+ for info in parse_line(line):
+ yield info
+
+ def gen_packages_items():
+ if exists(require_fpath):
+ for info in parse_require_file(require_fpath):
+ parts = [info['package']]
+ if with_version and 'version' in info:
+ parts.extend(info['version'])
+ if not sys.version.startswith('3.4'):
+ # apparently package_deps are broken in 3.4
+ platform_deps = info.get('platform_deps')
+ if platform_deps is not None:
+ parts.append(';' + platform_deps)
+ item = ''.join(parts)
+ yield item
+
+ packages = list(gen_packages_items())
+ return packages
+
+
+def add_mim_extension():
+ """Add extra files that are required to support MIM into the package.
+
+ These files will be added by creating a symlink to the originals if the
+ package is installed in `editable` mode (e.g. pip install -e .), or by
+ copying from the originals otherwise.
+ """
+
+ # parse installment mode
+ if 'develop' in sys.argv:
+ # installed by `pip install -e .`
+ if platform.system() == 'Windows':
+ # set `copy` mode here since symlink fails on Windows.
+ mode = 'copy'
+ else:
+ mode = 'symlink'
+ elif 'sdist' in sys.argv or 'bdist_wheel' in sys.argv or \
+ platform.system() == 'Windows':
+ # installed by `pip install .`
+ # or create source distribution by `python setup.py sdist`
+ # set `copy` mode here since symlink fails with WinError on Windows.
+ mode = 'copy'
+ else:
+ return
+
+ filenames = ['tools', 'configs', 'model-index.yml']
+ repo_path = osp.dirname(__file__)
+ mim_path = osp.join(repo_path, 'mmseg', '.mim')
+ os.makedirs(mim_path, exist_ok=True)
+
+ for filename in filenames:
+ if osp.exists(filename):
+ src_path = osp.join(repo_path, filename)
+ tar_path = osp.join(mim_path, filename)
+
+ if osp.isfile(tar_path) or osp.islink(tar_path):
+ os.remove(tar_path)
+ elif osp.isdir(tar_path):
+ shutil.rmtree(tar_path)
+
+ if mode == 'symlink':
+ src_relpath = osp.relpath(src_path, osp.dirname(tar_path))
+ try:
+ os.symlink(src_relpath, tar_path)
+ except OSError:
+ # Creating a symbolic link on windows may raise an
+ # `OSError: [WinError 1314]` due to privilege. If
+ # the error happens, the src file will be copied
+ mode = 'copy'
+ warnings.warn(
+ f'Failed to create a symbolic link for {src_relpath}, '
+ f'and it will be copied to {tar_path}')
+ else:
+ continue
+
+ if mode == 'copy':
+ if osp.isfile(src_path):
+ shutil.copyfile(src_path, tar_path)
+ elif osp.isdir(src_path):
+ shutil.copytree(src_path, tar_path)
+ else:
+ warnings.warn(f'Cannot copy file {src_path}.')
+ else:
+ raise ValueError(f'Invalid mode {mode}')
+
+
+if __name__ == '__main__':
+ add_mim_extension()
+ setup(
+ name='mmsegmentation',
+ version=get_version(),
+ description='Open MMLab Semantic Segmentation Toolbox and Benchmark',
+ long_description=readme(),
+ long_description_content_type='text/markdown',
+ author='MMSegmentation Contributors',
+ author_email='openmmlab@gmail.com',
+ keywords='computer vision, semantic segmentation',
+ url='http://github.com/open-mmlab/mmsegmentation',
+ packages=find_packages(exclude=('configs', 'tools', 'demo')),
+ include_package_data=True,
+ classifiers=[
+ 'Development Status :: 4 - Beta',
+ 'License :: OSI Approved :: Apache Software License',
+ 'Operating System :: OS Independent',
+ 'Programming Language :: Python :: 3.6',
+ 'Programming Language :: Python :: 3.7',
+ 'Programming Language :: Python :: 3.8',
+ 'Programming Language :: Python :: 3.9',
+ ],
+ license='Apache License 2.0',
+ install_requires=parse_requirements('requirements/runtime.txt'),
+ extras_require={
+ 'all': parse_requirements('requirements.txt'),
+ 'tests': parse_requirements('requirements/tests.txt'),
+ 'build': parse_requirements('requirements/build.txt'),
+ 'optional': parse_requirements('requirements/optional.txt'),
+ },
+ ext_modules=[],
+ zip_safe=False)
diff --git a/EgoHOS/raw/script/mmsegmentation/test.py b/EgoHOS/raw/script/mmsegmentation/test.py
new file mode 100644
index 0000000000000000000000000000000000000000..4b0a74a034ab21e2472722ed5202c26862d117b9
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/test.py
@@ -0,0 +1,54 @@
+from mmseg.apis import inference_segmentor, init_segmentor
+import mmcv
+import glob
+import os
+from tqdm import tqdm
+import argparse
+from PIL import Image
+import numpy as np
+from skimage.io import imsave
+import pdb
+
+def visualize_segmentation(img, seg_result, alpha = 0.4):
+ seg_color = np.zeros((img.shape))
+ seg_color[seg_result == 0] = (0, 0, 0) # background
+ seg_color[seg_result == 1] = (255, 0, 0) # left_hand
+ seg_color[seg_result == 2] = (0, 0, 255) # right_hand
+ seg_color[seg_result == 3] = (255, 0, 255) # left_object1
+ seg_color[seg_result == 4] = (0, 255, 255) # right_object1
+ seg_color[seg_result == 5] = (0, 255, 0) # two_object1
+ seg_color[seg_result == 6] = (255, 204, 255) # left_object2
+ seg_color[seg_result == 7] = (204, 255, 255) # right_object2
+ seg_color[seg_result == 8] = (204, 255, 204) # two_object2
+ vis = img * (1 - alpha) + seg_color * alpha
+ return vis
+
+
+
+parser = argparse.ArgumentParser(description="")
+parser.add_argument("--config_file", default='./work_dirs/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_pretrain_480x360_22K/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_pretrain_480x360_22K.py', type=str)
+parser.add_argument("--checkpoint_file", default='./work_dirs/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_pretrain_480x360_22K/best_mIoU_iter_42000.pth', type=str)
+parser.add_argument("--img_dir", default='../data/train/image', type=str)
+parser.add_argument("--vis_dir", default='./work_dirs/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_pretrain_480x360_22K/outputs/train', type=str)
+parser.add_argument("--seg_dir", default='./work_dirs/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_pretrain_480x360_22K/outputs/train_seg', type=str)
+args = parser.parse_args()
+
+# build the model from a config file and a checkpoint file
+model = init_segmentor(args.config_file, args.checkpoint_file, device='cuda:0')
+
+os.makedirs(args.vis_dir, exist_ok = True)
+os.makedirs(args.seg_dir, exist_ok = True)
+
+alpha = 0.3
+for file in tqdm(glob.glob(args.img_dir + '/*')):
+ fname = os.path.basename(file).split('.')[0]
+ img = np.array(Image.open(os.path.join(args.img_dir, fname + '.jpg')))
+ seg_result = inference_segmentor(model, file)[0]
+ vis = visualize_segmentation(img, seg_result, alpha = alpha)
+ imsave(os.path.join(args.vis_dir, fname + '.jpg'), vis)
+ imsave(os.path.join(args.seg_dir, fname + '.png'), seg_result.astype(np.uint8))
+
+
+
+ # pdb.set_trace()
+
diff --git a/EgoHOS/raw/script/mmsegmentation/test.sh b/EgoHOS/raw/script/mmsegmentation/test.sh
new file mode 100644
index 0000000000000000000000000000000000000000..d7615a1d30a7ffbd2c2fe37d536c9f52d91aa766
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/test.sh
@@ -0,0 +1,19 @@
+# python test.py --img_dir ../data/val/image \
+# --vis_dir ./work_dirs/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_pretrain_480x360_22K/outputs/val \
+# --seg_dir ./work_dirs/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_pretrain_480x360_22K/outputs/val_seg
+
+# python test.py --img_dir ../data/test_indomain/image \
+# --vis_dir ./work_dirs/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_pretrain_480x360_22K/outputs/test_indomain \
+# --seg_dir ./work_dirs/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_pretrain_480x360_22K/outputs/test_indomain_seg
+
+# python test.py --img_dir ../data/test_outdomain/image \
+# --vis_dir ./work_dirs/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_pretrain_480x360_22K/outputs/test_outdomain \
+# --seg_dir ./work_dirs/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_pretrain_480x360_22K/outputs/test_outdomain_seg
+
+
+python test.py --img_dir ../data/val/image \
+ --checkpoint_file ./work_dirs/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_subset_pretrain_480x360_22K/best_mIoU_iter_4000.pth \
+ --config_file ./work_dirs/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_subset_pretrain_480x360_22K/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_subset_pretrain_480x360_22K.py \
+ --vis_dir ./work_dirs/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_subset_pretrain_480x360_22K/outputs/val \
+ --seg_dir ./work_dirs/upernet_swin_base_patch4_window12_512x512_160k_egohos_handobj2_subset_pretrain_480x360_22K/outputs/val_seg
+
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/__init__.py b/EgoHOS/raw/script/mmsegmentation/tests/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..ef101fec61e72abc0eb90266d453b5b22331378d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/__init__.py
@@ -0,0 +1 @@
+# Copyright (c) OpenMMLab. All rights reserved.
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_apis/test_single_gpu.py b/EgoHOS/raw/script/mmsegmentation/tests/test_apis/test_single_gpu.py
new file mode 100644
index 0000000000000000000000000000000000000000..0b484f201a3dc699401b4c8d7c1f045548aa5f6d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_apis/test_single_gpu.py
@@ -0,0 +1,73 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import shutil
+from unittest.mock import MagicMock
+
+import numpy as np
+import pytest
+import torch
+import torch.nn as nn
+from torch.utils.data import DataLoader, Dataset, dataloader
+
+from mmseg.apis import single_gpu_test
+
+
+class ExampleDataset(Dataset):
+
+ def __getitem__(self, idx):
+ results = dict(img=torch.tensor([1]), img_metas=dict())
+ return results
+
+ def __len__(self):
+ return 1
+
+
+class ExampleModel(nn.Module):
+
+ def __init__(self):
+ super(ExampleModel, self).__init__()
+ self.test_cfg = None
+ self.conv = nn.Conv2d(3, 3, 3)
+
+ def forward(self, img, img_metas, return_loss=False, **kwargs):
+ return img
+
+
+def test_single_gpu():
+ test_dataset = ExampleDataset()
+ data_loader = DataLoader(
+ test_dataset,
+ batch_size=1,
+ sampler=None,
+ num_workers=0,
+ shuffle=False,
+ )
+ model = ExampleModel()
+
+ # Test efficient test compatibility (will be deprecated)
+ results = single_gpu_test(model, data_loader, efficient_test=True)
+ assert len(results) == 1
+ pred = np.load(results[0])
+ assert isinstance(pred, np.ndarray)
+ assert pred.shape == (1, )
+ assert pred[0] == 1
+
+ shutil.rmtree('.efficient_test')
+
+ # Test pre_eval
+ test_dataset.pre_eval = MagicMock(return_value=['success'])
+ results = single_gpu_test(model, data_loader, pre_eval=True)
+ assert results == ['success']
+
+ # Test format_only
+ test_dataset.format_results = MagicMock(return_value=['success'])
+ results = single_gpu_test(model, data_loader, format_only=True)
+ assert results == ['success']
+
+ # efficient_test, pre_eval and format_only are mutually exclusive
+ with pytest.raises(AssertionError):
+ single_gpu_test(
+ model,
+ dataloader,
+ efficient_test=True,
+ format_only=True,
+ pre_eval=True)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_config.py b/EgoHOS/raw/script/mmsegmentation/tests/test_config.py
new file mode 100644
index 0000000000000000000000000000000000000000..248214443966d4a0b4bb56d668210da1e4c45838
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_config.py
@@ -0,0 +1,162 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import glob
+import os
+from os.path import dirname, exists, isdir, join, relpath
+
+from mmcv import Config
+from torch import nn
+
+from mmseg.models import build_segmentor
+
+
+def _get_config_directory():
+ """Find the predefined segmentor config directory."""
+ try:
+ # Assume we are running in the source mmsegmentation repo
+ repo_dpath = dirname(dirname(__file__))
+ except NameError:
+ # For IPython development when this __file__ is not defined
+ import mmseg
+ repo_dpath = dirname(dirname(mmseg.__file__))
+ config_dpath = join(repo_dpath, 'configs')
+ if not exists(config_dpath):
+ raise Exception('Cannot find config path')
+ return config_dpath
+
+
+def test_config_build_segmentor():
+ """Test that all segmentation models defined in the configs can be
+ initialized."""
+ config_dpath = _get_config_directory()
+ print('Found config_dpath = {!r}'.format(config_dpath))
+
+ config_fpaths = []
+ # one config each sub folder
+ for sub_folder in os.listdir(config_dpath):
+ if isdir(sub_folder):
+ config_fpaths.append(
+ list(glob.glob(join(config_dpath, sub_folder, '*.py')))[0])
+ config_fpaths = [p for p in config_fpaths if p.find('_base_') == -1]
+ config_names = [relpath(p, config_dpath) for p in config_fpaths]
+
+ print('Using {} config files'.format(len(config_names)))
+
+ for config_fname in config_names:
+ config_fpath = join(config_dpath, config_fname)
+ config_mod = Config.fromfile(config_fpath)
+
+ config_mod.model
+ print('Building segmentor, config_fpath = {!r}'.format(config_fpath))
+
+ # Remove pretrained keys to allow for testing in an offline environment
+ if 'pretrained' in config_mod.model:
+ config_mod.model['pretrained'] = None
+
+ print('building {}'.format(config_fname))
+ segmentor = build_segmentor(config_mod.model)
+ assert segmentor is not None
+
+ head_config = config_mod.model['decode_head']
+ _check_decode_head(head_config, segmentor.decode_head)
+
+
+def test_config_data_pipeline():
+ """Test whether the data pipeline is valid and can process corner cases.
+
+ CommandLine:
+ xdoctest -m tests/test_config.py test_config_build_data_pipeline
+ """
+ import numpy as np
+ from mmcv import Config
+
+ from mmseg.datasets.pipelines import Compose
+
+ config_dpath = _get_config_directory()
+ print('Found config_dpath = {!r}'.format(config_dpath))
+
+ import glob
+ config_fpaths = list(glob.glob(join(config_dpath, '**', '*.py')))
+ config_fpaths = [p for p in config_fpaths if p.find('_base_') == -1]
+ config_names = [relpath(p, config_dpath) for p in config_fpaths]
+
+ print('Using {} config files'.format(len(config_names)))
+
+ for config_fname in config_names:
+ config_fpath = join(config_dpath, config_fname)
+ print(
+ 'Building data pipeline, config_fpath = {!r}'.format(config_fpath))
+ config_mod = Config.fromfile(config_fpath)
+
+ # remove loading pipeline
+ load_img_pipeline = config_mod.train_pipeline.pop(0)
+ to_float32 = load_img_pipeline.get('to_float32', False)
+ config_mod.train_pipeline.pop(0)
+ config_mod.test_pipeline.pop(0)
+
+ train_pipeline = Compose(config_mod.train_pipeline)
+ test_pipeline = Compose(config_mod.test_pipeline)
+
+ img = np.random.randint(0, 255, size=(1024, 2048, 3), dtype=np.uint8)
+ if to_float32:
+ img = img.astype(np.float32)
+ seg = np.random.randint(0, 255, size=(1024, 2048, 1), dtype=np.uint8)
+
+ results = dict(
+ filename='test_img.png',
+ ori_filename='test_img.png',
+ img=img,
+ img_shape=img.shape,
+ ori_shape=img.shape,
+ gt_semantic_seg=seg)
+ results['seg_fields'] = ['gt_semantic_seg']
+
+ print('Test training data pipeline: \n{!r}'.format(train_pipeline))
+ output_results = train_pipeline(results)
+ assert output_results is not None
+
+ results = dict(
+ filename='test_img.png',
+ ori_filename='test_img.png',
+ img=img,
+ img_shape=img.shape,
+ ori_shape=img.shape,
+ )
+ print('Test testing data pipeline: \n{!r}'.format(test_pipeline))
+ output_results = test_pipeline(results)
+ assert output_results is not None
+
+
+def _check_decode_head(decode_head_cfg, decode_head):
+ if isinstance(decode_head_cfg, list):
+ assert isinstance(decode_head, nn.ModuleList)
+ assert len(decode_head_cfg) == len(decode_head)
+ num_heads = len(decode_head)
+ for i in range(num_heads):
+ _check_decode_head(decode_head_cfg[i], decode_head[i])
+ return
+ # check consistency between head_config and roi_head
+ assert decode_head_cfg['type'] == decode_head.__class__.__name__
+
+ assert decode_head_cfg['type'] == decode_head.__class__.__name__
+
+ in_channels = decode_head_cfg.in_channels
+ input_transform = decode_head.input_transform
+ assert input_transform in ['resize_concat', 'multiple_select', None]
+ if input_transform is not None:
+ assert isinstance(in_channels, (list, tuple))
+ assert isinstance(decode_head.in_index, (list, tuple))
+ assert len(in_channels) == len(decode_head.in_index)
+ elif input_transform == 'resize_concat':
+ assert sum(in_channels) == decode_head.in_channels
+ else:
+ assert isinstance(in_channels, int)
+ assert in_channels == decode_head.in_channels
+ assert isinstance(decode_head.in_index, int)
+
+ if decode_head_cfg['type'] == 'PointHead':
+ assert decode_head_cfg.channels+decode_head_cfg.num_classes == \
+ decode_head.fc_seg.in_channels
+ assert decode_head.fc_seg.out_channels == decode_head_cfg.num_classes
+ else:
+ assert decode_head_cfg.channels == decode_head.conv_seg.in_channels
+ assert decode_head.conv_seg.out_channels == decode_head_cfg.num_classes
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_core/test_layer_decay_optimizer_constructor.py b/EgoHOS/raw/script/mmsegmentation/tests/test_core/test_layer_decay_optimizer_constructor.py
new file mode 100644
index 0000000000000000000000000000000000000000..4911f3b3a9b699e8a218f0357132f80ec53da843
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_core/test_layer_decay_optimizer_constructor.py
@@ -0,0 +1,275 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+import torch.nn as nn
+from mmcv.cnn import ConvModule
+
+from mmseg.core.optimizers.layer_decay_optimizer_constructor import (
+ LayerDecayOptimizerConstructor, LearningRateDecayOptimizerConstructor)
+
+base_lr = 1
+decay_rate = 2
+base_wd = 0.05
+weight_decay = 0.05
+
+expected_stage_wise_lr_wd_convnext = [{
+ 'weight_decay': 0.0,
+ 'lr_scale': 128
+}, {
+ 'weight_decay': 0.0,
+ 'lr_scale': 1
+}, {
+ 'weight_decay': 0.05,
+ 'lr_scale': 64
+}, {
+ 'weight_decay': 0.0,
+ 'lr_scale': 64
+}, {
+ 'weight_decay': 0.05,
+ 'lr_scale': 32
+}, {
+ 'weight_decay': 0.0,
+ 'lr_scale': 32
+}, {
+ 'weight_decay': 0.05,
+ 'lr_scale': 16
+}, {
+ 'weight_decay': 0.0,
+ 'lr_scale': 16
+}, {
+ 'weight_decay': 0.05,
+ 'lr_scale': 8
+}, {
+ 'weight_decay': 0.0,
+ 'lr_scale': 8
+}, {
+ 'weight_decay': 0.05,
+ 'lr_scale': 128
+}, {
+ 'weight_decay': 0.05,
+ 'lr_scale': 1
+}]
+
+expected_layer_wise_lr_wd_convnext = [{
+ 'weight_decay': 0.0,
+ 'lr_scale': 128
+}, {
+ 'weight_decay': 0.0,
+ 'lr_scale': 1
+}, {
+ 'weight_decay': 0.05,
+ 'lr_scale': 64
+}, {
+ 'weight_decay': 0.0,
+ 'lr_scale': 64
+}, {
+ 'weight_decay': 0.05,
+ 'lr_scale': 32
+}, {
+ 'weight_decay': 0.0,
+ 'lr_scale': 32
+}, {
+ 'weight_decay': 0.05,
+ 'lr_scale': 16
+}, {
+ 'weight_decay': 0.0,
+ 'lr_scale': 16
+}, {
+ 'weight_decay': 0.05,
+ 'lr_scale': 2
+}, {
+ 'weight_decay': 0.0,
+ 'lr_scale': 2
+}, {
+ 'weight_decay': 0.05,
+ 'lr_scale': 128
+}, {
+ 'weight_decay': 0.05,
+ 'lr_scale': 1
+}]
+
+expected_layer_wise_wd_lr_beit = [{
+ 'weight_decay': 0.0,
+ 'lr_scale': 16
+}, {
+ 'weight_decay': 0.05,
+ 'lr_scale': 8
+}, {
+ 'weight_decay': 0.0,
+ 'lr_scale': 8
+}, {
+ 'weight_decay': 0.05,
+ 'lr_scale': 4
+}, {
+ 'weight_decay': 0.0,
+ 'lr_scale': 4
+}, {
+ 'weight_decay': 0.05,
+ 'lr_scale': 2
+}, {
+ 'weight_decay': 0.0,
+ 'lr_scale': 2
+}, {
+ 'weight_decay': 0.05,
+ 'lr_scale': 1
+}, {
+ 'weight_decay': 0.0,
+ 'lr_scale': 1
+}]
+
+
+class ToyConvNeXt(nn.Module):
+
+ def __init__(self):
+ super().__init__()
+ self.stages = nn.ModuleList()
+ for i in range(4):
+ stage = nn.Sequential(ConvModule(3, 4, kernel_size=1, bias=True))
+ self.stages.append(stage)
+ self.norm0 = nn.BatchNorm2d(2)
+
+ # add some variables to meet unit test coverate rate
+ self.cls_token = nn.Parameter(torch.ones(1))
+ self.mask_token = nn.Parameter(torch.ones(1))
+ self.pos_embed = nn.Parameter(torch.ones(1))
+ self.stem_norm = nn.Parameter(torch.ones(1))
+ self.downsample_norm0 = nn.BatchNorm2d(2)
+ self.downsample_norm1 = nn.BatchNorm2d(2)
+ self.downsample_norm2 = nn.BatchNorm2d(2)
+ self.lin = nn.Parameter(torch.ones(1))
+ self.lin.requires_grad = False
+ self.downsample_layers = nn.ModuleList()
+ for _ in range(4):
+ stage = nn.Sequential(nn.Conv2d(3, 4, kernel_size=1, bias=True))
+ self.downsample_layers.append(stage)
+
+
+class ToyBEiT(nn.Module):
+
+ def __init__(self):
+ super().__init__()
+ # add some variables to meet unit test coverate rate
+ self.cls_token = nn.Parameter(torch.ones(1))
+ self.patch_embed = nn.Parameter(torch.ones(1))
+ self.layers = nn.ModuleList()
+ for _ in range(3):
+ layer = nn.Conv2d(3, 3, 1)
+ self.layers.append(layer)
+
+
+class ToyMAE(nn.Module):
+
+ def __init__(self):
+ super().__init__()
+ # add some variables to meet unit test coverate rate
+ self.cls_token = nn.Parameter(torch.ones(1))
+ self.patch_embed = nn.Parameter(torch.ones(1))
+ self.layers = nn.ModuleList()
+ for _ in range(3):
+ layer = nn.Conv2d(3, 3, 1)
+ self.layers.append(layer)
+
+
+class ToySegmentor(nn.Module):
+
+ def __init__(self, backbone):
+ super().__init__()
+ self.backbone = backbone
+ self.decode_head = nn.Conv2d(2, 2, kernel_size=1, groups=2)
+
+
+class PseudoDataParallel(nn.Module):
+
+ def __init__(self, model):
+ super().__init__()
+ self.module = model
+
+
+class ToyViT(nn.Module):
+
+ def __init__(self):
+ super().__init__()
+
+
+def check_optimizer_lr_wd(optimizer, gt_lr_wd):
+ assert isinstance(optimizer, torch.optim.AdamW)
+ assert optimizer.defaults['lr'] == base_lr
+ assert optimizer.defaults['weight_decay'] == base_wd
+ param_groups = optimizer.param_groups
+ print(param_groups)
+ assert len(param_groups) == len(gt_lr_wd)
+ for i, param_dict in enumerate(param_groups):
+ assert param_dict['weight_decay'] == gt_lr_wd[i]['weight_decay']
+ assert param_dict['lr_scale'] == gt_lr_wd[i]['lr_scale']
+ assert param_dict['lr_scale'] == param_dict['lr']
+
+
+def test_learning_rate_decay_optimizer_constructor():
+
+ # Test lr wd for ConvNeXT
+ backbone = ToyConvNeXt()
+ model = PseudoDataParallel(ToySegmentor(backbone))
+ optimizer_cfg = dict(
+ type='AdamW', lr=base_lr, betas=(0.9, 0.999), weight_decay=0.05)
+ # stagewise decay
+ stagewise_paramwise_cfg = dict(
+ decay_rate=decay_rate, decay_type='stage_wise', num_layers=6)
+ optim_constructor = LearningRateDecayOptimizerConstructor(
+ optimizer_cfg, stagewise_paramwise_cfg)
+ optimizer = optim_constructor(model)
+ check_optimizer_lr_wd(optimizer, expected_stage_wise_lr_wd_convnext)
+ # layerwise decay
+ layerwise_paramwise_cfg = dict(
+ decay_rate=decay_rate, decay_type='layer_wise', num_layers=6)
+ optim_constructor = LearningRateDecayOptimizerConstructor(
+ optimizer_cfg, layerwise_paramwise_cfg)
+ optimizer = optim_constructor(model)
+ check_optimizer_lr_wd(optimizer, expected_layer_wise_lr_wd_convnext)
+
+ # Test lr wd for BEiT
+ backbone = ToyBEiT()
+ model = PseudoDataParallel(ToySegmentor(backbone))
+
+ layerwise_paramwise_cfg = dict(
+ decay_rate=decay_rate, decay_type='layer_wise', num_layers=3)
+ optim_constructor = LearningRateDecayOptimizerConstructor(
+ optimizer_cfg, layerwise_paramwise_cfg)
+ optimizer = optim_constructor(model)
+ check_optimizer_lr_wd(optimizer, expected_layer_wise_wd_lr_beit)
+
+ # Test invalidation of lr wd for Vit
+ backbone = ToyViT()
+ model = PseudoDataParallel(ToySegmentor(backbone))
+ with pytest.raises(NotImplementedError):
+ optim_constructor = LearningRateDecayOptimizerConstructor(
+ optimizer_cfg, layerwise_paramwise_cfg)
+ optimizer = optim_constructor(model)
+ with pytest.raises(NotImplementedError):
+ optim_constructor = LearningRateDecayOptimizerConstructor(
+ optimizer_cfg, stagewise_paramwise_cfg)
+ optimizer = optim_constructor(model)
+
+ # Test lr wd for MAE
+ backbone = ToyMAE()
+ model = PseudoDataParallel(ToySegmentor(backbone))
+
+ layerwise_paramwise_cfg = dict(
+ decay_rate=decay_rate, decay_type='layer_wise', num_layers=3)
+ optim_constructor = LearningRateDecayOptimizerConstructor(
+ optimizer_cfg, layerwise_paramwise_cfg)
+ optimizer = optim_constructor(model)
+ check_optimizer_lr_wd(optimizer, expected_layer_wise_wd_lr_beit)
+
+
+def test_beit_layer_decay_optimizer_constructor():
+
+ # paramwise_cfg with BEiTExampleModel
+ backbone = ToyBEiT()
+ model = PseudoDataParallel(ToySegmentor(backbone))
+ optimizer_cfg = dict(
+ type='AdamW', lr=1, betas=(0.9, 0.999), weight_decay=0.05)
+ paramwise_cfg = dict(layer_decay_rate=2, num_layers=3)
+ optim_constructor = LayerDecayOptimizerConstructor(optimizer_cfg,
+ paramwise_cfg)
+ optimizer = optim_constructor(model)
+ check_optimizer_lr_wd(optimizer, expected_layer_wise_wd_lr_beit)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_core/test_optimizer.py b/EgoHOS/raw/script/mmsegmentation/tests/test_core/test_optimizer.py
new file mode 100644
index 0000000000000000000000000000000000000000..247f9feb10413a747f07f3ed1715a04cc990b0c5
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_core/test_optimizer.py
@@ -0,0 +1,59 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+import torch.nn as nn
+from mmcv.runner import DefaultOptimizerConstructor
+
+from mmseg.core.builder import (OPTIMIZER_BUILDERS, build_optimizer,
+ build_optimizer_constructor)
+
+
+class ExampleModel(nn.Module):
+
+ def __init__(self):
+ super().__init__()
+ self.param1 = nn.Parameter(torch.ones(1))
+ self.conv1 = nn.Conv2d(3, 4, kernel_size=1, bias=False)
+ self.conv2 = nn.Conv2d(4, 2, kernel_size=1)
+ self.bn = nn.BatchNorm2d(2)
+
+ def forward(self, x):
+ return x
+
+
+base_lr = 0.01
+base_wd = 0.0001
+momentum = 0.9
+
+
+def test_build_optimizer_constructor():
+ optimizer_cfg = dict(
+ type='SGD', lr=base_lr, weight_decay=base_wd, momentum=momentum)
+ optim_constructor_cfg = dict(
+ type='DefaultOptimizerConstructor', optimizer_cfg=optimizer_cfg)
+ optim_constructor = build_optimizer_constructor(optim_constructor_cfg)
+ # Test whether optimizer constructor can be built from parent.
+ assert type(optim_constructor) is DefaultOptimizerConstructor
+
+ @OPTIMIZER_BUILDERS.register_module()
+ class MyOptimizerConstructor(DefaultOptimizerConstructor):
+ pass
+
+ optim_constructor_cfg = dict(
+ type='MyOptimizerConstructor', optimizer_cfg=optimizer_cfg)
+ optim_constructor = build_optimizer_constructor(optim_constructor_cfg)
+ # Test optimizer constructor can be built from child registry.
+ assert type(optim_constructor) is MyOptimizerConstructor
+
+ # Test unregistered constructor cannot be built
+ with pytest.raises(KeyError):
+ build_optimizer_constructor(dict(type='A'))
+
+
+def test_build_optimizer():
+ model = ExampleModel()
+ optimizer_cfg = dict(
+ type='SGD', lr=base_lr, weight_decay=base_wd, momentum=momentum)
+ optimizer = build_optimizer(model, optimizer_cfg)
+ # test whether optimizer is successfully built from parent.
+ assert isinstance(optimizer, torch.optim.SGD)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_data/test_dataset.py b/EgoHOS/raw/script/mmsegmentation/tests/test_data/test_dataset.py
new file mode 100644
index 0000000000000000000000000000000000000000..6ea6eb9852d573a86231677ede849bb110534a12
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_data/test_dataset.py
@@ -0,0 +1,851 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import os
+import os.path as osp
+import shutil
+import tempfile
+from typing import Generator
+from unittest.mock import MagicMock, patch
+
+import numpy as np
+import pytest
+import torch
+from PIL import Image
+
+from mmseg.core.evaluation import get_classes, get_palette
+from mmseg.datasets import (DATASETS, ADE20KDataset, CityscapesDataset,
+ COCOStuffDataset, ConcatDataset, CustomDataset,
+ ISPRSDataset, LoveDADataset, MultiImageMixDataset,
+ PascalVOCDataset, PotsdamDataset, RepeatDataset,
+ build_dataset, iSAIDDataset)
+
+
+def test_classes():
+ assert list(CityscapesDataset.CLASSES) == get_classes('cityscapes')
+ assert list(PascalVOCDataset.CLASSES) == get_classes('voc') == get_classes(
+ 'pascal_voc')
+ assert list(
+ ADE20KDataset.CLASSES) == get_classes('ade') == get_classes('ade20k')
+ assert list(COCOStuffDataset.CLASSES) == get_classes('cocostuff')
+ assert list(LoveDADataset.CLASSES) == get_classes('loveda')
+ assert list(PotsdamDataset.CLASSES) == get_classes('potsdam')
+ assert list(ISPRSDataset.CLASSES) == get_classes('vaihingen')
+ assert list(iSAIDDataset.CLASSES) == get_classes('isaid')
+
+ with pytest.raises(ValueError):
+ get_classes('unsupported')
+
+
+def test_classes_file_path():
+ tmp_file = tempfile.NamedTemporaryFile()
+ classes_path = f'{tmp_file.name}.txt'
+ train_pipeline = [dict(type='LoadImageFromFile')]
+ kwargs = dict(pipeline=train_pipeline, img_dir='./', classes=classes_path)
+
+ # classes.txt with full categories
+ categories = get_classes('cityscapes')
+ with open(classes_path, 'w') as f:
+ f.write('\n'.join(categories))
+ assert list(CityscapesDataset(**kwargs).CLASSES) == categories
+
+ # classes.txt with sub categories
+ categories = ['road', 'sidewalk', 'building']
+ with open(classes_path, 'w') as f:
+ f.write('\n'.join(categories))
+ assert list(CityscapesDataset(**kwargs).CLASSES) == categories
+
+ # classes.txt with unknown categories
+ categories = ['road', 'sidewalk', 'unknown']
+ with open(classes_path, 'w') as f:
+ f.write('\n'.join(categories))
+
+ with pytest.raises(ValueError):
+ CityscapesDataset(**kwargs)
+
+ tmp_file.close()
+ os.remove(classes_path)
+ assert not osp.exists(classes_path)
+
+
+def test_palette():
+ assert CityscapesDataset.PALETTE == get_palette('cityscapes')
+ assert PascalVOCDataset.PALETTE == get_palette('voc') == get_palette(
+ 'pascal_voc')
+ assert ADE20KDataset.PALETTE == get_palette('ade') == get_palette('ade20k')
+ assert LoveDADataset.PALETTE == get_palette('loveda')
+ assert PotsdamDataset.PALETTE == get_palette('potsdam')
+ assert COCOStuffDataset.PALETTE == get_palette('cocostuff')
+ assert iSAIDDataset.PALETTE == get_palette('isaid')
+
+ with pytest.raises(ValueError):
+ get_palette('unsupported')
+
+
+@patch('mmseg.datasets.CustomDataset.load_annotations', MagicMock)
+@patch('mmseg.datasets.CustomDataset.__getitem__',
+ MagicMock(side_effect=lambda idx: idx))
+def test_dataset_wrapper():
+ # CustomDataset.load_annotations = MagicMock()
+ # CustomDataset.__getitem__ = MagicMock(side_effect=lambda idx: idx)
+ dataset_a = CustomDataset(img_dir=MagicMock(), pipeline=[])
+ len_a = 10
+ dataset_a.img_infos = MagicMock()
+ dataset_a.img_infos.__len__.return_value = len_a
+ dataset_b = CustomDataset(img_dir=MagicMock(), pipeline=[])
+ len_b = 20
+ dataset_b.img_infos = MagicMock()
+ dataset_b.img_infos.__len__.return_value = len_b
+
+ concat_dataset = ConcatDataset([dataset_a, dataset_b])
+ assert concat_dataset[5] == 5
+ assert concat_dataset[25] == 15
+ assert len(concat_dataset) == len(dataset_a) + len(dataset_b)
+
+ repeat_dataset = RepeatDataset(dataset_a, 10)
+ assert repeat_dataset[5] == 5
+ assert repeat_dataset[15] == 5
+ assert repeat_dataset[27] == 7
+ assert len(repeat_dataset) == 10 * len(dataset_a)
+
+ img_scale = (60, 60)
+ pipeline = [
+ dict(type='RandomMosaic', prob=1, img_scale=img_scale),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='Resize', img_scale=img_scale, keep_ratio=False),
+ ]
+
+ CustomDataset.load_annotations = MagicMock()
+ results = []
+ for _ in range(2):
+ height = np.random.randint(10, 30)
+ weight = np.random.randint(10, 30)
+ img = np.ones((height, weight, 3))
+ gt_semantic_seg = np.random.randint(5, size=(height, weight))
+ results.append(dict(gt_semantic_seg=gt_semantic_seg, img=img))
+
+ classes = ['0', '1', '2', '3', '4']
+ palette = [(0, 0, 0), (1, 1, 1), (2, 2, 2), (3, 3, 3), (4, 4, 4)]
+ CustomDataset.__getitem__ = MagicMock(side_effect=lambda idx: results[idx])
+ dataset_a = CustomDataset(
+ img_dir=MagicMock(),
+ pipeline=[],
+ test_mode=True,
+ classes=classes,
+ palette=palette)
+ len_a = 2
+ dataset_a.img_infos = MagicMock()
+ dataset_a.img_infos.__len__.return_value = len_a
+
+ multi_image_mix_dataset = MultiImageMixDataset(dataset_a, pipeline)
+ assert len(multi_image_mix_dataset) == len(dataset_a)
+
+ for idx in range(len_a):
+ results_ = multi_image_mix_dataset[idx]
+
+ # test skip_type_keys
+ multi_image_mix_dataset = MultiImageMixDataset(
+ dataset_a, pipeline, skip_type_keys=('RandomFlip'))
+ for idx in range(len_a):
+ results_ = multi_image_mix_dataset[idx]
+ assert results_['img'].shape == (img_scale[0], img_scale[1], 3)
+
+ skip_type_keys = ('RandomFlip', 'Resize')
+ multi_image_mix_dataset.update_skip_type_keys(skip_type_keys)
+ for idx in range(len_a):
+ results_ = multi_image_mix_dataset[idx]
+ assert results_['img'].shape[:2] != img_scale
+
+ # test pipeline
+ with pytest.raises(TypeError):
+ pipeline = [['Resize']]
+ multi_image_mix_dataset = MultiImageMixDataset(dataset_a, pipeline)
+
+
+def test_custom_dataset():
+ img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53],
+ std=[58.395, 57.12, 57.375],
+ to_rgb=True)
+ crop_size = (512, 1024)
+ train_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(type='LoadAnnotations'),
+ dict(type='Resize', img_scale=(128, 256), ratio_range=(0.5, 2.0)),
+ dict(type='RandomCrop', crop_size=crop_size, cat_max_ratio=0.75),
+ dict(type='RandomFlip', prob=0.5),
+ dict(type='PhotoMetricDistortion'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='Pad', size=crop_size, pad_val=0, seg_pad_val=255),
+ dict(type='DefaultFormatBundle'),
+ dict(type='Collect', keys=['img', 'gt_semantic_seg']),
+ ]
+ test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(128, 256),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+ ]
+
+ # with img_dir and ann_dir
+ train_dataset = CustomDataset(
+ train_pipeline,
+ data_root=osp.join(osp.dirname(__file__), '../data/pseudo_dataset'),
+ img_dir='imgs/',
+ ann_dir='gts/',
+ img_suffix='img.jpg',
+ seg_map_suffix='gt.png')
+ assert len(train_dataset) == 5
+
+ # with img_dir, ann_dir, split
+ train_dataset = CustomDataset(
+ train_pipeline,
+ data_root=osp.join(osp.dirname(__file__), '../data/pseudo_dataset'),
+ img_dir='imgs/',
+ ann_dir='gts/',
+ img_suffix='img.jpg',
+ seg_map_suffix='gt.png',
+ split='splits/train.txt')
+ assert len(train_dataset) == 4
+
+ # no data_root
+ train_dataset = CustomDataset(
+ train_pipeline,
+ img_dir=osp.join(osp.dirname(__file__), '../data/pseudo_dataset/imgs'),
+ ann_dir=osp.join(osp.dirname(__file__), '../data/pseudo_dataset/gts'),
+ img_suffix='img.jpg',
+ seg_map_suffix='gt.png')
+ assert len(train_dataset) == 5
+
+ # with data_root but img_dir/ann_dir are abs path
+ train_dataset = CustomDataset(
+ train_pipeline,
+ data_root=osp.join(osp.dirname(__file__), '../data/pseudo_dataset'),
+ img_dir=osp.abspath(
+ osp.join(osp.dirname(__file__), '../data/pseudo_dataset/imgs')),
+ ann_dir=osp.abspath(
+ osp.join(osp.dirname(__file__), '../data/pseudo_dataset/gts')),
+ img_suffix='img.jpg',
+ seg_map_suffix='gt.png')
+ assert len(train_dataset) == 5
+
+ # test_mode=True
+ test_dataset = CustomDataset(
+ test_pipeline,
+ img_dir=osp.join(osp.dirname(__file__), '../data/pseudo_dataset/imgs'),
+ img_suffix='img.jpg',
+ test_mode=True,
+ classes=('pseudo_class', ))
+ assert len(test_dataset) == 5
+
+ # training data get
+ train_data = train_dataset[0]
+ assert isinstance(train_data, dict)
+
+ # test data get
+ test_data = test_dataset[0]
+ assert isinstance(test_data, dict)
+
+ # get gt seg map
+ gt_seg_maps = train_dataset.get_gt_seg_maps(efficient_test=True)
+ assert isinstance(gt_seg_maps, Generator)
+ gt_seg_maps = list(gt_seg_maps)
+ assert len(gt_seg_maps) == 5
+
+ # format_results not implemented
+ with pytest.raises(NotImplementedError):
+ test_dataset.format_results([], '')
+
+ pseudo_results = []
+ for gt_seg_map in gt_seg_maps:
+ h, w = gt_seg_map.shape
+ pseudo_results.append(np.random.randint(low=0, high=7, size=(h, w)))
+
+ # test past evaluation without CLASSES
+ with pytest.raises(TypeError):
+ eval_results = train_dataset.evaluate(pseudo_results, metric=['mIoU'])
+
+ with pytest.raises(TypeError):
+ eval_results = train_dataset.evaluate(pseudo_results, metric='mDice')
+
+ with pytest.raises(TypeError):
+ eval_results = train_dataset.evaluate(
+ pseudo_results, metric=['mDice', 'mIoU'])
+
+ # test past evaluation with CLASSES
+ train_dataset.CLASSES = tuple(['a'] * 7)
+ eval_results = train_dataset.evaluate(pseudo_results, metric='mIoU')
+ assert isinstance(eval_results, dict)
+ assert 'mIoU' in eval_results
+ assert 'mAcc' in eval_results
+ assert 'aAcc' in eval_results
+
+ eval_results = train_dataset.evaluate(pseudo_results, metric='mDice')
+ assert isinstance(eval_results, dict)
+ assert 'mDice' in eval_results
+ assert 'mAcc' in eval_results
+ assert 'aAcc' in eval_results
+
+ eval_results = train_dataset.evaluate(pseudo_results, metric='mFscore')
+ assert isinstance(eval_results, dict)
+ assert 'mRecall' in eval_results
+ assert 'mPrecision' in eval_results
+ assert 'mFscore' in eval_results
+ assert 'aAcc' in eval_results
+
+ eval_results = train_dataset.evaluate(
+ pseudo_results, metric=['mIoU', 'mDice', 'mFscore'])
+ assert isinstance(eval_results, dict)
+ assert 'mIoU' in eval_results
+ assert 'mDice' in eval_results
+ assert 'mAcc' in eval_results
+ assert 'aAcc' in eval_results
+ assert 'mFscore' in eval_results
+ assert 'mPrecision' in eval_results
+ assert 'mRecall' in eval_results
+
+ assert not np.isnan(eval_results['mIoU'])
+ assert not np.isnan(eval_results['mDice'])
+ assert not np.isnan(eval_results['mAcc'])
+ assert not np.isnan(eval_results['aAcc'])
+ assert not np.isnan(eval_results['mFscore'])
+ assert not np.isnan(eval_results['mPrecision'])
+ assert not np.isnan(eval_results['mRecall'])
+
+ # test evaluation with pre-eval and the dataset.CLASSES is necessary
+ train_dataset.CLASSES = tuple(['a'] * 7)
+ pseudo_results = []
+ for idx in range(len(train_dataset)):
+ h, w = gt_seg_maps[idx].shape
+ pseudo_result = np.random.randint(low=0, high=7, size=(h, w))
+ pseudo_results.extend(train_dataset.pre_eval(pseudo_result, idx))
+ eval_results = train_dataset.evaluate(pseudo_results, metric=['mIoU'])
+ assert isinstance(eval_results, dict)
+ assert 'mIoU' in eval_results
+ assert 'mAcc' in eval_results
+ assert 'aAcc' in eval_results
+
+ eval_results = train_dataset.evaluate(pseudo_results, metric='mDice')
+ assert isinstance(eval_results, dict)
+ assert 'mDice' in eval_results
+ assert 'mAcc' in eval_results
+ assert 'aAcc' in eval_results
+
+ eval_results = train_dataset.evaluate(pseudo_results, metric='mFscore')
+ assert isinstance(eval_results, dict)
+ assert 'mRecall' in eval_results
+ assert 'mPrecision' in eval_results
+ assert 'mFscore' in eval_results
+ assert 'aAcc' in eval_results
+
+ eval_results = train_dataset.evaluate(
+ pseudo_results, metric=['mIoU', 'mDice', 'mFscore'])
+ assert isinstance(eval_results, dict)
+ assert 'mIoU' in eval_results
+ assert 'mDice' in eval_results
+ assert 'mAcc' in eval_results
+ assert 'aAcc' in eval_results
+ assert 'mFscore' in eval_results
+ assert 'mPrecision' in eval_results
+ assert 'mRecall' in eval_results
+
+ assert not np.isnan(eval_results['mIoU'])
+ assert not np.isnan(eval_results['mDice'])
+ assert not np.isnan(eval_results['mAcc'])
+ assert not np.isnan(eval_results['aAcc'])
+ assert not np.isnan(eval_results['mFscore'])
+ assert not np.isnan(eval_results['mPrecision'])
+ assert not np.isnan(eval_results['mRecall'])
+
+
+@pytest.mark.parametrize('separate_eval', [True, False])
+def test_eval_concat_custom_dataset(separate_eval):
+ img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53],
+ std=[58.395, 57.12, 57.375],
+ to_rgb=True)
+ test_pipeline = [
+ dict(type='LoadImageFromFile'),
+ dict(
+ type='MultiScaleFlipAug',
+ img_scale=(128, 256),
+ # img_ratios=[0.5, 0.75, 1.0, 1.25, 1.5, 1.75],
+ flip=False,
+ transforms=[
+ dict(type='Resize', keep_ratio=True),
+ dict(type='RandomFlip'),
+ dict(type='Normalize', **img_norm_cfg),
+ dict(type='ImageToTensor', keys=['img']),
+ dict(type='Collect', keys=['img']),
+ ])
+ ]
+ data_root = osp.join(osp.dirname(__file__), '../data/pseudo_dataset')
+ img_dir = 'imgs/'
+ ann_dir = 'gts/'
+
+ cfg1 = dict(
+ type='CustomDataset',
+ pipeline=test_pipeline,
+ data_root=data_root,
+ img_dir=img_dir,
+ ann_dir=ann_dir,
+ img_suffix='img.jpg',
+ seg_map_suffix='gt.png',
+ classes=tuple(['a'] * 7))
+ dataset1 = build_dataset(cfg1)
+ assert len(dataset1) == 5
+ # get gt seg map
+ gt_seg_maps = dataset1.get_gt_seg_maps(efficient_test=True)
+ assert isinstance(gt_seg_maps, Generator)
+ gt_seg_maps = list(gt_seg_maps)
+ assert len(gt_seg_maps) == 5
+
+ # test past evaluation
+ pseudo_results = []
+ for gt_seg_map in gt_seg_maps:
+ h, w = gt_seg_map.shape
+ pseudo_results.append(np.random.randint(low=0, high=7, size=(h, w)))
+ eval_results1 = dataset1.evaluate(
+ pseudo_results, metric=['mIoU', 'mDice', 'mFscore'])
+
+ # We use same dir twice for simplicity
+ # with ann_dir
+ cfg2 = dict(
+ type='CustomDataset',
+ pipeline=test_pipeline,
+ data_root=data_root,
+ img_dir=[img_dir, img_dir],
+ ann_dir=[ann_dir, ann_dir],
+ img_suffix='img.jpg',
+ seg_map_suffix='gt.png',
+ classes=tuple(['a'] * 7),
+ separate_eval=separate_eval)
+ dataset2 = build_dataset(cfg2)
+ assert isinstance(dataset2, ConcatDataset)
+ assert len(dataset2) == 10
+
+ eval_results2 = dataset2.evaluate(
+ pseudo_results * 2, metric=['mIoU', 'mDice', 'mFscore'])
+
+ if separate_eval:
+ assert eval_results1['mIoU'] == eval_results2[
+ '0_mIoU'] == eval_results2['1_mIoU']
+ assert eval_results1['mDice'] == eval_results2[
+ '0_mDice'] == eval_results2['1_mDice']
+ assert eval_results1['mAcc'] == eval_results2[
+ '0_mAcc'] == eval_results2['1_mAcc']
+ assert eval_results1['aAcc'] == eval_results2[
+ '0_aAcc'] == eval_results2['1_aAcc']
+ assert eval_results1['mFscore'] == eval_results2[
+ '0_mFscore'] == eval_results2['1_mFscore']
+ assert eval_results1['mPrecision'] == eval_results2[
+ '0_mPrecision'] == eval_results2['1_mPrecision']
+ assert eval_results1['mRecall'] == eval_results2[
+ '0_mRecall'] == eval_results2['1_mRecall']
+ else:
+ assert eval_results1['mIoU'] == eval_results2['mIoU']
+ assert eval_results1['mDice'] == eval_results2['mDice']
+ assert eval_results1['mAcc'] == eval_results2['mAcc']
+ assert eval_results1['aAcc'] == eval_results2['aAcc']
+ assert eval_results1['mFscore'] == eval_results2['mFscore']
+ assert eval_results1['mPrecision'] == eval_results2['mPrecision']
+ assert eval_results1['mRecall'] == eval_results2['mRecall']
+
+ # test get dataset_idx and sample_idx from ConcateDataset
+ dataset_idx, sample_idx = dataset2.get_dataset_idx_and_sample_idx(3)
+ assert dataset_idx == 0
+ assert sample_idx == 3
+
+ dataset_idx, sample_idx = dataset2.get_dataset_idx_and_sample_idx(7)
+ assert dataset_idx == 1
+ assert sample_idx == 2
+
+ dataset_idx, sample_idx = dataset2.get_dataset_idx_and_sample_idx(-7)
+ assert dataset_idx == 0
+ assert sample_idx == 3
+
+ # test negative indice exceed length of dataset
+ with pytest.raises(ValueError):
+ dataset_idx, sample_idx = dataset2.get_dataset_idx_and_sample_idx(-11)
+
+ # test negative indice value
+ indice = -6
+ dataset_idx1, sample_idx1 = dataset2.get_dataset_idx_and_sample_idx(indice)
+ dataset_idx2, sample_idx2 = dataset2.get_dataset_idx_and_sample_idx(
+ len(dataset2) + indice)
+ assert dataset_idx1 == dataset_idx2
+ assert sample_idx1 == sample_idx2
+
+ # test evaluation with pre-eval and the dataset.CLASSES is necessary
+ pseudo_results = []
+ eval_results1 = []
+ for idx in range(len(dataset1)):
+ h, w = gt_seg_maps[idx].shape
+ pseudo_result = np.random.randint(low=0, high=7, size=(h, w))
+ pseudo_results.append(pseudo_result)
+ eval_results1.extend(dataset1.pre_eval(pseudo_result, idx))
+
+ assert len(eval_results1) == len(dataset1)
+ assert isinstance(eval_results1[0], tuple)
+ assert len(eval_results1[0]) == 4
+ assert isinstance(eval_results1[0][0], torch.Tensor)
+
+ eval_results1 = dataset1.evaluate(
+ eval_results1, metric=['mIoU', 'mDice', 'mFscore'])
+
+ pseudo_results = pseudo_results * 2
+ eval_results2 = []
+ for idx in range(len(dataset2)):
+ eval_results2.extend(dataset2.pre_eval(pseudo_results[idx], idx))
+
+ assert len(eval_results2) == len(dataset2)
+ assert isinstance(eval_results2[0], tuple)
+ assert len(eval_results2[0]) == 4
+ assert isinstance(eval_results2[0][0], torch.Tensor)
+
+ eval_results2 = dataset2.evaluate(
+ eval_results2, metric=['mIoU', 'mDice', 'mFscore'])
+
+ if separate_eval:
+ assert eval_results1['mIoU'] == eval_results2[
+ '0_mIoU'] == eval_results2['1_mIoU']
+ assert eval_results1['mDice'] == eval_results2[
+ '0_mDice'] == eval_results2['1_mDice']
+ assert eval_results1['mAcc'] == eval_results2[
+ '0_mAcc'] == eval_results2['1_mAcc']
+ assert eval_results1['aAcc'] == eval_results2[
+ '0_aAcc'] == eval_results2['1_aAcc']
+ assert eval_results1['mFscore'] == eval_results2[
+ '0_mFscore'] == eval_results2['1_mFscore']
+ assert eval_results1['mPrecision'] == eval_results2[
+ '0_mPrecision'] == eval_results2['1_mPrecision']
+ assert eval_results1['mRecall'] == eval_results2[
+ '0_mRecall'] == eval_results2['1_mRecall']
+ else:
+ assert eval_results1['mIoU'] == eval_results2['mIoU']
+ assert eval_results1['mDice'] == eval_results2['mDice']
+ assert eval_results1['mAcc'] == eval_results2['mAcc']
+ assert eval_results1['aAcc'] == eval_results2['aAcc']
+ assert eval_results1['mFscore'] == eval_results2['mFscore']
+ assert eval_results1['mPrecision'] == eval_results2['mPrecision']
+ assert eval_results1['mRecall'] == eval_results2['mRecall']
+
+ # test batch_indices for pre eval
+ eval_results2 = dataset2.pre_eval(pseudo_results,
+ list(range(len(pseudo_results))))
+
+ assert len(eval_results2) == len(dataset2)
+ assert isinstance(eval_results2[0], tuple)
+ assert len(eval_results2[0]) == 4
+ assert isinstance(eval_results2[0][0], torch.Tensor)
+
+ eval_results2 = dataset2.evaluate(
+ eval_results2, metric=['mIoU', 'mDice', 'mFscore'])
+
+ if separate_eval:
+ assert eval_results1['mIoU'] == eval_results2[
+ '0_mIoU'] == eval_results2['1_mIoU']
+ assert eval_results1['mDice'] == eval_results2[
+ '0_mDice'] == eval_results2['1_mDice']
+ assert eval_results1['mAcc'] == eval_results2[
+ '0_mAcc'] == eval_results2['1_mAcc']
+ assert eval_results1['aAcc'] == eval_results2[
+ '0_aAcc'] == eval_results2['1_aAcc']
+ assert eval_results1['mFscore'] == eval_results2[
+ '0_mFscore'] == eval_results2['1_mFscore']
+ assert eval_results1['mPrecision'] == eval_results2[
+ '0_mPrecision'] == eval_results2['1_mPrecision']
+ assert eval_results1['mRecall'] == eval_results2[
+ '0_mRecall'] == eval_results2['1_mRecall']
+ else:
+ assert eval_results1['mIoU'] == eval_results2['mIoU']
+ assert eval_results1['mDice'] == eval_results2['mDice']
+ assert eval_results1['mAcc'] == eval_results2['mAcc']
+ assert eval_results1['aAcc'] == eval_results2['aAcc']
+ assert eval_results1['mFscore'] == eval_results2['mFscore']
+ assert eval_results1['mPrecision'] == eval_results2['mPrecision']
+ assert eval_results1['mRecall'] == eval_results2['mRecall']
+
+
+def test_ade():
+ test_dataset = ADE20KDataset(
+ pipeline=[],
+ img_dir=osp.join(osp.dirname(__file__), '../data/pseudo_dataset/imgs'))
+ assert len(test_dataset) == 5
+
+ # Test format_results
+ pseudo_results = []
+ for _ in range(len(test_dataset)):
+ h, w = (2, 2)
+ pseudo_results.append(np.random.randint(low=0, high=7, size=(h, w)))
+
+ file_paths = test_dataset.format_results(pseudo_results, '.format_ade')
+ assert len(file_paths) == len(test_dataset)
+ temp = np.array(Image.open(file_paths[0]))
+ assert np.allclose(temp, pseudo_results[0] + 1)
+
+ shutil.rmtree('.format_ade')
+
+
+@pytest.mark.parametrize('separate_eval', [True, False])
+def test_concat_ade(separate_eval):
+ test_dataset = ADE20KDataset(
+ pipeline=[],
+ img_dir=osp.join(osp.dirname(__file__), '../data/pseudo_dataset/imgs'))
+ assert len(test_dataset) == 5
+
+ concat_dataset = ConcatDataset([test_dataset, test_dataset],
+ separate_eval=separate_eval)
+ assert len(concat_dataset) == 10
+ # Test format_results
+ pseudo_results = []
+ for _ in range(len(concat_dataset)):
+ h, w = (2, 2)
+ pseudo_results.append(np.random.randint(low=0, high=7, size=(h, w)))
+
+ # test format per image
+ file_paths = []
+ for i in range(len(pseudo_results)):
+ file_paths.extend(
+ concat_dataset.format_results([pseudo_results[i]],
+ '.format_ade',
+ indices=[i]))
+ assert len(file_paths) == len(concat_dataset)
+ temp = np.array(Image.open(file_paths[0]))
+ assert np.allclose(temp, pseudo_results[0] + 1)
+
+ shutil.rmtree('.format_ade')
+
+ # test default argument
+ file_paths = concat_dataset.format_results(pseudo_results, '.format_ade')
+ assert len(file_paths) == len(concat_dataset)
+ temp = np.array(Image.open(file_paths[0]))
+ assert np.allclose(temp, pseudo_results[0] + 1)
+
+ shutil.rmtree('.format_ade')
+
+
+def test_cityscapes():
+ test_dataset = CityscapesDataset(
+ pipeline=[],
+ img_dir=osp.join(
+ osp.dirname(__file__),
+ '../data/pseudo_cityscapes_dataset/leftImg8bit'),
+ ann_dir=osp.join(
+ osp.dirname(__file__), '../data/pseudo_cityscapes_dataset/gtFine'))
+ assert len(test_dataset) == 1
+
+ gt_seg_maps = list(test_dataset.get_gt_seg_maps())
+
+ # Test format_results
+ pseudo_results = []
+ for idx in range(len(test_dataset)):
+ h, w = gt_seg_maps[idx].shape
+ pseudo_results.append(np.random.randint(low=0, high=19, size=(h, w)))
+
+ file_paths = test_dataset.format_results(pseudo_results, '.format_city')
+ assert len(file_paths) == len(test_dataset)
+ temp = np.array(Image.open(file_paths[0]))
+ assert np.allclose(temp,
+ test_dataset._convert_to_label_id(pseudo_results[0]))
+
+ # Test cityscapes evaluate
+
+ test_dataset.evaluate(
+ pseudo_results, metric='cityscapes', imgfile_prefix='.format_city')
+
+ shutil.rmtree('.format_city')
+
+
+@pytest.mark.parametrize('separate_eval', [True, False])
+def test_concat_cityscapes(separate_eval):
+ cityscape_dataset = CityscapesDataset(
+ pipeline=[],
+ img_dir=osp.join(
+ osp.dirname(__file__),
+ '../data/pseudo_cityscapes_dataset/leftImg8bit'),
+ ann_dir=osp.join(
+ osp.dirname(__file__), '../data/pseudo_cityscapes_dataset/gtFine'))
+ assert len(cityscape_dataset) == 1
+ with pytest.raises(NotImplementedError):
+ _ = ConcatDataset([cityscape_dataset, cityscape_dataset],
+ separate_eval=separate_eval)
+ ade_dataset = ADE20KDataset(
+ pipeline=[],
+ img_dir=osp.join(osp.dirname(__file__), '../data/pseudo_dataset/imgs'))
+ assert len(ade_dataset) == 5
+ with pytest.raises(NotImplementedError):
+ _ = ConcatDataset([cityscape_dataset, ade_dataset],
+ separate_eval=separate_eval)
+
+
+def test_loveda():
+ test_dataset = LoveDADataset(
+ pipeline=[],
+ img_dir=osp.join(
+ osp.dirname(__file__), '../data/pseudo_loveda_dataset/img_dir'),
+ ann_dir=osp.join(
+ osp.dirname(__file__), '../data/pseudo_loveda_dataset/ann_dir'))
+ assert len(test_dataset) == 3
+
+ gt_seg_maps = list(test_dataset.get_gt_seg_maps())
+
+ # Test format_results
+ pseudo_results = []
+ for idx in range(len(test_dataset)):
+ h, w = gt_seg_maps[idx].shape
+ pseudo_results.append(np.random.randint(low=0, high=7, size=(h, w)))
+ file_paths = test_dataset.format_results(pseudo_results, '.format_loveda')
+ assert len(file_paths) == len(test_dataset)
+ # Test loveda evaluate
+
+ test_dataset.evaluate(
+ pseudo_results, metric='mIoU', imgfile_prefix='.format_loveda')
+
+ shutil.rmtree('.format_loveda')
+
+
+def test_potsdam():
+ test_dataset = PotsdamDataset(
+ pipeline=[],
+ img_dir=osp.join(
+ osp.dirname(__file__), '../data/pseudo_potsdam_dataset/img_dir'),
+ ann_dir=osp.join(
+ osp.dirname(__file__), '../data/pseudo_potsdam_dataset/ann_dir'))
+ assert len(test_dataset) == 1
+
+
+def test_vaihingen():
+ test_dataset = ISPRSDataset(
+ pipeline=[],
+ img_dir=osp.join(
+ osp.dirname(__file__), '../data/pseudo_vaihingen_dataset/img_dir'),
+ ann_dir=osp.join(
+ osp.dirname(__file__), '../data/pseudo_vaihingen_dataset/ann_dir'))
+ assert len(test_dataset) == 1
+
+
+def test_isaid():
+ test_dataset = iSAIDDataset(
+ pipeline=[],
+ img_dir=osp.join(
+ osp.dirname(__file__), '../data/pseudo_isaid_dataset/img_dir'),
+ ann_dir=osp.join(
+ osp.dirname(__file__), '../data/pseudo_isaid_dataset/ann_dir'))
+ assert len(test_dataset) == 2
+ isaid_info = test_dataset.load_annotations(
+ img_dir=osp.join(
+ osp.dirname(__file__), '../data/pseudo_isaid_dataset/img_dir'),
+ img_suffix='.png',
+ ann_dir=osp.join(
+ osp.dirname(__file__), '../data/pseudo_isaid_dataset/ann_dir'),
+ seg_map_suffix='.png',
+ split=osp.join(
+ osp.dirname(__file__),
+ '../data/pseudo_isaid_dataset/splits/train.txt'))
+ assert len(isaid_info) == 1
+
+
+@patch('mmseg.datasets.CustomDataset.load_annotations', MagicMock)
+@patch('mmseg.datasets.CustomDataset.__getitem__',
+ MagicMock(side_effect=lambda idx: idx))
+@pytest.mark.parametrize('dataset, classes', [
+ ('ADE20KDataset', ('wall', 'building')),
+ ('CityscapesDataset', ('road', 'sidewalk')),
+ ('CustomDataset', ('bus', 'car')),
+ ('PascalVOCDataset', ('aeroplane', 'bicycle')),
+])
+def test_custom_classes_override_default(dataset, classes):
+
+ dataset_class = DATASETS.get(dataset)
+
+ original_classes = dataset_class.CLASSES
+
+ # Test setting classes as a tuple
+ custom_dataset = dataset_class(
+ pipeline=[],
+ img_dir=MagicMock(),
+ split=MagicMock(),
+ classes=classes,
+ test_mode=True)
+
+ assert custom_dataset.CLASSES != original_classes
+ assert custom_dataset.CLASSES == classes
+
+ # Test setting classes as a list
+ custom_dataset = dataset_class(
+ pipeline=[],
+ img_dir=MagicMock(),
+ split=MagicMock(),
+ classes=list(classes),
+ test_mode=True)
+
+ assert custom_dataset.CLASSES != original_classes
+ assert custom_dataset.CLASSES == list(classes)
+
+ # Test overriding not a subset
+ custom_dataset = dataset_class(
+ pipeline=[],
+ img_dir=MagicMock(),
+ split=MagicMock(),
+ classes=[classes[0]],
+ test_mode=True)
+
+ assert custom_dataset.CLASSES != original_classes
+ assert custom_dataset.CLASSES == [classes[0]]
+
+ # Test default behavior
+ if dataset_class is CustomDataset:
+ with pytest.raises(AssertionError):
+ custom_dataset = dataset_class(
+ pipeline=[],
+ img_dir=MagicMock(),
+ split=MagicMock(),
+ classes=None,
+ test_mode=True)
+ else:
+ custom_dataset = dataset_class(
+ pipeline=[],
+ img_dir=MagicMock(),
+ split=MagicMock(),
+ classes=None,
+ test_mode=True)
+
+ assert custom_dataset.CLASSES == original_classes
+
+
+@patch('mmseg.datasets.CustomDataset.load_annotations', MagicMock)
+@patch('mmseg.datasets.CustomDataset.__getitem__',
+ MagicMock(side_effect=lambda idx: idx))
+def test_custom_dataset_random_palette_is_generated():
+ dataset = CustomDataset(
+ pipeline=[],
+ img_dir=MagicMock(),
+ split=MagicMock(),
+ classes=('bus', 'car'),
+ test_mode=True)
+ assert len(dataset.PALETTE) == 2
+ for class_color in dataset.PALETTE:
+ assert len(class_color) == 3
+ assert all(x >= 0 and x <= 255 for x in class_color)
+
+
+@patch('mmseg.datasets.CustomDataset.load_annotations', MagicMock)
+@patch('mmseg.datasets.CustomDataset.__getitem__',
+ MagicMock(side_effect=lambda idx: idx))
+def test_custom_dataset_custom_palette():
+ dataset = CustomDataset(
+ pipeline=[],
+ img_dir=MagicMock(),
+ split=MagicMock(),
+ classes=('bus', 'car'),
+ palette=[[100, 100, 100], [200, 200, 200]],
+ test_mode=True)
+ assert tuple(dataset.PALETTE) == tuple([[100, 100, 100], [200, 200, 200]])
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_data/test_dataset_builder.py b/EgoHOS/raw/script/mmsegmentation/tests/test_data/test_dataset_builder.py
new file mode 100644
index 0000000000000000000000000000000000000000..30910b09bd8ec7af21a3b98cf854c5e2f5e60b2a
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_data/test_dataset_builder.py
@@ -0,0 +1,200 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import math
+import os.path as osp
+
+import pytest
+from torch.utils.data import (DistributedSampler, RandomSampler,
+ SequentialSampler)
+
+from mmseg.datasets import (DATASETS, ConcatDataset, MultiImageMixDataset,
+ build_dataloader, build_dataset)
+
+
+@DATASETS.register_module()
+class ToyDataset(object):
+
+ def __init__(self, cnt=0):
+ self.cnt = cnt
+
+ def __item__(self, idx):
+ return idx
+
+ def __len__(self):
+ return 100
+
+
+def test_build_dataset():
+ cfg = dict(type='ToyDataset')
+ dataset = build_dataset(cfg)
+ assert isinstance(dataset, ToyDataset)
+ assert dataset.cnt == 0
+ dataset = build_dataset(cfg, default_args=dict(cnt=1))
+ assert isinstance(dataset, ToyDataset)
+ assert dataset.cnt == 1
+
+ data_root = osp.join(osp.dirname(__file__), '../data/pseudo_dataset')
+ img_dir = 'imgs/'
+ ann_dir = 'gts/'
+
+ # We use same dir twice for simplicity
+ # with ann_dir
+ cfg = dict(
+ type='CustomDataset',
+ pipeline=[],
+ data_root=data_root,
+ img_dir=[img_dir, img_dir],
+ ann_dir=[ann_dir, ann_dir])
+ dataset = build_dataset(cfg)
+ assert isinstance(dataset, ConcatDataset)
+ assert len(dataset) == 10
+
+ cfg = dict(type='MultiImageMixDataset', dataset=cfg, pipeline=[])
+ dataset = build_dataset(cfg)
+ assert isinstance(dataset, MultiImageMixDataset)
+ assert len(dataset) == 10
+
+ # with ann_dir, split
+ cfg = dict(
+ type='CustomDataset',
+ pipeline=[],
+ data_root=data_root,
+ img_dir=img_dir,
+ ann_dir=ann_dir,
+ split=['splits/train.txt', 'splits/val.txt'])
+ dataset = build_dataset(cfg)
+ assert isinstance(dataset, ConcatDataset)
+ assert len(dataset) == 5
+
+ # with ann_dir, split
+ cfg = dict(
+ type='CustomDataset',
+ pipeline=[],
+ data_root=data_root,
+ img_dir=img_dir,
+ ann_dir=[ann_dir, ann_dir],
+ split=['splits/train.txt', 'splits/val.txt'])
+ dataset = build_dataset(cfg)
+ assert isinstance(dataset, ConcatDataset)
+ assert len(dataset) == 5
+
+ # test mode
+ cfg = dict(
+ type='CustomDataset',
+ pipeline=[],
+ data_root=data_root,
+ img_dir=[img_dir, img_dir],
+ test_mode=True,
+ classes=('pseudo_class', ))
+ dataset = build_dataset(cfg)
+ assert isinstance(dataset, ConcatDataset)
+ assert len(dataset) == 10
+
+ # test mode with splits
+ cfg = dict(
+ type='CustomDataset',
+ pipeline=[],
+ data_root=data_root,
+ img_dir=[img_dir, img_dir],
+ split=['splits/val.txt', 'splits/val.txt'],
+ test_mode=True,
+ classes=('pseudo_class', ))
+ dataset = build_dataset(cfg)
+ assert isinstance(dataset, ConcatDataset)
+ assert len(dataset) == 2
+
+ # len(ann_dir) should be zero or len(img_dir) when len(img_dir) > 1
+ with pytest.raises(AssertionError):
+ cfg = dict(
+ type='CustomDataset',
+ pipeline=[],
+ data_root=data_root,
+ img_dir=[img_dir, img_dir],
+ ann_dir=[ann_dir, ann_dir, ann_dir])
+ build_dataset(cfg)
+
+ # len(splits) should be zero or len(img_dir) when len(img_dir) > 1
+ with pytest.raises(AssertionError):
+ cfg = dict(
+ type='CustomDataset',
+ pipeline=[],
+ data_root=data_root,
+ img_dir=[img_dir, img_dir],
+ split=['splits/val.txt', 'splits/val.txt', 'splits/val.txt'])
+ build_dataset(cfg)
+
+ # len(splits) == len(ann_dir) when only len(img_dir) == 1 and len(
+ # ann_dir) > 1
+ with pytest.raises(AssertionError):
+ cfg = dict(
+ type='CustomDataset',
+ pipeline=[],
+ data_root=data_root,
+ img_dir=img_dir,
+ ann_dir=[ann_dir, ann_dir],
+ split=['splits/val.txt', 'splits/val.txt', 'splits/val.txt'])
+ build_dataset(cfg)
+
+
+def test_build_dataloader():
+ dataset = ToyDataset()
+ samples_per_gpu = 3
+ # dist=True, shuffle=True, 1GPU
+ dataloader = build_dataloader(
+ dataset, samples_per_gpu=samples_per_gpu, workers_per_gpu=2)
+ assert dataloader.batch_size == samples_per_gpu
+ assert len(dataloader) == int(math.ceil(len(dataset) / samples_per_gpu))
+ assert isinstance(dataloader.sampler, DistributedSampler)
+ assert dataloader.sampler.shuffle
+
+ # dist=True, shuffle=False, 1GPU
+ dataloader = build_dataloader(
+ dataset,
+ samples_per_gpu=samples_per_gpu,
+ workers_per_gpu=2,
+ shuffle=False)
+ assert dataloader.batch_size == samples_per_gpu
+ assert len(dataloader) == int(math.ceil(len(dataset) / samples_per_gpu))
+ assert isinstance(dataloader.sampler, DistributedSampler)
+ assert not dataloader.sampler.shuffle
+
+ # dist=True, shuffle=True, 8GPU
+ dataloader = build_dataloader(
+ dataset,
+ samples_per_gpu=samples_per_gpu,
+ workers_per_gpu=2,
+ num_gpus=8)
+ assert dataloader.batch_size == samples_per_gpu
+ assert len(dataloader) == int(math.ceil(len(dataset) / samples_per_gpu))
+ assert dataloader.num_workers == 2
+
+ # dist=False, shuffle=True, 1GPU
+ dataloader = build_dataloader(
+ dataset,
+ samples_per_gpu=samples_per_gpu,
+ workers_per_gpu=2,
+ dist=False)
+ assert dataloader.batch_size == samples_per_gpu
+ assert len(dataloader) == int(math.ceil(len(dataset) / samples_per_gpu))
+ assert isinstance(dataloader.sampler, RandomSampler)
+ assert dataloader.num_workers == 2
+
+ # dist=False, shuffle=False, 1GPU
+ dataloader = build_dataloader(
+ dataset,
+ samples_per_gpu=3,
+ workers_per_gpu=2,
+ shuffle=False,
+ dist=False)
+ assert dataloader.batch_size == samples_per_gpu
+ assert len(dataloader) == int(math.ceil(len(dataset) / samples_per_gpu))
+ assert isinstance(dataloader.sampler, SequentialSampler)
+ assert dataloader.num_workers == 2
+
+ # dist=False, shuffle=True, 8GPU
+ dataloader = build_dataloader(
+ dataset, samples_per_gpu=3, workers_per_gpu=2, num_gpus=8, dist=False)
+ assert dataloader.batch_size == samples_per_gpu * 8
+ assert len(dataloader) == int(
+ math.ceil(len(dataset) / samples_per_gpu / 8))
+ assert isinstance(dataloader.sampler, RandomSampler)
+ assert dataloader.num_workers == 16
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_data/test_loading.py b/EgoHOS/raw/script/mmsegmentation/tests/test_data/test_loading.py
new file mode 100644
index 0000000000000000000000000000000000000000..fdda93ef9770ba2085777f6c5bbeec7ee8662bcf
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_data/test_loading.py
@@ -0,0 +1,199 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import copy
+import os.path as osp
+import tempfile
+
+import mmcv
+import numpy as np
+
+from mmseg.datasets.pipelines import LoadAnnotations, LoadImageFromFile
+
+
+class TestLoading(object):
+
+ @classmethod
+ def setup_class(cls):
+ cls.data_prefix = osp.join(osp.dirname(__file__), '../data')
+
+ def test_load_img(self):
+ results = dict(
+ img_prefix=self.data_prefix, img_info=dict(filename='color.jpg'))
+ transform = LoadImageFromFile()
+ results = transform(copy.deepcopy(results))
+ assert results['filename'] == osp.join(self.data_prefix, 'color.jpg')
+ assert results['ori_filename'] == 'color.jpg'
+ assert results['img'].shape == (288, 512, 3)
+ assert results['img'].dtype == np.uint8
+ assert results['img_shape'] == (288, 512, 3)
+ assert results['ori_shape'] == (288, 512, 3)
+ assert results['pad_shape'] == (288, 512, 3)
+ assert results['scale_factor'] == 1.0
+ np.testing.assert_equal(results['img_norm_cfg']['mean'],
+ np.zeros(3, dtype=np.float32))
+ assert repr(transform) == transform.__class__.__name__ + \
+ "(to_float32=False,color_type='color',imdecode_backend='cv2')"
+
+ # no img_prefix
+ results = dict(
+ img_prefix=None, img_info=dict(filename='tests/data/color.jpg'))
+ transform = LoadImageFromFile()
+ results = transform(copy.deepcopy(results))
+ assert results['filename'] == 'tests/data/color.jpg'
+ assert results['ori_filename'] == 'tests/data/color.jpg'
+ assert results['img'].shape == (288, 512, 3)
+
+ # to_float32
+ transform = LoadImageFromFile(to_float32=True)
+ results = transform(copy.deepcopy(results))
+ assert results['img'].dtype == np.float32
+
+ # gray image
+ results = dict(
+ img_prefix=self.data_prefix, img_info=dict(filename='gray.jpg'))
+ transform = LoadImageFromFile()
+ results = transform(copy.deepcopy(results))
+ assert results['img'].shape == (288, 512, 3)
+ assert results['img'].dtype == np.uint8
+
+ transform = LoadImageFromFile(color_type='unchanged')
+ results = transform(copy.deepcopy(results))
+ assert results['img'].shape == (288, 512)
+ assert results['img'].dtype == np.uint8
+ np.testing.assert_equal(results['img_norm_cfg']['mean'],
+ np.zeros(1, dtype=np.float32))
+
+ def test_load_seg(self):
+ results = dict(
+ seg_prefix=self.data_prefix,
+ ann_info=dict(seg_map='seg.png'),
+ seg_fields=[])
+ transform = LoadAnnotations()
+ results = transform(copy.deepcopy(results))
+ assert results['seg_fields'] == ['gt_semantic_seg']
+ assert results['gt_semantic_seg'].shape == (288, 512)
+ assert results['gt_semantic_seg'].dtype == np.uint8
+ assert repr(transform) == transform.__class__.__name__ + \
+ "(reduce_zero_label=False,imdecode_backend='pillow')"
+
+ # no img_prefix
+ results = dict(
+ seg_prefix=None,
+ ann_info=dict(seg_map='tests/data/seg.png'),
+ seg_fields=[])
+ transform = LoadAnnotations()
+ results = transform(copy.deepcopy(results))
+ assert results['gt_semantic_seg'].shape == (288, 512)
+ assert results['gt_semantic_seg'].dtype == np.uint8
+
+ # reduce_zero_label
+ transform = LoadAnnotations(reduce_zero_label=True)
+ results = transform(copy.deepcopy(results))
+ assert results['gt_semantic_seg'].shape == (288, 512)
+ assert results['gt_semantic_seg'].dtype == np.uint8
+
+ # mmcv backend
+ results = dict(
+ seg_prefix=self.data_prefix,
+ ann_info=dict(seg_map='seg.png'),
+ seg_fields=[])
+ transform = LoadAnnotations(imdecode_backend='pillow')
+ results = transform(copy.deepcopy(results))
+ # this image is saved by PIL
+ assert results['gt_semantic_seg'].shape == (288, 512)
+ assert results['gt_semantic_seg'].dtype == np.uint8
+
+ def test_load_seg_custom_classes(self):
+
+ test_img = np.random.rand(10, 10)
+ test_gt = np.zeros_like(test_img)
+ test_gt[2:4, 2:4] = 1
+ test_gt[2:4, 6:8] = 2
+ test_gt[6:8, 2:4] = 3
+ test_gt[6:8, 6:8] = 4
+
+ tmp_dir = tempfile.TemporaryDirectory()
+ img_path = osp.join(tmp_dir.name, 'img.jpg')
+ gt_path = osp.join(tmp_dir.name, 'gt.png')
+
+ mmcv.imwrite(test_img, img_path)
+ mmcv.imwrite(test_gt, gt_path)
+
+ # test only train with label with id 3
+ results = dict(
+ img_info=dict(filename=img_path),
+ ann_info=dict(seg_map=gt_path),
+ label_map={
+ 0: 0,
+ 1: 0,
+ 2: 0,
+ 3: 1,
+ 4: 0
+ },
+ seg_fields=[])
+
+ load_imgs = LoadImageFromFile()
+ results = load_imgs(copy.deepcopy(results))
+
+ load_anns = LoadAnnotations()
+ results = load_anns(copy.deepcopy(results))
+
+ gt_array = results['gt_semantic_seg']
+
+ true_mask = np.zeros_like(gt_array)
+ true_mask[6:8, 2:4] = 1
+
+ assert results['seg_fields'] == ['gt_semantic_seg']
+ assert gt_array.shape == (10, 10)
+ assert gt_array.dtype == np.uint8
+ np.testing.assert_array_equal(gt_array, true_mask)
+
+ # test only train with label with id 4 and 3
+ results = dict(
+ img_info=dict(filename=img_path),
+ ann_info=dict(seg_map=gt_path),
+ label_map={
+ 0: 0,
+ 1: 0,
+ 2: 0,
+ 3: 2,
+ 4: 1
+ },
+ seg_fields=[])
+
+ load_imgs = LoadImageFromFile()
+ results = load_imgs(copy.deepcopy(results))
+
+ load_anns = LoadAnnotations()
+ results = load_anns(copy.deepcopy(results))
+
+ gt_array = results['gt_semantic_seg']
+
+ true_mask = np.zeros_like(gt_array)
+ true_mask[6:8, 2:4] = 2
+ true_mask[6:8, 6:8] = 1
+
+ assert results['seg_fields'] == ['gt_semantic_seg']
+ assert gt_array.shape == (10, 10)
+ assert gt_array.dtype == np.uint8
+ np.testing.assert_array_equal(gt_array, true_mask)
+
+ # test no custom classes
+ results = dict(
+ img_info=dict(filename=img_path),
+ ann_info=dict(seg_map=gt_path),
+ seg_fields=[])
+
+ load_imgs = LoadImageFromFile()
+ results = load_imgs(copy.deepcopy(results))
+
+ load_anns = LoadAnnotations()
+ results = load_anns(copy.deepcopy(results))
+
+ gt_array = results['gt_semantic_seg']
+
+ assert results['seg_fields'] == ['gt_semantic_seg']
+ assert gt_array.shape == (10, 10)
+ assert gt_array.dtype == np.uint8
+ np.testing.assert_array_equal(gt_array, test_gt)
+
+ tmp_dir.cleanup()
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_data/test_transform.py b/EgoHOS/raw/script/mmsegmentation/tests/test_data/test_transform.py
new file mode 100644
index 0000000000000000000000000000000000000000..fcc46e7d029ddf71df6c10ba92e3d722eed7675a
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_data/test_transform.py
@@ -0,0 +1,690 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import copy
+import os.path as osp
+
+import mmcv
+import numpy as np
+import pytest
+from mmcv.utils import build_from_cfg
+from PIL import Image
+
+from mmseg.datasets.builder import PIPELINES
+
+
+def test_resize_to_multiple():
+ transform = dict(type='ResizeToMultiple', size_divisor=32)
+ transform = build_from_cfg(transform, PIPELINES)
+
+ img = np.random.randn(213, 232, 3)
+ seg = np.random.randint(0, 19, (213, 232))
+ results = dict()
+ results['img'] = img
+ results['gt_semantic_seg'] = seg
+ results['seg_fields'] = ['gt_semantic_seg']
+ results['img_shape'] = img.shape
+ results['pad_shape'] = img.shape
+
+ results = transform(results)
+ assert results['img'].shape == (224, 256, 3)
+ assert results['gt_semantic_seg'].shape == (224, 256)
+ assert results['img_shape'] == (224, 256, 3)
+ assert results['pad_shape'] == (224, 256, 3)
+
+
+def test_resize():
+ # test assertion if img_scale is a list
+ with pytest.raises(AssertionError):
+ transform = dict(type='Resize', img_scale=[1333, 800], keep_ratio=True)
+ build_from_cfg(transform, PIPELINES)
+
+ # test assertion if len(img_scale) while ratio_range is not None
+ with pytest.raises(AssertionError):
+ transform = dict(
+ type='Resize',
+ img_scale=[(1333, 800), (1333, 600)],
+ ratio_range=(0.9, 1.1),
+ keep_ratio=True)
+ build_from_cfg(transform, PIPELINES)
+
+ # test assertion for invalid multiscale_mode
+ with pytest.raises(AssertionError):
+ transform = dict(
+ type='Resize',
+ img_scale=[(1333, 800), (1333, 600)],
+ keep_ratio=True,
+ multiscale_mode='2333')
+ build_from_cfg(transform, PIPELINES)
+
+ transform = dict(type='Resize', img_scale=(1333, 800), keep_ratio=True)
+ resize_module = build_from_cfg(transform, PIPELINES)
+
+ results = dict()
+ # (288, 512, 3)
+ img = mmcv.imread(
+ osp.join(osp.dirname(__file__), '../data/color.jpg'), 'color')
+ results['img'] = img
+ results['img_shape'] = img.shape
+ results['ori_shape'] = img.shape
+ # Set initial values for default meta_keys
+ results['pad_shape'] = img.shape
+ results['scale_factor'] = 1.0
+
+ resized_results = resize_module(results.copy())
+ assert resized_results['img_shape'] == (750, 1333, 3)
+
+ # test keep_ratio=False
+ transform = dict(
+ type='Resize',
+ img_scale=(1280, 800),
+ multiscale_mode='value',
+ keep_ratio=False)
+ resize_module = build_from_cfg(transform, PIPELINES)
+ resized_results = resize_module(results.copy())
+ assert resized_results['img_shape'] == (800, 1280, 3)
+
+ # test multiscale_mode='range'
+ transform = dict(
+ type='Resize',
+ img_scale=[(1333, 400), (1333, 1200)],
+ multiscale_mode='range',
+ keep_ratio=True)
+ resize_module = build_from_cfg(transform, PIPELINES)
+ resized_results = resize_module(results.copy())
+ assert max(resized_results['img_shape'][:2]) <= 1333
+ assert min(resized_results['img_shape'][:2]) >= 400
+ assert min(resized_results['img_shape'][:2]) <= 1200
+
+ # test multiscale_mode='value'
+ transform = dict(
+ type='Resize',
+ img_scale=[(1333, 800), (1333, 400)],
+ multiscale_mode='value',
+ keep_ratio=True)
+ resize_module = build_from_cfg(transform, PIPELINES)
+ resized_results = resize_module(results.copy())
+ assert resized_results['img_shape'] in [(750, 1333, 3), (400, 711, 3)]
+
+ # test multiscale_mode='range'
+ transform = dict(
+ type='Resize',
+ img_scale=(1333, 800),
+ ratio_range=(0.9, 1.1),
+ keep_ratio=True)
+ resize_module = build_from_cfg(transform, PIPELINES)
+ resized_results = resize_module(results.copy())
+ assert max(resized_results['img_shape'][:2]) <= 1333 * 1.1
+
+ # test img_scale=None and ratio_range is tuple.
+ # img shape: (288, 512, 3)
+ transform = dict(
+ type='Resize', img_scale=None, ratio_range=(0.5, 2.0), keep_ratio=True)
+ resize_module = build_from_cfg(transform, PIPELINES)
+ resized_results = resize_module(results.copy())
+ assert int(288 * 0.5) <= resized_results['img_shape'][0] <= 288 * 2.0
+ assert int(512 * 0.5) <= resized_results['img_shape'][1] <= 512 * 2.0
+
+ # test min_size=640
+ transform = dict(type='Resize', img_scale=(2560, 640), min_size=640)
+ resize_module = build_from_cfg(transform, PIPELINES)
+ resized_results = resize_module(results.copy())
+ assert resized_results['img_shape'] == (640, 1138, 3)
+
+ # test min_size=640 and img_scale=(512, 640)
+ transform = dict(type='Resize', img_scale=(512, 640), min_size=640)
+ resize_module = build_from_cfg(transform, PIPELINES)
+ resized_results = resize_module(results.copy())
+ assert resized_results['img_shape'] == (640, 1138, 3)
+
+ # test h > w
+ img = np.random.randn(512, 288, 3)
+ results['img'] = img
+ results['img_shape'] = img.shape
+ results['ori_shape'] = img.shape
+ # Set initial values for default meta_keys
+ results['pad_shape'] = img.shape
+ results['scale_factor'] = 1.0
+ transform = dict(type='Resize', img_scale=(2560, 640), min_size=640)
+ resize_module = build_from_cfg(transform, PIPELINES)
+ resized_results = resize_module(results.copy())
+ assert resized_results['img_shape'] == (1138, 640, 3)
+
+
+def test_flip():
+ # test assertion for invalid prob
+ with pytest.raises(AssertionError):
+ transform = dict(type='RandomFlip', prob=1.5)
+ build_from_cfg(transform, PIPELINES)
+
+ # test assertion for invalid direction
+ with pytest.raises(AssertionError):
+ transform = dict(type='RandomFlip', prob=1, direction='horizonta')
+ build_from_cfg(transform, PIPELINES)
+
+ transform = dict(type='RandomFlip', prob=1)
+ flip_module = build_from_cfg(transform, PIPELINES)
+
+ results = dict()
+ img = mmcv.imread(
+ osp.join(osp.dirname(__file__), '../data/color.jpg'), 'color')
+ original_img = copy.deepcopy(img)
+ seg = np.array(
+ Image.open(osp.join(osp.dirname(__file__), '../data/seg.png')))
+ original_seg = copy.deepcopy(seg)
+ results['img'] = img
+ results['gt_semantic_seg'] = seg
+ results['seg_fields'] = ['gt_semantic_seg']
+ results['img_shape'] = img.shape
+ results['ori_shape'] = img.shape
+ # Set initial values for default meta_keys
+ results['pad_shape'] = img.shape
+ results['scale_factor'] = 1.0
+
+ results = flip_module(results)
+
+ flip_module = build_from_cfg(transform, PIPELINES)
+ results = flip_module(results)
+ assert np.equal(original_img, results['img']).all()
+ assert np.equal(original_seg, results['gt_semantic_seg']).all()
+
+
+def test_random_crop():
+ # test assertion for invalid random crop
+ with pytest.raises(AssertionError):
+ transform = dict(type='RandomCrop', crop_size=(-1, 0))
+ build_from_cfg(transform, PIPELINES)
+
+ results = dict()
+ img = mmcv.imread(
+ osp.join(osp.dirname(__file__), '../data/color.jpg'), 'color')
+ seg = np.array(
+ Image.open(osp.join(osp.dirname(__file__), '../data/seg.png')))
+ results['img'] = img
+ results['gt_semantic_seg'] = seg
+ results['seg_fields'] = ['gt_semantic_seg']
+ results['img_shape'] = img.shape
+ results['ori_shape'] = img.shape
+ # Set initial values for default meta_keys
+ results['pad_shape'] = img.shape
+ results['scale_factor'] = 1.0
+
+ h, w, _ = img.shape
+ transform = dict(type='RandomCrop', crop_size=(h - 20, w - 20))
+ crop_module = build_from_cfg(transform, PIPELINES)
+ results = crop_module(results)
+ assert results['img'].shape[:2] == (h - 20, w - 20)
+ assert results['img_shape'][:2] == (h - 20, w - 20)
+ assert results['gt_semantic_seg'].shape[:2] == (h - 20, w - 20)
+
+
+def test_pad():
+ # test assertion if both size_divisor and size is None
+ with pytest.raises(AssertionError):
+ transform = dict(type='Pad')
+ build_from_cfg(transform, PIPELINES)
+
+ transform = dict(type='Pad', size_divisor=32)
+ transform = build_from_cfg(transform, PIPELINES)
+ results = dict()
+ img = mmcv.imread(
+ osp.join(osp.dirname(__file__), '../data/color.jpg'), 'color')
+ original_img = copy.deepcopy(img)
+ results['img'] = img
+ results['img_shape'] = img.shape
+ results['ori_shape'] = img.shape
+ # Set initial values for default meta_keys
+ results['pad_shape'] = img.shape
+ results['scale_factor'] = 1.0
+
+ results = transform(results)
+ # original img already divisible by 32
+ assert np.equal(results['img'], original_img).all()
+ img_shape = results['img'].shape
+ assert img_shape[0] % 32 == 0
+ assert img_shape[1] % 32 == 0
+
+ resize_transform = dict(
+ type='Resize', img_scale=(1333, 800), keep_ratio=True)
+ resize_module = build_from_cfg(resize_transform, PIPELINES)
+ results = resize_module(results)
+ results = transform(results)
+ img_shape = results['img'].shape
+ assert img_shape[0] % 32 == 0
+ assert img_shape[1] % 32 == 0
+
+
+def test_rotate():
+ # test assertion degree should be tuple[float] or float
+ with pytest.raises(AssertionError):
+ transform = dict(type='RandomRotate', prob=0.5, degree=-10)
+ build_from_cfg(transform, PIPELINES)
+ # test assertion degree should be tuple[float] or float
+ with pytest.raises(AssertionError):
+ transform = dict(type='RandomRotate', prob=0.5, degree=(10., 20., 30.))
+ build_from_cfg(transform, PIPELINES)
+
+ transform = dict(type='RandomRotate', degree=10., prob=1.)
+ transform = build_from_cfg(transform, PIPELINES)
+
+ assert str(transform) == f'RandomRotate(' \
+ f'prob={1.}, ' \
+ f'degree=({-10.}, {10.}), ' \
+ f'pad_val={0}, ' \
+ f'seg_pad_val={255}, ' \
+ f'center={None}, ' \
+ f'auto_bound={False})'
+
+ results = dict()
+ img = mmcv.imread(
+ osp.join(osp.dirname(__file__), '../data/color.jpg'), 'color')
+ h, w, _ = img.shape
+ seg = np.array(
+ Image.open(osp.join(osp.dirname(__file__), '../data/seg.png')))
+ results['img'] = img
+ results['gt_semantic_seg'] = seg
+ results['seg_fields'] = ['gt_semantic_seg']
+ results['img_shape'] = img.shape
+ results['ori_shape'] = img.shape
+ # Set initial values for default meta_keys
+ results['pad_shape'] = img.shape
+ results['scale_factor'] = 1.0
+
+ results = transform(results)
+ assert results['img'].shape[:2] == (h, w)
+ assert results['gt_semantic_seg'].shape[:2] == (h, w)
+
+
+def test_normalize():
+ img_norm_cfg = dict(
+ mean=[123.675, 116.28, 103.53],
+ std=[58.395, 57.12, 57.375],
+ to_rgb=True)
+ transform = dict(type='Normalize', **img_norm_cfg)
+ transform = build_from_cfg(transform, PIPELINES)
+ results = dict()
+ img = mmcv.imread(
+ osp.join(osp.dirname(__file__), '../data/color.jpg'), 'color')
+ original_img = copy.deepcopy(img)
+ results['img'] = img
+ results['img_shape'] = img.shape
+ results['ori_shape'] = img.shape
+ # Set initial values for default meta_keys
+ results['pad_shape'] = img.shape
+ results['scale_factor'] = 1.0
+
+ results = transform(results)
+
+ mean = np.array(img_norm_cfg['mean'])
+ std = np.array(img_norm_cfg['std'])
+ converted_img = (original_img[..., ::-1] - mean) / std
+ assert np.allclose(results['img'], converted_img)
+
+
+def test_rgb2gray():
+ # test assertion out_channels should be greater than 0
+ with pytest.raises(AssertionError):
+ transform = dict(type='RGB2Gray', out_channels=-1)
+ build_from_cfg(transform, PIPELINES)
+ # test assertion weights should be tuple[float]
+ with pytest.raises(AssertionError):
+ transform = dict(type='RGB2Gray', out_channels=1, weights=1.1)
+ build_from_cfg(transform, PIPELINES)
+
+ # test out_channels is None
+ transform = dict(type='RGB2Gray')
+ transform = build_from_cfg(transform, PIPELINES)
+
+ assert str(transform) == f'RGB2Gray(' \
+ f'out_channels={None}, ' \
+ f'weights={(0.299, 0.587, 0.114)})'
+
+ results = dict()
+ img = mmcv.imread(
+ osp.join(osp.dirname(__file__), '../data/color.jpg'), 'color')
+ h, w, c = img.shape
+ seg = np.array(
+ Image.open(osp.join(osp.dirname(__file__), '../data/seg.png')))
+ results['img'] = img
+ results['gt_semantic_seg'] = seg
+ results['seg_fields'] = ['gt_semantic_seg']
+ results['img_shape'] = img.shape
+ results['ori_shape'] = img.shape
+ # Set initial values for default meta_keys
+ results['pad_shape'] = img.shape
+ results['scale_factor'] = 1.0
+
+ results = transform(results)
+ assert results['img'].shape == (h, w, c)
+ assert results['img_shape'] == (h, w, c)
+ assert results['ori_shape'] == (h, w, c)
+
+ # test out_channels = 2
+ transform = dict(type='RGB2Gray', out_channels=2)
+ transform = build_from_cfg(transform, PIPELINES)
+
+ assert str(transform) == f'RGB2Gray(' \
+ f'out_channels={2}, ' \
+ f'weights={(0.299, 0.587, 0.114)})'
+
+ results = dict()
+ img = mmcv.imread(
+ osp.join(osp.dirname(__file__), '../data/color.jpg'), 'color')
+ h, w, c = img.shape
+ seg = np.array(
+ Image.open(osp.join(osp.dirname(__file__), '../data/seg.png')))
+ results['img'] = img
+ results['gt_semantic_seg'] = seg
+ results['seg_fields'] = ['gt_semantic_seg']
+ results['img_shape'] = img.shape
+ results['ori_shape'] = img.shape
+ # Set initial values for default meta_keys
+ results['pad_shape'] = img.shape
+ results['scale_factor'] = 1.0
+
+ results = transform(results)
+ assert results['img'].shape == (h, w, 2)
+ assert results['img_shape'] == (h, w, 2)
+ assert results['ori_shape'] == (h, w, c)
+
+
+def test_adjust_gamma():
+ # test assertion if gamma <= 0
+ with pytest.raises(AssertionError):
+ transform = dict(type='AdjustGamma', gamma=0)
+ build_from_cfg(transform, PIPELINES)
+
+ # test assertion if gamma is list
+ with pytest.raises(AssertionError):
+ transform = dict(type='AdjustGamma', gamma=[1.2])
+ build_from_cfg(transform, PIPELINES)
+
+ # test with gamma = 1.2
+ transform = dict(type='AdjustGamma', gamma=1.2)
+ transform = build_from_cfg(transform, PIPELINES)
+ results = dict()
+ img = mmcv.imread(
+ osp.join(osp.dirname(__file__), '../data/color.jpg'), 'color')
+ original_img = copy.deepcopy(img)
+ results['img'] = img
+ results['img_shape'] = img.shape
+ results['ori_shape'] = img.shape
+ # Set initial values for default meta_keys
+ results['pad_shape'] = img.shape
+ results['scale_factor'] = 1.0
+
+ results = transform(results)
+
+ inv_gamma = 1.0 / 1.2
+ table = np.array([((i / 255.0)**inv_gamma) * 255
+ for i in np.arange(0, 256)]).astype('uint8')
+ converted_img = mmcv.lut_transform(
+ np.array(original_img, dtype=np.uint8), table)
+ assert np.allclose(results['img'], converted_img)
+ assert str(transform) == f'AdjustGamma(gamma={1.2})'
+
+
+def test_rerange():
+ # test assertion if min_value or max_value is illegal
+ with pytest.raises(AssertionError):
+ transform = dict(type='Rerange', min_value=[0], max_value=[255])
+ build_from_cfg(transform, PIPELINES)
+
+ # test assertion if min_value >= max_value
+ with pytest.raises(AssertionError):
+ transform = dict(type='Rerange', min_value=1, max_value=1)
+ build_from_cfg(transform, PIPELINES)
+
+ # test assertion if img_min_value == img_max_value
+ with pytest.raises(AssertionError):
+ transform = dict(type='Rerange', min_value=0, max_value=1)
+ transform = build_from_cfg(transform, PIPELINES)
+ results = dict()
+ results['img'] = np.array([[1, 1], [1, 1]])
+ transform(results)
+
+ img_rerange_cfg = dict()
+ transform = dict(type='Rerange', **img_rerange_cfg)
+ transform = build_from_cfg(transform, PIPELINES)
+ results = dict()
+ img = mmcv.imread(
+ osp.join(osp.dirname(__file__), '../data/color.jpg'), 'color')
+ original_img = copy.deepcopy(img)
+ results['img'] = img
+ results['img_shape'] = img.shape
+ results['ori_shape'] = img.shape
+ # Set initial values for default meta_keys
+ results['pad_shape'] = img.shape
+ results['scale_factor'] = 1.0
+
+ results = transform(results)
+
+ min_value = np.min(original_img)
+ max_value = np.max(original_img)
+ converted_img = (original_img - min_value) / (max_value - min_value) * 255
+
+ assert np.allclose(results['img'], converted_img)
+ assert str(transform) == f'Rerange(min_value={0}, max_value={255})'
+
+
+def test_CLAHE():
+ # test assertion if clip_limit is None
+ with pytest.raises(AssertionError):
+ transform = dict(type='CLAHE', clip_limit=None)
+ build_from_cfg(transform, PIPELINES)
+
+ # test assertion if tile_grid_size is illegal
+ with pytest.raises(AssertionError):
+ transform = dict(type='CLAHE', tile_grid_size=(8.0, 8.0))
+ build_from_cfg(transform, PIPELINES)
+
+ # test assertion if tile_grid_size is illegal
+ with pytest.raises(AssertionError):
+ transform = dict(type='CLAHE', tile_grid_size=(9, 9, 9))
+ build_from_cfg(transform, PIPELINES)
+
+ transform = dict(type='CLAHE', clip_limit=2)
+ transform = build_from_cfg(transform, PIPELINES)
+ results = dict()
+ img = mmcv.imread(
+ osp.join(osp.dirname(__file__), '../data/color.jpg'), 'color')
+ original_img = copy.deepcopy(img)
+ results['img'] = img
+ results['img_shape'] = img.shape
+ results['ori_shape'] = img.shape
+ # Set initial values for default meta_keys
+ results['pad_shape'] = img.shape
+ results['scale_factor'] = 1.0
+
+ results = transform(results)
+
+ converted_img = np.empty(original_img.shape)
+ for i in range(original_img.shape[2]):
+ converted_img[:, :, i] = mmcv.clahe(
+ np.array(original_img[:, :, i], dtype=np.uint8), 2, (8, 8))
+
+ assert np.allclose(results['img'], converted_img)
+ assert str(transform) == f'CLAHE(clip_limit={2}, tile_grid_size={(8, 8)})'
+
+
+def test_seg_rescale():
+ results = dict()
+ seg = np.array(
+ Image.open(osp.join(osp.dirname(__file__), '../data/seg.png')))
+ results['gt_semantic_seg'] = seg
+ results['seg_fields'] = ['gt_semantic_seg']
+ h, w = seg.shape
+
+ transform = dict(type='SegRescale', scale_factor=1. / 2)
+ rescale_module = build_from_cfg(transform, PIPELINES)
+ rescale_results = rescale_module(results.copy())
+ assert rescale_results['gt_semantic_seg'].shape == (h // 2, w // 2)
+
+ transform = dict(type='SegRescale', scale_factor=1)
+ rescale_module = build_from_cfg(transform, PIPELINES)
+ rescale_results = rescale_module(results.copy())
+ assert rescale_results['gt_semantic_seg'].shape == (h, w)
+
+
+def test_cutout():
+ # test prob
+ with pytest.raises(AssertionError):
+ transform = dict(type='RandomCutOut', prob=1.5, n_holes=1)
+ build_from_cfg(transform, PIPELINES)
+ # test n_holes
+ with pytest.raises(AssertionError):
+ transform = dict(
+ type='RandomCutOut', prob=0.5, n_holes=(5, 3), cutout_shape=(8, 8))
+ build_from_cfg(transform, PIPELINES)
+ with pytest.raises(AssertionError):
+ transform = dict(
+ type='RandomCutOut',
+ prob=0.5,
+ n_holes=(3, 4, 5),
+ cutout_shape=(8, 8))
+ build_from_cfg(transform, PIPELINES)
+ # test cutout_shape and cutout_ratio
+ with pytest.raises(AssertionError):
+ transform = dict(
+ type='RandomCutOut', prob=0.5, n_holes=1, cutout_shape=8)
+ build_from_cfg(transform, PIPELINES)
+ with pytest.raises(AssertionError):
+ transform = dict(
+ type='RandomCutOut', prob=0.5, n_holes=1, cutout_ratio=0.2)
+ build_from_cfg(transform, PIPELINES)
+ # either of cutout_shape and cutout_ratio should be given
+ with pytest.raises(AssertionError):
+ transform = dict(type='RandomCutOut', prob=0.5, n_holes=1)
+ build_from_cfg(transform, PIPELINES)
+ with pytest.raises(AssertionError):
+ transform = dict(
+ type='RandomCutOut',
+ prob=0.5,
+ n_holes=1,
+ cutout_shape=(2, 2),
+ cutout_ratio=(0.4, 0.4))
+ build_from_cfg(transform, PIPELINES)
+ # test seg_fill_in
+ with pytest.raises(AssertionError):
+ transform = dict(
+ type='RandomCutOut',
+ prob=0.5,
+ n_holes=1,
+ cutout_shape=(8, 8),
+ seg_fill_in='a')
+ build_from_cfg(transform, PIPELINES)
+ with pytest.raises(AssertionError):
+ transform = dict(
+ type='RandomCutOut',
+ prob=0.5,
+ n_holes=1,
+ cutout_shape=(8, 8),
+ seg_fill_in=256)
+ build_from_cfg(transform, PIPELINES)
+
+ results = dict()
+ img = mmcv.imread(
+ osp.join(osp.dirname(__file__), '../data/color.jpg'), 'color')
+
+ seg = np.array(
+ Image.open(osp.join(osp.dirname(__file__), '../data/seg.png')))
+
+ results['img'] = img
+ results['gt_semantic_seg'] = seg
+ results['seg_fields'] = ['gt_semantic_seg']
+ results['img_shape'] = img.shape
+ results['ori_shape'] = img.shape
+ results['pad_shape'] = img.shape
+ results['img_fields'] = ['img']
+
+ transform = dict(
+ type='RandomCutOut', prob=1, n_holes=1, cutout_shape=(10, 10))
+ cutout_module = build_from_cfg(transform, PIPELINES)
+ assert 'cutout_shape' in repr(cutout_module)
+ cutout_result = cutout_module(copy.deepcopy(results))
+ assert cutout_result['img'].sum() < img.sum()
+
+ transform = dict(
+ type='RandomCutOut', prob=1, n_holes=1, cutout_ratio=(0.8, 0.8))
+ cutout_module = build_from_cfg(transform, PIPELINES)
+ assert 'cutout_ratio' in repr(cutout_module)
+ cutout_result = cutout_module(copy.deepcopy(results))
+ assert cutout_result['img'].sum() < img.sum()
+
+ transform = dict(
+ type='RandomCutOut', prob=0, n_holes=1, cutout_ratio=(0.8, 0.8))
+ cutout_module = build_from_cfg(transform, PIPELINES)
+ cutout_result = cutout_module(copy.deepcopy(results))
+ assert cutout_result['img'].sum() == img.sum()
+ assert cutout_result['gt_semantic_seg'].sum() == seg.sum()
+
+ transform = dict(
+ type='RandomCutOut',
+ prob=1,
+ n_holes=(2, 4),
+ cutout_shape=[(10, 10), (15, 15)],
+ fill_in=(255, 255, 255),
+ seg_fill_in=None)
+ cutout_module = build_from_cfg(transform, PIPELINES)
+ cutout_result = cutout_module(copy.deepcopy(results))
+ assert cutout_result['img'].sum() > img.sum()
+ assert cutout_result['gt_semantic_seg'].sum() == seg.sum()
+
+ transform = dict(
+ type='RandomCutOut',
+ prob=1,
+ n_holes=1,
+ cutout_ratio=(0.8, 0.8),
+ fill_in=(255, 255, 255),
+ seg_fill_in=255)
+ cutout_module = build_from_cfg(transform, PIPELINES)
+ cutout_result = cutout_module(copy.deepcopy(results))
+ assert cutout_result['img'].sum() > img.sum()
+ assert cutout_result['gt_semantic_seg'].sum() > seg.sum()
+
+
+def test_mosaic():
+ # test prob
+ with pytest.raises(AssertionError):
+ transform = dict(type='RandomMosaic', prob=1.5)
+ build_from_cfg(transform, PIPELINES)
+ # test assertion for invalid img_scale
+ with pytest.raises(AssertionError):
+ transform = dict(type='RandomMosaic', prob=1, img_scale=640)
+ build_from_cfg(transform, PIPELINES)
+
+ results = dict()
+ img = mmcv.imread(
+ osp.join(osp.dirname(__file__), '../data/color.jpg'), 'color')
+ seg = np.array(
+ Image.open(osp.join(osp.dirname(__file__), '../data/seg.png')))
+
+ results['img'] = img
+ results['gt_semantic_seg'] = seg
+ results['seg_fields'] = ['gt_semantic_seg']
+
+ transform = dict(type='RandomMosaic', prob=1, img_scale=(10, 12))
+ mosaic_module = build_from_cfg(transform, PIPELINES)
+ assert 'Mosaic' in repr(mosaic_module)
+
+ # test assertion for invalid mix_results
+ with pytest.raises(AssertionError):
+ mosaic_module(results)
+
+ results['mix_results'] = [copy.deepcopy(results)] * 3
+ results = mosaic_module(results)
+ assert results['img'].shape[:2] == (20, 24)
+
+ results = dict()
+ results['img'] = img[:, :, 0]
+ results['gt_semantic_seg'] = seg
+ results['seg_fields'] = ['gt_semantic_seg']
+
+ transform = dict(type='RandomMosaic', prob=0, img_scale=(10, 12))
+ mosaic_module = build_from_cfg(transform, PIPELINES)
+ results['mix_results'] = [copy.deepcopy(results)] * 3
+ results = mosaic_module(results)
+ assert results['img'].shape[:2] == img.shape[:2]
+
+ transform = dict(type='RandomMosaic', prob=1, img_scale=(10, 12))
+ mosaic_module = build_from_cfg(transform, PIPELINES)
+ results = mosaic_module(results)
+ assert results['img'].shape[:2] == (20, 24)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_data/test_tta.py b/EgoHOS/raw/script/mmsegmentation/tests/test_data/test_tta.py
new file mode 100644
index 0000000000000000000000000000000000000000..d61af27ae04b58ccdb228c05c2ed5c747b83ffda
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_data/test_tta.py
@@ -0,0 +1,151 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import os.path as osp
+
+import mmcv
+import pytest
+from mmcv.utils import build_from_cfg
+
+from mmseg.datasets.builder import PIPELINES
+
+
+def test_multi_scale_flip_aug():
+ # test assertion if img_scale=None, img_ratios=1 (not float).
+ with pytest.raises(AssertionError):
+ tta_transform = dict(
+ type='MultiScaleFlipAug',
+ img_scale=None,
+ img_ratios=1,
+ transforms=[dict(type='Resize', keep_ratio=False)],
+ )
+ build_from_cfg(tta_transform, PIPELINES)
+
+ # test assertion if img_scale=None, img_ratios=None.
+ with pytest.raises(AssertionError):
+ tta_transform = dict(
+ type='MultiScaleFlipAug',
+ img_scale=None,
+ img_ratios=None,
+ transforms=[dict(type='Resize', keep_ratio=False)],
+ )
+ build_from_cfg(tta_transform, PIPELINES)
+
+ # test assertion if img_scale=(512, 512), img_ratios=1 (not float).
+ with pytest.raises(AssertionError):
+ tta_transform = dict(
+ type='MultiScaleFlipAug',
+ img_scale=(512, 512),
+ img_ratios=1,
+ transforms=[dict(type='Resize', keep_ratio=False)],
+ )
+ build_from_cfg(tta_transform, PIPELINES)
+
+ tta_transform = dict(
+ type='MultiScaleFlipAug',
+ img_scale=(512, 512),
+ img_ratios=[0.5, 1.0, 2.0],
+ flip=False,
+ transforms=[dict(type='Resize', keep_ratio=False)],
+ )
+ tta_module = build_from_cfg(tta_transform, PIPELINES)
+
+ results = dict()
+ # (288, 512, 3)
+ img = mmcv.imread(
+ osp.join(osp.dirname(__file__), '../data/color.jpg'), 'color')
+ results['img'] = img
+ results['img_shape'] = img.shape
+ results['ori_shape'] = img.shape
+ # Set initial values for default meta_keys
+ results['pad_shape'] = img.shape
+ results['scale_factor'] = 1.0
+
+ tta_results = tta_module(results.copy())
+ assert tta_results['scale'] == [(256, 256), (512, 512), (1024, 1024)]
+ assert tta_results['flip'] == [False, False, False]
+
+ tta_transform = dict(
+ type='MultiScaleFlipAug',
+ img_scale=(512, 512),
+ img_ratios=[0.5, 1.0, 2.0],
+ flip=True,
+ transforms=[dict(type='Resize', keep_ratio=False)],
+ )
+ tta_module = build_from_cfg(tta_transform, PIPELINES)
+ tta_results = tta_module(results.copy())
+ assert tta_results['scale'] == [(256, 256), (256, 256), (512, 512),
+ (512, 512), (1024, 1024), (1024, 1024)]
+ assert tta_results['flip'] == [False, True, False, True, False, True]
+
+ tta_transform = dict(
+ type='MultiScaleFlipAug',
+ img_scale=(512, 512),
+ img_ratios=1.0,
+ flip=False,
+ transforms=[dict(type='Resize', keep_ratio=False)],
+ )
+ tta_module = build_from_cfg(tta_transform, PIPELINES)
+ tta_results = tta_module(results.copy())
+ assert tta_results['scale'] == [(512, 512)]
+ assert tta_results['flip'] == [False]
+
+ tta_transform = dict(
+ type='MultiScaleFlipAug',
+ img_scale=(512, 512),
+ img_ratios=1.0,
+ flip=True,
+ transforms=[dict(type='Resize', keep_ratio=False)],
+ )
+ tta_module = build_from_cfg(tta_transform, PIPELINES)
+ tta_results = tta_module(results.copy())
+ assert tta_results['scale'] == [(512, 512), (512, 512)]
+ assert tta_results['flip'] == [False, True]
+
+ tta_transform = dict(
+ type='MultiScaleFlipAug',
+ img_scale=None,
+ img_ratios=[0.5, 1.0, 2.0],
+ flip=False,
+ transforms=[dict(type='Resize', keep_ratio=False)],
+ )
+ tta_module = build_from_cfg(tta_transform, PIPELINES)
+ tta_results = tta_module(results.copy())
+ assert tta_results['scale'] == [(256, 144), (512, 288), (1024, 576)]
+ assert tta_results['flip'] == [False, False, False]
+
+ tta_transform = dict(
+ type='MultiScaleFlipAug',
+ img_scale=None,
+ img_ratios=[0.5, 1.0, 2.0],
+ flip=True,
+ transforms=[dict(type='Resize', keep_ratio=False)],
+ )
+ tta_module = build_from_cfg(tta_transform, PIPELINES)
+ tta_results = tta_module(results.copy())
+ assert tta_results['scale'] == [(256, 144), (256, 144), (512, 288),
+ (512, 288), (1024, 576), (1024, 576)]
+ assert tta_results['flip'] == [False, True, False, True, False, True]
+
+ tta_transform = dict(
+ type='MultiScaleFlipAug',
+ img_scale=[(256, 256), (512, 512), (1024, 1024)],
+ img_ratios=None,
+ flip=False,
+ transforms=[dict(type='Resize', keep_ratio=False)],
+ )
+ tta_module = build_from_cfg(tta_transform, PIPELINES)
+ tta_results = tta_module(results.copy())
+ assert tta_results['scale'] == [(256, 256), (512, 512), (1024, 1024)]
+ assert tta_results['flip'] == [False, False, False]
+
+ tta_transform = dict(
+ type='MultiScaleFlipAug',
+ img_scale=[(256, 256), (512, 512), (1024, 1024)],
+ img_ratios=None,
+ flip=True,
+ transforms=[dict(type='Resize', keep_ratio=False)],
+ )
+ tta_module = build_from_cfg(tta_transform, PIPELINES)
+ tta_results = tta_module(results.copy())
+ assert tta_results['scale'] == [(256, 256), (256, 256), (512, 512),
+ (512, 512), (1024, 1024), (1024, 1024)]
+ assert tta_results['flip'] == [False, True, False, True, False, True]
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_digit_version.py b/EgoHOS/raw/script/mmsegmentation/tests/test_digit_version.py
new file mode 100644
index 0000000000000000000000000000000000000000..45daf09ca1e91f53d334db5c9ca0bed086dd3058
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_digit_version.py
@@ -0,0 +1,21 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from mmseg import digit_version
+
+
+def test_digit_version():
+ assert digit_version('0.2.16') == (0, 2, 16, 0, 0, 0)
+ assert digit_version('1.2.3') == (1, 2, 3, 0, 0, 0)
+ assert digit_version('1.2.3rc0') == (1, 2, 3, 0, -1, 0)
+ assert digit_version('1.2.3rc1') == (1, 2, 3, 0, -1, 1)
+ assert digit_version('1.0rc0') == (1, 0, 0, 0, -1, 0)
+ assert digit_version('1.0') == digit_version('1.0.0')
+ assert digit_version('1.5.0+cuda90_cudnn7.6.3_lms') == digit_version('1.5')
+ assert digit_version('1.0.0dev') < digit_version('1.0.0a')
+ assert digit_version('1.0.0a') < digit_version('1.0.0a1')
+ assert digit_version('1.0.0a') < digit_version('1.0.0b')
+ assert digit_version('1.0.0b') < digit_version('1.0.0rc')
+ assert digit_version('1.0.0rc1') < digit_version('1.0.0')
+ assert digit_version('1.0.0') < digit_version('1.0.0post')
+ assert digit_version('1.0.0post') < digit_version('1.0.0post1')
+ assert digit_version('v1') == (1, 0, 0, 0, 0, 0)
+ assert digit_version('v1.1.5') == (1, 1, 5, 0, 0, 0)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_eval_hook.py b/EgoHOS/raw/script/mmsegmentation/tests/test_eval_hook.py
new file mode 100644
index 0000000000000000000000000000000000000000..5267438c32eef889585a88ac3d3503a1bbb0dc4f
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_eval_hook.py
@@ -0,0 +1,204 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import logging
+import tempfile
+from unittest.mock import MagicMock, patch
+
+import mmcv.runner
+import pytest
+import torch
+import torch.nn as nn
+from mmcv.runner import obj_from_dict
+from torch.utils.data import DataLoader, Dataset
+
+from mmseg.apis import single_gpu_test
+from mmseg.core import DistEvalHook, EvalHook
+
+
+class ExampleDataset(Dataset):
+
+ def __getitem__(self, idx):
+ results = dict(img=torch.tensor([1]), img_metas=dict())
+ return results
+
+ def __len__(self):
+ return 1
+
+
+class ExampleModel(nn.Module):
+
+ def __init__(self):
+ super(ExampleModel, self).__init__()
+ self.test_cfg = None
+ self.conv = nn.Conv2d(3, 3, 3)
+
+ def forward(self, img, img_metas, test_mode=False, **kwargs):
+ return img
+
+ def train_step(self, data_batch, optimizer):
+ loss = self.forward(**data_batch)
+ return dict(loss=loss)
+
+
+def test_iter_eval_hook():
+ with pytest.raises(TypeError):
+ test_dataset = ExampleModel()
+ data_loader = [
+ DataLoader(
+ test_dataset,
+ batch_size=1,
+ sampler=None,
+ num_worker=0,
+ shuffle=False)
+ ]
+ EvalHook(data_loader)
+
+ test_dataset = ExampleDataset()
+ test_dataset.pre_eval = MagicMock(return_value=[torch.tensor([1])])
+ test_dataset.evaluate = MagicMock(return_value=dict(test='success'))
+ loader = DataLoader(test_dataset, batch_size=1)
+ model = ExampleModel()
+ data_loader = DataLoader(
+ test_dataset, batch_size=1, sampler=None, num_workers=0, shuffle=False)
+ optim_cfg = dict(type='SGD', lr=0.01, momentum=0.9, weight_decay=0.0005)
+ optimizer = obj_from_dict(optim_cfg, torch.optim,
+ dict(params=model.parameters()))
+
+ # test EvalHook
+ with tempfile.TemporaryDirectory() as tmpdir:
+ eval_hook = EvalHook(data_loader, by_epoch=False, efficient_test=True)
+ runner = mmcv.runner.IterBasedRunner(
+ model=model,
+ optimizer=optimizer,
+ work_dir=tmpdir,
+ logger=logging.getLogger())
+ runner.register_hook(eval_hook)
+ runner.run([loader], [('train', 1)], 1)
+ test_dataset.evaluate.assert_called_with([torch.tensor([1])],
+ logger=runner.logger)
+
+
+def test_epoch_eval_hook():
+ with pytest.raises(TypeError):
+ test_dataset = ExampleModel()
+ data_loader = [
+ DataLoader(
+ test_dataset,
+ batch_size=1,
+ sampler=None,
+ num_worker=0,
+ shuffle=False)
+ ]
+ EvalHook(data_loader, by_epoch=True)
+
+ test_dataset = ExampleDataset()
+ test_dataset.pre_eval = MagicMock(return_value=[torch.tensor([1])])
+ test_dataset.evaluate = MagicMock(return_value=dict(test='success'))
+ loader = DataLoader(test_dataset, batch_size=1)
+ model = ExampleModel()
+ data_loader = DataLoader(
+ test_dataset, batch_size=1, sampler=None, num_workers=0, shuffle=False)
+ optim_cfg = dict(type='SGD', lr=0.01, momentum=0.9, weight_decay=0.0005)
+ optimizer = obj_from_dict(optim_cfg, torch.optim,
+ dict(params=model.parameters()))
+
+ # test EvalHook with interval
+ with tempfile.TemporaryDirectory() as tmpdir:
+ eval_hook = EvalHook(data_loader, by_epoch=True, interval=2)
+ runner = mmcv.runner.EpochBasedRunner(
+ model=model,
+ optimizer=optimizer,
+ work_dir=tmpdir,
+ logger=logging.getLogger())
+ runner.register_hook(eval_hook)
+ runner.run([loader], [('train', 1)], 2)
+ test_dataset.evaluate.assert_called_once_with([torch.tensor([1])],
+ logger=runner.logger)
+
+
+def multi_gpu_test(model,
+ data_loader,
+ tmpdir=None,
+ gpu_collect=False,
+ pre_eval=False):
+ # Pre eval is set by default when training.
+ results = single_gpu_test(model, data_loader, pre_eval=True)
+ return results
+
+
+@patch('mmseg.apis.multi_gpu_test', multi_gpu_test)
+def test_dist_eval_hook():
+ with pytest.raises(TypeError):
+ test_dataset = ExampleModel()
+ data_loader = [
+ DataLoader(
+ test_dataset,
+ batch_size=1,
+ sampler=None,
+ num_worker=0,
+ shuffle=False)
+ ]
+ DistEvalHook(data_loader)
+
+ test_dataset = ExampleDataset()
+ test_dataset.pre_eval = MagicMock(return_value=[torch.tensor([1])])
+ test_dataset.evaluate = MagicMock(return_value=dict(test='success'))
+ loader = DataLoader(test_dataset, batch_size=1)
+ model = ExampleModel()
+ data_loader = DataLoader(
+ test_dataset, batch_size=1, sampler=None, num_workers=0, shuffle=False)
+ optim_cfg = dict(type='SGD', lr=0.01, momentum=0.9, weight_decay=0.0005)
+ optimizer = obj_from_dict(optim_cfg, torch.optim,
+ dict(params=model.parameters()))
+
+ # test DistEvalHook
+ with tempfile.TemporaryDirectory() as tmpdir:
+ eval_hook = DistEvalHook(
+ data_loader, by_epoch=False, efficient_test=True)
+ runner = mmcv.runner.IterBasedRunner(
+ model=model,
+ optimizer=optimizer,
+ work_dir=tmpdir,
+ logger=logging.getLogger())
+ runner.register_hook(eval_hook)
+ runner.run([loader], [('train', 1)], 1)
+ test_dataset.evaluate.assert_called_with([torch.tensor([1])],
+ logger=runner.logger)
+
+
+@patch('mmseg.apis.multi_gpu_test', multi_gpu_test)
+def test_dist_eval_hook_epoch():
+ with pytest.raises(TypeError):
+ test_dataset = ExampleModel()
+ data_loader = [
+ DataLoader(
+ test_dataset,
+ batch_size=1,
+ sampler=None,
+ num_worker=0,
+ shuffle=False)
+ ]
+ DistEvalHook(data_loader)
+
+ test_dataset = ExampleDataset()
+ test_dataset.pre_eval = MagicMock(return_value=[torch.tensor([1])])
+ test_dataset.evaluate = MagicMock(return_value=dict(test='success'))
+ loader = DataLoader(test_dataset, batch_size=1)
+ model = ExampleModel()
+ data_loader = DataLoader(
+ test_dataset, batch_size=1, sampler=None, num_workers=0, shuffle=False)
+ optim_cfg = dict(type='SGD', lr=0.01, momentum=0.9, weight_decay=0.0005)
+ optimizer = obj_from_dict(optim_cfg, torch.optim,
+ dict(params=model.parameters()))
+
+ # test DistEvalHook
+ with tempfile.TemporaryDirectory() as tmpdir:
+ eval_hook = DistEvalHook(data_loader, by_epoch=True, interval=2)
+ runner = mmcv.runner.EpochBasedRunner(
+ model=model,
+ optimizer=optimizer,
+ work_dir=tmpdir,
+ logger=logging.getLogger())
+ runner.register_hook(eval_hook)
+ runner.run([loader], [('train', 1)], 2)
+ test_dataset.evaluate.assert_called_with([torch.tensor([1])],
+ logger=runner.logger)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_inference.py b/EgoHOS/raw/script/mmsegmentation/tests/test_inference.py
new file mode 100644
index 0000000000000000000000000000000000000000..f71a7ea56d84335a1f6f15af7d71e033e8ced3a1
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_inference.py
@@ -0,0 +1,30 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import os.path as osp
+
+import mmcv
+
+from mmseg.apis import inference_segmentor, init_segmentor
+
+
+def test_test_time_augmentation_on_cpu():
+ config_file = 'configs/pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py'
+ config = mmcv.Config.fromfile(config_file)
+
+ # Remove pretrain model download for testing
+ config.model.pretrained = None
+ # Replace SyncBN with BN to inference on CPU
+ norm_cfg = dict(type='BN', requires_grad=True)
+ config.model.backbone.norm_cfg = norm_cfg
+ config.model.decode_head.norm_cfg = norm_cfg
+ config.model.auxiliary_head.norm_cfg = norm_cfg
+
+ # Enable test time augmentation
+ config.data.test.pipeline[1].flip = True
+
+ checkpoint_file = None
+ model = init_segmentor(config, checkpoint_file, device='cpu')
+
+ img = mmcv.imread(
+ osp.join(osp.dirname(__file__), 'data/color.jpg'), 'color')
+ result = inference_segmentor(model, img)
+ assert result[0].shape == (288, 512)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_metrics.py b/EgoHOS/raw/script/mmsegmentation/tests/test_metrics.py
new file mode 100644
index 0000000000000000000000000000000000000000..51ad1f349c95050211b447be30805dc5b8fa400e
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_metrics.py
@@ -0,0 +1,351 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import numpy as np
+
+from mmseg.core.evaluation import (eval_metrics, mean_dice, mean_fscore,
+ mean_iou)
+from mmseg.core.evaluation.metrics import f_score
+
+
+def get_confusion_matrix(pred_label, label, num_classes, ignore_index):
+ """Intersection over Union
+ Args:
+ pred_label (np.ndarray): 2D predict map
+ label (np.ndarray): label 2D label map
+ num_classes (int): number of categories
+ ignore_index (int): index ignore in evaluation
+ """
+
+ mask = (label != ignore_index)
+ pred_label = pred_label[mask]
+ label = label[mask]
+
+ n = num_classes
+ inds = n * label + pred_label
+
+ mat = np.bincount(inds, minlength=n**2).reshape(n, n)
+
+ return mat
+
+
+# This func is deprecated since it's not memory efficient
+def legacy_mean_iou(results, gt_seg_maps, num_classes, ignore_index):
+ num_imgs = len(results)
+ assert len(gt_seg_maps) == num_imgs
+ total_mat = np.zeros((num_classes, num_classes), dtype=np.float)
+ for i in range(num_imgs):
+ mat = get_confusion_matrix(
+ results[i], gt_seg_maps[i], num_classes, ignore_index=ignore_index)
+ total_mat += mat
+ all_acc = np.diag(total_mat).sum() / total_mat.sum()
+ acc = np.diag(total_mat) / total_mat.sum(axis=1)
+ iou = np.diag(total_mat) / (
+ total_mat.sum(axis=1) + total_mat.sum(axis=0) - np.diag(total_mat))
+
+ return all_acc, acc, iou
+
+
+# This func is deprecated since it's not memory efficient
+def legacy_mean_dice(results, gt_seg_maps, num_classes, ignore_index):
+ num_imgs = len(results)
+ assert len(gt_seg_maps) == num_imgs
+ total_mat = np.zeros((num_classes, num_classes), dtype=np.float)
+ for i in range(num_imgs):
+ mat = get_confusion_matrix(
+ results[i], gt_seg_maps[i], num_classes, ignore_index=ignore_index)
+ total_mat += mat
+ all_acc = np.diag(total_mat).sum() / total_mat.sum()
+ acc = np.diag(total_mat) / total_mat.sum(axis=1)
+ dice = 2 * np.diag(total_mat) / (
+ total_mat.sum(axis=1) + total_mat.sum(axis=0))
+
+ return all_acc, acc, dice
+
+
+# This func is deprecated since it's not memory efficient
+def legacy_mean_fscore(results,
+ gt_seg_maps,
+ num_classes,
+ ignore_index,
+ beta=1):
+ num_imgs = len(results)
+ assert len(gt_seg_maps) == num_imgs
+ total_mat = np.zeros((num_classes, num_classes), dtype=np.float)
+ for i in range(num_imgs):
+ mat = get_confusion_matrix(
+ results[i], gt_seg_maps[i], num_classes, ignore_index=ignore_index)
+ total_mat += mat
+ all_acc = np.diag(total_mat).sum() / total_mat.sum()
+ recall = np.diag(total_mat) / total_mat.sum(axis=1)
+ precision = np.diag(total_mat) / total_mat.sum(axis=0)
+ fv = np.vectorize(f_score)
+ fscore = fv(precision, recall, beta=beta)
+
+ return all_acc, recall, precision, fscore
+
+
+def test_metrics():
+ pred_size = (10, 30, 30)
+ num_classes = 19
+ ignore_index = 255
+ results = np.random.randint(0, num_classes, size=pred_size)
+ label = np.random.randint(0, num_classes, size=pred_size)
+
+ # Test the availability of arg: ignore_index.
+ label[:, 2, 5:10] = ignore_index
+
+ # Test the correctness of the implementation of mIoU calculation.
+ ret_metrics = eval_metrics(
+ results, label, num_classes, ignore_index, metrics='mIoU')
+ all_acc, acc, iou = ret_metrics['aAcc'], ret_metrics['Acc'], ret_metrics[
+ 'IoU']
+ all_acc_l, acc_l, iou_l = legacy_mean_iou(results, label, num_classes,
+ ignore_index)
+ assert all_acc == all_acc_l
+ assert np.allclose(acc, acc_l)
+ assert np.allclose(iou, iou_l)
+ # Test the correctness of the implementation of mDice calculation.
+ ret_metrics = eval_metrics(
+ results, label, num_classes, ignore_index, metrics='mDice')
+ all_acc, acc, dice = ret_metrics['aAcc'], ret_metrics['Acc'], ret_metrics[
+ 'Dice']
+ all_acc_l, acc_l, dice_l = legacy_mean_dice(results, label, num_classes,
+ ignore_index)
+ assert all_acc == all_acc_l
+ assert np.allclose(acc, acc_l)
+ assert np.allclose(dice, dice_l)
+ # Test the correctness of the implementation of mDice calculation.
+ ret_metrics = eval_metrics(
+ results, label, num_classes, ignore_index, metrics='mFscore')
+ all_acc, recall, precision, fscore = ret_metrics['aAcc'], ret_metrics[
+ 'Recall'], ret_metrics['Precision'], ret_metrics['Fscore']
+ all_acc_l, recall_l, precision_l, fscore_l = legacy_mean_fscore(
+ results, label, num_classes, ignore_index)
+ assert all_acc == all_acc_l
+ assert np.allclose(recall, recall_l)
+ assert np.allclose(precision, precision_l)
+ assert np.allclose(fscore, fscore_l)
+ # Test the correctness of the implementation of joint calculation.
+ ret_metrics = eval_metrics(
+ results,
+ label,
+ num_classes,
+ ignore_index,
+ metrics=['mIoU', 'mDice', 'mFscore'])
+ all_acc, acc, iou, dice, precision, recall, fscore = ret_metrics[
+ 'aAcc'], ret_metrics['Acc'], ret_metrics['IoU'], ret_metrics[
+ 'Dice'], ret_metrics['Precision'], ret_metrics[
+ 'Recall'], ret_metrics['Fscore']
+ assert all_acc == all_acc_l
+ assert np.allclose(acc, acc_l)
+ assert np.allclose(iou, iou_l)
+ assert np.allclose(dice, dice_l)
+ assert np.allclose(precision, precision_l)
+ assert np.allclose(recall, recall_l)
+ assert np.allclose(fscore, fscore_l)
+
+ # Test the correctness of calculation when arg: num_classes is larger
+ # than the maximum value of input maps.
+ results = np.random.randint(0, 5, size=pred_size)
+ label = np.random.randint(0, 4, size=pred_size)
+ ret_metrics = eval_metrics(
+ results,
+ label,
+ num_classes,
+ ignore_index=255,
+ metrics='mIoU',
+ nan_to_num=-1)
+ all_acc, acc, iou = ret_metrics['aAcc'], ret_metrics['Acc'], ret_metrics[
+ 'IoU']
+ assert acc[-1] == -1
+ assert iou[-1] == -1
+
+ ret_metrics = eval_metrics(
+ results,
+ label,
+ num_classes,
+ ignore_index=255,
+ metrics='mDice',
+ nan_to_num=-1)
+ all_acc, acc, dice = ret_metrics['aAcc'], ret_metrics['Acc'], ret_metrics[
+ 'Dice']
+ assert acc[-1] == -1
+ assert dice[-1] == -1
+
+ ret_metrics = eval_metrics(
+ results,
+ label,
+ num_classes,
+ ignore_index=255,
+ metrics='mFscore',
+ nan_to_num=-1)
+ all_acc, precision, recall, fscore = ret_metrics['aAcc'], ret_metrics[
+ 'Precision'], ret_metrics['Recall'], ret_metrics['Fscore']
+ assert precision[-1] == -1
+ assert recall[-1] == -1
+ assert fscore[-1] == -1
+
+ ret_metrics = eval_metrics(
+ results,
+ label,
+ num_classes,
+ ignore_index=255,
+ metrics=['mDice', 'mIoU', 'mFscore'],
+ nan_to_num=-1)
+ all_acc, acc, iou, dice, precision, recall, fscore = ret_metrics[
+ 'aAcc'], ret_metrics['Acc'], ret_metrics['IoU'], ret_metrics[
+ 'Dice'], ret_metrics['Precision'], ret_metrics[
+ 'Recall'], ret_metrics['Fscore']
+ assert acc[-1] == -1
+ assert dice[-1] == -1
+ assert iou[-1] == -1
+ assert precision[-1] == -1
+ assert recall[-1] == -1
+ assert fscore[-1] == -1
+
+ # Test the bug which is caused by torch.histc.
+ # torch.histc: https://pytorch.org/docs/stable/generated/torch.histc.html
+ # When the arg:bins is set to be same as arg:max,
+ # some channels of mIoU may be nan.
+ results = np.array([np.repeat(31, 59)])
+ label = np.array([np.arange(59)])
+ num_classes = 59
+ ret_metrics = eval_metrics(
+ results, label, num_classes, ignore_index=255, metrics='mIoU')
+ all_acc, acc, iou = ret_metrics['aAcc'], ret_metrics['Acc'], ret_metrics[
+ 'IoU']
+ assert not np.any(np.isnan(iou))
+
+
+def test_mean_iou():
+ pred_size = (10, 30, 30)
+ num_classes = 19
+ ignore_index = 255
+ results = np.random.randint(0, num_classes, size=pred_size)
+ label = np.random.randint(0, num_classes, size=pred_size)
+ label[:, 2, 5:10] = ignore_index
+ ret_metrics = mean_iou(results, label, num_classes, ignore_index)
+ all_acc, acc, iou = ret_metrics['aAcc'], ret_metrics['Acc'], ret_metrics[
+ 'IoU']
+ all_acc_l, acc_l, iou_l = legacy_mean_iou(results, label, num_classes,
+ ignore_index)
+ assert all_acc == all_acc_l
+ assert np.allclose(acc, acc_l)
+ assert np.allclose(iou, iou_l)
+
+ results = np.random.randint(0, 5, size=pred_size)
+ label = np.random.randint(0, 4, size=pred_size)
+ ret_metrics = mean_iou(
+ results, label, num_classes, ignore_index=255, nan_to_num=-1)
+ all_acc, acc, iou = ret_metrics['aAcc'], ret_metrics['Acc'], ret_metrics[
+ 'IoU']
+ assert acc[-1] == -1
+ assert acc[-1] == -1
+
+
+def test_mean_dice():
+ pred_size = (10, 30, 30)
+ num_classes = 19
+ ignore_index = 255
+ results = np.random.randint(0, num_classes, size=pred_size)
+ label = np.random.randint(0, num_classes, size=pred_size)
+ label[:, 2, 5:10] = ignore_index
+ ret_metrics = mean_dice(results, label, num_classes, ignore_index)
+ all_acc, acc, iou = ret_metrics['aAcc'], ret_metrics['Acc'], ret_metrics[
+ 'Dice']
+ all_acc_l, acc_l, dice_l = legacy_mean_dice(results, label, num_classes,
+ ignore_index)
+ assert all_acc == all_acc_l
+ assert np.allclose(acc, acc_l)
+ assert np.allclose(iou, dice_l)
+
+ results = np.random.randint(0, 5, size=pred_size)
+ label = np.random.randint(0, 4, size=pred_size)
+ ret_metrics = mean_dice(
+ results, label, num_classes, ignore_index=255, nan_to_num=-1)
+ all_acc, acc, dice = ret_metrics['aAcc'], ret_metrics['Acc'], ret_metrics[
+ 'Dice']
+ assert acc[-1] == -1
+ assert dice[-1] == -1
+
+
+def test_mean_fscore():
+ pred_size = (10, 30, 30)
+ num_classes = 19
+ ignore_index = 255
+ results = np.random.randint(0, num_classes, size=pred_size)
+ label = np.random.randint(0, num_classes, size=pred_size)
+ label[:, 2, 5:10] = ignore_index
+ ret_metrics = mean_fscore(results, label, num_classes, ignore_index)
+ all_acc, recall, precision, fscore = ret_metrics['aAcc'], ret_metrics[
+ 'Recall'], ret_metrics['Precision'], ret_metrics['Fscore']
+ all_acc_l, recall_l, precision_l, fscore_l = legacy_mean_fscore(
+ results, label, num_classes, ignore_index)
+ assert all_acc == all_acc_l
+ assert np.allclose(recall, recall_l)
+ assert np.allclose(precision, precision_l)
+ assert np.allclose(fscore, fscore_l)
+
+ ret_metrics = mean_fscore(
+ results, label, num_classes, ignore_index, beta=2)
+ all_acc, recall, precision, fscore = ret_metrics['aAcc'], ret_metrics[
+ 'Recall'], ret_metrics['Precision'], ret_metrics['Fscore']
+ all_acc_l, recall_l, precision_l, fscore_l = legacy_mean_fscore(
+ results, label, num_classes, ignore_index, beta=2)
+ assert all_acc == all_acc_l
+ assert np.allclose(recall, recall_l)
+ assert np.allclose(precision, precision_l)
+ assert np.allclose(fscore, fscore_l)
+
+ results = np.random.randint(0, 5, size=pred_size)
+ label = np.random.randint(0, 4, size=pred_size)
+ ret_metrics = mean_fscore(
+ results, label, num_classes, ignore_index=255, nan_to_num=-1)
+ all_acc, recall, precision, fscore = ret_metrics['aAcc'], ret_metrics[
+ 'Recall'], ret_metrics['Precision'], ret_metrics['Fscore']
+ assert recall[-1] == -1
+ assert precision[-1] == -1
+ assert fscore[-1] == -1
+
+
+def test_filename_inputs():
+ import tempfile
+
+ import cv2
+
+ def save_arr(input_arrays: list, title: str, is_image: bool, dir: str):
+ filenames = []
+ SUFFIX = '.png' if is_image else '.npy'
+ for idx, arr in enumerate(input_arrays):
+ filename = '{}/{}-{}{}'.format(dir, title, idx, SUFFIX)
+ if is_image:
+ cv2.imwrite(filename, arr)
+ else:
+ np.save(filename, arr)
+ filenames.append(filename)
+ return filenames
+
+ pred_size = (10, 30, 30)
+ num_classes = 19
+ ignore_index = 255
+ results = np.random.randint(0, num_classes, size=pred_size)
+ labels = np.random.randint(0, num_classes, size=pred_size)
+ labels[:, 2, 5:10] = ignore_index
+
+ with tempfile.TemporaryDirectory() as temp_dir:
+
+ result_files = save_arr(results, 'pred', False, temp_dir)
+ label_files = save_arr(labels, 'label', True, temp_dir)
+
+ ret_metrics = eval_metrics(
+ result_files,
+ label_files,
+ num_classes,
+ ignore_index,
+ metrics='mIoU')
+ all_acc, acc, iou = ret_metrics['aAcc'], ret_metrics[
+ 'Acc'], ret_metrics['IoU']
+ all_acc_l, acc_l, iou_l = legacy_mean_iou(results, labels, num_classes,
+ ignore_index)
+ assert all_acc == all_acc_l
+ assert np.allclose(acc, acc_l)
+ assert np.allclose(iou, iou_l)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/__init__.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..ef101fec61e72abc0eb90266d453b5b22331378d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/__init__.py
@@ -0,0 +1 @@
+# Copyright (c) OpenMMLab. All rights reserved.
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/__init__.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..8b673fa5c34b4febd9757adc3bedbcd936270f53
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/__init__.py
@@ -0,0 +1,4 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from .utils import all_zeros, check_norm_state, is_block, is_norm
+
+__all__ = ['is_norm', 'is_block', 'all_zeros', 'check_norm_state']
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_beit.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_beit.py
new file mode 100644
index 0000000000000000000000000000000000000000..cf3960894d1f690e094634e0b63a5d9122e1206a
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_beit.py
@@ -0,0 +1,182 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.backbones.beit import BEiT
+from .utils import check_norm_state
+
+
+def test_beit_backbone():
+ with pytest.raises(TypeError):
+ # pretrained must be a string path
+ model = BEiT()
+ model.init_weights(pretrained=0)
+
+ with pytest.raises(TypeError):
+ # img_size must be int or tuple
+ model = BEiT(img_size=512.0)
+
+ with pytest.raises(TypeError):
+ # out_indices must be int ,list or tuple
+ model = BEiT(out_indices=1.)
+
+ with pytest.raises(AssertionError):
+ # The length of img_size tuple must be lower than 3.
+ BEiT(img_size=(224, 224, 224))
+
+ with pytest.raises(TypeError):
+ # Pretrained must be None or Str.
+ BEiT(pretrained=123)
+
+ # Test img_size isinstance tuple
+ imgs = torch.randn(1, 3, 224, 224)
+ model = BEiT(img_size=(224, ))
+ model.init_weights()
+ model(imgs)
+
+ # Test img_size isinstance tuple
+ imgs = torch.randn(1, 3, 224, 224)
+ model = BEiT(img_size=(224, 224))
+ model(imgs)
+
+ # Test norm_eval = True
+ model = BEiT(norm_eval=True)
+ model.train()
+
+ # Test BEiT backbone with input size of 224 and patch size of 16
+ model = BEiT()
+ model.init_weights()
+ model.train()
+
+ # Test qv_bias
+ model = BEiT(qv_bias=False)
+ model.train()
+
+ # Test out_indices = list
+ model = BEiT(out_indices=[2, 4, 8, 12])
+ model.train()
+
+ assert check_norm_state(model.modules(), True)
+
+ # Test image size = (224, 224)
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 14, 14)
+
+ # Test BEiT backbone with input size of 256 and patch size of 16
+ model = BEiT(img_size=(256, 256))
+ model.init_weights()
+ model.train()
+ imgs = torch.randn(1, 3, 256, 256)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 16, 16)
+
+ # Test BEiT backbone with input size of 32 and patch size of 16
+ model = BEiT(img_size=(32, 32))
+ model.init_weights()
+ model.train()
+ imgs = torch.randn(1, 3, 32, 32)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 2, 2)
+
+ # Test unbalanced size input image
+ model = BEiT(img_size=(112, 224))
+ model.init_weights()
+ model.train()
+ imgs = torch.randn(1, 3, 112, 224)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 7, 14)
+
+ # Test irregular input image
+ model = BEiT(img_size=(234, 345))
+ model.init_weights()
+ model.train()
+ imgs = torch.randn(1, 3, 234, 345)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 14, 21)
+
+ # Test init_values=0
+ model = BEiT(init_values=0)
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 14, 14)
+
+ # Test final norm
+ model = BEiT(final_norm=True)
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 14, 14)
+
+ # Test patch norm
+ model = BEiT(patch_norm=True)
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 14, 14)
+
+
+def test_beit_init():
+ path = 'PATH_THAT_DO_NOT_EXIST'
+ # Test all combinations of pretrained and init_cfg
+ # pretrained=None, init_cfg=None
+ model = BEiT(pretrained=None, init_cfg=None)
+ assert model.init_cfg is None
+ model.init_weights()
+
+ # pretrained=None
+ # init_cfg loads pretrain from an non-existent file
+ model = BEiT(
+ pretrained=None, init_cfg=dict(type='Pretrained', checkpoint=path))
+ assert model.init_cfg == dict(type='Pretrained', checkpoint=path)
+ # Test loading a checkpoint from an non-existent file
+ with pytest.raises(OSError):
+ model.init_weights()
+
+ # test resize_rel_pos_embed
+ value = torch.randn(732, 16)
+ ckpt = {
+ 'state_dict': {
+ 'layers.0.attn.relative_position_index': 0,
+ 'layers.0.attn.relative_position_bias_table': value
+ }
+ }
+ model = BEiT(img_size=(512, 512))
+ with pytest.raises(AttributeError):
+ model.resize_rel_pos_embed(ckpt)
+
+ # pretrained=None
+ # init_cfg=123, whose type is unsupported
+ model = BEiT(pretrained=None, init_cfg=123)
+ with pytest.raises(TypeError):
+ model.init_weights()
+
+ # pretrained loads pretrain from an non-existent file
+ # init_cfg=None
+ model = BEiT(pretrained=path, init_cfg=None)
+ assert model.init_cfg == dict(type='Pretrained', checkpoint=path)
+ # Test loading a checkpoint from an non-existent file
+ with pytest.raises(OSError):
+ model.init_weights()
+
+ # pretrained loads pretrain from an non-existent file
+ # init_cfg loads pretrain from an non-existent file
+ with pytest.raises(AssertionError):
+ model = BEiT(
+ pretrained=path, init_cfg=dict(type='Pretrained', checkpoint=path))
+ with pytest.raises(AssertionError):
+ model = BEiT(pretrained=path, init_cfg=123)
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg=None
+ with pytest.raises(TypeError):
+ model = BEiT(pretrained=123, init_cfg=None)
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg loads pretrain from an non-existent file
+ with pytest.raises(AssertionError):
+ model = BEiT(
+ pretrained=123, init_cfg=dict(type='Pretrained', checkpoint=path))
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg=123, whose type is unsupported
+ with pytest.raises(AssertionError):
+ model = BEiT(pretrained=123, init_cfg=123)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_bisenetv1.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_bisenetv1.py
new file mode 100644
index 0000000000000000000000000000000000000000..c0677493d6894f6285b6ee37a4a2c8a052ff8b4c
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_bisenetv1.py
@@ -0,0 +1,109 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.backbones import BiSeNetV1
+from mmseg.models.backbones.bisenetv1 import (AttentionRefinementModule,
+ ContextPath, FeatureFusionModule,
+ SpatialPath)
+
+
+def test_bisenetv1_backbone():
+ # Test BiSeNetV1 Standard Forward
+ backbone_cfg = dict(
+ type='ResNet',
+ in_channels=3,
+ depth=18,
+ num_stages=4,
+ out_indices=(0, 1, 2, 3),
+ dilations=(1, 1, 1, 1),
+ strides=(1, 2, 2, 2),
+ norm_eval=False,
+ style='pytorch',
+ contract_dilation=True)
+ model = BiSeNetV1(in_channels=3, backbone_cfg=backbone_cfg)
+ model.init_weights()
+ model.train()
+ batch_size = 2
+ imgs = torch.randn(batch_size, 3, 64, 128)
+ feat = model(imgs)
+
+ assert len(feat) == 3
+ # output for segment Head
+ assert feat[0].shape == torch.Size([batch_size, 256, 8, 16])
+ # for auxiliary head 1
+ assert feat[1].shape == torch.Size([batch_size, 128, 8, 16])
+ # for auxiliary head 2
+ assert feat[2].shape == torch.Size([batch_size, 128, 4, 8])
+
+ # Test input with rare shape
+ batch_size = 2
+ imgs = torch.randn(batch_size, 3, 95, 27)
+ feat = model(imgs)
+ assert len(feat) == 3
+
+ with pytest.raises(AssertionError):
+ # BiSeNetV1 spatial path channel constraints.
+ BiSeNetV1(
+ backbone_cfg=backbone_cfg,
+ in_channels=3,
+ spatial_channels=(16, 16, 16))
+
+ with pytest.raises(AssertionError):
+ # BiSeNetV1 context path constraints.
+ BiSeNetV1(
+ backbone_cfg=backbone_cfg,
+ in_channels=3,
+ context_channels=(16, 32, 64, 128))
+
+
+def test_bisenetv1_spatial_path():
+ with pytest.raises(AssertionError):
+ # BiSeNetV1 spatial path channel constraints.
+ SpatialPath(num_channels=(16, 16, 16), in_channels=3)
+
+
+def test_bisenetv1_context_path():
+ backbone_cfg = dict(
+ type='ResNet',
+ in_channels=3,
+ depth=50,
+ num_stages=4,
+ out_indices=(0, 1, 2, 3),
+ dilations=(1, 1, 1, 1),
+ strides=(1, 2, 2, 2),
+ norm_eval=False,
+ style='pytorch',
+ contract_dilation=True)
+
+ with pytest.raises(AssertionError):
+ # BiSeNetV1 context path constraints.
+ ContextPath(
+ backbone_cfg=backbone_cfg, context_channels=(16, 32, 64, 128))
+
+
+def test_bisenetv1_attention_refinement_module():
+ x_arm = AttentionRefinementModule(32, 8)
+ assert x_arm.conv_layer.in_channels == 32
+ assert x_arm.conv_layer.out_channels == 8
+ assert x_arm.conv_layer.kernel_size == (3, 3)
+ x = torch.randn(2, 32, 8, 16)
+ x_out = x_arm(x)
+ assert x_out.shape == torch.Size([2, 8, 8, 16])
+
+
+def test_bisenetv1_feature_fusion_module():
+ ffm = FeatureFusionModule(16, 32)
+ assert ffm.conv1.in_channels == 16
+ assert ffm.conv1.out_channels == 32
+ assert ffm.conv1.kernel_size == (1, 1)
+ assert ffm.gap.output_size == (1, 1)
+ assert ffm.conv_atten[0].in_channels == 32
+ assert ffm.conv_atten[0].out_channels == 32
+ assert ffm.conv_atten[0].kernel_size == (1, 1)
+
+ ffm = FeatureFusionModule(16, 16)
+ x1 = torch.randn(2, 8, 8, 16)
+ x2 = torch.randn(2, 8, 8, 16)
+ x_out = ffm(x1, x2)
+ assert x_out.shape == torch.Size([2, 16, 8, 16])
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_bisenetv2.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_bisenetv2.py
new file mode 100644
index 0000000000000000000000000000000000000000..cf2dfb3253a0c766b2a052f22a4140693910ade1
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_bisenetv2.py
@@ -0,0 +1,57 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+from mmcv.cnn import ConvModule
+
+from mmseg.models.backbones import BiSeNetV2
+from mmseg.models.backbones.bisenetv2 import (BGALayer, DetailBranch,
+ SemanticBranch)
+
+
+def test_bisenetv2_backbone():
+ # Test BiSeNetV2 Standard Forward
+ model = BiSeNetV2()
+ model.init_weights()
+ model.train()
+ batch_size = 2
+ imgs = torch.randn(batch_size, 3, 128, 256)
+ feat = model(imgs)
+
+ assert len(feat) == 5
+ # output for segment Head
+ assert feat[0].shape == torch.Size([batch_size, 128, 16, 32])
+ # for auxiliary head 1
+ assert feat[1].shape == torch.Size([batch_size, 16, 32, 64])
+ # for auxiliary head 2
+ assert feat[2].shape == torch.Size([batch_size, 32, 16, 32])
+ # for auxiliary head 3
+ assert feat[3].shape == torch.Size([batch_size, 64, 8, 16])
+ # for auxiliary head 4
+ assert feat[4].shape == torch.Size([batch_size, 128, 4, 8])
+
+ # Test input with rare shape
+ batch_size = 2
+ imgs = torch.randn(batch_size, 3, 95, 27)
+ feat = model(imgs)
+ assert len(feat) == 5
+
+
+def test_bisenetv2_DetailBranch():
+ x = torch.randn(1, 3, 32, 64)
+ detail_branch = DetailBranch(detail_channels=(64, 16, 32))
+ assert isinstance(detail_branch.detail_branch[0][0], ConvModule)
+ x_out = detail_branch(x)
+ assert x_out.shape == torch.Size([1, 32, 4, 8])
+
+
+def test_bisenetv2_SemanticBranch():
+ semantic_branch = SemanticBranch(semantic_channels=(16, 32, 64, 128))
+ assert semantic_branch.stage1.pool.stride == 2
+
+
+def test_bisenetv2_BGALayer():
+ x_a = torch.randn(1, 8, 8, 16)
+ x_b = torch.randn(1, 8, 2, 4)
+ bga = BGALayer(out_channels=8)
+ assert isinstance(bga.conv, ConvModule)
+ x_out = bga(x_a, x_b)
+ assert x_out.shape == torch.Size([1, 8, 8, 16])
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_blocks.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_blocks.py
new file mode 100644
index 0000000000000000000000000000000000000000..77c8564a4737c1f50b4c1e4652781c8316a48797
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_blocks.py
@@ -0,0 +1,186 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import mmcv
+import pytest
+import torch
+from mmcv.utils import TORCH_VERSION, digit_version
+
+from mmseg.models.utils import (InvertedResidual, InvertedResidualV3, SELayer,
+ make_divisible)
+
+
+def test_make_divisible():
+ # test with min_value = None
+ assert make_divisible(10, 4) == 12
+ assert make_divisible(9, 4) == 12
+ assert make_divisible(1, 4) == 4
+
+ # test with min_value = 8
+ assert make_divisible(10, 4, 8) == 12
+ assert make_divisible(9, 4, 8) == 12
+ assert make_divisible(1, 4, 8) == 8
+
+
+def test_inv_residual():
+ with pytest.raises(AssertionError):
+ # test stride assertion.
+ InvertedResidual(32, 32, 3, 4)
+
+ # test default config with res connection.
+ # set expand_ratio = 4, stride = 1 and inp=oup.
+ inv_module = InvertedResidual(32, 32, 1, 4)
+ assert inv_module.use_res_connect
+ assert inv_module.conv[0].kernel_size == (1, 1)
+ assert inv_module.conv[0].padding == 0
+ assert inv_module.conv[1].kernel_size == (3, 3)
+ assert inv_module.conv[1].padding == 1
+ assert inv_module.conv[0].with_norm
+ assert inv_module.conv[1].with_norm
+ x = torch.rand(1, 32, 64, 64)
+ output = inv_module(x)
+ assert output.shape == (1, 32, 64, 64)
+
+ # test inv_residual module without res connection.
+ # set expand_ratio = 4, stride = 2.
+ inv_module = InvertedResidual(32, 32, 2, 4)
+ assert not inv_module.use_res_connect
+ assert inv_module.conv[0].kernel_size == (1, 1)
+ x = torch.rand(1, 32, 64, 64)
+ output = inv_module(x)
+ assert output.shape == (1, 32, 32, 32)
+
+ # test expand_ratio == 1
+ inv_module = InvertedResidual(32, 32, 1, 1)
+ assert inv_module.conv[0].kernel_size == (3, 3)
+ x = torch.rand(1, 32, 64, 64)
+ output = inv_module(x)
+ assert output.shape == (1, 32, 64, 64)
+
+ # test with checkpoint forward
+ inv_module = InvertedResidual(32, 32, 1, 1, with_cp=True)
+ assert inv_module.with_cp
+ x = torch.rand(1, 32, 64, 64, requires_grad=True)
+ output = inv_module(x)
+ assert output.shape == (1, 32, 64, 64)
+
+
+def test_inv_residualv3():
+ with pytest.raises(AssertionError):
+ # test stride assertion.
+ InvertedResidualV3(32, 32, 16, stride=3)
+
+ with pytest.raises(AssertionError):
+ # test assertion.
+ InvertedResidualV3(32, 32, 16, with_expand_conv=False)
+
+ # test with se_cfg=None, with_expand_conv=False
+ inv_module = InvertedResidualV3(32, 32, 32, with_expand_conv=False)
+
+ assert inv_module.with_res_shortcut is True
+ assert inv_module.with_se is False
+ assert inv_module.with_expand_conv is False
+ assert not hasattr(inv_module, 'expand_conv')
+ assert isinstance(inv_module.depthwise_conv.conv, torch.nn.Conv2d)
+ assert inv_module.depthwise_conv.conv.kernel_size == (3, 3)
+ assert inv_module.depthwise_conv.conv.stride == (1, 1)
+ assert inv_module.depthwise_conv.conv.padding == (1, 1)
+ assert isinstance(inv_module.depthwise_conv.bn, torch.nn.BatchNorm2d)
+ assert isinstance(inv_module.depthwise_conv.activate, torch.nn.ReLU)
+ assert inv_module.linear_conv.conv.kernel_size == (1, 1)
+ assert inv_module.linear_conv.conv.stride == (1, 1)
+ assert inv_module.linear_conv.conv.padding == (0, 0)
+ assert isinstance(inv_module.linear_conv.bn, torch.nn.BatchNorm2d)
+
+ x = torch.rand(1, 32, 64, 64)
+ output = inv_module(x)
+ assert output.shape == (1, 32, 64, 64)
+
+ # test with se_cfg and with_expand_conv
+ se_cfg = dict(
+ channels=16,
+ ratio=4,
+ act_cfg=(dict(type='ReLU'),
+ dict(type='HSigmoid', bias=3.0, divisor=6.0)))
+ act_cfg = dict(type='HSwish')
+ inv_module = InvertedResidualV3(
+ 32, 40, 16, 3, 2, se_cfg=se_cfg, act_cfg=act_cfg)
+ assert inv_module.with_res_shortcut is False
+ assert inv_module.with_se is True
+ assert inv_module.with_expand_conv is True
+ assert inv_module.expand_conv.conv.kernel_size == (1, 1)
+ assert inv_module.expand_conv.conv.stride == (1, 1)
+ assert inv_module.expand_conv.conv.padding == (0, 0)
+
+ assert isinstance(inv_module.depthwise_conv.conv,
+ mmcv.cnn.bricks.Conv2dAdaptivePadding)
+ assert inv_module.depthwise_conv.conv.kernel_size == (3, 3)
+ assert inv_module.depthwise_conv.conv.stride == (2, 2)
+ assert inv_module.depthwise_conv.conv.padding == (0, 0)
+ assert isinstance(inv_module.depthwise_conv.bn, torch.nn.BatchNorm2d)
+
+ assert inv_module.linear_conv.conv.kernel_size == (1, 1)
+ assert inv_module.linear_conv.conv.stride == (1, 1)
+ assert inv_module.linear_conv.conv.padding == (0, 0)
+ assert isinstance(inv_module.linear_conv.bn, torch.nn.BatchNorm2d)
+
+ if (TORCH_VERSION == 'parrots'
+ or digit_version(TORCH_VERSION) < digit_version('1.7')):
+ # Note: Use PyTorch official HSwish
+ # when torch>=1.7 after MMCV >= 1.4.5.
+ # Hardswish is not supported when PyTorch version < 1.6.
+ # And Hardswish in PyTorch 1.6 does not support inplace.
+ # More details could be found from:
+ # https://github.com/open-mmlab/mmcv/pull/1709
+ assert isinstance(inv_module.expand_conv.activate, mmcv.cnn.HSwish)
+ assert isinstance(inv_module.depthwise_conv.activate, mmcv.cnn.HSwish)
+ else:
+ assert isinstance(inv_module.expand_conv.activate, torch.nn.Hardswish)
+ assert isinstance(inv_module.depthwise_conv.activate,
+ torch.nn.Hardswish)
+
+ x = torch.rand(1, 32, 64, 64)
+ output = inv_module(x)
+ assert output.shape == (1, 40, 32, 32)
+
+ # test with checkpoint forward
+ inv_module = InvertedResidualV3(
+ 32, 40, 16, 3, 2, se_cfg=se_cfg, act_cfg=act_cfg, with_cp=True)
+ assert inv_module.with_cp
+ x = torch.randn(2, 32, 64, 64, requires_grad=True)
+ output = inv_module(x)
+ assert output.shape == (2, 40, 32, 32)
+
+
+def test_se_layer():
+ with pytest.raises(AssertionError):
+ # test act_cfg assertion.
+ SELayer(32, act_cfg=(dict(type='ReLU'), ))
+
+ # test config with channels = 16.
+ se_layer = SELayer(16)
+ assert se_layer.conv1.conv.kernel_size == (1, 1)
+ assert se_layer.conv1.conv.stride == (1, 1)
+ assert se_layer.conv1.conv.padding == (0, 0)
+ assert isinstance(se_layer.conv1.activate, torch.nn.ReLU)
+ assert se_layer.conv2.conv.kernel_size == (1, 1)
+ assert se_layer.conv2.conv.stride == (1, 1)
+ assert se_layer.conv2.conv.padding == (0, 0)
+ assert isinstance(se_layer.conv2.activate, mmcv.cnn.HSigmoid)
+
+ x = torch.rand(1, 16, 64, 64)
+ output = se_layer(x)
+ assert output.shape == (1, 16, 64, 64)
+
+ # test config with channels = 16, act_cfg = dict(type='ReLU').
+ se_layer = SELayer(16, act_cfg=dict(type='ReLU'))
+ assert se_layer.conv1.conv.kernel_size == (1, 1)
+ assert se_layer.conv1.conv.stride == (1, 1)
+ assert se_layer.conv1.conv.padding == (0, 0)
+ assert isinstance(se_layer.conv1.activate, torch.nn.ReLU)
+ assert se_layer.conv2.conv.kernel_size == (1, 1)
+ assert se_layer.conv2.conv.stride == (1, 1)
+ assert se_layer.conv2.conv.padding == (0, 0)
+ assert isinstance(se_layer.conv2.activate, torch.nn.ReLU)
+
+ x = torch.rand(1, 16, 64, 64)
+ output = se_layer(x)
+ assert output.shape == (1, 16, 64, 64)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_cgnet.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_cgnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..f938525d0a4433cf1f7302c74a4a5bf20be9bec6
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_cgnet.py
@@ -0,0 +1,151 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.backbones import CGNet
+from mmseg.models.backbones.cgnet import (ContextGuidedBlock,
+ GlobalContextExtractor)
+
+
+def test_cgnet_GlobalContextExtractor():
+ block = GlobalContextExtractor(16, 16, with_cp=True)
+ x = torch.randn(2, 16, 64, 64, requires_grad=True)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([2, 16, 64, 64])
+
+
+def test_cgnet_context_guided_block():
+ with pytest.raises(AssertionError):
+ # cgnet ContextGuidedBlock GlobalContextExtractor channel and reduction
+ # constraints.
+ ContextGuidedBlock(8, 8)
+
+ # test cgnet ContextGuidedBlock with checkpoint forward
+ block = ContextGuidedBlock(
+ 16, 16, act_cfg=dict(type='PReLU'), with_cp=True)
+ assert block.with_cp
+ x = torch.randn(2, 16, 64, 64, requires_grad=True)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([2, 16, 64, 64])
+
+ # test cgnet ContextGuidedBlock without checkpoint forward
+ block = ContextGuidedBlock(32, 32)
+ assert not block.with_cp
+ x = torch.randn(3, 32, 32, 32)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([3, 32, 32, 32])
+
+ # test cgnet ContextGuidedBlock with down sampling
+ block = ContextGuidedBlock(32, 32, downsample=True)
+ assert block.conv1x1.conv.in_channels == 32
+ assert block.conv1x1.conv.out_channels == 32
+ assert block.conv1x1.conv.kernel_size == (3, 3)
+ assert block.conv1x1.conv.stride == (2, 2)
+ assert block.conv1x1.conv.padding == (1, 1)
+
+ assert block.f_loc.in_channels == 32
+ assert block.f_loc.out_channels == 32
+ assert block.f_loc.kernel_size == (3, 3)
+ assert block.f_loc.stride == (1, 1)
+ assert block.f_loc.padding == (1, 1)
+ assert block.f_loc.groups == 32
+ assert block.f_loc.dilation == (1, 1)
+ assert block.f_loc.bias is None
+
+ assert block.f_sur.in_channels == 32
+ assert block.f_sur.out_channels == 32
+ assert block.f_sur.kernel_size == (3, 3)
+ assert block.f_sur.stride == (1, 1)
+ assert block.f_sur.padding == (2, 2)
+ assert block.f_sur.groups == 32
+ assert block.f_sur.dilation == (2, 2)
+ assert block.f_sur.bias is None
+
+ assert block.bottleneck.in_channels == 64
+ assert block.bottleneck.out_channels == 32
+ assert block.bottleneck.kernel_size == (1, 1)
+ assert block.bottleneck.stride == (1, 1)
+ assert block.bottleneck.bias is None
+
+ x = torch.randn(1, 32, 32, 32)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 32, 16, 16])
+
+ # test cgnet ContextGuidedBlock without down sampling
+ block = ContextGuidedBlock(32, 32, downsample=False)
+ assert block.conv1x1.conv.in_channels == 32
+ assert block.conv1x1.conv.out_channels == 16
+ assert block.conv1x1.conv.kernel_size == (1, 1)
+ assert block.conv1x1.conv.stride == (1, 1)
+ assert block.conv1x1.conv.padding == (0, 0)
+
+ assert block.f_loc.in_channels == 16
+ assert block.f_loc.out_channels == 16
+ assert block.f_loc.kernel_size == (3, 3)
+ assert block.f_loc.stride == (1, 1)
+ assert block.f_loc.padding == (1, 1)
+ assert block.f_loc.groups == 16
+ assert block.f_loc.dilation == (1, 1)
+ assert block.f_loc.bias is None
+
+ assert block.f_sur.in_channels == 16
+ assert block.f_sur.out_channels == 16
+ assert block.f_sur.kernel_size == (3, 3)
+ assert block.f_sur.stride == (1, 1)
+ assert block.f_sur.padding == (2, 2)
+ assert block.f_sur.groups == 16
+ assert block.f_sur.dilation == (2, 2)
+ assert block.f_sur.bias is None
+
+ x = torch.randn(1, 32, 32, 32)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 32, 32, 32])
+
+
+def test_cgnet_backbone():
+ with pytest.raises(AssertionError):
+ # check invalid num_channels
+ CGNet(num_channels=(32, 64, 128, 256))
+
+ with pytest.raises(AssertionError):
+ # check invalid num_blocks
+ CGNet(num_blocks=(3, 21, 3))
+
+ with pytest.raises(AssertionError):
+ # check invalid dilation
+ CGNet(num_blocks=2)
+
+ with pytest.raises(AssertionError):
+ # check invalid reduction
+ CGNet(reductions=16)
+
+ with pytest.raises(AssertionError):
+ # check invalid num_channels and reduction
+ CGNet(num_channels=(32, 64, 128), reductions=(64, 129))
+
+ # Test CGNet with default settings
+ model = CGNet()
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(2, 3, 224, 224)
+ feat = model(imgs)
+ assert len(feat) == 3
+ assert feat[0].shape == torch.Size([2, 35, 112, 112])
+ assert feat[1].shape == torch.Size([2, 131, 56, 56])
+ assert feat[2].shape == torch.Size([2, 256, 28, 28])
+
+ # Test CGNet with norm_eval True and with_cp True
+ model = CGNet(norm_eval=True, with_cp=True)
+ with pytest.raises(TypeError):
+ # check invalid pretrained
+ model.init_weights(pretrained=8)
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(2, 3, 224, 224)
+ feat = model(imgs)
+ assert len(feat) == 3
+ assert feat[0].shape == torch.Size([2, 35, 112, 112])
+ assert feat[1].shape == torch.Size([2, 131, 56, 56])
+ assert feat[2].shape == torch.Size([2, 256, 28, 28])
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_erfnet.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_erfnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..6ae7345e1524fd104eb243e52bec5d0f75a24d64
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_erfnet.py
@@ -0,0 +1,146 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.backbones import ERFNet
+from mmseg.models.backbones.erfnet import (DownsamplerBlock, NonBottleneck1d,
+ UpsamplerBlock)
+
+
+def test_erfnet_backbone():
+ # Test ERFNet Standard Forward.
+ model = ERFNet(
+ in_channels=3,
+ enc_downsample_channels=(16, 64, 128),
+ enc_stage_non_bottlenecks=(5, 8),
+ enc_non_bottleneck_dilations=(2, 4, 8, 16),
+ enc_non_bottleneck_channels=(64, 128),
+ dec_upsample_channels=(64, 16),
+ dec_stages_non_bottleneck=(2, 2),
+ dec_non_bottleneck_channels=(64, 16),
+ dropout_ratio=0.1,
+ )
+ model.init_weights()
+ model.train()
+ batch_size = 2
+ imgs = torch.randn(batch_size, 3, 256, 512)
+ output = model(imgs)
+
+ # output for segment Head
+ assert output[0].shape == torch.Size([batch_size, 16, 128, 256])
+
+ # Test input with rare shape
+ batch_size = 2
+ imgs = torch.randn(batch_size, 3, 527, 279)
+ output = model(imgs)
+ assert len(output[0]) == batch_size
+
+ with pytest.raises(AssertionError):
+ # Number of encoder downsample block and decoder upsample block.
+ ERFNet(
+ in_channels=3,
+ enc_downsample_channels=(16, 64, 128),
+ enc_stage_non_bottlenecks=(5, 8),
+ enc_non_bottleneck_dilations=(2, 4, 8, 16),
+ enc_non_bottleneck_channels=(64, 128),
+ dec_upsample_channels=(128, 64, 16),
+ dec_stages_non_bottleneck=(2, 2),
+ dec_non_bottleneck_channels=(64, 16),
+ dropout_ratio=0.1,
+ )
+ with pytest.raises(AssertionError):
+ # Number of encoder downsample block and encoder Non-bottleneck block.
+ ERFNet(
+ in_channels=3,
+ enc_downsample_channels=(16, 64, 128),
+ enc_stage_non_bottlenecks=(5, 8, 10),
+ enc_non_bottleneck_dilations=(2, 4, 8, 16),
+ enc_non_bottleneck_channels=(64, 128),
+ dec_upsample_channels=(64, 16),
+ dec_stages_non_bottleneck=(2, 2),
+ dec_non_bottleneck_channels=(64, 16),
+ dropout_ratio=0.1,
+ )
+ with pytest.raises(AssertionError):
+ # Number of encoder downsample block and
+ # channels of encoder Non-bottleneck block.
+ ERFNet(
+ in_channels=3,
+ enc_downsample_channels=(16, 64, 128),
+ enc_stage_non_bottlenecks=(5, 8),
+ enc_non_bottleneck_dilations=(2, 4, 8, 16),
+ enc_non_bottleneck_channels=(64, 128, 256),
+ dec_upsample_channels=(64, 16),
+ dec_stages_non_bottleneck=(2, 2),
+ dec_non_bottleneck_channels=(64, 16),
+ dropout_ratio=0.1,
+ )
+
+ with pytest.raises(AssertionError):
+ # Number of encoder Non-bottleneck block and number of its channels.
+ ERFNet(
+ in_channels=3,
+ enc_downsample_channels=(16, 64, 128),
+ enc_stage_non_bottlenecks=(5, 8, 3),
+ enc_non_bottleneck_dilations=(2, 4, 8, 16),
+ enc_non_bottleneck_channels=(64, 128),
+ dec_upsample_channels=(64, 16),
+ dec_stages_non_bottleneck=(2, 2),
+ dec_non_bottleneck_channels=(64, 16),
+ dropout_ratio=0.1,
+ )
+ with pytest.raises(AssertionError):
+ # Number of decoder upsample block and decoder Non-bottleneck block.
+ ERFNet(
+ in_channels=3,
+ enc_downsample_channels=(16, 64, 128),
+ enc_stage_non_bottlenecks=(5, 8),
+ enc_non_bottleneck_dilations=(2, 4, 8, 16),
+ enc_non_bottleneck_channels=(64, 128),
+ dec_upsample_channels=(64, 16),
+ dec_stages_non_bottleneck=(2, 2, 3),
+ dec_non_bottleneck_channels=(64, 16),
+ dropout_ratio=0.1,
+ )
+ with pytest.raises(AssertionError):
+ # Number of decoder Non-bottleneck block and number of its channels.
+ ERFNet(
+ in_channels=3,
+ enc_downsample_channels=(16, 64, 128),
+ enc_stage_non_bottlenecks=(5, 8),
+ enc_non_bottleneck_dilations=(2, 4, 8, 16),
+ enc_non_bottleneck_channels=(64, 128),
+ dec_upsample_channels=(64, 16),
+ dec_stages_non_bottleneck=(2, 2),
+ dec_non_bottleneck_channels=(64, 16, 8),
+ dropout_ratio=0.1,
+ )
+
+
+def test_erfnet_downsampler_block():
+ x_db = DownsamplerBlock(16, 64)
+ assert x_db.conv.in_channels == 16
+ assert x_db.conv.out_channels == 48
+ assert len(x_db.bn.weight) == 64
+ assert x_db.pool.kernel_size == 2
+ assert x_db.pool.stride == 2
+
+
+def test_erfnet_non_bottleneck_1d():
+ x_nb1d = NonBottleneck1d(16, 0, 1)
+ assert x_nb1d.convs_layers[0].in_channels == 16
+ assert x_nb1d.convs_layers[0].out_channels == 16
+ assert x_nb1d.convs_layers[2].in_channels == 16
+ assert x_nb1d.convs_layers[2].out_channels == 16
+ assert x_nb1d.convs_layers[5].in_channels == 16
+ assert x_nb1d.convs_layers[5].out_channels == 16
+ assert x_nb1d.convs_layers[7].in_channels == 16
+ assert x_nb1d.convs_layers[7].out_channels == 16
+ assert x_nb1d.convs_layers[9].p == 0
+
+
+def test_erfnet_upsampler_block():
+ x_ub = UpsamplerBlock(64, 16)
+ assert x_ub.conv.in_channels == 64
+ assert x_ub.conv.out_channels == 16
+ assert len(x_ub.bn.weight) == 16
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_fast_scnn.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_fast_scnn.py
new file mode 100644
index 0000000000000000000000000000000000000000..7ee638b510af37783fc7f18f30302800b0196ddb
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_fast_scnn.py
@@ -0,0 +1,42 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.backbones import FastSCNN
+
+
+def test_fastscnn_backbone():
+ with pytest.raises(AssertionError):
+ # Fast-SCNN channel constraints.
+ FastSCNN(
+ 3, (32, 48),
+ 64, (64, 96, 128), (2, 2, 1),
+ global_out_channels=127,
+ higher_in_channels=64,
+ lower_in_channels=128)
+
+ # Test FastSCNN Standard Forward
+ model = FastSCNN(
+ in_channels=3,
+ downsample_dw_channels=(4, 6),
+ global_in_channels=8,
+ global_block_channels=(8, 12, 16),
+ global_block_strides=(2, 2, 1),
+ global_out_channels=16,
+ higher_in_channels=8,
+ lower_in_channels=16,
+ fusion_out_channels=16,
+ )
+ model.init_weights()
+ model.train()
+ batch_size = 4
+ imgs = torch.randn(batch_size, 3, 64, 128)
+ feat = model(imgs)
+
+ assert len(feat) == 3
+ # higher-res
+ assert feat[0].shape == torch.Size([batch_size, 8, 8, 16])
+ # lower-res
+ assert feat[1].shape == torch.Size([batch_size, 16, 2, 4])
+ # FFM output
+ assert feat[2].shape == torch.Size([batch_size, 16, 8, 16])
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_hrnet.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_hrnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..8329c84312675ccc589b169cb32732b12c6f27cc
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_hrnet.py
@@ -0,0 +1,144 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+from mmcv.utils.parrots_wrapper import _BatchNorm
+
+from mmseg.models.backbones.hrnet import HRModule, HRNet
+from mmseg.models.backbones.resnet import BasicBlock, Bottleneck
+
+
+@pytest.mark.parametrize('block', [BasicBlock, Bottleneck])
+def test_hrmodule(block):
+ # Test multiscale forward
+ num_channles = (32, 64)
+ in_channels = [c * block.expansion for c in num_channles]
+ hrmodule = HRModule(
+ num_branches=2,
+ blocks=block,
+ in_channels=in_channels,
+ num_blocks=(4, 4),
+ num_channels=num_channles,
+ )
+
+ feats = [
+ torch.randn(1, in_channels[0], 64, 64),
+ torch.randn(1, in_channels[1], 32, 32)
+ ]
+ feats = hrmodule(feats)
+
+ assert len(feats) == 2
+ assert feats[0].shape == torch.Size([1, in_channels[0], 64, 64])
+ assert feats[1].shape == torch.Size([1, in_channels[1], 32, 32])
+
+ # Test single scale forward
+ num_channles = (32, 64)
+ in_channels = [c * block.expansion for c in num_channles]
+ hrmodule = HRModule(
+ num_branches=2,
+ blocks=block,
+ in_channels=in_channels,
+ num_blocks=(4, 4),
+ num_channels=num_channles,
+ multiscale_output=False,
+ )
+
+ feats = [
+ torch.randn(1, in_channels[0], 64, 64),
+ torch.randn(1, in_channels[1], 32, 32)
+ ]
+ feats = hrmodule(feats)
+
+ assert len(feats) == 1
+ assert feats[0].shape == torch.Size([1, in_channels[0], 64, 64])
+
+
+def test_hrnet_backbone():
+ # only have 3 stages
+ extra = dict(
+ stage1=dict(
+ num_modules=1,
+ num_branches=1,
+ block='BOTTLENECK',
+ num_blocks=(4, ),
+ num_channels=(64, )),
+ stage2=dict(
+ num_modules=1,
+ num_branches=2,
+ block='BASIC',
+ num_blocks=(4, 4),
+ num_channels=(32, 64)),
+ stage3=dict(
+ num_modules=4,
+ num_branches=3,
+ block='BASIC',
+ num_blocks=(4, 4, 4),
+ num_channels=(32, 64, 128)))
+
+ with pytest.raises(AssertionError):
+ # HRNet now only support 4 stages
+ HRNet(extra=extra)
+ extra['stage4'] = dict(
+ num_modules=3,
+ num_branches=3, # should be 4
+ block='BASIC',
+ num_blocks=(4, 4, 4, 4),
+ num_channels=(32, 64, 128, 256))
+
+ with pytest.raises(AssertionError):
+ # len(num_blocks) should equal num_branches
+ HRNet(extra=extra)
+
+ extra['stage4']['num_branches'] = 4
+
+ # Test hrnetv2p_w32
+ model = HRNet(extra=extra)
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(1, 3, 64, 64)
+ feats = model(imgs)
+ assert len(feats) == 4
+ assert feats[0].shape == torch.Size([1, 32, 16, 16])
+ assert feats[3].shape == torch.Size([1, 256, 2, 2])
+
+ # Test single scale output
+ model = HRNet(extra=extra, multiscale_output=False)
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(1, 3, 64, 64)
+ feats = model(imgs)
+ assert len(feats) == 1
+ assert feats[0].shape == torch.Size([1, 32, 16, 16])
+
+ # Test HRNET with two stage frozen
+ frozen_stages = 2
+ model = HRNet(extra, frozen_stages=frozen_stages)
+ model.init_weights()
+ model.train()
+ assert model.norm1.training is False
+
+ for layer in [model.conv1, model.norm1]:
+ for param in layer.parameters():
+ assert param.requires_grad is False
+ for i in range(1, frozen_stages + 1):
+ if i == 1:
+ layer = getattr(model, f'layer{i}')
+ transition = getattr(model, f'transition{i}')
+ elif i == 4:
+ layer = getattr(model, f'stage{i}')
+ else:
+ layer = getattr(model, f'stage{i}')
+ transition = getattr(model, f'transition{i}')
+
+ for mod in layer.modules():
+ if isinstance(mod, _BatchNorm):
+ assert mod.training is False
+ for param in layer.parameters():
+ assert param.requires_grad is False
+
+ for mod in transition.modules():
+ if isinstance(mod, _BatchNorm):
+ assert mod.training is False
+ for param in transition.parameters():
+ assert param.requires_grad is False
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_icnet.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_icnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..a96d8d86fbd98db07b34770f7b46d03c32fb067c
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_icnet.py
@@ -0,0 +1,50 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.backbones import ICNet
+
+
+def test_icnet_backbone():
+ with pytest.raises(TypeError):
+ # Must give backbone dict in config file.
+ ICNet(
+ in_channels=3,
+ layer_channels=(128, 512),
+ light_branch_middle_channels=8,
+ psp_out_channels=128,
+ out_channels=(16, 128, 128),
+ backbone_cfg=None)
+
+ # Test ICNet Standard Forward
+ model = ICNet(
+ layer_channels=(128, 512),
+ backbone_cfg=dict(
+ type='ResNetV1c',
+ in_channels=3,
+ depth=18,
+ num_stages=4,
+ out_indices=(0, 1, 2, 3),
+ dilations=(1, 1, 2, 4),
+ strides=(1, 2, 1, 1),
+ norm_cfg=dict(type='BN', requires_grad=True),
+ norm_eval=False,
+ style='pytorch',
+ contract_dilation=True),
+ )
+ assert hasattr(model.backbone,
+ 'maxpool') and model.backbone.maxpool.ceil_mode is True
+ model.init_weights()
+ model.train()
+ batch_size = 2
+ imgs = torch.randn(batch_size, 3, 32, 64)
+ feat = model(imgs)
+
+ assert model.psp_modules[0][0].output_size == 1
+ assert model.psp_modules[1][0].output_size == 2
+ assert model.psp_modules[2][0].output_size == 3
+ assert model.psp_bottleneck.padding == 1
+ assert model.conv_sub1[0].padding == 1
+
+ assert len(feat) == 3
+ assert feat[0].shape == torch.Size([batch_size, 64, 4, 8])
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_mae.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_mae.py
new file mode 100644
index 0000000000000000000000000000000000000000..562d067a7c76d57fcfca7edf21a1fb66daa8f98f
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_mae.py
@@ -0,0 +1,183 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.backbones.mae import MAE
+from .utils import check_norm_state
+
+
+def test_mae_backbone():
+ with pytest.raises(TypeError):
+ # pretrained must be a string path
+ model = MAE()
+ model.init_weights(pretrained=0)
+
+ with pytest.raises(TypeError):
+ # img_size must be int or tuple
+ model = MAE(img_size=512.0)
+
+ with pytest.raises(TypeError):
+ # out_indices must be int ,list or tuple
+ model = MAE(out_indices=1.)
+
+ with pytest.raises(AssertionError):
+ # The length of img_size tuple must be lower than 3.
+ MAE(img_size=(224, 224, 224))
+
+ with pytest.raises(TypeError):
+ # Pretrained must be None or Str.
+ MAE(pretrained=123)
+
+ # Test img_size isinstance tuple
+ imgs = torch.randn(1, 3, 224, 224)
+ model = MAE(img_size=(224, ))
+ model.init_weights()
+ model(imgs)
+
+ # Test img_size isinstance tuple
+ imgs = torch.randn(1, 3, 224, 224)
+ model = MAE(img_size=(224, 224))
+ model(imgs)
+
+ # Test norm_eval = True
+ model = MAE(norm_eval=True)
+ model.train()
+
+ # Test BEiT backbone with input size of 224 and patch size of 16
+ model = MAE()
+ model.init_weights()
+ model.train()
+
+ # Test out_indices = list
+ model = MAE(out_indices=[2, 4, 8, 12])
+ model.train()
+
+ assert check_norm_state(model.modules(), True)
+
+ # Test image size = (224, 224)
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 14, 14)
+
+ # Test MAE backbone with input size of 256 and patch size of 16
+ model = MAE(img_size=(256, 256))
+ model.init_weights()
+ model.train()
+ imgs = torch.randn(1, 3, 256, 256)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 16, 16)
+
+ # Test MAE backbone with input size of 32 and patch size of 16
+ model = MAE(img_size=(32, 32))
+ model.init_weights()
+ model.train()
+ imgs = torch.randn(1, 3, 32, 32)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 2, 2)
+
+ # Test unbalanced size input image
+ model = MAE(img_size=(112, 224))
+ model.init_weights()
+ model.train()
+ imgs = torch.randn(1, 3, 112, 224)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 7, 14)
+
+ # Test irregular input image
+ model = MAE(img_size=(234, 345))
+ model.init_weights()
+ model.train()
+ imgs = torch.randn(1, 3, 234, 345)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 14, 21)
+
+ # Test init_values=0
+ model = MAE(init_values=0)
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 14, 14)
+
+ # Test final norm
+ model = MAE(final_norm=True)
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 14, 14)
+
+ # Test patch norm
+ model = MAE(patch_norm=True)
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 14, 14)
+
+
+def test_mae_init():
+ path = 'PATH_THAT_DO_NOT_EXIST'
+ # Test all combinations of pretrained and init_cfg
+ # pretrained=None, init_cfg=None
+ model = MAE(pretrained=None, init_cfg=None)
+ assert model.init_cfg is None
+ model.init_weights()
+
+ # pretrained=None
+ # init_cfg loads pretrain from an non-existent file
+ model = MAE(
+ pretrained=None, init_cfg=dict(type='Pretrained', checkpoint=path))
+ assert model.init_cfg == dict(type='Pretrained', checkpoint=path)
+ # Test loading a checkpoint from an non-existent file
+ with pytest.raises(OSError):
+ model.init_weights()
+
+ # test resize_rel_pos_embed
+ value = torch.randn(732, 16)
+ abs_pos_embed_value = torch.rand(1, 17, 768)
+ ckpt = {
+ 'state_dict': {
+ 'layers.0.attn.relative_position_index': 0,
+ 'layers.0.attn.relative_position_bias_table': value,
+ 'pos_embed': abs_pos_embed_value
+ }
+ }
+ model = MAE(img_size=(512, 512))
+ with pytest.raises(AttributeError):
+ model.resize_rel_pos_embed(ckpt)
+
+ # test resize abs pos embed
+ ckpt = model.resize_abs_pos_embed(ckpt['state_dict'])
+
+ # pretrained=None
+ # init_cfg=123, whose type is unsupported
+ model = MAE(pretrained=None, init_cfg=123)
+ with pytest.raises(TypeError):
+ model.init_weights()
+
+ # pretrained loads pretrain from an non-existent file
+ # init_cfg=None
+ model = MAE(pretrained=path, init_cfg=None)
+ assert model.init_cfg == dict(type='Pretrained', checkpoint=path)
+ # Test loading a checkpoint from an non-existent file
+ with pytest.raises(OSError):
+ model.init_weights()
+
+ # pretrained loads pretrain from an non-existent file
+ # init_cfg loads pretrain from an non-existent file
+ with pytest.raises(AssertionError):
+ model = MAE(
+ pretrained=path, init_cfg=dict(type='Pretrained', checkpoint=path))
+ with pytest.raises(AssertionError):
+ model = MAE(pretrained=path, init_cfg=123)
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg=None
+ with pytest.raises(TypeError):
+ model = MAE(pretrained=123, init_cfg=None)
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg loads pretrain from an non-existent file
+ with pytest.raises(AssertionError):
+ model = MAE(
+ pretrained=123, init_cfg=dict(type='Pretrained', checkpoint=path))
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg=123, whose type is unsupported
+ with pytest.raises(AssertionError):
+ model = MAE(pretrained=123, init_cfg=123)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_mit.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_mit.py
new file mode 100644
index 0000000000000000000000000000000000000000..72f74fe209423daed07fcf3bd59d5979e43c43d1
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_mit.py
@@ -0,0 +1,122 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.backbones import MixVisionTransformer
+from mmseg.models.backbones.mit import (EfficientMultiheadAttention, MixFFN,
+ TransformerEncoderLayer)
+
+
+def test_mit():
+ with pytest.raises(TypeError):
+ # Pretrained represents pretrain url and must be str or None.
+ MixVisionTransformer(pretrained=123)
+
+ # Test normal input
+ H, W = (224, 224)
+ temp = torch.randn((1, 3, H, W))
+ model = MixVisionTransformer(
+ embed_dims=32, num_heads=[1, 2, 5, 8], out_indices=(0, 1, 2, 3))
+ model.init_weights()
+ outs = model(temp)
+ assert outs[0].shape == (1, 32, H // 4, W // 4)
+ assert outs[1].shape == (1, 64, H // 8, W // 8)
+ assert outs[2].shape == (1, 160, H // 16, W // 16)
+ assert outs[3].shape == (1, 256, H // 32, W // 32)
+
+ # Test non-squared input
+ H, W = (224, 256)
+ temp = torch.randn((1, 3, H, W))
+ outs = model(temp)
+ assert outs[0].shape == (1, 32, H // 4, W // 4)
+ assert outs[1].shape == (1, 64, H // 8, W // 8)
+ assert outs[2].shape == (1, 160, H // 16, W // 16)
+ assert outs[3].shape == (1, 256, H // 32, W // 32)
+
+ # Test MixFFN
+ FFN = MixFFN(64, 128)
+ hw_shape = (32, 32)
+ token_len = 32 * 32
+ temp = torch.randn((1, token_len, 64))
+ # Self identity
+ out = FFN(temp, hw_shape)
+ assert out.shape == (1, token_len, 64)
+ # Out identity
+ outs = FFN(temp, hw_shape, temp)
+ assert out.shape == (1, token_len, 64)
+
+ # Test EfficientMHA
+ MHA = EfficientMultiheadAttention(64, 2)
+ hw_shape = (32, 32)
+ token_len = 32 * 32
+ temp = torch.randn((1, token_len, 64))
+ # Self identity
+ out = MHA(temp, hw_shape)
+ assert out.shape == (1, token_len, 64)
+ # Out identity
+ outs = MHA(temp, hw_shape, temp)
+ assert out.shape == (1, token_len, 64)
+
+ # Test TransformerEncoderLayer with checkpoint forward
+ block = TransformerEncoderLayer(
+ embed_dims=64, num_heads=4, feedforward_channels=256, with_cp=True)
+ assert block.with_cp
+ x = torch.randn(1, 56 * 56, 64)
+ x_out = block(x, (56, 56))
+ assert x_out.shape == torch.Size([1, 56 * 56, 64])
+
+
+def test_mit_init():
+ path = 'PATH_THAT_DO_NOT_EXIST'
+ # Test all combinations of pretrained and init_cfg
+ # pretrained=None, init_cfg=None
+ model = MixVisionTransformer(pretrained=None, init_cfg=None)
+ assert model.init_cfg is None
+ model.init_weights()
+
+ # pretrained=None
+ # init_cfg loads pretrain from an non-existent file
+ model = MixVisionTransformer(
+ pretrained=None, init_cfg=dict(type='Pretrained', checkpoint=path))
+ assert model.init_cfg == dict(type='Pretrained', checkpoint=path)
+ # Test loading a checkpoint from an non-existent file
+ with pytest.raises(OSError):
+ model.init_weights()
+
+ # pretrained=None
+ # init_cfg=123, whose type is unsupported
+ model = MixVisionTransformer(pretrained=None, init_cfg=123)
+ with pytest.raises(TypeError):
+ model.init_weights()
+
+ # pretrained loads pretrain from an non-existent file
+ # init_cfg=None
+ model = MixVisionTransformer(pretrained=path, init_cfg=None)
+ assert model.init_cfg == dict(type='Pretrained', checkpoint=path)
+ # Test loading a checkpoint from an non-existent file
+ with pytest.raises(OSError):
+ model.init_weights()
+
+ # pretrained loads pretrain from an non-existent file
+ # init_cfg loads pretrain from an non-existent file
+ with pytest.raises(AssertionError):
+ MixVisionTransformer(
+ pretrained=path, init_cfg=dict(type='Pretrained', checkpoint=path))
+ with pytest.raises(AssertionError):
+ MixVisionTransformer(pretrained=path, init_cfg=123)
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg=None
+ with pytest.raises(TypeError):
+ MixVisionTransformer(pretrained=123, init_cfg=None)
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg loads pretrain from an non-existent file
+ with pytest.raises(AssertionError):
+ MixVisionTransformer(
+ pretrained=123, init_cfg=dict(type='Pretrained', checkpoint=path))
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg=123, whose type is unsupported
+ with pytest.raises(AssertionError):
+ MixVisionTransformer(pretrained=123, init_cfg=123)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_mobilenet_v3.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_mobilenet_v3.py
new file mode 100644
index 0000000000000000000000000000000000000000..769ee14bc2423ba82a46e7637fa1fa7004609be0
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_mobilenet_v3.py
@@ -0,0 +1,67 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.backbones import MobileNetV3
+
+
+def test_mobilenet_v3():
+ with pytest.raises(AssertionError):
+ # check invalid arch
+ MobileNetV3('big')
+
+ with pytest.raises(AssertionError):
+ # check invalid reduction_factor
+ MobileNetV3(reduction_factor=0)
+
+ with pytest.raises(ValueError):
+ # check invalid out_indices
+ MobileNetV3(out_indices=(0, 1, 15))
+
+ with pytest.raises(ValueError):
+ # check invalid frozen_stages
+ MobileNetV3(frozen_stages=15)
+
+ with pytest.raises(TypeError):
+ # check invalid pretrained
+ model = MobileNetV3()
+ model.init_weights(pretrained=8)
+
+ # Test MobileNetV3 with default settings
+ model = MobileNetV3()
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(2, 3, 56, 56)
+ feat = model(imgs)
+ assert len(feat) == 3
+ assert feat[0].shape == (2, 16, 28, 28)
+ assert feat[1].shape == (2, 16, 14, 14)
+ assert feat[2].shape == (2, 576, 7, 7)
+
+ # Test MobileNetV3 with arch = 'large'
+ model = MobileNetV3(arch='large', out_indices=(1, 3, 16))
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(2, 3, 56, 56)
+ feat = model(imgs)
+ assert len(feat) == 3
+ assert feat[0].shape == (2, 16, 28, 28)
+ assert feat[1].shape == (2, 24, 14, 14)
+ assert feat[2].shape == (2, 960, 7, 7)
+
+ # Test MobileNetV3 with norm_eval True, with_cp True and frozen_stages=5
+ model = MobileNetV3(norm_eval=True, with_cp=True, frozen_stages=5)
+ with pytest.raises(TypeError):
+ # check invalid pretrained
+ model.init_weights(pretrained=8)
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(2, 3, 56, 56)
+ feat = model(imgs)
+ assert len(feat) == 3
+ assert feat[0].shape == (2, 16, 28, 28)
+ assert feat[1].shape == (2, 16, 14, 14)
+ assert feat[2].shape == (2, 576, 7, 7)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_resnest.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_resnest.py
new file mode 100644
index 0000000000000000000000000000000000000000..3013f34fcca8c6f052946a710c0007dc4b23570f
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_resnest.py
@@ -0,0 +1,44 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.backbones import ResNeSt
+from mmseg.models.backbones.resnest import Bottleneck as BottleneckS
+
+
+def test_resnest_bottleneck():
+ with pytest.raises(AssertionError):
+ # Style must be in ['pytorch', 'caffe']
+ BottleneckS(64, 64, radix=2, reduction_factor=4, style='tensorflow')
+
+ # Test ResNeSt Bottleneck structure
+ block = BottleneckS(
+ 64, 256, radix=2, reduction_factor=4, stride=2, style='pytorch')
+ assert block.avd_layer.stride == 2
+ assert block.conv2.channels == 256
+
+ # Test ResNeSt Bottleneck forward
+ block = BottleneckS(64, 16, radix=2, reduction_factor=4)
+ x = torch.randn(2, 64, 56, 56)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([2, 64, 56, 56])
+
+
+def test_resnest_backbone():
+ with pytest.raises(KeyError):
+ # ResNeSt depth should be in [50, 101, 152, 200]
+ ResNeSt(depth=18)
+
+ # Test ResNeSt with radix 2, reduction_factor 4
+ model = ResNeSt(
+ depth=50, radix=2, reduction_factor=4, out_indices=(0, 1, 2, 3))
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(2, 3, 224, 224)
+ feat = model(imgs)
+ assert len(feat) == 4
+ assert feat[0].shape == torch.Size([2, 256, 56, 56])
+ assert feat[1].shape == torch.Size([2, 512, 28, 28])
+ assert feat[2].shape == torch.Size([2, 1024, 14, 14])
+ assert feat[3].shape == torch.Size([2, 2048, 7, 7])
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_resnet.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_resnet.py
new file mode 100644
index 0000000000000000000000000000000000000000..fa632f5d83ee6be74c577b294cc2e04e9809e6d1
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_resnet.py
@@ -0,0 +1,575 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+from mmcv.ops import DeformConv2dPack
+from mmcv.utils.parrots_wrapper import _BatchNorm
+from torch.nn.modules import AvgPool2d, GroupNorm
+
+from mmseg.models.backbones import ResNet, ResNetV1d
+from mmseg.models.backbones.resnet import BasicBlock, Bottleneck
+from mmseg.models.utils import ResLayer
+from .utils import all_zeros, check_norm_state, is_block, is_norm
+
+
+def test_resnet_basic_block():
+ with pytest.raises(AssertionError):
+ # Not implemented yet.
+ dcn = dict(type='DCN', deform_groups=1, fallback_on_stride=False)
+ BasicBlock(64, 64, dcn=dcn)
+
+ with pytest.raises(AssertionError):
+ # Not implemented yet.
+ plugins = [
+ dict(
+ cfg=dict(type='ContextBlock', ratio=1. / 16),
+ position='after_conv3')
+ ]
+ BasicBlock(64, 64, plugins=plugins)
+
+ with pytest.raises(AssertionError):
+ # Not implemented yet
+ plugins = [
+ dict(
+ cfg=dict(
+ type='GeneralizedAttention',
+ spatial_range=-1,
+ num_heads=8,
+ attention_type='0010',
+ kv_stride=2),
+ position='after_conv2')
+ ]
+ BasicBlock(64, 64, plugins=plugins)
+
+ # Test BasicBlock with checkpoint forward
+ block = BasicBlock(16, 16, with_cp=True)
+ assert block.with_cp
+ x = torch.randn(1, 16, 28, 28)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 16, 28, 28])
+
+ # test BasicBlock structure and forward
+ block = BasicBlock(32, 32)
+ assert block.conv1.in_channels == 32
+ assert block.conv1.out_channels == 32
+ assert block.conv1.kernel_size == (3, 3)
+ assert block.conv2.in_channels == 32
+ assert block.conv2.out_channels == 32
+ assert block.conv2.kernel_size == (3, 3)
+ x = torch.randn(1, 32, 28, 28)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 32, 28, 28])
+
+
+def test_resnet_bottleneck():
+ with pytest.raises(AssertionError):
+ # Style must be in ['pytorch', 'caffe']
+ Bottleneck(64, 64, style='tensorflow')
+
+ with pytest.raises(AssertionError):
+ # Allowed positions are 'after_conv1', 'after_conv2', 'after_conv3'
+ plugins = [
+ dict(
+ cfg=dict(type='ContextBlock', ratio=1. / 16),
+ position='after_conv4')
+ ]
+ Bottleneck(64, 16, plugins=plugins)
+
+ with pytest.raises(AssertionError):
+ # Need to specify different postfix to avoid duplicate plugin name
+ plugins = [
+ dict(
+ cfg=dict(type='ContextBlock', ratio=1. / 16),
+ position='after_conv3'),
+ dict(
+ cfg=dict(type='ContextBlock', ratio=1. / 16),
+ position='after_conv3')
+ ]
+ Bottleneck(64, 16, plugins=plugins)
+
+ with pytest.raises(KeyError):
+ # Plugin type is not supported
+ plugins = [dict(cfg=dict(type='WrongPlugin'), position='after_conv3')]
+ Bottleneck(64, 16, plugins=plugins)
+
+ # Test Bottleneck with checkpoint forward
+ block = Bottleneck(64, 16, with_cp=True)
+ assert block.with_cp
+ x = torch.randn(1, 64, 56, 56)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 64, 56, 56])
+
+ # Test Bottleneck style
+ block = Bottleneck(64, 64, stride=2, style='pytorch')
+ assert block.conv1.stride == (1, 1)
+ assert block.conv2.stride == (2, 2)
+ block = Bottleneck(64, 64, stride=2, style='caffe')
+ assert block.conv1.stride == (2, 2)
+ assert block.conv2.stride == (1, 1)
+
+ # Test Bottleneck DCN
+ dcn = dict(type='DCN', deform_groups=1, fallback_on_stride=False)
+ with pytest.raises(AssertionError):
+ Bottleneck(64, 64, dcn=dcn, conv_cfg=dict(type='Conv'))
+ block = Bottleneck(64, 64, dcn=dcn)
+ assert isinstance(block.conv2, DeformConv2dPack)
+
+ # Test Bottleneck forward
+ block = Bottleneck(64, 16)
+ x = torch.randn(1, 64, 56, 56)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 64, 56, 56])
+
+ # Test Bottleneck with 1 ContextBlock after conv3
+ plugins = [
+ dict(
+ cfg=dict(type='ContextBlock', ratio=1. / 16),
+ position='after_conv3')
+ ]
+ block = Bottleneck(64, 16, plugins=plugins)
+ assert block.context_block.in_channels == 64
+ x = torch.randn(1, 64, 56, 56)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 64, 56, 56])
+
+ # Test Bottleneck with 1 GeneralizedAttention after conv2
+ plugins = [
+ dict(
+ cfg=dict(
+ type='GeneralizedAttention',
+ spatial_range=-1,
+ num_heads=8,
+ attention_type='0010',
+ kv_stride=2),
+ position='after_conv2')
+ ]
+ block = Bottleneck(64, 16, plugins=plugins)
+ assert block.gen_attention_block.in_channels == 16
+ x = torch.randn(1, 64, 56, 56)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 64, 56, 56])
+
+ # Test Bottleneck with 1 GeneralizedAttention after conv2, 1 NonLocal2d
+ # after conv2, 1 ContextBlock after conv3
+ plugins = [
+ dict(
+ cfg=dict(
+ type='GeneralizedAttention',
+ spatial_range=-1,
+ num_heads=8,
+ attention_type='0010',
+ kv_stride=2),
+ position='after_conv2'),
+ dict(cfg=dict(type='NonLocal2d'), position='after_conv2'),
+ dict(
+ cfg=dict(type='ContextBlock', ratio=1. / 16),
+ position='after_conv3')
+ ]
+ block = Bottleneck(64, 16, plugins=plugins)
+ assert block.gen_attention_block.in_channels == 16
+ assert block.nonlocal_block.in_channels == 16
+ assert block.context_block.in_channels == 64
+ x = torch.randn(1, 64, 56, 56)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 64, 56, 56])
+
+ # Test Bottleneck with 1 ContextBlock after conv2, 2 ContextBlock after
+ # conv3
+ plugins = [
+ dict(
+ cfg=dict(type='ContextBlock', ratio=1. / 16, postfix=1),
+ position='after_conv2'),
+ dict(
+ cfg=dict(type='ContextBlock', ratio=1. / 16, postfix=2),
+ position='after_conv3'),
+ dict(
+ cfg=dict(type='ContextBlock', ratio=1. / 16, postfix=3),
+ position='after_conv3')
+ ]
+ block = Bottleneck(64, 16, plugins=plugins)
+ assert block.context_block1.in_channels == 16
+ assert block.context_block2.in_channels == 64
+ assert block.context_block3.in_channels == 64
+ x = torch.randn(1, 64, 56, 56)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 64, 56, 56])
+
+
+def test_resnet_res_layer():
+ # Test ResLayer of 3 Bottleneck w\o downsample
+ layer = ResLayer(Bottleneck, 64, 16, 3)
+ assert len(layer) == 3
+ assert layer[0].conv1.in_channels == 64
+ assert layer[0].conv1.out_channels == 16
+ for i in range(1, len(layer)):
+ assert layer[i].conv1.in_channels == 64
+ assert layer[i].conv1.out_channels == 16
+ for i in range(len(layer)):
+ assert layer[i].downsample is None
+ x = torch.randn(1, 64, 56, 56)
+ x_out = layer(x)
+ assert x_out.shape == torch.Size([1, 64, 56, 56])
+
+ # Test ResLayer of 3 Bottleneck with downsample
+ layer = ResLayer(Bottleneck, 64, 64, 3)
+ assert layer[0].downsample[0].out_channels == 256
+ for i in range(1, len(layer)):
+ assert layer[i].downsample is None
+ x = torch.randn(1, 64, 56, 56)
+ x_out = layer(x)
+ assert x_out.shape == torch.Size([1, 256, 56, 56])
+
+ # Test ResLayer of 3 Bottleneck with stride=2
+ layer = ResLayer(Bottleneck, 64, 64, 3, stride=2)
+ assert layer[0].downsample[0].out_channels == 256
+ assert layer[0].downsample[0].stride == (2, 2)
+ for i in range(1, len(layer)):
+ assert layer[i].downsample is None
+ x = torch.randn(1, 64, 56, 56)
+ x_out = layer(x)
+ assert x_out.shape == torch.Size([1, 256, 28, 28])
+
+ # Test ResLayer of 3 Bottleneck with stride=2 and average downsample
+ layer = ResLayer(Bottleneck, 64, 64, 3, stride=2, avg_down=True)
+ assert isinstance(layer[0].downsample[0], AvgPool2d)
+ assert layer[0].downsample[1].out_channels == 256
+ assert layer[0].downsample[1].stride == (1, 1)
+ for i in range(1, len(layer)):
+ assert layer[i].downsample is None
+ x = torch.randn(1, 64, 56, 56)
+ x_out = layer(x)
+ assert x_out.shape == torch.Size([1, 256, 28, 28])
+
+ # Test ResLayer of 3 Bottleneck with dilation=2
+ layer = ResLayer(Bottleneck, 64, 16, 3, dilation=2)
+ for i in range(len(layer)):
+ assert layer[i].conv2.dilation == (2, 2)
+ x = torch.randn(1, 64, 56, 56)
+ x_out = layer(x)
+ assert x_out.shape == torch.Size([1, 64, 56, 56])
+
+ # Test ResLayer of 3 Bottleneck with dilation=2, contract_dilation=True
+ layer = ResLayer(Bottleneck, 64, 16, 3, dilation=2, contract_dilation=True)
+ assert layer[0].conv2.dilation == (1, 1)
+ for i in range(1, len(layer)):
+ assert layer[i].conv2.dilation == (2, 2)
+ x = torch.randn(1, 64, 56, 56)
+ x_out = layer(x)
+ assert x_out.shape == torch.Size([1, 64, 56, 56])
+
+ # Test ResLayer of 3 Bottleneck with dilation=2, multi_grid
+ layer = ResLayer(Bottleneck, 64, 16, 3, dilation=2, multi_grid=(1, 2, 4))
+ assert layer[0].conv2.dilation == (1, 1)
+ assert layer[1].conv2.dilation == (2, 2)
+ assert layer[2].conv2.dilation == (4, 4)
+ x = torch.randn(1, 64, 56, 56)
+ x_out = layer(x)
+ assert x_out.shape == torch.Size([1, 64, 56, 56])
+
+
+def test_resnet_backbone():
+ """Test resnet backbone."""
+ with pytest.raises(KeyError):
+ # ResNet depth should be in [18, 34, 50, 101, 152]
+ ResNet(20)
+
+ with pytest.raises(AssertionError):
+ # In ResNet: 1 <= num_stages <= 4
+ ResNet(50, num_stages=0)
+
+ with pytest.raises(AssertionError):
+ # len(stage_with_dcn) == num_stages
+ dcn = dict(type='DCN', deform_groups=1, fallback_on_stride=False)
+ ResNet(50, dcn=dcn, stage_with_dcn=(True, ))
+
+ with pytest.raises(AssertionError):
+ # len(stage_with_plugin) == num_stages
+ plugins = [
+ dict(
+ cfg=dict(type='ContextBlock', ratio=1. / 16),
+ stages=(False, True, True),
+ position='after_conv3')
+ ]
+ ResNet(50, plugins=plugins)
+
+ with pytest.raises(AssertionError):
+ # In ResNet: 1 <= num_stages <= 4
+ ResNet(18, num_stages=5)
+
+ with pytest.raises(AssertionError):
+ # len(strides) == len(dilations) == num_stages
+ ResNet(18, strides=(1, ), dilations=(1, 1), num_stages=3)
+
+ with pytest.raises(TypeError):
+ # pretrained must be a string path
+ model = ResNet(18, pretrained=0)
+ model.init_weights()
+
+ with pytest.raises(AssertionError):
+ # Style must be in ['pytorch', 'caffe']
+ ResNet(50, style='tensorflow')
+
+ # Test ResNet18 norm_eval=True
+ model = ResNet(18, norm_eval=True)
+ model.init_weights()
+ model.train()
+ assert check_norm_state(model.modules(), False)
+
+ # Test ResNet18 with torchvision pretrained weight
+ model = ResNet(
+ depth=18, norm_eval=True, pretrained='torchvision://resnet18')
+ model.init_weights()
+ model.train()
+ assert check_norm_state(model.modules(), False)
+
+ # Test ResNet18 with first stage frozen
+ frozen_stages = 1
+ model = ResNet(18, frozen_stages=frozen_stages)
+ model.init_weights()
+ model.train()
+ assert model.norm1.training is False
+ for layer in [model.conv1, model.norm1]:
+ for param in layer.parameters():
+ assert param.requires_grad is False
+ for i in range(1, frozen_stages + 1):
+ layer = getattr(model, 'layer{}'.format(i))
+ for mod in layer.modules():
+ if isinstance(mod, _BatchNorm):
+ assert mod.training is False
+ for param in layer.parameters():
+ assert param.requires_grad is False
+
+ # Test ResNet18V1d with first stage frozen
+ model = ResNetV1d(depth=18, frozen_stages=frozen_stages)
+ assert len(model.stem) == 9
+ model.init_weights()
+ model.train()
+ check_norm_state(model.stem, False)
+ for param in model.stem.parameters():
+ assert param.requires_grad is False
+ for i in range(1, frozen_stages + 1):
+ layer = getattr(model, 'layer{}'.format(i))
+ for mod in layer.modules():
+ if isinstance(mod, _BatchNorm):
+ assert mod.training is False
+ for param in layer.parameters():
+ assert param.requires_grad is False
+
+ # Test ResNet18 forward
+ model = ResNet(18)
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert len(feat) == 4
+ assert feat[0].shape == torch.Size([1, 64, 56, 56])
+ assert feat[1].shape == torch.Size([1, 128, 28, 28])
+ assert feat[2].shape == torch.Size([1, 256, 14, 14])
+ assert feat[3].shape == torch.Size([1, 512, 7, 7])
+
+ # Test ResNet18 with BatchNorm forward
+ model = ResNet(18)
+ for m in model.modules():
+ if is_norm(m):
+ assert isinstance(m, _BatchNorm)
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert len(feat) == 4
+ assert feat[0].shape == torch.Size([1, 64, 56, 56])
+ assert feat[1].shape == torch.Size([1, 128, 28, 28])
+ assert feat[2].shape == torch.Size([1, 256, 14, 14])
+ assert feat[3].shape == torch.Size([1, 512, 7, 7])
+
+ # Test ResNet18 with layers 1, 2, 3 out forward
+ model = ResNet(18, out_indices=(0, 1, 2))
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(1, 3, 112, 112)
+ feat = model(imgs)
+ assert len(feat) == 3
+ assert feat[0].shape == torch.Size([1, 64, 28, 28])
+ assert feat[1].shape == torch.Size([1, 128, 14, 14])
+ assert feat[2].shape == torch.Size([1, 256, 7, 7])
+
+ # Test ResNet18 with checkpoint forward
+ model = ResNet(18, with_cp=True)
+ for m in model.modules():
+ if is_block(m):
+ assert m.with_cp
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert len(feat) == 4
+ assert feat[0].shape == torch.Size([1, 64, 56, 56])
+ assert feat[1].shape == torch.Size([1, 128, 28, 28])
+ assert feat[2].shape == torch.Size([1, 256, 14, 14])
+ assert feat[3].shape == torch.Size([1, 512, 7, 7])
+
+ # Test ResNet18 with checkpoint forward
+ model = ResNet(18, with_cp=True)
+ for m in model.modules():
+ if is_block(m):
+ assert m.with_cp
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert len(feat) == 4
+ assert feat[0].shape == torch.Size([1, 64, 56, 56])
+ assert feat[1].shape == torch.Size([1, 128, 28, 28])
+ assert feat[2].shape == torch.Size([1, 256, 14, 14])
+ assert feat[3].shape == torch.Size([1, 512, 7, 7])
+
+ # Test ResNet18 with GroupNorm forward
+ model = ResNet(
+ 18, norm_cfg=dict(type='GN', num_groups=32, requires_grad=True))
+ for m in model.modules():
+ if is_norm(m):
+ assert isinstance(m, GroupNorm)
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert len(feat) == 4
+ assert feat[0].shape == torch.Size([1, 64, 56, 56])
+ assert feat[1].shape == torch.Size([1, 128, 28, 28])
+ assert feat[2].shape == torch.Size([1, 256, 14, 14])
+ assert feat[3].shape == torch.Size([1, 512, 7, 7])
+
+ # Test ResNet50 with 1 GeneralizedAttention after conv2, 1 NonLocal2d
+ # after conv2, 1 ContextBlock after conv3 in layers 2, 3, 4
+ plugins = [
+ dict(
+ cfg=dict(
+ type='GeneralizedAttention',
+ spatial_range=-1,
+ num_heads=8,
+ attention_type='0010',
+ kv_stride=2),
+ stages=(False, True, True, True),
+ position='after_conv2'),
+ dict(cfg=dict(type='NonLocal2d'), position='after_conv2'),
+ dict(
+ cfg=dict(type='ContextBlock', ratio=1. / 16),
+ stages=(False, True, True, False),
+ position='after_conv3')
+ ]
+ model = ResNet(50, plugins=plugins)
+ for m in model.layer1.modules():
+ if is_block(m):
+ assert not hasattr(m, 'context_block')
+ assert not hasattr(m, 'gen_attention_block')
+ assert m.nonlocal_block.in_channels == 64
+ for m in model.layer2.modules():
+ if is_block(m):
+ assert m.nonlocal_block.in_channels == 128
+ assert m.gen_attention_block.in_channels == 128
+ assert m.context_block.in_channels == 512
+
+ for m in model.layer3.modules():
+ if is_block(m):
+ assert m.nonlocal_block.in_channels == 256
+ assert m.gen_attention_block.in_channels == 256
+ assert m.context_block.in_channels == 1024
+
+ for m in model.layer4.modules():
+ if is_block(m):
+ assert m.nonlocal_block.in_channels == 512
+ assert m.gen_attention_block.in_channels == 512
+ assert not hasattr(m, 'context_block')
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert len(feat) == 4
+ assert feat[0].shape == torch.Size([1, 256, 56, 56])
+ assert feat[1].shape == torch.Size([1, 512, 28, 28])
+ assert feat[2].shape == torch.Size([1, 1024, 14, 14])
+ assert feat[3].shape == torch.Size([1, 2048, 7, 7])
+
+ # Test ResNet50 with 1 ContextBlock after conv2, 1 ContextBlock after
+ # conv3 in layers 2, 3, 4
+ plugins = [
+ dict(
+ cfg=dict(type='ContextBlock', ratio=1. / 16, postfix=1),
+ stages=(False, True, True, False),
+ position='after_conv3'),
+ dict(
+ cfg=dict(type='ContextBlock', ratio=1. / 16, postfix=2),
+ stages=(False, True, True, False),
+ position='after_conv3')
+ ]
+
+ model = ResNet(50, plugins=plugins)
+ for m in model.layer1.modules():
+ if is_block(m):
+ assert not hasattr(m, 'context_block')
+ assert not hasattr(m, 'context_block1')
+ assert not hasattr(m, 'context_block2')
+ for m in model.layer2.modules():
+ if is_block(m):
+ assert not hasattr(m, 'context_block')
+ assert m.context_block1.in_channels == 512
+ assert m.context_block2.in_channels == 512
+
+ for m in model.layer3.modules():
+ if is_block(m):
+ assert not hasattr(m, 'context_block')
+ assert m.context_block1.in_channels == 1024
+ assert m.context_block2.in_channels == 1024
+
+ for m in model.layer4.modules():
+ if is_block(m):
+ assert not hasattr(m, 'context_block')
+ assert not hasattr(m, 'context_block1')
+ assert not hasattr(m, 'context_block2')
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert len(feat) == 4
+ assert feat[0].shape == torch.Size([1, 256, 56, 56])
+ assert feat[1].shape == torch.Size([1, 512, 28, 28])
+ assert feat[2].shape == torch.Size([1, 1024, 14, 14])
+ assert feat[3].shape == torch.Size([1, 2048, 7, 7])
+
+ # Test ResNet18 zero initialization of residual
+ model = ResNet(18, zero_init_residual=True)
+ model.init_weights()
+ for m in model.modules():
+ if isinstance(m, Bottleneck):
+ assert all_zeros(m.norm3)
+ elif isinstance(m, BasicBlock):
+ assert all_zeros(m.norm2)
+ model.train()
+
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert len(feat) == 4
+ assert feat[0].shape == torch.Size([1, 64, 56, 56])
+ assert feat[1].shape == torch.Size([1, 128, 28, 28])
+ assert feat[2].shape == torch.Size([1, 256, 14, 14])
+ assert feat[3].shape == torch.Size([1, 512, 7, 7])
+
+ # Test ResNetV1d forward
+ model = ResNetV1d(depth=18)
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert len(feat) == 4
+ assert feat[0].shape == torch.Size([1, 64, 56, 56])
+ assert feat[1].shape == torch.Size([1, 128, 28, 28])
+ assert feat[2].shape == torch.Size([1, 256, 14, 14])
+ assert feat[3].shape == torch.Size([1, 512, 7, 7])
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_resnext.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_resnext.py
new file mode 100644
index 0000000000000000000000000000000000000000..2aecaf0d3d4c22d79654df26f088bdcbb5ec376e
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_resnext.py
@@ -0,0 +1,62 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.backbones import ResNeXt
+from mmseg.models.backbones.resnext import Bottleneck as BottleneckX
+from .utils import is_block
+
+
+def test_renext_bottleneck():
+ with pytest.raises(AssertionError):
+ # Style must be in ['pytorch', 'caffe']
+ BottleneckX(64, 64, groups=32, base_width=4, style='tensorflow')
+
+ # Test ResNeXt Bottleneck structure
+ block = BottleneckX(
+ 64, 64, groups=32, base_width=4, stride=2, style='pytorch')
+ assert block.conv2.stride == (2, 2)
+ assert block.conv2.groups == 32
+ assert block.conv2.out_channels == 128
+
+ # Test ResNeXt Bottleneck with DCN
+ dcn = dict(type='DCN', deform_groups=1, fallback_on_stride=False)
+ with pytest.raises(AssertionError):
+ # conv_cfg must be None if dcn is not None
+ BottleneckX(
+ 64,
+ 64,
+ groups=32,
+ base_width=4,
+ dcn=dcn,
+ conv_cfg=dict(type='Conv'))
+ BottleneckX(64, 64, dcn=dcn)
+
+ # Test ResNeXt Bottleneck forward
+ block = BottleneckX(64, 16, groups=32, base_width=4)
+ x = torch.randn(1, 64, 56, 56)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 64, 56, 56])
+
+
+def test_resnext_backbone():
+ with pytest.raises(KeyError):
+ # ResNeXt depth should be in [50, 101, 152]
+ ResNeXt(depth=18)
+
+ # Test ResNeXt with group 32, base_width 4
+ model = ResNeXt(depth=50, groups=32, base_width=4)
+ print(model)
+ for m in model.modules():
+ if is_block(m):
+ assert m.conv2.groups == 32
+ model.init_weights()
+ model.train()
+
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert len(feat) == 4
+ assert feat[0].shape == torch.Size([1, 256, 56, 56])
+ assert feat[1].shape == torch.Size([1, 512, 28, 28])
+ assert feat[2].shape == torch.Size([1, 1024, 14, 14])
+ assert feat[3].shape == torch.Size([1, 2048, 7, 7])
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_stdc.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_stdc.py
new file mode 100644
index 0000000000000000000000000000000000000000..1e3862b0b387e6f84edb4f6edca5e8d0db36dbdc
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_stdc.py
@@ -0,0 +1,131 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.backbones import STDCContextPathNet
+from mmseg.models.backbones.stdc import (AttentionRefinementModule,
+ FeatureFusionModule, STDCModule,
+ STDCNet)
+
+
+def test_stdc_context_path_net():
+ # Test STDCContextPathNet Standard Forward
+ model = STDCContextPathNet(
+ backbone_cfg=dict(
+ type='STDCNet',
+ stdc_type='STDCNet1',
+ in_channels=3,
+ channels=(32, 64, 256, 512, 1024),
+ bottleneck_type='cat',
+ num_convs=4,
+ norm_cfg=dict(type='BN', requires_grad=True),
+ act_cfg=dict(type='ReLU'),
+ with_final_conv=True),
+ last_in_channels=(1024, 512),
+ out_channels=128,
+ ffm_cfg=dict(in_channels=384, out_channels=256, scale_factor=4))
+ model.init_weights()
+ model.train()
+ batch_size = 2
+ imgs = torch.randn(batch_size, 3, 256, 512)
+ feat = model(imgs)
+
+ assert len(feat) == 4
+ # output for segment Head
+ assert feat[0].shape == torch.Size([batch_size, 256, 32, 64])
+ # for auxiliary head 1
+ assert feat[1].shape == torch.Size([batch_size, 128, 16, 32])
+ # for auxiliary head 2
+ assert feat[2].shape == torch.Size([batch_size, 128, 32, 64])
+ # for auxiliary head 3
+ assert feat[3].shape == torch.Size([batch_size, 256, 32, 64])
+
+ # Test input with rare shape
+ batch_size = 2
+ imgs = torch.randn(batch_size, 3, 527, 279)
+ model = STDCContextPathNet(
+ backbone_cfg=dict(
+ type='STDCNet',
+ stdc_type='STDCNet1',
+ in_channels=3,
+ channels=(32, 64, 256, 512, 1024),
+ bottleneck_type='add',
+ num_convs=4,
+ norm_cfg=dict(type='BN', requires_grad=True),
+ act_cfg=dict(type='ReLU'),
+ with_final_conv=False),
+ last_in_channels=(1024, 512),
+ out_channels=128,
+ ffm_cfg=dict(in_channels=384, out_channels=256, scale_factor=4))
+ model.init_weights()
+ model.train()
+ feat = model(imgs)
+ assert len(feat) == 4
+
+
+def test_stdcnet():
+ with pytest.raises(AssertionError):
+ # STDC backbone constraints.
+ STDCNet(
+ stdc_type='STDCNet3',
+ in_channels=3,
+ channels=(32, 64, 256, 512, 1024),
+ bottleneck_type='cat',
+ num_convs=4,
+ norm_cfg=dict(type='BN', requires_grad=True),
+ act_cfg=dict(type='ReLU'),
+ with_final_conv=False)
+
+ with pytest.raises(AssertionError):
+ # STDC bottleneck type constraints.
+ STDCNet(
+ stdc_type='STDCNet1',
+ in_channels=3,
+ channels=(32, 64, 256, 512, 1024),
+ bottleneck_type='dog',
+ num_convs=4,
+ norm_cfg=dict(type='BN', requires_grad=True),
+ act_cfg=dict(type='ReLU'),
+ with_final_conv=False)
+
+ with pytest.raises(AssertionError):
+ # STDC channels length constraints.
+ STDCNet(
+ stdc_type='STDCNet1',
+ in_channels=3,
+ channels=(16, 32, 64, 256, 512, 1024),
+ bottleneck_type='cat',
+ num_convs=4,
+ norm_cfg=dict(type='BN', requires_grad=True),
+ act_cfg=dict(type='ReLU'),
+ with_final_conv=False)
+
+
+def test_feature_fusion_module():
+ x_ffm = FeatureFusionModule(in_channels=64, out_channels=32)
+ assert x_ffm.conv0.in_channels == 64
+ assert x_ffm.attention[1].in_channels == 32
+ assert x_ffm.attention[2].in_channels == 8
+ assert x_ffm.attention[2].out_channels == 32
+ x1 = torch.randn(2, 32, 32, 64)
+ x2 = torch.randn(2, 32, 32, 64)
+ x_out = x_ffm(x1, x2)
+ assert x_out.shape == torch.Size([2, 32, 32, 64])
+
+
+def test_attention_refinement_module():
+ x_arm = AttentionRefinementModule(128, 32)
+ assert x_arm.conv_layer.in_channels == 128
+ assert x_arm.atten_conv_layer[1].conv.out_channels == 32
+ x = torch.randn(2, 128, 32, 64)
+ x_out = x_arm(x)
+ assert x_out.shape == torch.Size([2, 32, 32, 64])
+
+
+def test_stdc_module():
+ x_stdc = STDCModule(in_channels=32, out_channels=32, stride=4)
+ assert x_stdc.layers[0].conv.in_channels == 32
+ assert x_stdc.layers[3].conv.out_channels == 4
+ x = torch.randn(2, 32, 32, 64)
+ x_out = x_stdc(x)
+ assert x_out.shape == torch.Size([2, 32, 32, 64])
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_swin.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_swin.py
new file mode 100644
index 0000000000000000000000000000000000000000..8d14d47ab584b3eead28a6d777dfabbd59b33ba8
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_swin.py
@@ -0,0 +1,100 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.backbones.swin import SwinBlock, SwinTransformer
+
+
+def test_swin_block():
+ # test SwinBlock structure and forward
+ block = SwinBlock(embed_dims=32, num_heads=4, feedforward_channels=128)
+ assert block.ffn.embed_dims == 32
+ assert block.attn.w_msa.num_heads == 4
+ assert block.ffn.feedforward_channels == 128
+ x = torch.randn(1, 56 * 56, 32)
+ x_out = block(x, (56, 56))
+ assert x_out.shape == torch.Size([1, 56 * 56, 32])
+
+ # Test BasicBlock with checkpoint forward
+ block = SwinBlock(
+ embed_dims=64, num_heads=4, feedforward_channels=256, with_cp=True)
+ assert block.with_cp
+ x = torch.randn(1, 56 * 56, 64)
+ x_out = block(x, (56, 56))
+ assert x_out.shape == torch.Size([1, 56 * 56, 64])
+
+
+def test_swin_transformer():
+ """Test Swin Transformer backbone."""
+
+ with pytest.raises(TypeError):
+ # Pretrained arg must be str or None.
+ SwinTransformer(pretrained=123)
+
+ with pytest.raises(AssertionError):
+ # Because swin uses non-overlapping patch embed, so the stride of patch
+ # embed must be equal to patch size.
+ SwinTransformer(strides=(2, 2, 2, 2), patch_size=4)
+
+ # test pretrained image size
+ with pytest.raises(AssertionError):
+ SwinTransformer(pretrain_img_size=(112, 112, 112))
+
+ # Test absolute position embedding
+ temp = torch.randn((1, 3, 112, 112))
+ model = SwinTransformer(pretrain_img_size=112, use_abs_pos_embed=True)
+ model.init_weights()
+ model(temp)
+
+ # Test patch norm
+ model = SwinTransformer(patch_norm=False)
+ model(temp)
+
+ # Test normal inference
+ temp = torch.randn((1, 3, 256, 256))
+ model = SwinTransformer()
+ outs = model(temp)
+ assert outs[0].shape == (1, 96, 64, 64)
+ assert outs[1].shape == (1, 192, 32, 32)
+ assert outs[2].shape == (1, 384, 16, 16)
+ assert outs[3].shape == (1, 768, 8, 8)
+
+ # Test abnormal inference size
+ temp = torch.randn((1, 3, 255, 255))
+ model = SwinTransformer()
+ outs = model(temp)
+ assert outs[0].shape == (1, 96, 64, 64)
+ assert outs[1].shape == (1, 192, 32, 32)
+ assert outs[2].shape == (1, 384, 16, 16)
+ assert outs[3].shape == (1, 768, 8, 8)
+
+ # Test abnormal inference size
+ temp = torch.randn((1, 3, 112, 137))
+ model = SwinTransformer()
+ outs = model(temp)
+ assert outs[0].shape == (1, 96, 28, 35)
+ assert outs[1].shape == (1, 192, 14, 18)
+ assert outs[2].shape == (1, 384, 7, 9)
+ assert outs[3].shape == (1, 768, 4, 5)
+
+ # Test frozen
+ model = SwinTransformer(frozen_stages=4)
+ model.train()
+ for p in model.parameters():
+ assert not p.requires_grad
+
+ # Test absolute position embedding frozen
+ model = SwinTransformer(frozen_stages=4, use_abs_pos_embed=True)
+ model.train()
+ for p in model.parameters():
+ assert not p.requires_grad
+
+ # Test Swin with checkpoint forward
+ temp = torch.randn((1, 3, 56, 56))
+ model = SwinTransformer(with_cp=True)
+ for m in model.modules():
+ if isinstance(m, SwinBlock):
+ assert m.with_cp
+ model.init_weights()
+ model.train()
+ model(temp)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_timm_backbone.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_timm_backbone.py
new file mode 100644
index 0000000000000000000000000000000000000000..85ef9aa56ff3c70d8c3fb74fb00b75cc2c8c522f
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_timm_backbone.py
@@ -0,0 +1,133 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.backbones import TIMMBackbone
+from .utils import check_norm_state
+
+
+def test_timm_backbone():
+ with pytest.raises(TypeError):
+ # pretrained must be a string path
+ model = TIMMBackbone()
+ model.init_weights(pretrained=0)
+
+ # Test different norm_layer, can be: 'SyncBN', 'BN2d', 'GN', 'LN', 'IN'
+ # Test resnet18 from timm, norm_layer='BN2d'
+ model = TIMMBackbone(
+ model_name='resnet18',
+ features_only=True,
+ pretrained=False,
+ output_stride=32,
+ norm_layer='BN2d')
+
+ # Test resnet18 from timm, norm_layer='SyncBN'
+ model = TIMMBackbone(
+ model_name='resnet18',
+ features_only=True,
+ pretrained=False,
+ output_stride=32,
+ norm_layer='SyncBN')
+
+ # Test resnet18 from timm, features_only=True, output_stride=32
+ model = TIMMBackbone(
+ model_name='resnet18',
+ features_only=True,
+ pretrained=False,
+ output_stride=32)
+ model.init_weights()
+ model.train()
+ assert check_norm_state(model.modules(), True)
+
+ imgs = torch.randn(1, 3, 224, 224)
+ feats = model(imgs)
+ feats = [feat.shape for feat in feats]
+ assert len(feats) == 5
+ assert feats[0] == torch.Size((1, 64, 112, 112))
+ assert feats[1] == torch.Size((1, 64, 56, 56))
+ assert feats[2] == torch.Size((1, 128, 28, 28))
+ assert feats[3] == torch.Size((1, 256, 14, 14))
+ assert feats[4] == torch.Size((1, 512, 7, 7))
+
+ # Test resnet18 from timm, features_only=True, output_stride=16
+ model = TIMMBackbone(
+ model_name='resnet18',
+ features_only=True,
+ pretrained=False,
+ output_stride=16)
+ imgs = torch.randn(1, 3, 224, 224)
+ feats = model(imgs)
+ feats = [feat.shape for feat in feats]
+ assert len(feats) == 5
+ assert feats[0] == torch.Size((1, 64, 112, 112))
+ assert feats[1] == torch.Size((1, 64, 56, 56))
+ assert feats[2] == torch.Size((1, 128, 28, 28))
+ assert feats[3] == torch.Size((1, 256, 14, 14))
+ assert feats[4] == torch.Size((1, 512, 14, 14))
+
+ # Test resnet18 from timm, features_only=True, output_stride=8
+ model = TIMMBackbone(
+ model_name='resnet18',
+ features_only=True,
+ pretrained=False,
+ output_stride=8)
+ imgs = torch.randn(1, 3, 224, 224)
+ feats = model(imgs)
+ feats = [feat.shape for feat in feats]
+ assert len(feats) == 5
+ assert feats[0] == torch.Size((1, 64, 112, 112))
+ assert feats[1] == torch.Size((1, 64, 56, 56))
+ assert feats[2] == torch.Size((1, 128, 28, 28))
+ assert feats[3] == torch.Size((1, 256, 28, 28))
+ assert feats[4] == torch.Size((1, 512, 28, 28))
+
+ # Test efficientnet_b1 with pretrained weights
+ model = TIMMBackbone(model_name='efficientnet_b1', pretrained=True)
+
+ # Test resnetv2_50x1_bitm from timm, features_only=True, output_stride=8
+ model = TIMMBackbone(
+ model_name='resnetv2_50x1_bitm',
+ features_only=True,
+ pretrained=False,
+ output_stride=8)
+ imgs = torch.randn(1, 3, 8, 8)
+ feats = model(imgs)
+ feats = [feat.shape for feat in feats]
+ assert len(feats) == 5
+ assert feats[0] == torch.Size((1, 64, 4, 4))
+ assert feats[1] == torch.Size((1, 256, 2, 2))
+ assert feats[2] == torch.Size((1, 512, 1, 1))
+ assert feats[3] == torch.Size((1, 1024, 1, 1))
+ assert feats[4] == torch.Size((1, 2048, 1, 1))
+
+ # Test resnetv2_50x3_bitm from timm, features_only=True, output_stride=8
+ model = TIMMBackbone(
+ model_name='resnetv2_50x3_bitm',
+ features_only=True,
+ pretrained=False,
+ output_stride=8)
+ imgs = torch.randn(1, 3, 8, 8)
+ feats = model(imgs)
+ feats = [feat.shape for feat in feats]
+ assert len(feats) == 5
+ assert feats[0] == torch.Size((1, 192, 4, 4))
+ assert feats[1] == torch.Size((1, 768, 2, 2))
+ assert feats[2] == torch.Size((1, 1536, 1, 1))
+ assert feats[3] == torch.Size((1, 3072, 1, 1))
+ assert feats[4] == torch.Size((1, 6144, 1, 1))
+
+ # Test resnetv2_101x1_bitm from timm, features_only=True, output_stride=8
+ model = TIMMBackbone(
+ model_name='resnetv2_101x1_bitm',
+ features_only=True,
+ pretrained=False,
+ output_stride=8)
+ imgs = torch.randn(1, 3, 8, 8)
+ feats = model(imgs)
+ feats = [feat.shape for feat in feats]
+ assert len(feats) == 5
+ assert feats[0] == torch.Size((1, 64, 4, 4))
+ assert feats[1] == torch.Size((1, 256, 2, 2))
+ assert feats[2] == torch.Size((1, 512, 1, 1))
+ assert feats[3] == torch.Size((1, 1024, 1, 1))
+ assert feats[4] == torch.Size((1, 2048, 1, 1))
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_twins.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_twins.py
new file mode 100644
index 0000000000000000000000000000000000000000..aa3eaf9f45bb1097c5c90ec450d17638b68f5624
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_twins.py
@@ -0,0 +1,171 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.backbones.twins import (PCPVT, SVT,
+ ConditionalPositionEncoding,
+ LocallyGroupedSelfAttention)
+
+
+def test_pcpvt():
+ # Test normal input
+ H, W = (224, 224)
+ temp = torch.randn((1, 3, H, W))
+ model = PCPVT(
+ embed_dims=[32, 64, 160, 256],
+ num_heads=[1, 2, 5, 8],
+ mlp_ratios=[8, 8, 4, 4],
+ qkv_bias=True,
+ depths=[3, 4, 6, 3],
+ sr_ratios=[8, 4, 2, 1],
+ norm_after_stage=False)
+ model.init_weights()
+ outs = model(temp)
+ assert outs[0].shape == (1, 32, H // 4, W // 4)
+ assert outs[1].shape == (1, 64, H // 8, W // 8)
+ assert outs[2].shape == (1, 160, H // 16, W // 16)
+ assert outs[3].shape == (1, 256, H // 32, W // 32)
+
+
+def test_svt():
+ # Test normal input
+ H, W = (224, 224)
+ temp = torch.randn((1, 3, H, W))
+ model = SVT(
+ embed_dims=[32, 64, 128],
+ num_heads=[1, 2, 4],
+ mlp_ratios=[4, 4, 4],
+ qkv_bias=False,
+ depths=[4, 4, 4],
+ windiow_sizes=[7, 7, 7],
+ norm_after_stage=True)
+
+ model.init_weights()
+ outs = model(temp)
+ assert outs[0].shape == (1, 32, H // 4, W // 4)
+ assert outs[1].shape == (1, 64, H // 8, W // 8)
+ assert outs[2].shape == (1, 128, H // 16, W // 16)
+
+
+def test_svt_init():
+ path = 'PATH_THAT_DO_NOT_EXIST'
+ # Test all combinations of pretrained and init_cfg
+ # pretrained=None, init_cfg=None
+ model = SVT(pretrained=None, init_cfg=None)
+ assert model.init_cfg is None
+ model.init_weights()
+
+ # pretrained=None
+ # init_cfg loads pretrain from an non-existent file
+ model = SVT(
+ pretrained=None, init_cfg=dict(type='Pretrained', checkpoint=path))
+ assert model.init_cfg == dict(type='Pretrained', checkpoint=path)
+ # Test loading a checkpoint from an non-existent file
+ with pytest.raises(OSError):
+ model.init_weights()
+
+ # pretrained=None
+ # init_cfg=123, whose type is unsupported
+ model = SVT(pretrained=None, init_cfg=123)
+ with pytest.raises(TypeError):
+ model.init_weights()
+
+ # pretrained loads pretrain from an non-existent file
+ # init_cfg=None
+ model = SVT(pretrained=path, init_cfg=None)
+ assert model.init_cfg == dict(type='Pretrained', checkpoint=path)
+ # Test loading a checkpoint from an non-existent file
+ with pytest.raises(OSError):
+ model.init_weights()
+
+ # pretrained loads pretrain from an non-existent file
+ # init_cfg loads pretrain from an non-existent file
+ with pytest.raises(AssertionError):
+ model = SVT(
+ pretrained=path, init_cfg=dict(type='Pretrained', checkpoint=path))
+ with pytest.raises(AssertionError):
+ model = SVT(pretrained=path, init_cfg=123)
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg=None
+ with pytest.raises(TypeError):
+ model = SVT(pretrained=123, init_cfg=None)
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg loads pretrain from an non-existent file
+ with pytest.raises(AssertionError):
+ model = SVT(
+ pretrained=123, init_cfg=dict(type='Pretrained', checkpoint=path))
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg=123, whose type is unsupported
+ with pytest.raises(AssertionError):
+ model = SVT(pretrained=123, init_cfg=123)
+
+
+def test_pcpvt_init():
+ path = 'PATH_THAT_DO_NOT_EXIST'
+ # Test all combinations of pretrained and init_cfg
+ # pretrained=None, init_cfg=None
+ model = PCPVT(pretrained=None, init_cfg=None)
+ assert model.init_cfg is None
+ model.init_weights()
+
+ # pretrained=None
+ # init_cfg loads pretrain from an non-existent file
+ model = PCPVT(
+ pretrained=None, init_cfg=dict(type='Pretrained', checkpoint=path))
+ assert model.init_cfg == dict(type='Pretrained', checkpoint=path)
+ # Test loading a checkpoint from an non-existent file
+ with pytest.raises(OSError):
+ model.init_weights()
+
+ # pretrained=None
+ # init_cfg=123, whose type is unsupported
+ model = PCPVT(pretrained=None, init_cfg=123)
+ with pytest.raises(TypeError):
+ model.init_weights()
+
+ # pretrained loads pretrain from an non-existent file
+ # init_cfg=None
+ model = PCPVT(pretrained=path, init_cfg=None)
+ assert model.init_cfg == dict(type='Pretrained', checkpoint=path)
+ # Test loading a checkpoint from an non-existent file
+ with pytest.raises(OSError):
+ model.init_weights()
+
+ # pretrained loads pretrain from an non-existent file
+ # init_cfg loads pretrain from an non-existent file
+ with pytest.raises(AssertionError):
+ model = PCPVT(
+ pretrained=path, init_cfg=dict(type='Pretrained', checkpoint=path))
+ with pytest.raises(AssertionError):
+ model = PCPVT(pretrained=path, init_cfg=123)
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg=None
+ with pytest.raises(TypeError):
+ model = PCPVT(pretrained=123, init_cfg=None)
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg loads pretrain from an non-existent file
+ with pytest.raises(AssertionError):
+ model = PCPVT(
+ pretrained=123, init_cfg=dict(type='Pretrained', checkpoint=path))
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg=123, whose type is unsupported
+ with pytest.raises(AssertionError):
+ model = PCPVT(pretrained=123, init_cfg=123)
+
+
+def test_locallygrouped_self_attention_module():
+ LSA = LocallyGroupedSelfAttention(embed_dims=32, window_size=3)
+ outs = LSA(torch.randn(1, 3136, 32), (56, 56))
+ assert outs.shape == torch.Size([1, 3136, 32])
+
+
+def test_conditional_position_encoding_module():
+ CPE = ConditionalPositionEncoding(in_channels=32, embed_dims=32, stride=2)
+ outs = CPE(torch.randn(1, 3136, 32), (56, 56))
+ assert outs.shape == torch.Size([1, 784, 32])
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_unet.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_unet.py
new file mode 100644
index 0000000000000000000000000000000000000000..9beb7279a0f219518aa4efd2755c5fefc0d6e02c
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_unet.py
@@ -0,0 +1,822 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+from mmcv.cnn import ConvModule
+
+from mmseg.models.backbones.unet import (BasicConvBlock, DeconvModule,
+ InterpConv, UNet, UpConvBlock)
+from mmseg.ops import Upsample
+from .utils import check_norm_state
+
+
+def test_unet_basic_conv_block():
+ with pytest.raises(AssertionError):
+ # Not implemented yet.
+ dcn = dict(type='DCN', deform_groups=1, fallback_on_stride=False)
+ BasicConvBlock(64, 64, dcn=dcn)
+
+ with pytest.raises(AssertionError):
+ # Not implemented yet.
+ plugins = [
+ dict(
+ cfg=dict(type='ContextBlock', ratio=1. / 16),
+ position='after_conv3')
+ ]
+ BasicConvBlock(64, 64, plugins=plugins)
+
+ with pytest.raises(AssertionError):
+ # Not implemented yet
+ plugins = [
+ dict(
+ cfg=dict(
+ type='GeneralizedAttention',
+ spatial_range=-1,
+ num_heads=8,
+ attention_type='0010',
+ kv_stride=2),
+ position='after_conv2')
+ ]
+ BasicConvBlock(64, 64, plugins=plugins)
+
+ # test BasicConvBlock with checkpoint forward
+ block = BasicConvBlock(16, 16, with_cp=True)
+ assert block.with_cp
+ x = torch.randn(1, 16, 64, 64, requires_grad=True)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 16, 64, 64])
+
+ block = BasicConvBlock(16, 16, with_cp=False)
+ assert not block.with_cp
+ x = torch.randn(1, 16, 64, 64)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 16, 64, 64])
+
+ # test BasicConvBlock with stride convolution to downsample
+ block = BasicConvBlock(16, 16, stride=2)
+ x = torch.randn(1, 16, 64, 64)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 16, 32, 32])
+
+ # test BasicConvBlock structure and forward
+ block = BasicConvBlock(16, 64, num_convs=3, dilation=3)
+ assert block.convs[0].conv.in_channels == 16
+ assert block.convs[0].conv.out_channels == 64
+ assert block.convs[0].conv.kernel_size == (3, 3)
+ assert block.convs[0].conv.dilation == (1, 1)
+ assert block.convs[0].conv.padding == (1, 1)
+
+ assert block.convs[1].conv.in_channels == 64
+ assert block.convs[1].conv.out_channels == 64
+ assert block.convs[1].conv.kernel_size == (3, 3)
+ assert block.convs[1].conv.dilation == (3, 3)
+ assert block.convs[1].conv.padding == (3, 3)
+
+ assert block.convs[2].conv.in_channels == 64
+ assert block.convs[2].conv.out_channels == 64
+ assert block.convs[2].conv.kernel_size == (3, 3)
+ assert block.convs[2].conv.dilation == (3, 3)
+ assert block.convs[2].conv.padding == (3, 3)
+
+
+def test_deconv_module():
+ with pytest.raises(AssertionError):
+ # kernel_size should be greater than or equal to scale_factor and
+ # (kernel_size - scale_factor) should be even numbers
+ DeconvModule(64, 32, kernel_size=1, scale_factor=2)
+
+ with pytest.raises(AssertionError):
+ # kernel_size should be greater than or equal to scale_factor and
+ # (kernel_size - scale_factor) should be even numbers
+ DeconvModule(64, 32, kernel_size=3, scale_factor=2)
+
+ with pytest.raises(AssertionError):
+ # kernel_size should be greater than or equal to scale_factor and
+ # (kernel_size - scale_factor) should be even numbers
+ DeconvModule(64, 32, kernel_size=5, scale_factor=4)
+
+ # test DeconvModule with checkpoint forward and upsample 2X.
+ block = DeconvModule(64, 32, with_cp=True)
+ assert block.with_cp
+ x = torch.randn(1, 64, 128, 128, requires_grad=True)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 32, 256, 256])
+
+ block = DeconvModule(64, 32, with_cp=False)
+ assert not block.with_cp
+ x = torch.randn(1, 64, 128, 128)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 32, 256, 256])
+
+ # test DeconvModule with different kernel size for upsample 2X.
+ x = torch.randn(1, 64, 64, 64)
+ block = DeconvModule(64, 32, kernel_size=2, scale_factor=2)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 32, 128, 128])
+
+ block = DeconvModule(64, 32, kernel_size=6, scale_factor=2)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 32, 128, 128])
+
+ # test DeconvModule with different kernel size for upsample 4X.
+ x = torch.randn(1, 64, 64, 64)
+ block = DeconvModule(64, 32, kernel_size=4, scale_factor=4)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 32, 256, 256])
+
+ block = DeconvModule(64, 32, kernel_size=6, scale_factor=4)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 32, 256, 256])
+
+
+def test_interp_conv():
+ # test InterpConv with checkpoint forward and upsample 2X.
+ block = InterpConv(64, 32, with_cp=True)
+ assert block.with_cp
+ x = torch.randn(1, 64, 128, 128, requires_grad=True)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 32, 256, 256])
+
+ block = InterpConv(64, 32, with_cp=False)
+ assert not block.with_cp
+ x = torch.randn(1, 64, 128, 128)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 32, 256, 256])
+
+ # test InterpConv with conv_first=False for upsample 2X.
+ block = InterpConv(64, 32, conv_first=False)
+ x = torch.randn(1, 64, 128, 128)
+ x_out = block(x)
+ assert isinstance(block.interp_upsample[0], Upsample)
+ assert isinstance(block.interp_upsample[1], ConvModule)
+ assert x_out.shape == torch.Size([1, 32, 256, 256])
+
+ # test InterpConv with conv_first=True for upsample 2X.
+ block = InterpConv(64, 32, conv_first=True)
+ x = torch.randn(1, 64, 128, 128)
+ x_out = block(x)
+ assert isinstance(block.interp_upsample[0], ConvModule)
+ assert isinstance(block.interp_upsample[1], Upsample)
+ assert x_out.shape == torch.Size([1, 32, 256, 256])
+
+ # test InterpConv with bilinear upsample for upsample 2X.
+ block = InterpConv(
+ 64,
+ 32,
+ conv_first=False,
+ upsample_cfg=dict(
+ scale_factor=2, mode='bilinear', align_corners=False))
+ x = torch.randn(1, 64, 128, 128)
+ x_out = block(x)
+ assert isinstance(block.interp_upsample[0], Upsample)
+ assert isinstance(block.interp_upsample[1], ConvModule)
+ assert x_out.shape == torch.Size([1, 32, 256, 256])
+ assert block.interp_upsample[0].mode == 'bilinear'
+
+ # test InterpConv with nearest upsample for upsample 2X.
+ block = InterpConv(
+ 64,
+ 32,
+ conv_first=False,
+ upsample_cfg=dict(scale_factor=2, mode='nearest'))
+ x = torch.randn(1, 64, 128, 128)
+ x_out = block(x)
+ assert isinstance(block.interp_upsample[0], Upsample)
+ assert isinstance(block.interp_upsample[1], ConvModule)
+ assert x_out.shape == torch.Size([1, 32, 256, 256])
+ assert block.interp_upsample[0].mode == 'nearest'
+
+
+def test_up_conv_block():
+ with pytest.raises(AssertionError):
+ # Not implemented yet.
+ dcn = dict(type='DCN', deform_groups=1, fallback_on_stride=False)
+ UpConvBlock(BasicConvBlock, 64, 32, 32, dcn=dcn)
+
+ with pytest.raises(AssertionError):
+ # Not implemented yet.
+ plugins = [
+ dict(
+ cfg=dict(type='ContextBlock', ratio=1. / 16),
+ position='after_conv3')
+ ]
+ UpConvBlock(BasicConvBlock, 64, 32, 32, plugins=plugins)
+
+ with pytest.raises(AssertionError):
+ # Not implemented yet
+ plugins = [
+ dict(
+ cfg=dict(
+ type='GeneralizedAttention',
+ spatial_range=-1,
+ num_heads=8,
+ attention_type='0010',
+ kv_stride=2),
+ position='after_conv2')
+ ]
+ UpConvBlock(BasicConvBlock, 64, 32, 32, plugins=plugins)
+
+ # test UpConvBlock with checkpoint forward and upsample 2X.
+ block = UpConvBlock(BasicConvBlock, 64, 32, 32, with_cp=True)
+ skip_x = torch.randn(1, 32, 256, 256, requires_grad=True)
+ x = torch.randn(1, 64, 128, 128, requires_grad=True)
+ x_out = block(skip_x, x)
+ assert x_out.shape == torch.Size([1, 32, 256, 256])
+
+ # test UpConvBlock with upsample=True for upsample 2X. The spatial size of
+ # skip_x is 2X larger than x.
+ block = UpConvBlock(
+ BasicConvBlock, 64, 32, 32, upsample_cfg=dict(type='InterpConv'))
+ skip_x = torch.randn(1, 32, 256, 256)
+ x = torch.randn(1, 64, 128, 128)
+ x_out = block(skip_x, x)
+ assert x_out.shape == torch.Size([1, 32, 256, 256])
+
+ # test UpConvBlock with upsample=False for upsample 2X. The spatial size of
+ # skip_x is the same as that of x.
+ block = UpConvBlock(BasicConvBlock, 64, 32, 32, upsample_cfg=None)
+ skip_x = torch.randn(1, 32, 256, 256)
+ x = torch.randn(1, 64, 256, 256)
+ x_out = block(skip_x, x)
+ assert x_out.shape == torch.Size([1, 32, 256, 256])
+
+ # test UpConvBlock with different upsample method for upsample 2X.
+ # The upsample method is interpolation upsample (bilinear or nearest).
+ block = UpConvBlock(
+ BasicConvBlock,
+ 64,
+ 32,
+ 32,
+ upsample_cfg=dict(
+ type='InterpConv',
+ upsample_cfg=dict(
+ scale_factor=2, mode='bilinear', align_corners=False)))
+ skip_x = torch.randn(1, 32, 256, 256)
+ x = torch.randn(1, 64, 128, 128)
+ x_out = block(skip_x, x)
+ assert x_out.shape == torch.Size([1, 32, 256, 256])
+
+ # test UpConvBlock with different upsample method for upsample 2X.
+ # The upsample method is deconvolution upsample.
+ block = UpConvBlock(
+ BasicConvBlock,
+ 64,
+ 32,
+ 32,
+ upsample_cfg=dict(type='DeconvModule', kernel_size=4, scale_factor=2))
+ skip_x = torch.randn(1, 32, 256, 256)
+ x = torch.randn(1, 64, 128, 128)
+ x_out = block(skip_x, x)
+ assert x_out.shape == torch.Size([1, 32, 256, 256])
+
+ # test BasicConvBlock structure and forward
+ block = UpConvBlock(
+ conv_block=BasicConvBlock,
+ in_channels=64,
+ skip_channels=32,
+ out_channels=32,
+ num_convs=3,
+ dilation=3,
+ upsample_cfg=dict(
+ type='InterpConv',
+ upsample_cfg=dict(
+ scale_factor=2, mode='bilinear', align_corners=False)))
+ skip_x = torch.randn(1, 32, 256, 256)
+ x = torch.randn(1, 64, 128, 128)
+ x_out = block(skip_x, x)
+ assert x_out.shape == torch.Size([1, 32, 256, 256])
+
+ assert block.conv_block.convs[0].conv.in_channels == 64
+ assert block.conv_block.convs[0].conv.out_channels == 32
+ assert block.conv_block.convs[0].conv.kernel_size == (3, 3)
+ assert block.conv_block.convs[0].conv.dilation == (1, 1)
+ assert block.conv_block.convs[0].conv.padding == (1, 1)
+
+ assert block.conv_block.convs[1].conv.in_channels == 32
+ assert block.conv_block.convs[1].conv.out_channels == 32
+ assert block.conv_block.convs[1].conv.kernel_size == (3, 3)
+ assert block.conv_block.convs[1].conv.dilation == (3, 3)
+ assert block.conv_block.convs[1].conv.padding == (3, 3)
+
+ assert block.conv_block.convs[2].conv.in_channels == 32
+ assert block.conv_block.convs[2].conv.out_channels == 32
+ assert block.conv_block.convs[2].conv.kernel_size == (3, 3)
+ assert block.conv_block.convs[2].conv.dilation == (3, 3)
+ assert block.conv_block.convs[2].conv.padding == (3, 3)
+
+ assert block.upsample.interp_upsample[1].conv.in_channels == 64
+ assert block.upsample.interp_upsample[1].conv.out_channels == 32
+ assert block.upsample.interp_upsample[1].conv.kernel_size == (1, 1)
+ assert block.upsample.interp_upsample[1].conv.dilation == (1, 1)
+ assert block.upsample.interp_upsample[1].conv.padding == (0, 0)
+
+
+def test_unet():
+ with pytest.raises(AssertionError):
+ # Not implemented yet.
+ dcn = dict(type='DCN', deform_groups=1, fallback_on_stride=False)
+ UNet(3, 64, 5, dcn=dcn)
+
+ with pytest.raises(AssertionError):
+ # Not implemented yet.
+ plugins = [
+ dict(
+ cfg=dict(type='ContextBlock', ratio=1. / 16),
+ position='after_conv3')
+ ]
+ UNet(3, 64, 5, plugins=plugins)
+
+ with pytest.raises(AssertionError):
+ # Not implemented yet
+ plugins = [
+ dict(
+ cfg=dict(
+ type='GeneralizedAttention',
+ spatial_range=-1,
+ num_heads=8,
+ attention_type='0010',
+ kv_stride=2),
+ position='after_conv2')
+ ]
+ UNet(3, 64, 5, plugins=plugins)
+
+ with pytest.raises(AssertionError):
+ # Check whether the input image size can be divisible by the whole
+ # downsample rate of the encoder. The whole downsample rate of this
+ # case is 8.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=4,
+ strides=(1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2),
+ downsamples=(True, True, True),
+ enc_dilations=(1, 1, 1, 1),
+ dec_dilations=(1, 1, 1))
+ x = torch.randn(2, 3, 65, 65)
+ unet(x)
+
+ with pytest.raises(AssertionError):
+ # Check whether the input image size can be divisible by the whole
+ # downsample rate of the encoder. The whole downsample rate of this
+ # case is 16.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True, True),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+ x = torch.randn(2, 3, 65, 65)
+ unet(x)
+
+ with pytest.raises(AssertionError):
+ # Check whether the input image size can be divisible by the whole
+ # downsample rate of the encoder. The whole downsample rate of this
+ # case is 8.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True, False),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+ x = torch.randn(2, 3, 65, 65)
+ unet(x)
+
+ with pytest.raises(AssertionError):
+ # Check whether the input image size can be divisible by the whole
+ # downsample rate of the encoder. The whole downsample rate of this
+ # case is 8.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 2, 2, 2, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True, False),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+ x = torch.randn(2, 3, 65, 65)
+ unet(x)
+
+ with pytest.raises(AssertionError):
+ # Check whether the input image size can be divisible by the whole
+ # downsample rate of the encoder. The whole downsample rate of this
+ # case is 32.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=6,
+ strides=(1, 1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2, 2),
+ downsamples=(True, True, True, True, True),
+ enc_dilations=(1, 1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1, 1))
+ x = torch.randn(2, 3, 65, 65)
+ unet(x)
+
+ with pytest.raises(AssertionError):
+ # Check if num_stages matches strides, len(strides)=num_stages
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True, True),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+ x = torch.randn(2, 3, 64, 64)
+ unet(x)
+
+ with pytest.raises(AssertionError):
+ # Check if num_stages matches strides, len(enc_num_convs)=num_stages
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True, True),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+ x = torch.randn(2, 3, 64, 64)
+ unet(x)
+
+ with pytest.raises(AssertionError):
+ # Check if num_stages matches strides, len(dec_num_convs)=num_stages-1
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2, 2),
+ downsamples=(True, True, True, True),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+ x = torch.randn(2, 3, 64, 64)
+ unet(x)
+
+ with pytest.raises(AssertionError):
+ # Check if num_stages matches strides, len(downsamples)=num_stages-1
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+ x = torch.randn(2, 3, 64, 64)
+ unet(x)
+
+ with pytest.raises(AssertionError):
+ # Check if num_stages matches strides, len(enc_dilations)=num_stages
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True, True),
+ enc_dilations=(1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+ x = torch.randn(2, 3, 64, 64)
+ unet(x)
+
+ with pytest.raises(AssertionError):
+ # Check if num_stages matches strides, len(dec_dilations)=num_stages-1
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True, True),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1, 1))
+ x = torch.randn(2, 3, 64, 64)
+ unet(x)
+
+ # test UNet norm_eval=True
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True, True),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1),
+ norm_eval=True)
+ unet.train()
+ assert check_norm_state(unet.modules(), False)
+
+ # test UNet norm_eval=False
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True, True),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1),
+ norm_eval=False)
+ unet.train()
+ assert check_norm_state(unet.modules(), True)
+
+ # test UNet forward and outputs. The whole downsample rate is 16.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True, True),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+
+ x = torch.randn(2, 3, 128, 128)
+ x_outs = unet(x)
+ assert x_outs[0].shape == torch.Size([2, 64, 8, 8])
+ assert x_outs[1].shape == torch.Size([2, 32, 16, 16])
+ assert x_outs[2].shape == torch.Size([2, 16, 32, 32])
+ assert x_outs[3].shape == torch.Size([2, 8, 64, 64])
+ assert x_outs[4].shape == torch.Size([2, 4, 128, 128])
+
+ # test UNet forward and outputs. The whole downsample rate is 8.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True, False),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+
+ x = torch.randn(2, 3, 128, 128)
+ x_outs = unet(x)
+ assert x_outs[0].shape == torch.Size([2, 64, 16, 16])
+ assert x_outs[1].shape == torch.Size([2, 32, 16, 16])
+ assert x_outs[2].shape == torch.Size([2, 16, 32, 32])
+ assert x_outs[3].shape == torch.Size([2, 8, 64, 64])
+ assert x_outs[4].shape == torch.Size([2, 4, 128, 128])
+
+ # test UNet forward and outputs. The whole downsample rate is 8.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 2, 2, 2, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True, False),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+
+ x = torch.randn(2, 3, 128, 128)
+ x_outs = unet(x)
+ assert x_outs[0].shape == torch.Size([2, 64, 16, 16])
+ assert x_outs[1].shape == torch.Size([2, 32, 16, 16])
+ assert x_outs[2].shape == torch.Size([2, 16, 32, 32])
+ assert x_outs[3].shape == torch.Size([2, 8, 64, 64])
+ assert x_outs[4].shape == torch.Size([2, 4, 128, 128])
+
+ # test UNet forward and outputs. The whole downsample rate is 4.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, False, False),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+
+ x = torch.randn(2, 3, 128, 128)
+ x_outs = unet(x)
+ assert x_outs[0].shape == torch.Size([2, 64, 32, 32])
+ assert x_outs[1].shape == torch.Size([2, 32, 32, 32])
+ assert x_outs[2].shape == torch.Size([2, 16, 32, 32])
+ assert x_outs[3].shape == torch.Size([2, 8, 64, 64])
+ assert x_outs[4].shape == torch.Size([2, 4, 128, 128])
+
+ # test UNet forward and outputs. The whole downsample rate is 4.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 2, 2, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, False, False),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+
+ x = torch.randn(2, 3, 128, 128)
+ x_outs = unet(x)
+ assert x_outs[0].shape == torch.Size([2, 64, 32, 32])
+ assert x_outs[1].shape == torch.Size([2, 32, 32, 32])
+ assert x_outs[2].shape == torch.Size([2, 16, 32, 32])
+ assert x_outs[3].shape == torch.Size([2, 8, 64, 64])
+ assert x_outs[4].shape == torch.Size([2, 4, 128, 128])
+
+ # test UNet forward and outputs. The whole downsample rate is 8.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True, False),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+
+ x = torch.randn(2, 3, 128, 128)
+ x_outs = unet(x)
+ assert x_outs[0].shape == torch.Size([2, 64, 16, 16])
+ assert x_outs[1].shape == torch.Size([2, 32, 16, 16])
+ assert x_outs[2].shape == torch.Size([2, 16, 32, 32])
+ assert x_outs[3].shape == torch.Size([2, 8, 64, 64])
+ assert x_outs[4].shape == torch.Size([2, 4, 128, 128])
+
+ # test UNet forward and outputs. The whole downsample rate is 4.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, False, False),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+
+ x = torch.randn(2, 3, 128, 128)
+ x_outs = unet(x)
+ assert x_outs[0].shape == torch.Size([2, 64, 32, 32])
+ assert x_outs[1].shape == torch.Size([2, 32, 32, 32])
+ assert x_outs[2].shape == torch.Size([2, 16, 32, 32])
+ assert x_outs[3].shape == torch.Size([2, 8, 64, 64])
+ assert x_outs[4].shape == torch.Size([2, 4, 128, 128])
+
+ # test UNet forward and outputs. The whole downsample rate is 2.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, False, False, False),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+
+ x = torch.randn(2, 3, 128, 128)
+ x_outs = unet(x)
+ assert x_outs[0].shape == torch.Size([2, 64, 64, 64])
+ assert x_outs[1].shape == torch.Size([2, 32, 64, 64])
+ assert x_outs[2].shape == torch.Size([2, 16, 64, 64])
+ assert x_outs[3].shape == torch.Size([2, 8, 64, 64])
+ assert x_outs[4].shape == torch.Size([2, 4, 128, 128])
+
+ # test UNet forward and outputs. The whole downsample rate is 1.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 1, 1, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(False, False, False, False),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+
+ x = torch.randn(2, 3, 128, 128)
+ x_outs = unet(x)
+ assert x_outs[0].shape == torch.Size([2, 64, 128, 128])
+ assert x_outs[1].shape == torch.Size([2, 32, 128, 128])
+ assert x_outs[2].shape == torch.Size([2, 16, 128, 128])
+ assert x_outs[3].shape == torch.Size([2, 8, 128, 128])
+ assert x_outs[4].shape == torch.Size([2, 4, 128, 128])
+
+ # test UNet forward and outputs. The whole downsample rate is 16.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 2, 2, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True, True),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+ x = torch.randn(2, 3, 128, 128)
+ x_outs = unet(x)
+ assert x_outs[0].shape == torch.Size([2, 64, 8, 8])
+ assert x_outs[1].shape == torch.Size([2, 32, 16, 16])
+ assert x_outs[2].shape == torch.Size([2, 16, 32, 32])
+ assert x_outs[3].shape == torch.Size([2, 8, 64, 64])
+ assert x_outs[4].shape == torch.Size([2, 4, 128, 128])
+
+ # test UNet forward and outputs. The whole downsample rate is 8.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 2, 2, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True, False),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+ x = torch.randn(2, 3, 128, 128)
+ x_outs = unet(x)
+ assert x_outs[0].shape == torch.Size([2, 64, 16, 16])
+ assert x_outs[1].shape == torch.Size([2, 32, 16, 16])
+ assert x_outs[2].shape == torch.Size([2, 16, 32, 32])
+ assert x_outs[3].shape == torch.Size([2, 8, 64, 64])
+ assert x_outs[4].shape == torch.Size([2, 4, 128, 128])
+
+ # test UNet forward and outputs. The whole downsample rate is 8.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 2, 2, 2, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, True, False),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+ x = torch.randn(2, 3, 128, 128)
+ x_outs = unet(x)
+ assert x_outs[0].shape == torch.Size([2, 64, 16, 16])
+ assert x_outs[1].shape == torch.Size([2, 32, 16, 16])
+ assert x_outs[2].shape == torch.Size([2, 16, 32, 32])
+ assert x_outs[3].shape == torch.Size([2, 8, 64, 64])
+ assert x_outs[4].shape == torch.Size([2, 4, 128, 128])
+
+ # test UNet forward and outputs. The whole downsample rate is 4.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 2, 2, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, False, False),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1))
+ x = torch.randn(2, 3, 128, 128)
+ x_outs = unet(x)
+ assert x_outs[0].shape == torch.Size([2, 64, 32, 32])
+ assert x_outs[1].shape == torch.Size([2, 32, 32, 32])
+ assert x_outs[2].shape == torch.Size([2, 16, 32, 32])
+ assert x_outs[3].shape == torch.Size([2, 8, 64, 64])
+ assert x_outs[4].shape == torch.Size([2, 4, 128, 128])
+
+ # test UNet init_weights method.
+ unet = UNet(
+ in_channels=3,
+ base_channels=4,
+ num_stages=5,
+ strides=(1, 2, 2, 1, 1),
+ enc_num_convs=(2, 2, 2, 2, 2),
+ dec_num_convs=(2, 2, 2, 2),
+ downsamples=(True, True, False, False),
+ enc_dilations=(1, 1, 1, 1, 1),
+ dec_dilations=(1, 1, 1, 1),
+ pretrained=None)
+ unet.init_weights()
+ x = torch.randn(2, 3, 128, 128)
+ x_outs = unet(x)
+ assert x_outs[0].shape == torch.Size([2, 64, 32, 32])
+ assert x_outs[1].shape == torch.Size([2, 32, 32, 32])
+ assert x_outs[2].shape == torch.Size([2, 16, 32, 32])
+ assert x_outs[3].shape == torch.Size([2, 8, 64, 64])
+ assert x_outs[4].shape == torch.Size([2, 4, 128, 128])
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_vit.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_vit.py
new file mode 100644
index 0000000000000000000000000000000000000000..0d1ba7000967951347602f2d6e53563bd00b850d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/test_vit.py
@@ -0,0 +1,185 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.backbones.vit import (TransformerEncoderLayer,
+ VisionTransformer)
+from .utils import check_norm_state
+
+
+def test_vit_backbone():
+ with pytest.raises(TypeError):
+ # pretrained must be a string path
+ model = VisionTransformer()
+ model.init_weights(pretrained=0)
+
+ with pytest.raises(TypeError):
+ # img_size must be int or tuple
+ model = VisionTransformer(img_size=512.0)
+
+ with pytest.raises(TypeError):
+ # out_indices must be int ,list or tuple
+ model = VisionTransformer(out_indices=1.)
+
+ with pytest.raises(TypeError):
+ # test upsample_pos_embed function
+ x = torch.randn(1, 196)
+ VisionTransformer.resize_pos_embed(x, 512, 512, 224, 224, 'bilinear')
+
+ with pytest.raises(AssertionError):
+ # The length of img_size tuple must be lower than 3.
+ VisionTransformer(img_size=(224, 224, 224))
+
+ with pytest.raises(TypeError):
+ # Pretrained must be None or Str.
+ VisionTransformer(pretrained=123)
+
+ with pytest.raises(AssertionError):
+ # with_cls_token must be True when output_cls_token == True
+ VisionTransformer(with_cls_token=False, output_cls_token=True)
+
+ # Test img_size isinstance tuple
+ imgs = torch.randn(1, 3, 224, 224)
+ model = VisionTransformer(img_size=(224, ))
+ model.init_weights()
+ model(imgs)
+
+ # Test img_size isinstance tuple
+ imgs = torch.randn(1, 3, 224, 224)
+ model = VisionTransformer(img_size=(224, 224))
+ model(imgs)
+
+ # Test norm_eval = True
+ model = VisionTransformer(norm_eval=True)
+ model.train()
+
+ # Test ViT backbone with input size of 224 and patch size of 16
+ model = VisionTransformer()
+ model.init_weights()
+ model.train()
+
+ assert check_norm_state(model.modules(), True)
+
+ # Test normal size input image
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 14, 14)
+
+ # Test large size input image
+ imgs = torch.randn(1, 3, 256, 256)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 16, 16)
+
+ # Test small size input image
+ imgs = torch.randn(1, 3, 32, 32)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 2, 2)
+
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 14, 14)
+
+ # Test unbalanced size input image
+ imgs = torch.randn(1, 3, 112, 224)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 7, 14)
+
+ # Test irregular input image
+ imgs = torch.randn(1, 3, 234, 345)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 15, 22)
+
+ # Test with_cp=True
+ model = VisionTransformer(with_cp=True)
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 14, 14)
+
+ # Test with_cls_token=False
+ model = VisionTransformer(with_cls_token=False)
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 14, 14)
+
+ # Test final norm
+ model = VisionTransformer(final_norm=True)
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 14, 14)
+
+ # Test patch norm
+ model = VisionTransformer(patch_norm=True)
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert feat[-1].shape == (1, 768, 14, 14)
+
+ # Test output_cls_token
+ model = VisionTransformer(with_cls_token=True, output_cls_token=True)
+ imgs = torch.randn(1, 3, 224, 224)
+ feat = model(imgs)
+ assert feat[0][0].shape == (1, 768, 14, 14)
+ assert feat[0][1].shape == (1, 768)
+
+ # Test TransformerEncoderLayer with checkpoint forward
+ block = TransformerEncoderLayer(
+ embed_dims=64, num_heads=4, feedforward_channels=256, with_cp=True)
+ assert block.with_cp
+ x = torch.randn(1, 56 * 56, 64)
+ x_out = block(x)
+ assert x_out.shape == torch.Size([1, 56 * 56, 64])
+
+
+def test_vit_init():
+ path = 'PATH_THAT_DO_NOT_EXIST'
+ # Test all combinations of pretrained and init_cfg
+ # pretrained=None, init_cfg=None
+ model = VisionTransformer(pretrained=None, init_cfg=None)
+ assert model.init_cfg is None
+ model.init_weights()
+
+ # pretrained=None
+ # init_cfg loads pretrain from an non-existent file
+ model = VisionTransformer(
+ pretrained=None, init_cfg=dict(type='Pretrained', checkpoint=path))
+ assert model.init_cfg == dict(type='Pretrained', checkpoint=path)
+ # Test loading a checkpoint from an non-existent file
+ with pytest.raises(OSError):
+ model.init_weights()
+
+ # pretrained=None
+ # init_cfg=123, whose type is unsupported
+ model = VisionTransformer(pretrained=None, init_cfg=123)
+ with pytest.raises(TypeError):
+ model.init_weights()
+
+ # pretrained loads pretrain from an non-existent file
+ # init_cfg=None
+ model = VisionTransformer(pretrained=path, init_cfg=None)
+ assert model.init_cfg == dict(type='Pretrained', checkpoint=path)
+ # Test loading a checkpoint from an non-existent file
+ with pytest.raises(OSError):
+ model.init_weights()
+
+ # pretrained loads pretrain from an non-existent file
+ # init_cfg loads pretrain from an non-existent file
+ with pytest.raises(AssertionError):
+ model = VisionTransformer(
+ pretrained=path, init_cfg=dict(type='Pretrained', checkpoint=path))
+ with pytest.raises(AssertionError):
+ model = VisionTransformer(pretrained=path, init_cfg=123)
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg=None
+ with pytest.raises(TypeError):
+ model = VisionTransformer(pretrained=123, init_cfg=None)
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg loads pretrain from an non-existent file
+ with pytest.raises(AssertionError):
+ model = VisionTransformer(
+ pretrained=123, init_cfg=dict(type='Pretrained', checkpoint=path))
+
+ # pretrain=123, whose type is unsupported
+ # init_cfg=123, whose type is unsupported
+ with pytest.raises(AssertionError):
+ model = VisionTransformer(pretrained=123, init_cfg=123)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/utils.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..54b6404c603f54c25a02f13b39dc3ddec2181680
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_backbones/utils.py
@@ -0,0 +1,43 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+from torch.nn.modules import GroupNorm
+from torch.nn.modules.batchnorm import _BatchNorm
+
+from mmseg.models.backbones.resnet import BasicBlock, Bottleneck
+from mmseg.models.backbones.resnext import Bottleneck as BottleneckX
+
+
+def is_block(modules):
+ """Check if is ResNet building block."""
+ if isinstance(modules, (BasicBlock, Bottleneck, BottleneckX)):
+ return True
+ return False
+
+
+def is_norm(modules):
+ """Check if is one of the norms."""
+ if isinstance(modules, (GroupNorm, _BatchNorm)):
+ return True
+ return False
+
+
+def all_zeros(modules):
+ """Check if the weight(and bias) is all zero."""
+ weight_zero = torch.allclose(modules.weight.data,
+ torch.zeros_like(modules.weight.data))
+ if hasattr(modules, 'bias'):
+ bias_zero = torch.allclose(modules.bias.data,
+ torch.zeros_like(modules.bias.data))
+ else:
+ bias_zero = True
+
+ return weight_zero and bias_zero
+
+
+def check_norm_state(modules, train_state):
+ """Check if norm layer is in correct train state."""
+ for mod in modules:
+ if isinstance(mod, _BatchNorm):
+ if mod.training != train_state:
+ return False
+ return True
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_forward.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_forward.py
new file mode 100644
index 0000000000000000000000000000000000000000..ee707b35118149453c45f342b9cc1a642bb5f904
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_forward.py
@@ -0,0 +1,235 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+"""pytest tests/test_forward.py."""
+import copy
+from os.path import dirname, exists, join
+from unittest.mock import patch
+
+import numpy as np
+import pytest
+import torch
+import torch.nn as nn
+from mmcv.cnn.utils import revert_sync_batchnorm
+
+
+def _demo_mm_inputs(input_shape=(2, 3, 8, 16), num_classes=10):
+ """Create a superset of inputs needed to run test or train batches.
+
+ Args:
+ input_shape (tuple):
+ input batch dimensions
+
+ num_classes (int):
+ number of semantic classes
+ """
+ (N, C, H, W) = input_shape
+
+ rng = np.random.RandomState(0)
+
+ imgs = rng.rand(*input_shape)
+ segs = rng.randint(
+ low=0, high=num_classes - 1, size=(N, 1, H, W)).astype(np.uint8)
+
+ img_metas = [{
+ 'img_shape': (H, W, C),
+ 'ori_shape': (H, W, C),
+ 'pad_shape': (H, W, C),
+ 'filename': '.png',
+ 'scale_factor': 1.0,
+ 'flip': False,
+ 'flip_direction': 'horizontal'
+ } for _ in range(N)]
+
+ mm_inputs = {
+ 'imgs': torch.FloatTensor(imgs),
+ 'img_metas': img_metas,
+ 'gt_semantic_seg': torch.LongTensor(segs)
+ }
+ return mm_inputs
+
+
+def _get_config_directory():
+ """Find the predefined segmentor config directory."""
+ try:
+ # Assume we are running in the source mmsegmentation repo
+ repo_dpath = dirname(dirname(dirname(__file__)))
+ except NameError:
+ # For IPython development when this __file__ is not defined
+ import mmseg
+ repo_dpath = dirname(dirname(dirname(mmseg.__file__)))
+ config_dpath = join(repo_dpath, 'configs')
+ if not exists(config_dpath):
+ raise Exception('Cannot find config path')
+ return config_dpath
+
+
+def _get_config_module(fname):
+ """Load a configuration as a python module."""
+ from mmcv import Config
+ config_dpath = _get_config_directory()
+ config_fpath = join(config_dpath, fname)
+ config_mod = Config.fromfile(config_fpath)
+ return config_mod
+
+
+def _get_segmentor_cfg(fname):
+ """Grab configs necessary to create a segmentor.
+
+ These are deep copied to allow for safe modification of parameters without
+ influencing other tests.
+ """
+ config = _get_config_module(fname)
+ model = copy.deepcopy(config.model)
+ return model
+
+
+def test_pspnet_forward():
+ _test_encoder_decoder_forward(
+ 'pspnet/pspnet_r50-d8_512x1024_40k_cityscapes.py')
+
+
+def test_fcn_forward():
+ _test_encoder_decoder_forward('fcn/fcn_r50-d8_512x1024_40k_cityscapes.py')
+
+
+def test_deeplabv3_forward():
+ _test_encoder_decoder_forward(
+ 'deeplabv3/deeplabv3_r50-d8_512x1024_40k_cityscapes.py')
+
+
+def test_deeplabv3plus_forward():
+ _test_encoder_decoder_forward(
+ 'deeplabv3plus/deeplabv3plus_r50-d8_512x1024_40k_cityscapes.py')
+
+
+def test_gcnet_forward():
+ _test_encoder_decoder_forward(
+ 'gcnet/gcnet_r50-d8_512x1024_40k_cityscapes.py')
+
+
+def test_ann_forward():
+ _test_encoder_decoder_forward('ann/ann_r50-d8_512x1024_40k_cityscapes.py')
+
+
+def test_ccnet_forward():
+ if not torch.cuda.is_available():
+ pytest.skip('CCNet requires CUDA')
+ _test_encoder_decoder_forward(
+ 'ccnet/ccnet_r50-d8_512x1024_40k_cityscapes.py')
+
+
+def test_danet_forward():
+ _test_encoder_decoder_forward(
+ 'danet/danet_r50-d8_512x1024_40k_cityscapes.py')
+
+
+def test_nonlocal_net_forward():
+ _test_encoder_decoder_forward(
+ 'nonlocal_net/nonlocal_r50-d8_512x1024_40k_cityscapes.py')
+
+
+def test_upernet_forward():
+ _test_encoder_decoder_forward(
+ 'upernet/upernet_r50_512x1024_40k_cityscapes.py')
+
+
+def test_hrnet_forward():
+ _test_encoder_decoder_forward('hrnet/fcn_hr18s_512x1024_40k_cityscapes.py')
+
+
+def test_ocrnet_forward():
+ _test_encoder_decoder_forward(
+ 'ocrnet/ocrnet_hr18s_512x1024_40k_cityscapes.py')
+
+
+def test_psanet_forward():
+ _test_encoder_decoder_forward(
+ 'psanet/psanet_r50-d8_512x1024_40k_cityscapes.py')
+
+
+def test_encnet_forward():
+ _test_encoder_decoder_forward(
+ 'encnet/encnet_r50-d8_512x1024_40k_cityscapes.py')
+
+
+def test_sem_fpn_forward():
+ _test_encoder_decoder_forward('sem_fpn/fpn_r50_512x1024_80k_cityscapes.py')
+
+
+def test_point_rend_forward():
+ _test_encoder_decoder_forward(
+ 'point_rend/pointrend_r50_512x1024_80k_cityscapes.py')
+
+
+def test_mobilenet_v2_forward():
+ _test_encoder_decoder_forward(
+ 'mobilenet_v2/pspnet_m-v2-d8_512x1024_80k_cityscapes.py')
+
+
+def test_dnlnet_forward():
+ _test_encoder_decoder_forward(
+ 'dnlnet/dnl_r50-d8_512x1024_40k_cityscapes.py')
+
+
+def test_emanet_forward():
+ _test_encoder_decoder_forward(
+ 'emanet/emanet_r50-d8_512x1024_80k_cityscapes.py')
+
+
+def test_isanet_forward():
+ _test_encoder_decoder_forward(
+ 'isanet/isanet_r50-d8_512x1024_40k_cityscapes.py')
+
+
+def get_world_size(process_group):
+
+ return 1
+
+
+def _check_input_dim(self, inputs):
+ pass
+
+
+@patch('torch.nn.modules.batchnorm._BatchNorm._check_input_dim',
+ _check_input_dim)
+@patch('torch.distributed.get_world_size', get_world_size)
+def _test_encoder_decoder_forward(cfg_file):
+ model = _get_segmentor_cfg(cfg_file)
+ model['pretrained'] = None
+ model['test_cfg']['mode'] = 'whole'
+
+ from mmseg.models import build_segmentor
+ segmentor = build_segmentor(model)
+ segmentor.init_weights()
+
+ if isinstance(segmentor.decode_head, nn.ModuleList):
+ num_classes = segmentor.decode_head[-1].num_classes
+ else:
+ num_classes = segmentor.decode_head.num_classes
+ # batch_size=2 for BatchNorm
+ input_shape = (2, 3, 32, 32)
+ mm_inputs = _demo_mm_inputs(input_shape, num_classes=num_classes)
+
+ imgs = mm_inputs.pop('imgs')
+ img_metas = mm_inputs.pop('img_metas')
+ gt_semantic_seg = mm_inputs['gt_semantic_seg']
+
+ # convert to cuda Tensor if applicable
+ if torch.cuda.is_available():
+ segmentor = segmentor.cuda()
+ imgs = imgs.cuda()
+ gt_semantic_seg = gt_semantic_seg.cuda()
+ else:
+ segmentor = revert_sync_batchnorm(segmentor)
+
+ # Test forward train
+ losses = segmentor.forward(
+ imgs, img_metas, gt_semantic_seg=gt_semantic_seg, return_loss=True)
+ assert isinstance(losses, dict)
+
+ # Test forward test
+ with torch.no_grad():
+ segmentor.eval()
+ # pack into lists
+ img_list = [img[None, :] for img in imgs]
+ img_meta_list = [[img_meta] for img_meta in img_metas]
+ segmentor.forward(img_list, img_meta_list, return_loss=False)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/__init__.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..ef101fec61e72abc0eb90266d453b5b22331378d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/__init__.py
@@ -0,0 +1 @@
+# Copyright (c) OpenMMLab. All rights reserved.
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_ann_head.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_ann_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..c1e44bc6857524100197c5dbd511f20953ca13fa
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_ann_head.py
@@ -0,0 +1,20 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+
+from mmseg.models.decode_heads import ANNHead
+from .utils import to_cuda
+
+
+def test_ann_head():
+
+ inputs = [torch.randn(1, 4, 45, 45), torch.randn(1, 8, 21, 21)]
+ head = ANNHead(
+ in_channels=[4, 8],
+ channels=2,
+ num_classes=19,
+ in_index=[-2, -1],
+ project_channels=8)
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 21, 21)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_apc_head.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_apc_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..dc55ccc1d524425ff12225220a5bf0ccdbd56920
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_apc_head.py
@@ -0,0 +1,59 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.decode_heads import APCHead
+from .utils import _conv_has_norm, to_cuda
+
+
+def test_apc_head():
+
+ with pytest.raises(AssertionError):
+ # pool_scales must be list|tuple
+ APCHead(in_channels=8, channels=2, num_classes=19, pool_scales=1)
+
+ # test no norm_cfg
+ head = APCHead(in_channels=8, channels=2, num_classes=19)
+ assert not _conv_has_norm(head, sync_bn=False)
+
+ # test with norm_cfg
+ head = APCHead(
+ in_channels=8,
+ channels=2,
+ num_classes=19,
+ norm_cfg=dict(type='SyncBN'))
+ assert _conv_has_norm(head, sync_bn=True)
+
+ # fusion=True
+ inputs = [torch.randn(1, 8, 45, 45)]
+ head = APCHead(
+ in_channels=8,
+ channels=2,
+ num_classes=19,
+ pool_scales=(1, 2, 3),
+ fusion=True)
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ assert head.fusion is True
+ assert head.acm_modules[0].pool_scale == 1
+ assert head.acm_modules[1].pool_scale == 2
+ assert head.acm_modules[2].pool_scale == 3
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 45, 45)
+
+ # fusion=False
+ inputs = [torch.randn(1, 8, 45, 45)]
+ head = APCHead(
+ in_channels=8,
+ channels=2,
+ num_classes=19,
+ pool_scales=(1, 2, 3),
+ fusion=False)
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ assert head.fusion is False
+ assert head.acm_modules[0].pool_scale == 1
+ assert head.acm_modules[1].pool_scale == 2
+ assert head.acm_modules[2].pool_scale == 3
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 45, 45)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_aspp_head.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_aspp_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..db9e89324f53aa7942315593ae26aadc2eeebd8b
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_aspp_head.py
@@ -0,0 +1,76 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.decode_heads import ASPPHead, DepthwiseSeparableASPPHead
+from .utils import _conv_has_norm, to_cuda
+
+
+def test_aspp_head():
+
+ with pytest.raises(AssertionError):
+ # pool_scales must be list|tuple
+ ASPPHead(in_channels=8, channels=4, num_classes=19, dilations=1)
+
+ # test no norm_cfg
+ head = ASPPHead(in_channels=8, channels=4, num_classes=19)
+ assert not _conv_has_norm(head, sync_bn=False)
+
+ # test with norm_cfg
+ head = ASPPHead(
+ in_channels=8,
+ channels=4,
+ num_classes=19,
+ norm_cfg=dict(type='SyncBN'))
+ assert _conv_has_norm(head, sync_bn=True)
+
+ inputs = [torch.randn(1, 8, 45, 45)]
+ head = ASPPHead(
+ in_channels=8, channels=4, num_classes=19, dilations=(1, 12, 24))
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ assert head.aspp_modules[0].conv.dilation == (1, 1)
+ assert head.aspp_modules[1].conv.dilation == (12, 12)
+ assert head.aspp_modules[2].conv.dilation == (24, 24)
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 45, 45)
+
+
+def test_dw_aspp_head():
+
+ # test w.o. c1
+ inputs = [torch.randn(1, 8, 45, 45)]
+ head = DepthwiseSeparableASPPHead(
+ c1_in_channels=0,
+ c1_channels=0,
+ in_channels=8,
+ channels=4,
+ num_classes=19,
+ dilations=(1, 12, 24))
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ assert head.c1_bottleneck is None
+ assert head.aspp_modules[0].conv.dilation == (1, 1)
+ assert head.aspp_modules[1].depthwise_conv.dilation == (12, 12)
+ assert head.aspp_modules[2].depthwise_conv.dilation == (24, 24)
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 45, 45)
+
+ # test with c1
+ inputs = [torch.randn(1, 4, 45, 45), torch.randn(1, 16, 21, 21)]
+ head = DepthwiseSeparableASPPHead(
+ c1_in_channels=4,
+ c1_channels=2,
+ in_channels=16,
+ channels=8,
+ num_classes=19,
+ dilations=(1, 12, 24))
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ assert head.c1_bottleneck.in_channels == 4
+ assert head.c1_bottleneck.out_channels == 2
+ assert head.aspp_modules[0].conv.dilation == (1, 1)
+ assert head.aspp_modules[1].depthwise_conv.dilation == (12, 12)
+ assert head.aspp_modules[2].depthwise_conv.dilation == (24, 24)
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 45, 45)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_cc_head.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_cc_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..06304172dba1334e521dca3a6b7da7f78f091690
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_cc_head.py
@@ -0,0 +1,18 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.decode_heads import CCHead
+from .utils import to_cuda
+
+
+def test_cc_head():
+ head = CCHead(in_channels=16, channels=8, num_classes=19)
+ assert len(head.convs) == 2
+ assert hasattr(head, 'cca')
+ if not torch.cuda.is_available():
+ pytest.skip('CCHead requires CUDA')
+ inputs = [torch.randn(1, 16, 23, 23)]
+ head, inputs = to_cuda(head, inputs)
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 23, 23)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_da_head.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_da_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..7ab4a96142693fcd8dfd3564fca7d664d1efd93a
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_da_head.py
@@ -0,0 +1,19 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+
+from mmseg.models.decode_heads import DAHead
+from .utils import to_cuda
+
+
+def test_da_head():
+
+ inputs = [torch.randn(1, 16, 23, 23)]
+ head = DAHead(in_channels=16, channels=8, num_classes=19, pam_channels=8)
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ outputs = head(inputs)
+ assert isinstance(outputs, tuple) and len(outputs) == 3
+ for output in outputs:
+ assert output.shape == (1, head.num_classes, 23, 23)
+ test_output = head.forward_test(inputs, None, None)
+ assert test_output.shape == (1, head.num_classes, 23, 23)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_decode_head.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_decode_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..cb9ab97181b5ec2e060c8d3acdfa147d6aab9d9d
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_decode_head.py
@@ -0,0 +1,165 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+from unittest.mock import patch
+
+import pytest
+import torch
+
+from mmseg.models.decode_heads.decode_head import BaseDecodeHead
+from .utils import to_cuda
+
+
+@patch.multiple(BaseDecodeHead, __abstractmethods__=set())
+def test_decode_head():
+
+ with pytest.raises(AssertionError):
+ # default input_transform doesn't accept multiple inputs
+ BaseDecodeHead([32, 16], 16, num_classes=19)
+
+ with pytest.raises(AssertionError):
+ # default input_transform doesn't accept multiple inputs
+ BaseDecodeHead(32, 16, num_classes=19, in_index=[-1, -2])
+
+ with pytest.raises(AssertionError):
+ # supported mode is resize_concat only
+ BaseDecodeHead(32, 16, num_classes=19, input_transform='concat')
+
+ with pytest.raises(AssertionError):
+ # in_channels should be list|tuple
+ BaseDecodeHead(32, 16, num_classes=19, input_transform='resize_concat')
+
+ with pytest.raises(AssertionError):
+ # in_index should be list|tuple
+ BaseDecodeHead([32],
+ 16,
+ in_index=-1,
+ num_classes=19,
+ input_transform='resize_concat')
+
+ with pytest.raises(AssertionError):
+ # len(in_index) should equal len(in_channels)
+ BaseDecodeHead([32, 16],
+ 16,
+ num_classes=19,
+ in_index=[-1],
+ input_transform='resize_concat')
+
+ # test default dropout
+ head = BaseDecodeHead(32, 16, num_classes=19)
+ assert hasattr(head, 'dropout') and head.dropout.p == 0.1
+
+ # test set dropout
+ head = BaseDecodeHead(32, 16, num_classes=19, dropout_ratio=0.2)
+ assert hasattr(head, 'dropout') and head.dropout.p == 0.2
+
+ # test no input_transform
+ inputs = [torch.randn(1, 32, 45, 45)]
+ head = BaseDecodeHead(32, 16, num_classes=19)
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ assert head.in_channels == 32
+ assert head.input_transform is None
+ transformed_inputs = head._transform_inputs(inputs)
+ assert transformed_inputs.shape == (1, 32, 45, 45)
+
+ # test input_transform = resize_concat
+ inputs = [torch.randn(1, 32, 45, 45), torch.randn(1, 16, 21, 21)]
+ head = BaseDecodeHead([32, 16],
+ 16,
+ num_classes=19,
+ in_index=[0, 1],
+ input_transform='resize_concat')
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ assert head.in_channels == 48
+ assert head.input_transform == 'resize_concat'
+ transformed_inputs = head._transform_inputs(inputs)
+ assert transformed_inputs.shape == (1, 48, 45, 45)
+
+ # test multi-loss, loss_decode is dict
+ with pytest.raises(TypeError):
+ # loss_decode must be a dict or sequence of dict.
+ BaseDecodeHead(3, 16, num_classes=19, loss_decode=['CrossEntropyLoss'])
+
+ inputs = torch.randn(2, 19, 8, 8).float()
+ target = torch.ones(2, 1, 64, 64).long()
+ head = BaseDecodeHead(
+ 3,
+ 16,
+ num_classes=19,
+ loss_decode=dict(
+ type='CrossEntropyLoss', use_sigmoid=False, loss_weight=1.0))
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ head, target = to_cuda(head, target)
+ loss = head.losses(seg_logit=inputs, seg_label=target)
+ assert 'loss_ce' in loss
+
+ # test multi-loss, loss_decode is list of dict
+ inputs = torch.randn(2, 19, 8, 8).float()
+ target = torch.ones(2, 1, 64, 64).long()
+ head = BaseDecodeHead(
+ 3,
+ 16,
+ num_classes=19,
+ loss_decode=[
+ dict(type='CrossEntropyLoss', loss_name='loss_1'),
+ dict(type='CrossEntropyLoss', loss_name='loss_2')
+ ])
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ head, target = to_cuda(head, target)
+ loss = head.losses(seg_logit=inputs, seg_label=target)
+ assert 'loss_1' in loss
+ assert 'loss_2' in loss
+
+ # 'loss_decode' must be a dict or sequence of dict
+ with pytest.raises(TypeError):
+ BaseDecodeHead(3, 16, num_classes=19, loss_decode=['CrossEntropyLoss'])
+ with pytest.raises(TypeError):
+ BaseDecodeHead(3, 16, num_classes=19, loss_decode=0)
+
+ # test multi-loss, loss_decode is list of dict
+ inputs = torch.randn(2, 19, 8, 8).float()
+ target = torch.ones(2, 1, 64, 64).long()
+ head = BaseDecodeHead(
+ 3,
+ 16,
+ num_classes=19,
+ loss_decode=(dict(type='CrossEntropyLoss', loss_name='loss_1'),
+ dict(type='CrossEntropyLoss', loss_name='loss_2'),
+ dict(type='CrossEntropyLoss', loss_name='loss_3')))
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ head, target = to_cuda(head, target)
+ loss = head.losses(seg_logit=inputs, seg_label=target)
+ assert 'loss_1' in loss
+ assert 'loss_2' in loss
+ assert 'loss_3' in loss
+
+ # test multi-loss, loss_decode is list of dict, names of them are identical
+ inputs = torch.randn(2, 19, 8, 8).float()
+ target = torch.ones(2, 1, 64, 64).long()
+ head = BaseDecodeHead(
+ 3,
+ 16,
+ num_classes=19,
+ loss_decode=(dict(type='CrossEntropyLoss', loss_name='loss_ce'),
+ dict(type='CrossEntropyLoss', loss_name='loss_ce'),
+ dict(type='CrossEntropyLoss', loss_name='loss_ce')))
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ head, target = to_cuda(head, target)
+ loss_3 = head.losses(seg_logit=inputs, seg_label=target)
+
+ head = BaseDecodeHead(
+ 3,
+ 16,
+ num_classes=19,
+ loss_decode=(dict(type='CrossEntropyLoss', loss_name='loss_ce')))
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ head, target = to_cuda(head, target)
+ loss = head.losses(seg_logit=inputs, seg_label=target)
+ assert 'loss_ce' in loss
+ assert 'loss_ce' in loss_3
+ assert loss_3['loss_ce'] == 3 * loss['loss_ce']
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_dm_head.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_dm_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..a922ff72950de236c024ef0f311b0abe994bc3a5
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_dm_head.py
@@ -0,0 +1,59 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.decode_heads import DMHead
+from .utils import _conv_has_norm, to_cuda
+
+
+def test_dm_head():
+
+ with pytest.raises(AssertionError):
+ # filter_sizes must be list|tuple
+ DMHead(in_channels=8, channels=4, num_classes=19, filter_sizes=1)
+
+ # test no norm_cfg
+ head = DMHead(in_channels=8, channels=4, num_classes=19)
+ assert not _conv_has_norm(head, sync_bn=False)
+
+ # test with norm_cfg
+ head = DMHead(
+ in_channels=8,
+ channels=4,
+ num_classes=19,
+ norm_cfg=dict(type='SyncBN'))
+ assert _conv_has_norm(head, sync_bn=True)
+
+ # fusion=True
+ inputs = [torch.randn(1, 8, 23, 23)]
+ head = DMHead(
+ in_channels=8,
+ channels=4,
+ num_classes=19,
+ filter_sizes=(1, 3, 5),
+ fusion=True)
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ assert head.fusion is True
+ assert head.dcm_modules[0].filter_size == 1
+ assert head.dcm_modules[1].filter_size == 3
+ assert head.dcm_modules[2].filter_size == 5
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 23, 23)
+
+ # fusion=False
+ inputs = [torch.randn(1, 8, 23, 23)]
+ head = DMHead(
+ in_channels=8,
+ channels=4,
+ num_classes=19,
+ filter_sizes=(1, 3, 5),
+ fusion=False)
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ assert head.fusion is False
+ assert head.dcm_modules[0].filter_size == 1
+ assert head.dcm_modules[1].filter_size == 3
+ assert head.dcm_modules[2].filter_size == 5
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 23, 23)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_dnl_head.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_dnl_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..720cb07fc683e98949fb0ad89298cbf829a87dab
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_dnl_head.py
@@ -0,0 +1,44 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+
+from mmseg.models.decode_heads import DNLHead
+from .utils import to_cuda
+
+
+def test_dnl_head():
+ # DNL with 'embedded_gaussian' mode
+ head = DNLHead(in_channels=8, channels=4, num_classes=19)
+ assert len(head.convs) == 2
+ assert hasattr(head, 'dnl_block')
+ assert head.dnl_block.temperature == 0.05
+ inputs = [torch.randn(1, 8, 23, 23)]
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 23, 23)
+
+ # NonLocal2d with 'dot_product' mode
+ head = DNLHead(
+ in_channels=8, channels=4, num_classes=19, mode='dot_product')
+ inputs = [torch.randn(1, 8, 23, 23)]
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 23, 23)
+
+ # NonLocal2d with 'gaussian' mode
+ head = DNLHead(in_channels=8, channels=4, num_classes=19, mode='gaussian')
+ inputs = [torch.randn(1, 8, 23, 23)]
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 23, 23)
+
+ # NonLocal2d with 'concatenation' mode
+ head = DNLHead(
+ in_channels=8, channels=4, num_classes=19, mode='concatenation')
+ inputs = [torch.randn(1, 8, 23, 23)]
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 23, 23)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_dpt_head.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_dpt_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..0a6af610e18fe8eae1947672d80d1cd52ce42e98
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_dpt_head.py
@@ -0,0 +1,49 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+
+from mmseg.models.decode_heads import DPTHead
+
+
+def test_dpt_head():
+
+ with pytest.raises(AssertionError):
+ # input_transform must be 'multiple_select'
+ head = DPTHead(
+ in_channels=[768, 768, 768, 768],
+ channels=4,
+ num_classes=19,
+ in_index=[0, 1, 2, 3])
+
+ head = DPTHead(
+ in_channels=[768, 768, 768, 768],
+ channels=4,
+ num_classes=19,
+ in_index=[0, 1, 2, 3],
+ input_transform='multiple_select')
+
+ inputs = [[torch.randn(4, 768, 2, 2),
+ torch.randn(4, 768)] for _ in range(4)]
+ output = head(inputs)
+ assert output.shape == torch.Size((4, 19, 16, 16))
+
+ # test readout operation
+ head = DPTHead(
+ in_channels=[768, 768, 768, 768],
+ channels=4,
+ num_classes=19,
+ in_index=[0, 1, 2, 3],
+ input_transform='multiple_select',
+ readout_type='add')
+ output = head(inputs)
+ assert output.shape == torch.Size((4, 19, 16, 16))
+
+ head = DPTHead(
+ in_channels=[768, 768, 768, 768],
+ channels=4,
+ num_classes=19,
+ in_index=[0, 1, 2, 3],
+ input_transform='multiple_select',
+ readout_type='project')
+ output = head(inputs)
+ assert output.shape == torch.Size((4, 19, 16, 16))
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_ema_head.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_ema_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..1811cd2bb25eb6234975af28a9e10b054d678c71
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_ema_head.py
@@ -0,0 +1,23 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+
+from mmseg.models.decode_heads import EMAHead
+from .utils import to_cuda
+
+
+def test_emanet_head():
+ head = EMAHead(
+ in_channels=4,
+ ema_channels=3,
+ channels=2,
+ num_stages=3,
+ num_bases=2,
+ num_classes=19)
+ for param in head.ema_mid_conv.parameters():
+ assert not param.requires_grad
+ assert hasattr(head, 'ema_module')
+ inputs = [torch.randn(1, 4, 23, 23)]
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 23, 23)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_enc_head.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_enc_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..9c84c757c6305beca3fe8685979de1361db16b24
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_enc_head.py
@@ -0,0 +1,47 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+
+from mmseg.models.decode_heads import EncHead
+from .utils import to_cuda
+
+
+def test_enc_head():
+ # with se_loss, w.o. lateral
+ inputs = [torch.randn(1, 8, 21, 21)]
+ head = EncHead(in_channels=[8], channels=4, num_classes=19, in_index=[-1])
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ outputs = head(inputs)
+ assert isinstance(outputs, tuple) and len(outputs) == 2
+ assert outputs[0].shape == (1, head.num_classes, 21, 21)
+ assert outputs[1].shape == (1, head.num_classes)
+
+ # w.o se_loss, w.o. lateral
+ inputs = [torch.randn(1, 8, 21, 21)]
+ head = EncHead(
+ in_channels=[8],
+ channels=4,
+ use_se_loss=False,
+ num_classes=19,
+ in_index=[-1])
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 21, 21)
+
+ # with se_loss, with lateral
+ inputs = [torch.randn(1, 4, 45, 45), torch.randn(1, 8, 21, 21)]
+ head = EncHead(
+ in_channels=[4, 8],
+ channels=4,
+ add_lateral=True,
+ num_classes=19,
+ in_index=[-2, -1])
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ outputs = head(inputs)
+ assert isinstance(outputs, tuple) and len(outputs) == 2
+ assert outputs[0].shape == (1, head.num_classes, 21, 21)
+ assert outputs[1].shape == (1, head.num_classes)
+ test_output = head.forward_test(inputs, None, None)
+ assert test_output.shape == (1, head.num_classes, 21, 21)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_fcn_head.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_fcn_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..4e633fba483415eac86f97e5984699b947f82ca2
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_fcn_head.py
@@ -0,0 +1,131 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import pytest
+import torch
+from mmcv.cnn import ConvModule, DepthwiseSeparableConvModule
+from mmcv.utils.parrots_wrapper import SyncBatchNorm
+
+from mmseg.models.decode_heads import DepthwiseSeparableFCNHead, FCNHead
+from .utils import to_cuda
+
+
+def test_fcn_head():
+
+ with pytest.raises(AssertionError):
+ # num_convs must be not less than 0
+ FCNHead(num_classes=19, num_convs=-1)
+
+ # test no norm_cfg
+ head = FCNHead(in_channels=8, channels=4, num_classes=19)
+ for m in head.modules():
+ if isinstance(m, ConvModule):
+ assert not m.with_norm
+
+ # test with norm_cfg
+ head = FCNHead(
+ in_channels=8,
+ channels=4,
+ num_classes=19,
+ norm_cfg=dict(type='SyncBN'))
+ for m in head.modules():
+ if isinstance(m, ConvModule):
+ assert m.with_norm and isinstance(m.bn, SyncBatchNorm)
+
+ # test concat_input=False
+ inputs = [torch.randn(1, 8, 23, 23)]
+ head = FCNHead(
+ in_channels=8, channels=4, num_classes=19, concat_input=False)
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ assert len(head.convs) == 2
+ assert not head.concat_input and not hasattr(head, 'conv_cat')
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 23, 23)
+
+ # test concat_input=True
+ inputs = [torch.randn(1, 8, 23, 23)]
+ head = FCNHead(
+ in_channels=8, channels=4, num_classes=19, concat_input=True)
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ assert len(head.convs) == 2
+ assert head.concat_input
+ assert head.conv_cat.in_channels == 12
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 23, 23)
+
+ # test kernel_size=3
+ inputs = [torch.randn(1, 8, 23, 23)]
+ head = FCNHead(in_channels=8, channels=4, num_classes=19)
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ for i in range(len(head.convs)):
+ assert head.convs[i].kernel_size == (3, 3)
+ assert head.convs[i].padding == 1
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 23, 23)
+
+ # test kernel_size=1
+ inputs = [torch.randn(1, 8, 23, 23)]
+ head = FCNHead(in_channels=8, channels=4, num_classes=19, kernel_size=1)
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ for i in range(len(head.convs)):
+ assert head.convs[i].kernel_size == (1, 1)
+ assert head.convs[i].padding == 0
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 23, 23)
+
+ # test num_conv
+ inputs = [torch.randn(1, 8, 23, 23)]
+ head = FCNHead(in_channels=8, channels=4, num_classes=19, num_convs=1)
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ assert len(head.convs) == 1
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 23, 23)
+
+ # test num_conv = 0
+ inputs = [torch.randn(1, 8, 23, 23)]
+ head = FCNHead(
+ in_channels=8,
+ channels=8,
+ num_classes=19,
+ num_convs=0,
+ concat_input=False)
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ assert isinstance(head.convs, torch.nn.Identity)
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 23, 23)
+
+
+def test_sep_fcn_head():
+ # test sep_fcn_head with concat_input=False
+ head = DepthwiseSeparableFCNHead(
+ in_channels=128,
+ channels=128,
+ concat_input=False,
+ num_classes=19,
+ in_index=-1,
+ norm_cfg=dict(type='BN', requires_grad=True, momentum=0.01))
+ x = [torch.rand(2, 128, 8, 8)]
+ output = head(x)
+ assert output.shape == (2, head.num_classes, 8, 8)
+ assert not head.concat_input
+ assert isinstance(head.convs[0], DepthwiseSeparableConvModule)
+ assert isinstance(head.convs[1], DepthwiseSeparableConvModule)
+ assert head.conv_seg.kernel_size == (1, 1)
+
+ head = DepthwiseSeparableFCNHead(
+ in_channels=64,
+ channels=64,
+ concat_input=True,
+ num_classes=19,
+ in_index=-1,
+ norm_cfg=dict(type='BN', requires_grad=True, momentum=0.01))
+ x = [torch.rand(3, 64, 8, 8)]
+ output = head(x)
+ assert output.shape == (3, head.num_classes, 8, 8)
+ assert head.concat_input
+ assert isinstance(head.convs[0], DepthwiseSeparableConvModule)
+ assert isinstance(head.convs[1], DepthwiseSeparableConvModule)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_gc_head.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_gc_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..c62ac9ae74fa645c20f74fba893c85ef015cb54e
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_gc_head.py
@@ -0,0 +1,16 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+
+from mmseg.models.decode_heads import GCHead
+from .utils import to_cuda
+
+
+def test_gc_head():
+ head = GCHead(in_channels=4, channels=4, num_classes=19)
+ assert len(head.convs) == 2
+ assert hasattr(head, 'gc_block')
+ inputs = [torch.randn(1, 4, 23, 23)]
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 23, 23)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_isa_head.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_isa_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..b177f6d23ebc60a004435c6d9134e1ef8e8eb00a
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_isa_head.py
@@ -0,0 +1,20 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+
+from mmseg.models.decode_heads import ISAHead
+from .utils import to_cuda
+
+
+def test_isa_head():
+
+ inputs = [torch.randn(1, 8, 23, 23)]
+ isa_head = ISAHead(
+ in_channels=8,
+ channels=4,
+ num_classes=19,
+ isa_channels=4,
+ down_factor=(8, 8))
+ if torch.cuda.is_available():
+ isa_head, inputs = to_cuda(isa_head, inputs)
+ output = isa_head(inputs)
+ assert output.shape == (1, isa_head.num_classes, 23, 23)
diff --git a/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_knet_head.py b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_knet_head.py
new file mode 100644
index 0000000000000000000000000000000000000000..e6845a6d3fbaef07810fdf01930da0d08838863c
--- /dev/null
+++ b/EgoHOS/raw/script/mmsegmentation/tests/test_models/test_heads/test_knet_head.py
@@ -0,0 +1,195 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import torch
+
+from mmseg.models.decode_heads.knet_head import (IterativeDecodeHead,
+ KernelUpdateHead)
+from .utils import to_cuda
+
+num_stages = 3
+conv_kernel_size = 1
+
+kernel_updator_cfg = dict(
+ type='KernelUpdator',
+ in_channels=16,
+ feat_channels=16,
+ out_channels=16,
+ gate_norm_act=True,
+ activate_out=True,
+ act_cfg=dict(type='ReLU', inplace=True),
+ norm_cfg=dict(type='LN'))
+
+
+def test_knet_head():
+ # test init function of kernel update head
+ kernel_update_head = KernelUpdateHead(
+ num_classes=150,
+ num_ffn_fcs=2,
+ num_heads=8,
+ num_mask_fcs=1,
+ feedforward_channels=128,
+ in_channels=32,
+ out_channels=32,
+ dropout=0.0,
+ conv_kernel_size=conv_kernel_size,
+ ffn_act_cfg=dict(type='ReLU', inplace=True),
+ with_ffn=True,
+ feat_transform_cfg=dict(conv_cfg=dict(type='Conv2d'), act_cfg=None),
+ kernel_init=True,
+ kernel_updator_cfg=kernel_updator_cfg)
+ kernel_update_head.init_weights()
+
+ head = IterativeDecodeHead(
+ num_stages=num_stages,
+ kernel_update_head=[
+ dict(
+ type='KernelUpdateHead',
+ num_classes=150,
+ num_ffn_fcs=2,
+ num_heads=8,
+ num_mask_fcs=1,
+ feedforward_channels=128,
+ in_channels=32,
+ out_channels=32,
+ dropout=0.0,
+ conv_kernel_size=conv_kernel_size,
+ ffn_act_cfg=dict(type='ReLU', inplace=True),
+ with_ffn=True,
+ feat_transform_cfg=dict(
+ conv_cfg=dict(type='Conv2d'), act_cfg=None),
+ kernel_init=False,
+ kernel_updator_cfg=kernel_updator_cfg)
+ for _ in range(num_stages)
+ ],
+ kernel_generate_head=dict(
+ type='FCNHead',
+ in_channels=128,
+ in_index=3,
+ channels=32,
+ num_convs=2,
+ concat_input=True,
+ dropout_ratio=0.1,
+ num_classes=150,
+ align_corners=False))
+ head.init_weights()
+ inputs = [
+ torch.randn(1, 16, 27, 32),
+ torch.randn(1, 32, 27, 16),
+ torch.randn(1, 64, 27, 16),
+ torch.randn(1, 128, 27, 16)
+ ]
+
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ outputs = head(inputs)
+ assert outputs[-1].shape == (1, head.num_classes, 27, 16)
+
+ # test whether only return the prediction of
+ # the last stage during testing
+ with torch.no_grad():
+ head.eval()
+ outputs = head(inputs)
+ assert outputs.shape == (1, head.num_classes, 27, 16)
+
+ # test K-Net without `feat_transform_cfg`
+ head = IterativeDecodeHead(
+ num_stages=num_stages,
+ kernel_update_head=[
+ dict(
+ type='KernelUpdateHead',
+ num_classes=150,
+ num_ffn_fcs=2,
+ num_heads=8,
+ num_mask_fcs=1,
+ feedforward_channels=128,
+ in_channels=32,
+ out_channels=32,
+ dropout=0.0,
+ conv_kernel_size=conv_kernel_size,
+ ffn_act_cfg=dict(type='ReLU', inplace=True),
+ with_ffn=True,
+ feat_transform_cfg=None,
+ kernel_updator_cfg=kernel_updator_cfg)
+ for _ in range(num_stages)
+ ],
+ kernel_generate_head=dict(
+ type='FCNHead',
+ in_channels=128,
+ in_index=3,
+ channels=32,
+ num_convs=2,
+ concat_input=True,
+ dropout_ratio=0.1,
+ num_classes=150,
+ align_corners=False))
+ head.init_weights()
+
+ inputs = [
+ torch.randn(1, 16, 27, 32),
+ torch.randn(1, 32, 27, 16),
+ torch.randn(1, 64, 27, 16),
+ torch.randn(1, 128, 27, 16)
+ ]
+
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ outputs = head(inputs)
+ assert outputs[-1].shape == (1, head.num_classes, 27, 16)
+
+ # test K-Net with
+ # self.mask_transform_stride == 2 and self.feat_gather_stride == 1
+ head = IterativeDecodeHead(
+ num_stages=num_stages,
+ kernel_update_head=[
+ dict(
+ type='KernelUpdateHead',
+ num_classes=150,
+ num_ffn_fcs=2,
+ num_heads=8,
+ num_mask_fcs=1,
+ feedforward_channels=128,
+ in_channels=32,
+ out_channels=32,
+ dropout=0.0,
+ conv_kernel_size=conv_kernel_size,
+ ffn_act_cfg=dict(type='ReLU', inplace=True),
+ with_ffn=True,
+ feat_transform_cfg=dict(
+ conv_cfg=dict(type='Conv2d'), act_cfg=None),
+ kernel_init=False,
+ mask_transform_stride=2,
+ feat_gather_stride=1,
+ kernel_updator_cfg=kernel_updator_cfg)
+ for _ in range(num_stages)
+ ],
+ kernel_generate_head=dict(
+ type='FCNHead',
+ in_channels=128,
+ in_index=3,
+ channels=32,
+ num_convs=2,
+ concat_input=True,
+ dropout_ratio=0.1,
+ num_classes=150,
+ align_corners=False))
+ head.init_weights()
+
+ inputs = [
+ torch.randn(1, 16, 27, 32),
+ torch.randn(1, 32, 27, 16),
+ torch.randn(1, 64, 27, 16),
+ torch.randn(1, 128, 27, 16)
+ ]
+
+ if torch.cuda.is_available():
+ head, inputs = to_cuda(head, inputs)
+ outputs = head(inputs)
+ assert outputs[-1].shape == (1, head.num_classes, 26, 16)
+
+ # test loss function in K-Net
+ fake_label = torch.ones_like(
+ outputs[-1][:, 0:1, :, :], dtype=torch.int16).long()
+ loss = head.losses(seg_logit=outputs, seg_label=fake_label)
+ assert loss['loss_ce.s0'] != torch.zeros_like(loss['loss_ce.s0'])
+ assert loss['loss_ce.s1'] != torch.zeros_like(loss['loss_ce.s1'])
+ assert loss['loss_ce.s2'] != torch.zeros_like(loss['loss_ce.s2'])
+ assert loss['loss_ce.s3'] != torch.zeros_like(loss['loss_ce.s3'])