diff --git a/VideoX-Fun/comfyui/README.md b/VideoX-Fun/comfyui/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..ed17f1d3e6cf5e3ebf16864ef854c3b761aaf2c2
--- /dev/null
+++ b/VideoX-Fun/comfyui/README.md
@@ -0,0 +1,272 @@
+# ComfyUI VideoX-Fun
+Easily use VideoX-Fun and Wan2.1-Fun inside ComfyUI!
+
+- [Installation](#1-installation)
+- [Node types](#node-types)
+- [Example workflows](#example-workflows)
+
+## Installation
+### 1. ComfyUI Installation
+
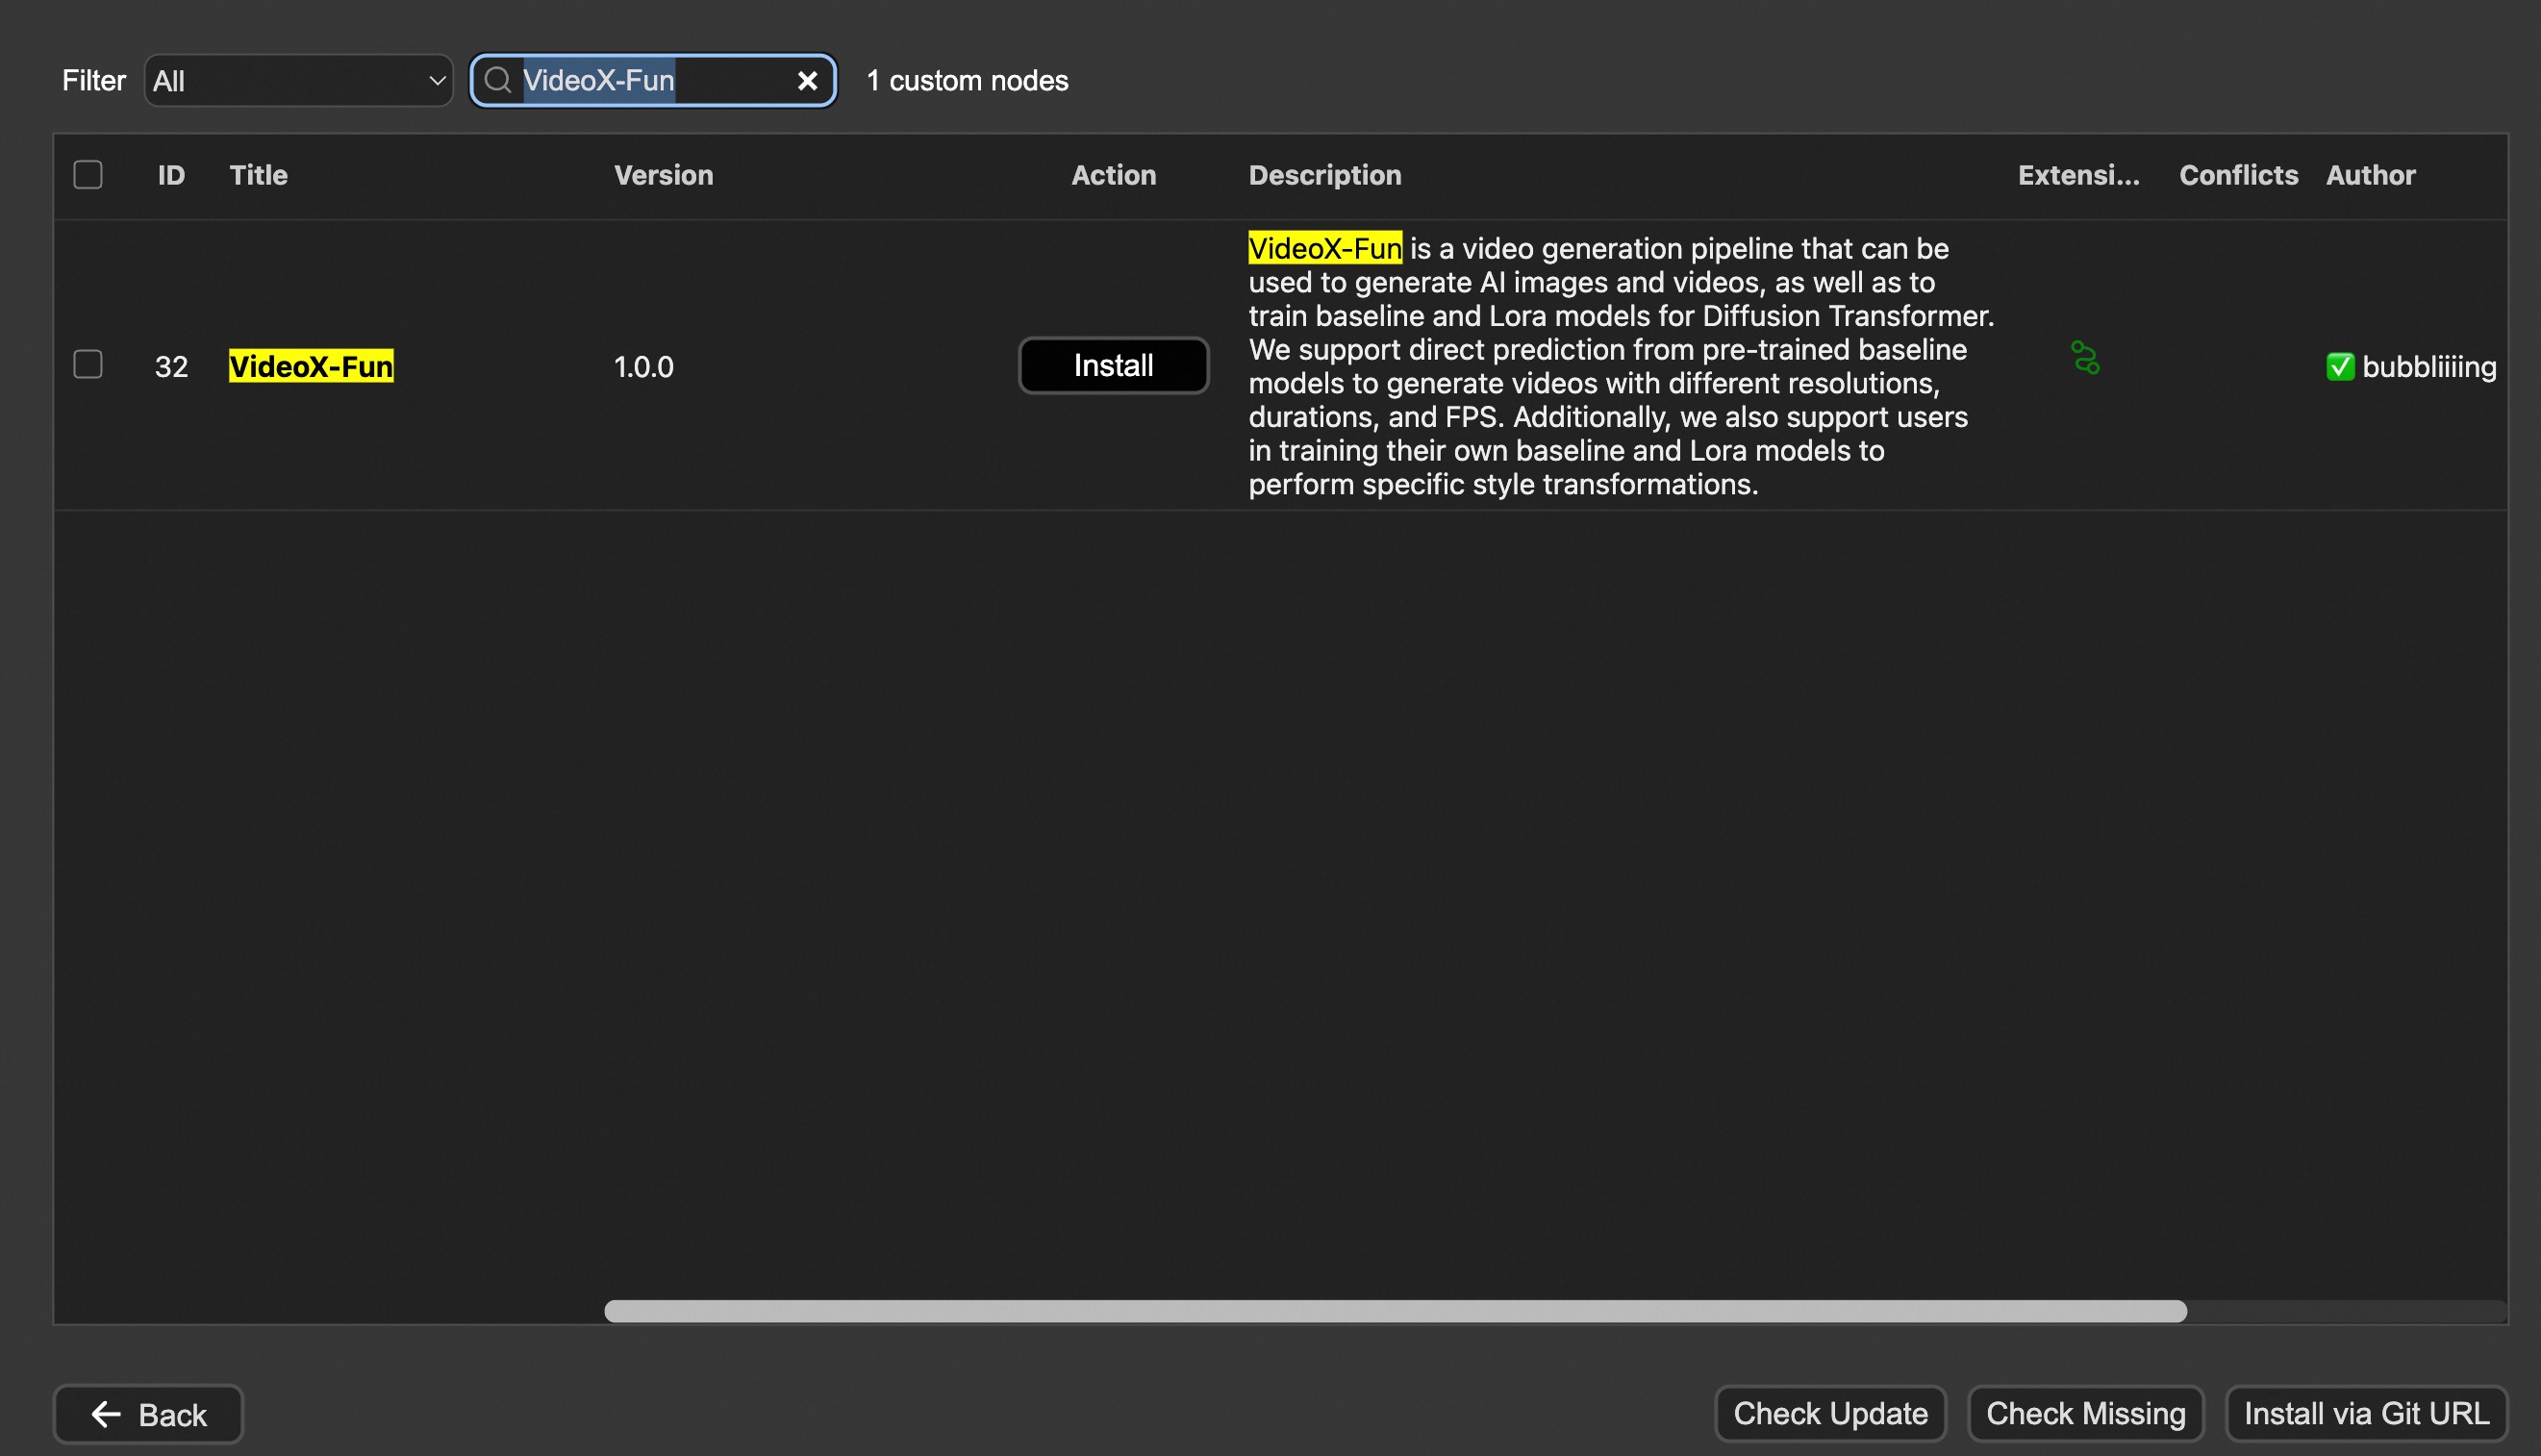
+#### Option 1: Install via ComfyUI Manager
+
+
+#### Option 2: Install manually
+The VideoX-Fun repository needs to be placed at `ComfyUI/custom_nodes/VideoX-Fun/`.
+
+```
+cd ComfyUI/custom_nodes/
+
+# Git clone the cogvideox_fun itself
+git clone https://github.com/aigc-apps/VideoX-Fun.git
+
+# Git clone the video outout node
+git clone https://github.com/Kosinkadink/ComfyUI-VideoHelperSuite.git
+
+# Git clone the KJ Nodes
+git clone https://github.com/kijai/ComfyUI-KJNodes.git
+
+cd VideoX-Fun/
+python install.py
+```
+
+### 2. Download models into `ComfyUI/models/Fun_Models/`
+
+### 3. (Optional) Download preprocess weights into `ComfyUI/custom_nodes/Fun_Models/Third_Party/`.
+Except for the fun models' weights, if you want to use the control preprocess nodes, you can download the preprocess weights to `ComfyUI/custom_nodes/Fun_Models/Third_Party/`.
+
+```
+remote_onnx_det = "https://huggingface.co/yzd-v/DWPose/resolve/main/yolox_l.onnx"
+remote_onnx_pose = "https://huggingface.co/yzd-v/DWPose/resolve/main/dw-ll_ucoco_384.onnx"
+remote_zoe= "https://huggingface.co/lllyasviel/Annotators/resolve/main/ZoeD_M12_N.pt"
+```
+#### i. Wan2.2-Fun
+| Name | Hugging Face | Model Scope | Description |
+|--|--|--|--|--|
+| Wan2.2-Fun-A14B-InP | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-InP) | Wan2.2-Fun-14B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction. |
+| Wan2.2-Fun-A14B-Control | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control)| Wan2.2-Fun-14B video control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc., and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction at 81 frames, trained at 16 frames per second, with multilingual prediction support. |
+| Wan2.2-Fun-A14B-Control-Camera | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control-Camera)| Wan2.2-Fun-14B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
+| Wan2.2-Fun-5B-InP | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-InP) | Wan2.2-Fun-5B text-to-video weights trained at 121 frames, 24 FPS, supporting first/last frame prediction. |
+| Wan2.2-Fun-5B-Control | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control)| Wan2.2-Fun-5B video control weights, supporting control conditions like Canny, Depth, Pose, MLSD, and trajectory control. Trained at 121 frames, 24 FPS, with multilingual prediction support. |
+| Wan2.2-Fun-5B-Control-Camera | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control-Camera)| Wan2.2-Fun-5B camera lens control weights. Trained at 121 frames, 24 FPS, with multilingual prediction support. |
+
+#### ii. Wan2.2
+
+| Name | Hugging Face | Model Scope | Description |
+|--|--|--|--|
+| Wan2.2-TI2V-5B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-TI2V-5B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-TI2V-5B) | Wan2.2-5B Text-to-Video Weights |
+| Wan2.2-T2V-14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-T2V-A14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-T2V-A14B) | Wan2.2-14B Text-to-Video Weights |
+| Wan2.2-I2V-A14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-I2V-A14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-I2V-A14B) | Wan2.2-I2V-A14B Image-to-Video Weights |
+
+#### iii. Wan2.1-Fun
+
+V1.1:
+| Name | Storage Size | Hugging Face | Model Scope | Description |
+|------|--------------|--------------|-------------|-------------|
+| Wan2.1-Fun-V1.1-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-InP) | Wan2.1-Fun-V1.1-1.3B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction. |
+| Wan2.1-Fun-V1.1-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP) | Wan2.1-Fun-V1.1-14B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction. |
+| Wan2.1-Fun-V1.1-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control) | Wan2.1-Fun-V1.1-1.3B video control weights support various control conditions such as Canny, Depth, Pose, MLSD, etc., supports reference image + control condition-based control, and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
+| Wan2.1-Fun-V1.1-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control) | Wan2.1-Fun-V1.1-14B video control weights support various control conditions such as Canny, Depth, Pose, MLSD, etc., supports reference image + control condition-based control, and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
+| Wan2.1-Fun-V1.1-1.3B-Control-Camera | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control-Camera) | Wan2.1-Fun-V1.1-1.3B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
+| Wan2.1-Fun-V1.1-14B-Control-Camera | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control-Camera) | Wan2.1-Fun-V1.1-14B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
+
+V1.0:
+| Name | Storage Space | Hugging Face | Model Scope | Description |
+|--|--|--|--|--|
+| Wan2.1-Fun-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-InP) | Wan2.1-Fun-1.3B text-to-video weights, trained at multiple resolutions, supporting start and end frame prediction. |
+| Wan2.1-Fun-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-InP) | Wan2.1-Fun-14B text-to-video weights, trained at multiple resolutions, supporting start and end frame prediction. |
+| Wan2.1-Fun-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-Control) | Wan2.1-Fun-1.3B video control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc., and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction at 81 frames, trained at 16 frames per second, with multilingual prediction support. |
+| Wan2.1-Fun-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-Control) | Wan2.1-Fun-14B video control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc., and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction at 81 frames, trained at 16 frames per second, with multilingual prediction support. |
+
+#### iv. Wan2.1
+
+| Name | Hugging Face | Model Scope | Description |
+|--|--|--|--|
+| Wan2.1-T2V-1.3B | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-InP) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-1.3B) | Wanxiang 2.1-1.3B text-to-video weights |
+| Wan2.1-T2V-14B | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-InP) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-14B) | Wanxiang 2.1-14B text-to-video weights |
+| Wan2.1-I2V-14B-480P | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-InP) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-480P) | Wanxiang 2.1-14B-480P image-to-video weights |
+| Wan2.1-I2V-14B-720P| [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-InP) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | Wanxiang 2.1-14B-720P image-to-video weights |
+
+#### v. CogVideoX-Fun
+
+V1.5:
+
+| Name | Storage Space | Hugging Face | Model Scope | Description |
+|--|--|--|--|--|
+| CogVideoX-Fun-V1.5-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.5-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-5b-InP) | Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024) and has been trained on 85 frames at a rate of 8 frames per second. |
+| CogVideoX-Fun-V1.5-Reward-LoRAs | - | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-Reward-LoRAs) | The official reward backpropagation technology model optimizes the videos generated by CogVideoX-Fun-V1.5 to better match human preferences. |
+
+V1.1:
+
+| Name | Storage Space | Hugging Face | Model Scope | Description |
+|--|--|--|--|--|
+| CogVideoX-Fun-V1.1-2b-InP | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-InP) | Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. |
+| CogVideoX-Fun-V1.1-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP) | Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. Noise has been added to the reference image, and the amplitude of motion is greater compared to V1.0. |
+| CogVideoX-Fun-V1.1-2b-Pose | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Pose) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Pose) | Our official pose-control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second.|
+| CogVideoX-Fun-V1.1-2b-Control | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Control) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Control) | Our official control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. Supporting various control conditions such as Canny, Depth, Pose, MLSD, etc.|
+| CogVideoX-Fun-V1.1-5b-Pose | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Pose) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Pose) | Our official pose-control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second.|
+| CogVideoX-Fun-V1.1-5b-Control | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Control) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Control) | Our official control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. Supporting various control conditions such as Canny, Depth, Pose, MLSD, etc.|
+| CogVideoX-Fun-V1.1-Reward-LoRAs | - | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-Reward-LoRAs) | The official reward backpropagation technology model optimizes the videos generated by CogVideoX-Fun-V1.1 to better match human preferences. |
+
+
+ (Obsolete) V1.0:
+
+| Name | Storage Space | Hugging Face | Model Scope | Description |
+|--|--|--|--|--|
+| CogVideoX-Fun-2b-InP | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-2b-InP) | Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. |
+| CogVideoX-Fun-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-5b-InP)| [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-5b-InP)| Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. |
+
+
+### 3. (Optional) Download Lora models into `ComfyUI/models/loras/fun_models/`
+If you want to use lora in CogVideoX-Fun, please put the lora to `ComfyUI/models/loras/fun_models/`.
+
+## Node types
+### 1. Wan-Fun
+- **LoadWanFunModel**
+ - Loads the Wan-Fun Model.
+- **LoadWanFunLora**
+ - Write the prompt for Wan-Fun model
+- **WanFunInpaintSampler**
+ - Wan-Fun Sampler for Image to Video
+- **WanFunT2VSampler**
+ - Wan-Fun Sampler for Text to Video
+
+### 2. Wan
+- **LoadWanModel**
+ - Loads the Wan-Fun Model.
+- **LoadWanLora**
+ - Write the prompt for Wan-Fun model
+- **WanI2VSampler**
+ - Wan-Fun Sampler for Image to Video
+- **WanT2VSampler**
+ - Wan-Fun Sampler for Text to Video
+
+### 3. CogVideoX-Fun
+- **LoadCogVideoXFunModel**
+ - Loads the CogVideoX-Fun model
+- **FunTextBox**
+ - Write the prompt for CogVideoX-Fun model
+- **CogVideoXFunInpaintSampler**
+ - CogVideoX-Fun Sampler for Image to Video
+- **CogVideoXFunT2VSampler**
+ - CogVideoX-Fun Sampler for Text to Video
+- **CogVideoXFunV2VSampler**
+ - CogVideoX-Fun Sampler for Video to Video
+
+## Example workflows
+### 1. Wan-Fun
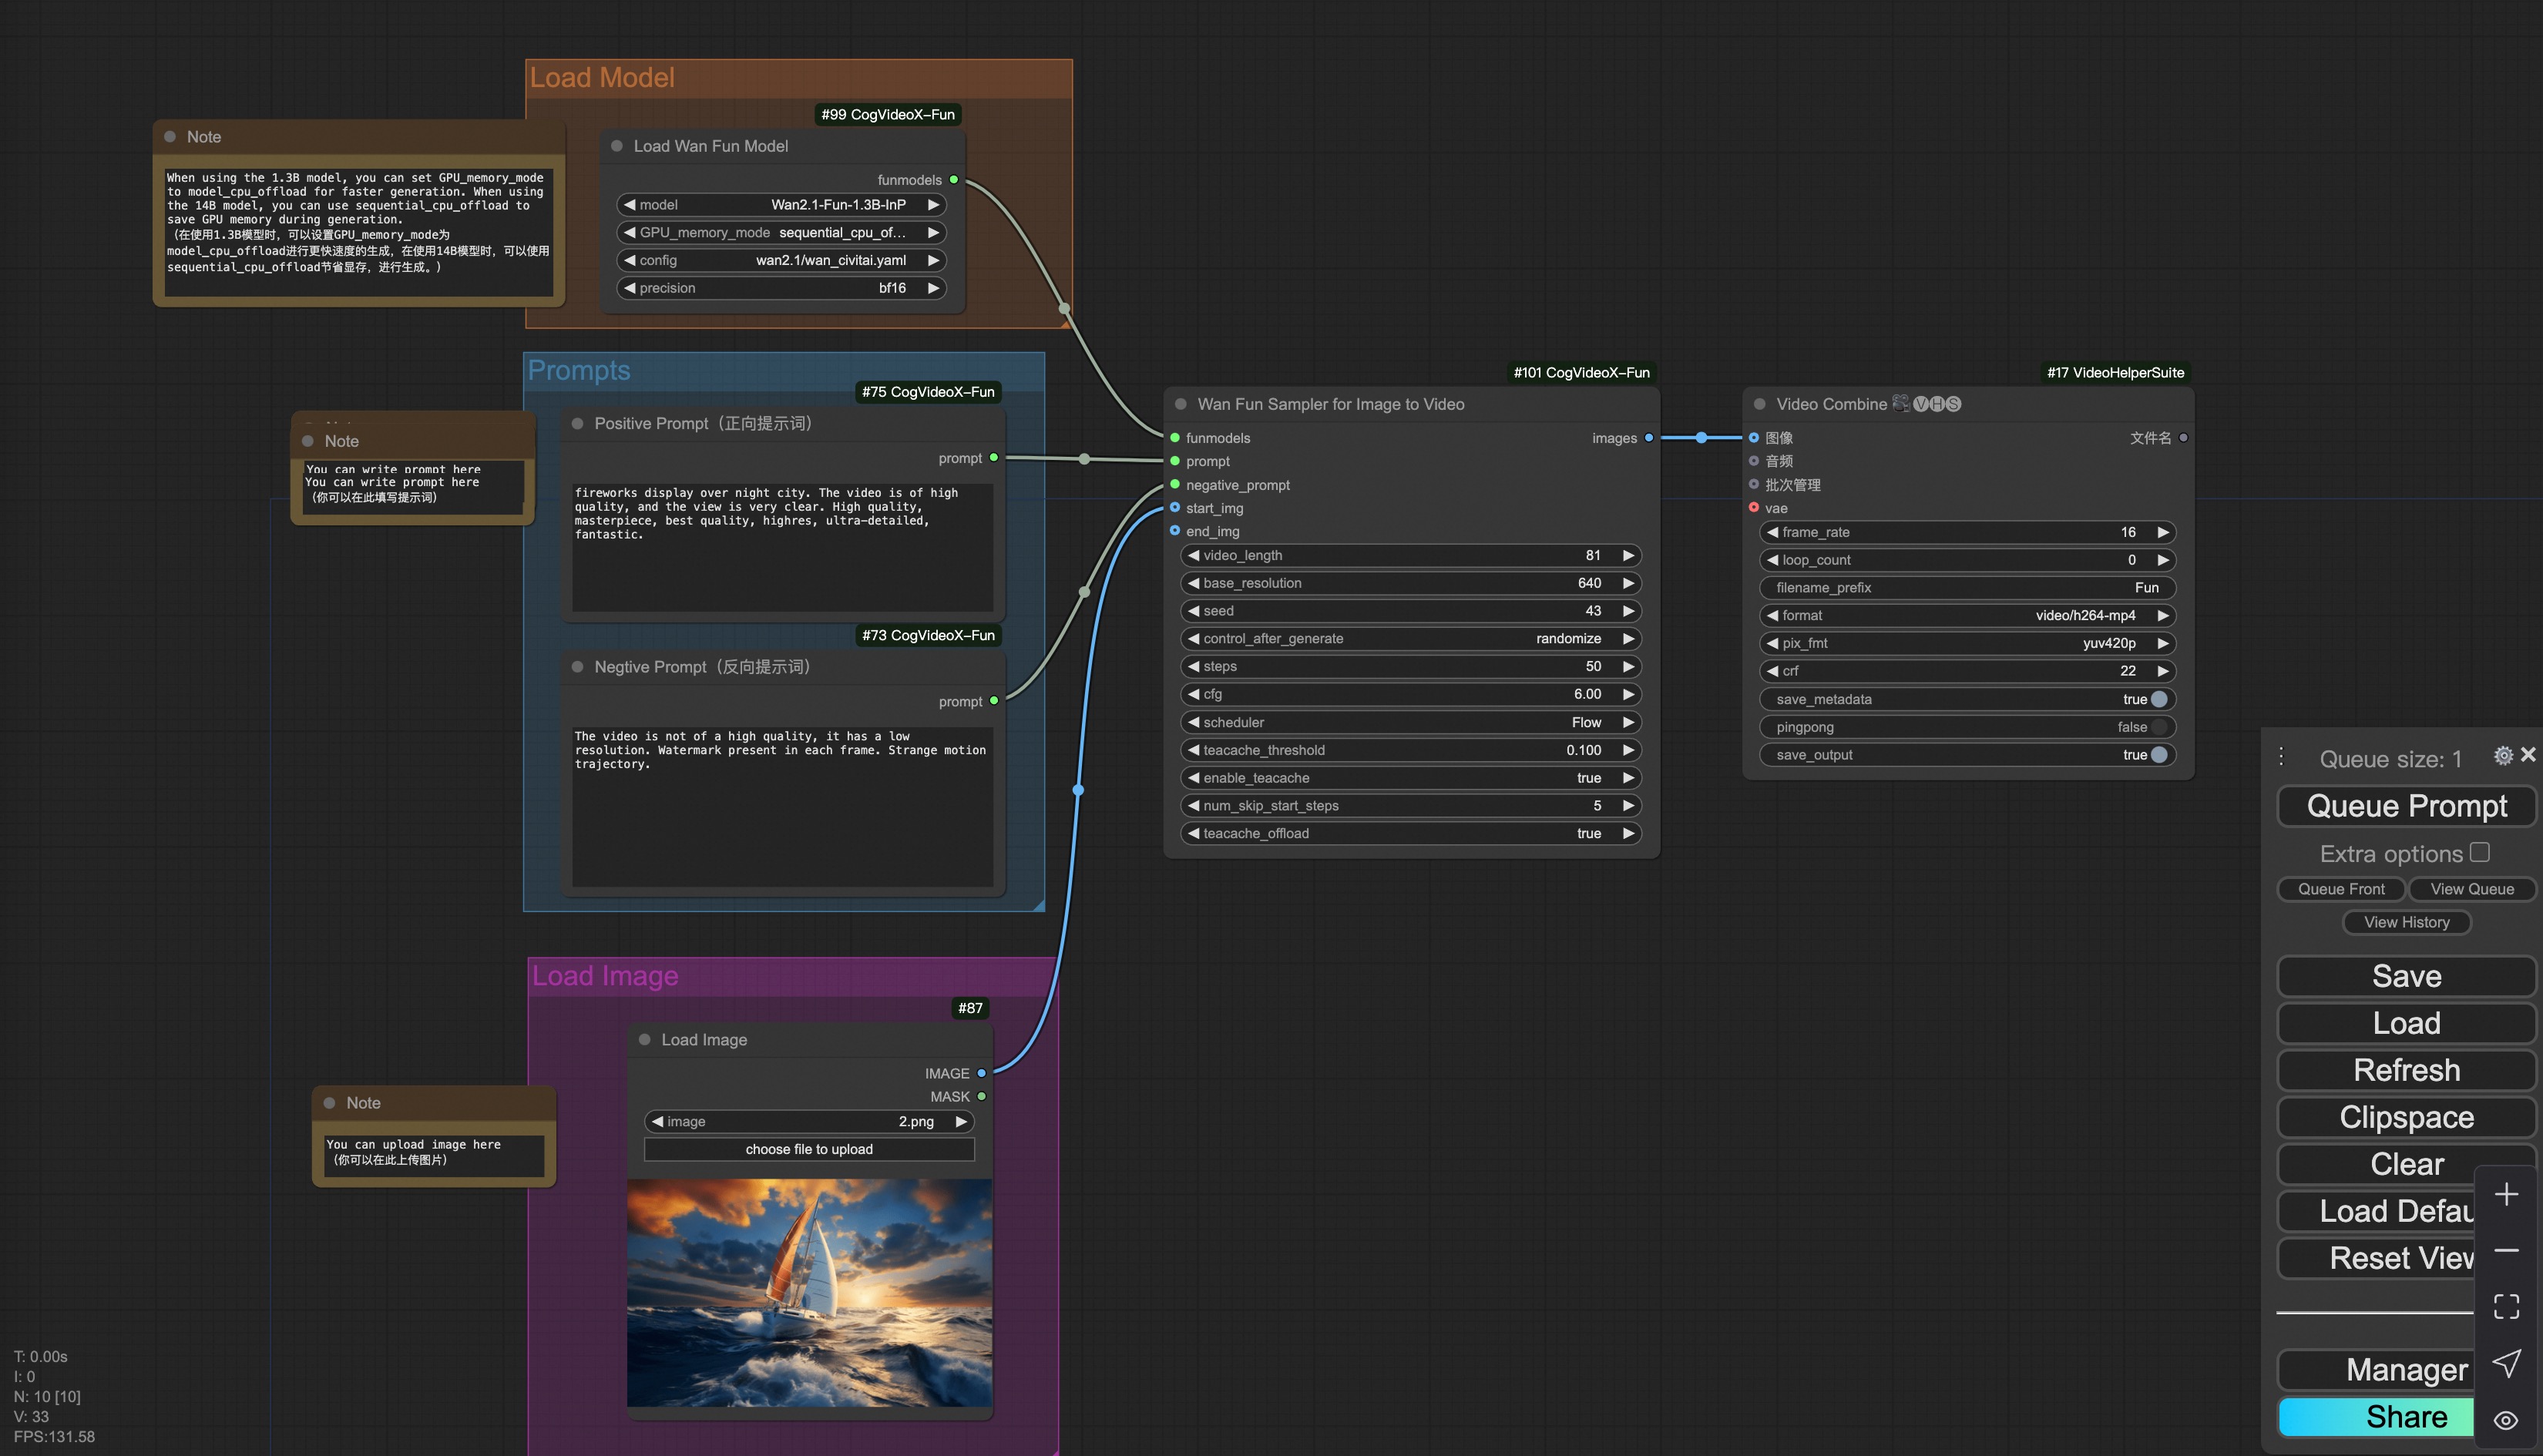
+#### i. Image to video generation
+[Download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_i2v.json) for wan-fun.
+
+Our ui is shown as follow:
+
+
+You can run the demo using following photo:
+
+
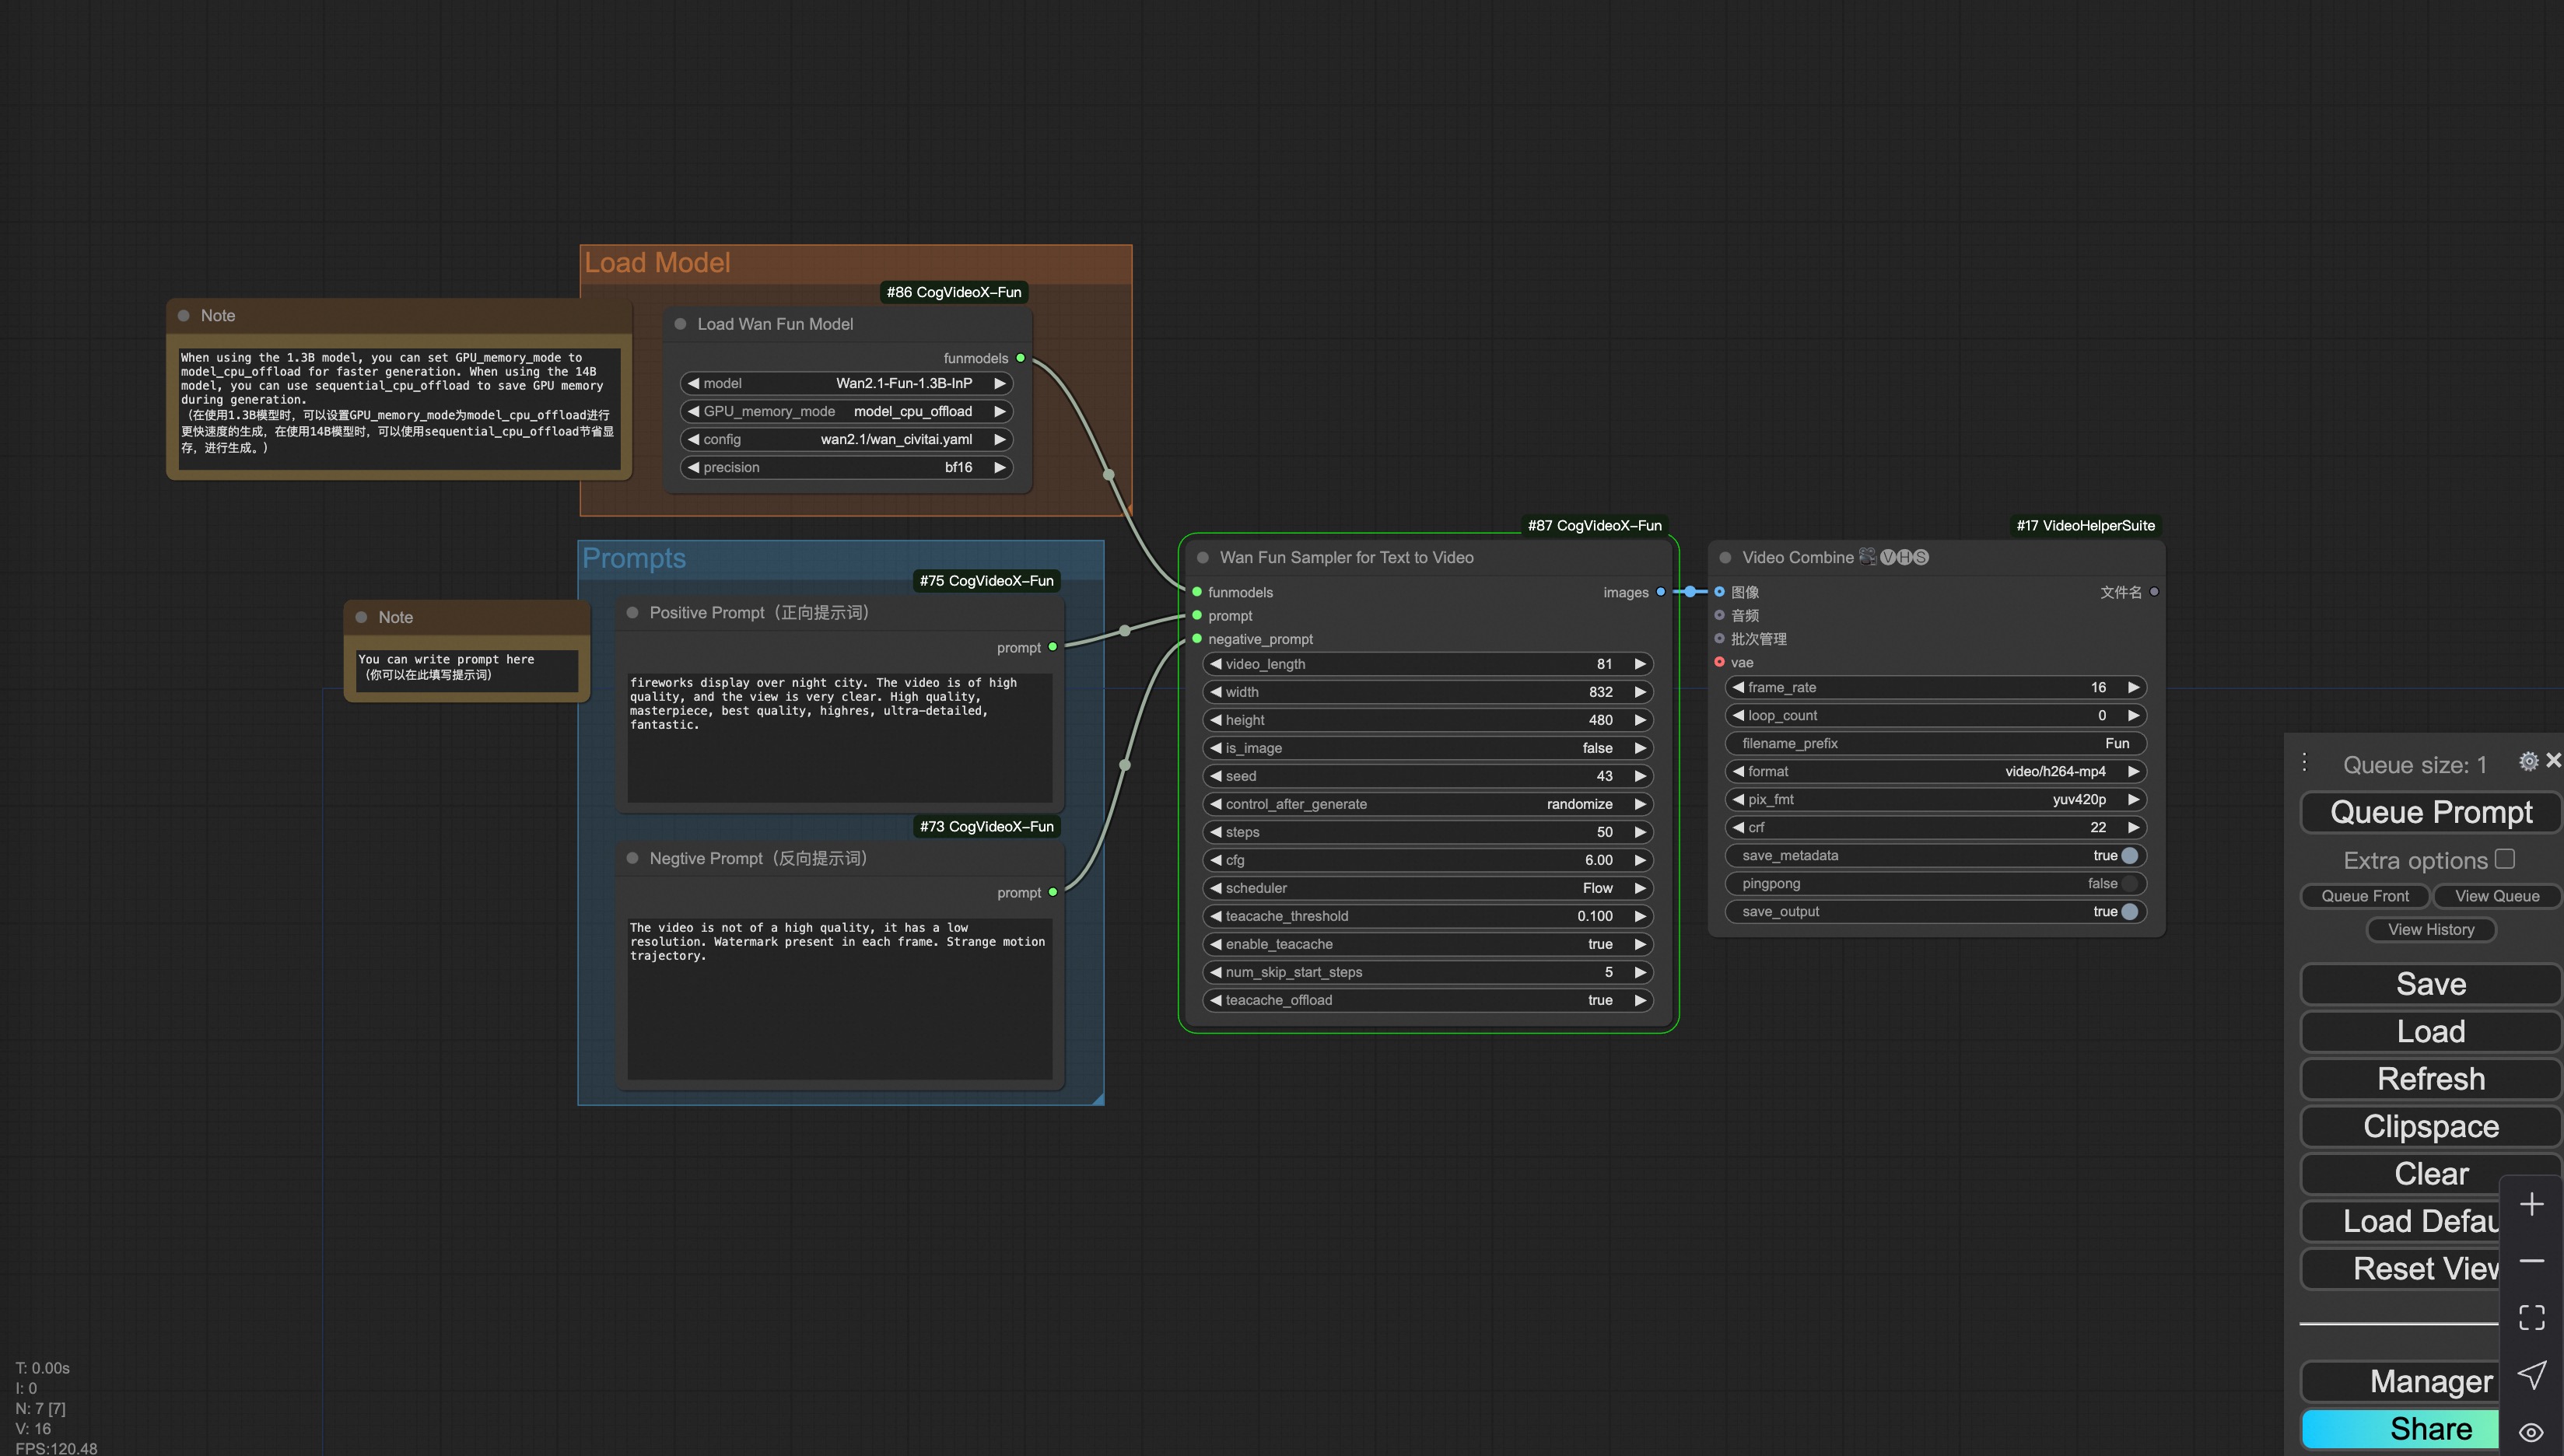
+#### ii. Text to video generation
+[Download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_t2v.json) for wan-fun.
+
+
+
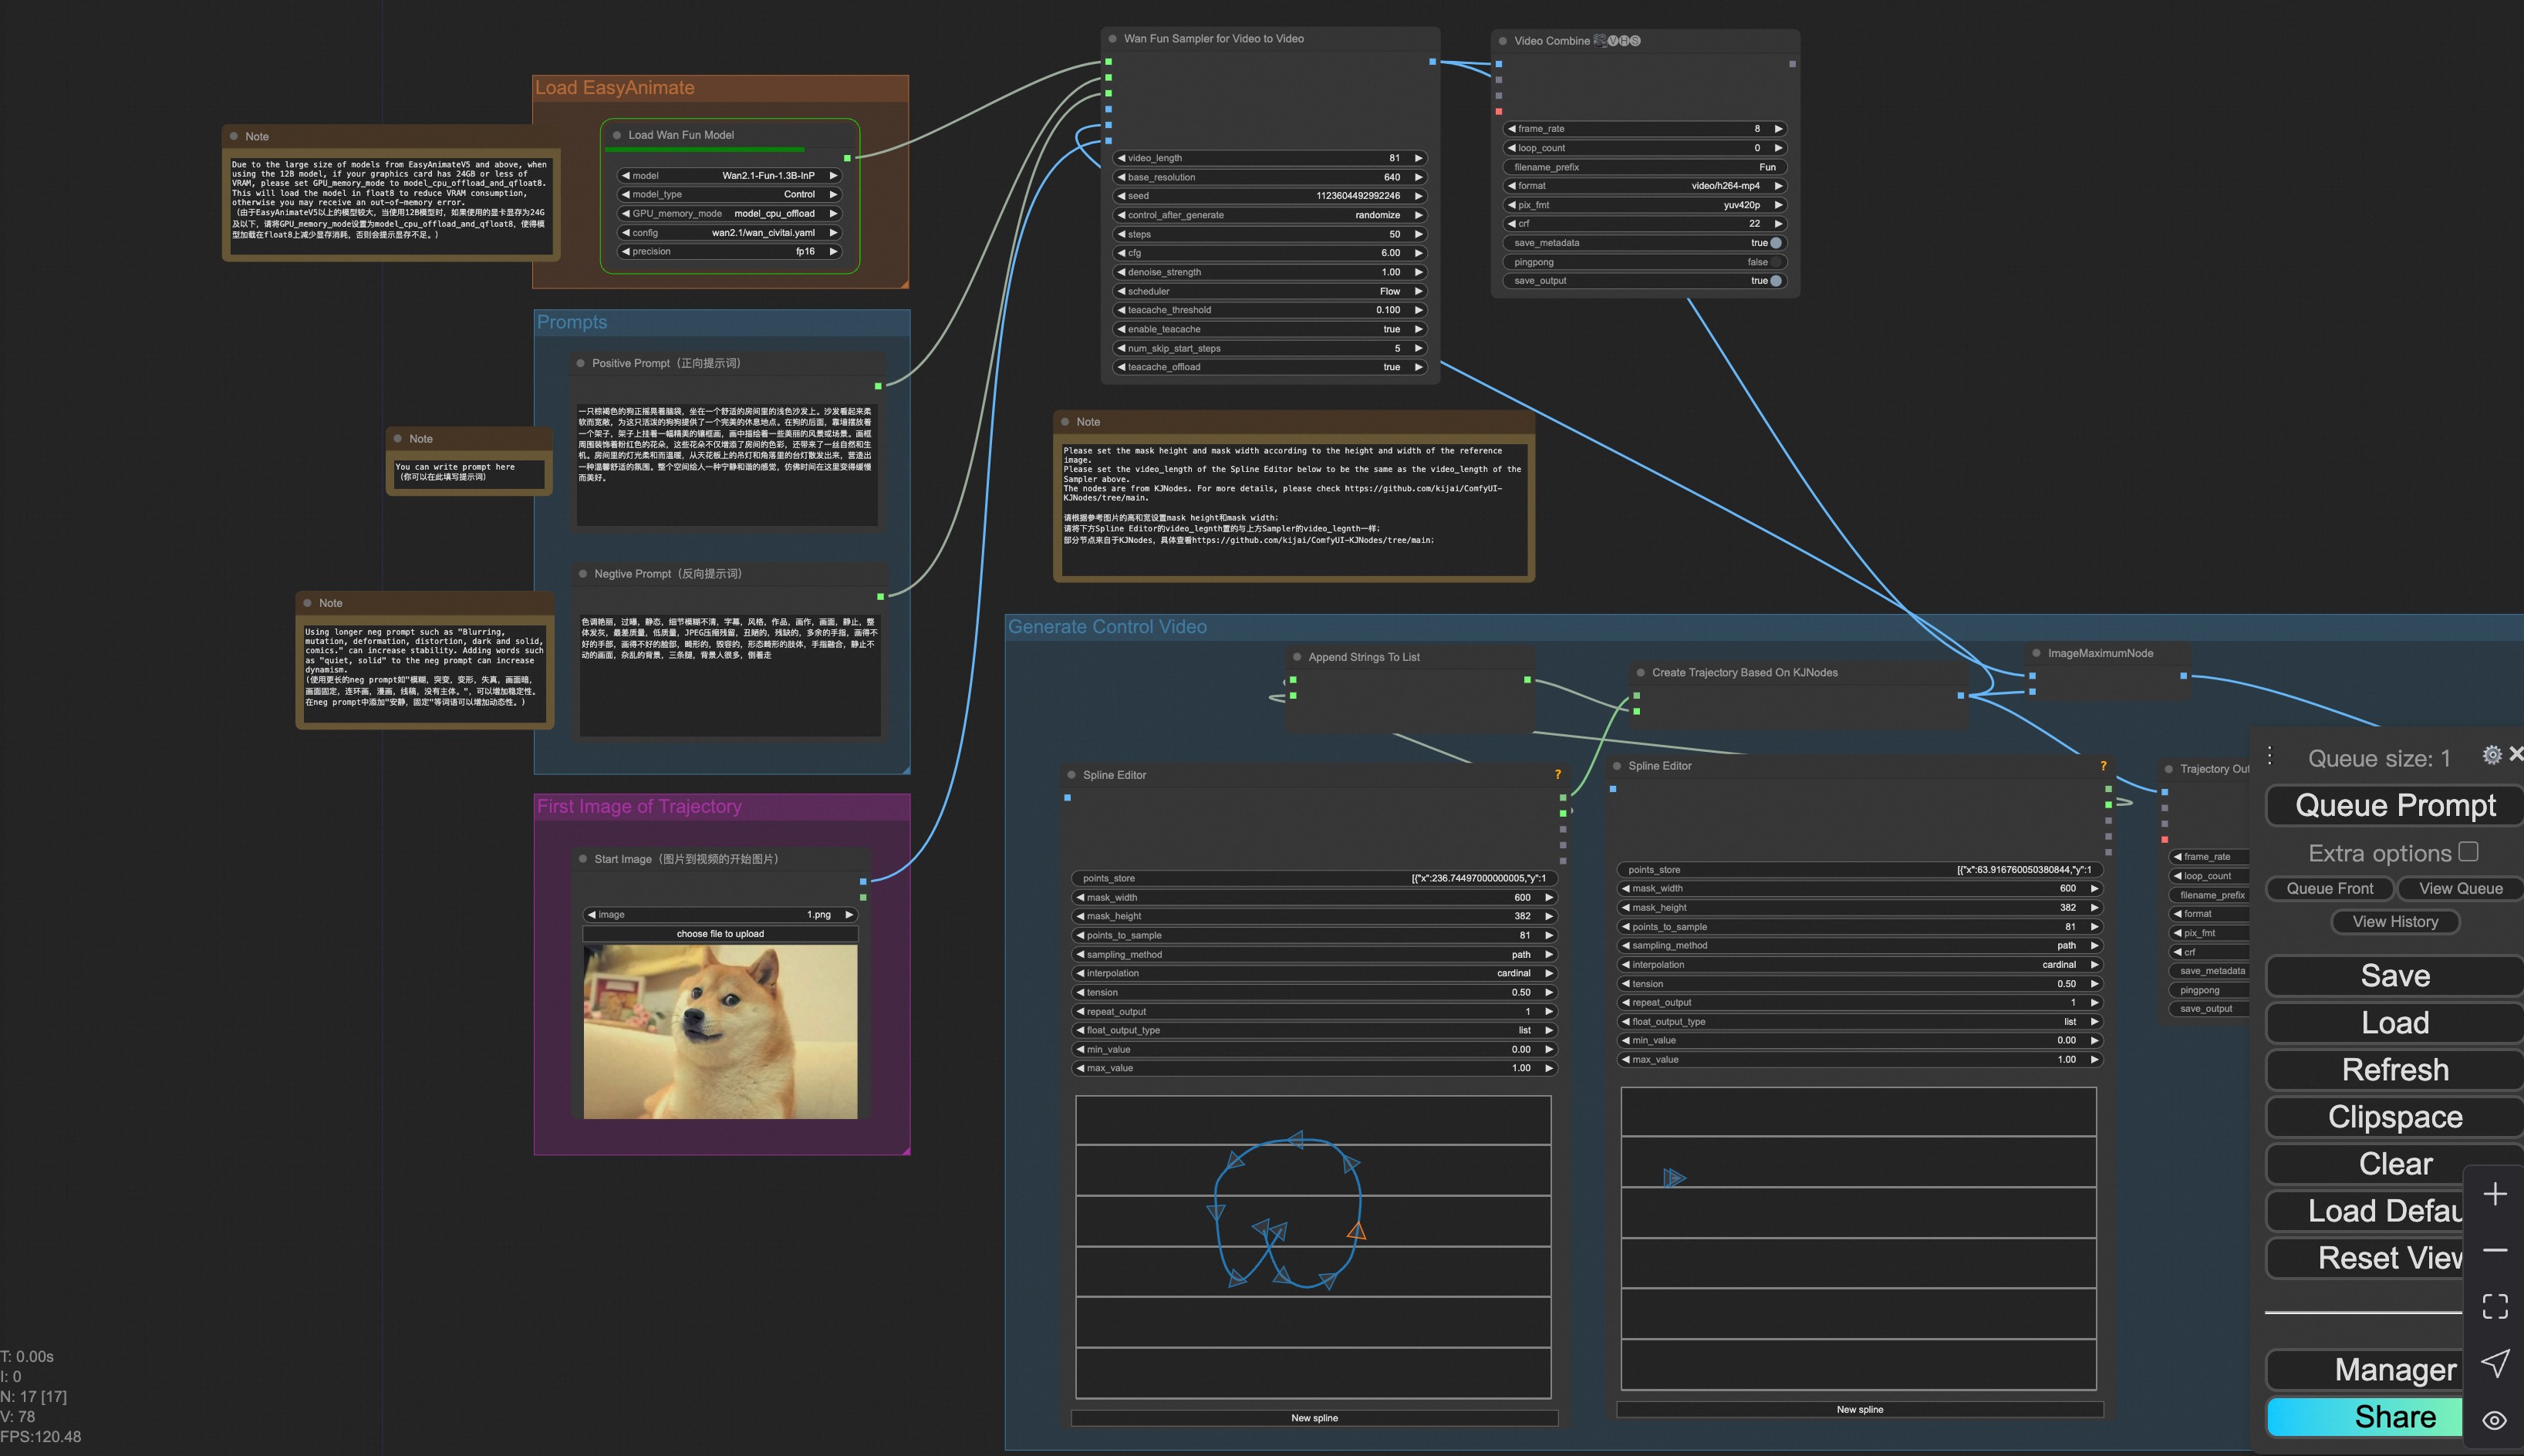
+### iii. Trajectory Control Video Generation
+Our user interface is shown as follows, this is the [json](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_control_trajectory.json):
+
+
+
+You can run a demo using the following photo:
+
+
+
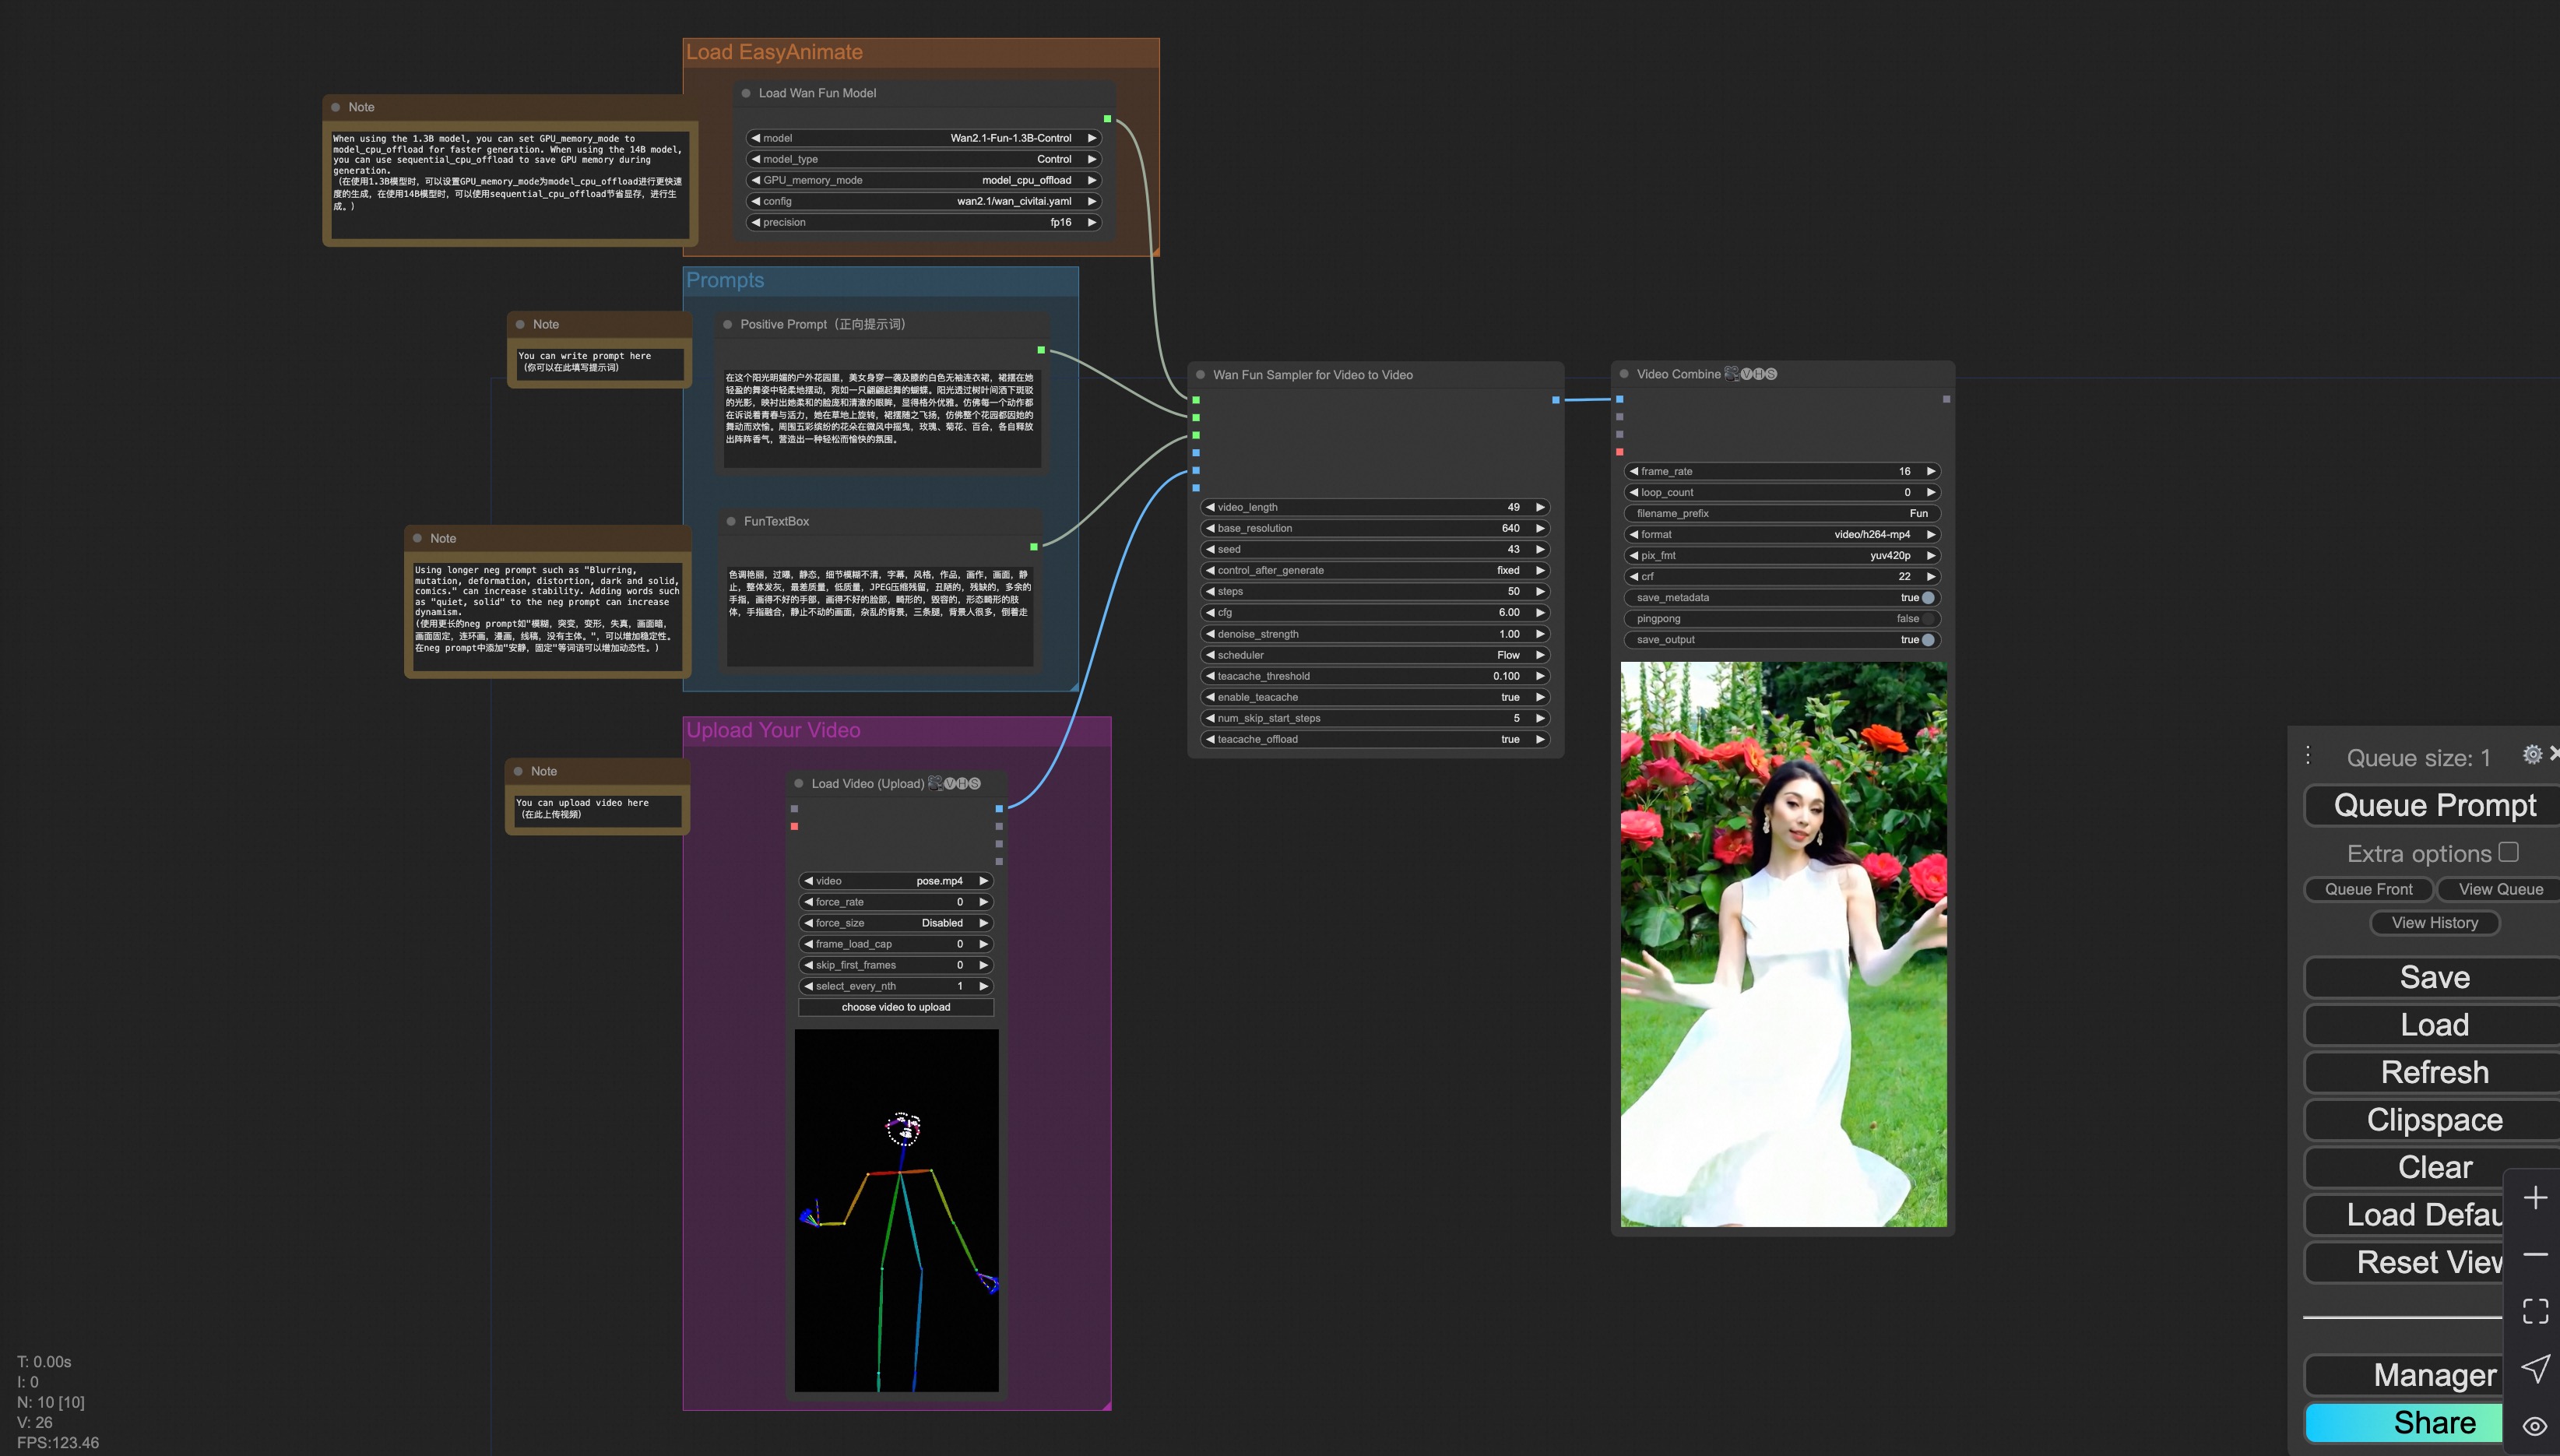
+### iv. Control Video Generation
+Our user interface is shown as follows, this is the [json](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_v2v_control.json):
+
+To facilitate usage, we have added several JSON configurations that automatically process input videos into the necessary control videos. These include [canny processing](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_v2v_control_canny.json), [pose processing](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_v2v_control_pose.json), and [depth processing](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_v2v_control_depth.json).
+
+
+
+You can run a demo using the following video:
+
+[Demo Video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/pose.mp4)
+
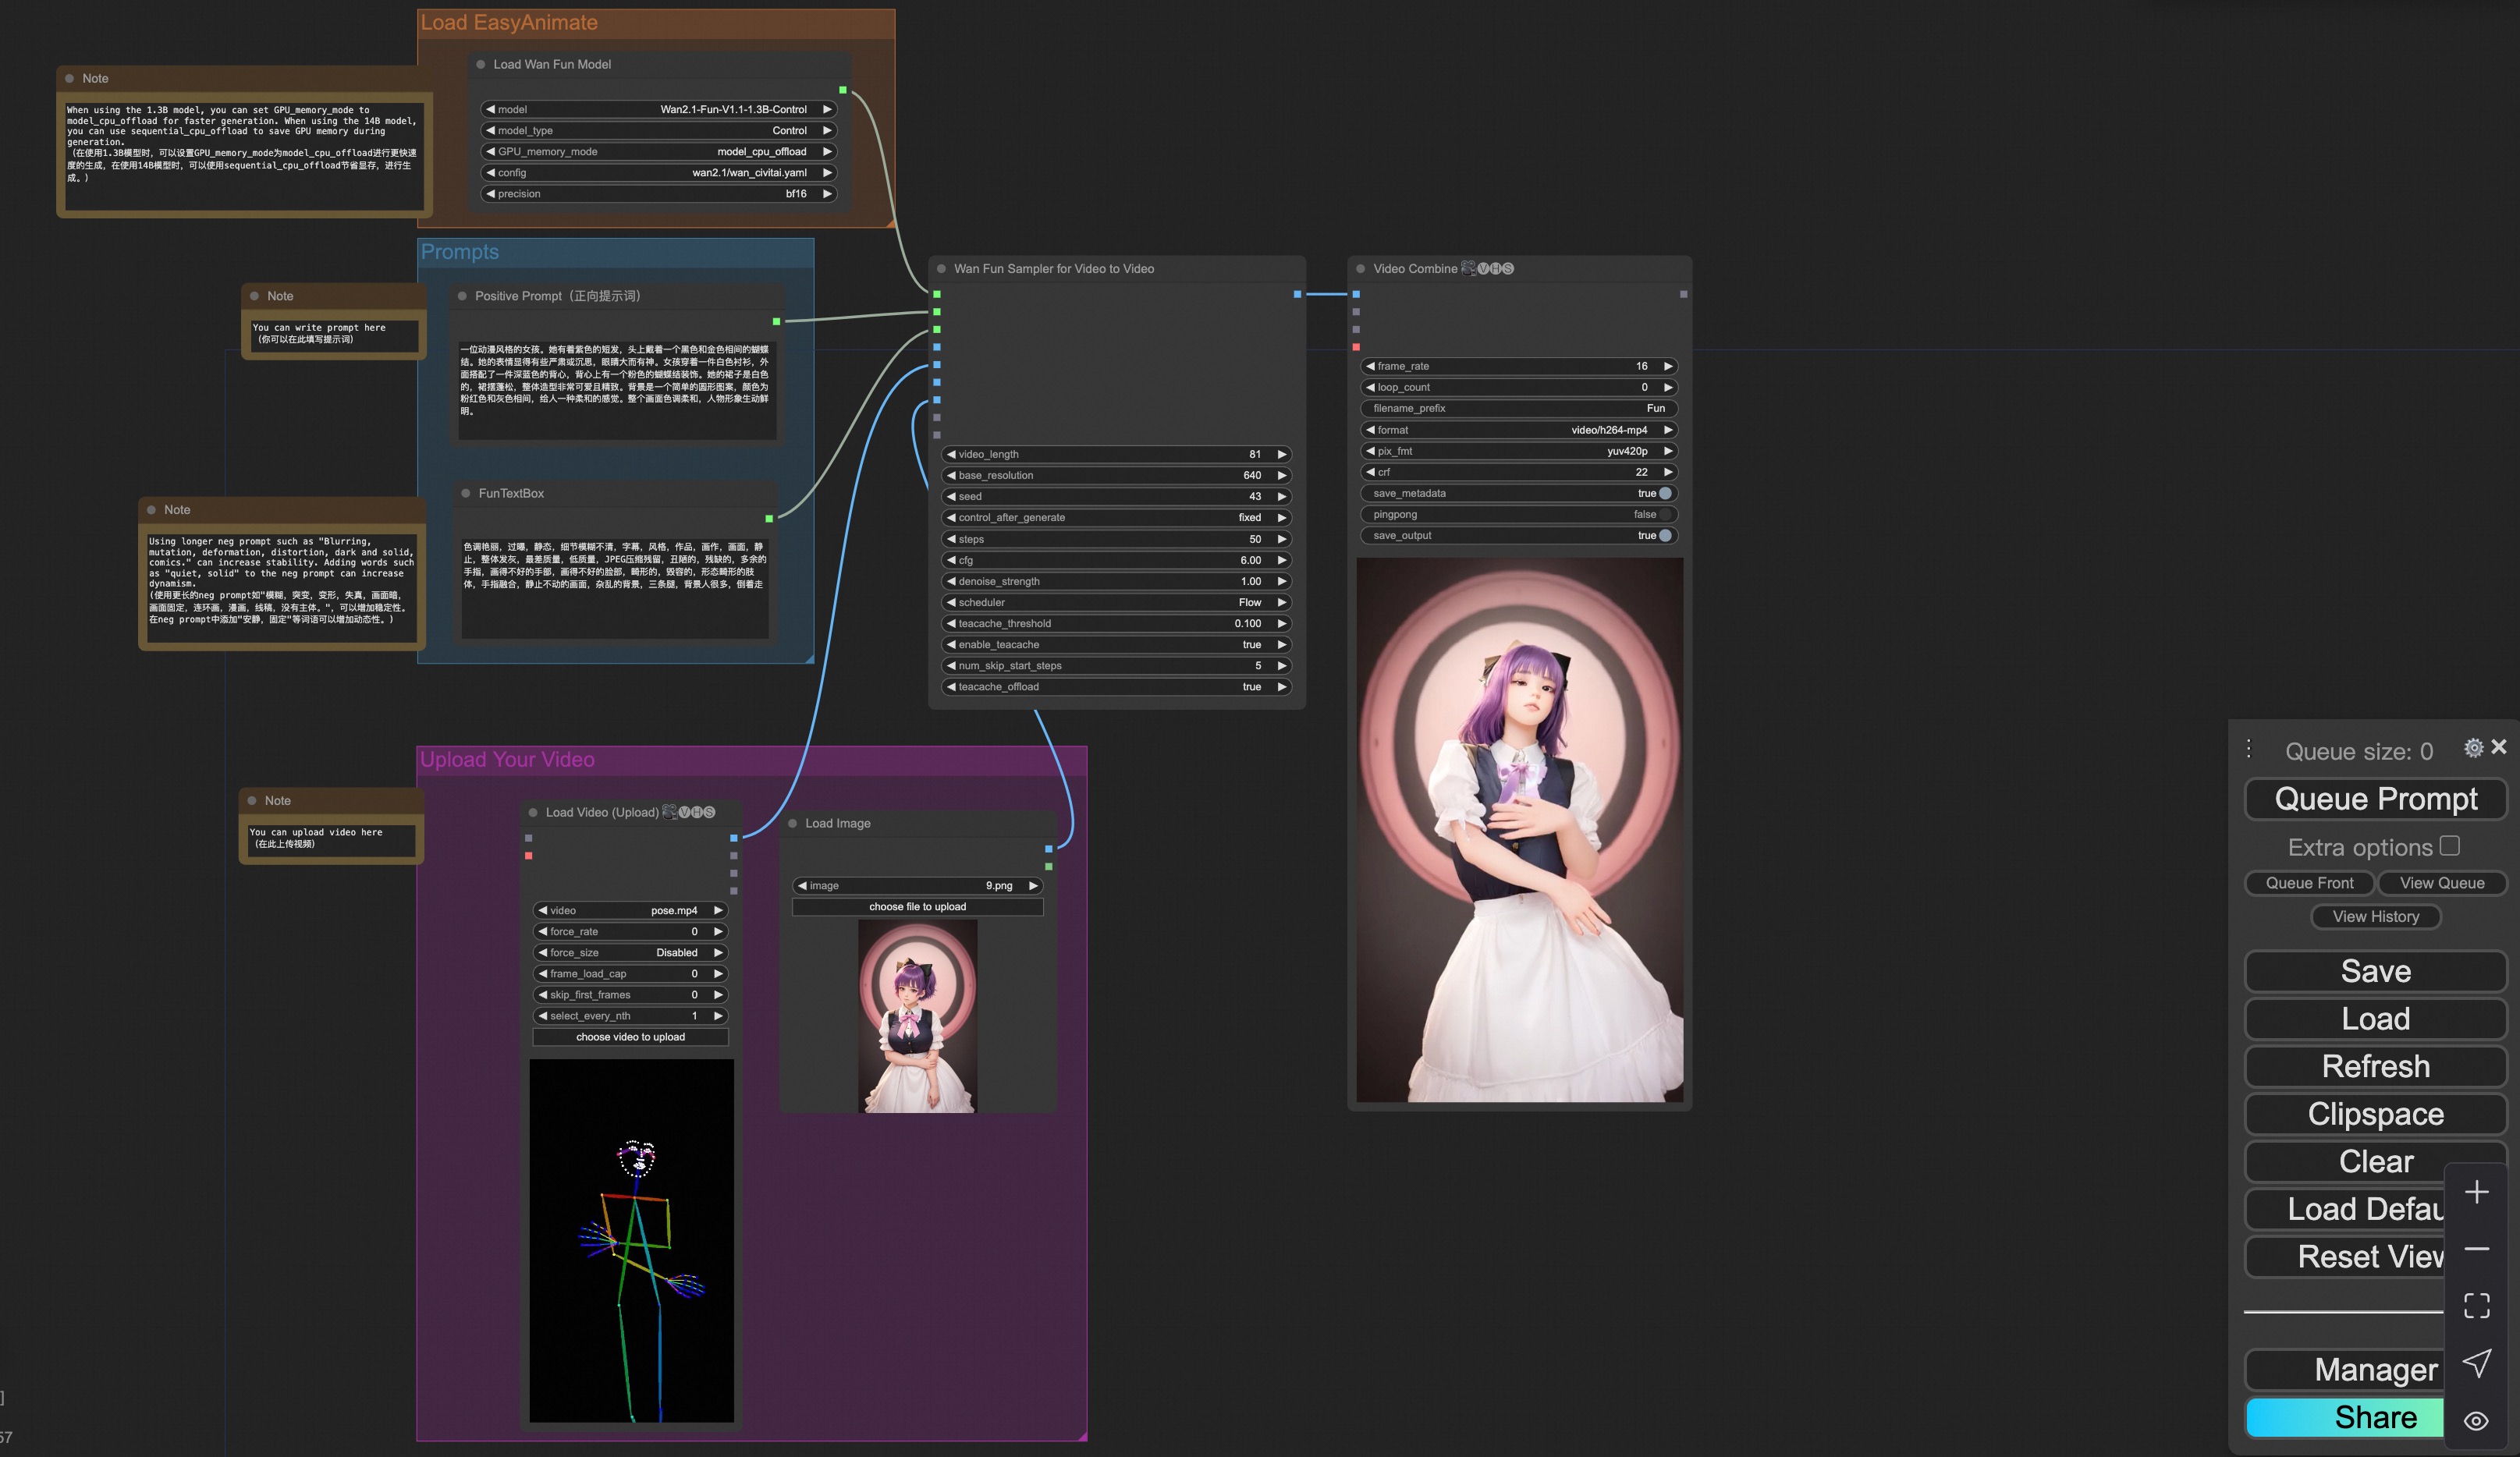
+### v. Control + Ref Video Generation
+Our user interface is shown as follows, this is the [json](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_v2v_control_ref.json):
+
+To facilitate usage, we have added several JSON configurations that automatically process input videos into the necessary control videos. These include [pose processing](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_v2v_control_pose_ref.json), and [depth processing](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_v2v_control_depth_ref.json).
+
+
+
+You can run a demo using the following video:
+
+[Demo Image](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/6.png)
+
+[Demo Video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/pose.mp4)
+
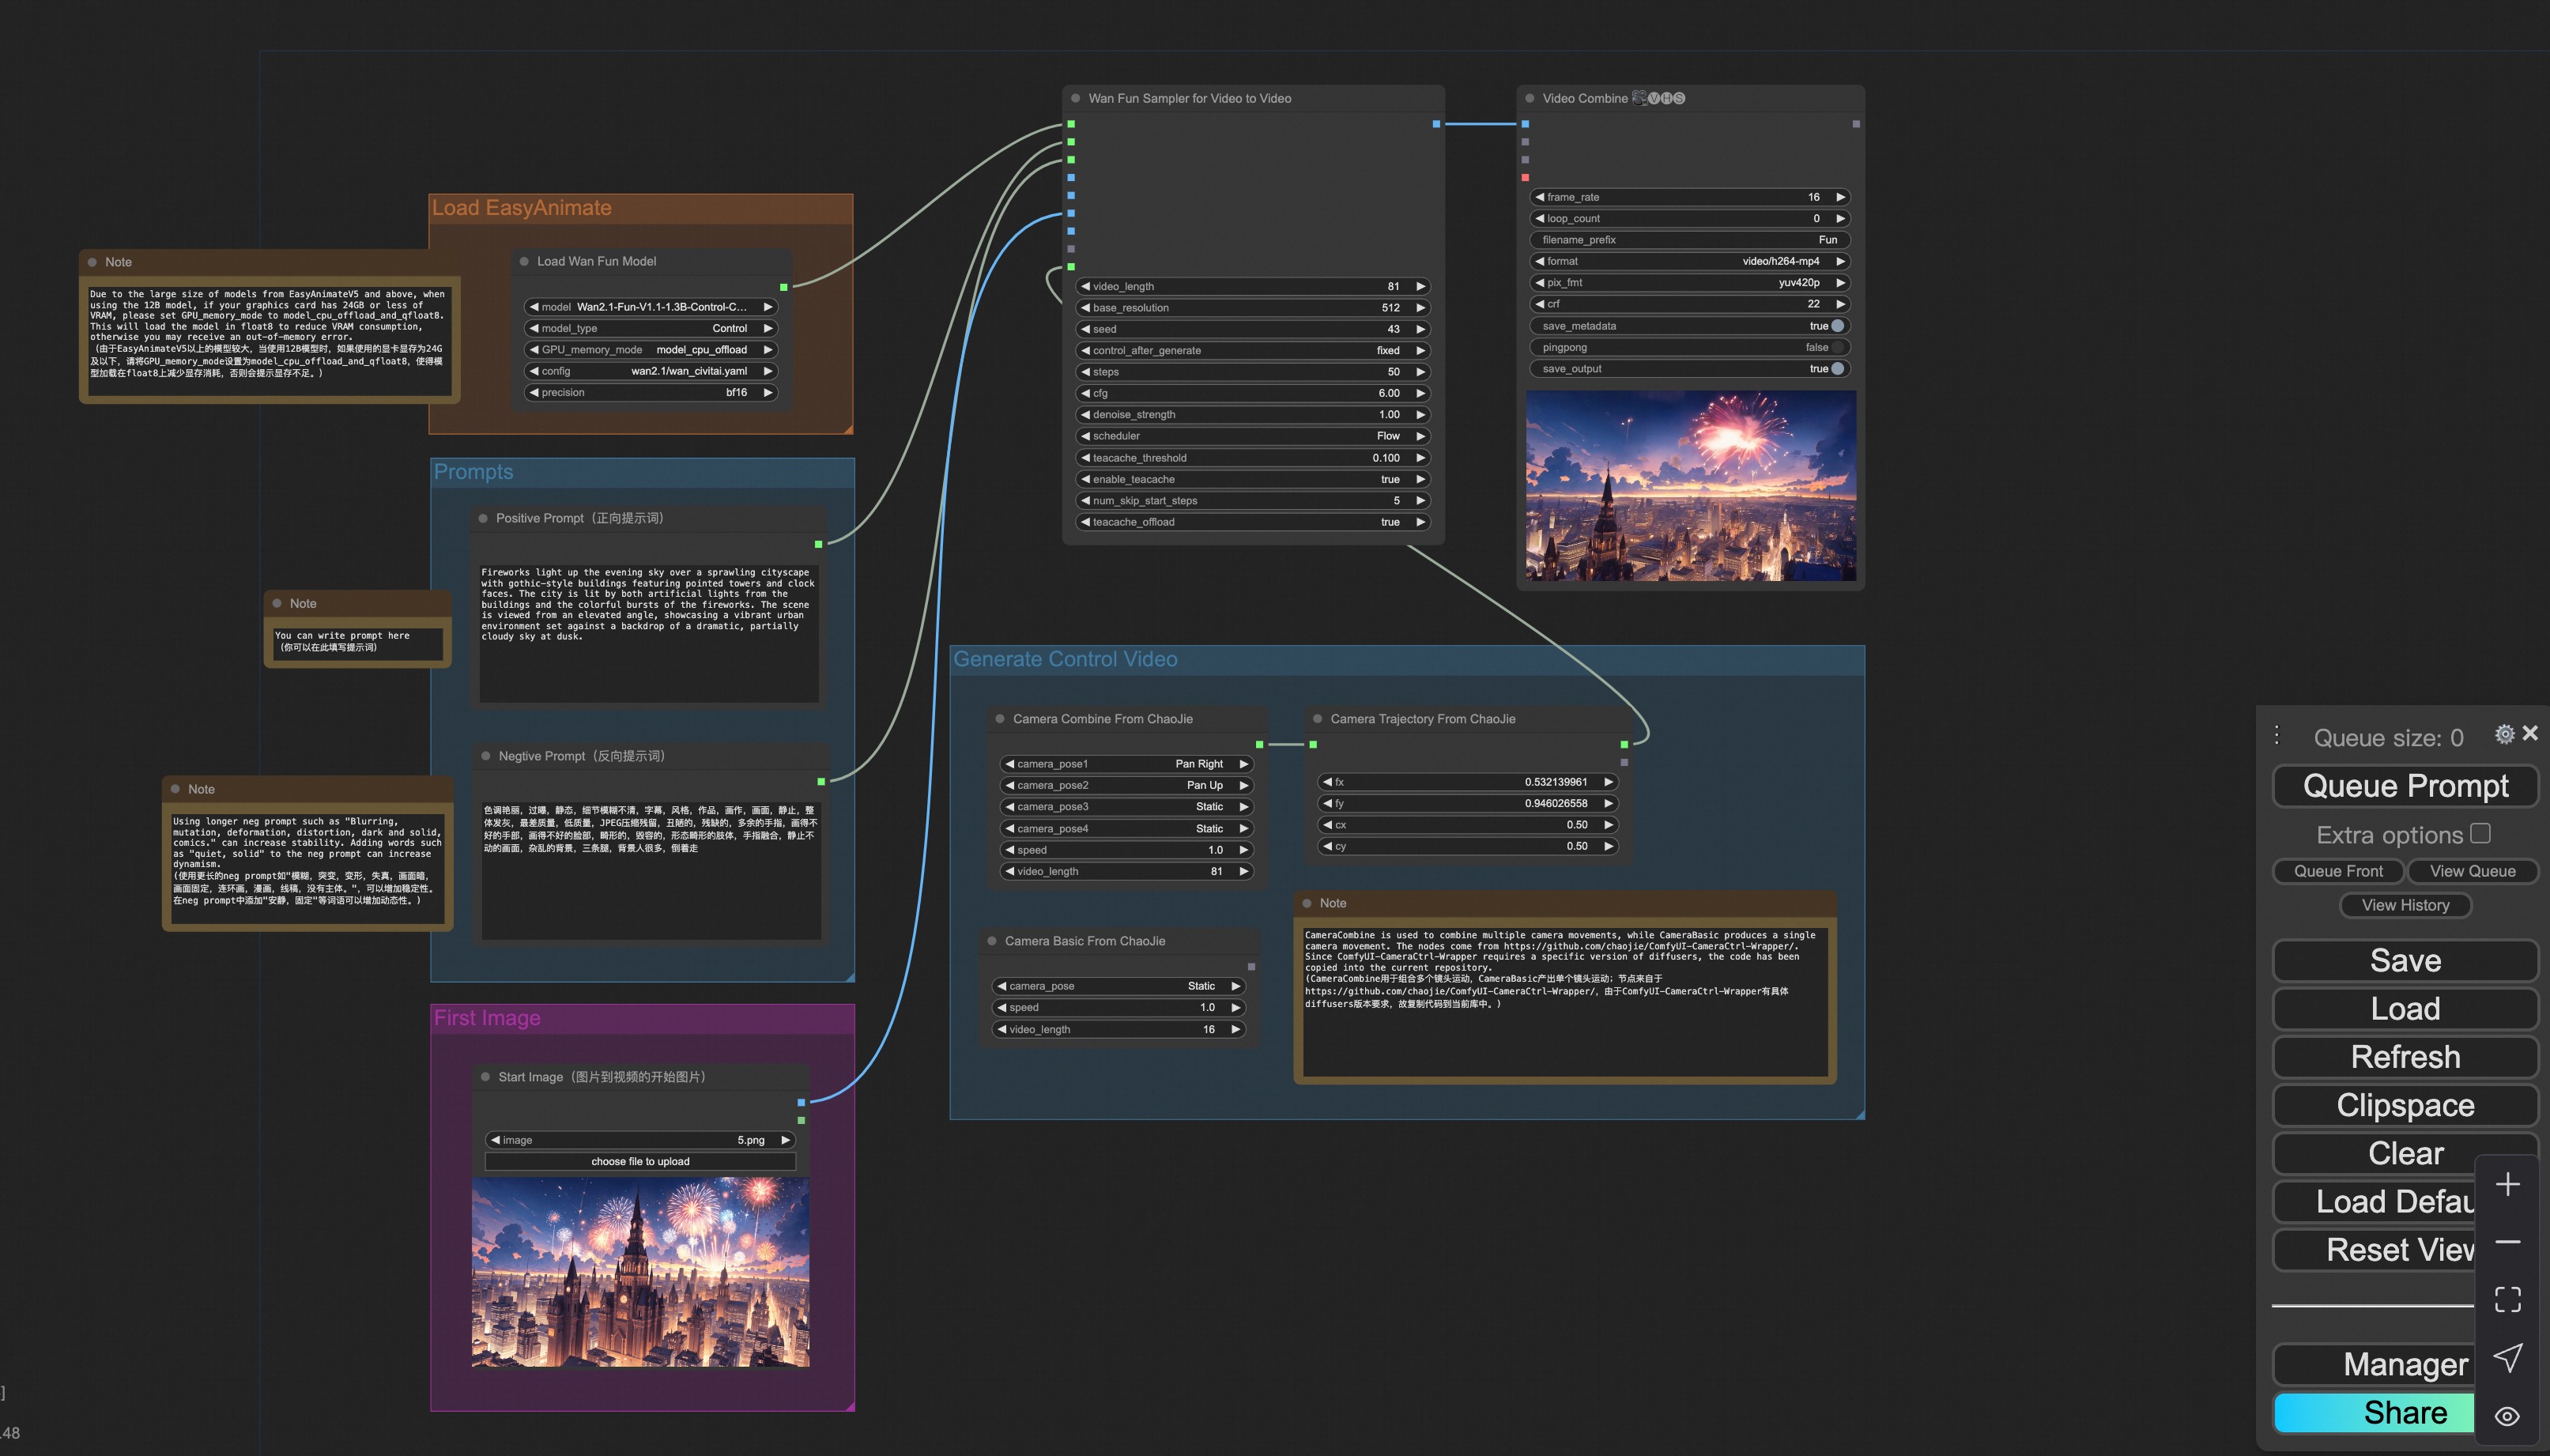
+### vi. Camera Control Video Generation
+Our user interface is shown as follows, this is the [json](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_control_camera.json):
+
+
+
+You can run a demo using the following photo:
+
+
+
+### 2. Wan
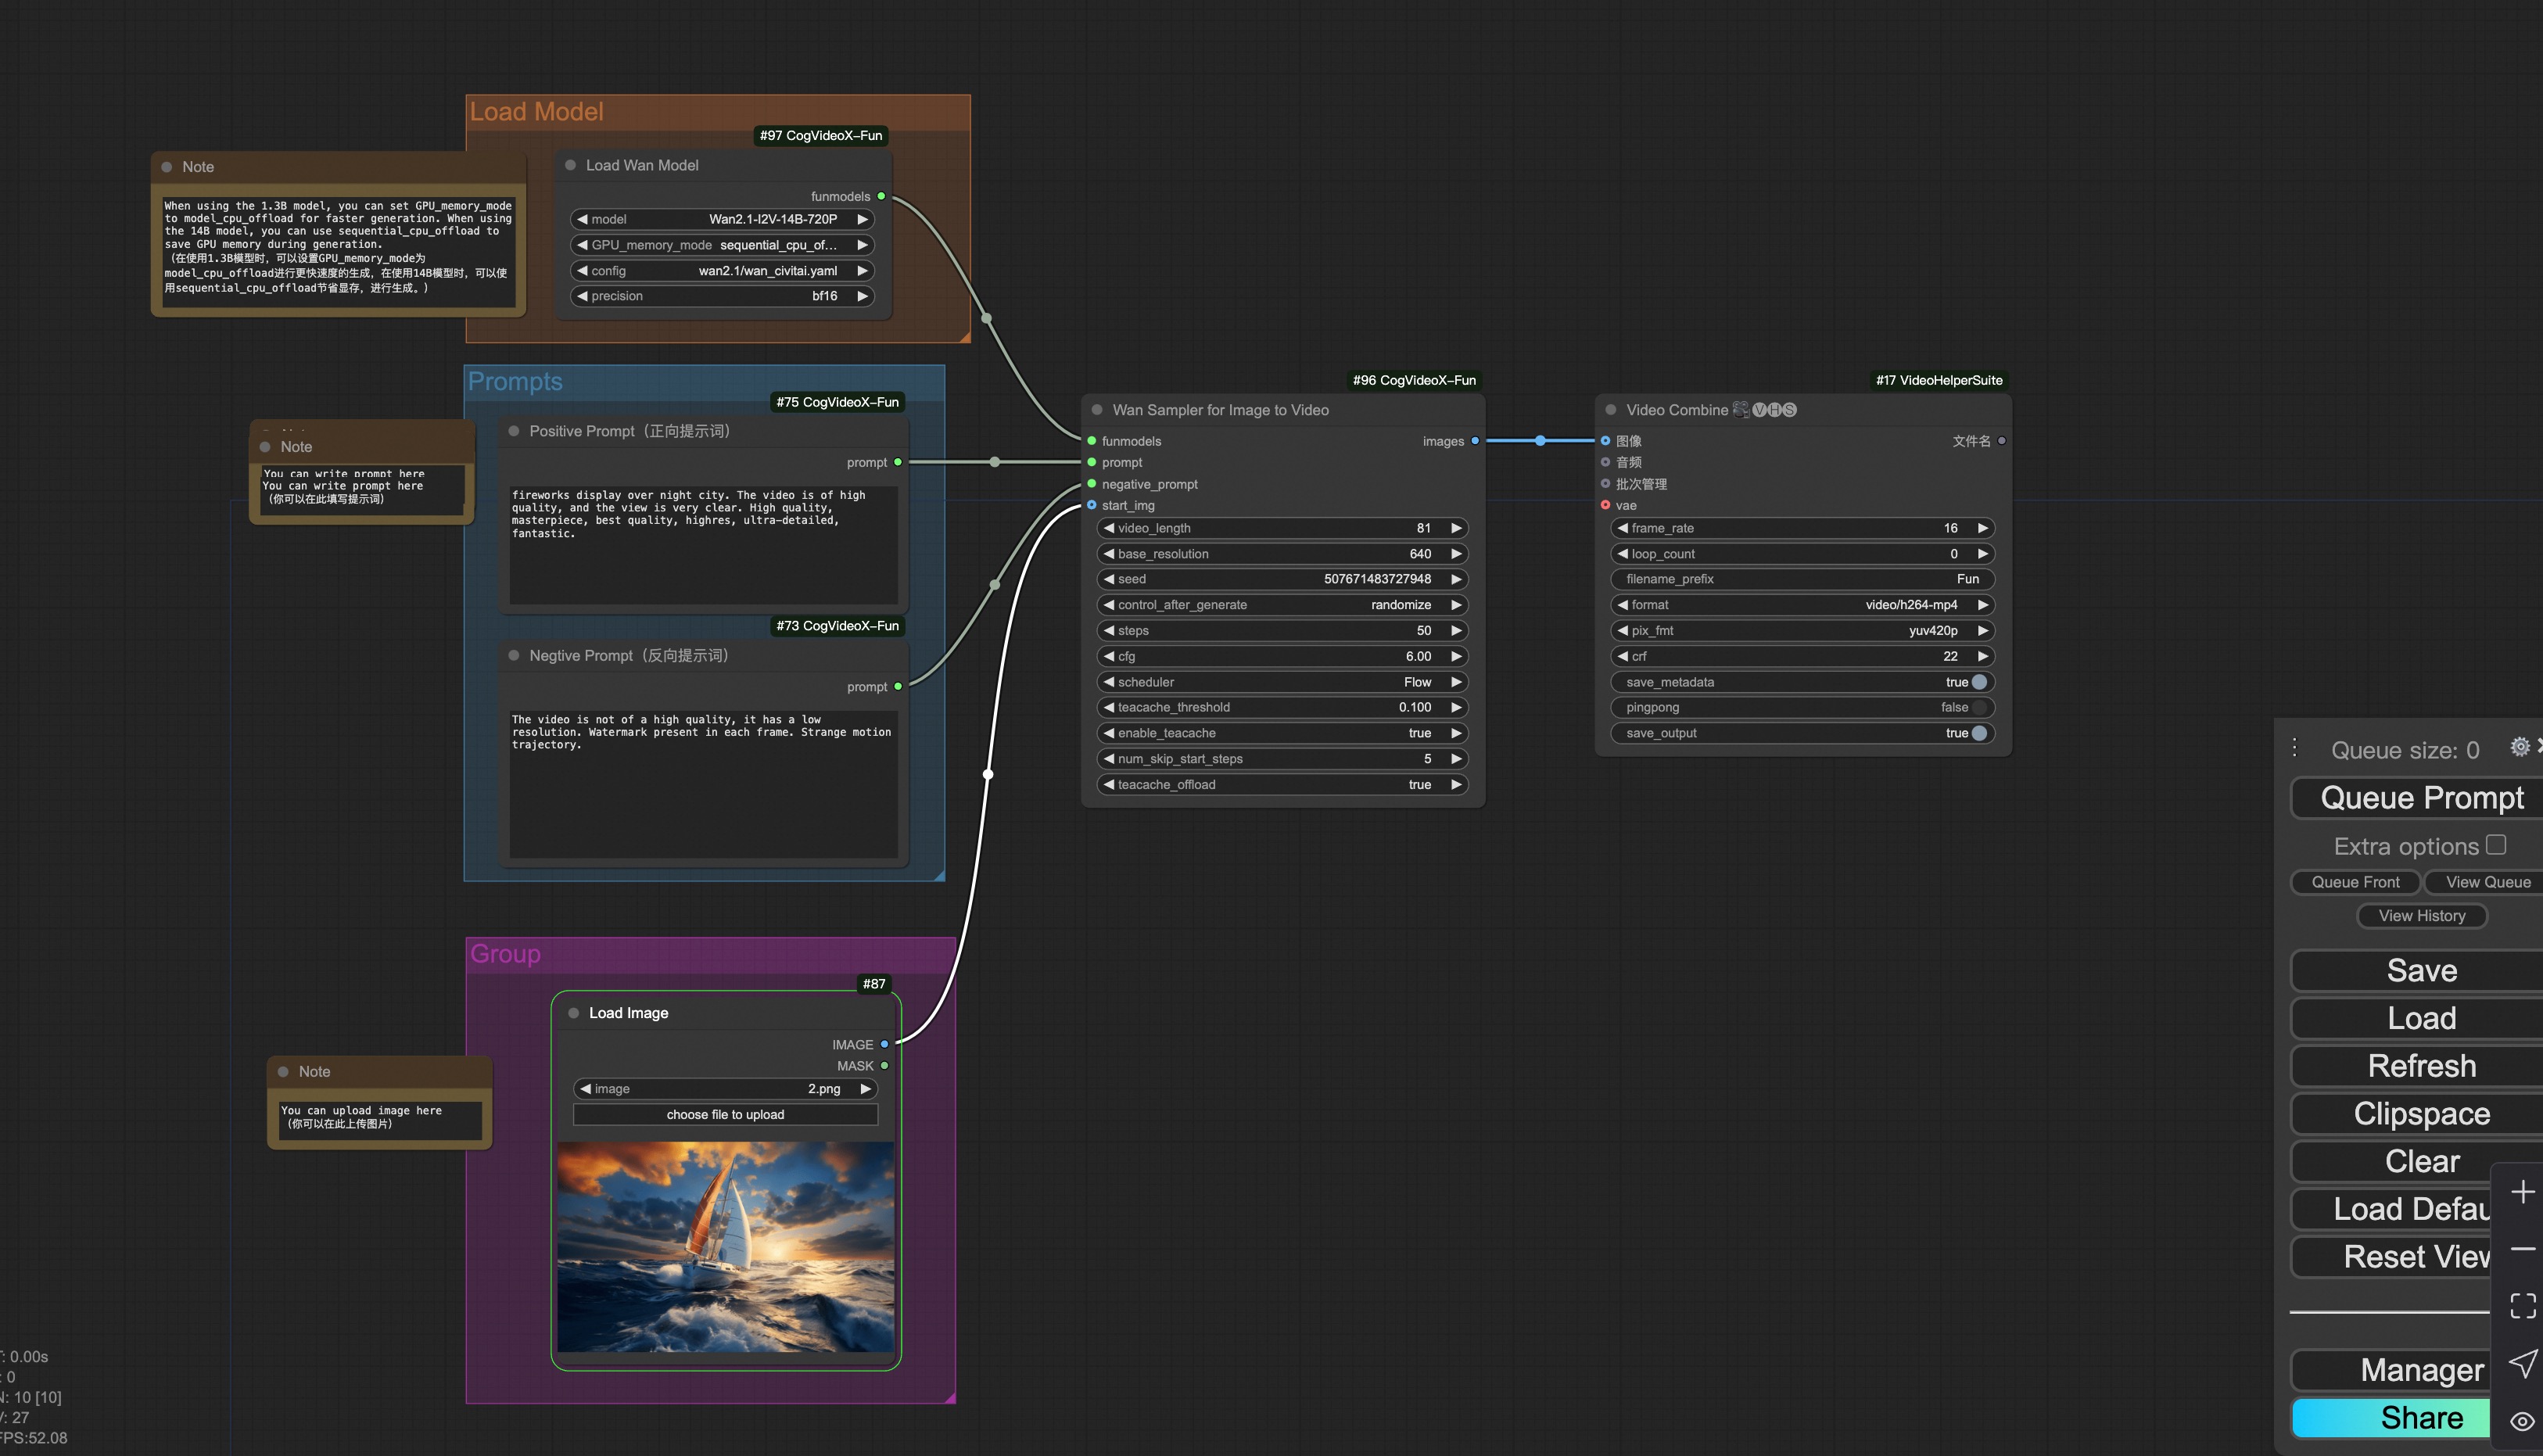
+#### i. Image to video generation
+[Download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan/asset/v1.0/wan2.1_workflow_i2v.json) for wan-fun.
+
+Our ui is shown as follow:
+
+
+You can run the demo using following photo:
+
+
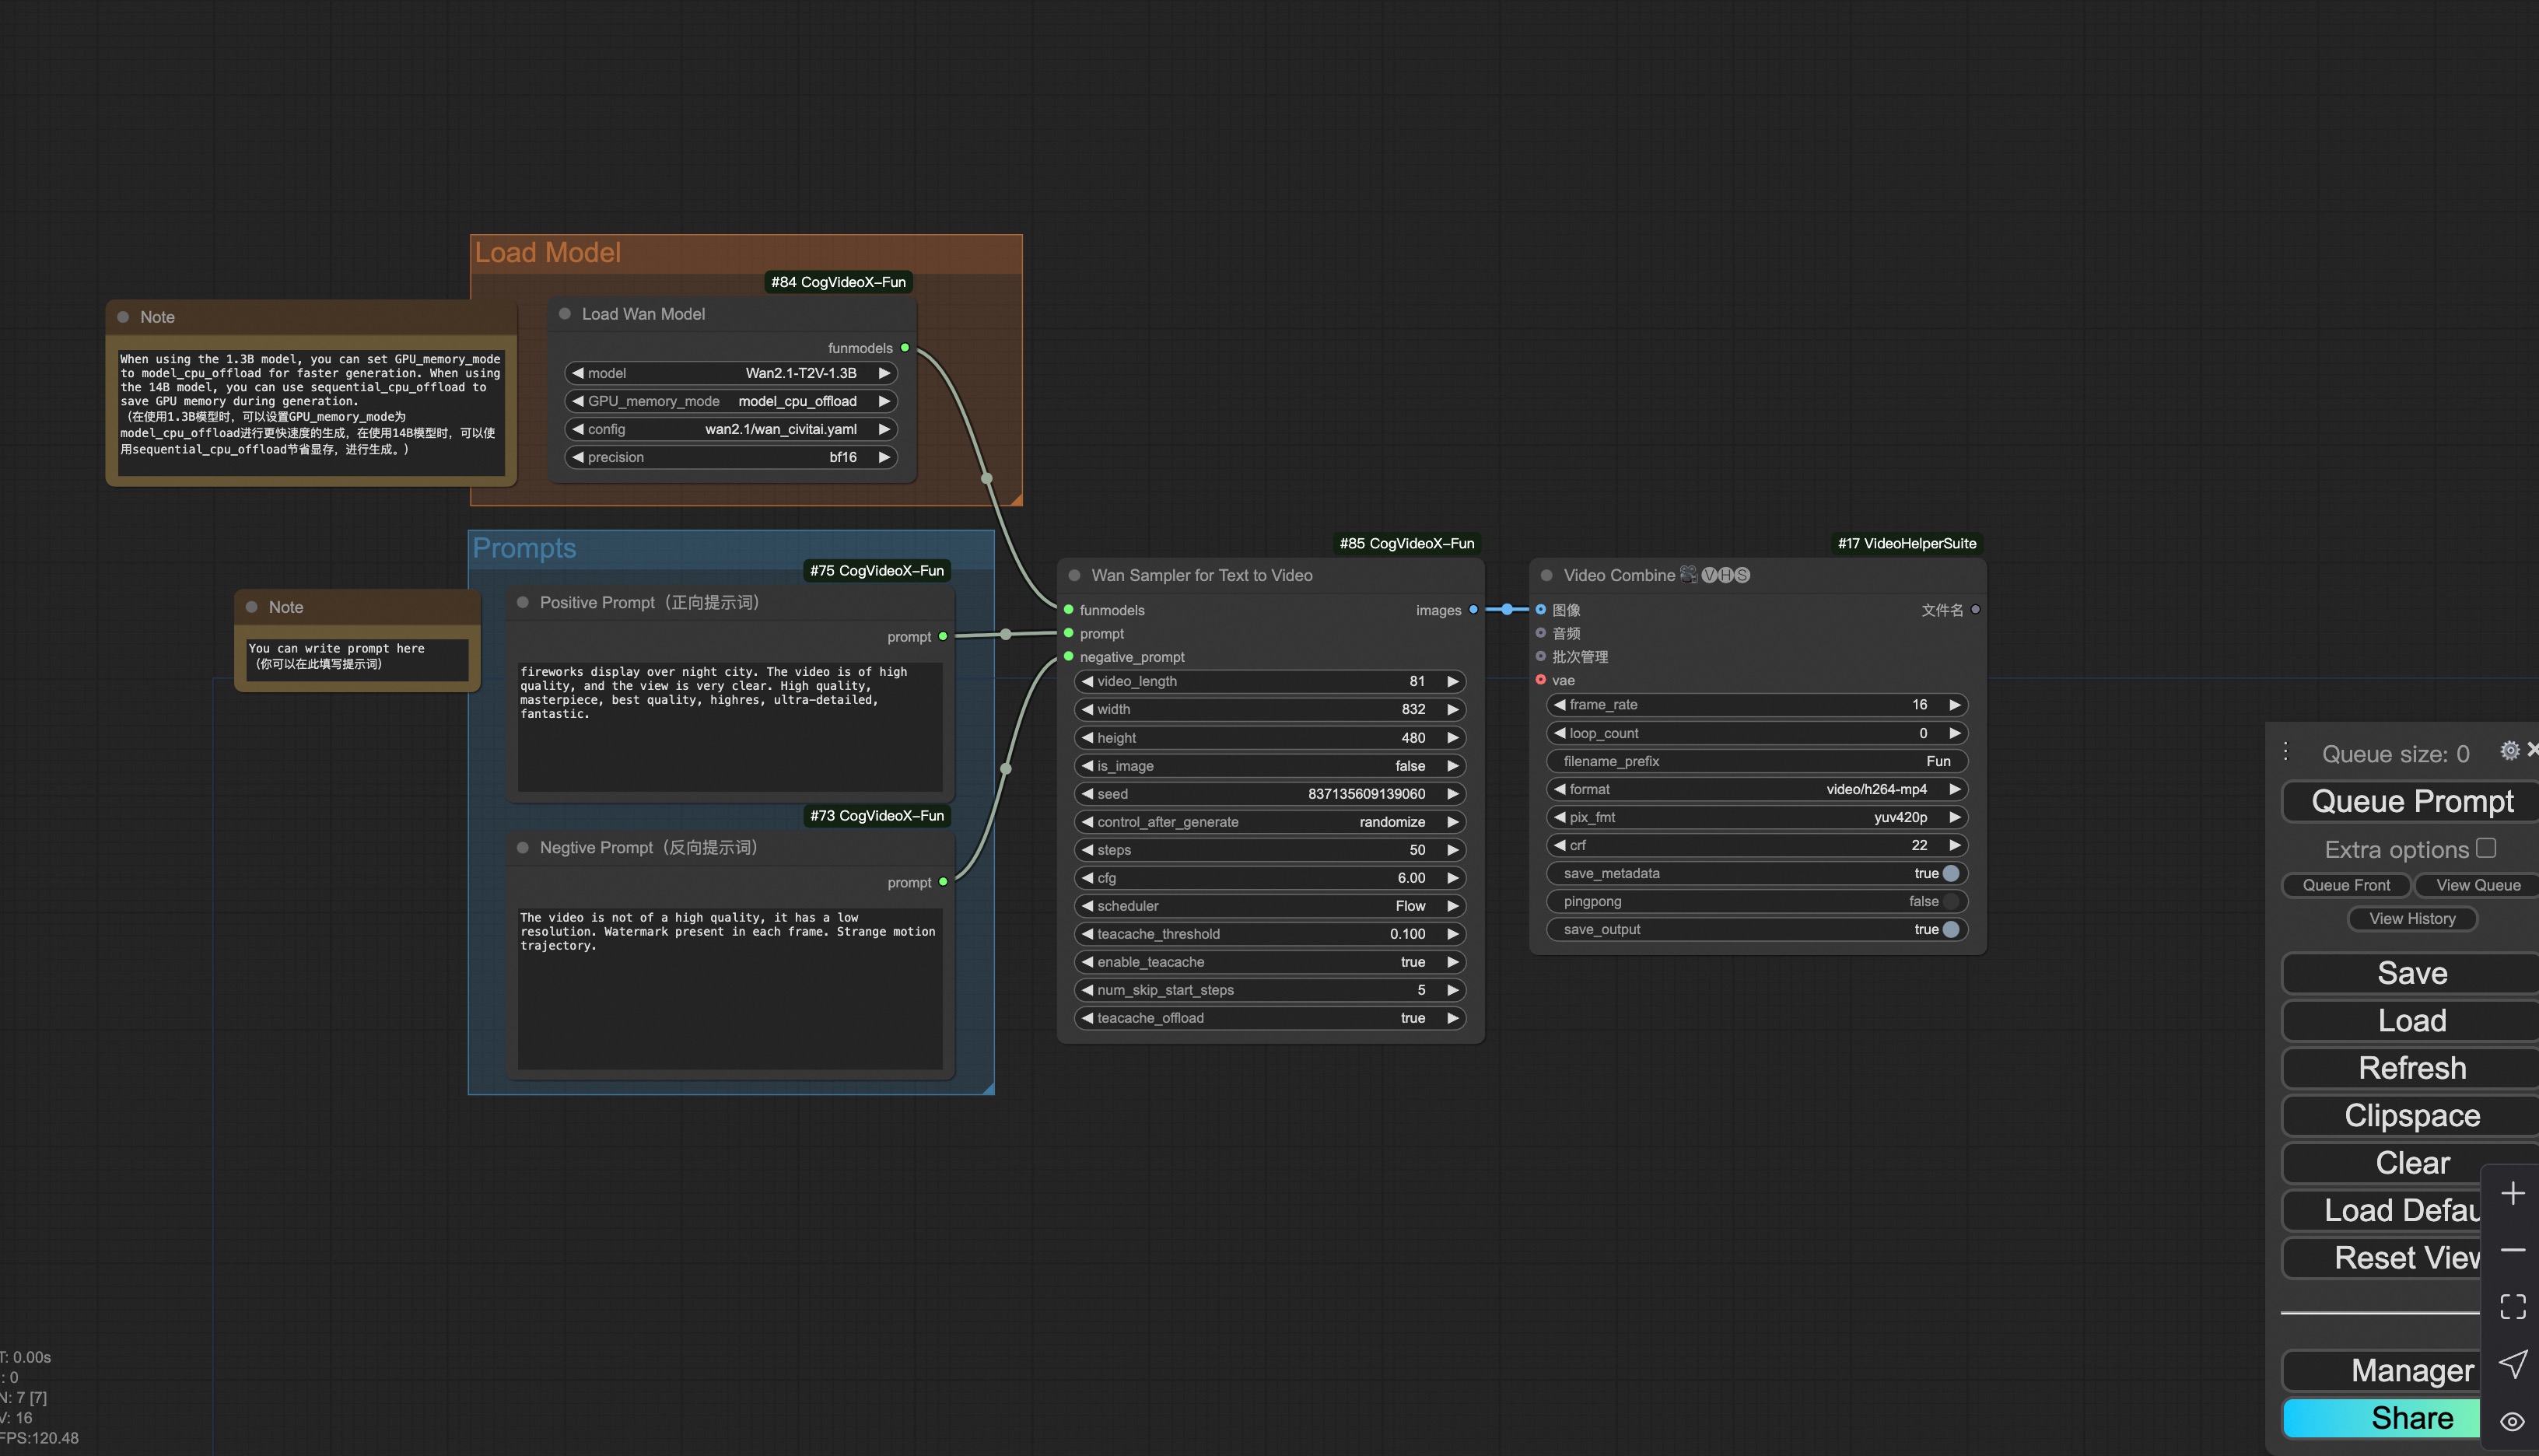
+#### ii. Text to video generation
+[Download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan/asset/v1.0/wan2.1_workflow_t2v.json) for wan-fun.
+
+
+
+### 3. CogVideoX-Fun
+#### i. Video to video generation
+[Download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.5/cogvideoxfunv1.5_workflow_v2v.json) for v1.5.
+
+[Download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/cogvideoxfunv1.1_workflow_v2v.json) for v1.1.
+
+Our ui is shown as follow:
+
+
+You can run the demo using following video:
+[demo video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/play_guitar.mp4)
+
+#### ii. Image to video generation
+[Download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.5/cogvideoxfunv1.5_workflow_i2v.json) for v1.5.
+
+[Download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/cogvideoxfunv1.1_workflow_i2v.json) for v1.1.
+
+Our ui is shown as follow:
+
+
+You can run the demo using following photo:
+
+
+#### iii. Text to video generation
+[Download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.5/cogvideoxfunv1.5_workflow_t2v.json) for v1.5.
+
+[Download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/cogvideoxfunv1.1_workflow_t2v.json) for v1.1.
+
+
+
+#### iv. Control video generation
+[Download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/cogvideoxfunv1.1_workflow_v2v_control.json) for v1.1.
+
+Our ui is shown as follow:
+
+
+You can run the demo using following video:
+[demo video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/pose.mp4)
+
+#### v. Lora usage.
+[Download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/cogvideoxfunv1.1_workflow_t2v_lora.json) for v1.1.
+
+Our ui is shown as follow:
+
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/dwpose_utils/__init__.py b/VideoX-Fun/comfyui/annotator/dwpose_utils/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..dd97b64a1cc3de419678f8ceef1d64d7a3e6b0e3
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/dwpose_utils/__init__.py
@@ -0,0 +1,43 @@
+# This folder is modified from the https://github.com/Mikubill/sd-webui-controlnet
+# Openpose
+# Original from CMU https://github.com/CMU-Perceptual-Computing-Lab/openpose
+# 2nd Edited by https://github.com/Hzzone/pytorch-openpose
+# 3rd Edited by ControlNet
+# 4th Edited by ControlNet (added face and correct hands)
+
+import os
+os.environ["KMP_DUPLICATE_LIB_OK"]="TRUE"
+
+import torch
+import numpy as np
+from . import util
+from .wholebody import Wholebody
+
+def draw_pose(poses, H, W):
+ canvas = np.zeros(shape=(H, W, 3), dtype=np.uint8)
+
+ for pose in poses:
+ canvas = util.draw_bodypose(canvas, pose.body.keypoints)
+
+ canvas = util.draw_handpose(canvas, pose.left_hand)
+ canvas = util.draw_handpose(canvas, pose.right_hand)
+
+ canvas = util.draw_facepose(canvas, pose.face)
+ return canvas
+
+
+class DWposeDetector:
+ def __init__(self, onnx_det, onnx_pose):
+ self.pose_estimation = Wholebody(onnx_det, onnx_pose)
+
+ def __call__(self, oriImg):
+ oriImg = oriImg.copy()
+ H, W, C = oriImg.shape
+ with torch.no_grad():
+ keypoints_info = self.pose_estimation(oriImg)
+ return draw_pose(
+ Wholebody.format_result(keypoints_info),
+ H,
+ W,
+ )
+
diff --git a/VideoX-Fun/comfyui/annotator/dwpose_utils/onnxdet.py b/VideoX-Fun/comfyui/annotator/dwpose_utils/onnxdet.py
new file mode 100644
index 0000000000000000000000000000000000000000..0c210a5307bb571410efaf1bbcce43f1d213cf3c
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/dwpose_utils/onnxdet.py
@@ -0,0 +1,128 @@
+import cv2
+import numpy as np
+
+def nms(boxes, scores, nms_thr):
+ """Single class NMS implemented in Numpy."""
+ x1 = boxes[:, 0]
+ y1 = boxes[:, 1]
+ x2 = boxes[:, 2]
+ y2 = boxes[:, 3]
+
+ areas = (x2 - x1 + 1) * (y2 - y1 + 1)
+ order = scores.argsort()[::-1]
+
+ keep = []
+ while order.size > 0:
+ i = order[0]
+ keep.append(i)
+ xx1 = np.maximum(x1[i], x1[order[1:]])
+ yy1 = np.maximum(y1[i], y1[order[1:]])
+ xx2 = np.minimum(x2[i], x2[order[1:]])
+ yy2 = np.minimum(y2[i], y2[order[1:]])
+
+ w = np.maximum(0.0, xx2 - xx1 + 1)
+ h = np.maximum(0.0, yy2 - yy1 + 1)
+ inter = w * h
+ ovr = inter / (areas[i] + areas[order[1:]] - inter)
+
+ inds = np.where(ovr <= nms_thr)[0]
+ order = order[inds + 1]
+
+ return keep
+
+def multiclass_nms(boxes, scores, nms_thr, score_thr):
+ """Multiclass NMS implemented in Numpy. Class-aware version."""
+ final_dets = []
+ num_classes = scores.shape[1]
+ for cls_ind in range(num_classes):
+ cls_scores = scores[:, cls_ind]
+ valid_score_mask = cls_scores > score_thr
+ if valid_score_mask.sum() == 0:
+ continue
+ else:
+ valid_scores = cls_scores[valid_score_mask]
+ valid_boxes = boxes[valid_score_mask]
+ keep = nms(valid_boxes, valid_scores, nms_thr)
+ if len(keep) > 0:
+ cls_inds = np.ones((len(keep), 1)) * cls_ind
+ dets = np.concatenate(
+ [valid_boxes[keep], valid_scores[keep, None], cls_inds], 1
+ )
+ final_dets.append(dets)
+ if len(final_dets) == 0:
+ return None
+ return np.concatenate(final_dets, 0)
+
+def demo_postprocess(outputs, img_size, p6=False):
+ grids = []
+ expanded_strides = []
+ strides = [8, 16, 32] if not p6 else [8, 16, 32, 64]
+
+ hsizes = [img_size[0] // stride for stride in strides]
+ wsizes = [img_size[1] // stride for stride in strides]
+
+ for hsize, wsize, stride in zip(hsizes, wsizes, strides):
+ xv, yv = np.meshgrid(np.arange(wsize), np.arange(hsize))
+ grid = np.stack((xv, yv), 2).reshape(1, -1, 2)
+ grids.append(grid)
+ shape = grid.shape[:2]
+ expanded_strides.append(np.full((*shape, 1), stride))
+
+ grids = np.concatenate(grids, 1)
+ expanded_strides = np.concatenate(expanded_strides, 1)
+ outputs[..., :2] = (outputs[..., :2] + grids) * expanded_strides
+ outputs[..., 2:4] = np.exp(outputs[..., 2:4]) * expanded_strides
+
+ return outputs
+
+def preprocess(img, input_size, swap=(2, 0, 1)):
+ if len(img.shape) == 3:
+ padded_img = np.ones((input_size[0], input_size[1], 3), dtype=np.uint8) * 114
+ else:
+ padded_img = np.ones(input_size, dtype=np.uint8) * 114
+
+ r = min(input_size[0] / img.shape[0], input_size[1] / img.shape[1])
+ resized_img = cv2.resize(
+ img,
+ (int(img.shape[1] * r), int(img.shape[0] * r)),
+ interpolation=cv2.INTER_LINEAR,
+ ).astype(np.uint8)
+ padded_img[: int(img.shape[0] * r), : int(img.shape[1] * r)] = resized_img
+
+ padded_img = padded_img.transpose(swap)
+ padded_img = np.ascontiguousarray(padded_img, dtype=np.float32)
+ return padded_img, r
+
+def inference_detector(session, oriImg, detect_classes=[0]):
+ input_shape = (640,640)
+ img, ratio = preprocess(oriImg, input_shape)
+
+ input = img[None, :, :, :]
+ if "InferenceSession" in type(session).__name__:
+ input_name = session.get_inputs()[0].name
+ output = session.run(None, {input_name: input})
+ else:
+ outNames = session.getUnconnectedOutLayersNames()
+ session.setInput(input)
+ output = session.forward(outNames)
+
+ predictions = demo_postprocess(output[0], input_shape)[0]
+
+ boxes = predictions[:, :4]
+ scores = predictions[:, 4:5] * predictions[:, 5:]
+
+ boxes_xyxy = np.ones_like(boxes)
+ boxes_xyxy[:, 0] = boxes[:, 0] - boxes[:, 2]/2.
+ boxes_xyxy[:, 1] = boxes[:, 1] - boxes[:, 3]/2.
+ boxes_xyxy[:, 2] = boxes[:, 0] + boxes[:, 2]/2.
+ boxes_xyxy[:, 3] = boxes[:, 1] + boxes[:, 3]/2.
+ boxes_xyxy /= ratio
+ dets = multiclass_nms(boxes_xyxy, scores, nms_thr=0.45, score_thr=0.1)
+ if dets is None:
+ return None
+ final_boxes, final_scores, final_cls_inds = dets[:, :4], dets[:, 4], dets[:, 5]
+ isscore = final_scores>0.3
+ iscat = np.isin(final_cls_inds, detect_classes)
+ isbbox = [ i and j for (i, j) in zip(isscore, iscat)]
+ final_boxes = final_boxes[isbbox]
+ return final_boxes
diff --git a/VideoX-Fun/comfyui/annotator/dwpose_utils/onnxpose.py b/VideoX-Fun/comfyui/annotator/dwpose_utils/onnxpose.py
new file mode 100644
index 0000000000000000000000000000000000000000..529404ca82e49fe67b6f3a57609bd41b9022a94c
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/dwpose_utils/onnxpose.py
@@ -0,0 +1,364 @@
+from typing import List, Tuple
+
+import cv2
+import numpy as np
+
+def preprocess(
+ img: np.ndarray, out_bbox, input_size: Tuple[int, int] = (192, 256)
+) -> Tuple[np.ndarray, np.ndarray, np.ndarray]:
+ """Do preprocessing for DWPose model inference.
+
+ Args:
+ img (np.ndarray): Input image in shape.
+ input_size (tuple): Input image size in shape (w, h).
+
+ Returns:
+ tuple:
+ - resized_img (np.ndarray): Preprocessed image.
+ - center (np.ndarray): Center of image.
+ - scale (np.ndarray): Scale of image.
+ """
+ # get shape of image
+ img_shape = img.shape[:2]
+ out_img, out_center, out_scale = [], [], []
+ if len(out_bbox) == 0:
+ out_bbox = [[0, 0, img_shape[1], img_shape[0]]]
+ for i in range(len(out_bbox)):
+ x0 = out_bbox[i][0]
+ y0 = out_bbox[i][1]
+ x1 = out_bbox[i][2]
+ y1 = out_bbox[i][3]
+ bbox = np.array([x0, y0, x1, y1])
+
+ # get center and scale
+ center, scale = bbox_xyxy2cs(bbox, padding=1.25)
+
+ # do affine transformation
+ resized_img, scale = top_down_affine(input_size, scale, center, img)
+
+ # normalize image
+ mean = np.array([123.675, 116.28, 103.53])
+ std = np.array([58.395, 57.12, 57.375])
+ resized_img = (resized_img - mean) / std
+
+ out_img.append(resized_img)
+ out_center.append(center)
+ out_scale.append(scale)
+
+ return out_img, out_center, out_scale
+
+
+def inference(sess, img):
+ """Inference DWPose model.
+
+ Args:
+ sess : ONNXRuntime session.
+ img : Input image in shape.
+
+ Returns:
+ outputs : Output of DWPose model.
+ """
+ all_out = []
+ # build input
+ input = np.stack(img, axis=0).transpose(0, 3, 1, 2)
+ input = input.astype(np.float32)
+ if "InferenceSession" in type(sess).__name__:
+ input_name = sess.get_inputs()[0].name
+ all_outputs = sess.run(None, {input_name: input})
+ for batch_idx in range(len(all_outputs[0])):
+ outputs = [all_outputs[i][batch_idx:batch_idx+1,...] for i in range(len(all_outputs))]
+ all_out.append(outputs)
+ return all_out
+
+ for i in range(len(img)):
+
+ input = img[i].transpose(2, 0, 1)
+ input = input[None, :, :, :]
+
+ outNames = sess.getUnconnectedOutLayersNames()
+ sess.setInput(input)
+ outputs = sess.forward(outNames)
+ all_out.append(outputs)
+
+ return all_out
+
+
+def postprocess(outputs: List[np.ndarray],
+ model_input_size: Tuple[int, int],
+ center: Tuple[int, int],
+ scale: Tuple[int, int],
+ simcc_split_ratio: float = 2.0
+ ) -> Tuple[np.ndarray, np.ndarray]:
+ """Postprocess for DWPose model output.
+
+ Args:
+ outputs (np.ndarray): Output of RTMPose model.
+ model_input_size (tuple): RTMPose model Input image size.
+ center (tuple): Center of bbox in shape (x, y).
+ scale (tuple): Scale of bbox in shape (w, h).
+ simcc_split_ratio (float): Split ratio of simcc.
+
+ Returns:
+ tuple:
+ - keypoints (np.ndarray): Rescaled keypoints.
+ - scores (np.ndarray): Model predict scores.
+ """
+ all_key = []
+ all_score = []
+ for i in range(len(outputs)):
+ # use simcc to decode
+ simcc_x, simcc_y = outputs[i]
+ keypoints, scores = decode(simcc_x, simcc_y, simcc_split_ratio)
+
+ # rescale keypoints
+ keypoints = keypoints / model_input_size * scale[i] + center[i] - scale[i] / 2
+ all_key.append(keypoints[0])
+ all_score.append(scores[0])
+
+ return np.array(all_key), np.array(all_score)
+
+
+def bbox_xyxy2cs(bbox: np.ndarray,
+ padding: float = 1.) -> Tuple[np.ndarray, np.ndarray]:
+ """Transform the bbox format from (x,y,w,h) into (center, scale)
+
+ Args:
+ bbox (ndarray): Bounding box(es) in shape (4,) or (n, 4), formatted
+ as (left, top, right, bottom)
+ padding (float): BBox padding factor that will be multilied to scale.
+ Default: 1.0
+
+ Returns:
+ tuple: A tuple containing center and scale.
+ - np.ndarray[float32]: Center (x, y) of the bbox in shape (2,) or
+ (n, 2)
+ - np.ndarray[float32]: Scale (w, h) of the bbox in shape (2,) or
+ (n, 2)
+ """
+ # convert single bbox from (4, ) to (1, 4)
+ dim = bbox.ndim
+ if dim == 1:
+ bbox = bbox[None, :]
+
+ # get bbox center and scale
+ x1, y1, x2, y2 = np.hsplit(bbox, [1, 2, 3])
+ center = np.hstack([x1 + x2, y1 + y2]) * 0.5
+ scale = np.hstack([x2 - x1, y2 - y1]) * padding
+
+ if dim == 1:
+ center = center[0]
+ scale = scale[0]
+
+ return center, scale
+
+
+def _fix_aspect_ratio(bbox_scale: np.ndarray,
+ aspect_ratio: float) -> np.ndarray:
+ """Extend the scale to match the given aspect ratio.
+
+ Args:
+ scale (np.ndarray): The image scale (w, h) in shape (2, )
+ aspect_ratio (float): The ratio of ``w/h``
+
+ Returns:
+ np.ndarray: The reshaped image scale in (2, )
+ """
+ w, h = np.hsplit(bbox_scale, [1])
+ bbox_scale = np.where(w > h * aspect_ratio,
+ np.hstack([w, w / aspect_ratio]),
+ np.hstack([h * aspect_ratio, h]))
+ return bbox_scale
+
+
+def _rotate_point(pt: np.ndarray, angle_rad: float) -> np.ndarray:
+ """Rotate a point by an angle.
+
+ Args:
+ pt (np.ndarray): 2D point coordinates (x, y) in shape (2, )
+ angle_rad (float): rotation angle in radian
+
+ Returns:
+ np.ndarray: Rotated point in shape (2, )
+ """
+ sn, cs = np.sin(angle_rad), np.cos(angle_rad)
+ rot_mat = np.array([[cs, -sn], [sn, cs]])
+ return rot_mat @ pt
+
+
+def _get_3rd_point(a: np.ndarray, b: np.ndarray) -> np.ndarray:
+ """To calculate the affine matrix, three pairs of points are required. This
+ function is used to get the 3rd point, given 2D points a & b.
+
+ The 3rd point is defined by rotating vector `a - b` by 90 degrees
+ anticlockwise, using b as the rotation center.
+
+ Args:
+ a (np.ndarray): The 1st point (x,y) in shape (2, )
+ b (np.ndarray): The 2nd point (x,y) in shape (2, )
+
+ Returns:
+ np.ndarray: The 3rd point.
+ """
+ direction = a - b
+ c = b + np.r_[-direction[1], direction[0]]
+ return c
+
+
+def get_warp_matrix(center: np.ndarray,
+ scale: np.ndarray,
+ rot: float,
+ output_size: Tuple[int, int],
+ shift: Tuple[float, float] = (0., 0.),
+ inv: bool = False) -> np.ndarray:
+ """Calculate the affine transformation matrix that can warp the bbox area
+ in the input image to the output size.
+
+ Args:
+ center (np.ndarray[2, ]): Center of the bounding box (x, y).
+ scale (np.ndarray[2, ]): Scale of the bounding box
+ wrt [width, height].
+ rot (float): Rotation angle (degree).
+ output_size (np.ndarray[2, ] | list(2,)): Size of the
+ destination heatmaps.
+ shift (0-100%): Shift translation ratio wrt the width/height.
+ Default (0., 0.).
+ inv (bool): Option to inverse the affine transform direction.
+ (inv=False: src->dst or inv=True: dst->src)
+
+ Returns:
+ np.ndarray: A 2x3 transformation matrix
+ """
+ shift = np.array(shift)
+ src_w = scale[0]
+ dst_w = output_size[0]
+ dst_h = output_size[1]
+
+ # compute transformation matrix
+ rot_rad = np.deg2rad(rot)
+ src_dir = _rotate_point(np.array([0., src_w * -0.5]), rot_rad)
+ dst_dir = np.array([0., dst_w * -0.5])
+
+ # get four corners of the src rectangle in the original image
+ src = np.zeros((3, 2), dtype=np.float32)
+ src[0, :] = center + scale * shift
+ src[1, :] = center + src_dir + scale * shift
+ src[2, :] = _get_3rd_point(src[0, :], src[1, :])
+
+ # get four corners of the dst rectangle in the input image
+ dst = np.zeros((3, 2), dtype=np.float32)
+ dst[0, :] = [dst_w * 0.5, dst_h * 0.5]
+ dst[1, :] = np.array([dst_w * 0.5, dst_h * 0.5]) + dst_dir
+ dst[2, :] = _get_3rd_point(dst[0, :], dst[1, :])
+
+ if inv:
+ warp_mat = cv2.getAffineTransform(np.float32(dst), np.float32(src))
+ else:
+ warp_mat = cv2.getAffineTransform(np.float32(src), np.float32(dst))
+
+ return warp_mat
+
+
+def top_down_affine(input_size: dict, bbox_scale: dict, bbox_center: dict,
+ img: np.ndarray) -> Tuple[np.ndarray, np.ndarray]:
+ """Get the bbox image as the model input by affine transform.
+
+ Args:
+ input_size (dict): The input size of the model.
+ bbox_scale (dict): The bbox scale of the img.
+ bbox_center (dict): The bbox center of the img.
+ img (np.ndarray): The original image.
+
+ Returns:
+ tuple: A tuple containing center and scale.
+ - np.ndarray[float32]: img after affine transform.
+ - np.ndarray[float32]: bbox scale after affine transform.
+ """
+ w, h = input_size
+ warp_size = (int(w), int(h))
+
+ # reshape bbox to fixed aspect ratio
+ bbox_scale = _fix_aspect_ratio(bbox_scale, aspect_ratio=w / h)
+
+ # get the affine matrix
+ center = bbox_center
+ scale = bbox_scale
+ rot = 0
+ warp_mat = get_warp_matrix(center, scale, rot, output_size=(w, h))
+
+ # do affine transform
+ img = cv2.warpAffine(img, warp_mat, warp_size, flags=cv2.INTER_LINEAR)
+
+ return img, bbox_scale
+
+
+def get_simcc_maximum(simcc_x: np.ndarray,
+ simcc_y: np.ndarray) -> Tuple[np.ndarray, np.ndarray]:
+ """Get maximum response location and value from simcc representations.
+
+ Note:
+ instance number: N
+ num_keypoints: K
+ heatmap height: H
+ heatmap width: W
+
+ Args:
+ simcc_x (np.ndarray): x-axis SimCC in shape (K, Wx) or (N, K, Wx)
+ simcc_y (np.ndarray): y-axis SimCC in shape (K, Wy) or (N, K, Wy)
+
+ Returns:
+ tuple:
+ - locs (np.ndarray): locations of maximum heatmap responses in shape
+ (K, 2) or (N, K, 2)
+ - vals (np.ndarray): values of maximum heatmap responses in shape
+ (K,) or (N, K)
+ """
+ N, K, Wx = simcc_x.shape
+ simcc_x = simcc_x.reshape(N * K, -1)
+ simcc_y = simcc_y.reshape(N * K, -1)
+
+ # get maximum value locations
+ x_locs = np.argmax(simcc_x, axis=1)
+ y_locs = np.argmax(simcc_y, axis=1)
+ locs = np.stack((x_locs, y_locs), axis=-1).astype(np.float32)
+ max_val_x = np.amax(simcc_x, axis=1)
+ max_val_y = np.amax(simcc_y, axis=1)
+
+ # get maximum value across x and y axis
+ mask = max_val_x > max_val_y
+ max_val_x[mask] = max_val_y[mask]
+ vals = max_val_x
+ locs[vals <= 0.] = -1
+
+ # reshape
+ locs = locs.reshape(N, K, 2)
+ vals = vals.reshape(N, K)
+
+ return locs, vals
+
+
+def decode(simcc_x: np.ndarray, simcc_y: np.ndarray,
+ simcc_split_ratio) -> Tuple[np.ndarray, np.ndarray]:
+ """Modulate simcc distribution with Gaussian.
+
+ Args:
+ simcc_x (np.ndarray[K, Wx]): model predicted simcc in x.
+ simcc_y (np.ndarray[K, Wy]): model predicted simcc in y.
+ simcc_split_ratio (int): The split ratio of simcc.
+
+ Returns:
+ tuple: A tuple containing center and scale.
+ - np.ndarray[float32]: keypoints in shape (K, 2) or (n, K, 2)
+ - np.ndarray[float32]: scores in shape (K,) or (n, K)
+ """
+ keypoints, scores = get_simcc_maximum(simcc_x, simcc_y)
+ keypoints /= simcc_split_ratio
+
+ return keypoints, scores
+
+
+def inference_pose(session, out_bbox, oriImg, model_input_size: Tuple[int, int]= (288, 384) ):
+ resized_img, center, scale = preprocess(oriImg, out_bbox, model_input_size)
+ outputs = inference(session, resized_img)
+ keypoints, scores = postprocess(outputs, model_input_size, center, scale)
+
+ return keypoints, scores
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/dwpose_utils/util.py b/VideoX-Fun/comfyui/annotator/dwpose_utils/util.py
new file mode 100644
index 0000000000000000000000000000000000000000..1c296984d8b1560ab63fd13b5a7ff31a13c71596
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/dwpose_utils/util.py
@@ -0,0 +1,359 @@
+import math
+import numpy as np
+import matplotlib
+import cv2
+
+eps = 0.01
+
+def smart_resize(x, s):
+ Ht, Wt = s
+ if x.ndim == 2:
+ Ho, Wo = x.shape
+ Co = 1
+ else:
+ Ho, Wo, Co = x.shape
+ if Co == 3 or Co == 1:
+ k = float(Ht + Wt) / float(Ho + Wo)
+ return cv2.resize(x, (int(Wt), int(Ht)), interpolation=cv2.INTER_AREA if k < 1 else cv2.INTER_LANCZOS4)
+ else:
+ return np.stack([smart_resize(x[:, :, i], s) for i in range(Co)], axis=2)
+
+def smart_resize_k(x, fx, fy):
+ if x.ndim == 2:
+ Ho, Wo = x.shape
+ Co = 1
+ else:
+ Ho, Wo, Co = x.shape
+ Ht, Wt = Ho * fy, Wo * fx
+ if Co == 3 or Co == 1:
+ k = float(Ht + Wt) / float(Ho + Wo)
+ return cv2.resize(x, (int(Wt), int(Ht)), interpolation=cv2.INTER_AREA if k < 1 else cv2.INTER_LANCZOS4)
+ else:
+ return np.stack([smart_resize_k(x[:, :, i], fx, fy) for i in range(Co)], axis=2)
+
+def padRightDownCorner(img, stride, padValue):
+ h = img.shape[0]
+ w = img.shape[1]
+
+ pad = 4 * [None]
+ pad[0] = 0 # up
+ pad[1] = 0 # left
+ pad[2] = 0 if (h % stride == 0) else stride - (h % stride) # down
+ pad[3] = 0 if (w % stride == 0) else stride - (w % stride) # right
+
+ img_padded = img
+ pad_up = np.tile(img_padded[0:1, :, :]*0 + padValue, (pad[0], 1, 1))
+ img_padded = np.concatenate((pad_up, img_padded), axis=0)
+ pad_left = np.tile(img_padded[:, 0:1, :]*0 + padValue, (1, pad[1], 1))
+ img_padded = np.concatenate((pad_left, img_padded), axis=1)
+ pad_down = np.tile(img_padded[-2:-1, :, :]*0 + padValue, (pad[2], 1, 1))
+ img_padded = np.concatenate((img_padded, pad_down), axis=0)
+ pad_right = np.tile(img_padded[:, -2:-1, :]*0 + padValue, (1, pad[3], 1))
+ img_padded = np.concatenate((img_padded, pad_right), axis=1)
+
+ return img_padded, pad
+
+def transfer(model, model_weights):
+ transfered_model_weights = {}
+ for weights_name in model.state_dict().keys():
+ transfered_model_weights[weights_name] = model_weights['.'.join(weights_name.split('.')[1:])]
+ return transfered_model_weights
+
+def is_normalized(keypoints) -> bool:
+ point_normalized = [
+ 0 <= abs(k.x) <= 1 and 0 <= abs(k.y) <= 1
+ for k in keypoints
+ if k is not None
+ ]
+ if not point_normalized:
+ return False
+ return all(point_normalized)
+
+def draw_bodypose(canvas: np.ndarray, keypoints) -> np.ndarray:
+ """
+ Draw keypoints and limbs representing body pose on a given canvas.
+
+ Args:
+ canvas (np.ndarray): A 3D numpy array representing the canvas (image) on which to draw the body pose.
+ keypoints (List[Keypoint]): A list of Keypoint objects representing the body keypoints to be drawn.
+
+ Returns:
+ np.ndarray: A 3D numpy array representing the modified canvas with the drawn body pose.
+
+ Note:
+ The function expects the x and y coordinates of the keypoints to be normalized between 0 and 1.
+ """
+ if not is_normalized(keypoints):
+ H, W = 1.0, 1.0
+ else:
+ H, W, _ = canvas.shape
+
+ stickwidth = 4
+
+ limbSeq = [
+ [2, 3], [2, 6], [3, 4], [4, 5],
+ [6, 7], [7, 8], [2, 9], [9, 10],
+ [10, 11], [2, 12], [12, 13], [13, 14],
+ [2, 1], [1, 15], [15, 17], [1, 16],
+ [16, 18],
+ ]
+
+ colors = [[255, 0, 0], [255, 85, 0], [255, 170, 0], [255, 255, 0], [170, 255, 0], [85, 255, 0], [0, 255, 0], \
+ [0, 255, 85], [0, 255, 170], [0, 255, 255], [0, 170, 255], [0, 85, 255], [0, 0, 255], [85, 0, 255], \
+ [170, 0, 255], [255, 0, 255], [255, 0, 170], [255, 0, 85]]
+
+ for (k1_index, k2_index), color in zip(limbSeq, colors):
+ keypoint1 = keypoints[k1_index - 1]
+ keypoint2 = keypoints[k2_index - 1]
+
+ if keypoint1 is None or keypoint2 is None:
+ continue
+
+ Y = np.array([keypoint1.x, keypoint2.x]) * float(W)
+ X = np.array([keypoint1.y, keypoint2.y]) * float(H)
+ mX = np.mean(X)
+ mY = np.mean(Y)
+ length = ((X[0] - X[1]) ** 2 + (Y[0] - Y[1]) ** 2) ** 0.5
+ angle = math.degrees(math.atan2(X[0] - X[1], Y[0] - Y[1]))
+ polygon = cv2.ellipse2Poly((int(mY), int(mX)), (int(length / 2), stickwidth), int(angle), 0, 360, 1)
+ cv2.fillConvexPoly(canvas, polygon, [int(float(c) * 0.6) for c in color])
+
+ for keypoint, color in zip(keypoints, colors):
+ if keypoint is None:
+ continue
+
+ x, y = keypoint.x, keypoint.y
+ x = int(x * W)
+ y = int(y * H)
+ cv2.circle(canvas, (int(x), int(y)), 4, color, thickness=-1)
+
+ return canvas
+
+def draw_handpose(canvas: np.ndarray, keypoints) -> np.ndarray:
+ """
+ Draw keypoints and connections representing hand pose on a given canvas.
+
+ Args:
+ canvas (np.ndarray): A 3D numpy array representing the canvas (image) on which to draw the hand pose.
+ keypoints (List[Keypoint]| None): A list of Keypoint objects representing the hand keypoints to be drawn
+ or None if no keypoints are present.
+
+ Returns:
+ np.ndarray: A 3D numpy array representing the modified canvas with the drawn hand pose.
+
+ Note:
+ The function expects the x and y coordinates of the keypoints to be normalized between 0 and 1.
+ """
+ if not keypoints:
+ return canvas
+
+ if not is_normalized(keypoints):
+ H, W = 1.0, 1.0
+ else:
+ H, W, _ = canvas.shape
+
+ edges = [[0, 1], [1, 2], [2, 3], [3, 4], [0, 5], [5, 6], [6, 7], [7, 8], [0, 9], [9, 10], \
+ [10, 11], [11, 12], [0, 13], [13, 14], [14, 15], [15, 16], [0, 17], [17, 18], [18, 19], [19, 20]]
+
+ for ie, (e1, e2) in enumerate(edges):
+ k1 = keypoints[e1]
+ k2 = keypoints[e2]
+ if k1 is None or k2 is None:
+ continue
+
+ x1 = int(k1.x * W)
+ y1 = int(k1.y * H)
+ x2 = int(k2.x * W)
+ y2 = int(k2.y * H)
+ if x1 > eps and y1 > eps and x2 > eps and y2 > eps:
+ cv2.line(canvas, (x1, y1), (x2, y2), matplotlib.colors.hsv_to_rgb([ie / float(len(edges)), 1.0, 1.0]) * 255, thickness=2)
+
+ for keypoint in keypoints:
+ if keypoint is None:
+ continue
+
+ x, y = keypoint.x, keypoint.y
+ x = int(x * W)
+ y = int(y * H)
+ if x > eps and y > eps:
+ cv2.circle(canvas, (x, y), 4, (0, 0, 255), thickness=-1)
+ return canvas
+
+
+def draw_facepose(canvas: np.ndarray, keypoints) -> np.ndarray:
+ """
+ Draw keypoints representing face pose on a given canvas.
+
+ Args:
+ canvas (np.ndarray): A 3D numpy array representing the canvas (image) on which to draw the face pose.
+ keypoints (List[Keypoint]| None): A list of Keypoint objects representing the face keypoints to be drawn
+ or None if no keypoints are present.
+
+ Returns:
+ np.ndarray: A 3D numpy array representing the modified canvas with the drawn face pose.
+
+ Note:
+ The function expects the x and y coordinates of the keypoints to be normalized between 0 and 1.
+ """
+ if not keypoints:
+ return canvas
+
+ if not is_normalized(keypoints):
+ H, W = 1.0, 1.0
+ else:
+ H, W, _ = canvas.shape
+
+ for keypoint in keypoints:
+ if keypoint is None:
+ continue
+
+ x, y = keypoint.x, keypoint.y
+ x = int(x * W)
+ y = int(y * H)
+ if x > eps and y > eps:
+ cv2.circle(canvas, (x, y), 3, (255, 255, 255), thickness=-1)
+ return canvas
+
+# detect hand according to body pose keypoints
+# please refer to https://github.com/CMU-Perceptual-Computing-Lab/openpose/blob/master/src/openpose/hand/handDetector.cpp
+def handDetect(candidate, subset, oriImg):
+ # right hand: wrist 4, elbow 3, shoulder 2
+ # left hand: wrist 7, elbow 6, shoulder 5
+ ratioWristElbow = 0.33
+ detect_result = []
+ image_height, image_width = oriImg.shape[0:2]
+ for person in subset.astype(int):
+ # if any of three not detected
+ has_left = np.sum(person[[5, 6, 7]] == -1) == 0
+ has_right = np.sum(person[[2, 3, 4]] == -1) == 0
+ if not (has_left or has_right):
+ continue
+ hands = []
+ #left hand
+ if has_left:
+ left_shoulder_index, left_elbow_index, left_wrist_index = person[[5, 6, 7]]
+ x1, y1 = candidate[left_shoulder_index][:2]
+ x2, y2 = candidate[left_elbow_index][:2]
+ x3, y3 = candidate[left_wrist_index][:2]
+ hands.append([x1, y1, x2, y2, x3, y3, True])
+ # right hand
+ if has_right:
+ right_shoulder_index, right_elbow_index, right_wrist_index = person[[2, 3, 4]]
+ x1, y1 = candidate[right_shoulder_index][:2]
+ x2, y2 = candidate[right_elbow_index][:2]
+ x3, y3 = candidate[right_wrist_index][:2]
+ hands.append([x1, y1, x2, y2, x3, y3, False])
+
+ for x1, y1, x2, y2, x3, y3, is_left in hands:
+ # pos_hand = pos_wrist + ratio * (pos_wrist - pos_elbox) = (1 + ratio) * pos_wrist - ratio * pos_elbox
+ # handRectangle.x = posePtr[wrist*3] + ratioWristElbow * (posePtr[wrist*3] - posePtr[elbow*3]);
+ # handRectangle.y = posePtr[wrist*3+1] + ratioWristElbow * (posePtr[wrist*3+1] - posePtr[elbow*3+1]);
+ # const auto distanceWristElbow = getDistance(poseKeypoints, person, wrist, elbow);
+ # const auto distanceElbowShoulder = getDistance(poseKeypoints, person, elbow, shoulder);
+ # handRectangle.width = 1.5f * fastMax(distanceWristElbow, 0.9f * distanceElbowShoulder);
+ x = x3 + ratioWristElbow * (x3 - x2)
+ y = y3 + ratioWristElbow * (y3 - y2)
+ distanceWristElbow = math.sqrt((x3 - x2) ** 2 + (y3 - y2) ** 2)
+ distanceElbowShoulder = math.sqrt((x2 - x1) ** 2 + (y2 - y1) ** 2)
+ width = 1.5 * max(distanceWristElbow, 0.9 * distanceElbowShoulder)
+ # x-y refers to the center --> offset to topLeft point
+ # handRectangle.x -= handRectangle.width / 2.f;
+ # handRectangle.y -= handRectangle.height / 2.f;
+ x -= width / 2
+ y -= width / 2 # width = height
+ # overflow the image
+ if x < 0: x = 0
+ if y < 0: y = 0
+ width1 = width
+ width2 = width
+ if x + width > image_width: width1 = image_width - x
+ if y + width > image_height: width2 = image_height - y
+ width = min(width1, width2)
+ # the max hand box value is 20 pixels
+ if width >= 20:
+ detect_result.append([int(x), int(y), int(width), is_left])
+
+ '''
+ return value: [[x, y, w, True if left hand else False]].
+ width=height since the network require squared input.
+ x, y is the coordinate of top left
+ '''
+ return detect_result
+
+# Written by Lvmin
+def faceDetect(candidate, subset, oriImg):
+ # left right eye ear 14 15 16 17
+ detect_result = []
+ image_height, image_width = oriImg.shape[0:2]
+ for person in subset.astype(int):
+ has_head = person[0] > -1
+ if not has_head:
+ continue
+
+ has_left_eye = person[14] > -1
+ has_right_eye = person[15] > -1
+ has_left_ear = person[16] > -1
+ has_right_ear = person[17] > -1
+
+ if not (has_left_eye or has_right_eye or has_left_ear or has_right_ear):
+ continue
+
+ head, left_eye, right_eye, left_ear, right_ear = person[[0, 14, 15, 16, 17]]
+
+ width = 0.0
+ x0, y0 = candidate[head][:2]
+
+ if has_left_eye:
+ x1, y1 = candidate[left_eye][:2]
+ d = max(abs(x0 - x1), abs(y0 - y1))
+ width = max(width, d * 3.0)
+
+ if has_right_eye:
+ x1, y1 = candidate[right_eye][:2]
+ d = max(abs(x0 - x1), abs(y0 - y1))
+ width = max(width, d * 3.0)
+
+ if has_left_ear:
+ x1, y1 = candidate[left_ear][:2]
+ d = max(abs(x0 - x1), abs(y0 - y1))
+ width = max(width, d * 1.5)
+
+ if has_right_ear:
+ x1, y1 = candidate[right_ear][:2]
+ d = max(abs(x0 - x1), abs(y0 - y1))
+ width = max(width, d * 1.5)
+
+ x, y = x0, y0
+
+ x -= width
+ y -= width
+
+ if x < 0:
+ x = 0
+
+ if y < 0:
+ y = 0
+
+ width1 = width * 2
+ width2 = width * 2
+
+ if x + width > image_width:
+ width1 = image_width - x
+
+ if y + width > image_height:
+ width2 = image_height - y
+
+ width = min(width1, width2)
+
+ if width >= 20:
+ detect_result.append([int(x), int(y), int(width)])
+
+ return detect_result
+
+# get max index of 2d array
+def npmax(array):
+ arrayindex = array.argmax(1)
+ arrayvalue = array.max(1)
+ i = arrayvalue.argmax()
+ j = arrayindex[i]
+ return i, j
diff --git a/VideoX-Fun/comfyui/annotator/dwpose_utils/wholebody.py b/VideoX-Fun/comfyui/annotator/dwpose_utils/wholebody.py
new file mode 100644
index 0000000000000000000000000000000000000000..3c1d88c43afb66826a5bb7d62584004163574f8c
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/dwpose_utils/wholebody.py
@@ -0,0 +1,129 @@
+import cv2
+import numpy as np
+
+import onnxruntime as ort
+from .onnxdet import inference_detector
+from .onnxpose import inference_pose
+from typing import NamedTuple, List, Optional, Union
+
+
+class Keypoint(NamedTuple):
+ x: float
+ y: float
+ score: float = 1.0
+ id: int = -1
+
+
+class BodyResult(NamedTuple):
+ # Note: Using `Optional` instead of `|` operator as the ladder is a Python
+ # 3.10 feature.
+ # Annotator code should be Python 3.8 Compatible, as controlnet repo uses
+ # Python 3.8 environment.
+ # https://github.com/lllyasviel/ControlNet/blob/d3284fcd0972c510635a4f5abe2eeb71dc0de524/environment.yaml#L6
+ keypoints: List[Optional[Keypoint]]
+ total_score: float = 0.0
+ total_parts: int = 0
+
+
+HandResult = List[Keypoint]
+FaceResult = List[Keypoint]
+AnimalPoseResult = List[Keypoint]
+
+
+class HumanPoseResult(NamedTuple):
+ body: BodyResult
+ left_hand: Optional[HandResult]
+ right_hand: Optional[HandResult]
+ face: Optional[FaceResult]
+
+
+class Wholebody:
+ def __init__(self, onnx_det: str, onnx_pose: str):
+ # Always loads to CPU to avoid building OpenCV.
+ device = 'cpu'
+ backend = cv2.dnn.DNN_BACKEND_OPENCV if device == 'cpu' else cv2.dnn.DNN_BACKEND_CUDA
+ # You need to manually build OpenCV through cmake to work with your GPU.
+ providers = cv2.dnn.DNN_TARGET_CPU if device == 'cpu' else cv2.dnn.DNN_TARGET_CUDA
+
+ self.session_det = cv2.dnn.readNetFromONNX(onnx_det)
+ self.session_det.setPreferableBackend(backend)
+ self.session_det.setPreferableTarget(providers)
+
+ self.session_pose = cv2.dnn.readNetFromONNX(onnx_pose)
+ self.session_pose.setPreferableBackend(backend)
+ self.session_pose.setPreferableTarget(providers)
+
+ def __call__(self, oriImg):
+ det_result = inference_detector(self.session_det, oriImg)
+ if det_result is None:
+ return None
+
+ keypoints, scores = inference_pose(self.session_pose, det_result, oriImg)
+
+ keypoints_info = np.concatenate(
+ (keypoints, scores[..., None]), axis=-1)
+ # compute neck joint
+ neck = np.mean(keypoints_info[:, [5, 6]], axis=1)
+ # neck score when visualizing pred
+ neck[:, 2:4] = np.logical_and(
+ keypoints_info[:, 5, 2:4] > 0.3,
+ keypoints_info[:, 6, 2:4] > 0.3).astype(int)
+ new_keypoints_info = np.insert(
+ keypoints_info, 17, neck, axis=1)
+ mmpose_idx = [
+ 17, 6, 8, 10, 7, 9, 12, 14, 16, 13, 15, 2, 1, 4, 3
+ ]
+ openpose_idx = [
+ 1, 2, 3, 4, 6, 7, 8, 9, 10, 12, 13, 14, 15, 16, 17
+ ]
+ new_keypoints_info[:, openpose_idx] = \
+ new_keypoints_info[:, mmpose_idx]
+ keypoints_info = new_keypoints_info
+
+ return keypoints_info
+
+ @staticmethod
+ def format_result(keypoints_info: Optional[np.ndarray]) -> List[HumanPoseResult]:
+ def format_keypoint_part(
+ part: np.ndarray,
+ ) -> Optional[List[Optional[Keypoint]]]:
+ keypoints = [
+ Keypoint(x, y, score, i) if score >= 0.3 else None
+ for i, (x, y, score) in enumerate(part)
+ ]
+ return (
+ None if all(keypoint is None for keypoint in keypoints) else keypoints
+ )
+
+ def total_score(keypoints: Optional[List[Optional[Keypoint]]]) -> float:
+ return (
+ sum(keypoint.score for keypoint in keypoints if keypoint is not None)
+ if keypoints is not None
+ else 0.0
+ )
+
+ pose_results = []
+ if keypoints_info is None:
+ return pose_results
+
+ for instance in keypoints_info:
+ body_keypoints = format_keypoint_part(instance[:18]) or ([None] * 18)
+ left_hand = format_keypoint_part(instance[92:113])
+ right_hand = format_keypoint_part(instance[113:134])
+ face = format_keypoint_part(instance[24:92])
+
+ # Openpose face consists of 70 points in total, while DWPose only
+ # provides 68 points. Padding the last 2 points.
+ if face is not None:
+ # left eye
+ face.append(body_keypoints[14])
+ # right eye
+ face.append(body_keypoints[15])
+
+ body = BodyResult(
+ body_keypoints, total_score(body_keypoints), len(body_keypoints)
+ )
+ pose_results.append(HumanPoseResult(body, left_hand, right_hand, face))
+
+ return pose_results
+
diff --git a/VideoX-Fun/comfyui/annotator/nodes.py b/VideoX-Fun/comfyui/annotator/nodes.py
new file mode 100644
index 0000000000000000000000000000000000000000..1fcd9cec5b9493e117d09392491c09b52a2e82fa
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/nodes.py
@@ -0,0 +1,274 @@
+# This folder is modified from the https://github.com/Mikubill/sd-webui-controlnet
+import os
+
+import cv2
+import folder_paths
+import numpy as np
+import torch
+from einops import rearrange
+
+from .dwpose_utils import DWposeDetector
+from .zoe.zoedepth.models.zoedepth.zoedepth_v1 import ZoeDepth
+from .zoe.zoedepth.utils.config import get_config
+
+remote_onnx_det = "https://huggingface.co/yzd-v/DWPose/resolve/main/yolox_l.onnx"
+remote_onnx_pose = "https://huggingface.co/yzd-v/DWPose/resolve/main/dw-ll_ucoco_384.onnx"
+remote_zoe= "https://huggingface.co/lllyasviel/Annotators/resolve/main/ZoeD_M12_N.pt"
+
+def read_video(video_path):
+ cap = cv2.VideoCapture(video_path)
+ frames = []
+ while cap.isOpened():
+ ret, frame = cap.read()
+ if not ret:
+ break
+ frame = cv2.cvtColor(frame, cv2.COLOR_RGB2BGR)
+ frames.append(frame)
+ cap.release()
+ return frames
+
+def HWC3(x):
+ assert x.dtype == np.uint8
+ if x.ndim == 2:
+ x = x[:, :, None]
+ assert x.ndim == 3
+ H, W, C = x.shape
+ assert C == 1 or C == 3 or C == 4
+ if C == 3:
+ return x
+ if C == 1:
+ return np.concatenate([x, x, x], axis=2)
+ if C == 4:
+ color = x[:, :, 0:3].astype(np.float32)
+ alpha = x[:, :, 3:4].astype(np.float32) / 255.0
+ y = color * alpha + 255.0 * (1.0 - alpha)
+ y = y.clip(0, 255).astype(np.uint8)
+ return y
+
+def pad64(x):
+ return int(np.ceil(float(x) / 64.0) * 64 - x)
+
+def safer_memory(x):
+ # Fix many MAC/AMD problems
+ return np.ascontiguousarray(x.copy()).copy()
+
+def resize_image_with_pad(input_image, resolution, skip_hwc3=False):
+ if skip_hwc3:
+ img = input_image
+ else:
+ img = HWC3(input_image)
+ H_raw, W_raw, _ = img.shape
+ k = float(resolution) / float(min(H_raw, W_raw))
+ interpolation = cv2.INTER_CUBIC if k > 1 else cv2.INTER_AREA
+ H_target = int(np.round(float(H_raw) * k))
+ W_target = int(np.round(float(W_raw) * k))
+ img = cv2.resize(img, (W_target, H_target), interpolation=interpolation)
+ H_pad, W_pad = pad64(H_target), pad64(W_target)
+ img_padded = np.pad(img, [[0, H_pad], [0, W_pad], [0, 0]], mode='edge')
+
+ def remove_pad(x):
+ return safer_memory(x[:H_target, :W_target])
+
+ return safer_memory(img_padded), remove_pad
+
+def load_file_from_url(
+ url: str,
+ model_dir: str,
+ progress: bool = True,
+ file_name: str | None = None,
+ hash_prefix: str | None = None,
+) -> str:
+ """Download a file from `url` into `model_dir`, using the file present if possible.
+
+ Returns the path to the downloaded file.
+ """
+ from urllib.parse import urlparse
+ os.makedirs(model_dir, exist_ok=True)
+ if not file_name:
+ parts = urlparse(url)
+ file_name = os.path.basename(parts.path)
+ cached_file = os.path.abspath(os.path.join(model_dir, file_name))
+ if not os.path.exists(cached_file):
+ print(f'Downloading: "{url}" to {cached_file}\n')
+ from torch.hub import download_url_to_file
+ download_url_to_file(url, cached_file, progress=progress, hash_prefix=hash_prefix)
+ return cached_file
+
+class VideoToCanny:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "input_video": ("IMAGE",),
+ "low_threshold": ("INT", {"default": 100, "min": 0, "max": 255, "step": 1}),
+ "high_threshold": ("INT", {"default": 200, "min": 0, "max": 255, "step": 1}),
+ "video_length": (
+ "INT", {"default": 81, "min": 1, "max": 81, "step": 4}
+ ),
+ }
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES =("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, input_video, low_threshold, high_threshold, video_length):
+ def extract_canny_frames(frames):
+ canny_frames = []
+ for frame in frames:
+ gray = cv2.cvtColor(frame, cv2.COLOR_RGB2GRAY)
+ edges = cv2.Canny(gray, low_threshold, high_threshold)
+ edges_colored = cv2.cvtColor(edges, cv2.COLOR_GRAY2RGB)
+ canny_frames.append(edges_colored)
+ return canny_frames
+
+ if type(input_video) is str:
+ video_frames = read_video(input_video)
+ else:
+ video_frames = np.array(input_video * 255, np.uint8)[:video_length]
+ output_video = extract_canny_frames(video_frames)
+ output_video = torch.from_numpy(np.array(output_video)) / 255
+ return (output_video,)
+
+class VideoToDepth:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "input_video": ("IMAGE",),
+ "video_length": (
+ "INT", {"default": 81, "min": 1, "max": 81, "step": 4}
+ ),
+ }
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES = ("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+
+ def process_frame(self, model, image, device, weight_dtype):
+ with torch.no_grad():
+ image, remove_pad = resize_image_with_pad(image, 512)
+ image_depth = image
+ with torch.no_grad():
+ image_depth = torch.from_numpy(image_depth).to(device, weight_dtype)
+ image_depth = image_depth / 255.0
+ image_depth = rearrange(image_depth, 'h w c -> 1 c h w')
+ depth = model.infer(image_depth)
+
+ depth = depth[0, 0].cpu().numpy()
+
+ vmin = np.percentile(depth, 2)
+ vmax = np.percentile(depth, 85)
+
+ depth -= vmin
+ depth /= vmax - vmin
+ depth = 1.0 - depth
+ depth_image = (depth * 255.0).clip(0, 255).astype(np.uint8)
+ image = remove_pad(depth_image)
+ image = HWC3(image)
+ return image
+
+ def process(self, input_video, video_length):
+ model = ZoeDepth.build_from_config(get_config("zoedepth", "infer"))
+
+ # Detect model is existing or not
+ possible_folders = ["CogVideoX_Fun/Third_Party", "Fun_Models/Third_Party", "VideoX_Fun/Third_Party"] # Possible folder names to check
+
+ # Check if the model exists in any of the possible folders within folder_paths.models_dir
+ zoe_model_path = "ZoeD_M12_N.pt"
+ for folder in possible_folders:
+ candidate_path = os.path.join(folder_paths.models_dir, folder, zoe_model_path)
+ if os.path.exists(candidate_path):
+ zoe_model_path = candidate_path
+ break
+ if not os.path.exists(zoe_model_path):
+ load_file_from_url(remote_zoe, model_dir=os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party"))
+ zoe_model_path = os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party", zoe_model_path)
+
+ model.load_state_dict(
+ torch.load(zoe_model_path, map_location="cpu")['model'],
+ strict=False
+ )
+ if torch.cuda.is_available():
+ device = "cuda"
+ weight_dtype = torch.float32
+ else:
+ device = "cpu"
+ weight_dtype = torch.float32
+ model = model.to(device=device, dtype=weight_dtype).eval().requires_grad_(False)
+
+ if isinstance(input_video, str):
+ video_frames = read_video(input_video)
+ else:
+ video_frames = np.array(input_video * 255, np.uint8)[:video_length]
+
+ output_video = [self.process_frame(model, frame, device, weight_dtype) for frame in video_frames]
+ output_video = torch.from_numpy(np.array(output_video)) / 255
+
+ return (output_video,)
+
+
+class VideoToPose:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "input_video": ("IMAGE",),
+ "video_length": (
+ "INT", {"default": 81, "min": 1, "max": 81, "step": 4}
+ ),
+ }
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES = ("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process_frame(self, model, image):
+ with torch.no_grad():
+ image, remove_pad = resize_image_with_pad(image, 512)
+ pose_image = model(image)
+ image = remove_pad(pose_image)
+ image = HWC3(image)
+ return image
+
+ def process(self, input_video, video_length):
+ # Detect model is existing or not
+ possible_folders = ["CogVideoX_Fun/Third_Party", "Fun_Models/Third_Party", "VideoX_Fun/Third_Party"] # Possible folder names to check
+
+ # Check if the model exists in any of the possible folders within folder_paths.models_dir
+ onnx_det = "yolox_l.onnx"
+ for folder in possible_folders:
+ candidate_path = os.path.join(folder_paths.models_dir, folder, onnx_det)
+ if os.path.exists(candidate_path):
+ onnx_det = candidate_path
+ break
+ if not os.path.exists(onnx_det):
+ load_file_from_url(remote_onnx_det, os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party"))
+ onnx_det = os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party", onnx_det)
+
+ onnx_pose = "dw-ll_ucoco_384.onnx"
+ for folder in possible_folders:
+ candidate_path = os.path.join(folder_paths.models_dir, folder, onnx_pose)
+ if os.path.exists(candidate_path):
+ onnx_pose = candidate_path
+ break
+ if not os.path.exists(onnx_pose):
+ load_file_from_url(remote_onnx_pose, os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party"))
+ onnx_pose = os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party", onnx_pose)
+
+ model = DWposeDetector(onnx_det, onnx_pose)
+
+ if isinstance(input_video, str):
+ video_frames = read_video(input_video)
+ else:
+ video_frames = np.array(input_video * 255, np.uint8)[:video_length]
+
+ output_video = [self.process_frame(model, frame) for frame in video_frames]
+ output_video = torch.from_numpy(np.array(output_video)) / 255
+ return (output_video,)
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/LICENSE b/VideoX-Fun/comfyui/annotator/zoe/LICENSE
new file mode 100644
index 0000000000000000000000000000000000000000..7a1e90d007836c327846ce8e5151013b115042ab
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/LICENSE
@@ -0,0 +1,21 @@
+MIT License
+
+Copyright (c) 2022 Intelligent Systems Lab Org
+
+Permission is hereby granted, free of charge, to any person obtaining a copy
+of this software and associated documentation files (the "Software"), to deal
+in the Software without restriction, including without limitation the rights
+to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+copies of the Software, and to permit persons to whom the Software is
+furnished to do so, subject to the following conditions:
+
+The above copyright notice and this permission notice shall be included in all
+copies or substantial portions of the Software.
+
+THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+SOFTWARE.
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/__init__.py b/VideoX-Fun/comfyui/annotator/zoe/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..c0ba8ae4b73f6424e6c1e6364571103d5b58027c
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/__init__.py
@@ -0,0 +1,40 @@
+# This folder is modified from the https://github.com/Mikubill/sd-webui-controlnet
+import os
+import cv2
+import numpy as np
+import torch
+from torch import nn
+
+from einops import rearrange
+from .zoedepth.models.zoedepth.zoedepth_v1 import ZoeDepth
+from .zoedepth.utils.config import get_config
+
+
+class ZoeDetector(nn.Module):
+ def __init__(self, model_path):
+ conf = get_config("zoedepth", "infer")
+ model = ZoeDepth.build_from_config(conf)
+ model.load_state_dict(torch.load(model_path, map_location=model.device)['model'])
+ model.eval()
+ self.model = model
+
+ def __call__(self, input_image):
+ assert input_image.ndim == 3
+ image_depth = input_image
+ with torch.no_grad():
+ image_depth = torch.from_numpy(image_depth).float()
+ image_depth = image_depth / 255.0
+ image_depth = rearrange(image_depth, 'h w c -> 1 c h w')
+ depth = self.model.infer(image_depth)
+
+ depth = depth[0, 0].cpu().numpy()
+
+ vmin = np.percentile(depth, 2)
+ vmax = np.percentile(depth, 85)
+
+ depth -= vmin
+ depth /= vmax - vmin
+ depth = 1.0 - depth
+ depth_image = (depth * 255.0).clip(0, 255).astype(np.uint8)
+
+ return depth_image
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/__init__.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..1ae1a1e4e86d9a5b14586cd006ed43d2bbc9b4a6
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/__init__.py
@@ -0,0 +1,24 @@
+# MIT License
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/__init__.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..1ae1a1e4e86d9a5b14586cd006ed43d2bbc9b4a6
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/__init__.py
@@ -0,0 +1,24 @@
+# MIT License
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas.py
new file mode 100644
index 0000000000000000000000000000000000000000..380c34974ad2528be9ed7d8ad0f5e9e264ecac8d
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas.py
@@ -0,0 +1,379 @@
+# MIT License
+import os
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
+import torch
+import torch.nn as nn
+import numpy as np
+from torchvision.transforms import Normalize
+
+
+def denormalize(x):
+ """Reverses the imagenet normalization applied to the input.
+
+ Args:
+ x (torch.Tensor - shape(N,3,H,W)): input tensor
+
+ Returns:
+ torch.Tensor - shape(N,3,H,W): Denormalized input
+ """
+ mean = torch.Tensor([0.485, 0.456, 0.406]).view(1, 3, 1, 1).to(x.device)
+ std = torch.Tensor([0.229, 0.224, 0.225]).view(1, 3, 1, 1).to(x.device)
+ return x * std + mean
+
+def get_activation(name, bank):
+ def hook(model, input, output):
+ bank[name] = output
+ return hook
+
+
+class Resize(object):
+ """Resize sample to given size (width, height).
+ """
+
+ def __init__(
+ self,
+ width,
+ height,
+ resize_target=True,
+ keep_aspect_ratio=False,
+ ensure_multiple_of=1,
+ resize_method="lower_bound",
+ ):
+ """Init.
+ Args:
+ width (int): desired output width
+ height (int): desired output height
+ resize_target (bool, optional):
+ True: Resize the full sample (image, mask, target).
+ False: Resize image only.
+ Defaults to True.
+ keep_aspect_ratio (bool, optional):
+ True: Keep the aspect ratio of the input sample.
+ Output sample might not have the given width and height, and
+ resize behaviour depends on the parameter 'resize_method'.
+ Defaults to False.
+ ensure_multiple_of (int, optional):
+ Output width and height is constrained to be multiple of this parameter.
+ Defaults to 1.
+ resize_method (str, optional):
+ "lower_bound": Output will be at least as large as the given size.
+ "upper_bound": Output will be at max as large as the given size. (Output size might be smaller than given size.)
+ "minimal": Scale as least as possible. (Output size might be smaller than given size.)
+ Defaults to "lower_bound".
+ """
+ print("Params passed to Resize transform:")
+ print("\twidth: ", width)
+ print("\theight: ", height)
+ print("\tresize_target: ", resize_target)
+ print("\tkeep_aspect_ratio: ", keep_aspect_ratio)
+ print("\tensure_multiple_of: ", ensure_multiple_of)
+ print("\tresize_method: ", resize_method)
+
+ self.__width = width
+ self.__height = height
+
+ self.__keep_aspect_ratio = keep_aspect_ratio
+ self.__multiple_of = ensure_multiple_of
+ self.__resize_method = resize_method
+
+ def constrain_to_multiple_of(self, x, min_val=0, max_val=None):
+ y = (np.round(x / self.__multiple_of) * self.__multiple_of).astype(int)
+
+ if max_val is not None and y > max_val:
+ y = (np.floor(x / self.__multiple_of)
+ * self.__multiple_of).astype(int)
+
+ if y < min_val:
+ y = (np.ceil(x / self.__multiple_of)
+ * self.__multiple_of).astype(int)
+
+ return y
+
+ def get_size(self, width, height):
+ # determine new height and width
+ scale_height = self.__height / height
+ scale_width = self.__width / width
+
+ if self.__keep_aspect_ratio:
+ if self.__resize_method == "lower_bound":
+ # scale such that output size is lower bound
+ if scale_width > scale_height:
+ # fit width
+ scale_height = scale_width
+ else:
+ # fit height
+ scale_width = scale_height
+ elif self.__resize_method == "upper_bound":
+ # scale such that output size is upper bound
+ if scale_width < scale_height:
+ # fit width
+ scale_height = scale_width
+ else:
+ # fit height
+ scale_width = scale_height
+ elif self.__resize_method == "minimal":
+ # scale as least as possbile
+ if abs(1 - scale_width) < abs(1 - scale_height):
+ # fit width
+ scale_height = scale_width
+ else:
+ # fit height
+ scale_width = scale_height
+ else:
+ raise ValueError(
+ f"resize_method {self.__resize_method} not implemented"
+ )
+
+ if self.__resize_method == "lower_bound":
+ new_height = self.constrain_to_multiple_of(
+ scale_height * height, min_val=self.__height
+ )
+ new_width = self.constrain_to_multiple_of(
+ scale_width * width, min_val=self.__width
+ )
+ elif self.__resize_method == "upper_bound":
+ new_height = self.constrain_to_multiple_of(
+ scale_height * height, max_val=self.__height
+ )
+ new_width = self.constrain_to_multiple_of(
+ scale_width * width, max_val=self.__width
+ )
+ elif self.__resize_method == "minimal":
+ new_height = self.constrain_to_multiple_of(scale_height * height)
+ new_width = self.constrain_to_multiple_of(scale_width * width)
+ else:
+ raise ValueError(
+ f"resize_method {self.__resize_method} not implemented")
+
+ return (new_width, new_height)
+
+ def __call__(self, x):
+ width, height = self.get_size(*x.shape[-2:][::-1])
+ return nn.functional.interpolate(x, (int(height), int(width)), mode='bilinear', align_corners=True)
+
+class PrepForMidas(object):
+ def __init__(self, resize_mode="minimal", keep_aspect_ratio=True, img_size=384, do_resize=True):
+ if isinstance(img_size, int):
+ img_size = (img_size, img_size)
+ net_h, net_w = img_size
+ self.normalization = Normalize(
+ mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
+ self.resizer = Resize(net_w, net_h, keep_aspect_ratio=keep_aspect_ratio, ensure_multiple_of=32, resize_method=resize_mode) \
+ if do_resize else nn.Identity()
+
+ def __call__(self, x):
+ return self.normalization(self.resizer(x))
+
+
+class MidasCore(nn.Module):
+ def __init__(self, midas, trainable=False, fetch_features=True, layer_names=('out_conv', 'l4_rn', 'r4', 'r3', 'r2', 'r1'), freeze_bn=False, keep_aspect_ratio=True,
+ img_size=384, **kwargs):
+ """Midas Base model used for multi-scale feature extraction.
+
+ Args:
+ midas (torch.nn.Module): Midas model.
+ trainable (bool, optional): Train midas model. Defaults to False.
+ fetch_features (bool, optional): Extract multi-scale features. Defaults to True.
+ layer_names (tuple, optional): Layers used for feature extraction. Order = (head output features, last layer features, ...decoder features). Defaults to ('out_conv', 'l4_rn', 'r4', 'r3', 'r2', 'r1').
+ freeze_bn (bool, optional): Freeze BatchNorm. Generally results in better finetuning performance. Defaults to False.
+ keep_aspect_ratio (bool, optional): Keep the aspect ratio of input images while resizing. Defaults to True.
+ img_size (int, tuple, optional): Input resolution. Defaults to 384.
+ """
+ super().__init__()
+ self.core = midas
+ self.output_channels = None
+ self.core_out = {}
+ self.trainable = trainable
+ self.fetch_features = fetch_features
+ # midas.scratch.output_conv = nn.Identity()
+ self.handles = []
+ # self.layer_names = ['out_conv','l4_rn', 'r4', 'r3', 'r2', 'r1']
+ self.layer_names = layer_names
+
+ self.set_trainable(trainable)
+ self.set_fetch_features(fetch_features)
+
+ self.prep = PrepForMidas(keep_aspect_ratio=keep_aspect_ratio,
+ img_size=img_size, do_resize=kwargs.get('do_resize', True))
+
+ if freeze_bn:
+ self.freeze_bn()
+
+ def set_trainable(self, trainable):
+ self.trainable = trainable
+ if trainable:
+ self.unfreeze()
+ else:
+ self.freeze()
+ return self
+
+ def set_fetch_features(self, fetch_features):
+ self.fetch_features = fetch_features
+ if fetch_features:
+ if len(self.handles) == 0:
+ self.attach_hooks(self.core)
+ else:
+ self.remove_hooks()
+ return self
+
+ def freeze(self):
+ for p in self.parameters():
+ p.requires_grad = False
+ self.trainable = False
+ return self
+
+ def unfreeze(self):
+ for p in self.parameters():
+ p.requires_grad = True
+ self.trainable = True
+ return self
+
+ def freeze_bn(self):
+ for m in self.modules():
+ if isinstance(m, nn.BatchNorm2d):
+ m.eval()
+ return self
+
+ def forward(self, x, denorm=False, return_rel_depth=False):
+ with torch.no_grad():
+ if denorm:
+ x = denormalize(x)
+ x = self.prep(x)
+ # print("Shape after prep: ", x.shape)
+
+ with torch.set_grad_enabled(self.trainable):
+
+ # print("Input size to Midascore", x.shape)
+ rel_depth = self.core(x)
+ # print("Output from midas shape", rel_depth.shape)
+ if not self.fetch_features:
+ return rel_depth
+ out = [self.core_out[k] for k in self.layer_names]
+
+ if return_rel_depth:
+ return rel_depth, out
+ return out
+
+ def get_rel_pos_params(self):
+ for name, p in self.core.pretrained.named_parameters():
+ if "relative_position" in name:
+ yield p
+
+ def get_enc_params_except_rel_pos(self):
+ for name, p in self.core.pretrained.named_parameters():
+ if "relative_position" not in name:
+ yield p
+
+ def freeze_encoder(self, freeze_rel_pos=False):
+ if freeze_rel_pos:
+ for p in self.core.pretrained.parameters():
+ p.requires_grad = False
+ else:
+ for p in self.get_enc_params_except_rel_pos():
+ p.requires_grad = False
+ return self
+
+ def attach_hooks(self, midas):
+ if len(self.handles) > 0:
+ self.remove_hooks()
+ if "out_conv" in self.layer_names:
+ self.handles.append(list(midas.scratch.output_conv.children())[
+ 3].register_forward_hook(get_activation("out_conv", self.core_out)))
+ if "r4" in self.layer_names:
+ self.handles.append(midas.scratch.refinenet4.register_forward_hook(
+ get_activation("r4", self.core_out)))
+ if "r3" in self.layer_names:
+ self.handles.append(midas.scratch.refinenet3.register_forward_hook(
+ get_activation("r3", self.core_out)))
+ if "r2" in self.layer_names:
+ self.handles.append(midas.scratch.refinenet2.register_forward_hook(
+ get_activation("r2", self.core_out)))
+ if "r1" in self.layer_names:
+ self.handles.append(midas.scratch.refinenet1.register_forward_hook(
+ get_activation("r1", self.core_out)))
+ if "l4_rn" in self.layer_names:
+ self.handles.append(midas.scratch.layer4_rn.register_forward_hook(
+ get_activation("l4_rn", self.core_out)))
+
+ return self
+
+ def remove_hooks(self):
+ for h in self.handles:
+ h.remove()
+ return self
+
+ def __del__(self):
+ self.remove_hooks()
+
+ def set_output_channels(self, model_type):
+ self.output_channels = MIDAS_SETTINGS[model_type]
+
+ @staticmethod
+ def build(midas_model_type="DPT_BEiT_L_384", train_midas=False, use_pretrained_midas=True, fetch_features=False, freeze_bn=True, force_keep_ar=False, force_reload=False, **kwargs):
+ if midas_model_type not in MIDAS_SETTINGS:
+ raise ValueError(
+ f"Invalid model type: {midas_model_type}. Must be one of {list(MIDAS_SETTINGS.keys())}")
+ if "img_size" in kwargs:
+ kwargs = MidasCore.parse_img_size(kwargs)
+ img_size = kwargs.pop("img_size", [384, 384])
+ print("img_size", img_size)
+ midas_path = os.path.join(os.path.dirname(__file__), 'midas_repo')
+ midas = torch.hub.load(midas_path, midas_model_type,
+ pretrained=use_pretrained_midas, force_reload=force_reload, source='local')
+ kwargs.update({'keep_aspect_ratio': force_keep_ar})
+ midas_core = MidasCore(midas, trainable=train_midas, fetch_features=fetch_features,
+ freeze_bn=freeze_bn, img_size=img_size, **kwargs)
+ midas_core.set_output_channels(midas_model_type)
+ return midas_core
+
+ @staticmethod
+ def build_from_config(config):
+ return MidasCore.build(**config)
+
+ @staticmethod
+ def parse_img_size(config):
+ assert 'img_size' in config
+ if isinstance(config['img_size'], str):
+ assert "," in config['img_size'], "img_size should be a string with comma separated img_size=H,W"
+ config['img_size'] = list(map(int, config['img_size'].split(",")))
+ assert len(
+ config['img_size']) == 2, "img_size should be a string with comma separated img_size=H,W"
+ elif isinstance(config['img_size'], int):
+ config['img_size'] = [config['img_size'], config['img_size']]
+ else:
+ assert isinstance(config['img_size'], list) and len(
+ config['img_size']) == 2, "img_size should be a list of H,W"
+ return config
+
+
+nchannels2models = {
+ tuple([256]*5): ["DPT_BEiT_L_384", "DPT_BEiT_L_512", "DPT_BEiT_B_384", "DPT_SwinV2_L_384", "DPT_SwinV2_B_384", "DPT_SwinV2_T_256", "DPT_Large", "DPT_Hybrid"],
+ (512, 256, 128, 64, 64): ["MiDaS_small"]
+}
+
+# Model name to number of output channels
+MIDAS_SETTINGS = {m: k for k, v in nchannels2models.items()
+ for m in v
+ }
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/.gitignore b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/.gitignore
new file mode 100644
index 0000000000000000000000000000000000000000..9b4486124f6db846f8746400e0826d8b37ce4a7f
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/.gitignore
@@ -0,0 +1,110 @@
+# Byte-compiled / optimized / DLL files
+__pycache__/
+*.py[cod]
+*$py.class
+
+# C extensions
+*.so
+
+# Distribution / packaging
+.Python
+build/
+develop-eggs/
+dist/
+downloads/
+eggs/
+.eggs/
+lib/
+lib64/
+parts/
+sdist/
+var/
+wheels/
+*.egg-info/
+.installed.cfg
+*.egg
+MANIFEST
+
+# PyInstaller
+# Usually these files are written by a python script from a template
+# before PyInstaller builds the exe, so as to inject date/other infos into it.
+*.manifest
+*.spec
+
+# Installer logs
+pip-log.txt
+pip-delete-this-directory.txt
+
+# Unit test / coverage reports
+htmlcov/
+.tox/
+.coverage
+.coverage.*
+.cache
+nosetests.xml
+coverage.xml
+*.cover
+.hypothesis/
+.pytest_cache/
+
+# Translations
+*.mo
+*.pot
+
+# Django stuff:
+*.log
+local_settings.py
+db.sqlite3
+
+# Flask stuff:
+instance/
+.webassets-cache
+
+# Scrapy stuff:
+.scrapy
+
+# Sphinx documentation
+docs/_build/
+
+# PyBuilder
+target/
+
+# Jupyter Notebook
+.ipynb_checkpoints
+
+# pyenv
+.python-version
+
+# celery beat schedule file
+celerybeat-schedule
+
+# SageMath parsed files
+*.sage.py
+
+# Environments
+.env
+.venv
+env/
+venv/
+ENV/
+env.bak/
+venv.bak/
+
+# Spyder project settings
+.spyderproject
+.spyproject
+
+# Rope project settings
+.ropeproject
+
+# mkdocs documentation
+/site
+
+# mypy
+.mypy_cache/
+
+*.png
+*.pfm
+*.jpg
+*.jpeg
+*.pt
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/Dockerfile b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/Dockerfile
new file mode 100644
index 0000000000000000000000000000000000000000..93164297a40e68cf479afc3b8e064468903f8bf1
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/Dockerfile
@@ -0,0 +1,29 @@
+# enables cuda support in docker
+FROM nvidia/cuda:10.2-cudnn7-runtime-ubuntu18.04
+
+# install python 3.6, pip and requirements for opencv-python
+# (see https://github.com/NVIDIA/nvidia-docker/issues/864)
+RUN apt-get update && apt-get -y install \
+ python3 \
+ python3-pip \
+ libsm6 \
+ libxext6 \
+ libxrender-dev \
+ curl \
+ && rm -rf /var/lib/apt/lists/*
+
+# install python dependencies
+RUN pip3 install --upgrade pip
+RUN pip3 install torch~=1.8 torchvision opencv-python-headless~=3.4 timm
+
+# copy inference code
+WORKDIR /opt/MiDaS
+COPY ./midas ./midas
+COPY ./*.py ./
+
+# download model weights so the docker image can be used offline
+RUN cd weights && {curl -OL https://github.com/isl-org/MiDaS/releases/download/v3/dpt_hybrid_384.pt; cd -; }
+RUN python3 run.py --model_type dpt_hybrid; exit 0
+
+# entrypoint (dont forget to mount input and output directories)
+CMD python3 run.py --model_type dpt_hybrid
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/LICENSE b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/LICENSE
new file mode 100644
index 0000000000000000000000000000000000000000..0365733785a449c285c6ac704ef443f385fe798c
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/LICENSE
@@ -0,0 +1,21 @@
+MIT License
+
+Copyright (c) 2019 Intel ISL (Intel Intelligent Systems Lab)
+
+Permission is hereby granted, free of charge, to any person obtaining a copy
+of this software and associated documentation files (the "Software"), to deal
+in the Software without restriction, including without limitation the rights
+to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+copies of the Software, and to permit persons to whom the Software is
+furnished to do so, subject to the following conditions:
+
+The above copyright notice and this permission notice shall be included in all
+copies or substantial portions of the Software.
+
+THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+SOFTWARE.
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/README.md b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..44d485c553211625a4f9303c9b6fb186d4aa56bb
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/README.md
@@ -0,0 +1,259 @@
+## Towards Robust Monocular Depth Estimation: Mixing Datasets for Zero-shot Cross-dataset Transfer
+
+This repository contains code to compute depth from a single image. It accompanies our [paper](https://arxiv.org/abs/1907.01341v3):
+
+>Towards Robust Monocular Depth Estimation: Mixing Datasets for Zero-shot Cross-dataset Transfer
+René Ranftl, Katrin Lasinger, David Hafner, Konrad Schindler, Vladlen Koltun
+
+
+and our [preprint](https://arxiv.org/abs/2103.13413):
+
+> Vision Transformers for Dense Prediction
+> René Ranftl, Alexey Bochkovskiy, Vladlen Koltun
+
+
+MiDaS was trained on up to 12 datasets (ReDWeb, DIML, Movies, MegaDepth, WSVD, TartanAir, HRWSI, ApolloScape, BlendedMVS, IRS, KITTI, NYU Depth V2) with
+multi-objective optimization.
+The original model that was trained on 5 datasets (`MIX 5` in the paper) can be found [here](https://github.com/isl-org/MiDaS/releases/tag/v2).
+The figure below shows an overview of the different MiDaS models; the bubble size scales with number of parameters.
+
+
+
+### Setup
+
+1) Pick one or more models and download the corresponding weights to the `weights` folder:
+
+MiDaS 3.1
+- For highest quality: [dpt_beit_large_512](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_large_512.pt)
+- For moderately less quality, but better speed-performance trade-off: [dpt_swin2_large_384](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin2_large_384.pt)
+- For embedded devices: [dpt_swin2_tiny_256](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin2_tiny_256.pt), [dpt_levit_224](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_levit_224.pt)
+- For inference on Intel CPUs, OpenVINO may be used for the small legacy model: openvino_midas_v21_small [.xml](https://github.com/isl-org/MiDaS/releases/download/v3_1/openvino_midas_v21_small_256.xml), [.bin](https://github.com/isl-org/MiDaS/releases/download/v3_1/openvino_midas_v21_small_256.bin)
+
+MiDaS 3.0: Legacy transformer models [dpt_large_384](https://github.com/isl-org/MiDaS/releases/download/v3/dpt_large_384.pt) and [dpt_hybrid_384](https://github.com/isl-org/MiDaS/releases/download/v3/dpt_hybrid_384.pt)
+
+MiDaS 2.1: Legacy convolutional models [midas_v21_384](https://github.com/isl-org/MiDaS/releases/download/v2_1/midas_v21_384.pt) and [midas_v21_small_256](https://github.com/isl-org/MiDaS/releases/download/v2_1/midas_v21_small_256.pt)
+
+1) Set up dependencies:
+
+ ```shell
+ conda env create -f environment.yaml
+ conda activate midas-py310
+ ```
+
+#### optional
+
+For the Next-ViT model, execute
+
+```shell
+git submodule add https://github.com/isl-org/Next-ViT midas/external/next_vit
+```
+
+For the OpenVINO model, install
+
+```shell
+pip install openvino
+```
+
+### Usage
+
+1) Place one or more input images in the folder `input`.
+
+2) Run the model with
+
+ ```shell
+ python run.py --model_type --input_path input --output_path output
+ ```
+ where `````` is chosen from [dpt_beit_large_512](#model_type), [dpt_beit_large_384](#model_type),
+ [dpt_beit_base_384](#model_type), [dpt_swin2_large_384](#model_type), [dpt_swin2_base_384](#model_type),
+ [dpt_swin2_tiny_256](#model_type), [dpt_swin_large_384](#model_type), [dpt_next_vit_large_384](#model_type),
+ [dpt_levit_224](#model_type), [dpt_large_384](#model_type), [dpt_hybrid_384](#model_type),
+ [midas_v21_384](#model_type), [midas_v21_small_256](#model_type), [openvino_midas_v21_small_256](#model_type).
+
+3) The resulting depth maps are written to the `output` folder.
+
+#### optional
+
+1) By default, the inference resizes the height of input images to the size of a model to fit into the encoder. This
+ size is given by the numbers in the model names of the [accuracy table](#accuracy). Some models do not only support a single
+ inference height but a range of different heights. Feel free to explore different heights by appending the extra
+ command line argument `--height`. Unsupported height values will throw an error. Note that using this argument may
+ decrease the model accuracy.
+2) By default, the inference keeps the aspect ratio of input images when feeding them into the encoder if this is
+ supported by a model (all models except for Swin, Swin2, LeViT). In order to resize to a square resolution,
+ disregarding the aspect ratio while preserving the height, use the command line argument `--square`.
+
+#### via Camera
+
+ If you want the input images to be grabbed from the camera and shown in a window, leave the input and output paths
+ away and choose a model type as shown above:
+
+ ```shell
+ python run.py --model_type --side
+ ```
+
+ The argument `--side` is optional and causes both the input RGB image and the output depth map to be shown
+ side-by-side for comparison.
+
+#### via Docker
+
+1) Make sure you have installed Docker and the
+ [NVIDIA Docker runtime](https://github.com/NVIDIA/nvidia-docker/wiki/Installation-\(Native-GPU-Support\)).
+
+2) Build the Docker image:
+
+ ```shell
+ docker build -t midas .
+ ```
+
+3) Run inference:
+
+ ```shell
+ docker run --rm --gpus all -v $PWD/input:/opt/MiDaS/input -v $PWD/output:/opt/MiDaS/output -v $PWD/weights:/opt/MiDaS/weights midas
+ ```
+
+ This command passes through all of your NVIDIA GPUs to the container, mounts the
+ `input` and `output` directories and then runs the inference.
+
+#### via PyTorch Hub
+
+The pretrained model is also available on [PyTorch Hub](https://pytorch.org/hub/intelisl_midas_v2/)
+
+#### via TensorFlow or ONNX
+
+See [README](https://github.com/isl-org/MiDaS/tree/master/tf) in the `tf` subdirectory.
+
+Currently only supports MiDaS v2.1.
+
+
+#### via Mobile (iOS / Android)
+
+See [README](https://github.com/isl-org/MiDaS/tree/master/mobile) in the `mobile` subdirectory.
+
+#### via ROS1 (Robot Operating System)
+
+See [README](https://github.com/isl-org/MiDaS/tree/master/ros) in the `ros` subdirectory.
+
+Currently only supports MiDaS v2.1. DPT-based models to be added.
+
+
+### Accuracy
+
+We provide a **zero-shot error** $\epsilon_d$ which is evaluated for 6 different datasets
+(see [paper](https://arxiv.org/abs/1907.01341v3)). **Lower error values are better**.
+$\color{green}{\textsf{Overall model quality is represented by the improvement}}$ ([Imp.](#improvement)) with respect to
+MiDaS 3.0 DPTL-384. The models are grouped by the height used for inference, whereas the square training resolution is given by
+the numbers in the model names. The table also shows the **number of parameters** (in millions) and the
+**frames per second** for inference at the training resolution (for GPU RTX 3090):
+
+| MiDaS Model | DIW WHDR | Eth3d AbsRel | Sintel AbsRel | TUM δ1 | KITTI δ1 | NYUv2 δ1 | $\color{green}{\textsf{Imp.}}$ % | Par.M | FPS |
+|-----------------------------------------------------------------------------------------------------------------------|-------------------------:|-----------------------------:|------------------------------:|-------------------------:|-------------------------:|-------------------------:|-------------------------------------------------:|----------------------:|--------------------------:|
+| **Inference height 512** | | | | | | | | | |
+| [v3.1 BEiTL-512](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_large_512.pt) | 0.1137 | 0.0659 | 0.2366 | **6.13** | 11.56* | **1.86*** | $\color{green}{\textsf{19}}$ | **345** | **5.7** |
+| [v3.1 BEiTL-512](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_large_512.pt)$\tiny{\square}$ | **0.1121** | **0.0614** | **0.2090** | 6.46 | **5.00*** | 1.90* | $\color{green}{\textsf{34}}$ | **345** | **5.7** |
+| | | | | | | | | | |
+| **Inference height 384** | | | | | | | | | |
+| [v3.1 BEiTL-512](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_large_512.pt) | 0.1245 | 0.0681 | **0.2176** | **6.13** | 6.28* | **2.16*** | $\color{green}{\textsf{28}}$ | 345 | 12 |
+| [v3.1 Swin2L-384](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin2_large_384.pt)$\tiny{\square}$ | 0.1106 | 0.0732 | 0.2442 | 8.87 | **5.84*** | 2.92* | $\color{green}{\textsf{22}}$ | 213 | 41 |
+| [v3.1 Swin2B-384](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin2_base_384.pt)$\tiny{\square}$ | 0.1095 | 0.0790 | 0.2404 | 8.93 | 5.97* | 3.28* | $\color{green}{\textsf{22}}$ | 102 | 39 |
+| [v3.1 SwinL-384](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin_large_384.pt)$\tiny{\square}$ | 0.1126 | 0.0853 | 0.2428 | 8.74 | 6.60* | 3.34* | $\color{green}{\textsf{17}}$ | 213 | 49 |
+| [v3.1 BEiTL-384](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_large_384.pt) | 0.1239 | **0.0667** | 0.2545 | 7.17 | 9.84* | 2.21* | $\color{green}{\textsf{17}}$ | 344 | 13 |
+| [v3.1 Next-ViTL-384](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_next_vit_large_384.pt) | **0.1031** | 0.0954 | 0.2295 | 9.21 | 6.89* | 3.47* | $\color{green}{\textsf{16}}$ | **72** | 30 |
+| [v3.1 BEiTB-384](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_base_384.pt) | 0.1159 | 0.0967 | 0.2901 | 9.88 | 26.60* | 3.91* | $\color{green}{\textsf{-31}}$ | 112 | 31 |
+| [v3.0 DPTL-384](https://github.com/isl-org/MiDaS/releases/download/v3/dpt_large_384.pt) | 0.1082 | 0.0888 | 0.2697 | 9.97 | 8.46 | 8.32 | $\color{green}{\textsf{0}}$ | 344 | **61** |
+| [v3.0 DPTH-384](https://github.com/isl-org/MiDaS/releases/download/v3/dpt_hybrid_384.pt) | 0.1106 | 0.0934 | 0.2741 | 10.89 | 11.56 | 8.69 | $\color{green}{\textsf{-10}}$ | 123 | 50 |
+| [v2.1 Large384](https://github.com/isl-org/MiDaS/releases/download/v2_1/midas_v21_384.pt) | 0.1295 | 0.1155 | 0.3285 | 12.51 | 16.08 | 8.71 | $\color{green}{\textsf{-32}}$ | 105 | 47 |
+| | | | | | | | | | |
+| **Inference height 256** | | | | | | | | | |
+| [v3.1 Swin2T-256](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin2_tiny_256.pt)$\tiny{\square}$ | **0.1211** | **0.1106** | **0.2868** | **13.43** | **10.13*** | **5.55*** | $\color{green}{\textsf{-11}}$ | 42 | 64 |
+| [v2.1 Small256](https://github.com/isl-org/MiDaS/releases/download/v2_1/midas_v21_small_256.pt) | 0.1344 | 0.1344 | 0.3370 | 14.53 | 29.27 | 13.43 | $\color{green}{\textsf{-76}}$ | **21** | **90** |
+| | | | | | | | | | |
+| **Inference height 224** | | | | | | | | | |
+| [v3.1 LeViT224](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_levit_224.pt)$\tiny{\square}$ | **0.1314** | **0.1206** | **0.3148** | **18.21** | **15.27*** | **8.64*** | $\color{green}{\textsf{-40}}$ | **51** | **73** |
+
+* No zero-shot error, because models are also trained on KITTI and NYU Depth V2\
+$\square$ Validation performed at **square resolution**, either because the transformer encoder backbone of a model
+does not support non-square resolutions (Swin, Swin2, LeViT) or for comparison with these models. All other
+validations keep the aspect ratio. A difference in resolution limits the comparability of the zero-shot error and the
+improvement, because these quantities are averages over the pixels of an image and do not take into account the
+advantage of more details due to a higher resolution.\
+Best values per column and same validation height in bold
+
+#### Improvement
+
+The improvement in the above table is defined as the relative zero-shot error with respect to MiDaS v3.0
+DPTL-384 and averaging over the datasets. So, if $\epsilon_d$ is the zero-shot error for dataset $d$, then
+the $\color{green}{\textsf{improvement}}$ is given by $100(1-(1/6)\sum_d\epsilon_d/\epsilon_{d,\rm{DPT_{L-384}}})$%.
+
+Note that the improvements of 10% for MiDaS v2.0 → v2.1 and 21% for MiDaS v2.1 → v3.0 are not visible from the
+improvement column (Imp.) in the table but would require an evaluation with respect to MiDaS v2.1 Large384
+and v2.0 Large384 respectively instead of v3.0 DPTL-384.
+
+### Depth map comparison
+
+Zoom in for better visibility
+
+
+### Speed on Camera Feed
+
+Test configuration
+- Windows 10
+- 11th Gen Intel Core i7-1185G7 3.00GHz
+- 16GB RAM
+- Camera resolution 640x480
+- openvino_midas_v21_small_256
+
+Speed: 22 FPS
+
+### Changelog
+
+* [Dec 2022] Released MiDaS v3.1:
+ - New models based on 5 different types of transformers ([BEiT](https://arxiv.org/pdf/2106.08254.pdf), [Swin2](https://arxiv.org/pdf/2111.09883.pdf), [Swin](https://arxiv.org/pdf/2103.14030.pdf), [Next-ViT](https://arxiv.org/pdf/2207.05501.pdf), [LeViT](https://arxiv.org/pdf/2104.01136.pdf))
+ - Training datasets extended from 10 to 12, including also KITTI and NYU Depth V2 using [BTS](https://github.com/cleinc/bts) split
+ - Best model, BEiTLarge 512, with resolution 512x512, is on average about [28% more accurate](#Accuracy) than MiDaS v3.0
+ - Integrated live depth estimation from camera feed
+* [Sep 2021] Integrated to [Huggingface Spaces](https://huggingface.co/spaces) with [Gradio](https://github.com/gradio-app/gradio). See [Gradio Web Demo](https://huggingface.co/spaces/akhaliq/DPT-Large).
+* [Apr 2021] Released MiDaS v3.0:
+ - New models based on [Dense Prediction Transformers](https://arxiv.org/abs/2103.13413) are on average [21% more accurate](#Accuracy) than MiDaS v2.1
+ - Additional models can be found [here](https://github.com/isl-org/DPT)
+* [Nov 2020] Released MiDaS v2.1:
+ - New model that was trained on 10 datasets and is on average about [10% more accurate](#Accuracy) than [MiDaS v2.0](https://github.com/isl-org/MiDaS/releases/tag/v2)
+ - New light-weight model that achieves [real-time performance](https://github.com/isl-org/MiDaS/tree/master/mobile) on mobile platforms.
+ - Sample applications for [iOS](https://github.com/isl-org/MiDaS/tree/master/mobile/ios) and [Android](https://github.com/isl-org/MiDaS/tree/master/mobile/android)
+ - [ROS package](https://github.com/isl-org/MiDaS/tree/master/ros) for easy deployment on robots
+* [Jul 2020] Added TensorFlow and ONNX code. Added [online demo](http://35.202.76.57/).
+* [Dec 2019] Released new version of MiDaS - the new model is significantly more accurate and robust
+* [Jul 2019] Initial release of MiDaS ([Link](https://github.com/isl-org/MiDaS/releases/tag/v1))
+
+### Citation
+
+Please cite our paper if you use this code or any of the models:
+```
+@ARTICLE {Ranftl2022,
+ author = "Ren\'{e} Ranftl and Katrin Lasinger and David Hafner and Konrad Schindler and Vladlen Koltun",
+ title = "Towards Robust Monocular Depth Estimation: Mixing Datasets for Zero-Shot Cross-Dataset Transfer",
+ journal = "IEEE Transactions on Pattern Analysis and Machine Intelligence",
+ year = "2022",
+ volume = "44",
+ number = "3"
+}
+```
+
+If you use a DPT-based model, please also cite:
+
+```
+@article{Ranftl2021,
+ author = {Ren\'{e} Ranftl and Alexey Bochkovskiy and Vladlen Koltun},
+ title = {Vision Transformers for Dense Prediction},
+ journal = {ICCV},
+ year = {2021},
+}
+```
+
+### Acknowledgements
+
+Our work builds on and uses code from [timm](https://github.com/rwightman/pytorch-image-models) and [Next-ViT](https://github.com/bytedance/Next-ViT).
+We'd like to thank the authors for making these libraries available.
+
+### License
+
+MIT License
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/environment.yaml b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/environment.yaml
new file mode 100644
index 0000000000000000000000000000000000000000..e20cfd31c52ecbdaba67382878fe281faf456beb
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/environment.yaml
@@ -0,0 +1,16 @@
+name: midas-py310
+channels:
+ - pytorch
+ - defaults
+dependencies:
+ - nvidia::cudatoolkit=11.7
+ - python=3.10.8
+ - pytorch::pytorch=1.13.0
+ - torchvision=0.14.0
+ - pip=22.3.1
+ - numpy=1.23.4
+ - pip:
+ - opencv-python==4.6.0.66
+ - imutils==0.5.4
+ - timm==0.6.12
+ - einops==0.6.0
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/hubconf.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/hubconf.py
new file mode 100644
index 0000000000000000000000000000000000000000..37c4cbd644c5a0533a7203f2115875be8e596ec1
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/hubconf.py
@@ -0,0 +1,435 @@
+dependencies = ["torch"]
+
+import torch
+
+from midas.dpt_depth import DPTDepthModel
+from midas.midas_net import MidasNet
+from midas.midas_net_custom import MidasNet_small
+
+def DPT_BEiT_L_512(pretrained=True, **kwargs):
+ """ # This docstring shows up in hub.help()
+ MiDaS DPT_BEiT_L_512 model for monocular depth estimation
+ pretrained (bool): load pretrained weights into model
+ """
+
+ model = DPTDepthModel(
+ path=None,
+ backbone="beitl16_512",
+ non_negative=True,
+ )
+
+ if pretrained:
+ checkpoint = (
+ "https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_large_512.pt"
+ )
+ state_dict = torch.hub.load_state_dict_from_url(
+ checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
+ )
+ model.load_state_dict(state_dict)
+
+ return model
+
+def DPT_BEiT_L_384(pretrained=True, **kwargs):
+ """ # This docstring shows up in hub.help()
+ MiDaS DPT_BEiT_L_384 model for monocular depth estimation
+ pretrained (bool): load pretrained weights into model
+ """
+
+ model = DPTDepthModel(
+ path=None,
+ backbone="beitl16_384",
+ non_negative=True,
+ )
+
+ if pretrained:
+ checkpoint = (
+ "https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_large_384.pt"
+ )
+ state_dict = torch.hub.load_state_dict_from_url(
+ checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
+ )
+ model.load_state_dict(state_dict)
+
+ return model
+
+def DPT_BEiT_B_384(pretrained=True, **kwargs):
+ """ # This docstring shows up in hub.help()
+ MiDaS DPT_BEiT_B_384 model for monocular depth estimation
+ pretrained (bool): load pretrained weights into model
+ """
+
+ model = DPTDepthModel(
+ path=None,
+ backbone="beitb16_384",
+ non_negative=True,
+ )
+
+ if pretrained:
+ checkpoint = (
+ "https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_base_384.pt"
+ )
+ state_dict = torch.hub.load_state_dict_from_url(
+ checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
+ )
+ model.load_state_dict(state_dict)
+
+ return model
+
+def DPT_SwinV2_L_384(pretrained=True, **kwargs):
+ """ # This docstring shows up in hub.help()
+ MiDaS DPT_SwinV2_L_384 model for monocular depth estimation
+ pretrained (bool): load pretrained weights into model
+ """
+
+ model = DPTDepthModel(
+ path=None,
+ backbone="swin2l24_384",
+ non_negative=True,
+ )
+
+ if pretrained:
+ checkpoint = (
+ "https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin2_large_384.pt"
+ )
+ state_dict = torch.hub.load_state_dict_from_url(
+ checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
+ )
+ model.load_state_dict(state_dict)
+
+ return model
+
+def DPT_SwinV2_B_384(pretrained=True, **kwargs):
+ """ # This docstring shows up in hub.help()
+ MiDaS DPT_SwinV2_B_384 model for monocular depth estimation
+ pretrained (bool): load pretrained weights into model
+ """
+
+ model = DPTDepthModel(
+ path=None,
+ backbone="swin2b24_384",
+ non_negative=True,
+ )
+
+ if pretrained:
+ checkpoint = (
+ "https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin2_base_384.pt"
+ )
+ state_dict = torch.hub.load_state_dict_from_url(
+ checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
+ )
+ model.load_state_dict(state_dict)
+
+ return model
+
+def DPT_SwinV2_T_256(pretrained=True, **kwargs):
+ """ # This docstring shows up in hub.help()
+ MiDaS DPT_SwinV2_T_256 model for monocular depth estimation
+ pretrained (bool): load pretrained weights into model
+ """
+
+ model = DPTDepthModel(
+ path=None,
+ backbone="swin2t16_256",
+ non_negative=True,
+ )
+
+ if pretrained:
+ checkpoint = (
+ "https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin2_tiny_256.pt"
+ )
+ state_dict = torch.hub.load_state_dict_from_url(
+ checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
+ )
+ model.load_state_dict(state_dict)
+
+ return model
+
+def DPT_Swin_L_384(pretrained=True, **kwargs):
+ """ # This docstring shows up in hub.help()
+ MiDaS DPT_Swin_L_384 model for monocular depth estimation
+ pretrained (bool): load pretrained weights into model
+ """
+
+ model = DPTDepthModel(
+ path=None,
+ backbone="swinl12_384",
+ non_negative=True,
+ )
+
+ if pretrained:
+ checkpoint = (
+ "https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin_large_384.pt"
+ )
+ state_dict = torch.hub.load_state_dict_from_url(
+ checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
+ )
+ model.load_state_dict(state_dict)
+
+ return model
+
+def DPT_Next_ViT_L_384(pretrained=True, **kwargs):
+ """ # This docstring shows up in hub.help()
+ MiDaS DPT_Next_ViT_L_384 model for monocular depth estimation
+ pretrained (bool): load pretrained weights into model
+ """
+
+ model = DPTDepthModel(
+ path=None,
+ backbone="next_vit_large_6m",
+ non_negative=True,
+ )
+
+ if pretrained:
+ checkpoint = (
+ "https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_next_vit_large_384.pt"
+ )
+ state_dict = torch.hub.load_state_dict_from_url(
+ checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
+ )
+ model.load_state_dict(state_dict)
+
+ return model
+
+def DPT_LeViT_224(pretrained=True, **kwargs):
+ """ # This docstring shows up in hub.help()
+ MiDaS DPT_LeViT_224 model for monocular depth estimation
+ pretrained (bool): load pretrained weights into model
+ """
+
+ model = DPTDepthModel(
+ path=None,
+ backbone="levit_384",
+ non_negative=True,
+ head_features_1=64,
+ head_features_2=8,
+ )
+
+ if pretrained:
+ checkpoint = (
+ "https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_levit_224.pt"
+ )
+ state_dict = torch.hub.load_state_dict_from_url(
+ checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
+ )
+ model.load_state_dict(state_dict)
+
+ return model
+
+def DPT_Large(pretrained=True, **kwargs):
+ """ # This docstring shows up in hub.help()
+ MiDaS DPT-Large model for monocular depth estimation
+ pretrained (bool): load pretrained weights into model
+ """
+
+ model = DPTDepthModel(
+ path=None,
+ backbone="vitl16_384",
+ non_negative=True,
+ )
+
+ if pretrained:
+ checkpoint = (
+ "https://github.com/isl-org/MiDaS/releases/download/v3/dpt_large_384.pt"
+ )
+ state_dict = torch.hub.load_state_dict_from_url(
+ checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
+ )
+ model.load_state_dict(state_dict)
+
+ return model
+
+def DPT_Hybrid(pretrained=True, **kwargs):
+ """ # This docstring shows up in hub.help()
+ MiDaS DPT-Hybrid model for monocular depth estimation
+ pretrained (bool): load pretrained weights into model
+ """
+
+ model = DPTDepthModel(
+ path=None,
+ backbone="vitb_rn50_384",
+ non_negative=True,
+ )
+
+ if pretrained:
+ checkpoint = (
+ "https://github.com/isl-org/MiDaS/releases/download/v3/dpt_hybrid_384.pt"
+ )
+ state_dict = torch.hub.load_state_dict_from_url(
+ checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
+ )
+ model.load_state_dict(state_dict)
+
+ return model
+
+def MiDaS(pretrained=True, **kwargs):
+ """ # This docstring shows up in hub.help()
+ MiDaS v2.1 model for monocular depth estimation
+ pretrained (bool): load pretrained weights into model
+ """
+
+ model = MidasNet()
+
+ if pretrained:
+ checkpoint = (
+ "https://github.com/isl-org/MiDaS/releases/download/v2_1/midas_v21_384.pt"
+ )
+ state_dict = torch.hub.load_state_dict_from_url(
+ checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
+ )
+ model.load_state_dict(state_dict)
+
+ return model
+
+def MiDaS_small(pretrained=True, **kwargs):
+ """ # This docstring shows up in hub.help()
+ MiDaS v2.1 small model for monocular depth estimation on resource-constrained devices
+ pretrained (bool): load pretrained weights into model
+ """
+
+ model = MidasNet_small(None, features=64, backbone="efficientnet_lite3", exportable=True, non_negative=True, blocks={'expand': True})
+
+ if pretrained:
+ checkpoint = (
+ "https://github.com/isl-org/MiDaS/releases/download/v2_1/midas_v21_small_256.pt"
+ )
+ state_dict = torch.hub.load_state_dict_from_url(
+ checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
+ )
+ model.load_state_dict(state_dict)
+
+ return model
+
+
+def transforms():
+ import cv2
+ from torchvision.transforms import Compose
+ from midas.transforms import Resize, NormalizeImage, PrepareForNet
+ from midas import transforms
+
+ transforms.default_transform = Compose(
+ [
+ lambda img: {"image": img / 255.0},
+ Resize(
+ 384,
+ 384,
+ resize_target=None,
+ keep_aspect_ratio=True,
+ ensure_multiple_of=32,
+ resize_method="upper_bound",
+ image_interpolation_method=cv2.INTER_CUBIC,
+ ),
+ NormalizeImage(mean=[0.485, 0.456, 0.406], std=[0.229, 0.224, 0.225]),
+ PrepareForNet(),
+ lambda sample: torch.from_numpy(sample["image"]).unsqueeze(0),
+ ]
+ )
+
+ transforms.small_transform = Compose(
+ [
+ lambda img: {"image": img / 255.0},
+ Resize(
+ 256,
+ 256,
+ resize_target=None,
+ keep_aspect_ratio=True,
+ ensure_multiple_of=32,
+ resize_method="upper_bound",
+ image_interpolation_method=cv2.INTER_CUBIC,
+ ),
+ NormalizeImage(mean=[0.485, 0.456, 0.406], std=[0.229, 0.224, 0.225]),
+ PrepareForNet(),
+ lambda sample: torch.from_numpy(sample["image"]).unsqueeze(0),
+ ]
+ )
+
+ transforms.dpt_transform = Compose(
+ [
+ lambda img: {"image": img / 255.0},
+ Resize(
+ 384,
+ 384,
+ resize_target=None,
+ keep_aspect_ratio=True,
+ ensure_multiple_of=32,
+ resize_method="minimal",
+ image_interpolation_method=cv2.INTER_CUBIC,
+ ),
+ NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5]),
+ PrepareForNet(),
+ lambda sample: torch.from_numpy(sample["image"]).unsqueeze(0),
+ ]
+ )
+
+ transforms.beit512_transform = Compose(
+ [
+ lambda img: {"image": img / 255.0},
+ Resize(
+ 512,
+ 512,
+ resize_target=None,
+ keep_aspect_ratio=True,
+ ensure_multiple_of=32,
+ resize_method="minimal",
+ image_interpolation_method=cv2.INTER_CUBIC,
+ ),
+ NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5]),
+ PrepareForNet(),
+ lambda sample: torch.from_numpy(sample["image"]).unsqueeze(0),
+ ]
+ )
+
+ transforms.swin384_transform = Compose(
+ [
+ lambda img: {"image": img / 255.0},
+ Resize(
+ 384,
+ 384,
+ resize_target=None,
+ keep_aspect_ratio=False,
+ ensure_multiple_of=32,
+ resize_method="minimal",
+ image_interpolation_method=cv2.INTER_CUBIC,
+ ),
+ NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5]),
+ PrepareForNet(),
+ lambda sample: torch.from_numpy(sample["image"]).unsqueeze(0),
+ ]
+ )
+
+ transforms.swin256_transform = Compose(
+ [
+ lambda img: {"image": img / 255.0},
+ Resize(
+ 256,
+ 256,
+ resize_target=None,
+ keep_aspect_ratio=False,
+ ensure_multiple_of=32,
+ resize_method="minimal",
+ image_interpolation_method=cv2.INTER_CUBIC,
+ ),
+ NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5]),
+ PrepareForNet(),
+ lambda sample: torch.from_numpy(sample["image"]).unsqueeze(0),
+ ]
+ )
+
+ transforms.levit_transform = Compose(
+ [
+ lambda img: {"image": img / 255.0},
+ Resize(
+ 224,
+ 224,
+ resize_target=None,
+ keep_aspect_ratio=False,
+ ensure_multiple_of=32,
+ resize_method="minimal",
+ image_interpolation_method=cv2.INTER_CUBIC,
+ ),
+ NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5]),
+ PrepareForNet(),
+ lambda sample: torch.from_numpy(sample["image"]).unsqueeze(0),
+ ]
+ )
+
+ return transforms
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/input/.placeholder b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/input/.placeholder
new file mode 100644
index 0000000000000000000000000000000000000000..e69de29bb2d1d6434b8b29ae775ad8c2e48c5391
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/beit.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/beit.py
new file mode 100644
index 0000000000000000000000000000000000000000..aadc019b6a8b0a1f84614c7da6f2267884eb60dd
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/beit.py
@@ -0,0 +1,198 @@
+import timm
+import torch
+import types
+
+import numpy as np
+import torch.nn.functional as F
+
+from .utils import forward_adapted_unflatten, make_backbone_default
+from timm.models.beit import gen_relative_position_index
+from torch.utils.checkpoint import checkpoint
+from typing import Optional
+
+
+def forward_beit(pretrained, x):
+ return forward_adapted_unflatten(pretrained, x, "forward_features")
+
+
+def patch_embed_forward(self, x):
+ """
+ Modification of timm.models.layers.patch_embed.py: PatchEmbed.forward to support arbitrary window sizes.
+ """
+ x = self.proj(x)
+ if self.flatten:
+ x = x.flatten(2).transpose(1, 2)
+ x = self.norm(x)
+ return x
+
+
+def _get_rel_pos_bias(self, window_size):
+ """
+ Modification of timm.models.beit.py: Attention._get_rel_pos_bias to support arbitrary window sizes.
+ """
+ old_height = 2 * self.window_size[0] - 1
+ old_width = 2 * self.window_size[1] - 1
+
+ new_height = 2 * window_size[0] - 1
+ new_width = 2 * window_size[1] - 1
+
+ old_relative_position_bias_table = self.relative_position_bias_table
+
+ old_num_relative_distance = self.num_relative_distance
+ new_num_relative_distance = new_height * new_width + 3
+
+ old_sub_table = old_relative_position_bias_table[:old_num_relative_distance - 3]
+
+ old_sub_table = old_sub_table.reshape(1, old_width, old_height, -1).permute(0, 3, 1, 2)
+ new_sub_table = F.interpolate(old_sub_table, size=(int(new_height), int(new_width)), mode="bilinear")
+ new_sub_table = new_sub_table.permute(0, 2, 3, 1).reshape(new_num_relative_distance - 3, -1)
+
+ new_relative_position_bias_table = torch.cat(
+ [new_sub_table, old_relative_position_bias_table[old_num_relative_distance - 3:]])
+
+ key = str(window_size[1]) + "," + str(window_size[0])
+ if key not in self.relative_position_indices.keys():
+ self.relative_position_indices[key] = gen_relative_position_index(window_size)
+
+ relative_position_bias = new_relative_position_bias_table[
+ self.relative_position_indices[key].view(-1)].view(
+ window_size[0] * window_size[1] + 1,
+ window_size[0] * window_size[1] + 1, -1) # Wh*Ww,Wh*Ww,nH
+ relative_position_bias = relative_position_bias.permute(2, 0, 1).contiguous() # nH, Wh*Ww, Wh*Ww
+ return relative_position_bias.unsqueeze(0)
+
+
+def attention_forward(self, x, resolution, shared_rel_pos_bias: Optional[torch.Tensor] = None):
+ """
+ Modification of timm.models.beit.py: Attention.forward to support arbitrary window sizes.
+ """
+ B, N, C = x.shape
+
+ qkv_bias = torch.cat((self.q_bias, self.k_bias, self.v_bias)) if self.q_bias is not None else None
+ qkv = F.linear(input=x, weight=self.qkv.weight, bias=qkv_bias)
+ qkv = qkv.reshape(B, N, 3, self.num_heads, -1).permute(2, 0, 3, 1, 4)
+ q, k, v = qkv.unbind(0) # make torchscript happy (cannot use tensor as tuple)
+
+ q = q * self.scale
+ attn = (q @ k.transpose(-2, -1))
+
+ if self.relative_position_bias_table is not None:
+ window_size = tuple(np.array(resolution) // 16)
+ attn = attn + self._get_rel_pos_bias(window_size)
+ if shared_rel_pos_bias is not None:
+ attn = attn + shared_rel_pos_bias
+
+ attn = attn.softmax(dim=-1)
+ attn = self.attn_drop(attn)
+
+ x = (attn @ v).transpose(1, 2).reshape(B, N, -1)
+ x = self.proj(x)
+ x = self.proj_drop(x)
+ return x
+
+
+def block_forward(self, x, resolution, shared_rel_pos_bias: Optional[torch.Tensor] = None):
+ """
+ Modification of timm.models.beit.py: Block.forward to support arbitrary window sizes.
+ """
+ if hasattr(self, 'drop_path1') and not hasattr(self, 'drop_path'):
+ self.drop_path = self.drop_path1
+ if self.gamma_1 is None:
+ x = x + self.drop_path(self.attn(self.norm1(x), resolution, shared_rel_pos_bias=shared_rel_pos_bias))
+ x = x + self.drop_path(self.mlp(self.norm2(x)))
+ else:
+ x = x + self.drop_path(self.gamma_1 * self.attn(self.norm1(x), resolution,
+ shared_rel_pos_bias=shared_rel_pos_bias))
+ x = x + self.drop_path(self.gamma_2 * self.mlp(self.norm2(x)))
+ return x
+
+
+def beit_forward_features(self, x):
+ """
+ Modification of timm.models.beit.py: Beit.forward_features to support arbitrary window sizes.
+ """
+ resolution = x.shape[2:]
+
+ x = self.patch_embed(x)
+ x = torch.cat((self.cls_token.expand(x.shape[0], -1, -1), x), dim=1)
+ if self.pos_embed is not None:
+ x = x + self.pos_embed
+ x = self.pos_drop(x)
+
+ rel_pos_bias = self.rel_pos_bias() if self.rel_pos_bias is not None else None
+ for blk in self.blocks:
+ if self.grad_checkpointing and not torch.jit.is_scripting():
+ x = checkpoint(blk, x, shared_rel_pos_bias=rel_pos_bias)
+ else:
+ x = blk(x, resolution, shared_rel_pos_bias=rel_pos_bias)
+ x = self.norm(x)
+ return x
+
+
+def _make_beit_backbone(
+ model,
+ features=[96, 192, 384, 768],
+ size=[384, 384],
+ hooks=[0, 4, 8, 11],
+ vit_features=768,
+ use_readout="ignore",
+ start_index=1,
+ start_index_readout=1,
+):
+ backbone = make_backbone_default(model, features, size, hooks, vit_features, use_readout, start_index,
+ start_index_readout)
+
+ backbone.model.patch_embed.forward = types.MethodType(patch_embed_forward, backbone.model.patch_embed)
+ backbone.model.forward_features = types.MethodType(beit_forward_features, backbone.model)
+
+ for block in backbone.model.blocks:
+ attn = block.attn
+ attn._get_rel_pos_bias = types.MethodType(_get_rel_pos_bias, attn)
+ attn.forward = types.MethodType(attention_forward, attn)
+ attn.relative_position_indices = {}
+
+ block.forward = types.MethodType(block_forward, block)
+
+ return backbone
+
+
+def _make_pretrained_beitl16_512(pretrained, use_readout="ignore", hooks=None):
+ model = timm.create_model("beit_large_patch16_512", pretrained=pretrained)
+
+ hooks = [5, 11, 17, 23] if hooks is None else hooks
+
+ features = [256, 512, 1024, 1024]
+
+ return _make_beit_backbone(
+ model,
+ features=features,
+ size=[512, 512],
+ hooks=hooks,
+ vit_features=1024,
+ use_readout=use_readout,
+ )
+
+
+def _make_pretrained_beitl16_384(pretrained, use_readout="ignore", hooks=None):
+ model = timm.create_model("beit_large_patch16_384", pretrained=pretrained)
+
+ hooks = [5, 11, 17, 23] if hooks is None else hooks
+ return _make_beit_backbone(
+ model,
+ features=[256, 512, 1024, 1024],
+ hooks=hooks,
+ vit_features=1024,
+ use_readout=use_readout,
+ )
+
+
+def _make_pretrained_beitb16_384(pretrained, use_readout="ignore", hooks=None):
+ model = timm.create_model("beit_base_patch16_384", pretrained=pretrained)
+
+ hooks = [2, 5, 8, 11] if hooks is None else hooks
+ return _make_beit_backbone(
+ model,
+ features=[96, 192, 384, 768],
+ hooks=hooks,
+ use_readout=use_readout,
+ )
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/levit.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/levit.py
new file mode 100644
index 0000000000000000000000000000000000000000..e6a7770fb76f085a0f3b6015902797c5805bba01
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/levit.py
@@ -0,0 +1,106 @@
+import timm
+import torch
+import torch.nn as nn
+import numpy as np
+
+from .utils import activations, get_activation, Transpose
+
+
+def forward_levit(pretrained, x):
+ pretrained.model.forward_features(x)
+
+ layer_1 = pretrained.activations["1"]
+ layer_2 = pretrained.activations["2"]
+ layer_3 = pretrained.activations["3"]
+
+ layer_1 = pretrained.act_postprocess1(layer_1)
+ layer_2 = pretrained.act_postprocess2(layer_2)
+ layer_3 = pretrained.act_postprocess3(layer_3)
+
+ return layer_1, layer_2, layer_3
+
+
+def _make_levit_backbone(
+ model,
+ hooks=[3, 11, 21],
+ patch_grid=[14, 14]
+):
+ pretrained = nn.Module()
+
+ pretrained.model = model
+ pretrained.model.blocks[hooks[0]].register_forward_hook(get_activation("1"))
+ pretrained.model.blocks[hooks[1]].register_forward_hook(get_activation("2"))
+ pretrained.model.blocks[hooks[2]].register_forward_hook(get_activation("3"))
+
+ pretrained.activations = activations
+
+ patch_grid_size = np.array(patch_grid, dtype=int)
+
+ pretrained.act_postprocess1 = nn.Sequential(
+ Transpose(1, 2),
+ nn.Unflatten(2, torch.Size(patch_grid_size.tolist()))
+ )
+ pretrained.act_postprocess2 = nn.Sequential(
+ Transpose(1, 2),
+ nn.Unflatten(2, torch.Size((np.ceil(patch_grid_size / 2).astype(int)).tolist()))
+ )
+ pretrained.act_postprocess3 = nn.Sequential(
+ Transpose(1, 2),
+ nn.Unflatten(2, torch.Size((np.ceil(patch_grid_size / 4).astype(int)).tolist()))
+ )
+
+ return pretrained
+
+
+class ConvTransposeNorm(nn.Sequential):
+ """
+ Modification of
+ https://github.com/rwightman/pytorch-image-models/blob/master/timm/models/levit.py: ConvNorm
+ such that ConvTranspose2d is used instead of Conv2d.
+ """
+
+ def __init__(
+ self, in_chs, out_chs, kernel_size=1, stride=1, pad=0, dilation=1,
+ groups=1, bn_weight_init=1):
+ super().__init__()
+ self.add_module('c',
+ nn.ConvTranspose2d(in_chs, out_chs, kernel_size, stride, pad, dilation, groups, bias=False))
+ self.add_module('bn', nn.BatchNorm2d(out_chs))
+
+ nn.init.constant_(self.bn.weight, bn_weight_init)
+
+ @torch.no_grad()
+ def fuse(self):
+ c, bn = self._modules.values()
+ w = bn.weight / (bn.running_var + bn.eps) ** 0.5
+ w = c.weight * w[:, None, None, None]
+ b = bn.bias - bn.running_mean * bn.weight / (bn.running_var + bn.eps) ** 0.5
+ m = nn.ConvTranspose2d(
+ w.size(1), w.size(0), w.shape[2:], stride=self.c.stride,
+ padding=self.c.padding, dilation=self.c.dilation, groups=self.c.groups)
+ m.weight.data.copy_(w)
+ m.bias.data.copy_(b)
+ return m
+
+
+def stem_b4_transpose(in_chs, out_chs, activation):
+ """
+ Modification of
+ https://github.com/rwightman/pytorch-image-models/blob/master/timm/models/levit.py: stem_b16
+ such that ConvTranspose2d is used instead of Conv2d and stem is also reduced to the half.
+ """
+ return nn.Sequential(
+ ConvTransposeNorm(in_chs, out_chs, 3, 2, 1),
+ activation(),
+ ConvTransposeNorm(out_chs, out_chs // 2, 3, 2, 1),
+ activation())
+
+
+def _make_pretrained_levit_384(pretrained, hooks=None):
+ model = timm.create_model("levit_384", pretrained=pretrained)
+
+ hooks = [3, 11, 21] if hooks == None else hooks
+ return _make_levit_backbone(
+ model,
+ hooks=hooks
+ )
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/next_vit.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/next_vit.py
new file mode 100644
index 0000000000000000000000000000000000000000..773acfb1f67537edf56f4f67b686d8f9b174658d
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/next_vit.py
@@ -0,0 +1,39 @@
+import timm
+
+import torch.nn as nn
+
+from pathlib import Path
+from .utils import activations, forward_default, get_activation
+
+from ..external.next_vit.classification.nextvit import *
+
+
+def forward_next_vit(pretrained, x):
+ return forward_default(pretrained, x, "forward")
+
+
+def _make_next_vit_backbone(
+ model,
+ hooks=[2, 6, 36, 39],
+):
+ pretrained = nn.Module()
+
+ pretrained.model = model
+ pretrained.model.features[hooks[0]].register_forward_hook(get_activation("1"))
+ pretrained.model.features[hooks[1]].register_forward_hook(get_activation("2"))
+ pretrained.model.features[hooks[2]].register_forward_hook(get_activation("3"))
+ pretrained.model.features[hooks[3]].register_forward_hook(get_activation("4"))
+
+ pretrained.activations = activations
+
+ return pretrained
+
+
+def _make_pretrained_next_vit_large_6m(hooks=None):
+ model = timm.create_model("nextvit_large")
+
+ hooks = [2, 6, 36, 39] if hooks == None else hooks
+ return _make_next_vit_backbone(
+ model,
+ hooks=hooks,
+ )
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/swin.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/swin.py
new file mode 100644
index 0000000000000000000000000000000000000000..7477c70cb0109c875ce58ba9b2dbd42e12b2cbe1
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/swin.py
@@ -0,0 +1,13 @@
+import timm
+
+from .swin_common import _make_swin_backbone
+
+
+def _make_pretrained_swinl12_384(pretrained, hooks=None):
+ model = timm.create_model("swin_large_patch4_window12_384", pretrained=pretrained)
+
+ hooks = [1, 1, 17, 1] if hooks == None else hooks
+ return _make_swin_backbone(
+ model,
+ hooks=hooks
+ )
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/swin2.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/swin2.py
new file mode 100644
index 0000000000000000000000000000000000000000..9b0ab3ccb244fc2d71cb01b96a2d6f0544a041ca
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/swin2.py
@@ -0,0 +1,34 @@
+import timm
+
+from .swin_common import _make_swin_backbone
+
+
+def _make_pretrained_swin2l24_384(pretrained, hooks=None):
+ model = timm.create_model("swinv2_large_window12to24_192to384_22kft1k", pretrained=pretrained)
+
+ hooks = [1, 1, 17, 1] if hooks == None else hooks
+ return _make_swin_backbone(
+ model,
+ hooks=hooks
+ )
+
+
+def _make_pretrained_swin2b24_384(pretrained, hooks=None):
+ model = timm.create_model("swinv2_base_window12to24_192to384_22kft1k", pretrained=pretrained)
+
+ hooks = [1, 1, 17, 1] if hooks == None else hooks
+ return _make_swin_backbone(
+ model,
+ hooks=hooks
+ )
+
+
+def _make_pretrained_swin2t16_256(pretrained, hooks=None):
+ model = timm.create_model("swinv2_tiny_window16_256", pretrained=pretrained)
+
+ hooks = [1, 1, 5, 1] if hooks == None else hooks
+ return _make_swin_backbone(
+ model,
+ hooks=hooks,
+ patch_grid=[64, 64]
+ )
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/swin_common.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/swin_common.py
new file mode 100644
index 0000000000000000000000000000000000000000..e61c3633fafcd496505ce209f8152f0aeee0572c
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/swin_common.py
@@ -0,0 +1,52 @@
+import torch
+
+import torch.nn as nn
+import numpy as np
+
+from .utils import activations, forward_default, get_activation, Transpose
+
+
+def forward_swin(pretrained, x):
+ return forward_default(pretrained, x)
+
+
+def _make_swin_backbone(
+ model,
+ hooks=[1, 1, 17, 1],
+ patch_grid=[96, 96]
+):
+ pretrained = nn.Module()
+
+ pretrained.model = model
+ pretrained.model.layers[0].blocks[hooks[0]].register_forward_hook(get_activation("1"))
+ pretrained.model.layers[1].blocks[hooks[1]].register_forward_hook(get_activation("2"))
+ pretrained.model.layers[2].blocks[hooks[2]].register_forward_hook(get_activation("3"))
+ pretrained.model.layers[3].blocks[hooks[3]].register_forward_hook(get_activation("4"))
+
+ pretrained.activations = activations
+
+ if hasattr(model, "patch_grid"):
+ used_patch_grid = model.patch_grid
+ else:
+ used_patch_grid = patch_grid
+
+ patch_grid_size = np.array(used_patch_grid, dtype=int)
+
+ pretrained.act_postprocess1 = nn.Sequential(
+ Transpose(1, 2),
+ nn.Unflatten(2, torch.Size(patch_grid_size.tolist()))
+ )
+ pretrained.act_postprocess2 = nn.Sequential(
+ Transpose(1, 2),
+ nn.Unflatten(2, torch.Size((patch_grid_size // 2).tolist()))
+ )
+ pretrained.act_postprocess3 = nn.Sequential(
+ Transpose(1, 2),
+ nn.Unflatten(2, torch.Size((patch_grid_size // 4).tolist()))
+ )
+ pretrained.act_postprocess4 = nn.Sequential(
+ Transpose(1, 2),
+ nn.Unflatten(2, torch.Size((patch_grid_size // 8).tolist()))
+ )
+
+ return pretrained
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/utils.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..b334c3c55d5ee1da23d481de8b7555c5e9093754
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/utils.py
@@ -0,0 +1,249 @@
+import torch
+
+import torch.nn as nn
+
+
+class Slice(nn.Module):
+ def __init__(self, start_index=1):
+ super(Slice, self).__init__()
+ self.start_index = start_index
+
+ def forward(self, x):
+ return x[:, self.start_index:]
+
+
+class AddReadout(nn.Module):
+ def __init__(self, start_index=1):
+ super(AddReadout, self).__init__()
+ self.start_index = start_index
+
+ def forward(self, x):
+ if self.start_index == 2:
+ readout = (x[:, 0] + x[:, 1]) / 2
+ else:
+ readout = x[:, 0]
+ return x[:, self.start_index:] + readout.unsqueeze(1)
+
+
+class ProjectReadout(nn.Module):
+ def __init__(self, in_features, start_index=1):
+ super(ProjectReadout, self).__init__()
+ self.start_index = start_index
+
+ self.project = nn.Sequential(nn.Linear(2 * in_features, in_features), nn.GELU())
+
+ def forward(self, x):
+ readout = x[:, 0].unsqueeze(1).expand_as(x[:, self.start_index:])
+ features = torch.cat((x[:, self.start_index:], readout), -1)
+
+ return self.project(features)
+
+
+class Transpose(nn.Module):
+ def __init__(self, dim0, dim1):
+ super(Transpose, self).__init__()
+ self.dim0 = dim0
+ self.dim1 = dim1
+
+ def forward(self, x):
+ x = x.transpose(self.dim0, self.dim1)
+ return x
+
+
+activations = {}
+
+
+def get_activation(name):
+ def hook(model, input, output):
+ activations[name] = output
+
+ return hook
+
+
+def forward_default(pretrained, x, function_name="forward_features"):
+ exec(f"pretrained.model.{function_name}(x)")
+
+ layer_1 = pretrained.activations["1"]
+ layer_2 = pretrained.activations["2"]
+ layer_3 = pretrained.activations["3"]
+ layer_4 = pretrained.activations["4"]
+
+ if hasattr(pretrained, "act_postprocess1"):
+ layer_1 = pretrained.act_postprocess1(layer_1)
+ if hasattr(pretrained, "act_postprocess2"):
+ layer_2 = pretrained.act_postprocess2(layer_2)
+ if hasattr(pretrained, "act_postprocess3"):
+ layer_3 = pretrained.act_postprocess3(layer_3)
+ if hasattr(pretrained, "act_postprocess4"):
+ layer_4 = pretrained.act_postprocess4(layer_4)
+
+ return layer_1, layer_2, layer_3, layer_4
+
+
+def forward_adapted_unflatten(pretrained, x, function_name="forward_features"):
+ b, c, h, w = x.shape
+
+ exec(f"glob = pretrained.model.{function_name}(x)")
+
+ layer_1 = pretrained.activations["1"]
+ layer_2 = pretrained.activations["2"]
+ layer_3 = pretrained.activations["3"]
+ layer_4 = pretrained.activations["4"]
+
+ layer_1 = pretrained.act_postprocess1[0:2](layer_1)
+ layer_2 = pretrained.act_postprocess2[0:2](layer_2)
+ layer_3 = pretrained.act_postprocess3[0:2](layer_3)
+ layer_4 = pretrained.act_postprocess4[0:2](layer_4)
+
+ unflatten = nn.Sequential(
+ nn.Unflatten(
+ 2,
+ torch.Size(
+ [
+ h // pretrained.model.patch_size[1],
+ w // pretrained.model.patch_size[0],
+ ]
+ ),
+ )
+ )
+
+ if layer_1.ndim == 3:
+ layer_1 = unflatten(layer_1)
+ if layer_2.ndim == 3:
+ layer_2 = unflatten(layer_2)
+ if layer_3.ndim == 3:
+ layer_3 = unflatten(layer_3)
+ if layer_4.ndim == 3:
+ layer_4 = unflatten(layer_4)
+
+ layer_1 = pretrained.act_postprocess1[3: len(pretrained.act_postprocess1)](layer_1)
+ layer_2 = pretrained.act_postprocess2[3: len(pretrained.act_postprocess2)](layer_2)
+ layer_3 = pretrained.act_postprocess3[3: len(pretrained.act_postprocess3)](layer_3)
+ layer_4 = pretrained.act_postprocess4[3: len(pretrained.act_postprocess4)](layer_4)
+
+ return layer_1, layer_2, layer_3, layer_4
+
+
+def get_readout_oper(vit_features, features, use_readout, start_index=1):
+ if use_readout == "ignore":
+ readout_oper = [Slice(start_index)] * len(features)
+ elif use_readout == "add":
+ readout_oper = [AddReadout(start_index)] * len(features)
+ elif use_readout == "project":
+ readout_oper = [
+ ProjectReadout(vit_features, start_index) for out_feat in features
+ ]
+ else:
+ assert (
+ False
+ ), "wrong operation for readout token, use_readout can be 'ignore', 'add', or 'project'"
+
+ return readout_oper
+
+
+def make_backbone_default(
+ model,
+ features=[96, 192, 384, 768],
+ size=[384, 384],
+ hooks=[2, 5, 8, 11],
+ vit_features=768,
+ use_readout="ignore",
+ start_index=1,
+ start_index_readout=1,
+):
+ pretrained = nn.Module()
+
+ pretrained.model = model
+ pretrained.model.blocks[hooks[0]].register_forward_hook(get_activation("1"))
+ pretrained.model.blocks[hooks[1]].register_forward_hook(get_activation("2"))
+ pretrained.model.blocks[hooks[2]].register_forward_hook(get_activation("3"))
+ pretrained.model.blocks[hooks[3]].register_forward_hook(get_activation("4"))
+
+ pretrained.activations = activations
+
+ readout_oper = get_readout_oper(vit_features, features, use_readout, start_index_readout)
+
+ # 32, 48, 136, 384
+ pretrained.act_postprocess1 = nn.Sequential(
+ readout_oper[0],
+ Transpose(1, 2),
+ nn.Unflatten(2, torch.Size([size[0] // 16, size[1] // 16])),
+ nn.Conv2d(
+ in_channels=vit_features,
+ out_channels=features[0],
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ ),
+ nn.ConvTranspose2d(
+ in_channels=features[0],
+ out_channels=features[0],
+ kernel_size=4,
+ stride=4,
+ padding=0,
+ bias=True,
+ dilation=1,
+ groups=1,
+ ),
+ )
+
+ pretrained.act_postprocess2 = nn.Sequential(
+ readout_oper[1],
+ Transpose(1, 2),
+ nn.Unflatten(2, torch.Size([size[0] // 16, size[1] // 16])),
+ nn.Conv2d(
+ in_channels=vit_features,
+ out_channels=features[1],
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ ),
+ nn.ConvTranspose2d(
+ in_channels=features[1],
+ out_channels=features[1],
+ kernel_size=2,
+ stride=2,
+ padding=0,
+ bias=True,
+ dilation=1,
+ groups=1,
+ ),
+ )
+
+ pretrained.act_postprocess3 = nn.Sequential(
+ readout_oper[2],
+ Transpose(1, 2),
+ nn.Unflatten(2, torch.Size([size[0] // 16, size[1] // 16])),
+ nn.Conv2d(
+ in_channels=vit_features,
+ out_channels=features[2],
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ ),
+ )
+
+ pretrained.act_postprocess4 = nn.Sequential(
+ readout_oper[3],
+ Transpose(1, 2),
+ nn.Unflatten(2, torch.Size([size[0] // 16, size[1] // 16])),
+ nn.Conv2d(
+ in_channels=vit_features,
+ out_channels=features[3],
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ ),
+ nn.Conv2d(
+ in_channels=features[3],
+ out_channels=features[3],
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ ),
+ )
+
+ pretrained.model.start_index = start_index
+ pretrained.model.patch_size = [16, 16]
+
+ return pretrained
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/vit.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/vit.py
new file mode 100644
index 0000000000000000000000000000000000000000..27e103c6e383da4fa6ea10e2ec5e19b486be0193
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/backbones/vit.py
@@ -0,0 +1,221 @@
+import torch
+import torch.nn as nn
+import timm
+import types
+import math
+import torch.nn.functional as F
+
+from .utils import (activations, forward_adapted_unflatten, get_activation, get_readout_oper,
+ make_backbone_default, Transpose)
+
+
+def forward_vit(pretrained, x):
+ return forward_adapted_unflatten(pretrained, x, "forward_flex")
+
+
+def _resize_pos_embed(self, posemb, gs_h, gs_w):
+ posemb_tok, posemb_grid = (
+ posemb[:, : self.start_index],
+ posemb[0, self.start_index:],
+ )
+
+ gs_old = int(math.sqrt(len(posemb_grid)))
+
+ posemb_grid = posemb_grid.reshape(1, gs_old, gs_old, -1).permute(0, 3, 1, 2)
+ posemb_grid = F.interpolate(posemb_grid, size=(gs_h, gs_w), mode="bilinear")
+ posemb_grid = posemb_grid.permute(0, 2, 3, 1).reshape(1, gs_h * gs_w, -1)
+
+ posemb = torch.cat([posemb_tok, posemb_grid], dim=1)
+
+ return posemb
+
+
+def forward_flex(self, x):
+ b, c, h, w = x.shape
+
+ pos_embed = self._resize_pos_embed(
+ self.pos_embed, h // self.patch_size[1], w // self.patch_size[0]
+ )
+
+ B = x.shape[0]
+
+ if hasattr(self.patch_embed, "backbone"):
+ x = self.patch_embed.backbone(x)
+ if isinstance(x, (list, tuple)):
+ x = x[-1] # last feature if backbone outputs list/tuple of features
+
+ x = self.patch_embed.proj(x).flatten(2).transpose(1, 2)
+
+ if getattr(self, "dist_token", None) is not None:
+ cls_tokens = self.cls_token.expand(
+ B, -1, -1
+ ) # stole cls_tokens impl from Phil Wang, thanks
+ dist_token = self.dist_token.expand(B, -1, -1)
+ x = torch.cat((cls_tokens, dist_token, x), dim=1)
+ else:
+ if self.no_embed_class:
+ x = x + pos_embed
+ cls_tokens = self.cls_token.expand(
+ B, -1, -1
+ ) # stole cls_tokens impl from Phil Wang, thanks
+ x = torch.cat((cls_tokens, x), dim=1)
+
+ if not self.no_embed_class:
+ x = x + pos_embed
+ x = self.pos_drop(x)
+
+ for blk in self.blocks:
+ x = blk(x)
+
+ x = self.norm(x)
+
+ return x
+
+
+def _make_vit_b16_backbone(
+ model,
+ features=[96, 192, 384, 768],
+ size=[384, 384],
+ hooks=[2, 5, 8, 11],
+ vit_features=768,
+ use_readout="ignore",
+ start_index=1,
+ start_index_readout=1,
+):
+ pretrained = make_backbone_default(model, features, size, hooks, vit_features, use_readout, start_index,
+ start_index_readout)
+
+ # We inject this function into the VisionTransformer instances so that
+ # we can use it with interpolated position embeddings without modifying the library source.
+ pretrained.model.forward_flex = types.MethodType(forward_flex, pretrained.model)
+ pretrained.model._resize_pos_embed = types.MethodType(
+ _resize_pos_embed, pretrained.model
+ )
+
+ return pretrained
+
+
+def _make_pretrained_vitl16_384(pretrained, use_readout="ignore", hooks=None):
+ model = timm.create_model("vit_large_patch16_384", pretrained=pretrained)
+
+ hooks = [5, 11, 17, 23] if hooks == None else hooks
+ return _make_vit_b16_backbone(
+ model,
+ features=[256, 512, 1024, 1024],
+ hooks=hooks,
+ vit_features=1024,
+ use_readout=use_readout,
+ )
+
+
+def _make_pretrained_vitb16_384(pretrained, use_readout="ignore", hooks=None):
+ model = timm.create_model("vit_base_patch16_384", pretrained=pretrained)
+
+ hooks = [2, 5, 8, 11] if hooks == None else hooks
+ return _make_vit_b16_backbone(
+ model, features=[96, 192, 384, 768], hooks=hooks, use_readout=use_readout
+ )
+
+
+def _make_vit_b_rn50_backbone(
+ model,
+ features=[256, 512, 768, 768],
+ size=[384, 384],
+ hooks=[0, 1, 8, 11],
+ vit_features=768,
+ patch_size=[16, 16],
+ number_stages=2,
+ use_vit_only=False,
+ use_readout="ignore",
+ start_index=1,
+):
+ pretrained = nn.Module()
+
+ pretrained.model = model
+
+ used_number_stages = 0 if use_vit_only else number_stages
+ for s in range(used_number_stages):
+ pretrained.model.patch_embed.backbone.stages[s].register_forward_hook(
+ get_activation(str(s + 1))
+ )
+ for s in range(used_number_stages, 4):
+ pretrained.model.blocks[hooks[s]].register_forward_hook(get_activation(str(s + 1)))
+
+ pretrained.activations = activations
+
+ readout_oper = get_readout_oper(vit_features, features, use_readout, start_index)
+
+ for s in range(used_number_stages):
+ value = nn.Sequential(nn.Identity(), nn.Identity(), nn.Identity())
+ exec(f"pretrained.act_postprocess{s + 1}=value")
+ for s in range(used_number_stages, 4):
+ if s < number_stages:
+ final_layer = nn.ConvTranspose2d(
+ in_channels=features[s],
+ out_channels=features[s],
+ kernel_size=4 // (2 ** s),
+ stride=4 // (2 ** s),
+ padding=0,
+ bias=True,
+ dilation=1,
+ groups=1,
+ )
+ elif s > number_stages:
+ final_layer = nn.Conv2d(
+ in_channels=features[3],
+ out_channels=features[3],
+ kernel_size=3,
+ stride=2,
+ padding=1,
+ )
+ else:
+ final_layer = None
+
+ layers = [
+ readout_oper[s],
+ Transpose(1, 2),
+ nn.Unflatten(2, torch.Size([size[0] // 16, size[1] // 16])),
+ nn.Conv2d(
+ in_channels=vit_features,
+ out_channels=features[s],
+ kernel_size=1,
+ stride=1,
+ padding=0,
+ ),
+ ]
+ if final_layer is not None:
+ layers.append(final_layer)
+
+ value = nn.Sequential(*layers)
+ exec(f"pretrained.act_postprocess{s + 1}=value")
+
+ pretrained.model.start_index = start_index
+ pretrained.model.patch_size = patch_size
+
+ # We inject this function into the VisionTransformer instances so that
+ # we can use it with interpolated position embeddings without modifying the library source.
+ pretrained.model.forward_flex = types.MethodType(forward_flex, pretrained.model)
+
+ # We inject this function into the VisionTransformer instances so that
+ # we can use it with interpolated position embeddings without modifying the library source.
+ pretrained.model._resize_pos_embed = types.MethodType(
+ _resize_pos_embed, pretrained.model
+ )
+
+ return pretrained
+
+
+def _make_pretrained_vitb_rn50_384(
+ pretrained, use_readout="ignore", hooks=None, use_vit_only=False
+):
+ model = timm.create_model("vit_base_resnet50_384", pretrained=pretrained)
+
+ hooks = [0, 1, 8, 11] if hooks == None else hooks
+ return _make_vit_b_rn50_backbone(
+ model,
+ features=[256, 512, 768, 768],
+ size=[384, 384],
+ hooks=hooks,
+ use_vit_only=use_vit_only,
+ use_readout=use_readout,
+ )
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/base_model.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/base_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..27fe93ec5bfcfae3f8e78392ca617cdb6adc9b11
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/base_model.py
@@ -0,0 +1,16 @@
+import torch
+
+
+class BaseModel(torch.nn.Module):
+ def load(self, path):
+ """Load model from file.
+
+ Args:
+ path (str): file path
+ """
+ parameters = torch.load(path, map_location=torch.device('cpu'))
+
+ if "optimizer" in parameters:
+ parameters = parameters["model"]
+
+ self.load_state_dict(parameters)
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/blocks.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/blocks.py
new file mode 100644
index 0000000000000000000000000000000000000000..7f48f075c3ad3f62d0f303937c410982f1491929
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/blocks.py
@@ -0,0 +1,439 @@
+import torch
+import torch.nn as nn
+
+from .backbones.beit import (
+ _make_pretrained_beitl16_512,
+ _make_pretrained_beitl16_384,
+ _make_pretrained_beitb16_384,
+ forward_beit,
+)
+from .backbones.swin_common import (
+ forward_swin,
+)
+from .backbones.swin2 import (
+ _make_pretrained_swin2l24_384,
+ _make_pretrained_swin2b24_384,
+ _make_pretrained_swin2t16_256,
+)
+from .backbones.swin import (
+ _make_pretrained_swinl12_384,
+)
+from .backbones.levit import (
+ _make_pretrained_levit_384,
+ forward_levit,
+)
+from .backbones.vit import (
+ _make_pretrained_vitb_rn50_384,
+ _make_pretrained_vitl16_384,
+ _make_pretrained_vitb16_384,
+ forward_vit,
+)
+
+def _make_encoder(backbone, features, use_pretrained, groups=1, expand=False, exportable=True, hooks=None,
+ use_vit_only=False, use_readout="ignore", in_features=[96, 256, 512, 1024]):
+ if backbone == "beitl16_512":
+ pretrained = _make_pretrained_beitl16_512(
+ use_pretrained, hooks=hooks, use_readout=use_readout
+ )
+ scratch = _make_scratch(
+ [256, 512, 1024, 1024], features, groups=groups, expand=expand
+ ) # BEiT_512-L (backbone)
+ elif backbone == "beitl16_384":
+ pretrained = _make_pretrained_beitl16_384(
+ use_pretrained, hooks=hooks, use_readout=use_readout
+ )
+ scratch = _make_scratch(
+ [256, 512, 1024, 1024], features, groups=groups, expand=expand
+ ) # BEiT_384-L (backbone)
+ elif backbone == "beitb16_384":
+ pretrained = _make_pretrained_beitb16_384(
+ use_pretrained, hooks=hooks, use_readout=use_readout
+ )
+ scratch = _make_scratch(
+ [96, 192, 384, 768], features, groups=groups, expand=expand
+ ) # BEiT_384-B (backbone)
+ elif backbone == "swin2l24_384":
+ pretrained = _make_pretrained_swin2l24_384(
+ use_pretrained, hooks=hooks
+ )
+ scratch = _make_scratch(
+ [192, 384, 768, 1536], features, groups=groups, expand=expand
+ ) # Swin2-L/12to24 (backbone)
+ elif backbone == "swin2b24_384":
+ pretrained = _make_pretrained_swin2b24_384(
+ use_pretrained, hooks=hooks
+ )
+ scratch = _make_scratch(
+ [128, 256, 512, 1024], features, groups=groups, expand=expand
+ ) # Swin2-B/12to24 (backbone)
+ elif backbone == "swin2t16_256":
+ pretrained = _make_pretrained_swin2t16_256(
+ use_pretrained, hooks=hooks
+ )
+ scratch = _make_scratch(
+ [96, 192, 384, 768], features, groups=groups, expand=expand
+ ) # Swin2-T/16 (backbone)
+ elif backbone == "swinl12_384":
+ pretrained = _make_pretrained_swinl12_384(
+ use_pretrained, hooks=hooks
+ )
+ scratch = _make_scratch(
+ [192, 384, 768, 1536], features, groups=groups, expand=expand
+ ) # Swin-L/12 (backbone)
+ elif backbone == "next_vit_large_6m":
+ from .backbones.next_vit import _make_pretrained_next_vit_large_6m
+ pretrained = _make_pretrained_next_vit_large_6m(hooks=hooks)
+ scratch = _make_scratch(
+ in_features, features, groups=groups, expand=expand
+ ) # Next-ViT-L on ImageNet-1K-6M (backbone)
+ elif backbone == "levit_384":
+ pretrained = _make_pretrained_levit_384(
+ use_pretrained, hooks=hooks
+ )
+ scratch = _make_scratch(
+ [384, 512, 768], features, groups=groups, expand=expand
+ ) # LeViT 384 (backbone)
+ elif backbone == "vitl16_384":
+ pretrained = _make_pretrained_vitl16_384(
+ use_pretrained, hooks=hooks, use_readout=use_readout
+ )
+ scratch = _make_scratch(
+ [256, 512, 1024, 1024], features, groups=groups, expand=expand
+ ) # ViT-L/16 - 85.0% Top1 (backbone)
+ elif backbone == "vitb_rn50_384":
+ pretrained = _make_pretrained_vitb_rn50_384(
+ use_pretrained,
+ hooks=hooks,
+ use_vit_only=use_vit_only,
+ use_readout=use_readout,
+ )
+ scratch = _make_scratch(
+ [256, 512, 768, 768], features, groups=groups, expand=expand
+ ) # ViT-H/16 - 85.0% Top1 (backbone)
+ elif backbone == "vitb16_384":
+ pretrained = _make_pretrained_vitb16_384(
+ use_pretrained, hooks=hooks, use_readout=use_readout
+ )
+ scratch = _make_scratch(
+ [96, 192, 384, 768], features, groups=groups, expand=expand
+ ) # ViT-B/16 - 84.6% Top1 (backbone)
+ elif backbone == "resnext101_wsl":
+ pretrained = _make_pretrained_resnext101_wsl(use_pretrained)
+ scratch = _make_scratch([256, 512, 1024, 2048], features, groups=groups, expand=expand) # efficientnet_lite3
+ elif backbone == "efficientnet_lite3":
+ pretrained = _make_pretrained_efficientnet_lite3(use_pretrained, exportable=exportable)
+ scratch = _make_scratch([32, 48, 136, 384], features, groups=groups, expand=expand) # efficientnet_lite3
+ else:
+ print(f"Backbone '{backbone}' not implemented")
+ assert False
+
+ return pretrained, scratch
+
+
+def _make_scratch(in_shape, out_shape, groups=1, expand=False):
+ scratch = nn.Module()
+
+ out_shape1 = out_shape
+ out_shape2 = out_shape
+ out_shape3 = out_shape
+ if len(in_shape) >= 4:
+ out_shape4 = out_shape
+
+ if expand:
+ out_shape1 = out_shape
+ out_shape2 = out_shape*2
+ out_shape3 = out_shape*4
+ if len(in_shape) >= 4:
+ out_shape4 = out_shape*8
+
+ scratch.layer1_rn = nn.Conv2d(
+ in_shape[0], out_shape1, kernel_size=3, stride=1, padding=1, bias=False, groups=groups
+ )
+ scratch.layer2_rn = nn.Conv2d(
+ in_shape[1], out_shape2, kernel_size=3, stride=1, padding=1, bias=False, groups=groups
+ )
+ scratch.layer3_rn = nn.Conv2d(
+ in_shape[2], out_shape3, kernel_size=3, stride=1, padding=1, bias=False, groups=groups
+ )
+ if len(in_shape) >= 4:
+ scratch.layer4_rn = nn.Conv2d(
+ in_shape[3], out_shape4, kernel_size=3, stride=1, padding=1, bias=False, groups=groups
+ )
+
+ return scratch
+
+
+def _make_pretrained_efficientnet_lite3(use_pretrained, exportable=False):
+ efficientnet = torch.hub.load(
+ "rwightman/gen-efficientnet-pytorch",
+ "tf_efficientnet_lite3",
+ pretrained=use_pretrained,
+ exportable=exportable
+ )
+ return _make_efficientnet_backbone(efficientnet)
+
+
+def _make_efficientnet_backbone(effnet):
+ pretrained = nn.Module()
+
+ pretrained.layer1 = nn.Sequential(
+ effnet.conv_stem, effnet.bn1, effnet.act1, *effnet.blocks[0:2]
+ )
+ pretrained.layer2 = nn.Sequential(*effnet.blocks[2:3])
+ pretrained.layer3 = nn.Sequential(*effnet.blocks[3:5])
+ pretrained.layer4 = nn.Sequential(*effnet.blocks[5:9])
+
+ return pretrained
+
+
+def _make_resnet_backbone(resnet):
+ pretrained = nn.Module()
+ pretrained.layer1 = nn.Sequential(
+ resnet.conv1, resnet.bn1, resnet.relu, resnet.maxpool, resnet.layer1
+ )
+
+ pretrained.layer2 = resnet.layer2
+ pretrained.layer3 = resnet.layer3
+ pretrained.layer4 = resnet.layer4
+
+ return pretrained
+
+
+def _make_pretrained_resnext101_wsl(use_pretrained):
+ resnet = torch.hub.load("facebookresearch/WSL-Images", "resnext101_32x8d_wsl")
+ return _make_resnet_backbone(resnet)
+
+
+
+class Interpolate(nn.Module):
+ """Interpolation module.
+ """
+
+ def __init__(self, scale_factor, mode, align_corners=False):
+ """Init.
+
+ Args:
+ scale_factor (float): scaling
+ mode (str): interpolation mode
+ """
+ super(Interpolate, self).__init__()
+
+ self.interp = nn.functional.interpolate
+ self.scale_factor = scale_factor
+ self.mode = mode
+ self.align_corners = align_corners
+
+ def forward(self, x):
+ """Forward pass.
+
+ Args:
+ x (tensor): input
+
+ Returns:
+ tensor: interpolated data
+ """
+
+ x = self.interp(
+ x, scale_factor=self.scale_factor, mode=self.mode, align_corners=self.align_corners
+ )
+
+ return x
+
+
+class ResidualConvUnit(nn.Module):
+ """Residual convolution module.
+ """
+
+ def __init__(self, features):
+ """Init.
+
+ Args:
+ features (int): number of features
+ """
+ super().__init__()
+
+ self.conv1 = nn.Conv2d(
+ features, features, kernel_size=3, stride=1, padding=1, bias=True
+ )
+
+ self.conv2 = nn.Conv2d(
+ features, features, kernel_size=3, stride=1, padding=1, bias=True
+ )
+
+ self.relu = nn.ReLU(inplace=True)
+
+ def forward(self, x):
+ """Forward pass.
+
+ Args:
+ x (tensor): input
+
+ Returns:
+ tensor: output
+ """
+ out = self.relu(x)
+ out = self.conv1(out)
+ out = self.relu(out)
+ out = self.conv2(out)
+
+ return out + x
+
+
+class FeatureFusionBlock(nn.Module):
+ """Feature fusion block.
+ """
+
+ def __init__(self, features):
+ """Init.
+
+ Args:
+ features (int): number of features
+ """
+ super(FeatureFusionBlock, self).__init__()
+
+ self.resConfUnit1 = ResidualConvUnit(features)
+ self.resConfUnit2 = ResidualConvUnit(features)
+
+ def forward(self, *xs):
+ """Forward pass.
+
+ Returns:
+ tensor: output
+ """
+ output = xs[0]
+
+ if len(xs) == 2:
+ output += self.resConfUnit1(xs[1])
+
+ output = self.resConfUnit2(output)
+
+ output = nn.functional.interpolate(
+ output, scale_factor=2, mode="bilinear", align_corners=True
+ )
+
+ return output
+
+
+
+
+class ResidualConvUnit_custom(nn.Module):
+ """Residual convolution module.
+ """
+
+ def __init__(self, features, activation, bn):
+ """Init.
+
+ Args:
+ features (int): number of features
+ """
+ super().__init__()
+
+ self.bn = bn
+
+ self.groups=1
+
+ self.conv1 = nn.Conv2d(
+ features, features, kernel_size=3, stride=1, padding=1, bias=True, groups=self.groups
+ )
+
+ self.conv2 = nn.Conv2d(
+ features, features, kernel_size=3, stride=1, padding=1, bias=True, groups=self.groups
+ )
+
+ if self.bn==True:
+ self.bn1 = nn.BatchNorm2d(features)
+ self.bn2 = nn.BatchNorm2d(features)
+
+ self.activation = activation
+
+ self.skip_add = nn.quantized.FloatFunctional()
+
+ def forward(self, x):
+ """Forward pass.
+
+ Args:
+ x (tensor): input
+
+ Returns:
+ tensor: output
+ """
+
+ out = self.activation(x)
+ out = self.conv1(out)
+ if self.bn==True:
+ out = self.bn1(out)
+
+ out = self.activation(out)
+ out = self.conv2(out)
+ if self.bn==True:
+ out = self.bn2(out)
+
+ if self.groups > 1:
+ out = self.conv_merge(out)
+
+ return self.skip_add.add(out, x)
+
+ # return out + x
+
+
+class FeatureFusionBlock_custom(nn.Module):
+ """Feature fusion block.
+ """
+
+ def __init__(self, features, activation, deconv=False, bn=False, expand=False, align_corners=True, size=None):
+ """Init.
+
+ Args:
+ features (int): number of features
+ """
+ super(FeatureFusionBlock_custom, self).__init__()
+
+ self.deconv = deconv
+ self.align_corners = align_corners
+
+ self.groups=1
+
+ self.expand = expand
+ out_features = features
+ if self.expand==True:
+ out_features = features//2
+
+ self.out_conv = nn.Conv2d(features, out_features, kernel_size=1, stride=1, padding=0, bias=True, groups=1)
+
+ self.resConfUnit1 = ResidualConvUnit_custom(features, activation, bn)
+ self.resConfUnit2 = ResidualConvUnit_custom(features, activation, bn)
+
+ self.skip_add = nn.quantized.FloatFunctional()
+
+ self.size=size
+
+ def forward(self, *xs, size=None):
+ """Forward pass.
+
+ Returns:
+ tensor: output
+ """
+ output = xs[0]
+
+ if len(xs) == 2:
+ res = self.resConfUnit1(xs[1])
+ output = self.skip_add.add(output, res)
+ # output += res
+
+ output = self.resConfUnit2(output)
+
+ if (size is None) and (self.size is None):
+ modifier = {"scale_factor": 2}
+ elif size is None:
+ modifier = {"size": self.size}
+ else:
+ modifier = {"size": size}
+
+ output = nn.functional.interpolate(
+ output, **modifier, mode="bilinear", align_corners=self.align_corners
+ )
+
+ output = self.out_conv(output)
+
+ return output
+
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/dpt_depth.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/dpt_depth.py
new file mode 100644
index 0000000000000000000000000000000000000000..0382e7303b3920db8c28bf84e0e289862fcb8f26
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/dpt_depth.py
@@ -0,0 +1,166 @@
+import torch
+import torch.nn as nn
+
+from .base_model import BaseModel
+from .blocks import (
+ FeatureFusionBlock_custom,
+ Interpolate,
+ _make_encoder,
+ forward_beit,
+ forward_swin,
+ forward_levit,
+ forward_vit,
+)
+from .backbones.levit import stem_b4_transpose
+from timm.models.layers import get_act_layer
+
+
+def _make_fusion_block(features, use_bn, size = None):
+ return FeatureFusionBlock_custom(
+ features,
+ nn.ReLU(False),
+ deconv=False,
+ bn=use_bn,
+ expand=False,
+ align_corners=True,
+ size=size,
+ )
+
+
+class DPT(BaseModel):
+ def __init__(
+ self,
+ head,
+ features=256,
+ backbone="vitb_rn50_384",
+ readout="project",
+ channels_last=False,
+ use_bn=False,
+ **kwargs
+ ):
+
+ super(DPT, self).__init__()
+
+ self.channels_last = channels_last
+
+ # For the Swin, Swin 2, LeViT and Next-ViT Transformers, the hierarchical architectures prevent setting the
+ # hooks freely. Instead, the hooks have to be chosen according to the ranges specified in the comments.
+ hooks = {
+ "beitl16_512": [5, 11, 17, 23],
+ "beitl16_384": [5, 11, 17, 23],
+ "beitb16_384": [2, 5, 8, 11],
+ "swin2l24_384": [1, 1, 17, 1], # Allowed ranges: [0, 1], [0, 1], [ 0, 17], [ 0, 1]
+ "swin2b24_384": [1, 1, 17, 1], # [0, 1], [0, 1], [ 0, 17], [ 0, 1]
+ "swin2t16_256": [1, 1, 5, 1], # [0, 1], [0, 1], [ 0, 5], [ 0, 1]
+ "swinl12_384": [1, 1, 17, 1], # [0, 1], [0, 1], [ 0, 17], [ 0, 1]
+ "next_vit_large_6m": [2, 6, 36, 39], # [0, 2], [3, 6], [ 7, 36], [37, 39]
+ "levit_384": [3, 11, 21], # [0, 3], [6, 11], [14, 21]
+ "vitb_rn50_384": [0, 1, 8, 11],
+ "vitb16_384": [2, 5, 8, 11],
+ "vitl16_384": [5, 11, 17, 23],
+ }[backbone]
+
+ if "next_vit" in backbone:
+ in_features = {
+ "next_vit_large_6m": [96, 256, 512, 1024],
+ }[backbone]
+ else:
+ in_features = None
+
+ # Instantiate backbone and reassemble blocks
+ self.pretrained, self.scratch = _make_encoder(
+ backbone,
+ features,
+ False, # Set to true of you want to train from scratch, uses ImageNet weights
+ groups=1,
+ expand=False,
+ exportable=False,
+ hooks=hooks,
+ use_readout=readout,
+ in_features=in_features,
+ )
+
+ self.number_layers = len(hooks) if hooks is not None else 4
+ size_refinenet3 = None
+ self.scratch.stem_transpose = None
+
+ if "beit" in backbone:
+ self.forward_transformer = forward_beit
+ elif "swin" in backbone:
+ self.forward_transformer = forward_swin
+ elif "next_vit" in backbone:
+ from .backbones.next_vit import forward_next_vit
+ self.forward_transformer = forward_next_vit
+ elif "levit" in backbone:
+ self.forward_transformer = forward_levit
+ size_refinenet3 = 7
+ self.scratch.stem_transpose = stem_b4_transpose(256, 128, get_act_layer("hard_swish"))
+ else:
+ self.forward_transformer = forward_vit
+
+ self.scratch.refinenet1 = _make_fusion_block(features, use_bn)
+ self.scratch.refinenet2 = _make_fusion_block(features, use_bn)
+ self.scratch.refinenet3 = _make_fusion_block(features, use_bn, size_refinenet3)
+ if self.number_layers >= 4:
+ self.scratch.refinenet4 = _make_fusion_block(features, use_bn)
+
+ self.scratch.output_conv = head
+
+
+ def forward(self, x):
+ if self.channels_last == True:
+ x.contiguous(memory_format=torch.channels_last)
+
+ layers = self.forward_transformer(self.pretrained, x)
+ if self.number_layers == 3:
+ layer_1, layer_2, layer_3 = layers
+ else:
+ layer_1, layer_2, layer_3, layer_4 = layers
+
+ layer_1_rn = self.scratch.layer1_rn(layer_1)
+ layer_2_rn = self.scratch.layer2_rn(layer_2)
+ layer_3_rn = self.scratch.layer3_rn(layer_3)
+ if self.number_layers >= 4:
+ layer_4_rn = self.scratch.layer4_rn(layer_4)
+
+ if self.number_layers == 3:
+ path_3 = self.scratch.refinenet3(layer_3_rn, size=layer_2_rn.shape[2:])
+ else:
+ path_4 = self.scratch.refinenet4(layer_4_rn, size=layer_3_rn.shape[2:])
+ path_3 = self.scratch.refinenet3(path_4, layer_3_rn, size=layer_2_rn.shape[2:])
+ path_2 = self.scratch.refinenet2(path_3, layer_2_rn, size=layer_1_rn.shape[2:])
+ path_1 = self.scratch.refinenet1(path_2, layer_1_rn)
+
+ if self.scratch.stem_transpose is not None:
+ path_1 = self.scratch.stem_transpose(path_1)
+
+ out = self.scratch.output_conv(path_1)
+
+ return out
+
+
+class DPTDepthModel(DPT):
+ def __init__(self, path=None, non_negative=True, **kwargs):
+ features = kwargs["features"] if "features" in kwargs else 256
+ head_features_1 = kwargs["head_features_1"] if "head_features_1" in kwargs else features
+ head_features_2 = kwargs["head_features_2"] if "head_features_2" in kwargs else 32
+ kwargs.pop("head_features_1", None)
+ kwargs.pop("head_features_2", None)
+
+ head = nn.Sequential(
+ nn.Conv2d(head_features_1, head_features_1 // 2, kernel_size=3, stride=1, padding=1),
+ Interpolate(scale_factor=2, mode="bilinear", align_corners=True),
+ nn.Conv2d(head_features_1 // 2, head_features_2, kernel_size=3, stride=1, padding=1),
+ nn.ReLU(True),
+ nn.Conv2d(head_features_2, 1, kernel_size=1, stride=1, padding=0),
+ nn.ReLU(True) if non_negative else nn.Identity(),
+ nn.Identity(),
+ )
+
+ super().__init__(head, **kwargs)
+
+ if path is not None:
+ self.load(path)
+
+ def forward(self, x):
+ return super().forward(x).squeeze(dim=1)
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/midas_net.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/midas_net.py
new file mode 100644
index 0000000000000000000000000000000000000000..e10487c8fd4d3b50a4d9cf9bb72ce0a4734894c2
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/midas_net.py
@@ -0,0 +1,76 @@
+"""MidashNet: Network for monocular depth estimation trained by mixing several datasets.
+This file contains code that is adapted from
+https://github.com/thomasjpfan/pytorch_refinenet/blob/master/pytorch_refinenet/refinenet/refinenet_4cascade.py
+"""
+import torch
+import torch.nn as nn
+
+from .base_model import BaseModel
+from .blocks import FeatureFusionBlock, Interpolate, _make_encoder
+
+
+class MidasNet(BaseModel):
+ """Network for monocular depth estimation.
+ """
+
+ def __init__(self, path=None, features=256, non_negative=True):
+ """Init.
+
+ Args:
+ path (str, optional): Path to saved model. Defaults to None.
+ features (int, optional): Number of features. Defaults to 256.
+ backbone (str, optional): Backbone network for encoder. Defaults to resnet50
+ """
+ print("Loading weights: ", path)
+
+ super(MidasNet, self).__init__()
+
+ use_pretrained = False if path is None else True
+
+ self.pretrained, self.scratch = _make_encoder(backbone="resnext101_wsl", features=features, use_pretrained=use_pretrained)
+
+ self.scratch.refinenet4 = FeatureFusionBlock(features)
+ self.scratch.refinenet3 = FeatureFusionBlock(features)
+ self.scratch.refinenet2 = FeatureFusionBlock(features)
+ self.scratch.refinenet1 = FeatureFusionBlock(features)
+
+ self.scratch.output_conv = nn.Sequential(
+ nn.Conv2d(features, 128, kernel_size=3, stride=1, padding=1),
+ Interpolate(scale_factor=2, mode="bilinear"),
+ nn.Conv2d(128, 32, kernel_size=3, stride=1, padding=1),
+ nn.ReLU(True),
+ nn.Conv2d(32, 1, kernel_size=1, stride=1, padding=0),
+ nn.ReLU(True) if non_negative else nn.Identity(),
+ )
+
+ if path:
+ self.load(path)
+
+ def forward(self, x):
+ """Forward pass.
+
+ Args:
+ x (tensor): input data (image)
+
+ Returns:
+ tensor: depth
+ """
+
+ layer_1 = self.pretrained.layer1(x)
+ layer_2 = self.pretrained.layer2(layer_1)
+ layer_3 = self.pretrained.layer3(layer_2)
+ layer_4 = self.pretrained.layer4(layer_3)
+
+ layer_1_rn = self.scratch.layer1_rn(layer_1)
+ layer_2_rn = self.scratch.layer2_rn(layer_2)
+ layer_3_rn = self.scratch.layer3_rn(layer_3)
+ layer_4_rn = self.scratch.layer4_rn(layer_4)
+
+ path_4 = self.scratch.refinenet4(layer_4_rn)
+ path_3 = self.scratch.refinenet3(path_4, layer_3_rn)
+ path_2 = self.scratch.refinenet2(path_3, layer_2_rn)
+ path_1 = self.scratch.refinenet1(path_2, layer_1_rn)
+
+ out = self.scratch.output_conv(path_1)
+
+ return torch.squeeze(out, dim=1)
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/midas_net_custom.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/midas_net_custom.py
new file mode 100644
index 0000000000000000000000000000000000000000..3a8df446c55f057deb6db828db276ae9c0e2308d
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/midas_net_custom.py
@@ -0,0 +1,128 @@
+"""MidashNet: Network for monocular depth estimation trained by mixing several datasets.
+This file contains code that is adapted from
+https://github.com/thomasjpfan/pytorch_refinenet/blob/master/pytorch_refinenet/refinenet/refinenet_4cascade.py
+"""
+import torch
+import torch.nn as nn
+
+from .base_model import BaseModel
+from .blocks import FeatureFusionBlock, FeatureFusionBlock_custom, Interpolate, _make_encoder
+
+
+class MidasNet_small(BaseModel):
+ """Network for monocular depth estimation.
+ """
+
+ def __init__(self, path=None, features=64, backbone="efficientnet_lite3", non_negative=True, exportable=True, channels_last=False, align_corners=True,
+ blocks={'expand': True}):
+ """Init.
+
+ Args:
+ path (str, optional): Path to saved model. Defaults to None.
+ features (int, optional): Number of features. Defaults to 256.
+ backbone (str, optional): Backbone network for encoder. Defaults to resnet50
+ """
+ print("Loading weights: ", path)
+
+ super(MidasNet_small, self).__init__()
+
+ use_pretrained = False if path else True
+
+ self.channels_last = channels_last
+ self.blocks = blocks
+ self.backbone = backbone
+
+ self.groups = 1
+
+ features1=features
+ features2=features
+ features3=features
+ features4=features
+ self.expand = False
+ if "expand" in self.blocks and self.blocks['expand'] == True:
+ self.expand = True
+ features1=features
+ features2=features*2
+ features3=features*4
+ features4=features*8
+
+ self.pretrained, self.scratch = _make_encoder(self.backbone, features, use_pretrained, groups=self.groups, expand=self.expand, exportable=exportable)
+
+ self.scratch.activation = nn.ReLU(False)
+
+ self.scratch.refinenet4 = FeatureFusionBlock_custom(features4, self.scratch.activation, deconv=False, bn=False, expand=self.expand, align_corners=align_corners)
+ self.scratch.refinenet3 = FeatureFusionBlock_custom(features3, self.scratch.activation, deconv=False, bn=False, expand=self.expand, align_corners=align_corners)
+ self.scratch.refinenet2 = FeatureFusionBlock_custom(features2, self.scratch.activation, deconv=False, bn=False, expand=self.expand, align_corners=align_corners)
+ self.scratch.refinenet1 = FeatureFusionBlock_custom(features1, self.scratch.activation, deconv=False, bn=False, align_corners=align_corners)
+
+
+ self.scratch.output_conv = nn.Sequential(
+ nn.Conv2d(features, features//2, kernel_size=3, stride=1, padding=1, groups=self.groups),
+ Interpolate(scale_factor=2, mode="bilinear"),
+ nn.Conv2d(features//2, 32, kernel_size=3, stride=1, padding=1),
+ self.scratch.activation,
+ nn.Conv2d(32, 1, kernel_size=1, stride=1, padding=0),
+ nn.ReLU(True) if non_negative else nn.Identity(),
+ nn.Identity(),
+ )
+
+ if path:
+ self.load(path)
+
+
+ def forward(self, x):
+ """Forward pass.
+
+ Args:
+ x (tensor): input data (image)
+
+ Returns:
+ tensor: depth
+ """
+ if self.channels_last==True:
+ print("self.channels_last = ", self.channels_last)
+ x.contiguous(memory_format=torch.channels_last)
+
+
+ layer_1 = self.pretrained.layer1(x)
+ layer_2 = self.pretrained.layer2(layer_1)
+ layer_3 = self.pretrained.layer3(layer_2)
+ layer_4 = self.pretrained.layer4(layer_3)
+
+ layer_1_rn = self.scratch.layer1_rn(layer_1)
+ layer_2_rn = self.scratch.layer2_rn(layer_2)
+ layer_3_rn = self.scratch.layer3_rn(layer_3)
+ layer_4_rn = self.scratch.layer4_rn(layer_4)
+
+
+ path_4 = self.scratch.refinenet4(layer_4_rn)
+ path_3 = self.scratch.refinenet3(path_4, layer_3_rn)
+ path_2 = self.scratch.refinenet2(path_3, layer_2_rn)
+ path_1 = self.scratch.refinenet1(path_2, layer_1_rn)
+
+ out = self.scratch.output_conv(path_1)
+
+ return torch.squeeze(out, dim=1)
+
+
+
+def fuse_model(m):
+ prev_previous_type = nn.Identity()
+ prev_previous_name = ''
+ previous_type = nn.Identity()
+ previous_name = ''
+ for name, module in m.named_modules():
+ if prev_previous_type == nn.Conv2d and previous_type == nn.BatchNorm2d and type(module) == nn.ReLU:
+ # print("FUSED ", prev_previous_name, previous_name, name)
+ torch.quantization.fuse_modules(m, [prev_previous_name, previous_name, name], inplace=True)
+ elif prev_previous_type == nn.Conv2d and previous_type == nn.BatchNorm2d:
+ # print("FUSED ", prev_previous_name, previous_name)
+ torch.quantization.fuse_modules(m, [prev_previous_name, previous_name], inplace=True)
+ # elif previous_type == nn.Conv2d and type(module) == nn.ReLU:
+ # print("FUSED ", previous_name, name)
+ # torch.quantization.fuse_modules(m, [previous_name, name], inplace=True)
+
+ prev_previous_type = previous_type
+ prev_previous_name = previous_name
+ previous_type = type(module)
+ previous_name = name
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/model_loader.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/model_loader.py
new file mode 100644
index 0000000000000000000000000000000000000000..6c6db0d7d421cebba21da140eeb6eb09b8906196
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/model_loader.py
@@ -0,0 +1,242 @@
+import cv2
+import torch
+
+from midas.dpt_depth import DPTDepthModel
+from midas.midas_net import MidasNet
+from midas.midas_net_custom import MidasNet_small
+from midas.transforms import Resize, NormalizeImage, PrepareForNet
+
+from torchvision.transforms import Compose
+
+default_models = {
+ "dpt_beit_large_512": "weights/dpt_beit_large_512.pt",
+ "dpt_beit_large_384": "weights/dpt_beit_large_384.pt",
+ "dpt_beit_base_384": "weights/dpt_beit_base_384.pt",
+ "dpt_swin2_large_384": "weights/dpt_swin2_large_384.pt",
+ "dpt_swin2_base_384": "weights/dpt_swin2_base_384.pt",
+ "dpt_swin2_tiny_256": "weights/dpt_swin2_tiny_256.pt",
+ "dpt_swin_large_384": "weights/dpt_swin_large_384.pt",
+ "dpt_next_vit_large_384": "weights/dpt_next_vit_large_384.pt",
+ "dpt_levit_224": "weights/dpt_levit_224.pt",
+ "dpt_large_384": "weights/dpt_large_384.pt",
+ "dpt_hybrid_384": "weights/dpt_hybrid_384.pt",
+ "midas_v21_384": "weights/midas_v21_384.pt",
+ "midas_v21_small_256": "weights/midas_v21_small_256.pt",
+ "openvino_midas_v21_small_256": "weights/openvino_midas_v21_small_256.xml",
+}
+
+
+def load_model(device, model_path, model_type="dpt_large_384", optimize=True, height=None, square=False):
+ """Load the specified network.
+
+ Args:
+ device (device): the torch device used
+ model_path (str): path to saved model
+ model_type (str): the type of the model to be loaded
+ optimize (bool): optimize the model to half-integer on CUDA?
+ height (int): inference encoder image height
+ square (bool): resize to a square resolution?
+
+ Returns:
+ The loaded network, the transform which prepares images as input to the network and the dimensions of the
+ network input
+ """
+ if "openvino" in model_type:
+ from openvino.runtime import Core
+
+ keep_aspect_ratio = not square
+
+ if model_type == "dpt_beit_large_512":
+ model = DPTDepthModel(
+ path=model_path,
+ backbone="beitl16_512",
+ non_negative=True,
+ )
+ net_w, net_h = 512, 512
+ resize_mode = "minimal"
+ normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
+
+ elif model_type == "dpt_beit_large_384":
+ model = DPTDepthModel(
+ path=model_path,
+ backbone="beitl16_384",
+ non_negative=True,
+ )
+ net_w, net_h = 384, 384
+ resize_mode = "minimal"
+ normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
+
+ elif model_type == "dpt_beit_base_384":
+ model = DPTDepthModel(
+ path=model_path,
+ backbone="beitb16_384",
+ non_negative=True,
+ )
+ net_w, net_h = 384, 384
+ resize_mode = "minimal"
+ normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
+
+ elif model_type == "dpt_swin2_large_384":
+ model = DPTDepthModel(
+ path=model_path,
+ backbone="swin2l24_384",
+ non_negative=True,
+ )
+ net_w, net_h = 384, 384
+ keep_aspect_ratio = False
+ resize_mode = "minimal"
+ normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
+
+ elif model_type == "dpt_swin2_base_384":
+ model = DPTDepthModel(
+ path=model_path,
+ backbone="swin2b24_384",
+ non_negative=True,
+ )
+ net_w, net_h = 384, 384
+ keep_aspect_ratio = False
+ resize_mode = "minimal"
+ normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
+
+ elif model_type == "dpt_swin2_tiny_256":
+ model = DPTDepthModel(
+ path=model_path,
+ backbone="swin2t16_256",
+ non_negative=True,
+ )
+ net_w, net_h = 256, 256
+ keep_aspect_ratio = False
+ resize_mode = "minimal"
+ normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
+
+ elif model_type == "dpt_swin_large_384":
+ model = DPTDepthModel(
+ path=model_path,
+ backbone="swinl12_384",
+ non_negative=True,
+ )
+ net_w, net_h = 384, 384
+ keep_aspect_ratio = False
+ resize_mode = "minimal"
+ normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
+
+ elif model_type == "dpt_next_vit_large_384":
+ model = DPTDepthModel(
+ path=model_path,
+ backbone="next_vit_large_6m",
+ non_negative=True,
+ )
+ net_w, net_h = 384, 384
+ resize_mode = "minimal"
+ normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
+
+ # We change the notation from dpt_levit_224 (MiDaS notation) to levit_384 (timm notation) here, where the 224 refers
+ # to the resolution 224x224 used by LeViT and 384 is the first entry of the embed_dim, see _cfg and model_cfgs of
+ # https://github.com/rwightman/pytorch-image-models/blob/main/timm/models/levit.py
+ # (commit id: 927f031293a30afb940fff0bee34b85d9c059b0e)
+ elif model_type == "dpt_levit_224":
+ model = DPTDepthModel(
+ path=model_path,
+ backbone="levit_384",
+ non_negative=True,
+ head_features_1=64,
+ head_features_2=8,
+ )
+ net_w, net_h = 224, 224
+ keep_aspect_ratio = False
+ resize_mode = "minimal"
+ normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
+
+ elif model_type == "dpt_large_384":
+ model = DPTDepthModel(
+ path=model_path,
+ backbone="vitl16_384",
+ non_negative=True,
+ )
+ net_w, net_h = 384, 384
+ resize_mode = "minimal"
+ normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
+
+ elif model_type == "dpt_hybrid_384":
+ model = DPTDepthModel(
+ path=model_path,
+ backbone="vitb_rn50_384",
+ non_negative=True,
+ )
+ net_w, net_h = 384, 384
+ resize_mode = "minimal"
+ normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
+
+ elif model_type == "midas_v21_384":
+ model = MidasNet(model_path, non_negative=True)
+ net_w, net_h = 384, 384
+ resize_mode = "upper_bound"
+ normalization = NormalizeImage(
+ mean=[0.485, 0.456, 0.406], std=[0.229, 0.224, 0.225]
+ )
+
+ elif model_type == "midas_v21_small_256":
+ model = MidasNet_small(model_path, features=64, backbone="efficientnet_lite3", exportable=True,
+ non_negative=True, blocks={'expand': True})
+ net_w, net_h = 256, 256
+ resize_mode = "upper_bound"
+ normalization = NormalizeImage(
+ mean=[0.485, 0.456, 0.406], std=[0.229, 0.224, 0.225]
+ )
+
+ elif model_type == "openvino_midas_v21_small_256":
+ ie = Core()
+ uncompiled_model = ie.read_model(model=model_path)
+ model = ie.compile_model(uncompiled_model, "CPU")
+ net_w, net_h = 256, 256
+ resize_mode = "upper_bound"
+ normalization = NormalizeImage(
+ mean=[0.485, 0.456, 0.406], std=[0.229, 0.224, 0.225]
+ )
+
+ else:
+ print(f"model_type '{model_type}' not implemented, use: --model_type large")
+ assert False
+
+ if not "openvino" in model_type:
+ print("Model loaded, number of parameters = {:.0f}M".format(sum(p.numel() for p in model.parameters()) / 1e6))
+ else:
+ print("Model loaded, optimized with OpenVINO")
+
+ if "openvino" in model_type:
+ keep_aspect_ratio = False
+
+ if height is not None:
+ net_w, net_h = height, height
+
+ transform = Compose(
+ [
+ Resize(
+ net_w,
+ net_h,
+ resize_target=None,
+ keep_aspect_ratio=keep_aspect_ratio,
+ ensure_multiple_of=32,
+ resize_method=resize_mode,
+ image_interpolation_method=cv2.INTER_CUBIC,
+ ),
+ normalization,
+ PrepareForNet(),
+ ]
+ )
+
+ if not "openvino" in model_type:
+ model.eval()
+
+ if optimize and (device == torch.device("cuda")):
+ if not "openvino" in model_type:
+ model = model.to(memory_format=torch.channels_last)
+ model = model.half()
+ else:
+ print("Error: OpenVINO models are already optimized. No optimization to half-float possible.")
+ exit()
+
+ if not "openvino" in model_type:
+ model.to(device)
+
+ return model, transform, net_w, net_h
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/transforms.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/transforms.py
new file mode 100644
index 0000000000000000000000000000000000000000..37d68afcebf67defadd7dfb2ff5494f257876575
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/midas/transforms.py
@@ -0,0 +1,234 @@
+import numpy as np
+import cv2
+import math
+
+
+def apply_min_size(sample, size, image_interpolation_method=cv2.INTER_AREA):
+ """Rezise the sample to ensure the given size. Keeps aspect ratio.
+
+ Args:
+ sample (dict): sample
+ size (tuple): image size
+
+ Returns:
+ tuple: new size
+ """
+ shape = list(sample["disparity"].shape)
+
+ if shape[0] >= size[0] and shape[1] >= size[1]:
+ return sample
+
+ scale = [0, 0]
+ scale[0] = size[0] / shape[0]
+ scale[1] = size[1] / shape[1]
+
+ scale = max(scale)
+
+ shape[0] = math.ceil(scale * shape[0])
+ shape[1] = math.ceil(scale * shape[1])
+
+ # resize
+ sample["image"] = cv2.resize(
+ sample["image"], tuple(shape[::-1]), interpolation=image_interpolation_method
+ )
+
+ sample["disparity"] = cv2.resize(
+ sample["disparity"], tuple(shape[::-1]), interpolation=cv2.INTER_NEAREST
+ )
+ sample["mask"] = cv2.resize(
+ sample["mask"].astype(np.float32),
+ tuple(shape[::-1]),
+ interpolation=cv2.INTER_NEAREST,
+ )
+ sample["mask"] = sample["mask"].astype(bool)
+
+ return tuple(shape)
+
+
+class Resize(object):
+ """Resize sample to given size (width, height).
+ """
+
+ def __init__(
+ self,
+ width,
+ height,
+ resize_target=True,
+ keep_aspect_ratio=False,
+ ensure_multiple_of=1,
+ resize_method="lower_bound",
+ image_interpolation_method=cv2.INTER_AREA,
+ ):
+ """Init.
+
+ Args:
+ width (int): desired output width
+ height (int): desired output height
+ resize_target (bool, optional):
+ True: Resize the full sample (image, mask, target).
+ False: Resize image only.
+ Defaults to True.
+ keep_aspect_ratio (bool, optional):
+ True: Keep the aspect ratio of the input sample.
+ Output sample might not have the given width and height, and
+ resize behaviour depends on the parameter 'resize_method'.
+ Defaults to False.
+ ensure_multiple_of (int, optional):
+ Output width and height is constrained to be multiple of this parameter.
+ Defaults to 1.
+ resize_method (str, optional):
+ "lower_bound": Output will be at least as large as the given size.
+ "upper_bound": Output will be at max as large as the given size. (Output size might be smaller than given size.)
+ "minimal": Scale as least as possible. (Output size might be smaller than given size.)
+ Defaults to "lower_bound".
+ """
+ self.__width = width
+ self.__height = height
+
+ self.__resize_target = resize_target
+ self.__keep_aspect_ratio = keep_aspect_ratio
+ self.__multiple_of = ensure_multiple_of
+ self.__resize_method = resize_method
+ self.__image_interpolation_method = image_interpolation_method
+
+ def constrain_to_multiple_of(self, x, min_val=0, max_val=None):
+ y = (np.round(x / self.__multiple_of) * self.__multiple_of).astype(int)
+
+ if max_val is not None and y > max_val:
+ y = (np.floor(x / self.__multiple_of) * self.__multiple_of).astype(int)
+
+ if y < min_val:
+ y = (np.ceil(x / self.__multiple_of) * self.__multiple_of).astype(int)
+
+ return y
+
+ def get_size(self, width, height):
+ # determine new height and width
+ scale_height = self.__height / height
+ scale_width = self.__width / width
+
+ if self.__keep_aspect_ratio:
+ if self.__resize_method == "lower_bound":
+ # scale such that output size is lower bound
+ if scale_width > scale_height:
+ # fit width
+ scale_height = scale_width
+ else:
+ # fit height
+ scale_width = scale_height
+ elif self.__resize_method == "upper_bound":
+ # scale such that output size is upper bound
+ if scale_width < scale_height:
+ # fit width
+ scale_height = scale_width
+ else:
+ # fit height
+ scale_width = scale_height
+ elif self.__resize_method == "minimal":
+ # scale as least as possbile
+ if abs(1 - scale_width) < abs(1 - scale_height):
+ # fit width
+ scale_height = scale_width
+ else:
+ # fit height
+ scale_width = scale_height
+ else:
+ raise ValueError(
+ f"resize_method {self.__resize_method} not implemented"
+ )
+
+ if self.__resize_method == "lower_bound":
+ new_height = self.constrain_to_multiple_of(
+ scale_height * height, min_val=self.__height
+ )
+ new_width = self.constrain_to_multiple_of(
+ scale_width * width, min_val=self.__width
+ )
+ elif self.__resize_method == "upper_bound":
+ new_height = self.constrain_to_multiple_of(
+ scale_height * height, max_val=self.__height
+ )
+ new_width = self.constrain_to_multiple_of(
+ scale_width * width, max_val=self.__width
+ )
+ elif self.__resize_method == "minimal":
+ new_height = self.constrain_to_multiple_of(scale_height * height)
+ new_width = self.constrain_to_multiple_of(scale_width * width)
+ else:
+ raise ValueError(f"resize_method {self.__resize_method} not implemented")
+
+ return (new_width, new_height)
+
+ def __call__(self, sample):
+ width, height = self.get_size(
+ sample["image"].shape[1], sample["image"].shape[0]
+ )
+
+ # resize sample
+ sample["image"] = cv2.resize(
+ sample["image"],
+ (width, height),
+ interpolation=self.__image_interpolation_method,
+ )
+
+ if self.__resize_target:
+ if "disparity" in sample:
+ sample["disparity"] = cv2.resize(
+ sample["disparity"],
+ (width, height),
+ interpolation=cv2.INTER_NEAREST,
+ )
+
+ if "depth" in sample:
+ sample["depth"] = cv2.resize(
+ sample["depth"], (width, height), interpolation=cv2.INTER_NEAREST
+ )
+
+ sample["mask"] = cv2.resize(
+ sample["mask"].astype(np.float32),
+ (width, height),
+ interpolation=cv2.INTER_NEAREST,
+ )
+ sample["mask"] = sample["mask"].astype(bool)
+
+ return sample
+
+
+class NormalizeImage(object):
+ """Normlize image by given mean and std.
+ """
+
+ def __init__(self, mean, std):
+ self.__mean = mean
+ self.__std = std
+
+ def __call__(self, sample):
+ sample["image"] = (sample["image"] - self.__mean) / self.__std
+
+ return sample
+
+
+class PrepareForNet(object):
+ """Prepare sample for usage as network input.
+ """
+
+ def __init__(self):
+ pass
+
+ def __call__(self, sample):
+ image = np.transpose(sample["image"], (2, 0, 1))
+ sample["image"] = np.ascontiguousarray(image).astype(np.float32)
+
+ if "mask" in sample:
+ sample["mask"] = sample["mask"].astype(np.float32)
+ sample["mask"] = np.ascontiguousarray(sample["mask"])
+
+ if "disparity" in sample:
+ disparity = sample["disparity"].astype(np.float32)
+ sample["disparity"] = np.ascontiguousarray(disparity)
+
+ if "depth" in sample:
+ depth = sample["depth"].astype(np.float32)
+ sample["depth"] = np.ascontiguousarray(depth)
+
+ return sample
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/LICENSE b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/LICENSE
new file mode 100644
index 0000000000000000000000000000000000000000..00ac5912e5fb9d000475d6dd6a0eec15f98b3b70
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/LICENSE
@@ -0,0 +1,21 @@
+MIT License
+
+Copyright (c) 2020 Alexey
+
+Permission is hereby granted, free of charge, to any person obtaining a copy
+of this software and associated documentation files (the "Software"), to deal
+in the Software without restriction, including without limitation the rights
+to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+copies of the Software, and to permit persons to whom the Software is
+furnished to do so, subject to the following conditions:
+
+The above copyright notice and this permission notice shall be included in all
+copies or substantial portions of the Software.
+
+THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+SOFTWARE.
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/README.md b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..ed0c7e8465d69c21928e86996b5222b2d3fbfd5d
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/README.md
@@ -0,0 +1,131 @@
+# MiDaS for ROS1 by using LibTorch in C++
+
+### Requirements
+
+- Ubuntu 17.10 / 18.04 / 20.04, Debian Stretch
+- ROS Melodic for Ubuntu (17.10 / 18.04) / Debian Stretch, ROS Noetic for Ubuntu 20.04
+- C++11
+- LibTorch >= 1.6
+
+## Quick Start with a MiDaS Example
+
+MiDaS is a neural network to compute depth from a single image.
+
+* input from `image_topic`: `sensor_msgs/Image` - `RGB8` image with any shape
+* output to `midas_topic`: `sensor_msgs/Image` - `TYPE_32FC1` inverse relative depth maps in range [0 - 255] with original size and channels=1
+
+### Install Dependecies
+
+* install ROS Melodic for Ubuntu 17.10 / 18.04:
+```bash
+wget https://raw.githubusercontent.com/isl-org/MiDaS/master/ros/additions/install_ros_melodic_ubuntu_17_18.sh
+./install_ros_melodic_ubuntu_17_18.sh
+```
+
+or Noetic for Ubuntu 20.04:
+
+```bash
+wget https://raw.githubusercontent.com/isl-org/MiDaS/master/ros/additions/install_ros_noetic_ubuntu_20.sh
+./install_ros_noetic_ubuntu_20.sh
+```
+
+
+* install LibTorch 1.7 with CUDA 11.0:
+
+On **Jetson (ARM)**:
+```bash
+wget https://nvidia.box.com/shared/static/wa34qwrwtk9njtyarwt5nvo6imenfy26.whl -O torch-1.7.0-cp36-cp36m-linux_aarch64.whl
+sudo apt-get install python3-pip libopenblas-base libopenmpi-dev
+pip3 install Cython
+pip3 install numpy torch-1.7.0-cp36-cp36m-linux_aarch64.whl
+```
+Or compile LibTorch from source: https://github.com/pytorch/pytorch#from-source
+
+On **Linux (x86_64)**:
+```bash
+cd ~/
+wget https://download.pytorch.org/libtorch/cu110/libtorch-cxx11-abi-shared-with-deps-1.7.0%2Bcu110.zip
+unzip libtorch-cxx11-abi-shared-with-deps-1.7.0+cu110.zip
+```
+
+* create symlink for OpenCV:
+
+```bash
+sudo ln -s /usr/include/opencv4 /usr/include/opencv
+```
+
+* download and install MiDaS:
+
+```bash
+source ~/.bashrc
+cd ~/
+mkdir catkin_ws
+cd catkin_ws
+git clone https://github.com/isl-org/MiDaS
+mkdir src
+cp -r MiDaS/ros/* src
+
+chmod +x src/additions/*.sh
+chmod +x src/*.sh
+chmod +x src/midas_cpp/scripts/*.py
+cp src/additions/do_catkin_make.sh ./do_catkin_make.sh
+./do_catkin_make.sh
+./src/additions/downloads.sh
+```
+
+### Usage
+
+* run only `midas` node: `~/catkin_ws/src/launch_midas_cpp.sh`
+
+#### Test
+
+* Test - capture video and show result in the window:
+ * place any `test.mp4` video file to the directory `~/catkin_ws/src/`
+ * run `midas` node: `~/catkin_ws/src/launch_midas_cpp.sh`
+ * run test nodes in another terminal: `cd ~/catkin_ws/src && ./run_talker_listener_test.sh` and wait 30 seconds
+
+ (to use Python 2, run command `sed -i 's/python3/python2/' ~/catkin_ws/src/midas_cpp/scripts/*.py` )
+
+## Mobile version of MiDaS - Monocular Depth Estimation
+
+### Accuracy
+
+* MiDaS v2 small - ResNet50 default-decoder 384x384
+* MiDaS v2.1 small - EfficientNet-Lite3 small-decoder 256x256
+
+**Zero-shot error** (the lower - the better):
+
+| Model | DIW WHDR | Eth3d AbsRel | Sintel AbsRel | Kitti δ>1.25 | NyuDepthV2 δ>1.25 | TUM δ>1.25 |
+|---|---|---|---|---|---|---|
+| MiDaS v2 small 384x384 | **0.1248** | 0.1550 | **0.3300** | **21.81** | 15.73 | 17.00 |
+| MiDaS v2.1 small 256x256 | 0.1344 | **0.1344** | 0.3370 | 29.27 | **13.43** | **14.53** |
+| Relative improvement, % | -8 % | **+13 %** | -2 % | -34 % | **+15 %** | **+15 %** |
+
+None of Train/Valid/Test subsets of datasets (DIW, Eth3d, Sintel, Kitti, NyuDepthV2, TUM) were not involved in Training or Fine Tuning.
+
+### Inference speed (FPS) on nVidia GPU
+
+Inference speed excluding pre and post processing, batch=1, **Frames Per Second** (the higher - the better):
+
+| Model | Jetson Nano, FPS | RTX 2080Ti, FPS |
+|---|---|---|
+| MiDaS v2 small 384x384 | 1.6 | 117 |
+| MiDaS v2.1 small 256x256 | 8.1 | 232 |
+| SpeedUp, X times | **5x** | **2x** |
+
+### Citation
+
+This repository contains code to compute depth from a single image. It accompanies our [paper](https://arxiv.org/abs/1907.01341v3):
+
+>Towards Robust Monocular Depth Estimation: Mixing Datasets for Zero-shot Cross-dataset Transfer
+René Ranftl, Katrin Lasinger, David Hafner, Konrad Schindler, Vladlen Koltun
+
+Please cite our paper if you use this code or any of the models:
+```
+@article{Ranftl2020,
+ author = {Ren\'{e} Ranftl and Katrin Lasinger and David Hafner and Konrad Schindler and Vladlen Koltun},
+ title = {Towards Robust Monocular Depth Estimation: Mixing Datasets for Zero-shot Cross-dataset Transfer},
+ journal = {IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI)},
+ year = {2020},
+}
+```
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/additions/do_catkin_make.sh b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/additions/do_catkin_make.sh
new file mode 100644
index 0000000000000000000000000000000000000000..291354217538efebf3464a77573f17961e81399d
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/additions/do_catkin_make.sh
@@ -0,0 +1,5 @@
+mkdir src
+catkin_make
+source devel/setup.bash
+echo $ROS_PACKAGE_PATH
+chmod +x ./devel/setup.bash
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/additions/downloads.sh b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/additions/downloads.sh
new file mode 100644
index 0000000000000000000000000000000000000000..6d41fb4d621e71075e70d716d060f78a465ce943
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/additions/downloads.sh
@@ -0,0 +1,5 @@
+mkdir ~/.ros
+wget https://github.com/isl-org/MiDaS/releases/download/v2_1/model-small-traced.pt
+cp ./model-small-traced.pt ~/.ros/model-small-traced.pt
+
+
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/additions/install_ros_melodic_ubuntu_17_18.sh b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/additions/install_ros_melodic_ubuntu_17_18.sh
new file mode 100644
index 0000000000000000000000000000000000000000..15630cf4ee85a415d932dc6ed3da7e7da8dad6a9
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/additions/install_ros_melodic_ubuntu_17_18.sh
@@ -0,0 +1,34 @@
+#@title { display-mode: "code" }
+
+#from http://wiki.ros.org/indigo/Installation/Ubuntu
+
+#1.2 Setup sources.list
+sudo sh -c 'echo "deb http://packages.ros.org/ros/ubuntu $(lsb_release -sc) main" > /etc/apt/sources.list.d/ros-latest.list'
+
+# 1.3 Setup keys
+sudo apt-key adv --keyserver 'hkp://keyserver.ubuntu.com:80' --recv-key C1CF6E31E6BADE8868B172B4F42ED6FBAB17C654
+sudo apt-key adv --keyserver 'hkp://ha.pool.sks-keyservers.net:80' --recv-key 421C365BD9FF1F717815A3895523BAEEB01FA116
+
+curl -sSL 'http://keyserver.ubuntu.com/pks/lookup?op=get&search=0xC1CF6E31E6BADE8868B172B4F42ED6FBAB17C654' | sudo apt-key add -
+
+# 1.4 Installation
+sudo apt-get update
+sudo apt-get upgrade
+
+# Desktop-Full Install:
+sudo apt-get install ros-melodic-desktop-full
+
+printf "\nsource /opt/ros/melodic/setup.bash\n" >> ~/.bashrc
+
+# 1.5 Initialize rosdep
+sudo rosdep init
+rosdep update
+
+
+# 1.7 Getting rosinstall (python)
+sudo apt-get install python-rosinstall
+sudo apt-get install python-catkin-tools
+sudo apt-get install python-rospy
+sudo apt-get install python-rosdep
+sudo apt-get install python-roscd
+sudo apt-get install python-pip
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/additions/install_ros_noetic_ubuntu_20.sh b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/additions/install_ros_noetic_ubuntu_20.sh
new file mode 100644
index 0000000000000000000000000000000000000000..4c62e758a8320ed71a60a1b9b591f0dfc21f04f4
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/additions/install_ros_noetic_ubuntu_20.sh
@@ -0,0 +1,33 @@
+#@title { display-mode: "code" }
+
+#from http://wiki.ros.org/indigo/Installation/Ubuntu
+
+#1.2 Setup sources.list
+sudo sh -c 'echo "deb http://packages.ros.org/ros/ubuntu $(lsb_release -sc) main" > /etc/apt/sources.list.d/ros-latest.list'
+
+# 1.3 Setup keys
+sudo apt-key adv --keyserver 'hkp://keyserver.ubuntu.com:80' --recv-key C1CF6E31E6BADE8868B172B4F42ED6FBAB17C654
+
+curl -sSL 'http://keyserver.ubuntu.com/pks/lookup?op=get&search=0xC1CF6E31E6BADE8868B172B4F42ED6FBAB17C654' | sudo apt-key add -
+
+# 1.4 Installation
+sudo apt-get update
+sudo apt-get upgrade
+
+# Desktop-Full Install:
+sudo apt-get install ros-noetic-desktop-full
+
+printf "\nsource /opt/ros/noetic/setup.bash\n" >> ~/.bashrc
+
+# 1.5 Initialize rosdep
+sudo rosdep init
+rosdep update
+
+
+# 1.7 Getting rosinstall (python)
+sudo apt-get install python3-rosinstall
+sudo apt-get install python3-catkin-tools
+sudo apt-get install python3-rospy
+sudo apt-get install python3-rosdep
+sudo apt-get install python3-roscd
+sudo apt-get install python3-pip
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/additions/make_package_cpp.sh b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/additions/make_package_cpp.sh
new file mode 100644
index 0000000000000000000000000000000000000000..82781ac1ecbdde527feb7dc3f5cd7d97a0ea1886
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/additions/make_package_cpp.sh
@@ -0,0 +1,16 @@
+cd ~/catkin_ws/src
+catkin_create_pkg midas_cpp std_msgs roscpp cv_bridge sensor_msgs image_transport
+cd ~/catkin_ws
+catkin_make
+
+chmod +x ~/catkin_ws/devel/setup.bash
+printf "\nsource ~/catkin_ws/devel/setup.bash" >> ~/.bashrc
+source ~/catkin_ws/devel/setup.bash
+
+
+sudo rosdep init
+rosdep update
+#rospack depends1 midas_cpp
+roscd midas_cpp
+#cat package.xml
+#rospack depends midas_cpp
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/launch_midas_cpp.sh b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/launch_midas_cpp.sh
new file mode 100644
index 0000000000000000000000000000000000000000..63e138549417f49173107ccbb1cce40f8fd46532
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/launch_midas_cpp.sh
@@ -0,0 +1,2 @@
+source ~/catkin_ws/devel/setup.bash
+roslaunch midas_cpp midas_cpp.launch model_name:="model-small-traced.pt" input_topic:="image_topic" output_topic:="midas_topic" out_orig_size:="true"
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/CMakeLists.txt b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/CMakeLists.txt
new file mode 100644
index 0000000000000000000000000000000000000000..63ae893bff0e5bb113cfd9a5c24186189dcb8b9a
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/CMakeLists.txt
@@ -0,0 +1,189 @@
+cmake_minimum_required(VERSION 3.0.2)
+project(midas_cpp)
+
+## Compile as C++11, supported in ROS Kinetic and newer
+# add_compile_options(-std=c++11)
+
+## Find catkin macros and libraries
+## if COMPONENTS list like find_package(catkin REQUIRED COMPONENTS xyz)
+## is used, also find other catkin packages
+find_package(catkin REQUIRED COMPONENTS
+ cv_bridge
+ image_transport
+ roscpp
+ rospy
+ sensor_msgs
+ std_msgs
+)
+
+## System dependencies are found with CMake's conventions
+# find_package(Boost REQUIRED COMPONENTS system)
+
+list(APPEND CMAKE_PREFIX_PATH "~/libtorch")
+list(APPEND CMAKE_PREFIX_PATH "/usr/local/lib/python3.6/dist-packages/torch/lib")
+list(APPEND CMAKE_PREFIX_PATH "/usr/local/lib/python2.7/dist-packages/torch/lib")
+
+if(NOT EXISTS "~/libtorch")
+ if (EXISTS "/usr/local/lib/python3.6/dist-packages/torch")
+ include_directories(/usr/local/include)
+ include_directories(/usr/local/lib/python3.6/dist-packages/torch/include/torch/csrc/api/include)
+ include_directories(/usr/local/lib/python3.6/dist-packages/torch/include)
+
+ link_directories(/usr/local/lib)
+ link_directories(/usr/local/lib/python3.6/dist-packages/torch/lib)
+
+ set(CMAKE_PREFIX_PATH /usr/local/lib/python3.6/dist-packages/torch)
+ set(Boost_USE_MULTITHREADED ON)
+ set(Torch_DIR /usr/local/lib/python3.6/dist-packages/torch)
+
+ elseif (EXISTS "/usr/local/lib/python2.7/dist-packages/torch")
+
+ include_directories(/usr/local/include)
+ include_directories(/usr/local/lib/python2.7/dist-packages/torch/include/torch/csrc/api/include)
+ include_directories(/usr/local/lib/python2.7/dist-packages/torch/include)
+
+ link_directories(/usr/local/lib)
+ link_directories(/usr/local/lib/python2.7/dist-packages/torch/lib)
+
+ set(CMAKE_PREFIX_PATH /usr/local/lib/python2.7/dist-packages/torch)
+ set(Boost_USE_MULTITHREADED ON)
+ set(Torch_DIR /usr/local/lib/python2.7/dist-packages/torch)
+ endif()
+endif()
+
+
+
+find_package(Torch REQUIRED)
+find_package(OpenCV REQUIRED)
+include_directories( ${OpenCV_INCLUDE_DIRS} )
+
+add_executable(midas_cpp src/main.cpp)
+target_link_libraries(midas_cpp "${TORCH_LIBRARIES}" "${OpenCV_LIBS} ${catkin_LIBRARIES}")
+set_property(TARGET midas_cpp PROPERTY CXX_STANDARD 14)
+
+
+
+###################################
+## catkin specific configuration ##
+###################################
+## The catkin_package macro generates cmake config files for your package
+## Declare things to be passed to dependent projects
+## INCLUDE_DIRS: uncomment this if your package contains header files
+## LIBRARIES: libraries you create in this project that dependent projects also need
+## CATKIN_DEPENDS: catkin_packages dependent projects also need
+## DEPENDS: system dependencies of this project that dependent projects also need
+catkin_package(
+# INCLUDE_DIRS include
+# LIBRARIES midas_cpp
+# CATKIN_DEPENDS cv_bridge image_transport roscpp sensor_msgs std_msgs
+# DEPENDS system_lib
+)
+
+###########
+## Build ##
+###########
+
+## Specify additional locations of header files
+## Your package locations should be listed before other locations
+include_directories(
+# include
+ ${catkin_INCLUDE_DIRS}
+)
+
+## Declare a C++ library
+# add_library(${PROJECT_NAME}
+# src/${PROJECT_NAME}/midas_cpp.cpp
+# )
+
+## Add cmake target dependencies of the library
+## as an example, code may need to be generated before libraries
+## either from message generation or dynamic reconfigure
+# add_dependencies(${PROJECT_NAME} ${${PROJECT_NAME}_EXPORTED_TARGETS} ${catkin_EXPORTED_TARGETS})
+
+## Declare a C++ executable
+## With catkin_make all packages are built within a single CMake context
+## The recommended prefix ensures that target names across packages don't collide
+# add_executable(${PROJECT_NAME}_node src/midas_cpp_node.cpp)
+
+## Rename C++ executable without prefix
+## The above recommended prefix causes long target names, the following renames the
+## target back to the shorter version for ease of user use
+## e.g. "rosrun someones_pkg node" instead of "rosrun someones_pkg someones_pkg_node"
+# set_target_properties(${PROJECT_NAME}_node PROPERTIES OUTPUT_NAME node PREFIX "")
+
+## Add cmake target dependencies of the executable
+## same as for the library above
+# add_dependencies(${PROJECT_NAME}_node ${${PROJECT_NAME}_EXPORTED_TARGETS} ${catkin_EXPORTED_TARGETS})
+
+## Specify libraries to link a library or executable target against
+# target_link_libraries(${PROJECT_NAME}_node
+# ${catkin_LIBRARIES}
+# )
+
+#############
+## Install ##
+#############
+
+# all install targets should use catkin DESTINATION variables
+# See http://ros.org/doc/api/catkin/html/adv_user_guide/variables.html
+
+## Mark executable scripts (Python etc.) for installation
+## in contrast to setup.py, you can choose the destination
+# catkin_install_python(PROGRAMS
+# scripts/my_python_script
+# DESTINATION ${CATKIN_PACKAGE_BIN_DESTINATION}
+# )
+
+## Mark executables for installation
+## See http://docs.ros.org/melodic/api/catkin/html/howto/format1/building_executables.html
+# install(TARGETS ${PROJECT_NAME}_node
+# RUNTIME DESTINATION ${CATKIN_PACKAGE_BIN_DESTINATION}
+# )
+
+## Mark libraries for installation
+## See http://docs.ros.org/melodic/api/catkin/html/howto/format1/building_libraries.html
+# install(TARGETS ${PROJECT_NAME}
+# ARCHIVE DESTINATION ${CATKIN_PACKAGE_LIB_DESTINATION}
+# LIBRARY DESTINATION ${CATKIN_PACKAGE_LIB_DESTINATION}
+# RUNTIME DESTINATION ${CATKIN_GLOBAL_BIN_DESTINATION}
+# )
+
+## Mark cpp header files for installation
+# install(DIRECTORY include/${PROJECT_NAME}/
+# DESTINATION ${CATKIN_PACKAGE_INCLUDE_DESTINATION}
+# FILES_MATCHING PATTERN "*.h"
+# PATTERN ".svn" EXCLUDE
+# )
+
+## Mark other files for installation (e.g. launch and bag files, etc.)
+# install(FILES
+# # myfile1
+# # myfile2
+# DESTINATION ${CATKIN_PACKAGE_SHARE_DESTINATION}
+# )
+
+#############
+## Testing ##
+#############
+
+## Add gtest based cpp test target and link libraries
+# catkin_add_gtest(${PROJECT_NAME}-test test/test_midas_cpp.cpp)
+# if(TARGET ${PROJECT_NAME}-test)
+# target_link_libraries(${PROJECT_NAME}-test ${PROJECT_NAME})
+# endif()
+
+## Add folders to be run by python nosetests
+# catkin_add_nosetests(test)
+
+install(TARGETS ${PROJECT_NAME}
+ ARCHIVE DESTINATION ${CATKIN_PACKAGE_LIB_DESTINATION}
+ LIBRARY DESTINATION ${CATKIN_PACKAGE_LIB_DESTINATION}
+ RUNTIME DESTINATION ${CATKIN_PACKAGE_BIN_DESTINATION}
+)
+
+add_custom_command(
+ TARGET midas_cpp POST_BUILD
+ COMMAND ${CMAKE_COMMAND} -E copy
+ ${CMAKE_CURRENT_BINARY_DIR}/midas_cpp
+ ${CMAKE_SOURCE_DIR}/midas_cpp
+)
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/launch/midas_cpp.launch b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/launch/midas_cpp.launch
new file mode 100644
index 0000000000000000000000000000000000000000..326b7dfb19e928a9199a633c45e630dd2ef22bc0
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/launch/midas_cpp.launch
@@ -0,0 +1,19 @@
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/launch/midas_talker_listener.launch b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/launch/midas_talker_listener.launch
new file mode 100644
index 0000000000000000000000000000000000000000..88d10c59b53b7031ef5c35424317b86991f2af8a
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/launch/midas_talker_listener.launch
@@ -0,0 +1,23 @@
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/package.xml b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/package.xml
new file mode 100644
index 0000000000000000000000000000000000000000..6a0d109e65dab0b7652bba809074ae012a175b7e
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/package.xml
@@ -0,0 +1,77 @@
+
+
+ midas_cpp
+ 0.1.0
+ The midas_cpp package
+
+ Alexey Bochkovskiy
+ MIT
+ https://github.com/isl-org/MiDaS/tree/master/ros
+
+
+
+
+
+
+ TODO
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+ catkin
+ cv_bridge
+ image_transport
+ roscpp
+ rospy
+ sensor_msgs
+ std_msgs
+ cv_bridge
+ image_transport
+ roscpp
+ rospy
+ sensor_msgs
+ std_msgs
+ cv_bridge
+ image_transport
+ roscpp
+ rospy
+ sensor_msgs
+ std_msgs
+
+
+
+
+
+
+
+
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/scripts/listener.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/scripts/listener.py
new file mode 100644
index 0000000000000000000000000000000000000000..7ad3f437dedd3759dc6d288d18499c93581bca26
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/scripts/listener.py
@@ -0,0 +1,61 @@
+#!/usr/bin/env python3
+from __future__ import print_function
+
+import roslib
+#roslib.load_manifest('my_package')
+import sys
+import rospy
+import cv2
+import numpy as np
+from std_msgs.msg import String
+from sensor_msgs.msg import Image
+from cv_bridge import CvBridge, CvBridgeError
+
+class video_show:
+
+ def __init__(self):
+ self.show_output = rospy.get_param('~show_output', True)
+ self.save_output = rospy.get_param('~save_output', False)
+ self.output_video_file = rospy.get_param('~output_video_file','result.mp4')
+ # rospy.loginfo(f"Listener - params: show_output={self.show_output}, save_output={self.save_output}, output_video_file={self.output_video_file}")
+
+ self.bridge = CvBridge()
+ self.image_sub = rospy.Subscriber("midas_topic", Image, self.callback)
+
+ def callback(self, data):
+ try:
+ cv_image = self.bridge.imgmsg_to_cv2(data)
+ except CvBridgeError as e:
+ print(e)
+ return
+
+ if cv_image.size == 0:
+ return
+
+ rospy.loginfo("Listener: Received new frame")
+ cv_image = cv_image.astype("uint8")
+
+ if self.show_output==True:
+ cv2.imshow("video_show", cv_image)
+ cv2.waitKey(10)
+
+ if self.save_output==True:
+ if self.video_writer_init==False:
+ fourcc = cv2.VideoWriter_fourcc(*'XVID')
+ self.out = cv2.VideoWriter(self.output_video_file, fourcc, 25, (cv_image.shape[1], cv_image.shape[0]))
+
+ self.out.write(cv_image)
+
+
+
+def main(args):
+ rospy.init_node('listener', anonymous=True)
+ ic = video_show()
+ try:
+ rospy.spin()
+ except KeyboardInterrupt:
+ print("Shutting down")
+ cv2.destroyAllWindows()
+
+if __name__ == '__main__':
+ main(sys.argv)
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/scripts/listener_original.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/scripts/listener_original.py
new file mode 100644
index 0000000000000000000000000000000000000000..59ec1be8f8c35559ca8938fb99ac81a14a494a4a
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/scripts/listener_original.py
@@ -0,0 +1,61 @@
+#!/usr/bin/env python3
+from __future__ import print_function
+
+import roslib
+#roslib.load_manifest('my_package')
+import sys
+import rospy
+import cv2
+import numpy as np
+from std_msgs.msg import String
+from sensor_msgs.msg import Image
+from cv_bridge import CvBridge, CvBridgeError
+
+class video_show:
+
+ def __init__(self):
+ self.show_output = rospy.get_param('~show_output', True)
+ self.save_output = rospy.get_param('~save_output', False)
+ self.output_video_file = rospy.get_param('~output_video_file','result.mp4')
+ # rospy.loginfo(f"Listener original - params: show_output={self.show_output}, save_output={self.save_output}, output_video_file={self.output_video_file}")
+
+ self.bridge = CvBridge()
+ self.image_sub = rospy.Subscriber("image_topic", Image, self.callback)
+
+ def callback(self, data):
+ try:
+ cv_image = self.bridge.imgmsg_to_cv2(data)
+ except CvBridgeError as e:
+ print(e)
+ return
+
+ if cv_image.size == 0:
+ return
+
+ rospy.loginfo("Listener_original: Received new frame")
+ cv_image = cv_image.astype("uint8")
+
+ if self.show_output==True:
+ cv2.imshow("video_show_orig", cv_image)
+ cv2.waitKey(10)
+
+ if self.save_output==True:
+ if self.video_writer_init==False:
+ fourcc = cv2.VideoWriter_fourcc(*'XVID')
+ self.out = cv2.VideoWriter(self.output_video_file, fourcc, 25, (cv_image.shape[1], cv_image.shape[0]))
+
+ self.out.write(cv_image)
+
+
+
+def main(args):
+ rospy.init_node('listener_original', anonymous=True)
+ ic = video_show()
+ try:
+ rospy.spin()
+ except KeyboardInterrupt:
+ print("Shutting down")
+ cv2.destroyAllWindows()
+
+if __name__ == '__main__':
+ main(sys.argv)
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/scripts/talker.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/scripts/talker.py
new file mode 100644
index 0000000000000000000000000000000000000000..ddbeabf25ad41f5a765bdfa6cfaa3102331d1d7c
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/scripts/talker.py
@@ -0,0 +1,53 @@
+#!/usr/bin/env python3
+
+
+import roslib
+#roslib.load_manifest('my_package')
+import sys
+import rospy
+import cv2
+from std_msgs.msg import String
+from sensor_msgs.msg import Image
+from cv_bridge import CvBridge, CvBridgeError
+
+
+def talker():
+ rospy.init_node('talker', anonymous=True)
+
+ use_camera = rospy.get_param('~use_camera', False)
+ input_video_file = rospy.get_param('~input_video_file','test.mp4')
+ # rospy.loginfo(f"Talker - params: use_camera={use_camera}, input_video_file={input_video_file}")
+
+ # rospy.loginfo("Talker: Trying to open a video stream")
+ if use_camera == True:
+ cap = cv2.VideoCapture(0)
+ else:
+ cap = cv2.VideoCapture(input_video_file)
+
+ pub = rospy.Publisher('image_topic', Image, queue_size=1)
+ rate = rospy.Rate(30) # 30hz
+ bridge = CvBridge()
+
+ while not rospy.is_shutdown():
+ ret, cv_image = cap.read()
+ if ret==False:
+ print("Talker: Video is over")
+ rospy.loginfo("Video is over")
+ return
+
+ try:
+ image = bridge.cv2_to_imgmsg(cv_image, "bgr8")
+ except CvBridgeError as e:
+ rospy.logerr("Talker: cv2image conversion failed: ", e)
+ print(e)
+ continue
+
+ rospy.loginfo("Talker: Publishing frame")
+ pub.publish(image)
+ rate.sleep()
+
+if __name__ == '__main__':
+ try:
+ talker()
+ except rospy.ROSInterruptException:
+ pass
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/src/main.cpp b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/src/main.cpp
new file mode 100644
index 0000000000000000000000000000000000000000..5ecc0c8a3232b933337c7512dfd48b4b4d01b157
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/midas_cpp/src/main.cpp
@@ -0,0 +1,285 @@
+#include
+#include
+#include
+#include
+
+#include
+
+#include // One-stop header.
+
+#include
+#include
+#include
+#include
+
+#include
+#include
+
+// includes for OpenCV >= 3.x
+#ifndef CV_VERSION_EPOCH
+#include
+#include
+#include
+#endif
+
+// OpenCV includes for OpenCV 2.x
+#ifdef CV_VERSION_EPOCH
+#include
+#include
+#include
+#include
+#endif
+
+static const std::string OPENCV_WINDOW = "Image window";
+
+class Midas
+{
+ ros::NodeHandle nh_;
+ image_transport::ImageTransport it_;
+ image_transport::Subscriber image_sub_;
+ image_transport::Publisher image_pub_;
+
+ torch::jit::script::Module module;
+ torch::Device device;
+
+ auto ToTensor(cv::Mat img, bool show_output = false, bool unsqueeze = false, int unsqueeze_dim = 0)
+ {
+ //std::cout << "image shape: " << img.size() << std::endl;
+ at::Tensor tensor_image = torch::from_blob(img.data, { img.rows, img.cols, 3 }, at::kByte);
+
+ if (unsqueeze)
+ {
+ tensor_image.unsqueeze_(unsqueeze_dim);
+ //std::cout << "tensors new shape: " << tensor_image.sizes() << std::endl;
+ }
+
+ if (show_output)
+ {
+ std::cout << tensor_image.slice(2, 0, 1) << std::endl;
+ }
+ //std::cout << "tenor shape: " << tensor_image.sizes() << std::endl;
+ return tensor_image;
+ }
+
+ auto ToInput(at::Tensor tensor_image)
+ {
+ // Create a vector of inputs.
+ return std::vector{tensor_image};
+ }
+
+ auto ToCvImage(at::Tensor tensor, int cv_type = CV_8UC3)
+ {
+ int width = tensor.sizes()[0];
+ int height = tensor.sizes()[1];
+ try
+ {
+ cv::Mat output_mat;
+ if (cv_type == CV_8UC4 || cv_type == CV_8UC3 || cv_type == CV_8UC2 || cv_type == CV_8UC1) {
+ cv::Mat cv_image(cv::Size{ height, width }, cv_type, tensor.data_ptr());
+ output_mat = cv_image;
+ }
+ else if (cv_type == CV_32FC4 || cv_type == CV_32FC3 || cv_type == CV_32FC2 || cv_type == CV_32FC1) {
+ cv::Mat cv_image(cv::Size{ height, width }, cv_type, tensor.data_ptr());
+ output_mat = cv_image;
+ }
+ else if (cv_type == CV_64FC4 || cv_type == CV_64FC3 || cv_type == CV_64FC2 || cv_type == CV_64FC1) {
+ cv::Mat cv_image(cv::Size{ height, width }, cv_type, tensor.data_ptr());
+ output_mat = cv_image;
+ }
+
+ //show_image(output_mat, "converted image from tensor");
+ return output_mat.clone();
+ }
+ catch (const c10::Error& e)
+ {
+ std::cout << "an error has occured : " << e.msg() << std::endl;
+ }
+ return cv::Mat(height, width, CV_8UC3);
+ }
+
+ std::string input_topic, output_topic, model_name;
+ bool out_orig_size;
+ int net_width, net_height;
+ torch::NoGradGuard guard;
+ at::Tensor mean, std;
+ at::Tensor output, tensor;
+
+public:
+ Midas()
+ : nh_(), it_(nh_), device(torch::Device(torch::kCPU))
+ {
+ ros::param::param("~input_topic", input_topic, "image_topic");
+ ros::param::param("~output_topic", output_topic, "midas_topic");
+ ros::param::param("~model_name", model_name, "model-small-traced.pt");
+ ros::param::param("~out_orig_size", out_orig_size, true);
+ ros::param::param("~net_width", net_width, 256);
+ ros::param::param("~net_height", net_height, 256);
+
+ std::cout << ", input_topic = " << input_topic <<
+ ", output_topic = " << output_topic <<
+ ", model_name = " << model_name <<
+ ", out_orig_size = " << out_orig_size <<
+ ", net_width = " << net_width <<
+ ", net_height = " << net_height <<
+ std::endl;
+
+ // Subscrive to input video feed and publish output video feed
+ image_sub_ = it_.subscribe(input_topic, 1, &Midas::imageCb, this);
+ image_pub_ = it_.advertise(output_topic, 1);
+
+ std::cout << "Try to load torchscript model \n";
+
+ try {
+ // Deserialize the ScriptModule from a file using torch::jit::load().
+ module = torch::jit::load(model_name);
+ }
+ catch (const c10::Error& e) {
+ std::cerr << "error loading the model\n";
+ exit(0);
+ }
+
+ std::cout << "ok\n";
+
+ try {
+ module.eval();
+ torch::jit::getProfilingMode() = false;
+ torch::jit::setGraphExecutorOptimize(true);
+
+ mean = torch::tensor({ 0.485, 0.456, 0.406 });
+ std = torch::tensor({ 0.229, 0.224, 0.225 });
+
+ if (torch::hasCUDA()) {
+ std::cout << "cuda is available" << std::endl;
+ at::globalContext().setBenchmarkCuDNN(true);
+ device = torch::Device(torch::kCUDA);
+ module.to(device);
+ mean = mean.to(device);
+ std = std.to(device);
+ }
+ }
+ catch (const c10::Error& e)
+ {
+ std::cerr << " module initialization: " << e.msg() << std::endl;
+ }
+ }
+
+ ~Midas()
+ {
+ }
+
+ void imageCb(const sensor_msgs::ImageConstPtr& msg)
+ {
+ cv_bridge::CvImagePtr cv_ptr;
+ try
+ {
+ // sensor_msgs::Image to cv::Mat
+ cv_ptr = cv_bridge::toCvCopy(msg, sensor_msgs::image_encodings::RGB8);
+ }
+ catch (cv_bridge::Exception& e)
+ {
+ ROS_ERROR("cv_bridge exception: %s", e.what());
+ return;
+ }
+
+ // pre-processing
+ auto tensor_cpu = ToTensor(cv_ptr->image); // OpenCV-image -> Libtorch-tensor
+
+ try {
+ tensor = tensor_cpu.to(device); // move to device (CPU or GPU)
+
+ tensor = tensor.toType(c10::kFloat);
+ tensor = tensor.permute({ 2, 0, 1 }); // HWC -> CHW
+ tensor = tensor.unsqueeze(0);
+ tensor = at::upsample_bilinear2d(tensor, { net_height, net_width }, true); // resize
+ tensor = tensor.squeeze(0);
+ tensor = tensor.permute({ 1, 2, 0 }); // CHW -> HWC
+
+ tensor = tensor.div(255).sub(mean).div(std); // normalization
+ tensor = tensor.permute({ 2, 0, 1 }); // HWC -> CHW
+ tensor.unsqueeze_(0); // CHW -> NCHW
+ }
+ catch (const c10::Error& e)
+ {
+ std::cerr << " pre-processing exception: " << e.msg() << std::endl;
+ return;
+ }
+
+ auto input_to_net = ToInput(tensor); // input to the network
+
+ // inference
+ output;
+ try {
+ output = module.forward(input_to_net).toTensor(); // run inference
+ }
+ catch (const c10::Error& e)
+ {
+ std::cerr << " module.forward() exception: " << e.msg() << std::endl;
+ return;
+ }
+
+ output = output.detach().to(torch::kF32);
+
+ // move to CPU temporary
+ at::Tensor output_tmp = output;
+ output_tmp = output_tmp.to(torch::kCPU);
+
+ // normalization
+ float min_val = std::numeric_limits::max();
+ float max_val = std::numeric_limits::min();
+
+ for (int i = 0; i < net_width * net_height; ++i) {
+ float val = output_tmp.data_ptr()[i];
+ if (min_val > val) min_val = val;
+ if (max_val < val) max_val = val;
+ }
+ float range_val = max_val - min_val;
+
+ output = output.sub(min_val).div(range_val).mul(255.0F).clamp(0, 255).to(torch::kF32); // .to(torch::kU8);
+
+ // resize to the original size if required
+ if (out_orig_size) {
+ try {
+ output = at::upsample_bilinear2d(output.unsqueeze(0), { cv_ptr->image.size().height, cv_ptr->image.size().width }, true);
+ output = output.squeeze(0);
+ }
+ catch (const c10::Error& e)
+ {
+ std::cout << " upsample_bilinear2d() exception: " << e.msg() << std::endl;
+ return;
+ }
+ }
+ output = output.permute({ 1, 2, 0 }).to(torch::kCPU);
+
+ int cv_type = CV_32FC1; // CV_8UC1;
+ auto cv_img = ToCvImage(output, cv_type);
+
+ sensor_msgs::Image img_msg;
+
+ try {
+ // cv::Mat -> sensor_msgs::Image
+ std_msgs::Header header; // empty header
+ header.seq = 0; // user defined counter
+ header.stamp = ros::Time::now();// time
+ //cv_bridge::CvImage img_bridge = cv_bridge::CvImage(header, sensor_msgs::image_encodings::MONO8, cv_img);
+ cv_bridge::CvImage img_bridge = cv_bridge::CvImage(header, sensor_msgs::image_encodings::TYPE_32FC1, cv_img);
+
+ img_bridge.toImageMsg(img_msg); // cv_bridge -> sensor_msgs::Image
+ }
+ catch (cv_bridge::Exception& e)
+ {
+ ROS_ERROR("cv_bridge exception: %s", e.what());
+ return;
+ }
+
+ // Output modified video stream
+ image_pub_.publish(img_msg);
+ }
+};
+
+int main(int argc, char** argv)
+{
+ ros::init(argc, argv, "midas", ros::init_options::AnonymousName);
+ Midas ic;
+ ros::spin();
+ return 0;
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/run_talker_listener_test.sh b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/run_talker_listener_test.sh
new file mode 100644
index 0000000000000000000000000000000000000000..181447a83afc9c273ab910cb7e71526b99069e9f
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/ros/run_talker_listener_test.sh
@@ -0,0 +1,16 @@
+# place any test.mp4 file near with this file
+
+# roscore
+# rosnode kill -a
+
+source ~/catkin_ws/devel/setup.bash
+
+roscore &
+P1=$!
+rosrun midas_cpp talker.py &
+P2=$!
+rosrun midas_cpp listener_original.py &
+P3=$!
+rosrun midas_cpp listener.py &
+P4=$!
+wait $P1 $P2 $P3 $P4
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/run.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/run.py
new file mode 100644
index 0000000000000000000000000000000000000000..55a3b65bb749954aa94602544ce2007bd5cb9145
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/run.py
@@ -0,0 +1,279 @@
+"""Compute depth maps for images in the input folder.
+"""
+import os
+import glob
+import torch
+import utils
+import cv2
+import argparse
+import time
+
+import numpy as np
+
+from imutils.video import VideoStream
+from midas.model_loader import default_models, load_model
+
+from modules import devices
+
+first_execution = True
+def process(device, model, model_type, image, input_size, target_size, optimize, use_camera):
+ """
+ Run the inference and interpolate.
+
+ Args:
+ device (torch.device): the torch device used
+ model: the model used for inference
+ model_type: the type of the model
+ image: the image fed into the neural network
+ input_size: the size (width, height) of the neural network input (for OpenVINO)
+ target_size: the size (width, height) the neural network output is interpolated to
+ optimize: optimize the model to half-floats on CUDA?
+ use_camera: is the camera used?
+
+ Returns:
+ the prediction
+ """
+ global first_execution
+
+ if "openvino" in model_type:
+ if first_execution or not use_camera:
+ print(f" Input resized to {input_size[0]}x{input_size[1]} before entering the encoder")
+ first_execution = False
+
+ sample = [np.reshape(image, (1, 3, *input_size))]
+ prediction = model(sample)[model.output(0)][0]
+ prediction = cv2.resize(prediction, dsize=target_size,
+ interpolation=cv2.INTER_CUBIC)
+ else:
+ sample = torch.from_numpy(image).to(device).unsqueeze(0)
+
+ if optimize and device == torch.device("cuda"):
+ if first_execution:
+ print(" Optimization to half-floats activated. Use with caution, because models like Swin require\n"
+ " float precision to work properly and may yield non-finite depth values to some extent for\n"
+ " half-floats.")
+ sample = sample.to(memory_format=torch.channels_last)
+ sample = sample.half()
+
+ if first_execution or not use_camera:
+ height, width = sample.shape[2:]
+ print(f" Input resized to {width}x{height} before entering the encoder")
+ first_execution = False
+
+ prediction = model.forward(sample)
+ prediction = (
+ torch.nn.functional.interpolate(
+ prediction.unsqueeze(1),
+ size=target_size[::-1],
+ mode="bicubic",
+ align_corners=False,
+ )
+ .squeeze()
+ .cpu()
+ .numpy()
+ )
+
+ return prediction
+
+
+def create_side_by_side(image, depth, grayscale):
+ """
+ Take an RGB image and depth map and place them side by side. This includes a proper normalization of the depth map
+ for better visibility.
+
+ Args:
+ image: the RGB image
+ depth: the depth map
+ grayscale: use a grayscale colormap?
+
+ Returns:
+ the image and depth map place side by side
+ """
+ depth_min = depth.min()
+ depth_max = depth.max()
+ normalized_depth = 255 * (depth - depth_min) / (depth_max - depth_min)
+ normalized_depth *= 3
+
+ right_side = np.repeat(np.expand_dims(normalized_depth, 2), 3, axis=2) / 3
+ if not grayscale:
+ right_side = cv2.applyColorMap(np.uint8(right_side), cv2.COLORMAP_INFERNO)
+
+ if image is None:
+ return right_side
+ else:
+ return np.concatenate((image, right_side), axis=1)
+
+
+def run(input_path, output_path, model_path, model_type="dpt_beit_large_512", optimize=False, side=False, height=None,
+ square=False, grayscale=False):
+ """Run MonoDepthNN to compute depth maps.
+
+ Args:
+ input_path (str): path to input folder
+ output_path (str): path to output folder
+ model_path (str): path to saved model
+ model_type (str): the model type
+ optimize (bool): optimize the model to half-floats on CUDA?
+ side (bool): RGB and depth side by side in output images?
+ height (int): inference encoder image height
+ square (bool): resize to a square resolution?
+ grayscale (bool): use a grayscale colormap?
+ """
+ print("Initialize")
+
+ # select device
+ device = devices.get_device_for("controlnet") if torch.cuda.is_available() else torch.device("cpu")
+ print("Device: %s" % device)
+
+ model, transform, net_w, net_h = load_model(device, model_path, model_type, optimize, height, square)
+
+ # get input
+ if input_path is not None:
+ image_names = glob.glob(os.path.join(input_path, "*"))
+ num_images = len(image_names)
+ else:
+ print("No input path specified. Grabbing images from camera.")
+
+ # create output folder
+ if output_path is not None:
+ os.makedirs(output_path, exist_ok=True)
+
+ print("Start processing")
+
+ if input_path is not None:
+ if output_path is None:
+ print("Warning: No output path specified. Images will be processed but not shown or stored anywhere.")
+ for index, image_name in enumerate(image_names):
+
+ print(" Processing {} ({}/{})".format(image_name, index + 1, num_images))
+
+ # input
+ original_image_rgb = utils.read_image(image_name) # in [0, 1]
+ image = transform({"image": original_image_rgb})["image"]
+
+ # compute
+ with torch.no_grad():
+ prediction = process(device, model, model_type, image, (net_w, net_h), original_image_rgb.shape[1::-1],
+ optimize, False)
+
+ # output
+ if output_path is not None:
+ filename = os.path.join(
+ output_path, os.path.splitext(os.path.basename(image_name))[0] + '-' + model_type
+ )
+ if not side:
+ utils.write_depth(filename, prediction, grayscale, bits=2)
+ else:
+ original_image_bgr = np.flip(original_image_rgb, 2)
+ content = create_side_by_side(original_image_bgr*255, prediction, grayscale)
+ cv2.imwrite(filename + ".png", content)
+ utils.write_pfm(filename + ".pfm", prediction.astype(np.float32))
+
+ else:
+ with torch.no_grad():
+ fps = 1
+ video = VideoStream(0).start()
+ time_start = time.time()
+ frame_index = 0
+ while True:
+ frame = video.read()
+ if frame is not None:
+ original_image_rgb = np.flip(frame, 2) # in [0, 255] (flip required to get RGB)
+ image = transform({"image": original_image_rgb/255})["image"]
+
+ prediction = process(device, model, model_type, image, (net_w, net_h),
+ original_image_rgb.shape[1::-1], optimize, True)
+
+ original_image_bgr = np.flip(original_image_rgb, 2) if side else None
+ content = create_side_by_side(original_image_bgr, prediction, grayscale)
+ cv2.imshow('MiDaS Depth Estimation - Press Escape to close window ', content/255)
+
+ if output_path is not None:
+ filename = os.path.join(output_path, 'Camera' + '-' + model_type + '_' + str(frame_index))
+ cv2.imwrite(filename + ".png", content)
+
+ alpha = 0.1
+ if time.time()-time_start > 0:
+ fps = (1 - alpha) * fps + alpha * 1 / (time.time()-time_start) # exponential moving average
+ time_start = time.time()
+ print(f"\rFPS: {round(fps,2)}", end="")
+
+ if cv2.waitKey(1) == 27: # Escape key
+ break
+
+ frame_index += 1
+ print()
+
+ print("Finished")
+
+
+if __name__ == "__main__":
+ parser = argparse.ArgumentParser()
+
+ parser.add_argument('-i', '--input_path',
+ default=None,
+ help='Folder with input images (if no input path is specified, images are tried to be grabbed '
+ 'from camera)'
+ )
+
+ parser.add_argument('-o', '--output_path',
+ default=None,
+ help='Folder for output images'
+ )
+
+ parser.add_argument('-m', '--model_weights',
+ default=None,
+ help='Path to the trained weights of model'
+ )
+
+ parser.add_argument('-t', '--model_type',
+ default='dpt_beit_large_512',
+ help='Model type: '
+ 'dpt_beit_large_512, dpt_beit_large_384, dpt_beit_base_384, dpt_swin2_large_384, '
+ 'dpt_swin2_base_384, dpt_swin2_tiny_256, dpt_swin_large_384, dpt_next_vit_large_384, '
+ 'dpt_levit_224, dpt_large_384, dpt_hybrid_384, midas_v21_384, midas_v21_small_256 or '
+ 'openvino_midas_v21_small_256'
+ )
+
+ parser.add_argument('-s', '--side',
+ action='store_true',
+ help='Output images contain RGB and depth images side by side'
+ )
+
+ parser.add_argument('--optimize', dest='optimize', action='store_true', help='Use half-float optimization')
+ parser.set_defaults(optimize=False)
+
+ parser.add_argument('--height',
+ type=int, default=None,
+ help='Preferred height of images feed into the encoder during inference. Note that the '
+ 'preferred height may differ from the actual height, because an alignment to multiples of '
+ '32 takes place. Many models support only the height chosen during training, which is '
+ 'used automatically if this parameter is not set.'
+ )
+ parser.add_argument('--square',
+ action='store_true',
+ help='Option to resize images to a square resolution by changing their widths when images are '
+ 'fed into the encoder during inference. If this parameter is not set, the aspect ratio of '
+ 'images is tried to be preserved if supported by the model.'
+ )
+ parser.add_argument('--grayscale',
+ action='store_true',
+ help='Use a grayscale colormap instead of the inferno one. Although the inferno colormap, '
+ 'which is used by default, is better for visibility, it does not allow storing 16-bit '
+ 'depth values in PNGs but only 8-bit ones due to the precision limitation of this '
+ 'colormap.'
+ )
+
+ args = parser.parse_args()
+
+
+ if args.model_weights is None:
+ args.model_weights = default_models[args.model_type]
+
+ # set torch options
+ torch.backends.cudnn.enabled = True
+ torch.backends.cudnn.benchmark = True
+
+ # compute depth maps
+ run(args.input_path, args.output_path, args.model_weights, args.model_type, args.optimize, args.side, args.height,
+ args.square, args.grayscale)
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/README.md b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..dca3cf8efd6110c698e218759cc7ef0a83980c0d
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/README.md
@@ -0,0 +1,147 @@
+## Towards Robust Monocular Depth Estimation: Mixing Datasets for Zero-shot Cross-dataset Transfer
+
+### TensorFlow inference using `.pb` and `.onnx` models
+
+1. [Run inference on TensorFlow-model by using TensorFlow](#run-inference-on-tensorflow-model-by-using-tensorFlow)
+
+2. [Run inference on ONNX-model by using TensorFlow](#run-inference-on-onnx-model-by-using-tensorflow)
+
+3. [Make ONNX model from downloaded Pytorch model file](#make-onnx-model-from-downloaded-pytorch-model-file)
+
+
+### Run inference on TensorFlow-model by using TensorFlow
+
+1) Download the model weights [model-f6b98070.pb](https://github.com/isl-org/MiDaS/releases/download/v2_1/model-f6b98070.pb)
+and [model-small.pb](https://github.com/isl-org/MiDaS/releases/download/v2_1/model-small.pb) and place the
+file in the `/tf/` folder.
+
+2) Set up dependencies:
+
+```shell
+# install OpenCV
+pip install --upgrade pip
+pip install opencv-python
+
+# install TensorFlow
+pip install -I grpcio tensorflow==2.3.0 tensorflow-addons==0.11.2 numpy==1.18.0
+```
+
+#### Usage
+
+1) Place one or more input images in the folder `tf/input`.
+
+2) Run the model:
+
+ ```shell
+ python tf/run_pb.py
+ ```
+
+ Or run the small model:
+
+ ```shell
+ python tf/run_pb.py --model_weights model-small.pb --model_type small
+ ```
+
+3) The resulting inverse depth maps are written to the `tf/output` folder.
+
+
+### Run inference on ONNX-model by using ONNX-Runtime
+
+1) Download the model weights [model-f6b98070.onnx](https://github.com/isl-org/MiDaS/releases/download/v2_1/model-f6b98070.onnx)
+and [model-small.onnx](https://github.com/isl-org/MiDaS/releases/download/v2_1/model-small.onnx) and place the
+file in the `/tf/` folder.
+
+2) Set up dependencies:
+
+```shell
+# install OpenCV
+pip install --upgrade pip
+pip install opencv-python
+
+# install ONNX
+pip install onnx==1.7.0
+
+# install ONNX Runtime
+pip install onnxruntime==1.5.2
+```
+
+#### Usage
+
+1) Place one or more input images in the folder `tf/input`.
+
+2) Run the model:
+
+ ```shell
+ python tf/run_onnx.py
+ ```
+
+ Or run the small model:
+
+ ```shell
+ python tf/run_onnx.py --model_weights model-small.onnx --model_type small
+ ```
+
+3) The resulting inverse depth maps are written to the `tf/output` folder.
+
+
+
+### Make ONNX model from downloaded Pytorch model file
+
+1) Download the model weights [model-f6b98070.pt](https://github.com/isl-org/MiDaS/releases/download/v2_1/model-f6b98070.pt) and place the
+file in the root folder.
+
+2) Set up dependencies:
+
+```shell
+# install OpenCV
+pip install --upgrade pip
+pip install opencv-python
+
+# install PyTorch TorchVision
+pip install -I torch==1.7.0 torchvision==0.8.0
+
+# install TensorFlow
+pip install -I grpcio tensorflow==2.3.0 tensorflow-addons==0.11.2 numpy==1.18.0
+
+# install ONNX
+pip install onnx==1.7.0
+
+# install ONNX-TensorFlow
+git clone https://github.com/onnx/onnx-tensorflow.git
+cd onnx-tensorflow
+git checkout 095b51b88e35c4001d70f15f80f31014b592b81e
+pip install -e .
+```
+
+#### Usage
+
+1) Run the converter:
+
+ ```shell
+ python tf/make_onnx_model.py
+ ```
+
+2) The resulting `model-f6b98070.onnx` file is written to the `/tf/` folder.
+
+
+### Requirements
+
+ The code was tested with Python 3.6.9, PyTorch 1.5.1, TensorFlow 2.2.0, TensorFlow-addons 0.8.3, ONNX 1.7.0, ONNX-TensorFlow (GitHub-master-17.07.2020) and OpenCV 4.3.0.
+
+### Citation
+
+Please cite our paper if you use this code or any of the models:
+```
+@article{Ranftl2019,
+ author = {Ren\'{e} Ranftl and Katrin Lasinger and David Hafner and Konrad Schindler and Vladlen Koltun},
+ title = {Towards Robust Monocular Depth Estimation: Mixing Datasets for Zero-shot Cross-dataset Transfer},
+ journal = {IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI)},
+ year = {2020},
+}
+```
+
+### License
+
+MIT License
+
+
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/input/.placeholder b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/input/.placeholder
new file mode 100644
index 0000000000000000000000000000000000000000..e69de29bb2d1d6434b8b29ae775ad8c2e48c5391
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/make_onnx_model.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/make_onnx_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..49afaee6851e453a06f3b58ba9a9558375c90164
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/make_onnx_model.py
@@ -0,0 +1,112 @@
+"""Compute depth maps for images in the input folder.
+"""
+import os
+import ntpath
+import glob
+import torch
+import utils
+import cv2
+import numpy as np
+from torchvision.transforms import Compose, Normalize
+from torchvision import transforms
+
+from shutil import copyfile
+import fileinput
+import sys
+sys.path.append(os.getcwd() + '/..')
+
+def modify_file():
+ modify_filename = '../midas/blocks.py'
+ copyfile(modify_filename, modify_filename+'.bak')
+
+ with open(modify_filename, 'r') as file :
+ filedata = file.read()
+
+ filedata = filedata.replace('align_corners=True', 'align_corners=False')
+ filedata = filedata.replace('import torch.nn as nn', 'import torch.nn as nn\nimport torchvision.models as models')
+ filedata = filedata.replace('torch.hub.load("facebookresearch/WSL-Images", "resnext101_32x8d_wsl")', 'models.resnext101_32x8d()')
+
+ with open(modify_filename, 'w') as file:
+ file.write(filedata)
+
+def restore_file():
+ modify_filename = '../midas/blocks.py'
+ copyfile(modify_filename+'.bak', modify_filename)
+
+modify_file()
+
+from midas.midas_net import MidasNet
+from midas.transforms import Resize, NormalizeImage, PrepareForNet
+
+restore_file()
+
+
+class MidasNet_preprocessing(MidasNet):
+ """Network for monocular depth estimation.
+ """
+ def forward(self, x):
+ """Forward pass.
+
+ Args:
+ x (tensor): input data (image)
+
+ Returns:
+ tensor: depth
+ """
+
+ mean = torch.tensor([0.485, 0.456, 0.406])
+ std = torch.tensor([0.229, 0.224, 0.225])
+ x.sub_(mean[None, :, None, None]).div_(std[None, :, None, None])
+
+ return MidasNet.forward(self, x)
+
+
+def run(model_path):
+ """Run MonoDepthNN to compute depth maps.
+
+ Args:
+ model_path (str): path to saved model
+ """
+ print("initialize")
+
+ # select device
+
+ # load network
+ #model = MidasNet(model_path, non_negative=True)
+ model = MidasNet_preprocessing(model_path, non_negative=True)
+
+ model.eval()
+
+ print("start processing")
+
+ # input
+ img_input = np.zeros((3, 384, 384), np.float32)
+
+ # compute
+ with torch.no_grad():
+ sample = torch.from_numpy(img_input).unsqueeze(0)
+ prediction = model.forward(sample)
+ prediction = (
+ torch.nn.functional.interpolate(
+ prediction.unsqueeze(1),
+ size=img_input.shape[:2],
+ mode="bicubic",
+ align_corners=False,
+ )
+ .squeeze()
+ .cpu()
+ .numpy()
+ )
+
+ torch.onnx.export(model, sample, ntpath.basename(model_path).rsplit('.', 1)[0]+'.onnx', opset_version=9)
+
+ print("finished")
+
+
+if __name__ == "__main__":
+ # set paths
+ # MODEL_PATH = "model.pt"
+ MODEL_PATH = "../model-f6b98070.pt"
+
+ # compute depth maps
+ run(MODEL_PATH)
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/run_onnx.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/run_onnx.py
new file mode 100644
index 0000000000000000000000000000000000000000..48587111c3e6a7cc97674f3bb35ebbf222a7123d
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/run_onnx.py
@@ -0,0 +1,119 @@
+"""Compute depth maps for images in the input folder.
+"""
+import os
+import glob
+import utils
+import cv2
+import sys
+import numpy as np
+import argparse
+
+import onnx
+import onnxruntime as rt
+
+from transforms import Resize, NormalizeImage, PrepareForNet
+
+
+def run(input_path, output_path, model_path, model_type="large"):
+ """Run MonoDepthNN to compute depth maps.
+
+ Args:
+ input_path (str): path to input folder
+ output_path (str): path to output folder
+ model_path (str): path to saved model
+ """
+ print("initialize")
+
+ # select device
+ device = "CUDA:0"
+ #device = "CPU"
+ print("device: %s" % device)
+
+ # network resolution
+ if model_type == "large":
+ net_w, net_h = 384, 384
+ elif model_type == "small":
+ net_w, net_h = 256, 256
+ else:
+ print(f"model_type '{model_type}' not implemented, use: --model_type large")
+ assert False
+
+ # load network
+ print("loading model...")
+ model = rt.InferenceSession(model_path)
+ input_name = model.get_inputs()[0].name
+ output_name = model.get_outputs()[0].name
+
+ resize_image = Resize(
+ net_w,
+ net_h,
+ resize_target=None,
+ keep_aspect_ratio=False,
+ ensure_multiple_of=32,
+ resize_method="upper_bound",
+ image_interpolation_method=cv2.INTER_CUBIC,
+ )
+
+ def compose2(f1, f2):
+ return lambda x: f2(f1(x))
+
+ transform = compose2(resize_image, PrepareForNet())
+
+ # get input
+ img_names = glob.glob(os.path.join(input_path, "*"))
+ num_images = len(img_names)
+
+ # create output folder
+ os.makedirs(output_path, exist_ok=True)
+
+ print("start processing")
+
+ for ind, img_name in enumerate(img_names):
+
+ print(" processing {} ({}/{})".format(img_name, ind + 1, num_images))
+
+ # input
+ img = utils.read_image(img_name)
+ img_input = transform({"image": img})["image"]
+
+ # compute
+ output = model.run([output_name], {input_name: img_input.reshape(1, 3, net_h, net_w).astype(np.float32)})[0]
+ prediction = np.array(output).reshape(net_h, net_w)
+ prediction = cv2.resize(prediction, (img.shape[1], img.shape[0]), interpolation=cv2.INTER_CUBIC)
+
+ # output
+ filename = os.path.join(
+ output_path, os.path.splitext(os.path.basename(img_name))[0]
+ )
+ utils.write_depth(filename, prediction, bits=2)
+
+ print("finished")
+
+
+if __name__ == "__main__":
+ parser = argparse.ArgumentParser()
+
+ parser.add_argument('-i', '--input_path',
+ default='input',
+ help='folder with input images'
+ )
+
+ parser.add_argument('-o', '--output_path',
+ default='output',
+ help='folder for output images'
+ )
+
+ parser.add_argument('-m', '--model_weights',
+ default='model-f6b98070.onnx',
+ help='path to the trained weights of model'
+ )
+
+ parser.add_argument('-t', '--model_type',
+ default='large',
+ help='model type: large or small'
+ )
+
+ args = parser.parse_args()
+
+ # compute depth maps
+ run(args.input_path, args.output_path, args.model_weights, args.model_type)
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/run_pb.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/run_pb.py
new file mode 100644
index 0000000000000000000000000000000000000000..0f3e8cbbf433f4fe43878b221da0517f770cc81f
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/run_pb.py
@@ -0,0 +1,135 @@
+"""Compute depth maps for images in the input folder.
+"""
+import os
+import glob
+import utils
+import cv2
+import argparse
+
+import tensorflow as tf
+
+from transforms import Resize, NormalizeImage, PrepareForNet
+
+def run(input_path, output_path, model_path, model_type="large"):
+ """Run MonoDepthNN to compute depth maps.
+
+ Args:
+ input_path (str): path to input folder
+ output_path (str): path to output folder
+ model_path (str): path to saved model
+ """
+ print("initialize")
+
+ # the runtime initialization will not allocate all memory on the device to avoid out of GPU memory
+ gpus = tf.config.experimental.list_physical_devices('GPU')
+ if gpus:
+ try:
+ for gpu in gpus:
+ #tf.config.experimental.set_memory_growth(gpu, True)
+ tf.config.experimental.set_virtual_device_configuration(gpu,
+ [tf.config.experimental.VirtualDeviceConfiguration(memory_limit=4000)])
+ except RuntimeError as e:
+ print(e)
+
+ # network resolution
+ if model_type == "large":
+ net_w, net_h = 384, 384
+ elif model_type == "small":
+ net_w, net_h = 256, 256
+ else:
+ print(f"model_type '{model_type}' not implemented, use: --model_type large")
+ assert False
+
+ # load network
+ graph_def = tf.compat.v1.GraphDef()
+ with tf.io.gfile.GFile(model_path, 'rb') as f:
+ graph_def.ParseFromString(f.read())
+ tf.import_graph_def(graph_def, name='')
+
+
+ model_operations = tf.compat.v1.get_default_graph().get_operations()
+ input_node = '0:0'
+ output_layer = model_operations[len(model_operations) - 1].name + ':0'
+ print("Last layer name: ", output_layer)
+
+ resize_image = Resize(
+ net_w,
+ net_h,
+ resize_target=None,
+ keep_aspect_ratio=False,
+ ensure_multiple_of=32,
+ resize_method="upper_bound",
+ image_interpolation_method=cv2.INTER_CUBIC,
+ )
+
+ def compose2(f1, f2):
+ return lambda x: f2(f1(x))
+
+ transform = compose2(resize_image, PrepareForNet())
+
+ # get input
+ img_names = glob.glob(os.path.join(input_path, "*"))
+ num_images = len(img_names)
+
+ # create output folder
+ os.makedirs(output_path, exist_ok=True)
+
+ print("start processing")
+
+ with tf.compat.v1.Session() as sess:
+ try:
+ # load images
+ for ind, img_name in enumerate(img_names):
+
+ print(" processing {} ({}/{})".format(img_name, ind + 1, num_images))
+
+ # input
+ img = utils.read_image(img_name)
+ img_input = transform({"image": img})["image"]
+
+ # compute
+ prob_tensor = sess.graph.get_tensor_by_name(output_layer)
+ prediction, = sess.run(prob_tensor, {input_node: [img_input] })
+ prediction = prediction.reshape(net_h, net_w)
+ prediction = cv2.resize(prediction, (img.shape[1], img.shape[0]), interpolation=cv2.INTER_CUBIC)
+
+ # output
+ filename = os.path.join(
+ output_path, os.path.splitext(os.path.basename(img_name))[0]
+ )
+ utils.write_depth(filename, prediction, bits=2)
+
+ except KeyError:
+ print ("Couldn't find input node: ' + input_node + ' or output layer: " + output_layer + ".")
+ exit(-1)
+
+ print("finished")
+
+
+if __name__ == "__main__":
+ parser = argparse.ArgumentParser()
+
+ parser.add_argument('-i', '--input_path',
+ default='input',
+ help='folder with input images'
+ )
+
+ parser.add_argument('-o', '--output_path',
+ default='output',
+ help='folder for output images'
+ )
+
+ parser.add_argument('-m', '--model_weights',
+ default='model-f6b98070.pb',
+ help='path to the trained weights of model'
+ )
+
+ parser.add_argument('-t', '--model_type',
+ default='large',
+ help='model type: large or small'
+ )
+
+ args = parser.parse_args()
+
+ # compute depth maps
+ run(args.input_path, args.output_path, args.model_weights, args.model_type)
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/transforms.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/transforms.py
new file mode 100644
index 0000000000000000000000000000000000000000..37d68afcebf67defadd7dfb2ff5494f257876575
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/transforms.py
@@ -0,0 +1,234 @@
+import numpy as np
+import cv2
+import math
+
+
+def apply_min_size(sample, size, image_interpolation_method=cv2.INTER_AREA):
+ """Rezise the sample to ensure the given size. Keeps aspect ratio.
+
+ Args:
+ sample (dict): sample
+ size (tuple): image size
+
+ Returns:
+ tuple: new size
+ """
+ shape = list(sample["disparity"].shape)
+
+ if shape[0] >= size[0] and shape[1] >= size[1]:
+ return sample
+
+ scale = [0, 0]
+ scale[0] = size[0] / shape[0]
+ scale[1] = size[1] / shape[1]
+
+ scale = max(scale)
+
+ shape[0] = math.ceil(scale * shape[0])
+ shape[1] = math.ceil(scale * shape[1])
+
+ # resize
+ sample["image"] = cv2.resize(
+ sample["image"], tuple(shape[::-1]), interpolation=image_interpolation_method
+ )
+
+ sample["disparity"] = cv2.resize(
+ sample["disparity"], tuple(shape[::-1]), interpolation=cv2.INTER_NEAREST
+ )
+ sample["mask"] = cv2.resize(
+ sample["mask"].astype(np.float32),
+ tuple(shape[::-1]),
+ interpolation=cv2.INTER_NEAREST,
+ )
+ sample["mask"] = sample["mask"].astype(bool)
+
+ return tuple(shape)
+
+
+class Resize(object):
+ """Resize sample to given size (width, height).
+ """
+
+ def __init__(
+ self,
+ width,
+ height,
+ resize_target=True,
+ keep_aspect_ratio=False,
+ ensure_multiple_of=1,
+ resize_method="lower_bound",
+ image_interpolation_method=cv2.INTER_AREA,
+ ):
+ """Init.
+
+ Args:
+ width (int): desired output width
+ height (int): desired output height
+ resize_target (bool, optional):
+ True: Resize the full sample (image, mask, target).
+ False: Resize image only.
+ Defaults to True.
+ keep_aspect_ratio (bool, optional):
+ True: Keep the aspect ratio of the input sample.
+ Output sample might not have the given width and height, and
+ resize behaviour depends on the parameter 'resize_method'.
+ Defaults to False.
+ ensure_multiple_of (int, optional):
+ Output width and height is constrained to be multiple of this parameter.
+ Defaults to 1.
+ resize_method (str, optional):
+ "lower_bound": Output will be at least as large as the given size.
+ "upper_bound": Output will be at max as large as the given size. (Output size might be smaller than given size.)
+ "minimal": Scale as least as possible. (Output size might be smaller than given size.)
+ Defaults to "lower_bound".
+ """
+ self.__width = width
+ self.__height = height
+
+ self.__resize_target = resize_target
+ self.__keep_aspect_ratio = keep_aspect_ratio
+ self.__multiple_of = ensure_multiple_of
+ self.__resize_method = resize_method
+ self.__image_interpolation_method = image_interpolation_method
+
+ def constrain_to_multiple_of(self, x, min_val=0, max_val=None):
+ y = (np.round(x / self.__multiple_of) * self.__multiple_of).astype(int)
+
+ if max_val is not None and y > max_val:
+ y = (np.floor(x / self.__multiple_of) * self.__multiple_of).astype(int)
+
+ if y < min_val:
+ y = (np.ceil(x / self.__multiple_of) * self.__multiple_of).astype(int)
+
+ return y
+
+ def get_size(self, width, height):
+ # determine new height and width
+ scale_height = self.__height / height
+ scale_width = self.__width / width
+
+ if self.__keep_aspect_ratio:
+ if self.__resize_method == "lower_bound":
+ # scale such that output size is lower bound
+ if scale_width > scale_height:
+ # fit width
+ scale_height = scale_width
+ else:
+ # fit height
+ scale_width = scale_height
+ elif self.__resize_method == "upper_bound":
+ # scale such that output size is upper bound
+ if scale_width < scale_height:
+ # fit width
+ scale_height = scale_width
+ else:
+ # fit height
+ scale_width = scale_height
+ elif self.__resize_method == "minimal":
+ # scale as least as possbile
+ if abs(1 - scale_width) < abs(1 - scale_height):
+ # fit width
+ scale_height = scale_width
+ else:
+ # fit height
+ scale_width = scale_height
+ else:
+ raise ValueError(
+ f"resize_method {self.__resize_method} not implemented"
+ )
+
+ if self.__resize_method == "lower_bound":
+ new_height = self.constrain_to_multiple_of(
+ scale_height * height, min_val=self.__height
+ )
+ new_width = self.constrain_to_multiple_of(
+ scale_width * width, min_val=self.__width
+ )
+ elif self.__resize_method == "upper_bound":
+ new_height = self.constrain_to_multiple_of(
+ scale_height * height, max_val=self.__height
+ )
+ new_width = self.constrain_to_multiple_of(
+ scale_width * width, max_val=self.__width
+ )
+ elif self.__resize_method == "minimal":
+ new_height = self.constrain_to_multiple_of(scale_height * height)
+ new_width = self.constrain_to_multiple_of(scale_width * width)
+ else:
+ raise ValueError(f"resize_method {self.__resize_method} not implemented")
+
+ return (new_width, new_height)
+
+ def __call__(self, sample):
+ width, height = self.get_size(
+ sample["image"].shape[1], sample["image"].shape[0]
+ )
+
+ # resize sample
+ sample["image"] = cv2.resize(
+ sample["image"],
+ (width, height),
+ interpolation=self.__image_interpolation_method,
+ )
+
+ if self.__resize_target:
+ if "disparity" in sample:
+ sample["disparity"] = cv2.resize(
+ sample["disparity"],
+ (width, height),
+ interpolation=cv2.INTER_NEAREST,
+ )
+
+ if "depth" in sample:
+ sample["depth"] = cv2.resize(
+ sample["depth"], (width, height), interpolation=cv2.INTER_NEAREST
+ )
+
+ sample["mask"] = cv2.resize(
+ sample["mask"].astype(np.float32),
+ (width, height),
+ interpolation=cv2.INTER_NEAREST,
+ )
+ sample["mask"] = sample["mask"].astype(bool)
+
+ return sample
+
+
+class NormalizeImage(object):
+ """Normlize image by given mean and std.
+ """
+
+ def __init__(self, mean, std):
+ self.__mean = mean
+ self.__std = std
+
+ def __call__(self, sample):
+ sample["image"] = (sample["image"] - self.__mean) / self.__std
+
+ return sample
+
+
+class PrepareForNet(object):
+ """Prepare sample for usage as network input.
+ """
+
+ def __init__(self):
+ pass
+
+ def __call__(self, sample):
+ image = np.transpose(sample["image"], (2, 0, 1))
+ sample["image"] = np.ascontiguousarray(image).astype(np.float32)
+
+ if "mask" in sample:
+ sample["mask"] = sample["mask"].astype(np.float32)
+ sample["mask"] = np.ascontiguousarray(sample["mask"])
+
+ if "disparity" in sample:
+ disparity = sample["disparity"].astype(np.float32)
+ sample["disparity"] = np.ascontiguousarray(disparity)
+
+ if "depth" in sample:
+ depth = sample["depth"].astype(np.float32)
+ sample["depth"] = np.ascontiguousarray(depth)
+
+ return sample
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/utils.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..cdc1c60e3291ebc1ba57ab0cc4788dcb02fecd76
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/tf/utils.py
@@ -0,0 +1,82 @@
+import numpy as np
+import sys
+import cv2
+
+
+def write_pfm(path, image, scale=1):
+ """Write pfm file.
+ Args:
+ path (str): pathto file
+ image (array): data
+ scale (int, optional): Scale. Defaults to 1.
+ """
+
+ with open(path, "wb") as file:
+ color = None
+
+ if image.dtype.name != "float32":
+ raise Exception("Image dtype must be float32.")
+
+ image = np.flipud(image)
+
+ if len(image.shape) == 3 and image.shape[2] == 3: # color image
+ color = True
+ elif (
+ len(image.shape) == 2 or len(image.shape) == 3 and image.shape[2] == 1
+ ): # greyscale
+ color = False
+ else:
+ raise Exception("Image must have H x W x 3, H x W x 1 or H x W dimensions.")
+
+ file.write("PF\n" if color else "Pf\n".encode())
+ file.write("%d %d\n".encode() % (image.shape[1], image.shape[0]))
+
+ endian = image.dtype.byteorder
+
+ if endian == "<" or endian == "=" and sys.byteorder == "little":
+ scale = -scale
+
+ file.write("%f\n".encode() % scale)
+
+ image.tofile(file)
+
+def read_image(path):
+ """Read image and output RGB image (0-1).
+ Args:
+ path (str): path to file
+ Returns:
+ array: RGB image (0-1)
+ """
+ img = cv2.imread(path)
+
+ if img.ndim == 2:
+ img = cv2.cvtColor(img, cv2.COLOR_GRAY2BGR)
+
+ img = cv2.cvtColor(img, cv2.COLOR_BGR2RGB) / 255.0
+
+ return img
+
+def write_depth(path, depth, bits=1):
+ """Write depth map to pfm and png file.
+ Args:
+ path (str): filepath without extension
+ depth (array): depth
+ """
+ write_pfm(path + ".pfm", depth.astype(np.float32))
+
+ depth_min = depth.min()
+ depth_max = depth.max()
+
+ max_val = (2**(8*bits))-1
+
+ if depth_max - depth_min > np.finfo("float").eps:
+ out = max_val * (depth - depth_min) / (depth_max - depth_min)
+ else:
+ out = 0
+
+ if bits == 1:
+ cv2.imwrite(path + ".png", out.astype("uint8"))
+ elif bits == 2:
+ cv2.imwrite(path + ".png", out.astype("uint16"))
+
+ return
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/utils.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..d836b7e196be6db8c0b145fe3b03357a10b4725d
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/utils.py
@@ -0,0 +1,199 @@
+"""Utils for monoDepth.
+"""
+import sys
+import re
+import numpy as np
+import cv2
+import torch
+
+
+def read_pfm(path):
+ """Read pfm file.
+
+ Args:
+ path (str): path to file
+
+ Returns:
+ tuple: (data, scale)
+ """
+ with open(path, "rb") as file:
+
+ color = None
+ width = None
+ height = None
+ scale = None
+ endian = None
+
+ header = file.readline().rstrip()
+ if header.decode("ascii") == "PF":
+ color = True
+ elif header.decode("ascii") == "Pf":
+ color = False
+ else:
+ raise Exception("Not a PFM file: " + path)
+
+ dim_match = re.match(r"^(\d+)\s(\d+)\s$", file.readline().decode("ascii"))
+ if dim_match:
+ width, height = list(map(int, dim_match.groups()))
+ else:
+ raise Exception("Malformed PFM header.")
+
+ scale = float(file.readline().decode("ascii").rstrip())
+ if scale < 0:
+ # little-endian
+ endian = "<"
+ scale = -scale
+ else:
+ # big-endian
+ endian = ">"
+
+ data = np.fromfile(file, endian + "f")
+ shape = (height, width, 3) if color else (height, width)
+
+ data = np.reshape(data, shape)
+ data = np.flipud(data)
+
+ return data, scale
+
+
+def write_pfm(path, image, scale=1):
+ """Write pfm file.
+
+ Args:
+ path (str): pathto file
+ image (array): data
+ scale (int, optional): Scale. Defaults to 1.
+ """
+
+ with open(path, "wb") as file:
+ color = None
+
+ if image.dtype.name != "float32":
+ raise Exception("Image dtype must be float32.")
+
+ image = np.flipud(image)
+
+ if len(image.shape) == 3 and image.shape[2] == 3: # color image
+ color = True
+ elif (
+ len(image.shape) == 2 or len(image.shape) == 3 and image.shape[2] == 1
+ ): # greyscale
+ color = False
+ else:
+ raise Exception("Image must have H x W x 3, H x W x 1 or H x W dimensions.")
+
+ file.write("PF\n" if color else "Pf\n".encode())
+ file.write("%d %d\n".encode() % (image.shape[1], image.shape[0]))
+
+ endian = image.dtype.byteorder
+
+ if endian == "<" or endian == "=" and sys.byteorder == "little":
+ scale = -scale
+
+ file.write("%f\n".encode() % scale)
+
+ image.tofile(file)
+
+
+def read_image(path):
+ """Read image and output RGB image (0-1).
+
+ Args:
+ path (str): path to file
+
+ Returns:
+ array: RGB image (0-1)
+ """
+ img = cv2.imread(path)
+
+ if img.ndim == 2:
+ img = cv2.cvtColor(img, cv2.COLOR_GRAY2BGR)
+
+ img = cv2.cvtColor(img, cv2.COLOR_BGR2RGB) / 255.0
+
+ return img
+
+
+def resize_image(img):
+ """Resize image and make it fit for network.
+
+ Args:
+ img (array): image
+
+ Returns:
+ tensor: data ready for network
+ """
+ height_orig = img.shape[0]
+ width_orig = img.shape[1]
+
+ if width_orig > height_orig:
+ scale = width_orig / 384
+ else:
+ scale = height_orig / 384
+
+ height = (np.ceil(height_orig / scale / 32) * 32).astype(int)
+ width = (np.ceil(width_orig / scale / 32) * 32).astype(int)
+
+ img_resized = cv2.resize(img, (width, height), interpolation=cv2.INTER_AREA)
+
+ img_resized = (
+ torch.from_numpy(np.transpose(img_resized, (2, 0, 1))).contiguous().float()
+ )
+ img_resized = img_resized.unsqueeze(0)
+
+ return img_resized
+
+
+def resize_depth(depth, width, height):
+ """Resize depth map and bring to CPU (numpy).
+
+ Args:
+ depth (tensor): depth
+ width (int): image width
+ height (int): image height
+
+ Returns:
+ array: processed depth
+ """
+ depth = torch.squeeze(depth[0, :, :, :]).to("cpu")
+
+ depth_resized = cv2.resize(
+ depth.numpy(), (width, height), interpolation=cv2.INTER_CUBIC
+ )
+
+ return depth_resized
+
+def write_depth(path, depth, grayscale, bits=1):
+ """Write depth map to png file.
+
+ Args:
+ path (str): filepath without extension
+ depth (array): depth
+ grayscale (bool): use a grayscale colormap?
+ """
+ if not grayscale:
+ bits = 1
+
+ if not np.isfinite(depth).all():
+ depth=np.nan_to_num(depth, nan=0.0, posinf=0.0, neginf=0.0)
+ print("WARNING: Non-finite depth values present")
+
+ depth_min = depth.min()
+ depth_max = depth.max()
+
+ max_val = (2**(8*bits))-1
+
+ if depth_max - depth_min > np.finfo("float").eps:
+ out = max_val * (depth - depth_min) / (depth_max - depth_min)
+ else:
+ out = np.zeros(depth.shape, dtype=depth.dtype)
+
+ if not grayscale:
+ out = cv2.applyColorMap(np.uint8(out), cv2.COLORMAP_INFERNO)
+
+ if bits == 1:
+ cv2.imwrite(path + ".png", out.astype("uint8"))
+ elif bits == 2:
+ cv2.imwrite(path + ".png", out.astype("uint16"))
+
+ return
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/weights/.placeholder b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/base_models/midas_repo/weights/.placeholder
new file mode 100644
index 0000000000000000000000000000000000000000..e69de29bb2d1d6434b8b29ae775ad8c2e48c5391
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/builder.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/builder.py
new file mode 100644
index 0000000000000000000000000000000000000000..a7c6f7bb6fa39af071b4d6ca267b53084b3ee5f6
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/builder.py
@@ -0,0 +1,51 @@
+# MIT License
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
+from importlib import import_module
+from .depth_model import DepthModel
+
+def build_model(config) -> DepthModel:
+ """Builds a model from a config. The model is specified by the model name and version in the config. The model is then constructed using the build_from_config function of the model interface.
+ This function should be used to construct models for training and evaluation.
+
+ Args:
+ config (dict): Config dict. Config is constructed in utils/config.py. Each model has its own config file(s) saved in its root model folder.
+
+ Returns:
+ torch.nn.Module: Model corresponding to name and version as specified in config
+ """
+ module_name = f"zoedepth.models.{config.model}"
+ try:
+ module = import_module(module_name)
+ except ModuleNotFoundError as e:
+ # print the original error message
+ print(e)
+ raise ValueError(
+ f"Model {config.model} not found. Refer above error for details.") from e
+ try:
+ get_version = getattr(module, "get_version")
+ except AttributeError as e:
+ raise ValueError(
+ f"Model {config.model} has no get_version function.") from e
+ return get_version(config.version_name).build_from_config(config)
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/depth_model.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/depth_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..982750b0c4c2fc6f25aae75e0a7002f96dd8a87d
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/depth_model.py
@@ -0,0 +1,148 @@
+# MIT License
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
+import numpy as np
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+from torchvision import transforms
+import PIL.Image
+from PIL import Image
+from typing import Union
+
+
+class DepthModel(nn.Module):
+ def __init__(self):
+ super().__init__()
+ self.device = 'cpu'
+
+ def forward(self, x, *args, **kwargs):
+ raise NotImplementedError
+
+ def _infer(self, x: torch.Tensor):
+ """
+ Inference interface for the model
+ Args:
+ x (torch.Tensor): input tensor of shape (b, c, h, w)
+ Returns:
+ torch.Tensor: output tensor of shape (b, 1, h, w)
+ """
+ return self(x)['metric_depth']
+
+ def _infer_with_pad_aug(self, x: torch.Tensor, pad_input: bool=True, fh: float=3, fw: float=3, upsampling_mode: str='bicubic', padding_mode="reflect", **kwargs) -> torch.Tensor:
+ """
+ Inference interface for the model with padding augmentation
+ Padding augmentation fixes the boundary artifacts in the output depth map.
+ Boundary artifacts are sometimes caused by the fact that the model is trained on NYU raw dataset which has a black or white border around the image.
+ This augmentation pads the input image and crops the prediction back to the original size / view.
+
+ Note: This augmentation is not required for the models trained with 'avoid_boundary'=True.
+ Args:
+ x (torch.Tensor): input tensor of shape (b, c, h, w)
+ pad_input (bool, optional): whether to pad the input or not. Defaults to True.
+ fh (float, optional): height padding factor. The padding is calculated as sqrt(h/2) * fh. Defaults to 3.
+ fw (float, optional): width padding factor. The padding is calculated as sqrt(w/2) * fw. Defaults to 3.
+ upsampling_mode (str, optional): upsampling mode. Defaults to 'bicubic'.
+ padding_mode (str, optional): padding mode. Defaults to "reflect".
+ Returns:
+ torch.Tensor: output tensor of shape (b, 1, h, w)
+ """
+ # assert x is nchw and c = 3
+ assert x.dim() == 4, "x must be 4 dimensional, got {}".format(x.dim())
+ assert x.shape[1] == 3, "x must have 3 channels, got {}".format(x.shape[1])
+
+ if pad_input:
+ assert fh > 0 or fw > 0, "atlease one of fh and fw must be greater than 0"
+ pad_h = int(np.sqrt(x.shape[2]/2) * fh)
+ pad_w = int(np.sqrt(x.shape[3]/2) * fw)
+ padding = [pad_w, pad_w]
+ if pad_h > 0:
+ padding += [pad_h, pad_h]
+
+ x = F.pad(x, padding, mode=padding_mode, **kwargs)
+ out = self._infer(x)
+ if out.shape[-2:] != x.shape[-2:]:
+ out = F.interpolate(out, size=(x.shape[2], x.shape[3]), mode=upsampling_mode, align_corners=False)
+ if pad_input:
+ # crop to the original size, handling the case where pad_h and pad_w is 0
+ if pad_h > 0:
+ out = out[:, :, pad_h:-pad_h,:]
+ if pad_w > 0:
+ out = out[:, :, :, pad_w:-pad_w]
+ return out
+
+ def infer_with_flip_aug(self, x, pad_input: bool=True, **kwargs) -> torch.Tensor:
+ """
+ Inference interface for the model with horizontal flip augmentation
+ Horizontal flip augmentation improves the accuracy of the model by averaging the output of the model with and without horizontal flip.
+ Args:
+ x (torch.Tensor): input tensor of shape (b, c, h, w)
+ pad_input (bool, optional): whether to use padding augmentation. Defaults to True.
+ Returns:
+ torch.Tensor: output tensor of shape (b, 1, h, w)
+ """
+ # infer with horizontal flip and average
+ out = self._infer_with_pad_aug(x, pad_input=pad_input, **kwargs)
+ out_flip = self._infer_with_pad_aug(torch.flip(x, dims=[3]), pad_input=pad_input, **kwargs)
+ out = (out + torch.flip(out_flip, dims=[3])) / 2
+ return out
+
+ def infer(self, x, pad_input: bool=True, with_flip_aug: bool=True, **kwargs) -> torch.Tensor:
+ """
+ Inference interface for the model
+ Args:
+ x (torch.Tensor): input tensor of shape (b, c, h, w)
+ pad_input (bool, optional): whether to use padding augmentation. Defaults to True.
+ with_flip_aug (bool, optional): whether to use horizontal flip augmentation. Defaults to True.
+ Returns:
+ torch.Tensor: output tensor of shape (b, 1, h, w)
+ """
+ if with_flip_aug:
+ return self.infer_with_flip_aug(x, pad_input=pad_input, **kwargs)
+ else:
+ return self._infer_with_pad_aug(x, pad_input=pad_input, **kwargs)
+
+ @torch.no_grad()
+ def infer_pil(self, pil_img, pad_input: bool=True, with_flip_aug: bool=True, output_type: str="numpy", **kwargs) -> Union[np.ndarray, PIL.Image.Image, torch.Tensor]:
+ """
+ Inference interface for the model for PIL image
+ Args:
+ pil_img (PIL.Image.Image): input PIL image
+ pad_input (bool, optional): whether to use padding augmentation. Defaults to True.
+ with_flip_aug (bool, optional): whether to use horizontal flip augmentation. Defaults to True.
+ output_type (str, optional): output type. Supported values are 'numpy', 'pil' and 'tensor'. Defaults to "numpy".
+ """
+ x = transforms.ToTensor()(pil_img).unsqueeze(0).to(self.device)
+ out_tensor = self.infer(x, pad_input=pad_input, with_flip_aug=with_flip_aug, **kwargs)
+ if output_type == "numpy":
+ return out_tensor.squeeze().cpu().numpy()
+ elif output_type == "pil":
+ # uint16 is required for depth pil image
+ out_16bit_numpy = (out_tensor.squeeze().cpu().numpy()*256).astype(np.uint16)
+ return Image.fromarray(out_16bit_numpy)
+ elif output_type == "tensor":
+ return out_tensor.squeeze().cpu()
+ else:
+ raise ValueError(f"output_type {output_type} not supported. Supported values are 'numpy', 'pil' and 'tensor'")
+
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/layers/attractor.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/layers/attractor.py
new file mode 100644
index 0000000000000000000000000000000000000000..b5e3473ca6e2271dc28666314cf8f92f52f7e3c6
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/layers/attractor.py
@@ -0,0 +1,208 @@
+# MIT License
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
+import torch
+import torch.nn as nn
+
+
+@torch.jit.script
+def exp_attractor(dx, alpha: float = 300, gamma: int = 2):
+ """Exponential attractor: dc = exp(-alpha*|dx|^gamma) * dx , where dx = a - c, a = attractor point, c = bin center, dc = shift in bin centermmary for exp_attractor
+
+ Args:
+ dx (torch.Tensor): The difference tensor dx = Ai - Cj, where Ai is the attractor point and Cj is the bin center.
+ alpha (float, optional): Proportional Attractor strength. Determines the absolute strength. Lower alpha = greater attraction. Defaults to 300.
+ gamma (int, optional): Exponential Attractor strength. Determines the "region of influence" and indirectly number of bin centers affected. Lower gamma = farther reach. Defaults to 2.
+
+ Returns:
+ torch.Tensor : Delta shifts - dc; New bin centers = Old bin centers + dc
+ """
+ return torch.exp(-alpha*(torch.abs(dx)**gamma)) * (dx)
+
+
+@torch.jit.script
+def inv_attractor(dx, alpha: float = 300, gamma: int = 2):
+ """Inverse attractor: dc = dx / (1 + alpha*dx^gamma), where dx = a - c, a = attractor point, c = bin center, dc = shift in bin center
+ This is the default one according to the accompanying paper.
+
+ Args:
+ dx (torch.Tensor): The difference tensor dx = Ai - Cj, where Ai is the attractor point and Cj is the bin center.
+ alpha (float, optional): Proportional Attractor strength. Determines the absolute strength. Lower alpha = greater attraction. Defaults to 300.
+ gamma (int, optional): Exponential Attractor strength. Determines the "region of influence" and indirectly number of bin centers affected. Lower gamma = farther reach. Defaults to 2.
+
+ Returns:
+ torch.Tensor: Delta shifts - dc; New bin centers = Old bin centers + dc
+ """
+ return dx.div(1+alpha*dx.pow(gamma))
+
+
+class AttractorLayer(nn.Module):
+ def __init__(self, in_features, n_bins, n_attractors=16, mlp_dim=128, min_depth=1e-3, max_depth=10,
+ alpha=300, gamma=2, kind='sum', attractor_type='exp', memory_efficient=False):
+ """
+ Attractor layer for bin centers. Bin centers are bounded on the interval (min_depth, max_depth)
+ """
+ super().__init__()
+
+ self.n_attractors = n_attractors
+ self.n_bins = n_bins
+ self.min_depth = min_depth
+ self.max_depth = max_depth
+ self.alpha = alpha
+ self.gamma = gamma
+ self.kind = kind
+ self.attractor_type = attractor_type
+ self.memory_efficient = memory_efficient
+
+ self._net = nn.Sequential(
+ nn.Conv2d(in_features, mlp_dim, 1, 1, 0),
+ nn.ReLU(inplace=True),
+ nn.Conv2d(mlp_dim, n_attractors*2, 1, 1, 0), # x2 for linear norm
+ nn.ReLU(inplace=True)
+ )
+
+ def forward(self, x, b_prev, prev_b_embedding=None, interpolate=True, is_for_query=False):
+ """
+ Args:
+ x (torch.Tensor) : feature block; shape - n, c, h, w
+ b_prev (torch.Tensor) : previous bin centers normed; shape - n, prev_nbins, h, w
+
+ Returns:
+ tuple(torch.Tensor,torch.Tensor) : new bin centers normed and scaled; shape - n, nbins, h, w
+ """
+ if prev_b_embedding is not None:
+ if interpolate:
+ prev_b_embedding = nn.functional.interpolate(
+ prev_b_embedding, x.shape[-2:], mode='bilinear', align_corners=True)
+ x = x + prev_b_embedding
+
+ A = self._net(x)
+ eps = 1e-3
+ A = A + eps
+ n, c, h, w = A.shape
+ A = A.view(n, self.n_attractors, 2, h, w)
+ A_normed = A / A.sum(dim=2, keepdim=True) # n, a, 2, h, w
+ A_normed = A[:, :, 0, ...] # n, na, h, w
+
+ b_prev = nn.functional.interpolate(
+ b_prev, (h, w), mode='bilinear', align_corners=True)
+ b_centers = b_prev
+
+ if self.attractor_type == 'exp':
+ dist = exp_attractor
+ else:
+ dist = inv_attractor
+
+ if not self.memory_efficient:
+ func = {'mean': torch.mean, 'sum': torch.sum}[self.kind]
+ # .shape N, nbins, h, w
+ delta_c = func(dist(A_normed.unsqueeze(
+ 2) - b_centers.unsqueeze(1)), dim=1)
+ else:
+ delta_c = torch.zeros_like(b_centers, device=b_centers.device)
+ for i in range(self.n_attractors):
+ # .shape N, nbins, h, w
+ delta_c += dist(A_normed[:, i, ...].unsqueeze(1) - b_centers)
+
+ if self.kind == 'mean':
+ delta_c = delta_c / self.n_attractors
+
+ b_new_centers = b_centers + delta_c
+ B_centers = (self.max_depth - self.min_depth) * \
+ b_new_centers + self.min_depth
+ B_centers, _ = torch.sort(B_centers, dim=1)
+ B_centers = torch.clip(B_centers, self.min_depth, self.max_depth)
+ return b_new_centers, B_centers
+
+
+class AttractorLayerUnnormed(nn.Module):
+ def __init__(self, in_features, n_bins, n_attractors=16, mlp_dim=128, min_depth=1e-3, max_depth=10,
+ alpha=300, gamma=2, kind='sum', attractor_type='exp', memory_efficient=False):
+ """
+ Attractor layer for bin centers. Bin centers are unbounded
+ """
+ super().__init__()
+
+ self.n_attractors = n_attractors
+ self.n_bins = n_bins
+ self.min_depth = min_depth
+ self.max_depth = max_depth
+ self.alpha = alpha
+ self.gamma = gamma
+ self.kind = kind
+ self.attractor_type = attractor_type
+ self.memory_efficient = memory_efficient
+
+ self._net = nn.Sequential(
+ nn.Conv2d(in_features, mlp_dim, 1, 1, 0),
+ nn.ReLU(inplace=True),
+ nn.Conv2d(mlp_dim, n_attractors, 1, 1, 0),
+ nn.Softplus()
+ )
+
+ def forward(self, x, b_prev, prev_b_embedding=None, interpolate=True, is_for_query=False):
+ """
+ Args:
+ x (torch.Tensor) : feature block; shape - n, c, h, w
+ b_prev (torch.Tensor) : previous bin centers normed; shape - n, prev_nbins, h, w
+
+ Returns:
+ tuple(torch.Tensor,torch.Tensor) : new bin centers unbounded; shape - n, nbins, h, w. Two outputs just to keep the API consistent with the normed version
+ """
+ if prev_b_embedding is not None:
+ if interpolate:
+ prev_b_embedding = nn.functional.interpolate(
+ prev_b_embedding, x.shape[-2:], mode='bilinear', align_corners=True)
+ x = x + prev_b_embedding
+
+ A = self._net(x)
+ n, c, h, w = A.shape
+
+ b_prev = nn.functional.interpolate(
+ b_prev, (h, w), mode='bilinear', align_corners=True)
+ b_centers = b_prev
+
+ if self.attractor_type == 'exp':
+ dist = exp_attractor
+ else:
+ dist = inv_attractor
+
+ if not self.memory_efficient:
+ func = {'mean': torch.mean, 'sum': torch.sum}[self.kind]
+ # .shape N, nbins, h, w
+ delta_c = func(
+ dist(A.unsqueeze(2) - b_centers.unsqueeze(1)), dim=1)
+ else:
+ delta_c = torch.zeros_like(b_centers, device=b_centers.device)
+ for i in range(self.n_attractors):
+ delta_c += dist(A[:, i, ...].unsqueeze(1) -
+ b_centers) # .shape N, nbins, h, w
+
+ if self.kind == 'mean':
+ delta_c = delta_c / self.n_attractors
+
+ b_new_centers = b_centers + delta_c
+ B_centers = b_new_centers
+
+ return b_new_centers, B_centers
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/layers/dist_layers.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/layers/dist_layers.py
new file mode 100644
index 0000000000000000000000000000000000000000..d5ff793e94aeb43aa554ef8c2392080df5572e19
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/layers/dist_layers.py
@@ -0,0 +1,121 @@
+# MIT License
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
+import torch
+import torch.nn as nn
+
+
+def log_binom(n, k, eps=1e-7):
+ """ log(nCk) using stirling approximation """
+ n = n + eps
+ k = k + eps
+ return n * torch.log(n) - k * torch.log(k) - (n-k) * torch.log(n-k+eps)
+
+
+class LogBinomial(nn.Module):
+ def __init__(self, n_classes=256, act=torch.softmax):
+ """Compute log binomial distribution for n_classes
+
+ Args:
+ n_classes (int, optional): number of output classes. Defaults to 256.
+ """
+ super().__init__()
+ self.K = n_classes
+ self.act = act
+ self.register_buffer('k_idx', torch.arange(
+ 0, n_classes).view(1, -1, 1, 1))
+ self.register_buffer('K_minus_1', torch.Tensor(
+ [self.K-1]).view(1, -1, 1, 1))
+
+ def forward(self, x, t=1., eps=1e-4):
+ """Compute log binomial distribution for x
+
+ Args:
+ x (torch.Tensor - NCHW): probabilities
+ t (float, torch.Tensor - NCHW, optional): Temperature of distribution. Defaults to 1..
+ eps (float, optional): Small number for numerical stability. Defaults to 1e-4.
+
+ Returns:
+ torch.Tensor -NCHW: log binomial distribution logbinomial(p;t)
+ """
+ if x.ndim == 3:
+ x = x.unsqueeze(1) # make it nchw
+
+ one_minus_x = torch.clamp(1 - x, eps, 1)
+ x = torch.clamp(x, eps, 1)
+ y = log_binom(self.K_minus_1, self.k_idx) + self.k_idx * \
+ torch.log(x) + (self.K - 1 - self.k_idx) * torch.log(one_minus_x)
+ return self.act(y/t, dim=1)
+
+
+class ConditionalLogBinomial(nn.Module):
+ def __init__(self, in_features, condition_dim, n_classes=256, bottleneck_factor=2, p_eps=1e-4, max_temp=50, min_temp=1e-7, act=torch.softmax):
+ """Conditional Log Binomial distribution
+
+ Args:
+ in_features (int): number of input channels in main feature
+ condition_dim (int): number of input channels in condition feature
+ n_classes (int, optional): Number of classes. Defaults to 256.
+ bottleneck_factor (int, optional): Hidden dim factor. Defaults to 2.
+ p_eps (float, optional): small eps value. Defaults to 1e-4.
+ max_temp (float, optional): Maximum temperature of output distribution. Defaults to 50.
+ min_temp (float, optional): Minimum temperature of output distribution. Defaults to 1e-7.
+ """
+ super().__init__()
+ self.p_eps = p_eps
+ self.max_temp = max_temp
+ self.min_temp = min_temp
+ self.log_binomial_transform = LogBinomial(n_classes, act=act)
+ bottleneck = (in_features + condition_dim) // bottleneck_factor
+ self.mlp = nn.Sequential(
+ nn.Conv2d(in_features + condition_dim, bottleneck,
+ kernel_size=1, stride=1, padding=0),
+ nn.GELU(),
+ # 2 for p linear norm, 2 for t linear norm
+ nn.Conv2d(bottleneck, 2+2, kernel_size=1, stride=1, padding=0),
+ nn.Softplus()
+ )
+
+ def forward(self, x, cond):
+ """Forward pass
+
+ Args:
+ x (torch.Tensor - NCHW): Main feature
+ cond (torch.Tensor - NCHW): condition feature
+
+ Returns:
+ torch.Tensor: Output log binomial distribution
+ """
+ pt = self.mlp(torch.concat((x, cond), dim=1))
+ p, t = pt[:, :2, ...], pt[:, 2:, ...]
+
+ p = p + self.p_eps
+ p = p[:, 0, ...] / (p[:, 0, ...] + p[:, 1, ...])
+
+ t = t + self.p_eps
+ t = t[:, 0, ...] / (t[:, 0, ...] + t[:, 1, ...])
+ t = t.unsqueeze(1)
+ t = (self.max_temp - self.min_temp) * t + self.min_temp
+
+ return self.log_binomial_transform(p, t)
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/layers/localbins_layers.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/layers/localbins_layers.py
new file mode 100644
index 0000000000000000000000000000000000000000..cda7b1f9c74ac0d54733ef6d1dcadc1c62ab4647
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/layers/localbins_layers.py
@@ -0,0 +1,169 @@
+# MIT License
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
+import torch
+import torch.nn as nn
+
+
+class SeedBinRegressor(nn.Module):
+ def __init__(self, in_features, n_bins=16, mlp_dim=256, min_depth=1e-3, max_depth=10):
+ """Bin center regressor network. Bin centers are bounded on (min_depth, max_depth) interval.
+
+ Args:
+ in_features (int): input channels
+ n_bins (int, optional): Number of bin centers. Defaults to 16.
+ mlp_dim (int, optional): Hidden dimension. Defaults to 256.
+ min_depth (float, optional): Min depth value. Defaults to 1e-3.
+ max_depth (float, optional): Max depth value. Defaults to 10.
+ """
+ super().__init__()
+ self.version = "1_1"
+ self.min_depth = min_depth
+ self.max_depth = max_depth
+
+ self._net = nn.Sequential(
+ nn.Conv2d(in_features, mlp_dim, 1, 1, 0),
+ nn.ReLU(inplace=True),
+ nn.Conv2d(mlp_dim, n_bins, 1, 1, 0),
+ nn.ReLU(inplace=True)
+ )
+
+ def forward(self, x):
+ """
+ Returns tensor of bin_width vectors (centers). One vector b for every pixel
+ """
+ B = self._net(x)
+ eps = 1e-3
+ B = B + eps
+ B_widths_normed = B / B.sum(dim=1, keepdim=True)
+ B_widths = (self.max_depth - self.min_depth) * \
+ B_widths_normed # .shape NCHW
+ # pad has the form (left, right, top, bottom, front, back)
+ B_widths = nn.functional.pad(
+ B_widths, (0, 0, 0, 0, 1, 0), mode='constant', value=self.min_depth)
+ B_edges = torch.cumsum(B_widths, dim=1) # .shape NCHW
+
+ B_centers = 0.5 * (B_edges[:, :-1, ...] + B_edges[:, 1:, ...])
+ return B_widths_normed, B_centers
+
+
+class SeedBinRegressorUnnormed(nn.Module):
+ def __init__(self, in_features, n_bins=16, mlp_dim=256, min_depth=1e-3, max_depth=10):
+ """Bin center regressor network. Bin centers are unbounded
+
+ Args:
+ in_features (int): input channels
+ n_bins (int, optional): Number of bin centers. Defaults to 16.
+ mlp_dim (int, optional): Hidden dimension. Defaults to 256.
+ min_depth (float, optional): Not used. (for compatibility with SeedBinRegressor)
+ max_depth (float, optional): Not used. (for compatibility with SeedBinRegressor)
+ """
+ super().__init__()
+ self.version = "1_1"
+ self._net = nn.Sequential(
+ nn.Conv2d(in_features, mlp_dim, 1, 1, 0),
+ nn.ReLU(inplace=True),
+ nn.Conv2d(mlp_dim, n_bins, 1, 1, 0),
+ nn.Softplus()
+ )
+
+ def forward(self, x):
+ """
+ Returns tensor of bin_width vectors (centers). One vector b for every pixel
+ """
+ B_centers = self._net(x)
+ return B_centers, B_centers
+
+
+class Projector(nn.Module):
+ def __init__(self, in_features, out_features, mlp_dim=128):
+ """Projector MLP
+
+ Args:
+ in_features (int): input channels
+ out_features (int): output channels
+ mlp_dim (int, optional): hidden dimension. Defaults to 128.
+ """
+ super().__init__()
+
+ self._net = nn.Sequential(
+ nn.Conv2d(in_features, mlp_dim, 1, 1, 0),
+ nn.ReLU(inplace=True),
+ nn.Conv2d(mlp_dim, out_features, 1, 1, 0),
+ )
+
+ def forward(self, x):
+ return self._net(x)
+
+
+
+class LinearSplitter(nn.Module):
+ def __init__(self, in_features, prev_nbins, split_factor=2, mlp_dim=128, min_depth=1e-3, max_depth=10):
+ super().__init__()
+
+ self.prev_nbins = prev_nbins
+ self.split_factor = split_factor
+ self.min_depth = min_depth
+ self.max_depth = max_depth
+
+ self._net = nn.Sequential(
+ nn.Conv2d(in_features, mlp_dim, 1, 1, 0),
+ nn.GELU(),
+ nn.Conv2d(mlp_dim, prev_nbins * split_factor, 1, 1, 0),
+ nn.ReLU()
+ )
+
+ def forward(self, x, b_prev, prev_b_embedding=None, interpolate=True, is_for_query=False):
+ """
+ x : feature block; shape - n, c, h, w
+ b_prev : previous bin widths normed; shape - n, prev_nbins, h, w
+ """
+ if prev_b_embedding is not None:
+ if interpolate:
+ prev_b_embedding = nn.functional.interpolate(prev_b_embedding, x.shape[-2:], mode='bilinear', align_corners=True)
+ x = x + prev_b_embedding
+ S = self._net(x)
+ eps = 1e-3
+ S = S + eps
+ n, c, h, w = S.shape
+ S = S.view(n, self.prev_nbins, self.split_factor, h, w)
+ S_normed = S / S.sum(dim=2, keepdim=True) # fractional splits
+
+ b_prev = nn.functional.interpolate(b_prev, (h,w), mode='bilinear', align_corners=True)
+
+
+ b_prev = b_prev / b_prev.sum(dim=1, keepdim=True) # renormalize for gurantees
+ # print(b_prev.shape, S_normed.shape)
+ # if is_for_query:(1).expand(-1, b_prev.size(0)//n, -1, -1, -1, -1).flatten(0,1) # TODO ? can replace all this with a single torch.repeat?
+ b = b_prev.unsqueeze(2) * S_normed
+ b = b.flatten(1,2) # .shape n, prev_nbins * split_factor, h, w
+
+ # calculate bin centers for loss calculation
+ B_widths = (self.max_depth - self.min_depth) * b # .shape N, nprev * splitfactor, H, W
+ # pad has the form (left, right, top, bottom, front, back)
+ B_widths = nn.functional.pad(B_widths, (0,0,0,0,1,0), mode='constant', value=self.min_depth)
+ B_edges = torch.cumsum(B_widths, dim=1) # .shape NCHW
+
+ B_centers = 0.5 * (B_edges[:, :-1, ...] + B_edges[:,1:,...])
+ return b, B_centers
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/layers/patch_transformer.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/layers/patch_transformer.py
new file mode 100644
index 0000000000000000000000000000000000000000..eacac4d38809db2b3c669d0134f91645225af531
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/layers/patch_transformer.py
@@ -0,0 +1,91 @@
+# MIT License
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
+import torch
+import torch.nn as nn
+
+
+class PatchTransformerEncoder(nn.Module):
+ def __init__(self, in_channels, patch_size=10, embedding_dim=128, num_heads=4, use_class_token=False):
+ """ViT-like transformer block
+
+ Args:
+ in_channels (int): Input channels
+ patch_size (int, optional): patch size. Defaults to 10.
+ embedding_dim (int, optional): Embedding dimension in transformer model. Defaults to 128.
+ num_heads (int, optional): number of attention heads. Defaults to 4.
+ use_class_token (bool, optional): Whether to use extra token at the start for global accumulation (called as "class token"). Defaults to False.
+ """
+ super(PatchTransformerEncoder, self).__init__()
+ self.use_class_token = use_class_token
+ encoder_layers = nn.TransformerEncoderLayer(
+ embedding_dim, num_heads, dim_feedforward=1024)
+ self.transformer_encoder = nn.TransformerEncoder(
+ encoder_layers, num_layers=4) # takes shape S,N,E
+
+ self.embedding_convPxP = nn.Conv2d(in_channels, embedding_dim,
+ kernel_size=patch_size, stride=patch_size, padding=0)
+
+ def positional_encoding_1d(self, sequence_length, batch_size, embedding_dim, device='cpu'):
+ """Generate positional encodings
+
+ Args:
+ sequence_length (int): Sequence length
+ embedding_dim (int): Embedding dimension
+
+ Returns:
+ torch.Tensor SBE: Positional encodings
+ """
+ position = torch.arange(
+ 0, sequence_length, dtype=torch.float32, device=device).unsqueeze(1)
+ index = torch.arange(
+ 0, embedding_dim, 2, dtype=torch.float32, device=device).unsqueeze(0)
+ div_term = torch.exp(index * (-torch.log(torch.tensor(10000.0, device=device)) / embedding_dim))
+ pos_encoding = position * div_term
+ pos_encoding = torch.cat([torch.sin(pos_encoding), torch.cos(pos_encoding)], dim=1)
+ pos_encoding = pos_encoding.unsqueeze(1).repeat(1, batch_size, 1)
+ return pos_encoding
+
+
+ def forward(self, x):
+ """Forward pass
+
+ Args:
+ x (torch.Tensor - NCHW): Input feature tensor
+
+ Returns:
+ torch.Tensor - SNE: Transformer output embeddings. S - sequence length (=HW/patch_size^2), N - batch size, E - embedding dim
+ """
+ embeddings = self.embedding_convPxP(x).flatten(
+ 2) # .shape = n,c,s = n, embedding_dim, s
+ if self.use_class_token:
+ # extra special token at start ?
+ embeddings = nn.functional.pad(embeddings, (1, 0))
+
+ # change to S,N,E format required by transformer
+ embeddings = embeddings.permute(2, 0, 1)
+ S, N, E = embeddings.shape
+ embeddings = embeddings + self.positional_encoding_1d(S, N, E, device=embeddings.device)
+ x = self.transformer_encoder(embeddings) # .shape = S, N, E
+ return x
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/model_io.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/model_io.py
new file mode 100644
index 0000000000000000000000000000000000000000..f63a9a1ff09e98da78a9a3da63e58509471f728d
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/model_io.py
@@ -0,0 +1,92 @@
+# MIT License
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
+import torch
+
+def load_state_dict(model, state_dict):
+ """Load state_dict into model, handling DataParallel and DistributedDataParallel. Also checks for "model" key in state_dict.
+
+ DataParallel prefixes state_dict keys with 'module.' when saving.
+ If the model is not a DataParallel model but the state_dict is, then prefixes are removed.
+ If the model is a DataParallel model but the state_dict is not, then prefixes are added.
+ """
+ state_dict = state_dict.get('model', state_dict)
+ # if model is a DataParallel model, then state_dict keys are prefixed with 'module.'
+
+ do_prefix = isinstance(
+ model, (torch.nn.DataParallel, torch.nn.parallel.DistributedDataParallel))
+ state = {}
+ for k, v in state_dict.items():
+ if k.startswith('module.') and not do_prefix:
+ k = k[7:]
+
+ if not k.startswith('module.') and do_prefix:
+ k = 'module.' + k
+
+ state[k] = v
+
+ model.load_state_dict(state)
+ print("Loaded successfully")
+ return model
+
+
+def load_wts(model, checkpoint_path):
+ ckpt = torch.load(checkpoint_path, map_location='cpu')
+ return load_state_dict(model, ckpt)
+
+
+def load_state_dict_from_url(model, url, **kwargs):
+ state_dict = torch.hub.load_state_dict_from_url(url, map_location='cpu', **kwargs)
+ return load_state_dict(model, state_dict)
+
+
+def load_state_from_resource(model, resource: str):
+ """Loads weights to the model from a given resource. A resource can be of following types:
+ 1. URL. Prefixed with "url::"
+ e.g. url::http(s)://url.resource.com/ckpt.pt
+
+ 2. Local path. Prefixed with "local::"
+ e.g. local::/path/to/ckpt.pt
+
+
+ Args:
+ model (torch.nn.Module): Model
+ resource (str): resource string
+
+ Returns:
+ torch.nn.Module: Model with loaded weights
+ """
+ print(f"Using pretrained resource {resource}")
+
+ if resource.startswith('url::'):
+ url = resource.split('url::')[1]
+ return load_state_dict_from_url(model, url, progress=True)
+
+ elif resource.startswith('local::'):
+ path = resource.split('local::')[1]
+ return load_wts(model, path)
+
+ else:
+ raise ValueError("Invalid resource type, only url:: and local:: are supported")
+
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth/__init__.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..f1e9a694852aaa28c500419d413ea8a572338e18
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth/__init__.py
@@ -0,0 +1,31 @@
+# MIT License
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
+from .zoedepth_v1 import ZoeDepth
+
+all_versions = {
+ "v1": ZoeDepth,
+}
+
+get_version = lambda v : all_versions[v]
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth/config_zoedepth.json b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth/config_zoedepth.json
new file mode 100644
index 0000000000000000000000000000000000000000..dfc9fa7b17615cf557b6ad01c8fedd6c0c32e88f
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth/config_zoedepth.json
@@ -0,0 +1,58 @@
+{
+ "model": {
+ "name": "ZoeDepth",
+ "version_name": "v1",
+ "n_bins": 64,
+ "bin_embedding_dim": 128,
+ "bin_centers_type": "softplus",
+ "n_attractors":[16, 8, 4, 1],
+ "attractor_alpha": 1000,
+ "attractor_gamma": 2,
+ "attractor_kind" : "mean",
+ "attractor_type" : "inv",
+ "midas_model_type" : "DPT_BEiT_L_384",
+ "min_temp": 0.0212,
+ "max_temp": 50.0,
+ "output_distribution": "logbinomial",
+ "memory_efficient": true,
+ "inverse_midas": false,
+ "img_size": [384, 512]
+ },
+
+ "train": {
+ "train_midas": true,
+ "use_pretrained_midas": true,
+ "trainer": "zoedepth",
+ "epochs": 5,
+ "bs": 16,
+ "optim_kwargs": {"lr": 0.000161, "wd": 0.01},
+ "sched_kwargs": {"div_factor": 1, "final_div_factor": 10000, "pct_start": 0.7, "three_phase":false, "cycle_momentum": true},
+ "same_lr": false,
+ "w_si": 1,
+ "w_domain": 0.2,
+ "w_reg": 0,
+ "w_grad": 0,
+ "avoid_boundary": false,
+ "random_crop": false,
+ "input_width": 640,
+ "input_height": 480,
+ "midas_lr_factor": 1,
+ "encoder_lr_factor":10,
+ "pos_enc_lr_factor":10,
+ "freeze_midas_bn": true
+
+ },
+
+ "infer":{
+ "train_midas": false,
+ "use_pretrained_midas": false,
+ "pretrained_resource" : null,
+ "force_keep_ar": true
+ },
+
+ "eval":{
+ "train_midas": false,
+ "use_pretrained_midas": false,
+ "pretrained_resource" : null
+ }
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth/config_zoedepth_kitti.json b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth/config_zoedepth_kitti.json
new file mode 100644
index 0000000000000000000000000000000000000000..3e7266ec2d7e918143f54ee728ea4d8d4e9adb11
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth/config_zoedepth_kitti.json
@@ -0,0 +1,22 @@
+{
+ "model": {
+ "bin_centers_type": "normed",
+ "img_size": [384, 768]
+ },
+
+ "train": {
+ },
+
+ "infer":{
+ "train_midas": false,
+ "use_pretrained_midas": false,
+ "pretrained_resource" : "url::https://github.com/isl-org/ZoeDepth/releases/download/v1.0/ZoeD_M12_K.pt",
+ "force_keep_ar": true
+ },
+
+ "eval":{
+ "train_midas": false,
+ "use_pretrained_midas": false,
+ "pretrained_resource" : "url::https://github.com/isl-org/ZoeDepth/releases/download/v1.0/ZoeD_M12_K.pt"
+ }
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth/zoedepth_v1.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth/zoedepth_v1.py
new file mode 100644
index 0000000000000000000000000000000000000000..4d5e8c2d272c3ae5f5ff1025aa96e6653b23d82f
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth/zoedepth_v1.py
@@ -0,0 +1,250 @@
+# MIT License
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
+import itertools
+
+import torch
+import torch.nn as nn
+from ..depth_model import DepthModel
+from ..base_models.midas import MidasCore
+from ..layers.attractor import AttractorLayer, AttractorLayerUnnormed
+from ..layers.dist_layers import ConditionalLogBinomial
+from ..layers.localbins_layers import (Projector, SeedBinRegressor,
+ SeedBinRegressorUnnormed)
+from ..model_io import load_state_from_resource
+
+
+class ZoeDepth(DepthModel):
+ def __init__(self, core, n_bins=64, bin_centers_type="softplus", bin_embedding_dim=128, min_depth=1e-3, max_depth=10,
+ n_attractors=[16, 8, 4, 1], attractor_alpha=300, attractor_gamma=2, attractor_kind='sum', attractor_type='exp', min_temp=5, max_temp=50, train_midas=True,
+ midas_lr_factor=10, encoder_lr_factor=10, pos_enc_lr_factor=10, inverse_midas=False, **kwargs):
+ """ZoeDepth model. This is the version of ZoeDepth that has a single metric head
+
+ Args:
+ core (models.base_models.midas.MidasCore): The base midas model that is used for extraction of "relative" features
+ n_bins (int, optional): Number of bin centers. Defaults to 64.
+ bin_centers_type (str, optional): "normed" or "softplus". Activation type used for bin centers. For "normed" bin centers, linear normalization trick is applied. This results in bounded bin centers.
+ For "softplus", softplus activation is used and thus are unbounded. Defaults to "softplus".
+ bin_embedding_dim (int, optional): bin embedding dimension. Defaults to 128.
+ min_depth (float, optional): Lower bound for normed bin centers. Defaults to 1e-3.
+ max_depth (float, optional): Upper bound for normed bin centers. Defaults to 10.
+ n_attractors (List[int], optional): Number of bin attractors at decoder layers. Defaults to [16, 8, 4, 1].
+ attractor_alpha (int, optional): Proportional attractor strength. Refer to models.layers.attractor for more details. Defaults to 300.
+ attractor_gamma (int, optional): Exponential attractor strength. Refer to models.layers.attractor for more details. Defaults to 2.
+ attractor_kind (str, optional): Attraction aggregation "sum" or "mean". Defaults to 'sum'.
+ attractor_type (str, optional): Type of attractor to use; "inv" (Inverse attractor) or "exp" (Exponential attractor). Defaults to 'exp'.
+ min_temp (int, optional): Lower bound for temperature of output probability distribution. Defaults to 5.
+ max_temp (int, optional): Upper bound for temperature of output probability distribution. Defaults to 50.
+ train_midas (bool, optional): Whether to train "core", the base midas model. Defaults to True.
+ midas_lr_factor (int, optional): Learning rate reduction factor for base midas model except its encoder and positional encodings. Defaults to 10.
+ encoder_lr_factor (int, optional): Learning rate reduction factor for the encoder in midas model. Defaults to 10.
+ pos_enc_lr_factor (int, optional): Learning rate reduction factor for positional encodings in the base midas model. Defaults to 10.
+ """
+ super().__init__()
+
+ self.core = core
+ self.max_depth = max_depth
+ self.min_depth = min_depth
+ self.min_temp = min_temp
+ self.bin_centers_type = bin_centers_type
+
+ self.midas_lr_factor = midas_lr_factor
+ self.encoder_lr_factor = encoder_lr_factor
+ self.pos_enc_lr_factor = pos_enc_lr_factor
+ self.train_midas = train_midas
+ self.inverse_midas = inverse_midas
+
+ if self.encoder_lr_factor <= 0:
+ self.core.freeze_encoder(
+ freeze_rel_pos=self.pos_enc_lr_factor <= 0)
+
+ N_MIDAS_OUT = 32
+ btlnck_features = self.core.output_channels[0]
+ num_out_features = self.core.output_channels[1:]
+
+ self.conv2 = nn.Conv2d(btlnck_features, btlnck_features,
+ kernel_size=1, stride=1, padding=0) # btlnck conv
+
+ if bin_centers_type == "normed":
+ SeedBinRegressorLayer = SeedBinRegressor
+ Attractor = AttractorLayer
+ elif bin_centers_type == "softplus":
+ SeedBinRegressorLayer = SeedBinRegressorUnnormed
+ Attractor = AttractorLayerUnnormed
+ elif bin_centers_type == "hybrid1":
+ SeedBinRegressorLayer = SeedBinRegressor
+ Attractor = AttractorLayerUnnormed
+ elif bin_centers_type == "hybrid2":
+ SeedBinRegressorLayer = SeedBinRegressorUnnormed
+ Attractor = AttractorLayer
+ else:
+ raise ValueError(
+ "bin_centers_type should be one of 'normed', 'softplus', 'hybrid1', 'hybrid2'")
+
+ self.seed_bin_regressor = SeedBinRegressorLayer(
+ btlnck_features, n_bins=n_bins, min_depth=min_depth, max_depth=max_depth)
+ self.seed_projector = Projector(btlnck_features, bin_embedding_dim)
+ self.projectors = nn.ModuleList([
+ Projector(num_out, bin_embedding_dim)
+ for num_out in num_out_features
+ ])
+ self.attractors = nn.ModuleList([
+ Attractor(bin_embedding_dim, n_bins, n_attractors=n_attractors[i], min_depth=min_depth, max_depth=max_depth,
+ alpha=attractor_alpha, gamma=attractor_gamma, kind=attractor_kind, attractor_type=attractor_type)
+ for i in range(len(num_out_features))
+ ])
+
+ last_in = N_MIDAS_OUT + 1 # +1 for relative depth
+
+ # use log binomial instead of softmax
+ self.conditional_log_binomial = ConditionalLogBinomial(
+ last_in, bin_embedding_dim, n_classes=n_bins, min_temp=min_temp, max_temp=max_temp)
+
+ def forward(self, x, return_final_centers=False, denorm=False, return_probs=False, **kwargs):
+ """
+ Args:
+ x (torch.Tensor): Input image tensor of shape (B, C, H, W)
+ return_final_centers (bool, optional): Whether to return the final bin centers. Defaults to False.
+ denorm (bool, optional): Whether to denormalize the input image. This reverses ImageNet normalization as midas normalization is different. Defaults to False.
+ return_probs (bool, optional): Whether to return the output probability distribution. Defaults to False.
+
+ Returns:
+ dict: Dictionary containing the following keys:
+ - rel_depth (torch.Tensor): Relative depth map of shape (B, H, W)
+ - metric_depth (torch.Tensor): Metric depth map of shape (B, 1, H, W)
+ - bin_centers (torch.Tensor): Bin centers of shape (B, n_bins). Present only if return_final_centers is True
+ - probs (torch.Tensor): Output probability distribution of shape (B, n_bins, H, W). Present only if return_probs is True
+
+ """
+ b, c, h, w = x.shape
+ # print("input shape ", x.shape)
+ self.orig_input_width = w
+ self.orig_input_height = h
+ rel_depth, out = self.core(x, denorm=denorm, return_rel_depth=True)
+ # print("output shapes", rel_depth.shape, out.shape)
+
+ outconv_activation = out[0]
+ btlnck = out[1]
+ x_blocks = out[2:]
+
+ x_d0 = self.conv2(btlnck)
+ x = x_d0
+ _, seed_b_centers = self.seed_bin_regressor(x)
+
+ if self.bin_centers_type == 'normed' or self.bin_centers_type == 'hybrid2':
+ b_prev = (seed_b_centers - self.min_depth) / \
+ (self.max_depth - self.min_depth)
+ else:
+ b_prev = seed_b_centers
+
+ prev_b_embedding = self.seed_projector(x)
+
+ # unroll this loop for better performance
+ for projector, attractor, x in zip(self.projectors, self.attractors, x_blocks):
+ b_embedding = projector(x)
+ b, b_centers = attractor(
+ b_embedding, b_prev, prev_b_embedding, interpolate=True)
+ b_prev = b.clone()
+ prev_b_embedding = b_embedding.clone()
+
+ last = outconv_activation
+
+ if self.inverse_midas:
+ # invert depth followed by normalization
+ rel_depth = 1.0 / (rel_depth + 1e-6)
+ rel_depth = (rel_depth - rel_depth.min()) / \
+ (rel_depth.max() - rel_depth.min())
+ # concat rel depth with last. First interpolate rel depth to last size
+ rel_cond = rel_depth.unsqueeze(1)
+ rel_cond = nn.functional.interpolate(
+ rel_cond, size=last.shape[2:], mode='bilinear', align_corners=True)
+ last = torch.cat([last, rel_cond], dim=1)
+
+ b_embedding = nn.functional.interpolate(
+ b_embedding, last.shape[-2:], mode='bilinear', align_corners=True)
+ x = self.conditional_log_binomial(last, b_embedding)
+
+ # Now depth value is Sum px * cx , where cx are bin_centers from the last bin tensor
+ # print(x.shape, b_centers.shape)
+ b_centers = nn.functional.interpolate(
+ b_centers, x.shape[-2:], mode='bilinear', align_corners=True)
+ out = torch.sum(x * b_centers, dim=1, keepdim=True)
+
+ # Structure output dict
+ output = dict(metric_depth=out)
+ if return_final_centers or return_probs:
+ output['bin_centers'] = b_centers
+
+ if return_probs:
+ output['probs'] = x
+
+ return output
+
+ def get_lr_params(self, lr):
+ """
+ Learning rate configuration for different layers of the model
+ Args:
+ lr (float) : Base learning rate
+ Returns:
+ list : list of parameters to optimize and their learning rates, in the format required by torch optimizers.
+ """
+ param_conf = []
+ if self.train_midas:
+ if self.encoder_lr_factor > 0:
+ param_conf.append({'params': self.core.get_enc_params_except_rel_pos(
+ ), 'lr': lr / self.encoder_lr_factor})
+
+ if self.pos_enc_lr_factor > 0:
+ param_conf.append(
+ {'params': self.core.get_rel_pos_params(), 'lr': lr / self.pos_enc_lr_factor})
+
+ midas_params = self.core.core.scratch.parameters()
+ midas_lr_factor = self.midas_lr_factor
+ param_conf.append(
+ {'params': midas_params, 'lr': lr / midas_lr_factor})
+
+ remaining_modules = []
+ for name, child in self.named_children():
+ if name != 'core':
+ remaining_modules.append(child)
+ remaining_params = itertools.chain(
+ *[child.parameters() for child in remaining_modules])
+
+ param_conf.append({'params': remaining_params, 'lr': lr})
+
+ return param_conf
+
+ @staticmethod
+ def build(midas_model_type="DPT_BEiT_L_384", pretrained_resource=None, use_pretrained_midas=False, train_midas=False, freeze_midas_bn=True, **kwargs):
+ core = MidasCore.build(midas_model_type=midas_model_type, use_pretrained_midas=use_pretrained_midas,
+ train_midas=train_midas, fetch_features=True, freeze_bn=freeze_midas_bn, **kwargs)
+ model = ZoeDepth(core, **kwargs)
+ if pretrained_resource:
+ assert isinstance(pretrained_resource, str), "pretrained_resource must be a string"
+ model = load_state_from_resource(model, pretrained_resource)
+ return model
+
+ @staticmethod
+ def build_from_config(config):
+ return ZoeDepth.build(**config)
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth_nk/__init__.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth_nk/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..56692da246c65d3c390236faa9ee1bf97040b824
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth_nk/__init__.py
@@ -0,0 +1,31 @@
+# MIT License
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
+from .zoedepth_nk_v1 import ZoeDepthNK
+
+all_versions = {
+ "v1": ZoeDepthNK,
+}
+
+get_version = lambda v : all_versions[v]
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth_nk/config_zoedepth_nk.json b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth_nk/config_zoedepth_nk.json
new file mode 100644
index 0000000000000000000000000000000000000000..ae036e38243566e0bb79a4821e4897d9bc4aaae1
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth_nk/config_zoedepth_nk.json
@@ -0,0 +1,67 @@
+{
+ "model": {
+ "name": "ZoeDepthNK",
+ "version_name": "v1",
+ "bin_conf" : [
+ {
+ "name": "nyu",
+ "n_bins": 64,
+ "min_depth": 1e-3,
+ "max_depth": 10.0
+ },
+ {
+ "name": "kitti",
+ "n_bins": 64,
+ "min_depth": 1e-3,
+ "max_depth": 80.0
+ }
+ ],
+ "bin_embedding_dim": 128,
+ "bin_centers_type": "softplus",
+ "n_attractors":[16, 8, 4, 1],
+ "attractor_alpha": 1000,
+ "attractor_gamma": 2,
+ "attractor_kind" : "mean",
+ "attractor_type" : "inv",
+ "min_temp": 0.0212,
+ "max_temp": 50.0,
+ "memory_efficient": true,
+ "midas_model_type" : "DPT_BEiT_L_384",
+ "img_size": [384, 512]
+ },
+
+ "train": {
+ "train_midas": true,
+ "use_pretrained_midas": true,
+ "trainer": "zoedepth_nk",
+ "epochs": 5,
+ "bs": 16,
+ "optim_kwargs": {"lr": 0.0002512, "wd": 0.01},
+ "sched_kwargs": {"div_factor": 1, "final_div_factor": 10000, "pct_start": 0.7, "three_phase":false, "cycle_momentum": true},
+ "same_lr": false,
+ "w_si": 1,
+ "w_domain": 100,
+ "avoid_boundary": false,
+ "random_crop": false,
+ "input_width": 640,
+ "input_height": 480,
+ "w_grad": 0,
+ "w_reg": 0,
+ "midas_lr_factor": 10,
+ "encoder_lr_factor":10,
+ "pos_enc_lr_factor":10
+ },
+
+ "infer": {
+ "train_midas": false,
+ "pretrained_resource": "url::https://github.com/isl-org/ZoeDepth/releases/download/v1.0/ZoeD_M12_NK.pt",
+ "use_pretrained_midas": false,
+ "force_keep_ar": true
+ },
+
+ "eval": {
+ "train_midas": false,
+ "pretrained_resource": "url::https://github.com/isl-org/ZoeDepth/releases/download/v1.0/ZoeD_M12_NK.pt",
+ "use_pretrained_midas": false
+ }
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth_nk/zoedepth_nk_v1.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth_nk/zoedepth_nk_v1.py
new file mode 100644
index 0000000000000000000000000000000000000000..af0bfd914c005e06ab67638941d423ef2058e242
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/models/zoedepth_nk/zoedepth_nk_v1.py
@@ -0,0 +1,333 @@
+# MIT License
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
+import itertools
+
+import torch
+import torch.nn as nn
+
+from zoedepth.models.depth_model import DepthModel
+from zoedepth.models.base_models.midas import MidasCore
+from zoedepth.models.layers.attractor import AttractorLayer, AttractorLayerUnnormed
+from zoedepth.models.layers.dist_layers import ConditionalLogBinomial
+from zoedepth.models.layers.localbins_layers import (Projector, SeedBinRegressor,
+ SeedBinRegressorUnnormed)
+from zoedepth.models.layers.patch_transformer import PatchTransformerEncoder
+from zoedepth.models.model_io import load_state_from_resource
+
+
+class ZoeDepthNK(DepthModel):
+ def __init__(self, core, bin_conf, bin_centers_type="softplus", bin_embedding_dim=128,
+ n_attractors=[16, 8, 4, 1], attractor_alpha=300, attractor_gamma=2, attractor_kind='sum', attractor_type='exp',
+ min_temp=5, max_temp=50,
+ memory_efficient=False, train_midas=True,
+ is_midas_pretrained=True, midas_lr_factor=1, encoder_lr_factor=10, pos_enc_lr_factor=10, inverse_midas=False, **kwargs):
+ """ZoeDepthNK model. This is the version of ZoeDepth that has two metric heads and uses a learned router to route to experts.
+
+ Args:
+ core (models.base_models.midas.MidasCore): The base midas model that is used for extraction of "relative" features
+
+ bin_conf (List[dict]): A list of dictionaries that contain the bin configuration for each metric head. Each dictionary should contain the following keys:
+ "name" (str, typically same as the dataset name), "n_bins" (int), "min_depth" (float), "max_depth" (float)
+
+ The length of this list determines the number of metric heads.
+ bin_centers_type (str, optional): "normed" or "softplus". Activation type used for bin centers. For "normed" bin centers, linear normalization trick is applied. This results in bounded bin centers.
+ For "softplus", softplus activation is used and thus are unbounded. Defaults to "normed".
+ bin_embedding_dim (int, optional): bin embedding dimension. Defaults to 128.
+
+ n_attractors (List[int], optional): Number of bin attractors at decoder layers. Defaults to [16, 8, 4, 1].
+ attractor_alpha (int, optional): Proportional attractor strength. Refer to models.layers.attractor for more details. Defaults to 300.
+ attractor_gamma (int, optional): Exponential attractor strength. Refer to models.layers.attractor for more details. Defaults to 2.
+ attractor_kind (str, optional): Attraction aggregation "sum" or "mean". Defaults to 'sum'.
+ attractor_type (str, optional): Type of attractor to use; "inv" (Inverse attractor) or "exp" (Exponential attractor). Defaults to 'exp'.
+
+ min_temp (int, optional): Lower bound for temperature of output probability distribution. Defaults to 5.
+ max_temp (int, optional): Upper bound for temperature of output probability distribution. Defaults to 50.
+
+ memory_efficient (bool, optional): Whether to use memory efficient version of attractor layers. Memory efficient version is slower but is recommended incase of multiple metric heads in order save GPU memory. Defaults to False.
+
+ train_midas (bool, optional): Whether to train "core", the base midas model. Defaults to True.
+ is_midas_pretrained (bool, optional): Is "core" pretrained? Defaults to True.
+ midas_lr_factor (int, optional): Learning rate reduction factor for base midas model except its encoder and positional encodings. Defaults to 10.
+ encoder_lr_factor (int, optional): Learning rate reduction factor for the encoder in midas model. Defaults to 10.
+ pos_enc_lr_factor (int, optional): Learning rate reduction factor for positional encodings in the base midas model. Defaults to 10.
+
+ """
+
+ super().__init__()
+
+ self.core = core
+ self.bin_conf = bin_conf
+ self.min_temp = min_temp
+ self.max_temp = max_temp
+ self.memory_efficient = memory_efficient
+ self.train_midas = train_midas
+ self.is_midas_pretrained = is_midas_pretrained
+ self.midas_lr_factor = midas_lr_factor
+ self.encoder_lr_factor = encoder_lr_factor
+ self.pos_enc_lr_factor = pos_enc_lr_factor
+ self.inverse_midas = inverse_midas
+
+ N_MIDAS_OUT = 32
+ btlnck_features = self.core.output_channels[0]
+ num_out_features = self.core.output_channels[1:]
+ # self.scales = [16, 8, 4, 2] # spatial scale factors
+
+ self.conv2 = nn.Conv2d(
+ btlnck_features, btlnck_features, kernel_size=1, stride=1, padding=0)
+
+ # Transformer classifier on the bottleneck
+ self.patch_transformer = PatchTransformerEncoder(
+ btlnck_features, 1, 128, use_class_token=True)
+ self.mlp_classifier = nn.Sequential(
+ nn.Linear(128, 128),
+ nn.ReLU(),
+ nn.Linear(128, 2)
+ )
+
+ if bin_centers_type == "normed":
+ SeedBinRegressorLayer = SeedBinRegressor
+ Attractor = AttractorLayer
+ elif bin_centers_type == "softplus":
+ SeedBinRegressorLayer = SeedBinRegressorUnnormed
+ Attractor = AttractorLayerUnnormed
+ elif bin_centers_type == "hybrid1":
+ SeedBinRegressorLayer = SeedBinRegressor
+ Attractor = AttractorLayerUnnormed
+ elif bin_centers_type == "hybrid2":
+ SeedBinRegressorLayer = SeedBinRegressorUnnormed
+ Attractor = AttractorLayer
+ else:
+ raise ValueError(
+ "bin_centers_type should be one of 'normed', 'softplus', 'hybrid1', 'hybrid2'")
+ self.bin_centers_type = bin_centers_type
+ # We have bins for each bin conf.
+ # Create a map (ModuleDict) of 'name' -> seed_bin_regressor
+ self.seed_bin_regressors = nn.ModuleDict(
+ {conf['name']: SeedBinRegressorLayer(btlnck_features, conf["n_bins"], mlp_dim=bin_embedding_dim//2, min_depth=conf["min_depth"], max_depth=conf["max_depth"])
+ for conf in bin_conf}
+ )
+
+ self.seed_projector = Projector(
+ btlnck_features, bin_embedding_dim, mlp_dim=bin_embedding_dim//2)
+ self.projectors = nn.ModuleList([
+ Projector(num_out, bin_embedding_dim, mlp_dim=bin_embedding_dim//2)
+ for num_out in num_out_features
+ ])
+
+ # Create a map (ModuleDict) of 'name' -> attractors (ModuleList)
+ self.attractors = nn.ModuleDict(
+ {conf['name']: nn.ModuleList([
+ Attractor(bin_embedding_dim, n_attractors[i],
+ mlp_dim=bin_embedding_dim, alpha=attractor_alpha,
+ gamma=attractor_gamma, kind=attractor_kind,
+ attractor_type=attractor_type, memory_efficient=memory_efficient,
+ min_depth=conf["min_depth"], max_depth=conf["max_depth"])
+ for i in range(len(n_attractors))
+ ])
+ for conf in bin_conf}
+ )
+
+ last_in = N_MIDAS_OUT
+ # conditional log binomial for each bin conf
+ self.conditional_log_binomial = nn.ModuleDict(
+ {conf['name']: ConditionalLogBinomial(last_in, bin_embedding_dim, conf['n_bins'], bottleneck_factor=4, min_temp=self.min_temp, max_temp=self.max_temp)
+ for conf in bin_conf}
+ )
+
+ def forward(self, x, return_final_centers=False, denorm=False, return_probs=False, **kwargs):
+ """
+ Args:
+ x (torch.Tensor): Input image tensor of shape (B, C, H, W). Assumes all images are from the same domain.
+ return_final_centers (bool, optional): Whether to return the final centers of the attractors. Defaults to False.
+ denorm (bool, optional): Whether to denormalize the input image. Defaults to False.
+ return_probs (bool, optional): Whether to return the probabilities of the bins. Defaults to False.
+
+ Returns:
+ dict: Dictionary of outputs with keys:
+ - "rel_depth": Relative depth map of shape (B, 1, H, W)
+ - "metric_depth": Metric depth map of shape (B, 1, H, W)
+ - "domain_logits": Domain logits of shape (B, 2)
+ - "bin_centers": Bin centers of shape (B, N, H, W). Present only if return_final_centers is True
+ - "probs": Bin probabilities of shape (B, N, H, W). Present only if return_probs is True
+ """
+ b, c, h, w = x.shape
+ self.orig_input_width = w
+ self.orig_input_height = h
+ rel_depth, out = self.core(x, denorm=denorm, return_rel_depth=True)
+
+ outconv_activation = out[0]
+ btlnck = out[1]
+ x_blocks = out[2:]
+
+ x_d0 = self.conv2(btlnck)
+ x = x_d0
+
+ # Predict which path to take
+ embedding = self.patch_transformer(x)[0] # N, E
+ domain_logits = self.mlp_classifier(embedding) # N, 2
+ domain_vote = torch.softmax(domain_logits.sum(
+ dim=0, keepdim=True), dim=-1) # 1, 2
+
+ # Get the path
+ bin_conf_name = ["nyu", "kitti"][torch.argmax(
+ domain_vote, dim=-1).squeeze().item()]
+
+ try:
+ conf = [c for c in self.bin_conf if c.name == bin_conf_name][0]
+ except IndexError:
+ raise ValueError(
+ f"bin_conf_name {bin_conf_name} not found in bin_confs")
+
+ min_depth = conf['min_depth']
+ max_depth = conf['max_depth']
+
+ seed_bin_regressor = self.seed_bin_regressors[bin_conf_name]
+ _, seed_b_centers = seed_bin_regressor(x)
+ if self.bin_centers_type == 'normed' or self.bin_centers_type == 'hybrid2':
+ b_prev = (seed_b_centers - min_depth)/(max_depth - min_depth)
+ else:
+ b_prev = seed_b_centers
+ prev_b_embedding = self.seed_projector(x)
+
+ attractors = self.attractors[bin_conf_name]
+ for projector, attractor, x in zip(self.projectors, attractors, x_blocks):
+ b_embedding = projector(x)
+ b, b_centers = attractor(
+ b_embedding, b_prev, prev_b_embedding, interpolate=True)
+ b_prev = b
+ prev_b_embedding = b_embedding
+
+ last = outconv_activation
+
+ b_centers = nn.functional.interpolate(
+ b_centers, last.shape[-2:], mode='bilinear', align_corners=True)
+ b_embedding = nn.functional.interpolate(
+ b_embedding, last.shape[-2:], mode='bilinear', align_corners=True)
+
+ clb = self.conditional_log_binomial[bin_conf_name]
+ x = clb(last, b_embedding)
+
+ # Now depth value is Sum px * cx , where cx are bin_centers from the last bin tensor
+ # print(x.shape, b_centers.shape)
+ # b_centers = nn.functional.interpolate(b_centers, x.shape[-2:], mode='bilinear', align_corners=True)
+ out = torch.sum(x * b_centers, dim=1, keepdim=True)
+
+ output = dict(domain_logits=domain_logits, metric_depth=out)
+ if return_final_centers or return_probs:
+ output['bin_centers'] = b_centers
+
+ if return_probs:
+ output['probs'] = x
+ return output
+
+ def get_lr_params(self, lr):
+ """
+ Learning rate configuration for different layers of the model
+
+ Args:
+ lr (float) : Base learning rate
+ Returns:
+ list : list of parameters to optimize and their learning rates, in the format required by torch optimizers.
+ """
+ param_conf = []
+ if self.train_midas:
+ def get_rel_pos_params():
+ for name, p in self.core.core.pretrained.named_parameters():
+ if "relative_position" in name:
+ yield p
+
+ def get_enc_params_except_rel_pos():
+ for name, p in self.core.core.pretrained.named_parameters():
+ if "relative_position" not in name:
+ yield p
+
+ encoder_params = get_enc_params_except_rel_pos()
+ rel_pos_params = get_rel_pos_params()
+ midas_params = self.core.core.scratch.parameters()
+ midas_lr_factor = self.midas_lr_factor if self.is_midas_pretrained else 1.0
+ param_conf.extend([
+ {'params': encoder_params, 'lr': lr / self.encoder_lr_factor},
+ {'params': rel_pos_params, 'lr': lr / self.pos_enc_lr_factor},
+ {'params': midas_params, 'lr': lr / midas_lr_factor}
+ ])
+
+ remaining_modules = []
+ for name, child in self.named_children():
+ if name != 'core':
+ remaining_modules.append(child)
+ remaining_params = itertools.chain(
+ *[child.parameters() for child in remaining_modules])
+ param_conf.append({'params': remaining_params, 'lr': lr})
+ return param_conf
+
+ def get_conf_parameters(self, conf_name):
+ """
+ Returns parameters of all the ModuleDicts children that are exclusively used for the given bin configuration
+ """
+ params = []
+ for name, child in self.named_children():
+ if isinstance(child, nn.ModuleDict):
+ for bin_conf_name, module in child.items():
+ if bin_conf_name == conf_name:
+ params += list(module.parameters())
+ return params
+
+ def freeze_conf(self, conf_name):
+ """
+ Freezes all the parameters of all the ModuleDicts children that are exclusively used for the given bin configuration
+ """
+ for p in self.get_conf_parameters(conf_name):
+ p.requires_grad = False
+
+ def unfreeze_conf(self, conf_name):
+ """
+ Unfreezes all the parameters of all the ModuleDicts children that are exclusively used for the given bin configuration
+ """
+ for p in self.get_conf_parameters(conf_name):
+ p.requires_grad = True
+
+ def freeze_all_confs(self):
+ """
+ Freezes all the parameters of all the ModuleDicts children
+ """
+ for name, child in self.named_children():
+ if isinstance(child, nn.ModuleDict):
+ for bin_conf_name, module in child.items():
+ for p in module.parameters():
+ p.requires_grad = False
+
+ @staticmethod
+ def build(midas_model_type="DPT_BEiT_L_384", pretrained_resource=None, use_pretrained_midas=False, train_midas=False, freeze_midas_bn=True, **kwargs):
+ core = MidasCore.build(midas_model_type=midas_model_type, use_pretrained_midas=use_pretrained_midas,
+ train_midas=train_midas, fetch_features=True, freeze_bn=freeze_midas_bn, **kwargs)
+ model = ZoeDepthNK(core, **kwargs)
+ if pretrained_resource:
+ assert isinstance(pretrained_resource, str), "pretrained_resource must be a string"
+ model = load_state_from_resource(model, pretrained_resource)
+ return model
+
+ @staticmethod
+ def build_from_config(config):
+ return ZoeDepthNK.build(**config)
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/__init__.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..1ae1a1e4e86d9a5b14586cd006ed43d2bbc9b4a6
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/__init__.py
@@ -0,0 +1,24 @@
+# MIT License
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/arg_utils.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/arg_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..5124e8c617874b6457b7dbaebeec61c166577933
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/arg_utils.py
@@ -0,0 +1,33 @@
+
+
+def infer_type(x): # hacky way to infer type from string args
+ if not isinstance(x, str):
+ return x
+
+ try:
+ x = int(x)
+ return x
+ except ValueError:
+ pass
+
+ try:
+ x = float(x)
+ return x
+ except ValueError:
+ pass
+
+ return x
+
+
+def parse_unknown(unknown_args):
+ clean = []
+ for a in unknown_args:
+ if "=" in a:
+ k, v = a.split("=")
+ clean.extend([k, v])
+ else:
+ clean.append(a)
+
+ keys = clean[::2]
+ values = clean[1::2]
+ return {k.replace("--", ""): infer_type(v) for k, v in zip(keys, values)}
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/config.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/config.py
new file mode 100644
index 0000000000000000000000000000000000000000..ff5cb7765994211de10946932a572e05901777d6
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/config.py
@@ -0,0 +1,437 @@
+# MIT License
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
+import json
+import os
+
+from .easydict import EasyDict as edict
+from .arg_utils import infer_type
+
+import pathlib
+import platform
+
+ROOT = pathlib.Path(__file__).parent.parent.resolve()
+
+HOME_DIR = os.path.expanduser("~")
+
+COMMON_CONFIG = {
+ "save_dir": os.path.expanduser("~/shortcuts/monodepth3_checkpoints"),
+ "project": "ZoeDepth",
+ "tags": '',
+ "notes": "",
+ "gpu": None,
+ "root": ".",
+ "uid": None,
+ "print_losses": False
+}
+
+DATASETS_CONFIG = {
+ "kitti": {
+ "dataset": "kitti",
+ "min_depth": 0.001,
+ "max_depth": 80,
+ "data_path": os.path.join(HOME_DIR, "shortcuts/datasets/kitti/raw"),
+ "gt_path": os.path.join(HOME_DIR, "shortcuts/datasets/kitti/gts"),
+ "filenames_file": "./train_test_inputs/kitti_eigen_train_files_with_gt.txt",
+ "input_height": 352,
+ "input_width": 1216, # 704
+ "data_path_eval": os.path.join(HOME_DIR, "shortcuts/datasets/kitti/raw"),
+ "gt_path_eval": os.path.join(HOME_DIR, "shortcuts/datasets/kitti/gts"),
+ "filenames_file_eval": "./train_test_inputs/kitti_eigen_test_files_with_gt.txt",
+
+ "min_depth_eval": 1e-3,
+ "max_depth_eval": 80,
+
+ "do_random_rotate": True,
+ "degree": 1.0,
+ "do_kb_crop": True,
+ "garg_crop": True,
+ "eigen_crop": False,
+ "use_right": False
+ },
+ "kitti_test": {
+ "dataset": "kitti",
+ "min_depth": 0.001,
+ "max_depth": 80,
+ "data_path": os.path.join(HOME_DIR, "shortcuts/datasets/kitti/raw"),
+ "gt_path": os.path.join(HOME_DIR, "shortcuts/datasets/kitti/gts"),
+ "filenames_file": "./train_test_inputs/kitti_eigen_train_files_with_gt.txt",
+ "input_height": 352,
+ "input_width": 1216,
+ "data_path_eval": os.path.join(HOME_DIR, "shortcuts/datasets/kitti/raw"),
+ "gt_path_eval": os.path.join(HOME_DIR, "shortcuts/datasets/kitti/gts"),
+ "filenames_file_eval": "./train_test_inputs/kitti_eigen_test_files_with_gt.txt",
+
+ "min_depth_eval": 1e-3,
+ "max_depth_eval": 80,
+
+ "do_random_rotate": False,
+ "degree": 1.0,
+ "do_kb_crop": True,
+ "garg_crop": True,
+ "eigen_crop": False,
+ "use_right": False
+ },
+ "nyu": {
+ "dataset": "nyu",
+ "avoid_boundary": False,
+ "min_depth": 1e-3, # originally 0.1
+ "max_depth": 10,
+ "data_path": os.path.join(HOME_DIR, "shortcuts/datasets/nyu_depth_v2/sync/"),
+ "gt_path": os.path.join(HOME_DIR, "shortcuts/datasets/nyu_depth_v2/sync/"),
+ "filenames_file": "./train_test_inputs/nyudepthv2_train_files_with_gt.txt",
+ "input_height": 480,
+ "input_width": 640,
+ "data_path_eval": os.path.join(HOME_DIR, "shortcuts/datasets/nyu_depth_v2/official_splits/test/"),
+ "gt_path_eval": os.path.join(HOME_DIR, "shortcuts/datasets/nyu_depth_v2/official_splits/test/"),
+ "filenames_file_eval": "./train_test_inputs/nyudepthv2_test_files_with_gt.txt",
+ "min_depth_eval": 1e-3,
+ "max_depth_eval": 10,
+ "min_depth_diff": -10,
+ "max_depth_diff": 10,
+
+ "do_random_rotate": True,
+ "degree": 1.0,
+ "do_kb_crop": False,
+ "garg_crop": False,
+ "eigen_crop": True
+ },
+ "ibims": {
+ "dataset": "ibims",
+ "ibims_root": os.path.join(HOME_DIR, "shortcuts/datasets/ibims/ibims1_core_raw/"),
+ "eigen_crop": True,
+ "garg_crop": False,
+ "do_kb_crop": False,
+ "min_depth_eval": 0,
+ "max_depth_eval": 10,
+ "min_depth": 1e-3,
+ "max_depth": 10
+ },
+ "sunrgbd": {
+ "dataset": "sunrgbd",
+ "sunrgbd_root": os.path.join(HOME_DIR, "shortcuts/datasets/SUNRGBD/test/"),
+ "eigen_crop": True,
+ "garg_crop": False,
+ "do_kb_crop": False,
+ "min_depth_eval": 0,
+ "max_depth_eval": 8,
+ "min_depth": 1e-3,
+ "max_depth": 10
+ },
+ "diml_indoor": {
+ "dataset": "diml_indoor",
+ "diml_indoor_root": os.path.join(HOME_DIR, "shortcuts/datasets/diml_indoor_test/"),
+ "eigen_crop": True,
+ "garg_crop": False,
+ "do_kb_crop": False,
+ "min_depth_eval": 0,
+ "max_depth_eval": 10,
+ "min_depth": 1e-3,
+ "max_depth": 10
+ },
+ "diml_outdoor": {
+ "dataset": "diml_outdoor",
+ "diml_outdoor_root": os.path.join(HOME_DIR, "shortcuts/datasets/diml_outdoor_test/"),
+ "eigen_crop": False,
+ "garg_crop": True,
+ "do_kb_crop": False,
+ "min_depth_eval": 2,
+ "max_depth_eval": 80,
+ "min_depth": 1e-3,
+ "max_depth": 80
+ },
+ "diode_indoor": {
+ "dataset": "diode_indoor",
+ "diode_indoor_root": os.path.join(HOME_DIR, "shortcuts/datasets/diode_indoor/"),
+ "eigen_crop": True,
+ "garg_crop": False,
+ "do_kb_crop": False,
+ "min_depth_eval": 1e-3,
+ "max_depth_eval": 10,
+ "min_depth": 1e-3,
+ "max_depth": 10
+ },
+ "diode_outdoor": {
+ "dataset": "diode_outdoor",
+ "diode_outdoor_root": os.path.join(HOME_DIR, "shortcuts/datasets/diode_outdoor/"),
+ "eigen_crop": False,
+ "garg_crop": True,
+ "do_kb_crop": False,
+ "min_depth_eval": 1e-3,
+ "max_depth_eval": 80,
+ "min_depth": 1e-3,
+ "max_depth": 80
+ },
+ "hypersim_test": {
+ "dataset": "hypersim_test",
+ "hypersim_test_root": os.path.join(HOME_DIR, "shortcuts/datasets/hypersim_test/"),
+ "eigen_crop": True,
+ "garg_crop": False,
+ "do_kb_crop": False,
+ "min_depth_eval": 1e-3,
+ "max_depth_eval": 80,
+ "min_depth": 1e-3,
+ "max_depth": 10
+ },
+ "vkitti": {
+ "dataset": "vkitti",
+ "vkitti_root": os.path.join(HOME_DIR, "shortcuts/datasets/vkitti_test/"),
+ "eigen_crop": False,
+ "garg_crop": True,
+ "do_kb_crop": True,
+ "min_depth_eval": 1e-3,
+ "max_depth_eval": 80,
+ "min_depth": 1e-3,
+ "max_depth": 80
+ },
+ "vkitti2": {
+ "dataset": "vkitti2",
+ "vkitti2_root": os.path.join(HOME_DIR, "shortcuts/datasets/vkitti2/"),
+ "eigen_crop": False,
+ "garg_crop": True,
+ "do_kb_crop": True,
+ "min_depth_eval": 1e-3,
+ "max_depth_eval": 80,
+ "min_depth": 1e-3,
+ "max_depth": 80,
+ },
+ "ddad": {
+ "dataset": "ddad",
+ "ddad_root": os.path.join(HOME_DIR, "shortcuts/datasets/ddad/ddad_val/"),
+ "eigen_crop": False,
+ "garg_crop": True,
+ "do_kb_crop": True,
+ "min_depth_eval": 1e-3,
+ "max_depth_eval": 80,
+ "min_depth": 1e-3,
+ "max_depth": 80,
+ },
+}
+
+ALL_INDOOR = ["nyu", "ibims", "sunrgbd", "diode_indoor", "hypersim_test"]
+ALL_OUTDOOR = ["kitti", "diml_outdoor", "diode_outdoor", "vkitti2", "ddad"]
+ALL_EVAL_DATASETS = ALL_INDOOR + ALL_OUTDOOR
+
+COMMON_TRAINING_CONFIG = {
+ "dataset": "nyu",
+ "distributed": True,
+ "workers": 16,
+ "clip_grad": 0.1,
+ "use_shared_dict": False,
+ "shared_dict": None,
+ "use_amp": False,
+
+ "aug": True,
+ "random_crop": False,
+ "random_translate": False,
+ "translate_prob": 0.2,
+ "max_translation": 100,
+
+ "validate_every": 0.25,
+ "log_images_every": 0.1,
+ "prefetch": False,
+}
+
+
+def flatten(config, except_keys=('bin_conf')):
+ def recurse(inp):
+ if isinstance(inp, dict):
+ for key, value in inp.items():
+ if key in except_keys:
+ yield (key, value)
+ if isinstance(value, dict):
+ yield from recurse(value)
+ else:
+ yield (key, value)
+
+ return dict(list(recurse(config)))
+
+
+def split_combined_args(kwargs):
+ """Splits the arguments that are combined with '__' into multiple arguments.
+ Combined arguments should have equal number of keys and values.
+ Keys are separated by '__' and Values are separated with ';'.
+ For example, '__n_bins__lr=256;0.001'
+
+ Args:
+ kwargs (dict): key-value pairs of arguments where key-value is optionally combined according to the above format.
+
+ Returns:
+ dict: Parsed dict with the combined arguments split into individual key-value pairs.
+ """
+ new_kwargs = dict(kwargs)
+ for key, value in kwargs.items():
+ if key.startswith("__"):
+ keys = key.split("__")[1:]
+ values = value.split(";")
+ assert len(keys) == len(
+ values), f"Combined arguments should have equal number of keys and values. Keys are separated by '__' and Values are separated with ';'. For example, '__n_bins__lr=256;0.001. Given (keys,values) is ({keys}, {values})"
+ for k, v in zip(keys, values):
+ new_kwargs[k] = v
+ return new_kwargs
+
+
+def parse_list(config, key, dtype=int):
+ """Parse a list of values for the key if the value is a string. The values are separated by a comma.
+ Modifies the config in place.
+ """
+ if key in config:
+ if isinstance(config[key], str):
+ config[key] = list(map(dtype, config[key].split(',')))
+ assert isinstance(config[key], list) and all([isinstance(e, dtype) for e in config[key]]
+ ), f"{key} should be a list of values dtype {dtype}. Given {config[key]} of type {type(config[key])} with values of type {[type(e) for e in config[key]]}."
+
+
+def get_model_config(model_name, model_version=None):
+ """Find and parse the .json config file for the model.
+
+ Args:
+ model_name (str): name of the model. The config file should be named config_{model_name}[_{model_version}].json under the models/{model_name} directory.
+ model_version (str, optional): Specific config version. If specified config_{model_name}_{model_version}.json is searched for and used. Otherwise config_{model_name}.json is used. Defaults to None.
+
+ Returns:
+ easydict: the config dictionary for the model.
+ """
+ config_fname = f"config_{model_name}_{model_version}.json" if model_version is not None else f"config_{model_name}.json"
+ config_file = os.path.join(ROOT, "models", model_name, config_fname)
+ if not os.path.exists(config_file):
+ return None
+
+ with open(config_file, "r") as f:
+ config = edict(json.load(f))
+
+ # handle dictionary inheritance
+ # only training config is supported for inheritance
+ if "inherit" in config.train and config.train.inherit is not None:
+ inherit_config = get_model_config(config.train["inherit"]).train
+ for key, value in inherit_config.items():
+ if key not in config.train:
+ config.train[key] = value
+ return edict(config)
+
+
+def update_model_config(config, mode, model_name, model_version=None, strict=False):
+ model_config = get_model_config(model_name, model_version)
+ if model_config is not None:
+ config = {**config, **
+ flatten({**model_config.model, **model_config[mode]})}
+ elif strict:
+ raise ValueError(f"Config file for model {model_name} not found.")
+ return config
+
+
+def check_choices(name, value, choices):
+ # return # No checks in dev branch
+ if value not in choices:
+ raise ValueError(f"{name} {value} not in supported choices {choices}")
+
+
+KEYS_TYPE_BOOL = ["use_amp", "distributed", "use_shared_dict", "same_lr", "aug", "three_phase",
+ "prefetch", "cycle_momentum"] # Casting is not necessary as their int casted values in config are 0 or 1
+
+
+def get_config(model_name, mode='train', dataset=None, **overwrite_kwargs):
+ """Main entry point to get the config for the model.
+
+ Args:
+ model_name (str): name of the desired model.
+ mode (str, optional): "train" or "infer". Defaults to 'train'.
+ dataset (str, optional): If specified, the corresponding dataset configuration is loaded as well. Defaults to None.
+
+ Keyword Args: key-value pairs of arguments to overwrite the default config.
+
+ The order of precedence for overwriting the config is (Higher precedence first):
+ # 1. overwrite_kwargs
+ # 2. "config_version": Config file version if specified in overwrite_kwargs. The corresponding config loaded is config_{model_name}_{config_version}.json
+ # 3. "version_name": Default Model version specific config specified in overwrite_kwargs. The corresponding config loaded is config_{model_name}_{version_name}.json
+ # 4. common_config: Default config for all models specified in COMMON_CONFIG
+
+ Returns:
+ easydict: The config dictionary for the model.
+ """
+
+
+ check_choices("Model", model_name, ["zoedepth", "zoedepth_nk"])
+ check_choices("Mode", mode, ["train", "infer", "eval"])
+ if mode == "train":
+ check_choices("Dataset", dataset, ["nyu", "kitti", "mix", None])
+
+ config = flatten({**COMMON_CONFIG, **COMMON_TRAINING_CONFIG})
+ config = update_model_config(config, mode, model_name)
+
+ # update with model version specific config
+ version_name = overwrite_kwargs.get("version_name", config["version_name"])
+ config = update_model_config(config, mode, model_name, version_name)
+
+ # update with config version if specified
+ config_version = overwrite_kwargs.get("config_version", None)
+ if config_version is not None:
+ print("Overwriting config with config_version", config_version)
+ config = update_model_config(config, mode, model_name, config_version)
+
+ # update with overwrite_kwargs
+ # Combined args are useful for hyperparameter search
+ overwrite_kwargs = split_combined_args(overwrite_kwargs)
+ config = {**config, **overwrite_kwargs}
+
+ # Casting to bool # TODO: Not necessary. Remove and test
+ for key in KEYS_TYPE_BOOL:
+ if key in config:
+ config[key] = bool(config[key])
+
+ # Model specific post processing of config
+ parse_list(config, "n_attractors")
+
+ # adjust n_bins for each bin configuration if bin_conf is given and n_bins is passed in overwrite_kwargs
+ if 'bin_conf' in config and 'n_bins' in overwrite_kwargs:
+ bin_conf = config['bin_conf'] # list of dicts
+ n_bins = overwrite_kwargs['n_bins']
+ new_bin_conf = []
+ for conf in bin_conf:
+ conf['n_bins'] = n_bins
+ new_bin_conf.append(conf)
+ config['bin_conf'] = new_bin_conf
+
+ if mode == "train":
+ orig_dataset = dataset
+ if dataset == "mix":
+ dataset = 'nyu' # Use nyu as default for mix. Dataset config is changed accordingly while loading the dataloader
+ if dataset is not None:
+ config['project'] = f"MonoDepth3-{orig_dataset}" # Set project for wandb
+
+ if dataset is not None:
+ config['dataset'] = dataset
+ config = {**DATASETS_CONFIG[dataset], **config}
+
+
+ config['model'] = model_name
+ typed_config = {k: infer_type(v) for k, v in config.items()}
+ # add hostname to config
+ config['hostname'] = platform.node()
+ return edict(typed_config)
+
+
+def change_dataset(config, new_dataset):
+ config.update(DATASETS_CONFIG[new_dataset])
+ return config
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/easydict/__init__.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/easydict/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..0d0c83507325193c88566ae0c6aa1347dd41c411
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/easydict/__init__.py
@@ -0,0 +1,158 @@
+"""
+EasyDict
+Copy/pasted from https://github.com/makinacorpus/easydict
+Original author: Mathieu Leplatre
+"""
+
+class EasyDict(dict):
+ """
+ Get attributes
+
+ >>> d = EasyDict({'foo':3})
+ >>> d['foo']
+ 3
+ >>> d.foo
+ 3
+ >>> d.bar
+ Traceback (most recent call last):
+ ...
+ AttributeError: 'EasyDict' object has no attribute 'bar'
+
+ Works recursively
+
+ >>> d = EasyDict({'foo':3, 'bar':{'x':1, 'y':2}})
+ >>> isinstance(d.bar, dict)
+ True
+ >>> d.bar.x
+ 1
+
+ Bullet-proof
+
+ >>> EasyDict({})
+ {}
+ >>> EasyDict(d={})
+ {}
+ >>> EasyDict(None)
+ {}
+ >>> d = {'a': 1}
+ >>> EasyDict(**d)
+ {'a': 1}
+ >>> EasyDict((('a', 1), ('b', 2)))
+ {'a': 1, 'b': 2}
+
+ Set attributes
+
+ >>> d = EasyDict()
+ >>> d.foo = 3
+ >>> d.foo
+ 3
+ >>> d.bar = {'prop': 'value'}
+ >>> d.bar.prop
+ 'value'
+ >>> d
+ {'foo': 3, 'bar': {'prop': 'value'}}
+ >>> d.bar.prop = 'newer'
+ >>> d.bar.prop
+ 'newer'
+
+
+ Values extraction
+
+ >>> d = EasyDict({'foo':0, 'bar':[{'x':1, 'y':2}, {'x':3, 'y':4}]})
+ >>> isinstance(d.bar, list)
+ True
+ >>> from operator import attrgetter
+ >>> list(map(attrgetter('x'), d.bar))
+ [1, 3]
+ >>> list(map(attrgetter('y'), d.bar))
+ [2, 4]
+ >>> d = EasyDict()
+ >>> list(d.keys())
+ []
+ >>> d = EasyDict(foo=3, bar=dict(x=1, y=2))
+ >>> d.foo
+ 3
+ >>> d.bar.x
+ 1
+
+ Still like a dict though
+
+ >>> o = EasyDict({'clean':True})
+ >>> list(o.items())
+ [('clean', True)]
+
+ And like a class
+
+ >>> class Flower(EasyDict):
+ ... power = 1
+ ...
+ >>> f = Flower()
+ >>> f.power
+ 1
+ >>> f = Flower({'height': 12})
+ >>> f.height
+ 12
+ >>> f['power']
+ 1
+ >>> sorted(f.keys())
+ ['height', 'power']
+
+ update and pop items
+ >>> d = EasyDict(a=1, b='2')
+ >>> e = EasyDict(c=3.0, a=9.0)
+ >>> d.update(e)
+ >>> d.c
+ 3.0
+ >>> d['c']
+ 3.0
+ >>> d.get('c')
+ 3.0
+ >>> d.update(a=4, b=4)
+ >>> d.b
+ 4
+ >>> d.pop('a')
+ 4
+ >>> d.a
+ Traceback (most recent call last):
+ ...
+ AttributeError: 'EasyDict' object has no attribute 'a'
+ """
+ def __init__(self, d=None, **kwargs):
+ if d is None:
+ d = {}
+ else:
+ d = dict(d)
+ if kwargs:
+ d.update(**kwargs)
+ for k, v in d.items():
+ setattr(self, k, v)
+ # Class attributes
+ for k in self.__class__.__dict__.keys():
+ if not (k.startswith('__') and k.endswith('__')) and not k in ('update', 'pop'):
+ setattr(self, k, getattr(self, k))
+
+ def __setattr__(self, name, value):
+ if isinstance(value, (list, tuple)):
+ value = [self.__class__(x)
+ if isinstance(x, dict) else x for x in value]
+ elif isinstance(value, dict) and not isinstance(value, self.__class__):
+ value = self.__class__(value)
+ super(EasyDict, self).__setattr__(name, value)
+ super(EasyDict, self).__setitem__(name, value)
+
+ __setitem__ = __setattr__
+
+ def update(self, e=None, **f):
+ d = e or dict()
+ d.update(f)
+ for k in d:
+ setattr(self, k, d[k])
+
+ def pop(self, k, d=None):
+ delattr(self, k)
+ return super(EasyDict, self).pop(k, d)
+
+
+if __name__ == "__main__":
+ import doctest
+ doctest.testmod()
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/geometry.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/geometry.py
new file mode 100644
index 0000000000000000000000000000000000000000..5b405f2c90efb002c7382d159f35a8a58adacd24
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/geometry.py
@@ -0,0 +1,98 @@
+# MIT License
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
+import numpy as np
+
+def get_intrinsics(H,W):
+ """
+ Intrinsics for a pinhole camera model.
+ Assume fov of 55 degrees and central principal point.
+ """
+ f = 0.5 * W / np.tan(0.5 * 55 * np.pi / 180.0)
+ cx = 0.5 * W
+ cy = 0.5 * H
+ return np.array([[f, 0, cx],
+ [0, f, cy],
+ [0, 0, 1]])
+
+def depth_to_points(depth, R=None, t=None):
+
+ K = get_intrinsics(depth.shape[1], depth.shape[2])
+ Kinv = np.linalg.inv(K)
+ if R is None:
+ R = np.eye(3)
+ if t is None:
+ t = np.zeros(3)
+
+ # M converts from your coordinate to PyTorch3D's coordinate system
+ M = np.eye(3)
+ M[0, 0] = -1.0
+ M[1, 1] = -1.0
+
+ height, width = depth.shape[1:3]
+
+ x = np.arange(width)
+ y = np.arange(height)
+ coord = np.stack(np.meshgrid(x, y), -1)
+ coord = np.concatenate((coord, np.ones_like(coord)[:, :, [0]]), -1) # z=1
+ coord = coord.astype(np.float32)
+ # coord = torch.as_tensor(coord, dtype=torch.float32, device=device)
+ coord = coord[None] # bs, h, w, 3
+
+ D = depth[:, :, :, None, None]
+ # print(D.shape, Kinv[None, None, None, ...].shape, coord[:, :, :, :, None].shape )
+ pts3D_1 = D * Kinv[None, None, None, ...] @ coord[:, :, :, :, None]
+ # pts3D_1 live in your coordinate system. Convert them to Py3D's
+ pts3D_1 = M[None, None, None, ...] @ pts3D_1
+ # from reference to targe tviewpoint
+ pts3D_2 = R[None, None, None, ...] @ pts3D_1 + t[None, None, None, :, None]
+ # pts3D_2 = pts3D_1
+ # depth_2 = pts3D_2[:, :, :, 2, :] # b,1,h,w
+ return pts3D_2[:, :, :, :3, 0][0]
+
+
+def create_triangles(h, w, mask=None):
+ """
+ Reference: https://github.com/google-research/google-research/blob/e96197de06613f1b027d20328e06d69829fa5a89/infinite_nature/render_utils.py#L68
+ Creates mesh triangle indices from a given pixel grid size.
+ This function is not and need not be differentiable as triangle indices are
+ fixed.
+ Args:
+ h: (int) denoting the height of the image.
+ w: (int) denoting the width of the image.
+ Returns:
+ triangles: 2D numpy array of indices (int) with shape (2(W-1)(H-1) x 3)
+ """
+ x, y = np.meshgrid(range(w - 1), range(h - 1))
+ tl = y * w + x
+ tr = y * w + x + 1
+ bl = (y + 1) * w + x
+ br = (y + 1) * w + x + 1
+ triangles = np.array([tl, bl, tr, br, tr, bl])
+ triangles = np.transpose(triangles, (1, 2, 0)).reshape(
+ ((w - 1) * (h - 1) * 2, 3))
+ if mask is not None:
+ mask = mask.reshape(-1)
+ triangles = triangles[mask[triangles].all(1)]
+ return triangles
diff --git a/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/misc.py b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/misc.py
new file mode 100644
index 0000000000000000000000000000000000000000..9fc1d469d1d7d831cd247f4c6634c957c2c9aba7
--- /dev/null
+++ b/VideoX-Fun/comfyui/annotator/zoe/zoedepth/utils/misc.py
@@ -0,0 +1,368 @@
+# MIT License
+
+# Copyright (c) 2022 Intelligent Systems Lab Org
+
+# Permission is hereby granted, free of charge, to any person obtaining a copy
+# of this software and associated documentation files (the "Software"), to deal
+# in the Software without restriction, including without limitation the rights
+# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+# copies of the Software, and to permit persons to whom the Software is
+# furnished to do so, subject to the following conditions:
+
+# The above copyright notice and this permission notice shall be included in all
+# copies or substantial portions of the Software.
+
+# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+# SOFTWARE.
+
+# File author: Shariq Farooq Bhat
+
+"""Miscellaneous utility functions."""
+
+from scipy import ndimage
+
+import base64
+import math
+import re
+from io import BytesIO
+
+import matplotlib
+import matplotlib.cm
+import numpy as np
+import requests
+import torch
+import torch.distributed as dist
+import torch.nn
+import torch.nn as nn
+import torch.utils.data.distributed
+from PIL import Image
+from torchvision.transforms import ToTensor
+
+
+class RunningAverage:
+ def __init__(self):
+ self.avg = 0
+ self.count = 0
+
+ def append(self, value):
+ self.avg = (value + self.count * self.avg) / (self.count + 1)
+ self.count += 1
+
+ def get_value(self):
+ return self.avg
+
+
+def denormalize(x):
+ """Reverses the imagenet normalization applied to the input.
+
+ Args:
+ x (torch.Tensor - shape(N,3,H,W)): input tensor
+
+ Returns:
+ torch.Tensor - shape(N,3,H,W): Denormalized input
+ """
+ mean = torch.Tensor([0.485, 0.456, 0.406]).view(1, 3, 1, 1).to(x.device)
+ std = torch.Tensor([0.229, 0.224, 0.225]).view(1, 3, 1, 1).to(x.device)
+ return x * std + mean
+
+
+class RunningAverageDict:
+ """A dictionary of running averages."""
+ def __init__(self):
+ self._dict = None
+
+ def update(self, new_dict):
+ if new_dict is None:
+ return
+
+ if self._dict is None:
+ self._dict = dict()
+ for key, value in new_dict.items():
+ self._dict[key] = RunningAverage()
+
+ for key, value in new_dict.items():
+ self._dict[key].append(value)
+
+ def get_value(self):
+ if self._dict is None:
+ return None
+ return {key: value.get_value() for key, value in self._dict.items()}
+
+
+def colorize(value, vmin=None, vmax=None, cmap='gray_r', invalid_val=-99, invalid_mask=None, background_color=(128, 128, 128, 255), gamma_corrected=False, value_transform=None):
+ """Converts a depth map to a color image.
+
+ Args:
+ value (torch.Tensor, numpy.ndarry): Input depth map. Shape: (H, W) or (1, H, W) or (1, 1, H, W). All singular dimensions are squeezed
+ vmin (float, optional): vmin-valued entries are mapped to start color of cmap. If None, value.min() is used. Defaults to None.
+ vmax (float, optional): vmax-valued entries are mapped to end color of cmap. If None, value.max() is used. Defaults to None.
+ cmap (str, optional): matplotlib colormap to use. Defaults to 'magma_r'.
+ invalid_val (int, optional): Specifies value of invalid pixels that should be colored as 'background_color'. Defaults to -99.
+ invalid_mask (numpy.ndarray, optional): Boolean mask for invalid regions. Defaults to None.
+ background_color (tuple[int], optional): 4-tuple RGB color to give to invalid pixels. Defaults to (128, 128, 128, 255).
+ gamma_corrected (bool, optional): Apply gamma correction to colored image. Defaults to False.
+ value_transform (Callable, optional): Apply transform function to valid pixels before coloring. Defaults to None.
+
+ Returns:
+ numpy.ndarray, dtype - uint8: Colored depth map. Shape: (H, W, 4)
+ """
+ if isinstance(value, torch.Tensor):
+ value = value.detach().cpu().numpy()
+
+ value = value.squeeze()
+ if invalid_mask is None:
+ invalid_mask = value == invalid_val
+ mask = np.logical_not(invalid_mask)
+
+ # normalize
+ vmin = np.percentile(value[mask],2) if vmin is None else vmin
+ vmax = np.percentile(value[mask],85) if vmax is None else vmax
+ if vmin != vmax:
+ value = (value - vmin) / (vmax - vmin) # vmin..vmax
+ else:
+ # Avoid 0-division
+ value = value * 0.
+
+ # squeeze last dim if it exists
+ # grey out the invalid values
+
+ value[invalid_mask] = np.nan
+ cmapper = matplotlib.cm.get_cmap(cmap)
+ if value_transform:
+ value = value_transform(value)
+ # value = value / value.max()
+ value = cmapper(value, bytes=True) # (nxmx4)
+
+ # img = value[:, :, :]
+ img = value[...]
+ img[invalid_mask] = background_color
+
+ # return img.transpose((2, 0, 1))
+ if gamma_corrected:
+ # gamma correction
+ img = img / 255
+ img = np.power(img, 2.2)
+ img = img * 255
+ img = img.astype(np.uint8)
+ return img
+
+
+def count_parameters(model, include_all=False):
+ return sum(p.numel() for p in model.parameters() if p.requires_grad or include_all)
+
+
+def compute_errors(gt, pred):
+ """Compute metrics for 'pred' compared to 'gt'
+
+ Args:
+ gt (numpy.ndarray): Ground truth values
+ pred (numpy.ndarray): Predicted values
+
+ gt.shape should be equal to pred.shape
+
+ Returns:
+ dict: Dictionary containing the following metrics:
+ 'a1': Delta1 accuracy: Fraction of pixels that are within a scale factor of 1.25
+ 'a2': Delta2 accuracy: Fraction of pixels that are within a scale factor of 1.25^2
+ 'a3': Delta3 accuracy: Fraction of pixels that are within a scale factor of 1.25^3
+ 'abs_rel': Absolute relative error
+ 'rmse': Root mean squared error
+ 'log_10': Absolute log10 error
+ 'sq_rel': Squared relative error
+ 'rmse_log': Root mean squared error on the log scale
+ 'silog': Scale invariant log error
+ """
+ thresh = np.maximum((gt / pred), (pred / gt))
+ a1 = (thresh < 1.25).mean()
+ a2 = (thresh < 1.25 ** 2).mean()
+ a3 = (thresh < 1.25 ** 3).mean()
+
+ abs_rel = np.mean(np.abs(gt - pred) / gt)
+ sq_rel = np.mean(((gt - pred) ** 2) / gt)
+
+ rmse = (gt - pred) ** 2
+ rmse = np.sqrt(rmse.mean())
+
+ rmse_log = (np.log(gt) - np.log(pred)) ** 2
+ rmse_log = np.sqrt(rmse_log.mean())
+
+ err = np.log(pred) - np.log(gt)
+ silog = np.sqrt(np.mean(err ** 2) - np.mean(err) ** 2) * 100
+
+ log_10 = (np.abs(np.log10(gt) - np.log10(pred))).mean()
+ return dict(a1=a1, a2=a2, a3=a3, abs_rel=abs_rel, rmse=rmse, log_10=log_10, rmse_log=rmse_log,
+ silog=silog, sq_rel=sq_rel)
+
+
+def compute_metrics(gt, pred, interpolate=True, garg_crop=False, eigen_crop=True, dataset='nyu', min_depth_eval=0.1, max_depth_eval=10, **kwargs):
+ """Compute metrics of predicted depth maps. Applies cropping and masking as necessary or specified via arguments. Refer to compute_errors for more details on metrics.
+ """
+ if 'config' in kwargs:
+ config = kwargs['config']
+ garg_crop = config.garg_crop
+ eigen_crop = config.eigen_crop
+ min_depth_eval = config.min_depth_eval
+ max_depth_eval = config.max_depth_eval
+
+ if gt.shape[-2:] != pred.shape[-2:] and interpolate:
+ pred = nn.functional.interpolate(
+ pred, gt.shape[-2:], mode='bilinear', align_corners=True)
+
+ pred = pred.squeeze().cpu().numpy()
+ pred[pred < min_depth_eval] = min_depth_eval
+ pred[pred > max_depth_eval] = max_depth_eval
+ pred[np.isinf(pred)] = max_depth_eval
+ pred[np.isnan(pred)] = min_depth_eval
+
+ gt_depth = gt.squeeze().cpu().numpy()
+ valid_mask = np.logical_and(
+ gt_depth > min_depth_eval, gt_depth < max_depth_eval)
+
+ if garg_crop or eigen_crop:
+ gt_height, gt_width = gt_depth.shape
+ eval_mask = np.zeros(valid_mask.shape)
+
+ if garg_crop:
+ eval_mask[int(0.40810811 * gt_height):int(0.99189189 * gt_height),
+ int(0.03594771 * gt_width):int(0.96405229 * gt_width)] = 1
+
+ elif eigen_crop:
+ # print("-"*10, " EIGEN CROP ", "-"*10)
+ if dataset == 'kitti':
+ eval_mask[int(0.3324324 * gt_height):int(0.91351351 * gt_height),
+ int(0.0359477 * gt_width):int(0.96405229 * gt_width)] = 1
+ else:
+ # assert gt_depth.shape == (480, 640), "Error: Eigen crop is currently only valid for (480, 640) images"
+ eval_mask[45:471, 41:601] = 1
+ else:
+ eval_mask = np.ones(valid_mask.shape)
+ valid_mask = np.logical_and(valid_mask, eval_mask)
+ return compute_errors(gt_depth[valid_mask], pred[valid_mask])
+
+
+#################################### Model uilts ################################################
+
+
+def parallelize(config, model, find_unused_parameters=True):
+
+ if config.gpu is not None:
+ torch.cuda.set_device(config.gpu)
+ model = model.cuda(config.gpu)
+
+ config.multigpu = False
+ if config.distributed:
+ # Use DDP
+ config.multigpu = True
+ config.rank = config.rank * config.ngpus_per_node + config.gpu
+ dist.init_process_group(backend=config.dist_backend, init_method=config.dist_url,
+ world_size=config.world_size, rank=config.rank)
+ config.batch_size = int(config.batch_size / config.ngpus_per_node)
+ # config.batch_size = 8
+ config.workers = int(
+ (config.num_workers + config.ngpus_per_node - 1) / config.ngpus_per_node)
+ print("Device", config.gpu, "Rank", config.rank, "batch size",
+ config.batch_size, "Workers", config.workers)
+ torch.cuda.set_device(config.gpu)
+ model = nn.SyncBatchNorm.convert_sync_batchnorm(model)
+ model = model.cuda(config.gpu)
+ model = torch.nn.parallel.DistributedDataParallel(model, device_ids=[config.gpu], output_device=config.gpu,
+ find_unused_parameters=find_unused_parameters)
+
+ elif config.gpu is None:
+ # Use DP
+ config.multigpu = True
+ model = model.cuda()
+ model = torch.nn.DataParallel(model)
+
+ return model
+
+
+#################################################################################################
+
+
+#####################################################################################################
+
+
+class colors:
+ '''Colors class:
+ Reset all colors with colors.reset
+ Two subclasses fg for foreground and bg for background.
+ Use as colors.subclass.colorname.
+ i.e. colors.fg.red or colors.bg.green
+ Also, the generic bold, disable, underline, reverse, strikethrough,
+ and invisible work with the main class
+ i.e. colors.bold
+ '''
+ reset = '\033[0m'
+ bold = '\033[01m'
+ disable = '\033[02m'
+ underline = '\033[04m'
+ reverse = '\033[07m'
+ strikethrough = '\033[09m'
+ invisible = '\033[08m'
+
+ class fg:
+ black = '\033[30m'
+ red = '\033[31m'
+ green = '\033[32m'
+ orange = '\033[33m'
+ blue = '\033[34m'
+ purple = '\033[35m'
+ cyan = '\033[36m'
+ lightgrey = '\033[37m'
+ darkgrey = '\033[90m'
+ lightred = '\033[91m'
+ lightgreen = '\033[92m'
+ yellow = '\033[93m'
+ lightblue = '\033[94m'
+ pink = '\033[95m'
+ lightcyan = '\033[96m'
+
+ class bg:
+ black = '\033[40m'
+ red = '\033[41m'
+ green = '\033[42m'
+ orange = '\033[43m'
+ blue = '\033[44m'
+ purple = '\033[45m'
+ cyan = '\033[46m'
+ lightgrey = '\033[47m'
+
+
+def printc(text, color):
+ print(f"{color}{text}{colors.reset}")
+
+############################################
+
+def get_image_from_url(url):
+ response = requests.get(url)
+ img = Image.open(BytesIO(response.content)).convert("RGB")
+ return img
+
+def url_to_torch(url, size=(384, 384)):
+ img = get_image_from_url(url)
+ img = img.resize(size, Image.ANTIALIAS)
+ img = torch.from_numpy(np.asarray(img)).float()
+ img = img.permute(2, 0, 1)
+ img.div_(255)
+ return img
+
+def pil_to_batched_tensor(img):
+ return ToTensor()(img).unsqueeze(0)
+
+def save_raw_16bit(depth, fpath="raw.png"):
+ if isinstance(depth, torch.Tensor):
+ depth = depth.squeeze().cpu().numpy()
+
+ assert isinstance(depth, np.ndarray), "Depth must be a torch tensor or numpy array"
+ assert depth.ndim == 2, "Depth must be 2D"
+ depth = depth * 256 # scale for 16-bit png
+ depth = depth.astype(np.uint16)
+ depth = Image.fromarray(depth)
+ depth.save(fpath)
+ print("Saved raw depth to", fpath)
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/camera_utils.py b/VideoX-Fun/comfyui/camera_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..efd05586b0c1c5fa24c9ae539da1ebbc72bdc575
--- /dev/null
+++ b/VideoX-Fun/comfyui/camera_utils.py
@@ -0,0 +1,80 @@
+"""Modified from https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper/blob/main/camera_utils.py
+"""
+import copy
+import numpy as np
+
+CAMERA = {
+ # T
+ "base_T_norm": 1.5,
+ "base_angle": np.pi/3,
+
+ "Static": { "angle":[0., 0., 0.], "T":[0., 0., 0.]},
+ "Pan Up": { "angle":[0., 0., 0.], "T":[0., 1., 0.]},
+ "Pan Down": { "angle":[0., 0., 0.], "T":[0.,-1.,0.]},
+ "Pan Left": { "angle":[0., 0., 0.], "T":[1.,0.,0.]},
+ "Pan Right": { "angle":[0., 0., 0.], "T": [-1.,0.,0.]},
+ "Zoom In": { "angle":[0., 0., 0.], "T": [0.,0.,-2.]},
+ "Zoom Out": { "angle":[0., 0., 0.], "T": [0.,0.,2.]},
+ "ACW": { "angle": [0., 0., 1.], "T":[0., 0., 0.]},
+ "CW": { "angle": [0., 0., -1.], "T":[0., 0., 0.]},
+}
+
+def compute_R_form_rad_angle(angles):
+ theta_x, theta_y, theta_z = angles
+ Rx = np.array([[1, 0, 0],
+ [0, np.cos(theta_x), -np.sin(theta_x)],
+ [0, np.sin(theta_x), np.cos(theta_x)]])
+
+ Ry = np.array([[np.cos(theta_y), 0, np.sin(theta_y)],
+ [0, 1, 0],
+ [-np.sin(theta_y), 0, np.cos(theta_y)]])
+
+ Rz = np.array([[np.cos(theta_z), -np.sin(theta_z), 0],
+ [np.sin(theta_z), np.cos(theta_z), 0],
+ [0, 0, 1]])
+
+ # 计算相机外参的旋转矩阵
+ R = np.dot(Rz, np.dot(Ry, Rx))
+ return R
+
+def get_camera_motion(angle, T, speed, n=16):
+ RT = []
+ for i in range(n):
+ _angle = (i/n)*speed*(CAMERA["base_angle"])*angle
+ R = compute_R_form_rad_angle(_angle)
+ # _T = (i/n)*speed*(T.reshape(3,1))
+ _T=(i/n)*speed*(CAMERA["base_T_norm"])*(T.reshape(3,1))
+ _RT = np.concatenate([R,_T], axis=1)
+ RT.append(_RT)
+ RT = np.stack(RT)
+ return RT
+
+def create_relative(RT_list, K_1=4.7, dataset="syn"):
+ RT = copy.deepcopy(RT_list[0])
+ R_inv = RT[:,:3].T
+ T = RT[:,-1]
+
+ temp = []
+ for _RT in RT_list:
+ _RT[:,:3] = np.dot(_RT[:,:3], R_inv)
+ _RT[:,-1] = _RT[:,-1] - np.dot(_RT[:,:3], T)
+ temp.append(_RT)
+ RT_list = temp
+
+ return RT_list
+
+def combine_camera_motion(RT_0, RT_1):
+ RT = copy.deepcopy(RT_0[-1])
+ R = RT[:,:3]
+ R_inv = RT[:,:3].T
+ T = RT[:,-1]
+
+ temp = []
+ for _RT in RT_1:
+ _RT[:,:3] = np.dot(_RT[:,:3], R)
+ _RT[:,-1] = _RT[:,-1] + np.dot(np.dot(_RT[:,:3], R_inv), T)
+ temp.append(_RT)
+
+ RT_1 = np.stack(temp)
+
+ return np.concatenate([RT_0, RT_1], axis=0)
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/cogvideox_fun/nodes.py b/VideoX-Fun/comfyui/cogvideox_fun/nodes.py
new file mode 100644
index 0000000000000000000000000000000000000000..963bf22b7788aee4cf9c754447aa9ce038f80802
--- /dev/null
+++ b/VideoX-Fun/comfyui/cogvideox_fun/nodes.py
@@ -0,0 +1,682 @@
+"""Modified from https://github.com/kijai/ComfyUI-EasyAnimateWrapper/blob/main/nodes.py
+"""
+import gc
+import json
+import os
+
+import comfy.model_management as mm
+import cv2
+import folder_paths
+import copy
+import numpy as np
+import torch
+from comfy.utils import ProgressBar, load_torch_file
+from diffusers import EulerDiscreteScheduler
+from einops import rearrange
+from PIL import Image
+
+from ...videox_fun.data.bucket_sampler import (ASPECT_RATIO_512,
+ get_closest_ratio)
+from ...videox_fun.models import (AutoencoderKLCogVideoX,
+ CogVideoXTransformer3DModel, T5EncoderModel,
+ T5Tokenizer)
+from ...videox_fun.pipeline import (CogVideoXFunPipeline,
+ CogVideoXFunControlPipeline,
+ CogVideoXFunInpaintPipeline)
+from ...videox_fun.ui.controller import all_cheduler_dict
+from ...videox_fun.utils.lora_utils import merge_lora, unmerge_lora
+from ...videox_fun.utils.utils import (get_image_to_video_latent,
+ get_video_to_video_latent,
+ save_videos_grid)
+from ...videox_fun.utils.fp8_optimization import convert_weight_dtype_wrapper
+from ..comfyui_utils import eas_cache_dir, to_pil
+
+# Used in lora cache
+transformer_cpu_cache = {}
+# lora path before
+lora_path_before = ""
+
+class LoadCogVideoXFunModel:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "model": (
+ [
+ 'CogVideoX-Fun-2b-InP',
+ 'CogVideoX-Fun-5b-InP',
+ 'CogVideoX-Fun-V1.1-2b-InP',
+ 'CogVideoX-Fun-V1.1-5b-InP',
+ 'CogVideoX-Fun-V1.1-2b-Pose',
+ 'CogVideoX-Fun-V1.1-5b-Pose',
+ "CogVideoX-Fun-V1.1-2b-Control",
+ 'CogVideoX-Fun-V1.1-5b-Control',
+ 'CogVideoX-Fun-V1.5-5b-InP',
+ ],
+ {
+ "default": 'CogVideoX-Fun-V1.1-2b-InP',
+ }
+ ),
+ "model_type": (
+ ["Inpaint", "Control"],
+ {
+ "default": "Inpaint",
+ }
+ ),
+ "GPU_memory_mode":(
+ ["model_full_load", "model_cpu_offload", "model_cpu_offload_and_qfloat8", "sequential_cpu_offload"],
+ {
+ "default": "model_cpu_offload",
+ }
+ ),
+ "precision": (
+ ['fp16', 'bf16'],
+ {
+ "default": 'fp16'
+ }
+ ),
+ },
+ }
+
+ RETURN_TYPES = ("FunModels",)
+ RETURN_NAMES = ("cogvideoxfun_model",)
+ FUNCTION = "loadmodel"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def loadmodel(self, GPU_memory_mode, model, model_type, precision):
+ # Init weight_dtype and device
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+ weight_dtype = {"bf16": torch.bfloat16, "fp16": torch.float16, "fp32": torch.float32}[precision]
+
+ # Init processbar
+ pbar = ProgressBar(5)
+
+ # Detect model is existing or not
+ possible_folders = ["CogVideoX_Fun", "Fun_Models", "VideoX_Fun"] + \
+ [os.path.join(os.path.dirname(os.path.dirname(os.path.dirname(os.path.abspath(__file__)))), "models/Diffusion_Transformer")] # Possible folder names to check
+ # Initialize model_name as None
+ model_name = None
+
+ # Check if the model exists in any of the possible folders within folder_paths.models_dir
+ for folder in possible_folders:
+ candidate_path = os.path.join(folder_paths.models_dir, folder, model)
+ if os.path.exists(candidate_path):
+ model_name = candidate_path
+ break
+
+ # If model_name is still None, check eas_cache_dir for each possible folder
+ if model_name is None and os.path.exists(eas_cache_dir):
+ for folder in possible_folders:
+ candidate_path = os.path.join(eas_cache_dir, folder, model)
+ if os.path.exists(candidate_path):
+ model_name = candidate_path
+ break
+
+ # If model_name is still None, prompt the user to download the model
+ if model_name is None:
+ print(f"Please download cogvideoxfun model to one of the following directories:")
+ for folder in possible_folders:
+ print(f"- {os.path.join(folder_paths.models_dir, folder)}")
+ if os.path.exists(eas_cache_dir):
+ print(f"- {os.path.join(eas_cache_dir, folder)}")
+ raise ValueError("Please download Fun model")
+
+ vae = AutoencoderKLCogVideoX.from_pretrained(
+ model_name,
+ subfolder="vae",
+ ).to(weight_dtype)
+ # Update pbar
+ pbar.update(1)
+
+ # Load Sampler
+ print("Load Sampler.")
+ scheduler = EulerDiscreteScheduler.from_pretrained(model_name, subfolder='scheduler')
+ # Update pbar
+ pbar.update(1)
+
+ # Get Transformer
+ transformer = CogVideoXTransformer3DModel.from_pretrained(
+ model_name,
+ subfolder="transformer",
+ torch_dtype=torch.float8_e4m3fn if GPU_memory_mode == "model_cpu_offload_and_qfloat8" else weight_dtype,
+ ).to(weight_dtype)
+ # Update pbar
+ pbar.update(1)
+
+ # Get tokenizer and text_encoder
+ tokenizer = T5Tokenizer.from_pretrained(
+ model_name, subfolder="tokenizer"
+ )
+ pbar.update(1)
+
+ text_encoder = T5EncoderModel.from_pretrained(
+ model_name, subfolder="text_encoder", torch_dtype=weight_dtype
+ )
+ pbar.update(1)
+
+ # Get pipeline
+ if model_type == "Inpaint":
+ if transformer.config.in_channels != vae.config.latent_channels:
+ pipeline = CogVideoXFunInpaintPipeline(
+ vae=vae,
+ tokenizer=tokenizer,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ scheduler=scheduler,
+ )
+ else:
+ pipeline = CogVideoXFunPipeline(
+ vae=vae,
+ tokenizer=tokenizer,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ scheduler=scheduler,
+ )
+ else:
+ pipeline = CogVideoXFunControlPipeline(
+ vae=vae,
+ tokenizer=tokenizer,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ scheduler=scheduler,
+ )
+ if GPU_memory_mode == "sequential_cpu_offload":
+ pipeline.enable_sequential_cpu_offload()
+ elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
+ convert_weight_dtype_wrapper(transformer, weight_dtype)
+ pipeline.enable_model_cpu_offload()
+ elif GPU_memory_mode == "model_cpu_offload":
+ pipeline.enable_model_cpu_offload()
+ elif GPU_memory_mode == "model_full_load_and_qfloat8":
+ convert_weight_dtype_wrapper(transformer, weight_dtype)
+ pipeline.to(device=device)
+ else:
+ pipeline.to("cuda")
+
+ cogvideoxfun_model = {
+ 'pipeline': pipeline,
+ 'dtype': weight_dtype,
+ 'model_name': model_name,
+ 'model_type': model_type,
+ 'loras': [],
+ 'strength_model': [],
+ }
+ return (cogvideoxfun_model,)
+
+class LoadCogVideoXFunLora:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "cogvideoxfun_model": ("FunModels",),
+ "lora_name": (folder_paths.get_filename_list("loras"), {"default": None,}),
+ "strength_model": ("FLOAT", {"default": 1.0, "min": -100.0, "max": 100.0, "step": 0.01}),
+ "lora_cache":([False, True], {"default": False,}),
+ }
+ }
+ RETURN_TYPES = ("FunModels",)
+ RETURN_NAMES = ("cogvideoxfun_model",)
+ FUNCTION = "load_lora"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def load_lora(self, cogvideoxfun_model, lora_name, strength_model, lora_cache):
+ if lora_name is not None:
+ cogvideoxfun_model['lora_cache'] = lora_cache
+ cogvideoxfun_model['loras'] = cogvideoxfun_model.get("loras", []) + [folder_paths.get_full_path("loras", lora_name)]
+ cogvideoxfun_model['strength_model'] = cogvideoxfun_model.get("strength_model", []) + [strength_model]
+ return (cogvideoxfun_model,)
+ else:
+ return (cogvideoxfun_model,)
+
+class CogVideoXFunT2VSampler:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "cogvideoxfun_model": (
+ "FunModels",
+ ),
+ "prompt": (
+ "STRING_PROMPT",
+ ),
+ "negative_prompt": (
+ "STRING_PROMPT",
+ ),
+ "video_length": (
+ "INT", {"default": 49, "min": 5, "max": 85, "step": 4}
+ ),
+ "width": (
+ "INT", {"default": 1008, "min": 64, "max": 2048, "step": 16}
+ ),
+ "height": (
+ "INT", {"default": 576, "min": 64, "max": 2048, "step": 16}
+ ),
+ "is_image":(
+ [
+ False,
+ True
+ ],
+ {
+ "default": False,
+ }
+ ),
+ "seed": (
+ "INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
+ ),
+ "steps": (
+ "INT", {"default": 50, "min": 1, "max": 200, "step": 1}
+ ),
+ "cfg": (
+ "FLOAT", {"default": 6.0, "min": 1.0, "max": 20.0, "step": 0.01}
+ ),
+ "scheduler": (
+ [
+ "Euler",
+ "Euler A",
+ "DPM++",
+ "PNDM",
+ "DDIM",
+ ],
+ {
+ "default": 'DDIM'
+ }
+ ),
+ },
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES =("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, cogvideoxfun_model, prompt, negative_prompt, video_length, width, height, is_image, seed, steps, cfg, scheduler):
+ global transformer_cpu_cache
+ global lora_path_before
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+
+ mm.soft_empty_cache()
+ gc.collect()
+
+ # Get Pipeline
+ pipeline = cogvideoxfun_model['pipeline']
+ model_name = cogvideoxfun_model['model_name']
+ weight_dtype = cogvideoxfun_model['dtype']
+
+ # Load Sampler
+ pipeline.scheduler = all_cheduler_dict[scheduler].from_pretrained(model_name, subfolder='scheduler')
+
+ generator= torch.Generator(device).manual_seed(seed)
+
+ video_length = 1 if is_image else video_length
+ with torch.no_grad():
+ video_length = int((video_length - 1) // pipeline.vae.config.temporal_compression_ratio * pipeline.vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(None, None, video_length=video_length, sample_size=(height, width))
+
+ # Apply lora
+ if cogvideoxfun_model.get("lora_cache", False):
+ if len(cogvideoxfun_model.get("loras", [])) != 0:
+ # Save the original weights to cpu
+ if len(transformer_cpu_cache) == 0:
+ print('Save transformer state_dict to cpu memory')
+ transformer_state_dict = pipeline.transformer.state_dict()
+ for key in transformer_state_dict:
+ transformer_cpu_cache[key] = transformer_state_dict[key].clone().cpu()
+
+ lora_path_now = str(cogvideoxfun_model.get("loras", []) + cogvideoxfun_model.get("strength_model", []))
+ if lora_path_now != lora_path_before:
+ print('Merge Lora with Cache')
+ lora_path_before = copy.deepcopy(lora_path_now)
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(cogvideoxfun_model.get("loras", []), cogvideoxfun_model.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ else:
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if len(transformer_cpu_cache) != 0:
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ transformer_cpu_cache = {}
+ lora_path_before = ""
+ gc.collect()
+ print('Merge Lora')
+ for _lora_path, _lora_weight in zip(cogvideoxfun_model.get("loras", []), cogvideoxfun_model.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ comfyui_progressbar = True,
+ ).videos
+ videos = rearrange(sample, "b c t h w -> (b t) h w c")
+
+ if not cogvideoxfun_model.get("lora_cache", False):
+ print('Unmerge Lora')
+ for _lora_path, _lora_weight in zip(cogvideoxfun_model.get("loras", []), cogvideoxfun_model.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ return (videos,)
+
+
+class CogVideoXFunInpaintSampler:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "cogvideoxfun_model": (
+ "FunModels",
+ ),
+ "prompt": (
+ "STRING_PROMPT",
+ ),
+ "negative_prompt": (
+ "STRING_PROMPT",
+ ),
+ "video_length": (
+ "INT", {"default": 49, "min": 5, "max": 85, "step": 4}
+ ),
+ "base_resolution": (
+ [
+ 512,
+ 768,
+ 960,
+ 1024,
+ ], {"default": 768}
+ ),
+ "seed": (
+ "INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
+ ),
+ "steps": (
+ "INT", {"default": 50, "min": 1, "max": 200, "step": 1}
+ ),
+ "cfg": (
+ "FLOAT", {"default": 6.0, "min": 1.0, "max": 20.0, "step": 0.01}
+ ),
+ "scheduler": (
+ [
+ "Euler",
+ "Euler A",
+ "DPM++",
+ "PNDM",
+ "DDIM",
+ ],
+ {
+ "default": 'DDIM'
+ }
+ )
+ },
+ "optional":{
+ "start_img": ("IMAGE",),
+ "end_img": ("IMAGE",),
+ },
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES =("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, cogvideoxfun_model, prompt, negative_prompt, video_length, base_resolution, seed, steps, cfg, scheduler, start_img=None, end_img=None):
+ global transformer_cpu_cache
+ global lora_path_before
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+
+ mm.soft_empty_cache()
+ gc.collect()
+
+ start_img = [to_pil(_start_img) for _start_img in start_img] if start_img is not None else None
+ end_img = [to_pil(_end_img) for _end_img in end_img] if end_img is not None else None
+ # Count most suitable height and width
+ aspect_ratio_sample_size = {key : [x / 512 * base_resolution for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+ original_width, original_height = start_img[0].size if type(start_img) is list else Image.open(start_img).size
+ closest_size, closest_ratio = get_closest_ratio(original_height, original_width, ratios=aspect_ratio_sample_size)
+ height, width = [int(x / 16) * 16 for x in closest_size]
+
+ # Get Pipeline
+ pipeline = cogvideoxfun_model['pipeline']
+ model_name = cogvideoxfun_model['model_name']
+ weight_dtype = cogvideoxfun_model['dtype']
+
+ # Load Sampler
+ pipeline.scheduler = all_cheduler_dict[scheduler].from_pretrained(model_name, subfolder='scheduler')
+
+ generator= torch.Generator(device).manual_seed(seed)
+
+ with torch.no_grad():
+ video_length = int((video_length - 1) // pipeline.vae.config.temporal_compression_ratio * pipeline.vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(start_img, end_img, video_length=video_length, sample_size=(height, width))
+
+ # Apply lora
+ if cogvideoxfun_model.get("lora_cache", False):
+ if len(cogvideoxfun_model.get("loras", [])) != 0:
+ # Save the original weights to cpu
+ if len(transformer_cpu_cache) == 0:
+ print('Save transformer state_dict to cpu memory')
+ transformer_state_dict = pipeline.transformer.state_dict()
+ for key in transformer_state_dict:
+ transformer_cpu_cache[key] = transformer_state_dict[key].clone().cpu()
+
+ lora_path_now = str(cogvideoxfun_model.get("loras", []) + cogvideoxfun_model.get("strength_model", []))
+ if lora_path_now != lora_path_before:
+ print('Merge Lora with Cache')
+ lora_path_before = copy.deepcopy(lora_path_now)
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(cogvideoxfun_model.get("loras", []), cogvideoxfun_model.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ else:
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if len(transformer_cpu_cache) != 0:
+ print('Delete cpu state_dict')
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ transformer_cpu_cache = {}
+ lora_path_before = ""
+ gc.collect()
+ print('Merge Lora')
+ for _lora_path, _lora_weight in zip(cogvideoxfun_model.get("loras", []), cogvideoxfun_model.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ comfyui_progressbar = True,
+ ).videos
+ videos = rearrange(sample, "b c t h w -> (b t) h w c")
+
+ if not cogvideoxfun_model.get("lora_cache", False):
+ print('Unmerge Lora')
+ for _lora_path, _lora_weight in zip(cogvideoxfun_model.get("loras", []), cogvideoxfun_model.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ return (videos,)
+
+
+class CogVideoXFunV2VSampler:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "cogvideoxfun_model": (
+ "FunModels",
+ ),
+ "prompt": (
+ "STRING_PROMPT",
+ ),
+ "negative_prompt": (
+ "STRING_PROMPT",
+ ),
+ "video_length": (
+ "INT", {"default": 49, "min": 5, "max": 85, "step": 4}
+ ),
+ "base_resolution": (
+ [
+ 512,
+ 768,
+ 960,
+ 1024,
+ ], {"default": 768}
+ ),
+ "seed": (
+ "INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
+ ),
+ "steps": (
+ "INT", {"default": 50, "min": 1, "max": 200, "step": 1}
+ ),
+ "cfg": (
+ "FLOAT", {"default": 6.0, "min": 1.0, "max": 20.0, "step": 0.01}
+ ),
+ "denoise_strength": (
+ "FLOAT", {"default": 0.70, "min": 0.05, "max": 1.00, "step": 0.01}
+ ),
+ "scheduler": (
+ [
+ "Euler",
+ "Euler A",
+ "DPM++",
+ "PNDM",
+ "DDIM",
+ ],
+ {
+ "default": 'DDIM'
+ }
+ ),
+ },
+ "optional":{
+ "validation_video": ("IMAGE",),
+ "control_video": ("IMAGE",),
+ },
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES =("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, cogvideoxfun_model, prompt, negative_prompt, video_length, base_resolution, seed, steps, cfg, denoise_strength, scheduler, validation_video=None, control_video=None):
+ global transformer_cpu_cache
+ global lora_path_before
+
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+
+ mm.soft_empty_cache()
+ gc.collect()
+
+ # Get Pipeline
+ pipeline = cogvideoxfun_model['pipeline']
+ model_name = cogvideoxfun_model['model_name']
+ weight_dtype = cogvideoxfun_model['dtype']
+ model_type = cogvideoxfun_model['model_type']
+
+ # Count most suitable height and width
+ aspect_ratio_sample_size = {key : [x / 512 * base_resolution for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+ if model_type == "Inpaint":
+ if type(validation_video) is str:
+ original_width, original_height = Image.fromarray(cv2.VideoCapture(validation_video).read()[1]).size
+ else:
+ validation_video = np.array(validation_video.cpu().numpy() * 255, np.uint8)
+ original_width, original_height = Image.fromarray(validation_video[0]).size
+ else:
+ if control_video is not None and type(control_video) is str:
+ original_width, original_height = Image.fromarray(cv2.VideoCapture(control_video).read()[1]).size
+ elif control_video is not None:
+ control_video = np.array(control_video.cpu().numpy() * 255, np.uint8)
+ original_width, original_height = Image.fromarray(control_video[0]).size
+ else:
+ original_width, original_height = 384 / 512 * base_resolution, 672 / 512 * base_resolution
+
+ closest_size, closest_ratio = get_closest_ratio(original_height, original_width, ratios=aspect_ratio_sample_size)
+ height, width = [int(x / 16) * 16 for x in closest_size]
+
+ # Load Sampler
+ pipeline.scheduler = all_cheduler_dict[scheduler].from_pretrained(model_name, subfolder='scheduler')
+
+ generator= torch.Generator(device).manual_seed(seed)
+
+ with torch.no_grad():
+ video_length = int((video_length - 1) // pipeline.vae.config.temporal_compression_ratio * pipeline.vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+ if model_type == "Inpaint":
+ input_video, input_video_mask, ref_image, clip_image = get_video_to_video_latent(validation_video, video_length=video_length, sample_size=(height, width), fps=8)
+ else:
+ input_video, input_video_mask, ref_image, clip_image = get_video_to_video_latent(control_video, video_length=video_length, sample_size=(height, width), fps=8)
+
+ # Apply lora
+ if cogvideoxfun_model.get("lora_cache", False):
+ if len(cogvideoxfun_model.get("loras", [])) != 0:
+ # Save the original weights to cpu
+ if len(transformer_cpu_cache) == 0:
+ print('Save transformer state_dict to cpu memory')
+ transformer_state_dict = pipeline.transformer.state_dict()
+ for key in transformer_state_dict:
+ transformer_cpu_cache[key] = transformer_state_dict[key].clone().cpu()
+
+ lora_path_now = str(cogvideoxfun_model.get("loras", []) + cogvideoxfun_model.get("strength_model", []))
+ if lora_path_now != lora_path_before:
+ print('Merge Lora with Cache')
+ lora_path_before = copy.deepcopy(lora_path_now)
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(cogvideoxfun_model.get("loras", []), cogvideoxfun_model.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ else:
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if len(transformer_cpu_cache) != 0:
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ transformer_cpu_cache = {}
+ lora_path_before = ""
+ gc.collect()
+ print('Merge Lora')
+ for _lora_path, _lora_weight in zip(cogvideoxfun_model.get("loras", []), cogvideoxfun_model.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ if model_type == "Inpaint":
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ strength = float(denoise_strength),
+ comfyui_progressbar = True,
+ ).videos
+ else:
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ control_video = input_video,
+ comfyui_progressbar = True,
+ ).videos
+ videos = rearrange(sample, "b c t h w -> (b t) h w c")
+
+ if not cogvideoxfun_model.get("lora_cache", False):
+ print('Unmerge Lora')
+ for _lora_path, _lora_weight in zip(cogvideoxfun_model.get("loras", []), cogvideoxfun_model.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ return (videos,)
diff --git a/VideoX-Fun/comfyui/cogvideox_fun/v1.1/cogvideoxfunv1.1_workflow_i2v.json b/VideoX-Fun/comfyui/cogvideox_fun/v1.1/cogvideoxfunv1.1_workflow_i2v.json
new file mode 100644
index 0000000000000000000000000000000000000000..132ff5d5a8e60ca23a226fe5682e692678a4e2d5
--- /dev/null
+++ b/VideoX-Fun/comfyui/cogvideox_fun/v1.1/cogvideoxfunv1.1_workflow_i2v.json
@@ -0,0 +1,451 @@
+{
+ "last_node_id": 83,
+ "last_link_id": 46,
+ "nodes": [
+ {
+ "id": 7,
+ "type": "LoadImage",
+ "pos": [
+ 258.76883544921907,
+ 468.15773315429715
+ ],
+ "size": [
+ 378.07147216796875,
+ 314.0000114440918
+ ],
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 45
+ ],
+ "shape": 3,
+ "label": "图像",
+ "slot_index": 0
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null,
+ "shape": 3,
+ "label": "遮罩"
+ }
+ ],
+ "title": "Start Image(图片到视频的开始图片)",
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "firework.png",
+ "image"
+ ]
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": [
+ 16,
+ 460
+ ],
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload image here\n(在此上传开始图像)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": [
+ 20,
+ -300
+ ],
+ "size": {
+ "0": 210,
+ "1": 66.98204040527344
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Load model here\n(在此选择要使用的模型)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ -50
+ ],
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 43
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 82,
+ "type": "CogVideoXFunInpaintSampler",
+ "pos": [
+ 758,
+ 93
+ ],
+ "size": {
+ "0": 336,
+ "1": 282
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "link": 42
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 43
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 44
+ },
+ {
+ "name": "start_img",
+ "type": "IMAGE",
+ "link": 45,
+ "slot_index": 3
+ },
+ {
+ "name": "end_img",
+ "type": "IMAGE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 46
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CogVideoXFunInpaintSampler"
+ },
+ "widgets_values": [
+ 49,
+ 512,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ "DDIM"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1134,
+ 93
+ ],
+ "size": [
+ 390.9534912109375,
+ 535.9734235491071
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 46,
+ "label": "图像",
+ "slot_index": 0
+ },
+ {
+ "name": "audio",
+ "type": "VHS_AUDIO",
+ "link": null,
+ "label": "音频"
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理"
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "shape": 3,
+ "label": "文件名",
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 8,
+ "loop_count": 0,
+ "filename_prefix": "CogVideoX-Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "CogVideoX-Fun_00003.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 83,
+ "type": "LoadCogVideoXFunModel",
+ "pos": [
+ 300,
+ -294
+ ],
+ "size": {
+ "0": 315,
+ "1": 130
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "links": [
+ 42
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadCogVideoXFunModel"
+ },
+ "widgets_values": [
+ "CogVideoX-Fun-V1.1-2b-InP",
+ "Inpaint",
+ "model_cpu_offload",
+ "bf16"
+ ]
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ 160
+ ],
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 44
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "The video is not of a high quality, it has a low resolution. Watermark present in each frame. Strange motion trajectory. "
+ ]
+ }
+ ],
+ "links": [
+ [
+ 42,
+ 83,
+ 0,
+ 82,
+ 0,
+ "FunModels"
+ ],
+ [
+ 43,
+ 75,
+ 0,
+ 82,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 44,
+ 73,
+ 0,
+ 82,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 45,
+ 7,
+ 0,
+ 82,
+ 3,
+ "IMAGE"
+ ],
+ [
+ 46,
+ 82,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24
+ },
+ {
+ "title": "Load CogVideoX-Fun",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24
+ },
+ {
+ "title": "Upload Your Start Image",
+ "bounding": [
+ 218,
+ 382,
+ 452,
+ 418
+ ],
+ "color": "#a1309b",
+ "font_size": 24
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.7513148009015778,
+ "offset": [
+ 268.77277812624413,
+ 436.3236112390962
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/cogvideox_fun/v1.1/cogvideoxfunv1.1_workflow_t2v.json b/VideoX-Fun/comfyui/cogvideox_fun/v1.1/cogvideoxfunv1.1_workflow_t2v.json
new file mode 100644
index 0000000000000000000000000000000000000000..16bc2a77dd4e490862950471f1cd6b0a2ce20895
--- /dev/null
+++ b/VideoX-Fun/comfyui/cogvideox_fun/v1.1/cogvideoxfunv1.1_workflow_t2v.json
@@ -0,0 +1,359 @@
+{
+ "last_node_id": 88,
+ "last_link_id": 52,
+ "nodes": [
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": [
+ 20,
+ -300
+ ],
+ "size": {
+ "0": 210,
+ "1": 66.98204040527344
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Load model here\n(在此选择要使用的模型)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ -50
+ ],
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 50
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "A young woman with beautiful and clear eyes and blonde hair standing and white dress in a forest wearing a crown. She seems to be lost in thought, and the camera focuses on her face. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 88,
+ "type": "CogVideoXFunT2VSampler",
+ "pos": [
+ 728,
+ -68
+ ],
+ "size": {
+ "0": 327.6000061035156,
+ "1": 290
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "link": 49
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 50
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 51,
+ "slot_index": 2
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 52
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CogVideoXFunT2VSampler"
+ },
+ "widgets_values": [
+ 49,
+ 672,
+ 384,
+ false,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ "DDIM"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1110,
+ -67
+ ],
+ "size": [
+ 390.9534912109375,
+ 535.9734235491071
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 52,
+ "label": "图像",
+ "slot_index": 0
+ },
+ {
+ "name": "audio",
+ "type": "VHS_AUDIO",
+ "link": null,
+ "label": "音频"
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理"
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "shape": 3,
+ "label": "文件名",
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 8,
+ "loop_count": 0,
+ "filename_prefix": "CogVideoX-Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "CogVideoX-Fun_00004.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ 160
+ ],
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 51
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "The video is not of a high quality, it has a low resolution. Watermark present in each frame. Strange motion trajectory. "
+ ]
+ },
+ {
+ "id": 87,
+ "type": "LoadCogVideoXFunModel",
+ "pos": [
+ 302,
+ -285
+ ],
+ "size": {
+ "0": 315,
+ "1": 130
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "links": [
+ 49
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadCogVideoXFunModel"
+ },
+ "widgets_values": [
+ "CogVideoX-Fun-V1.1-2b-InP",
+ "Inpaint",
+ "model_cpu_offload",
+ "bf16"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 49,
+ 87,
+ 0,
+ 88,
+ 0,
+ "FunModels"
+ ],
+ [
+ 50,
+ 75,
+ 0,
+ 88,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 51,
+ 73,
+ 0,
+ 88,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 52,
+ 88,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24
+ },
+ {
+ "title": "Load CogVideoX-Fun",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.8264462809917354,
+ "offset": [
+ 181.0702206286297,
+ 544.9672051634072
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/cogvideox_fun/v1.1/cogvideoxfunv1.1_workflow_t2v_lora.json b/VideoX-Fun/comfyui/cogvideox_fun/v1.1/cogvideoxfunv1.1_workflow_t2v_lora.json
new file mode 100644
index 0000000000000000000000000000000000000000..b3e4f044687ec629267e7e3e0771b3d006ff08ca
--- /dev/null
+++ b/VideoX-Fun/comfyui/cogvideox_fun/v1.1/cogvideoxfunv1.1_workflow_t2v_lora.json
@@ -0,0 +1,419 @@
+{
+ "last_node_id": 92,
+ "last_link_id": 57,
+ "nodes": [
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": {
+ "0": 22.407291412353516,
+ "1": -302.0006103515625
+ },
+ "size": {
+ "0": 210,
+ "1": 66.98204040527344
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Load model here\n(在此选择要使用的模型)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": -50
+ },
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 50
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "A young woman with beautiful and clear eyes and blonde hair standing and white dress in a forest wearing a crown. She seems to be lost in thought, and the camera focuses on her face. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": 160
+ },
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 51
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "The video is not of a high quality, it has a low resolution. Watermark present in each frame. Strange motion trajectory. "
+ ]
+ },
+ {
+ "id": 88,
+ "type": "CogVideoXFunT2VSampler",
+ "pos": {
+ "0": 728,
+ "1": -68
+ },
+ "size": {
+ "0": 327.6000061035156,
+ "1": 290
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "link": 57
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 50
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 51,
+ "slot_index": 2
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 52
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CogVideoXFunT2VSampler"
+ },
+ "widgets_values": [
+ 49,
+ 672,
+ 384,
+ false,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ "DDIM"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1098,
+ "1": -69
+ },
+ "size": [
+ 390.9534912109375,
+ 535.9734235491071
+ ],
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 52,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 8,
+ "loop_count": 0,
+ "filename_prefix": "CogVideoX-Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "CogVideoX-Fun_00001.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 87,
+ "type": "LoadCogVideoXFunModel",
+ "pos": {
+ "0": 260,
+ "1": -298
+ },
+ "size": {
+ "0": 315,
+ "1": 130
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "links": [
+ 56
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadCogVideoXFunModel"
+ },
+ "widgets_values": [
+ "CogVideoX-Fun-V1.1-2b-InP",
+ "Inpaint",
+ "model_cpu_offload",
+ "bf16"
+ ]
+ },
+ {
+ "id": 92,
+ "type": "LoadCogVideoXFunLora",
+ "pos": {
+ "0": 605,
+ "1": -297
+ },
+ "size": {
+ "0": 468.5999755859375,
+ "1": 82
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "link": 56
+ }
+ ],
+ "outputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "links": [
+ 57
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadCogVideoXFunLora"
+ },
+ "widgets_values": [
+ "cogvideox_fun/CogVideoX-Fun-V1.1-2b-InP-HPS2.1.safetensors",
+ 0.6
+ ]
+ }
+ ],
+ "links": [
+ [
+ 50,
+ 75,
+ 0,
+ 88,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 51,
+ 73,
+ 0,
+ 88,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 52,
+ 88,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 56,
+ 87,
+ 0,
+ 92,
+ 0,
+ "FunModels"
+ ],
+ [
+ 57,
+ 92,
+ 0,
+ 88,
+ 0,
+ "FunModels"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load CogVideoX-Fun",
+ "bounding": [
+ 222,
+ -382,
+ 873,
+ 235
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.8264462809917354,
+ "offset": [
+ 143.5668017223784,
+ 513.2159371946544
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/cogvideox_fun/v1.1/cogvideoxfunv1.1_workflow_v2v.json b/VideoX-Fun/comfyui/cogvideox_fun/v1.1/cogvideoxfunv1.1_workflow_v2v.json
new file mode 100644
index 0000000000000000000000000000000000000000..8e55eff73f75ec6073a3e9e24081202bd4d71d6e
--- /dev/null
+++ b/VideoX-Fun/comfyui/cogvideox_fun/v1.1/cogvideoxfunv1.1_workflow_v2v.json
@@ -0,0 +1,492 @@
+{
+ "last_node_id": 90,
+ "last_link_id": 57,
+ "nodes": [
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": [
+ 20,
+ -300
+ ],
+ "size": {
+ "0": 210,
+ "1": 66.98204040527344
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Load model here\n(在此选择要使用的模型)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": [
+ 15.739953613281248,
+ 462.38664912015946
+ ],
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": [
+ 336,
+ 470
+ ],
+ "size": [
+ 235.1999969482422,
+ 398.971426827567
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 56
+ ],
+ "shape": 3,
+ "slot_index": 0
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "00000125.mp4",
+ "force_rate": 0,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 0,
+ "filename": "00000125.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 88,
+ "type": "LoadCogVideoXFunModel",
+ "pos": [
+ 309,
+ -286
+ ],
+ "size": {
+ "0": 315,
+ "1": 130
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "links": [
+ 53
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadCogVideoXFunModel"
+ },
+ "widgets_values": [
+ "CogVideoX-Fun-V1.1-2b-InP",
+ "Inpaint",
+ "model_cpu_offload",
+ "bf16"
+ ]
+ },
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ -50
+ ],
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 54
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "A cute cat is playing the guitar."
+ ]
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ 160
+ ],
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 55
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "The video is not of a high quality, it has a low resolution. Watermark present in each frame. Strange motion trajectory. "
+ ]
+ },
+ {
+ "id": 90,
+ "type": "CogVideoXFunV2VSampler",
+ "pos": [
+ 754,
+ 14
+ ],
+ "size": {
+ "0": 317.4000244140625,
+ "1": 306
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "link": 53
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 54
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 55
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": 56,
+ "slot_index": 3
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 57
+ ],
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CogVideoXFunV2VSampler"
+ },
+ "widgets_values": [
+ 49,
+ 768,
+ 43,
+ "randomize",
+ 50,
+ 6,
+ 0.7,
+ "DDIM"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1125,
+ 15
+ ],
+ "size": [
+ 390.9534912109375,
+ 535.9734235491071
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 57,
+ "label": "图像",
+ "slot_index": 0
+ },
+ {
+ "name": "audio",
+ "type": "VHS_AUDIO",
+ "link": null,
+ "label": "音频"
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理"
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "shape": 3,
+ "label": "文件名",
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 8,
+ "loop_count": 0,
+ "filename_prefix": "EasyAnimate",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "EasyAnimate_00045.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ }
+ }
+ }
+ }
+ ],
+ "links": [
+ [
+ 53,
+ 88,
+ 0,
+ 90,
+ 0,
+ "FunModels"
+ ],
+ [
+ 54,
+ 75,
+ 0,
+ 90,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 55,
+ 73,
+ 0,
+ 90,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 56,
+ 85,
+ 0,
+ 90,
+ 3,
+ "IMAGE"
+ ],
+ [
+ 57,
+ 90,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24
+ },
+ {
+ "title": "Load CogVideoX-Fun",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24
+ },
+ {
+ "title": "Upload Your Video",
+ "bounding": [
+ 218,
+ 385,
+ 456,
+ 498
+ ],
+ "color": "#a1309b",
+ "font_size": 24
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.683013455365071,
+ "offset": [
+ 314.4077746994681,
+ 444.69453403364594
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/cogvideox_fun/v1.1/cogvideoxfunv1.1_workflow_v2v_control.json b/VideoX-Fun/comfyui/cogvideox_fun/v1.1/cogvideoxfunv1.1_workflow_v2v_control.json
new file mode 100644
index 0000000000000000000000000000000000000000..867a3df0ead8b5f0fd2a568af1b13fd96aa10b98
--- /dev/null
+++ b/VideoX-Fun/comfyui/cogvideox_fun/v1.1/cogvideoxfunv1.1_workflow_v2v_control.json
@@ -0,0 +1,492 @@
+{
+ "last_node_id": 90,
+ "last_link_id": 59,
+ "nodes": [
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": [
+ 20,
+ -300
+ ],
+ "size": {
+ "0": 210,
+ "1": 66.98204040527344
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Load model here\n(在此选择要使用的模型)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": [
+ 15.739953613281248,
+ 462.38664912015946
+ ],
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ 160
+ ],
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 55
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "The video is not of a high quality, it has a low resolution. Watermark present in each frame. Strange motion trajectory. "
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1125,
+ 15
+ ],
+ "size": [
+ 390.9534912109375,
+ 973.1686096191406
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 57,
+ "label": "图像",
+ "slot_index": 0
+ },
+ {
+ "name": "audio",
+ "type": "VHS_AUDIO",
+ "link": null,
+ "label": "音频"
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理"
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "shape": 3,
+ "label": "文件名",
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 8,
+ "loop_count": 0,
+ "filename_prefix": "CogVideoX-Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "CogVideoX-Fun_00007.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 88,
+ "type": "LoadCogVideoXFunModel",
+ "pos": [
+ 309,
+ -286
+ ],
+ "size": {
+ "0": 315,
+ "1": 130
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "links": [
+ 53
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadCogVideoXFunModel"
+ },
+ "widgets_values": [
+ "CogVideoX-Fun-V1.1-2b-Pose",
+ "Control",
+ "model_cpu_offload",
+ "bf16"
+ ]
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": [
+ 336,
+ 470
+ ],
+ "size": [
+ 235.1999969482422,
+ 658.5777723524305
+ ],
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 59
+ ],
+ "shape": 3,
+ "slot_index": 0
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "pose.mp4",
+ "force_rate": 8,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 8,
+ "filename": "pose.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ -50
+ ],
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 54
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "A person wearing a knee-length white sleeveless dress and white high-heeled sandals performs a dance in a well-lit room with wooden flooring. The room's background features a closed door, a shelf displaying clear glass bottles of alcoholic beverages, and a partially visible dark-colored sofa. "
+ ]
+ },
+ {
+ "id": 90,
+ "type": "CogVideoXFunV2VSampler",
+ "pos": [
+ 754,
+ 14
+ ],
+ "size": {
+ "0": 336,
+ "1": 306
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "link": 53
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 54
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 55
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "slot_index": 3
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": 59
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 57
+ ],
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CogVideoXFunV2VSampler"
+ },
+ "widgets_values": [
+ 49,
+ 512,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1,
+ "DDIM"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 53,
+ 88,
+ 0,
+ 90,
+ 0,
+ "FunModels"
+ ],
+ [
+ 54,
+ 75,
+ 0,
+ 90,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 55,
+ 73,
+ 0,
+ 90,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 57,
+ 90,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 59,
+ 85,
+ 0,
+ 90,
+ 4,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24
+ },
+ {
+ "title": "Load CogVideoX-Fun",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24
+ },
+ {
+ "title": "Upload Your Video",
+ "bounding": [
+ 218,
+ 385,
+ 457,
+ 776
+ ],
+ "color": "#a1309b",
+ "font_size": 24
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650712,
+ "offset": [
+ 250.2298948633902,
+ 399.72391778748613
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/cogvideox_fun/v1.5/cogvideoxfunv1.5_workflow_i2v.json b/VideoX-Fun/comfyui/cogvideox_fun/v1.5/cogvideoxfunv1.5_workflow_i2v.json
new file mode 100644
index 0000000000000000000000000000000000000000..a90947ad34f7483727c090d3c4fae92940076aaa
--- /dev/null
+++ b/VideoX-Fun/comfyui/cogvideox_fun/v1.5/cogvideoxfunv1.5_workflow_i2v.json
@@ -0,0 +1,470 @@
+{
+ "last_node_id": 83,
+ "last_link_id": 46,
+ "nodes": [
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": {
+ "0": 16,
+ "1": 460
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload image here\n(在此上传开始图像)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": {
+ "0": 20,
+ "1": -300
+ },
+ "size": {
+ "0": 210,
+ "1": 66.98204040527344
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Load model here\n(在此选择要使用的模型)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": -50
+ },
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 43
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1134,
+ "1": 93
+ },
+ "size": [
+ 390.9534912109375,
+ 310
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 46,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 8,
+ "loop_count": 0,
+ "filename_prefix": "CogVideoX-Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "CogVideoX-Fun_00003.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": 160
+ },
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 44
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "The video is not of a high quality, it has a low resolution. Watermark present in each frame. Strange motion trajectory. "
+ ]
+ },
+ {
+ "id": 83,
+ "type": "LoadCogVideoXFunModel",
+ "pos": {
+ "0": 300,
+ "1": -294
+ },
+ "size": {
+ "0": 315,
+ "1": 130
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "links": [
+ 42
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadCogVideoXFunModel"
+ },
+ "widgets_values": [
+ "CogVideoX-Fun-V1.5-5b-InP",
+ "Inpaint",
+ "model_cpu_offload",
+ "bf16"
+ ]
+ },
+ {
+ "id": 7,
+ "type": "LoadImage",
+ "pos": {
+ "0": 259,
+ "1": 468
+ },
+ "size": {
+ "0": 378.07147216796875,
+ "1": 314
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 45
+ ],
+ "slot_index": 0,
+ "shape": 3,
+ "label": "图像"
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null,
+ "shape": 3,
+ "label": "遮罩"
+ }
+ ],
+ "title": "Start Image(图片到视频的开始图片)",
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "firework.png",
+ "image"
+ ]
+ },
+ {
+ "id": 82,
+ "type": "CogVideoXFunInpaintSampler",
+ "pos": {
+ "0": 758,
+ "1": 93
+ },
+ "size": {
+ "0": 336,
+ "1": 282
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "link": 42
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 43
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 44
+ },
+ {
+ "name": "start_img",
+ "type": "IMAGE",
+ "link": 45,
+ "slot_index": 3,
+ "shape": 7
+ },
+ {
+ "name": "end_img",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 46
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CogVideoXFunInpaintSampler"
+ },
+ "widgets_values": [
+ 85,
+ 512,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ "DDIM"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 42,
+ 83,
+ 0,
+ 82,
+ 0,
+ "FunModels"
+ ],
+ [
+ 43,
+ 75,
+ 0,
+ 82,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 44,
+ 73,
+ 0,
+ 82,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 45,
+ 7,
+ 0,
+ 82,
+ 3,
+ "IMAGE"
+ ],
+ [
+ 46,
+ 82,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Upload Your Start Image",
+ "bounding": [
+ 218,
+ 382,
+ 452,
+ 418
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load CogVideoX-Fun",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.7513148009015777,
+ "offset": [
+ 253.7221767223781,
+ 421.7578981321543
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/cogvideox_fun/v1.5/cogvideoxfunv1.5_workflow_t2v.json b/VideoX-Fun/comfyui/cogvideox_fun/v1.5/cogvideoxfunv1.5_workflow_t2v.json
new file mode 100644
index 0000000000000000000000000000000000000000..3f444c19177c07c01de5ee25980a442b1eed83e3
--- /dev/null
+++ b/VideoX-Fun/comfyui/cogvideox_fun/v1.5/cogvideoxfunv1.5_workflow_t2v.json
@@ -0,0 +1,372 @@
+{
+ "last_node_id": 88,
+ "last_link_id": 52,
+ "nodes": [
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": {
+ "0": 20,
+ "1": -300
+ },
+ "size": {
+ "0": 210,
+ "1": 66.98204040527344
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Load model here\n(在此选择要使用的模型)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": -50
+ },
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 50
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "A young woman with beautiful and clear eyes and blonde hair standing and white dress in a forest wearing a crown. She seems to be lost in thought, and the camera focuses on her face. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1110,
+ "1": -67
+ },
+ "size": [
+ 390.9534912109375,
+ 310
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 52,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 8,
+ "loop_count": 0,
+ "filename_prefix": "CogVideoX-Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "CogVideoX-Fun_00004.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": 160
+ },
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 51
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "The video is not of a high quality, it has a low resolution. Watermark present in each frame. Strange motion trajectory. "
+ ]
+ },
+ {
+ "id": 87,
+ "type": "LoadCogVideoXFunModel",
+ "pos": {
+ "0": 302,
+ "1": -285
+ },
+ "size": {
+ "0": 315,
+ "1": 130
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "links": [
+ 49
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadCogVideoXFunModel"
+ },
+ "widgets_values": [
+ "CogVideoX-Fun-V1.5-5b-InP",
+ "Inpaint",
+ "model_cpu_offload",
+ "bf16"
+ ]
+ },
+ {
+ "id": 88,
+ "type": "CogVideoXFunT2VSampler",
+ "pos": {
+ "0": 728,
+ "1": -68
+ },
+ "size": {
+ "0": 327.6000061035156,
+ "1": 290
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "link": 49
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 50
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 51,
+ "slot_index": 2
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 52
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CogVideoXFunT2VSampler"
+ },
+ "widgets_values": [
+ 85,
+ 672,
+ 384,
+ "model_cpu_offload",
+ 43,
+ "fixed",
+ 50,
+ 6,
+ "DDIM"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 49,
+ 87,
+ 0,
+ 88,
+ 0,
+ "FunModels"
+ ],
+ [
+ 50,
+ 75,
+ 0,
+ 88,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 51,
+ 73,
+ 0,
+ 88,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 52,
+ 88,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Load CogVideoX-Fun",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.7513148009015777,
+ "offset": [
+ 302.3920634411272,
+ 585.6684684446539
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/cogvideox_fun/v1.5/cogvideoxfunv1.5_workflow_v2v.json b/VideoX-Fun/comfyui/cogvideox_fun/v1.5/cogvideoxfunv1.5_workflow_v2v.json
new file mode 100644
index 0000000000000000000000000000000000000000..c5e41f961121753722ee3468f27a75e26dddc4bc
--- /dev/null
+++ b/VideoX-Fun/comfyui/cogvideox_fun/v1.5/cogvideoxfunv1.5_workflow_v2v.json
@@ -0,0 +1,512 @@
+{
+ "last_node_id": 90,
+ "last_link_id": 57,
+ "nodes": [
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": {
+ "0": 20,
+ "1": -300
+ },
+ "size": {
+ "0": 210,
+ "1": 66.98204040527344
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Load model here\n(在此选择要使用的模型)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": {
+ "0": 15.739953994750977,
+ "1": 462.38665771484375
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": {
+ "0": 336,
+ "1": 470
+ },
+ "size": [
+ 235.1999969482422,
+ 262
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 56
+ ],
+ "slot_index": 0,
+ "shape": 3
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "00000125.mp4",
+ "force_rate": 0,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 0,
+ "filename": "00000125.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": -50
+ },
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 54
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "A cute cat is playing the guitar."
+ ]
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": 160
+ },
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 55
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "The video is not of a high quality, it has a low resolution. Watermark present in each frame. Strange motion trajectory. "
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1125,
+ "1": 15
+ },
+ "size": [
+ 390.9534912109375,
+ 310
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 57,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 8,
+ "loop_count": 0,
+ "filename_prefix": "EasyAnimate",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "EasyAnimate_00045.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 88,
+ "type": "LoadCogVideoXFunModel",
+ "pos": {
+ "0": 309,
+ "1": -286
+ },
+ "size": {
+ "0": 315,
+ "1": 130
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "links": [
+ 53
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadCogVideoXFunModel"
+ },
+ "widgets_values": [
+ "CogVideoX-Fun-V1.5-5b-InP",
+ "Inpaint",
+ "model_cpu_offload",
+ "bf16"
+ ]
+ },
+ {
+ "id": 90,
+ "type": "CogVideoXFunV2VSampler",
+ "pos": {
+ "0": 754,
+ "1": 14
+ },
+ "size": {
+ "0": 336,
+ "1": 306
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "link": 53
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 54
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 55
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": 56,
+ "slot_index": 3,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 57
+ ],
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CogVideoXFunV2VSampler"
+ },
+ "widgets_values": [
+ 45,
+ 512,
+ 43,
+ "randomize",
+ 50,
+ 6,
+ 0.7,
+ "DDIM"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 53,
+ 88,
+ 0,
+ 90,
+ 0,
+ "FunModels"
+ ],
+ [
+ 54,
+ 75,
+ 0,
+ 90,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 55,
+ 73,
+ 0,
+ 90,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 56,
+ 85,
+ 0,
+ 90,
+ 3,
+ "IMAGE"
+ ],
+ [
+ 57,
+ 90,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Upload Your Video",
+ "bounding": [
+ 218,
+ 385,
+ 456,
+ 498
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load CogVideoX-Fun",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.7513148009015777,
+ "offset": [
+ 258.3078876598779,
+ 405.0892028196541
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/cogvideox_fun/v1/cogvideoxfunv1_workflow_i2v.json b/VideoX-Fun/comfyui/cogvideox_fun/v1/cogvideoxfunv1_workflow_i2v.json
new file mode 100644
index 0000000000000000000000000000000000000000..52b7e04cf444c086aa57f6d85f59431ef5ac2ff0
--- /dev/null
+++ b/VideoX-Fun/comfyui/cogvideox_fun/v1/cogvideoxfunv1_workflow_i2v.json
@@ -0,0 +1,451 @@
+{
+ "last_node_id": 83,
+ "last_link_id": 46,
+ "nodes": [
+ {
+ "id": 7,
+ "type": "LoadImage",
+ "pos": [
+ 258.76883544921907,
+ 468.15773315429715
+ ],
+ "size": [
+ 378.07147216796875,
+ 314.0000114440918
+ ],
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 45
+ ],
+ "shape": 3,
+ "label": "图像",
+ "slot_index": 0
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null,
+ "shape": 3,
+ "label": "遮罩"
+ }
+ ],
+ "title": "Start Image(图片到视频的开始图片)",
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "firework.png",
+ "image"
+ ]
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": [
+ 16,
+ 460
+ ],
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload image here\n(在此上传开始图像)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": [
+ 20,
+ -300
+ ],
+ "size": {
+ "0": 210,
+ "1": 66.98204040527344
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Load model here\n(在此选择要使用的模型)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ -50
+ ],
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 43
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ 160
+ ],
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 44
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "The video is not of a high quality, it has a low resolution. Watermark present in each frame. Strange motion trajectory. "
+ ]
+ },
+ {
+ "id": 82,
+ "type": "CogVideoXFunInpaintSampler",
+ "pos": [
+ 758,
+ 93
+ ],
+ "size": {
+ "0": 336,
+ "1": 282
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "link": 42
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 43
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 44
+ },
+ {
+ "name": "start_img",
+ "type": "IMAGE",
+ "link": 45,
+ "slot_index": 3
+ },
+ {
+ "name": "end_img",
+ "type": "IMAGE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 46
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CogVideoXFunInpaintSampler"
+ },
+ "widgets_values": [
+ 49,
+ 512,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ "DDIM"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1134,
+ 93
+ ],
+ "size": [
+ 390.9534912109375,
+ 535.9734235491071
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 46,
+ "label": "图像",
+ "slot_index": 0
+ },
+ {
+ "name": "audio",
+ "type": "VHS_AUDIO",
+ "link": null,
+ "label": "音频"
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理"
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "shape": 3,
+ "label": "文件名",
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 8,
+ "loop_count": 0,
+ "filename_prefix": "CogVideoX-Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "CogVideoX-Fun_00003.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 83,
+ "type": "LoadCogVideoXFunModel",
+ "pos": [
+ 300,
+ -294
+ ],
+ "size": {
+ "0": 315,
+ "1": 106
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "links": [
+ 42
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadCogVideoXFunModel"
+ },
+ "widgets_values": [
+ "CogVideoX-Fun-2b-InP",
+ "Inpaint",
+ "model_cpu_offload",
+ "bf16"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 42,
+ 83,
+ 0,
+ 82,
+ 0,
+ "FunModels"
+ ],
+ [
+ 43,
+ 75,
+ 0,
+ 82,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 44,
+ 73,
+ 0,
+ 82,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 45,
+ 7,
+ 0,
+ 82,
+ 3,
+ "IMAGE"
+ ],
+ [
+ 46,
+ 82,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24
+ },
+ {
+ "title": "Load CogVideoX-Fun",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24
+ },
+ {
+ "title": "Upload Your Start Image",
+ "bounding": [
+ 218,
+ 382,
+ 452,
+ 418
+ ],
+ "color": "#a1309b",
+ "font_size": 24
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.7513148009015778,
+ "offset": [
+ 265.8612156262443,
+ 436.6199667078462
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/cogvideox_fun/v1/cogvideoxfunv1_workflow_t2v.json b/VideoX-Fun/comfyui/cogvideox_fun/v1/cogvideoxfunv1_workflow_t2v.json
new file mode 100644
index 0000000000000000000000000000000000000000..a4d1b6c46dcfaae426d9988b1174a4a592afb318
--- /dev/null
+++ b/VideoX-Fun/comfyui/cogvideox_fun/v1/cogvideoxfunv1_workflow_t2v.json
@@ -0,0 +1,359 @@
+{
+ "last_node_id": 88,
+ "last_link_id": 52,
+ "nodes": [
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": [
+ 20,
+ -300
+ ],
+ "size": {
+ "0": 210,
+ "1": 66.98204040527344
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Load model here\n(在此选择要使用的模型)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ 160
+ ],
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 51
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "The video is not of a high quality, it has a low resolution. Watermark present in each frame. Strange motion trajectory. "
+ ]
+ },
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ -50
+ ],
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 50
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "A young woman with beautiful and clear eyes and blonde hair standing and white dress in a forest wearing a crown. She seems to be lost in thought, and the camera focuses on her face. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 88,
+ "type": "CogVideoXFunT2VSampler",
+ "pos": [
+ 728,
+ -68
+ ],
+ "size": {
+ "0": 327.6000061035156,
+ "1": 290
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "link": 49
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 50
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 51,
+ "slot_index": 2
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 52
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CogVideoXFunT2VSampler"
+ },
+ "widgets_values": [
+ 49,
+ 672,
+ 384,
+ false,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ "DDIM"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1110,
+ -67
+ ],
+ "size": [
+ 390.9534912109375,
+ 535.9734235491071
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 52,
+ "label": "图像",
+ "slot_index": 0
+ },
+ {
+ "name": "audio",
+ "type": "VHS_AUDIO",
+ "link": null,
+ "label": "音频"
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理"
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "shape": 3,
+ "label": "文件名",
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 8,
+ "loop_count": 0,
+ "filename_prefix": "CogVideoX-Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "CogVideoX-Fun_00004.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 87,
+ "type": "LoadCogVideoXFunModel",
+ "pos": [
+ 302,
+ -285
+ ],
+ "size": {
+ "0": 315,
+ "1": 106
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "links": [
+ 49
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadCogVideoXFunModel"
+ },
+ "widgets_values": [
+ "CogVideoX-Fun-2b-InP",
+ "Inpaint",
+ "model_cpu_offload",
+ "bf16"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 49,
+ 87,
+ 0,
+ 88,
+ 0,
+ "FunModels"
+ ],
+ [
+ 50,
+ 75,
+ 0,
+ 88,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 51,
+ 73,
+ 0,
+ 88,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 52,
+ 88,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24
+ },
+ {
+ "title": "Load CogVideoX-Fun",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.8264462809917354,
+ "offset": [
+ 171.40912687862968,
+ 545.5627520384072
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/cogvideox_fun/v1/cogvideoxfunv1_workflow_v2v.json b/VideoX-Fun/comfyui/cogvideox_fun/v1/cogvideoxfunv1_workflow_v2v.json
new file mode 100644
index 0000000000000000000000000000000000000000..84c99e15d9b8a5821c447ef4f55ef8751b989a83
--- /dev/null
+++ b/VideoX-Fun/comfyui/cogvideox_fun/v1/cogvideoxfunv1_workflow_v2v.json
@@ -0,0 +1,489 @@
+{
+ "last_node_id": 88,
+ "last_link_id": 52,
+ "nodes": [
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": [
+ 20,
+ -300
+ ],
+ "size": {
+ "0": 210,
+ "1": 66.98204040527344
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Load model here\n(在此选择要使用的模型)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": [
+ 15.739953613281248,
+ 462.38664912015946
+ ],
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": [
+ 336,
+ 470
+ ],
+ "size": [
+ 235.1999969482422,
+ 398.971426827567
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 49
+ ],
+ "shape": 3,
+ "slot_index": 0
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "00000125.mp4",
+ "force_rate": 0,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 0,
+ "filename": "00000125.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ 160
+ ],
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 50
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "The video is not of a high quality, it has a low resolution. Watermark present in each frame. Strange motion trajectory. "
+ ]
+ },
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ -50
+ ],
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 51
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "A cute cat is playing the guitar."
+ ]
+ },
+ {
+ "id": 87,
+ "type": "CogVideoXFunV2VSampler",
+ "pos": [
+ 778,
+ 93
+ ],
+ "size": {
+ "0": 336,
+ "1": 286
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "link": 52
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 51,
+ "slot_index": 1
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 50
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": 49,
+ "slot_index": 3
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 48
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CogVideoXFunV2VSampler"
+ },
+ "widgets_values": [
+ 49,
+ 512,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 0.7,
+ "DDIM"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1134,
+ 93
+ ],
+ "size": [
+ 390.9534912109375,
+ 535.9734235491071
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 48,
+ "label": "图像",
+ "slot_index": 0
+ },
+ {
+ "name": "audio",
+ "type": "VHS_AUDIO",
+ "link": null,
+ "label": "音频"
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理"
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "shape": 3,
+ "label": "文件名",
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 8,
+ "loop_count": 0,
+ "filename_prefix": "EasyAnimate",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "EasyAnimate_00045.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 88,
+ "type": "LoadCogVideoXFunModel",
+ "pos": [
+ 309,
+ -286
+ ],
+ "size": {
+ "0": 315,
+ "1": 106
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "FunModels",
+ "links": [
+ 52
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadCogVideoXFunModel"
+ },
+ "widgets_values": [
+ "CogVideoX-Fun-2b-InP",
+ "Inpaint",
+ "model_cpu_offload",
+ "bf16"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 48,
+ 87,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 49,
+ 85,
+ 0,
+ 87,
+ 3,
+ "IMAGE"
+ ],
+ [
+ 50,
+ 73,
+ 0,
+ 87,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 51,
+ 75,
+ 0,
+ 87,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 52,
+ 88,
+ 0,
+ 87,
+ 0,
+ "FunModels"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24
+ },
+ {
+ "title": "Load CogVideoX-Fun",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24
+ },
+ {
+ "title": "Upload Your Video",
+ "bounding": [
+ 218,
+ 385,
+ 456,
+ 498
+ ],
+ "color": "#a1309b",
+ "font_size": 24
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.683013455365071,
+ "offset": [
+ 322.5575500900931,
+ 444.05399028364593
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/comfyui_nodes.py b/VideoX-Fun/comfyui/comfyui_nodes.py
new file mode 100644
index 0000000000000000000000000000000000000000..6fad69debe8ba6ede0bfb76bbc34ff5cb254fd6f
--- /dev/null
+++ b/VideoX-Fun/comfyui/comfyui_nodes.py
@@ -0,0 +1,406 @@
+import json
+
+import cv2
+import numpy as np
+import torch
+import torch.nn.functional as F
+
+from .annotator.nodes import VideoToCanny, VideoToDepth, VideoToPose
+from .camera_utils import CAMERA, combine_camera_motion, get_camera_motion
+from .cogvideox_fun.nodes import (CogVideoXFunInpaintSampler,
+ CogVideoXFunT2VSampler,
+ CogVideoXFunV2VSampler, LoadCogVideoXFunLora,
+ LoadCogVideoXFunModel)
+from .wan2_1.nodes import (LoadWanLora, LoadWanModel, WanI2VSampler,
+ WanT2VSampler)
+from .wan2_1_fun.nodes import (LoadWanFunLora, LoadWanFunModel,
+ WanFunInpaintSampler, WanFunT2VSampler,
+ WanFunV2VSampler)
+from .wan2_2.nodes import (LoadWan2_2Lora, LoadWan2_2Model, Wan2_2I2VSampler,
+ Wan2_2T2VSampler)
+from .wan2_2_fun.nodes import (LoadWan2_2FunLora, LoadWan2_2FunModel,
+ Wan2_2FunInpaintSampler, Wan2_2FunT2VSampler,
+ Wan2_2FunV2VSampler)
+
+
+class FunTextBox:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "prompt": ("STRING", {"multiline": True, "default": "",}),
+ },
+ }
+
+ RETURN_TYPES = ("STRING_PROMPT",)
+ RETURN_NAMES =("prompt",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, prompt):
+ return (prompt, )
+
+class FunRiflex:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "riflex_k": ("INT", {"default": 6, "min": 0, "max": 10086}),
+ },
+ }
+
+ RETURN_TYPES = ("RIFLEXT_ARGS",)
+ RETURN_NAMES = ("riflex_k",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, riflex_k):
+ return (riflex_k, )
+
+class FunCompile:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "cache_size_limit": ("INT", {"default": 64, "min": 0, "max": 10086}),
+ "funmodels": ("FunModels",)
+ }
+ }
+ RETURN_TYPES = ("FunModels",)
+ RETURN_NAMES = ("funmodels",)
+ FUNCTION = "compile"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def compile(self, cache_size_limit, funmodels):
+ torch._dynamo.config.cache_size_limit = cache_size_limit
+ if hasattr(funmodels["pipeline"].transformer, "blocks"):
+ for i in range(len(funmodels["pipeline"].transformer.blocks)):
+ funmodels["pipeline"].transformer.blocks[i] = torch.compile(funmodels["pipeline"].transformer.blocks[i])
+
+ if hasattr(funmodels["pipeline"], "transformer_2") and funmodels["pipeline"].transformer_2 is not None:
+ for i in range(len(funmodels["pipeline"].transformer_2.blocks)):
+ funmodels["pipeline"].transformer_2.blocks[i] = torch.compile(funmodels["pipeline"].transformer_2.blocks[i])
+
+ elif hasattr(funmodels["pipeline"].transformer, "transformer_blocks"):
+ for i in range(len(funmodels["pipeline"].transformer.transformer_blocks)):
+ funmodels["pipeline"].transformer.transformer_blocks[i] = torch.compile(funmodels["pipeline"].transformer.transformer_blocks[i])
+
+ if hasattr(funmodels["pipeline"], "transformer_2") and funmodels["pipeline"].transformer_2 is not None:
+ for i in range(len(funmodels["pipeline"].transformer_2.transformer_blocks)):
+ funmodels["pipeline"].transformer_2.transformer_blocks[i] = torch.compile(funmodels["pipeline"].transformer_2.transformer_blocks[i])
+
+ else:
+ funmodels["pipeline"].transformer.forward = torch.compile(funmodels["pipeline"].transformer.forward)
+
+ if hasattr(funmodels["pipeline"], "transformer_2") and funmodels["pipeline"].transformer_2 is not None:
+ funmodels["pipeline"].transformer_2.forward = torch.compile(funmodels["pipeline"].transformer_2.forward)
+
+ print("Add Compile")
+ return (funmodels,)
+
+def gen_gaussian_heatmap(imgSize=200):
+ circle_img = np.zeros((imgSize, imgSize,), np.float32)
+ circle_mask = cv2.circle(circle_img, (imgSize//2, imgSize//2), imgSize//2 - 1, 1, -1)
+
+ isotropicGrayscaleImage = np.zeros((imgSize, imgSize), np.float32)
+
+ # 生成高斯图
+ for i in range(imgSize):
+ for j in range(imgSize):
+ isotropicGrayscaleImage[i, j] = 1 / (2 * np.pi * (40 ** 2)) * np.exp(
+ -1 / 2 * ((i - imgSize / 2) ** 2 / (40 ** 2) + (j - imgSize / 2) ** 2 / (40 ** 2)))
+
+ isotropicGrayscaleImage = isotropicGrayscaleImage * circle_mask
+ isotropicGrayscaleImage = (isotropicGrayscaleImage / np.max(isotropicGrayscaleImage) * 255).astype(np.uint8)
+ return isotropicGrayscaleImage
+
+class CreateTrajectoryBasedOnKJNodes:
+ # Modified from https://github.com/kijai/ComfyUI-KJNodes/blob/main/nodes/curve_nodes.py
+ # Modify to meet the trajectory control requirements of EasyAnimate.
+ RETURN_TYPES = ("IMAGE", )
+ RETURN_NAMES = ("image", )
+ FUNCTION = "createtrajectory"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "coordinates": ("STRING", {"forceInput": True}),
+ "masks": ("MASK", {"forceInput": True}),
+ },
+ }
+
+ def createtrajectory(self, coordinates, masks):
+ # Define the number of images in the batch
+ if len(coordinates) < 10:
+ coords_list = []
+ for coords in coordinates:
+ coords = json.loads(coords.replace("'", '"'))
+ coords_list.append(coords)
+ else:
+ coords = json.loads(coordinates.replace("'", '"'))
+ coords_list = [coords]
+
+ _, frame_height, frame_width = masks.size()
+ heatmap = gen_gaussian_heatmap()
+
+ circle_size = int(50 * ((frame_height * frame_width) / (1280 * 720)) ** (1/2))
+
+ images_list = []
+ for coords in coords_list:
+ _images_list = []
+ for i in range(len(coords)):
+ _image = np.zeros((frame_height, frame_width, 3))
+ center_coordinate = [coords[i][key] for key in coords[i]]
+
+ y1 = max(center_coordinate[1] - circle_size, 0)
+ y2 = min(center_coordinate[1] + circle_size, np.shape(_image)[0] - 1)
+ x1 = max(center_coordinate[0] - circle_size, 0)
+ x2 = min(center_coordinate[0] + circle_size, np.shape(_image)[1] - 1)
+
+ if x2 - x1 > 3 and y2 - y1 > 3:
+ need_map = cv2.resize(heatmap, (x2 - x1, y2 - y1))[:, :, None]
+ _image[y1:y2, x1:x2] = np.maximum(need_map.copy(), _image[y1:y2, x1:x2])
+
+ _image = np.expand_dims(_image, 0) / 255
+ _images_list.append(_image)
+ images_list.append(np.concatenate(_images_list, axis=0))
+
+ out_images = torch.from_numpy(np.max(np.array(images_list), axis=0))
+ return (out_images, )
+
+class ImageMaximumNode:
+ RETURN_TYPES = ("IMAGE", )
+ RETURN_NAMES = ("image", )
+ FUNCTION = "imagemaximum"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "video_1": ("IMAGE",),
+ "video_2": ("IMAGE",),
+ },
+ }
+
+ def imagemaximum(self, video_1, video_2):
+ length_1, h_1, w_1, c_1 = video_1.size()
+ length_2, h_2, w_2, c_2 = video_2.size()
+
+ if h_1 != h_2 or w_1 != w_2:
+ video_1, video_2 = video_1.permute([0, 3, 1, 2]), video_2.permute([0, 3, 1, 2])
+ video_2 = F.interpolate(video_2, video_1.size()[-2:])
+ video_1, video_2 = video_1.permute([0, 2, 3, 1]), video_2.permute([0, 2, 3, 1])
+
+ if length_1 > length_2:
+ outputs = torch.maximum(video_1[:length_2], video_2)
+ else:
+ outputs = torch.maximum(video_1, video_2[:length_1])
+ return (outputs, )
+
+class CameraBasicFromChaoJie:
+ # Copied from https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper/blob/main/nodes.py
+ # Since ComfyUI-CameraCtrl-Wrapper requires a specific version of diffusers, which is not suitable for us.
+ # The code has been copied into the current repository.
+ @classmethod
+ def INPUT_TYPES(cls):
+ return {
+ "required": {
+ "camera_pose":(["Static","Pan Up","Pan Down","Pan Left","Pan Right","Zoom In","Zoom Out","ACW","CW"],{"default":"Static"}),
+ "speed":("FLOAT",{"default":1.0}),
+ "video_length":("INT",{"default":16}),
+ },
+ }
+
+ RETURN_TYPES = ("CameraPose",)
+ FUNCTION = "run"
+ CATEGORY = "CameraCtrl"
+
+ def run(self,camera_pose,speed,video_length):
+ camera_dict = {
+ "motion":[camera_pose],
+ "mode": "Basic Camera Poses", # "First A then B", "Both A and B", "Custom"
+ "speed": speed,
+ "complex": None
+ }
+ motion_list = camera_dict['motion']
+ mode = camera_dict['mode']
+ speed = camera_dict['speed']
+ angle = np.array(CAMERA[motion_list[0]]["angle"])
+ T = np.array(CAMERA[motion_list[0]]["T"])
+ RT = get_camera_motion(angle, T, speed, video_length)
+ return (RT,)
+
+class CameraCombineFromChaoJie:
+ # Copied from https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper/blob/main/nodes.py
+ # Since ComfyUI-CameraCtrl-Wrapper requires a specific version of diffusers, which is not suitable for us.
+ # The code has been copied into the current repository.
+ @classmethod
+ def INPUT_TYPES(cls):
+ return {
+ "required": {
+ "camera_pose1":(["Static","Pan Up","Pan Down","Pan Left","Pan Right","Zoom In","Zoom Out","ACW","CW"],{"default":"Static"}),
+ "camera_pose2":(["Static","Pan Up","Pan Down","Pan Left","Pan Right","Zoom In","Zoom Out","ACW","CW"],{"default":"Static"}),
+ "camera_pose3":(["Static","Pan Up","Pan Down","Pan Left","Pan Right","Zoom In","Zoom Out","ACW","CW"],{"default":"Static"}),
+ "camera_pose4":(["Static","Pan Up","Pan Down","Pan Left","Pan Right","Zoom In","Zoom Out","ACW","CW"],{"default":"Static"}),
+ "speed":("FLOAT",{"default":1.0}),
+ "video_length":("INT",{"default":16}),
+ },
+ }
+
+ RETURN_TYPES = ("CameraPose",)
+ FUNCTION = "run"
+ CATEGORY = "CameraCtrl"
+
+ def run(self,camera_pose1,camera_pose2,camera_pose3,camera_pose4,speed,video_length):
+ angle = np.array(CAMERA[camera_pose1]["angle"]) + np.array(CAMERA[camera_pose2]["angle"]) + np.array(CAMERA[camera_pose3]["angle"]) + np.array(CAMERA[camera_pose4]["angle"])
+ T = np.array(CAMERA[camera_pose1]["T"]) + np.array(CAMERA[camera_pose2]["T"]) + np.array(CAMERA[camera_pose3]["T"]) + np.array(CAMERA[camera_pose4]["T"])
+ RT = get_camera_motion(angle, T, speed, video_length)
+ return (RT,)
+
+class CameraJoinFromChaoJie:
+ # Copied from https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper/blob/main/nodes.py
+ # Since ComfyUI-CameraCtrl-Wrapper requires a specific version of diffusers, which is not suitable for us.
+ # The code has been copied into the current repository.
+ @classmethod
+ def INPUT_TYPES(cls):
+ return {
+ "required": {
+ "camera_pose1":("CameraPose",),
+ "camera_pose2":("CameraPose",),
+ },
+ }
+
+ RETURN_TYPES = ("CameraPose",)
+ FUNCTION = "run"
+ CATEGORY = "CameraCtrl"
+
+ def run(self,camera_pose1,camera_pose2):
+ RT = combine_camera_motion(camera_pose1, camera_pose2)
+ return (RT,)
+
+class CameraTrajectoryFromChaoJie:
+ # Copied from https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper/blob/main/nodes.py
+ # Since ComfyUI-CameraCtrl-Wrapper requires a specific version of diffusers, which is not suitable for us.
+ # The code has been copied into the current repository.
+ @classmethod
+ def INPUT_TYPES(cls):
+ return {
+ "required": {
+ "camera_pose":("CameraPose",),
+ "fx":("FLOAT",{"default":0.474812461, "min": 0, "max": 1, "step": 0.000000001}),
+ "fy":("FLOAT",{"default":0.844111024, "min": 0, "max": 1, "step": 0.000000001}),
+ "cx":("FLOAT",{"default":0.5, "min": 0, "max": 1, "step": 0.01}),
+ "cy":("FLOAT",{"default":0.5, "min": 0, "max": 1, "step": 0.01}),
+ },
+ }
+
+ RETURN_TYPES = ("STRING","INT",)
+ RETURN_NAMES = ("camera_trajectory","video_length",)
+ FUNCTION = "run"
+ CATEGORY = "CameraCtrl"
+
+ def run(self,camera_pose,fx,fy,cx,cy):
+ #print(camera_pose)
+ camera_pose_list=camera_pose.tolist()
+ trajs=[]
+ for cp in camera_pose_list:
+ traj=[fx,fy,cx,cy,0,0]
+ traj.extend(cp[0])
+ traj.extend(cp[1])
+ traj.extend(cp[2])
+ trajs.append(traj)
+ return (json.dumps(trajs),len(trajs),)
+
+NODE_CLASS_MAPPINGS = {
+ "FunTextBox": FunTextBox,
+ "FunRiflex": FunRiflex,
+ "FunCompile": FunCompile,
+
+ "LoadCogVideoXFunModel": LoadCogVideoXFunModel,
+ "LoadCogVideoXFunLora": LoadCogVideoXFunLora,
+ "CogVideoXFunT2VSampler": CogVideoXFunT2VSampler,
+ "CogVideoXFunInpaintSampler": CogVideoXFunInpaintSampler,
+ "CogVideoXFunV2VSampler": CogVideoXFunV2VSampler,
+
+ "LoadWanModel": LoadWanModel,
+ "LoadWanLora": LoadWanLora,
+ "WanT2VSampler": WanT2VSampler,
+ "WanI2VSampler": WanI2VSampler,
+
+ "LoadWanFunModel": LoadWanFunModel,
+ "LoadWanFunLora": LoadWanFunLora,
+ "WanFunT2VSampler": WanFunT2VSampler,
+ "WanFunInpaintSampler": WanFunInpaintSampler,
+ "WanFunV2VSampler": WanFunV2VSampler,
+
+ "LoadWan2_2Model": LoadWan2_2Model,
+ "LoadWan2_2Lora": LoadWan2_2Lora,
+ "Wan2_2T2VSampler": Wan2_2T2VSampler,
+ "Wan2_2I2VSampler": Wan2_2I2VSampler,
+
+ "LoadWan2_2FunModel": LoadWan2_2FunModel,
+ "LoadWan2_2FunLora": LoadWan2_2FunLora,
+ "Wan2_2FunT2VSampler": Wan2_2FunT2VSampler,
+ "Wan2_2FunInpaintSampler": Wan2_2FunInpaintSampler,
+ "Wan2_2FunV2VSampler": Wan2_2FunV2VSampler,
+
+ "VideoToCanny": VideoToCanny,
+ "VideoToDepth": VideoToDepth,
+ "VideoToOpenpose": VideoToPose,
+
+ "CreateTrajectoryBasedOnKJNodes": CreateTrajectoryBasedOnKJNodes,
+ "CameraBasicFromChaoJie": CameraBasicFromChaoJie,
+ "CameraTrajectoryFromChaoJie": CameraTrajectoryFromChaoJie,
+ "CameraJoinFromChaoJie": CameraJoinFromChaoJie,
+ "CameraCombineFromChaoJie": CameraCombineFromChaoJie,
+ "ImageMaximumNode": ImageMaximumNode,
+}
+
+
+NODE_DISPLAY_NAME_MAPPINGS = {
+ "FunTextBox": "FunTextBox",
+ "FunRiflex": "FunRiflex",
+ "FunCompile": "FunCompile",
+
+ "LoadCogVideoXFunModel": "Load CogVideoX-Fun Model",
+ "LoadCogVideoXFunLora": "Load CogVideoX-Fun Lora",
+ "CogVideoXFunInpaintSampler": "CogVideoX-Fun Sampler for Image to Video",
+ "CogVideoXFunT2VSampler": "CogVideoX-Fun Sampler for Text to Video",
+ "CogVideoXFunV2VSampler": "CogVideoX-Fun Sampler for Video to Video",
+
+ "LoadWanModel": "Load Wan Model",
+ "LoadWanLora": "Load Wan Lora",
+ "WanT2VSampler": "Wan Sampler for Text to Video",
+ "WanI2VSampler": "Wan Sampler for Image to Video",
+
+ "LoadWanFunModel": "Load Wan Fun Model",
+ "LoadWanFunLora": "Load Wan Fun Lora",
+ "WanFunT2VSampler": "Wan Fun Sampler for Text to Video",
+ "WanFunInpaintSampler": "Wan Fun Sampler for Image to Video",
+ "WanFunV2VSampler": "Wan Fun Sampler for Video to Video",
+
+ "LoadWan2_2Model": "Load Wan 2.2 Model",
+ "LoadWan2_2Lora": "Load Wan 2.2 Lora",
+ "Wan2_2T2VSampler": "Wan 2.2 Sampler for Text to Video",
+ "Wan2_2I2VSampler": "Wan 2.2 Sampler for Image to Video",
+
+ "LoadWan2_2FunModel": "Load Wan 2.2 Fun Model",
+ "LoadWan2_2FunLora": "Load Wan 2.2 Fun Lora",
+ "Wan2_2FunT2VSampler": "Wan 2.2 Fun Sampler for Text to Video",
+ "Wan2_2FunInpaintSampler": "Wan 2.2 Fun Sampler for Image to Video",
+ "Wan2_2FunV2VSampler": "Wan 2.2 Fun Sampler for Video to Video",
+
+ "VideoToCanny": "Video To Canny",
+ "VideoToDepth": "Video To Depth",
+ "VideoToOpenpose": "Video To Pose",
+
+ "CreateTrajectoryBasedOnKJNodes": "Create Trajectory Based On KJNodes",
+ "CameraBasicFromChaoJie": "Camera Basic From ChaoJie",
+ "CameraTrajectoryFromChaoJie": "Camera Trajectory From ChaoJie",
+ "CameraJoinFromChaoJie": "Camera Join From ChaoJie",
+ "CameraCombineFromChaoJie": "Camera Combine From ChaoJie",
+ "ImageMaximumNode": "Image Maximum Node",
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/comfyui_utils.py b/VideoX-Fun/comfyui/comfyui_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..2a1163f78bc987c09b94f0881a54c9e36f5849c6
--- /dev/null
+++ b/VideoX-Fun/comfyui/comfyui_utils.py
@@ -0,0 +1,25 @@
+import os
+
+import numpy as np
+import torch
+from PIL import Image
+
+# Compatible with Alibaba EAS for quick launch
+eas_cache_dir = '/stable-diffusion-cache/models'
+# The directory of the cogvideoxfun
+script_directory = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
+
+def tensor2pil(image):
+ return Image.fromarray(np.clip(255. * image.cpu().numpy(), 0, 255).astype(np.uint8))
+
+def numpy2pil(image):
+ return Image.fromarray(np.clip(255. * image, 0, 255).astype(np.uint8))
+
+def to_pil(image):
+ if isinstance(image, Image.Image):
+ return image
+ if isinstance(image, torch.Tensor):
+ return tensor2pil(image)
+ if isinstance(image, np.ndarray):
+ return numpy2pil(image)
+ raise ValueError(f"Cannot convert {type(image)} to PIL.Image")
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_1/nodes.py b/VideoX-Fun/comfyui/wan2_1/nodes.py
new file mode 100644
index 0000000000000000000000000000000000000000..fda736ab2d2a8998fbd4da82f3c0367c826b9aee
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_1/nodes.py
@@ -0,0 +1,590 @@
+"""Modified from https://github.com/kijai/ComfyUI-EasyAnimateWrapper/blob/main/nodes.py
+"""
+import copy
+import gc
+import json
+import os
+
+import comfy.model_management as mm
+import cv2
+import folder_paths
+import numpy as np
+import torch
+from comfy.utils import ProgressBar, load_torch_file
+from diffusers import FlowMatchEulerDiscreteScheduler
+from einops import rearrange
+from omegaconf import OmegaConf
+from PIL import Image
+
+from ...videox_fun.data.bucket_sampler import (ASPECT_RATIO_512,
+ get_closest_ratio)
+from ...videox_fun.models import (AutoencoderKLWan, AutoTokenizer, CLIPModel,
+ WanT5EncoderModel, WanTransformer3DModel)
+from ...videox_fun.pipeline import WanI2VPipeline, WanPipeline
+from ...videox_fun.ui.controller import all_cheduler_dict
+from ...videox_fun.utils.fp8_optimization import (
+ convert_model_weight_to_float8, convert_weight_dtype_wrapper, replace_parameters_by_name)
+from ...videox_fun.utils.lora_utils import merge_lora, unmerge_lora
+from ...videox_fun.utils.utils import (get_image_to_video_latent, filter_kwargs,
+ get_video_to_video_latent,
+ save_videos_grid)
+from ...videox_fun.models.cache_utils import get_teacache_coefficients
+from ..comfyui_utils import eas_cache_dir, script_directory, to_pil
+
+# Used in lora cache
+transformer_cpu_cache = {}
+# lora path before
+lora_path_before = ""
+
+def filter_kwargs(cls, kwargs):
+ import inspect
+ sig = inspect.signature(cls.__init__)
+ valid_params = set(sig.parameters.keys()) - {'self', 'cls'}
+ filtered_kwargs = {k: v for k, v in kwargs.items() if k in valid_params}
+ return filtered_kwargs
+
+class LoadWanModel:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "model": (
+ [
+ 'Wan2.1-T2V-1.3B',
+ 'Wan2.1-T2V-14B',
+ 'Wan2.1-I2V-14B-480P',
+ 'Wan2.1-I2V-14B-720P',
+ ],
+ {
+ "default": 'Wan2.1-T2V-1.3B',
+ }
+ ),
+ "GPU_memory_mode":(
+ ["model_full_load", "model_cpu_offload", "model_cpu_offload_and_qfloat8", "sequential_cpu_offload"],
+ {
+ "default": "model_cpu_offload",
+ }
+ ),
+ "config": (
+ [
+ "wan2.1/wan_civitai.yaml",
+ ],
+ {
+ "default": "wan2.1/wan_civitai.yaml",
+ }
+ ),
+ "precision": (
+ ['fp16', 'bf16'],
+ {
+ "default": 'fp16'
+ }
+ ),
+ },
+ }
+
+ RETURN_TYPES = ("FunModels",)
+ RETURN_NAMES = ("funmodels",)
+ FUNCTION = "loadmodel"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def loadmodel(self, GPU_memory_mode, model, precision, config):
+ # Init weight_dtype and device
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+ weight_dtype = {"bf16": torch.bfloat16, "fp16": torch.float16, "fp32": torch.float32}[precision]
+
+ # Init processbar
+ pbar = ProgressBar(5)
+
+ # Load config
+ config_path = f"{script_directory}/config/{config}"
+ config = OmegaConf.load(config_path)
+
+ # Detect model is existing or not
+ possible_folders = ["CogVideoX_Fun", "Fun_Models", "VideoX_Fun"] + \
+ [os.path.join(os.path.dirname(os.path.dirname(os.path.dirname(os.path.abspath(__file__)))), "models/Diffusion_Transformer")] # Possible folder names to check
+ # Initialize model_name as None
+ model_name = None
+
+ # Check if the model exists in any of the possible folders within folder_paths.models_dir
+ for folder in possible_folders:
+ candidate_path = os.path.join(folder_paths.models_dir, folder, model)
+ if os.path.exists(candidate_path):
+ model_name = candidate_path
+ break
+
+ # If model_name is still None, check eas_cache_dir for each possible folder
+ if model_name is None and os.path.exists(eas_cache_dir):
+ for folder in possible_folders:
+ candidate_path = os.path.join(eas_cache_dir, folder, model)
+ if os.path.exists(candidate_path):
+ model_name = candidate_path
+ break
+
+ # If model_name is still None, prompt the user to download the model
+ if model_name is None:
+ print(f"Please download cogvideoxfun model to one of the following directories:")
+ for folder in possible_folders:
+ print(f"- {os.path.join(folder_paths.models_dir, folder)}")
+ if os.path.exists(eas_cache_dir):
+ print(f"- {os.path.join(eas_cache_dir, folder)}")
+ raise ValueError("Please download Fun model")
+
+ vae = AutoencoderKLWan.from_pretrained(
+ os.path.join(model_name, config['vae_kwargs'].get('vae_subpath', 'vae')),
+ additional_kwargs=OmegaConf.to_container(config['vae_kwargs']),
+ ).to(weight_dtype)
+ # Update pbar
+ pbar.update(1)
+
+ # Load Sampler
+ print("Load Sampler.")
+ scheduler = FlowMatchEulerDiscreteScheduler(
+ **filter_kwargs(FlowMatchEulerDiscreteScheduler, OmegaConf.to_container(config['scheduler_kwargs']))
+ )
+ # Update pbar
+ pbar.update(1)
+
+ # Get Transformer
+ transformer = WanTransformer3DModel.from_pretrained(
+ os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
+ transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
+ low_cpu_mem_usage=True,
+ torch_dtype=weight_dtype,
+ )
+ # Update pbar
+ pbar.update(1)
+
+ # Get tokenizer and text_encoder
+ tokenizer = AutoTokenizer.from_pretrained(
+ os.path.join(model_name, config['text_encoder_kwargs'].get('tokenizer_subpath', 'tokenizer')),
+ )
+ pbar.update(1)
+
+ text_encoder = WanT5EncoderModel.from_pretrained(
+ os.path.join(model_name, config['text_encoder_kwargs'].get('text_encoder_subpath', 'text_encoder')),
+ additional_kwargs=OmegaConf.to_container(config['text_encoder_kwargs']),
+ low_cpu_mem_usage=True,
+ torch_dtype=weight_dtype,
+ )
+ pbar.update(1)
+
+ if transformer.config.in_channels != vae.config.latent_channels:
+ # Get Clip Image Encoder
+ clip_image_encoder = CLIPModel.from_pretrained(
+ os.path.join(model_name, config['image_encoder_kwargs'].get('image_encoder_subpath', 'image_encoder')),
+ ).to(weight_dtype)
+ clip_image_encoder = clip_image_encoder.eval()
+
+ # Get pipeline
+ model_type = "Inpaint"
+ if model_type == "Inpaint":
+ if transformer.config.in_channels != vae.config.latent_channels:
+ pipeline = WanI2VPipeline(
+ vae=vae,
+ tokenizer=tokenizer,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ scheduler=scheduler,
+ clip_image_encoder=clip_image_encoder
+ )
+ else:
+ pipeline = WanPipeline(
+ vae=vae,
+ tokenizer=tokenizer,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ scheduler=scheduler,
+ )
+ else:
+ raise ValueError(f"Model type {model_type} not supported")
+
+ if GPU_memory_mode == "sequential_cpu_offload":
+ replace_parameters_by_name(transformer, ["modulation",], device="cuda")
+ transformer.freqs = transformer.freqs.to(device="cuda")
+ pipeline.enable_sequential_cpu_offload()
+ elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
+ convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",])
+ convert_weight_dtype_wrapper(transformer, weight_dtype)
+ pipeline.enable_model_cpu_offload()
+ elif GPU_memory_mode == "model_cpu_offload":
+ pipeline.enable_model_cpu_offload()
+ elif GPU_memory_mode == "model_full_load_and_qfloat8":
+ convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",])
+ convert_weight_dtype_wrapper(transformer, weight_dtype)
+ pipeline.to(device=device)
+ else:
+ pipeline.to("cuda")
+
+ funmodels = {
+ 'pipeline': pipeline,
+ 'dtype': weight_dtype,
+ 'model_name': model_name,
+ 'model_type': model_type,
+ 'loras': [],
+ 'strength_model': [],
+ 'config': config,
+ }
+ return (funmodels,)
+
+class LoadWanLora:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "funmodels": ("FunModels",),
+ "lora_name": (folder_paths.get_filename_list("loras"), {"default": None,}),
+ "strength_model": ("FLOAT", {"default": 1.0, "min": -100.0, "max": 100.0, "step": 0.01}),
+ "lora_cache":([False, True], {"default": False,}),
+ }
+ }
+ RETURN_TYPES = ("FunModels",)
+ RETURN_NAMES = ("funmodels",)
+ FUNCTION = "load_lora"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def load_lora(self, funmodels, lora_name, strength_model, lora_cache):
+ if lora_name is not None:
+ funmodels['lora_cache'] = lora_cache
+ funmodels['loras'] = funmodels.get("loras", []) + [folder_paths.get_full_path("loras", lora_name)]
+ funmodels['strength_model'] = funmodels.get("strength_model", []) + [strength_model]
+ return (funmodels,)
+ else:
+ return (funmodels,)
+
+class WanT2VSampler:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "funmodels": (
+ "FunModels",
+ ),
+ "prompt": (
+ "STRING_PROMPT",
+ ),
+ "negative_prompt": (
+ "STRING_PROMPT",
+ ),
+ "video_length": (
+ "INT", {"default": 81, "min": 5, "max": 161, "step": 4}
+ ),
+ "width": (
+ "INT", {"default": 832, "min": 64, "max": 2048, "step": 16}
+ ),
+ "height": (
+ "INT", {"default": 480, "min": 64, "max": 2048, "step": 16}
+ ),
+ "is_image":(
+ [
+ False,
+ True
+ ],
+ {
+ "default": False,
+ }
+ ),
+ "seed": (
+ "INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
+ ),
+ "steps": (
+ "INT", {"default": 50, "min": 1, "max": 200, "step": 1}
+ ),
+ "cfg": (
+ "FLOAT", {"default": 6.0, "min": 1.0, "max": 20.0, "step": 0.01}
+ ),
+ "scheduler": (
+ [
+ "Flow",
+ ],
+ {
+ "default": 'Flow'
+ }
+ ),
+ "teacache_threshold": (
+ "FLOAT", {"default": 0.10, "min": 0.00, "max": 1.00, "step": 0.005}
+ ),
+ "enable_teacache":(
+ [False, True], {"default": True,}
+ ),
+ "num_skip_start_steps": (
+ "INT", {"default": 5, "min": 0, "max": 50, "step": 1}
+ ),
+ "teacache_offload":(
+ [False, True], {"default": True,}
+ ),
+ "cfg_skip_ratio":(
+ "FLOAT", {"default": 0, "min": 0, "max": 1, "step": 0.01}
+ ),
+ },
+ "optional":{
+ "riflex_k": ("RIFLEXT_ARGS",),
+ },
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES =("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, funmodels, prompt, negative_prompt, video_length, width, height, is_image, seed, steps, cfg, scheduler, teacache_threshold, enable_teacache, num_skip_start_steps, teacache_offload, cfg_skip_ratio, riflex_k=0):
+ global transformer_cpu_cache
+ global lora_path_before
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+
+ mm.soft_empty_cache()
+ gc.collect()
+
+ # Get Pipeline
+ pipeline = funmodels['pipeline']
+ model_name = funmodels['model_name']
+ config = funmodels['config']
+ weight_dtype = funmodels['dtype']
+
+ # Load Sampler
+ pipeline.scheduler = all_cheduler_dict[scheduler](**filter_kwargs(all_cheduler_dict[scheduler], OmegaConf.to_container(config['scheduler_kwargs'])))
+
+ coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
+ if coefficients is not None:
+ print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
+ pipeline.transformer.enable_teacache(
+ coefficients, steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
+ )
+ else:
+ pipeline.transformer.disable_teacache()
+
+ if cfg_skip_ratio is not None:
+ print(f"Enable cfg_skip_ratio {cfg_skip_ratio}.")
+ pipeline.transformer.enable_cfg_skip(cfg_skip_ratio, steps)
+
+ generator= torch.Generator(device).manual_seed(seed)
+
+ video_length = 1 if is_image else video_length
+ with torch.no_grad():
+ video_length = int((video_length - 1) // pipeline.vae.config.temporal_compression_ratio * pipeline.vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+
+ if riflex_k > 0:
+ latent_frames = (video_length - 1) // pipeline.vae.config.temporal_compression_ratio + 1
+ pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
+
+ # Apply lora
+ if funmodels.get("lora_cache", False):
+ if len(funmodels.get("loras", [])) != 0:
+ # Save the original weights to cpu
+ if len(transformer_cpu_cache) == 0:
+ print('Save transformer state_dict to cpu memory')
+ transformer_state_dict = pipeline.transformer.state_dict()
+ for key in transformer_state_dict:
+ transformer_cpu_cache[key] = transformer_state_dict[key].clone().cpu()
+
+ lora_path_now = str(funmodels.get("loras", []) + funmodels.get("strength_model", []))
+ if lora_path_now != lora_path_before:
+ print('Merge Lora with Cache')
+ lora_path_before = copy.deepcopy(lora_path_now)
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ else:
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if len(transformer_cpu_cache) != 0:
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ transformer_cpu_cache = {}
+ lora_path_before = ""
+ gc.collect()
+ print('Merge Lora')
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ comfyui_progressbar = True,
+ ).videos
+ videos = rearrange(sample, "b c t h w -> (b t) h w c")
+
+ if not funmodels.get("lora_cache", False):
+ print('Unmerge Lora')
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ return (videos,)
+
+
+class WanI2VSampler:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "funmodels": (
+ "FunModels",
+ ),
+ "prompt": (
+ "STRING_PROMPT",
+ ),
+ "negative_prompt": (
+ "STRING_PROMPT",
+ ),
+ "video_length": (
+ "INT", {"default": 81, "min": 5, "max": 161, "step": 4}
+ ),
+ "base_resolution": (
+ [
+ 512,
+ 640,
+ 768,
+ 896,
+ 960,
+ 1024,
+ ], {"default": 640}
+ ),
+ "seed": (
+ "INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
+ ),
+ "steps": (
+ "INT", {"default": 50, "min": 1, "max": 200, "step": 1}
+ ),
+ "cfg": (
+ "FLOAT", {"default": 6.0, "min": 1.0, "max": 20.0, "step": 0.01}
+ ),
+ "scheduler": (
+ [
+ "Flow",
+ ],
+ {
+ "default": 'Flow'
+ }
+ ),
+ "teacache_threshold": (
+ "FLOAT", {"default": 0.10, "min": 0.00, "max": 1.00, "step": 0.005}
+ ),
+ "enable_teacache":(
+ [False, True], {"default": True,}
+ ),
+ "num_skip_start_steps": (
+ "INT", {"default": 5, "min": 0, "max": 50, "step": 1}
+ ),
+ "teacache_offload":(
+ [False, True], {"default": True,}
+ ),
+ "cfg_skip_ratio":(
+ "FLOAT", {"default": 0, "min": 0, "max": 1, "step": 0.01}
+ ),
+ },
+ "optional":{
+ "start_img": ("IMAGE",),
+ "riflex_k": ("RIFLEXT_ARGS",),
+ },
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES =("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, funmodels, prompt, negative_prompt, video_length, base_resolution, seed, steps, cfg, scheduler, teacache_threshold, enable_teacache, num_skip_start_steps, teacache_offload, cfg_skip_ratio, start_img=None, end_img=None, riflex_k=0):
+ global transformer_cpu_cache
+ global lora_path_before
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+
+ mm.soft_empty_cache()
+ gc.collect()
+
+ start_img = [to_pil(_start_img) for _start_img in start_img] if start_img is not None else None
+ end_img = [to_pil(_end_img) for _end_img in end_img] if end_img is not None else None
+ # Count most suitable height and width
+ aspect_ratio_sample_size = {key : [x / 512 * base_resolution for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+ original_width, original_height = start_img[0].size if type(start_img) is list else Image.open(start_img).size
+ closest_size, closest_ratio = get_closest_ratio(original_height, original_width, ratios=aspect_ratio_sample_size)
+ height, width = [int(x / 16) * 16 for x in closest_size]
+
+ # Get Pipeline
+ pipeline = funmodels['pipeline']
+ model_name = funmodels['model_name']
+ config = funmodels['config']
+ weight_dtype = funmodels['dtype']
+
+ # Load Sampler
+ pipeline.scheduler = all_cheduler_dict[scheduler](**filter_kwargs(all_cheduler_dict[scheduler], OmegaConf.to_container(config['scheduler_kwargs'])))
+ coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
+ if coefficients is not None:
+ print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
+ pipeline.transformer.enable_teacache(
+ coefficients, steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
+ )
+ else:
+ pipeline.transformer.disable_teacache()
+
+ if cfg_skip_ratio is not None:
+ print(f"Enable cfg_skip_ratio {cfg_skip_ratio}.")
+ pipeline.transformer.enable_cfg_skip(cfg_skip_ratio, steps)
+
+ generator= torch.Generator(device).manual_seed(seed)
+
+ with torch.no_grad():
+ video_length = int((video_length - 1) // pipeline.vae.config.temporal_compression_ratio * pipeline.vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(start_img, end_img, video_length=video_length, sample_size=(height, width))
+
+ if riflex_k > 0:
+ latent_frames = (video_length - 1) // pipeline.vae.config.temporal_compression_ratio + 1
+ pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
+
+ # Apply lora
+ if funmodels.get("lora_cache", False):
+ if len(funmodels.get("loras", [])) != 0:
+ # Save the original weights to cpu
+ if len(transformer_cpu_cache) == 0:
+ print('Save transformer state_dict to cpu memory')
+ transformer_state_dict = pipeline.transformer.state_dict()
+ for key in transformer_state_dict:
+ transformer_cpu_cache[key] = transformer_state_dict[key].clone().cpu()
+
+ lora_path_now = str(funmodels.get("loras", []) + funmodels.get("strength_model", []))
+ if lora_path_now != lora_path_before:
+ print('Merge Lora with Cache')
+ lora_path_before = copy.deepcopy(lora_path_now)
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ else:
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if len(transformer_cpu_cache) != 0:
+ print('Delete cpu state_dict')
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ transformer_cpu_cache = {}
+ lora_path_before = ""
+ gc.collect()
+ print('Merge Lora')
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ clip_image = clip_image,
+ comfyui_progressbar = True,
+ ).videos
+ videos = rearrange(sample, "b c t h w -> (b t) h w c")
+
+ if not funmodels.get("lora_cache", False):
+ print('Unmerge Lora')
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ return (videos,)
+
diff --git a/VideoX-Fun/comfyui/wan2_1/v1/wan2.1_workflow_i2v.json b/VideoX-Fun/comfyui/wan2_1/v1/wan2.1_workflow_i2v.json
new file mode 100644
index 0000000000000000000000000000000000000000..30ebb28c6793468b7001cd21a9dda584c153419e
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_1/v1/wan2.1_workflow_i2v.json
@@ -0,0 +1,490 @@
+{
+ "last_node_id": 97,
+ "last_link_id": 63,
+ "nodes": [
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": -50
+ },
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 60
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1277,
+ "1": -70
+ },
+ "size": [
+ 390,
+ 310
+ ],
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 63,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00008.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 87,
+ "type": "LoadImage",
+ "pos": {
+ "0": 306,
+ "1": 495
+ },
+ "size": {
+ "0": 315,
+ "1": 314
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 62
+ ]
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "6.png",
+ "image"
+ ]
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 94,
+ "type": "Note",
+ "pos": {
+ "0": 17,
+ "1": -35
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 95,
+ "type": "Note",
+ "pos": {
+ "0": 34,
+ "1": 550
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload image here\n(你可以在此上传图片)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 97,
+ "type": "LoadWanModel",
+ "pos": {
+ "0": 304,
+ "1": -299
+ },
+ "size": {
+ "0": 315,
+ "1": 130
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 59
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanModel"
+ },
+ "widgets_values": [
+ "Wan2.1-I2V-14B-720P",
+ "sequential_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 96,
+ "type": "WanI2VSampler",
+ "pos": {
+ "0": 796,
+ "1": -70
+ },
+ "size": {
+ "0": 378,
+ "1": 358
+ },
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 59
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 60
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 61
+ },
+ {
+ "name": "start_img",
+ "type": "IMAGE",
+ "link": 62,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 63
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanI2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 507671483727948,
+ "randomize",
+ 50,
+ 6,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ },
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": {
+ "0": -75,
+ "1": -297
+ },
+ "size": {
+ "0": 350.7127990722656,
+ "1": 125.54820251464844
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": 160
+ },
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 61
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 59,
+ 97,
+ 0,
+ 96,
+ 0,
+ "FunModels"
+ ],
+ [
+ 60,
+ 75,
+ 0,
+ 96,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 61,
+ 73,
+ 0,
+ 96,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 62,
+ 87,
+ 0,
+ 96,
+ 3,
+ "IMAGE"
+ ],
+ [
+ 63,
+ 96,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Load Model",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Group",
+ "bounding": [
+ 220,
+ 409,
+ 458,
+ 436
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650705,
+ "offset": [
+ 356.367407042801,
+ 487.2362084107991
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "e054344e39c5030c23b0146ed4a1293bff2505ed",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "comfy-core": "v0.2.7-3-g8afb97c"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_1/v1/wan2.1_workflow_t2v.json b/VideoX-Fun/comfyui/wan2_1/v1/wan2.1_workflow_t2v.json
new file mode 100644
index 0000000000000000000000000000000000000000..d1823525937657d58e257a366ede6d228cc94854
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_1/v1/wan2.1_workflow_t2v.json
@@ -0,0 +1,378 @@
+{
+ "last_node_id": 85,
+ "last_link_id": 53,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": -50
+ },
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 49
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 85,
+ "type": "WanT2VSampler",
+ "pos": {
+ "0": 722,
+ "1": -73
+ },
+ "size": {
+ "0": 365.4000244140625,
+ "1": 386
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 48
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 49
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 52
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 53
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanT2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 832,
+ 480,
+ false,
+ 837135609139060,
+ "randomize",
+ 50,
+ 6,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1126,
+ "1": -73
+ },
+ "size": [
+ 390.9534912109375,
+ 310
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 53,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00008.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 84,
+ "type": "LoadWanModel",
+ "pos": {
+ "0": 286,
+ "1": -297
+ },
+ "size": {
+ "0": 315,
+ "1": 130
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 48
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanModel"
+ },
+ "widgets_values": [
+ "Wan2.1-T2V-1.3B",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": {
+ "0": -92,
+ "1": -294
+ },
+ "size": {
+ "0": 351.1499938964844,
+ "1": 130.12660217285156
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": 160
+ },
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 52
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 48,
+ 84,
+ 0,
+ 85,
+ 0,
+ "FunModels"
+ ],
+ [
+ 49,
+ 75,
+ 0,
+ 85,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 52,
+ 73,
+ 0,
+ 85,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 53,
+ 85,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Load Model",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650705,
+ "offset": [
+ 356.367407042801,
+ 487.2362084107991
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "e054344e39c5030c23b0146ed4a1293bff2505ed",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_1_fun/nodes.py b/VideoX-Fun/comfyui/wan2_1_fun/nodes.py
new file mode 100644
index 0000000000000000000000000000000000000000..7374e3d4b0b6fd4cd3dbc4bfc039f93255aea8b1
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_1_fun/nodes.py
@@ -0,0 +1,867 @@
+"""Modified from https://github.com/kijai/ComfyUI-EasyAnimateWrapper/blob/main/nodes.py
+"""
+import copy
+import gc
+import json
+import os
+
+import comfy.model_management as mm
+import cv2
+import folder_paths
+import numpy as np
+import torch
+from comfy.utils import ProgressBar, load_torch_file
+from diffusers import FlowMatchEulerDiscreteScheduler
+from einops import rearrange
+from omegaconf import OmegaConf
+from PIL import Image
+
+from ...videox_fun.data.bucket_sampler import (ASPECT_RATIO_512,
+ get_closest_ratio)
+from ...videox_fun.models import (AutoencoderKLWan, AutoTokenizer, CLIPModel,
+ WanT5EncoderModel, WanTransformer3DModel)
+from ...videox_fun.pipeline import WanFunInpaintPipeline, WanFunPipeline, WanFunControlPipeline
+from ...videox_fun.ui.controller import all_cheduler_dict
+from ...videox_fun.utils.fp8_optimization import (
+ convert_model_weight_to_float8, convert_weight_dtype_wrapper, replace_parameters_by_name)
+from ...videox_fun.utils.lora_utils import merge_lora, unmerge_lora
+from ...videox_fun.utils.utils import (get_image_to_video_latent, filter_kwargs, get_image_latent,
+ get_video_to_video_latent,
+ save_videos_grid)
+from ...videox_fun.models.cache_utils import get_teacache_coefficients
+from ...videox_fun.data.dataset_image_video import process_pose_params
+from ..comfyui_utils import eas_cache_dir, script_directory, to_pil
+
+# Used in lora cache
+transformer_cpu_cache = {}
+# lora path before
+lora_path_before = ""
+
+class LoadWanFunModel:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "model": (
+ [
+ 'Wan2.1-Fun-1.3B-InP',
+ 'Wan2.1-Fun-14B-InP',
+ 'Wan2.1-Fun-1.3B-Control',
+ 'Wan2.1-Fun-14B-Control',
+ 'Wan2.1-Fun-V1.1-1.3B-InP',
+ 'Wan2.1-Fun-V1.1-14B-InP',
+ 'Wan2.1-Fun-V1.1-1.3B-Control',
+ 'Wan2.1-Fun-V1.1-14B-Control',
+ 'Wan2.1-Fun-V1.1-1.3B-Control-Camera',
+ 'Wan2.1-Fun-V1.1-14B-Control-Camera',
+ ],
+ {
+ "default": 'Wan2.1-Fun-1.3B-InP',
+ }
+ ),
+ "model_type": (
+ ["Inpaint", "Control"],
+ {
+ "default": "Inpaint",
+ }
+ ),
+ "GPU_memory_mode":(
+ ["model_full_load", "model_cpu_offload", "model_cpu_offload_and_qfloat8", "sequential_cpu_offload"],
+ {
+ "default": "model_cpu_offload",
+ }
+ ),
+ "config": (
+ [
+ "wan2.1/wan_civitai.yaml",
+ ],
+ {
+ "default": "wan2.1/wan_civitai.yaml",
+ }
+ ),
+ "precision": (
+ ['fp16', 'bf16'],
+ {
+ "default": 'fp16'
+ }
+ ),
+ },
+ }
+
+ RETURN_TYPES = ("FunModels",)
+ RETURN_NAMES = ("funmodels",)
+ FUNCTION = "loadmodel"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def loadmodel(self, GPU_memory_mode, model_type, model, precision, config):
+ # Init weight_dtype and device
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+ weight_dtype = {"bf16": torch.bfloat16, "fp16": torch.float16, "fp32": torch.float32}[precision]
+
+ # Init processbar
+ pbar = ProgressBar(5)
+
+ # Load config
+ config_path = f"{script_directory}/config/{config}"
+ config = OmegaConf.load(config_path)
+
+ # Detect model is existing or not
+ possible_folders = ["CogVideoX_Fun", "Fun_Models", "VideoX_Fun"] + \
+ [os.path.join(os.path.dirname(os.path.dirname(os.path.dirname(os.path.abspath(__file__)))), "models/Diffusion_Transformer")] # Possible folder names to check
+ # Initialize model_name as None
+ model_name = None
+
+ # Check if the model exists in any of the possible folders within folder_paths.models_dir
+ for folder in possible_folders:
+ candidate_path = os.path.join(folder_paths.models_dir, folder, model)
+ if os.path.exists(candidate_path):
+ model_name = candidate_path
+ break
+
+ # If model_name is still None, check eas_cache_dir for each possible folder
+ if model_name is None and os.path.exists(eas_cache_dir):
+ for folder in possible_folders:
+ candidate_path = os.path.join(eas_cache_dir, folder, model)
+ if os.path.exists(candidate_path):
+ model_name = candidate_path
+ break
+
+ # If model_name is still None, prompt the user to download the model
+ if model_name is None:
+ print(f"Please download cogvideoxfun model to one of the following directories:")
+ for folder in possible_folders:
+ print(f"- {os.path.join(folder_paths.models_dir, folder)}")
+ if os.path.exists(eas_cache_dir):
+ print(f"- {os.path.join(eas_cache_dir, folder)}")
+ raise ValueError("Please download Fun model")
+
+ vae = AutoencoderKLWan.from_pretrained(
+ os.path.join(model_name, config['vae_kwargs'].get('vae_subpath', 'vae')),
+ additional_kwargs=OmegaConf.to_container(config['vae_kwargs']),
+ ).to(weight_dtype)
+ # Update pbar
+ pbar.update(1)
+
+ # Load Sampler
+ print("Load Sampler.")
+ scheduler = FlowMatchEulerDiscreteScheduler(
+ **filter_kwargs(FlowMatchEulerDiscreteScheduler, OmegaConf.to_container(config['scheduler_kwargs']))
+ )
+ # Update pbar
+ pbar.update(1)
+
+ # Get Transformer
+ transformer = WanTransformer3DModel.from_pretrained(
+ os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
+ transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
+ low_cpu_mem_usage=True,
+ torch_dtype=weight_dtype,
+ )
+ # Update pbar
+ pbar.update(1)
+
+ # Get tokenizer and text_encoder
+ tokenizer = AutoTokenizer.from_pretrained(
+ os.path.join(model_name, config['text_encoder_kwargs'].get('tokenizer_subpath', 'tokenizer')),
+ )
+ pbar.update(1)
+
+ text_encoder = WanT5EncoderModel.from_pretrained(
+ os.path.join(model_name, config['text_encoder_kwargs'].get('text_encoder_subpath', 'text_encoder')),
+ additional_kwargs=OmegaConf.to_container(config['text_encoder_kwargs']),
+ low_cpu_mem_usage=True,
+ torch_dtype=weight_dtype,
+ )
+ pbar.update(1)
+
+ if transformer.config.in_channels != vae.config.latent_channels:
+ # Get Clip Image Encoder
+ clip_image_encoder = CLIPModel.from_pretrained(
+ os.path.join(model_name, config['image_encoder_kwargs'].get('image_encoder_subpath', 'image_encoder')),
+ ).to(weight_dtype)
+ clip_image_encoder = clip_image_encoder.eval()
+
+ # Get pipeline
+ if model_type == "Inpaint":
+ if transformer.config.in_channels != vae.config.latent_channels:
+ pipeline = WanFunInpaintPipeline(
+ vae=vae,
+ tokenizer=tokenizer,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ scheduler=scheduler,
+ clip_image_encoder=clip_image_encoder
+ )
+ else:
+ pipeline = WanFunPipeline(
+ vae=vae,
+ tokenizer=tokenizer,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ scheduler=scheduler,
+ )
+ else:
+ pipeline = WanFunControlPipeline(
+ vae=vae,
+ tokenizer=tokenizer,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ scheduler=scheduler,
+ clip_image_encoder=clip_image_encoder
+ )
+
+ if GPU_memory_mode == "sequential_cpu_offload":
+ replace_parameters_by_name(transformer, ["modulation",], device="cuda")
+ transformer.freqs = transformer.freqs.to(device="cuda")
+ pipeline.enable_sequential_cpu_offload()
+ elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
+ convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",])
+ convert_weight_dtype_wrapper(transformer, weight_dtype)
+ pipeline.enable_model_cpu_offload()
+ elif GPU_memory_mode == "model_cpu_offload":
+ pipeline.enable_model_cpu_offload()
+ elif GPU_memory_mode == "model_full_load_and_qfloat8":
+ convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",])
+ convert_weight_dtype_wrapper(transformer, weight_dtype)
+ pipeline.to(device=device)
+ else:
+ pipeline.to("cuda")
+
+ funmodels = {
+ 'pipeline': pipeline,
+ 'dtype': weight_dtype,
+ 'model_name': model_name,
+ 'model_type': model_type,
+ 'loras': [],
+ 'strength_model': [],
+ 'config': config,
+ }
+ return (funmodels,)
+
+class LoadWanFunLora:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "funmodels": ("FunModels",),
+ "lora_name": (folder_paths.get_filename_list("loras"), {"default": None,}),
+ "strength_model": ("FLOAT", {"default": 1.0, "min": -100.0, "max": 100.0, "step": 0.01}),
+ "lora_cache":([False, True], {"default": False,}),
+ }
+ }
+ RETURN_TYPES = ("FunModels",)
+ RETURN_NAMES = ("funmodels",)
+ FUNCTION = "load_lora"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def load_lora(self, funmodels, lora_name, strength_model, lora_cache):
+ if lora_name is not None:
+ funmodels['lora_cache'] = lora_cache
+ funmodels['loras'] = funmodels.get("loras", []) + [folder_paths.get_full_path("loras", lora_name)]
+ funmodels['strength_model'] = funmodels.get("strength_model", []) + [strength_model]
+ return (funmodels,)
+ else:
+ return (funmodels,)
+
+class WanFunT2VSampler:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "funmodels": (
+ "FunModels",
+ ),
+ "prompt": (
+ "STRING_PROMPT",
+ ),
+ "negative_prompt": (
+ "STRING_PROMPT",
+ ),
+ "video_length": (
+ "INT", {"default": 81, "min": 5, "max": 161, "step": 4}
+ ),
+ "width": (
+ "INT", {"default": 832, "min": 64, "max": 2048, "step": 16}
+ ),
+ "height": (
+ "INT", {"default": 480, "min": 64, "max": 2048, "step": 16}
+ ),
+ "is_image":(
+ [
+ False,
+ True
+ ],
+ {
+ "default": False,
+ }
+ ),
+ "seed": (
+ "INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
+ ),
+ "steps": (
+ "INT", {"default": 50, "min": 1, "max": 200, "step": 1}
+ ),
+ "cfg": (
+ "FLOAT", {"default": 6.0, "min": 1.0, "max": 20.0, "step": 0.01}
+ ),
+ "scheduler": (
+ [
+ "Flow",
+ ],
+ {
+ "default": 'Flow'
+ }
+ ),
+ "teacache_threshold": (
+ "FLOAT", {"default": 0.10, "min": 0.00, "max": 1.00, "step": 0.005}
+ ),
+ "enable_teacache":(
+ [False, True], {"default": True,}
+ ),
+ "num_skip_start_steps": (
+ "INT", {"default": 5, "min": 0, "max": 50, "step": 1}
+ ),
+ "teacache_offload":(
+ [False, True], {"default": True,}
+ ),
+ "cfg_skip_ratio":(
+ "FLOAT", {"default": 0, "min": 0, "max": 1, "step": 0.01}
+ ),
+ },
+ "optional": {
+ "riflex_k": ("RIFLEXT_ARGS",),
+ },
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES =("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, funmodels, prompt, negative_prompt, video_length, width, height, is_image, seed, steps, cfg, scheduler, teacache_threshold, enable_teacache, num_skip_start_steps, teacache_offload, cfg_skip_ratio, riflex_k=0):
+ global transformer_cpu_cache
+ global lora_path_before
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+
+ mm.soft_empty_cache()
+ gc.collect()
+
+ # Get Pipeline
+ pipeline = funmodels['pipeline']
+ model_name = funmodels['model_name']
+ config = funmodels['config']
+ weight_dtype = funmodels['dtype']
+
+ # Load Sampler
+ pipeline.scheduler = all_cheduler_dict[scheduler](**filter_kwargs(all_cheduler_dict[scheduler], OmegaConf.to_container(config['scheduler_kwargs'])))
+
+ coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
+ if coefficients is not None:
+ print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
+ pipeline.transformer.enable_teacache(
+ coefficients, steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
+ )
+ else:
+ pipeline.transformer.disable_teacache()
+
+ if cfg_skip_ratio is not None:
+ print(f"Enable cfg_skip_ratio {cfg_skip_ratio}.")
+ pipeline.transformer.enable_cfg_skip(cfg_skip_ratio, steps)
+
+ generator= torch.Generator(device).manual_seed(seed)
+
+ video_length = 1 if is_image else video_length
+ with torch.no_grad():
+ video_length = int((video_length - 1) // pipeline.vae.config.temporal_compression_ratio * pipeline.vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+
+ if riflex_k > 0:
+ latent_frames = (video_length - 1) // pipeline.vae.config.temporal_compression_ratio + 1
+ pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
+
+ # Apply lora
+ if funmodels.get("lora_cache", False):
+ if len(funmodels.get("loras", [])) != 0:
+ # Save the original weights to cpu
+ if len(transformer_cpu_cache) == 0:
+ print('Save transformer state_dict to cpu memory')
+ transformer_state_dict = pipeline.transformer.state_dict()
+ for key in transformer_state_dict:
+ transformer_cpu_cache[key] = transformer_state_dict[key].clone().cpu()
+
+ lora_path_now = str(funmodels.get("loras", []) + funmodels.get("strength_model", []))
+ if lora_path_now != lora_path_before:
+ print('Merge Lora with Cache')
+ lora_path_before = copy.deepcopy(lora_path_now)
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ else:
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if len(transformer_cpu_cache) != 0:
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ transformer_cpu_cache = {}
+ lora_path_before = ""
+ gc.collect()
+ print('Merge Lora')
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ if pipeline.transformer.config.in_channels != pipeline.vae.config.latent_channels:
+ input_video, input_video_mask, _ = get_image_to_video_latent(None, None, video_length=video_length, sample_size=(height, width))
+
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ comfyui_progressbar = True,
+ ).videos
+ else:
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+ comfyui_progressbar = True,
+ ).videos
+ videos = rearrange(sample, "b c t h w -> (b t) h w c")
+
+ if not funmodels.get("lora_cache", False):
+ print('Unmerge Lora')
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ return (videos,)
+
+
+class WanFunInpaintSampler:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "funmodels": (
+ "FunModels",
+ ),
+ "prompt": (
+ "STRING_PROMPT",
+ ),
+ "negative_prompt": (
+ "STRING_PROMPT",
+ ),
+ "video_length": (
+ "INT", {"default": 81, "min": 5, "max": 161, "step": 4}
+ ),
+ "base_resolution": (
+ [
+ 512,
+ 640,
+ 768,
+ 896,
+ 960,
+ 1024,
+ ], {"default": 640}
+ ),
+ "seed": (
+ "INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
+ ),
+ "steps": (
+ "INT", {"default": 50, "min": 1, "max": 200, "step": 1}
+ ),
+ "cfg": (
+ "FLOAT", {"default": 6.0, "min": 1.0, "max": 20.0, "step": 0.01}
+ ),
+ "scheduler": (
+ [
+ "Flow",
+ ],
+ {
+ "default": 'Flow'
+ }
+ ),
+ "teacache_threshold": (
+ "FLOAT", {"default": 0.10, "min": 0.00, "max": 1.00, "step": 0.005}
+ ),
+ "enable_teacache":(
+ [False, True], {"default": True,}
+ ),
+ "num_skip_start_steps": (
+ "INT", {"default": 5, "min": 0, "max": 50, "step": 1}
+ ),
+ "teacache_offload":(
+ [False, True], {"default": True,}
+ ),
+ "cfg_skip_ratio":(
+ "FLOAT", {"default": 0, "min": 0, "max": 1, "step": 0.01}
+ ),
+ },
+ "optional": {
+ "start_img": ("IMAGE",),
+ "end_img": ("IMAGE",),
+ "riflex_k": ("RIFLEXT_ARGS",),
+ },
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES =("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, funmodels, prompt, negative_prompt, video_length, base_resolution, seed, steps, cfg, scheduler, teacache_threshold, enable_teacache, num_skip_start_steps, teacache_offload, cfg_skip_ratio, start_img=None, end_img=None, riflex_k=0):
+ global transformer_cpu_cache
+ global lora_path_before
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+
+ mm.soft_empty_cache()
+ gc.collect()
+
+ start_img = [to_pil(_start_img) for _start_img in start_img] if start_img is not None else None
+ end_img = [to_pil(_end_img) for _end_img in end_img] if end_img is not None else None
+ # Count most suitable height and width
+ aspect_ratio_sample_size = {key : [x / 512 * base_resolution for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+ original_width, original_height = start_img[0].size if type(start_img) is list else Image.open(start_img).size
+ closest_size, closest_ratio = get_closest_ratio(original_height, original_width, ratios=aspect_ratio_sample_size)
+ height, width = [int(x / 16) * 16 for x in closest_size]
+
+ # Get Pipeline
+ pipeline = funmodels['pipeline']
+ model_name = funmodels['model_name']
+ config = funmodels['config']
+ weight_dtype = funmodels['dtype']
+
+ # Load Sampler
+ pipeline.scheduler = all_cheduler_dict[scheduler](**filter_kwargs(all_cheduler_dict[scheduler], OmegaConf.to_container(config['scheduler_kwargs'])))
+ coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
+ if coefficients is not None:
+ print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
+ pipeline.transformer.enable_teacache(
+ coefficients, steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
+ )
+ else:
+ pipeline.transformer.disable_teacache()
+
+ if cfg_skip_ratio is not None:
+ print(f"Enable cfg_skip_ratio {cfg_skip_ratio}.")
+ pipeline.transformer.enable_cfg_skip(cfg_skip_ratio, steps)
+
+ generator= torch.Generator(device).manual_seed(seed)
+
+ with torch.no_grad():
+ video_length = int((video_length - 1) // pipeline.vae.config.temporal_compression_ratio * pipeline.vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+
+ if riflex_k > 0:
+ latent_frames = (video_length - 1) // pipeline.vae.config.temporal_compression_ratio + 1
+ pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
+
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(start_img, end_img, video_length=video_length, sample_size=(height, width))
+
+ # Apply lora
+ if funmodels.get("lora_cache", False):
+ if len(funmodels.get("loras", [])) != 0:
+ # Save the original weights to cpu
+ if len(transformer_cpu_cache) == 0:
+ print('Save transformer state_dict to cpu memory')
+ transformer_state_dict = pipeline.transformer.state_dict()
+ for key in transformer_state_dict:
+ transformer_cpu_cache[key] = transformer_state_dict[key].clone().cpu()
+
+ lora_path_now = str(funmodels.get("loras", []) + funmodels.get("strength_model", []))
+ if lora_path_now != lora_path_before:
+ print('Merge Lora with Cache')
+ lora_path_before = copy.deepcopy(lora_path_now)
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ else:
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if len(transformer_cpu_cache) != 0:
+ print('Delete cpu state_dict')
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ transformer_cpu_cache = {}
+ lora_path_before = ""
+ gc.collect()
+ print('Merge Lora')
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ clip_image = clip_image,
+ comfyui_progressbar = True,
+ ).videos
+ videos = rearrange(sample, "b c t h w -> (b t) h w c")
+
+ if not funmodels.get("lora_cache", False):
+ print('Unmerge Lora')
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ return (videos,)
+
+
+class WanFunV2VSampler:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "funmodels": (
+ "FunModels",
+ ),
+ "prompt": (
+ "STRING_PROMPT",
+ ),
+ "negative_prompt": (
+ "STRING_PROMPT",
+ ),
+ "video_length": (
+ "INT", {"default": 81, "min": 1, "max": 161, "step": 4}
+ ),
+ "base_resolution": (
+ [
+ 512,
+ 640,
+ 768,
+ 896,
+ 960,
+ 1024,
+ ], {"default": 640}
+ ),
+ "seed": (
+ "INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
+ ),
+ "steps": (
+ "INT", {"default": 25, "min": 1, "max": 200, "step": 1}
+ ),
+ "cfg": (
+ "FLOAT", {"default": 7.0, "min": 1.0, "max": 20.0, "step": 0.01}
+ ),
+ "denoise_strength": (
+ "FLOAT", {"default": 0.70, "min": 0.05, "max": 1.00, "step": 0.01}
+ ),
+ "scheduler": (
+ [
+ "Flow",
+ ],
+ {
+ "default": 'Flow'
+ }
+ ),
+ "teacache_threshold": (
+ "FLOAT", {"default": 0.10, "min": 0.00, "max": 1.00, "step": 0.005}
+ ),
+ "enable_teacache":(
+ [False, True], {"default": True,}
+ ),
+ "num_skip_start_steps": (
+ "INT", {"default": 5, "min": 0, "max": 50, "step": 1}
+ ),
+ "teacache_offload":(
+ [False, True], {"default": True,}
+ ),
+ "cfg_skip_ratio":(
+ "FLOAT", {"default": 0, "min": 0, "max": 1, "step": 0.01}
+ ),
+ },
+ "optional": {
+ "validation_video": ("IMAGE",),
+ "control_video": ("IMAGE",),
+ "start_image": ("IMAGE",),
+ "ref_image": ("IMAGE",),
+ "camera_conditions": ("STRING", {"forceInput": True}),
+ "riflex_k": ("RIFLEXT_ARGS",),
+ },
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES =("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, funmodels, prompt, negative_prompt, video_length, base_resolution, seed, steps, cfg, denoise_strength, scheduler, teacache_threshold, enable_teacache, num_skip_start_steps, teacache_offload, cfg_skip_ratio, validation_video=None, control_video=None, start_image=None, ref_image=None, camera_conditions=None, riflex_k=0):
+ global transformer_cpu_cache
+ global lora_path_before
+
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+
+ mm.soft_empty_cache()
+ gc.collect()
+
+ # Get Pipeline
+ pipeline = funmodels['pipeline']
+ model_name = funmodels['model_name']
+ config = funmodels['config']
+ weight_dtype = funmodels['dtype']
+ model_type = funmodels['model_type']
+
+ # Count most suitable height and width
+ aspect_ratio_sample_size = {key : [x / 512 * base_resolution for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+ if model_type == "Inpaint":
+ if type(validation_video) is str:
+ original_width, original_height = Image.fromarray(cv2.VideoCapture(validation_video).read()[1]).size
+ else:
+ validation_video = np.array(validation_video.cpu().numpy() * 255, np.uint8)
+ original_width, original_height = Image.fromarray(validation_video[0]).size
+ else:
+ if control_video is not None and type(control_video) is str:
+ original_width, original_height = Image.fromarray(cv2.VideoCapture(control_video).read()[1]).size
+ elif control_video is not None:
+ control_video = np.array(control_video.cpu().numpy() * 255, np.uint8)
+ original_width, original_height = Image.fromarray(control_video[0]).size
+ else:
+ original_width, original_height = 384 / 512 * base_resolution, 672 / 512 * base_resolution
+
+ if ref_image is not None:
+ ref_image = [to_pil(_ref_image) for _ref_image in ref_image]
+ original_width, original_height = ref_image[0].size if type(ref_image) is list else Image.open(ref_image).size
+
+ if start_image is not None:
+ start_image = [to_pil(_start_image) for _start_image in start_image]
+ original_width, original_height = start_image[0].size if type(start_image) is list else Image.open(start_image).size
+
+ closest_size, closest_ratio = get_closest_ratio(original_height, original_width, ratios=aspect_ratio_sample_size)
+ height, width = [int(x / 16) * 16 for x in closest_size]
+
+ # Load Sampler
+ pipeline.scheduler = all_cheduler_dict[scheduler](**filter_kwargs(all_cheduler_dict[scheduler], OmegaConf.to_container(config['scheduler_kwargs'])))
+ coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
+ if coefficients is not None:
+ print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
+ pipeline.transformer.enable_teacache(
+ coefficients, steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
+ )
+ else:
+ pipeline.transformer.disable_teacache()
+
+ if cfg_skip_ratio is not None:
+ print(f"Enable cfg_skip_ratio {cfg_skip_ratio}.")
+ pipeline.transformer.enable_cfg_skip(cfg_skip_ratio, steps)
+
+ generator= torch.Generator(device).manual_seed(seed)
+
+ with torch.no_grad():
+ video_length = int((video_length - 1) // pipeline.vae.config.temporal_compression_ratio * pipeline.vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+
+ if riflex_k > 0:
+ latent_frames = (video_length - 1) // pipeline.vae.config.temporal_compression_ratio + 1
+ pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
+
+ if model_type == "Inpaint":
+ input_video, input_video_mask, ref_image, clip_image = get_video_to_video_latent(validation_video, video_length=video_length, sample_size=(height, width), fps=16, ref_image=ref_image[0] if ref_image is not None else ref_image)
+ else:
+ if ref_image is not None:
+ clip_image = ref_image[0].convert("RGB")
+ elif start_image is not None:
+ clip_image = start_image[0].convert("RGB")
+ else:
+ clip_image = None
+
+ if ref_image is not None:
+ ref_image = get_image_latent(ref_image[0] if ref_image is not None else ref_image, sample_size=(height, width))
+
+ if start_image is not None:
+ start_image = get_image_latent(start_image[0] if start_image is not None else start_image, sample_size=(height, width))
+
+ if camera_conditions is not None and len(camera_conditions) > 0:
+ poses = json.loads(camera_conditions)
+ cam_params = np.array([[float(x) for x in pose] for pose in poses])
+ cam_params = np.concatenate([np.zeros_like(cam_params[:, :1]), cam_params], 1)
+ control_camera_video = process_pose_params(cam_params, width=width, height=height)
+ control_camera_video = control_camera_video[:video_length].permute([3, 0, 1, 2]).unsqueeze(0)
+ input_video, input_video_mask = None, None
+ else:
+ control_camera_video = None
+ input_video, input_video_mask, _, _ = get_video_to_video_latent(control_video, video_length=video_length, sample_size=(height, width), fps=16, ref_image=None)
+
+ # Apply lora
+ if funmodels.get("lora_cache", False):
+ if len(funmodels.get("loras", [])) != 0:
+ # Save the original weights to cpu
+ if len(transformer_cpu_cache) == 0:
+ print('Save transformer state_dict to cpu memory')
+ transformer_state_dict = pipeline.transformer.state_dict()
+ for key in transformer_state_dict:
+ transformer_cpu_cache[key] = transformer_state_dict[key].clone().cpu()
+
+ lora_path_now = str(funmodels.get("loras", []) + funmodels.get("strength_model", []))
+ if lora_path_now != lora_path_before:
+ print('Merge Lora with Cache')
+ lora_path_before = copy.deepcopy(lora_path_now)
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ else:
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if len(transformer_cpu_cache) != 0:
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ transformer_cpu_cache = {}
+ lora_path_before = ""
+ gc.collect()
+ print('Merge Lora')
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ if model_type == "Inpaint":
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ clip_image = clip_image,
+ strength = float(denoise_strength),
+ comfyui_progressbar = True,
+ ).videos
+ else:
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ ref_image = ref_image,
+ start_image = start_image,
+ clip_image = clip_image,
+ control_video = input_video,
+ control_camera_video = control_camera_video,
+ comfyui_progressbar = True,
+ ).videos
+ videos = rearrange(sample, "b c t h w -> (b t) h w c")
+
+ if not funmodels.get("lora_cache", False):
+ print('Unmerge Lora')
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ return (videos,)
+
diff --git a/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_control_camera.json b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_control_camera.json
new file mode 100644
index 0000000000000000000000000000000000000000..50ae04161d721367c69dfbccd1861cc17b535da1
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_control_camera.json
@@ -0,0 +1,665 @@
+{
+ "id": "addf6f13-291c-4b88-a80c-cd5785fa8f42",
+ "revision": 0,
+ "last_node_id": 132,
+ "last_link_id": 292,
+ "nodes": [
+ {
+ "id": 107,
+ "type": "Note",
+ "pos": [
+ 4,
+ 634
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 108,
+ "type": "Note",
+ "pos": [
+ -110,
+ 842
+ ],
+ "size": [
+ 326.1556091308594,
+ 145.20904541015625
+ ],
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 122,
+ "type": "FunTextBox",
+ "pos": [
+ 238,
+ 805
+ ],
+ "size": [
+ 400,
+ 200
+ ],
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 289
+ ]
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 129,
+ "type": "CameraBasicFromChaoJie",
+ "pos": [
+ 805.2059326171875,
+ 1012.381103515625
+ ],
+ "size": [
+ 315,
+ 106
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "CameraPose",
+ "type": "CameraPose",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CameraBasicFromChaoJie"
+ },
+ "widgets_values": [
+ "Static",
+ 1,
+ 16
+ ]
+ },
+ {
+ "id": 130,
+ "type": "CameraTrajectoryFromChaoJie",
+ "pos": [
+ 1170.206298828125,
+ 763.3814697265625
+ ],
+ "size": [
+ 367.79998779296875,
+ 150
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "camera_pose",
+ "type": "CameraPose",
+ "link": 285
+ }
+ ],
+ "outputs": [
+ {
+ "name": "camera_trajectory",
+ "type": "STRING",
+ "slot_index": 0,
+ "links": [
+ 292
+ ]
+ },
+ {
+ "name": "video_length",
+ "type": "INT",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CameraTrajectoryFromChaoJie"
+ },
+ "widgets_values": [
+ 0.532139961,
+ 0.946026558,
+ 0.5,
+ 0.5
+ ]
+ },
+ {
+ "id": 106,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1408,
+ 68
+ ],
+ "size": [
+ 390,
+ 537.4615478515625
+ ],
+ "flags": {},
+ "order": 12,
+ "mode": 0,
+ "inputs": [
+ {
+ "label": "图像",
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 291
+ },
+ {
+ "label": "音频",
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "label": "批次管理",
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "label": "文件名",
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "slot_index": 0,
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00061.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 121,
+ "type": "FunTextBox",
+ "pos": [
+ 235,
+ 539
+ ],
+ "size": [
+ 400,
+ 200
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 288
+ ]
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "Fireworks light up the evening sky over a sprawling cityscape with gothic-style buildings featuring pointed towers and clock faces. The city is lit by both artificial lights from the buildings and the colorful bursts of the fireworks. The scene is viewed from an elevated angle, showcasing a vibrant urban environment set against a backdrop of a dramatic, partially cloudy sky at dusk."
+ ]
+ },
+ {
+ "id": 100,
+ "type": "LoadImage",
+ "pos": [
+ 237.59738159179688,
+ 1164.597412109375
+ ],
+ "size": [
+ 378.07147216796875,
+ 314
+ ],
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "label": "图像",
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "slot_index": 0,
+ "links": [
+ 290
+ ]
+ },
+ {
+ "label": "遮罩",
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "title": "Start Image(图片到视频的开始图片)",
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "5.png",
+ "image"
+ ]
+ },
+ {
+ "id": 131,
+ "type": "CameraCombineFromChaoJie",
+ "pos": [
+ 814.2059326171875,
+ 763.3814697265625
+ ],
+ "size": [
+ 315,
+ 178
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "CameraPose",
+ "type": "CameraPose",
+ "links": [
+ 285
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CameraCombineFromChaoJie"
+ },
+ "widgets_values": [
+ "Pan Right",
+ "Pan Up",
+ "Static",
+ "Static",
+ 1,
+ 81
+ ]
+ },
+ {
+ "id": 110,
+ "type": "Note",
+ "pos": [
+ 1158.206298828125,
+ 970.381103515625
+ ],
+ "size": [
+ 608.1410522460938,
+ 188.2682342529297
+ ],
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "CameraCombine is used to combine multiple camera movements, while CameraBasic produces a single camera movement. The nodes come from https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper/. Since ComfyUI-CameraCtrl-Wrapper requires a specific version of diffusers, the code has been copied into the current repository.\n(CameraCombine用于组合多个镜头运动,CameraBasic产出单个镜头运动;节点来自于https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper/,由于ComfyUI-CameraCtrl-Wrapper有具体diffusers版本要求,故复制代码到当前库中。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 132,
+ "type": "WanFunV2VSampler",
+ "pos": [
+ 899,
+ 68
+ ],
+ "size": [
+ 428.4000244140625,
+ 506
+ ],
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 287
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 288
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 289
+ },
+ {
+ "name": "validation_video",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "control_video",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "start_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 290
+ },
+ {
+ "name": "ref_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "camera_conditions",
+ "shape": 7,
+ "type": "STRING",
+ "link": 292
+ },
+ {
+ "name": "riflex_k",
+ "shape": 7,
+ "type": "RIFLEXT_ARGS",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 291
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ },
+ {
+ "id": 123,
+ "type": "LoadWanFunModel",
+ "pos": [
+ 281,
+ 251
+ ],
+ "size": [
+ 315,
+ 154
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "slot_index": 0,
+ "links": [
+ 287
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-V1.1-1.3B-Control-Camera",
+ "Control",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 112,
+ "type": "Note",
+ "pos": [
+ -203,
+ 252
+ ],
+ "size": [
+ 427.074951171875,
+ 143.9142608642578
+ ],
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ }
+ ],
+ "links": [
+ [
+ 285,
+ 131,
+ 0,
+ 130,
+ 0,
+ "CameraPose"
+ ],
+ [
+ 287,
+ 123,
+ 0,
+ 132,
+ 0,
+ "FunModels"
+ ],
+ [
+ 288,
+ 121,
+ 0,
+ 132,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 289,
+ 122,
+ 0,
+ 132,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 290,
+ 100,
+ 0,
+ 132,
+ 5,
+ "IMAGE"
+ ],
+ [
+ 291,
+ 132,
+ 0,
+ 106,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 292,
+ 130,
+ 0,
+ 132,
+ 7,
+ "STRING"
+ ]
+ ],
+ "groups": [
+ {
+ "id": 1,
+ "title": "Generate Control Video",
+ "bounding": [
+ 773,
+ 666,
+ 1025,
+ 531
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 2,
+ "title": "First Image",
+ "bounding": [
+ 191,
+ 1068,
+ 475,
+ 456
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 3,
+ "title": "Prompts",
+ "bounding": [
+ 191,
+ 456,
+ 475,
+ 587
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 4,
+ "title": "Load Model",
+ "bounding": [
+ 189,
+ 160,
+ 475,
+ 269
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650709,
+ "offset": [
+ 236.8040025924094,
+ -27.611371387475245
+ ]
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "e935795d7684aaba72be65d2ad5ef580c0526f7a",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "comfy-core": "0.3.44"
+ },
+ "frontendVersion": "1.21.3"
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_control_trajectory.json b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_control_trajectory.json
new file mode 100644
index 0000000000000000000000000000000000000000..d6e14b974e2f5ce6d07084d6a66f63a3ec895edc
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_control_trajectory.json
@@ -0,0 +1,1040 @@
+{
+ "id": "34fdaa39-a397-46b5-84d1-8846799c8c09",
+ "revision": 0,
+ "last_node_id": 126,
+ "last_link_id": 287,
+ "nodes": [
+ {
+ "id": 107,
+ "type": "Note",
+ "pos": [
+ 4,
+ 634
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 108,
+ "type": "Note",
+ "pos": [
+ -110,
+ 842
+ ],
+ "size": [
+ 326.1556091308594,
+ 145.20904541015625
+ ],
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 100,
+ "type": "LoadImage",
+ "pos": [
+ 238,
+ 1165
+ ],
+ "size": [
+ 378.07147216796875,
+ 314
+ ],
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "label": "图像",
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "slot_index": 0,
+ "links": [
+ 285
+ ]
+ },
+ {
+ "label": "遮罩",
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "title": "Start Image(图片到视频的开始图片)",
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "1.png",
+ "image"
+ ]
+ },
+ {
+ "id": 110,
+ "type": "Note",
+ "pos": [
+ 847,
+ 613
+ ],
+ "size": [
+ 608.1410522460938,
+ 188.2682342529297
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Please set the mask height and mask width according to the height and width of the reference image. \nPlease set the video_length of the Spline Editor below to be the same as the video_length of the Sampler above. \nThe nodes are from KJNodes. For more details, please check https://github.com/kijai/ComfyUI-KJNodes/tree/main. \n\n请根据参考图片的高和宽设置mask height和mask width;\n请将下方Spline Editor的video_legnth置的与上方Sampler的video_legnth一样;\n部分节点来自于KJNodes,具体查看https://github.com/kijai/ComfyUI-KJNodes/tree/main;"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 118,
+ "type": "AppendStringsToList",
+ "pos": [
+ 1140.1396484375,
+ 909.9193115234375
+ ],
+ "size": [
+ 315,
+ 82
+ ],
+ "flags": {
+ "collapsed": false
+ },
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "string1",
+ "type": "STRING",
+ "link": 265
+ },
+ {
+ "name": "string2",
+ "type": "STRING",
+ "link": 266
+ }
+ ],
+ "outputs": [
+ {
+ "name": "STRING",
+ "type": "STRING",
+ "slot_index": 0,
+ "links": [
+ 267
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "AppendStringsToList"
+ },
+ "widgets_values": []
+ },
+ {
+ "id": 121,
+ "type": "FunTextBox",
+ "pos": [
+ 235,
+ 539
+ ],
+ "size": [
+ 400,
+ 200
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 282
+ ]
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "一只棕褐色的狗正摇晃着脑袋,坐在一个舒适的房间里的浅色沙发上。沙发看起来柔软而宽敞,为这只活泼的狗狗提供了一个完美的休息地点。在狗的后面,靠墙摆放着一个架子,架子上挂着一幅精美的镶框画,画中描绘着一些美丽的风景或场景。画框周围装饰着粉红色的花朵,这些花朵不仅增添了房间的色彩,还带来了一丝自然和生机。房间里的灯光柔和而温暖,从天花板上的吊灯和角落里的台灯散发出来,营造出一种温馨舒适的氛围。整个空间给人一种宁静和谐的感觉,仿佛时间在这里变得缓慢而美好。"
+ ]
+ },
+ {
+ "id": 114,
+ "type": "ImageMaximumNode",
+ "pos": [
+ 2074,
+ 905
+ ],
+ "size": [
+ 210,
+ 46
+ ],
+ "flags": {},
+ "order": 15,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "video_1",
+ "type": "IMAGE",
+ "link": 287
+ },
+ {
+ "name": "video_2",
+ "type": "IMAGE",
+ "link": 262
+ }
+ ],
+ "outputs": [
+ {
+ "name": "image",
+ "type": "IMAGE",
+ "links": [
+ 264
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "ImageMaximumNode"
+ },
+ "widgets_values": []
+ },
+ {
+ "id": 95,
+ "type": "CreateTrajectoryBasedOnKJNodes",
+ "pos": [
+ 1574.139404296875,
+ 929.9193115234375
+ ],
+ "size": [
+ 428.4000244140625,
+ 58
+ ],
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "coordinates",
+ "type": "STRING",
+ "link": 267
+ },
+ {
+ "name": "masks",
+ "type": "MASK",
+ "link": 249
+ }
+ ],
+ "outputs": [
+ {
+ "name": "image",
+ "type": "IMAGE",
+ "slot_index": 0,
+ "links": [
+ 237,
+ 262,
+ 284
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CreateTrajectoryBasedOnKJNodes"
+ },
+ "widgets_values": []
+ },
+ {
+ "id": 122,
+ "type": "FunTextBox",
+ "pos": [
+ 238,
+ 805
+ ],
+ "size": [
+ 400,
+ 200
+ ],
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 283
+ ]
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 97,
+ "type": "SplineEditor",
+ "pos": [
+ 855.1397705078125,
+ 1058.91943359375
+ ],
+ "size": [
+ 645,
+ 832
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "bg_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "mask",
+ "type": "MASK",
+ "slot_index": 0,
+ "links": [
+ 249
+ ]
+ },
+ {
+ "name": "coord_str",
+ "type": "STRING",
+ "slot_index": 1,
+ "links": [
+ 265
+ ]
+ },
+ {
+ "name": "float",
+ "type": "FLOAT",
+ "links": null
+ },
+ {
+ "name": "count",
+ "type": "INT",
+ "links": null
+ },
+ {
+ "name": "normalized_str",
+ "type": "STRING",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "SplineEditor",
+ "points": "SplineEditor",
+ "imgData": null
+ },
+ "widgets_values": [
+ "[{\"points\":[{\"x\":236.74497000000005,\"y\":169.10355000000004},{\"x\":263.53799999999995,\"y\":230.59575},{\"x\":321.61075881587004,\"y\":229.72197058276433},{\"x\":355.3934015486295,\"y\":168.9132136637973},{\"x\":343.23165016483614,\"y\":82.42964826793309},{\"x\":275.6663646993172,\"y\":55.40353408172552},{\"x\":197.29063355931524,\"y\":85.13225968655384},{\"x\":177.02104791965957,\"y\":148.64362802414163},{\"x\":205.39846781517753,\"y\":232.4245820013851},{\"x\":259.45069618759265,\"y\":167.56190795448694}],\"color\":\"#1f77b4\",\"name\":\"Spline 1\"}]",
+ "[[{\"x\":236.74496459960938,\"y\":169.10354614257812},{\"x\":238.94464111328125,\"y\":177.68576049804688},{\"x\":241.3327178955078,\"y\":186.21737670898438},{\"x\":243.95693969726562,\"y\":194.67919921875},{\"x\":246.88812255859375,\"y\":203.03933715820312},{\"x\":250.2393035888672,\"y\":211.23939514160156},{\"x\":254.20826721191406,\"y\":219.15655517578125},{\"x\":259.18768310546875,\"y\":226.46995544433594},{\"x\":265.87689208984375,\"y\":232.22171020507812},{\"x\":273.4639892578125,\"y\":236.787353515625},{\"x\":281.6380920410156,\"y\":240.17092895507812},{\"x\":290.3527526855469,\"y\":241.61793518066406},{\"x\":299.1367492675781,\"y\":240.67857360839844},{\"x\":307.49658203125,\"y\":237.7835235595703},{\"x\":315.3465576171875,\"y\":233.68600463867188},{\"x\":322.80859375,\"y\":228.9126739501953},{\"x\":330.00958251953125,\"y\":223.75323486328125},{\"x\":336.7490234375,\"y\":218.0097198486328},{\"x\":342.5494689941406,\"y\":211.32901000976562},{\"x\":346.96185302734375,\"y\":203.6618194580078},{\"x\":350.05450439453125,\"y\":195.3665771484375},{\"x\":352.2560729980469,\"y\":186.787109375},{\"x\":353.9389343261719,\"y\":178.08937072753906},{\"x\":355.33001708984375,\"y\":169.3397216796875},{\"x\":356.59344482421875,\"y\":160.57052612304688},{\"x\":357.7420959472656,\"y\":151.78565979003906},{\"x\":358.6518249511719,\"y\":142.9732208251953},{\"x\":359.1504211425781,\"y\":134.1287384033203},{\"x\":359.0207214355469,\"y\":125.2725601196289},{\"x\":358.035400390625,\"y\":116.4721908569336},{\"x\":356.0333251953125,\"y\":107.84730529785156},{\"x\":352.9960632324219,\"y\":99.53003692626953},{\"x\":349.046142578125,\"y\":91.60392761230469},{\"x\":344.37164306640625,\"y\":84.08070373535156},{\"x\":339.17694091796875,\"y\":76.9051742553711},{\"x\":333.4718322753906,\"y\":70.13098907470703},{\"x\":326.9710693359375,\"y\":64.12535858154297},{\"x\":319.4295654296875,\"y\":59.51286315917969},{\"x\":311.02655029296875,\"y\":56.7620735168457},{\"x\":302.25640869140625,\"y\":55.55453872680664},{\"x\":293.40484619140625,\"y\":55.21137619018555},{\"x\":284.5453796386719,\"y\":55.24800491333008},{\"x\":275.68701171875,\"y\":55.40314865112305},{\"x\":266.83221435546875,\"y\":55.690216064453125},{\"x\":257.9945373535156,\"y\":56.30451965332031},{\"x\":249.2041473388672,\"y\":57.398460388183594},{\"x\":240.5244140625,\"y\":59.16102981567383},{\"x\":232.06307983398438,\"y\":61.773162841796875},{\"x\":223.95306396484375,\"y\":65.32772827148438},{\"x\":216.29017639160156,\"y\":69.7664566040039},{\"x\":209.08375549316406,\"y\":74.91584777832031},{\"x\":202.27122497558594,\"y\":80.57798767089844},{\"x\":195.76087951660156,\"y\":86.58625030517578},{\"x\":189.468505859375,\"y\":92.8224105834961},{\"x\":183.6200714111328,\"y\":99.47235107421875},{\"x\":178.9163055419922,\"y\":106.95783233642578},{\"x\":176.3991241455078,\"y\":115.42044830322266},{\"x\":175.83934020996094,\"y\":124.25370788574219},{\"x\":176.12339782714844,\"y\":133.10797119140625},{\"x\":176.63381958007812,\"y\":141.95301818847656},{\"x\":177.14378356933594,\"y\":150.79808044433594},{\"x\":177.73876953125,\"y\":159.63778686523438},{\"x\":178.5083770751953,\"y\":168.46385192871094},{\"x\":179.4958038330078,\"y\":177.26815795898438},{\"x\":180.75762939453125,\"y\":186.03709411621094},{\"x\":182.37294006347656,\"y\":194.7476043701172},{\"x\":184.4583282470703,\"y\":203.35687255859375},{\"x\":187.1986083984375,\"y\":211.7789306640625},{\"x\":190.9047393798828,\"y\":219.81732177734375},{\"x\":196.108154296875,\"y\":226.9572296142578},{\"x\":203.41249084472656,\"y\":231.83749389648438},{\"x\":211.85409545898438,\"y\":230.89816284179688},{\"x\":218.7886199951172,\"y\":225.41867065429688},{\"x\":224.8160400390625,\"y\":218.92974853515625},{\"x\":230.3641357421875,\"y\":212.0236358642578},{\"x\":235.608642578125,\"y\":204.8833770751953},{\"x\":240.63941955566406,\"y\":197.59080505371094},{\"x\":245.50965881347656,\"y\":190.1898651123047},{\"x\":250.25364685058594,\"y\":182.7073516845703},{\"x\":254.8948974609375,\"y\":175.16050720214844},{\"x\":259.45068359375,\"y\":167.56190490722656}]]",
+ 600,
+ 382,
+ 81,
+ "path",
+ "cardinal",
+ 0.5,
+ 1,
+ "list",
+ 0,
+ 1,
+ "",
+ null
+ ]
+ },
+ {
+ "id": 119,
+ "type": "SplineEditor",
+ "pos": [
+ 1544.139404296875,
+ 1047.919189453125
+ ],
+ "size": [
+ 645,
+ 832
+ ],
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "bg_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "mask",
+ "type": "MASK",
+ "slot_index": 0,
+ "links": []
+ },
+ {
+ "name": "coord_str",
+ "type": "STRING",
+ "slot_index": 1,
+ "links": [
+ 266
+ ]
+ },
+ {
+ "name": "float",
+ "type": "FLOAT",
+ "links": null
+ },
+ {
+ "name": "count",
+ "type": "INT",
+ "links": null
+ },
+ {
+ "name": "normalized_str",
+ "type": "STRING",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "SplineEditor",
+ "points": "SplineEditor",
+ "imgData": null
+ },
+ "widgets_values": [
+ "[{\"points\":[{\"x\":63.916760050380844,\"y\":114.45559357858895},{\"x\":71.34894145158792,\"y\":114.45559357858895}],\"color\":\"#1f77b4\",\"name\":\"Spline 1\"}]",
+ "[[{\"x\":63.9167594909668,\"y\":114.45559692382812},{\"x\":64.00965881347656,\"y\":114.45559692382812},{\"x\":64.1025619506836,\"y\":114.45559692382812},{\"x\":64.19546508789062,\"y\":114.45559692382812},{\"x\":64.28836822509766,\"y\":114.45559692382812},{\"x\":64.38127136230469,\"y\":114.45559692382812},{\"x\":64.47417449951172,\"y\":114.45559692382812},{\"x\":64.56707763671875,\"y\":114.45559692382812},{\"x\":64.65998077392578,\"y\":114.45559692382812},{\"x\":64.75287628173828,\"y\":114.45559692382812},{\"x\":64.84577941894531,\"y\":114.45559692382812},{\"x\":64.93868255615234,\"y\":114.45559692382812},{\"x\":65.03158569335938,\"y\":114.45559692382812},{\"x\":65.1244888305664,\"y\":114.45559692382812},{\"x\":65.21739196777344,\"y\":114.45559692382812},{\"x\":65.31029510498047,\"y\":114.45559692382812},{\"x\":65.4031982421875,\"y\":114.45559692382812},{\"x\":65.49609375,\"y\":114.45559692382812},{\"x\":65.58899688720703,\"y\":114.45559692382812},{\"x\":65.68190002441406,\"y\":114.45559692382812},{\"x\":65.7748031616211,\"y\":114.45559692382812},{\"x\":65.86770629882812,\"y\":114.45559692382812},{\"x\":65.96060943603516,\"y\":114.45559692382812},{\"x\":66.05351257324219,\"y\":114.45559692382812},{\"x\":66.14641571044922,\"y\":114.45559692382812},{\"x\":66.23931884765625,\"y\":114.45559692382812},{\"x\":66.33221435546875,\"y\":114.45559692382812},{\"x\":66.42511749267578,\"y\":114.45559692382812},{\"x\":66.51802062988281,\"y\":114.45559692382812},{\"x\":66.61092376708984,\"y\":114.45559692382812},{\"x\":66.70382690429688,\"y\":114.45559692382812},{\"x\":66.7967300415039,\"y\":114.45559692382812},{\"x\":66.88963317871094,\"y\":114.45559692382812},{\"x\":66.98253631591797,\"y\":114.45559692382812},{\"x\":67.075439453125,\"y\":114.45559692382812},{\"x\":67.1683349609375,\"y\":114.45559692382812},{\"x\":67.26123809814453,\"y\":114.45559692382812},{\"x\":67.35414123535156,\"y\":114.45559692382812},{\"x\":67.4470443725586,\"y\":114.45559692382812},{\"x\":67.53994750976562,\"y\":114.45559692382812},{\"x\":67.63285064697266,\"y\":114.45559692382812},{\"x\":67.72575378417969,\"y\":114.45559692382812},{\"x\":67.81864929199219,\"y\":114.45559692382812},{\"x\":67.91155242919922,\"y\":114.45559692382812},{\"x\":68.00445556640625,\"y\":114.45559692382812},{\"x\":68.09735870361328,\"y\":114.45559692382812},{\"x\":68.19026184082031,\"y\":114.45559692382812},{\"x\":68.28316497802734,\"y\":114.45559692382812},{\"x\":68.37606811523438,\"y\":114.45559692382812},{\"x\":68.4689712524414,\"y\":114.45559692382812},{\"x\":68.56187438964844,\"y\":114.45559692382812},{\"x\":68.65476989746094,\"y\":114.45559692382812},{\"x\":68.74767303466797,\"y\":114.45559692382812},{\"x\":68.840576171875,\"y\":114.45559692382812},{\"x\":68.93347930908203,\"y\":114.45559692382812},{\"x\":69.02638244628906,\"y\":114.45559692382812},{\"x\":69.1192855834961,\"y\":114.45559692382812},{\"x\":69.21218872070312,\"y\":114.45559692382812},{\"x\":69.30509185791016,\"y\":114.45559692382812},{\"x\":69.39799499511719,\"y\":114.45559692382812},{\"x\":69.49089050292969,\"y\":114.45559692382812},{\"x\":69.58379364013672,\"y\":114.45559692382812},{\"x\":69.67669677734375,\"y\":114.45559692382812},{\"x\":69.76959991455078,\"y\":114.45559692382812},{\"x\":69.86250305175781,\"y\":114.45559692382812},{\"x\":69.95540618896484,\"y\":114.45559692382812},{\"x\":70.04830932617188,\"y\":114.45559692382812},{\"x\":70.1412124633789,\"y\":114.45559692382812},{\"x\":70.2341079711914,\"y\":114.45559692382812},{\"x\":70.32701110839844,\"y\":114.45559692382812},{\"x\":70.41991424560547,\"y\":114.45559692382812},{\"x\":70.5128173828125,\"y\":114.45559692382812},{\"x\":70.60572052001953,\"y\":114.45559692382812},{\"x\":70.69862365722656,\"y\":114.45559692382812},{\"x\":70.7915267944336,\"y\":114.45559692382812},{\"x\":70.88442993164062,\"y\":114.45559692382812},{\"x\":70.97732543945312,\"y\":114.45559692382812},{\"x\":71.07022857666016,\"y\":114.45559692382812},{\"x\":71.16313171386719,\"y\":114.45559692382812},{\"x\":71.25603485107422,\"y\":114.45559692382812},{\"x\":71.34893798828125,\"y\":114.45559692382812}]]",
+ 600,
+ 382,
+ 81,
+ "path",
+ "cardinal",
+ 0.5,
+ 1,
+ "list",
+ 0,
+ 1,
+ "",
+ null
+ ]
+ },
+ {
+ "id": 44,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 2241.138427734375,
+ 1051.91943359375
+ ],
+ "size": [
+ 530,
+ 650.4000244140625
+ ],
+ "flags": {},
+ "order": 12,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 237
+ },
+ {
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "slot_index": 0,
+ "links": null
+ }
+ ],
+ "title": "Trajectory Outputs",
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun-Trajectory",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun-Trajectory_00002.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ },
+ "muted": false
+ }
+ }
+ },
+ {
+ "id": 115,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 2819,
+ 1056
+ ],
+ "size": [
+ 530,
+ 310
+ ],
+ "flags": {},
+ "order": 16,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 264
+ },
+ {
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "slot_index": 0,
+ "links": null
+ }
+ ],
+ "title": "Video with Trajectory Outputs",
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun-Trajectory-Merge",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "EasyAnimate-Trajectory-Merge_00009.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ },
+ "muted": false
+ }
+ }
+ },
+ {
+ "id": 126,
+ "type": "WanFunV2VSampler",
+ "pos": [
+ 902,
+ 60
+ ],
+ "size": [
+ 428.4000244140625,
+ 506
+ ],
+ "flags": {},
+ "order": 13,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 281
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 282
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 283
+ },
+ {
+ "name": "validation_video",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "control_video",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 284
+ },
+ {
+ "name": "start_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 285
+ },
+ {
+ "name": "ref_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "camera_conditions",
+ "shape": 7,
+ "type": "STRING",
+ "link": null
+ },
+ {
+ "name": "riflex_k",
+ "shape": 7,
+ "type": "RIFLEXT_ARGS",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 286,
+ 287
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ },
+ {
+ "id": 106,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1390,
+ 61
+ ],
+ "size": [
+ 390,
+ 310
+ ],
+ "flags": {},
+ "order": 14,
+ "mode": 0,
+ "inputs": [
+ {
+ "label": "图像",
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 286
+ },
+ {
+ "label": "音频",
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "label": "批次管理",
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "label": "文件名",
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "slot_index": 0,
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "EasyAnimate_00105.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 123,
+ "type": "LoadWanFunModel",
+ "pos": [
+ 281,
+ 251
+ ],
+ "size": [
+ 315,
+ 154
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "slot_index": 0,
+ "links": [
+ 281
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-V1.1-1.3B-Control",
+ "Control",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 112,
+ "type": "Note",
+ "pos": [
+ -203,
+ 252
+ ],
+ "size": [
+ 427.074951171875,
+ 143.9142608642578
+ ],
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ }
+ ],
+ "links": [
+ [
+ 237,
+ 95,
+ 0,
+ 44,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 249,
+ 97,
+ 0,
+ 95,
+ 1,
+ "MASK"
+ ],
+ [
+ 262,
+ 95,
+ 0,
+ 114,
+ 1,
+ "IMAGE"
+ ],
+ [
+ 264,
+ 114,
+ 0,
+ 115,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 265,
+ 97,
+ 1,
+ 118,
+ 0,
+ "STRING"
+ ],
+ [
+ 266,
+ 119,
+ 1,
+ 118,
+ 1,
+ "STRING"
+ ],
+ [
+ 267,
+ 118,
+ 0,
+ 95,
+ 0,
+ "STRING"
+ ],
+ [
+ 281,
+ 123,
+ 0,
+ 126,
+ 0,
+ "FunModels"
+ ],
+ [
+ 282,
+ 121,
+ 0,
+ 126,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 283,
+ 122,
+ 0,
+ 126,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 284,
+ 95,
+ 0,
+ 126,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 285,
+ 100,
+ 0,
+ 126,
+ 5,
+ "IMAGE"
+ ],
+ [
+ 286,
+ 126,
+ 0,
+ 106,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 287,
+ 126,
+ 0,
+ 114,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "id": 1,
+ "title": "Load Model",
+ "bounding": [
+ 189,
+ 160,
+ 475,
+ 269
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 2,
+ "title": "Prompts",
+ "bounding": [
+ 191,
+ 456,
+ 475,
+ 587
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 3,
+ "title": "First Image of Trajectory",
+ "bounding": [
+ 191,
+ 1068,
+ 475,
+ 456
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 4,
+ "title": "Generate Control Video",
+ "bounding": [
+ 786,
+ 841,
+ 2616,
+ 1056
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.7513148009015782,
+ "offset": [
+ 119.78785424088606,
+ -47.62140429778734
+ ]
+ },
+ "node_versions": {
+ "comfy-core": "0.3.44",
+ "ComfyUI-KJNodes": "ff49e1b01f10a14496b08e21bb89b64d2b15f333",
+ "CogVideoX-Fun": "e935795d7684aaba72be65d2ad5ef580c0526f7a",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
+ },
+ "frontendVersion": "1.21.3"
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_i2v.json b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_i2v.json
new file mode 100644
index 0000000000000000000000000000000000000000..6c9aaa255d36fdc0ea18ea7cc80a418d19ff7be3
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_i2v.json
@@ -0,0 +1,496 @@
+{
+ "last_node_id": 102,
+ "last_link_id": 68,
+ "nodes": [
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": -50
+ },
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 66
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 94,
+ "type": "Note",
+ "pos": {
+ "0": 17,
+ "1": -35
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 95,
+ "type": "Note",
+ "pos": {
+ "0": 35.71394348144531,
+ "1": 536.9210205078125
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload image here\n(你可以在此上传图片)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1271,
+ "1": -67
+ },
+ "size": [
+ 390,
+ 537.4615384615385
+ ],
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 64,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00008.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": {
+ "0": -95.01139068603516,
+ "1": -334.30706787109375
+ },
+ "size": {
+ "0": 355.636474609375,
+ "1": 132.4238739013672
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 87,
+ "type": "LoadImage",
+ "pos": {
+ "0": 308,
+ "1": 482
+ },
+ "size": {
+ "0": 315,
+ "1": 314
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 68
+ ]
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "2.png",
+ "image"
+ ]
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": 160
+ },
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 67
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 99,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 290,
+ "1": -334
+ },
+ "size": {
+ "0": 315,
+ "1": 154
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 65
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-1.3B-InP",
+ "Inpaint",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 101,
+ "type": "WanFunInpaintSampler",
+ "pos": {
+ "0": 771,
+ "1": -67
+ },
+ "size": {
+ "0": 428.4000244140625,
+ "1": 378
+ },
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 65
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 66
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 67
+ },
+ {
+ "name": "start_img",
+ "type": "IMAGE",
+ "link": 68,
+ "shape": 7
+ },
+ {
+ "name": "end_img",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 64
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunInpaintSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "randomize",
+ 50,
+ 6,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ }
+ ],
+ "links": [
+ [
+ 64,
+ 101,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 65,
+ 99,
+ 0,
+ 101,
+ 0,
+ "FunModels"
+ ],
+ [
+ 66,
+ 75,
+ 0,
+ 101,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 67,
+ 73,
+ 0,
+ 101,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 68,
+ 87,
+ 0,
+ 101,
+ 3,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Load Image",
+ "bounding": [
+ 222,
+ 396,
+ 458,
+ 436
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load Model",
+ "bounding": [
+ 227,
+ -416,
+ 469,
+ 256
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.8264462809917354,
+ "offset": [
+ 73.82229219905072,
+ 565.0461564576733
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "10076a3aee6547541ca9442bf22389bfc2ea7526",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "comfy-core": "v0.2.7-3-g8afb97c"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_i2v_lora.json b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_i2v_lora.json
new file mode 100644
index 0000000000000000000000000000000000000000..97e3ac677bc4ac2bb2a9c0364f63e70923b846dc
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_i2v_lora.json
@@ -0,0 +1,544 @@
+{
+ "last_node_id": 103,
+ "last_link_id": 70,
+ "nodes": [
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": -50
+ },
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 66
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 94,
+ "type": "Note",
+ "pos": {
+ "0": 17,
+ "1": -35
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 95,
+ "type": "Note",
+ "pos": {
+ "0": 35.71394348144531,
+ "1": 536.9210205078125
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload image here\n(你可以在此上传图片)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1271,
+ "1": -67
+ },
+ "size": [
+ 390,
+ 546
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 64,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00021.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": {
+ "0": -95.01139068603516,
+ "1": -334.30706787109375
+ },
+ "size": {
+ "0": 355.636474609375,
+ "1": 132.4238739013672
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 87,
+ "type": "LoadImage",
+ "pos": {
+ "0": 308,
+ "1": 482
+ },
+ "size": {
+ "0": 315,
+ "1": 314
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 68
+ ]
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "2.png",
+ "image"
+ ]
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": 160
+ },
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 67
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 99,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 290,
+ "1": -334
+ },
+ "size": {
+ "0": 315,
+ "1": 154
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 69
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-1.3B-InP",
+ "Inpaint",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 103,
+ "type": "LoadWanFunLora",
+ "pos": {
+ "0": 659,
+ "1": -335
+ },
+ "size": {
+ "0": 315,
+ "1": 106
+ },
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 69
+ }
+ ],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 70
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunLora"
+ },
+ "widgets_values": [
+ "cogvideox_fun/Wan2.1-Fun-1.3B-InP_MovieGen_tail_10_hpsv2.1_max_grad_norm0.3_lr1e-5_latent1_checkpoint-1000.safetensors",
+ 0.35,
+ false
+ ]
+ },
+ {
+ "id": 101,
+ "type": "WanFunInpaintSampler",
+ "pos": {
+ "0": 771,
+ "1": -67
+ },
+ "size": {
+ "0": 428.4000244140625,
+ "1": 378
+ },
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 70
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 66
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 67
+ },
+ {
+ "name": "start_img",
+ "type": "IMAGE",
+ "link": 68,
+ "shape": 7
+ },
+ {
+ "name": "end_img",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 64
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunInpaintSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 844054136754572,
+ "randomize",
+ 50,
+ 6,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ }
+ ],
+ "links": [
+ [
+ 64,
+ 101,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 66,
+ 75,
+ 0,
+ 101,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 67,
+ 73,
+ 0,
+ 101,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 68,
+ 87,
+ 0,
+ 101,
+ 3,
+ "IMAGE"
+ ],
+ [
+ 69,
+ 99,
+ 0,
+ 103,
+ 0,
+ "FunModels"
+ ],
+ [
+ 70,
+ 103,
+ 0,
+ 101,
+ 0,
+ "FunModels"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Load Image",
+ "bounding": [
+ 222,
+ 396,
+ 458,
+ 436
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load Model",
+ "bounding": [
+ 227,
+ -416,
+ 822,
+ 262
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.8264462809917354,
+ "offset": [
+ 73.82229219905072,
+ 564.8949064576733
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "10076a3aee6547541ca9442bf22389bfc2ea7526",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "comfy-core": "v0.2.7-3-g8afb97c"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_t2v.json b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_t2v.json
new file mode 100644
index 0000000000000000000000000000000000000000..cdfc97f881545a6f8e9bbcd50f5d693243562b07
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_t2v.json
@@ -0,0 +1,378 @@
+{
+ "last_node_id": 87,
+ "last_link_id": 58,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": -50
+ },
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 57
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1185,
+ "1": -97
+ },
+ "size": [
+ 390.9534912109375,
+ 538.0116295447716
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 55,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00008.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 87,
+ "type": "WanFunT2VSampler",
+ "pos": {
+ "0": 738,
+ "1": -97
+ },
+ "size": {
+ "0": 415.8000183105469,
+ "1": 386
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 56
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 57
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 58
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 55
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunT2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 832,
+ 480,
+ false,
+ 43,
+ "randomize",
+ 50,
+ 6,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ },
+ {
+ "id": 86,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 291,
+ "1": -317.7618408203125
+ },
+ "size": {
+ "0": 315,
+ "1": 154
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 56
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-1.3B-InP",
+ "Inpaint",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": {
+ "0": -134,
+ "1": -324.7618408203125
+ },
+ "size": {
+ "0": 397.7547302246094,
+ "1": 125.90532684326172
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": 160
+ },
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 58
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 55,
+ 87,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 56,
+ 86,
+ 0,
+ 87,
+ 0,
+ "FunModels"
+ ],
+ [
+ 57,
+ 75,
+ 0,
+ 87,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 58,
+ 73,
+ 0,
+ 87,
+ 2,
+ "STRING_PROMPT"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load Model",
+ "bounding": [
+ 220,
+ -401,
+ 469,
+ 251
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.8264462809917354,
+ "offset": [
+ 137.06842501155074,
+ 523.7785392701735
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "10076a3aee6547541ca9442bf22389bfc2ea7526",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_t2v_lora.json b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_t2v_lora.json
new file mode 100644
index 0000000000000000000000000000000000000000..2eb35ee8f4725f433978cedf995d872d7f28d4ba
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_t2v_lora.json
@@ -0,0 +1,426 @@
+{
+ "last_node_id": 89,
+ "last_link_id": 60,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": -50
+ },
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 57
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1185,
+ "1": -97
+ },
+ "size": [
+ 390.9534912109375,
+ 538.0116295447716
+ ],
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 55,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00017.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 86,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 299.31610107421875,
+ "1": -334.70806884765625
+ },
+ "size": {
+ "0": 315,
+ "1": 154
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 59
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-1.3B-InP",
+ "Inpaint",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": 160
+ },
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 58
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": {
+ "0": -125.68385314941406,
+ "1": -341.70806884765625
+ },
+ "size": [
+ 413.06488553532427,
+ 159.48434647201407
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 89,
+ "type": "LoadWanFunLora",
+ "pos": {
+ "0": 646,
+ "1": -334
+ },
+ "size": {
+ "0": 315,
+ "1": 106
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 59
+ }
+ ],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 60
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunLora"
+ },
+ "widgets_values": [
+ "cogvideox_fun/Wan2.1-Fun-1.3B-InP_MovieGen_tail_10_hpsv2.1_max_grad_norm0.3_lr1e-5_latent1_checkpoint-1000.safetensors",
+ 0.55,
+ false
+ ]
+ },
+ {
+ "id": 87,
+ "type": "WanFunT2VSampler",
+ "pos": {
+ "0": 738,
+ "1": -97
+ },
+ "size": {
+ "0": 415.8000183105469,
+ "1": 386
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 60
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 57
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 58
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 55
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunT2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 832,
+ 480,
+ false,
+ 637063819662010,
+ "randomize",
+ 50,
+ 6,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ }
+ ],
+ "links": [
+ [
+ 55,
+ 87,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 57,
+ 75,
+ 0,
+ 87,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 58,
+ 73,
+ 0,
+ 87,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 59,
+ 86,
+ 0,
+ 89,
+ 0,
+ "FunModels"
+ ],
+ [
+ 60,
+ 89,
+ 0,
+ 87,
+ 0,
+ "FunModels"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Load Model",
+ "bounding": [
+ 229,
+ -418,
+ 747,
+ 259
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.8264462809917354,
+ "offset": [
+ 137.21967501155075,
+ 523.9297892701735
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "10076a3aee6547541ca9442bf22389bfc2ea7526",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control.json b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control.json
new file mode 100644
index 0000000000000000000000000000000000000000..e7630e5b4d18487742eca28b6827ac994347bef9
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control.json
@@ -0,0 +1,568 @@
+{
+ "last_node_id": 97,
+ "last_link_id": 65,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": {
+ "0": 15.739953994750977,
+ "1": 462.38665771484375
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 88,
+ "type": "Note",
+ "pos": {
+ "0": -99,
+ "1": 197
+ },
+ "size": {
+ "0": 326.1556091308594,
+ "1": 145.20904541015625
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 89,
+ "type": "Note",
+ "pos": {
+ "0": -192,
+ "1": -293
+ },
+ "size": {
+ "0": 427.074951171875,
+ "1": 143.9142608642578
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": {
+ "0": 335,
+ "1": 476
+ },
+ "size": [
+ 252.056640625,
+ 688.5451388888889
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 64
+ ],
+ "slot_index": 0,
+ "shape": 3
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "pose.mp4",
+ "force_rate": 0,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 0,
+ "filename": "pose.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 92,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 254,
+ "1": -46
+ },
+ "size": {
+ "0": 380.845703125,
+ "1": 157.68350219726562
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 62
+ ],
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "在这个阳光明媚的户外花园里,美女身穿一袭及膝的白色无袖连衣裙,裙摆在她轻盈的舞姿中轻柔地摆动,宛如一只翩翩起舞的蝴蝶。阳光透过树叶间洒下斑驳的光影,映衬出她柔和的脸庞和清澈的眼眸,显得格外优雅。仿佛每一个动作都在诉说着青春与活力,她在草地上旋转,裙摆随之飞扬,仿佛整个花园都因她的舞动而欢愉。周围五彩缤纷的花朵在微风中摇曳,玫瑰、菊花、百合,各自释放出阵阵香气,营造出一种轻松而愉快的氛围。"
+ ]
+ },
+ {
+ "id": 94,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 258,
+ "1": 178
+ },
+ "size": {
+ "0": 368.5529479980469,
+ "1": 159.4075927734375
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 63
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1274,
+ "1": 10
+ },
+ "size": [
+ 390.9534912109375,
+ 966.9860514322917
+ ],
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 65,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00004.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 97,
+ "type": "WanFunV2VSampler",
+ "pos": {
+ "0": 792,
+ "1": 11
+ },
+ "size": [
+ 428.4000244140625,
+ 486
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 61
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 62
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 63
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": 64,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "ref_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": null,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 65
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1.0,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ },
+ {
+ "id": 95,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 275,
+ "1": -309
+ },
+ "size": {
+ "0": 435.2322082519531,
+ "1": 154
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 61
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-V1.1-1.3B-Control",
+ "Control",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 61,
+ 95,
+ 0,
+ 97,
+ 0,
+ "FunModels"
+ ],
+ [
+ 62,
+ 92,
+ 0,
+ 97,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 63,
+ 94,
+ 0,
+ 97,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 64,
+ 85,
+ 0,
+ 97,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 65,
+ 97,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load Model",
+ "bounding": [
+ 218,
+ -387,
+ 542,
+ 248
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Upload Your Video",
+ "bounding": [
+ 218,
+ 385,
+ 487,
+ 789
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650709,
+ "offset": [
+ 249.86519634240904,
+ 438.3739973625246
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "CogVideoX-Fun": "717f0629175ad192927dc51ec95c4376816a4212"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_canny.json b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_canny.json
new file mode 100644
index 0000000000000000000000000000000000000000..37f6e6d6fb791926ad046b5da688c6870d8da539
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_canny.json
@@ -0,0 +1,698 @@
+{
+ "last_node_id": 100,
+ "last_link_id": 71,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": {
+ "0": 15.739953994750977,
+ "1": 462.38665771484375
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 88,
+ "type": "Note",
+ "pos": {
+ "0": -99,
+ "1": 197
+ },
+ "size": {
+ "0": 326.1556091308594,
+ "1": 145.20904541015625
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 89,
+ "type": "Note",
+ "pos": {
+ "0": -192,
+ "1": -293
+ },
+ "size": {
+ "0": 427.074951171875,
+ "1": 143.9142608642578
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 92,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 254,
+ "1": -46
+ },
+ "size": {
+ "0": 380.845703125,
+ "1": 157.68350219726562
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 68
+ ],
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "在这个阳光明媚的户外花园里,美女身穿一袭及膝的白色无袖连衣裙,裙摆在她轻盈的舞姿中轻柔地摆动,宛如一只翩翩起舞的蝴蝶。阳光透过树叶间洒下斑驳的光影,映衬出她柔和的脸庞和清澈的眼眸,显得格外优雅。仿佛每一个动作都在诉说着青春与活力,她在草地上旋转,裙摆随之飞扬,仿佛整个花园都因她的舞动而欢愉。周围五彩缤纷的花朵在微风中摇曳,玫瑰、菊花、百合,各自释放出阵阵香气,营造出一种轻松而愉快的氛围。"
+ ]
+ },
+ {
+ "id": 94,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 258,
+ "1": 178
+ },
+ "size": {
+ "0": 368.5529479980469,
+ "1": 159.4075927734375
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 69
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": {
+ "0": 335,
+ "1": 476
+ },
+ "size": [
+ 252.056640625,
+ 262
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 66
+ ],
+ "slot_index": 0,
+ "shape": 3
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "00339.mp4",
+ "force_rate": 0,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 0,
+ "filename": "00339.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 97,
+ "type": "VideoToCanny",
+ "pos": {
+ "0": 729,
+ "1": 566
+ },
+ "size": {
+ "0": 315,
+ "1": 106
+ },
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "input_video",
+ "type": "IMAGE",
+ "link": 66
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 65,
+ 70
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VideoToCanny"
+ },
+ "widgets_values": [
+ 100,
+ 200,
+ 81
+ ]
+ },
+ {
+ "id": 99,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1094,
+ "1": 559
+ },
+ "size": {
+ "0": 315,
+ "1": 310
+ },
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 65,
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun-Preprocess-Video",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 19,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "AnimateDiff_00001.gif",
+ "subfolder": "",
+ "type": "output",
+ "format": "image/gif",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1467,
+ "1": -158
+ },
+ "size": [
+ 390.9534912109375,
+ 966.9860514322917
+ ],
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 71,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00004.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 100,
+ "type": "WanFunV2VSampler",
+ "pos": {
+ "0": 973,
+ "1": -160
+ },
+ "size": [
+ 428.4000244140625,
+ 486
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 67
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 68
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 69
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": 70,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "ref_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": null,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 71
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1.0,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ },
+ {
+ "id": 95,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 275,
+ "1": -309
+ },
+ "size": {
+ "0": 435.2322082519531,
+ "1": 154
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 67
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-V1.1-1.3B-Control",
+ "Control",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 65,
+ 97,
+ 0,
+ 99,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 66,
+ 85,
+ 0,
+ 97,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 67,
+ 95,
+ 0,
+ 100,
+ 0,
+ "FunModels"
+ ],
+ [
+ 68,
+ 92,
+ 0,
+ 100,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 69,
+ 94,
+ 0,
+ 100,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 70,
+ 97,
+ 0,
+ 100,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 71,
+ 100,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Upload Your Video",
+ "bounding": [
+ 218,
+ 385,
+ 487,
+ 789
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load Model",
+ "bounding": [
+ 218,
+ -387,
+ 542,
+ 248
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650709,
+ "offset": [
+ 249.86519634240904,
+ 438.3739973625246
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "717f0629175ad192927dc51ec95c4376816a4212",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_depth.json b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_depth.json
new file mode 100644
index 0000000000000000000000000000000000000000..5cdd1a74e4b688b31d19f8cfe931de441e33a6cc
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_depth.json
@@ -0,0 +1,696 @@
+{
+ "last_node_id": 101,
+ "last_link_id": 75,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": {
+ "0": 15.739953994750977,
+ "1": 462.38665771484375
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 88,
+ "type": "Note",
+ "pos": {
+ "0": -99,
+ "1": 197
+ },
+ "size": {
+ "0": 326.1556091308594,
+ "1": 145.20904541015625
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 89,
+ "type": "Note",
+ "pos": {
+ "0": -192,
+ "1": -293
+ },
+ "size": {
+ "0": 427.074951171875,
+ "1": 143.9142608642578
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 92,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 254,
+ "1": -46
+ },
+ "size": {
+ "0": 380.845703125,
+ "1": 157.68350219726562
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 72
+ ],
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "在这个阳光明媚的户外花园里,美女身穿一袭及膝的白色无袖连衣裙,裙摆在她轻盈的舞姿中轻柔地摆动,宛如一只翩翩起舞的蝴蝶。阳光透过树叶间洒下斑驳的光影,映衬出她柔和的脸庞和清澈的眼眸,显得格外优雅。仿佛每一个动作都在诉说着青春与活力,她在草地上旋转,裙摆随之飞扬,仿佛整个花园都因她的舞动而欢愉。周围五彩缤纷的花朵在微风中摇曳,玫瑰、菊花、百合,各自释放出阵阵香气,营造出一种轻松而愉快的氛围。"
+ ]
+ },
+ {
+ "id": 94,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 258,
+ "1": 178
+ },
+ "size": {
+ "0": 368.5529479980469,
+ "1": 159.4075927734375
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 73
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": {
+ "0": 335,
+ "1": 476
+ },
+ "size": [
+ 252.056640625,
+ 262
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 70
+ ],
+ "slot_index": 0,
+ "shape": 3
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "00339.mp4",
+ "force_rate": 0,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 0,
+ "filename": "00339.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 100,
+ "type": "VideoToDepth",
+ "pos": {
+ "0": 725,
+ "1": 477
+ },
+ "size": {
+ "0": 229.20001220703125,
+ "1": 58
+ },
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "input_video",
+ "type": "IMAGE",
+ "link": 70
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 68,
+ 74
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VideoToDepth"
+ },
+ "widgets_values": [
+ 81
+ ]
+ },
+ {
+ "id": 99,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 996,
+ "1": 505
+ },
+ "size": {
+ "0": 315,
+ "1": 310
+ },
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 68,
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun-Preprocess-Video",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 19,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun-Preprocess-Video_00001.gif",
+ "subfolder": "",
+ "type": "output",
+ "format": "image/gif",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 101,
+ "type": "WanFunV2VSampler",
+ "pos": {
+ "0": 989,
+ "1": -180
+ },
+ "size": [
+ 428.4000244140625,
+ 486
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 71
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 72
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 73
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": 74,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "ref_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": null,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 75
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1.0,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ },
+ {
+ "id": 95,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 275,
+ "1": -309
+ },
+ "size": {
+ "0": 435.2322082519531,
+ "1": 154
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 71
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-V1.1-1.3B-Control",
+ "Control",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1459,
+ "1": -180
+ },
+ "size": [
+ 390.9534912109375,
+ 966.9860514322917
+ ],
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 75,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00039.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ }
+ ],
+ "links": [
+ [
+ 68,
+ 100,
+ 0,
+ 99,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 70,
+ 85,
+ 0,
+ 100,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 71,
+ 95,
+ 0,
+ 101,
+ 0,
+ "FunModels"
+ ],
+ [
+ 72,
+ 92,
+ 0,
+ 101,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 73,
+ 94,
+ 0,
+ 101,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 74,
+ 100,
+ 0,
+ 101,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 75,
+ 101,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Upload Your Video",
+ "bounding": [
+ 218,
+ 385,
+ 487,
+ 789
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load Model",
+ "bounding": [
+ 218,
+ -387,
+ 542,
+ 248
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650709,
+ "offset": [
+ 249.86519634240904,
+ 438.3739973625246
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "717f0629175ad192927dc51ec95c4376816a4212",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_depth_ref.json b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_depth_ref.json
new file mode 100644
index 0000000000000000000000000000000000000000..3063d4a5ce4731a3a5ccb651fd5c2badc5ac5fad
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_depth_ref.json
@@ -0,0 +1,742 @@
+{
+ "last_node_id": 104,
+ "last_link_id": 85,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": {
+ "0": -111.46612548828125,
+ "1": 460.2178955078125
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 88,
+ "type": "Note",
+ "pos": {
+ "0": -99,
+ "1": 197
+ },
+ "size": {
+ "0": 326.1556091308594,
+ "1": 145.20904541015625
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 89,
+ "type": "Note",
+ "pos": {
+ "0": -192,
+ "1": -293
+ },
+ "size": {
+ "0": 427.074951171875,
+ "1": 143.9142608642578
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 94,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 258,
+ "1": 178
+ },
+ "size": {
+ "0": 368.5529479980469,
+ "1": 159.4075927734375
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 82
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1488,
+ "1": 8
+ },
+ "size": [
+ 390.9534912109375,
+ 942.2558186848959
+ ],
+ "flags": {},
+ "order": 12,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 85,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00050.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 99,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1005,
+ "1": 554
+ },
+ "size": [
+ 315,
+ 849.46875
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 79,
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun-Preprocess-Video",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 19,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun-Preprocess-Video_00008.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 102,
+ "type": "LoadImage",
+ "pos": {
+ "0": 553,
+ "1": 598
+ },
+ "size": {
+ "0": 315,
+ "1": 314
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 84
+ ]
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "9.png",
+ "image"
+ ]
+ },
+ {
+ "id": 92,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 254,
+ "1": -46
+ },
+ "size": {
+ "0": 380.845703125,
+ "1": 157.68350219726562
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 81
+ ],
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "一位动漫风格的女孩。她有着紫色的短发,头上戴着一个黑色和金色相间的蝴蝶结。她的表情显得有些严肃或沉思,眼睛大而有神。女孩穿着一件白色衬衫,外面搭配了一件深蓝色的背心,背心上有一个粉色的蝴蝶结装饰。她的裙子是白色的,裙摆蓬松,整体造型非常可爱且精致。背景是一个简单的圆形图案,颜色为粉红色和灰色相间,给人一种柔和的感觉。整个画面色调柔和,人物形象生动鲜明。"
+ ]
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": {
+ "0": 207.79391479492188,
+ "1": 473.83123779296875
+ },
+ "size": [
+ 252.056640625,
+ 688.5451388888889
+ ],
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 76
+ ],
+ "slot_index": 0,
+ "shape": 3
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "000007.mp4",
+ "force_rate": 16,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 16,
+ "filename": "000007.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 103,
+ "type": "VideoToDepth",
+ "pos": {
+ "0": 553,
+ "1": 472
+ },
+ "size": {
+ "0": 315,
+ "1": 58
+ },
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "input_video",
+ "type": "IMAGE",
+ "link": 76
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 79,
+ 83
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VideoToDepth"
+ },
+ "widgets_values": [
+ 81
+ ]
+ },
+ {
+ "id": 104,
+ "type": "WanFunV2VSampler",
+ "pos": {
+ "0": 996,
+ "1": 9
+ },
+ "size": [
+ 428.4000244140625,
+ 486
+ ],
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 80
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 81
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 82
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": 83,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "ref_image",
+ "type": "IMAGE",
+ "link": 84,
+ "shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": null,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 85
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 490544951141590,
+ "fixed",
+ 50,
+ 6,
+ 1.0,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ },
+ {
+ "id": 95,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 275,
+ "1": -309
+ },
+ "size": {
+ "0": 435.2322082519531,
+ "1": 154
+ },
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 80
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-V1.1-1.3B-Control",
+ "Control",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 76,
+ 85,
+ 0,
+ 103,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 79,
+ 103,
+ 0,
+ 99,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 80,
+ 95,
+ 0,
+ 104,
+ 0,
+ "FunModels"
+ ],
+ [
+ 81,
+ 92,
+ 0,
+ 104,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 82,
+ 94,
+ 0,
+ 104,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 83,
+ 103,
+ 0,
+ 104,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 84,
+ 102,
+ 0,
+ 104,
+ 6,
+ "IMAGE"
+ ],
+ [
+ 85,
+ 104,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Upload Your Video And Reference Image",
+ "bounding": [
+ 91,
+ 383,
+ 859,
+ 841
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load Model",
+ "bounding": [
+ 218,
+ -387,
+ 542,
+ 248
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650709,
+ "offset": [
+ 246.99418774865902,
+ 428.7658411125245
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "a7fa7028d52498f13e983eba012a81ebcae24977",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "comfy-core": "v0.2.7-3-g8afb97c"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_pose.json b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_pose.json
new file mode 100644
index 0000000000000000000000000000000000000000..cd2a01c5b9a4e0b2688f7ccb031e5f5f0fbb5a82
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_pose.json
@@ -0,0 +1,696 @@
+{
+ "last_node_id": 102,
+ "last_link_id": 79,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": {
+ "0": 15.739953994750977,
+ "1": 462.38665771484375
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 88,
+ "type": "Note",
+ "pos": {
+ "0": -99,
+ "1": 197
+ },
+ "size": {
+ "0": 326.1556091308594,
+ "1": 145.20904541015625
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 89,
+ "type": "Note",
+ "pos": {
+ "0": -192,
+ "1": -293
+ },
+ "size": {
+ "0": 427.074951171875,
+ "1": 143.9142608642578
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 92,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 254,
+ "1": -46
+ },
+ "size": {
+ "0": 380.845703125,
+ "1": 157.68350219726562
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 76
+ ],
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "在这个阳光明媚的户外花园里,美女身穿一袭及膝的白色无袖连衣裙,裙摆在她轻盈的舞姿中轻柔地摆动,宛如一只翩翩起舞的蝴蝶。阳光透过树叶间洒下斑驳的光影,映衬出她柔和的脸庞和清澈的眼眸,显得格外优雅。仿佛每一个动作都在诉说着青春与活力,她在草地上旋转,裙摆随之飞扬,仿佛整个花园都因她的舞动而欢愉。周围五彩缤纷的花朵在微风中摇曳,玫瑰、菊花、百合,各自释放出阵阵香气,营造出一种轻松而愉快的氛围。"
+ ]
+ },
+ {
+ "id": 94,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 258,
+ "1": 178
+ },
+ "size": {
+ "0": 368.5529479980469,
+ "1": 159.4075927734375
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 77
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": {
+ "0": 335,
+ "1": 476
+ },
+ "size": [
+ 252.056640625,
+ 262
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 72
+ ],
+ "slot_index": 0,
+ "shape": 3
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "00339.mp4",
+ "force_rate": 0,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 0,
+ "filename": "00339.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 101,
+ "type": "VideoToOpenpose",
+ "pos": {
+ "0": 719,
+ "1": 542
+ },
+ "size": {
+ "0": 315,
+ "1": 58
+ },
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "input_video",
+ "type": "IMAGE",
+ "link": 72
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 73,
+ 78
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VideoToOpenpose"
+ },
+ "widgets_values": [
+ 81
+ ]
+ },
+ {
+ "id": 99,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1067,
+ "1": 540
+ },
+ "size": [
+ 315,
+ 854.078125
+ ],
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 73,
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun-Preprocess-Video",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 19,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun-Preprocess-Video_00003.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1432,
+ "1": -135
+ },
+ "size": [
+ 390.9534912109375,
+ 966.9860514322917
+ ],
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 79,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00041.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 102,
+ "type": "WanFunV2VSampler",
+ "pos": {
+ "0": 890,
+ "1": -136
+ },
+ "size": [
+ 428.4000244140625,
+ 486
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 75
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 76
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 77
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": 78,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "ref_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": null,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 79
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1.0,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ },
+ {
+ "id": 95,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 275,
+ "1": -309
+ },
+ "size": {
+ "0": 435.2322082519531,
+ "1": 154
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 75
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-V1.1-1.3B-Control",
+ "Control",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 72,
+ 85,
+ 0,
+ 101,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 73,
+ 101,
+ 0,
+ 99,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 75,
+ 95,
+ 0,
+ 102,
+ 0,
+ "FunModels"
+ ],
+ [
+ 76,
+ 92,
+ 0,
+ 102,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 77,
+ 94,
+ 0,
+ 102,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 78,
+ 101,
+ 0,
+ 102,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 79,
+ 102,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Upload Your Video",
+ "bounding": [
+ 218,
+ 385,
+ 487,
+ 789
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load Model",
+ "bounding": [
+ 218,
+ -387,
+ 542,
+ 248
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650709,
+ "offset": [
+ 249.86519634240904,
+ 438.3739973625246
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "717f0629175ad192927dc51ec95c4376816a4212",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_pose_ref.json b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_pose_ref.json
new file mode 100644
index 0000000000000000000000000000000000000000..f080828c14e96e5496647d2e24c63cf7b2a12290
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_pose_ref.json
@@ -0,0 +1,742 @@
+{
+ "last_node_id": 103,
+ "last_link_id": 81,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": {
+ "0": -111.46612548828125,
+ "1": 460.2178955078125
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 88,
+ "type": "Note",
+ "pos": {
+ "0": -99,
+ "1": 197
+ },
+ "size": {
+ "0": 326.1556091308594,
+ "1": 145.20904541015625
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 89,
+ "type": "Note",
+ "pos": {
+ "0": -192,
+ "1": -293
+ },
+ "size": {
+ "0": 427.074951171875,
+ "1": 143.9142608642578
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 94,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 258,
+ "1": 178
+ },
+ "size": {
+ "0": 368.5529479980469,
+ "1": 159.4075927734375
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 78
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1488,
+ "1": 8
+ },
+ "size": [
+ 390.9534912109375,
+ 942.2558186848959
+ ],
+ "flags": {},
+ "order": 12,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 81,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00049.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 99,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1005,
+ "1": 554
+ },
+ "size": [
+ 315,
+ 849.46875
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 73,
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun-Preprocess-Video",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 19,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun-Preprocess-Video_00007.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 101,
+ "type": "VideoToOpenpose",
+ "pos": {
+ "0": 558,
+ "1": 474
+ },
+ "size": {
+ "0": 315,
+ "1": 58
+ },
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "input_video",
+ "type": "IMAGE",
+ "link": 72
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 73,
+ 79
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VideoToOpenpose"
+ },
+ "widgets_values": [
+ 81
+ ]
+ },
+ {
+ "id": 102,
+ "type": "LoadImage",
+ "pos": {
+ "0": 553,
+ "1": 598
+ },
+ "size": {
+ "0": 315,
+ "1": 314
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 80
+ ]
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "9.png",
+ "image"
+ ]
+ },
+ {
+ "id": 95,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 275,
+ "1": -309
+ },
+ "size": {
+ "0": 435.2322082519531,
+ "1": 154
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 76
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun1.1-1.3B-Control",
+ "Control",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 92,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 254,
+ "1": -46
+ },
+ "size": {
+ "0": 380.845703125,
+ "1": 157.68350219726562
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 77
+ ],
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "一位动漫风格的女孩。她有着紫色的短发,头上戴着一个黑色和金色相间的蝴蝶结。她的表情显得有些严肃或沉思,眼睛大而有神。女孩穿着一件白色衬衫,外面搭配了一件深蓝色的背心,背心上有一个粉色的蝴蝶结装饰。她的裙子是白色的,裙摆蓬松,整体造型非常可爱且精致。背景是一个简单的圆形图案,颜色为粉红色和灰色相间,给人一种柔和的感觉。整个画面色调柔和,人物形象生动鲜明。"
+ ]
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": {
+ "0": 207.79391479492188,
+ "1": 473.83123779296875
+ },
+ "size": [
+ 252.056640625,
+ 688.5451388888889
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 72
+ ],
+ "slot_index": 0,
+ "shape": 3
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "000007.mp4",
+ "force_rate": 16,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 16,
+ "filename": "000007.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 103,
+ "type": "WanFunV2VSampler",
+ "pos": {
+ "0": 996,
+ "1": 9
+ },
+ "size": [
+ 428.4000244140625,
+ 486
+ ],
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 76
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 77
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 78
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": 79,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "ref_image",
+ "type": "IMAGE",
+ "link": 80,
+ "shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": null,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 81
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1.0,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ }
+ ],
+ "links": [
+ [
+ 72,
+ 85,
+ 0,
+ 101,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 73,
+ 101,
+ 0,
+ 99,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 76,
+ 95,
+ 0,
+ 103,
+ 0,
+ "FunModels"
+ ],
+ [
+ 77,
+ 92,
+ 0,
+ 103,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 78,
+ 94,
+ 0,
+ 103,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 79,
+ 101,
+ 0,
+ 103,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 80,
+ 102,
+ 0,
+ 103,
+ 6,
+ "IMAGE"
+ ],
+ [
+ 81,
+ 103,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Upload Your Video And Reference Image",
+ "bounding": [
+ 91,
+ 383,
+ 859,
+ 841
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load Model",
+ "bounding": [
+ 218,
+ -387,
+ 542,
+ 248
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650709,
+ "offset": [
+ 246.99418774865902,
+ 428.7658411125245
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "717f0629175ad192927dc51ec95c4376816a4212",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "comfy-core": "v0.2.7-3-g8afb97c"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_ref.json b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_ref.json
new file mode 100644
index 0000000000000000000000000000000000000000..3b9e1e0c711086187519cec3b4645eb29e443866
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_ref.json
@@ -0,0 +1,614 @@
+{
+ "last_node_id": 98,
+ "last_link_id": 67,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": {
+ "0": 15.145149230957031,
+ "1": 527.0673217773438
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 88,
+ "type": "Note",
+ "pos": {
+ "0": -99,
+ "1": 197
+ },
+ "size": {
+ "0": 326.1556091308594,
+ "1": 145.20904541015625
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 89,
+ "type": "Note",
+ "pos": {
+ "0": -192,
+ "1": -293
+ },
+ "size": {
+ "0": 427.074951171875,
+ "1": 143.9142608642578
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": {
+ "0": 334.4051513671875,
+ "1": 540.6806640625
+ },
+ "size": [
+ 252.056640625,
+ 688.5451388888889
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 65
+ ],
+ "slot_index": 0,
+ "shape": 3
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "pose.mp4",
+ "force_rate": 0,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 0,
+ "filename": "pose.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 94,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 258,
+ "1": 178
+ },
+ "size": {
+ "0": 368.5529479980469,
+ "1": 159.4075927734375
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 64
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1274,
+ "1": -77
+ },
+ "size": [
+ 390.9534912109375,
+ 942.2558186848959
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 67,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00051.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 92,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 254,
+ "1": -46
+ },
+ "size": {
+ "0": 380.845703125,
+ "1": 157.68350219726562
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 63
+ ],
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "一位动漫风格的女孩。她有着紫色的短发,头上戴着一个黑色和金色相间的蝴蝶结。她的表情显得有些严肃或沉思,眼睛大而有神。女孩穿着一件白色衬衫,外面搭配了一件深蓝色的背心,背心上有一个粉色的蝴蝶结装饰。她的裙子是白色的,裙摆蓬松,整体造型非常可爱且精致。背景是一个简单的圆形图案,颜色为粉红色和灰色相间,给人一种柔和的感觉。整个画面色调柔和,人物形象生动鲜明。"
+ ]
+ },
+ {
+ "id": 97,
+ "type": "LoadImage",
+ "pos": {
+ "0": 629,
+ "1": 553
+ },
+ "size": {
+ "0": 315,
+ "1": 314
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 66
+ ]
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "9.png",
+ "image"
+ ]
+ },
+ {
+ "id": 95,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 275,
+ "1": -309
+ },
+ "size": {
+ "0": 435.2322082519531,
+ "1": 154
+ },
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 62
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-V1.1-1.3B-Control",
+ "Control",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 98,
+ "type": "WanFunV2VSampler",
+ "pos": {
+ "0": 798,
+ "1": -77
+ },
+ "size": [
+ 428.4000244140625,
+ 486
+ ],
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 62
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 63
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 64
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": 65,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "ref_image",
+ "type": "IMAGE",
+ "link": 66,
+ "shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": null,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 67
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1.0,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ }
+ ],
+ "links": [
+ [
+ 62,
+ 95,
+ 0,
+ 98,
+ 0,
+ "FunModels"
+ ],
+ [
+ 63,
+ 92,
+ 0,
+ 98,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 64,
+ 94,
+ 0,
+ 98,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 65,
+ 85,
+ 0,
+ 98,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 66,
+ 97,
+ 0,
+ 98,
+ 6,
+ "IMAGE"
+ ],
+ [
+ 67,
+ 98,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Upload Your Video",
+ "bounding": [
+ 217,
+ 450,
+ 761,
+ 789
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load Model",
+ "bounding": [
+ 218,
+ -387,
+ 542,
+ 248
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.8264462809917358,
+ "offset": [
+ 23.894387748659057,
+ 254.96144111252457
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "CogVideoX-Fun": "a7fa7028d52498f13e983eba012a81ebcae24977",
+ "comfy-core": "v0.2.7-3-g8afb97c"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_2/nodes.py b/VideoX-Fun/comfyui/wan2_2/nodes.py
new file mode 100644
index 0000000000000000000000000000000000000000..291e74410bf4a695df2d832bf0d3f23c05d2eadf
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_2/nodes.py
@@ -0,0 +1,709 @@
+"""Modified from https://github.com/kijai/ComfyUI-EasyAnimateWrapper/blob/main/nodes.py
+"""
+import copy
+import gc
+import json
+import os
+
+import comfy.model_management as mm
+import cv2
+import folder_paths
+import numpy as np
+import torch
+from comfy.utils import ProgressBar, load_torch_file
+from diffusers import FlowMatchEulerDiscreteScheduler
+from einops import rearrange
+from omegaconf import OmegaConf
+from PIL import Image
+
+from ...videox_fun.data.bucket_sampler import (ASPECT_RATIO_512,
+ get_closest_ratio)
+from ...videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8, AutoTokenizer, CLIPModel,
+ WanT5EncoderModel, Wan2_2Transformer3DModel)
+from ...videox_fun.pipeline import Wan2_2I2VPipeline, Wan2_2Pipeline, Wan2_2TI2VPipeline
+from ...videox_fun.ui.controller import all_cheduler_dict
+from ...videox_fun.utils.fp8_optimization import (
+ convert_model_weight_to_float8, convert_weight_dtype_wrapper, replace_parameters_by_name)
+from ...videox_fun.utils.lora_utils import merge_lora, unmerge_lora
+from ...videox_fun.utils.utils import (get_image_to_video_latent, filter_kwargs,
+ get_video_to_video_latent,
+ save_videos_grid)
+from ...videox_fun.models.cache_utils import get_teacache_coefficients
+from ..comfyui_utils import eas_cache_dir, script_directory, to_pil
+
+# Used in lora cache
+transformer_cpu_cache = {}
+transformer_high_cpu_cache = {}
+# lora path before
+lora_path_before = ""
+lora_high_path_before = ""
+
+def filter_kwargs(cls, kwargs):
+ import inspect
+ sig = inspect.signature(cls.__init__)
+ valid_params = set(sig.parameters.keys()) - {'self', 'cls'}
+ filtered_kwargs = {k: v for k, v in kwargs.items() if k in valid_params}
+ return filtered_kwargs
+
+class LoadWan2_2Model:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "model": (
+ [
+ 'Wan2.2-T2V-A14B',
+ 'Wan2.2-I2V-A14B',
+ 'Wan2.2-TI2V-5B',
+ ],
+ {
+ "default": 'Wan2.2-T2V-A14B',
+ }
+ ),
+ "GPU_memory_mode":(
+ ["model_full_load", "model_cpu_offload", "model_cpu_offload_and_qfloat8", "sequential_cpu_offload"],
+ {
+ "default": "model_cpu_offload",
+ }
+ ),
+ "config": (
+ [
+ "wan2.2/wan_civitai_t2v.yaml",
+ "wan2.2/wan_civitai_i2v.yaml",
+ "wan2.2/wan_civitai_5b.yaml",
+ ],
+ {
+ "default": "wan2.2/wan_civitai_t2v.yaml",
+ }
+ ),
+ "precision": (
+ ['fp16', 'bf16'],
+ {
+ "default": 'fp16'
+ }
+ ),
+ },
+ }
+
+ RETURN_TYPES = ("FunModels",)
+ RETURN_NAMES = ("funmodels",)
+ FUNCTION = "loadmodel"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def loadmodel(self, GPU_memory_mode, model, precision, config):
+ # Init weight_dtype and device
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+ weight_dtype = {"bf16": torch.bfloat16, "fp16": torch.float16, "fp32": torch.float32}[precision]
+
+ # Init processbar
+ pbar = ProgressBar(5)
+
+ # Load config
+ config_path = f"{script_directory}/config/{config}"
+ config = OmegaConf.load(config_path)
+
+ # Detect model is existing or not
+ possible_folders = ["CogVideoX_Fun", "Fun_Models", "VideoX_Fun"] + \
+ [os.path.join(os.path.dirname(os.path.dirname(os.path.dirname(os.path.abspath(__file__)))), "models/Diffusion_Transformer")] # Possible folder names to check
+ # Initialize model_name as None
+ model_name = None
+
+ # Check if the model exists in any of the possible folders within folder_paths.models_dir
+ for folder in possible_folders:
+ candidate_path = os.path.join(folder_paths.models_dir, folder, model)
+ if os.path.exists(candidate_path):
+ model_name = candidate_path
+ break
+
+ # If model_name is still None, check eas_cache_dir for each possible folder
+ if model_name is None and os.path.exists(eas_cache_dir):
+ for folder in possible_folders:
+ candidate_path = os.path.join(eas_cache_dir, folder, model)
+ if os.path.exists(candidate_path):
+ model_name = candidate_path
+ break
+
+ # If model_name is still None, prompt the user to download the model
+ if model_name is None:
+ print(f"Please download cogvideoxfun model to one of the following directories:")
+ for folder in possible_folders:
+ print(f"- {os.path.join(folder_paths.models_dir, folder)}")
+ if os.path.exists(eas_cache_dir):
+ print(f"- {os.path.join(eas_cache_dir, folder)}")
+ raise ValueError("Please download Fun model")
+
+ # Get Vae
+ Chosen_AutoencoderKL = {
+ "AutoencoderKLWan": AutoencoderKLWan,
+ "AutoencoderKLWan3_8": AutoencoderKLWan3_8
+ }[config['vae_kwargs'].get('vae_type', 'AutoencoderKLWan')]
+ vae = Chosen_AutoencoderKL.from_pretrained(
+ os.path.join(model_name, config['vae_kwargs'].get('vae_subpath', 'vae')),
+ additional_kwargs=OmegaConf.to_container(config['vae_kwargs']),
+ ).to(weight_dtype)
+ # Update pbar
+ pbar.update(1)
+
+ # Load Sampler
+ print("Load Sampler.")
+ scheduler = FlowMatchEulerDiscreteScheduler(
+ **filter_kwargs(FlowMatchEulerDiscreteScheduler, OmegaConf.to_container(config['scheduler_kwargs']))
+ )
+ # Update pbar
+ pbar.update(1)
+
+ # Get Transformer
+ transformer = Wan2_2Transformer3DModel.from_pretrained(
+ os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_low_noise_model_subpath', 'transformer')),
+ transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
+ low_cpu_mem_usage=True,
+ torch_dtype=weight_dtype,
+ )
+ if config['transformer_additional_kwargs'].get('transformer_combination_type', 'single') == "moe":
+ transformer_2 = Wan2_2Transformer3DModel.from_pretrained(
+ os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_high_noise_model_subpath', 'transformer')),
+ transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
+ low_cpu_mem_usage=True,
+ torch_dtype=weight_dtype,
+ )
+ else:
+ transformer_2 = None
+ # Update pbar
+ pbar.update(1)
+
+ # Get tokenizer and text_encoder
+ tokenizer = AutoTokenizer.from_pretrained(
+ os.path.join(model_name, config['text_encoder_kwargs'].get('tokenizer_subpath', 'tokenizer')),
+ )
+ pbar.update(1)
+
+ text_encoder = WanT5EncoderModel.from_pretrained(
+ os.path.join(model_name, config['text_encoder_kwargs'].get('text_encoder_subpath', 'text_encoder')),
+ additional_kwargs=OmegaConf.to_container(config['text_encoder_kwargs']),
+ low_cpu_mem_usage=True,
+ torch_dtype=weight_dtype,
+ )
+ pbar.update(1)
+
+ # Get pipeline
+ model_type = "Inpaint"
+ if model_type == "Inpaint":
+ if "wan_civitai_5b" in config_path:
+ pipeline = Wan2_2TI2VPipeline(
+ vae=vae,
+ tokenizer=tokenizer,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ transformer_2=transformer_2,
+ scheduler=scheduler,
+ )
+ else:
+ if transformer.config.in_channels != vae.config.latent_channels:
+ pipeline = Wan2_2I2VPipeline(
+ transformer=transformer,
+ transformer_2=transformer_2,
+ vae=vae,
+ tokenizer=tokenizer,
+ text_encoder=text_encoder,
+ scheduler=scheduler,
+ )
+ else:
+ pipeline = Wan2_2Pipeline(
+ transformer=transformer,
+ transformer_2=transformer_2,
+ vae=vae,
+ tokenizer=tokenizer,
+ text_encoder=text_encoder,
+ scheduler=scheduler,
+ )
+ else:
+ raise ValueError(f"Model type {model_type} not supported")
+
+ if GPU_memory_mode == "sequential_cpu_offload":
+ replace_parameters_by_name(transformer, ["modulation",], device=device)
+ transformer.freqs = transformer.freqs.to(device=device)
+ if transformer_2 is not None:
+ replace_parameters_by_name(transformer_2, ["modulation",], device=device)
+ transformer_2.freqs = transformer_2.freqs.to(device=device)
+ pipeline.enable_sequential_cpu_offload(device=device)
+ elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
+ convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
+ convert_weight_dtype_wrapper(transformer, weight_dtype)
+ if transformer_2 is not None:
+ convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
+ convert_weight_dtype_wrapper(transformer_2, weight_dtype)
+ pipeline.enable_model_cpu_offload(device=device)
+ elif GPU_memory_mode == "model_cpu_offload":
+ pipeline.enable_model_cpu_offload(device=device)
+ elif GPU_memory_mode == "model_full_load_and_qfloat8":
+ convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
+ convert_weight_dtype_wrapper(transformer, weight_dtype)
+ if transformer_2 is not None:
+ convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
+ convert_weight_dtype_wrapper(transformer_2, weight_dtype)
+ pipeline.to(device=device)
+ else:
+ pipeline.to(device=device)
+
+ funmodels = {
+ 'pipeline': pipeline,
+ 'dtype': weight_dtype,
+ 'model_name': model_name,
+ 'model_type': model_type,
+ 'loras': [],
+ 'strength_model': [],
+ 'config': config,
+ }
+ return (funmodels,)
+
+class LoadWan2_2Lora:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "funmodels": ("FunModels",),
+ "lora_name": (folder_paths.get_filename_list("loras"), {"default": None,}),
+ "lora_high_name": (folder_paths.get_filename_list("loras"), {"default": None,}),
+ "strength_model": ("FLOAT", {"default": 1.0, "min": -100.0, "max": 100.0, "step": 0.01}),
+ "lora_cache":([False, True], {"default": False,}),
+ }
+ }
+ RETURN_TYPES = ("FunModels",)
+ RETURN_NAMES = ("funmodels",)
+ FUNCTION = "load_lora"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def load_lora(self, funmodels, lora_name, lora_high_name, strength_model, lora_cache):
+ if lora_name is not None:
+ funmodels['lora_cache'] = lora_cache
+ funmodels['loras'] = funmodels.get("loras", []) + [folder_paths.get_full_path("loras", lora_name)]
+ funmodels['loras_high'] = funmodels.get("loras_high", []) + [folder_paths.get_full_path("loras", lora_high_name)]
+ funmodels['strength_model'] = funmodels.get("strength_model", []) + [strength_model]
+ return (funmodels,)
+ else:
+ return (funmodels,)
+
+class Wan2_2T2VSampler:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "funmodels": (
+ "FunModels",
+ ),
+ "prompt": (
+ "STRING_PROMPT",
+ ),
+ "negative_prompt": (
+ "STRING_PROMPT",
+ ),
+ "video_length": (
+ "INT", {"default": 81, "min": 5, "max": 161, "step": 4}
+ ),
+ "width": (
+ "INT", {"default": 832, "min": 64, "max": 2048, "step": 16}
+ ),
+ "height": (
+ "INT", {"default": 480, "min": 64, "max": 2048, "step": 16}
+ ),
+ "is_image":(
+ [
+ False,
+ True
+ ],
+ {
+ "default": False,
+ }
+ ),
+ "seed": (
+ "INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
+ ),
+ "steps": (
+ "INT", {"default": 50, "min": 1, "max": 200, "step": 1}
+ ),
+ "cfg": (
+ "FLOAT", {"default": 6.0, "min": 1.0, "max": 20.0, "step": 0.01}
+ ),
+ "scheduler": (
+ [
+ "Flow",
+ ],
+ {
+ "default": 'Flow'
+ }
+ ),
+ "teacache_threshold": (
+ "FLOAT", {"default": 0.10, "min": 0.00, "max": 1.00, "step": 0.005}
+ ),
+ "enable_teacache":(
+ [False, True], {"default": True,}
+ ),
+ "num_skip_start_steps": (
+ "INT", {"default": 5, "min": 0, "max": 50, "step": 1}
+ ),
+ "teacache_offload":(
+ [False, True], {"default": True,}
+ ),
+ "cfg_skip_ratio":(
+ "FLOAT", {"default": 0, "min": 0, "max": 1, "step": 0.01}
+ ),
+ },
+ "optional":{
+ "riflex_k": ("RIFLEXT_ARGS",),
+ },
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES =("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, funmodels, prompt, negative_prompt, video_length, width, height, is_image, seed, steps, cfg, scheduler, teacache_threshold, enable_teacache, num_skip_start_steps, teacache_offload, cfg_skip_ratio, riflex_k=0):
+ global transformer_cpu_cache
+ global transformer_high_cpu_cache
+ global lora_path_before
+ global lora_high_path_before
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+
+ mm.soft_empty_cache()
+ gc.collect()
+
+ # Get Pipeline
+ pipeline = funmodels['pipeline']
+ model_name = funmodels['model_name']
+ config = funmodels['config']
+ weight_dtype = funmodels['dtype']
+
+ # Get boundary for wan
+ boundary = config['transformer_additional_kwargs'].get('boundary', 0.900)
+
+ # Load Sampler
+ pipeline.scheduler = all_cheduler_dict[scheduler](**filter_kwargs(all_cheduler_dict[scheduler], OmegaConf.to_container(config['scheduler_kwargs'])))
+
+ coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
+ if coefficients is not None:
+ print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
+ pipeline.transformer.enable_teacache(
+ coefficients, steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
+ )
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.share_teacache(transformer=pipeline.transformer)
+ else:
+ pipeline.transformer.disable_teacache()
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.disable_teacache()
+
+ if cfg_skip_ratio is not None:
+ print(f"Enable cfg_skip_ratio {cfg_skip_ratio}.")
+ pipeline.transformer.enable_cfg_skip(cfg_skip_ratio, steps)
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.share_cfg_skip(transformer=pipeline.transformer)
+
+ generator= torch.Generator(device).manual_seed(seed)
+
+ video_length = 1 if is_image else video_length
+ with torch.no_grad():
+ video_length = int((video_length - 1) // pipeline.vae.config.temporal_compression_ratio * pipeline.vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+
+ if riflex_k > 0:
+ latent_frames = (video_length - 1) // pipeline.vae.config.temporal_compression_ratio + 1
+ pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.enable_riflex(k = riflex_k, L_test = latent_frames)
+
+ # Apply lora
+ if funmodels.get("lora_cache", False):
+ if len(funmodels.get("loras", [])) != 0:
+ # Save the original weights to cpu
+ if len(transformer_cpu_cache) == 0:
+ print('Save transformer state_dict to cpu memory')
+ transformer_state_dict = pipeline.transformer.state_dict()
+ for key in transformer_state_dict:
+ transformer_cpu_cache[key] = transformer_state_dict[key].clone().cpu()
+
+ lora_path_now = str(funmodels.get("loras", []) + funmodels.get("strength_model", []))
+ if lora_path_now != lora_path_before:
+ print('Merge Lora with Cache')
+ lora_path_before = copy.deepcopy(lora_path_now)
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ if pipeline.transformer_2 is not None:
+ # Save the original weights to cpu
+ if len(transformer_high_cpu_cache) == 0:
+ print('Save transformer high state_dict to cpu memory')
+ transformer_high_state_dict = pipeline.transformer_2.state_dict()
+ for key in transformer_high_state_dict:
+ transformer_high_cpu_cache[key] = transformer_high_state_dict[key].clone().cpu()
+
+ lora_high_path_now = str(funmodels.get("loras_high", []) + funmodels.get("strength_model", []))
+ if lora_high_path_now != lora_high_path_before:
+ print('Merge Lora High with Cache')
+ lora_high_path_before = copy.deepcopy(lora_high_path_now)
+ pipeline.transformer_2.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(funmodels.get("loras_high", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype, sub_transformer_name="transformer_2")
+ else:
+ print('Merge Lora')
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if len(transformer_cpu_cache) != 0:
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ transformer_cpu_cache = {}
+ lora_path_before = ""
+ gc.collect()
+
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if pipeline.transformer_2 is not None:
+ if len(transformer_high_cpu_cache) != 0:
+ pipeline.transformer_2.load_state_dict(transformer_high_cpu_cache)
+ transformer_high_cpu_cache = {}
+ lora_high_path_before = ""
+ gc.collect()
+
+ for _lora_path, _lora_weight in zip(funmodels.get("loras_high", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype, sub_transformer_name="transformer_2")
+
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+ boundary = boundary,
+ comfyui_progressbar = True,
+ ).videos
+ videos = rearrange(sample, "b c t h w -> (b t) h w c")
+
+ if not funmodels.get("lora_cache", False):
+ print('Unmerge Lora')
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ if pipeline.transformer_2 is not None:
+ for _lora_path, _lora_weight in zip(funmodels.get("loras_high", []), funmodels.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype, sub_transformer_name="transformer_2")
+ return (videos,)
+
+
+class Wan2_2I2VSampler:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "funmodels": (
+ "FunModels",
+ ),
+ "prompt": (
+ "STRING_PROMPT",
+ ),
+ "negative_prompt": (
+ "STRING_PROMPT",
+ ),
+ "video_length": (
+ "INT", {"default": 81, "min": 5, "max": 161, "step": 4}
+ ),
+ "base_resolution": (
+ [
+ 512,
+ 640,
+ 768,
+ 896,
+ 960,
+ 1024,
+ ], {"default": 640}
+ ),
+ "seed": (
+ "INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
+ ),
+ "steps": (
+ "INT", {"default": 50, "min": 1, "max": 200, "step": 1}
+ ),
+ "cfg": (
+ "FLOAT", {"default": 6.0, "min": 1.0, "max": 20.0, "step": 0.01}
+ ),
+ "scheduler": (
+ [
+ "Flow",
+ ],
+ {
+ "default": 'Flow'
+ }
+ ),
+ "teacache_threshold": (
+ "FLOAT", {"default": 0.10, "min": 0.00, "max": 1.00, "step": 0.005}
+ ),
+ "enable_teacache":(
+ [False, True], {"default": True,}
+ ),
+ "num_skip_start_steps": (
+ "INT", {"default": 5, "min": 0, "max": 50, "step": 1}
+ ),
+ "teacache_offload":(
+ [False, True], {"default": True,}
+ ),
+ "cfg_skip_ratio":(
+ "FLOAT", {"default": 0, "min": 0, "max": 1, "step": 0.01}
+ ),
+ },
+ "optional":{
+ "start_img": ("IMAGE",),
+ "riflex_k": ("RIFLEXT_ARGS",),
+ },
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES =("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, funmodels, prompt, negative_prompt, video_length, base_resolution, seed, steps, cfg, scheduler, teacache_threshold, enable_teacache, num_skip_start_steps, teacache_offload, cfg_skip_ratio, start_img=None, end_img=None, riflex_k=0):
+ global transformer_cpu_cache
+ global transformer_high_cpu_cache
+ global lora_path_before
+ global lora_high_path_before
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+
+ mm.soft_empty_cache()
+ gc.collect()
+
+ # Get Pipeline
+ pipeline = funmodels['pipeline']
+ model_name = funmodels['model_name']
+ config = funmodels['config']
+ weight_dtype = funmodels['dtype']
+
+ start_img = [to_pil(_start_img) for _start_img in start_img] if start_img is not None else None
+ end_img = [to_pil(_end_img) for _end_img in end_img] if end_img is not None else None
+ # Count most suitable height and width
+ spatial_compression_ratio = pipeline.vae.config.spatial_compression_ratio if hasattr(pipeline.vae.config, "spatial_compression_ratio") else 8
+ aspect_ratio_sample_size = {key : [x / 512 * base_resolution for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+ original_width, original_height = start_img[0].size if type(start_img) is list else Image.open(start_img).size
+ closest_size, closest_ratio = get_closest_ratio(original_height, original_width, ratios=aspect_ratio_sample_size)
+ height, width = [int(x / spatial_compression_ratio / 2) * spatial_compression_ratio * 2 for x in closest_size]
+
+ # Get boundary for wan
+ boundary = config['transformer_additional_kwargs'].get('boundary', 0.900)
+
+ # Load Sampler
+ pipeline.scheduler = all_cheduler_dict[scheduler](**filter_kwargs(all_cheduler_dict[scheduler], OmegaConf.to_container(config['scheduler_kwargs'])))
+ coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
+ if coefficients is not None:
+ print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
+ pipeline.transformer.enable_teacache(
+ coefficients, steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
+ )
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.share_teacache(transformer=pipeline.transformer)
+ else:
+ pipeline.transformer.disable_teacache()
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.disable_teacache()
+
+ if cfg_skip_ratio is not None:
+ print(f"Enable cfg_skip_ratio {cfg_skip_ratio}.")
+ pipeline.transformer.enable_cfg_skip(cfg_skip_ratio, steps)
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.share_cfg_skip(transformer=pipeline.transformer)
+
+ generator= torch.Generator(device).manual_seed(seed)
+
+ with torch.no_grad():
+ video_length = int((video_length - 1) // pipeline.vae.config.temporal_compression_ratio * pipeline.vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(start_img, end_img, video_length=video_length, sample_size=(height, width))
+
+ if riflex_k > 0:
+ latent_frames = (video_length - 1) // pipeline.vae.config.temporal_compression_ratio + 1
+ pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.enable_riflex(k = riflex_k, L_test = latent_frames)
+
+ # Apply lora
+ if funmodels.get("lora_cache", False):
+ if len(funmodels.get("loras", [])) != 0:
+ # Save the original weights to cpu
+ if len(transformer_cpu_cache) == 0:
+ print('Save transformer state_dict to cpu memory')
+ transformer_state_dict = pipeline.transformer.state_dict()
+ for key in transformer_state_dict:
+ transformer_cpu_cache[key] = transformer_state_dict[key].clone().cpu()
+
+ lora_path_now = str(funmodels.get("loras", []) + funmodels.get("strength_model", []))
+ if lora_path_now != lora_path_before:
+ print('Merge Lora with Cache')
+ lora_path_before = copy.deepcopy(lora_path_now)
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ if pipeline.transformer_2 is not None:
+ # Save the original weights to cpu
+ if len(transformer_high_cpu_cache) == 0:
+ print('Save transformer high state_dict to cpu memory')
+ transformer_high_state_dict = pipeline.transformer_2.state_dict()
+ for key in transformer_high_state_dict:
+ transformer_high_cpu_cache[key] = transformer_high_state_dict[key].clone().cpu()
+
+ lora_high_path_now = str(funmodels.get("loras_high", []) + funmodels.get("strength_model", []))
+ if lora_high_path_now != lora_high_path_before:
+ print('Merge Lora High with Cache')
+ lora_high_path_before = copy.deepcopy(lora_high_path_now)
+ pipeline.transformer_2.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(funmodels.get("loras_high", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype, sub_transformer_name="transformer_2")
+ else:
+ print('Merge Lora')
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if len(transformer_cpu_cache) != 0:
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ transformer_cpu_cache = {}
+ lora_path_before = ""
+ gc.collect()
+
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if pipeline.transformer_2 is not None:
+ if len(transformer_high_cpu_cache) != 0:
+ pipeline.transformer_2.load_state_dict(transformer_high_cpu_cache)
+ transformer_high_cpu_cache = {}
+ lora_high_path_before = ""
+ gc.collect()
+
+ for _lora_path, _lora_weight in zip(funmodels.get("loras_high", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype, sub_transformer_name="transformer_2")
+
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ boundary = boundary,
+ comfyui_progressbar = True,
+ ).videos
+ videos = rearrange(sample, "b c t h w -> (b t) h w c")
+
+ if not funmodels.get("lora_cache", False):
+ print('Unmerge Lora')
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ if pipeline.transformer_2 is not None:
+ for _lora_path, _lora_weight in zip(funmodels.get("loras_high", []), funmodels.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype, sub_transformer_name="transformer_2")
+ return (videos,)
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_2/v1/wan2.2_workflow_i2v.json b/VideoX-Fun/comfyui/wan2_2/v1/wan2.2_workflow_i2v.json
new file mode 100644
index 0000000000000000000000000000000000000000..daa231f8ba9b36e12139bef6f827c02e7408f638
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_2/v1/wan2.2_workflow_i2v.json
@@ -0,0 +1,473 @@
+{
+ "id": "ca87b2cd-bd4a-4f31-82ec-e5e028f8848c",
+ "revision": 0,
+ "last_node_id": 101,
+ "last_link_id": 70,
+ "nodes": [
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ -50
+ ],
+ "size": [
+ 383.54010009765625,
+ 156.71620178222656
+ ],
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 68
+ ]
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 87,
+ "type": "LoadImage",
+ "pos": [
+ 306,
+ 495
+ ],
+ "size": [
+ 315,
+ 314
+ ],
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 66
+ ]
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "6.png",
+ "image"
+ ]
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 95,
+ "type": "Note",
+ "pos": [
+ 34,
+ 550
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload image here\n(你可以在此上传图片)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ 160
+ ],
+ "size": [
+ 383.7149963378906,
+ 183.83506774902344
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 69
+ ]
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": [
+ -75,
+ -297
+ ],
+ "size": [
+ 350.7127990722656,
+ 125.54820251464844
+ ],
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1277,
+ -70
+ ],
+ "size": [
+ 390,
+ 537.4615478515625
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "label": "图像",
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 70
+ },
+ {
+ "label": "音频",
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "label": "批次管理",
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "label": "文件名",
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "slot_index": 0,
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00008.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 101,
+ "type": "Wan2_2I2VSampler",
+ "pos": [
+ 819.5313110351562,
+ -63.450443267822266
+ ],
+ "size": [
+ 325.5747985839844,
+ 402
+ ],
+ "flags": {
+ "pinned": true
+ },
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 67
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 68
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 69
+ },
+ {
+ "name": "start_img",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 66
+ },
+ {
+ "name": "riflex_k",
+ "shape": 7,
+ "type": "RIFLEXT_ARGS",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 70
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "Wan2_2I2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 43,
+ 6,
+ "Flow",
+ 0.15000000000000002,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ },
+ {
+ "id": 99,
+ "type": "LoadWan2_2Model",
+ "pos": [
+ 347.27996826171875,
+ -299.0150146484375
+ ],
+ "size": [
+ 276.705078125,
+ 130
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 67
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWan2_2Model"
+ },
+ "widgets_values": [
+ "Wan2.2-I2V-A14B",
+ "sequential_cpu_offload",
+ "wan2.2/wan_civitai_i2v.yaml",
+ "bf16"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 66,
+ 87,
+ 0,
+ 101,
+ 3,
+ "IMAGE"
+ ],
+ [
+ 67,
+ 99,
+ 0,
+ 101,
+ 0,
+ "FunModels"
+ ],
+ [
+ 68,
+ 75,
+ 0,
+ 101,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 69,
+ 73,
+ 0,
+ 101,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 70,
+ 101,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "id": 1,
+ "title": "Load Model",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 2,
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 3,
+ "title": "Group",
+ "bounding": [
+ 220,
+ 409,
+ 458,
+ 436
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650705,
+ "offset": [
+ 272.66873113564736,
+ 429.81230900451357
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "ffe64f2b8c101da85e0707c59b355f21a83f5464",
+ "comfy-core": "0.3.44",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
+ },
+ "frontendVersion": "1.21.3"
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_2/v1/wan2.2_workflow_i2v_5b.json b/VideoX-Fun/comfyui/wan2_2/v1/wan2.2_workflow_i2v_5b.json
new file mode 100644
index 0000000000000000000000000000000000000000..661c7eacee6553ff81910e85b23a393072ed7dc9
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_2/v1/wan2.2_workflow_i2v_5b.json
@@ -0,0 +1,471 @@
+{
+ "id": "ca87b2cd-bd4a-4f31-82ec-e5e028f8848c",
+ "revision": 0,
+ "last_node_id": 103,
+ "last_link_id": 80,
+ "nodes": [
+ {
+ "id": 87,
+ "type": "LoadImage",
+ "pos": [
+ 306,
+ 495
+ ],
+ "size": [
+ 315,
+ 314
+ ],
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 79
+ ]
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "6.png",
+ "image"
+ ]
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 95,
+ "type": "Note",
+ "pos": [
+ 34,
+ 550
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload image here\n(你可以在此上传图片)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ 160
+ ],
+ "size": [
+ 383.7149963378906,
+ 183.83506774902344
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 78
+ ]
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": [
+ -75,
+ -297
+ ],
+ "size": [
+ 350.7127990722656,
+ 125.54820251464844
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1277,
+ -70
+ ],
+ "size": [
+ 390,
+ 577.7142944335938
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "label": "图像",
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 80
+ },
+ {
+ "label": "音频",
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "label": "批次管理",
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "label": "文件名",
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "slot_index": 0,
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00107.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 99,
+ "type": "LoadWan2_2Model",
+ "pos": [
+ 347.27996826171875,
+ -299.0150146484375
+ ],
+ "size": [
+ 276.705078125,
+ 130
+ ],
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 76
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWan2_2Model"
+ },
+ "widgets_values": [
+ "Wan2.2-TI2V-5B",
+ "sequential_cpu_offload",
+ "wan2.2/wan_civitai_5b.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 103,
+ "type": "Wan2_2I2VSampler",
+ "pos": [
+ 819.5313110351562,
+ -63.450443267822266
+ ],
+ "size": [
+ 325.5747985839844,
+ 402
+ ],
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 76
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 77
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 78
+ },
+ {
+ "name": "start_img",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 79
+ },
+ {
+ "name": "riflex_k",
+ "shape": 7,
+ "type": "RIFLEXT_ARGS",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 80
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "Wan2_2I2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 960,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ },
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ -50
+ ],
+ "size": [
+ 383.54010009765625,
+ 156.71620178222656
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 77
+ ]
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ }
+ ],
+ "links": [
+ [
+ 76,
+ 99,
+ 0,
+ 103,
+ 0,
+ "FunModels"
+ ],
+ [
+ 77,
+ 75,
+ 0,
+ 103,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 78,
+ 73,
+ 0,
+ 103,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 79,
+ 87,
+ 0,
+ 103,
+ 3,
+ "IMAGE"
+ ],
+ [
+ 80,
+ 103,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "id": 1,
+ "title": "Load Model",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 2,
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 3,
+ "title": "Group",
+ "bounding": [
+ 220,
+ 409,
+ 458,
+ 436
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650705,
+ "offset": [
+ 282.91743113564746,
+ 433.6498523638886
+ ]
+ },
+ "frontendVersion": "1.21.3",
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "comfy-core": "0.3.44",
+ "CogVideoX-Fun": "5f2a55692d0834e00d477939b818b9bb63c06535",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_2/v1/wan2.2_workflow_t2v.json b/VideoX-Fun/comfyui/wan2_2/v1/wan2.2_workflow_t2v.json
new file mode 100644
index 0000000000000000000000000000000000000000..8a19bdf5eb404928278f4c78ef4bf053a972da97
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_2/v1/wan2.2_workflow_t2v.json
@@ -0,0 +1,383 @@
+{
+ "id": "f52daf1e-5f66-4c8b-9f68-890324faf01e",
+ "revision": 0,
+ "last_node_id": 87,
+ "last_link_id": 57,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ -50
+ ],
+ "size": [
+ 383.54010009765625,
+ 156.71620178222656
+ ],
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 55
+ ]
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1126,
+ -73
+ ],
+ "size": [
+ 390.9534912109375,
+ 538.0116577148438
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [
+ {
+ "label": "图像",
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 54
+ },
+ {
+ "label": "音频",
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "label": "批次管理",
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "label": "文件名",
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "slot_index": 0,
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00008.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ 160
+ ],
+ "size": [
+ 383.7149963378906,
+ 183.83506774902344
+ ],
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 56
+ ]
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 87,
+ "type": "LoadWan2_2Model",
+ "pos": [
+ 305.3617858886719,
+ -300.4237060546875
+ ],
+ "size": [
+ 276.705078125,
+ 130
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 57
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWan2_2Model"
+ },
+ "widgets_values": [
+ "Wan2.2-T2V-A14B",
+ "sequential_cpu_offload",
+ "wan2.2/wan_civitai_t2v.yaml",
+ "fp16"
+ ]
+ },
+ {
+ "id": 86,
+ "type": "Wan2_2T2VSampler",
+ "pos": [
+ 746.95556640625,
+ -69.9979248046875
+ ],
+ "size": [
+ 312.3404235839844,
+ 430
+ ],
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 57
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 55
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 56
+ },
+ {
+ "name": "riflex_k",
+ "shape": 7,
+ "type": "RIFLEXT_ARGS",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 54
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "Wan2_2T2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 832,
+ 480,
+ false,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ "Flow",
+ 0.15000000000000002,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ },
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": [
+ -92,
+ -294
+ ],
+ "size": [
+ 351.1499938964844,
+ 130.12660217285156
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ }
+ ],
+ "links": [
+ [
+ 54,
+ 86,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 55,
+ 75,
+ 0,
+ 86,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 56,
+ 73,
+ 0,
+ 86,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 57,
+ 87,
+ 0,
+ 86,
+ 0,
+ "FunModels"
+ ]
+ ],
+ "groups": [
+ {
+ "id": 1,
+ "title": "Load Model",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 2,
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.9090909090909091,
+ "offset": [
+ 149.60461329280074,
+ 495.60652716079886
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "ffe64f2b8c101da85e0707c59b355f21a83f5464",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
+ },
+ "frontendVersion": "1.21.3"
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_2/v1/wan2.2_workflow_t2v_5b.json b/VideoX-Fun/comfyui/wan2_2/v1/wan2.2_workflow_t2v_5b.json
new file mode 100644
index 0000000000000000000000000000000000000000..f1ff90bdce008ddca39c393e09d48bd9addaec92
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_2/v1/wan2.2_workflow_t2v_5b.json
@@ -0,0 +1,383 @@
+{
+ "id": "ca87b2cd-bd4a-4f31-82ec-e5e028f8848c",
+ "revision": 0,
+ "last_node_id": 105,
+ "last_link_id": 84,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ 160
+ ],
+ "size": [
+ 383.7149963378906,
+ 183.83506774902344
+ ],
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 83
+ ]
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": [
+ -75,
+ -297
+ ],
+ "size": [
+ 350.7127990722656,
+ 125.54820251464844
+ ],
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ -50
+ ],
+ "size": [
+ 383.54010009765625,
+ 156.71620178222656
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 82
+ ]
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 99,
+ "type": "LoadWan2_2Model",
+ "pos": [
+ 347.27996826171875,
+ -299.0150146484375
+ ],
+ "size": [
+ 276.705078125,
+ 130
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 81
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWan2_2Model"
+ },
+ "widgets_values": [
+ "Wan2.2-TI2V-5B",
+ "sequential_cpu_offload",
+ "wan2.2/wan_civitai_5b.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1277,
+ -70
+ ],
+ "size": [
+ 390,
+ 577.7142944335938
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [
+ {
+ "label": "图像",
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 84
+ },
+ {
+ "label": "音频",
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "label": "批次管理",
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "label": "文件名",
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "slot_index": 0,
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00108.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 105,
+ "type": "Wan2_2FunT2VSampler",
+ "pos": [
+ 827.6821899414062,
+ -69.17436981201172
+ ],
+ "size": [
+ 340.3540954589844,
+ 430
+ ],
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 81
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 82
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 83
+ },
+ {
+ "name": "riflex_k",
+ "shape": 7,
+ "type": "RIFLEXT_ARGS",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 84
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "Wan2_2FunT2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 1280,
+ 704,
+ false,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ }
+ ],
+ "links": [
+ [
+ 81,
+ 99,
+ 0,
+ 105,
+ 0,
+ "FunModels"
+ ],
+ [
+ 82,
+ 75,
+ 0,
+ 105,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 83,
+ 73,
+ 0,
+ 105,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 84,
+ 105,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "id": 1,
+ "title": "Load Model",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 2,
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650705,
+ "offset": [
+ 313.88657762002225,
+ 431.4308258013887
+ ]
+ },
+ "frontendVersion": "1.21.3",
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "5f2a55692d0834e00d477939b818b9bb63c06535",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_2_fun/nodes.py b/VideoX-Fun/comfyui/wan2_2_fun/nodes.py
new file mode 100644
index 0000000000000000000000000000000000000000..9b36ccfc4b38ee57d3adfa76623d69c21a7f3af2
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_2_fun/nodes.py
@@ -0,0 +1,1006 @@
+"""Modified from https://github.com/kijai/ComfyUI-EasyAnimateWrapper/blob/main/nodes.py
+"""
+import copy
+import gc
+import json
+import os
+
+import comfy.model_management as mm
+import cv2
+import folder_paths
+import numpy as np
+import torch
+from comfy.utils import ProgressBar, load_torch_file
+from diffusers import FlowMatchEulerDiscreteScheduler
+from einops import rearrange
+from omegaconf import OmegaConf
+from PIL import Image
+
+from ...videox_fun.data.bucket_sampler import (ASPECT_RATIO_512,
+ get_closest_ratio)
+from ...videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8, AutoTokenizer, CLIPModel,
+ WanT5EncoderModel, Wan2_2Transformer3DModel)
+from ...videox_fun.pipeline import Wan2_2FunInpaintPipeline, Wan2_2FunPipeline, Wan2_2FunControlPipeline
+from ...videox_fun.ui.controller import all_cheduler_dict
+from ...videox_fun.utils.fp8_optimization import (
+ convert_model_weight_to_float8, convert_weight_dtype_wrapper, replace_parameters_by_name)
+from ...videox_fun.utils.lora_utils import merge_lora, unmerge_lora
+from ...videox_fun.utils.utils import (get_image_to_video_latent, filter_kwargs, get_image_latent,
+ get_video_to_video_latent,
+ save_videos_grid)
+from ...videox_fun.models.cache_utils import get_teacache_coefficients
+from ...videox_fun.data.dataset_image_video import process_pose_params
+from ..comfyui_utils import eas_cache_dir, script_directory, to_pil
+
+# Used in lora cache
+transformer_cpu_cache = {}
+transformer_high_cpu_cache = {}
+# lora path before
+lora_path_before = ""
+lora_high_path_before = ""
+
+class LoadWan2_2FunModel:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "model": (
+ [
+ 'Wan2.2-Fun-A14B-InP',
+ 'Wan2.2-Fun-A14B-Control',
+ 'Wan2.2-Fun-A14B-Control-Camera',
+ 'Wan2.2-Fun-5B-InP',
+ 'Wan2.2-Fun-5B-Control',
+ 'Wan2.2-Fun-5B-Control-Camera',
+ ],
+ {
+ "default": 'Wan2.2-Fun-A14B-InP',
+ }
+ ),
+ "model_type": (
+ ["Inpaint", "Control"],
+ {
+ "default": "Inpaint",
+ }
+ ),
+ "GPU_memory_mode":(
+ ["model_full_load", "model_cpu_offload", "model_cpu_offload_and_qfloat8", "sequential_cpu_offload"],
+ {
+ "default": "model_cpu_offload",
+ }
+ ),
+ "config": (
+ [
+ "wan2.2/wan_civitai_i2v.yaml",
+ "wan2.2/wan_civitai_5b.yaml",
+ ],
+ {
+ "default": "wan2.2/wan_civitai_i2v.yaml",
+ }
+ ),
+ "precision": (
+ ['fp16', 'bf16'],
+ {
+ "default": 'fp16'
+ }
+ ),
+ },
+ }
+ RETURN_TYPES = ("FunModels",)
+ RETURN_NAMES = ("funmodels",)
+ FUNCTION = "loadmodel"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def loadmodel(self, GPU_memory_mode, model_type, model, precision, config):
+ # Init weight_dtype and device
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+ weight_dtype = {"bf16": torch.bfloat16, "fp16": torch.float16, "fp32": torch.float32}[precision]
+
+ # Init processbar
+ pbar = ProgressBar(5)
+
+ # Load config
+ config_path = f"{script_directory}/config/{config}"
+ config = OmegaConf.load(config_path)
+
+ # Detect model is existing or not
+ possible_folders = ["CogVideoX_Fun", "Fun_Models", "VideoX_Fun"] + \
+ [os.path.join(os.path.dirname(os.path.dirname(os.path.dirname(os.path.abspath(__file__)))), "models/Diffusion_Transformer")] # Possible folder names to check
+ # Initialize model_name as None
+ model_name = None
+
+ # Check if the model exists in any of the possible folders within folder_paths.models_dir
+ for folder in possible_folders:
+ candidate_path = os.path.join(folder_paths.models_dir, folder, model)
+ if os.path.exists(candidate_path):
+ model_name = candidate_path
+ break
+
+ # If model_name is still None, check eas_cache_dir for each possible folder
+ if model_name is None and os.path.exists(eas_cache_dir):
+ for folder in possible_folders:
+ candidate_path = os.path.join(eas_cache_dir, folder, model)
+ if os.path.exists(candidate_path):
+ model_name = candidate_path
+ break
+
+ # If model_name is still None, prompt the user to download the model
+ if model_name is None:
+ print(f"Please download cogvideoxfun model to one of the following directories:")
+ for folder in possible_folders:
+ print(f"- {os.path.join(folder_paths.models_dir, folder)}")
+ if os.path.exists(eas_cache_dir):
+ print(f"- {os.path.join(eas_cache_dir, folder)}")
+ raise ValueError("Please download Fun model")
+
+ Chosen_AutoencoderKL = {
+ "AutoencoderKLWan": AutoencoderKLWan,
+ "AutoencoderKLWan3_8": AutoencoderKLWan3_8
+ }[config['vae_kwargs'].get('vae_type', 'AutoencoderKLWan')]
+ vae = Chosen_AutoencoderKL.from_pretrained(
+ os.path.join(model_name, config['vae_kwargs'].get('vae_subpath', 'vae')),
+ additional_kwargs=OmegaConf.to_container(config['vae_kwargs']),
+ ).to(weight_dtype)
+ # Update pbar
+ pbar.update(1)
+
+ # Load Sampler
+ print("Load Sampler.")
+ scheduler = FlowMatchEulerDiscreteScheduler(
+ **filter_kwargs(FlowMatchEulerDiscreteScheduler, OmegaConf.to_container(config['scheduler_kwargs']))
+ )
+ # Update pbar
+ pbar.update(1)
+
+ # Get Transformer
+ transformer = Wan2_2Transformer3DModel.from_pretrained(
+ os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_low_noise_model_subpath', 'transformer')),
+ transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
+ low_cpu_mem_usage=True,
+ torch_dtype=weight_dtype,
+ )
+
+ if config['transformer_additional_kwargs'].get('transformer_combination_type', 'single') == "moe":
+ transformer_2 = Wan2_2Transformer3DModel.from_pretrained(
+ os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_high_noise_model_subpath', 'transformer')),
+ transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
+ low_cpu_mem_usage=True,
+ torch_dtype=weight_dtype,
+ )
+ else:
+ transformer_2 = None
+ # Update pbar
+ pbar.update(1)
+
+ # Get tokenizer and text_encoder
+ tokenizer = AutoTokenizer.from_pretrained(
+ os.path.join(model_name, config['text_encoder_kwargs'].get('tokenizer_subpath', 'tokenizer')),
+ )
+ pbar.update(1)
+
+ text_encoder = WanT5EncoderModel.from_pretrained(
+ os.path.join(model_name, config['text_encoder_kwargs'].get('text_encoder_subpath', 'text_encoder')),
+ additional_kwargs=OmegaConf.to_container(config['text_encoder_kwargs']),
+ low_cpu_mem_usage=True,
+ torch_dtype=weight_dtype,
+ )
+ pbar.update(1)
+
+ # Get pipeline
+ if model_type == "Inpaint":
+ if transformer.config.in_channels != vae.config.latent_channels:
+ pipeline = Wan2_2FunInpaintPipeline(
+ vae=vae,
+ tokenizer=tokenizer,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ transformer_2=transformer_2,
+ scheduler=scheduler,
+ )
+ else:
+ pipeline = Wan2_2FunPipeline(
+ vae=vae,
+ tokenizer=tokenizer,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ transformer_2=transformer_2,
+ scheduler=scheduler,
+ )
+ else:
+ pipeline = Wan2_2FunControlPipeline(
+ vae=vae,
+ tokenizer=tokenizer,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ transformer_2=transformer_2,
+ scheduler=scheduler,
+ )
+
+ if GPU_memory_mode == "sequential_cpu_offload":
+ replace_parameters_by_name(transformer, ["modulation",], device=device)
+ transformer.freqs = transformer.freqs.to(device=device)
+ if transformer_2 is not None:
+ replace_parameters_by_name(transformer_2, ["modulation",], device=device)
+ transformer_2.freqs = transformer_2.freqs.to(device=device)
+ pipeline.enable_sequential_cpu_offload(device=device)
+ elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
+ convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
+ convert_weight_dtype_wrapper(transformer, weight_dtype)
+ if transformer_2 is not None:
+ convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
+ convert_weight_dtype_wrapper(transformer_2, weight_dtype)
+ pipeline.enable_model_cpu_offload(device=device)
+ elif GPU_memory_mode == "model_cpu_offload":
+ pipeline.enable_model_cpu_offload(device=device)
+ elif GPU_memory_mode == "model_full_load_and_qfloat8":
+ convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
+ convert_weight_dtype_wrapper(transformer, weight_dtype)
+ if transformer_2 is not None:
+ convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
+ convert_weight_dtype_wrapper(transformer_2, weight_dtype)
+ pipeline.to(device=device)
+ else:
+ pipeline.to(device=device)
+
+ funmodels = {
+ 'pipeline': pipeline,
+ 'dtype': weight_dtype,
+ 'model_name': model_name,
+ 'model_type': model_type,
+ 'loras': [],
+ 'strength_model': [],
+ 'config': config,
+ }
+ return (funmodels,)
+
+class LoadWan2_2FunLora:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "funmodels": ("FunModels",),
+ "lora_name": (folder_paths.get_filename_list("loras"), {"default": None,}),
+ "lora_high_name": (folder_paths.get_filename_list("loras"), {"default": None,}),
+ "strength_model": ("FLOAT", {"default": 1.0, "min": -100.0, "max": 100.0, "step": 0.01}),
+ "lora_cache":([False, True], {"default": False,}),
+ }
+ }
+ RETURN_TYPES = ("FunModels",)
+ RETURN_NAMES = ("funmodels",)
+ FUNCTION = "load_lora"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def load_lora(self, funmodels, lora_name, lora_high_name, strength_model, lora_cache):
+ if lora_name is not None:
+ funmodels['lora_cache'] = lora_cache
+ funmodels['loras'] = funmodels.get("loras", []) + [folder_paths.get_full_path("loras", lora_name)]
+ funmodels['loras_high'] = funmodels.get("loras_high", []) + [folder_paths.get_full_path("loras", lora_high_name)]
+ funmodels['strength_model'] = funmodels.get("strength_model", []) + [strength_model]
+ return (funmodels,)
+ else:
+ return (funmodels,)
+
+class Wan2_2FunT2VSampler:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "funmodels": (
+ "FunModels",
+ ),
+ "prompt": (
+ "STRING_PROMPT",
+ ),
+ "negative_prompt": (
+ "STRING_PROMPT",
+ ),
+ "video_length": (
+ "INT", {"default": 81, "min": 5, "max": 161, "step": 4}
+ ),
+ "width": (
+ "INT", {"default": 832, "min": 64, "max": 2048, "step": 16}
+ ),
+ "height": (
+ "INT", {"default": 480, "min": 64, "max": 2048, "step": 16}
+ ),
+ "is_image":(
+ [
+ False,
+ True
+ ],
+ {
+ "default": False,
+ }
+ ),
+ "seed": (
+ "INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
+ ),
+ "steps": (
+ "INT", {"default": 50, "min": 1, "max": 200, "step": 1}
+ ),
+ "cfg": (
+ "FLOAT", {"default": 6.0, "min": 1.0, "max": 20.0, "step": 0.01}
+ ),
+ "scheduler": (
+ [
+ "Flow",
+ ],
+ {
+ "default": 'Flow'
+ }
+ ),
+ "teacache_threshold": (
+ "FLOAT", {"default": 0.10, "min": 0.00, "max": 1.00, "step": 0.005}
+ ),
+ "enable_teacache":(
+ [False, True], {"default": True,}
+ ),
+ "num_skip_start_steps": (
+ "INT", {"default": 5, "min": 0, "max": 50, "step": 1}
+ ),
+ "teacache_offload":(
+ [False, True], {"default": True,}
+ ),
+ "cfg_skip_ratio":(
+ "FLOAT", {"default": 0, "min": 0, "max": 1, "step": 0.01}
+ ),
+ },
+ "optional": {
+ "riflex_k": ("RIFLEXT_ARGS",),
+ },
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES =("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, funmodels, prompt, negative_prompt, video_length, width, height, is_image, seed, steps, cfg, scheduler, teacache_threshold, enable_teacache, num_skip_start_steps, teacache_offload, cfg_skip_ratio, riflex_k=0):
+ global transformer_cpu_cache
+ global transformer_high_cpu_cache
+ global lora_path_before
+ global lora_high_path_before
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+
+ mm.soft_empty_cache()
+ gc.collect()
+
+ # Get Pipeline
+ pipeline = funmodels['pipeline']
+ model_name = funmodels['model_name']
+ config = funmodels['config']
+ weight_dtype = funmodels['dtype']
+
+ # Get boundary for wan
+ boundary = config['transformer_additional_kwargs'].get('boundary', 0.900)
+
+ # Load Sampler
+ pipeline.scheduler = all_cheduler_dict[scheduler](**filter_kwargs(all_cheduler_dict[scheduler], OmegaConf.to_container(config['scheduler_kwargs'])))
+ coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
+ if coefficients is not None:
+ print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
+ pipeline.transformer.enable_teacache(
+ coefficients, steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
+ )
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.share_teacache(transformer=pipeline.transformer)
+ else:
+ pipeline.transformer.disable_teacache()
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.disable_teacache()
+
+ if cfg_skip_ratio is not None:
+ print(f"Enable cfg_skip_ratio {cfg_skip_ratio}.")
+ pipeline.transformer.enable_cfg_skip(cfg_skip_ratio, steps)
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.share_cfg_skip(transformer=pipeline.transformer)
+
+ generator= torch.Generator(device).manual_seed(seed)
+
+ video_length = 1 if is_image else video_length
+ with torch.no_grad():
+ video_length = int((video_length - 1) // pipeline.vae.config.temporal_compression_ratio * pipeline.vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+
+ if riflex_k > 0:
+ latent_frames = (video_length - 1) // pipeline.vae.config.temporal_compression_ratio + 1
+ pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.enable_riflex(k = riflex_k, L_test = latent_frames)
+
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(None, None, video_length=video_length, sample_size=(height, width))
+
+ # Apply lora
+ if funmodels.get("lora_cache", False):
+ if len(funmodels.get("loras", [])) != 0:
+ # Save the original weights to cpu
+ if len(transformer_cpu_cache) == 0:
+ print('Save transformer state_dict to cpu memory')
+ transformer_state_dict = pipeline.transformer.state_dict()
+ for key in transformer_state_dict:
+ transformer_cpu_cache[key] = transformer_state_dict[key].clone().cpu()
+
+ lora_path_now = str(funmodels.get("loras", []) + funmodels.get("strength_model", []))
+ if lora_path_now != lora_path_before:
+ print('Merge Lora with Cache')
+ lora_path_before = copy.deepcopy(lora_path_now)
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ if pipeline.transformer_2 is not None:
+ # Save the original weights to cpu
+ if len(transformer_high_cpu_cache) == 0:
+ print('Save transformer high state_dict to cpu memory')
+ transformer_high_state_dict = pipeline.transformer_2.state_dict()
+ for key in transformer_high_state_dict:
+ transformer_high_cpu_cache[key] = transformer_high_state_dict[key].clone().cpu()
+
+ lora_high_path_now = str(funmodels.get("loras_high", []) + funmodels.get("strength_model", []))
+ if lora_high_path_now != lora_high_path_before:
+ print('Merge Lora High with Cache')
+ lora_high_path_before = copy.deepcopy(lora_high_path_now)
+ pipeline.transformer_2.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(funmodels.get("loras_high", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype, sub_transformer_name="transformer_2")
+ else:
+ print('Merge Lora')
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if len(transformer_cpu_cache) != 0:
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ transformer_cpu_cache = {}
+ lora_path_before = ""
+ gc.collect()
+
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if pipeline.transformer_2 is not None:
+ if len(transformer_high_cpu_cache) != 0:
+ pipeline.transformer_2.load_state_dict(transformer_high_cpu_cache)
+ transformer_high_cpu_cache = {}
+ lora_high_path_before = ""
+ gc.collect()
+
+ for _lora_path, _lora_weight in zip(funmodels.get("loras_high", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype, sub_transformer_name="transformer_2")
+
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ boundary = boundary,
+ comfyui_progressbar = True,
+ ).videos
+ videos = rearrange(sample, "b c t h w -> (b t) h w c")
+
+ if not funmodels.get("lora_cache", False):
+ print('Unmerge Lora')
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ if pipeline.transformer_2 is not None:
+ for _lora_path, _lora_weight in zip(funmodels.get("loras_high", []), funmodels.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype, sub_transformer_name="transformer_2")
+ return (videos,)
+
+
+class Wan2_2FunInpaintSampler:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "funmodels": (
+ "FunModels",
+ ),
+ "prompt": (
+ "STRING_PROMPT",
+ ),
+ "negative_prompt": (
+ "STRING_PROMPT",
+ ),
+ "video_length": (
+ "INT", {"default": 81, "min": 5, "max": 161, "step": 4}
+ ),
+ "base_resolution": (
+ [
+ 512,
+ 640,
+ 768,
+ 896,
+ 960,
+ 1024,
+ ], {"default": 640}
+ ),
+ "seed": (
+ "INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
+ ),
+ "steps": (
+ "INT", {"default": 50, "min": 1, "max": 200, "step": 1}
+ ),
+ "cfg": (
+ "FLOAT", {"default": 6.0, "min": 1.0, "max": 20.0, "step": 0.01}
+ ),
+ "scheduler": (
+ [
+ "Flow",
+ ],
+ {
+ "default": 'Flow'
+ }
+ ),
+ "teacache_threshold": (
+ "FLOAT", {"default": 0.10, "min": 0.00, "max": 1.00, "step": 0.005}
+ ),
+ "enable_teacache":(
+ [False, True], {"default": True,}
+ ),
+ "num_skip_start_steps": (
+ "INT", {"default": 5, "min": 0, "max": 50, "step": 1}
+ ),
+ "teacache_offload":(
+ [False, True], {"default": True,}
+ ),
+ "cfg_skip_ratio":(
+ "FLOAT", {"default": 0, "min": 0, "max": 1, "step": 0.01}
+ ),
+ },
+ "optional": {
+ "start_img": ("IMAGE",),
+ "end_img": ("IMAGE",),
+ "riflex_k": ("RIFLEXT_ARGS",),
+ },
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES =("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, funmodels, prompt, negative_prompt, video_length, base_resolution, seed, steps, cfg, scheduler, teacache_threshold, enable_teacache, num_skip_start_steps, teacache_offload, cfg_skip_ratio, start_img=None, end_img=None, riflex_k=0):
+ global transformer_cpu_cache
+ global transformer_high_cpu_cache
+ global lora_path_before
+ global lora_high_path_before
+
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+
+ mm.soft_empty_cache()
+ gc.collect()
+
+ # Get Pipeline
+ pipeline = funmodels['pipeline']
+ model_name = funmodels['model_name']
+ config = funmodels['config']
+ weight_dtype = funmodels['dtype']
+
+ start_img = [to_pil(_start_img) for _start_img in start_img] if start_img is not None else None
+ end_img = [to_pil(_end_img) for _end_img in end_img] if end_img is not None else None
+ # Count most suitable height and width
+ aspect_ratio_sample_size = {key : [x / 512 * base_resolution for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+ original_width, original_height = start_img[0].size if type(start_img) is list else Image.open(start_img).size
+ closest_size, closest_ratio = get_closest_ratio(original_height, original_width, ratios=aspect_ratio_sample_size)
+ height, width = [int(x / 16) * 16 for x in closest_size]
+
+ # Get boundary for wan
+ boundary = config['transformer_additional_kwargs'].get('boundary', 0.900)
+
+ # Load Sampler
+ pipeline.scheduler = all_cheduler_dict[scheduler](**filter_kwargs(all_cheduler_dict[scheduler], OmegaConf.to_container(config['scheduler_kwargs'])))
+ coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
+ if coefficients is not None:
+ print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
+ pipeline.transformer.enable_teacache(
+ coefficients, steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
+ )
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.share_teacache(transformer=pipeline.transformer)
+ else:
+ pipeline.transformer.disable_teacache()
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.disable_teacache()
+
+ if cfg_skip_ratio is not None:
+ print(f"Enable cfg_skip_ratio {cfg_skip_ratio}.")
+ pipeline.transformer.enable_cfg_skip(cfg_skip_ratio, steps)
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.share_cfg_skip(transformer=pipeline.transformer)
+
+ generator= torch.Generator(device).manual_seed(seed)
+
+ with torch.no_grad():
+ video_length = int((video_length - 1) // pipeline.vae.config.temporal_compression_ratio * pipeline.vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+
+ if riflex_k > 0:
+ latent_frames = (video_length - 1) // pipeline.vae.config.temporal_compression_ratio + 1
+ pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.enable_riflex(k = riflex_k, L_test = latent_frames)
+
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(start_img, end_img, video_length=video_length, sample_size=(height, width))
+
+ # Apply lora
+ if funmodels.get("lora_cache", False):
+ if len(funmodels.get("loras", [])) != 0:
+ # Save the original weights to cpu
+ if len(transformer_cpu_cache) == 0:
+ print('Save transformer state_dict to cpu memory')
+ transformer_state_dict = pipeline.transformer.state_dict()
+ for key in transformer_state_dict:
+ transformer_cpu_cache[key] = transformer_state_dict[key].clone().cpu()
+
+ lora_path_now = str(funmodels.get("loras", []) + funmodels.get("strength_model", []))
+ if lora_path_now != lora_path_before:
+ print('Merge Lora with Cache')
+ lora_path_before = copy.deepcopy(lora_path_now)
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ if pipeline.transformer_2 is not None:
+ # Save the original weights to cpu
+ if len(transformer_high_cpu_cache) == 0:
+ print('Save transformer high state_dict to cpu memory')
+ transformer_high_state_dict = pipeline.transformer_2.state_dict()
+ for key in transformer_high_state_dict:
+ transformer_high_cpu_cache[key] = transformer_high_state_dict[key].clone().cpu()
+
+ lora_high_path_now = str(funmodels.get("loras_high", []) + funmodels.get("strength_model", []))
+ if lora_high_path_now != lora_high_path_before:
+ print('Merge Lora High with Cache')
+ lora_high_path_before = copy.deepcopy(lora_high_path_now)
+ pipeline.transformer_2.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(funmodels.get("loras_high", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype, sub_transformer_name="transformer_2")
+ else:
+ print('Merge Lora')
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if len(transformer_cpu_cache) != 0:
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ transformer_cpu_cache = {}
+ lora_path_before = ""
+ gc.collect()
+
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if pipeline.transformer_2 is not None:
+ if len(transformer_high_cpu_cache) != 0:
+ pipeline.transformer_2.load_state_dict(transformer_high_cpu_cache)
+ transformer_high_cpu_cache = {}
+ lora_high_path_before = ""
+ gc.collect()
+
+ for _lora_path, _lora_weight in zip(funmodels.get("loras_high", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype, sub_transformer_name="transformer_2")
+
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ boundary = boundary,
+ comfyui_progressbar = True,
+ ).videos
+ videos = rearrange(sample, "b c t h w -> (b t) h w c")
+
+ if not funmodels.get("lora_cache", False):
+ print('Unmerge Lora')
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ if pipeline.transformer_2 is not None:
+ for _lora_path, _lora_weight in zip(funmodels.get("loras_high", []), funmodels.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype, sub_transformer_name="transformer_2")
+ return (videos,)
+
+
+class Wan2_2FunV2VSampler:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "funmodels": (
+ "FunModels",
+ ),
+ "prompt": (
+ "STRING_PROMPT",
+ ),
+ "negative_prompt": (
+ "STRING_PROMPT",
+ ),
+ "video_length": (
+ "INT", {"default": 81, "min": 1, "max": 161, "step": 4}
+ ),
+ "base_resolution": (
+ [
+ 512,
+ 640,
+ 768,
+ 896,
+ 960,
+ 1024,
+ ], {"default": 640}
+ ),
+ "seed": (
+ "INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
+ ),
+ "steps": (
+ "INT", {"default": 25, "min": 1, "max": 200, "step": 1}
+ ),
+ "cfg": (
+ "FLOAT", {"default": 7.0, "min": 1.0, "max": 20.0, "step": 0.01}
+ ),
+ "denoise_strength": (
+ "FLOAT", {"default": 0.70, "min": 0.05, "max": 1.00, "step": 0.01}
+ ),
+ "scheduler": (
+ [
+ "Flow",
+ ],
+ {
+ "default": 'Flow'
+ }
+ ),
+ "teacache_threshold": (
+ "FLOAT", {"default": 0.10, "min": 0.00, "max": 1.00, "step": 0.005}
+ ),
+ "enable_teacache":(
+ [False, True], {"default": True,}
+ ),
+ "num_skip_start_steps": (
+ "INT", {"default": 5, "min": 0, "max": 50, "step": 1}
+ ),
+ "teacache_offload":(
+ [False, True], {"default": True,}
+ ),
+ "cfg_skip_ratio":(
+ "FLOAT", {"default": 0, "min": 0, "max": 1, "step": 0.01}
+ ),
+ },
+ "optional": {
+ "validation_video": ("IMAGE",),
+ "control_video": ("IMAGE",),
+ "start_image": ("IMAGE",),
+ "end_image": ("IMAGE",),
+ "ref_image": ("IMAGE",),
+ "camera_conditions": ("STRING", {"forceInput": True}),
+ "riflex_k": ("RIFLEXT_ARGS",),
+ },
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES =("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, funmodels, prompt, negative_prompt, video_length, base_resolution, seed, steps, cfg, denoise_strength, scheduler, teacache_threshold, enable_teacache, num_skip_start_steps, teacache_offload, cfg_skip_ratio, validation_video=None, control_video=None, start_image=None, end_image=None, ref_image=None, camera_conditions=None, riflex_k=0):
+ global transformer_cpu_cache
+ global transformer_high_cpu_cache
+ global lora_path_before
+ global lora_high_path_before
+
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+
+ mm.soft_empty_cache()
+ gc.collect()
+
+ # Get Pipeline
+ pipeline = funmodels['pipeline']
+ model_name = funmodels['model_name']
+ config = funmodels['config']
+ weight_dtype = funmodels['dtype']
+ model_type = funmodels['model_type']
+
+ # Get boundary for wan
+ boundary = config['transformer_additional_kwargs'].get('boundary', 0.900)
+
+ # Count most suitable height and width
+ aspect_ratio_sample_size = {key : [x / 512 * base_resolution for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+ if model_type == "Inpaint":
+ if type(validation_video) is str:
+ original_width, original_height = Image.fromarray(cv2.VideoCapture(validation_video).read()[1]).size
+ else:
+ validation_video = np.array(validation_video.cpu().numpy() * 255, np.uint8)
+ original_width, original_height = Image.fromarray(validation_video[0]).size
+ else:
+ if control_video is not None and type(control_video) is str:
+ original_width, original_height = Image.fromarray(cv2.VideoCapture(control_video).read()[1]).size
+ elif control_video is not None:
+ control_video = np.array(control_video.cpu().numpy() * 255, np.uint8)
+ original_width, original_height = Image.fromarray(control_video[0]).size
+ else:
+ original_width, original_height = 384 / 512 * base_resolution, 672 / 512 * base_resolution
+
+ if ref_image is not None:
+ ref_image = [to_pil(_ref_image) for _ref_image in ref_image]
+ original_width, original_height = ref_image[0].size if type(ref_image) is list else Image.open(ref_image).size
+
+ if start_image is not None:
+ start_image = [to_pil(_start_image) for _start_image in start_image]
+ original_width, original_height = start_image[0].size if type(start_image) is list else Image.open(start_image).size
+
+ if end_image is not None:
+ end_image = [to_pil(_end_image) for _end_image in end_image]
+
+ closest_size, closest_ratio = get_closest_ratio(original_height, original_width, ratios=aspect_ratio_sample_size)
+ height, width = [int(x / 16) * 16 for x in closest_size]
+
+ # Load Sampler
+ pipeline.scheduler = all_cheduler_dict[scheduler](**filter_kwargs(all_cheduler_dict[scheduler], OmegaConf.to_container(config['scheduler_kwargs'])))
+ coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
+ if coefficients is not None:
+ print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
+ pipeline.transformer.enable_teacache(
+ coefficients, steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
+ )
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.share_teacache(transformer=pipeline.transformer)
+ else:
+ pipeline.transformer.disable_teacache()
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.disable_teacache()
+
+ if cfg_skip_ratio is not None:
+ print(f"Enable cfg_skip_ratio {cfg_skip_ratio}.")
+ pipeline.transformer.enable_cfg_skip(cfg_skip_ratio, steps)
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.share_cfg_skip(transformer=pipeline.transformer)
+
+ generator= torch.Generator(device).manual_seed(seed)
+
+ with torch.no_grad():
+ video_length = int((video_length - 1) // pipeline.vae.config.temporal_compression_ratio * pipeline.vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+
+ if riflex_k > 0:
+ latent_frames = (video_length - 1) // pipeline.vae.config.temporal_compression_ratio + 1
+ pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
+ if pipeline.transformer_2 is not None:
+ pipeline.transformer_2.enable_riflex(k = riflex_k, L_test = latent_frames)
+
+ if model_type == "Inpaint":
+ input_video, input_video_mask, ref_image, clip_image = get_video_to_video_latent(validation_video, video_length=video_length, sample_size=(height, width), fps=16, ref_image=ref_image[0] if ref_image is not None else ref_image)
+ else:
+ if ref_image is not None:
+ clip_image = ref_image[0].convert("RGB")
+ elif start_image is not None:
+ clip_image = start_image[0].convert("RGB")
+ else:
+ clip_image = None
+
+ inpaint_video, inpaint_video_mask, clip_image = get_image_to_video_latent(start_image, end_image, video_length=video_length, sample_size=(height, width))
+
+ if ref_image is not None:
+ ref_image = get_image_latent(ref_image[0] if ref_image is not None else ref_image, sample_size=(height, width))
+
+ if camera_conditions is not None and len(camera_conditions) > 0:
+ poses = json.loads(camera_conditions)
+ cam_params = np.array([[float(x) for x in pose] for pose in poses])
+ cam_params = np.concatenate([np.zeros_like(cam_params[:, :1]), cam_params], 1)
+ control_camera_video = process_pose_params(cam_params, width=width, height=height)
+ control_camera_video = control_camera_video[:video_length].permute([3, 0, 1, 2]).unsqueeze(0)
+ input_video, input_video_mask = None, None
+ else:
+ control_camera_video = None
+ input_video, input_video_mask, _, _ = get_video_to_video_latent(control_video, video_length=video_length, sample_size=(height, width), fps=16, ref_image=None)
+
+ # Apply lora
+ if funmodels.get("lora_cache", False):
+ if len(funmodels.get("loras", [])) != 0:
+ # Save the original weights to cpu
+ if len(transformer_cpu_cache) == 0:
+ print('Save transformer state_dict to cpu memory')
+ transformer_state_dict = pipeline.transformer.state_dict()
+ for key in transformer_state_dict:
+ transformer_cpu_cache[key] = transformer_state_dict[key].clone().cpu()
+
+ lora_path_now = str(funmodels.get("loras", []) + funmodels.get("strength_model", []))
+ if lora_path_now != lora_path_before:
+ print('Merge Lora with Cache')
+ lora_path_before = copy.deepcopy(lora_path_now)
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ if pipeline.transformer_2 is not None:
+ # Save the original weights to cpu
+ if len(transformer_high_cpu_cache) == 0:
+ print('Save transformer high state_dict to cpu memory')
+ transformer_high_state_dict = pipeline.transformer_2.state_dict()
+ for key in transformer_high_state_dict:
+ transformer_high_cpu_cache[key] = transformer_high_state_dict[key].clone().cpu()
+
+ lora_high_path_now = str(funmodels.get("loras_high", []) + funmodels.get("strength_model", []))
+ if lora_high_path_now != lora_high_path_before:
+ print('Merge Lora High with Cache')
+ lora_high_path_before = copy.deepcopy(lora_high_path_now)
+ pipeline.transformer_2.load_state_dict(transformer_cpu_cache)
+ for _lora_path, _lora_weight in zip(funmodels.get("loras_high", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype, sub_transformer_name="transformer_2")
+ else:
+ print('Merge Lora')
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if len(transformer_cpu_cache) != 0:
+ pipeline.transformer.load_state_dict(transformer_cpu_cache)
+ transformer_cpu_cache = {}
+ lora_path_before = ""
+ gc.collect()
+
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+
+ # Clear lora when switch from lora_cache=True to lora_cache=False.
+ if pipeline.transformer_2 is not None:
+ if len(transformer_high_cpu_cache) != 0:
+ pipeline.transformer_2.load_state_dict(transformer_high_cpu_cache)
+ transformer_high_cpu_cache = {}
+ lora_high_path_before = ""
+ gc.collect()
+
+ for _lora_path, _lora_weight in zip(funmodels.get("loras_high", []), funmodels.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype, sub_transformer_name="transformer_2")
+
+ if model_type == "Inpaint":
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ clip_image = clip_image,
+ strength = float(denoise_strength),
+ comfyui_progressbar = True,
+ ).videos
+ else:
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ video = inpaint_video,
+ mask_video = inpaint_video_mask,
+ control_video = input_video,
+ control_camera_video = control_camera_video,
+ ref_image = ref_image,
+ boundary = boundary,
+ comfyui_progressbar = True,
+ ).videos
+ videos = rearrange(sample, "b c t h w -> (b t) h w c")
+
+ if not funmodels.get("lora_cache", False):
+ print('Unmerge Lora')
+ for _lora_path, _lora_weight in zip(funmodels.get("loras", []), funmodels.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype)
+ if pipeline.transformer_2 is not None:
+ for _lora_path, _lora_weight in zip(funmodels.get("loras_high", []), funmodels.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight, device="cuda", dtype=weight_dtype, sub_transformer_name="transformer_2")
+ return (videos,)
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_control_camera.json b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_control_camera.json
new file mode 100644
index 0000000000000000000000000000000000000000..723886f4a6d25484b558c7e08ccf1fd3f6a4b3a8
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_control_camera.json
@@ -0,0 +1,670 @@
+{
+ "id": "f2736b24-5147-427c-a9dd-036fd3053b5d",
+ "revision": 0,
+ "last_node_id": 135,
+ "last_link_id": 300,
+ "nodes": [
+ {
+ "id": 107,
+ "type": "Note",
+ "pos": [
+ 4,
+ 634
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 108,
+ "type": "Note",
+ "pos": [
+ -110,
+ 842
+ ],
+ "size": [
+ 326.1556091308594,
+ 145.20904541015625
+ ],
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 122,
+ "type": "FunTextBox",
+ "pos": [
+ 238,
+ 805
+ ],
+ "size": [
+ 400,
+ 200
+ ],
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 297
+ ]
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 129,
+ "type": "CameraBasicFromChaoJie",
+ "pos": [
+ 805.2059326171875,
+ 1012.381103515625
+ ],
+ "size": [
+ 315,
+ 106
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "CameraPose",
+ "type": "CameraPose",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CameraBasicFromChaoJie"
+ },
+ "widgets_values": [
+ "Static",
+ 1,
+ 16
+ ]
+ },
+ {
+ "id": 130,
+ "type": "CameraTrajectoryFromChaoJie",
+ "pos": [
+ 1170.206298828125,
+ 763.3814697265625
+ ],
+ "size": [
+ 367.79998779296875,
+ 150
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "camera_pose",
+ "type": "CameraPose",
+ "link": 285
+ }
+ ],
+ "outputs": [
+ {
+ "name": "camera_trajectory",
+ "type": "STRING",
+ "slot_index": 0,
+ "links": [
+ 299
+ ]
+ },
+ {
+ "name": "video_length",
+ "type": "INT",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CameraTrajectoryFromChaoJie"
+ },
+ "widgets_values": [
+ 0.532139961,
+ 0.946026558,
+ 0.5,
+ 0.5
+ ]
+ },
+ {
+ "id": 106,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1408,
+ 68
+ ],
+ "size": [
+ 390,
+ 310
+ ],
+ "flags": {},
+ "order": 12,
+ "mode": 0,
+ "inputs": [
+ {
+ "label": "图像",
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 300
+ },
+ {
+ "label": "音频",
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "label": "批次管理",
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "label": "文件名",
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "slot_index": 0,
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00112.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 121,
+ "type": "FunTextBox",
+ "pos": [
+ 235,
+ 539
+ ],
+ "size": [
+ 400,
+ 200
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 296
+ ]
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "Fireworks light up the evening sky over a sprawling cityscape with gothic-style buildings featuring pointed towers and clock faces. The city is lit by both artificial lights from the buildings and the colorful bursts of the fireworks. The scene is viewed from an elevated angle, showcasing a vibrant urban environment set against a backdrop of a dramatic, partially cloudy sky at dusk."
+ ]
+ },
+ {
+ "id": 100,
+ "type": "LoadImage",
+ "pos": [
+ 237.59738159179688,
+ 1164.597412109375
+ ],
+ "size": [
+ 378.07147216796875,
+ 314
+ ],
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "label": "图像",
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "slot_index": 0,
+ "links": [
+ 298
+ ]
+ },
+ {
+ "label": "遮罩",
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "title": "Start Image(图片到视频的开始图片)",
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "5.png",
+ "image"
+ ]
+ },
+ {
+ "id": 131,
+ "type": "CameraCombineFromChaoJie",
+ "pos": [
+ 814.2059326171875,
+ 763.3814697265625
+ ],
+ "size": [
+ 315,
+ 178
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "CameraPose",
+ "type": "CameraPose",
+ "links": [
+ 285
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CameraCombineFromChaoJie"
+ },
+ "widgets_values": [
+ "Pan Right",
+ "Pan Up",
+ "Static",
+ "Static",
+ 1,
+ 81
+ ]
+ },
+ {
+ "id": 110,
+ "type": "Note",
+ "pos": [
+ 1158.206298828125,
+ 970.381103515625
+ ],
+ "size": [
+ 608.1410522460938,
+ 188.2682342529297
+ ],
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "CameraCombine is used to combine multiple camera movements, while CameraBasic produces a single camera movement. The nodes come from https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper/. Since ComfyUI-CameraCtrl-Wrapper requires a specific version of diffusers, the code has been copied into the current repository.\n(CameraCombine用于组合多个镜头运动,CameraBasic产出单个镜头运动;节点来自于https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper/,由于ComfyUI-CameraCtrl-Wrapper有具体diffusers版本要求,故复制代码到当前库中。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 112,
+ "type": "Note",
+ "pos": [
+ -203,
+ 252
+ ],
+ "size": [
+ 427.074951171875,
+ 143.9142608642578
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 134,
+ "type": "LoadWan2_2FunModel",
+ "pos": [
+ 273.49224853515625,
+ 249.6970672607422
+ ],
+ "size": [
+ 350.6878662109375,
+ 155.20101928710938
+ ],
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 295
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWan2_2FunModel"
+ },
+ "widgets_values": [
+ "Wan2.2-Fun-A14B-Control-Camera",
+ "Control",
+ "sequential_cpu_offload",
+ "wan2.2/wan_civitai_i2v.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 135,
+ "type": "Wan2_2FunV2VSampler",
+ "pos": [
+ 923.0663452148438,
+ 107.64505767822266
+ ],
+ "size": [
+ 350.2320251464844,
+ 526
+ ],
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 295
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 296
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 297
+ },
+ {
+ "name": "validation_video",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "control_video",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "start_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 298
+ },
+ {
+ "name": "end_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "ref_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "camera_conditions",
+ "shape": 7,
+ "type": "STRING",
+ "link": 299
+ },
+ {
+ "name": "riflex_k",
+ "shape": 7,
+ "type": "RIFLEXT_ARGS",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 300
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "Wan2_2FunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6.000000000000001,
+ 1,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ }
+ ],
+ "links": [
+ [
+ 285,
+ 131,
+ 0,
+ 130,
+ 0,
+ "CameraPose"
+ ],
+ [
+ 295,
+ 134,
+ 0,
+ 135,
+ 0,
+ "FunModels"
+ ],
+ [
+ 296,
+ 121,
+ 0,
+ 135,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 297,
+ 122,
+ 0,
+ 135,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 298,
+ 100,
+ 0,
+ 135,
+ 5,
+ "IMAGE"
+ ],
+ [
+ 299,
+ 130,
+ 0,
+ 135,
+ 8,
+ "STRING"
+ ],
+ [
+ 300,
+ 135,
+ 0,
+ 106,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "id": 1,
+ "title": "Generate Control Video",
+ "bounding": [
+ 773,
+ 666,
+ 1025,
+ 531
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 2,
+ "title": "First Image",
+ "bounding": [
+ 191,
+ 1068,
+ 475,
+ 456
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 3,
+ "title": "Prompts",
+ "bounding": [
+ 191,
+ 456,
+ 475,
+ 587
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 4,
+ "title": "Load Model",
+ "bounding": [
+ 189,
+ 160,
+ 475,
+ 269
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650709,
+ "offset": [
+ 246.58945220178464,
+ 51.36424150314978
+ ]
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "e935795d7684aaba72be65d2ad5ef580c0526f7a",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "comfy-core": "0.3.44"
+ },
+ "frontendVersion": "1.21.3"
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_control_trajectory.json b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_control_trajectory.json
new file mode 100644
index 0000000000000000000000000000000000000000..6280aa8f843038f7c8a7901a41f50edb712f6871
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_control_trajectory.json
@@ -0,0 +1,1045 @@
+{
+ "id": "a707e0b0-7fbd-4f91-9c23-1c5bdca19bad",
+ "revision": 0,
+ "last_node_id": 129,
+ "last_link_id": 294,
+ "nodes": [
+ {
+ "id": 107,
+ "type": "Note",
+ "pos": [
+ 4,
+ 634
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 108,
+ "type": "Note",
+ "pos": [
+ -110,
+ 842
+ ],
+ "size": [
+ 326.1556091308594,
+ 145.20904541015625
+ ],
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 100,
+ "type": "LoadImage",
+ "pos": [
+ 238,
+ 1165
+ ],
+ "size": [
+ 378.07147216796875,
+ 314
+ ],
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "label": "图像",
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "slot_index": 0,
+ "links": [
+ 292
+ ]
+ },
+ {
+ "label": "遮罩",
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "title": "Start Image(图片到视频的开始图片)",
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "1.png",
+ "image"
+ ]
+ },
+ {
+ "id": 118,
+ "type": "AppendStringsToList",
+ "pos": [
+ 1140.1396484375,
+ 909.9193115234375
+ ],
+ "size": [
+ 315,
+ 82
+ ],
+ "flags": {
+ "collapsed": false
+ },
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "string1",
+ "type": "STRING",
+ "link": 265
+ },
+ {
+ "name": "string2",
+ "type": "STRING",
+ "link": 266
+ }
+ ],
+ "outputs": [
+ {
+ "name": "STRING",
+ "type": "STRING",
+ "slot_index": 0,
+ "links": [
+ 267
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "AppendStringsToList"
+ },
+ "widgets_values": []
+ },
+ {
+ "id": 121,
+ "type": "FunTextBox",
+ "pos": [
+ 235,
+ 539
+ ],
+ "size": [
+ 400,
+ 200
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 289
+ ]
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "一只棕褐色的狗正摇晃着脑袋,坐在一个舒适的房间里的浅色沙发上。沙发看起来柔软而宽敞,为这只活泼的狗狗提供了一个完美的休息地点。在狗的后面,靠墙摆放着一个架子,架子上挂着一幅精美的镶框画,画中描绘着一些美丽的风景或场景。画框周围装饰着粉红色的花朵,这些花朵不仅增添了房间的色彩,还带来了一丝自然和生机。房间里的灯光柔和而温暖,从天花板上的吊灯和角落里的台灯散发出来,营造出一种温馨舒适的氛围。整个空间给人一种宁静和谐的感觉,仿佛时间在这里变得缓慢而美好。"
+ ]
+ },
+ {
+ "id": 95,
+ "type": "CreateTrajectoryBasedOnKJNodes",
+ "pos": [
+ 1574.139404296875,
+ 929.9193115234375
+ ],
+ "size": [
+ 428.4000244140625,
+ 58
+ ],
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "coordinates",
+ "type": "STRING",
+ "link": 267
+ },
+ {
+ "name": "masks",
+ "type": "MASK",
+ "link": 249
+ }
+ ],
+ "outputs": [
+ {
+ "name": "image",
+ "type": "IMAGE",
+ "slot_index": 0,
+ "links": [
+ 237,
+ 262,
+ 291
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CreateTrajectoryBasedOnKJNodes"
+ },
+ "widgets_values": []
+ },
+ {
+ "id": 122,
+ "type": "FunTextBox",
+ "pos": [
+ 238,
+ 805
+ ],
+ "size": [
+ 400,
+ 200
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 290
+ ]
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 97,
+ "type": "SplineEditor",
+ "pos": [
+ 855.1397705078125,
+ 1058.91943359375
+ ],
+ "size": [
+ 645,
+ 832
+ ],
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "bg_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "mask",
+ "type": "MASK",
+ "slot_index": 0,
+ "links": [
+ 249
+ ]
+ },
+ {
+ "name": "coord_str",
+ "type": "STRING",
+ "slot_index": 1,
+ "links": [
+ 265
+ ]
+ },
+ {
+ "name": "float",
+ "type": "FLOAT",
+ "links": null
+ },
+ {
+ "name": "count",
+ "type": "INT",
+ "links": null
+ },
+ {
+ "name": "normalized_str",
+ "type": "STRING",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "SplineEditor",
+ "points": "SplineEditor",
+ "imgData": null
+ },
+ "widgets_values": [
+ "[{\"points\":[{\"x\":236.74497000000005,\"y\":169.10355000000004},{\"x\":263.53799999999995,\"y\":230.59575},{\"x\":321.61075881587004,\"y\":229.72197058276433},{\"x\":355.3934015486295,\"y\":168.9132136637973},{\"x\":343.23165016483614,\"y\":82.42964826793309},{\"x\":275.6663646993172,\"y\":55.40353408172552},{\"x\":197.29063355931524,\"y\":85.13225968655384},{\"x\":177.02104791965957,\"y\":148.64362802414163},{\"x\":205.39846781517753,\"y\":232.4245820013851},{\"x\":259.45069618759265,\"y\":167.56190795448694}],\"color\":\"#1f77b4\",\"name\":\"Spline 1\"}]",
+ "[[{\"x\":236.74496459960938,\"y\":169.10354614257812},{\"x\":238.94464111328125,\"y\":177.68576049804688},{\"x\":241.3327178955078,\"y\":186.21737670898438},{\"x\":243.95693969726562,\"y\":194.67919921875},{\"x\":246.88812255859375,\"y\":203.03933715820312},{\"x\":250.2393035888672,\"y\":211.23939514160156},{\"x\":254.20826721191406,\"y\":219.15655517578125},{\"x\":259.18768310546875,\"y\":226.46995544433594},{\"x\":265.87689208984375,\"y\":232.22171020507812},{\"x\":273.4639892578125,\"y\":236.787353515625},{\"x\":281.6380920410156,\"y\":240.17092895507812},{\"x\":290.3527526855469,\"y\":241.61793518066406},{\"x\":299.1367492675781,\"y\":240.67857360839844},{\"x\":307.49658203125,\"y\":237.7835235595703},{\"x\":315.3465576171875,\"y\":233.68600463867188},{\"x\":322.80859375,\"y\":228.9126739501953},{\"x\":330.00958251953125,\"y\":223.75323486328125},{\"x\":336.7490234375,\"y\":218.0097198486328},{\"x\":342.5494689941406,\"y\":211.32901000976562},{\"x\":346.96185302734375,\"y\":203.6618194580078},{\"x\":350.05450439453125,\"y\":195.3665771484375},{\"x\":352.2560729980469,\"y\":186.787109375},{\"x\":353.9389343261719,\"y\":178.08937072753906},{\"x\":355.33001708984375,\"y\":169.3397216796875},{\"x\":356.59344482421875,\"y\":160.57052612304688},{\"x\":357.7420959472656,\"y\":151.78565979003906},{\"x\":358.6518249511719,\"y\":142.9732208251953},{\"x\":359.1504211425781,\"y\":134.1287384033203},{\"x\":359.0207214355469,\"y\":125.2725601196289},{\"x\":358.035400390625,\"y\":116.4721908569336},{\"x\":356.0333251953125,\"y\":107.84730529785156},{\"x\":352.9960632324219,\"y\":99.53003692626953},{\"x\":349.046142578125,\"y\":91.60392761230469},{\"x\":344.37164306640625,\"y\":84.08070373535156},{\"x\":339.17694091796875,\"y\":76.9051742553711},{\"x\":333.4718322753906,\"y\":70.13098907470703},{\"x\":326.9710693359375,\"y\":64.12535858154297},{\"x\":319.4295654296875,\"y\":59.51286315917969},{\"x\":311.02655029296875,\"y\":56.7620735168457},{\"x\":302.25640869140625,\"y\":55.55453872680664},{\"x\":293.40484619140625,\"y\":55.21137619018555},{\"x\":284.5453796386719,\"y\":55.24800491333008},{\"x\":275.68701171875,\"y\":55.40314865112305},{\"x\":266.83221435546875,\"y\":55.690216064453125},{\"x\":257.9945373535156,\"y\":56.30451965332031},{\"x\":249.2041473388672,\"y\":57.398460388183594},{\"x\":240.5244140625,\"y\":59.16102981567383},{\"x\":232.06307983398438,\"y\":61.773162841796875},{\"x\":223.95306396484375,\"y\":65.32772827148438},{\"x\":216.29017639160156,\"y\":69.7664566040039},{\"x\":209.08375549316406,\"y\":74.91584777832031},{\"x\":202.27122497558594,\"y\":80.57798767089844},{\"x\":195.76087951660156,\"y\":86.58625030517578},{\"x\":189.468505859375,\"y\":92.8224105834961},{\"x\":183.6200714111328,\"y\":99.47235107421875},{\"x\":178.9163055419922,\"y\":106.95783233642578},{\"x\":176.3991241455078,\"y\":115.42044830322266},{\"x\":175.83934020996094,\"y\":124.25370788574219},{\"x\":176.12339782714844,\"y\":133.10797119140625},{\"x\":176.63381958007812,\"y\":141.95301818847656},{\"x\":177.14378356933594,\"y\":150.79808044433594},{\"x\":177.73876953125,\"y\":159.63778686523438},{\"x\":178.5083770751953,\"y\":168.46385192871094},{\"x\":179.4958038330078,\"y\":177.26815795898438},{\"x\":180.75762939453125,\"y\":186.03709411621094},{\"x\":182.37294006347656,\"y\":194.7476043701172},{\"x\":184.4583282470703,\"y\":203.35687255859375},{\"x\":187.1986083984375,\"y\":211.7789306640625},{\"x\":190.9047393798828,\"y\":219.81732177734375},{\"x\":196.108154296875,\"y\":226.9572296142578},{\"x\":203.41249084472656,\"y\":231.83749389648438},{\"x\":211.85409545898438,\"y\":230.89816284179688},{\"x\":218.7886199951172,\"y\":225.41867065429688},{\"x\":224.8160400390625,\"y\":218.92974853515625},{\"x\":230.3641357421875,\"y\":212.0236358642578},{\"x\":235.608642578125,\"y\":204.8833770751953},{\"x\":240.63941955566406,\"y\":197.59080505371094},{\"x\":245.50965881347656,\"y\":190.1898651123047},{\"x\":250.25364685058594,\"y\":182.7073516845703},{\"x\":254.8948974609375,\"y\":175.16050720214844},{\"x\":259.45068359375,\"y\":167.56190490722656}]]",
+ 600,
+ 382,
+ 81,
+ "path",
+ "cardinal",
+ 0.5,
+ 1,
+ "list",
+ 0,
+ 1,
+ "",
+ null
+ ]
+ },
+ {
+ "id": 119,
+ "type": "SplineEditor",
+ "pos": [
+ 1544.139404296875,
+ 1047.919189453125
+ ],
+ "size": [
+ 645,
+ 832
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "bg_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "mask",
+ "type": "MASK",
+ "slot_index": 0,
+ "links": []
+ },
+ {
+ "name": "coord_str",
+ "type": "STRING",
+ "slot_index": 1,
+ "links": [
+ 266
+ ]
+ },
+ {
+ "name": "float",
+ "type": "FLOAT",
+ "links": null
+ },
+ {
+ "name": "count",
+ "type": "INT",
+ "links": null
+ },
+ {
+ "name": "normalized_str",
+ "type": "STRING",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "SplineEditor",
+ "points": "SplineEditor",
+ "imgData": null
+ },
+ "widgets_values": [
+ "[{\"points\":[{\"x\":63.916760050380844,\"y\":114.45559357858895},{\"x\":71.34894145158792,\"y\":114.45559357858895}],\"color\":\"#1f77b4\",\"name\":\"Spline 1\"}]",
+ "[[{\"x\":63.9167594909668,\"y\":114.45559692382812},{\"x\":64.00965881347656,\"y\":114.45559692382812},{\"x\":64.1025619506836,\"y\":114.45559692382812},{\"x\":64.19546508789062,\"y\":114.45559692382812},{\"x\":64.28836822509766,\"y\":114.45559692382812},{\"x\":64.38127136230469,\"y\":114.45559692382812},{\"x\":64.47417449951172,\"y\":114.45559692382812},{\"x\":64.56707763671875,\"y\":114.45559692382812},{\"x\":64.65998077392578,\"y\":114.45559692382812},{\"x\":64.75287628173828,\"y\":114.45559692382812},{\"x\":64.84577941894531,\"y\":114.45559692382812},{\"x\":64.93868255615234,\"y\":114.45559692382812},{\"x\":65.03158569335938,\"y\":114.45559692382812},{\"x\":65.1244888305664,\"y\":114.45559692382812},{\"x\":65.21739196777344,\"y\":114.45559692382812},{\"x\":65.31029510498047,\"y\":114.45559692382812},{\"x\":65.4031982421875,\"y\":114.45559692382812},{\"x\":65.49609375,\"y\":114.45559692382812},{\"x\":65.58899688720703,\"y\":114.45559692382812},{\"x\":65.68190002441406,\"y\":114.45559692382812},{\"x\":65.7748031616211,\"y\":114.45559692382812},{\"x\":65.86770629882812,\"y\":114.45559692382812},{\"x\":65.96060943603516,\"y\":114.45559692382812},{\"x\":66.05351257324219,\"y\":114.45559692382812},{\"x\":66.14641571044922,\"y\":114.45559692382812},{\"x\":66.23931884765625,\"y\":114.45559692382812},{\"x\":66.33221435546875,\"y\":114.45559692382812},{\"x\":66.42511749267578,\"y\":114.45559692382812},{\"x\":66.51802062988281,\"y\":114.45559692382812},{\"x\":66.61092376708984,\"y\":114.45559692382812},{\"x\":66.70382690429688,\"y\":114.45559692382812},{\"x\":66.7967300415039,\"y\":114.45559692382812},{\"x\":66.88963317871094,\"y\":114.45559692382812},{\"x\":66.98253631591797,\"y\":114.45559692382812},{\"x\":67.075439453125,\"y\":114.45559692382812},{\"x\":67.1683349609375,\"y\":114.45559692382812},{\"x\":67.26123809814453,\"y\":114.45559692382812},{\"x\":67.35414123535156,\"y\":114.45559692382812},{\"x\":67.4470443725586,\"y\":114.45559692382812},{\"x\":67.53994750976562,\"y\":114.45559692382812},{\"x\":67.63285064697266,\"y\":114.45559692382812},{\"x\":67.72575378417969,\"y\":114.45559692382812},{\"x\":67.81864929199219,\"y\":114.45559692382812},{\"x\":67.91155242919922,\"y\":114.45559692382812},{\"x\":68.00445556640625,\"y\":114.45559692382812},{\"x\":68.09735870361328,\"y\":114.45559692382812},{\"x\":68.19026184082031,\"y\":114.45559692382812},{\"x\":68.28316497802734,\"y\":114.45559692382812},{\"x\":68.37606811523438,\"y\":114.45559692382812},{\"x\":68.4689712524414,\"y\":114.45559692382812},{\"x\":68.56187438964844,\"y\":114.45559692382812},{\"x\":68.65476989746094,\"y\":114.45559692382812},{\"x\":68.74767303466797,\"y\":114.45559692382812},{\"x\":68.840576171875,\"y\":114.45559692382812},{\"x\":68.93347930908203,\"y\":114.45559692382812},{\"x\":69.02638244628906,\"y\":114.45559692382812},{\"x\":69.1192855834961,\"y\":114.45559692382812},{\"x\":69.21218872070312,\"y\":114.45559692382812},{\"x\":69.30509185791016,\"y\":114.45559692382812},{\"x\":69.39799499511719,\"y\":114.45559692382812},{\"x\":69.49089050292969,\"y\":114.45559692382812},{\"x\":69.58379364013672,\"y\":114.45559692382812},{\"x\":69.67669677734375,\"y\":114.45559692382812},{\"x\":69.76959991455078,\"y\":114.45559692382812},{\"x\":69.86250305175781,\"y\":114.45559692382812},{\"x\":69.95540618896484,\"y\":114.45559692382812},{\"x\":70.04830932617188,\"y\":114.45559692382812},{\"x\":70.1412124633789,\"y\":114.45559692382812},{\"x\":70.2341079711914,\"y\":114.45559692382812},{\"x\":70.32701110839844,\"y\":114.45559692382812},{\"x\":70.41991424560547,\"y\":114.45559692382812},{\"x\":70.5128173828125,\"y\":114.45559692382812},{\"x\":70.60572052001953,\"y\":114.45559692382812},{\"x\":70.69862365722656,\"y\":114.45559692382812},{\"x\":70.7915267944336,\"y\":114.45559692382812},{\"x\":70.88442993164062,\"y\":114.45559692382812},{\"x\":70.97732543945312,\"y\":114.45559692382812},{\"x\":71.07022857666016,\"y\":114.45559692382812},{\"x\":71.16313171386719,\"y\":114.45559692382812},{\"x\":71.25603485107422,\"y\":114.45559692382812},{\"x\":71.34893798828125,\"y\":114.45559692382812}]]",
+ 600,
+ 382,
+ 81,
+ "path",
+ "cardinal",
+ 0.5,
+ 1,
+ "list",
+ 0,
+ 1,
+ "",
+ null
+ ]
+ },
+ {
+ "id": 44,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 2241.138427734375,
+ 1051.91943359375
+ ],
+ "size": [
+ 530,
+ 650.4000244140625
+ ],
+ "flags": {},
+ "order": 12,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 237
+ },
+ {
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "slot_index": 0,
+ "links": null
+ }
+ ],
+ "title": "Trajectory Outputs",
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun-Trajectory",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun-Trajectory_00002.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ },
+ "muted": false
+ }
+ }
+ },
+ {
+ "id": 115,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 2819,
+ 1056
+ ],
+ "size": [
+ 530,
+ 310
+ ],
+ "flags": {},
+ "order": 16,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 264
+ },
+ {
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "slot_index": 0,
+ "links": null
+ }
+ ],
+ "title": "Video with Trajectory Outputs",
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun-Trajectory-Merge",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "EasyAnimate-Trajectory-Merge_00009.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ },
+ "muted": false
+ }
+ }
+ },
+ {
+ "id": 112,
+ "type": "Note",
+ "pos": [
+ -203,
+ 252
+ ],
+ "size": [
+ 427.074951171875,
+ 143.9142608642578
+ ],
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 128,
+ "type": "LoadWan2_2FunModel",
+ "pos": [
+ 277.63623046875,
+ 254.2862548828125
+ ],
+ "size": [
+ 363.85333251953125,
+ 154
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 288
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWan2_2FunModel"
+ },
+ "widgets_values": [
+ "Wan2.2-Fun-A14B-Control",
+ "Control",
+ "sequential_cpu_offload",
+ "wan2.2/wan_civitai_i2v.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 110,
+ "type": "Note",
+ "pos": [
+ 836.5111083984375,
+ 639.8340454101562
+ ],
+ "size": [
+ 608.1410522460938,
+ 188.2682342529297
+ ],
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Please set the mask height and mask width according to the height and width of the reference image. \nPlease set the video_length of the Spline Editor below to be the same as the video_length of the Sampler above. \nThe nodes are from KJNodes. For more details, please check https://github.com/kijai/ComfyUI-KJNodes/tree/main. \n\n请根据参考图片的高和宽设置mask height和mask width;\n请将下方Spline Editor的video_legnth置的与上方Sampler的video_legnth一样;\n部分节点来自于KJNodes,具体查看https://github.com/kijai/ComfyUI-KJNodes/tree/main;"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 106,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1386.0306396484375,
+ 42.99613952636719
+ ],
+ "size": [
+ 390,
+ 310
+ ],
+ "flags": {},
+ "order": 14,
+ "mode": 0,
+ "inputs": [
+ {
+ "label": "图像",
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 293
+ },
+ {
+ "label": "音频",
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "label": "批次管理",
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "label": "文件名",
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "slot_index": 0,
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "EasyAnimate_00105.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 114,
+ "type": "ImageMaximumNode",
+ "pos": [
+ 2114.7646484375,
+ 884.5827026367188
+ ],
+ "size": [
+ 210,
+ 46
+ ],
+ "flags": {},
+ "order": 15,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "video_1",
+ "type": "IMAGE",
+ "link": 294
+ },
+ {
+ "name": "video_2",
+ "type": "IMAGE",
+ "link": 262
+ }
+ ],
+ "outputs": [
+ {
+ "name": "image",
+ "type": "IMAGE",
+ "links": [
+ 264
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "ImageMaximumNode"
+ },
+ "widgets_values": []
+ },
+ {
+ "id": 129,
+ "type": "Wan2_2FunV2VSampler",
+ "pos": [
+ 835.7046508789062,
+ 41.22541809082031
+ ],
+ "size": [
+ 470.3740234375,
+ 526
+ ],
+ "flags": {},
+ "order": 13,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 288
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 289
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 290
+ },
+ {
+ "name": "validation_video",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "control_video",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 291
+ },
+ {
+ "name": "start_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 292
+ },
+ {
+ "name": "end_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "ref_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "camera_conditions",
+ "shape": 7,
+ "type": "STRING",
+ "link": null
+ },
+ {
+ "name": "riflex_k",
+ "shape": 7,
+ "type": "RIFLEXT_ARGS",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 293,
+ 294
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "Wan2_2FunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6.000000000000001,
+ 1,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ }
+ ],
+ "links": [
+ [
+ 237,
+ 95,
+ 0,
+ 44,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 249,
+ 97,
+ 0,
+ 95,
+ 1,
+ "MASK"
+ ],
+ [
+ 262,
+ 95,
+ 0,
+ 114,
+ 1,
+ "IMAGE"
+ ],
+ [
+ 264,
+ 114,
+ 0,
+ 115,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 265,
+ 97,
+ 1,
+ 118,
+ 0,
+ "STRING"
+ ],
+ [
+ 266,
+ 119,
+ 1,
+ 118,
+ 1,
+ "STRING"
+ ],
+ [
+ 267,
+ 118,
+ 0,
+ 95,
+ 0,
+ "STRING"
+ ],
+ [
+ 288,
+ 128,
+ 0,
+ 129,
+ 0,
+ "FunModels"
+ ],
+ [
+ 289,
+ 121,
+ 0,
+ 129,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 290,
+ 122,
+ 0,
+ 129,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 291,
+ 95,
+ 0,
+ 129,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 292,
+ 100,
+ 0,
+ 129,
+ 5,
+ "IMAGE"
+ ],
+ [
+ 293,
+ 129,
+ 0,
+ 106,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 294,
+ 129,
+ 0,
+ 114,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "id": 1,
+ "title": "Load Model",
+ "bounding": [
+ 189,
+ 160,
+ 475,
+ 269
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 2,
+ "title": "Prompts",
+ "bounding": [
+ 191,
+ 456,
+ 475,
+ 587
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 3,
+ "title": "First Image of Trajectory",
+ "bounding": [
+ 191,
+ 1068,
+ 475,
+ 456
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 4,
+ "title": "Generate Control Video",
+ "bounding": [
+ 786,
+ 841,
+ 2616,
+ 1056
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650711,
+ "offset": [
+ 109.96141399088638,
+ -28.91205721966216
+ ]
+ },
+ "frontendVersion": "1.21.3",
+ "node_versions": {
+ "comfy-core": "0.3.44",
+ "ComfyUI-KJNodes": "ff49e1b01f10a14496b08e21bb89b64d2b15f333",
+ "CogVideoX-Fun": "e935795d7684aaba72be65d2ad5ef580c0526f7a",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_flf.json b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_flf.json
new file mode 100644
index 0000000000000000000000000000000000000000..105c0f0a222a131825b08e3e2d95464e47dc3914
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_flf.json
@@ -0,0 +1,551 @@
+{
+ "id": "7771a2ee-e50b-4606-8122-63139795c002",
+ "revision": 0,
+ "last_node_id": 103,
+ "last_link_id": 69,
+ "nodes": [
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ -50
+ ],
+ "size": [
+ 383.54010009765625,
+ 156.71620178222656
+ ],
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 66
+ ]
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 94,
+ "type": "Note",
+ "pos": [
+ 17,
+ -35
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 95,
+ "type": "Note",
+ "pos": [
+ 35.71394348144531,
+ 536.9210205078125
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload image here\n(你可以在此上传图片)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1271,
+ -67
+ ],
+ "size": [
+ 390,
+ 537.4615478515625
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "label": "图像",
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 64
+ },
+ {
+ "label": "音频",
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "label": "批次管理",
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "label": "文件名",
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "slot_index": 0,
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00008.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": [
+ -95.01139068603516,
+ -334.30706787109375
+ ],
+ "size": [
+ 355.636474609375,
+ 132.4238739013672
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ 160
+ ],
+ "size": [
+ 383.7149963378906,
+ 183.83506774902344
+ ],
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 67
+ ]
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 87,
+ "type": "LoadImage",
+ "pos": [
+ 280.5103759765625,
+ 477.9588623046875
+ ],
+ "size": [
+ 315,
+ 314
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 68
+ ]
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "title": "Start Image",
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "2.png",
+ "image"
+ ]
+ },
+ {
+ "id": 103,
+ "type": "LoadImage",
+ "pos": [
+ 689.5659790039062,
+ 477.3172302246094
+ ],
+ "size": [
+ 318.56072998046875,
+ 326
+ ],
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 69
+ ]
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "title": "End Image",
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "070008-d3df70b6-1c49-43d5-a39b-ba357e48c17a-3149685904.png",
+ "image"
+ ]
+ },
+ {
+ "id": 99,
+ "type": "LoadWan2_2FunModel",
+ "pos": [
+ 290,
+ -334
+ ],
+ "size": [
+ 315,
+ 154
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 65
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWan2_2FunModel"
+ },
+ "widgets_values": [
+ "Wan2.2-Fun-A14B-InP",
+ "Inpaint",
+ "sequential_cpu_offload",
+ "wan2.2/wan_civitai_i2v.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 101,
+ "type": "Wan2_2FunInpaintSampler",
+ "pos": [
+ 771,
+ -67
+ ],
+ "size": [
+ 428.4000244140625,
+ 422
+ ],
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 65
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 66
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 67
+ },
+ {
+ "name": "start_img",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 68
+ },
+ {
+ "name": "end_img",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 69
+ },
+ {
+ "name": "riflex_k",
+ "shape": 7,
+ "type": "RIFLEXT_ARGS",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "slot_index": 0,
+ "links": [
+ 64
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "Wan2_2FunInpaintSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 1035488842362745,
+ "randomize",
+ 50,
+ 6,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ }
+ ],
+ "links": [
+ [
+ 64,
+ 101,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 65,
+ 99,
+ 0,
+ 101,
+ 0,
+ "FunModels"
+ ],
+ [
+ 66,
+ 75,
+ 0,
+ 101,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 67,
+ 73,
+ 0,
+ 101,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 68,
+ 87,
+ 0,
+ 101,
+ 3,
+ "IMAGE"
+ ],
+ [
+ 69,
+ 103,
+ 0,
+ 101,
+ 4,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "id": 1,
+ "title": "Load Image",
+ "bounding": [
+ 222,
+ 396,
+ 875.5350952148438,
+ 432.9040832519531
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 2,
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 3,
+ "title": "Load Model",
+ "bounding": [
+ 227,
+ -416,
+ 469,
+ 256
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.8264462809917354,
+ "offset": [
+ 37.99022188655044,
+ 404.3950236451732
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "a1b1e5e74589b3902bdf54d942862de0e6d30b08",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "comfy-core": "0.3.44"
+ },
+ "frontendVersion": "1.21.3"
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_i2v.json b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_i2v.json
new file mode 100644
index 0000000000000000000000000000000000000000..c7a0965d72173555e10e8496f470e8b122ca869c
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_i2v.json
@@ -0,0 +1,496 @@
+{
+ "last_node_id": 102,
+ "last_link_id": 68,
+ "nodes": [
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": -50
+ },
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 66
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 94,
+ "type": "Note",
+ "pos": {
+ "0": 17,
+ "1": -35
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 95,
+ "type": "Note",
+ "pos": {
+ "0": 35.71394348144531,
+ "1": 536.9210205078125
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload image here\n(你可以在此上传图片)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1271,
+ "1": -67
+ },
+ "size": [
+ 390,
+ 537.4615384615385
+ ],
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 64,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00008.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": {
+ "0": -95.01139068603516,
+ "1": -334.30706787109375
+ },
+ "size": {
+ "0": 355.636474609375,
+ "1": 132.4238739013672
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 87,
+ "type": "LoadImage",
+ "pos": {
+ "0": 308,
+ "1": 482
+ },
+ "size": {
+ "0": 315,
+ "1": 314
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 68
+ ]
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "2.png",
+ "image"
+ ]
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 250,
+ "1": 160
+ },
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 67
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 99,
+ "type": "LoadWan2_2FunModel",
+ "pos": {
+ "0": 290,
+ "1": -334
+ },
+ "size": {
+ "0": 315,
+ "1": 154
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 65
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWan2_2FunModel"
+ },
+ "widgets_values": [
+ "Wan2.2-Fun-A14B-InP",
+ "Inpaint",
+ "sequential_cpu_offload",
+ "wan2.2/wan_civitai_i2v.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 101,
+ "type": "Wan2_2FunInpaintSampler",
+ "pos": {
+ "0": 771,
+ "1": -67
+ },
+ "size": {
+ "0": 428.4000244140625,
+ "1": 378
+ },
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 65
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 66
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 67
+ },
+ {
+ "name": "start_img",
+ "type": "IMAGE",
+ "link": 68,
+ "shape": 7
+ },
+ {
+ "name": "end_img",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 64
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "Wan2_2FunInpaintSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "randomize",
+ 50,
+ 6,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ }
+ ],
+ "links": [
+ [
+ 64,
+ 101,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 65,
+ 99,
+ 0,
+ 101,
+ 0,
+ "FunModels"
+ ],
+ [
+ 66,
+ 75,
+ 0,
+ 101,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 67,
+ 73,
+ 0,
+ 101,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 68,
+ 87,
+ 0,
+ 101,
+ 3,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Load Image",
+ "bounding": [
+ 222,
+ 396,
+ 458,
+ 436
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load Model",
+ "bounding": [
+ 227,
+ -416,
+ 469,
+ 256
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.8264462809917354,
+ "offset": [
+ 73.82229219905072,
+ 565.0461564576733
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "10076a3aee6547541ca9442bf22389bfc2ea7526",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "comfy-core": "v0.2.7-3-g8afb97c"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_t2v.json b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_t2v.json
new file mode 100644
index 0000000000000000000000000000000000000000..9a8fdc6d524372df9afbaafb2fbe6c63cfca244d
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_t2v.json
@@ -0,0 +1,409 @@
+{
+ "id": "8d9a378f-1cac-4610-8858-351d5982a6ab",
+ "revision": 0,
+ "last_node_id": 103,
+ "last_link_id": 73,
+ "nodes": [
+ {
+ "id": 75,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ -50
+ ],
+ "size": [
+ 383.54010009765625,
+ 156.71620178222656
+ ],
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 72
+ ]
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 94,
+ "type": "Note",
+ "pos": [
+ 17,
+ -35
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": [
+ -95.01139068603516,
+ -334.30706787109375
+ ],
+ "size": [
+ 355.636474609375,
+ 132.4238739013672
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 73,
+ "type": "FunTextBox",
+ "pos": [
+ 250,
+ 160
+ ],
+ "size": [
+ 383.7149963378906,
+ 183.83506774902344
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 73
+ ]
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1257.373291015625,
+ -146.444091796875
+ ],
+ "size": [
+ 390,
+ 537.4615478515625
+ ],
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "label": "图像",
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 70
+ },
+ {
+ "label": "音频",
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "label": "批次管理",
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "label": "文件名",
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "slot_index": 0,
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00008.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 99,
+ "type": "LoadWan2_2FunModel",
+ "pos": [
+ 290,
+ -334
+ ],
+ "size": [
+ 315,
+ 154
+ ],
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 71
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWan2_2FunModel"
+ },
+ "widgets_values": [
+ "Wan2.2-Fun-A14B-InP",
+ "Inpaint",
+ "sequential_cpu_offload",
+ "wan2.2/wan_civitai_i2v.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 103,
+ "type": "Wan2_2FunT2VSampler",
+ "pos": [
+ 819.128173828125,
+ -145.90399169921875
+ ],
+ "size": [
+ 340.3540954589844,
+ 430
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 71
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 72
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 73
+ },
+ {
+ "name": "riflex_k",
+ "shape": 7,
+ "type": "RIFLEXT_ARGS",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 70
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "Wan2_2FunT2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 832,
+ 480,
+ false,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ }
+ ],
+ "links": [
+ [
+ 70,
+ 103,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 71,
+ 99,
+ 0,
+ 103,
+ 0,
+ "FunModels"
+ ],
+ [
+ 72,
+ 75,
+ 0,
+ 103,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 73,
+ 73,
+ 0,
+ 103,
+ 2,
+ "STRING_PROMPT"
+ ]
+ ],
+ "groups": [
+ {
+ "id": 2,
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 3,
+ "title": "Load Model",
+ "bounding": [
+ 227,
+ -416,
+ 469,
+ 256
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.8264462809917354,
+ "offset": [
+ 175.2685031365507,
+ 463.74646895767313
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "5f2a55692d0834e00d477939b818b9bb63c06535",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
+ },
+ "frontendVersion": "1.21.3"
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_v2v_control.json b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_v2v_control.json
new file mode 100644
index 0000000000000000000000000000000000000000..308b51aa21d20ed3f3bd63846011a4cd0f98bc33
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_v2v_control.json
@@ -0,0 +1,574 @@
+{
+ "last_node_id": 97,
+ "last_link_id": 65,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": {
+ "0": 15.739953994750977,
+ "1": 462.38665771484375
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 88,
+ "type": "Note",
+ "pos": {
+ "0": -99,
+ "1": 197
+ },
+ "size": {
+ "0": 326.1556091308594,
+ "1": 145.20904541015625
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 89,
+ "type": "Note",
+ "pos": {
+ "0": -192,
+ "1": -293
+ },
+ "size": {
+ "0": 427.074951171875,
+ "1": 143.9142608642578
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": {
+ "0": 335,
+ "1": 476
+ },
+ "size": [
+ 252.056640625,
+ 688.5451388888889
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 64
+ ],
+ "slot_index": 0,
+ "shape": 3
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "pose.mp4",
+ "force_rate": 0,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 0,
+ "filename": "pose.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 92,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 254,
+ "1": -46
+ },
+ "size": {
+ "0": 380.845703125,
+ "1": 157.68350219726562
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 62
+ ],
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "在这个阳光明媚的户外花园里,美女身穿一袭及膝的白色无袖连衣裙,裙摆在她轻盈的舞姿中轻柔地摆动,宛如一只翩翩起舞的蝴蝶。阳光透过树叶间洒下斑驳的光影,映衬出她柔和的脸庞和清澈的眼眸,显得格外优雅。仿佛每一个动作都在诉说着青春与活力,她在草地上旋转,裙摆随之飞扬,仿佛整个花园都因她的舞动而欢愉。周围五彩缤纷的花朵在微风中摇曳,玫瑰、菊花、百合,各自释放出阵阵香气,营造出一种轻松而愉快的氛围。"
+ ]
+ },
+ {
+ "id": 94,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 258,
+ "1": 178
+ },
+ "size": {
+ "0": 368.5529479980469,
+ "1": 159.4075927734375
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 63
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1274,
+ "1": 10
+ },
+ "size": [
+ 390.9534912109375,
+ 966.9860514322917
+ ],
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 65,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00004.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 97,
+ "type": "Wan2_2FunV2VSampler",
+ "pos": {
+ "0": 792,
+ "1": 11
+ },
+ "size": [
+ 428.4000244140625,
+ 486
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 61
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 62
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 63
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": 64,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "end_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "ref_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": null,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 65
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "Wan2_2FunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1.0,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ },
+ {
+ "id": 95,
+ "type": "LoadWan2_2FunModel",
+ "pos": {
+ "0": 275,
+ "1": -309
+ },
+ "size": {
+ "0": 435.2322082519531,
+ "1": 154
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 61
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWan2_2FunModel"
+ },
+ "widgets_values": [
+ "Wan2.2-Fun-A14B-Control",
+ "Control",
+ "sequential_cpu_offload",
+ "wan2.2/wan_civitai_i2v.yaml",
+ "bf16"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 61,
+ 95,
+ 0,
+ 97,
+ 0,
+ "FunModels"
+ ],
+ [
+ 62,
+ 92,
+ 0,
+ 97,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 63,
+ 94,
+ 0,
+ 97,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 64,
+ 85,
+ 0,
+ 97,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 65,
+ 97,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load Model",
+ "bounding": [
+ 218,
+ -387,
+ 542,
+ 248
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Upload Your Video",
+ "bounding": [
+ 218,
+ 385,
+ 487,
+ 789
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650709,
+ "offset": [
+ 249.86519634240904,
+ 438.3739973625246
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "CogVideoX-Fun": "717f0629175ad192927dc51ec95c4376816a4212"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_v2v_control_canny.json b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_v2v_control_canny.json
new file mode 100644
index 0000000000000000000000000000000000000000..d458e195df46952c64fc39552af5391ec07e5f47
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_v2v_control_canny.json
@@ -0,0 +1,700 @@
+{
+ "id": "90329caf-a94f-48a6-80d7-d6e167a8b1e3",
+ "revision": 0,
+ "last_node_id": 102,
+ "last_link_id": 78,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": [
+ 15.739953994750977,
+ 462.38665771484375
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 88,
+ "type": "Note",
+ "pos": [
+ -99,
+ 197
+ ],
+ "size": [
+ 326.1556091308594,
+ 145.20904541015625
+ ],
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 89,
+ "type": "Note",
+ "pos": [
+ -192,
+ -293
+ ],
+ "size": [
+ 427.074951171875,
+ 143.9142608642578
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 92,
+ "type": "FunTextBox",
+ "pos": [
+ 254,
+ -46
+ ],
+ "size": [
+ 380.845703125,
+ 157.68350219726562
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 73
+ ]
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "在这个阳光明媚的户外花园里,美女身穿一袭及膝的白色无袖连衣裙,裙摆在她轻盈的舞姿中轻柔地摆动,宛如一只翩翩起舞的蝴蝶。阳光透过树叶间洒下斑驳的光影,映衬出她柔和的脸庞和清澈的眼眸,显得格外优雅。仿佛每一个动作都在诉说着青春与活力,她在草地上旋转,裙摆随之飞扬,仿佛整个花园都因她的舞动而欢愉。周围五彩缤纷的花朵在微风中摇曳,玫瑰、菊花、百合,各自释放出阵阵香气,营造出一种轻松而愉快的氛围。"
+ ]
+ },
+ {
+ "id": 99,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1094,
+ 559
+ ],
+ "size": [
+ 315,
+ 851.4834594726562
+ ],
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 65
+ },
+ {
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun-Preprocess-Video",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 19,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "AnimateDiff_00001.gif",
+ "subfolder": "",
+ "type": "output",
+ "format": "image/gif",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 94,
+ "type": "FunTextBox",
+ "pos": [
+ 258,
+ 178
+ ],
+ "size": [
+ 368.5529479980469,
+ 159.4075927734375
+ ],
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 74
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 97,
+ "type": "VideoToCanny",
+ "pos": [
+ 729,
+ 566
+ ],
+ "size": [
+ 315,
+ 106
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "input_video",
+ "type": "IMAGE",
+ "link": 66
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "slot_index": 0,
+ "links": [
+ 65,
+ 75
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VideoToCanny"
+ },
+ "widgets_values": [
+ 100,
+ 200,
+ 81
+ ]
+ },
+ {
+ "id": 101,
+ "type": "LoadWan2_2FunModel",
+ "pos": [
+ 306.2298583984375,
+ -313.5478515625
+ ],
+ "size": [
+ 397.9565734863281,
+ 154
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 78
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWan2_2FunModel"
+ },
+ "widgets_values": [
+ "Wan2.2-Fun-A14B-Control",
+ "Control",
+ "sequential_cpu_offload",
+ "wan2.2/wan_civitai_i2v.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1465.6671142578125,
+ -174.95152282714844
+ ],
+ "size": [
+ 390.9534912109375,
+ 966.9860229492188
+ ],
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "label": "图像",
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 77
+ },
+ {
+ "label": "音频",
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "label": "批次管理",
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "label": "文件名",
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "slot_index": 0,
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00004.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": [
+ 335,
+ 476
+ ],
+ "size": [
+ 252.056640625,
+ 409.87884521484375
+ ],
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "slot_index": 0,
+ "links": [
+ 66
+ ]
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "00000005.mp4",
+ "force_rate": 0,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 0,
+ "filename": "00000005.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 102,
+ "type": "Wan2_2FunV2VSampler",
+ "pos": [
+ 848.4100341796875,
+ -180.23484802246094
+ ],
+ "size": [
+ 458.36383056640625,
+ 526
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 78
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 73
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 74
+ },
+ {
+ "name": "validation_video",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "control_video",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 75
+ },
+ {
+ "name": "start_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "end_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "ref_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "camera_conditions",
+ "shape": 7,
+ "type": "STRING",
+ "link": null
+ },
+ {
+ "name": "riflex_k",
+ "shape": 7,
+ "type": "RIFLEXT_ARGS",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 77
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "Wan2_2FunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6.000000000000001,
+ 1,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ }
+ ],
+ "links": [
+ [
+ 65,
+ 97,
+ 0,
+ 99,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 66,
+ 85,
+ 0,
+ 97,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 73,
+ 92,
+ 0,
+ 102,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 74,
+ 94,
+ 0,
+ 102,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 75,
+ 97,
+ 0,
+ 102,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 77,
+ 102,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 78,
+ 101,
+ 0,
+ 102,
+ 0,
+ "FunModels"
+ ]
+ ],
+ "groups": [
+ {
+ "id": 1,
+ "title": "Upload Your Video",
+ "bounding": [
+ 218,
+ 385,
+ 487,
+ 789
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 2,
+ "title": "Load Model",
+ "bounding": [
+ 218,
+ -387,
+ 542,
+ 248
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 3,
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650709,
+ "offset": [
+ 192.62803696741028,
+ 413.1926211906501
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "e935795d7684aaba72be65d2ad5ef580c0526f7a",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
+ },
+ "frontendVersion": "1.21.3"
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_v2v_control_depth.json b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_v2v_control_depth.json
new file mode 100644
index 0000000000000000000000000000000000000000..4ca78992b3ee6623ed3d4baa121d972a3e0b53b1
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_v2v_control_depth.json
@@ -0,0 +1,697 @@
+{
+ "id": "90329caf-a94f-48a6-80d7-d6e167a8b1e3",
+ "revision": 0,
+ "last_node_id": 103,
+ "last_link_id": 83,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": [
+ 15.739953994750977,
+ 462.38665771484375
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 88,
+ "type": "Note",
+ "pos": [
+ -99,
+ 197
+ ],
+ "size": [
+ 326.1556091308594,
+ 145.20904541015625
+ ],
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 89,
+ "type": "Note",
+ "pos": [
+ -192,
+ -293
+ ],
+ "size": [
+ 427.074951171875,
+ 143.9142608642578
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 92,
+ "type": "FunTextBox",
+ "pos": [
+ 254,
+ -46
+ ],
+ "size": [
+ 380.845703125,
+ 157.68350219726562
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 73
+ ]
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "在这个阳光明媚的户外花园里,美女身穿一袭及膝的白色无袖连衣裙,裙摆在她轻盈的舞姿中轻柔地摆动,宛如一只翩翩起舞的蝴蝶。阳光透过树叶间洒下斑驳的光影,映衬出她柔和的脸庞和清澈的眼眸,显得格外优雅。仿佛每一个动作都在诉说着青春与活力,她在草地上旋转,裙摆随之飞扬,仿佛整个花园都因她的舞动而欢愉。周围五彩缤纷的花朵在微风中摇曳,玫瑰、菊花、百合,各自释放出阵阵香气,营造出一种轻松而愉快的氛围。"
+ ]
+ },
+ {
+ "id": 99,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1094,
+ 559
+ ],
+ "size": [
+ 315,
+ 851.4834594726562
+ ],
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 81
+ },
+ {
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun-Preprocess-Video",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 19,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "AnimateDiff_00001.gif",
+ "subfolder": "",
+ "type": "output",
+ "format": "image/gif",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
+ {
+ "id": 94,
+ "type": "FunTextBox",
+ "pos": [
+ 258,
+ 178
+ ],
+ "size": [
+ 368.5529479980469,
+ 159.4075927734375
+ ],
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 74
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 101,
+ "type": "LoadWan2_2FunModel",
+ "pos": [
+ 306.2298583984375,
+ -313.5478515625
+ ],
+ "size": [
+ 397.9565734863281,
+ 154
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 78
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWan2_2FunModel"
+ },
+ "widgets_values": [
+ "Wan2.2-Fun-A14B-Control",
+ "Control",
+ "sequential_cpu_offload",
+ "wan2.2/wan_civitai_i2v.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1465.6671142578125,
+ -174.95152282714844
+ ],
+ "size": [
+ 390.9534912109375,
+ 966.9860229492188
+ ],
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "label": "图像",
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 77
+ },
+ {
+ "label": "音频",
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "label": "批次管理",
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "label": "文件名",
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "slot_index": 0,
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00004.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": [
+ 335,
+ 476
+ ],
+ "size": [
+ 252.056640625,
+ 409.87884521484375
+ ],
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "slot_index": 0,
+ "links": [
+ 82
+ ]
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "00000005.mp4",
+ "force_rate": 0,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 0,
+ "filename": "00000005.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 102,
+ "type": "Wan2_2FunV2VSampler",
+ "pos": [
+ 848.4100341796875,
+ -180.23484802246094
+ ],
+ "size": [
+ 458.36383056640625,
+ 526
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 78
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 73
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 74
+ },
+ {
+ "name": "validation_video",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "control_video",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 83
+ },
+ {
+ "name": "start_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "end_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "ref_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "camera_conditions",
+ "shape": 7,
+ "type": "STRING",
+ "link": null
+ },
+ {
+ "name": "riflex_k",
+ "shape": 7,
+ "type": "RIFLEXT_ARGS",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 77
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "Wan2_2FunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6.000000000000001,
+ 1,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ },
+ {
+ "id": 103,
+ "type": "VideoToDepth",
+ "pos": [
+ 734.0958862304688,
+ 474.7727355957031
+ ],
+ "size": [
+ 270,
+ 58
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "input_video",
+ "type": "IMAGE",
+ "link": 82
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 81,
+ 83
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VideoToDepth"
+ },
+ "widgets_values": [
+ 81
+ ]
+ }
+ ],
+ "links": [
+ [
+ 73,
+ 92,
+ 0,
+ 102,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 74,
+ 94,
+ 0,
+ 102,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 77,
+ 102,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 78,
+ 101,
+ 0,
+ 102,
+ 0,
+ "FunModels"
+ ],
+ [
+ 81,
+ 103,
+ 0,
+ 99,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 82,
+ 85,
+ 0,
+ 103,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 83,
+ 103,
+ 0,
+ 102,
+ 4,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "id": 1,
+ "title": "Upload Your Video",
+ "bounding": [
+ 218,
+ 385,
+ 487,
+ 789
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 2,
+ "title": "Load Model",
+ "bounding": [
+ 218,
+ -387,
+ 542,
+ 248
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 3,
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650709,
+ "offset": [
+ 192.62803696741028,
+ 413.1926211906501
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "e935795d7684aaba72be65d2ad5ef580c0526f7a",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
+ },
+ "frontendVersion": "1.21.3"
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_v2v_control_pose_ref.json b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_v2v_control_pose_ref.json
new file mode 100644
index 0000000000000000000000000000000000000000..7bde83670b0c31148c684898f25a96d3cd19df54
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_v2v_control_pose_ref.json
@@ -0,0 +1,753 @@
+{
+ "id": "c5a53a91-88dc-41d4-b414-12e402c59e4c",
+ "revision": 0,
+ "last_node_id": 105,
+ "last_link_id": 91,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": [
+ -111.46612548828125,
+ 460.2178955078125
+ ],
+ "size": [
+ 210,
+ 88
+ ],
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 88,
+ "type": "Note",
+ "pos": [
+ -99,
+ 197
+ ],
+ "size": [
+ 326.1556091308594,
+ 145.20904541015625
+ ],
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 89,
+ "type": "Note",
+ "pos": [
+ -192,
+ -293
+ ],
+ "size": [
+ 427.074951171875,
+ 143.9142608642578
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 99,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1005,
+ 554
+ ],
+ "size": [
+ 315,
+ 849.46875
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 73
+ },
+ {
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun-Preprocess-Video",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 19,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun-Preprocess-Video_00007.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": [
+ 207.79391479492188,
+ 473.83123779296875
+ ],
+ "size": [
+ 252.056640625,
+ 688.545166015625
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "slot_index": 0,
+ "links": [
+ 72
+ ]
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "000007.mp4",
+ "force_rate": 16,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 16,
+ "filename": "000007.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1488,
+ 8
+ ],
+ "size": [
+ 390.9534912109375,
+ 942.2557983398438
+ ],
+ "flags": {},
+ "order": 12,
+ "mode": 0,
+ "inputs": [
+ {
+ "label": "图像",
+ "name": "images",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 84
+ },
+ {
+ "label": "音频",
+ "name": "audio",
+ "shape": 7,
+ "type": "AUDIO",
+ "link": null
+ },
+ {
+ "label": "批次管理",
+ "name": "meta_batch",
+ "shape": 7,
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "shape": 7,
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "label": "文件名",
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "slot_index": 0,
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00049.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 102,
+ "type": "LoadImage",
+ "pos": [
+ 553,
+ 598
+ ],
+ "size": [
+ 315,
+ 314
+ ],
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 86
+ ]
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "9.png",
+ "image"
+ ]
+ },
+ {
+ "id": 101,
+ "type": "VideoToOpenpose",
+ "pos": [
+ 558,
+ 474
+ ],
+ "size": [
+ 315,
+ 58
+ ],
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "input_video",
+ "type": "IMAGE",
+ "link": 72
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "slot_index": 0,
+ "links": [
+ 73,
+ 87,
+ 91
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VideoToOpenpose"
+ },
+ "widgets_values": [
+ 81
+ ]
+ },
+ {
+ "id": 104,
+ "type": "LoadWan2_2FunModel",
+ "pos": [
+ 303.9479064941406,
+ -309.996337890625
+ ],
+ "size": [
+ 390.1385192871094,
+ 154
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 88
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWan2_2FunModel"
+ },
+ "widgets_values": [
+ "Wan2.2-Fun-A14B-Control",
+ "Control",
+ "sequential_cpu_offload",
+ "wan2.2/wan_civitai_i2v.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 92,
+ "type": "FunTextBox",
+ "pos": [
+ 254,
+ -46
+ ],
+ "size": [
+ 380.845703125,
+ 157.68350219726562
+ ],
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 89
+ ]
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "一位动漫风格的女孩。她有着紫色的短发,头上戴着一个黑色和金色相间的蝴蝶结。她的表情显得有些严肃或沉思,眼睛大而有神。女孩穿着一件白色衬衫,外面搭配了一件深蓝色的背心,背心上有一个粉色的蝴蝶结装饰。她的裙子是白色的,裙摆蓬松,整体造型非常可爱且精致。背景是一个简单的圆形图案,颜色为粉红色和灰色相间,给人一种柔和的感觉。整个画面色调柔和,人物形象生动鲜明。"
+ ]
+ },
+ {
+ "id": 94,
+ "type": "FunTextBox",
+ "pos": [
+ 258,
+ 178
+ ],
+ "size": [
+ 368.5529479980469,
+ 159.4075927734375
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "slot_index": 0,
+ "links": [
+ 90
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 105,
+ "type": "Wan2_2FunV2VSampler",
+ "pos": [
+ 987.7456665039062,
+ -76.86135864257812
+ ],
+ "size": [
+ 434.938232421875,
+ 526
+ ],
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 88
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 89
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 90
+ },
+ {
+ "name": "validation_video",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 91
+ },
+ {
+ "name": "control_video",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 87
+ },
+ {
+ "name": "start_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "end_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": null
+ },
+ {
+ "name": "ref_image",
+ "shape": 7,
+ "type": "IMAGE",
+ "link": 86
+ },
+ {
+ "name": "camera_conditions",
+ "shape": 7,
+ "type": "STRING",
+ "link": null
+ },
+ {
+ "name": "riflex_k",
+ "shape": 7,
+ "type": "RIFLEXT_ARGS",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 84
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "Wan2_2FunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6.000000000000001,
+ 1,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ }
+ ],
+ "links": [
+ [
+ 72,
+ 85,
+ 0,
+ 101,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 73,
+ 101,
+ 0,
+ 99,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 84,
+ 105,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 86,
+ 102,
+ 0,
+ 105,
+ 7,
+ "IMAGE"
+ ],
+ [
+ 87,
+ 101,
+ 0,
+ 105,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 88,
+ 104,
+ 0,
+ 105,
+ 0,
+ "FunModels"
+ ],
+ [
+ 89,
+ 92,
+ 0,
+ 105,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 90,
+ 94,
+ 0,
+ 105,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 91,
+ 101,
+ 0,
+ 105,
+ 3,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "id": 1,
+ "title": "Upload Your Video And Reference Image",
+ "bounding": [
+ 91,
+ 383,
+ 859,
+ 841
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 2,
+ "title": "Load Model",
+ "bounding": [
+ 218,
+ -387,
+ 542,
+ 248
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "id": 3,
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.7513148009015781,
+ "offset": [
+ 235.41928184428536,
+ 445.7655228500244
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "comfy-core": "0.3.44",
+ "CogVideoX-Fun": "e935795d7684aaba72be65d2ad5ef580c0526f7a"
+ },
+ "frontendVersion": "1.21.3"
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_v2v_control_ref.json b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_v2v_control_ref.json
new file mode 100644
index 0000000000000000000000000000000000000000..e0ba01a94fffd24075484033a9edd958495366e9
--- /dev/null
+++ b/VideoX-Fun/comfyui/wan2_2_fun/v1/wan2.2_fun_workflow_v2v_control_ref.json
@@ -0,0 +1,620 @@
+{
+ "last_node_id": 98,
+ "last_link_id": 67,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": {
+ "0": 15.145149230957031,
+ "1": 527.0673217773438
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 88,
+ "type": "Note",
+ "pos": {
+ "0": -99,
+ "1": 197
+ },
+ "size": {
+ "0": 326.1556091308594,
+ "1": 145.20904541015625
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 89,
+ "type": "Note",
+ "pos": {
+ "0": -192,
+ "1": -293
+ },
+ "size": {
+ "0": 427.074951171875,
+ "1": 143.9142608642578
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": {
+ "0": 334.4051513671875,
+ "1": 540.6806640625
+ },
+ "size": [
+ 252.056640625,
+ 688.5451388888889
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 65
+ ],
+ "slot_index": 0,
+ "shape": 3
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "pose.mp4",
+ "force_rate": 0,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 0,
+ "filename": "pose.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 94,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 258,
+ "1": 178
+ },
+ "size": {
+ "0": 368.5529479980469,
+ "1": 159.4075927734375
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 64
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1274,
+ "1": -77
+ },
+ "size": [
+ 390.9534912109375,
+ 942.2558186848959
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 67,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00051.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 92,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 254,
+ "1": -46
+ },
+ "size": {
+ "0": 380.845703125,
+ "1": 157.68350219726562
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 63
+ ],
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "一位动漫风格的女孩。她有着紫色的短发,头上戴着一个黑色和金色相间的蝴蝶结。她的表情显得有些严肃或沉思,眼睛大而有神。女孩穿着一件白色衬衫,外面搭配了一件深蓝色的背心,背心上有一个粉色的蝴蝶结装饰。她的裙子是白色的,裙摆蓬松,整体造型非常可爱且精致。背景是一个简单的圆形图案,颜色为粉红色和灰色相间,给人一种柔和的感觉。整个画面色调柔和,人物形象生动鲜明。"
+ ]
+ },
+ {
+ "id": 97,
+ "type": "LoadImage",
+ "pos": {
+ "0": 629,
+ "1": 553
+ },
+ "size": {
+ "0": 315,
+ "1": 314
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 66
+ ]
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "9.png",
+ "image"
+ ]
+ },
+ {
+ "id": 95,
+ "type": "LoadWan2_2FunModel",
+ "pos": {
+ "0": 275,
+ "1": -309
+ },
+ "size": {
+ "0": 435.2322082519531,
+ "1": 154
+ },
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 62
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWan2_2FunModel"
+ },
+ "widgets_values": [
+ "Wan2.2-Fun-A14B-Control",
+ "Control",
+ "sequential_cpu_offload",
+ "wan2.2/wan_civitai_i2v.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 98,
+ "type": "Wan2_2FunV2VSampler",
+ "pos": {
+ "0": 798,
+ "1": -77
+ },
+ "size": [
+ 428.4000244140625,
+ 486
+ ],
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 62
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 63
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 64
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": 65,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "end_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "ref_image",
+ "type": "IMAGE",
+ "link": 66,
+ "shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": null,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 67
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "Wan2_2FunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1.0,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ 0
+ ]
+ }
+ ],
+ "links": [
+ [
+ 62,
+ 95,
+ 0,
+ 98,
+ 0,
+ "FunModels"
+ ],
+ [
+ 63,
+ 92,
+ 0,
+ 98,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 64,
+ 94,
+ 0,
+ 98,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 65,
+ 85,
+ 0,
+ 98,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 66,
+ 97,
+ 0,
+ 98,
+ 6,
+ "IMAGE"
+ ],
+ [
+ 67,
+ 98,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Upload Your Video",
+ "bounding": [
+ 217,
+ 450,
+ 761,
+ 789
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load Model",
+ "bounding": [
+ 218,
+ -387,
+ 542,
+ 248
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.8264462809917358,
+ "offset": [
+ 23.894387748659057,
+ 254.96144111252457
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "CogVideoX-Fun": "a7fa7028d52498f13e983eba012a81ebcae24977",
+ "comfy-core": "v0.2.7-3-g8afb97c"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file