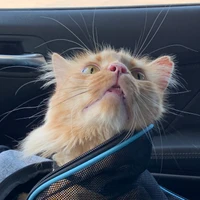
Text-to-Image
Diffusers
PyTorch
StableDiffusionPipeline
stable-diffusion
diffusion-models-class
dreambooth-hackathon
animal
Instructions to use jefsnacker/azzy with libraries, inference providers, notebooks, and local apps. Follow these links to get started.
- Libraries
- Diffusers
How to use jefsnacker/azzy with Diffusers:
pip install -U diffusers transformers accelerate
import torch from diffusers import DiffusionPipeline # switch to "mps" for apple devices pipe = DiffusionPipeline.from_pretrained("jefsnacker/azzy", dtype=torch.bfloat16, device_map="cuda") prompt = "portrait of azzy cat anthro as a dapper bartender with a big, fluffy tail, retro futurism, art deco, detailed, painterly digital art by wlop and cory loftis and delphin enjolras, ๐ฟ๐ธ๐, furaffinity, trending on artstation" image = pipe(prompt).images[0] - Notebooks
- Google Colab
- Kaggle
- Local Apps Settings
- Draw Things
- DiffusionBee
Commit History
-
Add model to competition
d4d5120 -
remove a sentence
eb939b7 -
small changes
9817415 -
Update README with output images
38ed149 -
rm fake file
18ab309 -
upload output images
a3f46ee -
add a fake file to make a dir
10ac321
-
Update README.md
a28f83e -
Update README.md
9a11185 -
Upload concept_images with huggingface_hub
bd70102 -
Upload with huggingface_hub
7c29c09 -
Upload the concept azzy embeds and token
a271429 -
initial commit
a5256d7