

v0.46.1
Browse filesSee https://github.com/quic/ai-hub-models/releases/v0.46.1 for changelog.
- README.md +73 -221
- Sequencer2D_float.dlc +0 -3
- Sequencer2D_float.onnx.zip +0 -3
- Sequencer2D_float.tflite +0 -3
- tool-versions.yaml +0 -4
README.md
CHANGED
|
@@ -9,239 +9,91 @@ pipeline_tag: image-classification
|
|
| 9 |
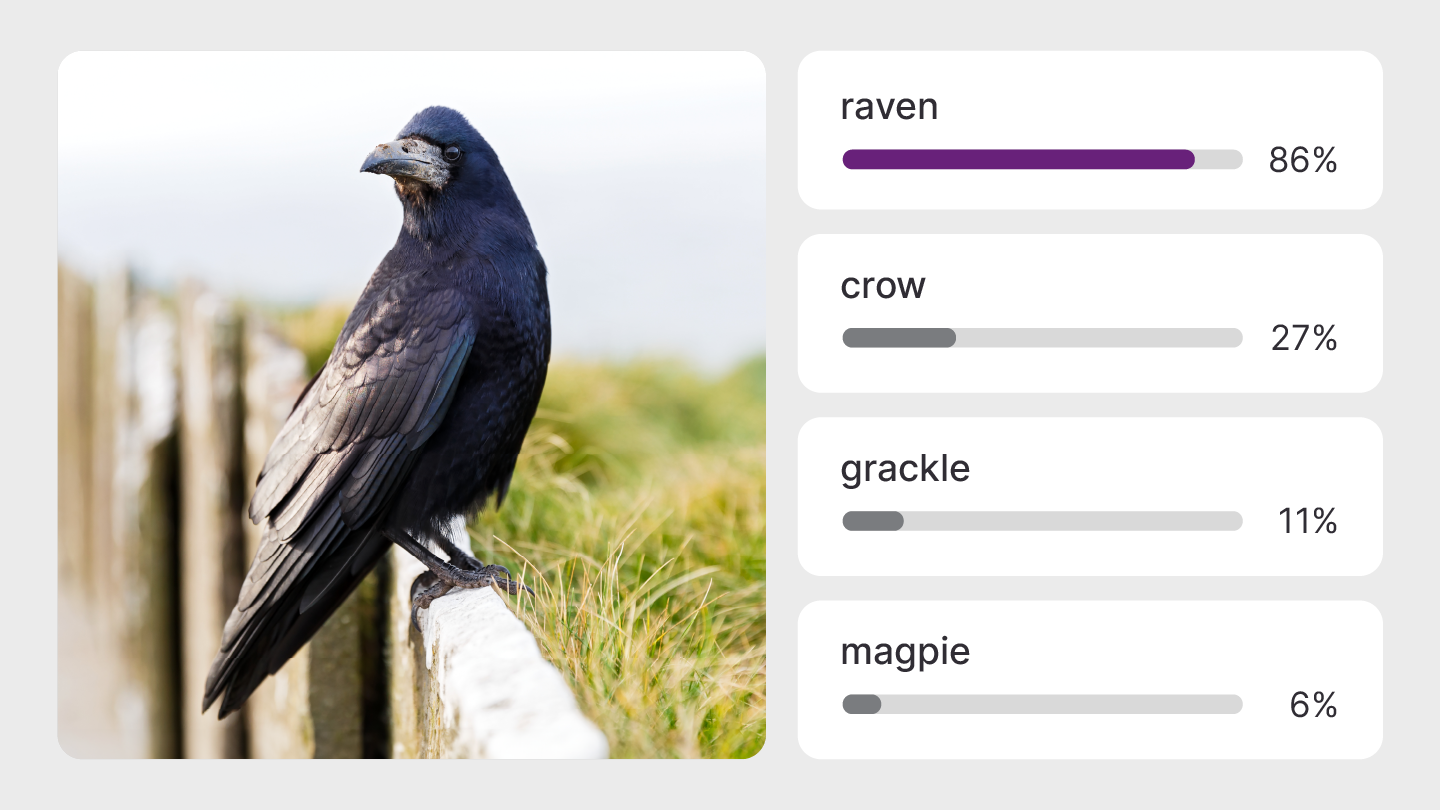
|
| 10 |
|
| 11 |
|
| 12 |
-
# Sequencer2D: Optimized for
|
| 13 |
-
## Imagenet classifier and general purpose backbone
|
| 14 |
-
|
| 15 |
|
| 16 |
Sequencer2D is a vision transformer model that can classify images from the Imagenet dataset.
|
| 17 |
|
| 18 |
-
This
|
| 19 |
-
|
| 20 |
-
|
| 21 |
-
|
| 22 |
-
|
| 23 |
-
|
| 24 |
-
|
| 25 |
-
|
| 26 |
-
|
| 27 |
-
|
| 28 |
-
|
| 29 |
-
|
| 30 |
-
|
| 31 |
-
|
| 32 |
-
|
| 33 |
-
|
| 34 |
-
|
| 35 |
-
|
| 36 |
-
|
| 37 |
-
|
| 38 |
-
|
| 39 |
-
|
| 40 |
-
|
| 41 |
-
|
| 42 |
-
|
| 43 |
-
|
| 44 |
-
|
| 45 |
-
|
| 46 |
-
|
| 47 |
-
|
| 48 |
-
|
| 49 |
-
|
| 50 |
-
|
| 51 |
-
|
| 52 |
-
|
| 53 |
-
|
| 54 |
-
|
| 55 |
-
|
| 56 |
-
|
| 57 |
-
|
| 58 |
-
|
| 59 |
-
|
| 60 |
-
|
| 61 |
-
|
| 62 |
-
##
|
| 63 |
-
|
| 64 |
-
|
| 65 |
-
|
| 66 |
-
|
| 67 |
-
|
| 68 |
-
|
| 69 |
-
|
| 70 |
-
|
| 71 |
-
|
| 72 |
-
|
| 73 |
-
|
| 74 |
-
|
| 75 |
-
|
| 76 |
-
|
| 77 |
-
|
| 78 |
-
|
| 79 |
-
|
| 80 |
-
|
| 81 |
-
|
| 82 |
-
|
| 83 |
-
|
| 84 |
-
|
| 85 |
-
|
| 86 |
-
|
| 87 |
-
|
| 88 |
-
|
| 89 |
-
|
| 90 |
-
|
| 91 |
-
```bash
|
| 92 |
-
python -m qai_hub_models.models.sequencer2d.demo
|
| 93 |
-
```
|
| 94 |
-
|
| 95 |
-
The above demo runs a reference implementation of pre-processing, model
|
| 96 |
-
inference, and post processing.
|
| 97 |
-
|
| 98 |
-
**NOTE**: If you want running in a Jupyter Notebook or Google Colab like
|
| 99 |
-
environment, please add the following to your cell (instead of the above).
|
| 100 |
-
```
|
| 101 |
-
%run -m qai_hub_models.models.sequencer2d.demo
|
| 102 |
-
```
|
| 103 |
-
|
| 104 |
-
|
| 105 |
-
### Run model on a cloud-hosted device
|
| 106 |
-
|
| 107 |
-
In addition to the demo, you can also run the model on a cloud-hosted Qualcomm®
|
| 108 |
-
device. This script does the following:
|
| 109 |
-
* Performance check on-device on a cloud-hosted device
|
| 110 |
-
* Downloads compiled assets that can be deployed on-device for Android.
|
| 111 |
-
* Accuracy check between PyTorch and on-device outputs.
|
| 112 |
-
|
| 113 |
-
```bash
|
| 114 |
-
python -m qai_hub_models.models.sequencer2d.export
|
| 115 |
-
```
|
| 116 |
-
|
| 117 |
-
|
| 118 |
-
|
| 119 |
-
## How does this work?
|
| 120 |
-
|
| 121 |
-
This [export script](https://aihub.qualcomm.com/models/sequencer2d/qai_hub_models/models/Sequencer2D/export.py)
|
| 122 |
-
leverages [Qualcomm® AI Hub](https://aihub.qualcomm.com/) to optimize, validate, and deploy this model
|
| 123 |
-
on-device. Lets go through each step below in detail:
|
| 124 |
-
|
| 125 |
-
Step 1: **Compile model for on-device deployment**
|
| 126 |
-
|
| 127 |
-
To compile a PyTorch model for on-device deployment, we first trace the model
|
| 128 |
-
in memory using the `jit.trace` and then call the `submit_compile_job` API.
|
| 129 |
-
|
| 130 |
-
```python
|
| 131 |
-
import torch
|
| 132 |
-
|
| 133 |
-
import qai_hub as hub
|
| 134 |
-
from qai_hub_models.models.sequencer2d import Model
|
| 135 |
-
|
| 136 |
-
# Load the model
|
| 137 |
-
torch_model = Model.from_pretrained()
|
| 138 |
-
|
| 139 |
-
# Device
|
| 140 |
-
device = hub.Device("Samsung Galaxy S25")
|
| 141 |
-
|
| 142 |
-
# Trace model
|
| 143 |
-
input_shape = torch_model.get_input_spec()
|
| 144 |
-
sample_inputs = torch_model.sample_inputs()
|
| 145 |
-
|
| 146 |
-
pt_model = torch.jit.trace(torch_model, [torch.tensor(data[0]) for _, data in sample_inputs.items()])
|
| 147 |
-
|
| 148 |
-
# Compile model on a specific device
|
| 149 |
-
compile_job = hub.submit_compile_job(
|
| 150 |
-
model=pt_model,
|
| 151 |
-
device=device,
|
| 152 |
-
input_specs=torch_model.get_input_spec(),
|
| 153 |
-
)
|
| 154 |
-
|
| 155 |
-
# Get target model to run on-device
|
| 156 |
-
target_model = compile_job.get_target_model()
|
| 157 |
-
|
| 158 |
-
```
|
| 159 |
-
|
| 160 |
-
|
| 161 |
-
Step 2: **Performance profiling on cloud-hosted device**
|
| 162 |
-
|
| 163 |
-
After compiling models from step 1. Models can be profiled model on-device using the
|
| 164 |
-
`target_model`. Note that this scripts runs the model on a device automatically
|
| 165 |
-
provisioned in the cloud. Once the job is submitted, you can navigate to a
|
| 166 |
-
provided job URL to view a variety of on-device performance metrics.
|
| 167 |
-
```python
|
| 168 |
-
profile_job = hub.submit_profile_job(
|
| 169 |
-
model=target_model,
|
| 170 |
-
device=device,
|
| 171 |
-
)
|
| 172 |
-
|
| 173 |
-
```
|
| 174 |
-
|
| 175 |
-
Step 3: **Verify on-device accuracy**
|
| 176 |
-
|
| 177 |
-
To verify the accuracy of the model on-device, you can run on-device inference
|
| 178 |
-
on sample input data on the same cloud hosted device.
|
| 179 |
-
```python
|
| 180 |
-
input_data = torch_model.sample_inputs()
|
| 181 |
-
inference_job = hub.submit_inference_job(
|
| 182 |
-
model=target_model,
|
| 183 |
-
device=device,
|
| 184 |
-
inputs=input_data,
|
| 185 |
-
)
|
| 186 |
-
on_device_output = inference_job.download_output_data()
|
| 187 |
-
|
| 188 |
-
```
|
| 189 |
-
With the output of the model, you can compute like PSNR, relative errors or
|
| 190 |
-
spot check the output with expected output.
|
| 191 |
-
|
| 192 |
-
**Note**: This on-device profiling and inference requires access to Qualcomm®
|
| 193 |
-
AI Hub Workbench. [Sign up for access](https://myaccount.qualcomm.com/signup).
|
| 194 |
-
|
| 195 |
-
|
| 196 |
-
|
| 197 |
-
## Run demo on a cloud-hosted device
|
| 198 |
-
|
| 199 |
-
You can also run the demo on-device.
|
| 200 |
-
|
| 201 |
-
```bash
|
| 202 |
-
python -m qai_hub_models.models.sequencer2d.demo --eval-mode on-device
|
| 203 |
-
```
|
| 204 |
-
|
| 205 |
-
**NOTE**: If you want running in a Jupyter Notebook or Google Colab like
|
| 206 |
-
environment, please add the following to your cell (instead of the above).
|
| 207 |
-
```
|
| 208 |
-
%run -m qai_hub_models.models.sequencer2d.demo -- --eval-mode on-device
|
| 209 |
-
```
|
| 210 |
-
|
| 211 |
-
|
| 212 |
-
## Deploying compiled model to Android
|
| 213 |
-
|
| 214 |
-
|
| 215 |
-
The models can be deployed using multiple runtimes:
|
| 216 |
-
- TensorFlow Lite (`.tflite` export): [This
|
| 217 |
-
tutorial](https://www.tensorflow.org/lite/android/quickstart) provides a
|
| 218 |
-
guide to deploy the .tflite model in an Android application.
|
| 219 |
-
|
| 220 |
-
|
| 221 |
-
- QNN (`.so` export ): This [sample
|
| 222 |
-
app](https://docs.qualcomm.com/bundle/publicresource/topics/80-63442-50/sample_app.html)
|
| 223 |
-
provides instructions on how to use the `.so` shared library in an Android application.
|
| 224 |
-
|
| 225 |
-
|
| 226 |
-
## View on Qualcomm® AI Hub
|
| 227 |
-
Get more details on Sequencer2D's performance across various devices [here](https://aihub.qualcomm.com/models/sequencer2d).
|
| 228 |
-
Explore all available models on [Qualcomm® AI Hub](https://aihub.qualcomm.com/)
|
| 229 |
-
|
| 230 |
|
| 231 |
## License
|
| 232 |
* The license for the original implementation of Sequencer2D can be found
|
| 233 |
[here](https://github.com/okojoalg/sequencer/blob/main/LICENSE).
|
| 234 |
|
| 235 |
-
|
| 236 |
-
|
| 237 |
## References
|
| 238 |
* [Sequencer: Deep LSTM for Image Classification](https://arxiv.org/abs/2205.01972)
|
| 239 |
* [Source Model Implementation](https://github.com/okojoalg/sequencer)
|
| 240 |
|
| 241 |
-
|
| 242 |
-
|
| 243 |
## Community
|
| 244 |
* Join [our AI Hub Slack community](https://aihub.qualcomm.com/community/slack) to collaborate, post questions and learn more about on-device AI.
|
| 245 |
* For questions or feedback please [reach out to us](mailto:ai-hub-support@qti.qualcomm.com).
|
| 246 |
-
|
| 247 |
-
|
|
|
|
| 9 |
|
| 10 |

|
| 11 |
|
| 12 |
+
# Sequencer2D: Optimized for Qualcomm Devices
|
|
|
|
|
|
|
| 13 |
|
| 14 |
Sequencer2D is a vision transformer model that can classify images from the Imagenet dataset.
|
| 15 |
|
| 16 |
+
This is based on the implementation of Sequencer2D found [here](https://github.com/okojoalg/sequencer).
|
| 17 |
+
This repository contains pre-exported model files optimized for Qualcomm® devices. You can use the [Qualcomm® AI Hub Models](https://github.com/quic/ai-hub-models/blob/main/qai_hub_models/models/sequencer2d) library to export with custom configurations. More details on model performance across various devices, can be found [here](#performance-summary).
|
| 18 |
+
|
| 19 |
+
Qualcomm AI Hub Models uses [Qualcomm AI Hub Workbench](https://workbench.aihub.qualcomm.com) to compile, profile, and evaluate this model. [Sign up](https://myaccount.qualcomm.com/signup) to run these models on a hosted Qualcomm® device.
|
| 20 |
+
|
| 21 |
+
## Getting Started
|
| 22 |
+
There are two ways to deploy this model on your device:
|
| 23 |
+
|
| 24 |
+
### Option 1: Download Pre-Exported Models
|
| 25 |
+
|
| 26 |
+
Below are pre-exported model assets ready for deployment.
|
| 27 |
+
|
| 28 |
+
| Runtime | Precision | Chipset | SDK Versions | Download |
|
| 29 |
+
|---|---|---|---|---|
|
| 30 |
+
| ONNX | float | Universal | QAIRT 2.37, ONNX Runtime 1.23.0 | [Download](https://qaihub-public-assets.s3.us-west-2.amazonaws.com/qai-hub-models/models/sequencer2d/releases/v0.46.1/sequencer2d-onnx-float.zip)
|
| 31 |
+
| ONNX | w8a16 | Universal | QAIRT 2.37, ONNX Runtime 1.23.0 | [Download](https://qaihub-public-assets.s3.us-west-2.amazonaws.com/qai-hub-models/models/sequencer2d/releases/v0.46.1/sequencer2d-onnx-w8a16.zip)
|
| 32 |
+
| QNN_DLC | float | Universal | QAIRT 2.42 | [Download](https://qaihub-public-assets.s3.us-west-2.amazonaws.com/qai-hub-models/models/sequencer2d/releases/v0.46.1/sequencer2d-qnn_dlc-float.zip)
|
| 33 |
+
| TFLITE | float | Universal | QAIRT 2.42, TFLite 2.17.0 | [Download](https://qaihub-public-assets.s3.us-west-2.amazonaws.com/qai-hub-models/models/sequencer2d/releases/v0.46.1/sequencer2d-tflite-float.zip)
|
| 34 |
+
|
| 35 |
+
For more device-specific assets and performance metrics, visit **[Sequencer2D on Qualcomm® AI Hub](https://aihub.qualcomm.com/models/sequencer2d)**.
|
| 36 |
+
|
| 37 |
+
|
| 38 |
+
### Option 2: Export with Custom Configurations
|
| 39 |
+
|
| 40 |
+
Use the [Qualcomm® AI Hub Models](https://github.com/quic/ai-hub-models/blob/main/qai_hub_models/models/sequencer2d) Python library to compile and export the model with your own:
|
| 41 |
+
- Custom weights (e.g., fine-tuned checkpoints)
|
| 42 |
+
- Custom input shapes
|
| 43 |
+
- Target device and runtime configurations
|
| 44 |
+
|
| 45 |
+
This option is ideal if you need to customize the model beyond the default configuration provided here.
|
| 46 |
+
|
| 47 |
+
See our repository for [Sequencer2D on GitHub](https://github.com/quic/ai-hub-models/blob/main/qai_hub_models/models/sequencer2d) for usage instructions.
|
| 48 |
+
|
| 49 |
+
## Model Details
|
| 50 |
+
|
| 51 |
+
**Model Type:** Model_use_case.image_classification
|
| 52 |
+
|
| 53 |
+
**Model Stats:**
|
| 54 |
+
- Model checkpoint: sequencer2d_s
|
| 55 |
+
- Input resolution: 224x224
|
| 56 |
+
- Number of parameters: 27.6M
|
| 57 |
+
- Model size (float): 106 MB
|
| 58 |
+
- Model size (w8a8): 69.1 MB
|
| 59 |
+
|
| 60 |
+
## Performance Summary
|
| 61 |
+
| Model | Runtime | Precision | Chipset | Inference Time (ms) | Peak Memory Range (MB) | Primary Compute Unit
|
| 62 |
+
|---|---|---|---|---|---|---
|
| 63 |
+
| Sequencer2D | ONNX | float | Snapdragon® X Elite | 48.401 ms | 66 - 66 MB | NPU
|
| 64 |
+
| Sequencer2D | ONNX | float | Snapdragon® 8 Gen 3 Mobile | 33.466 ms | 1 - 1349 MB | NPU
|
| 65 |
+
| Sequencer2D | ONNX | float | Qualcomm® QCS8550 (Proxy) | 46.558 ms | 0 - 83 MB | NPU
|
| 66 |
+
| Sequencer2D | ONNX | float | Qualcomm® QCS9075 | 57.399 ms | 0 - 4 MB | NPU
|
| 67 |
+
| Sequencer2D | ONNX | float | Snapdragon® 8 Elite For Galaxy Mobile | 23.058 ms | 1 - 766 MB | NPU
|
| 68 |
+
| Sequencer2D | ONNX | float | Snapdragon® 8 Elite Gen 5 Mobile | 17.991 ms | 1 - 807 MB | NPU
|
| 69 |
+
| Sequencer2D | ONNX | w8a16 | Snapdragon® X Elite | 123.498 ms | 132 - 132 MB | NPU
|
| 70 |
+
| Sequencer2D | ONNX | w8a16 | Qualcomm® QCS6490 | 647.033 ms | 46 - 56 MB | CPU
|
| 71 |
+
| Sequencer2D | ONNX | w8a16 | Qualcomm® QCS9075 | 165.125 ms | 107 - 110 MB | NPU
|
| 72 |
+
| Sequencer2D | ONNX | w8a16 | Qualcomm® QCM6690 | 274.09 ms | 47 - 63 MB | CPU
|
| 73 |
+
| Sequencer2D | ONNX | w8a16 | Snapdragon® 8 Elite For Galaxy Mobile | 105.431 ms | 106 - 488 MB | NPU
|
| 74 |
+
| Sequencer2D | ONNX | w8a16 | Snapdragon® 7 Gen 4 Mobile | 260.838 ms | 26 - 37 MB | CPU
|
| 75 |
+
| Sequencer2D | ONNX | w8a16 | Snapdragon® 8 Elite Gen 5 Mobile | 102.361 ms | 50 - 436 MB | NPU
|
| 76 |
+
| Sequencer2D | QNN_DLC | float | Snapdragon® X Elite | 21.419 ms | 1 - 1 MB | NPU
|
| 77 |
+
| Sequencer2D | QNN_DLC | float | Snapdragon® 8 Gen 3 Mobile | 14.292 ms | 0 - 2279 MB | NPU
|
| 78 |
+
| Sequencer2D | QNN_DLC | float | Qualcomm® QCS8550 (Proxy) | 20.806 ms | 1 - 565 MB | NPU
|
| 79 |
+
| Sequencer2D | QNN_DLC | float | Qualcomm® QCS8450 (Proxy) | 26.272 ms | 0 - 846 MB | NPU
|
| 80 |
+
| Sequencer2D | QNN_DLC | float | Snapdragon® 8 Elite For Galaxy Mobile | 12.521 ms | 1 - 1065 MB | NPU
|
| 81 |
+
| Sequencer2D | QNN_DLC | float | Snapdragon® 8 Elite Gen 5 Mobile | 9.34 ms | 0 - 1225 MB | NPU
|
| 82 |
+
| Sequencer2D | TFLITE | float | Snapdragon® 8 Gen 3 Mobile | 11.933 ms | 0 - 917 MB | NPU
|
| 83 |
+
| Sequencer2D | TFLITE | float | Qualcomm® QCS8275 (Proxy) | 37.369 ms | 0 - 810 MB | NPU
|
| 84 |
+
| Sequencer2D | TFLITE | float | Qualcomm® QCS8550 (Proxy) | 17.044 ms | 0 - 12 MB | NPU
|
| 85 |
+
| Sequencer2D | TFLITE | float | Qualcomm® QCS8450 (Proxy) | 21.299 ms | 0 - 724 MB | NPU
|
| 86 |
+
| Sequencer2D | TFLITE | float | Snapdragon® 8 Elite For Galaxy Mobile | 9.406 ms | 0 - 744 MB | NPU
|
| 87 |
+
| Sequencer2D | TFLITE | float | Snapdragon® 8 Elite Gen 5 Mobile | 7.34 ms | 0 - 1082 MB | NPU
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 88 |
|
| 89 |
## License
|
| 90 |
* The license for the original implementation of Sequencer2D can be found
|
| 91 |
[here](https://github.com/okojoalg/sequencer/blob/main/LICENSE).
|
| 92 |
|
|
|
|
|
|
|
| 93 |
## References
|
| 94 |
* [Sequencer: Deep LSTM for Image Classification](https://arxiv.org/abs/2205.01972)
|
| 95 |
* [Source Model Implementation](https://github.com/okojoalg/sequencer)
|
| 96 |
|
|
|
|
|
|
|
| 97 |
## Community
|
| 98 |
* Join [our AI Hub Slack community](https://aihub.qualcomm.com/community/slack) to collaborate, post questions and learn more about on-device AI.
|
| 99 |
* For questions or feedback please [reach out to us](mailto:ai-hub-support@qti.qualcomm.com).
|
|
|
|
|
|
Sequencer2D_float.dlc
DELETED
|
@@ -1,3 +0,0 @@
|
|
| 1 |
-
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:d06ccb3a689682c1d37163aed322fdd7be4de21cb67a78d38ab219cb562bf0f6
|
| 3 |
-
size 123861260
|
|
|
|
|
|
|
|
|
|
|
|
Sequencer2D_float.onnx.zip
DELETED
|
@@ -1,3 +0,0 @@
|
|
| 1 |
-
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:91447c9fb86fcb3bf1d99ec17934e23c2fb584a0f895702a2ee42d229c314a57
|
| 3 |
-
size 102959885
|
|
|
|
|
|
|
|
|
|
|
|
Sequencer2D_float.tflite
DELETED
|
@@ -1,3 +0,0 @@
|
|
| 1 |
-
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:0f1dccc18a5341ce10321f8a6515ca6f6860a33e37f0d7d80d227cb4ea207cb5
|
| 3 |
-
size 114050616
|
|
|
|
|
|
|
|
|
|
|
|
tool-versions.yaml
DELETED
|
@@ -1,4 +0,0 @@
|
|
| 1 |
-
tool_versions:
|
| 2 |
-
onnx:
|
| 3 |
-
qairt: 2.37.1.250807093845_124904
|
| 4 |
-
onnx_runtime: 1.23.0
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|