diff --git a/.dockerignore b/.dockerignore
new file mode 100644
index 0000000000000000000000000000000000000000..fd4f0fdd44df5f44c7580b750d64593da987a728
--- /dev/null
+++ b/.dockerignore
@@ -0,0 +1,47 @@
+# Environment files (may contain secrets)
+.env
+.env.*
+!.env.example
+
+# Logs
+logs
+*.log
+npm-debug.log*
+yarn-debug.log*
+yarn-error.log*
+pnpm-debug.log*
+lerna-debug.log*
+
+# Dependencies and build output. Vite writes to `client/dist`, so these need
+# `**/` for the same reason as the test patterns below.
+node_modules
+**/dist
+**/dist-ssr
+*.local
+
+# Test files (not needed at runtime). The `**/` matters: a leading `*` does not
+# cross `/`, so a bare `*.test.ts` would only match the context root.
+**/*.test.ts
+**/*.test.tsx
+**/__tests__
+
+# Documentation and CI (not needed at runtime)
+docs
+.github
+
+# Coverage and lint reports
+coverage
+vite-build-stats.html
+knip
+jscpd-report
+
+# Editor directories and files
+.vscode/*
+!.vscode/extensions.json
+.idea
+.DS_Store
+*.suo
+*.ntvs*
+*.njsproj
+*.sln
+*.sw?
diff --git a/.editorconfig b/.editorconfig
new file mode 100644
index 0000000000000000000000000000000000000000..a78447ebf932f1bb3a5b124b472bea8b3a86f80f
--- /dev/null
+++ b/.editorconfig
@@ -0,0 +1,7 @@
+[*]
+charset = utf-8
+insert_final_newline = true
+end_of_line = lf
+indent_style = space
+indent_size = 2
+max_line_length = 80
\ No newline at end of file
diff --git a/.env.example b/.env.example
new file mode 100644
index 0000000000000000000000000000000000000000..645d3465ba32140a50eadd428eb0fc417f898e25
--- /dev/null
+++ b/.env.example
@@ -0,0 +1,27 @@
+# A comma-separated list of access keys. Example: `ACCESS_KEYS="ABC123,JUD71F,HUWE3"`. Leave blank for unrestricted access.
+ACCESS_KEYS=""
+
+# The timeout in hours for access key validation. Set to 0 to require validation on every page load.
+ACCESS_KEY_TIMEOUT_HOURS="24"
+
+# The default model ID for Wllama.
+WLLAMA_DEFAULT_MODEL_ID="littlelamb-290m"
+
+# The base URL for the internal OpenAI compatible API. Example: `INTERNAL_OPENAI_COMPATIBLE_API_BASE_URL="https://api.openai.com/v1"`. Leave blank to disable internal OpenAI compatible API.
+INTERNAL_OPENAI_COMPATIBLE_API_BASE_URL=""
+
+# The access key for the internal OpenAI compatible API.
+INTERNAL_OPENAI_COMPATIBLE_API_KEY=""
+
+# The model for the internal OpenAI compatible API.
+INTERNAL_OPENAI_COMPATIBLE_API_MODEL=""
+
+# The name of the internal OpenAI compatible API, displayed in the UI.
+INTERNAL_OPENAI_COMPATIBLE_API_NAME="Internal API"
+
+# The type of inference to use by default. The possible values are:
+# "browser" -> In the browser
+# "openai" -> Remote Server (OpenAI-compatible API)
+# "horde" -> AI Horde
+# "internal" -> $INTERNAL_OPENAI_COMPATIBLE_API_NAME
+DEFAULT_INFERENCE_TYPE="browser"
diff --git a/.github/CODE_OF_CONDUCT.md b/.github/CODE_OF_CONDUCT.md
new file mode 100644
index 0000000000000000000000000000000000000000..d8b74ecb7d9fc0bb8f7e0d0b1da260ff2938a903
--- /dev/null
+++ b/.github/CODE_OF_CONDUCT.md
@@ -0,0 +1,84 @@
+# Contributor Code of Conduct
+
+## Our Pledge
+
+We as members, contributors, and leaders pledge to make participation in our community a harassment-free experience for everyone, regardless of age, body size, visible or invisible disability, ethnicity, sex characteristics, gender identity and expression, level of experience, education, socio-economic status, nationality, personal appearance, race, religion, or sexual identity and orientation.
+
+We pledge to act and interact in ways that contribute to an open, welcoming, diverse, inclusive, and healthy community.
+
+## Our Standards
+
+Examples of behavior that contributes to a positive environment for our community include:
+
+* Demonstrating empathy and kindness toward other people
+* Being respectful of differing opinions, viewpoints, and experiences
+* Giving and gracefully accepting constructive feedback
+* Accepting responsibility and apologizing to those affected by our mistakes, and learning from the experience
+* Focusing on what is best not just for us as individuals, but for the overall community
+
+Examples of unacceptable behavior include:
+
+* The use of sexualized language or imagery, and sexual attention or advances of any kind
+* Trolling, insulting or derogatory comments, and personal or political attacks
+* Public or private harassment
+* Publishing others' private information, such as a physical or email address, without their explicit permission
+* Other conduct which could reasonably be considered inappropriate in a professional setting
+
+## Enforcement Responsibilities
+
+Community leaders are responsible for clarifying and enforcing our standards of acceptable behavior and will take appropriate and fair corrective action in response to any behavior that they deem inappropriate, threatening, offensive, or harmful.
+
+Community leaders have the right and responsibility to remove, edit, or reject comments, commits, code, wiki edits, issues, and other contributions that are not aligned to this Code of Conduct, and will communicate reasons for moderation decisions when appropriate.
+
+## Scope
+
+This Code of Conduct applies within all community spaces, and also applies when an individual is officially representing the community in public spaces. Examples of representing our community include using an official e-mail address, posting via an official social media account, or acting as an appointed representative at an online or offline event.
+
+## Enforcement
+
+Instances of abusive, harassing, or otherwise unacceptable behavior may be reported to the community leaders responsible for enforcement at:
+
+- GitHub: [@felladrin](https://github.com/felladrin)
+- Email: (private contact can be provided upon request)
+
+All complaints will be reviewed and investigated promptly and fairly.
+
+All community leaders are obligated to respect the privacy and security of the reporter of any incident.
+
+## Enforcement Guidelines
+
+Community leaders will follow these Community Impact Guidelines in determining the consequences for any action they deem in violation of this Code of Conduct:
+
+### 1. Correction
+
+**Community Impact**: Use of inappropriate language or other behavior deemed unprofessional or unwelcome in the community.
+
+**Consequence**: A private, written warning from community leaders, providing clarity around the nature of the violation and an explanation of why the behavior was inappropriate. A public apology may be requested.
+
+### 2. Warning
+
+**Community Impact**: A violation through a single incident or series of actions.
+
+**Consequence**: A warning with consequences for continued behavior. No interaction with the people involved, including unsolicited interaction with those enforcing the Code of Conduct, for a specified period of time. This includes avoiding interactions in community spaces as well as external channels like social media. Violating these terms may lead to a temporary or permanent ban.
+
+### 3. Temporary Ban
+
+**Community Impact**: A serious violation of community standards, including sustained inappropriate behavior.
+
+**Consequence**: A temporary ban from any sort of interaction or public communication with the community for a specified period of time. No public or private interaction with the people involved, including unsolicited interaction with those enforcing the Code of Conduct, is allowed during this period. Violating these terms may lead to a permanent ban.
+
+### 4. Permanent Ban
+
+**Community Impact**: Demonstrating a pattern of violation of community standards, including sustained inappropriate behavior, harassment of an individual, or aggression toward or disparagement of classes of individuals.
+
+**Consequence**: A permanent ban from any sort of public interaction within the community.
+
+## Attribution
+
+This Code of Conduct is adapted from the [Contributor Covenant][homepage], version 2.0, available at https://www.contributor-covenant.org/version/2/0/code_of_conduct.html.
+
+Community Impact Guidelines were inspired by [Mozilla's code of conduct enforcement ladder](https://github.com/mozilla/diversity).
+
+[homepage]: https://www.contributor-covenant.org
+
+For answers to common questions about this code of conduct, see https://www.contributor-covenant.org/faq. Translations are available at https://www.contributor-covenant.org/translations.
diff --git a/.github/CONTRIBUTING.md b/.github/CONTRIBUTING.md
new file mode 100644
index 0000000000000000000000000000000000000000..4cbf743654b0fedd45ff36423e86354adb66d185
--- /dev/null
+++ b/.github/CONTRIBUTING.md
@@ -0,0 +1,55 @@
+# Contributing to MiniSearch
+
+First off, thank you for considering contributing to MiniSearch! It's people like you that make MiniSearch such a great tool.
+
+## Your First Contribution
+
+Not sure where to start? [Browse issues labeled "good first issue"](https://github.com/felladrin/MiniSearch/issues?q=label%3A%22good+first+issue%22+state%3Aopen). They are curated for first-time contributors, and you are welcome to ask for help in the issue comments.
+
+## Quick Start
+
+- **Onboarding**: See [`../docs/quick-start.md`](../docs/quick-start.md) for setup and running the app.
+- **Development workflow**: See [`../docs/pull-requests.md`](../docs/pull-requests.md) for the full PR process.
+- **Architecture guide**: See [`../agents.md`](../agents.md) for codebase navigation.
+- **Full docs**: Browse [`../docs/`](../docs/) for architecture, configuration, and AI integration.
+
+## Code Quality
+
+Before submitting a pull request, please run:
+
+```bash
+docker compose exec development-server npm run lint
+```
+
+This runs:
+
+- Biome (formatting/linting)
+- TypeScript (type checking)
+- knip (dead code detection)
+- jscpd (copy-paste detection)
+- Custom architectural linter
+- `doc-gardening.cjs` (documentation checks)
+- `documentation-validator.cjs` (documentation validation)
+
+## Reporting Bugs
+
+- Use the [GitHub issue tracker](https://github.com/felladrin/MiniSearch/issues) to report bugs.
+- Check if the issue has already been reported before creating a new one.
+- Provide clear steps to reproduce the issue.
+- Include your environment details (OS, browser, Docker version if applicable).
+- Add screenshots if the issue is UI-related.
+
+## Suggesting Features
+
+- Use the [GitHub issue tracker](https://github.com/felladrin/MiniSearch/issues) for feature suggestions.
+- Clearly describe the feature and why it would be useful.
+- Consider if it fits with the project's minimalist philosophy.
+- Provide examples of how you envision the feature working.
+
+## Questions?
+
+Don't hesitate to ask questions! We're here to help you contribute successfully.
+
+---
+
+Thanks again for your interest in contributing to MiniSearch! 🎉
diff --git a/.github/ISSUE_TEMPLATE/bug_report.yml b/.github/ISSUE_TEMPLATE/bug_report.yml
new file mode 100644
index 0000000000000000000000000000000000000000..a537f6c1f52ff96ab8c44717fa72bcaa1fd05ddc
--- /dev/null
+++ b/.github/ISSUE_TEMPLATE/bug_report.yml
@@ -0,0 +1,123 @@
+---
+name: Bug report
+description: Create a report to help us improve
+title: "[BUG] "
+labels: ["bug"]
+assignees: []
+body:
+ - type: markdown
+ attributes:
+ value: |
+ Thanks for taking the time to fill out this bug report! Please provide as much detail as possible.
+
+ - type: textarea
+ id: bug-description
+ attributes:
+ label: Describe the bug
+ description: A clear and concise description of what the bug is
+ placeholder: What happened? What did you expect to happen?
+ validations:
+ required: true
+
+ - type: textarea
+ id: steps-to-reproduce
+ attributes:
+ label: Steps to reproduce
+ description: Please provide detailed steps to reproduce the issue
+ placeholder: |
+ 1. Go to '...'
+ 2. Click on '....'
+ 3. Scroll down to '....'
+ 4. See error
+ validations:
+ required: true
+
+ - type: textarea
+ id: expected-behavior
+ attributes:
+ label: Expected behavior
+ description: A clear and concise description of what you expected to happen
+ validations:
+ required: true
+
+ - type: textarea
+ id: screenshots
+ attributes:
+ label: Screenshots
+ description: If applicable, add screenshots to help explain your problem
+ placeholder: Drag and drop images here or paste them
+
+ - type: dropdown
+ id: os
+ attributes:
+ label: Operating System
+ description: What operating system are you using?
+ options:
+ - Windows 11
+ - Windows 10
+ - macOS 15.x
+ - macOS 14.x
+ - macOS 13.x
+ - Ubuntu 22.04
+ - Ubuntu 20.04
+ - Other Linux
+ - Other
+ validations:
+ required: true
+
+ - type: dropdown
+ id: browser
+ attributes:
+ label: Browser
+ description: What browser are you using?
+ options:
+ - Chrome
+ - Firefox
+ - Safari
+ - Edge
+ - Other
+ validations:
+ required: true
+
+ - type: input
+ id: version
+ attributes:
+ label: MiniSearch version
+ description: What version of MiniSearch are you using?
+ placeholder: latest, v1.0.0, etc.
+ validations:
+ required: true
+
+ - type: input
+ id: docker-version
+ attributes:
+ label: Docker version (if applicable)
+ description: What Docker version are you using?
+ placeholder: e.g., 24.0.7
+
+ - type: textarea
+ id: additional-context
+ attributes:
+ label: Additional context
+ description: Add any other context about the problem here
+
+ - type: dropdown
+ id: deployment-type
+ attributes:
+ label: Deployment type
+ description: How are you running MiniSearch?
+ options:
+ - Docker image
+ - Building from source
+ - Development server
+ - Other
+ validations:
+ required: true
+
+ - type: textarea
+ id: custom-config
+ attributes:
+ label: Custom configuration (if applicable)
+ description: Any custom configuration you're using
+ placeholder: Environment variables, custom settings, etc.
+---
diff --git a/.github/ISSUE_TEMPLATE/config.yml b/.github/ISSUE_TEMPLATE/config.yml
new file mode 100644
index 0000000000000000000000000000000000000000..60f0402db018c2b032ff2e3b8c222cdc797fac2e
--- /dev/null
+++ b/.github/ISSUE_TEMPLATE/config.yml
@@ -0,0 +1,10 @@
+contact_links:
+ - name: MiniSearch Discussions
+ url: https://github.com/felladrin/MiniSearch/discussions
+ about: Ask questions, share ideas, and discuss features
+ - name: Report a Security Vulnerability Privately
+ url: https://docs.github.com/en/code-security/security-advisories/guidance-on-reporting-and-writing/privately-reporting-a-security-vulnerability
+ about: Report security vulnerabilities privately via GitHub's Private Vulnerability Reporting
+ - name: Live Demo
+ url: https://felladrin-minisearch.hf.space
+ about: Try MiniSearch in your browser
diff --git a/.github/ISSUE_TEMPLATE/feature_request.yml b/.github/ISSUE_TEMPLATE/feature_request.yml
new file mode 100644
index 0000000000000000000000000000000000000000..3c7173ac945df19485fd6743ecc1d20c76e64627
--- /dev/null
+++ b/.github/ISSUE_TEMPLATE/feature_request.yml
@@ -0,0 +1,73 @@
+---
+name: Feature request
+description: Suggest an idea for this project
+title: "[FEATURE] "
+labels: ["enhancement"]
+assignees: []
+body:
+ - type: markdown
+ attributes:
+ value: |
+ Thanks for suggesting a new feature! Please provide as much detail as possible to help us understand your vision.
+
+ - type: textarea
+ id: problem-description
+ attributes:
+ label: Is your feature request related to a problem?
+ description: A clear and concise description of what the problem is
+ placeholder: I'm always frustrated when [...]
+ validations:
+ required: true
+
+ - type: textarea
+ id: solution-description
+ attributes:
+ label: Describe the solution you'd like
+ description: A clear and concise description of what you want to happen
+ validations:
+ required: true
+
+ - type: textarea
+ id: alternatives
+ attributes:
+ label: Describe alternatives you've considered
+ description: A clear and concise description of any alternative solutions or features you've considered
+
+ - type: textarea
+ id: additional-context
+ attributes:
+ label: Additional context
+ description: Add any other context or screenshots about the feature request here
+
+ - type: dropdown
+ id: alignment
+ attributes:
+ label: Alignment with MiniSearch's goals
+ description: How does this feature align with MiniSearch's minimalist, privacy-focused philosophy?
+ options:
+ - "Strongly aligns - enhances privacy/minimalism"
+ - "Moderately aligns - useful but adds complexity"
+ - "Needs consideration - potential trade-offs"
+ - "Not sure - need discussion"
+ validations:
+ required: true
+
+ - type: textarea
+ id: implementation-ideas
+ attributes:
+ label: Implementation ideas (optional)
+ description: Do you have any ideas about how this could be implemented?
+ placeholder: Technical thoughts, potential approaches, etc.
+
+ - type: dropdown
+ id: priority
+ attributes:
+ label: Priority (your assessment)
+ description: How important is this feature to you?
+ options:
+ - "High - would significantly improve my experience"
+ - "Medium - nice to have"
+ - "Low - minor improvement"
+ validations:
+ required: true
+---
diff --git a/.github/ISSUE_TEMPLATE/security_vulnerability.yml b/.github/ISSUE_TEMPLATE/security_vulnerability.yml
new file mode 100644
index 0000000000000000000000000000000000000000..313c7891691d7f2c8f82d2e0bc6ff0bb45d20d1e
--- /dev/null
+++ b/.github/ISSUE_TEMPLATE/security_vulnerability.yml
@@ -0,0 +1,95 @@
+---
+name: Security Vulnerability
+description: Report a security vulnerability (PRIVATE - will be converted to private report)
+title: "[SECURITY] "
+labels: ["security"]
+assignees: []
+body:
+ - type: markdown
+ attributes:
+ value: |
+ # ⚠️ IMPORTANT: SECURITY VULNERABILITIES SHOULD NOT BE REPORTED PUBLICLY ⚠️
+
+ This template will create a public issue, but security vulnerabilities must be reported privately through GitHub's [Private Vulnerability Reporting](https://docs.github.com/en/code-security/security-advisories/guidance-on-reporting-and-writing/privately-reporting-a-security-vulnerability).
+
+ If you accidentally created a public issue, please close it and report privately instead.
+
+ - type: checkboxes
+ id: confirmation
+ attributes:
+ label: Confirmation
+ description: Please confirm you understand the security reporting process
+ options:
+ - label: I understand this should be reported privately and will use the method above
+ required: true
+
+ - type: dropdown
+ id: vulnerability-type
+ attributes:
+ label: Vulnerability Type
+ description: What type of security vulnerability is this?
+ options:
+ - Cross-site Scripting (XSS)
+ - Authentication/Authorization Bypass
+ - Information Disclosure
+ - Remote Code Execution
+ - Denial of Service
+ - Configuration Issue
+ - Other
+ validations:
+ required: true
+
+ - type: dropdown
+ id: severity
+ attributes:
+ label: Severity
+ description: How severe is this vulnerability?
+ options:
+ - Critical
+ - High
+ - Medium
+ - Low
+ validations:
+ required: true
+
+ - type: textarea
+ id: description
+ attributes:
+ label: Description
+ description: A clear description of the security vulnerability
+ validations:
+ required: true
+
+ - type: textarea
+ id: steps-to-reproduce
+ attributes:
+ label: Steps to Reproduce
+ description: Detailed steps to reproduce the vulnerability
+ validations:
+ required: true
+
+ - type: textarea
+ id: impact
+ attributes:
+ label: Impact
+ description: Describe the potential impact of this vulnerability
+ validations:
+ required: true
+
+ - type: textarea
+ id: mitigation
+ attributes:
+ label: Mitigation (if known)
+ description: Any known workarounds or mitigations
+
+ - type: textarea
+ id: additional-information
+ attributes:
+ label: Additional Information
+ description: Any additional context or information about the vulnerability
+
+ - type: markdown
+ attributes:
+ value: |
+ ## 🚨 PLEASE DO NOT SUBMIT THIS PUBLICLY - USE PRIVATE REPORTING METHODS ABOVE 🚨
+---
diff --git a/.github/PULL_REQUEST_TEMPLATE.md b/.github/PULL_REQUEST_TEMPLATE.md
new file mode 100644
index 0000000000000000000000000000000000000000..82e7a7ac7ec047bf760b4eb38bc316d0d3b7ac43
--- /dev/null
+++ b/.github/PULL_REQUEST_TEMPLATE.md
@@ -0,0 +1,8 @@
+## Description
+
+
+## How to test
+
+
+## Screenshots
+
diff --git a/.github/SECURITY.md b/.github/SECURITY.md
new file mode 100644
index 0000000000000000000000000000000000000000..7066c09049ecac1a4a95f9f0f913eafd6486dc7b
--- /dev/null
+++ b/.github/SECURITY.md
@@ -0,0 +1,132 @@
+# Security Policy
+
+## Supported Versions
+
+Only the latest version of MiniSearch receives security updates.
+
+| Version | Supported |
+|---------|------------|
+| Latest | ✅ |
+| Older | ❌ |
+
+## Reporting a Vulnerability
+
+### Private Vulnerability Reporting
+
+Report security vulnerabilities through GitHub's [Private Vulnerability Reporting](https://docs.github.com/en/code-security/security-advisories/guidance-on-reporting-and-writing/privately-reporting-a-security-vulnerability) feature. It is the only reporting channel, so every report stays private and tracked in one place.
+
+**Do not report security vulnerabilities through public issues.**
+
+### What to Include
+
+When reporting a vulnerability, please include:
+- A clear description of the vulnerability
+- Steps to reproduce the issue
+- Potential impact of the vulnerability
+- Any suggested mitigations (if known)
+
+### What to Expect
+
+- We will acknowledge receipt of your report within 48 hours
+- We will provide a detailed response within 7 days
+- We will work with you to understand and validate the report
+- We will coordinate disclosure timing to minimize user risk
+
+## Security Scope
+
+### In Scope
+
+- Vulnerabilities in the MiniSearch web application
+- Security issues in the Docker container configuration
+- Authentication and authorization bypasses
+- Cross-site scripting (XSS) vulnerabilities
+- Information disclosure issues
+- Remote code execution vulnerabilities
+- Privilege escalation in the application context
+
+### Out of Scope
+
+- Issues in third-party dependencies (report to respective projects)
+- Vulnerabilities in the underlying browser or Node.js runtime
+- Physical attacks on infrastructure
+- Social engineering attacks
+- Denial of service attacks that don't indicate a vulnerability
+- Issues requiring physical access to user devices
+
+## Threat Model
+
+### MiniSearch's Security Boundaries
+
+MiniSearch is designed as a privacy-focused search application with the following security assumptions:
+
+**Trust Boundaries:**
+- **Browser Environment**: The application runs entirely in the user's browser
+- **Server Component**: Optional backend for search and AI processing
+- **AI Models**: Local or remote AI processing with configurable endpoints
+
+**Data Flow:**
+- User queries are sent to SearXNG instances (configurable)
+- AI processing can be local (Wllama) or remote (API endpoints)
+- Search history is stored locally in the browser
+- No tracking or analytics by default
+
+**Security Controls:**
+- Optional access key protection for deployment
+- Configurable AI endpoints for privacy
+- Local-first data storage
+- No third-party tracking or analytics
+
+**Potential Risks:**
+- Malicious SearXNG instances could log queries
+- Remote AI endpoints could access user queries
+- Browser extensions could interfere with the application
+- Man-in-the-middle attacks without HTTPS
+
+## Security Best Practices
+
+### For Users
+
+- Always use HTTPS when accessing MiniSearch instances
+- Configure trusted SearXNG instances
+- Use local AI models for maximum privacy
+- Set access keys for deployed instances
+- Keep browsers updated
+
+### For Deployers
+
+- Use the official Docker image
+- Configure environment variables securely
+- Set up proper access controls
+- Use HTTPS in production
+- Regularly update dependencies
+- Monitor for security advisories
+
+## Security Features
+
+- **Access Key Protection**: Optional password-based access control
+- **Configurable Endpoints**: Users control search and AI providers
+- **Local Processing**: AI models can run entirely in the browser
+- **No Tracking**: Built without analytics or tracking
+- **HTTPS Ready**: Designed for secure deployment
+
+## Security Updates
+
+Security updates will be:
+- Released as new versions
+- Announced in release notes
+- Coordinated with dependency updates when applicable
+
+## Security Team
+
+The MiniSearch security team is currently the project maintainer:
+- [@felladrin](https://github.com/felladrin) - Project Maintainer
+
+## Acknowledgments
+
+We thank security researchers who help us keep MiniSearch secure. All valid security reports will be acknowledged in our release notes (with reporter permission).
+
+## Related Resources
+
+- [GitHub Security Advisories](https://docs.github.com/en/code-security/security-advisories)
+- [OWASP Web Security Testing Guide](https://owasp.org/www-project-web-security-testing-guide/)
+- [Mozilla Security Guidelines](https://infosec.mozilla.org/guidelines)
diff --git a/.github/SUPPORT.md b/.github/SUPPORT.md
new file mode 100644
index 0000000000000000000000000000000000000000..34a36a1a2eda274df033350847a98b97f18f86cc
--- /dev/null
+++ b/.github/SUPPORT.md
@@ -0,0 +1,36 @@
+# Support
+
+## Getting help
+
+If you need help with MiniSearch, these are the best support channels.
+
+### GitHub Discussions
+
+For questions, feature requests, and general discussion, use [GitHub Discussions](https://github.com/felladrin/MiniSearch/discussions). This is the best place to:
+
+- Ask how to configure MiniSearch for your use case
+- Request new features
+- Share ideas and feedback
+- Discuss best practices
+
+### Bug reports
+
+Report bugs through [GitHub Issues](https://github.com/felladrin/MiniSearch/issues/new?template=bug_report.yml). Before opening an issue, check whether the problem has already been reported and include enough detail to reproduce it.
+
+### Security vulnerabilities
+
+Do not report security vulnerabilities in a public issue. Use [GitHub's Private Vulnerability Reporting](https://github.com/felladrin/MiniSearch/security/advisories/new) instead.
+
+### Live demo
+
+Try MiniSearch in your browser at [felladrin-minisearch.hf.space](https://felladrin-minisearch.hf.space) before deploying your own instance.
+
+## Community
+
+- Follow [@felladrin](https://github.com/felladrin) for project updates
+- Star the repository to show your support
+- Contribute by opening pull requests after reading the [contribution guidelines](CONTRIBUTING.md)
+
+## Response times
+
+This is a community-maintained project. While the maintainer tries to respond to issues and discussions promptly, response times may vary.
diff --git a/.github/hf-space-config.yml b/.github/hf-space-config.yml
new file mode 100644
index 0000000000000000000000000000000000000000..6d9d5b00160bb6ad09b8a92ab74ab6cd0a360b3b
--- /dev/null
+++ b/.github/hf-space-config.yml
@@ -0,0 +1,11 @@
+title: MiniSearch
+emoji: 👌🔍
+colorFrom: yellow
+colorTo: yellow
+sdk: docker
+short_description: Minimalist web-searching app with browser-based AI assistant
+pinned: true
+custom_headers:
+ cross-origin-embedder-policy: require-corp
+ cross-origin-opener-policy: same-origin
+ cross-origin-resource-policy: cross-origin
diff --git a/.github/workflows/ci.yml b/.github/workflows/ci.yml
new file mode 100644
index 0000000000000000000000000000000000000000..5a3c828894c19b6f51db60e825ea3f299271977b
--- /dev/null
+++ b/.github/workflows/ci.yml
@@ -0,0 +1,47 @@
+name: CI
+
+on:
+ push:
+ branches: [main, master]
+ pull_request:
+ branches: [main, master]
+
+jobs:
+ build-test:
+ runs-on: ubuntu-latest
+ permissions:
+ contents: read
+
+ strategy:
+ matrix:
+ node-version: [lts/*, current]
+
+ steps:
+ - name: Checkout repository
+ uses: actions/checkout@v7
+
+ - name: Set up Node.js
+ uses: actions/setup-node@v7
+ with:
+ node-version: ${{ matrix.node-version }}
+ cache: npm
+
+ - name: Install dependencies
+ run: npm ci
+
+ - name: Run npm audit
+ run: npm audit --audit-level=high
+
+ - name: Run lint
+ run: npm run lint
+
+ - name: Lint Dockerfile
+ uses: hadolint/hadolint-action@v3.5.0
+ with:
+ dockerfile: Dockerfile
+
+ - name: Check formatting
+ run: npm run format:check
+
+ - name: Run tests
+ run: npm run test:coverage
diff --git a/.github/workflows/deploy-to-hugging-face.yml b/.github/workflows/deploy-to-hugging-face.yml
new file mode 100644
index 0000000000000000000000000000000000000000..12688c4d5400ad9ed28f3ae958db126e8c3a3b52
--- /dev/null
+++ b/.github/workflows/deploy-to-hugging-face.yml
@@ -0,0 +1,24 @@
+name: Deploy to Hugging Face
+
+on:
+ workflow_dispatch:
+
+jobs:
+ sync-to-hf:
+ name: Sync to Hugging Face Spaces
+ runs-on: ubuntu-latest
+ permissions:
+ contents: read
+ steps:
+ - uses: actions/checkout@v7
+ # Pin to the tip of the action's `v1` branch, which is where its build
+ # output lives. Its release tags point at source commits, and `dist/` is
+ # gitignored there, so a tag digest resolves to a tree with no
+ # `dist/index.js` and the step fails before it runs.
+ - uses: JacobLinCool/huggingface-sync@48eb49940149dc1015d8294621cb203635fe9ff3 # v1 branch, 2026-05-12
+ with:
+ github: ${{ secrets.GITHUB_TOKEN }}
+ user: ${{ vars.HF_SPACE_OWNER }}
+ space: ${{ vars.HF_SPACE_NAME }}
+ token: ${{ secrets.HF_TOKEN }}
+ configuration: ".github/hf-space-config.yml"
diff --git a/.github/workflows/on-pull-request-to-main.yml b/.github/workflows/on-pull-request-to-main.yml
new file mode 100644
index 0000000000000000000000000000000000000000..7976fd1438eb13ca09681a420eaa70f2792bf569
--- /dev/null
+++ b/.github/workflows/on-pull-request-to-main.yml
@@ -0,0 +1,11 @@
+name: On Pull Request To Main
+on:
+ pull_request:
+ types: [opened, synchronize, reopened]
+ branches: ["main"]
+jobs:
+ check-docker:
+ if: ${{ !contains(github.event.pull_request.labels.*.name, 'skip-check-docker') }}
+ permissions:
+ contents: read
+ uses: ./.github/workflows/reusable-check-docker.yml
diff --git a/.github/workflows/on-push-to-main.yml b/.github/workflows/on-push-to-main.yml
new file mode 100644
index 0000000000000000000000000000000000000000..43350e46e1f4237d8b1a6bc5adeadb7473460ec3
--- /dev/null
+++ b/.github/workflows/on-push-to-main.yml
@@ -0,0 +1,9 @@
+name: On Push To Main
+on:
+ push:
+ branches: ["main"]
+jobs:
+ check-docker:
+ permissions:
+ contents: read
+ uses: ./.github/workflows/reusable-check-docker.yml
diff --git a/.github/workflows/publish-docker-image.yml b/.github/workflows/publish-docker-image.yml
new file mode 100644
index 0000000000000000000000000000000000000000..100b12a35e34464c16d632c98e5b7964653cd0e1
--- /dev/null
+++ b/.github/workflows/publish-docker-image.yml
@@ -0,0 +1,50 @@
+name: Publish Docker Image
+
+on:
+ workflow_dispatch:
+
+jobs:
+ build-and-push-image:
+ name: Publish Docker Image to GitHub Packages
+ runs-on: ubuntu-latest
+ env:
+ REGISTRY: ghcr.io
+ IMAGE_NAME: ${{ github.repository }}
+ permissions:
+ contents: read
+ packages: write
+ steps:
+ - name: Checkout repository
+ uses: actions/checkout@v7
+ - name: Log in to the Container registry
+ uses: docker/login-action@dbcb813823bdd20940b903addbd779551569679f # v4
+ with:
+ registry: ${{ env.REGISTRY }}
+ username: ${{ github.actor }}
+ password: ${{ secrets.GITHUB_TOKEN }}
+ - name: Extract metadata (tags, labels) for Docker
+ id: meta
+ uses: docker/metadata-action@dc802804100637a589fabce1cb79ff13a1411302 # v6
+ with:
+ images: ${{ env.REGISTRY }}/${{ env.IMAGE_NAME }}
+ # `latest` replaces the `main` tag this action emits by default. With
+ # releases cut on demand, the image can sit several commits behind the
+ # branch, so naming it after the branch misleads. The
+ # `is_default_branch` guard stops a dispatch from a side branch from
+ # moving the tag for everyone.
+ tags: |
+ type=raw,value=latest,enable={{is_default_branch}}
+ - name: Set up Docker Buildx
+ uses: docker/setup-buildx-action@37fe631027851001ddb9b187196cc803df7f5f0e # v4
+ - name: Build and push Docker Image
+ uses: docker/build-push-action@53b7df96c91f9c12dcc8a07bcb9ccacbed38856a # v7
+ with:
+ context: .
+ push: true
+ tags: ${{ steps.meta.outputs.tags }}
+ labels: ${{ steps.meta.outputs.labels }}
+ platforms: linux/amd64,linux/arm64
+ # BuildKit pushes these attestations with the registry credentials
+ # already in use, so no extra job permissions are needed.
+ provenance: mode=max
+ sbom: true
diff --git a/.github/workflows/reusable-check-docker.yml b/.github/workflows/reusable-check-docker.yml
new file mode 100644
index 0000000000000000000000000000000000000000..331ba1c7a1dc95b7deb39f96d360429fde883675
--- /dev/null
+++ b/.github/workflows/reusable-check-docker.yml
@@ -0,0 +1,48 @@
+on:
+ workflow_call:
+ inputs:
+ port:
+ type: string
+ default: "7860"
+jobs:
+ check-docker-container:
+ name: Check Docker Container
+ runs-on: ubuntu-latest
+ env:
+ PORT: ${{ inputs.port }}
+ permissions:
+ contents: read
+ steps:
+ - uses: actions/checkout@v7
+ - run: docker compose -f docker-compose.production.yml up -d
+ - name: Check if main page is available
+ run: until curl -s -o /dev/null -w "%{http_code}" localhost:"$PORT" | grep 200; do sleep 1; done
+ timeout-minutes: 1
+
+ - uses: actions/setup-node@v7
+ with:
+ node-version-file: .nvmrc
+ cache: npm
+
+ - run: npm ci
+
+ - name: Install Playwright Chromium
+ run: npx playwright install --with-deps chromium
+
+ - name: Playwright e2e smoke
+ run: npm run test:e2e
+ env:
+ PLAYWRIGHT_BASE_URL: http://127.0.0.1:${{ inputs.port }}
+
+ - name: Upload Playwright report
+ if: ${{ failure() }}
+ uses: actions/upload-artifact@v7
+ with:
+ name: playwright-report
+ path: |
+ playwright-report/
+ test-results/
+ retention-days: 7
+
+ - if: ${{ always() }}
+ run: docker compose -f docker-compose.production.yml down
diff --git a/.github/workflows/scan-docker-image.yml b/.github/workflows/scan-docker-image.yml
new file mode 100644
index 0000000000000000000000000000000000000000..767c4586f6903163e913ec86ba9218bd28824397
--- /dev/null
+++ b/.github/workflows/scan-docker-image.yml
@@ -0,0 +1,33 @@
+name: Scan Docker Image
+
+# Deliberately not tied to pull requests. The image inherits its base OS
+# packages from `node:lts-slim`, so findings arrive when upstream publishes an
+# advisory rather than when someone changes the app, and gating pull requests on
+# them would only produce a red check nobody can act on.
+on:
+ schedule:
+ - cron: "0 6 * * 1"
+ workflow_dispatch:
+
+jobs:
+ scan-published-image:
+ name: Scan Published Image for Vulnerabilities
+ runs-on: ubuntu-latest
+ permissions:
+ contents: read
+ security-events: write
+ steps:
+ - name: Run Trivy on the published image
+ uses: aquasecurity/trivy-action@ed142fd0673e97e23eac54620cfb913e5ce36c25 # v0.36.0
+ with:
+ image-ref: ghcr.io/${{ github.repository }}:latest
+ format: sarif
+ output: trivy-results.sarif
+ severity: HIGH,CRITICAL
+ # Without this, the report fills with advisories that have no patched
+ # version, drowning out the findings that can actually be fixed.
+ ignore-unfixed: true
+ - name: Upload results to code scanning
+ uses: github/codeql-action/upload-sarif@v4
+ with:
+ sarif_file: trivy-results.sarif
diff --git a/.github/workflows/security.yml b/.github/workflows/security.yml
new file mode 100644
index 0000000000000000000000000000000000000000..15c4db9a4838d81042227d41b9a09ed195b762e1
--- /dev/null
+++ b/.github/workflows/security.yml
@@ -0,0 +1,24 @@
+name: Security Scanning
+
+on:
+ push:
+ branches: [main, master]
+ pull_request:
+ branches: [main, master]
+
+jobs:
+ secret-scanning:
+ name: Secret Scanning (Gitleaks)
+ runs-on: ubuntu-latest
+ permissions:
+ contents: read
+ steps:
+ - name: Checkout repository (full history)
+ uses: actions/checkout@v7
+ with:
+ fetch-depth: 0
+
+ - name: Run Gitleaks
+ uses: gitleaks/gitleaks-action@e0c47f4f8be36e29cdc102c57e68cb5cbf0e8d1e # v3.0.0
+ env:
+ GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
diff --git a/.github/workflows/stale.yml b/.github/workflows/stale.yml
new file mode 100644
index 0000000000000000000000000000000000000000..fb0f6c544f927cd6b06bccf107a1b3df1af8f0f0
--- /dev/null
+++ b/.github/workflows/stale.yml
@@ -0,0 +1,38 @@
+name: Stale
+
+on:
+ schedule:
+ - cron: "30 1 * * *"
+ workflow_dispatch:
+
+jobs:
+ stale:
+ name: Mark and Close Stale Items
+ runs-on: ubuntu-latest
+ permissions:
+ issues: write
+ pull-requests: write
+ steps:
+ - name: Mark and close stale issues and pull requests
+ uses: actions/stale@v11
+ with:
+ days-before-stale: 60
+ # Counted from the moment an item is marked stale, so an issue is
+ # closed once it reaches 90 days of inactivity.
+ days-before-close: 30
+ # Pull requests are labelled and commented on, but never closed
+ # automatically: a stale branch is still worth rebasing.
+ days-before-pr-close: -1
+ stale-issue-label: stale
+ stale-pr-label: stale
+ stale-issue-message: >
+ This issue has been inactive for 60 days. It will be closed in 30 days if there is no
+ further activity. Comment to keep it open.
+ stale-pr-message: >
+ This pull request has been inactive for 60 days. It will not be closed automatically,
+ but please rebase it on `main` and comment if it is still relevant.
+ close-issue-message: >
+ This issue was closed due to inactivity. Comment if it is still relevant and it will be
+ reopened.
+ exempt-issue-labels: good first issue,security,pinned
+ exempt-pr-labels: good first issue,security,pinned
diff --git a/.gitignore b/.gitignore
new file mode 100644
index 0000000000000000000000000000000000000000..fdcf6136ca13352c0a005afa92aaf1dd9136ba07
--- /dev/null
+++ b/.gitignore
@@ -0,0 +1,16 @@
+node_modules
+.DS_Store
+/client/dist
+/server/models
+.vscode
+/vite-build-stats.html
+.env
+/coverage
+.playwright-cli
+*.tsbuildinfo
+
+# Playwright
+test-results/
+playwright-report/
+blob-report/
+playwright/.cache/
diff --git a/.hadolint.yaml b/.hadolint.yaml
new file mode 100644
index 0000000000000000000000000000000000000000..9afbb8db755d1ba7e108879c13bdd3c85df786f8
--- /dev/null
+++ b/.hadolint.yaml
@@ -0,0 +1,10 @@
+# Hadolint configuration for MiniSearch
+# Suppress rules that are not applicable to our Dockerfile
+
+ignored:
+ - DL3064
+ - DL3008
+ - SC2046
+ - DL3025
+ # We run as the named `node` user that the base image already provides, by design.
+ - DL3066
diff --git a/.husky/pre-commit b/.husky/pre-commit
new file mode 100644
index 0000000000000000000000000000000000000000..3e99a15f8ba95155dafceccf7827d7329c245ef4
--- /dev/null
+++ b/.husky/pre-commit
@@ -0,0 +1,21 @@
+#!/usr/bin/env sh
+
+# Secret scanning - runs on every commit to catch credentials before they land in git
+# Requires gitleaks to be installed globally (https://github.com/gitleaks/gitleaks)
+# Skips silently if not installed; CI enforces the check regardless.
+if command -v gitleaks >/dev/null 2>&1; then
+ gitleaks detect --source . --redact --exit-code 1 || exit 1
+else
+ echo "WARNING: gitleaks not installed. Skipping pre-commit secret scanning." >&2
+fi
+
+# Lint and format staged JS/TS files
+if git diff --cached --name-only | grep -qE '\.(ts|tsx|js|jsx|mjs|cjs)$'; then
+ biome="$(git rev-parse --show-toplevel)/node_modules/.bin/biome"
+ if [ ! -x "$biome" ]; then
+ echo "pre-commit: @biomejs/biome not found in node_modules. Run 'npm ci' and try again." >&2
+ exit 1
+ fi
+ "$biome" check --write --staged --no-errors-on-unmatched
+fi
+git diff --cached --name-only --diff-filter=d | while read -r file; do [ -f "$file" ] && git add "$file"; done
diff --git a/.npmrc b/.npmrc
new file mode 100644
index 0000000000000000000000000000000000000000..d62a6cce2647ddb2db2c0c5e9c8041ed768f0928
--- /dev/null
+++ b/.npmrc
@@ -0,0 +1,8 @@
+legacy-peer-deps = true
+min-release-age = 3
+
+# onnxruntime-node's postinstall downloads a CUDA 12 nupkg on linux/x64 and
+# unpacks it with adm-zip, which follows symlinks at the extraction destination
+# (GHSA-vwc7-r8mq-g2x9, unfixed upstream). Both inference services pin
+# `executionProviders: ["cpu"]`, so those binaries are never loaded.
+onnxruntime-node-install = skip
diff --git a/.nvmrc b/.nvmrc
new file mode 100644
index 0000000000000000000000000000000000000000..b009dfb9d9f98f39d71d2a4ecc3110332b969fd3
--- /dev/null
+++ b/.nvmrc
@@ -0,0 +1 @@
+lts/*
diff --git a/Dockerfile b/Dockerfile
new file mode 100644
index 0000000000000000000000000000000000000000..f865c87a005e647604189d73de0a7539ee7c801c
--- /dev/null
+++ b/Dockerfile
@@ -0,0 +1,74 @@
+FROM node:lts-slim
+
+ARG SEARXNG_COMMIT_SHA="6da6eee265daeb4a62ab638d6921522bf405de69"
+
+ENV PORT=7860
+EXPOSE $PORT
+
+ARG USERNAME=node
+ARG HOME_DIR=/home/${USERNAME}
+ARG APP_DIR=${HOME_DIR}/app
+
+# The slim base omits tools the full `node` image ships implicitly: `git` for
+# the SearXNG checkout and the build's commit hash, `curl` for the HEALTHCHECK
+# below, `openssl` for the SearXNG secret key, and `ca-certificates` for both
+# the clone and pip.
+RUN apt-get update && \
+ apt-get install -y --no-install-recommends \
+ ca-certificates \
+ curl \
+ git \
+ openssl \
+ python3 \
+ python3-venv && \
+ apt-get clean && \
+ rm -rf /var/lib/apt/lists/*
+
+RUN mkdir -p /usr/local/searxng /etc/searxng && \
+ chown -R ${USERNAME}:${USERNAME} /usr/local/searxng /etc/searxng && \
+ chmod 755 /etc/searxng
+
+WORKDIR /usr/local/searxng
+RUN python3 -m venv searxng-venv && \
+ chown -R ${USERNAME}:${USERNAME} /usr/local/searxng/searxng-venv && \
+ /usr/local/searxng/searxng-venv/bin/pip install --upgrade pip && \
+ /usr/local/searxng/searxng-venv/bin/pip install wheel setuptools pyyaml lxml
+
+RUN git clone https://github.com/searxng/searxng.git /usr/local/searxng/searxng-src && \
+ git -C /usr/local/searxng/searxng-src checkout $SEARXNG_COMMIT_SHA && \
+ chown -R ${USERNAME}:${USERNAME} /usr/local/searxng/searxng-src
+
+ARG SEARXNG_SETTINGS_PATH="/etc/searxng/settings.yml"
+
+COPY --chown=${USERNAME}:${USERNAME} searxng-settings.yml $SEARXNG_SETTINGS_PATH
+
+WORKDIR /usr/local/searxng/searxng-src
+RUN chmod 644 $SEARXNG_SETTINGS_PATH && \
+ sed -i 's/ultrasecretkey/'$(openssl rand -hex 32)'/g' $SEARXNG_SETTINGS_PATH && \
+ /usr/local/searxng/searxng-venv/bin/pip install -r requirements.txt && \
+ /usr/local/searxng/searxng-venv/bin/pip install --no-build-isolation -e .
+
+USER ${USERNAME}
+
+WORKDIR ${APP_DIR}
+
+COPY --chown=${USERNAME}:${USERNAME} ./package.json ./package-lock.json ./.npmrc ./
+
+RUN npm ci
+
+COPY --chown=${USERNAME}:${USERNAME} . .
+
+# The commit hash is optional build metadata, so a build context without a
+# usable repository must not fail the build. This happens when building from a
+# git worktree, where `.git` is a file pointing at a gitdir outside the context;
+# git then treats every command as fatal, including `config --global`.
+RUN git config --global --add safe.directory ${APP_DIR} 2>/dev/null || true; \
+ git rev-parse --short HEAD >/dev/null 2>&1 || \
+ echo "WARNING: no usable git repository in the build context, so the app will report an empty commit hash."; \
+ npm run build
+
+HEALTHCHECK --start-period=60s --interval=30s --timeout=10s --retries=3 CMD curl -fsS http://localhost:${PORT}/status || exit 1
+
+ENTRYPOINT [ "/bin/sh", "-c" ]
+
+CMD ["(cd /usr/local/searxng/searxng-src && /usr/local/searxng/searxng-venv/bin/python -m searx.webapp > /dev/null 2>&1) & npm start -- --host"]
diff --git a/README.md b/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..8edcbaed488941d31e971bd6eb3982da79af6d12
--- /dev/null
+++ b/README.md
@@ -0,0 +1,179 @@
+---
+title: MiniSearch
+emoji: 👌🔍
+colorFrom: yellow
+colorTo: yellow
+sdk: docker
+short_description: Minimalist web-searching app with browser-based AI assistant
+pinned: true
+custom_headers:
+ cross-origin-embedder-policy: require-corp
+ cross-origin-opener-policy: same-origin
+ cross-origin-resource-policy: cross-origin
+---
+
+
+
+## About
+
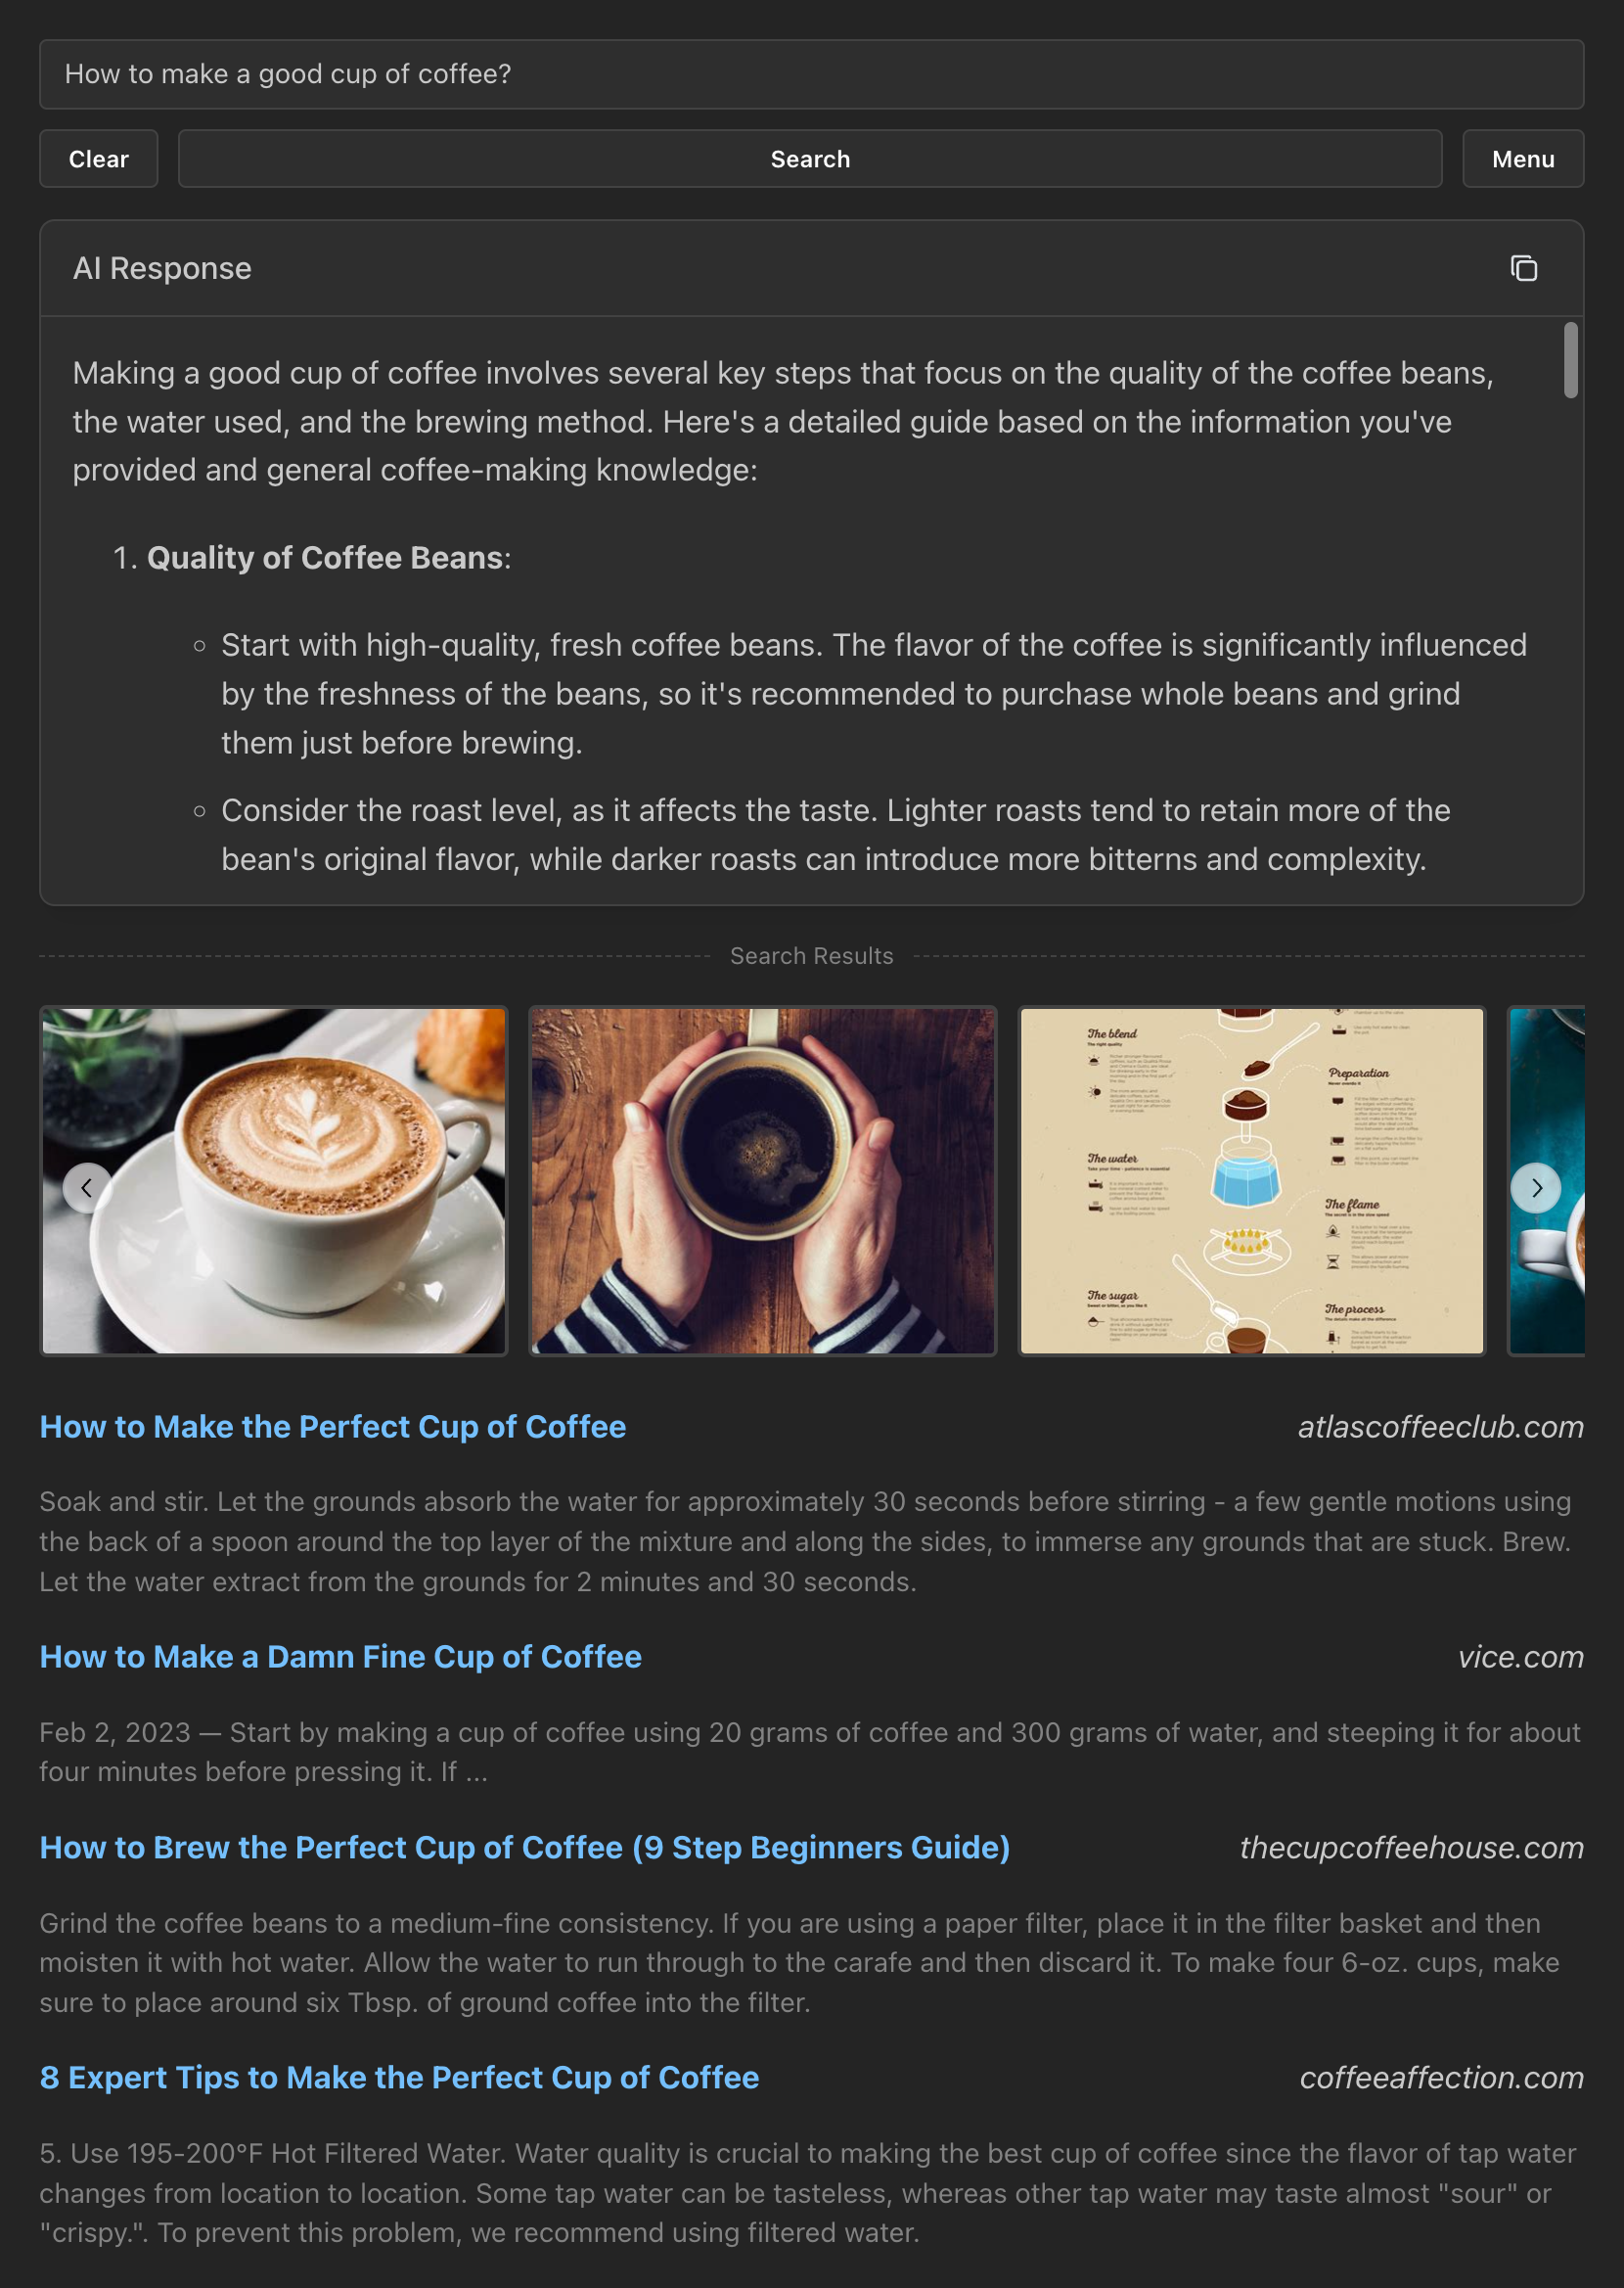
+MiniSearch is a self-hosted search engine with an AI assistant.
+
+The AI can run entirely inside your browser tab, on GPU or CPU, so a working setup needs no API key, no separate inference server, and no third party seeing your queries. Web results come from a bundled [SearXNG](https://github.com/searxng/searxng) metasearch instance, are reranked locally, and the whole thing ships as a single Docker container.
+
+## Features
+
+- **Private by design.** No tracking, no telemetry, no accounts. Search history, cached results, and chats are stored in your browser and never leave your machine.
+- **AI in your browser.** Pick from several curated models (135M to 4B parameters) that run on WebGPU where available and on CPU elsewhere. Models are downloaded once and cached by the browser.
+- **Any backend you like.** Connect an OpenAI-compatible API (Ollama, LM Studio, vLLM, llama.cpp server, or a hosted provider), use the crowdsourced AI Horde, or let the server proxy your own API without exposing its key.
+- **A real search pipeline.** Text and image results aggregated by SearXNG, reranked locally by a cross-encoder model, cached, and rate-limited; all inside the container.
+- **Answers you can verify.** Responses cite the sources they draw from, support follow-up questions with conversation memory, reveal the model's reasoning on demand, and can be read aloud.
+- **Local history and analytics.** Fuzzy-searchable history with pinning and full-session restore, plus usage statistics and an activity heatmap. Retention is configurable, and storage stays in the browser.
+- **Fits your workflow.** Set it as your browser's default search engine, trigger it from Raycast, embed it in your own pages, and optionally protect your instance with access keys.
+
+## Quick start
+
+Run the published image:
+
+```bash
+docker run -p 7860:7860 ghcr.io/felladrin/minisearch
+```
+
+Then open and start searching.
+
+
+Pin to a specific build
+
+`latest` moves on every release, so it changes under you. To stay on a known-good build, pin the digest, which always identifies the same image:
+
+```bash
+docker inspect --format '{{index .RepoDigests 0}}' ghcr.io/felladrin/minisearch:latest
+docker run -p 7860:7860 ghcr.io/felladrin/minisearch@sha256:1a2b3c...
+```
+
+The version the running instance reports (in the menu, and under `build` on `/status`) tells you which commit it was built from.
+
+Images carry provenance and SBOM attestations, which you can inspect with:
+
+```bash
+docker buildx imagetools inspect ghcr.io/felladrin/minisearch:latest
+```
+
+
+
+
+Use Docker Compose
+
+Add the service to your `docker-compose.yml`:
+
+```yaml
+services:
+ minisearch:
+ image: ghcr.io/felladrin/minisearch:latest
+ ports:
+ - "7860:7860"
+```
+
+
+
+
+Build from source
+
+```bash
+git clone https://github.com/felladrin/MiniSearch.git
+cd MiniSearch
+docker compose -f docker-compose.production.yml up --build
+```
+
+
+
+
+Host it on Hugging Face
+
+[Duplicate the Space](https://huggingface.co/spaces/Felladrin/MiniSearch?duplicate=true) to get your own hosted instance, no server required. Environment variables can be set in the Space settings.
+
+
+
+## How it works
+
+```mermaid
+flowchart LR
+ subgraph browser [Your browser]
+ UI[Search UI]
+ LocalAI[In-browser model WebGPU or CPU]
+ Storage[(IndexedDB history and cache)]
+ end
+ subgraph container [Docker container]
+ Server[App server]
+ SearXNG[SearXNG metasearch]
+ Reranker[Reranker ONNX Runtime]
+ end
+ UI <--> Storage
+ UI -->|search| Server
+ Server --> SearXNG
+ SearXNG --> Web((Web))
+ Server --> Reranker
+ UI -.->|in-browser inference| LocalAI
+ UI -.->|remote inference, optional| RemoteAPI[OpenAI-compatible API or AI Horde]
+```
+
+Your query goes to the app server, which asks the bundled SearXNG instance to aggregate results from multiple search engines. The server reranks them with a small cross-encoder model before returning them, and the browser caches them locally. If the AI response is enabled, the assistant reads the top results and writes a cited answer, either with a model running in your browser or through the backend you configured. The full picture is in [docs/overview.md](docs/overview.md).
+
+## Configuration
+
+MiniSearch works out-of-the-box, but you can customize it if you want. More details at [docs/configuration.md](docs/configuration.md).
+
+## FAQ
+
+
+How do I make it my browser's default search engine?
+
+Add a custom search engine in your browser settings using the pattern `http://localhost:7860/?q=%s`, replacing the host with your instance's address. Your search term replaces `%s`.
+
+
+
+
+How do I search from Raycast?
+
+Add [this Quicklink](https://ray.so/quicklinks/shared?quicklinks=%7B%22link%22:%22https:%5C/%5C/felladrin-minisearch.hf.space%5C/?q%3D%7BQuery%7D%22,%22name%22:%22MiniSearch%22%7D) to Raycast, and edit it to point to your own instance if you have one.
+
+
+
+
+Can I use my own models through an OpenAI-compatible API?
+
+Yes. Open the menu, set "AI Processing Location" to `Remote server (OpenAI-compatible API)`, then fill in the base URL, and optionally an API key and a model name. If the model is left blank, it is picked from the ones the API lists.
+
+
+
+
+Can others use my instance with my API key without seeing it?
+
+Yes. Configure the `INTERNAL_OPENAI_COMPATIBLE_API_*` variables from the [Configuration](#configuration) table and restart the container. A new option with the name you chose appears in the "AI Processing Location" menu, and the key stays on the server.
+
+
+
+## Contributing
+
+See the [Contributing Guidelines](.github/CONTRIBUTING.md), [Code of Conduct](.github/CODE_OF_CONDUCT.md), and [Security Policy](.github/SECURITY.md).
+
+## Releases
+
+Notable changes are documented in the [Changelog](changelog.md). Docker images are published to [ghcr.io/felladrin/minisearch](https://github.com/felladrin/MiniSearch/pkgs/container/minisearch) as `latest` and `YYYY.M.D-`; pin to a dated tag if you want a stable reference.
+
+## License
+
+[Apache License 2.0](license.txt)
diff --git a/agents.md b/agents.md
new file mode 100644
index 0000000000000000000000000000000000000000..ebda93cc42215047c5b7724a01e7ff51b4e5150a
--- /dev/null
+++ b/agents.md
@@ -0,0 +1,257 @@
+# MiniSearch Agent Guidelines
+
+This is your navigation hub. Start here, follow the links, and return when you need orientation.
+
+## Before You Start
+
+**New to this codebase?** Read in this order:
+1. `docs/quick-start.md` - Get it running
+2. `docs/overview.md` - Understand the system
+3. `docs/project-structure.md` - Navigate the code
+
+**Making changes?** Check:
+- `docs/coding-conventions.md` - Code style
+- `docs/development-commands.md` - Available commands
+- `docs/pull-requests.md` - How to submit
+
+## Repository Map
+
+### Getting Started
+- **`docs/quick-start.md`** - Installation, first run, verification
+- **`docs/overview.md`** - System architecture and data flow
+- **`docs/project-structure.md`** - Directory layout and component organization
+
+### Configuration & Setup
+- **`docs/configuration.md`** - Environment variables and settings reference
+- **`docs/security.md`** - Access control, privacy, and security model
+
+### Core Functionality
+- **`docs/api.md`** - HTTP endpoint reference: parameters, responses, and error codes
+- **`docs/ai-integration.md`** - AI inference types (Wllama, OpenAI, AI Horde, Internal)
+- **`docs/ui-components.md`** - Component architecture and PubSub patterns
+- **`docs/search-history.md`** - History database schema and management
+- **`docs/conversation-memory.md`** - Token budgeting and rolling summaries
+- **`docs/reranking.md`** - Reranker subsystem and model lifecycle
+- **`docs/page-content.md`** - Reading result pages to ground AI answers
+- **`docs/glossary.md`** - Codebase-specific terms and domain concepts
+
+### Development
+- **`docs/development-commands.md`** - Docker, npm, and testing commands
+- **`docs/failure-injection.md`** - Graceful-degradation test matrix
+- **`docs/coding-conventions.md`** - Style guide and patterns
+- **`docs/pull-requests.md`** - PR process and merge philosophy
+- **`docs/core-technologies.md`** - Technology stack and dependencies
+- **`docs/design.md`** - UI/UX design principles
+
+## Agent Decision Tree
+
+```
+Need to:
+├── Add a feature?
+│ ├── UI component → docs/ui-components.md
+│ ├── AI integration → docs/ai-integration.md
+│ ├── Search functionality → client/modules/search.ts
+│ └── Settings option → docs/configuration.md
+├── Fix a bug?
+│ ├── UI issue → Check component + PubSub channels
+│ ├── AI not working → docs/ai-integration.md + browser console
+│ ├── Search failing → Check SearXNG + server hooks
+│ └── Build error → docs/development-commands.md
+├── Configure deployment?
+│ ├── Environment variables → docs/configuration.md
+│ ├── Access control → docs/security.md
+│ └── Docker setup → docs/overview.md
+└── Understand data flow?
+ ├── Search flow → client/modules/search.ts
+ ├── AI generation → client/modules/textGeneration.ts
+ ├── State management → docs/ui-components.md
+ └── History/Chat → docs/search-history.md + docs/conversation-memory.md
+```
+
+## Key Files Reference
+
+### Entry Points
+- `client/index.tsx` - React app initialization
+- `vite.config.ts` - Vite dev server with hooks
+- `Dockerfile` - Multi-stage container build
+
+### Business Logic Modules
+- `client/modules/search.ts` - Search orchestration and caching
+- `client/modules/textGeneration.ts` - AI response flow
+- `client/modules/pubSub.ts` - All PubSub channels
+- `client/modules/settings.ts` - Settings management
+- `client/modules/history.ts` - Search history database
+
+### Server-Side Modules
+- `server/searchEndpointServerHook.ts` - `/search` endpoints
+- `server/pageContentEndpointServerHook.ts` - `/page-content` endpoint
+- `server/internalApiEndpointServerHook.ts` - `/inference` proxy
+- `server/webSearchService.ts` - SearXNG integration
+- `server/rerankerService.ts` - Local result reranking
+
+### UI Components
+- `client/components/App/` - Application shell with error boundaries
+- `client/components/Search/Form/` - Search input and form
+- `client/components/Search/Results/` - Textual and graphical results display
+- `client/components/Search/History/` - History drawer and button
+- `client/components/AiResponse/` - AI response display and chat interface
+- `client/components/Pages/Main/` - Main page layout
+- `client/components/Pages/Main/Menu/` - Settings drawers (AI, Search, Interface, History, Voice, Actions)
+- `client/components/Pages/AccessPage.tsx` - Access key validation page
+- `client/components/Analytics/SearchStats.tsx` - Search analytics cards
+- `client/components/Logs/` - Application logging modal
+- `client/components/Settings/HistorySettings.tsx` - History configuration UI
+
+### Client Modules
+- `client/modules/pubSub.ts` - All PubSub channels for state management
+- `client/modules/search.ts` - Search orchestration and IndexedDB caching
+- `client/modules/textGeneration.ts` - AI response generation and chat handling
+- `client/modules/textGenerationWithWllama.ts` - Browser-based inference
+- `client/modules/textGenerationWithOpenAi.ts` - OpenAI-compatible API inference
+- `client/modules/textGenerationWithHorde.ts` - AI Horde distributed inference
+- `client/modules/textGenerationWithInternalApi.ts` - Internal API proxy inference
+- `client/modules/settings.ts` - Default settings and inference type definitions
+- `client/modules/history.ts` - IndexedDB persistence for searches and chat
+- `client/modules/wllama.ts` - Wllama model configuration and management
+- `client/modules/webGpu.ts` - WebGPU availability detection (`"gpu" in navigator`)
+- `client/modules/querySuggestions.ts` - Search suggestion UI, stored in IndexedDB
+- `client/modules/relatedSearchQuery.ts` - Generates related search queries
+- `client/modules/followUpQuestions.ts` - Generates follow-up questions via `followUpQuestionPubSub`
+- `client/modules/accessKey.ts` - Validates and stores access keys using argon2id hashing and localStorage
+- `client/modules/parentWindow.ts` - PostMessage API for embedding in parent windows
+- `client/modules/searchTokenHash.ts` - CSRF protection token generation
+- `client/modules/pageContent.ts` - Requests extracted page text from `/page-content`
+- `client/modules/systemPrompt.ts` - System prompt templates
+- `client/modules/logEntries.ts` - Application logging with unique IDs
+- `client/modules/appInfo.ts` - Application metadata and version info
+- `client/modules/textToSpeech.ts` - Reads answers aloud: engine selection, fallback, and the playback queue
+- `client/modules/textToSpeechWorker.ts` - Synthesizes sentences off the main thread
+- `client/modules/textToSpeechWorkerProtocol.ts` - Message types shared by both sides of the worker
+- `client/modules/piper.ts` - The only module that imports `@diffusionstudio/vits-web`
+- `client/modules/speechToText.ts` - Dictation: microphone capture, the worker's lifecycle, and the `SpeechRecognition` fallback
+- `client/modules/speechToTextWorker.ts` - Runs the Moonshine transcriber off the main thread
+- `client/modules/speechToTextWorkerProtocol.ts` - Message types shared by both sides of the dictation worker
+- `client/modules/moonshine.ts` - The only module that imports `@moonshine-ai/moonshine-wasm`
+- `client/modules/keyboard.ts` - Keyboard shortcut handling
+- `client/modules/stringFormatters.ts` - Text formatting utilities
+- `client/modules/types.ts` - Shared TypeScript type definitions
+
+### Server Modules
+- `server/searchEndpointServerHook.ts` - `/search/text` and `/search/images` endpoints
+- `server/thumbnailEndpointServerHook.ts` - `/thumbnail` endpoint: one search-result thumbnail at a time, token-gated, with an in-process LRU in front of the upstream host
+- `server/internalApiEndpointServerHook.ts` - `/inference` proxy to self-hosted API
+- `server/validateAccessKeyServerHook.ts` - Access key validation endpoint
+- `server/statusEndpointServerHook.ts` - `/status` health check endpoint
+- `server/configEndpointServerHook.ts` - `/api/config` runtime client configuration
+- `server/rerankerServiceHook.ts` - Reranker model lifecycle management
+- `server/compressionServerHook.ts` - gzip/brotli compression for responses
+- `server/crossOriginServerHook.ts` - COOP/COEP headers for SharedArrayBuffer
+- `server/dictationModelServerHook.ts` - `/dictation-models/` endpoint: serves the pinned speech-to-text model files from the instance
+- `server/cacheServerHook.ts` - Cache-Control headers (preview server only)
+- `server/webSearchService.ts` - SearXNG integration with circuit breaker and retry logic
+- `server/pageContentService.ts` - Reads result pages and extracts query-relevant passages
+- `server/utils/publicUrl.ts` - Blocks private and reserved addresses before a server-side fetch
+- `server/rerankerService.ts` - Reranker service (ONNX Runtime inference)
+- `server/rankSearchResults.ts` - Score-based filtering and result reordering
+- `server/searchToken.ts` - CSRF token generation and storage
+- `server/verifiedTokens.ts` - In-memory `Set` of verified session tokens
+- `server/verifyTokenAndRateLimit.ts` - Token verification and rate limiting
+- `server/handleTokenVerification.ts` - Search token validation logic
+- `server/searchesSinceLastRestart.ts` - In-memory search counters for analytics
+- `server/downloadFileFromHuggingFaceRepository.ts` - Downloads model files from HuggingFace
+
+### Hooks
+- `client/hooks/useSearchHistory.ts` - Search history management from IndexedDB
+- `client/hooks/useHistoryRestore.ts` - Restores full search state from history
+- `client/hooks/useDrawerState.ts` - Drawer open/close state with logging
+- `client/hooks/useScreenWakeLock.ts` - Keeps the screen awake while a response is generating
+
+## Common Tasks Quick Reference
+
+### Add a new AI model
+1. Add to `client/modules/wllama.ts`
+2. Update `docs/ai-integration.md`
+3. Update `docs/configuration.md` defaults
+
+### Add a new setting
+1. Add to `client/modules/settings.ts` default object
+2. Add UI in `client/components/Pages/Main/Menu/`
+3. Update `docs/configuration.md` settings table
+
+### Modify search behavior
+1. Edit `client/modules/search.ts`
+2. Update `server/webSearchService.ts` if server-side changes needed
+3. Check `server/rerankerService.ts` if reranking affected
+
+### Fix UI state issues
+1. Check PubSub channels in `client/modules/pubSub.ts`
+2. Verify component subscriptions in `docs/ui-components.md`
+3. Ensure proper state updates in business logic modules
+
+### Analyze test coverage
+1. Run `npm run test:coverage` to generate reports
+2. Check `coverage/coverage-summary.json` for quick metrics
+3. See `docs/development-commands.md` for full coverage analysis guide
+
+## Quality Gates
+
+Before any change:
+```bash
+npm run lint
+```
+
+Inside the dev container, the same command is `docker compose exec development-server npm run lint`.
+
+This runs:
+- Biome (formatting/linting)
+- TypeScript (type checking)
+- knip (dead code detection)
+- jscpd (copy-paste detection)
+- Custom architectural linter
+- Doc gardening and documentation validator scripts
+
+### A bare `tsc` is not a full typecheck
+
+The project is split across three TypeScript configs, and the default one covers less than its name suggests:
+
+| Config | Covers |
+| --- | --- |
+| `tsconfig.json` | `client`, `shared`, `test` |
+| `tsconfig.node.json` | `vite.config.ts`, `server`, `shared` |
+| `tsconfig.eval.json` | `eval`, `shared` |
+
+So `npx tsc --noEmit` reports success while type errors sit in `server/` or `eval/`, and CI then fails on a change that looked clean locally. Only `npm run lint` runs all three configs. Never treat a bare `tsc` as a green typecheck.
+
+## Agent-First Principles
+
+**Repository as System of Record:**
+- All knowledge lives in versioned docs/ structure
+- This file is your entry point - start here
+- Follow links, don't assume - verify in code
+
+**Context Efficiency:**
+- Use this map to navigate quickly
+- Return to this file when context drifts
+- Follow the decision tree for common tasks
+
+**Architecture & Boundaries:**
+- Respect PubSub boundaries - don't cross concerns
+- Client vs server - keep them separate
+- Feature-based organization - one folder per feature
+
+**Documentation Maintenance:**
+- Update these docs when you learn something new
+- Add cross-references when linking concepts
+- Keep examples current with actual code
+
+## Technology Stack
+
+React + TypeScript + Mantine UI v9, with privacy-first architecture.
+See `docs/core-technologies.md` for complete dependency list and selection criteria.
+
+## Need Help?
+
+1. Check relevant doc in `docs/`
+2. Read the module code in `client/modules/` or `server/`
+3. Look at similar existing implementations
+4. Run `npm run lint` to validate changes
diff --git a/biome.json b/biome.json
new file mode 100644
index 0000000000000000000000000000000000000000..8eabdbc127fd59154cfc74d2c740e00dcf6f6161
--- /dev/null
+++ b/biome.json
@@ -0,0 +1,34 @@
+{
+ "$schema": "./node_modules/@biomejs/biome/configuration_schema.json",
+ "vcs": {
+ "enabled": true,
+ "clientKind": "git",
+ "useIgnoreFile": true
+ },
+ "files": {
+ "ignoreUnknown": false
+ },
+ "formatter": {
+ "enabled": true,
+ "indentStyle": "space"
+ },
+ "linter": {
+ "enabled": true,
+ "rules": {
+ "preset": "recommended"
+ }
+ },
+ "javascript": {
+ "formatter": {
+ "quoteStyle": "double"
+ }
+ },
+ "assist": {
+ "enabled": true,
+ "actions": {
+ "source": {
+ "organizeImports": "on"
+ }
+ }
+ }
+}
diff --git a/changelog.md b/changelog.md
new file mode 100644
index 0000000000000000000000000000000000000000..830cbdd3b6a66965ed0e6f5141ac8e46268e7a06
--- /dev/null
+++ b/changelog.md
@@ -0,0 +1,765 @@
+# Changelog
+
+Notable changes, grouped by date, most recent first.
+
+
+## 2026-09-13
+
+- Fixed /status reporting the web search service as healthy while its circuit breaker was open and every search was failing.
+- Added a degraded state and per-engine failure counts to the web search service status on /status.
+
+## 2026-09-11
+
+- Added text-to-speech playback that reads answers aloud with a local neural TTS model, falling back to OS voices.
+
+## 2026-09-10
+
+- Added a wake lock that keeps the screen awake while a response is generating.
+
+## 2026-09-08
+
+- Fixed search history cleanup failing with a TransactionInactiveError.
+
+## 2026-08-31
+
+- Dropped image results that come back without a thumbnail URL instead of rendering broken tiles.
+
+## 2026-08-30
+
+- Added the server start time to the /status endpoint.
+- Added a token-gated /thumbnail endpoint that loads image result thumbnails lazily through the server.
+
+## 2026-08-28
+
+- Made searches degrade to cached and image results when the search engines are down.
+
+## 2026-08-26
+
+- Kept the reranker relevance score on results and tagged results in the prompt for the model.
+- Fixed untrusted text in the prompt by labeling all of it, not only page excerpts.
+
+## 2026-08-25
+
+- Fixed OpenAI-compatible inference to retry the next model when a stream reports an error.
+
+## 2026-08-23
+
+- Security: refused token and access-key hashes with mismatched argon2 parameters.
+- Security: refused an already-rejected token without performing a second argon2 verification.
+- Fixed searches that came back empty with unresponsive engines by retrying them.
+
+## 2026-08-21
+
+- Security: rate-limited the access-key validation endpoint.
+- Improved page-content excerpt selection by fusing bi-encoder dense scores with lexical ranking, reading PDF results instead of dropping them, and overlapping splits of long passages.
+- Fixed the configured request timeout to act as an idle timeout on the upstream stream.
+
+## 2026-08-20
+
+- Fixed treating a SearXNG response with unresponsive engines as a successful search.
+- Added operational reporting to /status for search timing, reranker effect, dropped thumbnails, inference outcomes, and token and rate-limit rejections.
+
+## 2026-08-19
+
+- Security: pinned deepmerge-ts to 8.0.1 via overrides to address a vulnerability.
+
+## 2026-08-17
+
+- Fixed duplicate inference when the search form remounts.
+
+## 2026-08-16
+
+- Showed the model size while a model is downloading.
+- Reworked the search results hierarchy and the drawer transitions.
+- Fixed the search form submitting while composing text with an IME.
+- Fixed non-Latin follow-up questions being mangled.
+
+## 2026-08-15
+
+- Security: guarded thumbnail fetches against SSRF with a size cap, rate-limited requests before token verification, and stopped logging whole error objects on the internal API endpoint.
+- Fixed the image lightbox source label crashing on relative URLs.
+- Fixed failed searches being reported as "no results".
+- Added a value proposition and AI opt-in prompt on first run, shown only after the first search.
+
+## 2026-08-14
+
+- Security: bumped nanoid to 3.3.18 to address a vulnerability.
+- Fixed the server logging the search query.
+- Added grounding of AI answers on fetched page content.
+
+## 2026-08-13
+
+- Fixed pre-stream inference failures to return 503.
+
+## 2026-08-12
+
+- Fixed treating an empty upstream stream as a successful response.
+
+## 2026-08-10
+
+- Published the Docker image as `latest` instead of `main`, with provenance, SBOM, and a scan.
+
+## 2026-08-08
+
+- Security: bumped postcss to resolve a nanoid vulnerability.
+
+## 2026-08-07
+
+- Set LittleLamb 290M as the new default Wllama model.
+- Scaled the default CPU thread count with the machine.
+- Fixed the UI transitioning to the generating state before any content arrived.
+
+## 2026-08-05
+
+- Replaced the reranker with a multilingual cross-encoder.
+
+## 2026-07-31
+
+- Security: validated and clamped server proxy inputs.
+
+## 2026-07-30
+
+- Removed secret build args from the Dockerfile and hardened .dockerignore.
+- Made client configuration runtime-resolved via a new /api/config endpoint.
+- Fixed truncating reranker input by characters instead of tokens.
+- Fixed handling of chunk boundaries in internal API streams.
+- Consolidated duplicate circuit breakers in the web search service.
+
+## 2026-07-29
+
+- Fixed /status reporting sessions as zero.
+
+## 2026-07-28
+
+- Validated cached model files before reusing them.
+- Security: overrode adm-zip to 0.6.0 to clear GHSA-xcpc-8h2w-3j85.
+- Replaced llama.cpp with ONNX Runtime for reranking.
+- Made the reranker retry on CPU when the GPU provider fails.
+- Made image thumbnails keyboard accessible.
+
+## 2026-07-27
+
+- Security: generated the search token with a CSPRNG, widened access-key and search-token hash digests to 32 bytes, and tightened search token file permissions.
+
+## 2026-07-24
+
+- Fixed internal API stream errors being swallowed instead of surfaced.
+
+## 2026-07-23
+
+- Used SHA-256 for cache keys and included the result limit in the hash input.
+- Added screen-reader landmarks and a live region for streaming responses.
+
+## 2026-07-22
+
+- Keyed the rate limiter on the client IP behind a TRUST_PROXY setting to close a rate-limit bypass, and cleaned up verified tokens.
+
+## 2026-07-21
+
+- Clamped max_tokens on the /inference proxy.
+
+## 2026-07-13
+
+- Removed the searchResultsToConsider setting and hardcoded it to 6.
+
+## 2026-07-08
+
+- Replaced the recent-activity list with a contribution heatmap.
+- Added a browser notification when an AI response is ready, which focuses the tab when clicked, with a toggle that properly requests permission.
+
+## 2026-06-27
+
+- Removed user-configurable sampling parameters from the settings and UI.
+
+## 2026-05-11
+
+- Replaced WebLLM with Wllama WebGPU support and fixed Wllama not receiving search results in its prompt.
+
+## 2026-03-07
+
+- Gave each log entry a unique ID so the Logs modal renders them correctly.
+
+## 2026-02-13
+
+- Fixed image results and the image carousel not displaying by using the correct thumbnail property.
+- Fixed analytics handling an undefined search source.
+- Added a loading state during access key validation.
+
+## 2026-02-12
+
+- Replaced the axios and searxng packages with a native fetch implementation.
+- Added binary-compatibility detection and platform logging to the reranker service.
+
+## 2026-02-03
+
+- Added Unicode surrogate sanitization to the reranker service.
+
+## 2026-01-01
+
+- Fixed the counting of daily average searches.
+- Added reasoning content streaming support for AI responses.
+
+## 2025-12-01
+
+- Ensured the model always has access to search results relevant to the current question, not just the original search query.
+
+## 2025-11-21
+
+- Added auto-restart on error for the reranker service.
+
+## 2025-11-08
+
+- Fixed stale chat messages carrying over by clearing them before a new search starts.
+
+## 2025-11-07
+
+- Prevented duplicate auto-initialization of searches triggered from the URL query.
+
+## 2025-11-06
+
+- Recorded searches made from the address bar in the search history.
+
+## 2025-11-05
+
+- Implemented a search history system.
+
+## 2025-10-14
+
+- Removed the PM2 process manager in favor of a direct npm start command.
+
+## 2025-10-13
+
+- Implemented conversation summarization to handle context window overflow.
+
+## 2025-10-07
+
+- Added message editing and response regeneration to the chat interface.
+
+## 2025-10-03
+
+- Added automatic retry with random model fallback for OpenAI-compatible APIs.
+
+## 2025-09-15
+
+- Added model auto-selection for text generation with OpenAI-compatible APIs.
+
+## 2025-09-01
+
+- Added blockquote support to the Markdown renderer.
+
+## 2025-08-14
+
+- Enabled flash attention in Wllama for faster inference.
+
+## 2025-08-11
+
+- Made AI Horde text generation race parallel requests and use the first to finish.
+
+## 2025-08-10
+
+- Implemented parallel text generation for AI Horde.
+
+## 2025-08-09
+
+- Added an error boundary fallback for code highlighting of unknown languages.
+
+## 2025-07-06
+
+- Ensured unique model IDs in the model dropdown.
+
+## 2025-07-02
+
+- Downgraded Wllama to a version that can run larger models without running out of memory.
+
+## 2025-06-11
+
+- Tracked and prevented duplicate follow-up questions.
+- Interrupted the AI Horde waiting loop when the selected model cannot fulfill the request.
+- Improved text-to-speech preprocessing by removing reasoning blocks and preserving link text.
+
+## 2025-06-10
+
+- Kept the system prompt with search results when the context buffer fills and preserved user/assistant alternation when truncating messages.
+- Implemented related search query generation with accumulation of search results.
+- Fixed the key used to deduplicate image results from new search results.
+- Added expandable links so users can see what a link is about while the response generates.
+
+## 2025-06-06
+
+- Implemented statistical filtering for search results.
+- Added web search service health checks, exposed the health status on /status, and added a Docker healthcheck.
+- Added log filtering to the logs view.
+
+## 2025-05-22
+
+- Improved API auth token handling by moving the token to query parameters with proper status codes and error formatting.
+
+## 2025-05-21
+
+- Replaced react-syntax-highlighter with Mantine's Shiki-based code highlight component.
+
+## 2025-05-16
+
+- Fell back to "text" syntax highlighting when no language is provided for a code block.
+
+## 2025-05-11
+
+- Added an AI response opt-in prompt for first-time users.
+
+## 2025-05-07
+
+- Migrated the Docker base image from Alpine to Debian for compatibility with the latest SearXNG image.
+
+## 2025-05-05
+
+- Updated the WebLLM package and its model IDs to Qwen3-0.6B.
+- Refactored search caching to use Dexie.js.
+
+## 2025-03-14
+
+- Fixed the transition from the "Preparing response" to "Generating response" state when using Wllama.
+
+## 2025-03-05
+
+- Added a loader indicating that the AI thinking process is running.
+
+## 2025-03-02
+
+- Fixed an issue preventing typing in the input field from the Follow-up Questions area.
+
+## 2025-02-22
+
+- Fixed image results occasionally appearing duplicated.
+
+## 2025-02-21
+
+- Added an AI reasoning section driven by custom markers in the response.
+
+## 2025-02-20
+
+- Improved search result quality by removing less relevant matches.
+- Fixed image re-ranking returning the unranked list and added a one-second timeout when fetching image thumbnails.
+
+## 2025-02-11
+
+- Changed the default models to 1B-parameter models.
+
+## 2025-02-09
+
+- Replaced the "openai" package with "@ai-sdk/openai-compatible" for OpenAI-compatible inference.
+
+## 2025-02-08
+
+- Displayed the username and kudos balance of the configured AI Horde API key.
+
+## 2025-02-02
+
+- Reduced the Docker image size by switching to a multi-stage build.
+
+## 2025-01-25
+
+- Switched the reranker to a faster model running on a single thread.
+- Replaced the node-llama-cpp dependency with a llama-server instance running inside the container.
+
+## 2025-01-24
+
+- Allowed setting allowed-hosts via environment variable.
+
+## 2025-01-23
+
+- Opened links in AI responses in new tabs.
+- Improved the read-aloud feature by cleaning the text before invoking speech synthesis.
+- Allowed manually entering a model name when the API returns an empty model list.
+
+## 2025-01-17
+
+- Streamed responses from AI Horde models.
+
+## 2025-01-05
+
+- Added an AI Horde model selection dropdown.
+
+## 2025-01-03
+
+- Fixed unhandled errors in the read-aloud (speak response) feature.
+- Allowed users to supply their own AI Horde API key for faster responses.
+
+## 2024-12-28
+
+- Allowed manually setting the model identifier when the /models endpoint is unavailable.
+
+## 2024-12-03
+
+- Removed the custom Wllama cache manager now that iOS 18 caches correctly by default.
+
+## 2024-12-01
+
+- Increased the default context size to 4096 tokens and updated Wllama cache settings.
+- Improved markdown rendering in AI responses with copyable code blocks, table styling, and correct nested list items.
+- Added error and loading handling to the search results section.
+
+## 2024-11-26
+
+- Added voice selection for AI responses.
+
+## 2024-11-25
+
+- Added speech synthesis for reading AI responses aloud.
+
+## 2024-11-24
+
+- Allowed users to customize AI inference parameters such as temperature, top-p, frequency penalty, and presence penalty.
+
+## 2024-11-23
+
+- Filtered out invalid image results to avoid broken entries in image search.
+- Decoupled text and image search so results load independently, raising the rate limit to match.
+
+## 2024-11-20
+
+- Fixed the model selector resetting the chosen model when re-opening the menu on Remote Server (API).
+
+## 2024-11-14
+
+- Reduced Wllama memory usage by switching the cache from f16 to q8_0.
+
+## 2024-11-13
+
+- Made searches faster by processing SearXNG results concurrently.
+
+## 2024-11-09
+
+- Added AI Horde as an additional inference provider alongside the existing browser-based and OpenAI options.
+
+## 2024-11-07
+
+- Added a Search Settings section to the menu, including a new Search Results Limit setting.
+
+## 2024-11-06
+
+- Capped the maximum number of search results server-side while keeping the client-side setting configurable.
+
+## 2024-11-03
+
+- Improved error handling in the AI Settings form when Remote Server (API) is selected.
+- Allowed copying messages from the Follow-up Questions area.
+- Added a button to regenerate the response.
+
+## 2024-11-01
+
+- Improved image search quality and speed by downloading only images that pass similarity checks.
+
+## 2024-10-30
+
+- Fixed the Interrupt Generation behavior.
+- Added an option to turn AI response auto-scrolling on and off.
+
+## 2024-10-28
+
+- Stopped fetching the model list until the user sets an API Base URL.
+- Displayed a suggested CPU thread count for Wllama.
+
+## 2024-10-26
+
+- Fixed the categories queried from SearXNG, avoiding errors from unused categories.
+- Displayed the model size alongside the model download progress bar.
+
+## 2024-10-25
+
+- Displayed Wllama model sizes in megabytes, matching the WebLLM models.
+- Added average searches per session statistics.
+
+## 2024-10-24
+
+- Renamed "Inference Type" to "AI Processing Location" for clarity.
+- Made the Docker image runnable on both ARM64 and AMD64 platforms.
+- Displayed an error message under the API Model field when listing models from the API fails.
+- Added access key persistence with a configurable timeout, including an ACCESS_KEY_TIMEOUT_HOURS build argument.
+
+## 2024-10-23
+
+- Improved the re-ranking of search results.
+
+## 2024-10-22
+
+- Fixed the response state not updating after approving an AI model download.
+
+## 2024-10-21
+
+- Required user permission before downloading AI models, for transparency and data-usage control.
+- Included search result URLs in Wllama prompts by default.
+- Implemented dynamic context window management using token counting for chat responses.
+
+## 2024-10-19
+
+- Passed only the last three messages when continuing a Follow-up Questions conversation, to fit small context limits.
+
+## 2024-10-18
+
+- Removed search results whose snippets start with "[data:image".
+
+## 2024-10-16
+
+- Fixed link snippets overflowing their container when content contains extremely long strings.
+- Added a button to restore the default AI instructions.
+
+## 2024-10-13
+
+- Allowed reading the default inference type from the DEFAULT_INFERENCE_TYPE environment variable.
+
+## 2024-10-11
+
+- Added automatic selection of the first available model when configuring an OpenAI-compatible API.
+
+## 2024-10-10
+
+- Added support for asking follow-up questions to the AI response.
+
+## 2024-10-08
+
+- Fixed OpenAI-compatible inference for models that do not accept a System role.
+- Added support for an internal OpenAI-compatible API as a text-generation backend.
+
+## 2024-10-05
+
+- Added support for customizing the default models via the `.env` file.
+
+## 2024-10-04
+
+- Added an access page that gates the app when `ACCESS_KEYS` is configured in the `.env` file.
+
+## 2024-09-29
+
+- Replaced the image zoom library with `yet-another-react-lightbox` to improve previewing of image results.
+- Made the model selection list searchable to handle long model lists.
+
+## 2024-09-23
+
+- Added sending the search query to the parent window via postMessage when navigating from an embedded instance.
+
+## 2024-09-21
+
+- Made Qwen 0.5B the default Wllama model.
+- Added a setting to enable or disable submitting a search with the Enter key.
+- Added a dark mode toggle to the interface settings.
+
+## 2024-09-18
+
+- Fixed settings to always fall back to a valid model when a previously selected model is no longer available.
+- Added an option to show the full AI response without a scroll bar.
+
+## 2024-09-16
+
+- Integrated an OpenAI-compatible API for text generation.
+
+## 2024-09-15
+
+- Replaced the image results scroll area with a carousel.
+- Limited text results only after processing them so more results are available for reranking.
+- Displayed the AI response in a card and added a button to copy it.
+- Added recommended-model indicators for WebGPU and CPU in the model selection.
+
+## 2024-09-14
+
+- Switched production server process management to PM2.
+- Migrated the UI components from React Suite to Mantine.
+
+## 2024-09-09
+
+- Kept the already-generated part of the AI response visible by showing failure messages below it instead of hiding the response.
+- Added a logs viewer accessible from a menu button.
+
+## 2024-09-08
+
+- Fixed duplicate source URLs for image results returned by SearXNG.
+- Added a setting for customizing the AI instructions.
+
+## 2024-09-07
+
+- Added image search with zoomable image results.
+
+## 2024-09-05
+
+- Added a setting to select the model used when running inference on CPU.
+
+## 2024-09-04
+
+- Fixed the CPU thread count saved through the settings menu being stored with the wrong type.
+
+## 2024-09-01
+
+- Added a configurable background image.
+
+## 2024-08-30
+
+- Improved Markdown rendering and syntax highlighting, including fixing code blocks overflowing the container width.
+
+## 2024-08-29
+
+- Added IndexedDB caching for search results.
+
+## 2024-08-25
+
+- Avoided showing more than one search result from the same hostname.
+- Added a setting to choose the AI model used when WebGPU is enabled.
+- Added a button to interrupt response generation.
+
+## 2024-08-24
+
+- Removed the RatchetML inference backend.
+- Fixed Wllama models not loading from cache on iPads by using a custom cache manager.
+- Allowed multi-threading for Wllama on mobile devices.
+- Added a progress bar when loading the AI model.
+
+## 2024-08-22
+
+- Revamped the UI using React Suite components.
+
+## 2024-07-26
+
+- Replaced the built-in search functionality with the SearXNG library.
+
+## 2024-07-20
+
+- Renamed settings to menu and added an option to reset settings and delete all cached files to free up space.
+
+## 2024-07-13
+
+- Allowed Wllama models to run when the browser reports no internet access.
+
+## 2024-06-28
+
+- Replaced react-router-dom with the wouter library to reduce memory usage.
+
+## 2024-06-27
+
+- Started responding immediately when the number of search results to consider is zero.
+
+## 2024-06-23
+
+- Added client-side caching of search results during a session.
+
+## 2024-06-20
+
+- Added a setting for the number of search results to consider when generating AI responses.
+
+## 2024-06-14
+
+- Restricted RatchetML inference to the Safari browser.
+- Added a clear button shown when the search field is not empty.
+
+## 2024-06-12
+
+- Added a score threshold to avoid showing irrelevant search results.
+
+## 2024-06-09
+
+- Interrupted text generation when the user runs another search while one is still in progress.
+- Added client-side routing so new searches no longer reload the page.
+
+## 2024-06-05
+
+- Added embedding-based reranking of search results using node-llama-cpp.
+
+## 2024-05-21
+
+- Started loading the AI model while web search results were being fetched, speeding up responses.
+- Removed the Summarize Links feature.
+
+## 2024-05-18
+
+- Replaced the compression middleware with http-compression to support HTTP/2.
+
+## 2024-05-17
+
+- Added a setting for the number of CPU threads to use.
+
+## 2024-05-11
+
+- Switched to single-threaded Wllama on mobile devices due to low available memory.
+
+## 2024-05-10
+
+- Used sharded GGUF models on desktop to stay within Safari's cache size limit.
+- Displayed the model loading progress percentage when using Wllama.
+
+## 2024-05-08
+
+- Increased the variety of query suggestions by fetching new ones at runtime instead of defining them at build time.
+
+## 2024-05-06
+
+- Improved the link summarization feature by using Jina AI Reader.
+
+## 2024-05-03
+
+- Added RatchetML as a WebGPU inference backend alongside Web-LLM.
+
+## 2024-05-01
+
+- Moved search result ranking to the backend so mobile devices benefit from better results.
+
+## 2024-04-27
+
+- Added a rate limiter and token verification to prevent abuse of the search endpoint.
+- Added a /status endpoint for monitoring the server.
+
+## 2024-04-20
+
+- Added Llama 3 8B as the larger model for Web-LLM.
+
+## 2024-04-17
+
+- Replaced the Express server with Vite's preview server.
+
+## 2024-03-28
+
+- Added a keyword-based re-search when the original query returns no results.
+
+## 2024-03-23
+
+- Added suggested queries to the search form.
+
+## 2024-03-22
+
+- Displayed the domain alongside each search result link to increase click confidence.
+
+## 2024-03-16
+
+- Added Wllama as an alternative in-browser inference library.
+
+## 2024-03-12
+
+- Added re-ranking of search results before passing them to the language model.
+
+## 2024-01-09
+
+- Added three model sizes to fit all devices when running on transformers.js.
+
+## 2023-12-31
+
+- Added support for a larger model option when using transformers.js.
+
+## 2023-12-23
+
+- Switched from a text-to-text-generation model to a text-generation model.
+
+## 2023-11-02
+
+- Started publishing the Docker image to GitHub Packages.
+
+## 2023-10-23
+
+- Added a setting for disabling AI responses.
+
+## 2023-10-22
+
+- Adopted SearXNG as the metasearch engine.
+
+## 2023-10-21
+
+- Added a settings menu with options to toggle links summarization and use of a larger model.
+
+## 2023-10-14
+
+- Started MiniSearch as a self-hosted metasearch app with in-browser AI-generated answers.
diff --git a/client/components/AiResponse/AiModelDownloadAllowanceContent.tsx b/client/components/AiResponse/AiModelDownloadAllowanceContent.tsx
new file mode 100644
index 0000000000000000000000000000000000000000..48fbb9ce81045bc0cd3ba2e5f99b66cfb7e30c5c
--- /dev/null
+++ b/client/components/AiResponse/AiModelDownloadAllowanceContent.tsx
@@ -0,0 +1,62 @@
+import { Alert, Button, Group, Text } from "@mantine/core";
+import { IconCheck, IconInfoCircle, IconX } from "@tabler/icons-react";
+import { usePubSub } from "create-pubsub/react";
+import { useState } from "react";
+import { addLogEntry } from "@/modules/logEntries";
+import { settingsPubSub } from "@/modules/pubSub";
+
+export default function AiModelDownloadAllowanceContent() {
+ const [settings, setSettings] = usePubSub(settingsPubSub);
+ const [hasDeniedDownload, setDeniedDownload] = useState(false);
+
+ const handleAccept = () => {
+ setSettings({
+ ...settings,
+ allowAiModelDownload: true,
+ });
+ addLogEntry("User allowed the AI model download");
+ };
+
+ const handleDecline = () => {
+ setDeniedDownload(true);
+ addLogEntry("User denied the AI model download");
+ };
+
+ return hasDeniedDownload ? null : (
+ }
+ >
+
+ To obtain AI responses, a language model needs to be downloaded to your
+ browser. Enabling this option lets the app store it and load it
+ instantly on subsequent uses.
+
+
+ Please note that the download size ranges from 100 MB to 4 GB, depending
+ on the model you select in the Menu, so it's best to avoid using mobile
+ data for this.
+
+
+ }
+ onClick={handleDecline}
+ size="xs"
+ >
+ Not now
+
+ }
+ onClick={handleAccept}
+ size="xs"
+ >
+ Allow download
+
+
+
+ );
+}
diff --git a/client/components/AiResponse/AiResponseContent.test.tsx b/client/components/AiResponse/AiResponseContent.test.tsx
new file mode 100644
index 0000000000000000000000000000000000000000..fc7da14fb787a3a51acd63789bab8510f07c4adf
--- /dev/null
+++ b/client/components/AiResponse/AiResponseContent.test.tsx
@@ -0,0 +1,72 @@
+import { MantineProvider } from "@mantine/core";
+import { render, screen } from "@testing-library/react";
+import { usePubSub } from "create-pubsub/react";
+import { beforeEach, describe, expect, it, vi } from "vitest";
+import AiResponseContent from "./AiResponseContent";
+
+vi.mock("create-pubsub/react", () => ({
+ usePubSub: vi.fn(),
+}));
+
+vi.mock("@/modules/textGeneration", () => ({
+ searchAndRespond: vi.fn(),
+}));
+
+vi.mock("@/modules/textToSpeech", () => ({
+ speak: vi.fn(),
+}));
+
+vi.mock("./FormattedMarkdown", () => ({
+ default: ({ children }: { children: string }) => (
+
{children}
+ ),
+}));
+
+function renderContent(textGenerationState: string) {
+ vi.mocked(usePubSub)
+ .mockReturnValueOnce([{ enableAiResponseScrolling: false }, vi.fn()])
+ .mockReturnValueOnce(["idle", vi.fn()]);
+
+ return render(
+
+
+ ,
+ );
+}
+
+describe("AiResponseContent", () => {
+ beforeEach(() => {
+ vi.clearAllMocks();
+ });
+
+ it("wraps the response body in a polite live region", () => {
+ renderContent("generating");
+
+ const liveRegion = screen
+ .getByTestId("formatted-markdown")
+ .closest("[aria-live]");
+ expect(liveRegion).toHaveAttribute("aria-live", "polite");
+ });
+
+ it("marks the live region busy while generating", () => {
+ renderContent("generating");
+
+ const liveRegion = screen
+ .getByTestId("formatted-markdown")
+ .closest("[aria-live]");
+ expect(liveRegion).toHaveAttribute("aria-busy", "true");
+ });
+
+ it("clears the busy flag once generation is no longer in progress", () => {
+ renderContent("completed");
+
+ const liveRegion = screen
+ .getByTestId("formatted-markdown")
+ .closest("[aria-live]");
+ expect(liveRegion).toHaveAttribute("aria-busy", "false");
+ });
+});
diff --git a/client/components/AiResponse/AiResponseContent.tsx b/client/components/AiResponse/AiResponseContent.tsx
new file mode 100644
index 0000000000000000000000000000000000000000..fbcf3a9a86353c015ee6762c06ab875a73b61f34
--- /dev/null
+++ b/client/components/AiResponse/AiResponseContent.tsx
@@ -0,0 +1,174 @@
+import {
+ ActionIcon,
+ Alert,
+ Badge,
+ Box,
+ Card,
+ Group,
+ ScrollArea,
+ Text,
+ Tooltip,
+} from "@mantine/core";
+import {
+ IconArrowsMaximize,
+ IconArrowsMinimize,
+ IconHandStop,
+ IconInfoCircle,
+ IconRefresh,
+ IconVolume2,
+} from "@tabler/icons-react";
+import type { PublishFunction } from "create-pubsub";
+import { usePubSub } from "create-pubsub/react";
+import { type ReactNode, useMemo } from "react";
+import { settingsPubSub, textToSpeechStatePubSub } from "@/modules/pubSub";
+import { searchAndRespond } from "@/modules/textGeneration";
+import { speak } from "@/modules/textToSpeech";
+import CopyIconButton from "./CopyIconButton";
+import FormattedMarkdown from "./FormattedMarkdown";
+
+export default function AiResponseContent({
+ textGenerationState,
+ response,
+ setTextGenerationState,
+}: {
+ textGenerationState: string;
+ response: string;
+ setTextGenerationState: PublishFunction<
+ | "failed"
+ | "awaitingSearchResults"
+ | "preparingToGenerate"
+ | "idle"
+ | "loadingModel"
+ | "generating"
+ | "interrupted"
+ | "completed"
+ >;
+}) {
+ const [settings, setSettings] = usePubSub(settingsPubSub);
+ const [textToSpeechState] = usePubSub(textToSpeechStatePubSub);
+ const isSpeaking = textToSpeechState === "speaking";
+ const isGenerating = textGenerationState === "generating";
+
+ const ConditionalScrollArea = useMemo(
+ () =>
+ ({ children }: { children: ReactNode }) => {
+ return settings.enableAiResponseScrolling ? (
+
+ {children}
+
+ ) : (
+ {children}
+ );
+ },
+ [settings.enableAiResponseScrolling],
+ );
+
+ return (
+
+
+
+
+
+ {textGenerationState === "generating"
+ ? "Generating AI Response..."
+ : "AI Response"}
+
+ {textGenerationState === "interrupted" && (
+
+ Interrupted
+
+ )}
+
+
+ {textGenerationState === "generating" ? (
+
+ setTextGenerationState("interrupted")}
+ variant="subtle"
+ color="gray"
+ >
+
+
+
+ ) : (
+
+ searchAndRespond()}
+ variant="subtle"
+ color="gray"
+ >
+
+
+
+ )}
+
+ speak(response)}
+ variant="subtle"
+ color={isSpeaking ? "blue" : "gray"}
+ >
+
+
+
+ {settings.enableAiResponseScrolling ? (
+
+ {
+ setSettings({
+ ...settings,
+ enableAiResponseScrolling: false,
+ });
+ }}
+ variant="subtle"
+ color="gray"
+ >
+
+
+
+ ) : (
+
+ {
+ setSettings({
+ ...settings,
+ enableAiResponseScrolling: true,
+ });
+ }}
+ variant="subtle"
+ color="gray"
+ >
+
+
+
+ )}
+
+
+
+
+
+
+
+ {response}
+
+
+ {textGenerationState === "failed" && (
+ }
+ >
+ Could not generate response. Please try refreshing the page.
+
+ )}
+
+
+ );
+}
diff --git a/client/components/AiResponse/AiResponseSection.tsx b/client/components/AiResponse/AiResponseSection.tsx
new file mode 100644
index 0000000000000000000000000000000000000000..11f0352c25e476d4bccc2e626d73b841deb0b895
--- /dev/null
+++ b/client/components/AiResponse/AiResponseSection.tsx
@@ -0,0 +1,112 @@
+import { CodeHighlightAdapterProvider } from "@mantine/code-highlight";
+import { usePubSub } from "create-pubsub/react";
+import { useMemo } from "react";
+import { useScreenWakeLock } from "@/hooks/useScreenWakeLock";
+import {
+ chatMessagesPubSub,
+ isRestoringFromHistoryPubSub,
+ modelLoadingProgressPubSub,
+ modelSizeInMegabytesPubSub,
+ queryPubSub,
+ responsePubSub,
+ settingsPubSub,
+ textGenerationStatePubSub,
+} from "@/modules/pubSub";
+import { shikiAdapter } from "@/modules/shiki";
+import type { TextGenerationState } from "@/modules/types";
+import "@mantine/code-highlight/styles.css";
+import AiModelDownloadAllowanceContent from "./AiModelDownloadAllowanceContent";
+import AiResponseContent from "./AiResponseContent";
+import ChatInterface from "./ChatInterface";
+import LoadingModelContent from "./LoadingModelContent";
+import PreparingContent from "./PreparingContent";
+
+const statesKeepingTheScreenAwake: TextGenerationState[] = [
+ "loadingModel",
+ "awaitingSearchResults",
+ "preparingToGenerate",
+ "generating",
+];
+
+export default function AiResponseSection() {
+ const [query] = usePubSub(queryPubSub);
+ const [response] = usePubSub(responsePubSub);
+ const [textGenerationState, setTextGenerationState] = usePubSub(
+ textGenerationStatePubSub,
+ );
+ const [modelLoadingProgress] = usePubSub(modelLoadingProgressPubSub);
+ const [settings] = usePubSub(settingsPubSub);
+ const [modelSizeInMegabytes] = usePubSub(modelSizeInMegabytesPubSub);
+ const [chatMessages] = usePubSub(chatMessagesPubSub);
+ const [isRestoringFromHistory] = usePubSub(isRestoringFromHistoryPubSub);
+
+ useScreenWakeLock(statesKeepingTheScreenAwake.includes(textGenerationState));
+
+ return useMemo(() => {
+ if (!settings.enableAiResponse || textGenerationState === "idle") {
+ return null;
+ }
+
+ const generatingStates = [
+ "generating",
+ "interrupted",
+ "completed",
+ "failed",
+ ];
+ if (generatingStates.includes(textGenerationState)) {
+ return (
+
+
+
+ {textGenerationState === "completed" && (
+ 0 ? chatMessages : undefined
+ }
+ suppressInitialFollowUp={isRestoringFromHistory}
+ />
+ )}
+
+ );
+ }
+
+ if (textGenerationState === "loadingModel") {
+ return (
+
+ );
+ }
+
+ if (textGenerationState === "preparingToGenerate") {
+ return ;
+ }
+
+ if (textGenerationState === "awaitingSearchResults") {
+ return ;
+ }
+
+ if (textGenerationState === "awaitingModelDownloadAllowance") {
+ return ;
+ }
+
+ return null;
+ }, [
+ settings.enableAiResponse,
+ textGenerationState,
+ response,
+ query,
+ chatMessages,
+ modelLoadingProgress,
+ modelSizeInMegabytes,
+ setTextGenerationState,
+ isRestoringFromHistory,
+ ]);
+}
diff --git a/client/components/AiResponse/ChatHeader.tsx b/client/components/AiResponse/ChatHeader.tsx
new file mode 100644
index 0000000000000000000000000000000000000000..f62bc98185cb401cd8db79b7f2368ad9c1ef42a5
--- /dev/null
+++ b/client/components/AiResponse/ChatHeader.tsx
@@ -0,0 +1,33 @@
+import { Group, Text } from "@mantine/core";
+import type { ChatMessage } from "@/modules/types";
+import CopyIconButton from "./CopyIconButton";
+
+interface ChatHeaderProps {
+ messages: ChatMessage[];
+}
+
+function ChatHeader({ messages }: ChatHeaderProps) {
+ const getChatContent = () => {
+ return messages
+ .slice(2)
+ .map(
+ (msg, index) =>
+ `${index + 1}. ${msg.role?.toUpperCase()}\n\n${msg.content}`,
+ )
+ .join("\n\n");
+ };
+
+ return (
+
+ Follow-up questions
+ {messages.length > 2 && (
+
+ )}
+
+ );
+}
+
+export default ChatHeader;
diff --git a/client/components/AiResponse/ChatInputArea.tsx b/client/components/AiResponse/ChatInputArea.tsx
new file mode 100644
index 0000000000000000000000000000000000000000..92ddfd2a22fbf65a81b2eadbd623ee0c532e4f2e
--- /dev/null
+++ b/client/components/AiResponse/ChatInputArea.tsx
@@ -0,0 +1,112 @@
+import { Button, Group, Textarea } from "@mantine/core";
+import { IconSend } from "@tabler/icons-react";
+import { usePubSub } from "create-pubsub/react";
+import {
+ chatGenerationStatePubSub,
+ chatInputPubSub,
+ followUpQuestionPubSub,
+ isRestoringFromHistoryPubSub,
+ suppressNextFollowUpPubSub,
+} from "@/modules/pubSub";
+
+interface ChatInputAreaProps {
+ onKeyDown: (event: React.KeyboardEvent) => void;
+ handleSend: (textToSend?: string) => void;
+}
+
+function ChatInputArea({ onKeyDown, handleSend }: ChatInputAreaProps) {
+ const [input, setInput] = usePubSub(chatInputPubSub);
+ const [generationState] = usePubSub(chatGenerationStatePubSub);
+ const [followUpQuestion] = usePubSub(followUpQuestionPubSub);
+ const [isRestoringFromHistory] = usePubSub(isRestoringFromHistoryPubSub);
+ const [suppressNextFollowUp] = usePubSub(suppressNextFollowUpPubSub);
+
+ const isGenerating =
+ generationState.isGeneratingResponse &&
+ !generationState.isGeneratingFollowUpQuestion;
+
+ const defaultPlaceholder = "Anything else you would like to know?";
+ const placeholder =
+ isRestoringFromHistory || suppressNextFollowUp
+ ? defaultPlaceholder
+ : followUpQuestion || defaultPlaceholder;
+
+ const onChange = (event: React.ChangeEvent) => {
+ setInput(event.target.value);
+ };
+ const handleKeyDownWithPlaceholder = (
+ event: React.KeyboardEvent,
+ ) => {
+ // Same IME guard as handleEnterKeyDown: the Enter that confirms a
+ // composition candidate must not fire the follow-up question while the
+ // composition text has not reached the input value yet.
+ const isComposing = event.nativeEvent.isComposing || event.keyCode === 229;
+
+ if (
+ input.trim() === "" &&
+ followUpQuestion &&
+ !isRestoringFromHistory &&
+ !suppressNextFollowUp &&
+ !isComposing
+ ) {
+ if (event.key === "Enter" && !event.shiftKey) {
+ event.preventDefault();
+ handleSend(followUpQuestion);
+ return;
+ }
+ }
+
+ onKeyDown(event);
+ };
+
+ const handleSendWithPlaceholder = () => {
+ if (
+ input.trim() === "" &&
+ followUpQuestion &&
+ !isRestoringFromHistory &&
+ !suppressNextFollowUp
+ ) {
+ handleSend(followUpQuestion);
+ } else {
+ handleSend();
+ }
+ };
+
+ return (
+
+
+
+
+ );
+}
+
+export default ChatInputArea;
diff --git a/client/components/AiResponse/ChatInterface.test.tsx b/client/components/AiResponse/ChatInterface.test.tsx
new file mode 100644
index 0000000000000000000000000000000000000000..85bd1d44e6a54f64a6201378858a974d8443ece4
--- /dev/null
+++ b/client/components/AiResponse/ChatInterface.test.tsx
@@ -0,0 +1,651 @@
+import { MantineProvider } from "@mantine/core";
+import { act, render } from "@testing-library/react";
+import { afterEach, beforeEach, describe, expect, it, vi } from "vitest";
+import {
+ chatGenerationStatePubSub,
+ chatInputPubSub,
+ followUpQuestionPubSub,
+ suppressNextFollowUpPubSub,
+} from "@/modules/pubSub";
+import type { ChatMessage } from "@/modules/types";
+import ChatInterface from "./ChatInterface";
+
+const [updateChatGenerationState, , getChatGenerationState] =
+ chatGenerationStatePubSub;
+const [updateChatInput] = chatInputPubSub;
+const [updateFollowUpQuestion, , getFollowUpQuestion] = followUpQuestionPubSub;
+const [updateSuppressNextFollowUp] = suppressNextFollowUpPubSub;
+
+vi.mock("@/modules/textGeneration", () => ({
+ generateChatResponse: vi.fn(),
+}));
+
+vi.mock("@/modules/followUpQuestions", () => ({
+ generateFollowUpQuestion: vi.fn(),
+}));
+
+vi.mock("@/modules/chatHelpers", () => ({
+ persistChatMessages: vi.fn(() => Promise.resolve()),
+ runFollowUpSearch: vi.fn(() => Promise.resolve()),
+}));
+
+vi.mock("@/modules/notifications", () => ({
+ showAiCompleteNotification: vi.fn(),
+}));
+
+vi.mock("@/modules/logEntries", () => ({ addLogEntry: vi.fn() }));
+
+vi.mock("./ChatHeader", () => ({ default: () => null }));
+
+let sendMessage: (textToSend?: string) => Promise;
+let regenerateResponse: () => Promise;
+let messageListMessages: ChatMessage[] = [];
+let messageListIsGenerating = false;
+
+vi.mock("./ChatInputArea", () => ({
+ default: (props: { handleSend: (textToSend?: string) => Promise }) => {
+ sendMessage = props.handleSend;
+ return null;
+ },
+}));
+
+vi.mock("./MessageList", () => ({
+ default: (props: {
+ messages: ChatMessage[];
+ isGenerating: boolean;
+ onRegenerate: () => Promise;
+ }) => {
+ regenerateResponse = props.onRegenerate;
+ messageListMessages = props.messages;
+ messageListIsGenerating = props.isGenerating;
+ return null;
+ },
+}));
+
+const { generateChatResponse } = await import("@/modules/textGeneration");
+const { generateFollowUpQuestion } = await import(
+ "@/modules/followUpQuestions"
+);
+
+/** A promise plus the handle to settle it, so a test can hold a call open. */
+function deferred() {
+ let resolve: (value: T) => void = () => undefined;
+ let reject: (reason: Error) => void = () => undefined;
+ const promise = new Promise((resolvePromise, rejectPromise) => {
+ resolve = resolvePromise;
+ reject = rejectPromise;
+ });
+ return { promise, resolve, reject };
+}
+
+const initialQuery = "What is a wake lock?";
+const initialResponse = "An API that keeps the screen on.";
+
+function renderChatInterface({ suppressInitialFollowUp = true } = {}) {
+ return render(
+
+
+ ,
+ );
+}
+
+function stubWakeLockApi() {
+ const release = vi.fn(() => Promise.resolve());
+ const request = vi.fn(() =>
+ Promise.resolve({ released: false, release, addEventListener: vi.fn() }),
+ );
+
+ Object.defineProperty(navigator, "wakeLock", {
+ value: { request },
+ configurable: true,
+ });
+
+ return { request, release };
+}
+
+beforeEach(() => {
+ updateChatGenerationState({
+ isGeneratingResponse: false,
+ isGeneratingFollowUpQuestion: false,
+ });
+ updateChatInput("");
+ updateFollowUpQuestion("");
+ updateSuppressNextFollowUp(false);
+ messageListMessages = [];
+ messageListIsGenerating = false;
+ vi.mocked(generateChatResponse).mockResolvedValue("An answer.");
+ vi.mocked(generateFollowUpQuestion).mockResolvedValue("A question?");
+});
+
+afterEach(() => {
+ Reflect.deleteProperty(navigator, "wakeLock");
+ vi.resetAllMocks();
+});
+
+describe("ChatInterface generation state", () => {
+ it("leaves the follow-up question flag off after sending during its generation", async () => {
+ const earlierQuestion = deferred();
+ vi.mocked(generateFollowUpQuestion).mockReturnValueOnce(
+ earlierQuestion.promise,
+ );
+
+ renderChatInterface({ suppressInitialFollowUp: false });
+
+ await act(async () => {});
+
+ expect(getChatGenerationState().isGeneratingFollowUpQuestion).toBe(true);
+
+ await act(async () => {
+ await sendMessage("And how do I use it?");
+ });
+
+ expect(getChatGenerationState().isGeneratingFollowUpQuestion).toBe(false);
+
+ await act(async () => {
+ earlierQuestion.resolve("An earlier question?");
+ });
+ });
+
+ it("keeps the response flag on when an earlier follow-up question completes mid-response", async () => {
+ const followUpQuestion = deferred();
+ vi.mocked(generateFollowUpQuestion).mockReturnValueOnce(
+ followUpQuestion.promise,
+ );
+ const chatResponse = deferred();
+ vi.mocked(generateChatResponse).mockReturnValueOnce(chatResponse.promise);
+
+ renderChatInterface({ suppressInitialFollowUp: false });
+
+ await act(async () => {});
+
+ expect(getChatGenerationState().isGeneratingFollowUpQuestion).toBe(true);
+
+ let send: Promise = Promise.resolve();
+
+ await act(async () => {
+ send = sendMessage("And how do I use it?");
+ });
+
+ expect(getChatGenerationState().isGeneratingResponse).toBe(true);
+
+ await act(async () => {
+ followUpQuestion.resolve("An earlier question?");
+ });
+
+ expect(getChatGenerationState().isGeneratingResponse).toBe(true);
+
+ await act(async () => {
+ chatResponse.resolve("An answer.");
+ await send;
+ });
+ });
+
+ it("leaves a concurrent follow-up question flag alone when the response fails", async () => {
+ const followUpQuestion = deferred();
+ vi.mocked(generateFollowUpQuestion).mockReturnValueOnce(
+ followUpQuestion.promise,
+ );
+ vi.mocked(generateChatResponse).mockRejectedValueOnce(
+ new Error("no model"),
+ );
+
+ renderChatInterface({ suppressInitialFollowUp: false });
+
+ await act(async () => {});
+
+ await act(async () => {
+ await sendMessage("And how do I use it?");
+ });
+
+ expect(getChatGenerationState()).toEqual({
+ isGeneratingResponse: false,
+ isGeneratingFollowUpQuestion: true,
+ });
+
+ await act(async () => {
+ followUpQuestion.resolve("An earlier question?");
+ });
+ });
+
+ it("starts one generation when two sends land in the same task", async () => {
+ renderChatInterface();
+
+ await act(async () => {
+ await Promise.all([
+ sendMessage("And how do I use it?"),
+ sendMessage("Does it work offline?"),
+ ]);
+ });
+
+ expect(generateChatResponse).toHaveBeenCalledTimes(1);
+ });
+
+ it("accepts a send while the follow-up question is still being generated", async () => {
+ const followUpQuestion = deferred();
+ vi.mocked(generateFollowUpQuestion).mockReturnValueOnce(
+ followUpQuestion.promise,
+ );
+ // Streams the answer, so the placeholder row holds it the way it does in
+ // the app and a leftover copy would be visible.
+ vi.mocked(generateChatResponse).mockImplementationOnce(
+ async (_messages, onUpdate) => {
+ onUpdate("An answer.");
+ return "An answer.";
+ },
+ );
+
+ renderChatInterface();
+
+ let send: Promise = Promise.resolve();
+
+ await act(async () => {
+ send = sendMessage("And how do I use it?");
+ });
+
+ expect(getChatGenerationState()).toEqual({
+ isGeneratingResponse: false,
+ isGeneratingFollowUpQuestion: true,
+ });
+
+ // The input stays enabled through this window, so the guard has to accept
+ // the send rather than refuse it silently, and the streamed placeholder
+ // must not leave a second copy of the answer in the list.
+ expect(messageListIsGenerating).toBe(false);
+ expect(
+ messageListMessages.filter((message) => message.content === "An answer."),
+ ).toHaveLength(1);
+
+ await act(async () => {
+ await sendMessage("Does it work offline?");
+ });
+
+ expect(generateChatResponse).toHaveBeenCalledTimes(2);
+
+ await act(async () => {
+ followUpQuestion.resolve("An earlier question?");
+ await send;
+ });
+ });
+
+ it("regenerates without clobbering a follow-up question in flight", async () => {
+ const followUpQuestion = deferred();
+ vi.mocked(generateFollowUpQuestion).mockReturnValueOnce(
+ followUpQuestion.promise,
+ );
+ const regeneratedQuestion = deferred();
+ vi.mocked(generateFollowUpQuestion).mockReturnValueOnce(
+ regeneratedQuestion.promise,
+ );
+ const chatResponse = deferred();
+ vi.mocked(generateChatResponse)
+ .mockResolvedValueOnce("An answer.")
+ .mockReturnValueOnce(chatResponse.promise);
+
+ renderChatInterface();
+
+ let send: Promise = Promise.resolve();
+
+ await act(async () => {
+ send = sendMessage("And how do I use it?");
+ });
+
+ let regenerate: Promise = Promise.resolve();
+
+ await act(async () => {
+ regenerate = regenerateResponse();
+ });
+
+ expect(getChatGenerationState().isGeneratingResponse).toBe(true);
+ expect(getChatGenerationState().isGeneratingFollowUpQuestion).toBe(true);
+
+ await act(async () => {
+ followUpQuestion.resolve("An earlier question?");
+ });
+
+ expect(getChatGenerationState().isGeneratingResponse).toBe(true);
+
+ await act(async () => {
+ chatResponse.resolve("A regenerated answer.");
+ });
+
+ // The regenerate hands the lock over the way the send does: it must not
+ // stay in the response phase while its own question is still coming.
+ expect(getChatGenerationState()).toEqual({
+ isGeneratingResponse: false,
+ isGeneratingFollowUpQuestion: true,
+ });
+
+ await act(async () => {
+ regeneratedQuestion.resolve("A later question?");
+ await Promise.all([send, regenerate]);
+ });
+ });
+
+ it("keeps the follow-up question flag on until the newest call finishes", async () => {
+ const earlierQuestion = deferred();
+ const newerQuestion = deferred();
+ vi.mocked(generateFollowUpQuestion)
+ .mockReturnValueOnce(earlierQuestion.promise)
+ .mockReturnValueOnce(newerQuestion.promise);
+
+ renderChatInterface({ suppressInitialFollowUp: false });
+ await act(async () => {});
+
+ expect(getChatGenerationState().isGeneratingFollowUpQuestion).toBe(true);
+
+ let send: Promise = Promise.resolve();
+ await act(async () => {
+ send = sendMessage("And how do I use it?");
+ });
+
+ // The orphaned call settles first. Its completion must write nothing.
+ await act(async () => {
+ earlierQuestion.resolve("The previous answer's question?");
+ });
+
+ expect(getChatGenerationState().isGeneratingFollowUpQuestion).toBe(true);
+ expect(getFollowUpQuestion()).toBe("");
+
+ await act(async () => {
+ newerQuestion.resolve("The newest question?");
+ await send;
+ });
+
+ expect(getFollowUpQuestion()).toBe("The newest question?");
+ expect(getChatGenerationState().isGeneratingFollowUpQuestion).toBe(false);
+ });
+
+ it("leaves both generation flags off after unmounting mid-generation", async () => {
+ const heldQuestion = deferred();
+ vi.mocked(generateFollowUpQuestion).mockReturnValueOnce(
+ heldQuestion.promise,
+ );
+
+ const { unmount } = renderChatInterface({ suppressInitialFollowUp: false });
+ await act(async () => {});
+
+ expect(getChatGenerationState().isGeneratingFollowUpQuestion).toBe(true);
+
+ await act(async () => {
+ unmount();
+ });
+
+ expect(getChatGenerationState()).toEqual({
+ isGeneratingResponse: false,
+ isGeneratingFollowUpQuestion: false,
+ });
+
+ // The orphaned call lands after the unmount; it must not write into what
+ // is now the next mount's state.
+ await act(async () => {
+ heldQuestion.resolve("A question nobody asked for?");
+ });
+
+ expect(getChatGenerationState()).toEqual({
+ isGeneratingResponse: false,
+ isGeneratingFollowUpQuestion: false,
+ });
+ expect(getFollowUpQuestion()).toBe("");
+ });
+
+ it("leaves an in-flight call valid when a later one returns early", async () => {
+ const heldQuestion = deferred();
+ vi.mocked(generateFollowUpQuestion).mockReturnValueOnce(
+ heldQuestion.promise,
+ );
+ // An empty answer makes the send's own follow-up call return at the
+ // `!currentResponse` guard, without ever reaching the request.
+ vi.mocked(generateChatResponse).mockResolvedValueOnce("");
+
+ renderChatInterface({ suppressInitialFollowUp: false });
+ await act(async () => {});
+
+ expect(getChatGenerationState().isGeneratingFollowUpQuestion).toBe(true);
+
+ await act(async () => {
+ await sendMessage("And how do I use it?");
+ });
+
+ // Only the held call ever asked for a question.
+ expect(generateFollowUpQuestion).toHaveBeenCalledTimes(1);
+
+ await act(async () => {
+ heldQuestion.resolve("The original question?");
+ });
+
+ // The early return bumped nothing, so the in-flight call is still the
+ // current one and clears the flag. Bumping before the guards would have
+ // orphaned it and left the flag, and the wake lock, held until unmount.
+ expect(getChatGenerationState().isGeneratingFollowUpQuestion).toBe(false);
+ });
+
+ it("blanks nothing when an orphaned call rejects after a newer one started", async () => {
+ const earlierQuestion = deferred();
+ const newerQuestion = deferred();
+ vi.mocked(generateFollowUpQuestion)
+ .mockReturnValueOnce(earlierQuestion.promise)
+ .mockReturnValueOnce(newerQuestion.promise);
+
+ renderChatInterface({ suppressInitialFollowUp: false });
+ await act(async () => {});
+
+ let send: Promise = Promise.resolve();
+ await act(async () => {
+ send = sendMessage("And how do I use it?");
+ });
+
+ // The orphaned call fails. Its catch must not blank the newer one's work.
+ await act(async () => {
+ earlierQuestion.reject(new Error("no model"));
+ });
+
+ expect(getChatGenerationState().isGeneratingFollowUpQuestion).toBe(true);
+
+ await act(async () => {
+ newerQuestion.resolve("The newest question?");
+ await send;
+ });
+
+ expect(getFollowUpQuestion()).toBe("The newest question?");
+ expect(getChatGenerationState().isGeneratingFollowUpQuestion).toBe(false);
+ });
+
+ it("starts no follow-up question for a send that settles after unmount", async () => {
+ const chatResponse = deferred();
+ vi.mocked(generateChatResponse).mockReturnValueOnce(chatResponse.promise);
+
+ const { unmount } = renderChatInterface();
+
+ let send: Promise = Promise.resolve();
+ await act(async () => {
+ send = sendMessage("And how do I use it?");
+ });
+
+ await act(async () => {
+ unmount();
+ });
+
+ // The send closure runs to the end regardless, and asks for a question the
+ // dead instance's token would have accepted.
+ await act(async () => {
+ chatResponse.resolve("An answer.");
+ await send;
+ });
+
+ expect(generateFollowUpQuestion).not.toHaveBeenCalled();
+ expect(getFollowUpQuestion()).toBe("");
+ expect(getChatGenerationState().isGeneratingFollowUpQuestion).toBe(false);
+ });
+
+ it("leaves the next mount's response flag alone when an orphaned send settles", async () => {
+ const firstResponse = deferred();
+ const secondResponse = deferred();
+ vi.mocked(generateChatResponse)
+ .mockReturnValueOnce(firstResponse.promise)
+ .mockReturnValueOnce(secondResponse.promise);
+
+ const first = renderChatInterface();
+
+ let firstSend: Promise = Promise.resolve();
+ await act(async () => {
+ firstSend = sendMessage("And how do I use it?");
+ });
+
+ await act(async () => {
+ first.unmount();
+ });
+
+ renderChatInterface();
+
+ let secondSend: Promise = Promise.resolve();
+ await act(async () => {
+ secondSend = sendMessage("Does it work offline?");
+ });
+
+ expect(getChatGenerationState().isGeneratingResponse).toBe(true);
+ // The live generation really started, rather than the flag being stale.
+ expect(generateChatResponse).toHaveBeenCalledTimes(2);
+
+ // The orphan's `finally` must not clear the live generation's flag, which
+ // would drop the spinner and let a third send start alongside it.
+ await act(async () => {
+ firstResponse.resolve("The orphaned answer.");
+ await firstSend;
+ });
+
+ expect(getChatGenerationState().isGeneratingResponse).toBe(true);
+
+ await act(async () => {
+ secondResponse.resolve("The live answer.");
+ await secondSend;
+ });
+
+ expect(getChatGenerationState().isGeneratingResponse).toBe(false);
+ });
+
+ it("leaves the next mount's response flag alone when an orphaned regenerate settles", async () => {
+ const firstResponse = deferred();
+ const secondResponse = deferred();
+ vi.mocked(generateChatResponse)
+ .mockResolvedValueOnce("An answer.")
+ .mockReturnValueOnce(firstResponse.promise)
+ .mockReturnValueOnce(secondResponse.promise);
+
+ const first = renderChatInterface();
+
+ await act(async () => {
+ await sendMessage("And how do I use it?");
+ });
+
+ let firstRegenerate: Promise = Promise.resolve();
+ await act(async () => {
+ firstRegenerate = regenerateResponse();
+ });
+
+ await act(async () => {
+ first.unmount();
+ });
+
+ renderChatInterface();
+
+ let secondSend: Promise = Promise.resolve();
+ await act(async () => {
+ secondSend = sendMessage("Does it work offline?");
+ });
+
+ expect(getChatGenerationState().isGeneratingResponse).toBe(true);
+ // The live generation really started, rather than the flag being stale.
+ expect(generateChatResponse).toHaveBeenCalledTimes(3);
+
+ await act(async () => {
+ firstResponse.resolve("The orphaned regeneration.");
+ await firstRegenerate;
+ });
+
+ expect(getChatGenerationState().isGeneratingResponse).toBe(true);
+
+ await act(async () => {
+ secondResponse.resolve("The live answer.");
+ await secondSend;
+ });
+
+ expect(getChatGenerationState().isGeneratingResponse).toBe(false);
+ });
+
+ it("starts one re-generation when two regenerates land in the same task", async () => {
+ renderChatInterface();
+
+ await act(async () => {
+ await sendMessage("And how do I use it?");
+ });
+
+ await act(async () => {
+ await Promise.all([regenerateResponse(), regenerateResponse()]);
+ });
+
+ expect(generateChatResponse).toHaveBeenCalledTimes(2);
+ });
+
+ it("keeps the response flag on when a follow-up question fails mid-response", async () => {
+ const earlierQuestion = deferred();
+ vi.mocked(generateFollowUpQuestion).mockReturnValueOnce(
+ earlierQuestion.promise,
+ );
+ const chatResponse = deferred();
+ vi.mocked(generateChatResponse).mockReturnValueOnce(chatResponse.promise);
+
+ renderChatInterface({ suppressInitialFollowUp: false });
+
+ await act(async () => {});
+
+ let send: Promise = Promise.resolve();
+
+ await act(async () => {
+ send = sendMessage("And how do I use it?");
+ });
+
+ await act(async () => {
+ earlierQuestion.reject(new Error("no model"));
+ });
+
+ expect(getChatGenerationState()).toEqual({
+ isGeneratingResponse: true,
+ isGeneratingFollowUpQuestion: false,
+ });
+
+ await act(async () => {
+ chatResponse.resolve("An answer.");
+ await send;
+ });
+ });
+
+ it("holds the screen wake lock from the response through the follow-up question", async () => {
+ const { request, release } = stubWakeLockApi();
+ const followUpQuestion = deferred();
+ vi.mocked(generateFollowUpQuestion).mockReturnValueOnce(
+ followUpQuestion.promise,
+ );
+
+ renderChatInterface();
+
+ let send: Promise = Promise.resolve();
+
+ await act(async () => {
+ send = sendMessage("And how do I use it?");
+ });
+
+ expect(request).toHaveBeenCalledExactlyOnceWith("screen");
+ expect(release).not.toHaveBeenCalled();
+
+ await act(async () => {
+ followUpQuestion.resolve("An earlier question?");
+ await send;
+ });
+
+ expect(release).toHaveBeenCalled();
+ });
+});
diff --git a/client/components/AiResponse/ChatInterface.tsx b/client/components/AiResponse/ChatInterface.tsx
new file mode 100644
index 0000000000000000000000000000000000000000..4d4e32d1669c6c35c2f6af4b44ae8beb5554de29
--- /dev/null
+++ b/client/components/AiResponse/ChatInterface.tsx
@@ -0,0 +1,430 @@
+import { Card, Stack } from "@mantine/core";
+import { usePubSub } from "create-pubsub/react";
+import {
+ type KeyboardEvent,
+ useCallback,
+ useEffect,
+ useRef,
+ useState,
+} from "react";
+import throttle from "throttleit";
+import { useScreenWakeLock } from "@/hooks/useScreenWakeLock";
+import { persistChatMessages, runFollowUpSearch } from "@/modules/chatHelpers";
+import { generateFollowUpQuestion } from "@/modules/followUpQuestions";
+import { handleEnterKeyDown } from "@/modules/keyboard";
+import { addLogEntry } from "@/modules/logEntries";
+import { showAiCompleteNotification } from "@/modules/notifications";
+import {
+ chatGenerationStatePubSub,
+ chatInputPubSub,
+ followUpQuestionPubSub,
+ getChatGenerationState,
+ imageSearchResultsPubSub,
+ queryPubSub,
+ settingsPubSub,
+ suppressNextFollowUpPubSub,
+ textSearchResultsPubSub,
+} from "@/modules/pubSub";
+import { generateChatResponse } from "@/modules/textGeneration";
+import type { ChatMessage } from "@/modules/types";
+import ChatHeader from "./ChatHeader";
+import ChatInputArea from "./ChatInputArea";
+import MessageList from "./MessageList";
+
+interface ChatInterfaceProps {
+ initialQuery?: string;
+ initialResponse?: string;
+ initialMessages?: ChatMessage[];
+ suppressInitialFollowUp?: boolean;
+}
+
+export default function ChatInterface({
+ initialQuery,
+ initialResponse,
+ initialMessages,
+ suppressInitialFollowUp,
+}: ChatInterfaceProps) {
+ const initialMessagesArray =
+ initialMessages &&
+ initialMessages.length > 0 &&
+ initialQuery &&
+ initialResponse
+ ? [
+ { role: "user" as const, content: initialQuery },
+ { role: "assistant" as const, content: initialResponse },
+ ...initialMessages,
+ ]
+ : initialMessages || [];
+
+ const [messages, setMessages] = useState(initialMessagesArray);
+ const [input, setInput] = usePubSub(chatInputPubSub);
+ const [generationState, setGenerationState] = usePubSub(
+ chatGenerationStatePubSub,
+ );
+ const [, setFollowUpQuestion] = usePubSub(followUpQuestionPubSub);
+ const [textSearchResults] = usePubSub(textSearchResultsPubSub);
+ const [imageSearchResults] = usePubSub(imageSearchResultsPubSub);
+ const [currentQuery] = usePubSub(queryPubSub);
+ const [suppressNextFollowUp] = usePubSub(suppressNextFollowUpPubSub);
+ const [previousFollowUpQuestions, setPreviousFollowUpQuestions] = useState<
+ string[]
+ >([]);
+ const [settings] = usePubSub(settingsPubSub);
+ const [streamedResponse, setStreamedResponse] = useState("");
+ const hasInitialized = useRef(false);
+ const prevInitialMessagesRef = useRef(undefined);
+ /**
+ * Identifies the newest `regenerateFollowUpQuestion` call. A boolean cannot
+ * represent two in flight, so a completion whose id is no longer current does
+ * nothing: otherwise whichever finished first would clear the flag while the
+ * other was still working, dropping the wake lock, and an orphaned call would
+ * write the previous answer's question into the input placeholder.
+ */
+ const followUpInvocationRef = useRef(0);
+ /**
+ * False once this instance has unmounted. The pubsub setters are module-level
+ * publishers, so an orphaned flow keeps writing into whatever is mounted now
+ * unless it checks first.
+ */
+ const isMountedRef = useRef(true);
+ const updateStreamedResponse = useCallback(
+ throttle((response: string) => {
+ setStreamedResponse(response);
+ }, 1000 / 12),
+ [],
+ );
+
+ useScreenWakeLock(
+ generationState.isGeneratingResponse ||
+ generationState.isGeneratingFollowUpQuestion,
+ );
+
+ const regenerateFollowUpQuestion = useCallback(
+ async (currentQuery: string, currentResponse: string) => {
+ // A send that settles after unmount still runs its closure to the end and
+ // calls this. Bumping the dead instance's token would not stop it: it
+ // would pass its own check and write into the live mount.
+ if (!isMountedRef.current) return;
+ if (suppressNextFollowUp) return;
+ if (!currentResponse || !currentQuery.trim()) return;
+
+ // After the guards, never before them. A call that returns early never
+ // set the flag, so invalidating the in-flight one would make its
+ // completion a no-op and leave the flag, and the wake lock, held until
+ // unmount.
+ const invocation = ++followUpInvocationRef.current;
+
+ try {
+ setGenerationState({
+ ...getChatGenerationState(),
+ isGeneratingFollowUpQuestion: true,
+ });
+
+ const newQuestion = await generateFollowUpQuestion({
+ topic: currentQuery,
+ currentContent: currentResponse,
+ previousQuestions: previousFollowUpQuestions,
+ });
+
+ // A newer call, or an unmount, took over while this one awaited.
+ if (invocation !== followUpInvocationRef.current) return;
+
+ setPreviousFollowUpQuestions((prev) =>
+ [...prev, newQuestion].slice(-5),
+ );
+ setFollowUpQuestion(newQuestion);
+ setGenerationState({
+ ...getChatGenerationState(),
+ isGeneratingFollowUpQuestion: false,
+ });
+ } catch (_) {
+ if (invocation !== followUpInvocationRef.current) return;
+ setFollowUpQuestion("");
+ setGenerationState({
+ ...getChatGenerationState(),
+ isGeneratingFollowUpQuestion: false,
+ });
+ }
+ },
+ [
+ setFollowUpQuestion,
+ setGenerationState,
+ previousFollowUpQuestions,
+ suppressNextFollowUp,
+ ],
+ );
+
+ useEffect(() => {
+ const messagesChanged =
+ !prevInitialMessagesRef.current ||
+ JSON.stringify(prevInitialMessagesRef.current) !==
+ JSON.stringify(initialMessages);
+
+ if (!messagesChanged) return;
+
+ prevInitialMessagesRef.current = initialMessages;
+
+ const newInitialMessagesArray =
+ initialMessages &&
+ initialMessages.length > 0 &&
+ initialQuery &&
+ initialResponse
+ ? [
+ { role: "user" as const, content: initialQuery },
+ { role: "assistant" as const, content: initialResponse },
+ ...initialMessages,
+ ]
+ : initialMessages || [];
+
+ if (newInitialMessagesArray.length > 0) {
+ setMessages(newInitialMessagesArray);
+ } else if (initialQuery && initialResponse) {
+ setMessages([
+ { role: "user", content: initialQuery },
+ { role: "assistant", content: initialResponse },
+ ]);
+ }
+ }, [initialQuery, initialResponse, initialMessages]);
+
+ useEffect(() => {
+ if (suppressNextFollowUp) {
+ hasInitialized.current = true;
+ return;
+ }
+ if (suppressInitialFollowUp) return;
+ if (hasInitialized.current) return;
+
+ if (initialMessages && initialMessages.length > 0) {
+ const lastAssistant = messages
+ .filter((m) => m.role === "assistant")
+ .pop();
+ const lastUser = messages.filter((m) => m.role === "user").pop();
+ if (lastUser && lastAssistant) {
+ regenerateFollowUpQuestion(lastUser.content, lastAssistant.content);
+ hasInitialized.current = true;
+ }
+ } else if (messages.length >= 2 && initialQuery && initialResponse) {
+ regenerateFollowUpQuestion(initialQuery, initialResponse);
+ hasInitialized.current = true;
+ }
+ }, [
+ initialQuery,
+ initialResponse,
+ initialMessages,
+ messages,
+ regenerateFollowUpQuestion,
+ suppressInitialFollowUp,
+ suppressNextFollowUp,
+ ]);
+
+ useEffect(() => {
+ // Re-armed rather than left to the initial value, so a future re-run of
+ // this effect cannot leave the instance marked dead. It does not make the
+ // component StrictMode-safe: there the cleanup's token bump would orphan
+ // the mount effect's call while `hasInitialized` stays true, and the first
+ // answer would get no follow-up question at all.
+ isMountedRef.current = true;
+
+ return () => {
+ // Invalidate any in-flight call so its completion cannot write into the
+ // next mount, then clear the generation flags the same way the question
+ // is cleared: an orphaned flow's `finally` would otherwise resurrect them
+ // there, and nothing else resets this channel on unmount.
+ isMountedRef.current = false;
+ followUpInvocationRef.current += 1;
+ setFollowUpQuestion("");
+ setPreviousFollowUpQuestions([]);
+ setGenerationState({
+ isGeneratingResponse: false,
+ isGeneratingFollowUpQuestion: false,
+ });
+ };
+ }, [setFollowUpQuestion, setGenerationState]);
+
+ const handleEditMessage = useCallback(
+ (absoluteIndex: number) => {
+ const target = messages[absoluteIndex];
+ if (target?.role !== "user") return;
+ setInput(target.content);
+ setMessages(messages.slice(0, absoluteIndex));
+ setFollowUpQuestion("");
+ },
+ [messages, setInput, setFollowUpQuestion],
+ );
+
+ const handleRegenerateResponse = useCallback(async () => {
+ if (
+ getChatGenerationState().isGeneratingResponse ||
+ messages.length < 3 ||
+ messages[messages.length - 1].role !== "assistant"
+ )
+ return;
+
+ const history = messages.slice(0, -1);
+ const lastUser = history[history.length - 1];
+
+ setMessages(history);
+ setGenerationState({
+ ...getChatGenerationState(),
+ isGeneratingResponse: true,
+ });
+ setFollowUpQuestion("");
+ setStreamedResponse("");
+
+ try {
+ const finalResponse = await generateChatResponse(
+ history,
+ updateStreamedResponse,
+ );
+
+ setMessages((prev) => [
+ ...prev,
+ { role: "assistant", content: finalResponse },
+ ]);
+
+ addLogEntry("AI response re-generated");
+
+ if (lastUser?.role === "user") {
+ if (settings.enableNotificationOnAiComplete) {
+ showAiCompleteNotification(lastUser.content);
+ }
+ // Not awaited: the follow-up question raises its own flag
+ // synchronously, so the `finally` below can hand the wake lock over
+ // and release the response flag while that question is still coming.
+ regenerateFollowUpQuestion(lastUser.content, finalResponse);
+ }
+ } catch (error) {
+ addLogEntry(`Error re-generating response: ${error}`);
+ } finally {
+ if (isMountedRef.current) {
+ setGenerationState({
+ ...getChatGenerationState(),
+ isGeneratingResponse: false,
+ });
+ }
+ }
+ }, [
+ messages,
+ regenerateFollowUpQuestion,
+ settings,
+ setFollowUpQuestion,
+ setGenerationState,
+ updateStreamedResponse,
+ ]);
+
+ const handleSend = useCallback(
+ async (textToSend?: string) => {
+ const currentInput = textToSend ?? input;
+ if (
+ currentInput.trim() === "" ||
+ getChatGenerationState().isGeneratingResponse
+ ) {
+ return;
+ }
+
+ const userMessage: ChatMessage = { role: "user", content: currentInput };
+ const newMessages: ChatMessage[] = [...messages, userMessage];
+
+ setMessages(newMessages);
+ if (!textToSend) setInput("");
+ setGenerationState({
+ ...getChatGenerationState(),
+ isGeneratingResponse: true,
+ });
+ setFollowUpQuestion("");
+ setStreamedResponse("");
+
+ try {
+ await runFollowUpSearch(
+ newMessages,
+ currentInput,
+ settings,
+ textSearchResults,
+ imageSearchResults,
+ );
+ } catch (error) {
+ addLogEntry(`Error in follow-up search: ${error}`);
+ }
+
+ try {
+ const finalResponse = await generateChatResponse(
+ newMessages,
+ updateStreamedResponse,
+ );
+
+ setMessages((prevMessages) => [
+ ...prevMessages,
+ { role: "assistant", content: finalResponse },
+ ]);
+
+ addLogEntry("AI response completed");
+
+ if (settings.enableNotificationOnAiComplete) {
+ showAiCompleteNotification(currentInput);
+ }
+
+ await persistChatMessages(currentQuery, currentInput, finalResponse);
+
+ regenerateFollowUpQuestion(currentInput, finalResponse);
+ } catch (error) {
+ addLogEntry(`Error in chat response: ${error}`);
+ setMessages((prevMessages) => [
+ ...prevMessages,
+ {
+ role: "assistant",
+ content:
+ "Sorry, I encountered an error while generating a response.",
+ },
+ ]);
+ } finally {
+ if (isMountedRef.current) {
+ setGenerationState({
+ ...getChatGenerationState(),
+ isGeneratingResponse: false,
+ });
+ }
+ }
+ },
+ [
+ messages,
+ settings,
+ input,
+ regenerateFollowUpQuestion,
+ setFollowUpQuestion,
+ setGenerationState,
+ setInput,
+ updateStreamedResponse,
+ currentQuery,
+ textSearchResults,
+ imageSearchResults,
+ ],
+ );
+
+ const handleKeyDown = useCallback(
+ (event: KeyboardEvent) => {
+ handleEnterKeyDown(event, settings, handleSend);
+ },
+ [settings, handleSend],
+ );
+
+ return (
+
+
+
+
+
+
+
+
+
+ );
+}
diff --git a/client/components/AiResponse/CopyIconButton.tsx b/client/components/AiResponse/CopyIconButton.tsx
new file mode 100644
index 0000000000000000000000000000000000000000..af8d82dfe54056adf9761d7c2d74d7fae37b348b
--- /dev/null
+++ b/client/components/AiResponse/CopyIconButton.tsx
@@ -0,0 +1,32 @@
+import { ActionIcon, CopyButton, Tooltip } from "@mantine/core";
+import { IconCheck, IconCopy } from "@tabler/icons-react";
+
+interface CopyIconButtonProps {
+ value: string;
+ tooltipLabel?: string;
+}
+
+export default function CopyIconButton({
+ value,
+ tooltipLabel = "Copy",
+}: CopyIconButtonProps) {
+ return (
+
+ {({ copied, copy }) => (
+
+
+ {copied ? : }
+
+
+ )}
+
+ );
+}
diff --git a/client/components/AiResponse/EnableAiResponsePrompt.test.tsx b/client/components/AiResponse/EnableAiResponsePrompt.test.tsx
new file mode 100644
index 0000000000000000000000000000000000000000..bb2a94853ed5add0a17bbc125c46a315999e44e8
--- /dev/null
+++ b/client/components/AiResponse/EnableAiResponsePrompt.test.tsx
@@ -0,0 +1,32 @@
+import { MantineProvider } from "@mantine/core";
+import { render, screen } from "@testing-library/react";
+import { describe, expect, it } from "vitest";
+import EnableAiResponsePrompt from "./EnableAiResponsePrompt";
+
+describe("EnableAiResponsePrompt", () => {
+ it("is announced politely (status), not assertively (alert)", () => {
+ render(
+
+ {}} onDecline={() => {}} />
+ ,
+ );
+
+ expect(screen.getByRole("status")).toBeInTheDocument();
+ expect(screen.queryByRole("alert")).not.toBeInTheDocument();
+ });
+
+ it("offers accept and decline", () => {
+ render(
+
+ {}} onDecline={() => {}} />
+ ,
+ );
+
+ expect(
+ screen.getByRole("button", { name: "Yes, please" }),
+ ).toBeInTheDocument();
+ expect(
+ screen.getByRole("button", { name: "No, thanks" }),
+ ).toBeInTheDocument();
+ });
+});
diff --git a/client/components/AiResponse/EnableAiResponsePrompt.tsx b/client/components/AiResponse/EnableAiResponsePrompt.tsx
new file mode 100644
index 0000000000000000000000000000000000000000..2828a3b2b6428351a880e1defec3b1eb8d0eafb3
--- /dev/null
+++ b/client/components/AiResponse/EnableAiResponsePrompt.tsx
@@ -0,0 +1,85 @@
+import {
+ ActionIcon,
+ Alert,
+ Button,
+ Grid,
+ Group,
+ Popover,
+ Stack,
+ Text,
+} from "@mantine/core";
+import { IconCheck, IconInfoCircle, IconX } from "@tabler/icons-react";
+
+interface EnableAiResponsePromptProps {
+ onAccept: () => void;
+ onDecline: () => void;
+}
+
+export default function EnableAiResponsePrompt({
+ onAccept,
+ onDecline,
+}: EnableAiResponsePromptProps) {
+ const helpContent = (
+
+
+ MiniSearch is a web-searching app with an integrated AI assistant.
+
+
+ With AI Responses enabled, it will generate summaries and answer
+ questions based on search results.
+
+
+ If disabled, it will function as a classic web search tool.
+
+
+ You can toggle this feature at anytime through the Menu.
+
+
+ );
+
+ return (
+
+
+
+
+ Enable AI Responses?
+
+
+
+
+
+
+ {helpContent}
+
+
+
+
+
+ }
+ onClick={onDecline}
+ size="xs"
+ >
+ No, thanks
+
+ }
+ onClick={onAccept}
+ size="xs"
+ >
+ Yes, please
+
+
+
+
+
+ );
+}
diff --git a/client/components/AiResponse/ExpandableLink.tsx b/client/components/AiResponse/ExpandableLink.tsx
new file mode 100644
index 0000000000000000000000000000000000000000..187b87fbd284f6c7e0cb21466d213cffe6fcac5a
--- /dev/null
+++ b/client/components/AiResponse/ExpandableLink.tsx
@@ -0,0 +1,123 @@
+import type { MantineTheme } from "@mantine/core";
+import { Button } from "@mantine/core";
+import React from "react";
+
+interface ExpandableLinkProps {
+ href: string;
+ children: React.ReactNode;
+}
+
+export default function ExpandableLink({
+ href,
+ children,
+}: ExpandableLinkProps) {
+ const childContent = children?.toString() || "";
+ const firstChar = childContent.charAt(0);
+ const [isExpanded, setIsExpanded] = React.useState(true);
+ const timerRef = React.useRef(null);
+
+ React.useEffect(() => {
+ timerRef.current = window.setTimeout(() => {
+ setIsExpanded(false);
+ timerRef.current = null;
+ }, 3000);
+
+ return () => {
+ if (timerRef.current) {
+ clearTimeout(timerRef.current);
+ }
+ };
+ }, []);
+
+ const handleMouseEnter = () => {
+ if (timerRef.current) {
+ clearTimeout(timerRef.current);
+ timerRef.current = null;
+ }
+ setIsExpanded(true);
+ };
+
+ const handleMouseLeave = () => {
+ timerRef.current = window.setTimeout(() => {
+ setIsExpanded(false);
+ timerRef.current = null;
+ }, 3000);
+ };
+
+ const fullTextRef = React.useRef(null);
+ const [fullTextWidth, setFullTextWidth] = React.useState(0);
+
+ React.useEffect(() => {
+ const measureText = () => {
+ if (fullTextRef.current) {
+ setFullTextWidth(fullTextRef.current.scrollWidth);
+ }
+ };
+
+ measureText();
+
+ window.addEventListener("resize", measureText);
+ return () => {
+ window.removeEventListener("resize", measureText);
+ };
+ }, []);
+
+ return (
+
+ );
+}
diff --git a/client/components/AiResponse/FormattedMarkdown.tsx b/client/components/AiResponse/FormattedMarkdown.tsx
new file mode 100644
index 0000000000000000000000000000000000000000..7a0455f4721dfae21e6c1fc0df0164c8715286c2
--- /dev/null
+++ b/client/components/AiResponse/FormattedMarkdown.tsx
@@ -0,0 +1,41 @@
+import { Typography } from "@mantine/core";
+import { useReasoningContent } from "./hooks/useReasoningContent";
+import MarkdownRenderer from "./MarkdownRenderer";
+import ReasoningSection from "./ReasoningSection";
+
+interface FormattedMarkdownProps {
+ children: string;
+ className?: string;
+ enableCopy?: boolean;
+}
+
+export default function FormattedMarkdown({
+ children,
+ className = "",
+ enableCopy = true,
+}: FormattedMarkdownProps) {
+ const { reasoningContent, mainContent, isGenerating } =
+ useReasoningContent(children);
+
+ if (!children && !reasoningContent) {
+ return null;
+ }
+
+ return (
+
+ {reasoningContent && (
+
+ )}
+ {mainContent && (
+
+ )}
+
+ );
+}
diff --git a/client/components/AiResponse/LoadingModelContent.test.tsx b/client/components/AiResponse/LoadingModelContent.test.tsx
new file mode 100644
index 0000000000000000000000000000000000000000..c935dac6842e3d777fb55a46a2f7c1930b42ba79
--- /dev/null
+++ b/client/components/AiResponse/LoadingModelContent.test.tsx
@@ -0,0 +1,31 @@
+import { MantineProvider } from "@mantine/core";
+import { render, screen } from "@testing-library/react";
+import { describe, expect, it } from "vitest";
+import LoadingModelContent from "./LoadingModelContent";
+
+function renderContent(props: {
+ modelLoadingProgress: number;
+ modelSizeInMegabytes: number;
+}) {
+ return render(
+
+
+ ,
+ );
+}
+
+describe("LoadingModelContent", () => {
+ it("omits the size while it is still unknown, keeping the percentage", () => {
+ renderContent({ modelLoadingProgress: 70, modelSizeInMegabytes: 0 });
+
+ expect(screen.queryByText(/MB/)).not.toBeInTheDocument();
+ expect(screen.getByText("70.0%")).toBeInTheDocument();
+ });
+
+ it("shows how much of the model was downloaded once the size is known", () => {
+ renderContent({ modelLoadingProgress: 70, modelSizeInMegabytes: 250 });
+
+ expect(screen.getByText("175 MB / 250 MB")).toBeInTheDocument();
+ expect(screen.getByText("70.0%")).toBeInTheDocument();
+ });
+});
diff --git a/client/components/AiResponse/LoadingModelContent.tsx b/client/components/AiResponse/LoadingModelContent.tsx
new file mode 100644
index 0000000000000000000000000000000000000000..8a11bafc3b1515ee666242c50bd10496be9c5bf1
--- /dev/null
+++ b/client/components/AiResponse/LoadingModelContent.tsx
@@ -0,0 +1,43 @@
+import { Card, Group, Progress, Stack, Text } from "@mantine/core";
+
+export default function LoadingModelContent({
+ modelLoadingProgress,
+ modelSizeInMegabytes,
+}: {
+ modelLoadingProgress: number;
+ modelSizeInMegabytes: number;
+}) {
+ const isLoadingStarting = modelLoadingProgress === 0;
+ const isLoadingComplete = modelLoadingProgress === 100;
+ const percent =
+ isLoadingComplete || isLoadingStarting ? 100 : modelLoadingProgress;
+ const strokeColor = percent === 100 ? "#52c41a" : "#3385ff";
+ const isModelSizeKnown = modelSizeInMegabytes > 0;
+ const downloadedSize = (modelSizeInMegabytes * modelLoadingProgress) / 100;
+ const sizeText = `${downloadedSize.toFixed(0)} MB / ${modelSizeInMegabytes.toFixed(0)} MB`;
+
+ return (
+
+
+ Loading AI...
+
+
+
+
+ {!isLoadingStarting && (
+
+ {isModelSizeKnown && (
+
+ {sizeText}
+
+ )}
+
+ {percent.toFixed(1)}%
+
+
+ )}
+
+
+
+ );
+}
diff --git a/client/components/AiResponse/MarkdownRenderer.tsx b/client/components/AiResponse/MarkdownRenderer.tsx
new file mode 100644
index 0000000000000000000000000000000000000000..b0ec794c66ce188ac28a8c019aa37ac7231e5871
--- /dev/null
+++ b/client/components/AiResponse/MarkdownRenderer.tsx
@@ -0,0 +1,104 @@
+import { CodeHighlight } from "@mantine/code-highlight";
+import { Blockquote, Box, Code, Divider, Text } from "@mantine/core";
+import React from "react";
+import { ErrorBoundary } from "react-error-boundary";
+import Markdown from "react-markdown";
+import rehypeExternalLinks from "rehype-external-links";
+import remarkGfm from "remark-gfm";
+import ExpandableLink from "./ExpandableLink";
+
+interface MarkdownRendererProps {
+ content: string;
+ enableCopy?: boolean;
+ className?: string;
+}
+
+export default function MarkdownRenderer({
+ content,
+ enableCopy = true,
+ className = "",
+}: MarkdownRendererProps) {
+ if (!content) {
+ return null;
+ }
+
+ const unwrapParagraphs = (children: React.ReactNode) => {
+ return React.Children.map(children, (child) => {
+ if (React.isValidElement(child) && child.type === "p") {
+ return (child.props as { children: React.ReactNode }).children;
+ }
+ return child;
+ });
+ };
+
+ return (
+
+ {children}
+ );
+ },
+ li(props) {
+ const { children } = props;
+ return