
File size: 6,485 Bytes
f38408b 9d347fe f38408b 9d347fe 77dd57b 96574b3 77dd57b 2dca1ac 77dd57b 855a1f1 77dd57b 96574b3 21c1a3e 96574b3 21c1a3e 96574b3 2ff38a6 2dca1ac 2ff38a6 2dca1ac 2ff38a6 96574b3 2dca1ac 96574b3 2ff38a6 96574b3 | 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 107 108 109 110 111 112 113 114 115 116 117 118 119 120 121 122 123 124 125 126 127 128 129 130 131 132 133 134 135 136 | ---
license: mit
datasets:
- teapotai/synthqa
- teapotai/teapot-chat
language:
- en
base_model:
- google/flan-t5-small
---
⠀⠀⠀⠀⠀⠀⠀⠀⠀⠀⠀⠀⠀⠀⠀⠀⠀⠀⠀⠀⠀
# TinyTeapot 🫖
[Website](https://teapotai.com/) | [Try out our Demo](https://teapotai-tinyteapotchat.hf.space/) | [Join the discussion on Discord](https://discord.gg/xW5TjRnY)
TinyTeapot is a lightweight (~77M parameter) grounded language model optimized for low-latency, hallucination-resistant question answering and RAG workflows. Building on our prior work, [TeapotLLM](https://huggingface.co/teapotai/teapotllm), TinyTeapot delivers strong context-faithful performance while being ~10× faster on CPU, making it ideal for real-time, on-device, and cost-efficient deployments across CPUs, mobile devices, and other resource-constrained environments.
TinyTeapot is distilled from our previous model, [TeapotLLM](https://huggingface.co/teapotai/teapotllm), and trained on grounded datasets including [SynthQA](https://huggingface.co/datasets/teapotai/synthqa), a context-focused QnA and extraction benchmark, and [TeapotChat](https://huggingface.co/datasets/teapotai/teapotchat) for instruction-following and grounded dialogue. This distillation transfers TeapotLLM’s refusal behavior, structured extraction patterns, and context-only answering into a significantly smaller, edge-efficient model.
### Hallucination Resistance
Through distillation from TeapotLLM and training on SynthQA, TinyTeapot learns to refuse questions when the answer is not present in the context, improving reliability compared to similarly sized models in RAG and document QA pipelines.
---
## Training & Evaluation
### 🚀 ~10x Faster CPU Inference than TeapotLLM with Strong Grounded Performance
TinyTeapot is evaluated primarily against its teacher model (TeapotLLM) on SynthQA-style grounded tasks, with additional comparisons to larger instruction-tuned models such as LLaMA and Qwen to contextualize efficiency vs quality tradeoffs.
### Task Performance vs TeapotLLM
The chart below shows task-level similarity across boolean reasoning, QA, extraction, summarization, and unanswerable queries. While smaller (~77M vs ~800M+), TinyTeapot retains strong grounded behavior due to distillation from TeapotLLM and training on SynthQA and TeapotChat.
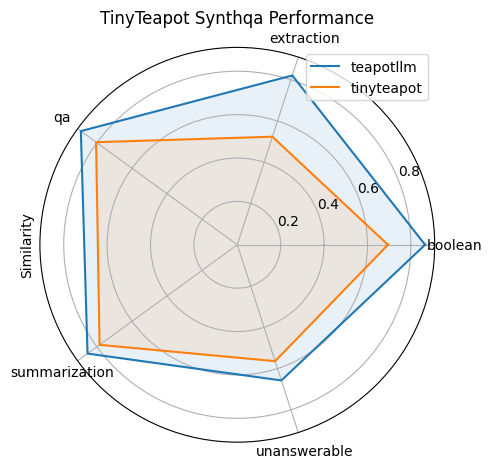
- TeapotLLM remains the strongest overall teacher model
- TinyTeapot maintains high QA and summarization similarity for its size
- Strong refusal performance on unanswerable questions due to grounded training
- Significant efficiency gains with minimal degradation on core grounded tasks
### Latency vs Answer Similarity (CPU & Accelerator)
TinyTeapot is designed for real-time and edge deployments where latency is critical. Benchmarks on Google Colab (100 runs) show that TinyTeapot delivers competitive grounded similarity while being dramatically faster than larger models.
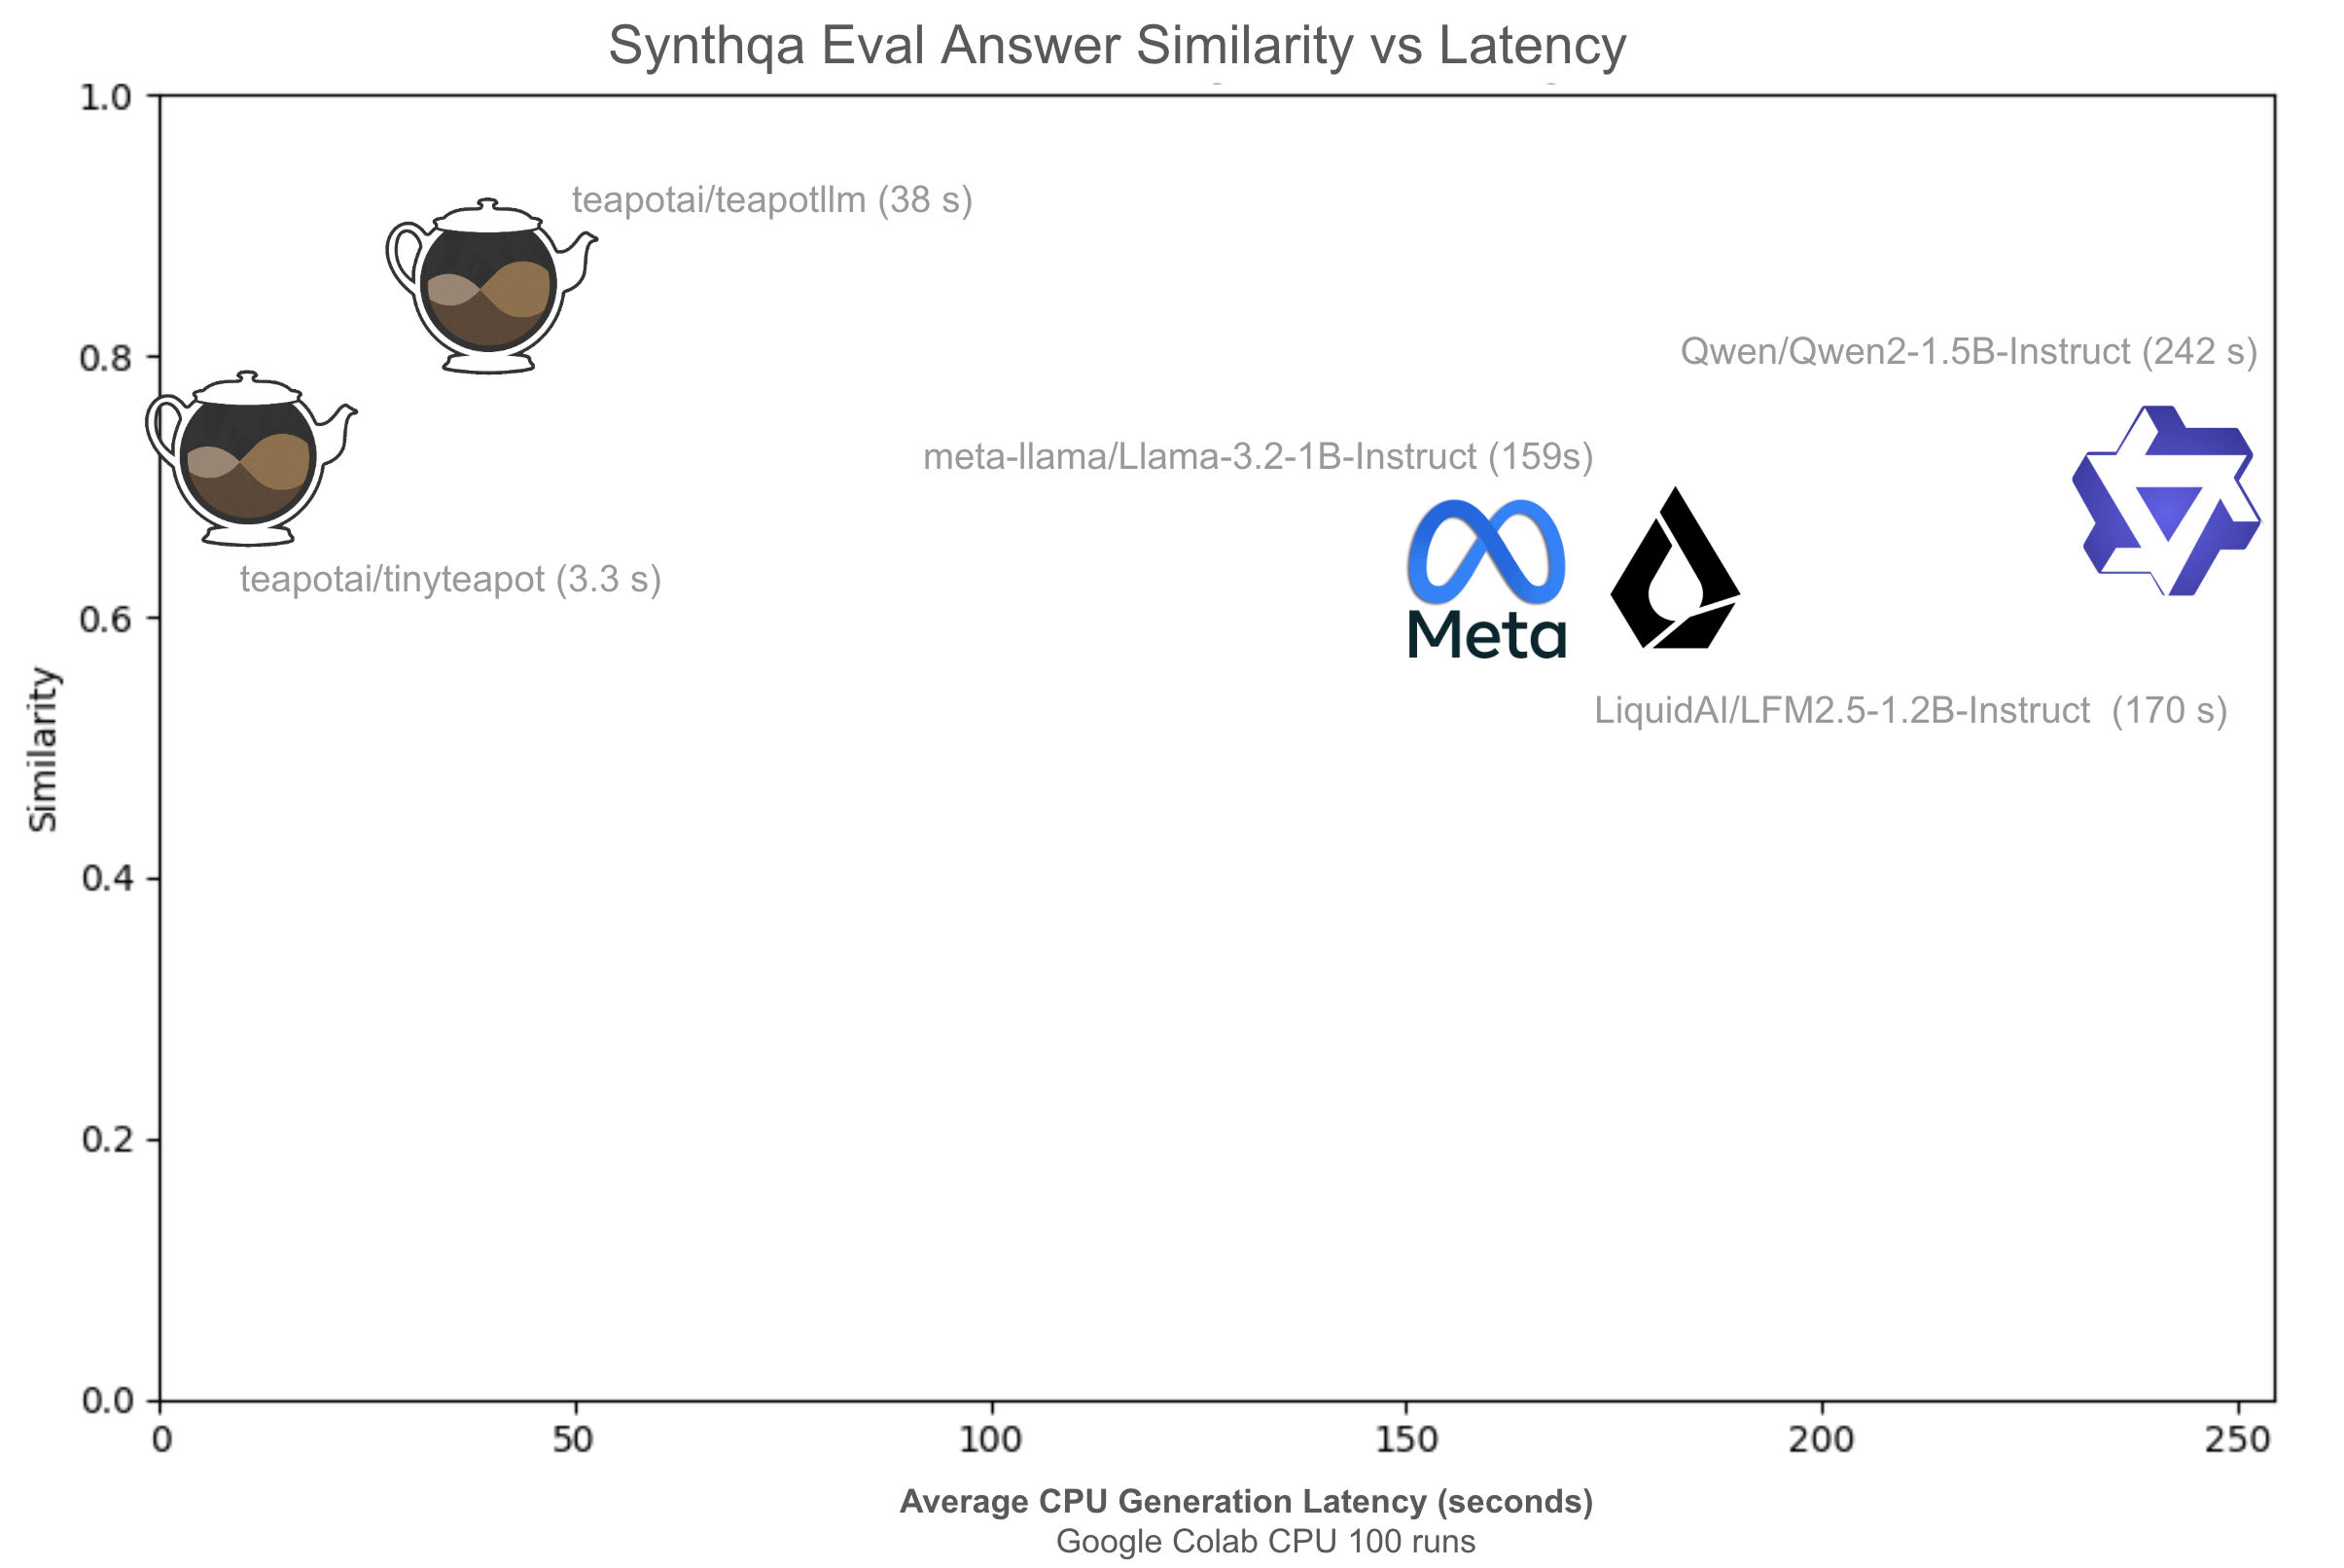
Key observations:
- 3.3s Average CPU latency for TinyTeapot vs 38s for TeapotLLM (~10x faster)
- Competitive similarity despite 10x smaller parameter count
- Significantly faster and more accurate than other SOTA ~1b parameter models in CPU-constrained settings
- Sub-second accelerator latency while maintaining grounded response quality
These results position TinyTeapot as a high-efficiency distilled model that preserves TeapotLLM’s grounded reasoning while enabling low-cost, low-latency deployment.
---
## Getting Started
TinyTeapot can be used directly with Hugging Face Transformers or with our python library [teapotai](https://pypi.org/project/teapotai) and follows a text-to-text format. It performs best when given explicit grounding context and the pre-trained system prompt.
```python
from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
MODEL_NAME = "teapotai/tinyteapot"
# Load tokenizer and model
tokenizer = AutoTokenizer.from_pretrained(MODEL_NAME)
model = AutoModelForSeq2SeqLM.from_pretrained(MODEL_NAME)
# Context
context = (
"The Eiffel Tower is a wrought iron lattice tower in Paris, France. "
"It was designed by Gustave Eiffel and completed in 1889. "
"It stands at a height of 330 meters and is one of the most recognizable "
"structures in the world."
)
# System prompt
system_prompt = (
"You are Teapot, an open-source AI assistant optimized for low-end devices, "
"providing short, accurate responses without hallucinating while excelling at "
"information extraction and text summarization. "
"If the context does not answer the question, reply exactly: "
"'I am sorry but I don't have any information on that'."
)
def ask(question: str):
prompt = f"{context}\n{system_prompt}\n{question}\n"
inputs = tokenizer(prompt, return_tensors="pt")
outputs = model.generate(
**inputs,
do_sample=False
)
answer = tokenizer.decode(outputs[0], skip_special_tokens=True)
print(f"{question}")
print(f"{answer}\n")
# Test 1: Grounded question (should use context)
ask("How tall is the Eiffel Tower") # => 330 meters
# Test 2: Out-of-context question (tests hallucination resistance)
ask("How tall is the Death Star") # => Sorry, I don't have any information on the Death Star.
```
---
## Recommended Use Cases
- Retrieval-Augmented Generation (RAG)
- Document question answering
- Information extraction
- On-device assistants
- Mobile and edge inference
- Low-latency production pipelines
TinyTeapot performs best when paired with retrieval or structured
context inputs rather than open-ended chat.
------------------------------------------------------------------------
### Limitations and Risks
TinyTeapot is optimized for grounded QnA, RAG, and extraction. It is not intended for open-ended chat, creative writing, or deep multi-step reasoning. Due to its small size (~77M parameters), performance is highly dependent on the quality and relevance of the provided context and may be more prone to hallucinations.
## Questions, Feature Requests?
We hope you find TinyTeapot useful and are continuously improving the TeapotAI ecosystem. Please reach out on our [Discord](https://discord.gg/teapotai) for technical help, feedback, or feature requests. We look forward to seeing what the community builds!
## License
MIT License
⠀ |