


Add README_zh
Browse files- README_zh_CN.md +565 -0
README_zh_CN.md
ADDED
|
@@ -0,0 +1,565 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
[English Documentation](./README.md)
|
| 2 |
+
|
| 3 |
+
<div align="center">
|
| 4 |
+
|
| 5 |
+
<img src="./assets/logo.png" alt="HunyuanImage-3.0 Logo" width="600">
|
| 6 |
+
|
| 7 |
+
# 🎨 HunyuanImage-3.0: 强大的原生多模态图像生成模型
|
| 8 |
+
|
| 9 |
+
</div>
|
| 10 |
+
|
| 11 |
+
|
| 12 |
+
<div align="center">
|
| 13 |
+
<img src="./assets/banner.png" alt="HunyuanImage-3.0 Banner" width="800">
|
| 14 |
+
|
| 15 |
+
</div>
|
| 16 |
+
|
| 17 |
+
<div align="center">
|
| 18 |
+
<a href=https://hunyuan.tencent.com/image target="_blank"><img src=https://img.shields.io/badge/Official%20Site-333399.svg?logo=homepage height=22px></a>
|
| 19 |
+
<a href=https://huggingface.co/tencent/HunyuanImage-3.0 target="_blank"><img src=https://img.shields.io/badge/%F0%9F%A4%97%20Models-d96902.svg height=22px></a>
|
| 20 |
+
<a href=https://github.com/Tencent-Hunyuan/HunyuanImage-3.0 target="_blank"><img src= https://img.shields.io/badge/Page-bb8a2e.svg?logo=github height=22px></a>
|
| 21 |
+
<a href=https://arxiv.org/pdf/2509.23951 target="_blank"><img src=https://img.shields.io/badge/Report-b5212f.svg?logo=arxiv height=22px></a>
|
| 22 |
+
<a href=https://x.com/TencentHunyuan target="_blank"><img src=https://img.shields.io/badge/Hunyuan-black.svg?logo=x height=22px></a>
|
| 23 |
+
<a href=https://docs.qq.com/doc/DUVVadmhCdG9qRXBU target="_blank"><img src=https://img.shields.io/badge/📚-提示词手册-blue.svg?logo=book height=22px></a>
|
| 24 |
+
</div>
|
| 25 |
+
|
| 26 |
+
|
| 27 |
+
<p align="center">
|
| 28 |
+
👏 加入我们的 <a href="./assets/WECHAT.md" target="_blank">微信</a> 和 <a href="https://discord.gg/ehjWMqF5wY">Discord</a> |
|
| 29 |
+
💻 <a href="https://hunyuan.tencent.com/modelSquare/home/play?modelId=289&from=/visual">官网试用我们的模型!</a>  
|
| 30 |
+
</p>
|
| 31 |
+
|
| 32 |
+
## 🔥🔥🔥 最新消息
|
| 33 |
+
|
| 34 |
+
- **2026年1月26日**: 🚀 **[HunyuanImage-3.0-Instruct-Distil](https://huggingface.co/tencent/HunyuanImage-3.0-Instruct-Distil)** - 蒸馏版本用于高效部署(推荐8步采样)。
|
| 35 |
+
- **2026年1月26日**: 🎉 **[HunyuanImage-3.0-Instruct](https://huggingface.co/tencent/HunyuanImage-3.0-Instruct)** - 发布了 **Instruct(带推理能力)**版本,支持智能提示词增强和**图像到图像**生成用于创意编辑。
|
| 36 |
+
- **2025年10月30日**: 🚀 **[HunyuanImage-3.0 vLLM 加速](./vllm_infer/README.md)** - 通过 vLLM 支持实现显著更快的推理速度。
|
| 37 |
+
- **2025年09月28日**: 📖 **[HunyuanImage-3.0 技术报告](https://arxiv.org/pdf/2509.23951)** - 全面的技术文档现已发布。
|
| 38 |
+
- **2025年09月28日**: 🎉 **[HunyuanImage-3.0 开源](https://github.com/Tencent-Hunyuan/HunyuanImage-3.0)** - 推理代码和模型权重现已公开可用。
|
| 39 |
+
|
| 40 |
+
|
| 41 |
+
## 🧩 社区贡献
|
| 42 |
+
|
| 43 |
+
如果您在项目中使用或开发了 HunyuanImage-3.0,欢迎告知我们。
|
| 44 |
+
|
| 45 |
+
## 📑 开源计划
|
| 46 |
+
|
| 47 |
+
- HunyuanImage-3.0 (图像生成模型)
|
| 48 |
+
- [x] 推理代码
|
| 49 |
+
- [x] HunyuanImage-3.0 模型权重
|
| 50 |
+
- [x] HunyuanImage-3.0-Instruct 模型权重(带推理能力)
|
| 51 |
+
- [x] vLLM 支持
|
| 52 |
+
- [x] 蒸馏版本权重
|
| 53 |
+
- [x] 图像到图像生成
|
| 54 |
+
- [ ] 多轮交互能力
|
| 55 |
+
|
| 56 |
+
|
| 57 |
+
## 🗂️ 目录
|
| 58 |
+
- [🔥🔥🔥 最新消息](#-最新消息)
|
| 59 |
+
- [🧩 社区贡献](#-社区贡献)
|
| 60 |
+
- [📑 开源计划](#-开源计划)
|
| 61 |
+
- [📖 概览](#-概览)
|
| 62 |
+
- [✨ 模型亮点](#-模型亮点)
|
| 63 |
+
- [🚀 使用方法](#-使用方法)
|
| 64 |
+
- [📦 环境配置](#-环境配置)
|
| 65 |
+
- [📥 安装依赖](#-安装依赖)
|
| 66 |
+
- [HunyuanImage-3.0-Instruct](#hunyuanimage-30-instruct-指令推理和图像到图像生成包括编辑和多图像融合)
|
| 67 |
+
- [🔥 使用 Transformers 快速开始](#-使用-transformers-快速开始)
|
| 68 |
+
- [1️⃣ 下载模型权重](#1-下载模型权重)
|
| 69 |
+
- [2️⃣ 使用 Transformers 运行](#2-使用-transformers-运行)
|
| 70 |
+
- [🏠 本地安装和使用](#-本地安装和使用)
|
| 71 |
+
- [1️⃣ 克隆仓库](#1-克隆仓库)
|
| 72 |
+
- [2️⃣ 下载模型权重](#2-下载模型权重)
|
| 73 |
+
- [3️⃣ 运行演示](#3-运行演示)
|
| 74 |
+
- [4️⃣ 命令行参数](#4-命令行参数)
|
| 75 |
+
- [5️⃣ 更少的采样步数](#5-更少的采样步数)
|
| 76 |
+
- [HunyuanImage-3.0 (文本生成图像)](#hunyuanimage-30-文本生成图像)
|
| 77 |
+
- [📥 安装依赖](#-安装依赖-1)
|
| 78 |
+
- [🔥 使用 Transformers 快速开始](#-使用-transformers-快速开始-1)
|
| 79 |
+
- [1️⃣ 下载模型权重](#1-下载模型权重-1)
|
| 80 |
+
- [2️⃣ 使用 Transformers 运行](#2-使用-transformers-运行-1)
|
| 81 |
+
- [🏠 本地安装和使用](#-本地安装和使用-1)
|
| 82 |
+
- [1️⃣ 克隆仓库](#1-克隆仓库-1)
|
| 83 |
+
- [2️⃣ 下载模型权重](#2-下载模型权重-1)
|
| 84 |
+
- [3️⃣ 运行演示](#3-运行演示-1)
|
| 85 |
+
- [4️⃣ 命令行参数](#4-命令行参数-1)
|
| 86 |
+
- [🎨 交互式 Gradio 演示](#-交互式-gradio-演示)
|
| 87 |
+
- [1️⃣ 安装 Gradio](#1-安装-gradio)
|
| 88 |
+
- [2️⃣ 配置环境](#2-配置环境)
|
| 89 |
+
- [3️⃣ 启动 Web 界面](#3-启动-web-界面)
|
| 90 |
+
- [4️⃣ 访问界面](#4-访问界面)
|
| 91 |
+
- [🧱 模型卡片](#-模型卡片)
|
| 92 |
+
- [📊 评估结果](#-评估结果)
|
| 93 |
+
- [HunyuanImage-3.0-Instruct 评估](#hunyuanimage-30-instruct-评估)
|
| 94 |
+
- [HunyuanImage-3.0 评估](#hunyuanimage-30-评估)
|
| 95 |
+
- [🖼️ 展示](#-展示)
|
| 96 |
+
- [HunyuanImage-3.0-Instruct 展示](#hunyuanimage-30-instruct-展示)
|
| 97 |
+
- [📚 引用](#-引用)
|
| 98 |
+
- [🙏 致谢](#-致谢)
|
| 99 |
+
- [🌟🚀 GitHub Star 历史](#-github-star-历史)
|
| 100 |
+
|
| 101 |
+
---
|
| 102 |
+
|
| 103 |
+
## 📖 概览
|
| 104 |
+
|
| 105 |
+
**HunyuanImage-3.0** 是一个突破性的原生多模态模型,它在自回归框架内统一了多模态理解和生成任务。它的文生图和图生图能力实现了与领先的闭源模型**相当或更优**的性能。
|
| 106 |
+
|
| 107 |
+
|
| 108 |
+
<div align="center">
|
| 109 |
+
<img src="./assets/framework.png" alt="HunyuanImage-3.0 Framework" width="90%">
|
| 110 |
+
</div>
|
| 111 |
+
|
| 112 |
+
## ✨ 模型亮点
|
| 113 |
+
|
| 114 |
+
* 🧠 **统一的多模态架构:** HunyuanImage-3.0 突破当前主流的 DiT 架构,采用统一的自回归框架。该设计能更直接、统一地对文本与图像模态进行建模,实现了语义理解与图像生成的高度融合,从而生成效果惊人、语境丰富的图像。
|
| 115 |
+
|
| 116 |
+
* 🏆 **最大规模图像生成MoE模型:** 作为当前开源社区参数规模最大的图像生成 MoE 模型,其拥有64个专家、总参数量达 800 亿,单 token 激活 130 亿参数,显著提升了模型容量与性能表现。
|
| 117 |
+
|
| 118 |
+
* 🎨 **卓越的图像生成质量:** 通过精细的数据集构建与强化学习后训练,我们在语义准确性与视觉表现力间取得最佳平衡。该模型不仅能精准遵循提示词要求,更可生成细节丰富、具有摄影级真实感与艺术美感的图像。
|
| 119 |
+
|
| 120 |
+
* 💭 **智能图像理解与世界知识推理:** 得益于统一的多模态架构,HunyuanImage-3.0 拥有强大的推理能力。它不仅能深度理解用户输入的图像,还能利用其海量的世界知识精准解读用户意图。针对简略的提示词(prompts),它能够自动补全符合语境的细节,从而生成更出色、更完整的视觉作品。
|
| 121 |
+
|
| 122 |
+
|
| 123 |
+
## 🚀 使用方法
|
| 124 |
+
|
| 125 |
+
### 📦 环境配置
|
| 126 |
+
|
| 127 |
+
* 🐍 **Python:** 3.12+ (推荐并已测试)
|
| 128 |
+
* ⚡ **CUDA:** 12.8
|
| 129 |
+
|
| 130 |
+
#### 📥 安装依赖
|
| 131 |
+
|
| 132 |
+
```bash
|
| 133 |
+
# 1. 首先安装 PyTorch (CUDA 12.8 版本)
|
| 134 |
+
pip install torch==2.8.0 torchvision==0.23.0 torchaudio==2.8.0 --index-url https://download.pytorch.org/whl/cu128
|
| 135 |
+
|
| 136 |
+
# 2. 安装 tencentcloud-sdk
|
| 137 |
+
pip install -i https://mirrors.tencent.com/pypi/simple/ --upgrade tencentcloud-sdk-python
|
| 138 |
+
|
| 139 |
+
# 3. 然后安装其他依赖
|
| 140 |
+
pip install -r requirements.txt
|
| 141 |
+
```
|
| 142 |
+
|
| 143 |
+
为了**获得多达3倍的推理加速**,请安装以下优化:
|
| 144 |
+
|
| 145 |
+
```bash
|
| 146 |
+
# FlashInfer 用于优化的 moe 推理。v0.5.0 已测试。
|
| 147 |
+
pip install flashinfer-python==0.5.0
|
| 148 |
+
```
|
| 149 |
+
> 💡**安装提示:** PyTorch 使用的 CUDA 版本必须与系统的 CUDA 版本匹配,这一点至关重要。
|
| 150 |
+
> FlashInfer 依赖此兼容性在运行时编译内核。
|
| 151 |
+
> 推荐使用 GCC 版本 >=9 来编译 FlashAttention 和 FlashInfer。
|
| 152 |
+
|
| 153 |
+
> ⚡ **性能提示:** 这些优化可以显著加快您的推理速度!
|
| 154 |
+
|
| 155 |
+
> 💡**注意:** 启用 FlashInfer 时,首次推理可能会较慢(约 10 分钟),因为需要编译内核。在同一台机器上的后续推理会快得多。
|
| 156 |
+
|
| 157 |
+
### HunyuanImage-3.0-Instruct (指令推理和图像到图像生成,包括编辑和多图像融合)
|
| 158 |
+
|
| 159 |
+
#### 🔥 使用 Transformers 快速开始
|
| 160 |
+
|
| 161 |
+
##### 1️⃣ 下载模型权重
|
| 162 |
+
|
| 163 |
+
```bash
|
| 164 |
+
# 从 HuggingFace 下载并重命名目录。
|
| 165 |
+
# 注意目录名称不应包含点号,否则使用 Transformers 加载时可能出现问题。
|
| 166 |
+
hf download tencent/HunyuanImage-3.0-Instruct --local-dir ./HunyuanImage-3-Instruct
|
| 167 |
+
```
|
| 168 |
+
|
| 169 |
+
##### 2️⃣ 使用 Transformers 运行
|
| 170 |
+
|
| 171 |
+
```python
|
| 172 |
+
from transformers import AutoModelForCausalLM
|
| 173 |
+
|
| 174 |
+
# 加载模型
|
| 175 |
+
model_id = "./HunyuanImage-3-Instruct"
|
| 176 |
+
# 目前我们无法使用 HF 模型 ID `tencent/HunyuanImage-3.0-Instruct` 直接加载模型
|
| 177 |
+
# 因为名称中包含点号。
|
| 178 |
+
|
| 179 |
+
kwargs = dict(
|
| 180 |
+
attn_implementation="sdpa",
|
| 181 |
+
trust_remote_code=True,
|
| 182 |
+
torch_dtype="auto",
|
| 183 |
+
device_map="auto",
|
| 184 |
+
moe_impl="eager", # 如果已安装 FlashInfer,可使用 "flashinfer"
|
| 185 |
+
moe_drop_tokens=True,
|
| 186 |
+
)
|
| 187 |
+
|
| 188 |
+
model = AutoModelForCausalLM.from_pretrained(model_id, **kwargs)
|
| 189 |
+
model.load_tokenizer(model_id)
|
| 190 |
+
|
| 191 |
+
# 图像到图像生成 (TI2I)
|
| 192 |
+
prompt = "基于图一的logo,参考图二中冰箱贴的材质,制作一个新的冰箱贴"
|
| 193 |
+
|
| 194 |
+
input_img1 = "./assets/demo_instruct_imgs/input_1_0.png"
|
| 195 |
+
input_img2 = "./assets/demo_instruct_imgs/input_1_1.png"
|
| 196 |
+
imgs_input = [input_img1, input_img2]
|
| 197 |
+
|
| 198 |
+
cot_text, samples = model.generate_image(
|
| 199 |
+
prompt=prompt,
|
| 200 |
+
image=imgs_input,
|
| 201 |
+
seed=42,
|
| 202 |
+
image_size="auto",
|
| 203 |
+
use_system_prompt="en_unified",
|
| 204 |
+
bot_task="think_recaption", # 使用 "think_recaption" 进行推理和增强
|
| 205 |
+
infer_align_image_size=True, # 将输出图像大小对齐到输入图像大小
|
| 206 |
+
diff_infer_steps=50,
|
| 207 |
+
verbose=2
|
| 208 |
+
)
|
| 209 |
+
|
| 210 |
+
# 保存生成的图像
|
| 211 |
+
samples[0].save("image_edit.png")
|
| 212 |
+
```
|
| 213 |
+
|
| 214 |
+
#### 🏠 本地安装和使用
|
| 215 |
+
|
| 216 |
+
##### 1️⃣ 克隆仓库
|
| 217 |
+
|
| 218 |
+
```bash
|
| 219 |
+
git clone https://github.com/Tencent-Hunyuan/HunyuanImage-3.0.git
|
| 220 |
+
cd HunyuanImage-3.0/
|
| 221 |
+
```
|
| 222 |
+
|
| 223 |
+
##### 2️⃣ 下载模型权重
|
| 224 |
+
|
| 225 |
+
```bash
|
| 226 |
+
# 从 HuggingFace 下载
|
| 227 |
+
hf download tencent/HunyuanImage-3.0-Instruct --local-dir ./HunyuanImage-3-Instruct
|
| 228 |
+
```
|
| 229 |
+
|
| 230 |
+
##### 3️⃣ 运行演示
|
| 231 |
+
|
| 232 |
+
更多演示在 `run_demo_instruct.sh` 中。
|
| 233 |
+
|
| 234 |
+
```bash
|
| 235 |
+
export MODEL_PATH="./HunyuanImage-3-Instruct"
|
| 236 |
+
bash run_demo_instruct.sh
|
| 237 |
+
```
|
| 238 |
+
|
| 239 |
+
##### 4️⃣ 命令行参数
|
| 240 |
+
|
| 241 |
+
| 参数 | 说明 | 推荐值 |
|
| 242 |
+
|----------------------|------------------------------------------------|-------------|
|
| 243 |
+
| `--prompt` | 输入提示词 | (必填) |
|
| 244 |
+
| `--image` | 要处理的图像。多个图像使用逗号分隔的路径(例如 'img1.png,img2.png') | (必填) |
|
| 245 |
+
| `--model-id` | 模型路径 | (必填) |
|
| 246 |
+
| `--attn-impl` | Attention 实现方式。目前仅支持 'sdpa' | `sdpa` |
|
| 247 |
+
| `--moe-impl` | MoE 实现方式。可选 `eager` 或 `flashinfer` | `flashinfer` |
|
| 248 |
+
| `--seed` | 图像生成的随机种子。使用 None 表示随机种子 | `None` |
|
| 249 |
+
| `--diff-infer-steps` | 推理步数 | `50` |
|
| 250 |
+
| `--image-size` | 图像分辨率。可以是 `auto`、`1280x768` 或 `16:9` | `auto` |
|
| 251 |
+
| `--use-system-prompt` | 系统提示词类型。选项:`None`、`dynamic`、`en_vanilla`、`en_recaption`、`en_think_recaption`、`en_unified`、`custom` | `en_unified` |
|
| 252 |
+
| `--system-prompt` | 自定义系统提示词。当 `--use-system-prompt` 为 `custom` 时使用 | `None` |
|
| 253 |
+
| `--bot-task` | 任务类型。`image` 用于直接生成;`auto` 用于文本;`recaption` 用于重写->图像;`think_recaption` 用于思考->重写->图像 | `think_recaption` |
|
| 254 |
+
| `--save` | 图像保存路径 | `image.png` |
|
| 255 |
+
| `--verbose` | 详细程度 | `2` |
|
| 256 |
+
| `--reproduce` | 是否复现结果 | `True` |
|
| 257 |
+
| `--infer-align-image-size` | 是否将目标图像大小对齐到源图像大小 | `True` |
|
| 258 |
+
| `--max_new_tokens` | 生成的最大 token 数 | `2048` |
|
| 259 |
+
| `--use-taylor-cache` | 采样时使用 Taylor Cache | `False` |
|
| 260 |
+
|
| 261 |
+
##### 5️⃣ 更少的采样步数
|
| 262 |
+
|
| 263 |
+
我们推荐使用模型 [HunyuanImage-3.0-Instruct-Distil](https://huggingface.co/tencent/HunyuanImage-3.0-Instruct-Distil),设置 `--diff-infer-steps 8`,同时保持所有其他推荐参数值**不变**。
|
| 264 |
+
|
| 265 |
+
```bash
|
| 266 |
+
# 从 HuggingFace 下载 HunyuanImage-3.0-Instruct-Distil
|
| 267 |
+
hf download tencent/HunyuanImage-3.0-Instruct-Distil --local-dir ./HunyuanImage-3-Instruct-Distil
|
| 268 |
+
|
| 269 |
+
# 使用 8 步采样运行演示
|
| 270 |
+
export MODEL_PATH="./HunyuanImage-3-Instruct-Distil"
|
| 271 |
+
bash run_demo_instruct_distil.sh
|
| 272 |
+
```
|
| 273 |
+
|
| 274 |
+
<details>
|
| 275 |
+
<summary> 先前版本(纯文本生成图像) </summary>
|
| 276 |
+
|
| 277 |
+
### HunyuanImage-3.0 (文本生成图像)
|
| 278 |
+
|
| 279 |
+
#### 📥 安装依赖
|
| 280 |
+
|
| 281 |
+
```bash
|
| 282 |
+
# 1. 首先安装 PyTorch (CUDA 12.8 版本)
|
| 283 |
+
pip install torch==2.8.0 torchvision==0.23.0 torchaudio==2.8.0 --index-url https://download.pytorch.org/whl/cu128
|
| 284 |
+
|
| 285 |
+
# 2. 安装 tencentcloud-sdk
|
| 286 |
+
pip install -i https://mirrors.tencent.com/pypi/simple/ --upgrade tencentcloud-sdk-python
|
| 287 |
+
|
| 288 |
+
# 3. 然后安装其他依赖
|
| 289 |
+
pip install -r requirements.txt
|
| 290 |
+
```
|
| 291 |
+
|
| 292 |
+
为了**获得多达3倍的推理加速**,请安装以下优化:
|
| 293 |
+
|
| 294 |
+
```bash
|
| 295 |
+
# FlashInfer 用于优化的 moe 推理。v0.5.0 已测试。
|
| 296 |
+
pip install flashinfer-python==0.5.0
|
| 297 |
+
```
|
| 298 |
+
|
| 299 |
+
#### 🔥 使用 Transformers 快速开始
|
| 300 |
+
|
| 301 |
+
##### 1️⃣ 下载模型权重
|
| 302 |
+
|
| 303 |
+
```bash
|
| 304 |
+
# 从 HuggingFace 下载并重命名目录。
|
| 305 |
+
# 注意目录名称不应包含点号,否则使用 Transformers 加载时可能出现问题。
|
| 306 |
+
hf download tencent/HunyuanImage-3.0 --local-dir ./HunyuanImage-3
|
| 307 |
+
```
|
| 308 |
+
|
| 309 |
+
##### 2️⃣ 使用 Transformers 运行
|
| 310 |
+
|
| 311 |
+
```python
|
| 312 |
+
from transformers import AutoModelForCausalLM
|
| 313 |
+
|
| 314 |
+
# 加载模型
|
| 315 |
+
model_id = "./HunyuanImage-3"
|
| 316 |
+
# 目前我们无法使用 HF 模型 ID `tencent/HunyuanImage-3.0` 直接加载模型
|
| 317 |
+
# 因为名称中包含点号。
|
| 318 |
+
|
| 319 |
+
kwargs = dict(
|
| 320 |
+
attn_implementation="sdpa", # 如果已安装 FlashAttention,可使用 "flash_attention_2"
|
| 321 |
+
trust_remote_code=True,
|
| 322 |
+
torch_dtype="auto",
|
| 323 |
+
device_map="auto",
|
| 324 |
+
moe_impl="eager", # 如果已安装 FlashInfer,可使用 "flashinfer"
|
| 325 |
+
)
|
| 326 |
+
|
| 327 |
+
model = AutoModelForCausalLM.from_pretrained(model_id, **kwargs)
|
| 328 |
+
model.load_tokenizer(model_id)
|
| 329 |
+
|
| 330 |
+
# 生成图像
|
| 331 |
+
prompt = "一只棕色和白色相间的小狗奔跑在草地上"
|
| 332 |
+
image = model.generate_image(prompt=prompt, stream=True)
|
| 333 |
+
image.save("image.png")
|
| 334 |
+
```
|
| 335 |
+
|
| 336 |
+
#### 🏠 本地安装和使用
|
| 337 |
+
|
| 338 |
+
##### 1️⃣ 克隆仓库
|
| 339 |
+
|
| 340 |
+
```bash
|
| 341 |
+
git clone https://github.com/Tencent-Hunyuan/HunyuanImage-3.0.git
|
| 342 |
+
cd HunyuanImage-3.0/
|
| 343 |
+
```
|
| 344 |
+
|
| 345 |
+
##### 2️⃣ 下载模型权重
|
| 346 |
+
|
| 347 |
+
```bash
|
| 348 |
+
# 从 HuggingFace 下载
|
| 349 |
+
hf download tencent/HunyuanImage-3.0 --local-dir ./HunyuanImage-3
|
| 350 |
+
```
|
| 351 |
+
|
| 352 |
+
##### 3️⃣ 运行演示
|
| 353 |
+
|
| 354 |
+
预训练检查点不会自动重写或增强输入提示词,为了获得最佳效果,我们目前建议社区伙伴使用 deepseek 来重写提示词。您可以前往[腾讯云](https://cloud.tencent.com/document/product/1772/115963#.E5.BF.AB.E9.80.9F.E6.8E.A5.E5.85.A5)申请 API Key。
|
| 355 |
+
|
| 356 |
+
```bash
|
| 357 |
+
# 设置环境变量
|
| 358 |
+
export DEEPSEEK_KEY_ID="your_deepseek_key_id"
|
| 359 |
+
export DEEPSEEK_KEY_SECRET="your_deepseek_key_secret"
|
| 360 |
+
|
| 361 |
+
bash run_demo.sh
|
| 362 |
+
```
|
| 363 |
+
|
| 364 |
+
##### 4️⃣ 命令行参数
|
| 365 |
+
|
| 366 |
+
| 参数 | 说明 | 推荐值 |
|
| 367 |
+
|----------------------|------------------------------------------------|-------------|
|
| 368 |
+
| `--prompt` | 输入提示词 | (必填) |
|
| 369 |
+
| `--model-id` | 模型路径 | (必填) |
|
| 370 |
+
| `--attn-impl` | Attention 实现方式。可选 `sdpa` 或 `flash_attention_2` | `sdpa` |
|
| 371 |
+
| `--moe-impl` | MoE 实现方式。可选 `eager` 或 `flashinfer` | `flashinfer` |
|
| 372 |
+
| `--seed` | 图像生成的随机种子 | `None` |
|
| 373 |
+
| `--diff-infer-steps` | Diffusion 推理步数 | `50` |
|
| 374 |
+
| `--image-size` | 图像分辨率。可以是 `auto`、`1280x768` 或 `16:9` | `auto` |
|
| 375 |
+
| `--save` | 图像保存路径 | `image.png` |
|
| 376 |
+
| `--verbose` | 详细程度。0: 无日志;1: 记录推理信息。 | `0` |
|
| 377 |
+
| `--rewrite` | 是否启用重写 | `1` |
|
| 378 |
+
| `--sys-deepseek-prompt` | 从 `universal` 或 `text_rendering` 中选择系统提示词 | `universal` |
|
| 379 |
+
|
| 380 |
+
#### 🎨 交互式 Gradio 演示
|
| 381 |
+
|
| 382 |
+
启动交互式 Web 界面,方便进行文本到图像生成。
|
| 383 |
+
|
| 384 |
+
##### 1️⃣ 安装 Gradio
|
| 385 |
+
|
| 386 |
+
```bash
|
| 387 |
+
pip install gradio>=4.21.0
|
| 388 |
+
```
|
| 389 |
+
|
| 390 |
+
##### 2️⃣ 配置环境
|
| 391 |
+
|
| 392 |
+
```bash
|
| 393 |
+
# 设置您的模型路径
|
| 394 |
+
export MODEL_ID="path/to/your/model"
|
| 395 |
+
|
| 396 |
+
# 可选:配置 GPU 使用(默认:0,1,2,3)
|
| 397 |
+
export GPUS="0,1,2,3"
|
| 398 |
+
|
| 399 |
+
# 可选:配置主机和端口(默认:0.0.0.0:443)
|
| 400 |
+
export HOST="0.0.0.0"
|
| 401 |
+
export PORT="443"
|
| 402 |
+
```
|
| 403 |
+
|
| 404 |
+
##### 3️⃣ 启动 Web 界面
|
| 405 |
+
|
| 406 |
+
**基础启动:**
|
| 407 |
+
```bash
|
| 408 |
+
sh run_app.sh
|
| 409 |
+
```
|
| 410 |
+
|
| 411 |
+
**使用性能优化:**
|
| 412 |
+
```bash
|
| 413 |
+
# 同时使用两种优化以获得最佳性能
|
| 414 |
+
sh run_app.sh --moe-impl flashinfer --attn-impl flash_attention_2
|
| 415 |
+
```
|
| 416 |
+
|
| 417 |
+
##### 4️⃣ 访问界面
|
| 418 |
+
|
| 419 |
+
> 🌐 **Web 界面:** 打开浏览器并访问 `http://localhost:443`(或您配置的端口)
|
| 420 |
+
|
| 421 |
+
</details>
|
| 422 |
+
|
| 423 |
+
## 🧱 模型卡片
|
| 424 |
+
|
| 425 |
+
| 模型 | 参数量 | 下载地址 | 推荐显存 | 支持功能 |
|
| 426 |
+
|---------------------------| --- | --- | --- | --- |
|
| 427 |
+
| HunyuanImage-3.0 | 总计 80B (激活 13B) | [HuggingFace](https://huggingface.co/tencent/HunyuanImage-3.0) | ≥ 3 × 80 GB | ✅ 文本生成图像
|
| 428 |
+
| HunyuanImage-3.0-Instruct | 总计 80B (激活 13B) | [HuggingFace](https://huggingface.co/tencent/HunyuanImage-3.0-Instruct) | ≥ 8 × 80 GB | ✅ 文本生成图像<br>✅ 文本图像到图像<br>✅ 提示词自动重写 <br>✅ CoT 思考
|
| 429 |
+
| HunyuanImage-3.0-Instruct-Distil | 总计 80B (激活 13B) | [HuggingFace](https://huggingface.co/tencent/HunyuanImage-3.0-Instruct-Distil) | ≥ 8 × 80 GB |✅ 文本生成图像<br>✅ 文本图像到图像<br>✅ 提示词自动重写 <br>✅ CoT 思考 <br>✅ 更少的采样步数(推荐 8 步)
|
| 430 |
+
|
| 431 |
+
注意事项:
|
| 432 |
+
- 安装性能优化工具(FlashAttention、FlashInfer)以获得更快的推理速度。
|
| 433 |
+
- 基础模型推荐使用多 GPU 推理。
|
| 434 |
+
|
| 435 |
+
## 📊 评估结果
|
| 436 |
+
|
| 437 |
+
### HunyuanImage-3.0-Instruct 评估
|
| 438 |
+
* 👥 **GSB (人工评估)**
|
| 439 |
+
我们采用了 GSB(好/相同/差)评估方法,该方法通常用于从整体图像感知角度评估两个模型之间的相对性能。我们总共使用了 1000+ 个单图像和多图像编辑案例,在一次运行中为所有比较的模型生成相等数量的图像样本。为了公平比较,我们对每个提示词只进行一次推理,避免任何结果筛选。在与基线方法比较时,我们保持了所有选定模型的默认设置。评估由 100 多名专业评估员执行。
|
| 440 |
+
|
| 441 |
+
<p align="center">
|
| 442 |
+
<img src="./assets/gsb_instruct.png" width=60% alt="Human Evaluation with Other Models">
|
| 443 |
+
</p>
|
| 444 |
+
|
| 445 |
+
|
| 446 |
+
### HunyuanImage-3.0 评估
|
| 447 |
+
|
| 448 |
+
* 🤖 **SSAE (机器评估)**
|
| 449 |
+
SSAE(结构化语义对齐评估)是一种基于先进多模态大语言模型(MLLMs)的图像-文本对齐智能评估指标。我们提取了 12 个类别的 3500 个关键点,然后使用多模态大语言模型通过将生成的图像与这些关键点进行比较,基于图像的视觉内容自动评估和打分。平均图像准确率表示所有关键点的图像级平均分数,而全局准确率直接计算所有关键点的平均分数。
|
| 450 |
+
|
| 451 |
+
<p align="center">
|
| 452 |
+
<img src="./assets/ssae_side_by_side_comparison.png" width=98% alt="Human Evaluation with Other Models">
|
| 453 |
+
</p>
|
| 454 |
+
|
| 455 |
+
<p align="center">
|
| 456 |
+
<img src="./assets/ssae_side_by_side_heatmap.png" width=98% alt="Human Evaluation with Other Models">
|
| 457 |
+
</p>
|
| 458 |
+
|
| 459 |
+
|
| 460 |
+
* 👥 **GSB (人工评估)**
|
| 461 |
+
|
| 462 |
+
我们采用了 GSB(好/相同/差)评估方法,该方法通常用于从整体图像感知角度评估两个模型之间的相对性能。我们总共使用了 1000 个文本提示词,在一次运行中为所有比较的模型生成相等数量的图像样本。为了公平比较,我们对每个提示词只进行一次推理,避免任何结果筛选。在与基线方法比较时,我们保持了所有选定模型的默认设置。评估由 100 多名专业评估员执行。
|
| 463 |
+
|
| 464 |
+
<p align="center">
|
| 465 |
+
<img src="./assets/gsb.png" width=98% alt="Human Evaluation with Other Models">
|
| 466 |
+
</p>
|
| 467 |
+
|
| 468 |
+
## 🖼️ 展示
|
| 469 |
+
|
| 470 |
+
我们的模型可以遵循复杂指令生成高质量、富有创意的图像。
|
| 471 |
+
|
| 472 |
+
<div align="center">
|
| 473 |
+
<img src="./assets/banner_all.jpg" width=100% alt="HunyuanImage 3.0 Demo">
|
| 474 |
+
</div>
|
| 475 |
+
|
| 476 |
+
文本生成图像的展示,请点击以下链接:
|
| 477 |
+
|
| 478 |
+
- [HunyuanImage-3.0](./Hunyuan-Image3.md)
|
| 479 |
+
|
| 480 |
+
### HunyuanImage-3.0-Instruct 展示
|
| 481 |
+
|
| 482 |
+
HunyuanImage-3.0-Instruct 展示了在智能图像生成和编辑方面的强大能力。以下展示突出了其核心功能:
|
| 483 |
+
|
| 484 |
+
* 🧠 **智能视觉理解与推理(CoT Think)**: 模型执行结构化思考,分析用户输入的图像和提示词,将用户的意图和编辑任务扩展为结构化、全面的指令,从而带来更好的图像生成和编辑表现。
|
| 485 |
+
|
| 486 |
+
将复杂的提示词和编辑任务分解为详细的视觉组件,包括主体、构图、光照、色彩搭配和风格。
|
| 487 |
+
|
| 488 |
+
* ✏️ **提示词自动重写**: 自动将稀疏或模糊的提示词增强为专业级、细节丰富的描述,更准确地捕捉用户意图。
|
| 489 |
+
|
| 490 |
+
* 🎨 **文本生成图像(T2I)**: 从文本提示词生成高质量图像,具有出色的提示词遵循度和照片级真实感。
|
| 491 |
+
|
| 492 |
+
* 🖼️ **图像到图像(TI2I)**: 支持创意图像编辑,包括添加元素、移除对象、修改风格和无缝背景替换,同时保留关键视觉元素。
|
| 493 |
+
|
| 494 |
+
* 🔀 **多图像融合**: 智能组合多个参考图像(最多3个参考图输入),创建融合来自不同来源的视觉元素的连贯合成图像。
|
| 495 |
+
|
| 496 |
+
|
| 497 |
+
**展示 1: 详细的思考和推理过程**
|
| 498 |
+
|
| 499 |
+
<div align="center">
|
| 500 |
+
<img src="./assets/pg_instruct_imgs/cot_ti2i.gif" alt="HunyuanImage-3.0-Instruct Showcase 1" width="90%">
|
| 501 |
+
</div>
|
| 502 |
+
|
| 503 |
+
**展示 2: 具有复杂场景理解的创意 T2I 生成**
|
| 504 |
+
|
| 505 |
+
> Prompt: 3D 毛绒质感拟人化马,暖棕浅棕肌理,穿藏蓝西装、白衬衫,戴深棕手套;疲惫带期待,坐于电脑前,旁置印 "HAPPY AGAIN" 的马克杯。橙红渐变背景,配超大号藏蓝粗体 "马上下班",叠加米黄 "Happy New Year" 并标 "(2026)"。橙红为主,藏蓝米黄撞色,毛绒温暖柔和。
|
| 506 |
+
|
| 507 |
+
<div align="center">
|
| 508 |
+
<img src="./assets/pg_instruct_imgs/image0.png" alt="HunyuanImage-3.0-Instruct Showcase 2" width="75%">
|
| 509 |
+
</div>
|
| 510 |
+
|
| 511 |
+
**展示 3: 精确图像编辑与元素保留**
|
| 512 |
+
|
| 513 |
+
<div align="center">
|
| 514 |
+
<img src="./assets/pg_instruct_imgs/image1.png" alt="HunyuanImage-3.0-Instruct Showcase 3" width="85%">
|
| 515 |
+
</div>
|
| 516 |
+
|
| 517 |
+
**展示 4: 风格转换与主题增强**
|
| 518 |
+
|
| 519 |
+
<div align="center">
|
| 520 |
+
<img src="./assets/pg_instruct_imgs/image2.png" alt="HunyuanImage-3.0-Instruct Showcase 4" width="85%">
|
| 521 |
+
</div>
|
| 522 |
+
|
| 523 |
+
|
| 524 |
+
**展示 5: 高级风格转换与产品效果图生成**
|
| 525 |
+
|
| 526 |
+
<div align="center">
|
| 527 |
+
<img src="./assets/pg_instruct_imgs/image3.png" alt="HunyuanImage-3.0-Instruct Showcase 5" width="85%">
|
| 528 |
+
</div>
|
| 529 |
+
|
| 530 |
+
|
| 531 |
+
**展示 6: 多图像融合与创意合成**
|
| 532 |
+
|
| 533 |
+
<div align="center">
|
| 534 |
+
<img src="./assets/pg_instruct_imgs/image4.png" alt="HunyuanImage-3.0-Instruct Showcase 6" width="85%">
|
| 535 |
+
</div>
|
| 536 |
+
|
| 537 |
+
## 📚 引用
|
| 538 |
+
|
| 539 |
+
如果您在研究中发现 HunyuanImage-3.0 有用,请引用我们的工作:
|
| 540 |
+
|
| 541 |
+
```bibtex
|
| 542 |
+
@article{cao2025hunyuanimage,
|
| 543 |
+
title={HunyuanImage 3.0 Technical Report},
|
| 544 |
+
author={Cao, Siyu and Chen, Hangting and Chen, Peng and Cheng, Yiji and Cui, Yutao and Deng, Xinchi and Dong, Ying and Gong, Kipper and Gu, Tianpeng and Gu, Xiusen and others},
|
| 545 |
+
journal={arXiv preprint arXiv:2509.23951},
|
| 546 |
+
year={2025}
|
| 547 |
+
}
|
| 548 |
+
```
|
| 549 |
+
|
| 550 |
+
## 🙏 致谢
|
| 551 |
+
|
| 552 |
+
我们衷心感谢以下开源项目和社区的宝贵贡献:
|
| 553 |
+
|
| 554 |
+
* 🤗 [Transformers](https://github.com/huggingface/transformers) - 最先进的 NLP 库
|
| 555 |
+
* 🎨 [Diffusers](https://github.com/huggingface/diffusers) - 扩散模型库
|
| 556 |
+
* 🌐 [HuggingFace](https://huggingface.co/) - AI 模型中心和社区
|
| 557 |
+
* ⚡ [FlashAttention](https://github.com/Dao-AILab/flash-attention) - 内存高效的注意力机制
|
| 558 |
+
* 🚀 [FlashInfer](https://github.com/flashinfer-ai/flashinfer) - 优化的推理引擎
|
| 559 |
+
|
| 560 |
+
## 🌟🚀 GitHub Star 历史
|
| 561 |
+
|
| 562 |
+
[](https://github.com/Tencent-Hunyuan/HunyuanImage-3.0)
|
| 563 |
+
[](https://github.com/Tencent-Hunyuan/HunyuanImage-3.0)
|
| 564 |
+
|
| 565 |
+
[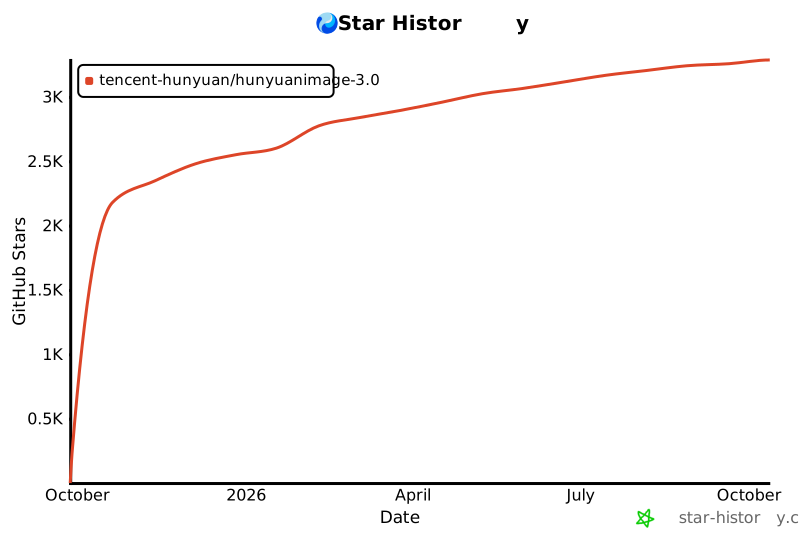](https://www.star-history.com/#Tencent-Hunyuan/HunyuanImage-3.0&Date)
|