

ainvfx-fluid · paint your fluid, skip the simulation, generate the result
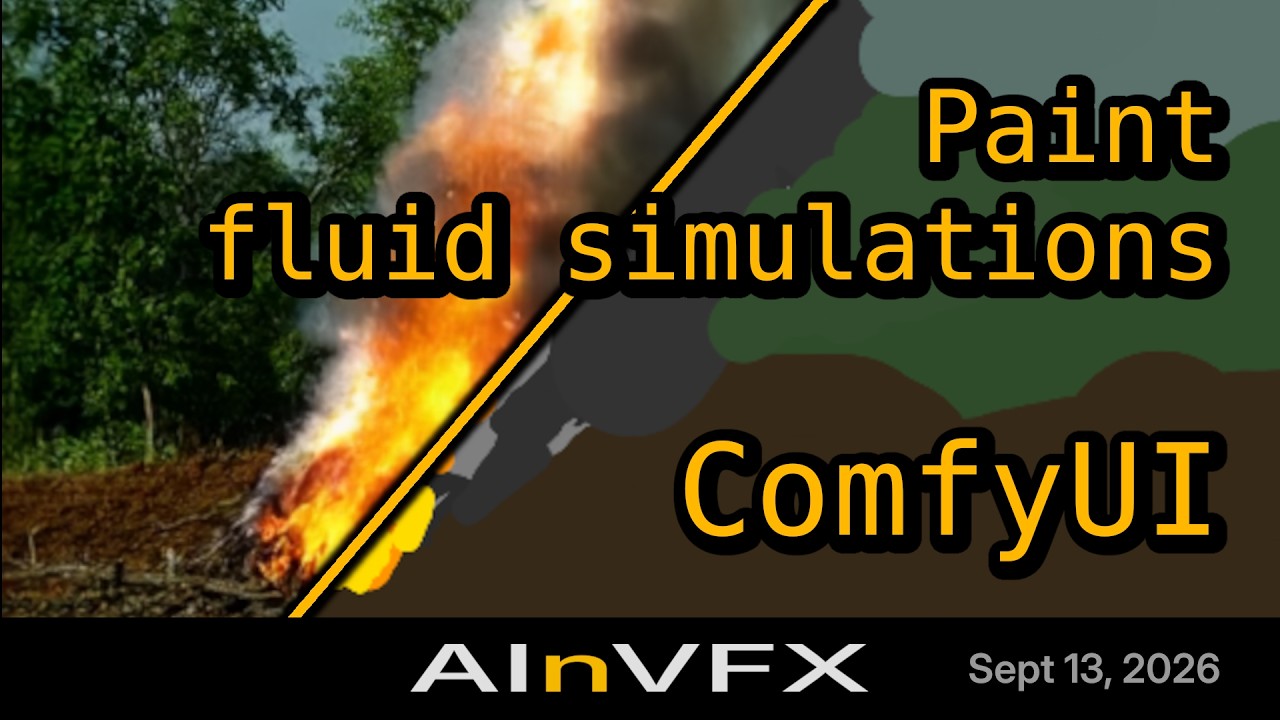
An IC-LoRA for LTX 2.5 (22B) by AInVFX. You paint flat colour blobs on one or a few keyframes (the first frame, the last frame, any frame of the 8-frame grid in between); the LoRA replaces the blobs with smoke, steam, fire, explosions, water and other liquids, dust or clouds, and animates from one keyframe to the next. Trigger word: ainvfxfluid.
Please update (1 November 2026). An earlier version of this LoRA was trained by mistake on stock clips whose terms did not allow it. It has been retrained only on synthetic clips that we generated and publish (AInVFX/ainvfx-fluid). Delete any older copy and download this file again: same name, same settings, same workflow.
Made for compositing and previz as an art-directable stock footage generator. It started as the instructor's demo of cohort 1 of the AInVFX Generative AI Bootcamp for Film and TV - Come learn and build with us! ainvfx.com/bootcamp.
📺 Watch the 45-minute tutorial · 📰 Read the article: setup, control video rules, painting, prompting, and how the model was trained. Both were made with an earlier version; every step still applies.
| File | ltx-2.5/ainvfx-fluid.safetensors (654 MB, ComfyUI format, rank 32), retrained on 1 Nov 2026 |
| Base model | Lightricks/LTX-2.5, 22B transformer, dev or distilled |
| Control | a video, same resolution and length as the output: keyframes painted in flat colours, black frames in between |
| Training data | AInVFX/ainvfx-fluid (dataset): 528 synthetic training pairs from 176 scenes, every clip documented |
| Test plates | AInVFX/ainvfx-paintaplate (dataset): 23 synthetic plates to paint over |
| Workflow | workflow/ainvfx-fluid_painted_smoke_plume.json, paints both frames inside ComfyUI |
| App | AInVFX PaintAPlate, open source: paint on a plate and run this LoRA in ComfyUI |
| Tutorial | 45-minute deep dive on YouTube |
| Article | Paint your fluid simulations |
| License | LTX-2.x Community License (see below) |
Samples
Left: the control video. Right: the result. Nine pairs. No control comes from a training clip and none uses stock footage: they are painted by a script over AI-generated clips held out of training, painted directly by a script, or painted by hand in ComfyUI. All results were generated with the LTX 2.5 22B distilled transformer (int8), 8 steps, CFG 1, seed 42, sampler euler_ancestral, LoRA strength 1.0, negative prompt blurry, low quality, distorted, watermark. The frame rate follows the control video (24 or 25 fps here). Every _result video is AI-generated with LTX 2.5 and this LoRA. Each sample file carries a one-line AI-generation label in its metadata and nothing else; this card is the written disclosure.
| Control (painted keyframes, black in between) | Result |
|---|---|
01 · 1024 x 576 · a landscape painted in flat colours (sky, hills, forest, smoke, a fire line) by a script over an AI-generated clip held out of training · ainvfxfluid, A wildfire burns through a forested hillside, emitting thick smoke. The camera hovers steadily above, capturing the scene in wide frame under clear daylight. Autumn foliage contrasts with charred areas and rising smoke plumes. | |
02 · 1024 x 576 · a chimney and its plume on a flat sky, painted the same way · ainvfxfluid, A large chimney smoke stack over a clear blue sky. | |
03 · 512 x 512 · the two frames of the workflow below, painted by hand in ComfyUI on black · ainvfxfluid, smoke plume | |
04 · 960 x 512 · a fireball painted on black, small on the first frame, filling the frame on the last · ainvfxfluid, fire ball exploding towards camera | |
05 · 576 x 1024 (portrait) · flames painted on black, growing taller · ainvfxfluid, fire | |
06 · 1024 x 576 · a plate painted in flat colours: sky and desert ground, then a fireball and black smoke · ainvfxfluid, an explosion in a vast empty desert with nothing else in sight, an orange fireball rising into thick black smoke, clear sky | |
07 · 1024 x 576 · a splash painted on black, small on the first frame, a tall crown on the last · ainvfxfluid, A splash of clear water bursts upward from the bottom of the frame against a black background, droplets scattering and falling. The camera remains static, capturing the splash in a centered frame. | |
08 · 1024 x 576 · a seascape painted in flat zones (sky, sea, a swell), thin foam on the first frame and a breaking wave on the last · ainvfxfluid, A large ocean wave rolls toward the camera and crashes into white foam under a clear blue sky. The camera remains static, capturing the wide seascape in daylight. | |
09 · 1024 x 576 · the words HELLO WORLD painted on black as brush letters with cloud-like edges, one light flat colour per letter, swollen and risen on the last frame · ainvfxfluid, smoke plume | |
How to use it in ComfyUI
- Put
ainvfx-fluid.safetensorsinComfyUI/models/loras/. You need ComfyUI with the ComfyUI-LTXVideo node pack by Lightricks (Manager: search « LTXVideo »; the IC-LoRA loader and guide nodes come from it) and the LTX 2.5 models of its example workflows (transformer, video and audio VAE, Gemma text encoder). - Load it with
LTX IC-LoRA Loader Model Only, strength 1.0. The loader reads the reference downscale factor (2) from the file: nothing to set. - Build the control video, same size and length as the shot you want:
- width and height multiples of 64 (512 x 512, 960 x 512, 576 x 1024, 1024 x 576, 1920 x 1088 all work);
- 121 frames is the tested length; 24, 25 and 50 fps were trained;
- keyframes painted on frame 0, on the 8-frame grid of the LTX VAE in between (index 1, 9, 17, ... 113: a multiple of 8, plus 1) or on the last frame (120), black frames everywhere else. One keyframe is enough: the first frame alone, the last frame alone, or one in between. Several work too, such as the first and the last frame. Each keyframe is a single painted frame, as in training; holding one over its 8 frames also worked in our tests;
- paint flat colours: one blob per volume (light grey for smoke, white for steam, dark grey for heavy smoke, orange and yellow for fire, light blue and white for water), a black background or a few flat zones for sky and ground. Sharp, deliberate shapes are followed closely.
- Prompt:
ainvfxfluid,then what the fluid is and how it is lit.ainvfxfluid, smoke plumeis enough; a fuller sentence helps for what the LoRA saw less. - Generate with the distilled model (8 steps, CFG 1) or the dev model with its usual sampler settings. Strength 0 gives the "no LoRA" comparison.
Every step above is shown on screen in the tutorial, including the ComfyUI-LTXVideo install, the Kornia pad import fix, and where each gated LTX 2.5 file goes.
The shipped workflow does steps 2 to 5 with two Painter nodes and opens pre-painted with a smoke plume (sample 03): copy the two PNGs from workflow/inputs/ into ComfyUI/input/ once, load the workflow, queue. Then repaint: the first frame, and the changes on the last frame. Replace the Painters with a Load Video of your own 121-frame control clip if you prefer to paint elsewhere. Apart from the LTXVideo pack, every node is ComfyUI core (the Painter node needs a recent ComfyUI and Nodes 2.0 enabled).
An element on black, or the whole shot. Paint on a black canvas and you get a stock element on black, ready to composite (samples 03, 04, 05, 07 and 09). Paint flat zones for the sky and the ground and you get the whole shot (samples 01, 02, 06 and 08). For plates to paint over, see AInVFX/ainvfx-paintaplate.
Painting over a photo. You can paint a fluid on a photograph and use that as first and last frame. The result keeps the composition and the colours of the photograph and puts the fluid where you painted it, but it is a video inspired by the photo, not a pixel-exact match of it. For a locked plate, generate the fluid over a black background and composite it back over the plate.
Limitations
- Trained on smoke, steam, fire, explosions, liquids (water among them), dust, fog and clouds. For what it saw less, a fuller prompt helps.
- In a full scene, the result can include something you did not paint, such as a person. Describe the setting as empty: for sample 06, « a vast empty desert with nothing else in sight » removed the person that « a desert » produced.
- A control clip that leaves the 8-frame grid, or whose size is not a multiple of 64, degrades quickly.
- 121 frames at 24, 25 or 50 fps were tested. The trainer also saw 321-frame and 33-frame clips, so other 8k + 1 lengths should work; testing there was limited.
- The base model's own limits apply (faces, fine motion). Painted words stay readable at first, then billow; letters with soft, cloud-like edges read as smoke, while crisp letters can come out as solid objects (sample 09).
Training
- Trainer: musubi-tuner (kohya-ss), the LTX-2 fork by AkaneTendo25, branch
ltx-2-dev(commit9dc9abc), run with theltx_iclorarecipe of AInVFX's ainvfx-runpod toolkit. Base weightsltx-2.5-22b-dev-transformer-bf16, loaded in fp8, gradient checkpointing, 8-bit AdamW, batch 1. LoRA rank 32, alpha 32,--lora_target_preset v2v(attention and feed-forward of every video block),--reference_downscale 2(the control is encoded at half resolution),--ltx2_first_frame_conditioning_p 0.2, the control always present. - Dataset: AInVFX/ainvfx-fluid (CC BY 4.0), 528 training pairs from 176 synthetic scenes: 56 elements on black and 120 full scenes (fire, smoke, explosions, steam, liquids, dust, fog and clouds), landscape, portrait and square, at 24, 25 and 50 fps. First frames by MOSS-Image SFT, motion by LTX 2.5 22B distilled, both in ComfyUI. Captions by Qwen3-VL-8B-Instruct, trigger word first. The control videos were painted automatically over each clip: full scenes in flat zones, elements on black as black plus a few colours. Every keyframe is a single frame on the 8-frame grid: half the clips have one keyframe (the first frame, the last frame or one in between), the other half have several. Every clip's prompts, seeds and settings are in the dataset's manifests.
- Three-stage resolution chain, each stage starting from the last checkpoint of the one before, one dataset block per frame rate (24, 25, 50 fps):
| Stage | Pairs | Geometry | Steps | Learning rate | Time |
|---|---|---|---|---|---|
| 1 · motion | 176 | 576 x 320 x 321 frames | 4000 | 1e-4 | 7 h 59 |
| 2 · shape and material | 176 | 1024 x 576 x 121 | 2000 | 5e-5 | 5 h 14 |
| 3 · fine detail | 176 | 1920 x 1088 x 33 | 1000 | 2e-5 | 3 h 06 |
- Compute: one NVIDIA RTX PRO 6000 (96 GB) on Runpod, 16 h 20 min wall-clock for the three stages, downloads, caching and samples included. At the card's 600 W maximum that is at most about 9.8 kWh. Generating the dataset took about 14 GPU-hours (at most about 8.5 kWh). With captions, tests and idle time, this file used about 33 GPU-hours in all, at most about 20 kWh. We did not meter it.
- Loss: in stage 1 it went from about 0.28 to about 0.26 and was flat over the last 1,000 steps. It is noisy; the samples on held-out controls were the signal, not the curve.
Transparency, data and ethics
This model follows the AInVFX statement of AI ethics: open weights first, documented training data, creator consent, labelled generated content, frugal compute, a human who stays in control of the shot.
Data provenance. This file is trained only on synthetic clips that AInVFX generated, documented clip by clip in AInVFX/ainvfx-fluid (prompts, seeds, models, settings, licences). No stock footage, no scraped content, no real people. The sample controls are synthetic or painted.
Earlier versions are withdrawn. One was trained by mistake on stock clips whose terms did not allow it (see the notice at the top). Please use this file.
Generated content. The
_resultvideos are AI-generated. Every sample MP4 carries a one-line AI-generation label in its metadata (the generation graph was removed), and this README is the written disclosure.Compute. Stated above, in GPU-hours and an energy upper bound, so you can judge the cost of reproducing it.
What it is for. Adding a visual effect to a shot you own. Do not use it to depict a real place, event or person without appropriate consent.
License
The LoRA is a derivative of LTX-2.5 and is released under the LTX-2.x Community License, the same license as the base model; a full copy is in LICENSE. Notice required by that license: this derivative is subject to its Section 4 (use restrictions) and Attachment A (acceptable use policy) in their entirety. Worth knowing before you ship: a Commercial Entity (annual revenue of 10 M USD or more) needs a paid Commercial Use Agreement from Lightricks (ltxv-licensing@lightricks.com) for any use of LTX-2.x or its derivatives beyond testing and evaluation. This paragraph is a summary, not legal advice: read the file.
Who made it, and come build with us
Adrien Toupet trained the first version as the instructor's demo during cohort 1 of the AInVFX Generative AI Bootcamp for Film and TV; AInVFX has since retrained it on synthetic data only.
AInVFX runs a masterclass series (4-hour live sessions) and a bootcamp (60 hours of live training, project based), each with several dates a year, online and in English. Come learn and build with us! For the next dates, see the masterclass and the bootcamp pages.
Questions, results, bugs: contact AInVFX or open a discussion on this repo.
Credits
Lightricks for LTX-2.5 and the IC-LoRA design · MOSS-Image (OpenMOSS) for the dataset's first frames · Qwen3-VL for the captions · kohya-ss and AkaneTendo25 for the trainer · ComfyUI · Runpod for the GPU.
- Downloads last month
- 957
Model tree for AInVFX/ainvfx-fluid
Base model
Lightricks/LTX-2.5