

RynnUnify
Collection
3 items • Updated
Agentic Embodied Intelligence via Reciprocal VLM Reasoning and World Modeling


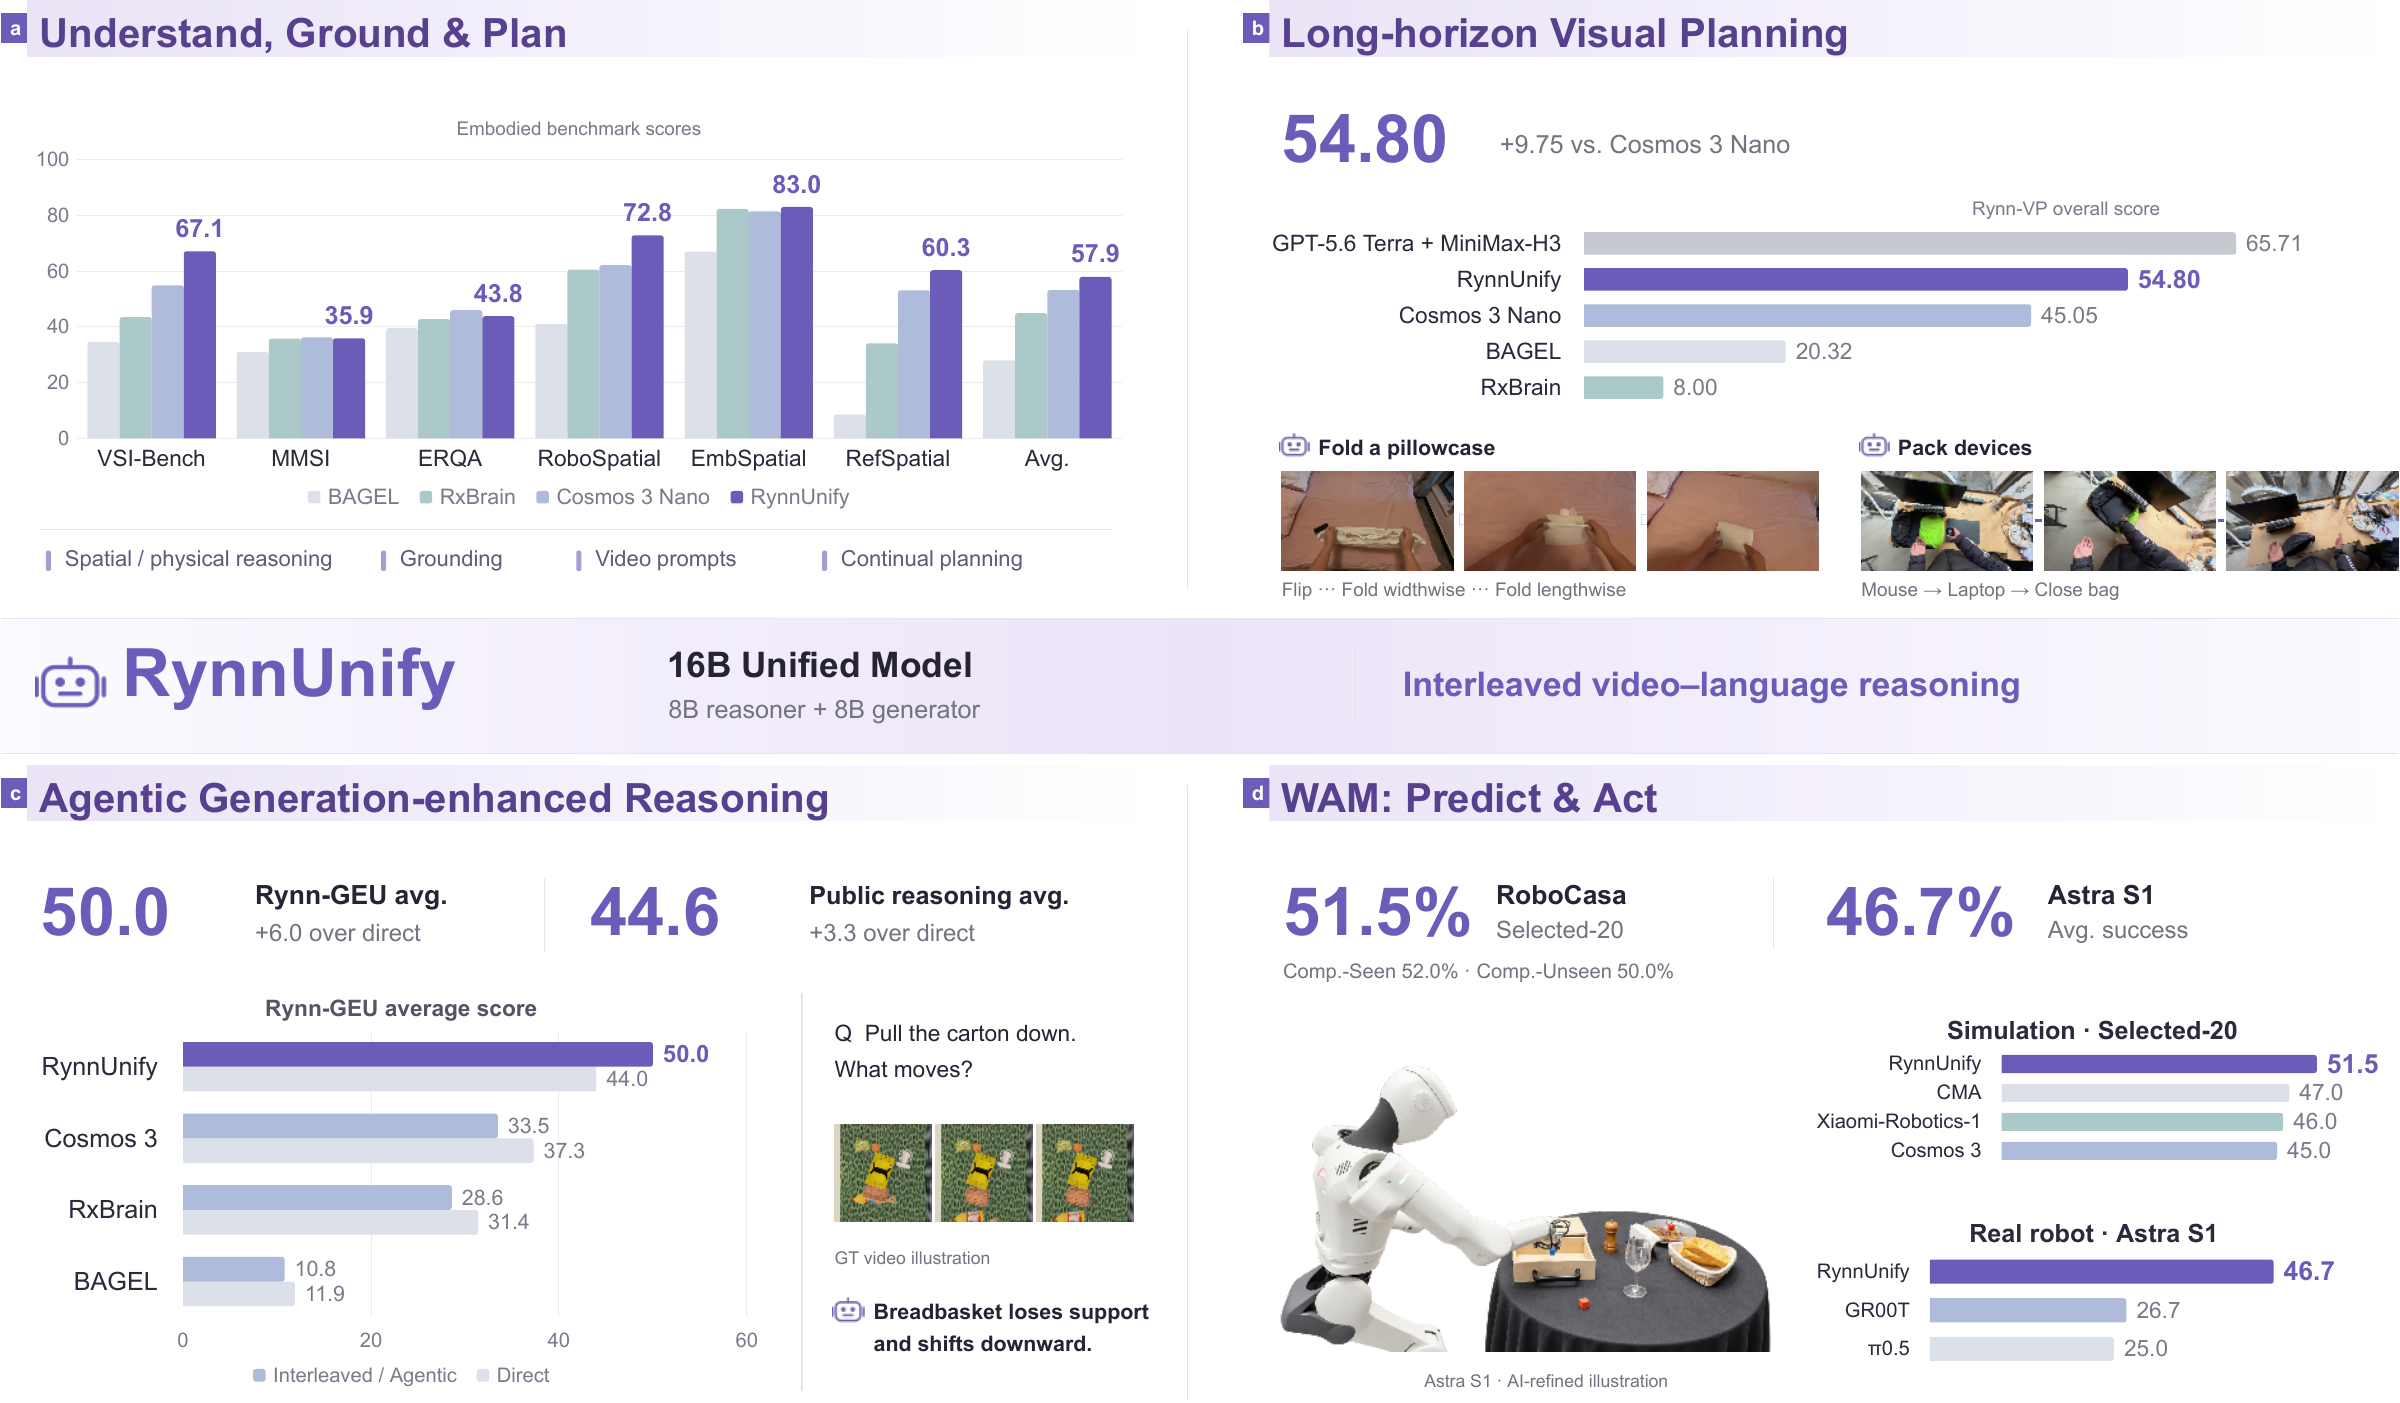
We present RynnUnify, a Mixture-of-Transformers architecture with an autoregressive Reasoner and a rectified-flow video Generator. Built on Cosmos3, RynnUnify connects embodied understanding, spatial grounding, and long-horizon visual planning through interleaved video-language reasoning.
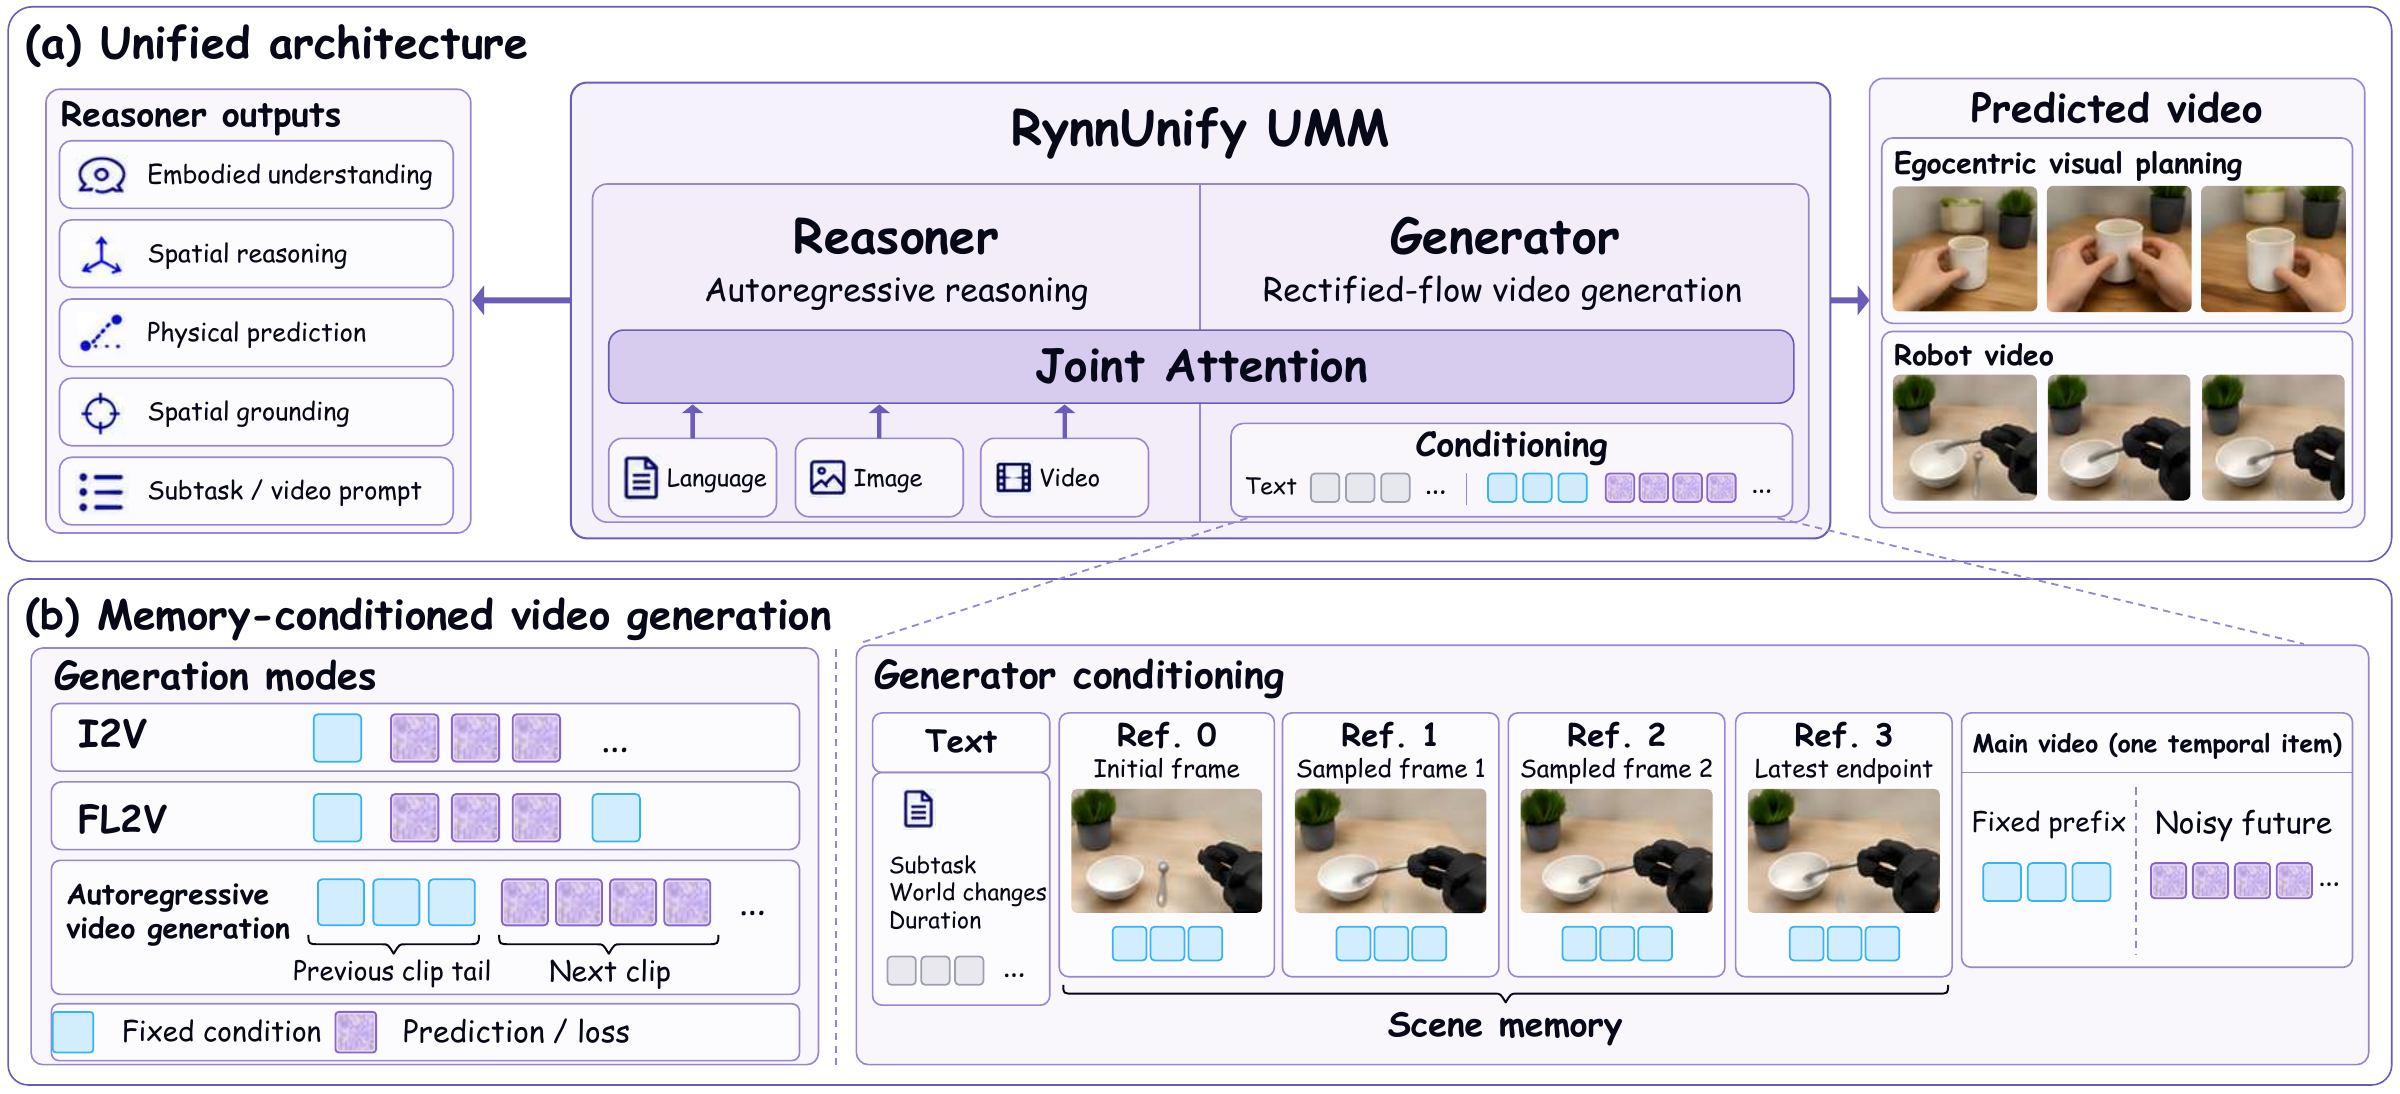
RynnUnify adopts a 16B unified embodied model comprising an 8B autoregressive reasoner and an 8B video generator. The Reasoner predicts the next subtask, visual description, and duration. Through joint attention, the Generator attends to the Reasoner’s representations and predicts a video segment conditioned on scene memory and recent motion.
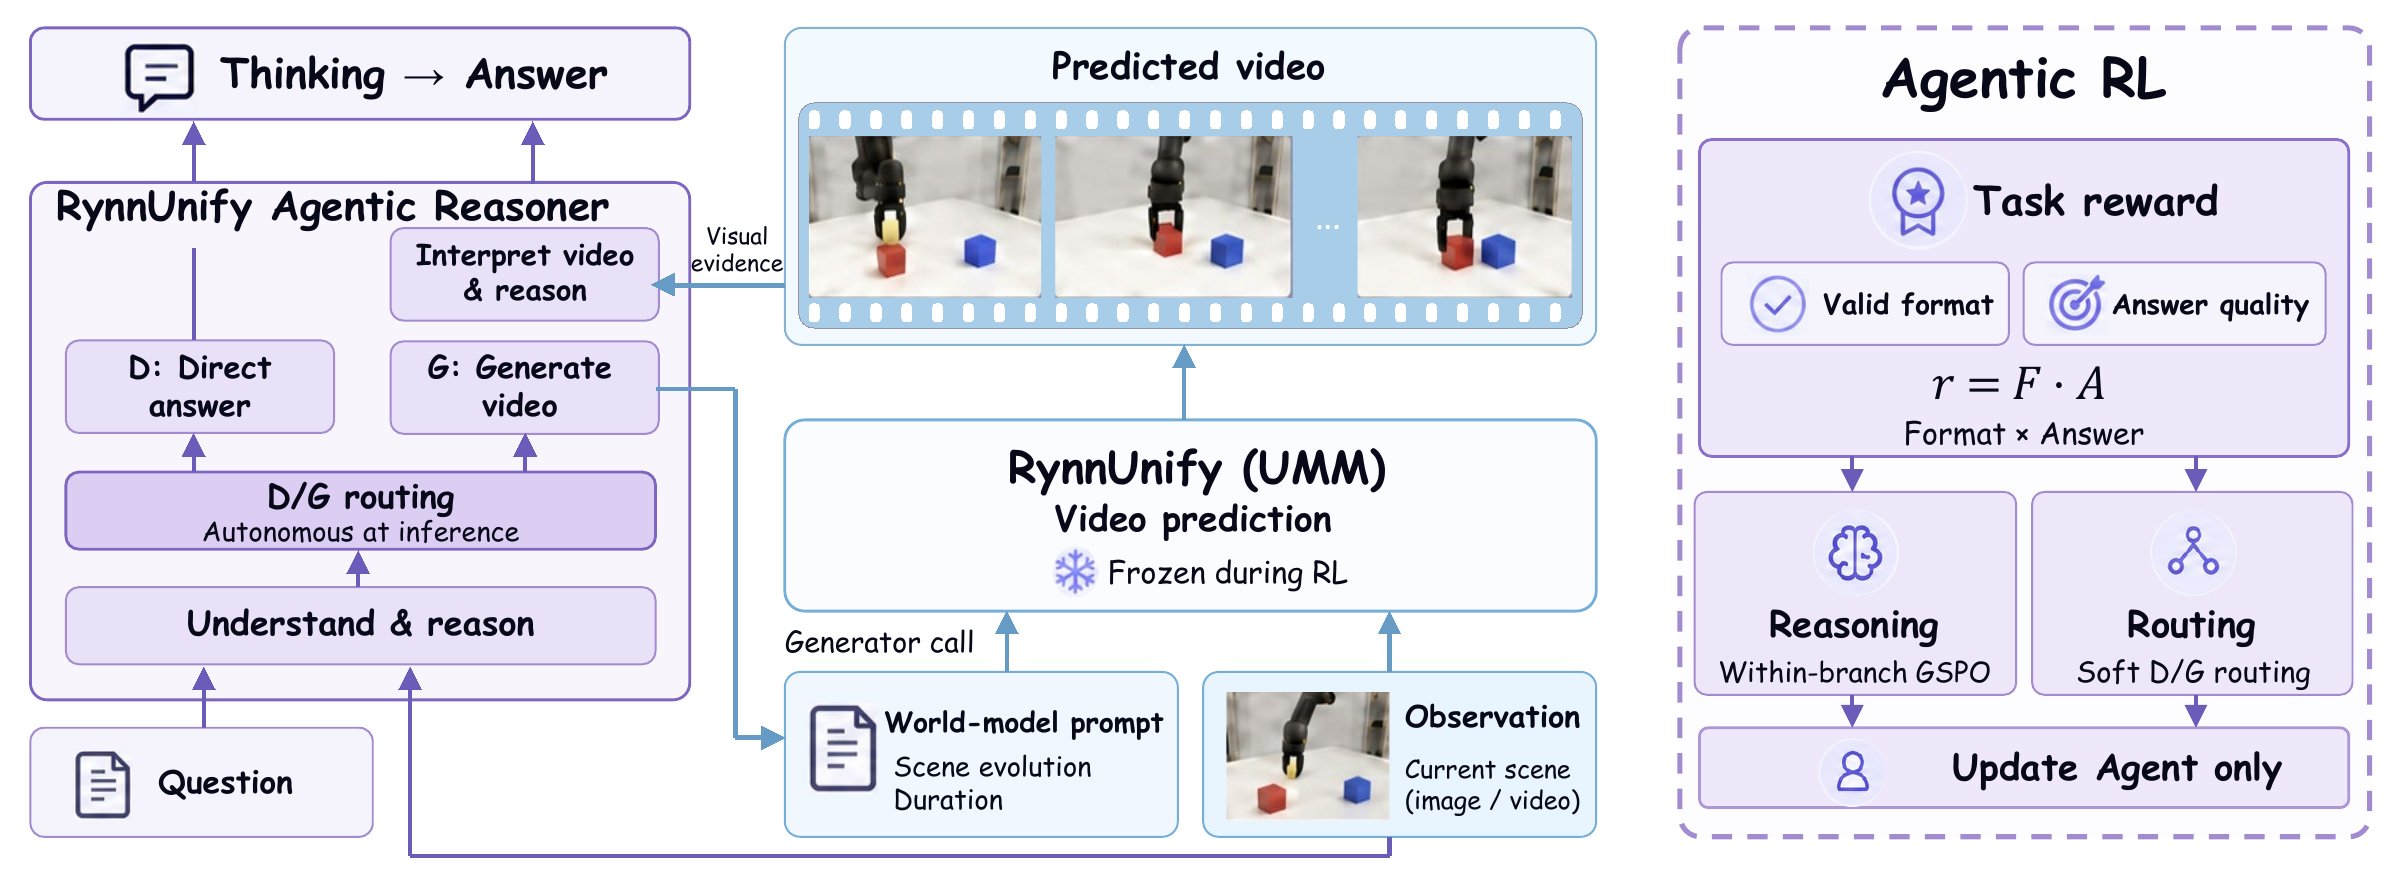
Agentic interleaved thinking enhances embodied reasoning by using world modeling to imagine future scene dynamics and bring the resulting visual evidence into the reasoning process. We introduce Branch-Conditional Policy Optimization (BCPO) to learn both reasoning behavior and generator invocation.
BCPO samples four direct and four generation-assisted trajectories for each routable question. Within-branch reward comparisons improve reasoning behavior; differences between branch rewards supervise the routing policy. At inference time, the agent selects a branch from the original input and optionally requests generated visual evidence before answering. Only the agent is updated during training; the generator remains frozen.
See the algorithm, reward definitions, and service interfaces.
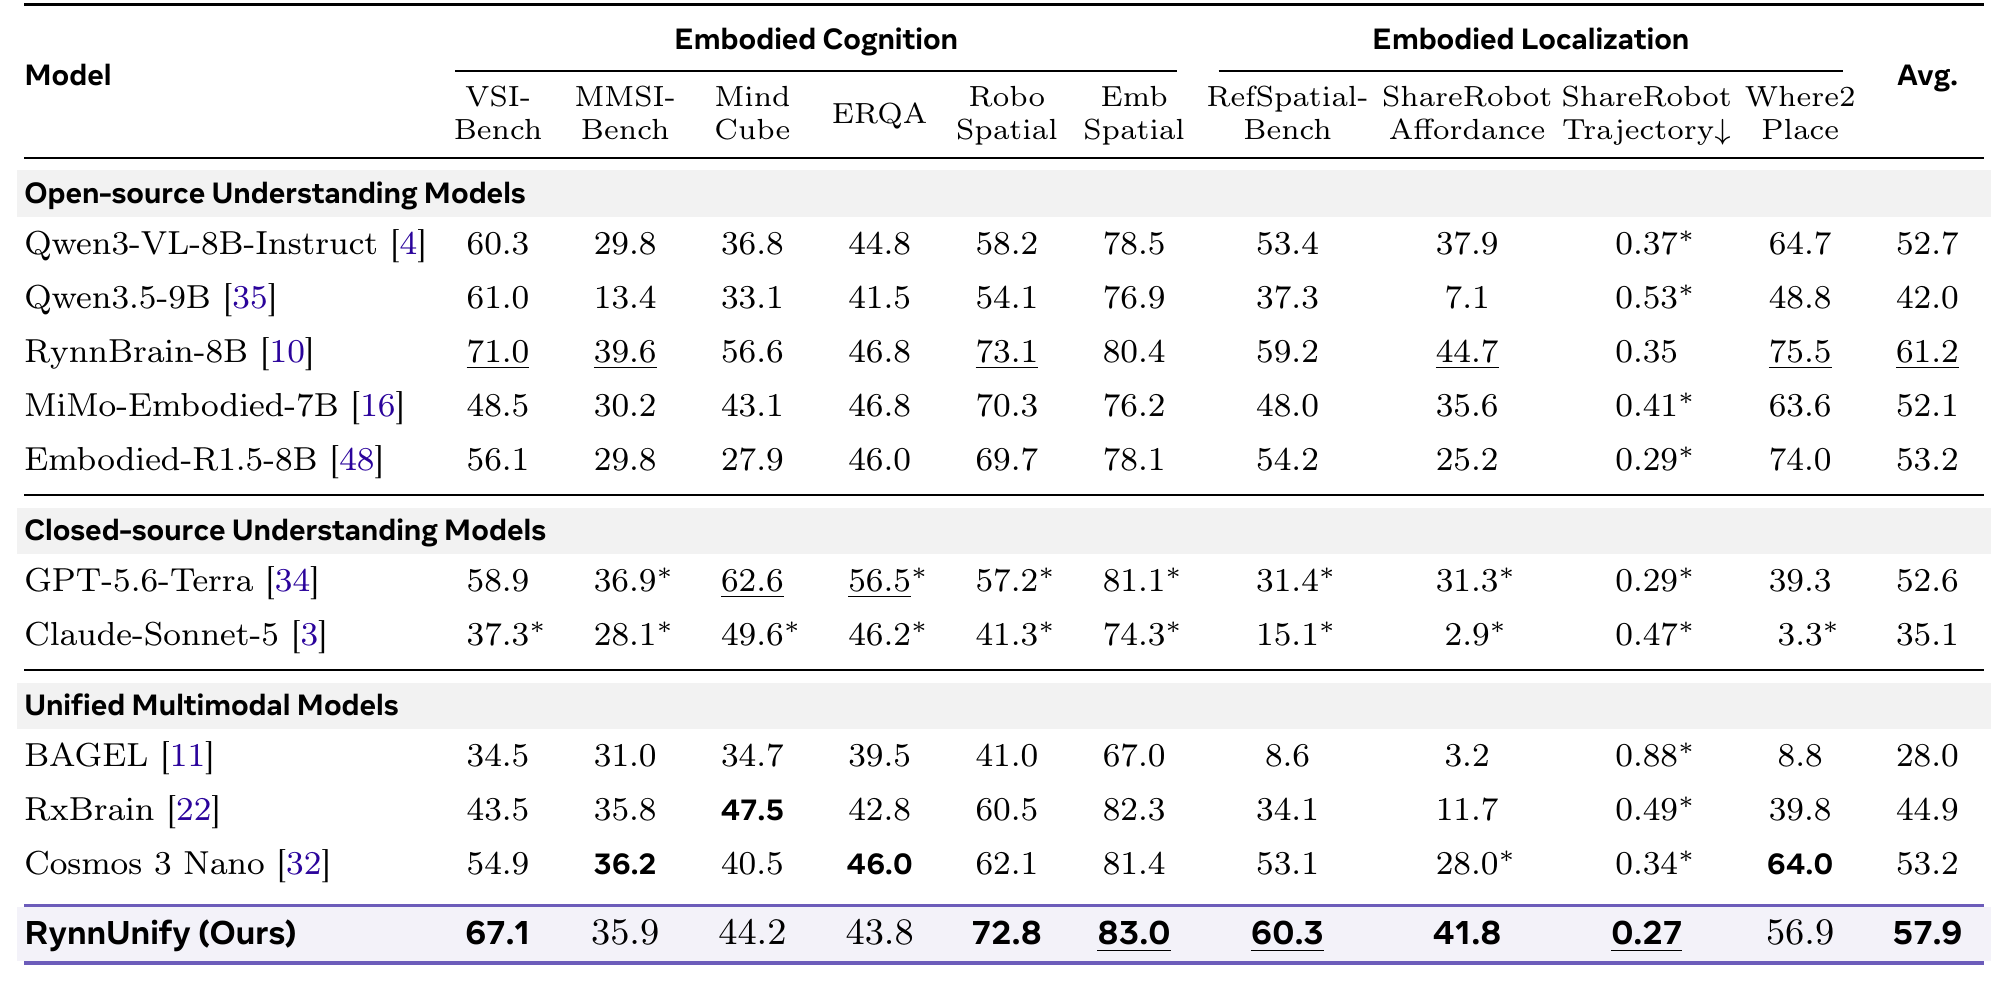
General Embodied Understanding
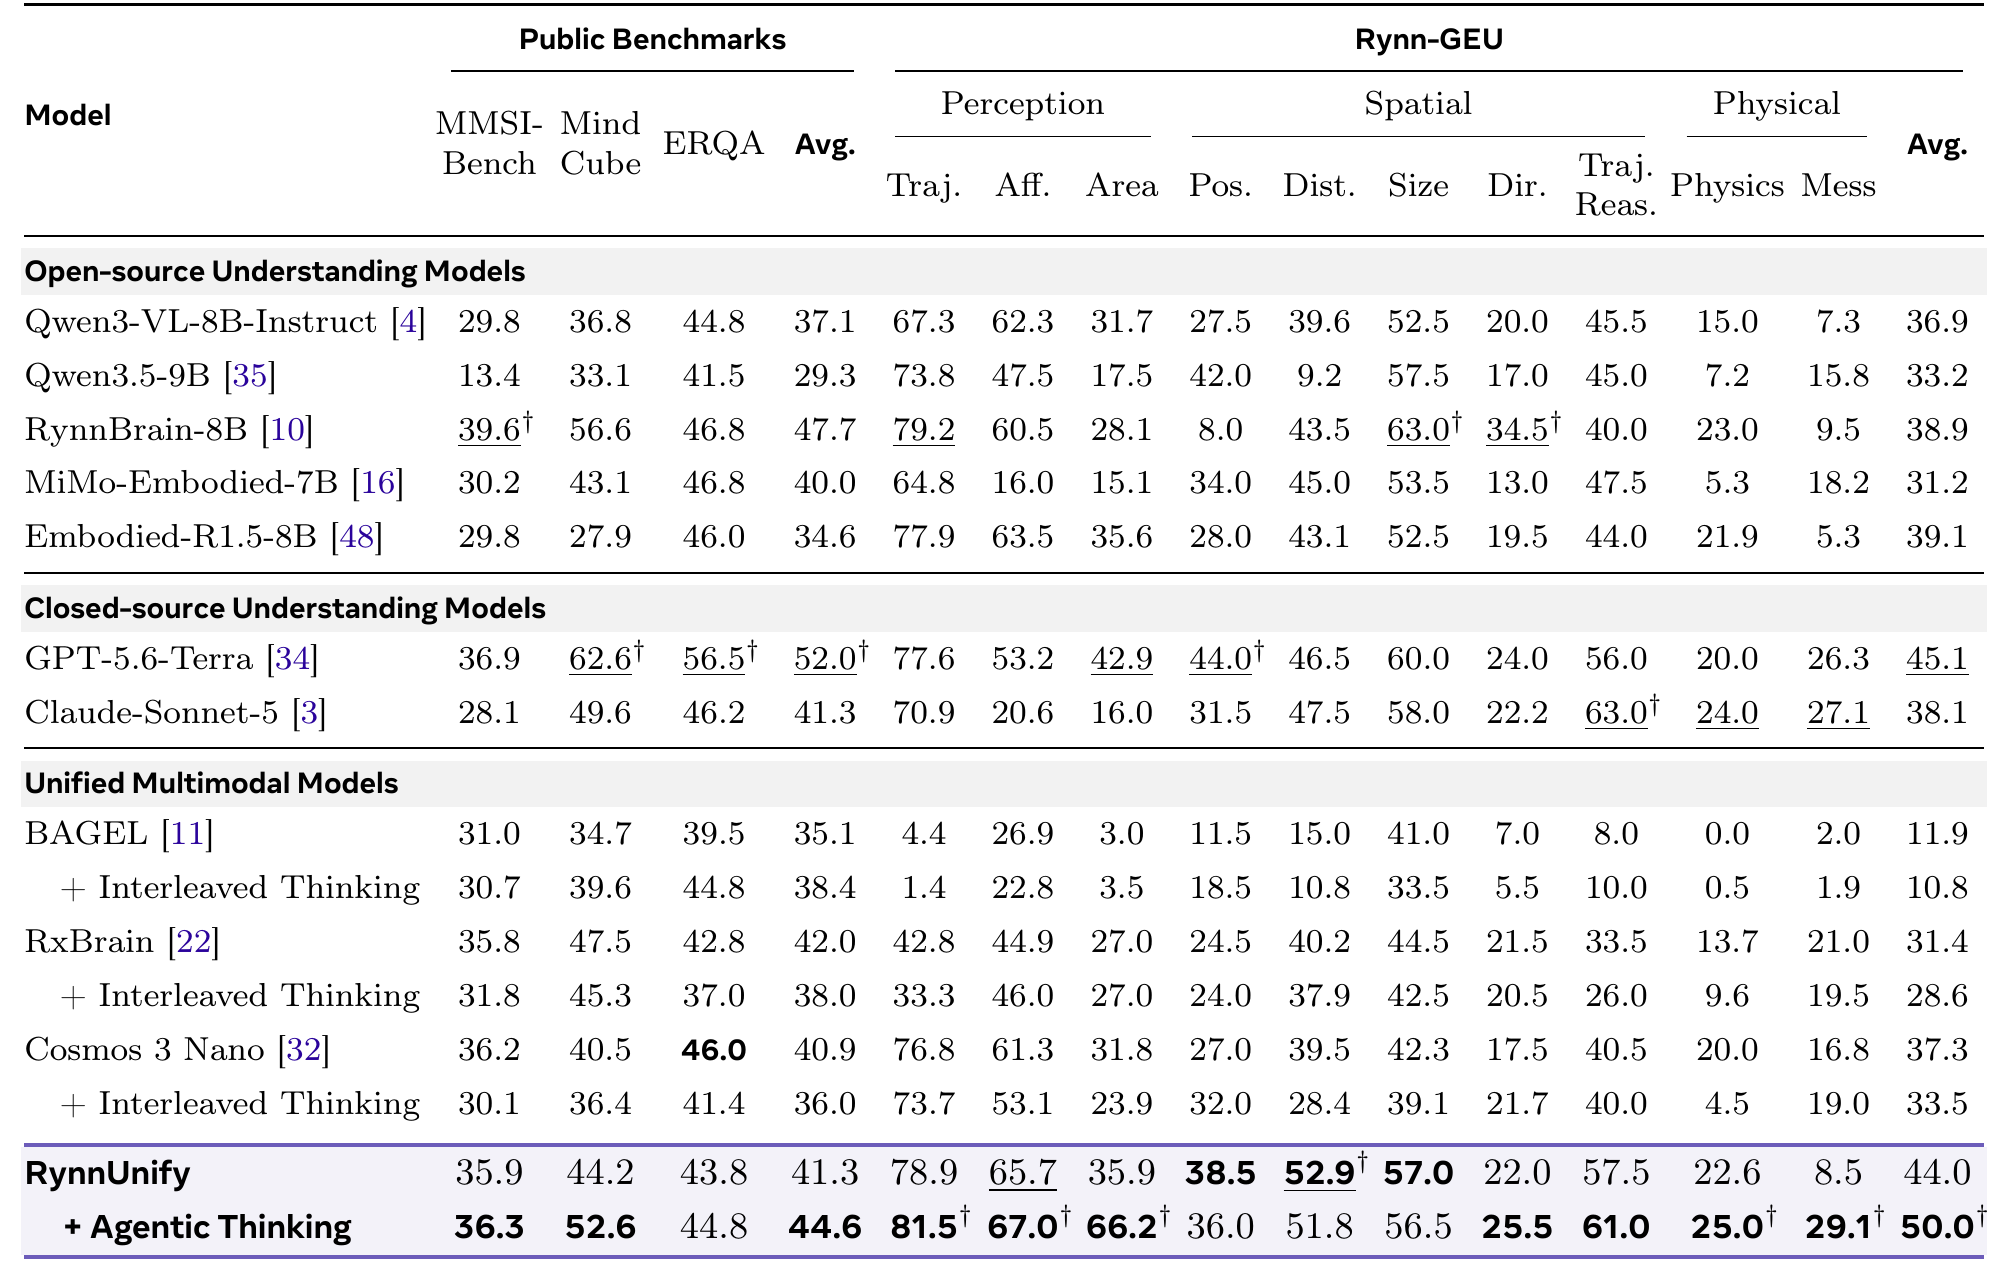
Interleaved Thinking on Public Benchmarks and Rynn-GEU
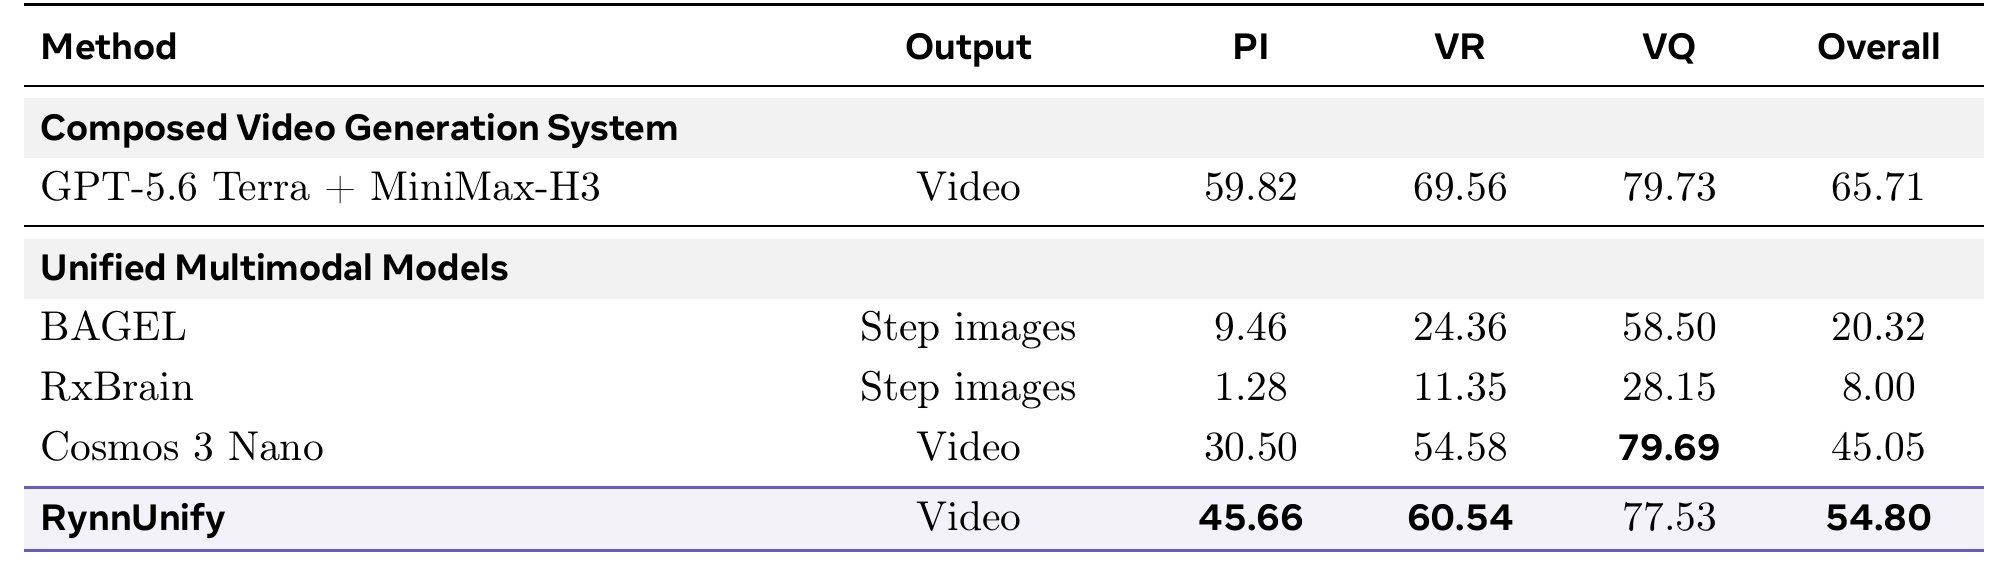
Long-horizon Visual Planning on Rynn-VP
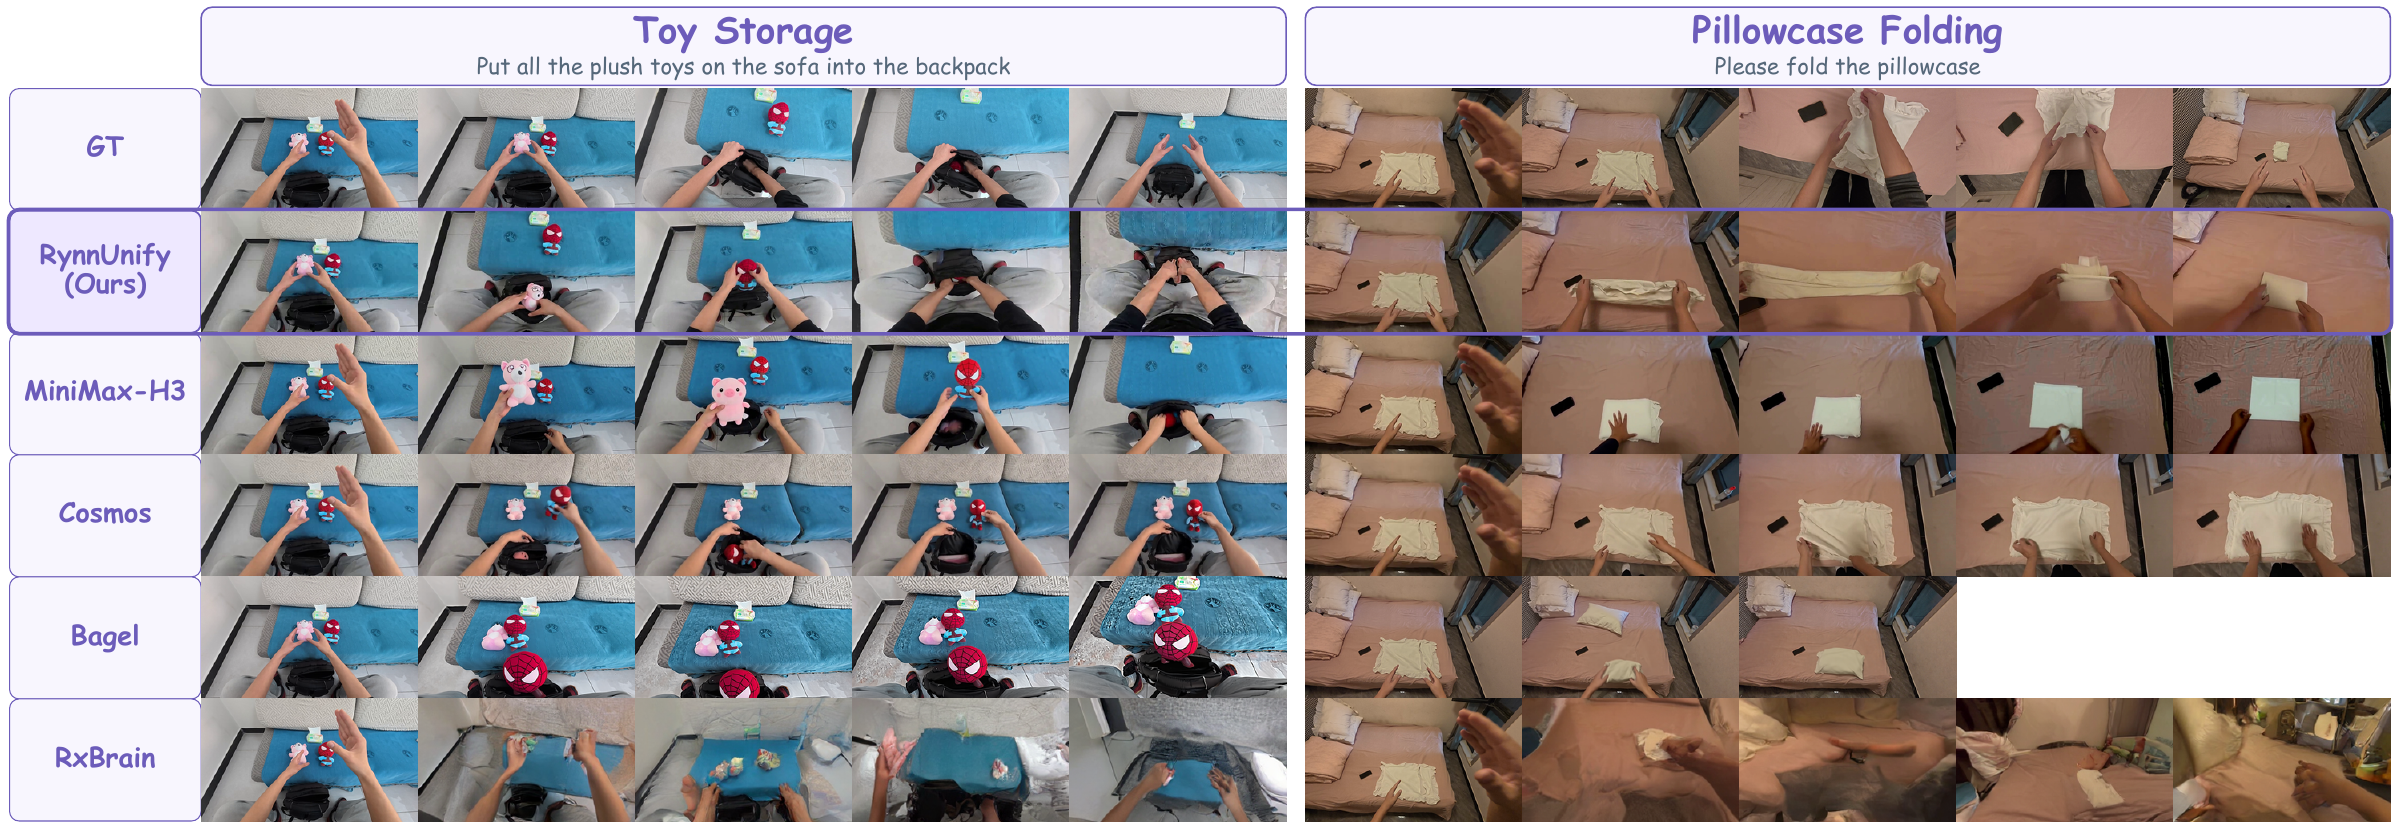
Visual Planning Visualizations
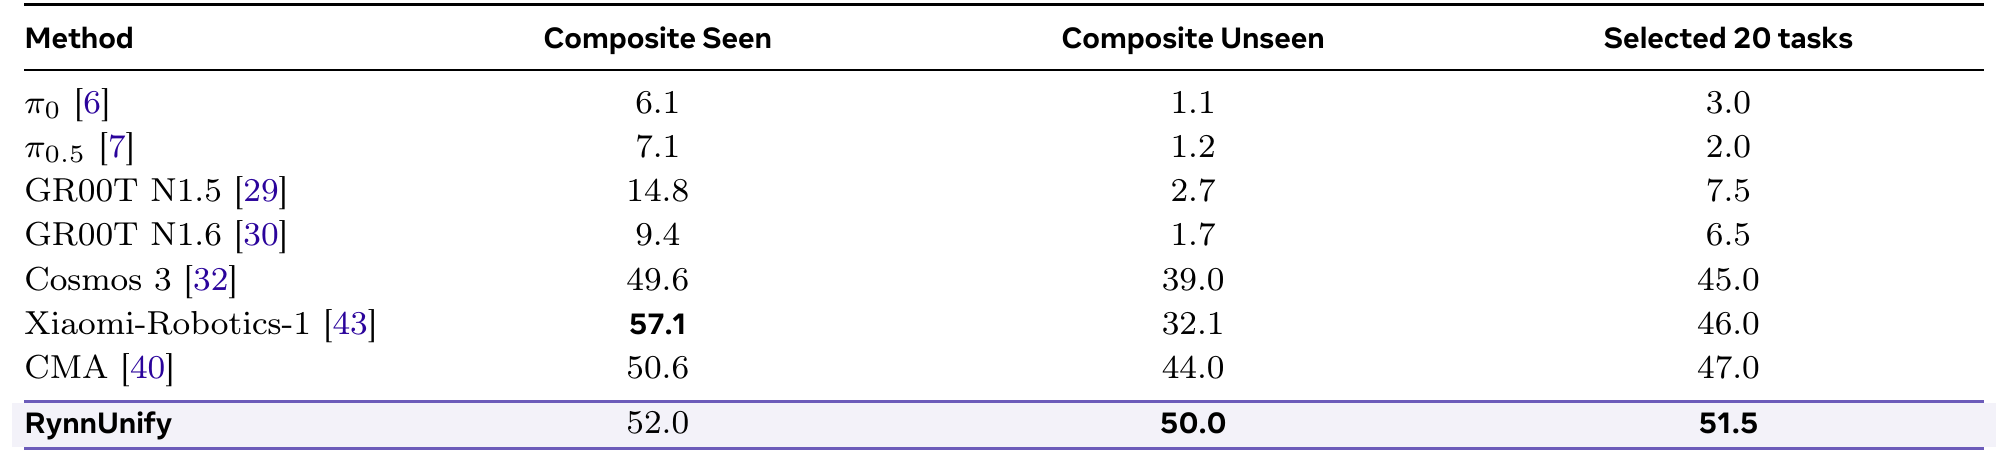
Robot Manipulation on RoboCasa365
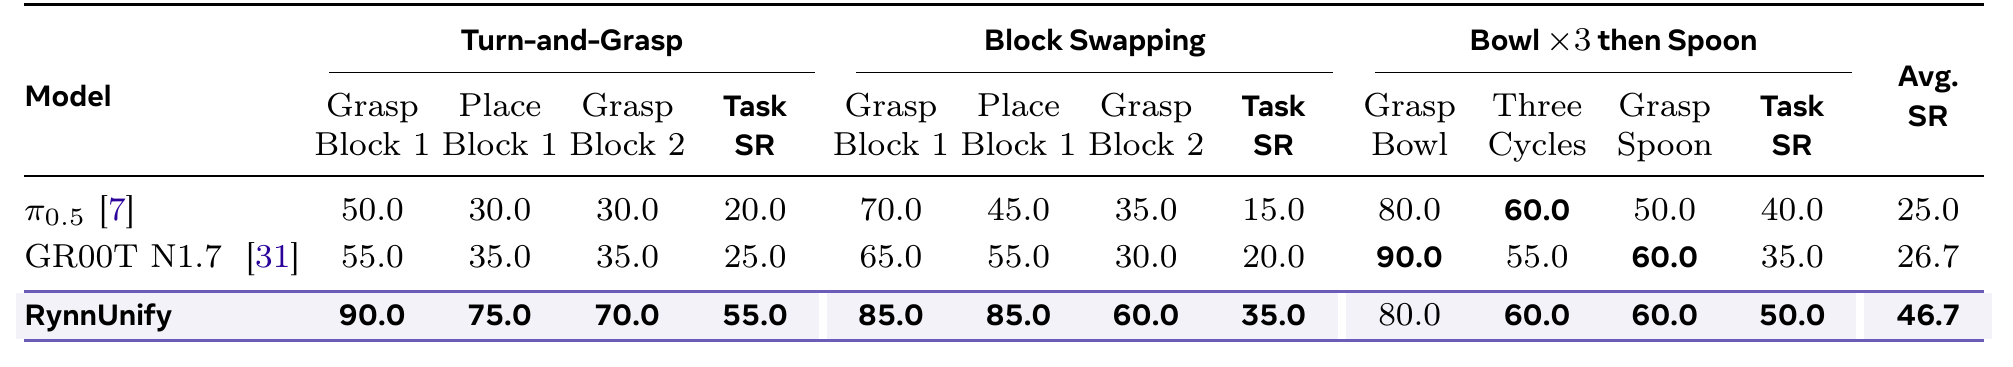
Real-Robot Evaluation on Astribot S1
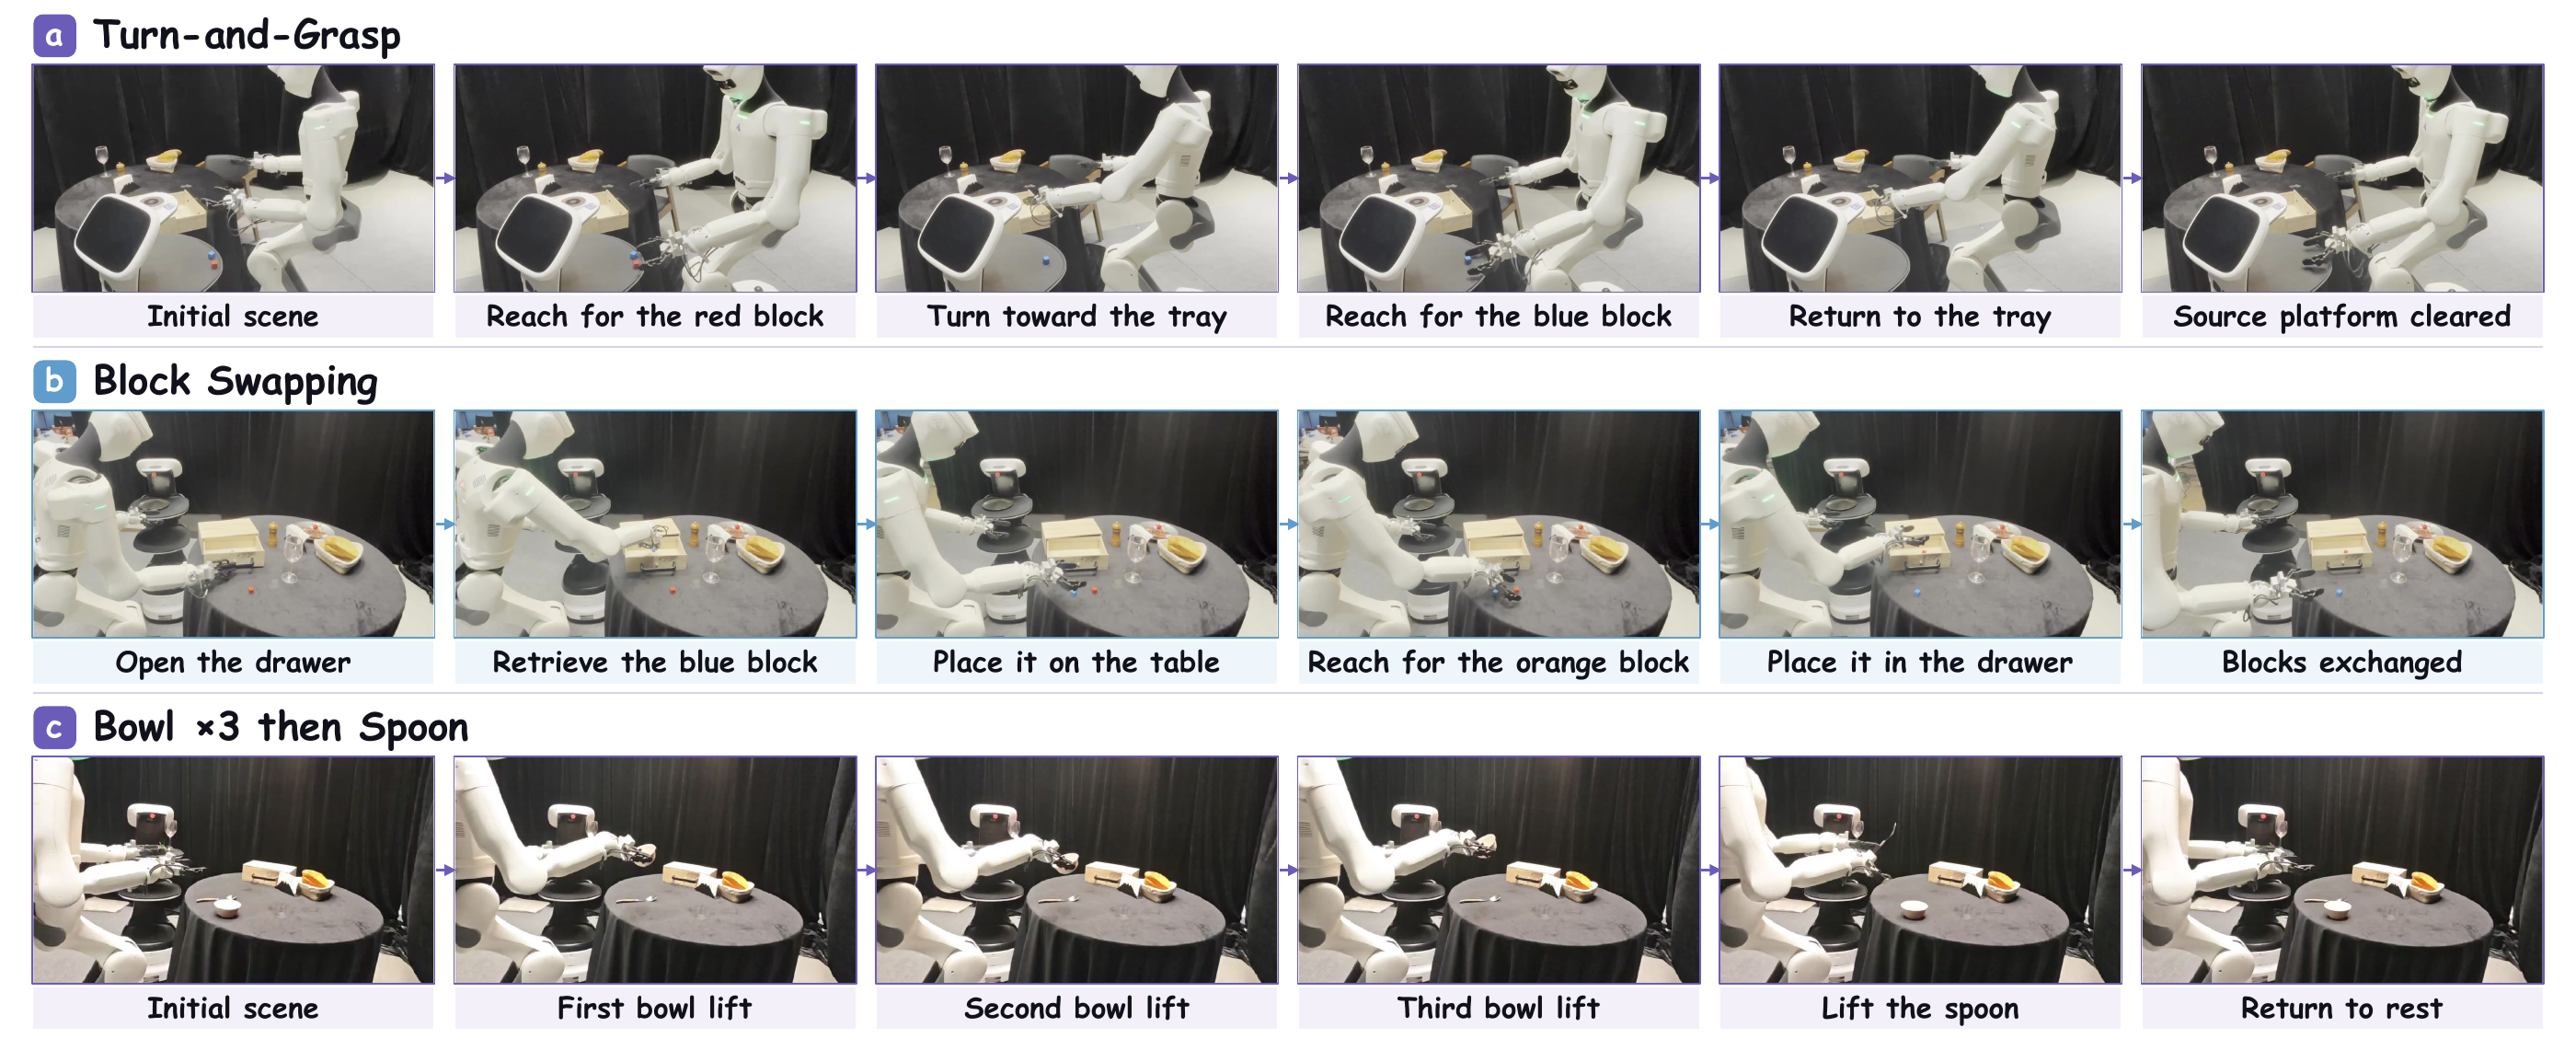
Real-Robot Execution Examples
| Model | Base Model | HuggingFace | ModelScope |
|---|---|---|---|
| RynnUnify-Base | Cosmos3 Nano | Link | Link |
| RynnUnify-Agentic-Reasoner | RynnUnify-Base | Link | Link |
| RynnUnify-WAM-RoboCasa | RynnUnify-Base | Link | Link |
Run each workflow from the repository root. Use separate environments for Agentic RL and Visual Planning, with Linux, CUDA-compatible PyTorch and compatible checkpoints.
Please refer to RynnScale for Reasoner SFT and cosmos-framework for Generator training.
Install the BCPO package in a separate environment:
cd BCPO
python3 -m venv .venv
source .venv/bin/activate
python -m pip install -e '.[train,eval,serve]'
Prepare a compatible Reasoner checkpoint, training/evaluation JSONL, and a frozen Generator service. Start a Judge service for text / mess tasks; see service setup. Then train and evaluate:
CUDA_VISIBLE_DEVICES=0 \
REASONER_MODEL=/path/to/reasoner \
TRAIN_DATA=/path/to/train.jsonl EVAL_DATA=/path/to/eval.jsonl \
GENERATOR_URL=http://127.0.0.1:18900/generate_video \
JUDGE_URL=http://127.0.0.1:8001/v1 JUDGE_MODEL=judge \
RUN_DIR=runs/bcpo BATCH_SIZE=1 bash scripts/train_and_evaluate.sh
Use a new RUN_DIR for each run. The script validates data, trains the Reasoner, then evaluates train/final/ and writes results to eval/. Omit the Judge variables for tasks that do not need it. Start with BATCH_SIZE=1 and adjust for available memory; each question produces eight trajectories. See training options.
Prepare the compatible Cosmos framework, a checkpoint with a visual Reasoner, and an episode JSONL with your input images. See setup and data format.
cd VisualPlan
CHECKPOINT_PATH=/path/to/compatible/hf_export \
TEST_DATA=/path/to/episodes.jsonl \
OUTPUT_DIR="$PWD/outputs/demo" \
NPROC_PER_NODE=1 bash run_interleave.sh
Add DRY_RUN=1 to inspect the command without loading models. Results include generated clips, a stitched rollout and JSON summaries.
Please refer to RynnScale for embodied understanding and reasoning evaluation using the Reasoner from RynnUnify-Base, and to the BCPO evaluation guide for Agentic Interleaved Thinking evaluation.
@article{damo2026rynnunify,
  title={RynnUnify: Towards Unified Embodied Brain},
  author={Minghao Zhu and Bohan Hou and Kun Xiang and
          Zixuan Wang and Yinzhou Tang and Yifei Yang and
          Zhikai Wang and Tianyi Zhang and Kehan Li and
          Haoyu Zhao and Siteng Huang and Leigang Qu and
          Sicong Leng and Dongchi Huang and Mingxiu Chen and
          Shijian Lu and Yue Wang and Xiaodan Liang and
          Zhenyu Zeng and Deli Zhao and Chengju Liu and
          Jianfei Yang and Xin Li},
  journal={arXiv preprint arXiv:2610.32965},
  year={2026},
  url={https://arxiv.org/abs/2610.32965}
}