| --- |
| license: apache-2.0 |
| language: |
| - en |
| - zh |
| pipeline_tag: text-generation |
| tags: |
| - causal-lm |
| - hybrid-attention |
| - linear-attention |
| - gated-deltanet |
| - attention-residual |
| - bpe |
| --- |
| |
| # MotifChord-Base |
|
|
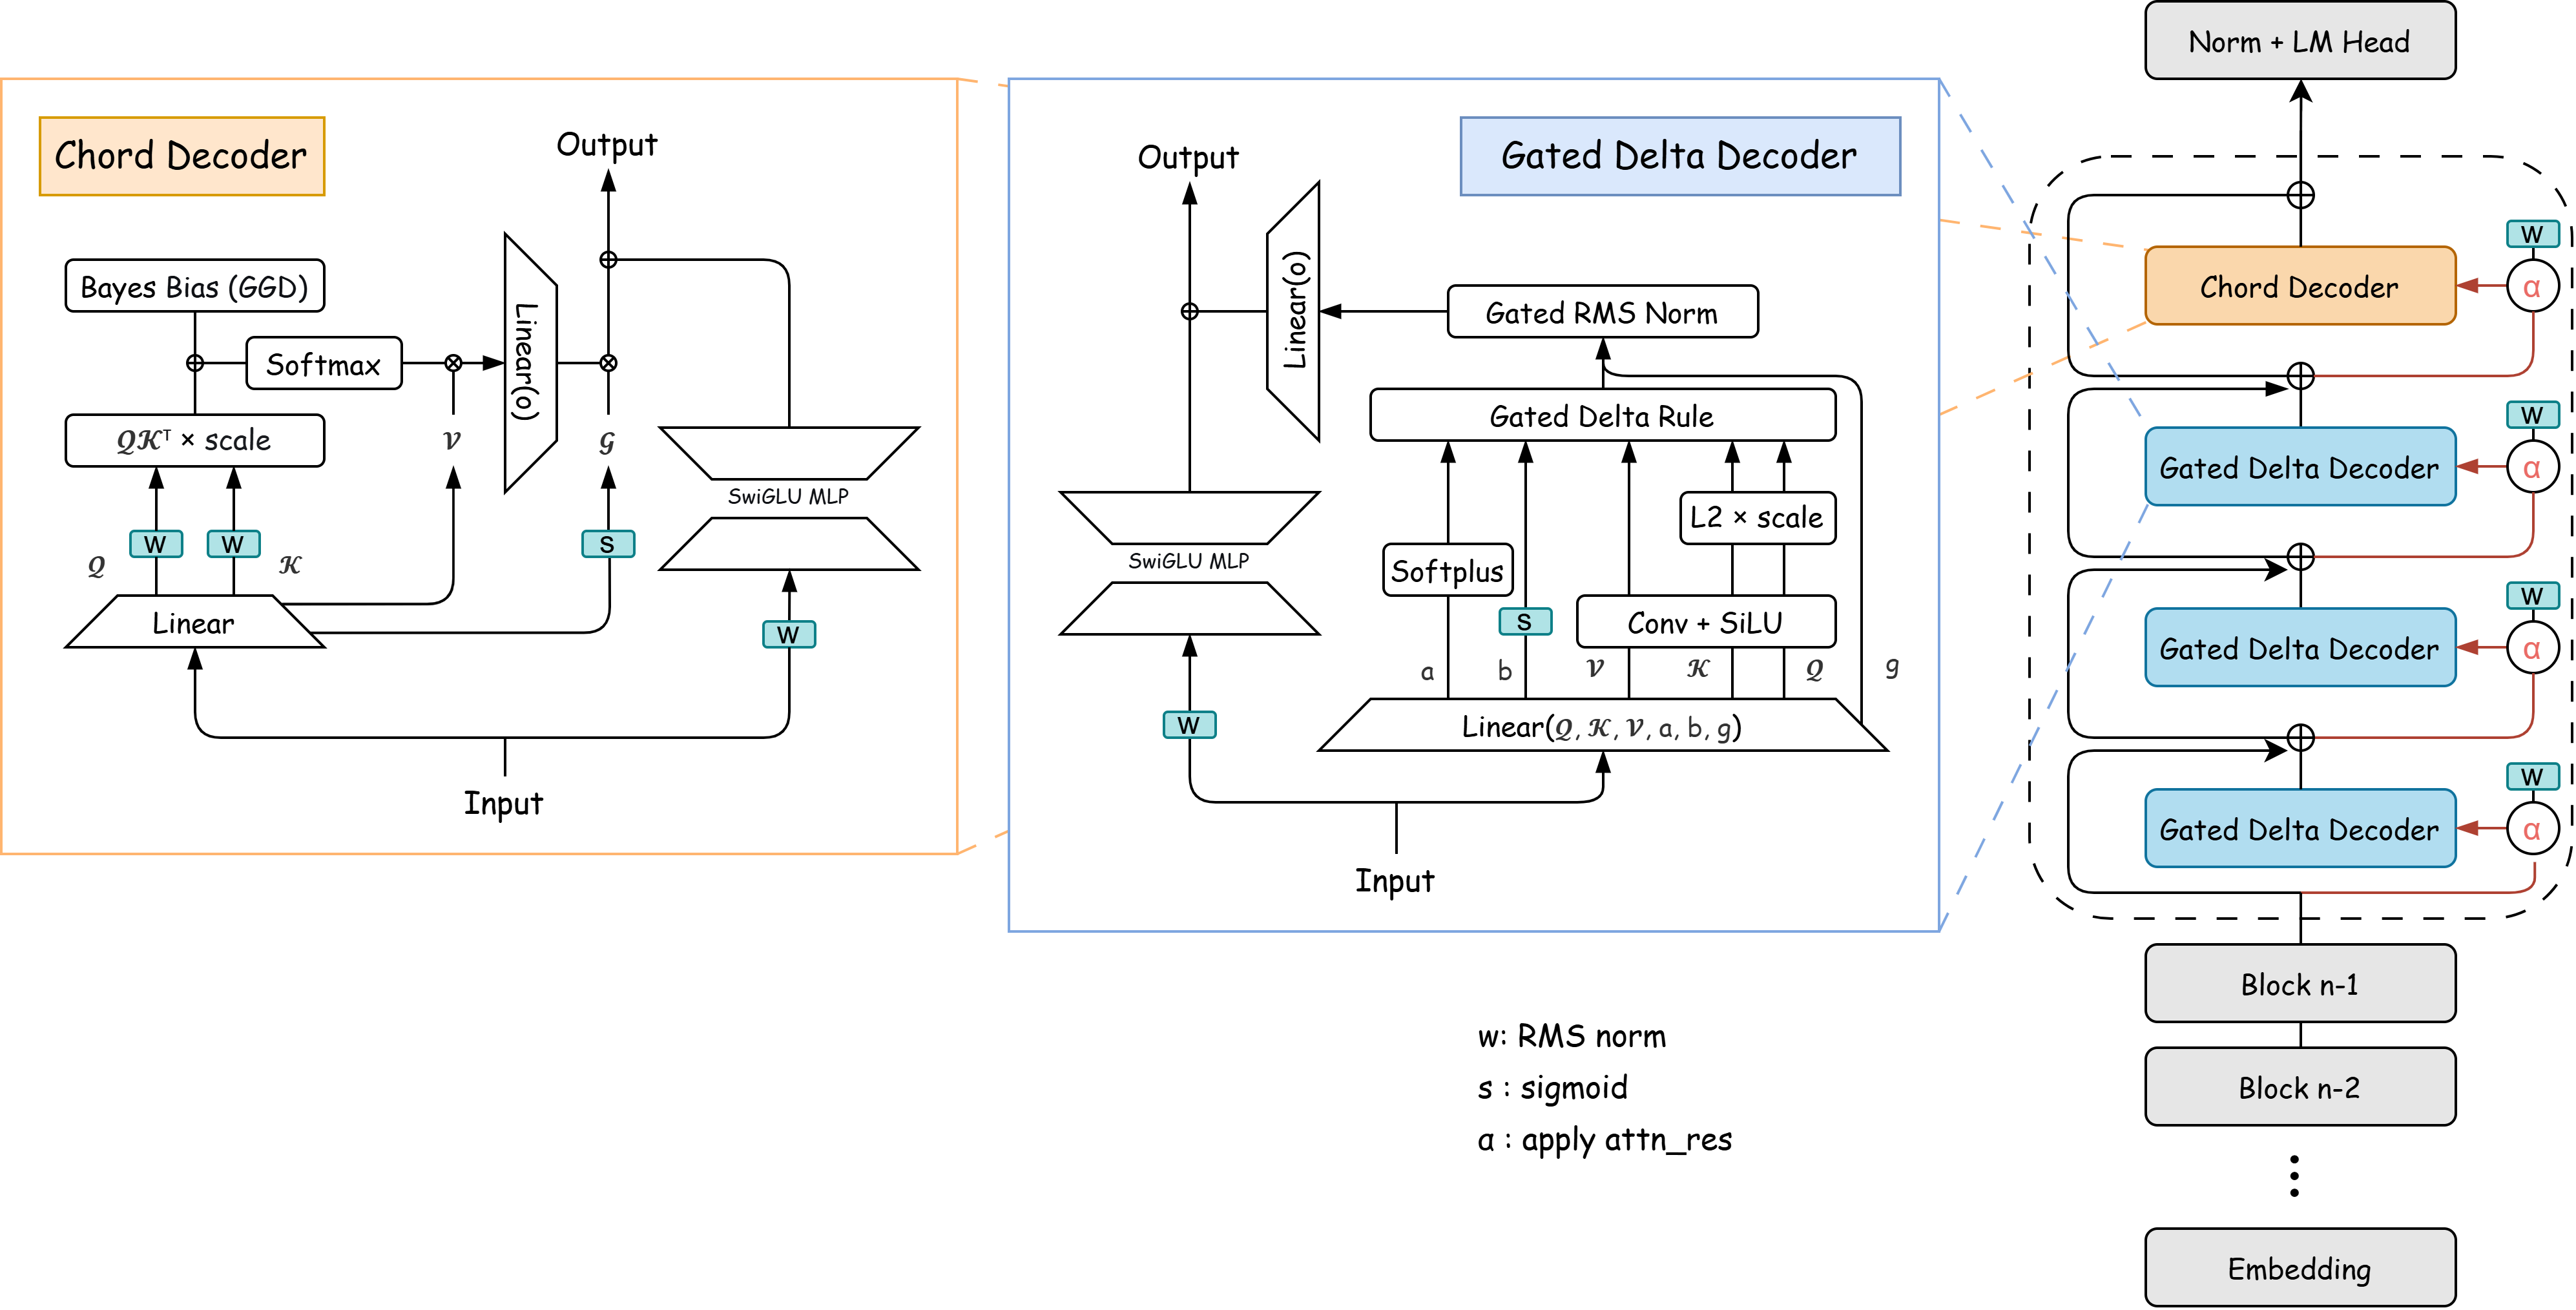
| MotifChord-Base is a 172 M parameter decoder-only causal language model built around two ideas: a 3:1 hybrid of linear-time gated delta-net layers and exact chord attention, and a learned attention residual inside every block instead of a fixed additive one. It is small enough to run on a CPU or a single consumer GPU. |
|
|
|  |
|
|
| ## Model details |
|
|
| | Field | Value | |
| | :--- | :--- | |
| | Architecture | Decoder-only causal LM, hybrid gated delta-net + chord attention, intra-block attention residual | |
| | Embedding | 40,960 × 768, tied to the output head | |
| | Layers | 4 blocks × 4 sub-layers = 16 layers; each block holds 3 gated delta-net layers and 1 chord layer | |
| | Attention heads | 12 query heads / 3 kv heads (GQA); key head dim 64 for the gated delta-net, value expansion 2 | |
| | Context | Trained in stages from 1024 up to 4096 tokens; the inference cache has no fixed limit | |
| | License | Apache-2.0 | |
| | Source | <https://github.com/CodonProject/codon-motif> | |
|
|
| ## Architecture |
|
|
| The stack is an embedding, four blocks and a final RMSNorm + LM head. Inside a block, four sub-layers run in sequence; each one is a parallel attention-and-MLP residual, `x = x + attn(norm(x)) + mlp(norm(x))`, 768 wide, with a SwiGLU MLP. |
|
|
| - **Gated delta-net** carries three of the four sub-layers with a linear-time chunked recurrence. Its state is a fixed-size matrix, so the memory a long sequence costs does not grow with its length. A short causal convolution (Conv1d + SiLU) sits in front of q, k and v. |
| - **Chord attention** is exact softmax attention whose scores carry a gated geometric-decay bias, `-alpha * (|d - mu| + eps) ** beta`, with `alpha`, `beta` and `mu` learnable per head (`mu` is frozen). This stands in for RoPE — a Bayesian positional prior at the cost of a few parameters per head, and no position table to extend. |
| - **Intra-block attention residual** makes each sub-layer read the outputs of the earlier sub-layers in the same block through a learnable query vector and an RMSNorm, instead of the fixed `x + f(x)`. It is the lightweight intra-block form of Attention Residuals (Kimi Team), not a global aggregation across blocks. A fused Triton kernel implements the read, with an eager fallback when a call does not qualify. In the figure, `w` marks an RMSNorm, `s` a sigmoid gate and `a` an attn-res read. |
|
|
| The architecture follows Gated DeltaNet (Yang et al., 2025), Attention Residuals (Kimi Team, 2026), the Bayesian Attention Mechanism (Bianchessi et al., 2026) and the Qwen3 hybrid-attention recipe. |
|
|
| ## Intended use |
|
|
| - **Primary**: text completion and continuation with the base weights; research on hybrid attention, linear-attention recurrence and attention residuals; a small local model for CPU or single-GPU experiments. |
| - **Out of scope**: instruction following, chat, tool use, retrieval, safety-critical or production decisions, and any use that treats the output as factual. The weights have had **no** instruction tuning and **no** alignment; the model continues text, which includes continuing it badly. |
|
|
| Post-training and a chat template exist for development, but no chat checkpoint is released. With these weights, use plain text completion. |
|
|
| ## How to use |
|
|
| ```bash |
| pip install codon-motif |
| ``` |
|
|
| ```python |
| from motif.model import MotifChordModel, Sampler, TextGeneration |
| from motif.tokenizer.tokenizer import PackedTokenizer |
| |
| tokenizer = PackedTokenizer('tokenizer.zip') # shipped in the repository root |
| model = MotifChordModel.from_pretrained('MotifChord-Base.safetensors').eval() |
| |
| generation = TextGeneration( |
| model, |
| tokenizer, |
| 'The capital of France is', |
| max_new_tokens=64, |
| sampler=Sampler(temperature=0.0), # greedy |
| ) |
| print(generation.run().text) |
| ``` |
|
|
| `from_pretrained` accepts a safetensors file or shard directory (with an optional `config.json` sidecar), a bare PyTorch state dict, and the training checkpoints written by this project's pipelines. When a file carries no config, the hyper-parameters are recovered from the tensor shapes. |
|
|
| ### Sampling |
|
|
| `Sampler(temperature=0.0)` is deterministic: the temperature is clamped to `1e-5`, so the multinomial collapses onto the top token. Note that the repetition penalty still applies at temperature 0 (`repetition_penalty=1.15` by default); pass `repetition_penalty=1.0` as well for a plain argmax. For sampled text, `temperature` in 0.7-1.0 with `top_k=50` or `top_p=0.9` is a reasonable starting point. |
|
|
| ### Prompt format |
|
|
| The base weights were trained on raw text, so a plain prefix is the right prompt. The chat template (`<|im_start|>`, `<|thought_start|>`, effort tokens, `<|tool_call_start|>`, ...) occupies 256 reserved special-token slots in the vocabulary; using it with the base weights is not meaningful. |
|
|
| ## Training |
|
|
| | Field | Value | |
| | :--- | :--- | |
| | Tokens | 13.78 B | |
| | Steps | 4,042,962 (the last checkpoint records `step = 4042960`) | |
| | Sequence length | 1024 → 2048 → 4096, progressive | |
| | Hardware | one 32 GB consumer GPU | |
| | Final loss | cross-entropy ≈ 2.9 on the pretraining mixture | |
|
|
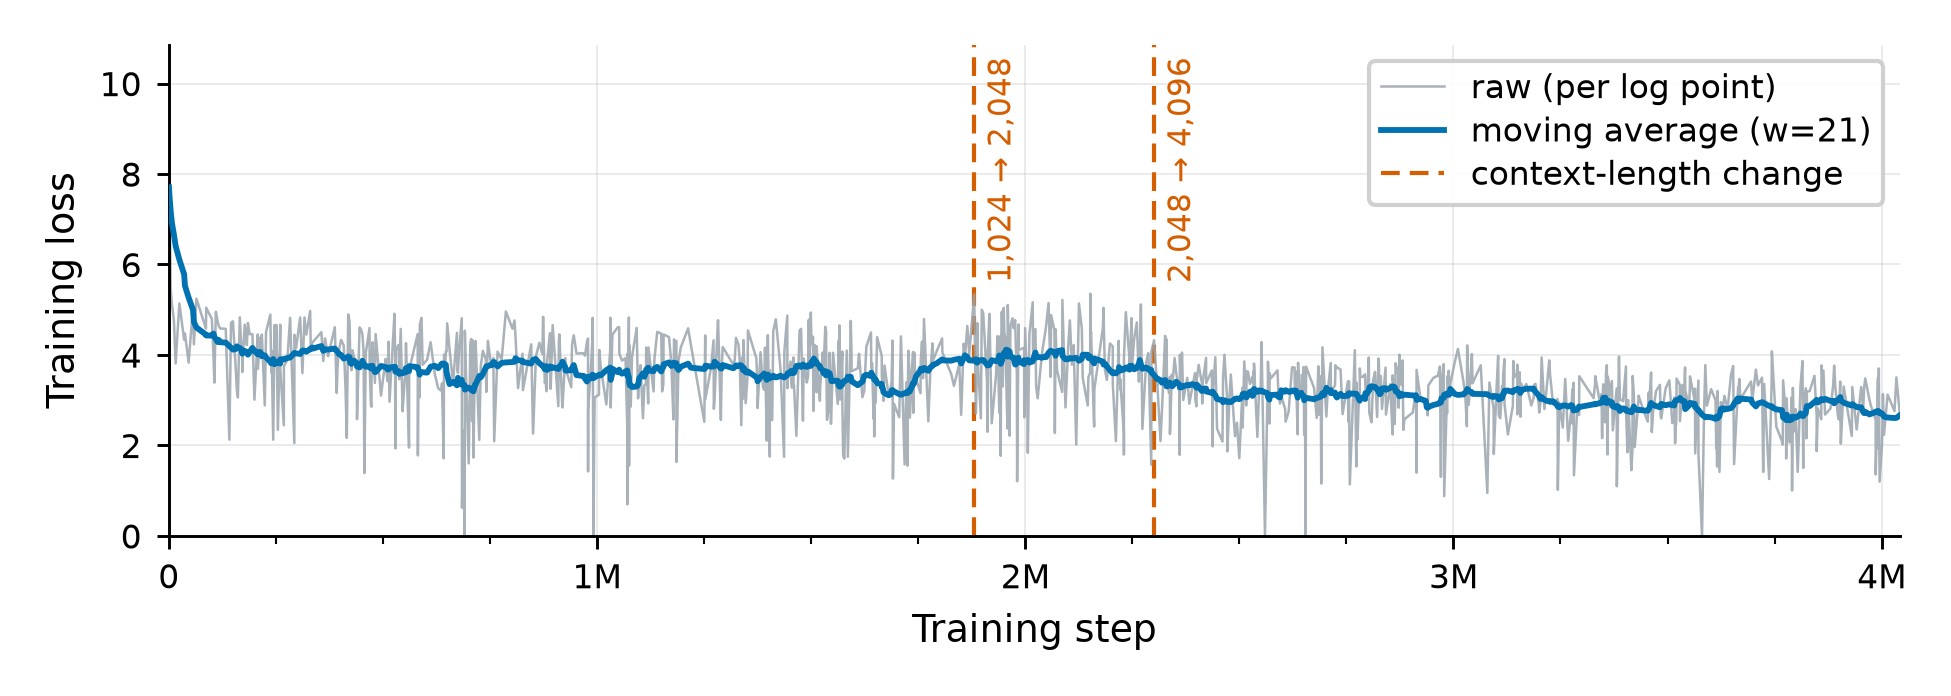
| The stages the published curve marks with dashed lines: |
|
|
| | Stage | Sequence length | Batch size | Tokens | Steps | Ends at step | |
| | :--- | :--- | :--- | :--- | :--- | :--- | |
| | Foundation | 1024 | 4 | 5.77 B | 1,877,825 | 1,877,825 | |
| | Expansion | 2048 | 2 | 0.86 B | 422,048 | 2,299,873 | |
| | Stabilization | 4096 | 1 | 7.14 B | 1,743,089 | 4,042,962 | |
|
|
| Training loss, raw per log point and as a 21-point moving average, with the two context-length changes marked: |
|
|
|  |
|
|
| Pretraining data: **UltraData-Code**, **arXiv Complete**, **WMT17 Zh-En**, **Nemotron-CC-Math-v1**, **Ultra-FineWeb-L3** (citations in the repository README). No data filtering, deduplication or contamination analysis is published, and no evaluation benchmark suite was run. |
|
|
| ## Evaluation |
|
|
| No task benchmark (held-out perplexity, MMLU, HellaSwag, ...) has been run. What is published is the training loss above: |
|
|
| - The 21-point moving average ends around 2.4-2.5 at 4M steps, the last logged value stored in the checkpoint metadata is 2.9288, and the training notes describe convergence "near 2.8". The three differ because they are three different reductions of a noisy curve; the raw per-log-point value fluctuates widely. |
| - A cross-entropy of 2.9 over a 40,960-token vocabulary is a perplexity of roughly 18. |
|
|
| For speed, one RTX 5070 Laptop GPU reaches a steady state of ≈ 34 tokens/s for batched greedy generation after the first steps (a cold start, including the checkpoint load, is a few tokens/s). These are single-machine numbers on a laptop GPU; treat them as an order of magnitude, not a guarantee. |
|
|
| ## Limitations |
|
|
| - **Not a chat model.** No instruction tuning or alignment; it continues text, and a question gets a continuation rather than an answer. |
| - **Unaudited data.** The mixture is large and web-derived. The model can and will reproduce biases, stereotypes, personal information and toxic or illegal content present in the data, mainly in English and Chinese. |
| - **No factuality or safety evaluation.** No red-teaming, no guardrails, no refusal behaviour. |
| - **Weak long-context guarantees.** Training only reached 4096 tokens. The gated delta-net state is fixed size, so long contexts degrade rather than error, but quality beyond the training length is not measured. |
| - **No comparison against comparable models.** The 3:1 hybrid recipe and the intra-block residual are engineering choices validated by a loss curve, not by ablation against published baselines. |
| - **Tokenizer coverage.** The vocabulary was trained on the pretraining mixture; code and low-resource languages tokenize worse than the domains it saw most. |
|
|
| ## Environmental impact |
|
|
| One 32 GB consumer GPU; no cluster, and no CO2 estimate is published. |
|
|
| ## Citation |
|
|
| ```bibtex |
| @misc{codonproject2026motifchord, |
| title = {MotifChord: Bayesian Positional Priors and Learned Attention Residuals}, |
| author = {CodonProject}, |
| year = {2026}, |
| howpublished = {\url{https://github.com/CodonProject/codon-motif}}, |
| note = {Model release MotifChord-Base} |
| } |
| ``` |
|
|
| ## Contact |
|
|
| Open an issue at <https://github.com/CodonProject/codon-motif/issues>. |
|
|


