

flm-models-XDNA2
Collection
Models built for AMD XDNA2 NPUs, runnable with FastFlowLM. • 57 items • Updated • 2
This repository is the NPU2 package of openbmb/MiniCPM-V-4.7-35B-A3B for FastFlowLM (FLM), which runs it on the XDNA 2 NPU of Ryzen™ AI 300 series and newer processors. The model, its licence (Apache-2.0) and its intended use are the upstream's; this repository only repackages the weights.
flm run   minicpm-v-4.7-moe:35b-a3b          # chat in the terminal
flm serve minicpm-v-4.7-moe:35b-a3b          # OpenAI-compatible server (images, tools, thinking on request)
Needs FastFlowLM 1.0.12 or later and about 22 GB of memory. Images (a view of the whole picture plus up to 9 tiles), tool calling, the prefix cache and a thinking switch (off by default, as the model card recommends) are supported; video and audio input are not.
| File | What it is |
|---|---|
model.q4nx |
language model: 256-expert MoE, Q4_K body, Q8_0 output head, BF16 embedding / norms / router / gate projections (21.0 GB) |
vision_weight.q4nx |
the SigLIP vision tower and projector, BF16 (1.1 GB) |
config.json, tokenizer.json, tokenizer_config.json, chat_template.jinja |
from the upstream checkpoint (chat template unchanged; thinking only when enable_thinking is true) |
From the llama.cpp release MiniCPM-V-4_7-35B-A3B-Q4_K_M.gguf and its mmproj-model-f16.gguf (GGUF repository revision cf943fbe),
converted with FLM_Q4NX_Converter (-f minicpm-v-35b-a3b), taking the token embedding and the output head from the BF16 checkpoint
(revision ee2d0a27) instead of the GGUF's quantized copies. Q4_K tensors are repacked as they are; the 61 tensors that the Q4_K_M keeps at
Q6_K (half of attn_v / ffn_down, some attn_qkv) are re-fitted to Q4_K; the output head becomes Q8_0; the two gate projections of every
linear-attention layer, which the engine reads as BF16, are dequantized.
Greedy decoding, no sampling. "BF16" is the upstream checkpoint run with Hugging Face Transformers on the CPU.
| Check | FastFlowLM (NPU) | llama.cpp Q4_K_M (same GGUF) | BF16 |
|---|---|---|---|
| GSM8K, first 100 test problems, thinking off | 98 / 100 | 97 / 100 | 99 / 100 |
| DocVQA, 50 validation questions, ANLS | 97.50 | 97.42 | 97.42 |
GSM8K allows up to 1024 new tokens. Paired with the BF16 model on those 100 problems the NPU build is 1.0 point lower (95 % confidence interval -2.4 to +4.4 points; 2 problems only BF16 solves, 1 only the NPU build). With 50–100 questions these numbers cannot tell a loss of a point or two from none; they show that nothing is broken. Token by token, on 14 fixed prompts (text, multi-turn, long context, tool call, thinking, one to five pictures), the quantized model follows the BF16 model's greedy answer to the end on 7 of the 12 prompts that can be compared word for word and departs from it on 5; llama.cpp's own Q4_K_M, run on the same prompts, departs on 6. The vision tower runs in bf16 on the NPU: on one multi-tile picture the same language model fed by a reference (fp32, CPU) tower stayed closer to the BF16 wording, and on the DocVQA questions above there is no measurable difference.
Ryzen™ AI MAX+ PRO 395, 128 GB, FastFlowLM 1.0.12, default power mode (one run; the NPU box is shared, expect ±15 %).
| Context | 1k | 2k | 4k | 8k | 16k | 32k |
|---|---|---|---|---|---|---|
| Prefill (tokens/s) | 148 | 219 | 278 | 288 | 284 | 269 |
| Decode (tokens/s, starting at that context) | 16.2 | 16.1 | 15.2 | 14.6 | 13.1 | 10.9 |
Time to first token with a picture and the prompt "Describe this image.": 7.8 s at 720p, 9.1 s at 1080p, 8.8 s at 2K, 8.4 s at 4K (larger pictures stop growing: at most 9 tiles).
GitHub · On-device results · Evaluation · Examples · Usage · Model weights · DSpark
MiniCPM-V 4.7 is the latest model in the MiniCPM-V series, available in a 35B-A3B variant, with 35B-A3B being the first MoE model in the MiniCPM-V series. It builds on the family's single-image, multi-image, and video understanding capabilities, combining stronger foundation capabilities with efficient visual encoding and on-device inference. Notable features of MiniCPM-V 4.7 include:
Model weights · Inference · Fine-tuning · Live demo · Local deployment · API · Cookbook
An MoE model can have far more total parameters than it activates for a single token, but its on-device storage requirements are not limited to those active parameters. Different tokens can select different experts at different layers, while device memory often cannot hold all expert weights. Without a latency constraint, weights can remain on SSD or other storage, be loaded as needed, and be released after computation. This makes large-model inference possible, but repeated loading stalls can make decoding too slow for real-time interaction.
Another approach is to restrict the pool of available experts. For example, fixing an expert subset for an entire prompt can reduce loading frequency, but limits subsequent token-level routing to that subset, potentially excluding experts the model would otherwise select and reducing its capabilities. The central goal is therefore smooth inference without compromising performance: preserving model capability while delivering sufficient throughput under limited memory and bandwidth.
MiniCPM-V 4.7 35B-A3B addresses this challenge through three complementary techniques:
Together, these techniques make MiniCPM-V 4.7 35B-A3B the first open-source MoE model to run smoothly on-device without compromising performance, achieving 13+ tokens/s on iPhone 17 Pro Max.
On-Device MoE Inference: Before and After Optimization
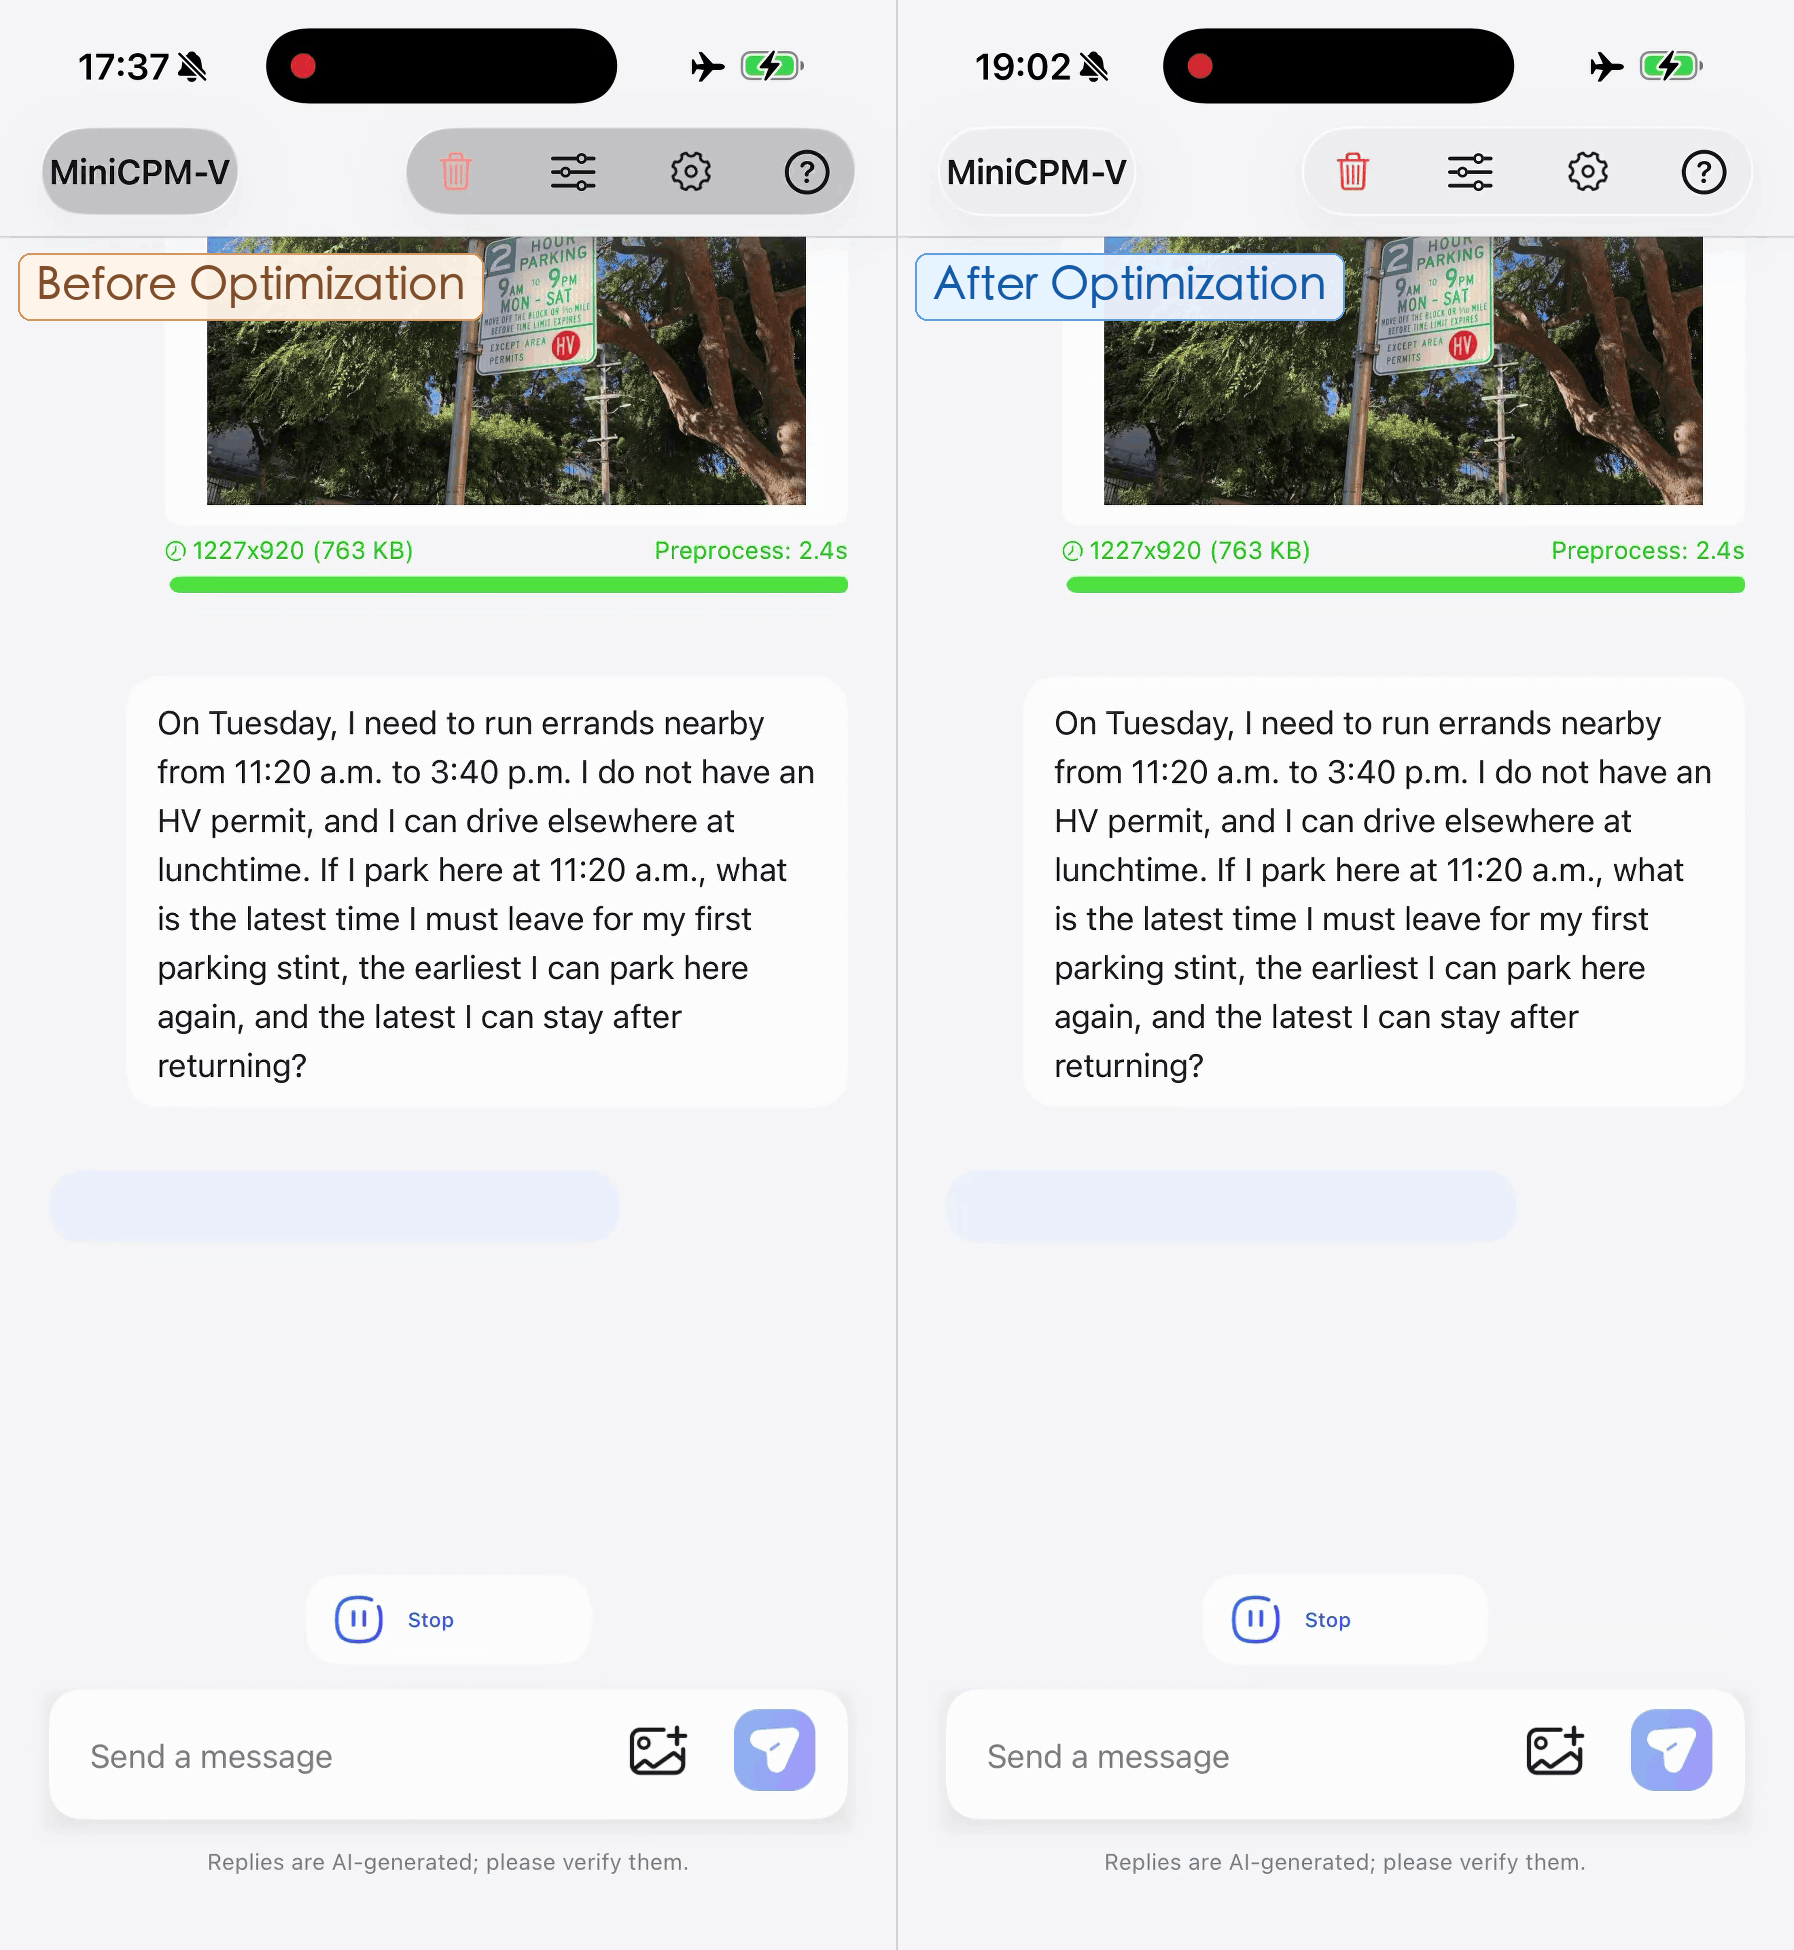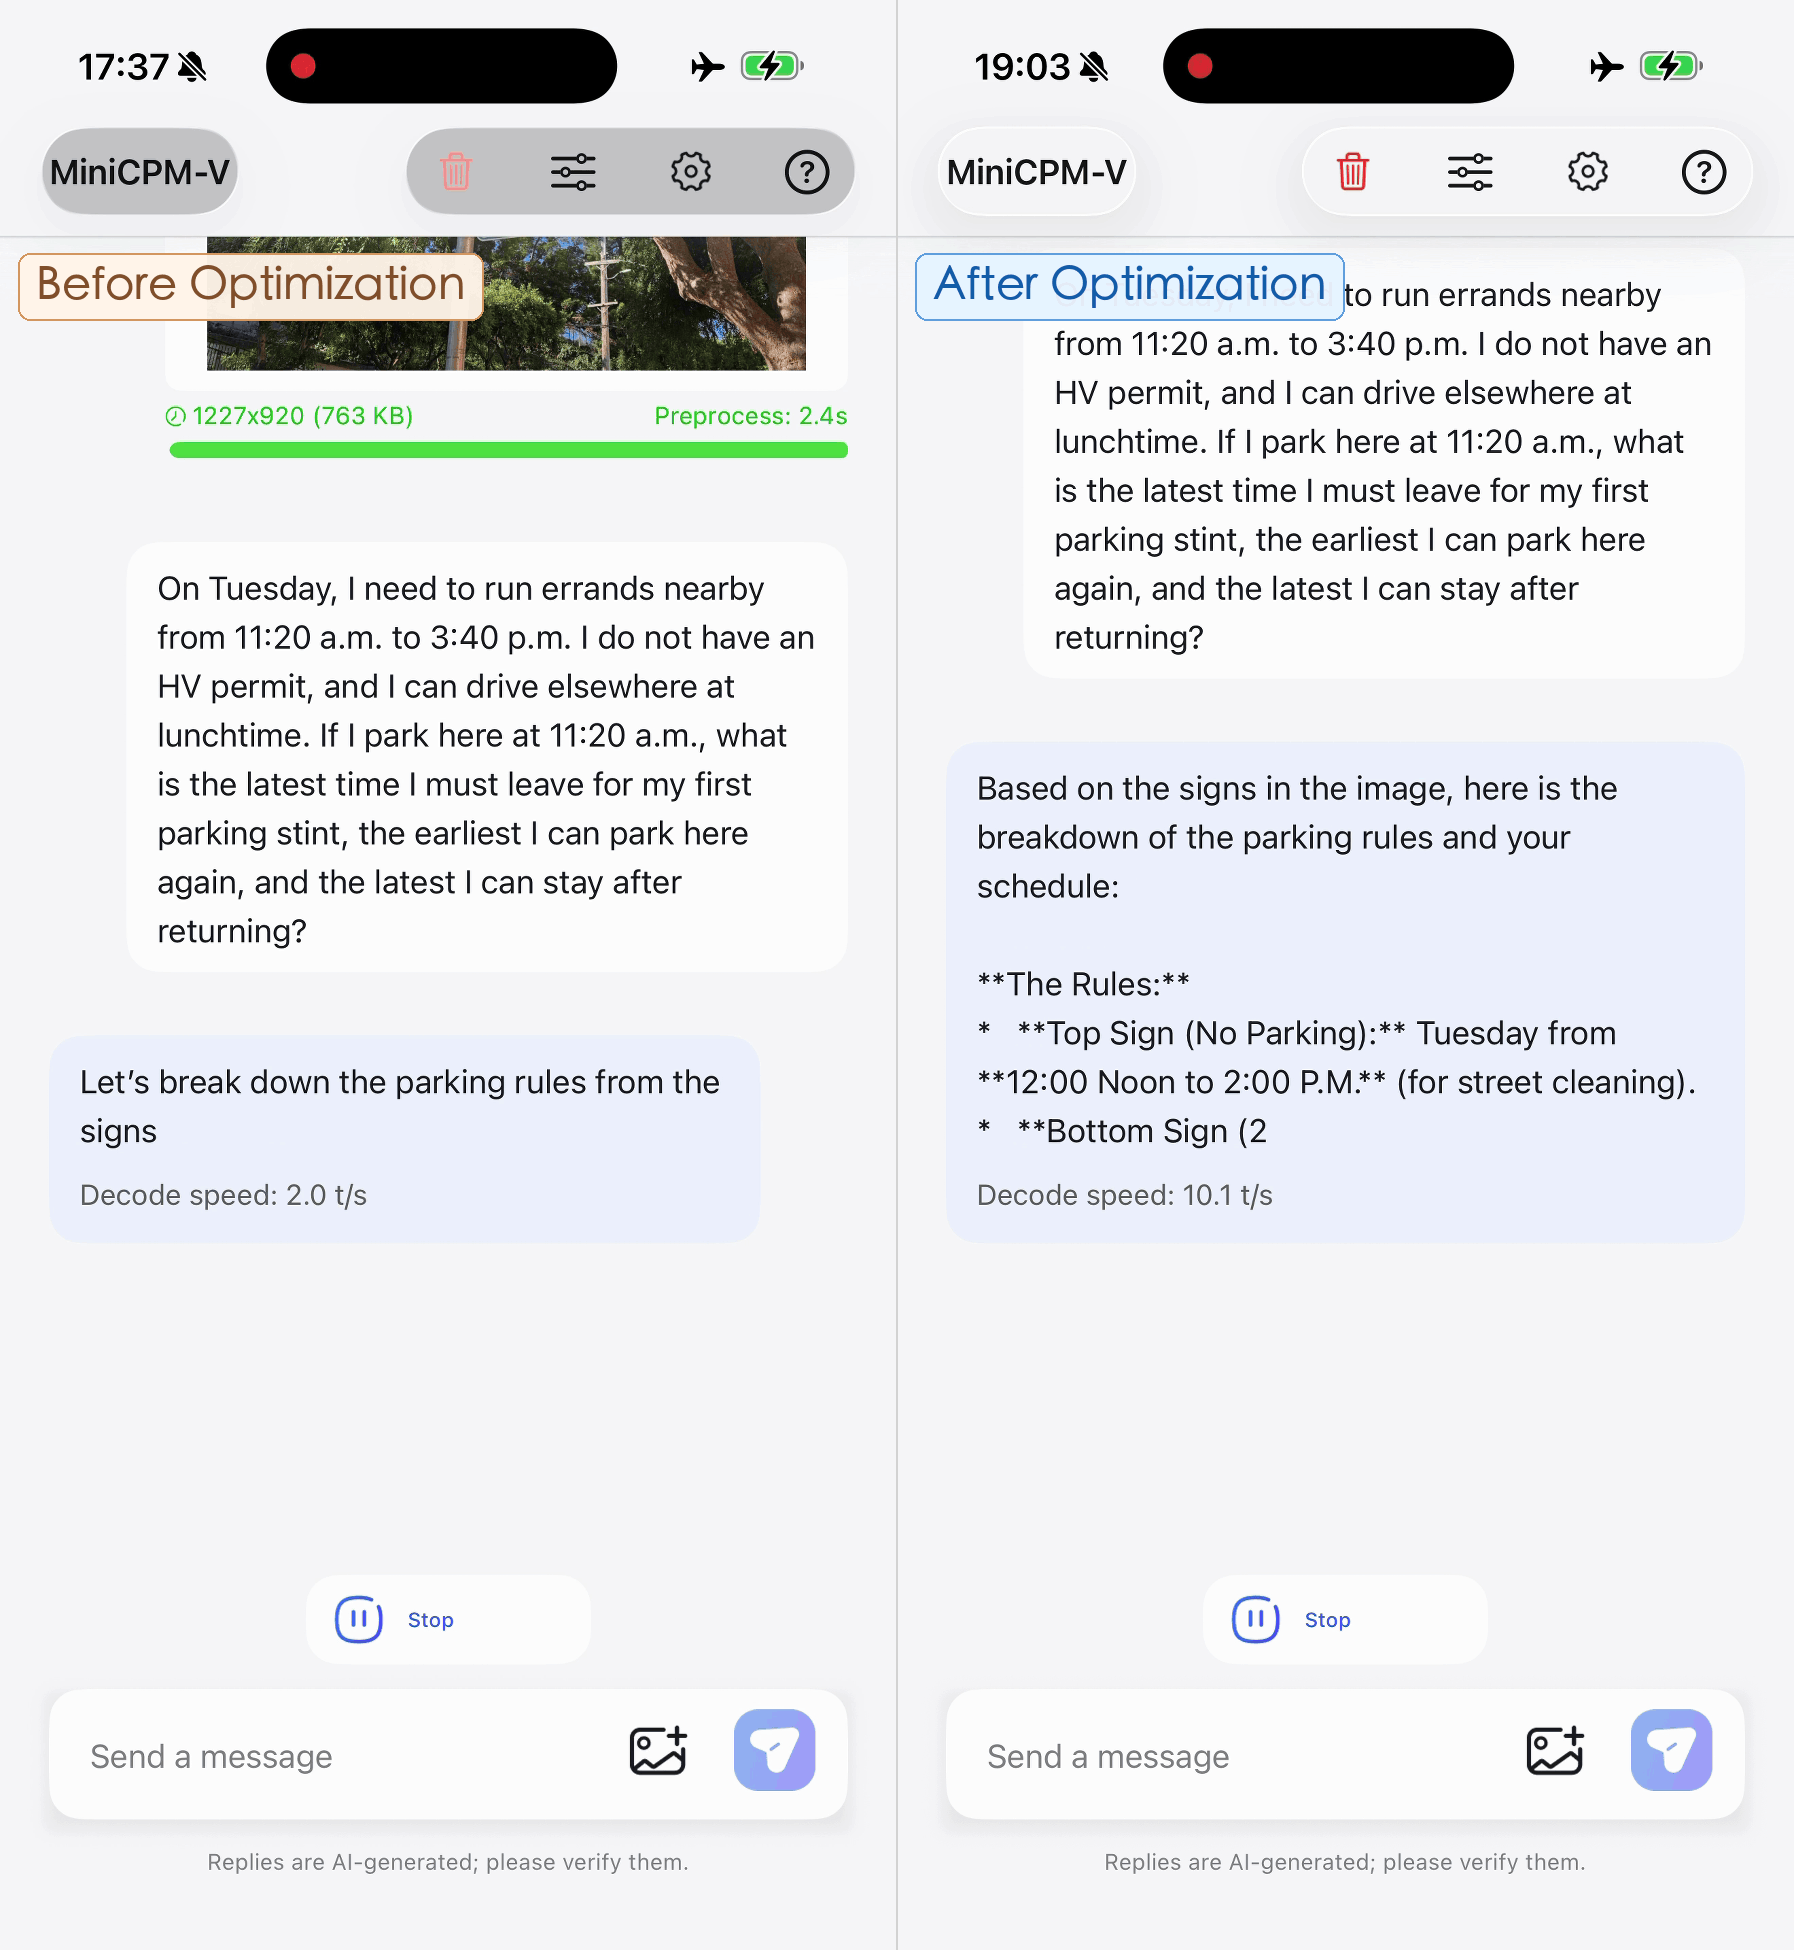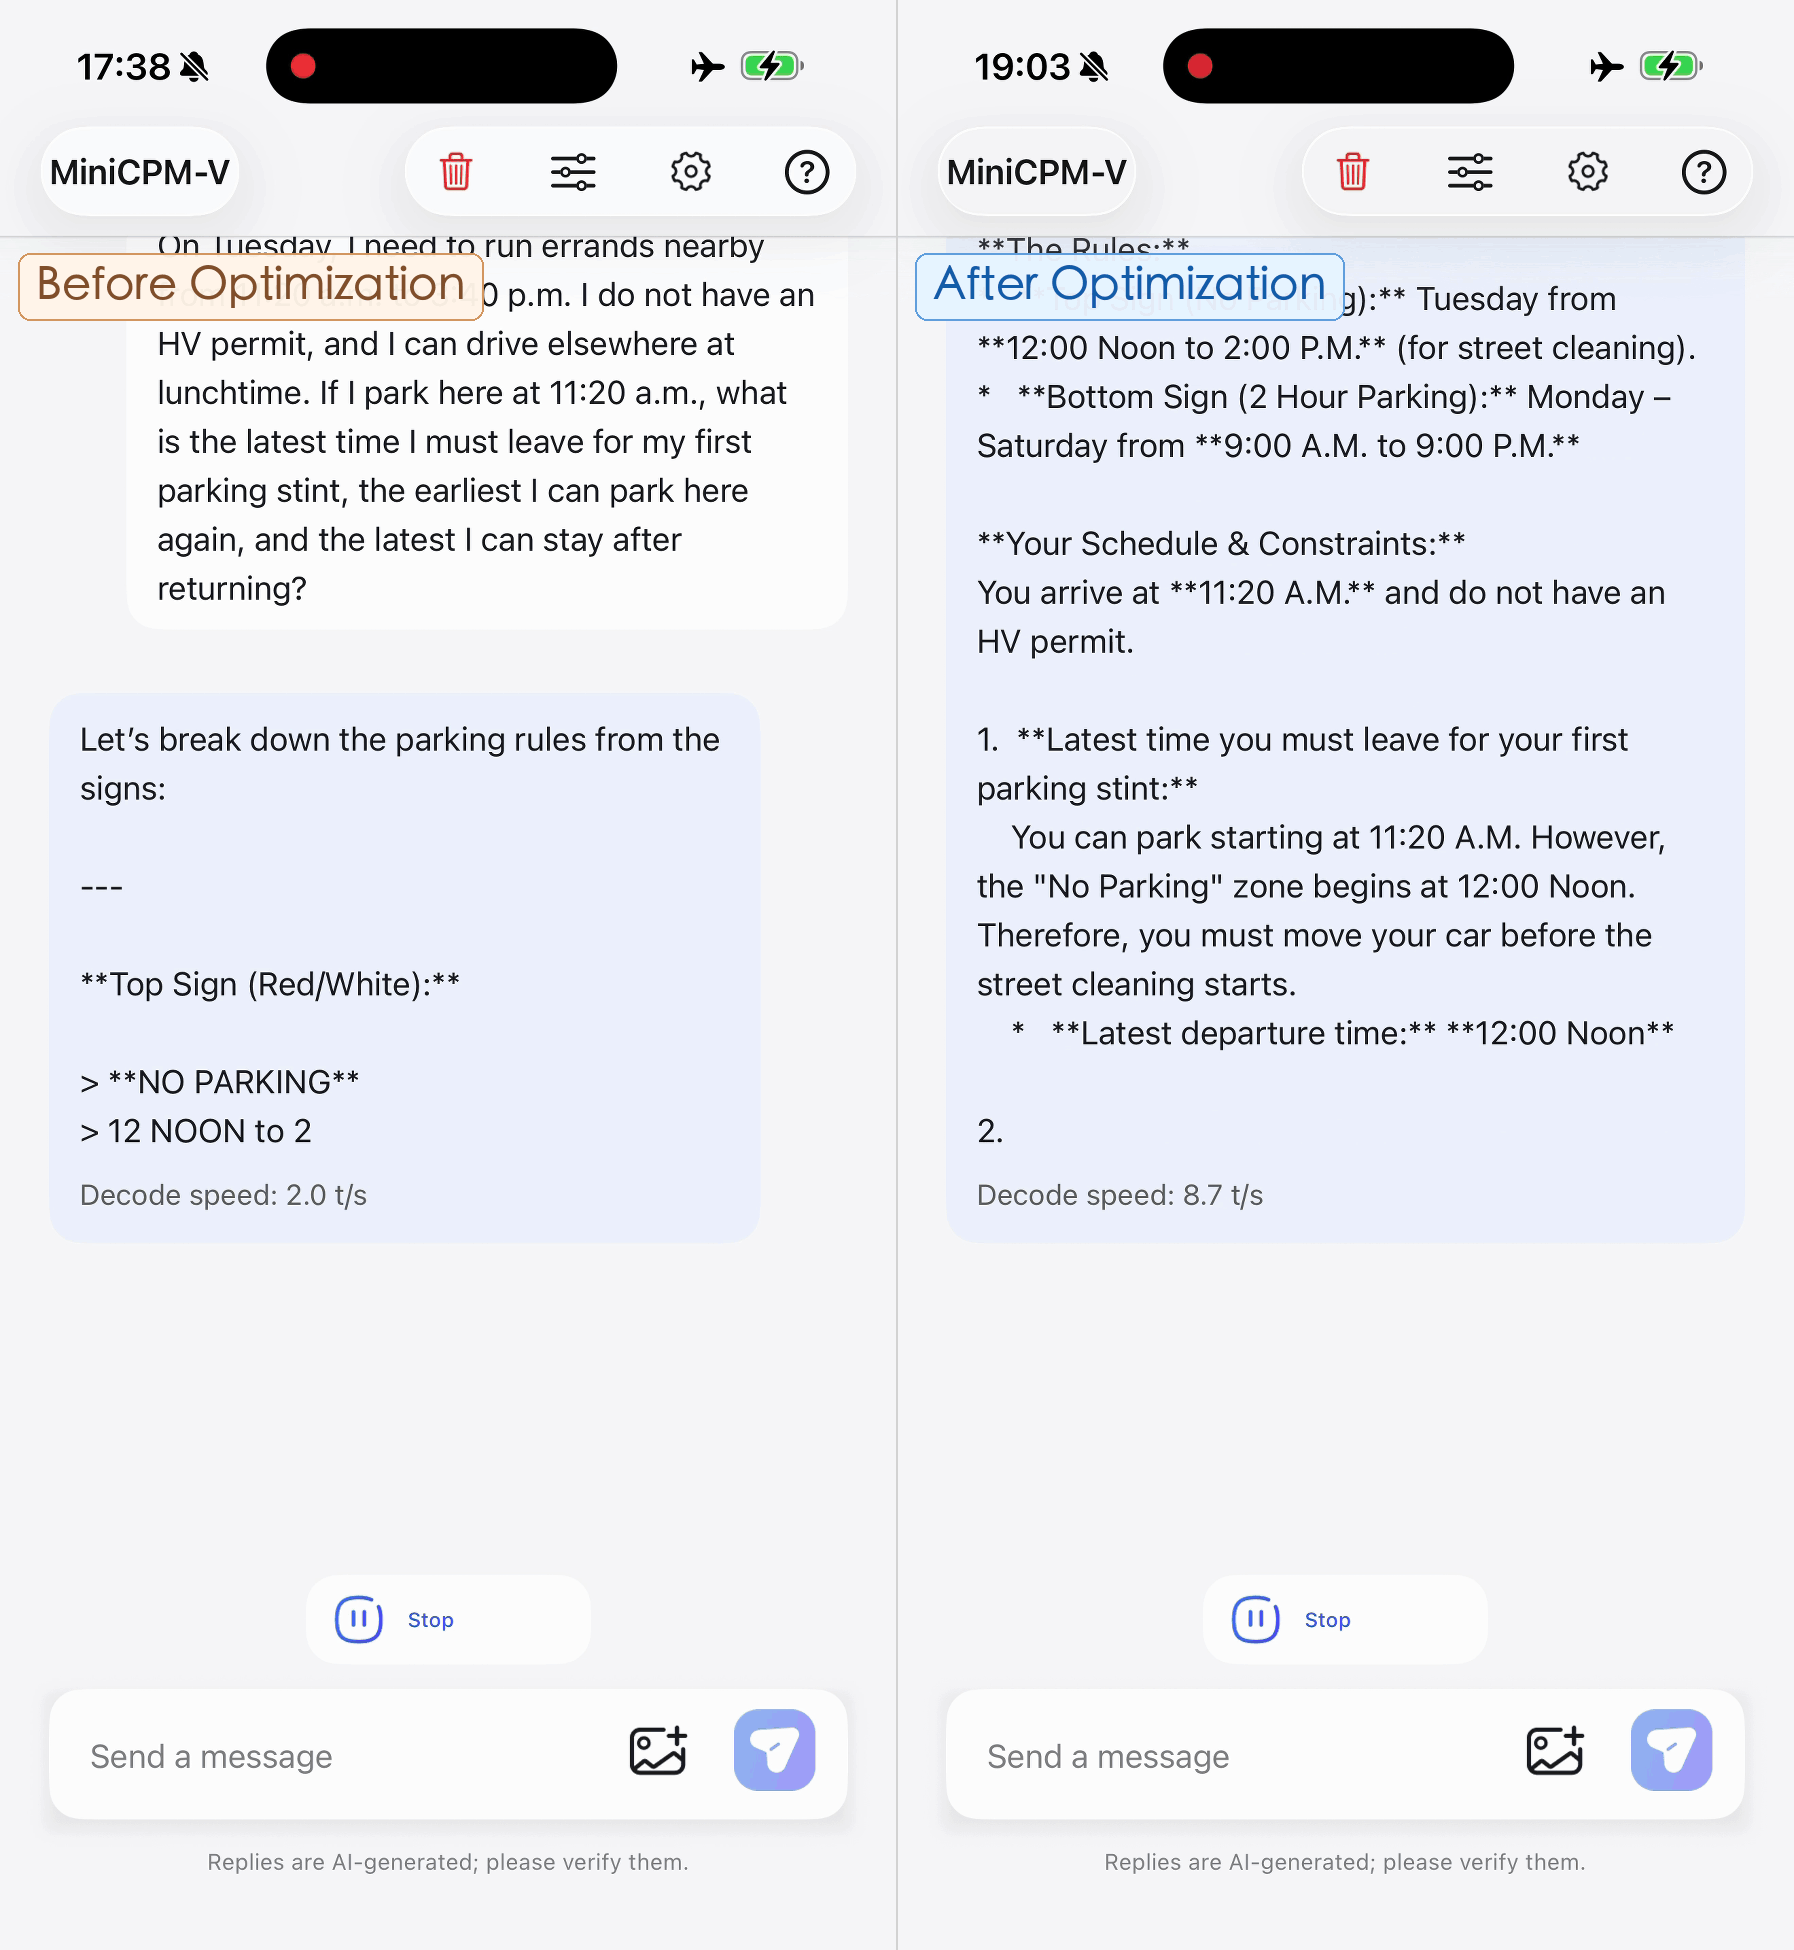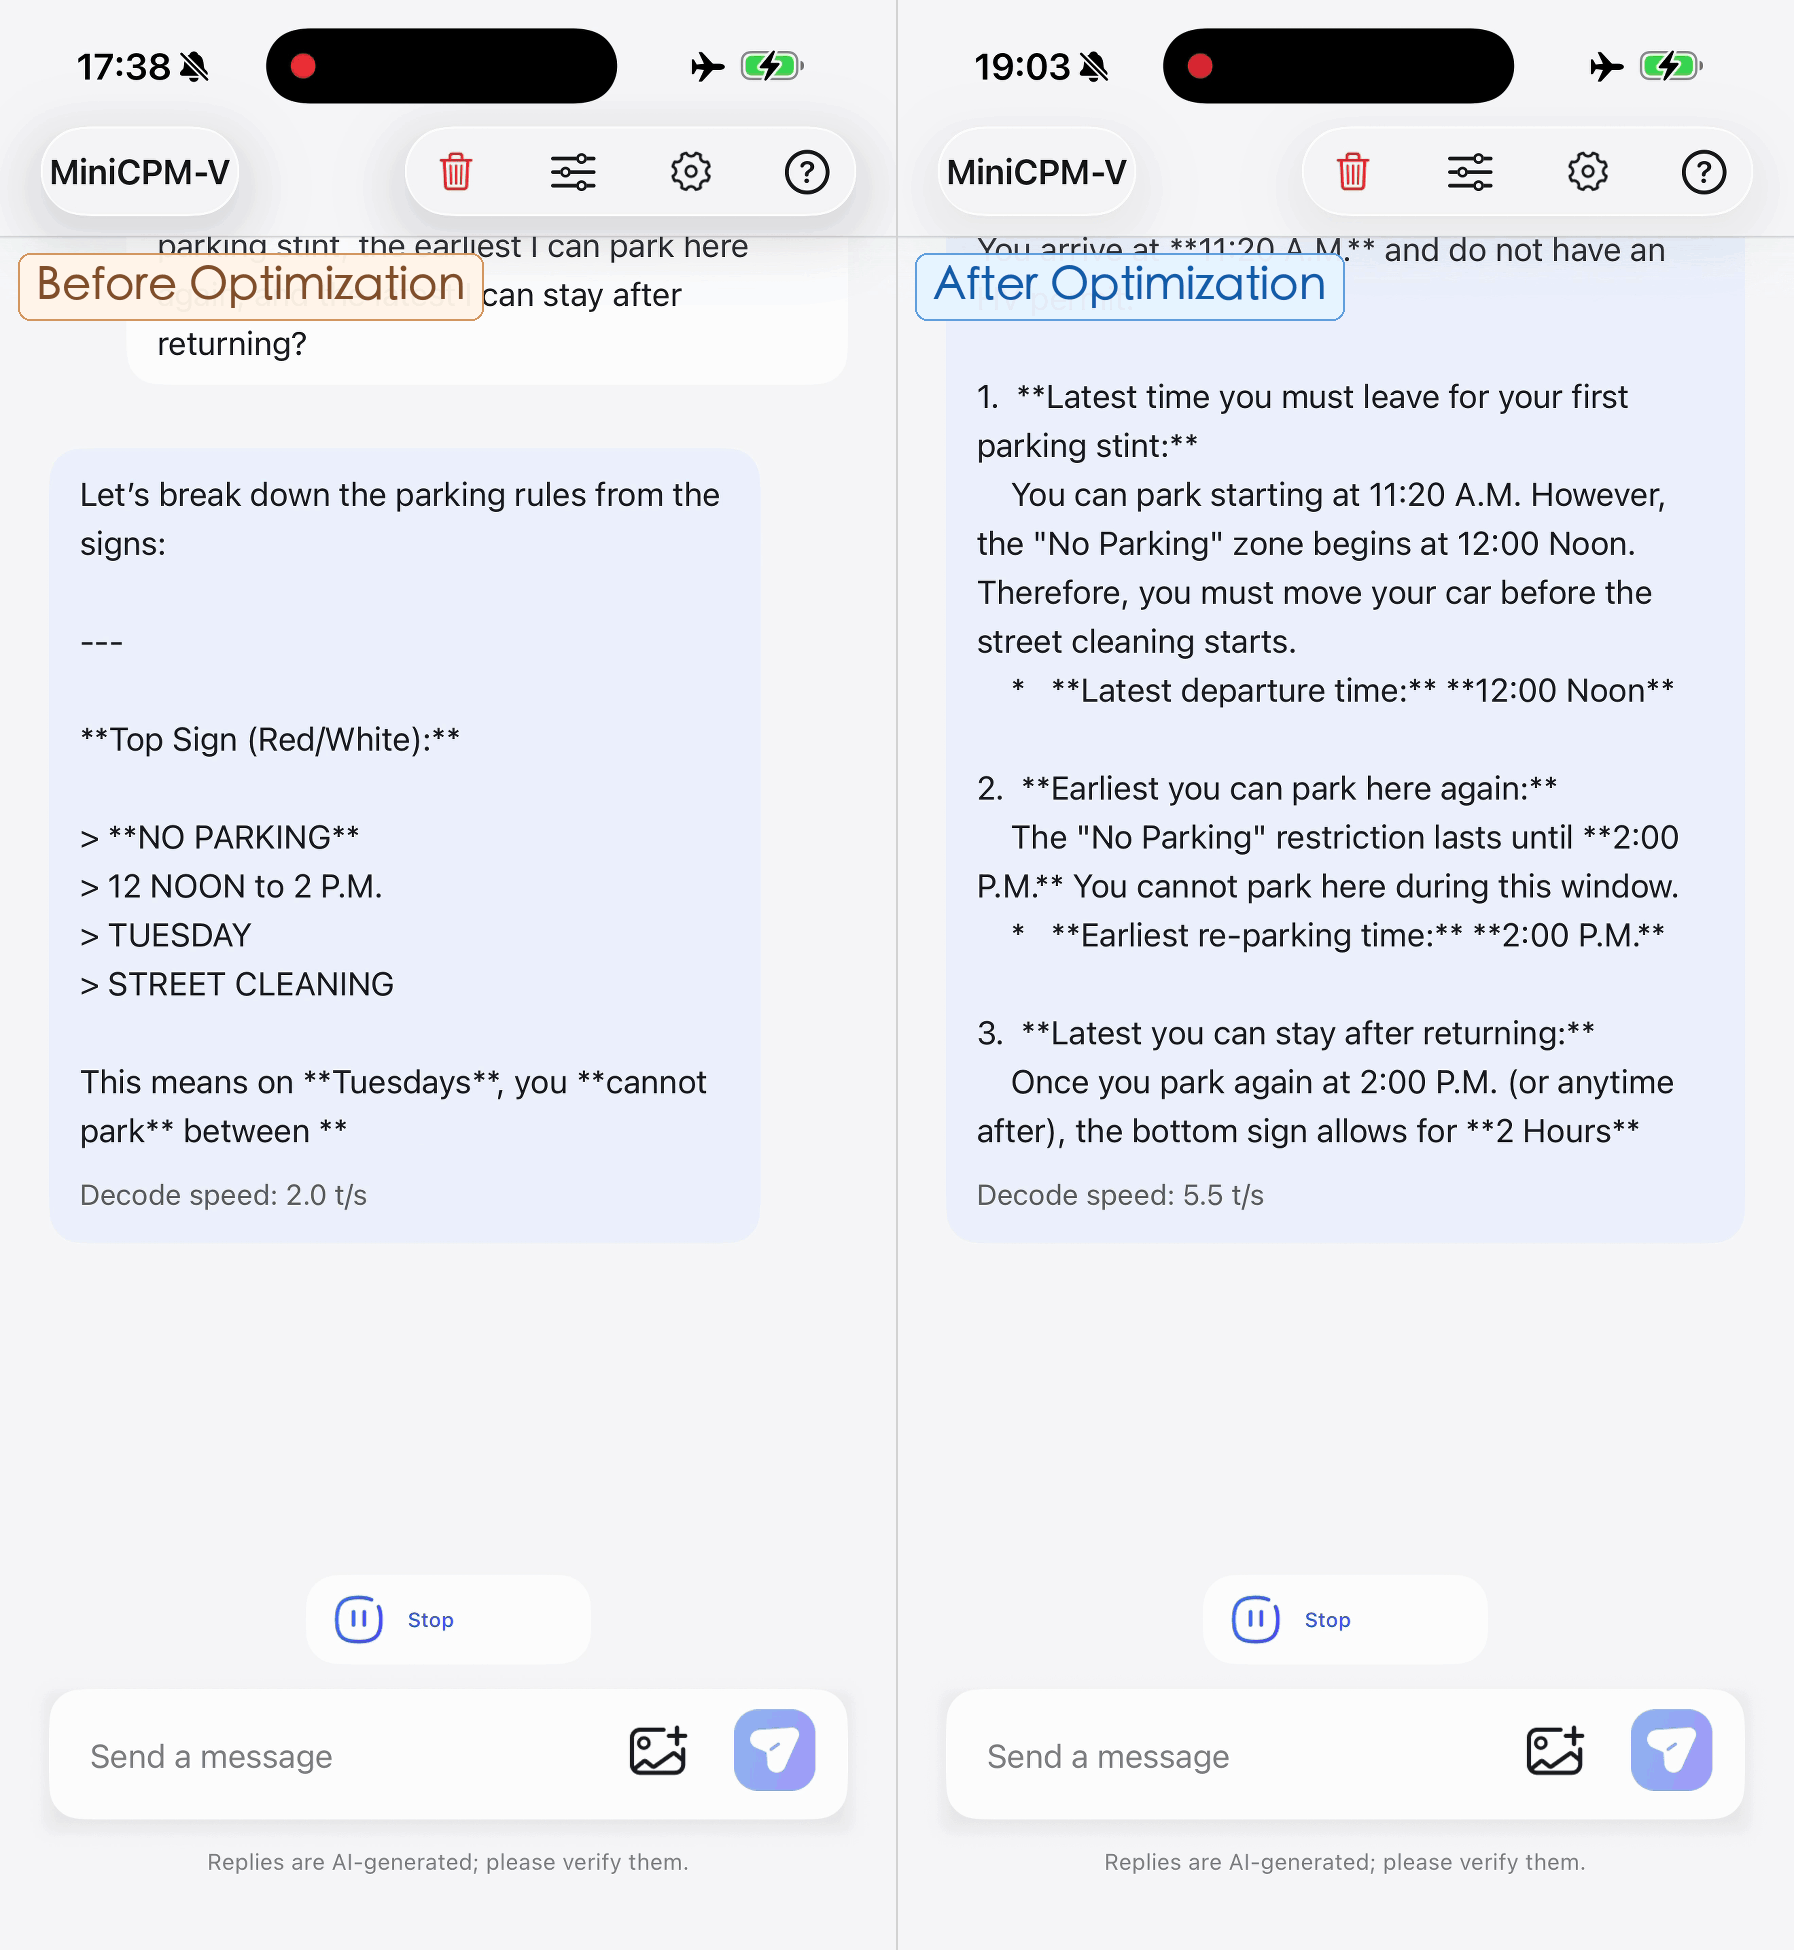
Significantly Advancing the Performance–Efficiency Pareto Frontier
The 35B-A3B variant of MiniCPM-V 4.7 advances the performance–efficiency Pareto frontier. In Instruct mode, 35B-A3B reaches a higher overall score in less inference time than Qwen3.6 35B-A3B.
Overall Performance (35B-A3B, Instruct)
Vision-Language
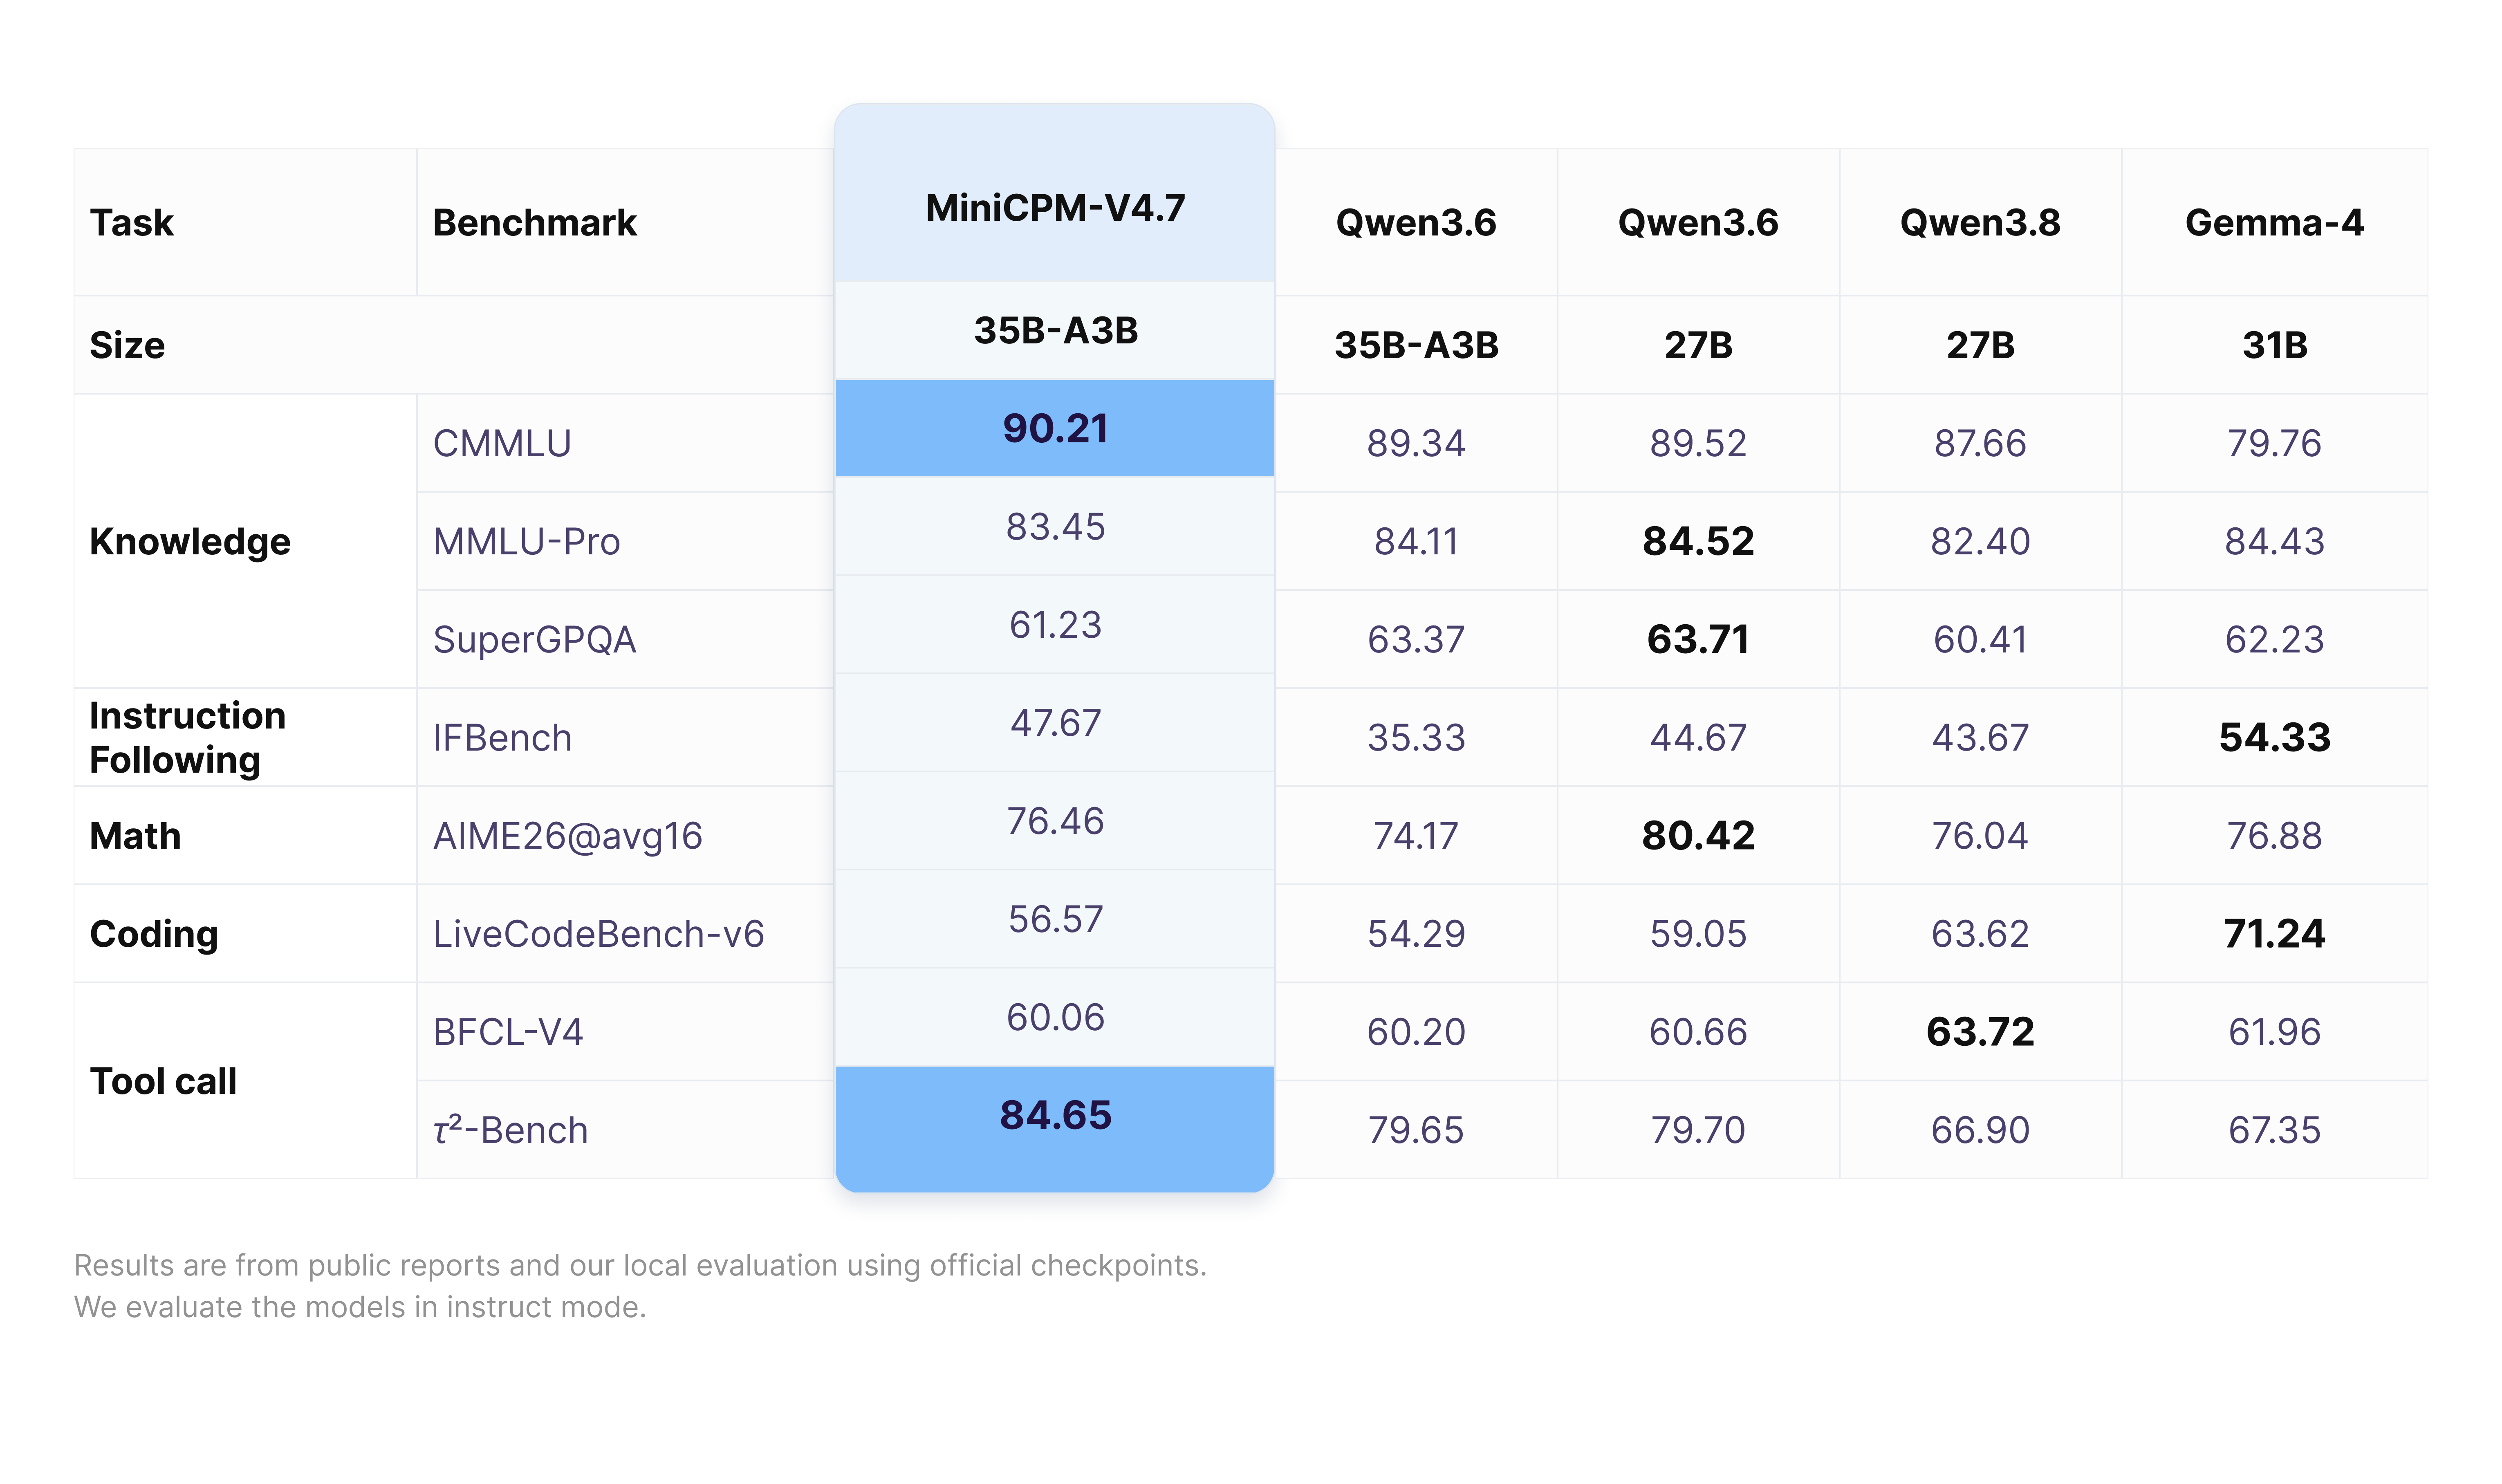
Language
MiniCPM-V 4.7 can run on phones and tablets. The clips below are unedited screen recordings captured directly on the devices.
| 35B-A3B iPhone 17 Pro Max |
35B-A3B iPad M4 |
 |
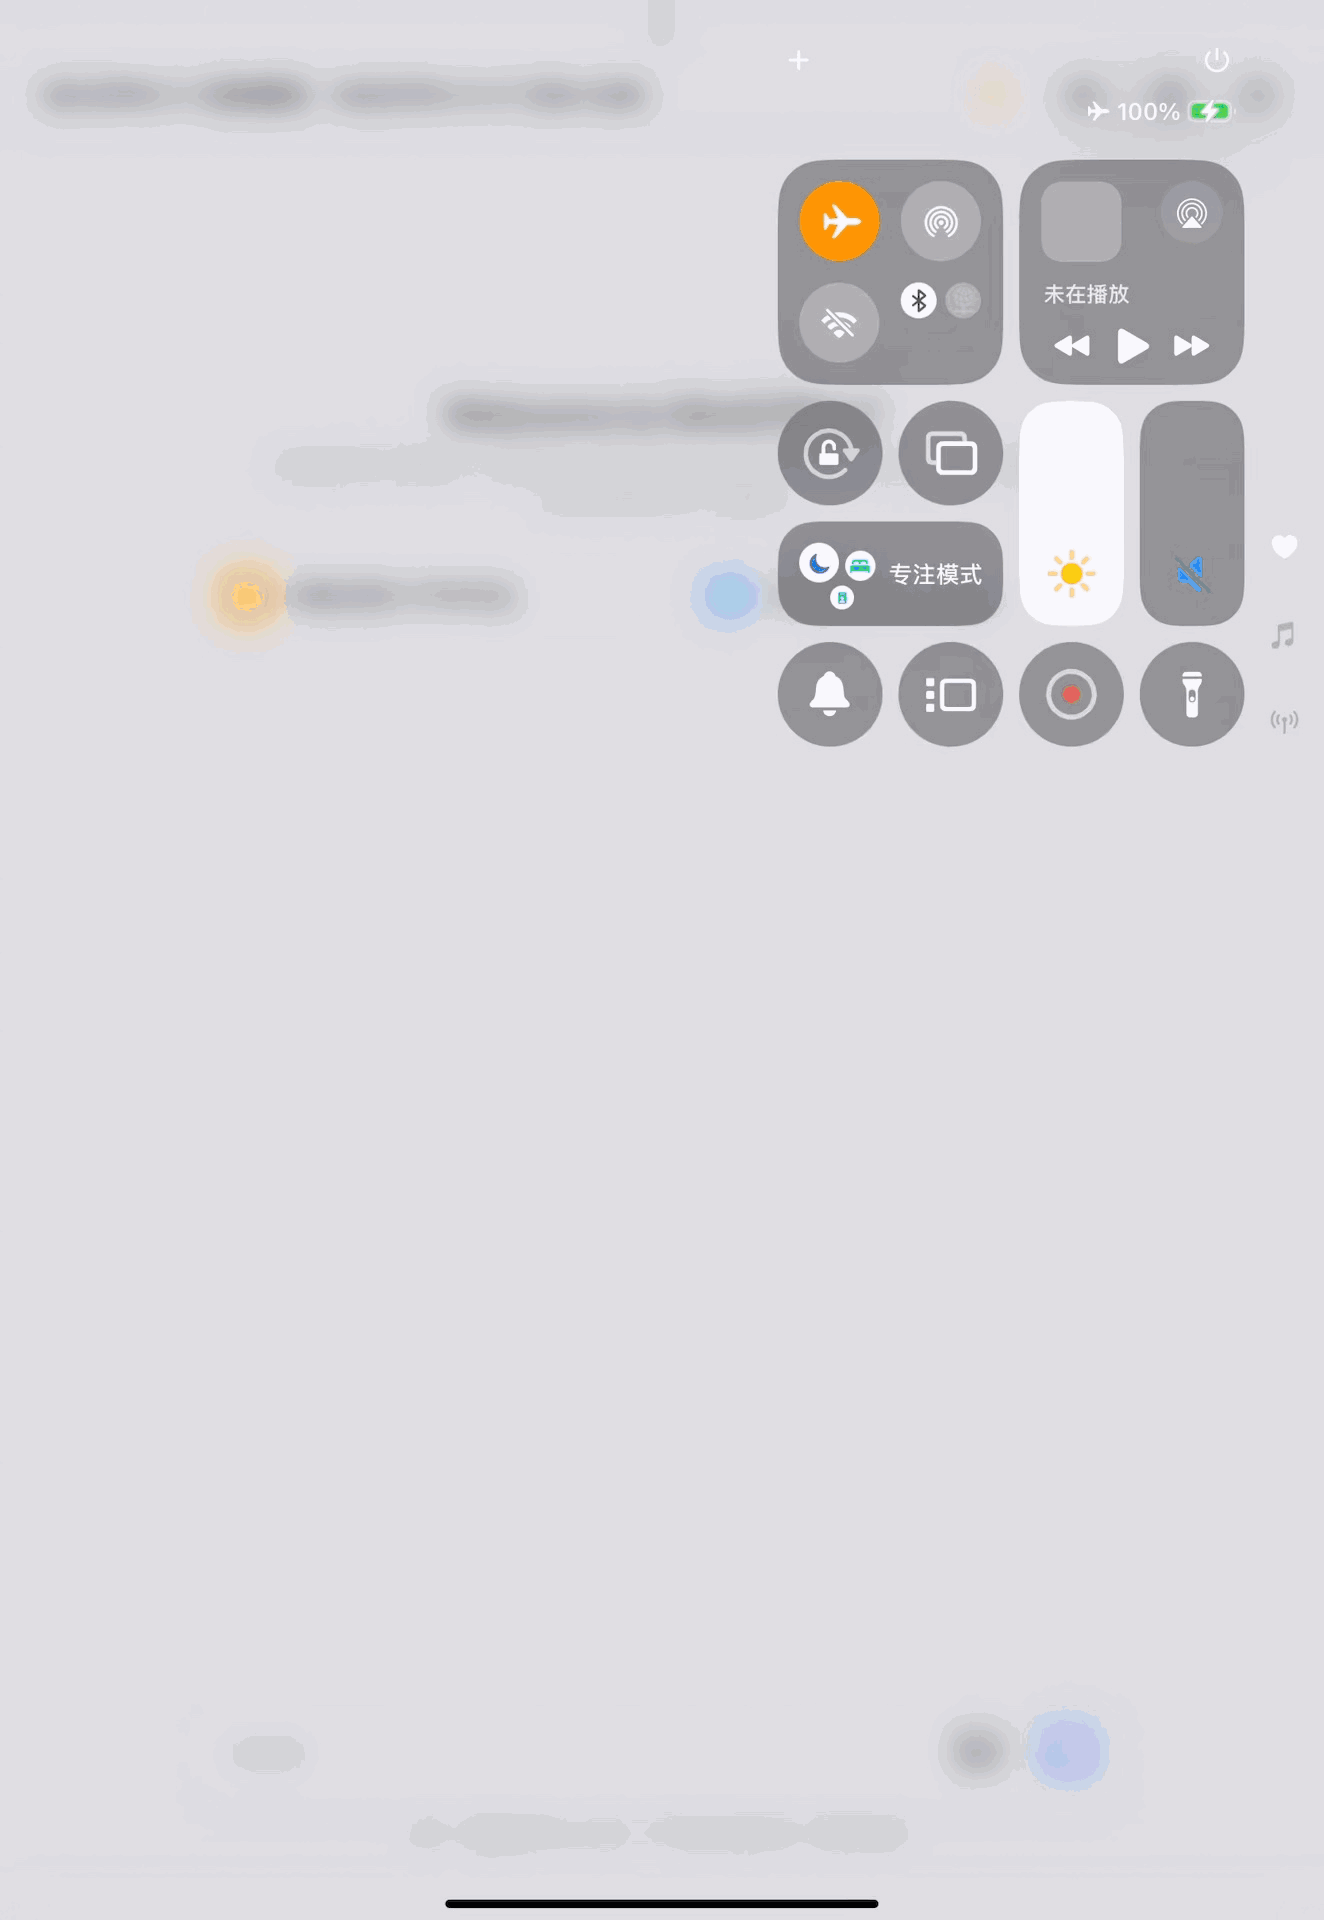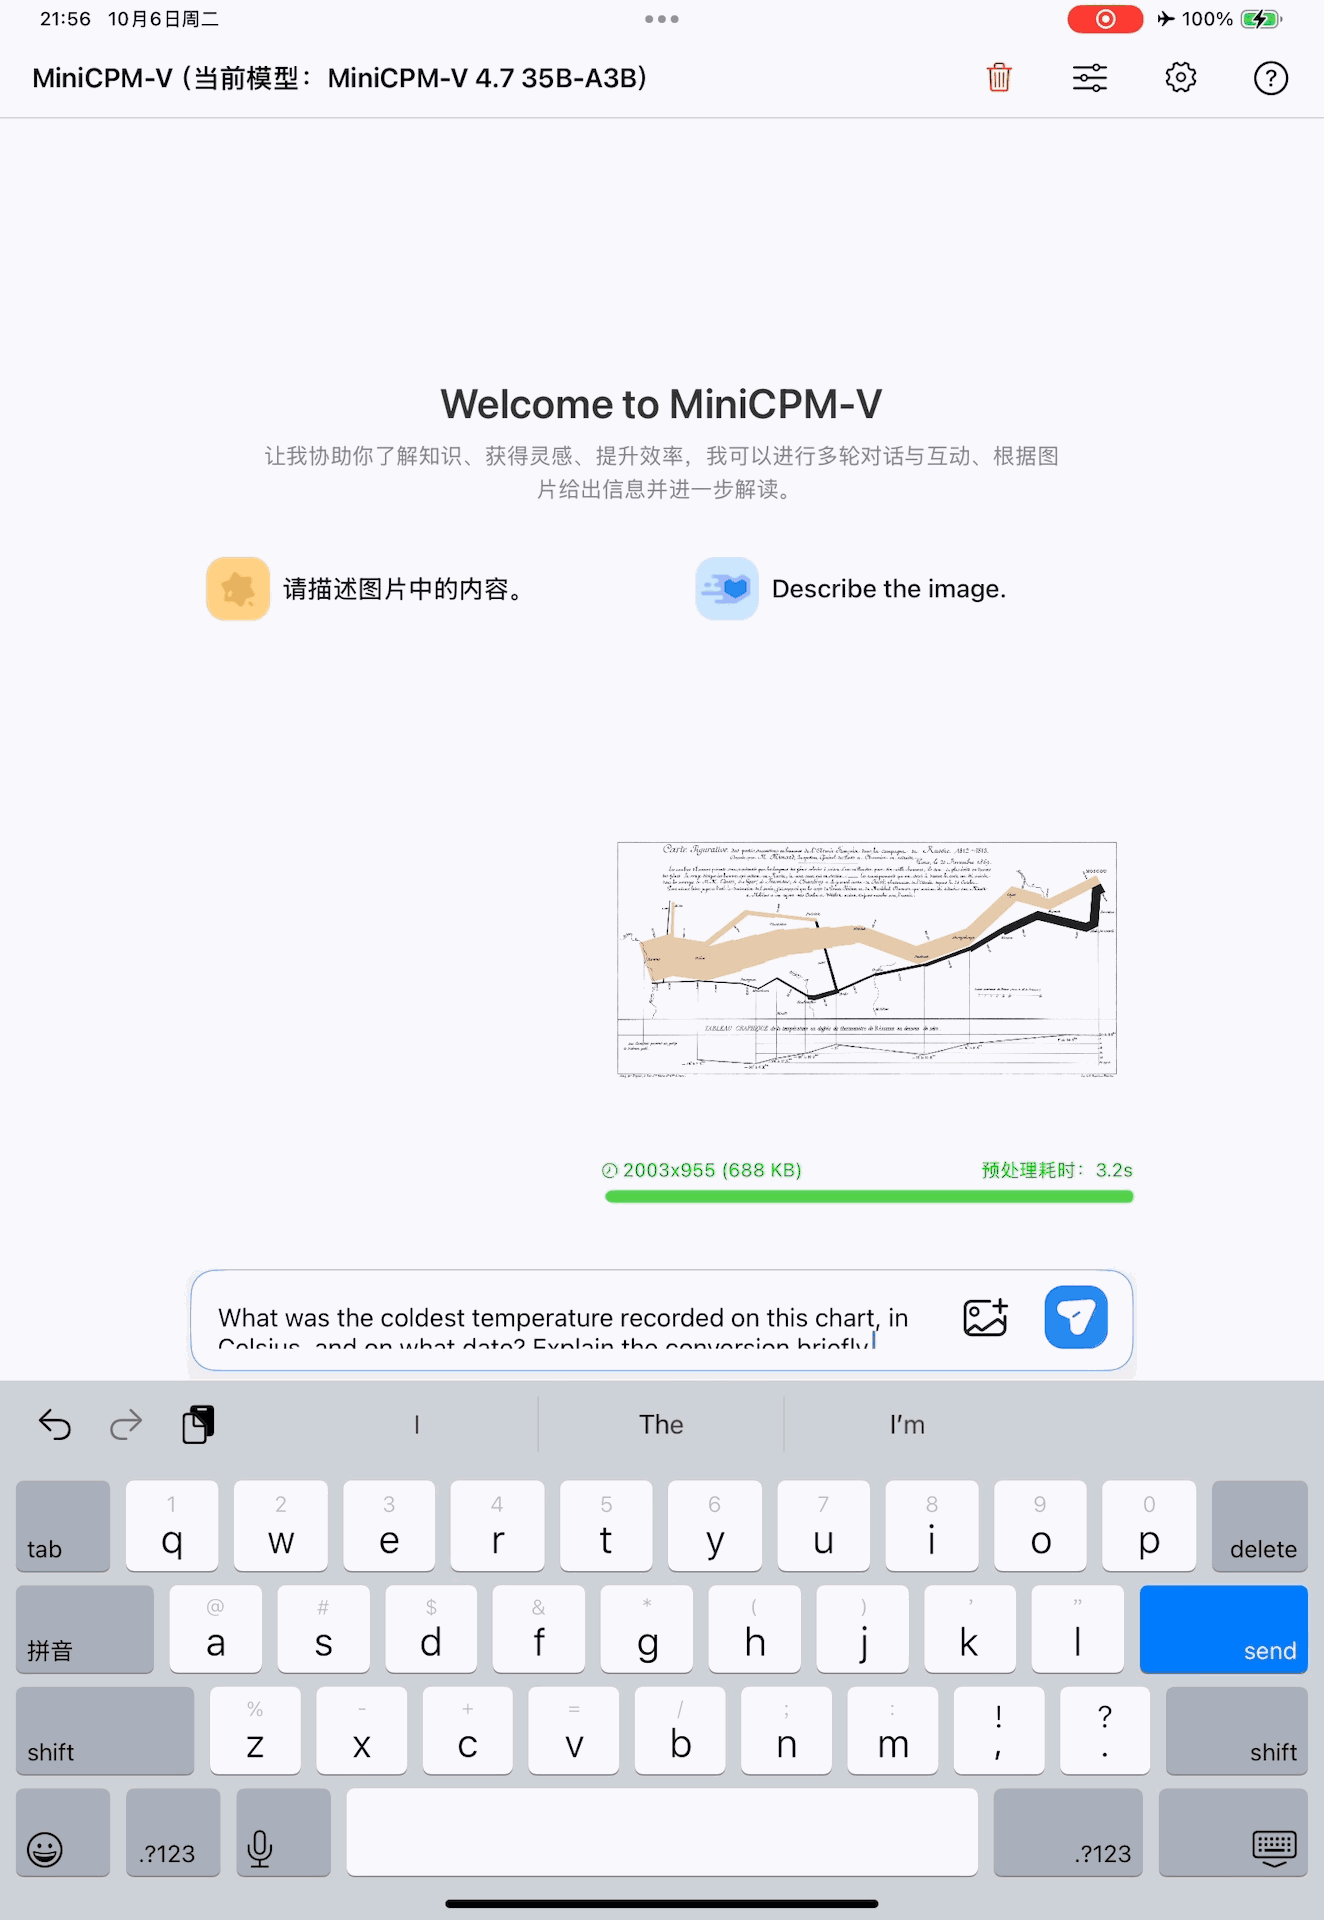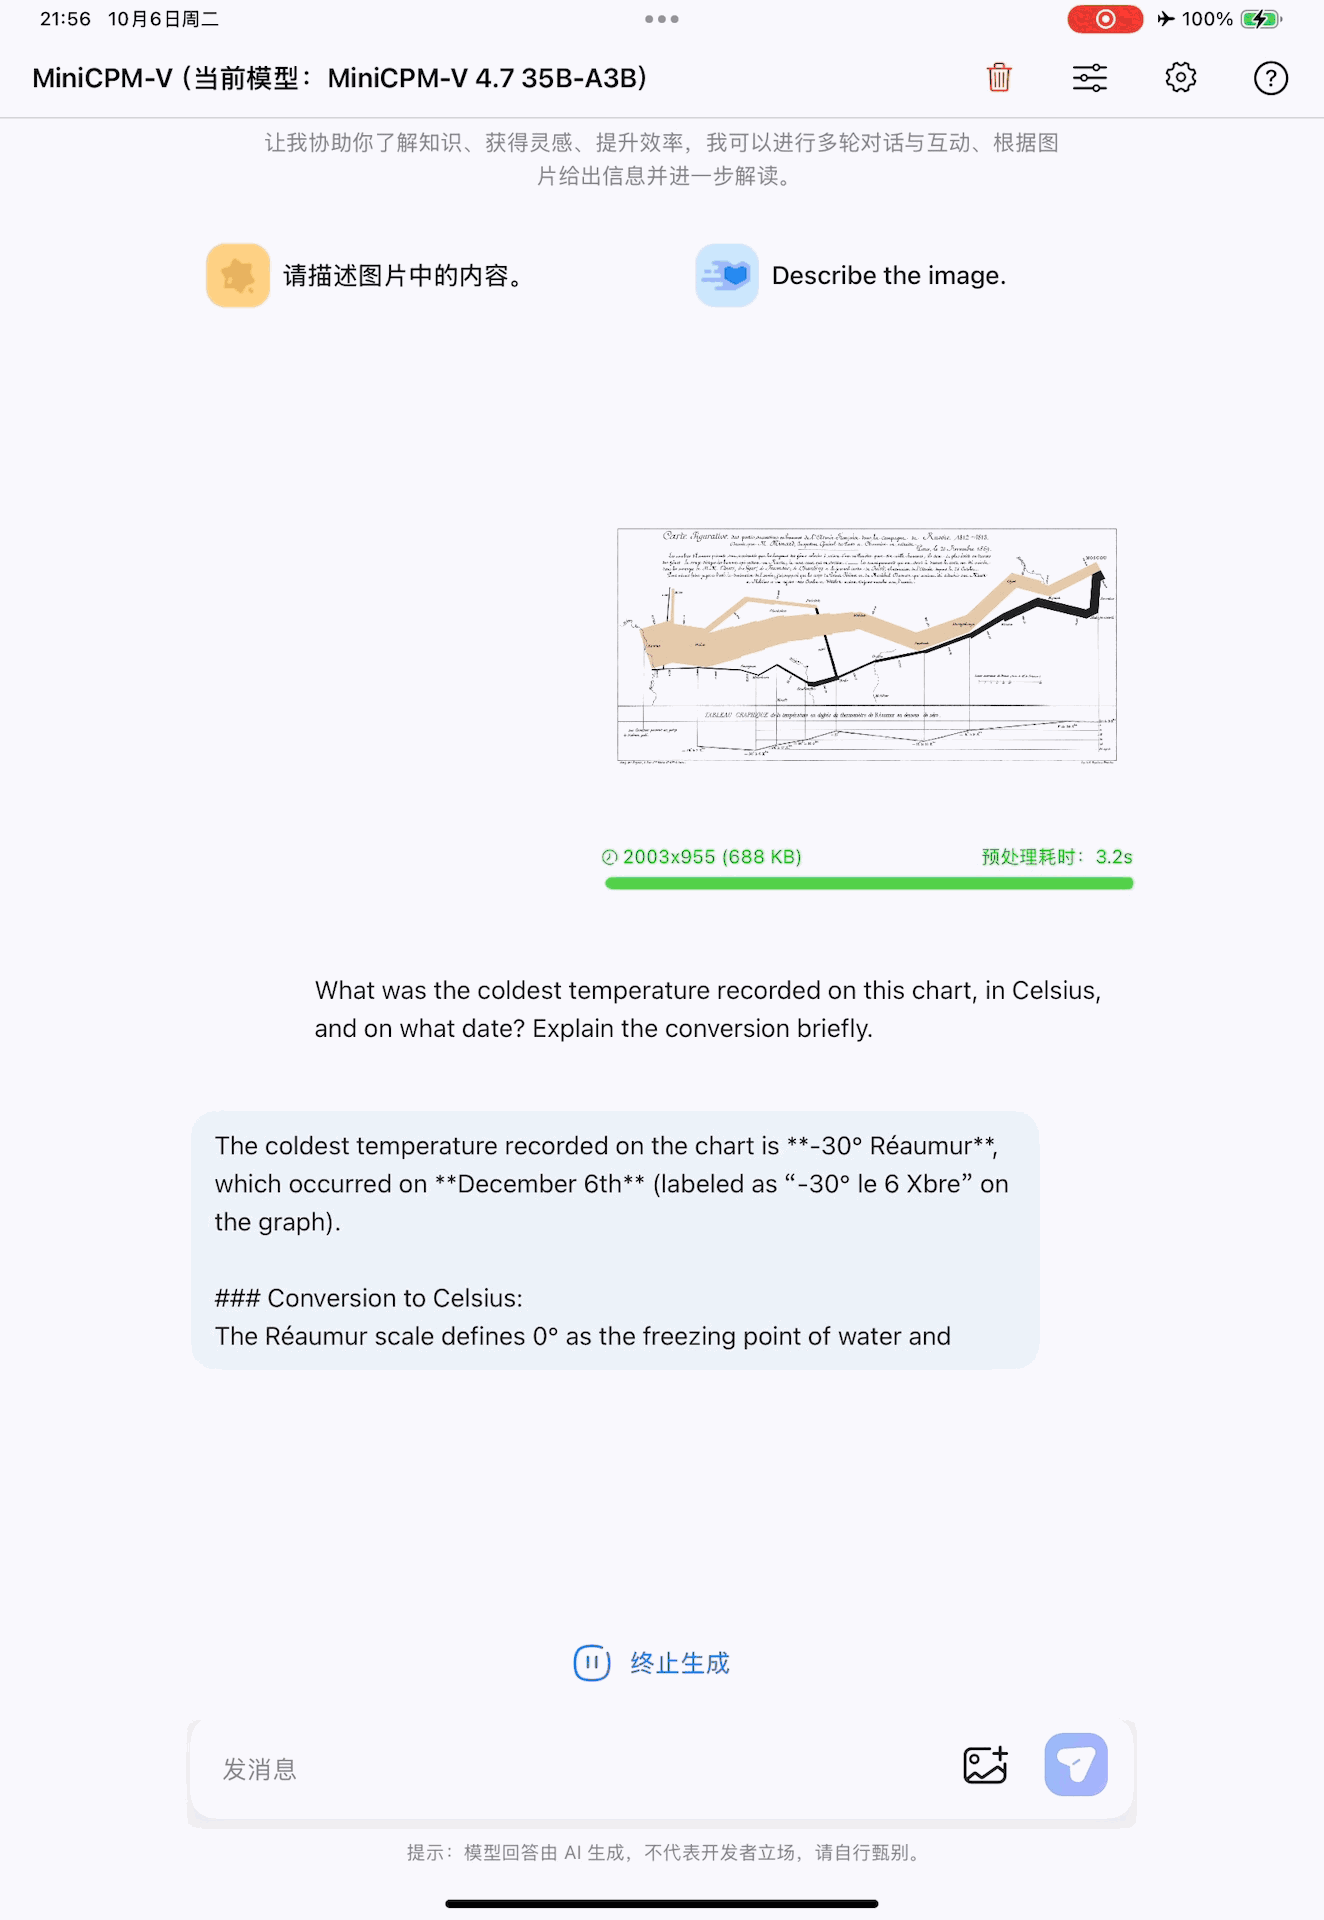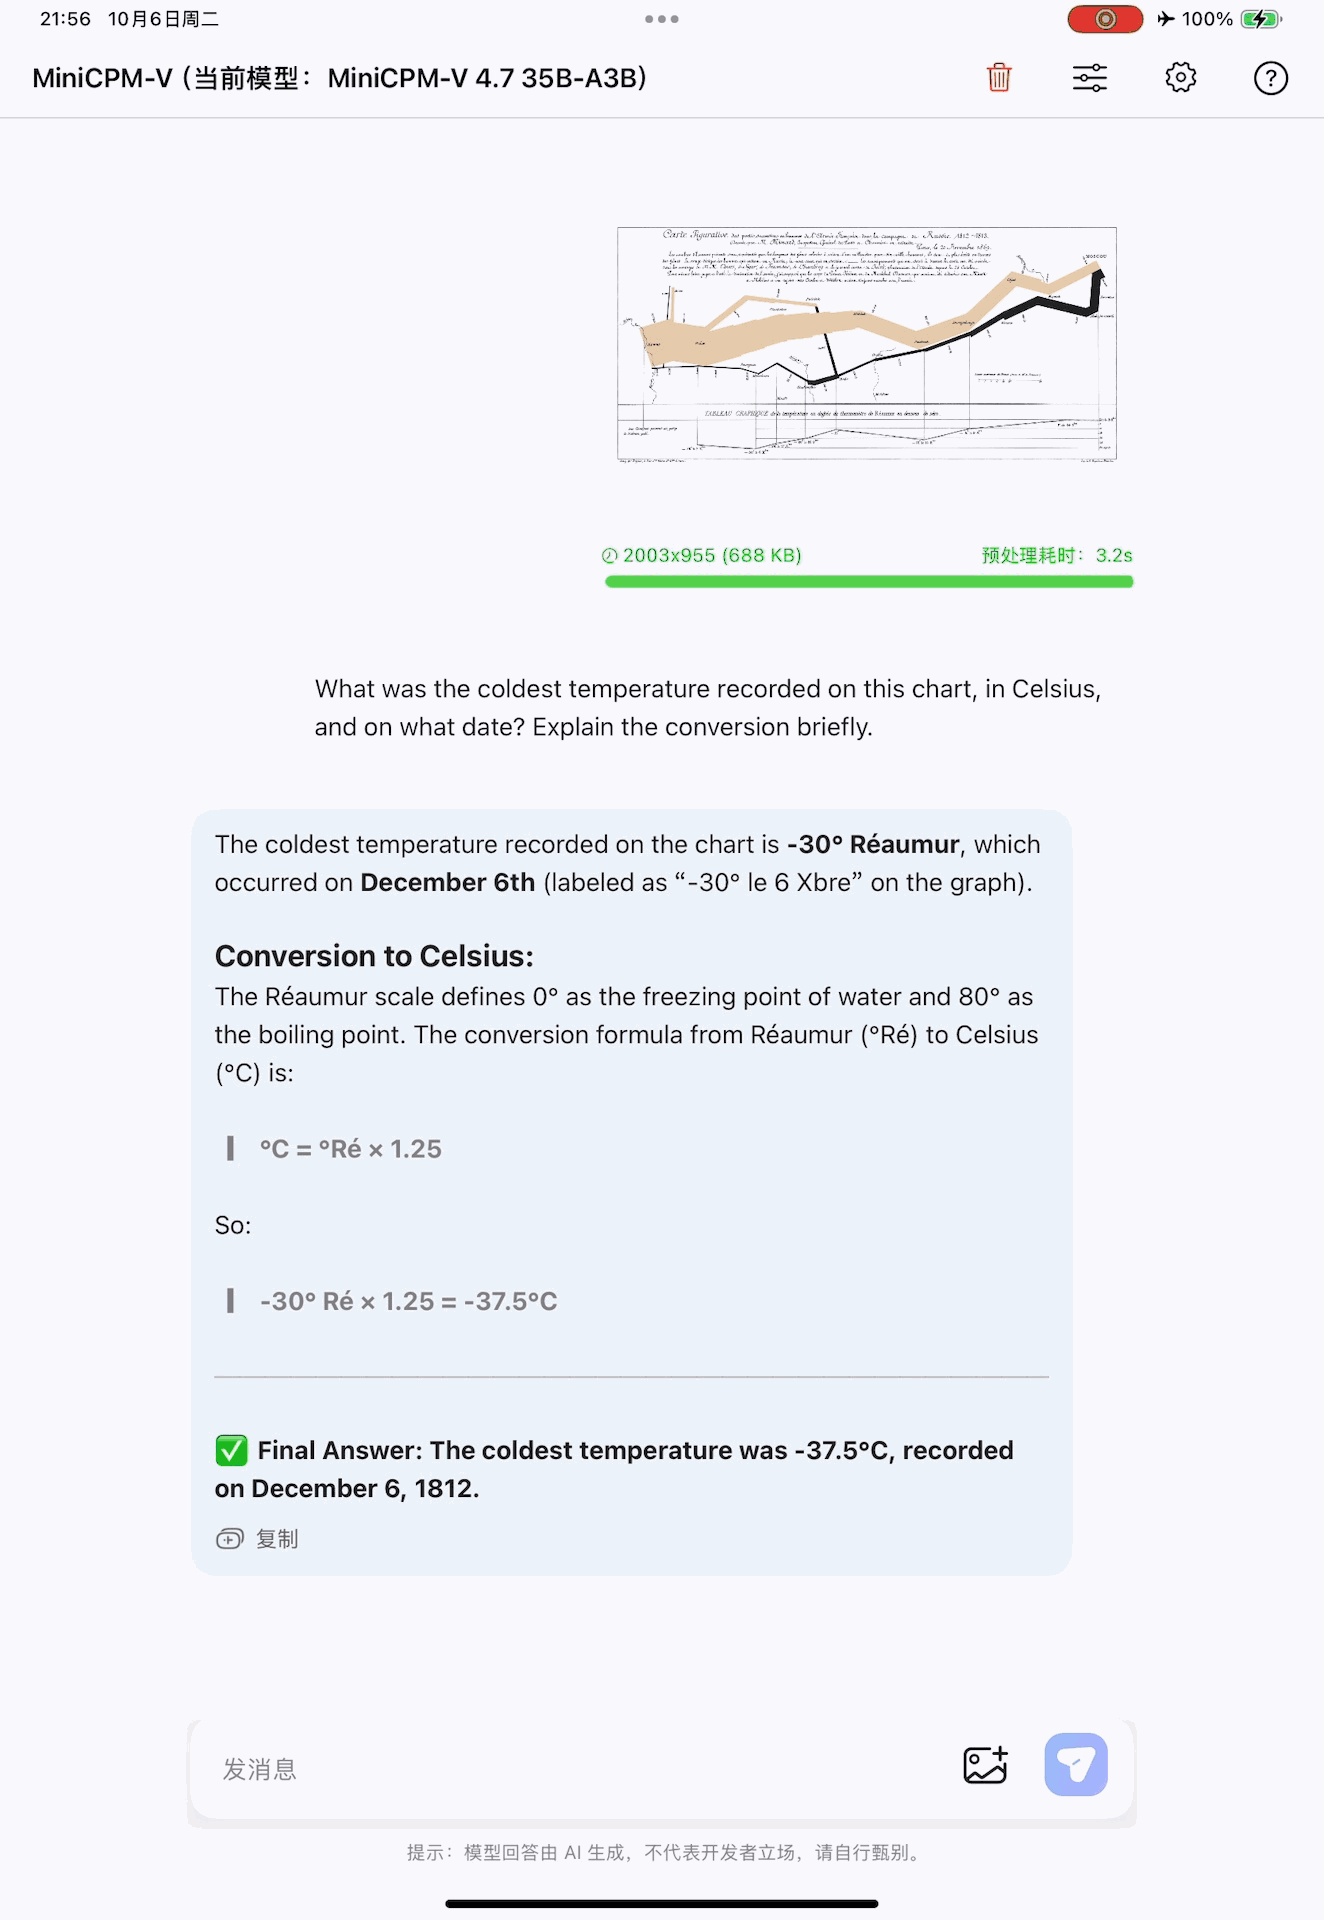 |
pip install "transformers[torch]>=5.18.0" torchvision torchcodec
Note on CUDA compatibility:
torchcodec(used for video decoding) may have compatibility issues with certain CUDA versions. For example,torch>=2.11bundles CUDA 13.1 by default, while environments with CUDA 12.x may encounter errors such asRuntimeError: Could not load libtorchcodec. Two workarounds:
- Replace
torchcodecwithPyAV— supports both image and video inference without CUDA version constraints:pip install "transformers[torch]>=5.18.0" torchvision av- Pin the CUDA version when installing torch to match your environment (e.g. CUDA 12.8):
pip install "transformers>=5.18.0" torchvision torchcodec --index-url https://download.pytorch.org/whl/cu128
import torch
from transformers import AutoModelForImageTextToText, AutoProcessor

model_id = "openbmb/MiniCPM-V-4.7-35B-A3B"

processor = AutoProcessor.from_pretrained(model_id)
model = AutoModelForImageTextToText.from_pretrained(
    model_id, torch_dtype="auto", device_map="auto"
)

# Flash Attention 2 is recommended for faster inference and lower GPU memory usage,
# especially in multi-image and video scenarios.
# model = AutoModelForImageTextToText.from_pretrained(
#     model_id,
#     torch_dtype=torch.bfloat16,
#     attn_implementation="flash_attention_2",
#     device_map="auto",
# )
messages = [
    {
        "role": "user",
        "content": [
            {"type": "image", "url": "https://huggingface.co/datasets/openbmb/DemoCase/resolve/main/refract.png"},
            {"type": "text", "text": "What causes this phenomenon?"},
        ],
    }
]

downsample_mode = "16x"  # Using `downsample_mode="4x"` for Finer Detail

inputs = processor.apply_chat_template(
    messages, tokenize=True, add_generation_prompt=True,
    return_dict=True, return_tensors="pt",
    downsample_mode=downsample_mode,
    max_slice_nums=36,
    enable_thinking=False,
).to(model.device)

generated_ids = model.generate(
    **inputs,
    downsample_mode=downsample_mode,
    max_new_tokens=512,
    # recommended instruct-mode sampling parameters
    do_sample=True,
    temperature=0.7,
    top_p=0.95,
    top_k=100,
    min_p=0.0,
    presence_penalty=0,
    repetition_penalty=1.03,
)
generated_ids_trimmed = [
    out_ids[len(in_ids):] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
]
output_text = processor.batch_decode(
    generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
)
print(output_text[0])
messages = [
    {
        "role": "user",
        "content": [
            {"type": "video", "url": "https://huggingface.co/datasets/openbmb/DemoCase/resolve/main/football.mp4"},
            {"type": "text", "text": "Describe this video in detail. Follow the timeline and focus on on-screen text, interface changes, main actions, and scene changes."},
        ],
    }
]

downsample_mode = "16x"  # Using `downsample_mode="4x"` for Finer Detail

inputs = processor.apply_chat_template(
    messages, tokenize=True, add_generation_prompt=True,
    return_dict=True, return_tensors="pt",
    downsample_mode=downsample_mode,
    max_num_frames=128,
    stack_frames=1,
    max_slice_nums=1,
    use_image_id=False,
    enable_thinking=False,
).to(model.device)

generated_ids = model.generate(
    **inputs,
    downsample_mode=downsample_mode,
    max_new_tokens=2048,
    # recommended instruct-mode sampling parameters
    do_sample=True,
    temperature=0.7,
    top_p=0.95,
    top_k=100,
    min_p=0.0,
    presence_penalty=0,
    repetition_penalty=1.03,
)
generated_ids_trimmed = [
    out_ids[len(in_ids):] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
]
output_text = processor.batch_decode(
    generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
)
print(output_text[0])
You can customize image/video processing by passing additional parameters to apply_chat_template:
| Parameter | Default | Applies to | Description |
|---|---|---|---|
downsample_mode |
"16x" |
Image & Video | Visual token downsampling. "16x" merges tokens for efficiency; "4x" keeps four times as many tokens for finer detail. Must also be passed to generate(). |
max_slice_nums |
9 |
Image & Video | Maximum number of slices when splitting a high-resolution image. Higher values preserve more detail for large images. Recommended: 36 for image, 1 for video. |
max_num_frames |
128 |
Video only | Maximum number of main frames sampled from the video. |
stack_frames |
1 |
Video only | Total sample points per second. 1 = main frame only (no stacking). N (N>1) = 1 main frame + N−1 sub-frames per second; the sub-frames are composited into a grid image and interleaved with main frames. Recommended: 3 or 5. |
use_image_id |
True |
Image & Video | Whether to prepend <image_id>N</image_id> tags before each image/frame placeholder. Recommended: True for image, False for video. |
Note:
downsample_modemust be passed to bothapply_chat_template(for correct placeholder count) andgenerate(for the vision encoder). All other parameters only need to be passed toapply_chat_template.
transformers serve
Hugging Face Transformers includes a lightweight OpenAI-compatible server for quick testing and moderate-load deployment.
pip install "transformers[serving]>=5.18.0"
Start the server:
transformers serve openbmb/MiniCPM-V-4.7-35B-A3B --port 8000 --host 0.0.0.0
Send a request:
curl -s http://localhost:8000/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -d '{
    "model": "openbmb/MiniCPM-V-4.7-35B-A3B",
    "messages": [{
      "role": "user",
      "content": [
        {"type": "image_url", "image_url": {"url": "https://huggingface.co/datasets/openbmb/DemoCase/resolve/main/refract.png"}},
        {"type": "text", "text": "What causes this phenomenon?"}
      ]
    }]
  }'
Tool calling example:
curl -s http://localhost:8000/v1/chat/completions -H 'Content-Type: application/json' -d '{
  "model": "openbmb/MiniCPM-V-4.7-35B-A3B",
  "messages": [{"role": "user", "content": [
    {"type": "text", "text": "the weather of Beijing"}
  ]}],
  "tools": [{
    "type": "function",
    "function": {
      "name": "get_weather",
      "description": "Get the current weather for a given location",
      "parameters": {
        "type": "object",
        "properties": {
          "location": {"type": "string", "description": "City name"}
        },
        "required": ["location"]
      }
    }
  }]
}'
We recommend using the following set of sampling parameters for generation in instruct mode: temperature=0.7, top_p=0.95, top_k=100, min_p=0.0, presence_penalty=0, repetition_penalty=1.03.
Speculative decoding (DSpark): we also release MiniCPM-V-4.7-35B-A3B-DSpark, a DSpark draft model trained for MiniCPM-V-4.7-35B-A3B.
OpenVINO™ is an open-source toolkit for optimizing and deploying AI inference on Intel CPU/GPU/NPU platforms. OpenVINO provides day-0 support for MiniCPM-V-4.7 on Intel platforms with high-performance inference. See the OpenVINO™ Toolkit to get started. You can install and run the example with this notebook.
MiniCPM-V 4.7 supports deployment on iOS, Android, and HarmonyOS, with day-0 support for Rockchip, Houmo, Intel, AMD, and Arm chip platforms. See the edge deployment repository for the apps and source code.
For supported inference and training frameworks, see Supported Inference and Training Frameworks and API. The MiniCPM-V 4.7 Cookbook covers deployment, fine-tuning, and quantization workflows.
Task guides
Quantization
| Method | Guide |
|---|---|
| GGUF | Quantization guide |
| BNB | Quantization guide |
| AWQ | Quantization guide |
| GPTQ | Quantization guide |
| FP8 / INT4 | Quantization guide |
We would like to thank the following projects:
MiniCPM-V 4.7 is available in 35B-A3B and 1B variants. Each model is paired with its DSpark speculative decoding heads, available in BF16 and GGUF.
| Model | Description | Model weights | DSpark heads |
|---|---|---|---|
| MiniCPM‑V 4.7 35B-A3B |
The first open-source MoE model to run smoothly on-device without compromising performance, raising the bar for on-device performance. |
🤗  BF16 🤗 FP8🤗 int4🤗 AWQ🤗 GPTQ🤗 GGUF
|
🤗 BF16 🤗 GGUF
|
| MiniCPM‑V 4.7 1B |
Combines stronger capabilities with extremely high efficiency, advancing the performance–efficiency Pareto frontier for multimodal large language models. |
🤗 BF16 🤗 int4🤗 AWQ🤗 GPTQ🤗 GGUF
|
🤗 BF16 🤗 GGUF
|
The 1B int4 variant uses bitsandbytes; AWQ and GPTQ use W4A16 quantization. Quantized variants reduce memory usage; GGUF weights support CPU inference.
Each GGUF repository also ships a thinking/ subfolder with the same quantization levels
suffixed -thinking. Those files restore the upstream chat template and therefore emit a
[Start thinking] … [End thinking] trace; the files at the repository root keep thinking disabled.
Tensor weights are identical between the two sets; only the embedded template differs.
Also available on Ollama.
Base model
openbmb/MiniCPM-V-4.7-35B-A3B