

Sors-2B
Sors-2B is a 2B decision model that turns a state and a set of typed questions into decisions. It reads the state as text, JSON or images and returns a probability for every allowed option of every question. There is no free-form text generation and no output parsing.
The Sors API follows the Jev / SystemOne request and response format.
Sors-2B is fine-tuned from Qwen/Qwen3.5-2B-Base.
Model
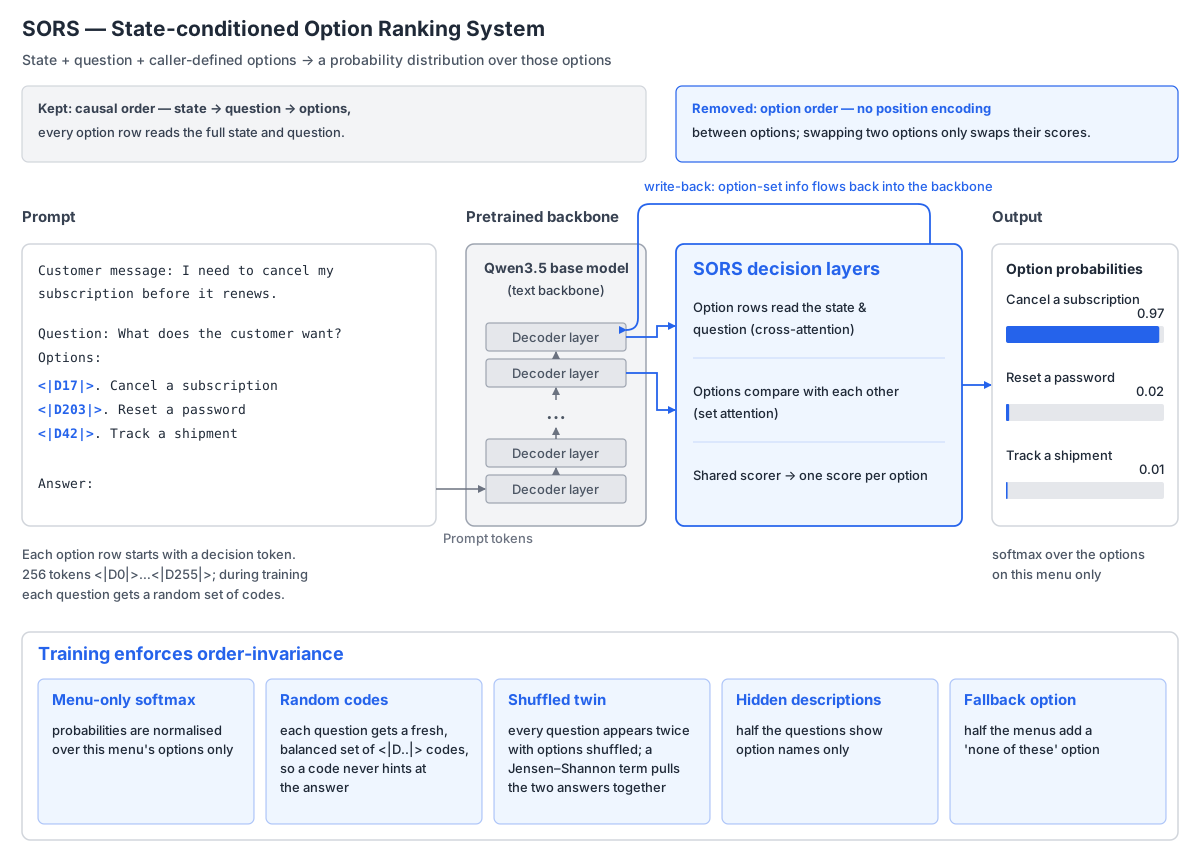
- Backbone: Qwen/Qwen3.5-2B-Base text backbone, fully fine-tuned.
- Vision: the Qwen3.5-2B-Base vision encoder (24 blocks), frozen and packed in as-is. Images in the state are encoded into the shared prefix, so every option branch reads them.
- One branch per option: each question becomes a shared prefix (state, then question) plus one short suffix per option,
Option: <|D1|> <option text>andAnswer:. The prefix is encoded once and shared; no branch sees another option. - Readout: a scalar head on the normalised final hidden state at
Answer:gives one score per option. - Output: one probability per allowed option, a softmax over that question's options only. Options are defined per request, up to 255 per question, with no retraining.
Because options are scored independently, reordering the menu only reorders the scores. The head and the backbone train together from the first step on the softmax over each question's menu. Ambiguous questions train toward a probability distribution, half the questions hide option descriptions, and half the menus add a "none of these" option.
Training data
Sors-2B is trained only on our own synthetic dataset, synth-intents-v6 (to be open-sourced once it is cleaned up): 56,990 yes/no, named-option and ordered-score questions in 33 domains, English and Chinese, chosen family by family from the 516,464 questions of synth-intents-v5.25. The size of each family was set by experiment: a family stopped growing once more of it no longer improved that family's own held-out questions. Every question is seen once (845 steps at batch 72), which keeps the model's confidence close to its accuracy and keeps more of the base model's general knowledge than longer training.
None of the evaluation sets below take part in training. The synthetic data is written from scratch and contains no content from existing datasets. Compared against every evaluation set below, no text is identical after normalisation. A run of 8 consecutive words is shared by no MASSIVE item, 3 of Banking77's 3,080 items, 4 of BoolQ's 3,270 and 1 public JevBench item, all of them everyday phrases or lists such as "I don't want to be charged for" or a list of public holidays.
Files
| File | Purpose |
|---|---|
model.safetensors |
All weights (4.43 GB): backbone and vision encoder in BF16, scalar head in FP32, learned `< |
config.json |
Sors architecture, text- and vision-model configuration, decision-token IDs and per-parameter precision |
preprocessor_config.json |
Image preprocessor of the vision encoder |
tokenizer.json, tokenizer_config.json, chat_template.jinja |
Training tokenizer, including its 261 added special tokens |
LICENSE |
Apache-2.0 license |
Usage
Sors-2B runs with the SORS runtime from the code repository. Tested with torch 2.14 and transformers 5.17 on a single
A100 40GB.
git clone https://github.com/madousho-ai/sors && cd sors
uv sync
PYTHONPATH=src .venv/bin/python scripts/serve.py \
  --init SakuraYuyuko/Sors-2B --max-tokens 16384 --warmup --port 8000
--init downloads this repository into the standard Hugging Face cache on first start.
Jev / SystemOne API
The server answers POST /v1/systemone. The response has model, answers keyed by question ID, and usage. A choice
answer has choice, confidence and probabilities; a score answer has the expected score, confidence, legend and
probabilities; a noul answer has the probability of true.
curl -s http://127.0.0.1:8000/v1/systemone \
  -H 'Content-Type: application/json' \
  -d '{
    "model": "Sors-2B",
    "state": "I need to cancel my subscription before it renews.",
    "questions": {
      "intent": {
        "type": "choice",
        "instructions": "What does the customer want?",
        "criteria": {"Cancel a subscription": null, "Reset a password": null, "Track a shipment": null}
      },
      "urgent": {"type": "noul", "instructions": "Does the customer need this done right away?"}
    }
  }'
Images
Images go in state, following TypeSafe System One's images format: list each image
under a top-level assets key, keyed by a reference string, and write that string where the image belongs in state.
The server needs no extra flag.
curl -s http://127.0.0.1:8000/v1/systemone \
  -H 'Content-Type: application/json' \
  -d '{
    "model": "Sors-2B",
    "state": {"screenshot": "img-1", "note": "The user wants to check out."},
    "assets": {"img-1": {"type": "image", "format": "png", "data_base64": "<base64 PNG>"}},
    "questions": {
      "next": {
        "type": "choice",
        "instructions": "Which button should be clicked next?",
        "criteria": {"Add to cart": null, "Checkout": null, "Sign in": null}
      }
    }
  }'
- Images are read only in
state; a reference ininstructionsorcriteriais rejected. - PNG or JPEG, each side 280–1568 pixels, up to 16 MiB per image. The server downsizes each image to at most
--max-image-pixels(default 1024×1024, one token per 32×32 pixels). - synth-intents-v6 is text only, so the decision head has not trained on images and accuracy on image questions has not been measured yet.
Python
from pathlib import Path

from huggingface_hub import snapshot_download
from sors.serve.api import Choice
from sors.serve.engine import load_engine

engine = load_engine(Path(snapshot_download("SakuraYuyuko/Sors-2B")), device="cuda", local_files_only=True)
question = Choice(
    type="choice",
    instructions="What does the customer want?",
    criteria={"Cancel a subscription": None, "Reset a password": None, "Track a shipment": None},
)
result = engine.evaluate("I need to cancel my subscription before it renews.", {"intent": question})
print(dict(zip(question.criteria, result.probs["intent"])))
Input format
| Field | Description |
|---|---|
model |
Served model name, Sors-2B by default |
state |
Any string or JSON value describing the situation to decide on; may reference images in assets |
assets |
Optional mapping of reference string to image (type, format, data_base64) |
questions |
Mapping of question ID to question; several questions share one state |
Each question has:
type:noul(yes/no),choice(named options), orscore(ordered options)instructions: what to decide, as a string or JSONcriteria: forchoice, a mapping of option name to an optional description (2–255 options); forscore, a list of ordered levels; fornoul, optional descriptions fortrueandfalse
The model is trained on inputs up to 16,384 tokens; start the server with --max-tokens 16384 to accept them.
Results
Accuracy (%). Banking77 and MASSIVE are answered against the full intent menu: all 77 and all 60 intents on every question, with no top-K shortlist. "+ descriptions" adds a one-line description after each intent name. The previous weights (2026-10-29) are shown for comparison.
| Benchmark | Questions | Sors-2B (2026-11-18) | previous (2026-10-29) |
|---|---|---|---|
| Banking77 | 3,080 | 67.5 | 67.0 |
| Banking77 + descriptions | 3,080 | 79.0 | 79.7 |
| MASSIVE | 2,974 | 71.9 | 68.6 |
| MASSIVE + descriptions | 2,974 | 81.9 | 80.4 |
| BoolQ | 3,270 | 84.9 | 81.1 |
| Public JevBench easy | 48 | 100.0 | 100.0 |
| Public JevBench original | 72 | 97.2 | 97.2 |
| Public JevBench hard | 111 | 71.2 | 66.7 |
| Public JevBench overall | 231 | 85.3 | 83.1 |
| Decision Index 0.3, public index | 140,620 | 27.68 | 21.22 |
- Calibration improved with the shorter training: expected calibration error on MASSIVE fell from 0.14 to 0.08 and on BoolQ from 0.064 to 0.043.
- Public JevBench is JevBench's public question set, scored with the official JevBench CLI and its
typesafeadapter. Its tiers are small, so differences of a few points there are noise. - The Decision Index public index is our own run of the public Decision Index kit (edition 0.3, HTTP engine), not a leaderboard submission. 243 requests longer than the server's context count as wrong, as the kit prescribes.
- On the JevBench leaderboard, the previous weights (2026-10-29) rank 165 of 261 overall, with intelligence 31.4 and calibration 76.5. These weights have not been measured there yet.
- These weights are revision
v6-2026-11-18. Earlier weights remain available as revisionsv78-2026-10-29(trained on synth-intents-v5.17) andv5.3-2026-10-08(trained on synth-intents-v5.3).
License
Model weights are released under Apache-2.0, following the Qwen base model. The API format follows TypeSafe's System One; this project is not affiliated with TypeSafe AI.
- Downloads last month
- 95
Model tree for SakuraYuyuko/Sors-2B
Base model
Qwen/Qwen3.5-2B-Base