

File size: 11,370 Bytes
9f2bc3e | 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 107 108 109 110 111 112 113 114 115 116 117 118 119 120 121 122 123 124 125 126 127 128 129 130 131 132 133 134 135 136 137 138 139 140 141 142 143 144 145 146 147 148 149 150 151 152 153 154 155 156 157 158 159 160 161 162 163 164 165 166 167 168 169 170 171 172 173 174 175 176 177 178 179 180 181 182 183 184 185 186 187 188 189 190 191 192 193 194 195 196 197 198 199 200 201 202 203 204 205 206 207 208 209 210 211 212 213 214 215 216 217 218 219 220 221 222 223 224 225 226 227 228 229 230 231 232 233 234 235 236 237 238 239 240 241 242 243 244 245 246 247 248 249 250 251 252 253 254 255 256 257 258 259 260 261 262 263 264 265 266 267 268 269 270 271 272 273 274 | ---
license: other
license_name: flux-1-dev-non-commercial-license
license_link: https://huggingface.co/black-forest-labs/FLUX.1-Kontext-dev/blob/main/LICENSE.md
library_name: transformers
pipeline_tag: image-to-image
inference: false
base_model:
- Qwen/Qwen2.5-VL-3B-Instruct
- black-forest-labs/FLUX.1-Kontext-dev
datasets:
- yztian/IIMT30k
- yztian/MTedIIMT
- yztian/PRIM
language:
- de
- en
- fr
- ro
- cs
- ru
tags:
- in-image-machine-translation
- image-translation
- image-editing
- multimodal
- qwen2.5-vl
- flux
- arxiv:2606.24333
---
# UniTranslator
## A Unified Multimodal Framework for End-to-End In-Image Machine Translation
<p align="center">
📄 <a href="https://arxiv.org/abs/2606.24333">Paper</a> ·
💻 <a href="https://github.com/SeerRay-Lab/Unitranslator">Code</a> ·
🤗 <a href="https://huggingface.co/SeerRay-Lab/Unitranslator">Model</a>
</p>
**UniTranslator**, accepted at **ECCV 2026**, is an end-to-end framework for **in-image machine translation (IIMT)**. Given an image and a translation instruction, it predicts the translated text and renders that translation back into the source text regions while preserving the surrounding scene, layout, and typography as closely as possible.
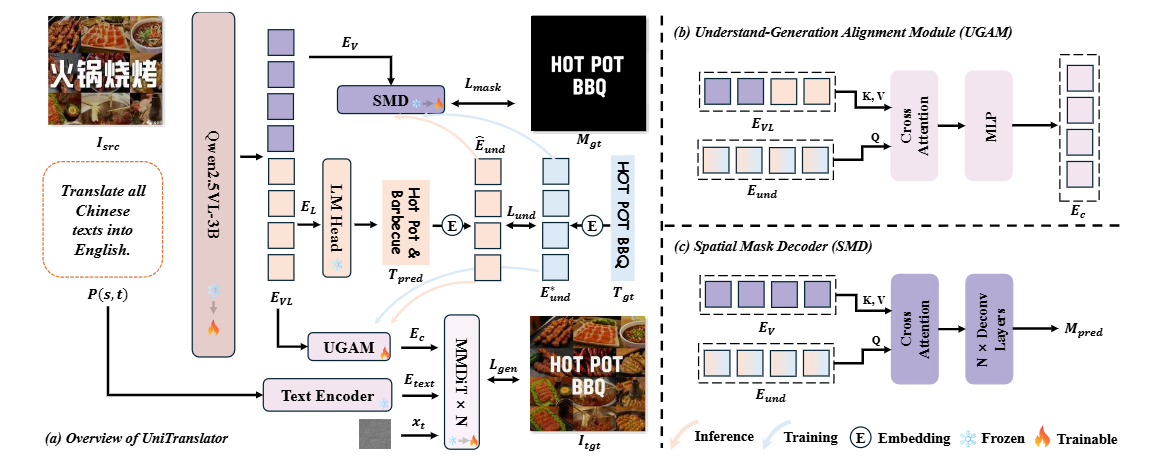
UniTranslator introduces two components:
- **Understand-Generation Alignment Module (UGAM):** aligns translation-understanding representations with the image-generation condition, reducing semantic inconsistency between predicted and rendered text.
- **Spatial Mask Decoder (SMD):** adds pixel-level supervision over text regions to improve localization, geometric alignment, and layout-preserving text replacement.
> This repository contains a research checkpoint that uses custom model classes from the GitHub repository. It is not directly compatible with `AutoPipeline.from_pretrained("SeerRay-Lab/Unitranslator")` or the hosted Hugging Face Inference API.
## Model details
| Property | Description |
|---|---|
| Task | End-to-end in-image machine translation |
| Input | Source image, source language, and target language |
| Output | Predicted translation text and an edited image containing the translated text |
| Multimodal backbone | Qwen2.5-VL-3B-based checkpoint |
| Image generator | FLUX.1-Kontext-dev-based denoiser |
| Main components | UGAM and SMD |
| Training | Two-stage warm-up and joint fine-tuning |
| Recommended precision | BF16 |
The released checkpoint combines a multimodal understanding branch, a FLUX-based generation branch, and task-specific alignment and spatial-supervision modules. Inference first autoregressively predicts the translation and then uses the resulting representation to condition image generation.
## Supported and evaluated translation directions
The paper evaluates the following directions:
- German → English (`De → En`)
- English → German (`En → De`)
- French → English (`Fr → En`)
- Romanian → English (`Ro → En`)
- English → French (`En → Fr`)
- English → Czech (`En → Cs`)
- English → Russian (`En → Ru`)
- English → Romanian (`En → Ro`)
Other language directions are not guaranteed to provide comparable quality.
## Checkpoint contents
| Path | Purpose |
|---|---|
| `univa/` | Final combined UniTranslator task checkpoint, including the multimodal model, denoiser, UGAM, and SMD weights |
| `lora/` | Rank-64 LoRA adapter used in stage-two Qwen2.5-VL fine-tuning |
| `denoise_projector.bin` | Standalone denoise-projector/UGAM checkpoint artifact |
| `pytorch_model/` | DeepSpeed training state for resuming training |
| `random_states_*.pkl`, `scheduler.bin`, `latest` | Training-resume metadata |
For inference, download `univa/` and `lora/`. The large DeepSpeed optimizer and random-state files are not required.
## Installation
```bash
git clone https://github.com/SeerRay-Lab/Unitranslator.git
cd Unitranslator
conda create -n univa python=3.10 -y
conda activate univa
pip install -r requirements.txt
pip install flash_attn --no-build-isolation
```
The reference environment uses PyTorch 2.7.1, Transformers 4.57.0, Diffusers 0.32.2, Accelerate 1.5.2, and PEFT 0.10.0.
## Download
Download only the files needed for inference:
```bash
hf download SeerRay-Lab/Unitranslator \
--include "univa/*" \
--include "lora/*" \
--local-dir checkpoints/Unitranslator
```
UniTranslator also depends on Qwen2.5-VL-3B-Instruct and FLUX.1-Kontext-dev:
```bash
hf download Qwen/Qwen2.5-VL-3B-Instruct \
--local-dir checkpoints/Qwen2.5-VL-3B-Instruct
hf download black-forest-labs/FLUX.1-Kontext-dev \
--local-dir checkpoints/FLUX.1-Kontext-dev
```
FLUX.1-Kontext-dev is gated. You must first accept its license on the [model page](https://huggingface.co/black-forest-labs/FLUX.1-Kontext-dev) and authenticate with Hugging Face.
## Inference
### 1. Construct the base hybrid checkpoint
The released inference code reconstructs the base Qwen2.5-VL + FLUX hybrid model before loading the UniTranslator task weights and LoRA adapter:
```bash
python scripts/make_univa_qwen2p5vl_tf.py \
--origin_qwenvl_ckpt_path checkpoints/Qwen2.5-VL-3B-Instruct \
--origin_flux_ckpt_path checkpoints/FLUX.1-Kontext-dev \
--save_path checkpoints/UniWorld_Kontext_3b_TF
```
### 2. Translate a directory of images
```bash
python infer_dir_tf.py \
--base_model_path checkpoints/UniWorld_Kontext_3b_TF \
--lora_adapter_path checkpoints/Unitranslator/lora \
--flux_finetune_path checkpoints/Unitranslator/univa \
--flux_base_path checkpoints/FLUX.1-Kontext-dev \
--input_dir path/to/input_images \
--output_dir results/de_to_en \
--gpu_id 0 \
--total_gpus 1 \
--source_language German \
--target_language English \
--dtype bf16 \
--height 1024 \
--width 1024 \
--num_inference_steps 50 \
--guidance_scale 5.0
```
The generated images and a JSONL file containing the predicted translations are written to `--output_dir`.
For multi-GPU directory inference, launch one process per GPU with different `--gpu_id` values and the same `--total_gpus`. Input images are assigned to processes by round-robin sharding.
The prompt format used by the inference script is:
```text
Translate all {source_language} texts into {target_language}.
```
### Hardware note
The paper reports approximately **50 GB peak GPU memory** and **9.51 seconds per image** under its evaluation setting. Actual memory use and latency depend on resolution, precision, hardware, and inference steps. A high-memory CUDA GPU is recommended.
## Training
UniTranslator uses a two-stage training strategy:
1. **Module warm-up:** freeze the pretrained Qwen2.5-VL and diffusion backbones and optimize the task-specific alignment and spatial modules.
2. **Joint fine-tuning:** jointly train the understanding and generation paths, including rank-64 Qwen2.5-VL LoRA adapters, UGAM, SMD, and MMDiT attention projections.
The paper reports BF16 mixed precision, AdamW, gradient checkpointing, gradient accumulation of 8, and NVIDIA H800 GPUs. See the configuration files under [`scripts/denoiser/`](https://github.com/SeerRay-Lab/Unitranslator/tree/main/scripts/denoiser) for the released training setup.
The repository provides `train_stage1.sh` and `train_stage2.sh` as reference launchers. Update their configuration paths for your environment before running them; the checked-in scripts and YAML files contain project-local paths and may require adaptation.
### Data preparation
```bash
# Stage-one supervision
python convert_en_de.py
# Stage-two mask supervision
python convert_transv_mask.py
```
Datasets used by the project include:
- [Translatotron-V](https://drive.google.com/drive/folders/12r54tAQ98Oxtp6Eb3dvaoiOKzu4lD_7h?usp=sharing)
- [IIMT30k](https://huggingface.co/datasets/yztian/IIMT30k)
- [MTedIIMT](https://huggingface.co/datasets/yztian/MTedIIMT)
- [PRIM](https://huggingface.co/datasets/yztian/PRIM)
Users are responsible for complying with the licenses and terms of each dataset.
## Evaluation results
All numbers below are reported in the UniTranslator paper.
### Translatotron-V
| Direction | BLEU ↑ | Structure-BLEU ↑ | SSIM ↑ |
|---|---:|---:|---:|
| De → En | **25.03** | **24.86** | **0.8184** |
| En → De | **13.41** | **13.36** | **0.7887** |
| Fr → En | **27.77** | **27.14** | **0.8060** |
| Ro → En | **18.45** | **18.29** | **0.8045** |
### IIMT30k test set
| Direction | BLEU ↑ | COMET ↑ | FID ↓ |
|---|---:|---:|---:|
| De → En | **14.7** | **59.8** | **8.9** |
| En → De | **13.0** | **45.5** | 12.5 |
### PRIM
| System | Average BLEU ↑ | Average COMET ↑ | Average FID ↓ |
|---|---:|---:|---:|
| Translatotron-V | 1.4 | 32.2 | 69.1 |
| VisTrans | 11.3 | 47.0 | 28.8 |
| **UniTranslator** | **12.8** | **50.7** | **22.9** |
BLEU and COMET evaluate translation quality, Structure-BLEU additionally considers text-region alignment, SSIM measures source/target structural similarity, and FID evaluates generated-image distribution quality.
## Limitations and risks
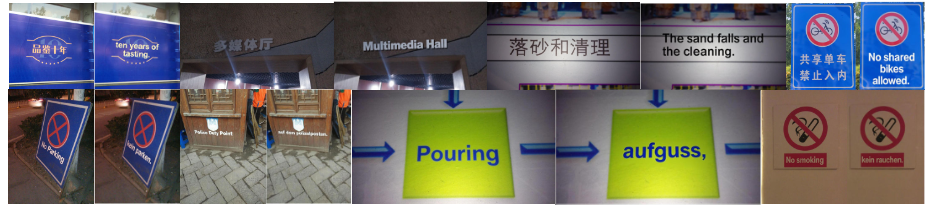
- Low-resource language settings may produce missing words or incorrect character rendering.
- Highly stylized typography can lead to imperfect preservation of strokes, glow, erosion, or cursive deformation.
- Complex backgrounds may be altered outside the intended text region, including texture, color, or local appearance changes.
- Small, dense, curved, occluded, or low-resolution text remains challenging.
- Results may vary for language directions and domains not represented in the evaluated datasets.
- Generated translations and images should be verified before use in safety-critical, legal, medical, financial, or public-facing contexts.
- Input images may contain personal or copyrighted material; users are responsible for lawful processing and distribution.
## License
The source code repository is released under the [Apache 2.0 License](https://github.com/SeerRay-Lab/Unitranslator/blob/main/LICENSE).
The released model is based in part on [FLUX.1-Kontext-dev](https://huggingface.co/black-forest-labs/FLUX.1-Kontext-dev). Use of the model weights is therefore also subject to the [FLUX.1 Dev Non-Commercial License](https://huggingface.co/black-forest-labs/FLUX.1-Kontext-dev/blob/main/LICENSE.md) and its Acceptable Use Policy. Users must comply with all applicable upstream model and dataset licenses; the more restrictive terms apply where relevant.
## Citation
If you find this work useful, please cite:
```bibtex
@article{lyu2026unitranslator,
title={UniTranslator: A Unified Multi-modal Framework for End-to-end In-Image Machine Translation},
author={Lyu, Jiahao and Fu, Pei and Li, Zhenhang and Zhang, Shaojie and Yang, Jiahui and Ma, Can and Zhou, Yu and Luo, Zhenbo and Luan, Jian},
journal={arXiv preprint arXiv:2606.24333},
year={2026}
}
```
## Acknowledgements
This project builds on [UniWorld](https://github.com/PKU-YuanGroup/UniWorld-V1), [Qwen2.5-VL](https://huggingface.co/Qwen/Qwen2.5-VL-3B-Instruct), and [FLUX.1-Kontext-dev](https://huggingface.co/black-forest-labs/FLUX.1-Kontext-dev). See the paper and GitHub repository for the complete acknowledgements.
|