

MiniMax-H3 PE is a prompt enhancement model fine-tuned from Gemma4-12B-IT for MiniMax-H3 audio and video generation.
The model is jointly trained to enhance prompts for the FL2VA / Ref2VA input formats using a single set of PE weights. It uses user instructions and task context to organize audiovisual descriptions for H3 generation. This repository provides two independent ComfyUI workflows, one for FL2VA and one for Ref2VA, along with standard and quantized model versions.
Input Formats and Use Cases
| H3 input format | Use cases | Prompt enhancement focus |
|---|---|---|
| FL2VA | T2VA (text only), I2VA (first frame), L2VA (last frame), and FL2VA (first and last frames) | Organize scenes, actions, camera movement, changes over time, and sound descriptions; incorporate frame constraints when provided |
| Ref2VA | Reference-conditioned generation | Organize subject definitions, reference relationships, content retention, actions, camera movement, and sound descriptions |
Here, FL2VA refers to an input format used by MiniMax-H3, covering T2VA, I2VA, and FL2VA modes. Choose the independent FL2VA / Ref2VA workflow that matches your generation task.
Interactive Demo
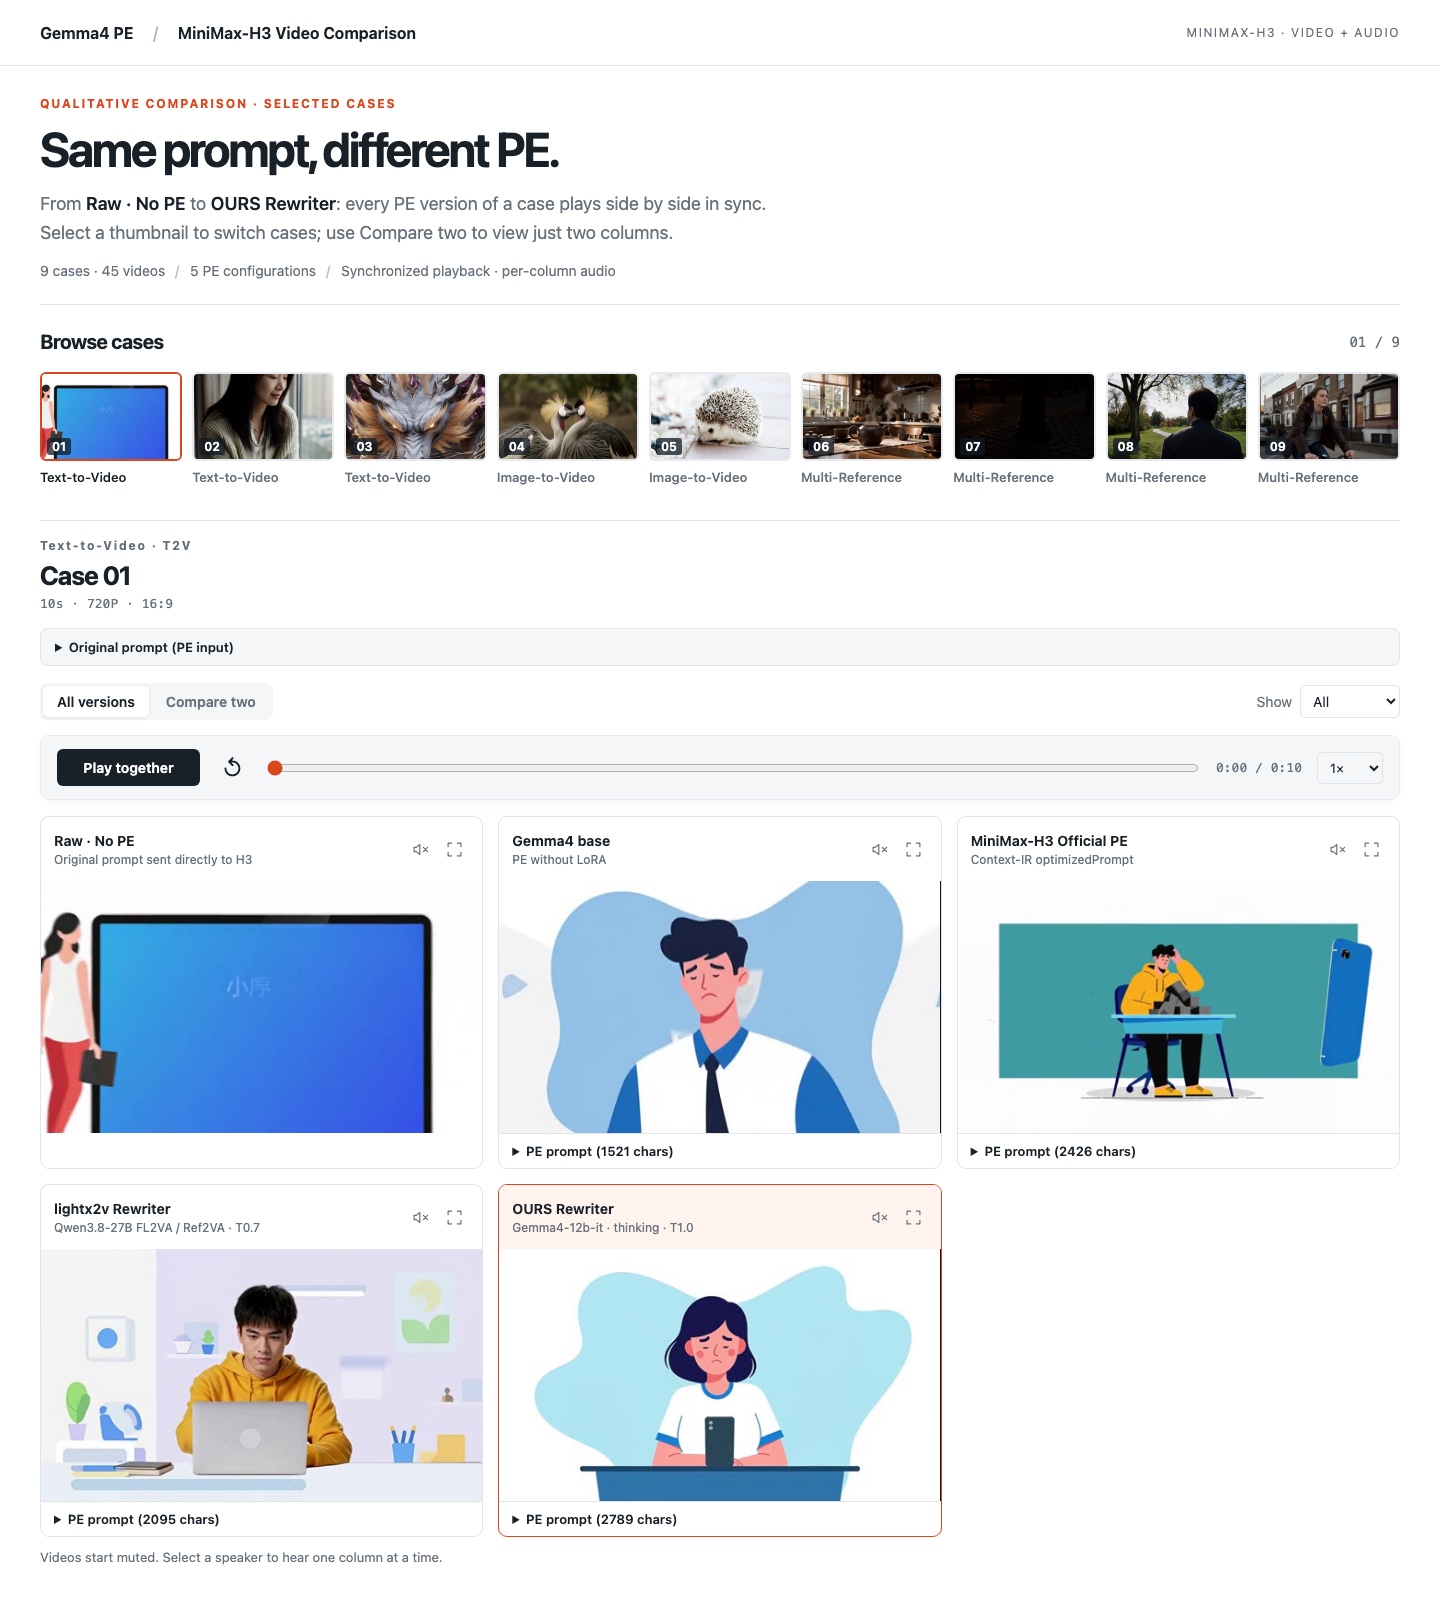
Explore the MiniMax-H3 prompt enhancement comparison →
Compare Raw (No PE), Gemma4 base, MiniMax-H3 Official PE, lightx2v Rewriter, and Ours across 9 selected cases and 45 videos. The showcase covers text-to-video, image-to-video, and multi-reference generation, with synchronized playback, two-column comparisons, selectable audio, and expandable original and enhanced prompts.
Workflow Overview
                      User instructions + task context
                                      ↓
                  ┌───────────────────┴───────────────────┐
                  ↓                                       ↓
           FL2VA Workflow                          Ref2VA Workflow
                  │                                       │
                  └───────────────────┬───────────────────┘
                                      ↓
                      Ours Prompt Rewriter (BF16 / FP8 / Int8)
                                      ↓
                               Enhanced prompt
                                      ↓
                         MiniMax-H3 (FL2VA / Ref2VA)
                                      ↓
                               Video and audio
The two workflows are alternative options. PE produces an enhanced prompt, which the corresponding H3 generation pipeline uses with the required assets to generate video and audio.
ComfyUI Workflows
Two independent workflows are available. Download the one that matches your task and import it into ComfyUI:
| Workflow | Use cases | Download |
|---|---|---|
| FL2VA Workflow | Prompt enhancement for first and last frames generation | minimax_h3_gemma4_pe_fl2va.json |
| Ref2VA Workflow | Prompt enhancement for reference-conditioned generation | minimax_h3_gemma4_pe_ref2va.json |
Model Download
This repository provides standard and quantized PE models. Both workflows share the same PE model. Choose a model file supported by the workflow's loader node.
| Version | Model file | Precision / quantization |
|---|---|---|
| Standard | Hugging Face / ModelScope | BF16 |
| Quantized | Hugging Face / ModelScope | FP8/Int8 |
Usage
Download the model files required by your chosen workflow, place them in the corresponding directories, and install the required custom nodes.
Restart ComfyUI or refresh the model list.
Drag the JSON file for your chosen FL2VA Workflow / Ref2VA Workflow onto the ComfyUI canvas.
Select the standard model or a compatible quantized model in the PE loader node, and check that all other loader nodes point to the correct files.
Select the task mode and prepare your inputs:
FL2VA: Load first and last frames in the FL2VA workflow and describe the content you want to retain or use.
Ref2VA: Load reference assets in the Ref2VA workflow and describe the content you want to retain or use.
Run the workflow to obtain the enhanced prompt and use it in the corresponding H3 generation pipeline.
Keep asset order and reference numbering consistent with the selected workflow. Follow each workflow's configuration for its specific input requirements.
Acknowledgements
We thank the Google Gemma team for the base model and the MiniMax team for MiniMax-H3 and its prompt writing guides.
- Downloads last month
- 641