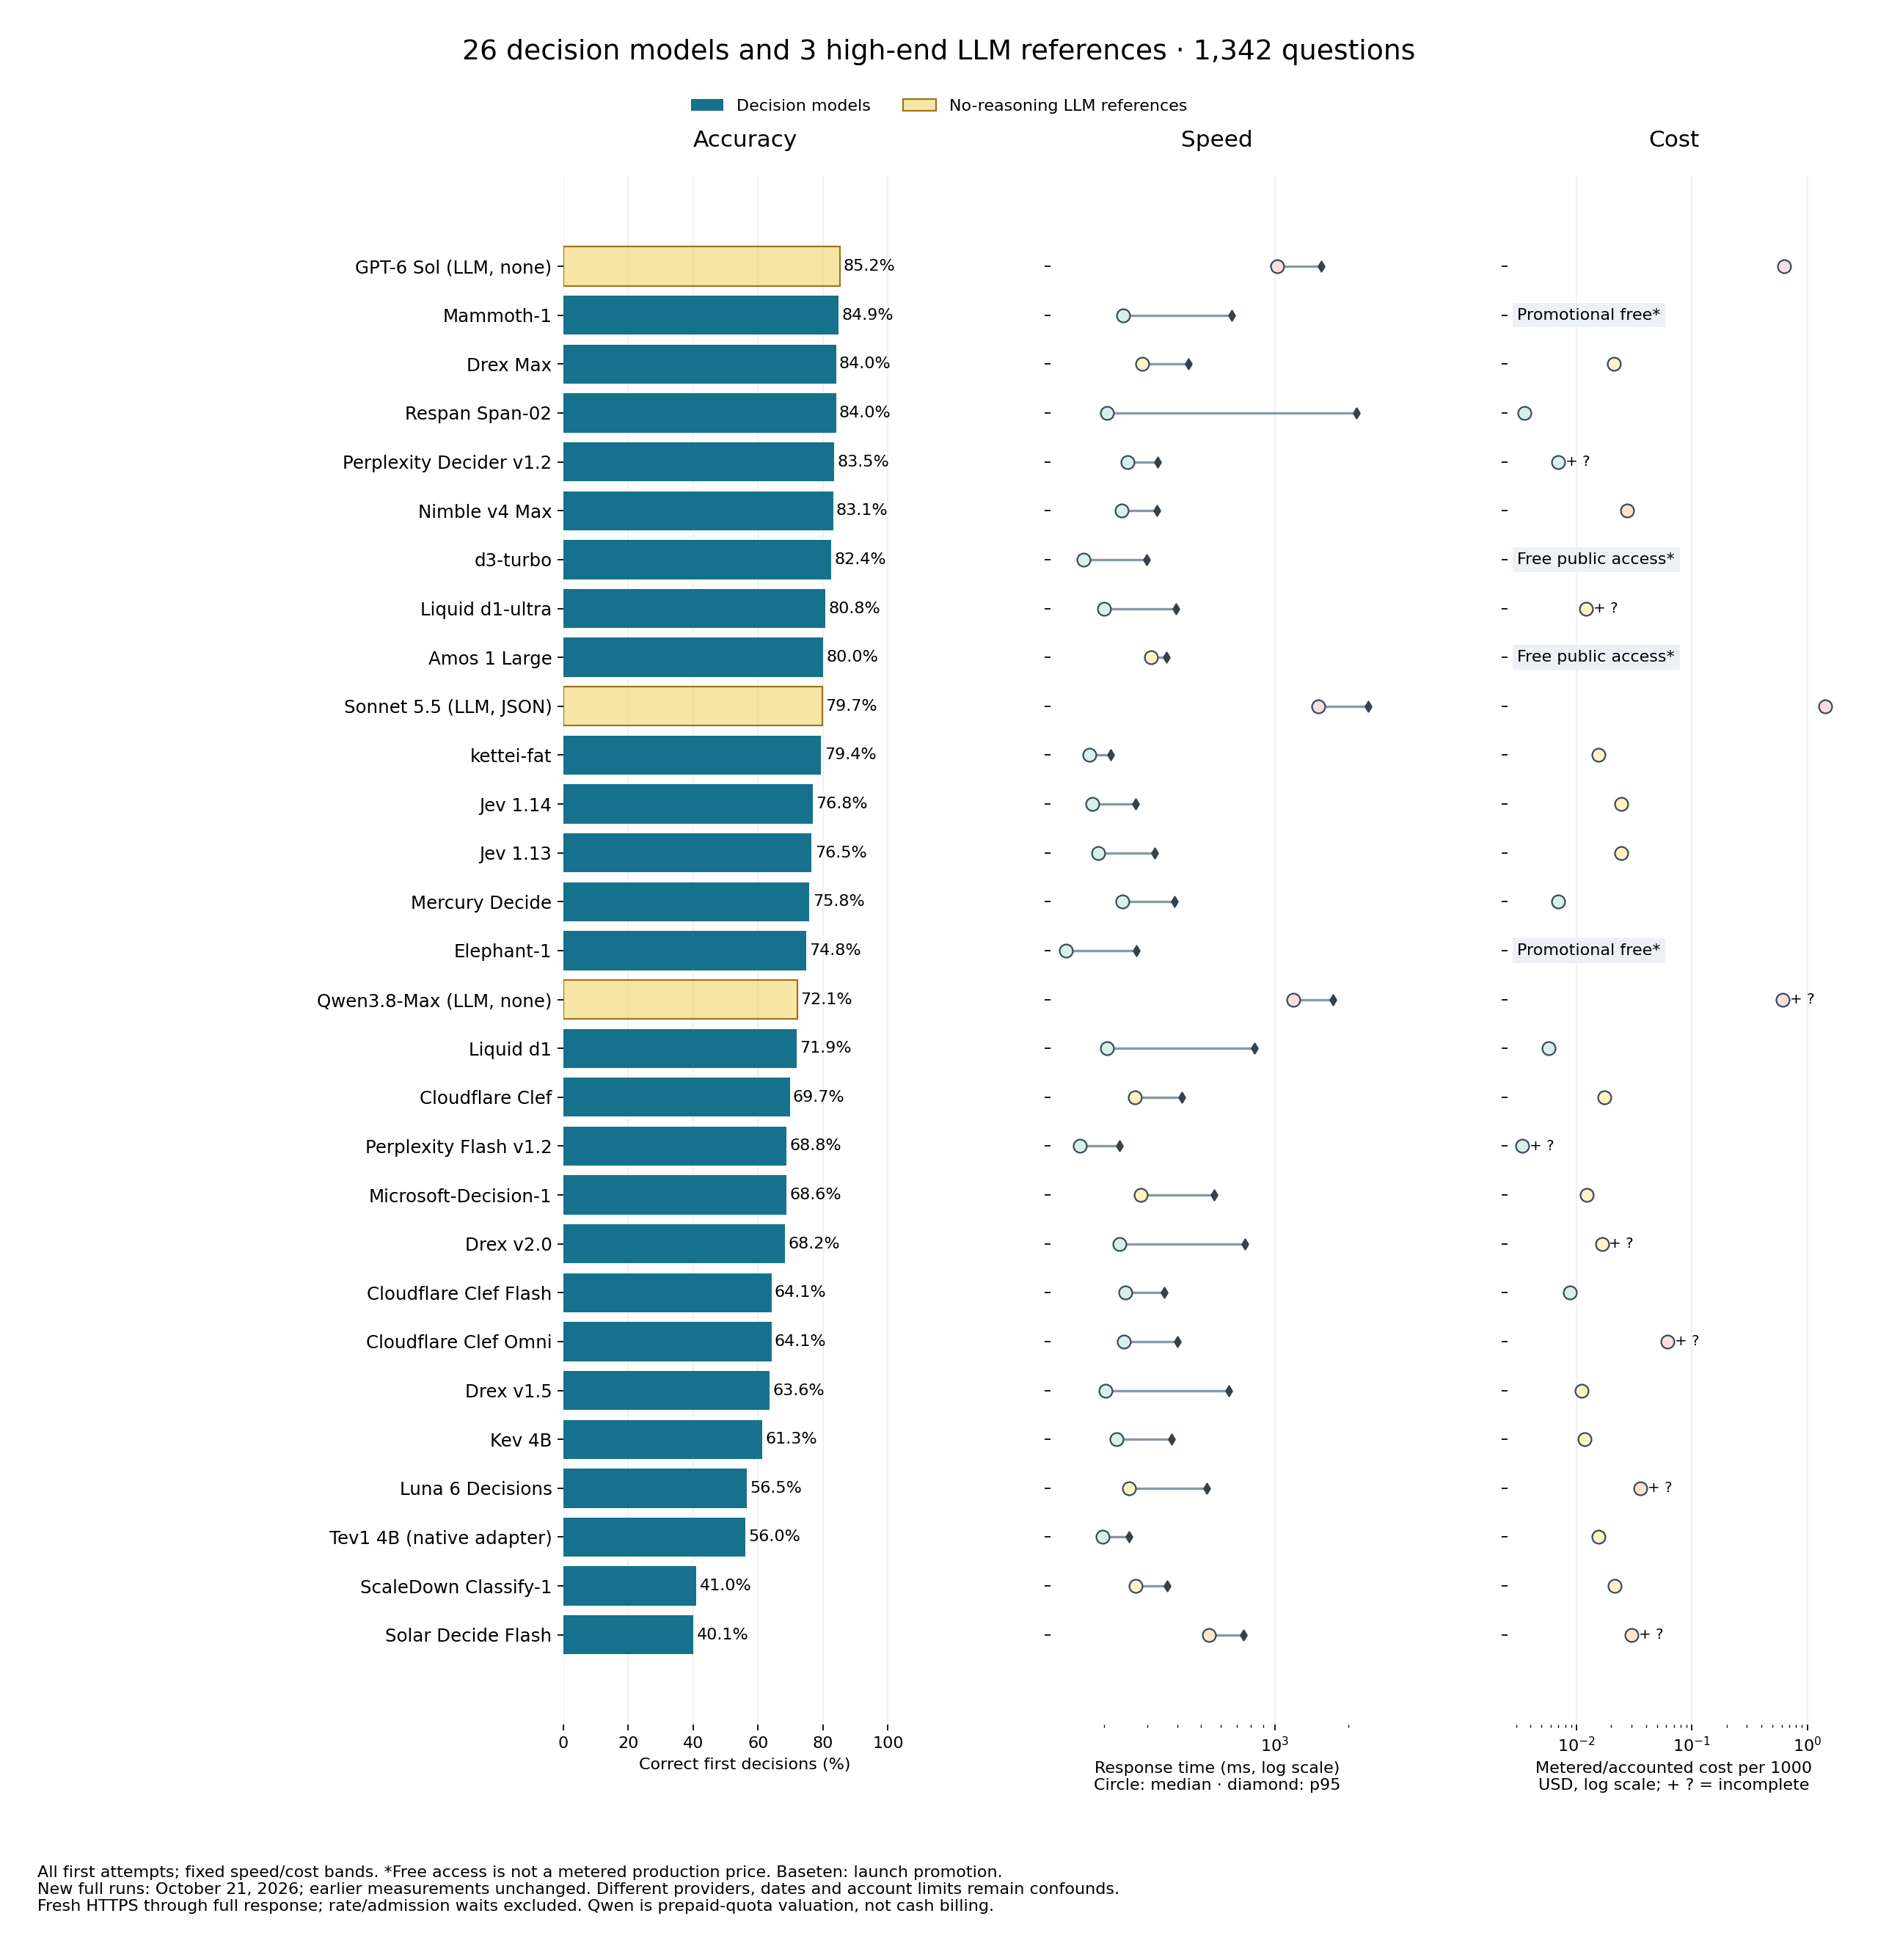
Mammoth-1 tops my System 1 decision benchmark — 84.9%, 240 ms median

I tested Mammoth-1 on my 1,342-question text decision benchmark, across 31 categories. It answered 1,139 correctly (84.9%), the highest observed score among the 26 specialized decision models tested so far.
GPT-6 Sol without reasoning scored 1,143/1,342 (85.2%) — four more correct answers. Mammoth’s median response was 240 ms, versus 1,023 ms for Sol. That small accuracy gap does not establish a reliable ordering.
Mammoth’s strongest results included:
- One-to-one assignments: 64/67 — matching each person or object to exactly one available slot.
- Exceptions and priority rules: 57/58 — applying the right rule when a specific exception overrides a general one.
- Tracking what others know: 47/50 — for example, where someone will search after an object moved while they were absent.
Its results were less consistent on exact truth counting (44/71) and step-by-step procedures (18/48). Span-02 scored 33/48 on the procedures, despite a lower overall total.
This measures immediate five-choice decisions, without tools or agentic iteration, not unrestricted reasoning. Mammoth was tested through Baseten directly on October 21, 2026, under its launch promotion; that is not a permanent production-price claim. Earlier comparison runs used different dates and providers. This is a developing benchmark with dependent variants and uneven category sizes.
Full GitHub benchmark, questions and analysis · Readable report with named categories, timings and costs