
Buckets:


Liger Kernel Integration
Liger Kernel is a collection of Triton kernels designed specifically for LLM training. It can effectively increase multi-GPU training throughput by 20% and reduce memory usage by 60%. That way, we can 4x our context length, as described in the benchmark below. They have implemented Hugging Face compatible RMSNorm, RoPE, SwiGLU, CrossEntropy, FusedLinearCrossEntropy, with more to come. The kernel works out of the box with FlashAttention, PyTorch FSDP, and Microsoft DeepSpeed.
With this memory reduction, you can potentially turn off cpu_offloading or gradient checkpointing to further boost the performance.
| Speed Up | Memory Reduction |
|---|---|
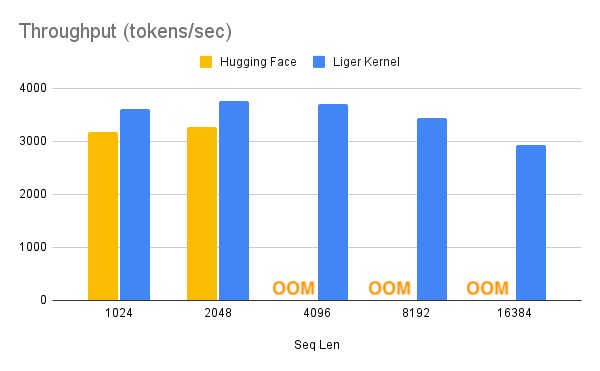 |
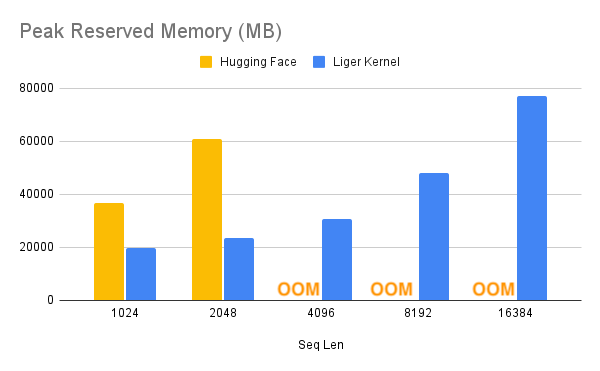 |
use_liger_kernel=True is deprecated in SFTTrainer, DPOTrainer, KTOTrainer, GRPOTrainer and RLOOTrainer, and will be removed in v2.0.0. These trainers compute the log-probabilities with a fused LM head, so only Liger's layer kernels (RMSNorm, RoPE, SwiGLU) apply. Use the Hub kernels instead, with model_init_kwargs={"use_kernels": True}.
Supported Trainers
Liger Kernel is supported in the following TRL trainers:
- SFT (Supervised Fine-Tuning)
- DPO (Direct Preference Optimization)
- GRPO (Group Relative Policy Optimization)
- KTO (Kahneman-Tversky Optimization)
Usage
- First, install Liger Kernel:
pip install liger-kernel
- Once installed, set
use_liger_kernel=Truein your trainer config. No other changes are needed!
from trl import SFTConfig

training_args = SFTConfig(..., use_liger_kernel=True)
from trl import DPOConfig

training_args = DPOConfig(..., use_liger_kernel=True)
from trl import GRPOConfig

training_args = GRPOConfig(..., use_liger_kernel=True)
from trl import KTOConfig

training_args = KTOConfig(..., use_liger_kernel=True)
To learn more about Liger-Kernel, visit their official repository.
Xet Storage Details
- Size:
- 2.66 kB
- Xet hash:
- 7dbb3d71c87beb5014adb61454d4bfc0f38cb21d62948d4060acab2cf927d8ea
Xet efficiently stores files, intelligently splitting them into unique chunks and accelerating uploads and downloads. More info.