

| Name | Size | Uploaded | Xet hash |
|---|---|---|---|
| openseg | 1,521 items | ||
| processed | 6,086 items | ||
| scannet200_mca | 1,511 items | ||
| scannet200_mea | 1,511 items | ||
| scannet_mca | 1,511 items | ||
| scannet_mea | 1,511 items | ||
| .gitattributes | 2.31 kB xet | b6a9e0dd | |
| README.md | 4.93 kB xet | 634f02b6 | |
| backbone_scannet.ckpt | 476 MB xet | 4f875d39 | |
| backbone_scannet200.ckpt | 159 MB xet | 1677d55a | |
| replica.ckpt | 371 MB xet | b07bbd35 | |
| scannet.ckpt | 186 MB xet | 2612cc68 | |
| scannet200.ckpt | 371 MB xet | 7b74ba5a |
Segment Any 3D Object with Language
Seungjun Lee* ·
Yuyang Zhao* ·
Gim Hee Lee
National University of Singapore
*equal contribution
ICLR 2025
Code | Paper | Project Page
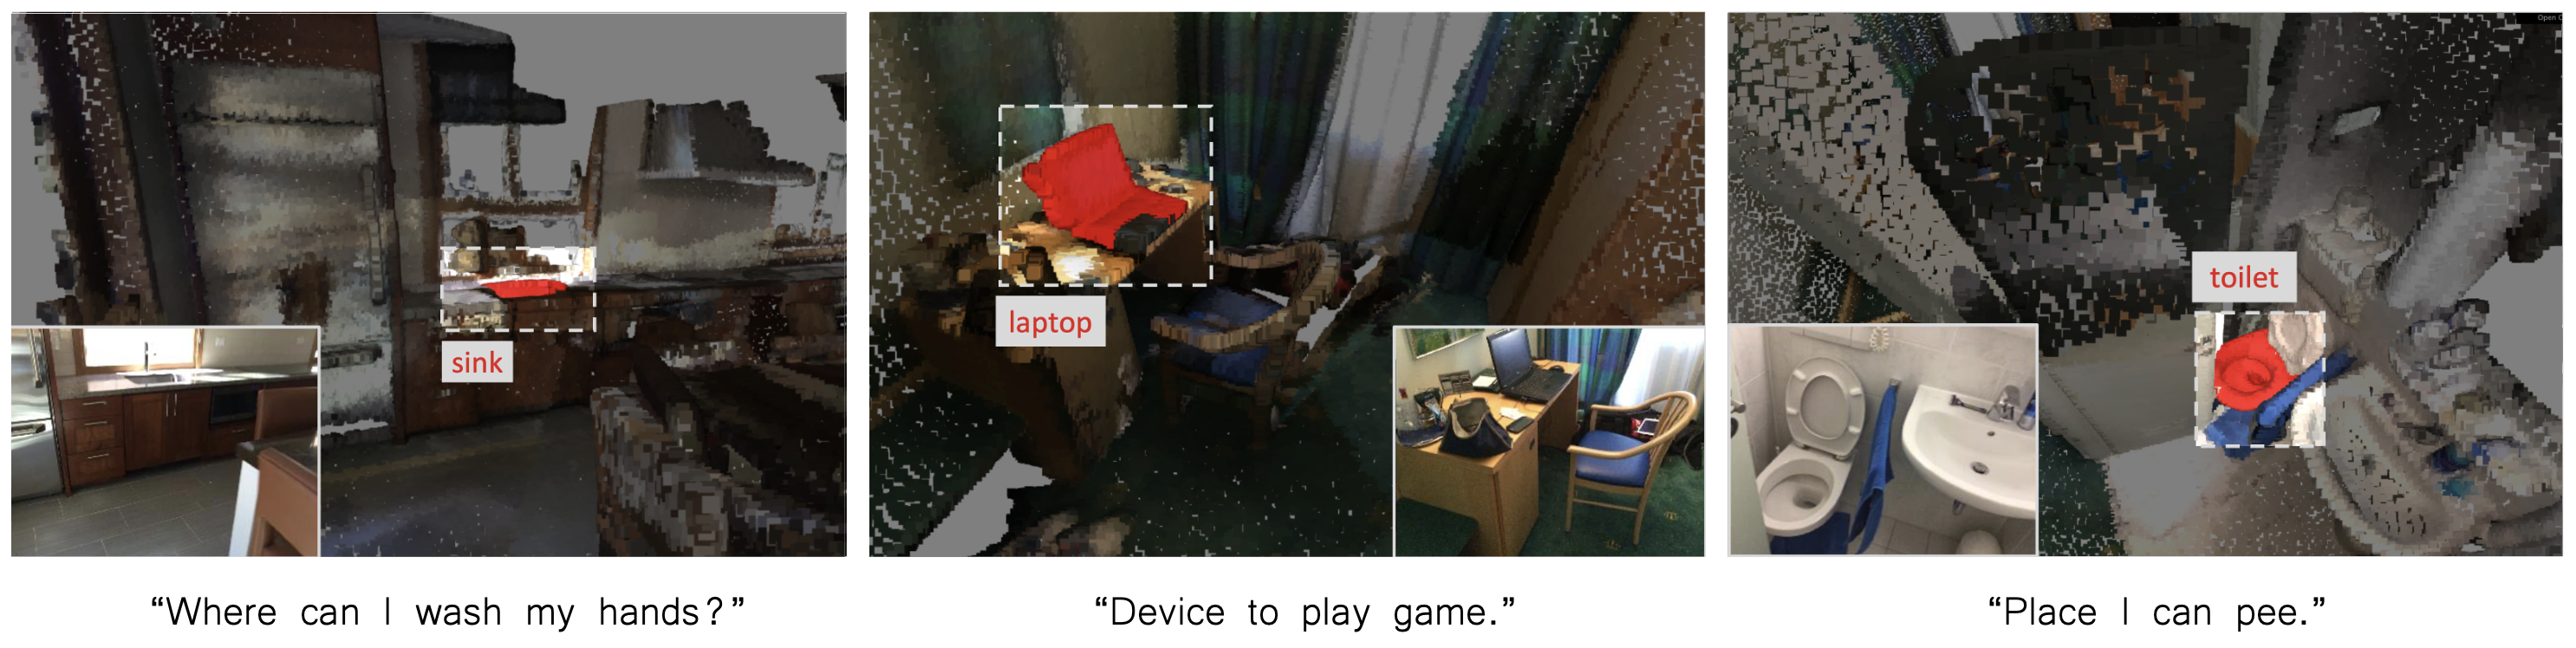
SOLE is highly generalizable and can segment corresponding instances with various language instructions, including but not limited to visual questions, attributes description, and functional description.
In this repository, we provide the preprocessed data and official weights to train and evaluate our SOLE model. The provided data are listed below:
Pre-processed data
- Pre-processed 3D data
- Precomputed per-point CLIP features
- Precomputed features of MCA and MEA
Weights
Backbone weights
Official weights
Data Configuration
Pre-processed Data
We first download the official ScanNet dataset and subsequently process it with running datasets/preprocessing/scannet_preprocessing.py script in the SOLE github repository. If you want to process the data by yourself, 1) first download the official ScanNet dataset and 2) run the command below:
python -m datasets.preprocessing.scannet_preprocessing preprocess \
--data_dir="PATH_TO_RAW_SCANNET_DATASET" \
--save_dir="data/processed/scannet" \
--git_repo="PATH_TO_SCANNET_GIT_REPO" \
--scannet200=false/true
Pre-computed per-point CLIP features
This files provide pointwise CLIP features computed with following OpenScene. Each file consists of one tensor which has the shape of:
torch.Size([N, 768])
where N is the number of points in one scene.
Pre-computed MCA features
This files provide generated captions for each instance and CLIP text features of corresponding caption. Example of the MCA file is:
{
  "captions" : ["a wooden desk with the monitor", ...], // list of generated captions for every instances in a scene
  "features" : [torch.Size([1, 768]), ...], // list of CLIP text features for generated captions
}
Pre-computed MEA features
This files provide CLIP text features of the entity-level captions for each instance. Example of the MEA file is:
{
  "guide" : torch.Size([K, 768]), // CLIP text features of entity-level captions for every K instances
}
where K is the number of intances in one scene.
Citation
If you find our code or paper useful, please cite
@article{lee2024segment,
      title = {Segment Any 3D Object with Language},
      author = {Lee, Seungjun and Zhao, Yuyang and Lee, Gim Hee},
      year = {2024},
      journal   = {arXiv preprint arXiv:2404.02157},
}
- Total size
- 380 GB
- Files
- 13,658
- Last updated
- Nov 2
- Pre-warmed CDN
- US EU US EU