

H3Remover: Reinforcing Video Object Removal without Paired Data
Paper • 2611.24633 • Published
✨ Remove Anything with H3Remover.

GitHub Code · Watch eight comparisons · 🏃 Run the Gradio demo locally · Quickstart · Citation
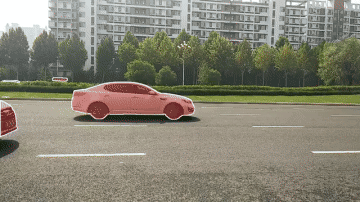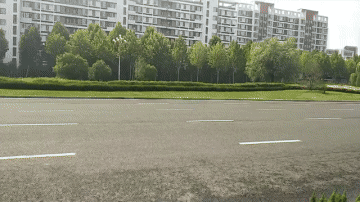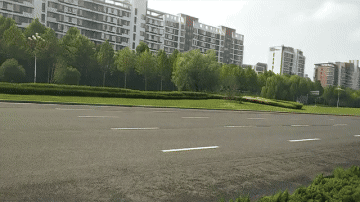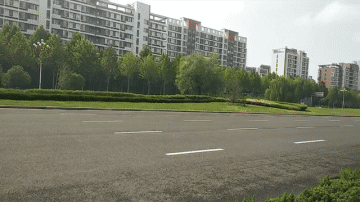
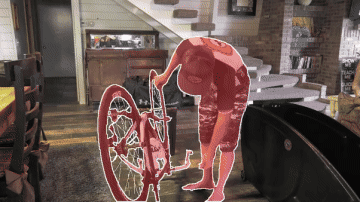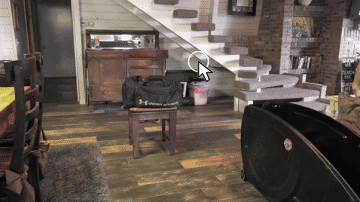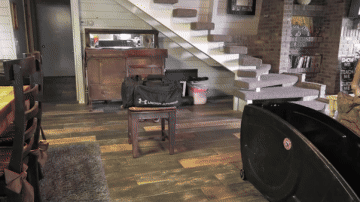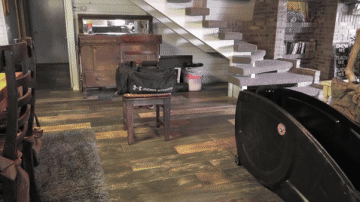
Left: clearing traffic from an intersection (MOSE). Right: a person lifting a bicycle indoors (DAVIS). Click either preview for the synchronized input and result, or watch the 100-example showcase.
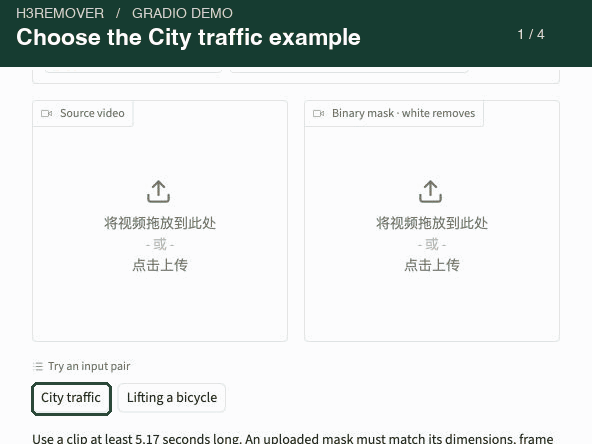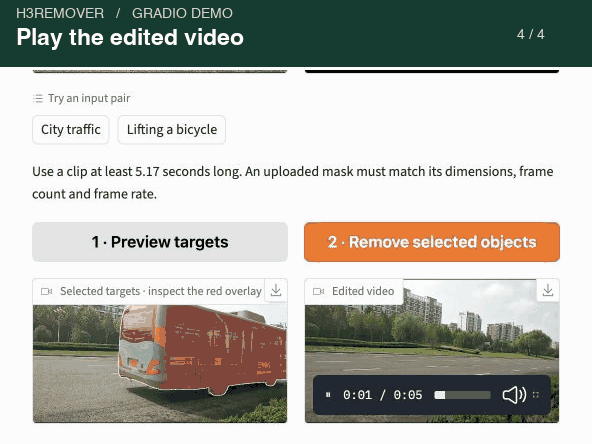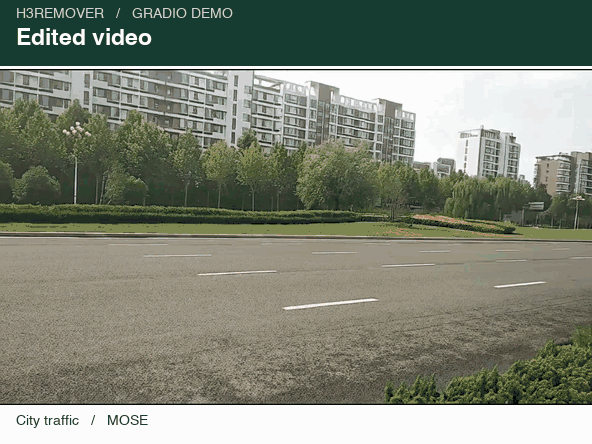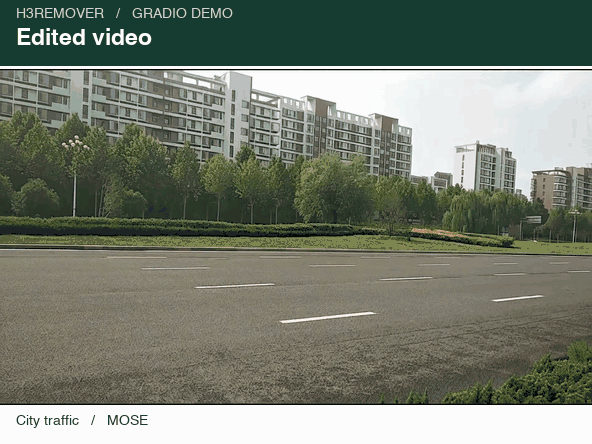
From a mask to a finished edit in the local Gradio demo. The final video comes from this run; the inference wait is shortened.
Eight clips from the released adapter. In every player, the left shows the input with the selected targets highlighted; the right shows the edit at the same instant. Watch the shadows on the dunes, the reflection on the lake, or the second camel that stays in the scene.
| People and long shadows on sand PROVE-H · Open video |
A boat and its reflection WIPER · Open video |
| One camel, not the other DAVIS · Open video |
Remove the players, keep the ball PROVE-H · Open video |
| Traffic beneath an overpass Waymo · Open video |
Two people in a kitchen PROVE-M · Open video |
| A deer against a snowy forest WIPER · Open video |
A mirrored ball and its shadow WIPER · Open video |
Browse all 88 comparisons on the project page · Watch the full showcase film
Give H3Remover a video and a mask of what should disappear. The mask can select one object or several at once. The edit targets not just the object itself, but also the shadows, reflections and light it casts, while preserving unrelated textures and camera motion. This release is a LoRA adapter for MiniMax H3 Ref2VA, trained with reinforcement learning without paired object-free targets.
No street mask yet? The optional street workflow selects people and vehicles with SAM 3.1 and uses Pi4 to propose other moving regions. Preview the combined mask before editing.
Use Linux, an NVIDIA GPU, and FFmpeg. The reference setup uses Python 3.13 and PyTorch 2.10.0 with CUDA 13:
git clone https://github.com/chenkangjie1123/H3Remover.git
cd H3Remover
conda create -n h3remover python=3.13 -y
conda activate h3remover
python -m pip install torch==2.10.0 torchvision==0.25.0 --index-url https://download.pytorch.org/whl/cu130
python -m pip install -r requirements.txt
python download_weights.py
This downloads the pinned adapter and full Ref2VA base to weights/ and verifies the adapter checksum. If access is required, accept the model licenses and run hf auth login first.
python infer.py \
  --video examples/street/source.mp4 --mask examples/street/mask.mp4 \
  --output outputs/street.mp4
Replace the example with your own video and synchronized binary mask. White selects objects to remove; black keeps the rest. The pipeline creates the visual mask reference automatically.
The output is a silent 124-frame, 24 FPS, 960 × 544 MP4, using 50 inference steps. Provide at least 5.17 seconds; longer inputs use the first clip. Component CPU offloading and tiled VAE decoding are enabled. See the inference guide for input previews and settings.
| Property | Value |
|---|---|
| Base | MiniMax H3 Ref2VA |
| Rank / alpha | 16 / 16 |
| Format | Safetensors, FP32 |
| Size | 160,613,888 bytes |
SHA-256: 6fe5b881ec1a9804af005a3ed512e54a6c3341b0e5a2204323a2ed6482262c84
@misc{chen2026h3removerreinforcingvideoobject,
  title         = {H3Remover: Reinforcing Video Object Removal without Paired Data},
  author        = {Kangjie Chen and Xiangyu Li and Jinhao Deng and Dongbin Zhang and
                   Chaoda Zheng and Shijia Chen and Yuqi Zhang and Choo Sin Wai and
                   Boyi Sun and Puyi Wang and Yu Zhang and Xianming Liu and Boyang Wang},
  year          = {2026},
  eprint        = {2611.24633},
  archivePrefix = {arXiv},
  primaryClass  = {cs.CV},
  url           = {https://arxiv.org/abs/2611.24633}
}
The adapter is a modified derivative of MiniMax H3, distributed under the MiniMax H3 Community License. The base model is downloaded separately.
Base model
MiniMaxAI/MiniMax-H3