
Prompt stringlengths 10 31k | Chosen stringlengths 3 29.4k | Rejected stringlengths 3 51.1k | Title stringlengths 9 150 | Tags listlengths 3 7 |
|---|---|---|---|---|
This is an embarrassingly simple question. I'm trying to understand how to incorporate a simple Python function in the first Django app I'm building. Here is my views.py file...
```
from django.shortcuts import render
from noticeboard.models import Listings
from django.views import generic
from django.template import ... | There are a few possibilities:
1. Pass the variable through the `upper` template filter in the html template, like so:
```
{{ listing.listing|upper }}
```
... as jpic said. Here, the context object is "listing", and its attribute that you want to upcase is listing.listing.
2. Create a method on the model... | Why not just use the [`upper` template filter](https://docs.djangoproject.com/en/dev/ref/templates/builtins/#upper) ?
No need to write any pure python to display a view context variable in uppercase ... | How to write Python Code in Django | [
"",
"python",
"django",
""
] |
Is it possible to download and name a file from website using Python 2.7.2 and save it on desktop? If yes, then how to do it? | Here are 3 way to do it using [urllib2](http://docs.python.org/2/library/urllib2.html), [requests](http://docs.python-requests.org/en/latest/) or [urllib](http://docs.python.org/3.0/library/urllib.request.html)
```
import urllib2
with open('filename','wb') as f:
f.write(urllib2.urlopen(URL).read())
f.close()
... | You can use `urllib.urlretrieve`:
```
urllib.urlretrieve(url[, filename[, reporthook[, data]]])
```
From [docs](http://docs.python.org/2/library/urllib.html#urllib.urlretrieve):
> Copy a network object denoted by a URL to a local file, if necessary. If the
> URL points to a local file, or a valid cached copy of the ... | Download, name and save a file using Python 2.7.2 | [
"",
"python",
""
] |
I have an adjacency list maintained between 2 sets of entities
```
dict1={'x1':[y1,y2],'x2':[y2,y3,y4]...}
dict2={'y1':[x1],'y2':[x1,x2],'y3':[x2]....}
```
Given a new entry coming in ,what is the recommended way to update the dicts.
Assuming the entry is 'x3':[y2,y4].
Please note that x3 may not necessarily be a... | First, I'd suggest `defaultdict` so that referencing an index that doesn't exist will initialize it to an empty list.
```
from collections import defaultdict
dict1 = defaultdict(list)
dict1['x1'] = ['y1','y2']
dict1['x2'] = ['y2','y3','y4']
dict2 = defaultdict(list)
dict2['y1'] = ['x1']
dict2['y2'] = ['x1','x2']
dict... | Why can't you do it in a simple way?
```
dict1[x3] = [y2, y4]
for yi in dict1[x3]:
if yi in dict2.keys():
dict2[yi].append(x3)
else:
dict2[yi] = [x3]
``` | inserting a new entry into adjacency list | [
"",
"python",
""
] |
I have the following equation:
```
result=[(i,j,k) for i in S for j in S for k in S if sum([i,j,k])==0]
```
I want to add another condition in the if statement such that my result set does not contain (0,0,0). I tried to do the following:
`result=[(i,j,k) for i in S for j in S for k in S if sum([i,j,k])==0 && (i,j,k)... | You are looking for the [`and` boolean operator](http://docs.python.org/2/reference/expressions.html#boolean-operations) instead:
```
result=[(i,j,k) for i in S for j in S for k in S if sum([i,j,k])==0 and (i,j,k)!=(0,0,0)]
```
`&&` is [JavaScript](https://developer.mozilla.org/en-US/docs/Web/JavaScript/Reference/Ope... | Apart from that error instead of triple nested for-loops you can also use [`itertools.product`](http://docs.python.org/2/library/itertools.html#itertools.product) here to get the Cartesian product of `S * S * S`:
```
from itertools import product
result=[ x for x in product(S, repeat = 3) if sum(x)==0 and x != (0,0,0)... | How to use two conditions in an if statement | [
"",
"python",
"if-statement",
""
] |
I have a little problem with my SQL sentence. I have a table with a product\_id and a flag\_id, now I want to get the product\_id which matches all the flags specified. I know you have to inner join it self, to match more than one, but I don't know the exact SQL for it.
Table for flags
```
product_id | flag_id
... | > get the product\_id which ***matches all*** the flags specified
This problem is called [Relational Division](https://www.simple-talk.com/sql/t-sql-programming/divided-we-stand-the-sql-of-relational-division/). One way to solve it, is to do this:
* `GROUP BY product_id` .
* Use the `IN` predicate to specify which fl... | try this:
```
SELECT *
FROM your_table
WHERE flag_id IN(1,2,..);
``` | Selecting a value from multiple rows in MySQL | [
"",
"mysql",
"sql",
"attributes",
""
] |
I have a XML file with Russian text:
```
<p>все чашки имеют стандартный посадочный диаметр - 22,2 мм</p>
```
I use `xml.etree.ElementTree` to do manipulate it in various ways (without ever touching the text content). Then, I use `ElementTree.tostring`:
```
info["table"] = ET.tostring(table, encoding="utf8") #table i... | You use
```
info["table"] = ET.tostring(table, encoding="utf8")
```
which returns `bytes`. Then later you apply that to a format string, which is a `str` (unicode), if you do that you'll end up with a representation of the bytes object.
etree can return an unicode object instead if you use:
```
info["table"] = ET... | The problem is that ElementTree.tostring returns a binary object and not an actual string. The answer to this is:
```
info["table"] = ET.tostring(table, encoding="utf8").decode("utf8")
``` | How do I get this to encode properly? | [
"",
"python",
"xml",
"encoding",
"utf-8",
"python-3.x",
""
] |
I will try to explain but, if it is not clear, please let me know. English is not my first language.
I need some help with a query that would serve as condition to insert set of records or not.
First, I've got a db table EmployeeProviders.
In one of the stored procedures, I recalculate credits according to some cond... | I'll take a stab at it. Try this in the stored procedure:
```
if (EXISTS(select 3465,pr.plan_id,pr.id,epr.credits,effective_date from
providers pr left join @EmployeeProviders epr on
pr.id = epr.id and pr.plan_id = epr.plan_id and pr.credits = epr.credits and effective_date = '2013-07-01'
where epr.credits... | If I understand your question correctly, your problem can be solved by making your insert conditional on the outcome of an `Except`
```
if exists(
select ID, plan_id , credits from @Providers
except
SELECT id, plan_id, credits FROM @EmployeeProviders WHERE plan_id = 18753 and datediff(dd,effective_date,@StartDate) =... | Construct a query as a condition to insert set of records | [
"",
"sql",
"sql-server",
"sql-server-2008",
""
] |
Here is the problem I am looking at: Take a list of dictionaries. Inside this, you can have the obvious cases of valid and invalid results. So you write a simple ternary operator inside a list comprehension to get out a default message on failure. However, it gives the default for each failure.
In the case where you k... | The key is not in any of the three dictionaries, so the `'DEFAULT'` value is generated three times. If the first dictionary held the value and the other two did not, you would get a list with one value and two `'DEFAULT'`s. Anyway, try:
```
out = [i[key] for i in lis_dic if key in i] or ['DEFAULT']
``` | Unless you have a constraint on your data structure, the simplest solution would be to transform it once so it is trivial to retrieve the information you need every time. This is also likely more efficient, depending on what you are actually doing.
The transformed data structure would look like this:
```
transformed_... | Single failure result form ternary operator inside a list comprehension of a list of dictionaries in python | [
"",
"python",
"list",
"dictionary",
"list-comprehension",
"conditional-operator",
""
] |
i have a table with the following structure.

From that table i need to find the price using the range that was given in the table.
```
ex:
if i give the Footage_Range1=100 means it will give the output as 0.00 and
if Footage_Range1=101 means the output is 2.... | If i understood your requirements correctly you can try this:
```
SELECT
price
FROM
my_table
WHERE
Footage_Range1 <= YOUR_RANGE
ORDER BY
Footage_Range1 DESC
LIMIT 1
```
Where `YOUR_RANGE` is the input : 100,101,498 etc
Basically this query will return the closest price to the `Footage_Range1` input... | I have the sample for your requirement. Please take a look.
```
DECLARE @range INT = 498
DECLARE @Test TABLE(mfg_id INT, footage_range INT, price FLOAT)
INSERT INTO @Test ( mfg_id, footage_range, price )
SELECT 2, 0, 0.00
UNION ALL SELECT 2, 101, 2.66
UNION ALL SELECT 2, 500, 2.34
UNION ALL SELECT 2... | how to get the range of the price using range in sql? | [
"",
"mysql",
"sql",
"oracle",
""
] |
I have the following database structure :
```
create table Accounting
(
Channel,
Account
)
create table ChannelMapper
(
AccountingChannel,
ShipmentsMarketPlace,
ShipmentsChannel
)
create table AccountMapper
(
AccountingAccount,
ShipmentsComponent
)
create table Shipments
(
MarketPlace,
Component... | Indexes are essential to any database.
Speaking in "layman" terms, indexes are... well, precisely that. You can think of an index as a second, hidden, table that stores two things: The sorted data and a pointer to its position in the table.
Some thumb rules on creating indexes:
1. Create indexes on every field that ... | Your JOINS should be the first place to look. The two most obvious candidates for indexes are `AccountMapper.AccountingAccount` and `ChannelMapper.AccountingChannel`.
You should consider indexing `Shipments.MarketPlace`,`Shipments.ShipmentChannel` and `Shipments.Component` as well.
However, adding indexes increases t... | How to speed up sql queries ? Indexes? | [
"",
"mysql",
"sql",
"database",
"optimization",
""
] |
I'm running Mac OS X 10.8 and get strange behavior for time.clock(), which some online sources say I should prefer over time.time() for timing my code. For example:
```
import time
t0clock = time.clock()
t0time = time.time()
time.sleep(5)
t1clock = time.clock()
t1time = time.time()
print t1clock - t0clock
print t1... | From the docs on [`time.clock`](http://docs.python.org/2/library/time.html#time.clock):
> On Unix, return the current processor time as a floating point number expressed in seconds. The precision, and in fact the very definition of the meaning of “processor time”, depends on that of the C function of the same name, bu... | Instead of using `time.time` or `time.clock` use `timeit.default_timer`. This will return `time.clock` when `sys.platform == "win32"` and `time.time` for all other platforms.
That way, your code will use the best choice of timer, independent of platform.
---
From timeit.py:
```
if sys.platform == "win32":
# On ... | Why are there differences in Python time.time() and time.clock() on Mac OS X? | [
"",
"python",
"macos",
"time",
""
] |
I want to implement Test First Development in a project that will be implemented only using stored procedures and function in SQL Server.
There is a way to simplify the implementation of unit tests for the stored procedures and functions? If not, what is the best strategic to create those unit tests? | It's certainly possible to do xUnit style SQL unit testing and TDD for database development - I've been doing it that way for the last 4 years. There are a number of popular T-SQL based test frameworks, such as tsqlunit. Red Gate also have a product in this area that I've briefly looked at.
Then of course you have the... | Unit testing in database is actually big topic,and there is a lot of different ways to do it.I The simplest way of doing it is to write you own test like this:
```
BEGIN TRY
<statement to test>
THROW 50000,'No error raised',16;
END TRY
BEGIN CATCH
if ERROR_MESSAGE() not like '%<constraint being violated>%'
THROW 50000... | Unit tests for Stored Procedures in SQL Server | [
"",
"sql",
"sql-server",
"unit-testing",
"stored-procedures",
"test-first",
""
] |
I am trying to do something very similar to a question I have asked before but I cant seem to get it to work correctly. Here is my previous question: [How to get totals per day](https://stackoverflow.com/questions/16013175/how-to-get-totals-per-day)
the table looks as follows:
```
Table Name: Totals
Dat... | Try this
```
select Date,
sum(case when [Program label] = 'Salary Day' then count else 0 end) [Salary Day],
sum(case when [Program label] = 'Monthly' then count else 0 end) [Monthly],
sum(case when [Program label] = 'Policy' then count else 0 end) [Policy],
sum(case when [Program label] = 'Worst Record' then ... | Use the [`PIVOT`](http://msdn.microsoft.com/en-us/library/ms177410%28v=sql.105%29.aspx) table operator like this:
```
SELECT *
FROM Totals AS t
PIVOT
(
SUM(count)
FOR [Program label] IN ([Salary Day],
[Monthly],
[Policy],
[Worst... | MSSQL Totals per day for a month | [
"",
"sql",
"sql-server",
"sql-server-2008",
"t-sql",
"pivot",
""
] |
What is the most elegant and concise way (without creating my own class with operator overloading) to perform tuple arithmetic in Python 2.7?
Lets say I have two tuples:
```
a = (10, 10)
b = (4, 4)
```
My intended result is
```
c = a - b = (6, 6)
```
I currently use:
```
c = (a[0] - b[0], a[1] - b[1])
```
I also... | If you're looking for fast, you can use numpy:
```
>>> import numpy
>>> numpy.subtract((10, 10), (4, 4))
array([6, 6])
```
and if you want to keep it in a tuple:
```
>>> tuple(numpy.subtract((10, 10), (4, 4)))
(6, 6)
``` | One option would be,
```
>>> from operator import sub
>>> c = tuple(map(sub, a, b))
>>> c
(6, 6)
```
And [`itertools.imap`](http://docs.python.org/2/library/itertools.html#itertools.imap) can serve as a replacement for `map`.
Of course you can also use other functions from [`operator`](http://docs.python.org/2/libra... | Elegant way to perform tuple arithmetic | [
"",
"python",
"python-2.7",
"numpy",
"tuples",
""
] |
I was trying to work on Pyladies website on my local folder. I cloned the repo, (<https://github.com/pyladies/pyladies>) ! and created the virtual environment. However when I do the pip install -r requirements, I am getting this error
```
Installing collected packages: gevent, greenlet
Running setup.py install for gev... | I had the same problem and just as the other answer suggested I had to install "libevent". It's apparently not called "libevent-devel" anymore (apt-get couldn't find it) but doing:
```
$ apt-cache search libevent
```
listed a bunch of available packages.
```
$ apt-get install libevent-dev
```
worked for me. | I think you just forget to install the "libevent" in the environment. If you are on a OSX machine, please try to install brew here <http://mxcl.github.io/homebrew/> and use brew install libevent to install the dependency. If you are on an ubuntu machine, you can try apt-get to install the corresponding library. | gevent/libevent.h:9:19: fatal error: event.h: No such file or directory | [
"",
"python",
"virtualenv",
""
] |
I have two lists with values in example:
```
List 1 = TK123,TK221,TK132
```
AND
```
List 2 = TK123A,TK1124B,TK221L,TK132P
```
What I want to do is get another array with all of the values that match between List 1 and List 2 and then output the ones that Don't match.
For my purposes, "TK123" and "TK123A" are consi... | This compares every item in the list to every item in the other list. This won't work if both have letters (e.g. TK132C and TK132P wouldn't match). If that is a problem, comment below.
```
list_1 = ['TK123','TK221','TK132']
list_2 = ['TK123A','TK1124B','TK221L','TK132P']
ans = []
for itm1 in list_1:
for itm2 in ... | ```
>>> list1 = 'TK123','TK221','TK132'
>>> list2 = 'TK123A','TK1124B','TK221L','TK132P'
>>> def remove_trailing_letter(s):
... return s[:-1] if s[-1].isalpha() else s
...
>>> diff = set(map(remove_trailing_letter, list2)).difference(list1)
>>> diff
set(['TK1124'])
```
And you can add the last letter back in,
``... | Comparing two lists in Python (almost the same) | [
"",
"python",
"sortedlist",
""
] |
I currently have a table called People. Within this table there are thousands of rows of data which follow the below layout:
```
gkey | Name | Date | Person_Id
1 | Fred | 12/05/2012 | ABC123456
2 | John | 12/05/2012 | DEF123456
3 | Dave | 12/05/2012 | GHI123456
4 | Fred | 12/05/20... | ```
WITH a as
(
SELECT row_number() over (partition by [PERSON_ID] order by name) rn
FROM [Database].[dbo].[People]
)
DELETE FROM a
WHERE rn = 2
``` | Try this
```
DELETE FROM [People]
WHERE gkey IN
(
SELECT MIN(gkey)
FROM [People]
GROUP BY [PERSON_ID]
HAVING COUNT(*) > 1
)
```
You can use either `MIN` or `Max` | Remove 1 instance of duplicate values T-SQL | [
"",
"sql",
"t-sql",
"sql-server-2008-r2",
""
] |
I'm having a hard time explaining this through writing, so please be patient.
I'm making this project in which I have to choose a month and a year to know all the active employees during that month of the year.. but **in my database I'm storing the dates when they started and when they finished in dd/mm/yyyy format.**... | There is no need to create a range to make an overlap:
```
select to_char(d, 'YYYY-MM') as "Month", e.name
from
(
select generate_series(
'2013-01-01'::date, '2013-05-01', '1 month'
)::date
) s(d)
inner join
employee e on
date_trunc('month', e.start_date)::date <= s.... | First, you can generate multiple date intervals easily with [**`generate_series()`**](http://www.postgresql.org/docs/current/interactive/functions-srf.html). To get lower and upper bound add an interval of 1 month to the start:
```
SELECT g::date AS d_lower
, (g + interval '1 month')::date AS... | Choose active employes per month with dates formatted dd/mm/yyyy | [
"",
"sql",
"postgresql",
"overlap",
"date-range",
"generate-series",
""
] |

I am trying to retrieve unique values from the table above (order\_status\_data2). I would like to get the most recent order with the following fields: **id,order\_id and status\_id**. High id field value signifies the most recent item i.e.
4 - 56 - 4... | Like so:
```
select d.*
from order_status_data2 d
join (select max(id) mxid from order_status_data2 group by order_id) s
on d.id = s.mxid
``` | ```
SELECT o.id, o.order_id, o.status_id
FROM order_status_data2 o
JOIN (SELECT order_id, MAX(id) maxid
FROM order_status_data2
GROUP BY order_id) m
ON o.order_id = m.order_id AND o.id = m.maxid
```
[SQL Fiddle](http://sqlfiddle.com/#!3/f5ccf/1)
In your query, you didn't put any constraints on `status_id`... | select unique data from a table with similar id data field | [
"",
"mysql",
"sql",
""
] |
I am trying to drop a table but getting the following message:
> Msg 3726, Level 16, State 1, Line 3
> Could not drop object 'dbo.UserProfile' because it is referenced by a FOREIGN KEY constraint.
> Msg 2714, Level 16, State 6, Line 2
> There is already an object named 'UserProfile' in the database.
I looked ar... | Here it is:
```
SELECT
OBJECT_NAME(f.parent_object_id) TableName,
COL_NAME(fc.parent_object_id,fc.parent_column_id) ColName
FROM
sys.foreign_keys AS f
INNER JOIN
sys.foreign_key_columns AS fc
ON f.OBJECT_ID = fc.constraint_object_id
INNER JOIN
sys.tables t
ON t.OBJECT_ID = fc.reference... | Another way is to check the results of
```
sp_help 'TableName'
```
(or just highlight the quoted TableName and press ALT+F1)
With time passing, I just decided to refine my answer. Below is a screenshot of the results that `sp_help` provides. A have used the AdventureWorksDW2012 DB for this example. There is numerous... | How can I find out what FOREIGN KEY constraint references a table in SQL Server? | [
"",
"sql",
"sql-server",
"sql-server-2008",
""
] |
So first of all, I need to extract the numbers from a range of 455,111,451, to 455,112,000.
I could do this manually, there's only 50 numbers I need, but that's not the point.
I tried to:
```
for a in range(49999951,50000000):
print +str(a)
```
What should I do? | Use [`sum`](http://docs.python.org/2/library/functions.html#sum)
```
>>> sum(range(49999951,50000000))
2449998775L
```
---
It is a [builtin function](http://docs.python.org/2/library/functions.html), Which means you don't need to import anything or do anything special to use it. you should always consult the documen... | `sum` is the obvious way, but if you had a massive range and to compute the sum by incrementing each number each time could take a while, then you can do this mathematically instead (as shown in `sum_range`):
```
start = 49999951
end = 50000000
total = sum(range(start, end))
def sum_range(start, end):
return (en... | How to sum a list of numbers in python | [
"",
"python",
"numbers",
"sum",
""
] |
I just finished some online tutorial and i was experimenting with [Discogs Api](https://github.com/discogs/discogs_client)
My code is as follows :
```
import discogs_client as discogs
discogs.user_agent = '--' #i removed it
artist_input = raw_input("Enter artist\'s name : ")
artist = discogs.Artist(artist_input)
... | You are looking at the Python representation of objects, not strings. Each element in the list is an instance of the `MasterRelease` class.
These objects have an `id` attribute, simply refer to the attribute directly:
```
for masterrelease in thereleases:
print masterrelease.id
```
Other attributes are `.version... | The problem is that you are working with objects and assuming them to be strings. `artist.releases` is a list containing a number of objects.
```
newlist = ["<abc> 43242"]
print newlist[0][1]
```
This works because newlist is a list which contains a single element, a string. so `newlist[0]` gives you a string `'<abc>... | Parsing from a list in python | [
"",
"python",
"list",
"api",
"indexing",
"discogs-api",
""
] |
This is a language design question. Why the designer didn't use
```
import A.B
```
instead of
```
from A import B
```
assuming A is a module that contains function B. Isn't it better to have a single style for import syntax? What was the design principle behind this? I think that the Java style import syntax feels ... | Python import statements primarily exist to load modules and packages. You have to import a module before you can use it. The second form of import is merely an additional feature, loading the module and then copying some parts of it into the local namespace.
Java import statements exist to make shortcuts to names loa... | Consistency. `import A.B` *never* adds `B` to the local namespace, even for cases in which it is valid; it simply makes `B` available via `A`, which functions already naturally are. | Why not import A.B in Python? | [
"",
"python",
""
] |
I have been asked this question in interview and it seems common question but yet I am unable to get or come up with some solutions so need your help
Can you please tell me method to retrive top 1 row from a table using plain sql and no rownum, rowid, top or limit.
Thanks | A sample of a query without top.
```
select * from Contests
Where ContestId = (SELECT MAX(ContestId) FROM Contests)
``` | You can do this using ANSI standard SQL using the `row_number()` function and a subquery:
```
select t.*
from (select t.*,
row_number() over (order by <however you define the "top" row>) as seqnum
from t
) t
where t = 1;
```
This assumes that you have some method for ordering that specifies wh... | Query to retrieve top row without using TOP except plain sql | [
"",
"sql",
""
] |
I would like use something like that:
```
class Board():
...
def __getitem__(self, y, x):
return self.board[y][x]
```
but unfortunatelly, when I call:
```
board[x][y]
```
I get:
`TypeError: __getitem__() takes exactly 3 arguments (2 given)` | When you do `board[x][y]` you will cause *two* calls to `__getitem__` because you are doing two separate accesses: `[x]` is one and `[y]` is another. There's no way to handle this directly in `__getitem__`; you'd have to have `board[x]` return some kind of sub-object that you could use `[y]` on to get the individual it... | You might want to consider using this syntax:
```
board[(x, y)]
```
It's less pretty, but it allows you to have multidimensional arrays simply. Any number of dimensions in fact:
```
board[(1,6,34,2,6)]
```
By making board a defaultdict you can even have sparse dictionaries:
```
board[(1,6,34,2,6)]
>>> from collec... | Python - is there a way to implement __getitem__ for multidimension array? | [
"",
"python",
"arrays",
"python-2.7",
"numpy",
"multidimensional-array",
""
] |
I have the following:
```
IF OBJECT_ID(N'[dbo].[webpages_Roles_UserProfiles_Target]', 'xxxxx') IS NOT NULL
DROP CONSTRAINT [dbo].[webpages_Roles_UserProfiles_Target]
```
I want to be able to check if there is a constraint existing before I drop it. I use the code above with a type of 'U' for tables.
How could I m... | ```
SELECT
*
FROM INFORMATION_SCHEMA.REFERENTIAL_CONSTRAINTS
```
or else try this
```
SELECT OBJECT_NAME(OBJECT_ID) AS NameofConstraint,
SCHEMA_NAME(schema_id) AS SchemaName,
OBJECT_NAME(parent_object_id) AS TableName,
type_desc AS ConstraintType
FROM sys.objects
WHERE type_desc LIKE '%CONSTRAINT'
```
or... | Try something like this
```
IF OBJECTPROPERTY(OBJECT_ID('constraint_name'), 'IsConstraint') = 1
ALTER TABLE table_name DROP CONSTRAINT constraint_name
``` | How can I check if a SQL Server constraint exists? | [
"",
"sql",
"sql-server",
"sql-server-2008",
""
] |
Obviously new to Pandas. How can i simply count the number of records in a dataframe.
I would have thought some thing as simple as this would do it and i can't seem to even find the answer in searches...probably because it is too simple.
```
cnt = df.count
print cnt
```
the above code actually just prints the whole ... | Regards to your question... counting one Field? I decided to make it a question, but I hope it helps...
Say I have the following DataFrame
```
import numpy as np
import pandas as pd
df = pd.DataFrame(np.random.normal(0, 1, (5, 2)), columns=["A", "B"])
```
You could count a single column by
```
df.A.count()
#or
df[... | To get the number of rows in a dataframe use:
```
df.shape[0]
```
(and `df.shape[1]` to get the number of columns).
As an alternative you can use
```
len(df)
```
or
```
len(df.index)
```
(and `len(df.columns)` for the columns)
`shape` is more versatile and more convenient than `len()`, especially for interactiv... | pandas python how to count the number of records or rows in a dataframe | [
"",
"python",
"pandas",
"dataframe",
"count",
""
] |
I have a complex INNER JOIN SQL request I can't wrap my head around. I was hoping someone could help me. It involves 3 tables, so it has 2 inner joins.
My database has the tables "users", "statement", "opinion".
Users can author statements and opinions.
Opinions have an "authorid" variable referencing the id of the u... | ```
SELECT DISTINCT users.uid
FROM users
JOIN opinion o, opinion o2
WHERE users.uid = o.authorid
AND users.uid = o2.authorid
AND o2.statementid = $sid2
AND o.statementid = $sid1
``` | ```
SELECT DISTINCT user.*
FROM opinion o
JOIN usrs u
ON u.uid = o.author_id
AND o.statement_id = $sid1
INTERSECT
SELECT DISTINCT user.*
FROM opinion o
JOIN usrs u
ON u.uid = o.author_id
AND o.statement_id = $sid2
```
Don't have INTERSECT available in your SQL dialect?
```
... | Complex INNER JOIN SQL request | [
"",
"sql",
"join",
""
] |
I always get confused with date format in ORACLE SQL query and spend minutes together to google, Can someone explain me the simplest way to tackle when we have different format of date in database table ?
for instance i have a date column as ES\_DATE, holds data as 27-APR-12 11.52.48.294030000 AM of Data type TIMESTAM... | `to_date()` returns a date at 00:00:00, so you need to "remove" the minutes from the date you are comparing to:
```
select *
from table
where trunc(es_date) = TO_DATE('27-APR-12','dd-MON-yy')
```
You probably want to create an index on `trunc(es_date)` if that is something you are doing on a regular basis.
The lite... | if you are using same date format and have select query where date in oracle :
```
select count(id) from Table_name where TO_DATE(Column_date)='07-OCT-2015';
```
To\_DATE provided by oracle | Oracle SQL query for Date format | [
"",
"sql",
"database",
"oracle",
"oracle11g",
""
] |
I am running a query using a regular expression function on a field where a row may contain one or more matches but I cannot get Access to return any matches except either the first one of the collection or the last one (appears random to me).
Sample Data:
```
tbl_1 (queried table)
row_1 abc1234567890 some text... | Seems you intend to split out multiple text matches from a field in `tbl_1` and store each of those matches as a separate row in `tbl_2`. Doing that with an Access query is not easy. Consider a VBA procedure instead. Using your sample data in Access 2007, this procedure stores what you asked for in `tbl_2` (in a text f... | This function is only returning one value because that's the way you have set it up with the logic. This will always return the *last* matching value.
```
For Each foundMatch In foundMatches
OrderMatch = foundMatch.Value
Next
```
Even though your function implicitly returns a `Variant` data type, it's not returni... | Access 2010 Only returning first result Regular Expression result from MatchCollection | [
"",
"sql",
"regex",
"vba",
"ms-access",
""
] |
In python, if I have a tuple of tuples, like so:
```
((1, 'foo'), (2, 'bar'), (3, 'baz'))
```
what is the most efficient/clean/pythonic way to return the 0th element of a tuple containing a particular 1st element. I'm assuming it can be done as a simple one-liner.
In other words, how do I return 2 using 'bar'?
---
... | Use a list comprehension if you want all such values:
```
>>> lis = ((1, 'foo'), (2, 'bar'), (3, 'baz'))
>>> [x[0] for x in lis if x[1]=='bar' ]
[2]
```
If you want only one value:
```
>>> next((x[0] for x in lis if x[1]=='bar'), None)
2
```
If you're doing this multiple times then convert that list of tuples into ... | ```
>>> lis = ((1, 'foo'), (2, 'bar'), (3, 'baz'))
>>> dict(map(reversed, lis))['bar']
2
``` | Cleanest way to return a tuple containing a particular element? | [
"",
"python",
"tuples",
""
] |
I have the following database table on a Postgres server:
```
id date Product Sales
1245 01/04/2013 Toys 1000
1245 01/04/2013 Toys 2000
1231 01/02/2013 Bicycle 50000
456461 01/01/2014 Bananas 4546
```
I would like to create a query that gives the `SUM` of the `Sales` col... | ```
select to_char(date,'Mon') as mon,
extract(year from date) as yyyy,
sum("Sales") as "Sales"
from yourtable
group by 1,2
```
At the request of Radu, I will explain that query:
`to_char(date,'Mon') as mon,` : converts the "date" attribute into the defined format of the short form of month.
`extract(y... | I can't believe the accepted answer has so many upvotes -- it's a horrible method.
Here's the correct way to do it, with [date\_trunc](http://www.postgresql.org/docs/current/static/functions-datetime.html#FUNCTIONS-DATETIME-TRUNC):
```
SELECT date_trunc('month', txn_date) AS txn_month, sum(amount) as monthly_sum
... | Group query results by month and year in postgresql | [
"",
"sql",
"postgresql",
""
] |
Afternoon all, hope you can help an SQL newbie with what's probably a simple request. I'll jump straight in with the question/problem.
For table `Property_Information`, I'd like to retrieve either a complete record, or even specified fields if possible where the below criteria are met.
The table has column `PLCODE` w... | Something like this will give you all columns for your grouped rows.
```
WITH CTE AS
(
SELECT
PLCODE
, MIN(PCODE) AS PCODE
FROM Property_Information
GROUP BY PLCODE
)
SELECT p.* FROM CTE c
LEFT JOIN Property_Information p
ON c.PLCODE = p.PLCODE AND c.PCODE = p.PCODE
``` | ```
select PLCODE, min(PCODE) from table group by PLCODE
```
you google any ansi sql site or find SQL tutorials. | SQL return distinct while sorting on another column | [
"",
"sql",
"sql-server",
"sql-server-2005",
""
] |
I'm trying to execute a while loop only under a defined time like this, but the while loop continues its execution even when we are above the defined limit :
```
import datetime
import time
now = datetime.datetime.now()
minute = now.minute
while minute < 46 :
print "test"
time.sleep(5)
minute = now.minu... | You're not updating the value of `minute` inside while loop properly. You should recalculate the value of `now` in loop and then assign the new `now.minute` to `minute`.
```
while minute < 46 :
print "test"
time.sleep(5)
now = datetime.datetime.now()
minute = now.minute
``` | You need to determine the time anew in your loop. The `minute` variable is *static*, it does not update to reflect changing time.
If you want to loop for a certain *amount* of time, start with `time.time()` instead and then calculate elapsed time:
```
import time
start = time.time()
while time.time() - start < 300:... | executing a while loop between defined time | [
"",
"python",
""
] |
I am trying to use array slicing to reverse part of a [NumPy](http://en.wikipedia.org/wiki/NumPy) array. If my array is, for example,
```
a = np.array([1,2,3,4,5,6])
```
then I can get a slice b
```
b = a[::-1]
```
Which is a view on the original array. What I would like is a view that is partially reversed, for ex... | If you don't like the off by one indices
```
>>> a = np.array([1,2,3,4,5,6])
>>> a[1:4] = a[1:4][::-1]
>>> a
array([1, 4, 3, 2, 5, 6])
``` | ```
>>> a = np.array([1,2,3,4,5,6])
>>> a[1:4] = a[3:0:-1]
>>> a
array([1, 4, 3, 2, 5, 6])
``` | Reverse part of an array using NumPy | [
"",
"python",
"numpy",
""
] |
If I used 'Having' as 'Where' (i.e. without group by clause),
Can you please tell me which one is faster ‘Where’ OR ‘Having (as where)’?
Which one we have to prefer?
Scenario - I am using this condition in finding locations in certain distance using lat and longitude. | If a condition refers to an `aggregate` function, put that condition in the `HAVING` clause. Otherwise, use the `WHERE` clause.
You can use `HAVING` but recommended you should use with `GROUP BY`.
`SQL Standard` says that `WHERE` restricts the result set before returning rows and `HAVING` restricts the result set aft... | Here is the difference between `HAVING` and `WHERE`:
[HAVING without GROUP BY](https://stackoverflow.com/questions/6924896/having-without-group-by)
You can not in general use it alternatively, but all about it is covered in this link
And here is the topic about their speed: [Which SQL statement is faster? (HAVING vs. ... | Having OR Where, Which is Faster in performance? | [
"",
"mysql",
"sql",
""
] |
I have a pandas dataFrame created through a mysql call which returns the data as object type.
The data is mostly numeric, with some 'na' values.
How can I cast the type of the dataFrame so the numeric values are appropriately typed (floats) and the 'na' values are represented as numpy NaN values? | Use the replace method on dataframes:
```
import numpy as np
df = DataFrame({
'k1': ['na'] * 3 + ['two'] * 4,
'k2': [1, 'na', 2, 'na', 3, 4, 4]})
print df
df = df.replace('na', np.nan)
print df
```
I think it's helpful to point out that df.replace('na', np.nan) by itself won't work. You must assign it back to the ... | `df = df.convert_objects(convert_numeric=True)` will work in most cases.
I should note that this copies the data. It would be preferable to get it to a numeric type on the initial read. If you post your code and a small example, someone might be able to help you with that. | Converting Pandas Dataframe types | [
"",
"python",
"numpy",
"pandas",
""
] |
I am trying to query some information from certain large data on connections among a set of clients and servers. Below are sample data from relevant columns in the table (connection\_stats):
```
+---------------------------------------------------------+
| timestamp | client_id | server_id | status |
+--... | Admittedly not very elegant, but what I can come up with straight off the bat that works with MySQL that does not have CTEs or ranking functions, and without a guaranteed unique row id to work with.
```
SELECT aborted.* FROM Table1 aborted JOIN Table1 failed
ON aborted.server_id = failed.server_id
AND aborted.clie... | I'm answring this question (albeit late) because I want to offer a more general approach. MySQL does not have a `lag()` or `lead()` function, but you can implement it using a subquery. The idea is to lookup the next timestamp for the client\_id/server\_id pair and then join back to the original data to get the full rec... | How to select records based on sequential relationship using SQL query | [
"",
"mysql",
"sql",
""
] |
Mysql database is like that;
```
userID -> primaryKey, required, unsigned integer, auto increment, unique
usermail -> unique,varchar,required
```
I'm creating new users. userId is auto increment. If usermail inserted before,it occurs an error. My question is this
```
Let's think that userID is between 1-9.(there are... | Is it necessary for you to increment the userID from Database properties itself. Because what I am saying is, before inserting any records, just retrieve the last userID from database, store it in a integer variable and then increment it and insert back into database along with the new record.
Say your last user id wa... | When the error is being caused it seems to be inserting a new row and incrementing the uniqueid. On error you will need to query the table for the latest ID and reset the auto increment value
```
ALTER TABLE `table_name` AUTO_INCREMENT =new_number_here
```
Found Here: <http://forums.mysql.com/read.php?20,16088,17748#... | SQL userID auto increment | [
"",
"mysql",
"sql",
"database",
"unique",
"userid",
""
] |
How do use the python type in List Comprehension??
Can I?
```
>>> ll
[1, 2, 5, 'foo', 'baz', 'wert']
>>> [x for x in ll ]
[1, 2, 5, 'foo', 'baz', 'wert']
>>> [x for x in ll if type(x) == 'int']
[]
>>> [x*20.0 for x in ll if type(x) == 'int']
[]
>>> type(ll[0])
<type 'int'>
```
Looking for :`[20, 40, 100, 'foo', 'b... | Generally, in Python, best practice is to use "Duck Typing". One way to do that is to use exception handling, which in this case would need a helper function:
```
def safe_multiply(x, y):
try:
return x * y
except TypeError:
return x
[safe_multiply(x, 20) for x in ll]
```
The alternative duck-... | Try that:
```
In [6]: [x * 20.0 if type(x) is int else x for x in ll]
Out[6]: [20.0, 40.0, 100.0, 'foo', 'baz', 'wert']
```
Here you're checking type with `type(x) is int`, and if it so - multiply, else you just append x to your resulting list (`else x`), exactly as you wanted to. | How to use python type in List Comprehension | [
"",
"python",
"if-statement",
"list-comprehension",
""
] |
I looking for some tweak in mysql ordering , I normally select record from table and then order the record by Name(varchar) ASC **but the number is always come first**
here some example of my question (*note. mysql sort the record with 0-9 first*)
```
SELECT name FROM list ORDER BY name ASC
record returned:
1 star
2 ... | Use the following `ORDER BY` clause:
```
ORDER BY IF(name RLIKE '^[a-z]', 1, 2), name
``` | Ref [this](https://stackoverflow.com/questions/5055049/how-to-order-mysql-varchar-results)
```
SELECT name FROM list ORDER BY name * 1 ASC
```
Edited
```
SELECT name FROM list ORDER BY name * 1, name ASC
``` | ORDER BY alphabet first then follow by number | [
"",
"mysql",
"sql",
"sorting",
"sql-order-by",
""
] |
last parts of the code:
```
lda = LdaModel(corpus=corpus,id2word=dictionary, num_topics=2)
print lda
```
bash output:
```
INFO : adding document #0 to Dictionary(0 unique tokens)
INFO : built Dictionary(18 unique tokens) from 5 documents (total 20 corpus positions)
INFO : using serial LDA version on this node
INFO ... | you just need to use `lda.show_topics(topics=-1)` or any number of topics you want to have (topics=10, topics=15, topics=1000....). I am usually doing just:
```
logfile = open('.../yourfile.txt', 'a')
print>>logfile, lda.show_topics(topics=-1, topn=10)
```
All these parameters and others are available in gensim [docu... | Here is how to save a model for gensim LDA:
```
from gensim import corpora, models, similarities
# create corpus and dictionary
corpus = ...
dictionary = ...
# train model, this might takes time
model = models.LdaModel.LdaModel(corpus=corpus,id2word=dictionary, num_topics=200,passes=5, alpha='auto')
# save model to ... | Gensim: How to save LDA model's produced topics to a readable format (csv,txt,etc)? | [
"",
"python",
"lda",
"gensim",
""
] |
I have seen questions like this asked many many times but none are helpful
Im trying to submit data to a form on the web ive tried requests, and urllib and none have worked
for example here is code that should search for the [python] tag on SO:
```
import urllib
import urllib2
url = 'http://stackoverflow.com/'
# P... | If you want to pass `q` as a parameter in the URL using [`requests`](http://docs.python-requests.org/), use the `params` argument, not `data` (see [Passing Parameters In URLs](http://docs.python-requests.org/en/latest/user/quickstart.html#passing-parameters-in-urls)):
```
r = requests.get('http://stackoverflow.com', p... | ```
import urllib
import urllib2
url = 'http://www.someserver.com/cgi-bin/register.cgi'
values = {'name' : 'Michael Foord',
'location' : 'Northampton',
'language' : 'Python' }
data = urllib.urlencode(values)
req = urllib2.Request(url, data)
response = urllib2.urlopen(req)
the_page = response.read()
```
... | Submitting to a web form using python | [
"",
"python",
"post",
"request",
"urllib2",
"urllib",
""
] |
I get the following result:
```
>>> x = '-15'
>>> print x.isdigit()
False
```
When I expect it to be `True`. There seems to be no built in function that returns `True` for a string of negative number. What is the recommend to detect it? | The recommended way would be to `try` it:
```
try:
x = int(x)
except ValueError:
print "{} is not an integer".format(x)
```
If you also expect decimal numbers, use `float()` instead of `int()`. | There might be a more elegant Python way, but a general method is to check if the first character is `'-'`, and if so, call `isdigit` on the 2nd character onward. | How to determine whether string is a number when the number is negative | [
"",
"python",
""
] |
I have a dictionary of list like below:
```
dict = {'key1':list1, 'key2':list2}
```
and
```
list1=['a', 'b', 'c']
list2=['d', 'e', 'f']
```
i.e.,
```
dict = {'key1': ['a', 'b', 'c'], 'key2': ['d', 'e', 'f']}
```
I would like to get the object of the list containing 'b', that is list1, using map rather than using ... | There's really no way to do this without an explicit or implicit loop.
That is, you can do one of these:
```
key = next(lst for lst in d.values() if 'b' in lst)
```
But either way, that's really doing the same thing a for loop does. In particular, it's roughly the same as this:
```
for lst in d.values():
if 'b'... | ```
next(x for x in D.itervalues() if 'b' in x)
``` | How to access a list containing specific item in a dictionary? | [
"",
"python",
"list",
"dictionary",
""
] |
Today I was positively surprised by the fact that while reading data from a data file (for example) pandas is able to recognize types of values:
```
df = pandas.read_csv('test.dat', delimiter=r"\s+", names=['col1','col2','col3'])
```
For example it can be checked in this way:
```
for i, r in df.iterrows():
print... | You should add `parse_dates=True`, or `parse_dates=['column name']` when reading, thats usually enough to magically parse it. But there are always weird formats which need to be defined manually. In such a case you can also add a date parser function, which is the most flexible way possible.
Suppose you have a column ... | Perhaps the pandas interface has changed since @Rutger answered, but in the version I'm using (0.15.2), the `date_parser` function receives a list of dates instead of a single value. In this case, his code should be updated like so:
```
from datetime import datetime
import pandas as pd
dateparse = lambda dates: [date... | Can pandas automatically read dates from a CSV file? | [
"",
"python",
"date",
"types",
"dataframe",
"pandas",
""
] |
I'm trying to write a code that automatically logs into two websites and goes to a certain page. I use [Splinter](http://splinter.cobrateam.info/).
I only get the error with the "Mijn ING Zakelijk" website using [PhantomJS](http://www.phantomjs.org) as browser type.
Until a few days ago the code ran perfectly fine 20... | It may be that there was already some active javascript or background AJAX on the page, which confused PhantomJS into thinking that button click was unsuccessful. You could try inserting wait or try to stop the browser before clicking. | The current version of the ghostdriver source code fixes the issue (there is no longer any "Click succeeded but Load Failed" message" - see [here](https://github.com/detro/ghostdriver/commit/d0615a547f5a036df3134ef946c33d972c384aac)). The thing is, that version is not yet released (as of 08/19/2013), so you need to get... | Automate browser actions - Clicking the submit button errors - "Click succeeded but Load Failed. .." | [
"",
"python",
"selenium",
"webdriver",
"urllib2",
"phantomjs",
""
] |
I have set of points in tuples, like this:
```
>>> s
set([(209, 147),
(220, 177),
(222, 181),
(225, 185),
(288, 173),
(211, 155),
(222, 182)])
```
What is the right way to do scatter plot of this set? | You can do:
```
x,y = zip(*s)
plt.scatter(x, y)
```
Or even in an "one-liner":
```
plt.scatter(*zip(*s))
```
[`zip()` can be used to pack and unpack arrays](https://stackoverflow.com/q/19339/832621) and when you call using `method(*list_or_tuple)`, each element in the list or tuple is passed as an argument. | ```
x = []; y=[]
for point in s:
x.append(point[0])
y.append(point[1])
plt.scatter(x,y)
``` | Make scatter plot from set of points in tuples | [
"",
"python",
"matplotlib",
"set",
""
] |
I have this code:
```
for urls in new_keywords
if urls not in old_keywords
upload_keywords.append(urls)
```
And my error:
```
File "controller.py", line 56
for urls in new_keywords
^
SyntaxError: invalid syntax
```
I had this error before and the ... | You're missing a colon, it should be like:
```
for urls in new_keywords:
if urls not in old_keywords:
upload_keywords.append(urls)
```
That's why you get the invalid syntax error | You missed a colon on each of the first 2 lines of your snippet.
Change
```
for urls in new_keywords
if urls not in old_keywords
```
To
```
for urls in new_keywords:
if urls not in old_keywords:
```
You should always put colons after `for` statements (as well as `while`, `if` and some other) | SyntaxError: invalid syntax I have checked for mix of Tabs & Spaces | [
"",
"python",
""
] |
I am trying to find a clean way to handle different, mutually-exclusive function inputs. The idea is that I have a function which returns 4 values (these values are linked through mathematical equations), and when you input one of the 4 values, it returns all the values.
Currently the function works like this:
```
#e... | A common approach to avoid many `if`-`elif`s is to build a dictionary of functions:
```
def relations(v, vtype='a'):
functions = {
'a': lambda x: x, 'b': lambda x: x-1,
'c': lambda x: x * 2, 'd': lambda x: x**2
}
a = functions[vtype](v)
b = 1 + a
c = 0.5 * a
d = a ** 0.5
re... | You could use variable keyword arguments:
```
def relations(**kwargs):
if 'a' in kwargs:
a = kwargs['a']
elif 'b' in kwargs:
a = kwargs['b'] - 1
elif 'c' in kwargs:
a = kwargs['c'] * 2
elif 'd' in kwargs:
a = kwargs['d'] ** 2
else:
raise TypeError('missing an... | What’s the most Pythonic way of handling different, mutually-exclusive function inputs? | [
"",
"python",
"input",
""
] |
Okay so here's my dilemma:
I'm working on a FAQ bot for a subreddit. I'm having trouble with boolean logic and could use a pair of more experienced eyes (this is my first adventure in Python). Right now the bot is basically spamming the test subreddit I created. Rather than share that specific information, here's an e... | I think [`any`](http://docs.python.org/2/library/functions.html#any), [`all`](http://docs.python.org/2/library/functions.html#all), and [generators](http://wiki.python.org/moin/Generators) can help you out here.
## The code
```
#Define Key Words
##################################
#System Requirements Definitions
sysR... | Two problems. First, you can't use `and` and `or` to "store" some kind of comparison operator for use later. When you write `and` and `or` the result is evaluated immediately. The rules for that are described in [the documentation](http://docs.python.org/2/reference/expressions.html#boolean-operations).
Second, you ca... | Python: Trying to create the equivalent of and(or(value,value,value)) | [
"",
"python",
"boolean-logic",
""
] |
Hoping someone can help me here.
I'm very new to Python, and I'm trying to work out what I'm doing wrong.
I've already searched and found out that that Python variables can be linked so that changing one changes the other, and I have done numerous tests with the `id()` function to get to grips with this concept. But ... | `b = a[:]` creates a [shallow copy](http://en.wikipedia.org/wiki/Object_copy#Shallow_copy) of `a`, so changing the mutable lists within `b` still effects *those same lists* in `a`.
In other words, `a` and `b` do not point to the same list (which is why `a is not b`), but rather to two different lists which both *conta... | You need to make a *deepcopy* of your list. `a[:]` only makes a *shallow copy* - [see docs](http://docs.python.org/2/library/copy.html)
You can use `copy.deepcopy` function:
```
>>> import copy
>>> a = [[0,0],[0,0]]
>>> b = copy.deepcopy(a)
>>> b
[[0, 0], [0, 0]]
>>> b[0][0]=1
>>> a
[[0, 0], [0, 0]]
``` | Python: copying a list within a list | [
"",
"python",
"list",
""
] |
We have a stored procedure in a MSSQL Server 2008 database that performs a number of reads and writes in response to user action on a website.
I would like to know if there is any way of counting how many rows were edited/created during the procedure, preferably without having to alter the proc (although alterations ar... | Without editing the proc, your best bet would be to start a SQL Server Profiler session, track [SP:StmtCompleted](http://msdn.microsoft.com/en-us/library/ms189570.aspx), filter ObjectName to your proc, and filter TextData to the statements you want to monitor. Be sure to include the RowCount column.
Note that you can'... | MS Sql Profiler is where you want to start for something like this. | Count number of rows edited by Stored Proc | [
"",
"sql",
"sql-server-2008",
"stored-procedures",
""
] |
Say I have a 3D numpy.array, e.g. with dimensions x y z, is there a way to iterate over slices along a particular axis? Something like:
```
for layer in data.slices(dim=2):
# do something with layer
```
Edit:
To clarify, the example is a dim=3 array, i.e. shape=(len\_x, len\_y, len\_z). Elazar and equivalently ka... | Iterating over the first dimension is very easy, see below. To iterate over the others, roll that dimension to the front and do the same:
```
>>> data = np.arange(24).reshape(2, 3, 4)
>>> for dim_0_slice in data: # the first dimension is easy
... print dim_0_slice
...
[[ 0 1 2 3]
[ 4 5 6 7]
[ 8 9 10 11]]... | This could probably be solved more elegantly than this, but one way of doing it if you know dim beforehand(e.g. 2) is:
```
for i in range(data.shape[dim]):
layer = data[:,:,i]
```
or if dim=0
```
for i in range(data.shape[dim]):
layer = data[i,:,:]
```
etc. | iterate over slices of an ndarray | [
"",
"python",
"numpy",
"slice",
""
] |
I have a log file which has text that looks like this.
```
Jul 1 03:27:12 syslog: [m_java][ 1/Jul/2013 03:27:12.818][j:[SessionThread <]^Iat com/avc/abc/magr/service/find.something(abc/1235/locator/abc;Ljava/lang/String;)Labc/abc/abcd/abcd;(bytecode:7)
```
There are two time formats in the file. I need to sort this ... | You are not matching the initial space; you also want to group the date for easy extraction, and limit the `\D` and `.*` patterns to non-greedy:
```
t_pat = re.compile(r".*\[\s?(\d+/\D+?/.*?)\]")
```
Demo:
```
>>> re.compile(r".*\[\s?(\d+/\D+?/.*?)\]").search(line).group(1)
'1/Jul/2013 03:27:12.818'
```
You can nar... | You have a space in there that needs to be added to the regular expression
```
text = "Jul 1 03:27:12 syslog: [m_java][ 1/Jul/2013 03:27:12.818][j:[SessionThread <]^Iat com/avc/abc/magr/service/find.something(abc/1235/locator/abc;Ljava/lang/String;)Labc/abc/abcd/abcd;(bytecode:7)"
matches = re.findall(r"\[\s*(\d+/\D+... | python : reading a datetime from a log file using regex | [
"",
"python",
"regex",
""
] |
I was building a bidimensional vector in Python, and since I wanted it to be all zero at first, and didn't wanted to use numpy, I tried this:
```
columns = 8
rows = 5
m = [[0]* (columns)] * (rows)
m[3][2] = 1
print m
```
And I got an unexpected behaviour:
```
>> [[0, 0, 1, 0, 0, 0, 0, 0], [0, 0, 1, 0, 0, 0, 0, 0], [... | This is a common Python gothca. You are not creating `rows` inner lists, you're creating `rows` references to the same list.
Your code is equivalent to the following:
```
inner_list = [0] * columns
m = [inner_list] * rows
```
I would recommend building the rows without using the `*` operator. (You don't run into the... | `[0] * size_of_array` creates a list which multiple references to `0`. If you put another value into this list, it won't be affected.
As you noticed, `[[]] * num` creates a list which contains a reference to the same list over and over again. Of you change this list, the change is visible via all references.
```
>>> ... | Building a bidimensional array in Python | [
"",
"python",
"arrays",
"multidimensional-array",
""
] |
Say I have loaded `Report WW26blueprint_with_chart_330.xlsm` in the `report` object with the following code (the `print.range` is used here to test that the workbook is loaded):
```
import xl
report = xl.Workbook("Report WW26blueprint_with_chart_330.xlsm")
print report
print(report.range("A1:E50").get())
```
From the... | This did it for me:
```
report.xlWorkbook.Application.Run('Macro1')
``` | Didn't manage to do it with `pyvot` but can be done using `pywin32` as following:
```
import win32com.client
xl=win32com.client.Dispatch("Excel.Application")
xl.Workbooks.Open(Filename="C:\Users\florinescu_eduard\Downloads\\Report WW26blueprint_with_chart_330.xlsm",ReadOnly=1)
xl.Application.Run("Macro1")
xl.Workbooks... | pyvot: can I run Excel VBA macros from python script? | [
"",
"python",
"excel",
"python-2.7",
"com",
"vba",
""
] |
I am trying to flip an image horizontally.
From this:

To This:

But I keep getting it mirrored half way.
Like This:

I am trying to reverse the x-axis index... | In your `flip()` function (like in any function), as mentioned by the other answers, you return `picture` which is the image passed as a parameter of the function but is defined in d()...
It is a matter of `scope` of the variables, so I invite you to have a look again at the discussion we had [here](https://stackoverf... | ```
def flip(picture):
height = getHeight(picture)
width = getWidth(picture)
newPicture = makeEmptyPicture(width, height)
for x in range(width):
for y in range(height):
color = getColor(getPixel(picture, x, y))
setColor(getPixel(newPicture, width-1-x, y), color)
return newPicture
```
How abou... | Flipping Image Python | [
"",
"python",
"image",
"jython",
"image-rotation",
"jes",
""
] |
Why doesn't the first print statement give me '5 = 3'? This is from John Guttag's book. Can't get my head around it.
It looks like this by the way:
```
3 = 4
2 = 4
1 = abc
4 = 4
5 = 3
6 = <function g at 0x026B22F0>
1 = abc
```
Script:
```
def f(x):
def g():
x = 'abc'
print '1 =',x
def h():
... | Defining a function does not execute it, So after `f` is defined, `x=3` is executed. The function `f(x)` is called and the result assigned to z.
During the `f(x)` call, two more functions are defined, then `x=x+1` is executed. So the first print statement is `3 = 4`.
That should be enough to help you figure out the r... | All the changes you do to `x` is limited to the local scope of function `f`. Unless you declare x global (`global x`), `x` will not change from being `3` in the global space. | Scope confusion. Can't explain order of print statements in o/p | [
"",
"python",
""
] |
I have the following code structure in my Python script:
```
for fullName in lines[:-1]:
do stuff ...
```
This processes every line except for the last one. The last line is a company name and all the rest are people's names. This works except in the case where there's no company name. In this case the loop doesn... | You could do it like this, dynamically setting the end of your range based on the length of `lines`:
```
i = len(lines)
i = -1 if i > 1 else i
for fullName in lines[:i]:
dostuff()
``` | How about using Python's [conditional](http://www.python.org/dev/peps/pep-0308/):
```
>>> name=['Roger']
>>> names=['Pete','Bob','Acme Corp']
>>>
>>> tgt=name
>>> for n in tgt if len(tgt)==1 else tgt[:-1]:
... print(n)
...
Roger
>>> tgt=names
>>> for n in tgt if len(tgt)==1 else tgt[:-1]:
... print(n)
...
Pet... | Process at least one line in Python | [
"",
"python",
""
] |
```
Claim# Total ValuationDt
1 100 1/1/12
2 550 1/1/12
1 2000 3/1/12
2 100 4/1/12
1 2100 8/1/12
3 200 8/1/12
3 250 11/1/12
```
Using MS Access, I need a query that returns only claims which have been valuated greater than $500 at some point in that cl... | You can use `IN`:
```
SELECT *
FROM Table1
WHERE Claim IN (SELECT Claim
FROM Table1
WHERE Total > 500)
```
[Sql Fiddle Demo](http://sqlfiddle.com/#!3/70a7e/2/0) | This should work
```
Select DISTINCT Claim FROM yourtable Where Total > 500
```
EDIT:
In the case that my initial answer does not fulfill your requirements, then you can use a sub-query. A subquery is a query inside your query (nested queries). The reason we have to do it like that is because if you use something li... | MS Access query table without primary key | [
"",
"sql",
"ms-access",
""
] |
I have a feeling that this is very easy but I can't quite figure out how to do it. Say I have a Numpy array
```
[1,2,3,4]
```
How do I convert this to
```
[[1],[2],[3],[4]]
```
In an easy way?
Thanks | You can use `np.newaxis`:
```
>>> a = np.array([1,2,3,4]
array([1, 2, 3, 4])
>>> a[:,np.newaxis]
array([[1],
[2],
[3],
[4]])
``` | You can use [numpy.reshape](http://docs.scipy.org/doc/numpy/reference/generated/numpy.reshape.html):
```
>>> import numpy as np
>>> a = np.array([1,2,3,4])
>>> np.reshape(a, (-1, 1))
array([[1],
[2],
[3],
[4]])
```
If you want normal python list then use `list comprehension`:
```
>>> a = np.arra... | Convert Python Numpy array to array of single arrays | [
"",
"python",
"arrays",
"numpy",
""
] |
Suppose there are 3 tables: BOOKS, TAGS and ASOC
```
+----------+ +----------+ +----------+
|BOOKS | |TAGS | |ASOC |
+----------+ +----------+ +----------+
|book_id | |tag_id | |book_id |
|book_name | |tag | |tag_id |
|... | +----------+ +----------+
+----------+
```
Ho... | The simplest way is to change `SELECT B.book_name` to `SELECT DISTINCT B.book_name`; however, it might be better to write:
```
SELECT book_name
FROM books
WHERE book_id IN
( SELECT book_id
FROM asoc
WHERE tag_id IN
( SELECT tag_id
FROM tags
... | Use `DISTINCT` to get a unique list:
```
SELECT DISTINCT B.book_name
FROM BOOKS B
, TAGS T
, ASOC A
WHERE B.book_id = A.book_id
AND T.tag_id = A.tag_id
AND (T.tag = 'Classic' OR T.tag = 'Fiction')
```
As a further enhancement, that last line can be rewritten to be slightly more readable:
```
AND ... | SQL join query returning row for each matching ASOC | [
"",
"sql",
"join",
""
] |
I am trying to install python(epd\_free-7.3-2-win-x86) on my PC (windows 7 - 32bit) but not able to do so. it shows error which says a DLL is missing. searched every where but could not found. i have attached an image of error message dialog.
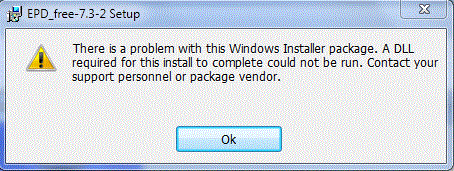
I also... | Was facing the same problem in windows 8 - 64 bit ..
try doing this..
Go to **C:/Users//AppData/Local** .
right click on the folder **"Temp"**.
Go to **Properties**.
Go to **Security** Tab.
Click on **"Everyone"** and "**Edit"** the permission to **"full control"-> allow**.
Click apply.
try running the installer agai... | Run Command Prompt as Administrator. See Image

Change directory to location of .msi file using cd command and type the name of of your file with extension i.e. .msi (see image below). You may give the complete path of file instead of changing direct... | Missing dll Error Whle installing Python 2.7 | [
"",
"python",
"python-2.7",
"enthought",
""
] |
I'm trying to echo the output of a SELECT request in bash, in a structured form with column names. The issue is that i cannot do it properly with more than 2 fields or if the value is larger that the column name.
Example :
My table looks like this : value1 value2
If i do in bash : echo "select value1, value2 from ta... | Use the mysql -e option to execute your query, and -t to print table output to stdout:
> mysql -uUSER -t -e "select value1, value2, value3 from table" -pPASS
Your output will look something like this:
```
+-----------+-------------+--------+
| value1 | value2 | value3 |
+-----------+-------------+--------+
|... | ```
echo "select value1, value2 from table" | mysql -uUSER -pPASS | column -t
``` | Simple way to print structured SQL SELECT in bash | [
"",
"mysql",
"sql",
"bash",
"echo",
"shapes",
""
] |
# Django
Following the official documentation, I am creating a Django app (the same poll app as in the documentation page). While using the class-based view, I got a error. I did not understand much about class based view, for instance, may someone explain, what is the difference between a class based view from a norm... | `as_view` should be called, not referenced, according to the [docs](https://docs.djangoproject.com/en/dev/topics/class-based-views/#simple-usage-in-your-urlconf), your url should look like:
```
url(r'^(?P<pk>\d+)/$', views.DetailView.as_view(), name='detail')
```
Note the usage of parenthesis.
Also, you should rathe... | When you use url for the CBV ensure that you can not use the reference of the of the url filed, so first you need to add change the as\_view to **as\_view()**.
And you can use DetailView like this.,
```
class PollDetail(DetailView):
model=Book
def get_context_data(self,*args,**kwargs):
... | Django class-based view | [
"",
"python",
"django",
"django-class-based-views",
""
] |
I have currently trimmed a section of my data set, but I need to filter it further.
My goal is to isolate only those IDs for which a single row is returned.
For example, with a data set as follows:
```
ID Client Name Client Manager
1 XYZ Corp. Ralph
2 ... | ```
SELECT ID,
Client_Name,
Client_Manager
FROM table_name
WHERE ID IN
(
SELECT ID
FROM table_name
GROUP BY ID
HAVING COUNT(*) = 1
)
``` | ```
SELECT ID, [Client Name], min([Client Manager]) as [Client Manager]
FROM dbo.Table1
GROUP BY ID, [Client Name]
HAVING COUNT(*) = 1
``` | How do I return IDs for which only a single record is returned in SQL? | [
"",
"sql",
"ms-access",
""
] |
Using MS SQL: The scenario is I have already a Contact master table (tbl\_Customer)for all contacts in the company. The staffs suggested that they do not want to see all the contact and that they will only choose which contacts are applicable for them. The contact table is not gonna be store on the client like an outlo... | Why don't you have a staff table with a staff id - then every contact the staff in question wants can be a row in staffContacts. Column 1 is staffID and col 2 is contactID. Then you can join on the contact table to retrieve the details you want.
The contacts table then only needs be updated...You only need to add one ... | If I understand correctly you want to have a list of the contacts that is filtered specifically based on a particular users preferences?
Personally I would create another table like this:
```
Create Table UserContactPreferences
(
ID int identity(1,1),
UserID int,
ContactID int,
)
```
And then each individual user ca... | Commonly concepts in adding contacts for staffs using master table | [
"",
"sql",
""
] |
I have actually finished this exercise (almost) but am just stuck on a tiny problem with `__str__` which is inside an object. If i do this
```
elif choice == "9":
try:
for i in sworm:
print(i)
except TypeError:
None`
```
Then it will only print out the details of the first object i... | A Python list always shows the *contents* as representations, calling `repr()` on the objects.
You can hook into that by specifying a `__repr__` method as well. Alternatively, don't print the list directly, but only the contents:
```
for elem in sworm:
print(elem)
```
or join them as a long string:
```
print(',... | If you need the `__str__` method to work, then you should return a string from it - something like this
```
def __str__(self):
return 'Critter object: %s %s %s' %(self.name, self.hunger, self.boredom)
```
Please read the documentation [here](http://docs.python.org/2/reference/datamodel.html#object.__str__) | Printing Python __str__ from an object | [
"",
"python",
"string",
""
] |
I have table:
```
Bonus Value
500 1400
1500 177
1800 453
1200 100
800 2500
200 50
780 740
```
I wanted to print the sum of column whichever is maximum.
I Tried Following:
```
select
case when sum(bonus)>sum(Value) then sum(bonus) end
case when sum(Value)>sum(... | Your syntax is incorrect, `CASE` keyword goes only once:
```
select
case when sum(bonus)>sum(Value) then sum(bonus)
else sum(Value)
end as MaxSum
from emp
``` | Your `case` statement is wrong, try this one:
```
select case when sum(bonus)>sum(Value) then sum(bonus) else sum(Value) end
from emp
``` | max sum of two sums in sql | [
"",
"sql",
"sql-server-2005",
""
] |
I wanna to fetch web pages under different domain, that means I have to use different spider under the command "scrapy crawl myspider". However, I have to use different pipeline logic to put the data into database since the content of web pages are different. But for every spider, they have to go through all of the pip... | `ITEM_PIPELINES` setting is defined globally for all spiders in the project during the engine start. It cannot be changed per spider on the fly.
Here are some options to consider:
* Change the code of pipelines. Skip/continue processing items returned by spiders in the `process_item` method of your pipeline, e.g.:
... | A slightly better version of the above is as follows. It is better because this way allows you to selectively turn on pipelines for different spiders more easily than the coding of 'not in ['spider1','spider2']' *in the pipeline* above.
In your spider class, add:
```
#start_urls=...
pipelines = ['pipeline1', 'pipelin... | Is there any method to using seperate scrapy pipeline for each spider? | [
"",
"python",
"web-scraping",
"scrapy",
""
] |
here is my SQL statement and I am getting `Error 170 Incorrect syntax near ',' at line 4`
```
INSERT INTO SEO_Permalink_Test
( IDObjekt ,IDType ,IDLanguage ,StateSEOName ,StateSEOPermalink ,DatumErstellungSEOName ,DatumLetzteAenderungSEOName ,SEOName)
VALUES
( 19988 , 72 , 1 , 0 , 0 , GETDATE() , GETDATE() , 'H_KD... | I am guessing that it is SQL Server 2005 or below
From: <http://msdn.microsoft.com/en-us/library/ms174335%28v=sql.100%29.aspx>
SQL Server 2008 introduces the Transact-SQL row constructor (also called a table value constructor) to specify **multiple rows in a
single INSERT statement**. The row constructor consists of ... | You cannot perform a multi-row insert into SQL Server prior than 2008.
You have two ways to do it:
```
INSERT INTO SEO_Permalink_Test
( IDObjekt ,IDType ,IDLanguage ,StateSEOName ,StateSEOPermalink ,DatumErstellungSEOName ,DatumLetzteAenderungSEOName ,SEOName)
SELECT 19988 , 72 , 1 , 0 , 0 , GETDATE() , GETDATE() , ... | SQL syntax error 170 in insert statement | [
"",
"sql",
"t-sql",
""
] |
I have a `Char(15)` field, in this field I have the data below:
```
94342KMR
947JCP
7048MYC
```
I need to break down this, I need to get the last RIGHT 3 characters and I need to get whatever is to the LEFT. My issue is that the code on the LEFT is not always the same length as you can see.
How can I accomplish this... | ```
SELECT RIGHT(RTRIM(column), 3),
LEFT(column, LEN(column) - 3)
FROM table
```
Use `RIGHT` w/ `RTRIM` (to avoid complications with a fixed-length column), and `LEFT` coupled with `LEN` (to only grab what you need, exempt of the last 3 characters).
if there's ever a situation where the length is <= 3, th... | You can use `RTRIM` or cast your value to `VARCHAR`:
```
SELECT RIGHT(RTRIM(Field),3), LEFT(Field,LEN(Field)-3)
```
Or
```
SELECT RIGHT(CAST(Field AS VARCHAR(15)),3), LEFT(Field,LEN(Field)-3)
``` | How can I use LEFT & RIGHT Functions in SQL to get last 3 characters? | [
"",
"sql",
"sql-server",
"t-sql",
""
] |
i have table test with columns as id , month, year . i need to get id where maximum of month and maximum of year in one query.
for example
```
id month year
1 10 2012
2 9 2013
```
my result should be id 2 .
first checks with year based on that maximum month based on these to i need to ge... | Just sort using month and year:
[Demo](http://sqlfiddle.com/#!2/6cccf/7)
```
SELECT id
FROM books
ORDER BY year DESC, month DESC
LIMIT 1
``` | For this type of query, `order by` and `limit` are the best approach. You seem to want the latest date, so start with the year (in descending order) and then month (in descending order):
```
select *
from book
order by year desc, month desc
limit 1
```
In particular, you *don't* want the maximum month and maximum yea... | comparing with two maximum of columns get one row | [
"",
"mysql",
"sql",
""
] |
I am currently reading through a book about MVVM and I need to use the Northwind database for the next section. Unfortunately, when I try to add Northwind to my project, I get the following error:
> "An error occurred while connecting to the database. The database might be unavailable. An exception of type 'Microsoft.... | one way to potentially fix it is, install [Sql Server 2012 Express](http://www.microsoft.com/en-us/download/details.aspx?id=29062) and use database connection to sql server. Do not use local database. That might work. Just a suggestion.
Also as an extra note, you might want to download SQL Server 2012 *Management Stud... | my simple way:
go to VisualStadio 2012
In Server Explorer Windows
open Data Connections
Right click on ASPNETDB.MDF
click on Modify Connection...
a new windows open for you ... you just click OK
if other windows open for you click Yes
FINISH ( be Happy ) :D | "This database file is not compatible with the current instance of SQL Server" | [
"",
"sql",
"visual-studio",
"visual-studio-2012",
""
] |
I'm trying to craft a regular expression that will match something like this:
`[[uid::page name|page alias]]`
for example:
`[[nw::Home|Home page]]`
The uid and page alias are both optional.
I want to allow the delimiters `::` or `|` to appear only once, and only in the order shown. However, the character `:` shoul... | If I understand your needs correctly, you could use this:
```
\[\[(?:(?<uid>\w+)::)?(?!.*::)(?<page>[^|\t\n\r\f\v]+)(?:\|(?<alias>[^|\t\n\r\f\v]+))?\]\]
^^^^^^^^
```
See [here](http://www.regex101.com/r/mT4mY4) for a demo. I added a negative lookahead after the `uid` capture.
I have given names... | So, what do you think of this one:
```
import re
regex = r'''
\[\[ # opening [[
([\w ]+) # first word (with possible spaces)
(?:
:: # the two colons
( # second word (with possible space... | Python regex to match 2 distinct delimiters | [
"",
"python",
"regex",
"regex-negation",
""
] |
My question is probably quite simple, however I have been puzzling over numerous methods and cannot seem to find an efficient answer without using many for loops.
I have a dictionary:
```
my_dict = {'full_name1' : 1,
'full_name2' : 2,
'full_name3' : 3}
```
I also have this dictionary:
```
ano... | Use [dictionary comprehension](http://docs.python.org/2/tutorial/datastructures.html#dictionaries):
```
>>> my_dict = {'full_name1' : 1, 'full_name2' : 2, 'full_name3' : 3}
>>> another_dict = {'name1' : 'x', 'name2' : 'y', 'name3' : 'z'}
>>> {key:value for S, key in my_dict.iteritems() for s, value in another_dict.ite... | This worked for me:
```
full_name1 = 'Will Smith'
full_name2 = 'Matt Damon'
full_name3 = 'Mark yMark'
name1 = 'Will'
name2 = 'Matt'
name3 = 'Mark'
my_dict = {full_name1 : 1,
full_name2 : 2,
full_name3 : 3}
another_dict = {name1 : 'x',
name2 : 'y',
name3 : 'z'}
... | Check if dictionary key contains any of another dictionary's keys and print matching pairs | [
"",
"python",
"dictionary",
"key",
"contains",
"key-value",
""
] |
I have a PostgreSQL table with 2 indices. One of the indices is covers the `website_id` and `tweet_id` columns and is an unique B-tree index.
The 2nd index only covers the `website_id` column, and is a non-unique index.
Is the 2nd index redundant if the first index exists? In other words, will there be no advantages t... | postgres multicolumn indexes can be used to search on the first columns only,so in practise it is redundant.
> A multicolumn B-tree index can be used with query conditions that involve any subset of the index's columns, but the index is most efficient when there are constraints on the leading (leftmost) columns. The e... | It depends.
Assuming we are talking about default B-Tree indexes only. If other index types like [GIN](http://www.postgresql.org/docs/current/interactive/gin.html) or [GiST](http://www.postgresql.org/docs/current/interactive/gist.html) are involved, things are not as simple.
In principal an index on `(a,b)` is good f... | 2 PostgreSQL indices on the same column of the same table - redundant? | [
"",
"sql",
"database",
"postgresql",
"indexing",
""
] |
So there are two ways to take a list and add the members of a second list to the first. You can use list concatenation or your can iterate over it. You can:
```
for obj in list2:
list1.append(obj)
```
or you can:
```
list1 = list1 + list2
```
or
```
list1 += list2
```
My question is: which is faster, and why?... | `append` adds each item one at a time, which is the cause of its slowness, as well as the repeated function calls to `append`.
**However** in this case the `+=` operator is **not** syntactic sugar for the `+`. The `+=` operator does not actually create a new list then assign it back, it modifies the left hand operand ... | I ran the following code
```
l1 = list(range(0, 100000))
l2 = list(range(0, 100000))
def t1():
starttime = time.monotonic()
for item in l1:
l2.append(item)
print(time.monotonic() - starttime)
l1 = list(range(0, 100000))
l2 = list(range(0, 100000))
def t2():
starttime = time.monotonic()
g... | Iterating vs List Concatenation | [
"",
"python",
"profiling",
"performance",
""
] |
I'm new to python. I have a dictionary with subsets as values, link this:
```
dict = {key1: [value1, value2, value 3], key2: [value4], key3: [value5, value6]}
```
and so on.
I would like to store some of the sub-sets of values in a new set. For instance, I would like to merge values from key1 and key3 so to have
``... | ```
d1= set()
map(d1.add, dict['key1'])
map(d1.add, dict['key3'])
``` | You must coerce each list to a set before trying to join their values:
```
>>> set(dict["key1"]) | set(dict["key3"])
{'value 3', 'value1', 'value2', 'value5', 'value6'}
``` | Add dictionary values to a set in python | [
"",
"python",
"dictionary",
"set",
""
] |
I need a way to, give a string of text in python, separate its contents into a list, splitting by 3 parameters - outermost brackets versus outermost parentheses versus normal text, preserving the original syntax.
For example, given a string
```
(([a] b) c ) [d] (e) f
```
The expected output would be this list:
```
... | Only very lightly tested (and the output includes white space). As with @Marius' answer (and the general rule about paren matching requiring a PDA), I use a stack. However, I have a little extra paranoia built in to mine.
```
def paren_matcher(string, opens, closes):
"""Yield (in order) the parts of a string that ... | I managed to do this using a simple parser that keeps track of how deep you are in the stack using the `level` variable.
```
import string
def get_string_items(s):
in_object = False
level = 0
current_item = ''
for char in s:
if char in string.ascii_letters:
current_item += char
... | separate string into contents in parentheses vs brackets vs flat text | [
"",
"python",
"regex",
"stack",
"pyparsing",
""
] |
In [this question](https://stackoverflow.com/q/8905501/832621) it is explained how to access the `lower` and `upper` triagular parts of a given matrix, say:
```
m = np.matrix([[11, 12, 13],
[21, 22, 23],
[31, 32, 33]])
```
Here I need to transform the matrix in a 1D array, which can be d... | **The fastest and smartest way to put back a vector into a 2D symmetric array is to do this:**
---
**Case 1: No offset (k=0) i.e. upper triangle part includes the diagonal**
```
import numpy as np
X = np.array([[1,2,3],[4,5,6],[7,8,9]])
#array([[1, 2, 3],
# [4, 5, 6],
# [7, 8, 9]])
#get the upper trian... | Do you just want to form a symmetric array? You can skip the diagonal indices completely.
```
m=np.array(m)
inds = np.triu_indices_from(m,k=1)
m[(inds[1], inds[0])] = m[inds]
m
array([[11, 12, 13],
[12, 22, 23],
[13, 23, 33]])
```
Creating a symmetric array from a:
```
new = np.zeros((3,3))
vals = np... | transform the upper/lower triangular part of a symmetric matrix (2D array) into a 1D array and return it to the 2D format | [
"",
"python",
"arrays",
"numpy",
"matrix",
""
] |
In bash, we can:
```
python - << EOF
import os
print 'hello'
EOF
```
to embed python code snippet in bash script.
But in Windows batch, this doesn't work - although I can still use python -c but that requires me to collpase my code into one line, which is something I try to avoid.
Is there a way to achieve this in ... | You could use a hybrid technic, this solution works also with an python import.
```
1>2# : ^
'''
@echo off
echo normal
echo batch code
echo Switch to python
python "%~f0"
exit /b
rem ^
'''
print "This is Python code"
```
The batch code is in a multiline string `'''` so this is invisible for python.
The batch parse... | Even more efficient, plus it passes all command-line arguments to and returns the exit code from the script:
```
@SETLOCAL ENABLEDELAYEDEXPANSION & python -x "%~f0" %* & EXIT /B !ERRORLEVEL!
# Your python code goes here...
```
Here's a break-down of what's happening:
* `@` prevents the script line from being printed... | How to embed python code in batch script | [
"",
"python",
"windows",
"bash",
"batch-file",
""
] |
**Updated, look bottom!**
I am stuck! I get a IndexError: list index out of range Error.
```
def makeInverseIndex(strlist):
numStrList = list(enumerate(strlist))
n = 0
m = 0
dictionary = {}
while (n < len(strList)-1):
while (m < len(strlist)-1):
if numStrList[n][1].split()[m]... | Good to see some smart veggies programming.
First, your question. Like @Vasiliy said, you have 3 indices. The `n` is alright, since you protect it with your `while` condition. The `1` is fine since `enumerate` always generates 2 things. That just leaves `m`. This is your problem.
Let's say you have `N` elements in `s... | I do not have enough reputation to leave a comment on your post so I'm posting an answer here:
I have copy and pasted the latest code at the bottom (edit 2) and it runs as expected, so there are two potential issues I can see:
1) You might have forgotten to indent your function definition
2) You might have capitalize... | Python: IndexError: list index out of range Error | [
"",
"python",
"list",
"python-3.x",
""
] |
The Kivy Language automatically creates internal binds in properties. For example, if we assign the position of the parent to the position of the child, then the position of the child is going to be updated automatically:
```
Widget:
Label:
pos: self.parent.pos
```
In this case, if we move the parent `Wid... | Comments don't seem to be working right now so I'll post this as a answer.
1. You already have a FloatLayout(your root widget). Use that instead of
creating a new FloatLayout.
2. Before removing the widget from the grid.
* store it's size,
* set size\_hint to None, None
* set pos\_hint to position the widg... | Following @qua-non suggestion, I am temporarily moving the child to another parent. It actually unbinds it, or maybe, rebinds it to the new parent. This is a partial solution because of whatever reason, it doesn't update the position automatically when I took it out of the GridLayout (i.e. when I press enter) and put i... | How to unbind a property automatically binded in Kivy language? | [
"",
"python",
"kivy",
""
] |
Perhaps as a remnant of my days with a strongly-typed language (Java), I often find myself writing functions and then forcing type checks. For example:
```
def orSearch(d, query):
assert (type(d) == dict)
assert (type(query) == list)
```
Should I keep doing this? what are the advantages to doing/not doing thi... | Stop doing that.
The point of using a "dynamic" language (that is strongly typed as to values\*, untyped as to variables, and late bound) is that your functions can be properly polymorphic, in that they will cope with any object which supports the interface your function relies on ("duck typing").
Python defines a nu... | In most of the cases it would interfere with duck typing and with inheritance.
* *Inheritance:* You certainly intended to write something with the effect of
```
assert isinstance(d, dict)
```
to make sure that your code also works correctly with subclasses of `dict`. This is similar to the usage in Java, I t... | Should I force Python type checking? | [
"",
"python",
"types",
"semantics",
""
] |
```
>>> match = re.findall('a.*?a', 'a 1 a 2 a 3 a 4 a')
>>> match
['a 1 a', 'a 3 a']
```
How do I get it to print
```
['a 1 a', 'a 2 a', 'a 3 a', 'a 4 a']
```
Thank you! | I think using a positive lookahead assertion should do the trick:
```
>>> re.findall('(?=(a.*?a))', 'a 1 a 2 a 3 a 4 a')
['a 1 a', 'a 2 a', 'a 3 a', 'a 4 a']
```
[`re.findall`](http://docs.python.org/2/library/re.html#re.findall) returns all the groups in the regex - including those in look-aheads. This works because... | You may use alternative [`regex`](https://pypi.python.org/pypi/regex/2013-06-26) module which allows overlapping matches:
```
>>> regex.findall('a.*?a', 'a 1 a 2 a 3 a 4 a', overlapped = True)
['a 1 a', 'a 2 a', 'a 3 a', 'a 4 a']
``` | Python re.findall print all patterns | [
"",
"python",
"regex",
"findall",
""
] |
```
import subprocess
sample_file_directory = "..." # directory where file is
SCRIPT_DIR = "..." # directory where script is
p = subprocess.Popen([SCRIPT_DIR,sample_file_directory,'min','edgelen'],stdout=subprocess.PIPE,stderr=subprocess.PIPE)
min_side_len, err = p.communicate()
print len(err)
```
So i have this sc... | "One other thing it could potentially be is that you're trying to run a 32-bit binary on a 64-bit system without the 32-bit libraries installed. I actually ran into this issue earlier today. A fix is documented here. I don't know anything about your system, so this may be completely irrelevant advice, but I figured it ... | The problem lies here:
```
p = subprocess.Popen([SCRIPT_DIR,sample_file_directory,'min','edgelen'],stdout=subprocess.PIPE,stderr=subprocess.PIPE)
```
Notice this part:
```
Popen([SCRIPT_DIR,sample_file_directory,'min','edgelen']
```
Now, see, you already know that `subprocess` takes a list. But the problem is that ... | subprocessing library in Python | [
"",
"python",
"subprocess",
""
] |
It's blowing my mind a little bit that OrderedDict in Python is not a sequence type. It has a concept of order, but it's not a sequence.
The [Python docs](http://docs.python.org/2/library/stdtypes.html#sequence-types-str-unicode-list-tuple-bytearray-buffer-xrange) say
> There are seven sequence types: strings, Unicod... | In a duck typing world, this is a difficult question.
Both [sequences and mapping](http://docs.python.org/3/glossary.html#term-sequence) use `__getitem__()` to access items, using inter indexes and keys, respectively. Looking for the availability of the `__getitem__()` method does not tell them apart, you need to look... | [`issubclass(list, collections.abc.Sequence)`](http://docs.python.org/3/library/collections.abc.html#collections.abc.Sequence)
Note this only works on built-in types. | How to know if a Python type has a concept of order? What is a sequence, really? | [
"",
"python",
"types",
"sequences",
""
] |
I have Student table and I want to update (sequence\_No.) field like that:
```
ID Name age sequence_No.
-- ----- --- ------------
1 sara 20 1
2 sara 20 2
3 sara 20 3
4 john 24 1
5 john 2... | ```
SELECT
ID,
Name,
age,
(
CASE Name
WHEN @curType
THEN @curRow := @curRow + 1
ELSE @curRow := 1 AND @curType := Name END
) + 1 AS sequence_No
FROM student, (SELECT @curRow := 0, @curType := '') r
ORDER BY ID,NAME;
```
**[SQL FIDDLE](http://www.sqlfiddle.com/#!2/3e6b6d/5)** | hope this will help you :
```
SELECT *, count(*) as seq_number FROM student a
JOIN student b ON a.name = b.name AND a.id >= b.id
GROUP BY a.id
```
[Sqlfiddle](http://sqlfiddle.com/#!9/7c08f/4) | Numbering duplicates record in mysql | [
"",
"mysql",
"sql",
""
] |
I am calculating `TotalHours` of a employee worked in office based on `Intime` and `Outtime` resultant in the form of `hh.mm` like `8.30`.
So, I wrote below sql query :
```
SELECT EMPLOYEEID, sum(DateDiff(mi,isnull(In_Time,0),isnull(Out_Time,0))/60) +
sum(round(DateDiff(mi,isnull(In_Time,0),isnull(Out_Time,0))%60,2))... | You may try this:
```
select empid,
convert(varchar(5), sum(datediff(minute, [intime], isnull([outtime], dateadd(hh, 19, DATEADD(dd, DATEDIFF(dd, 0, [intime]), 0))))) / 60)
+ ':' +
convert(varchar(5),sum(datediff(minute, [intime], isnull([outtime], dateadd(hh, 19, DATEADD(dd, DATEDIFF(dd, 0, [intime]), 0))))) % 60)
a... | Is it not easier to just discard the null values (returning datediff in seconds from a datetime of zero is what's probably overflowing your query) and also use 'hh' for `datediff`? Or are you also looking for the number of minutes (do you NEED seconds?? If this is for timesheets etc, seconds don't really matter do they... | SQL datediff function resulted in an overflow | [
"",
"sql",
"sql-server-2008",
"sqlexception",
""
] |
I'm having some difficulty implementing a modified version of binary search (it just needs to check if there is a 1 in the sub list, and then continue searching until it returns the index).
Currently the code I've come up with is:
```
def binary_search(inList):
low = 0
high = len(inList) -1
while low <= h... | Man you're asking like three questions in one, but here goes nothing.
To create a testsuit simply write a few good examples and assert that they work, so something like:
```
from binary_search import binary_search
# Test a basic case
inlist = [0] * 256
inlist[123] = 1
assert binary_search(inlist) == 123
# Test a ca... | You can build a simple test suite using `unittest` that can test the result for different inputs, it should be quite simple for this example.
This should get you started - try running this script (after modifying the import to import your binary search module), a google for `python unittest` should give you plenty of ... | Unit testing binary search | [
"",
"python",
""
] |
I'm using django-storages and amazon s3 for my static files. Following the documentation, I put these settings in my settings.py
```
STATIC_URL = 'https://mybucket.s3.amazonaws.com/'
ADMIN_MEDIA_PREFIX = 'https://mybucket.s3.amazonaws.com/admin/'
INSTALLED_APPS += (
'storages',
)
DEFAULT_FILE_STORAGE = 'storage... | collectstatic skips files if "target" file is "younger" than source file. Seems like amazon S3 storage returns wrong date for you file.
you could investigate [code][1] and debug server responses. Maybe there is a problem with timezone.
Or you could just pass --clear argument to collectstatic so that all files are del... | <https://github.com/antonagestam/collectfast>
From readme.txt : Custom management command that compares the MD5 sum and etag from S3 and if the two are the same skips file copy. This makes running collect static MUCH faster
if you are using git as a source control system which updates timestamps. | Django-storages not detecting changed static files | [
"",
"python",
"django",
"amazon-web-services",
"amazon-s3",
""
] |
The user selects various words from a drop down list and these values get added into a comma delimited string. When passing the string to a stored procedure I want it to `select * from` a table where that word exists.
Table
```
id----word
1-----cat
2-----dog
3-----mouse
4-----dog
```
string that is passed into t... | you first need to make a function SplitCSV :
```
CREATE FUNCTION [dbo].[SplitCSV] (@CSVString VARCHAR(8000), @Delimiter CHAR(1))
RETURNS @temptable TABLE (items VARCHAR(8000))
AS
BEGIN
DECLARE @pos INT;
DECLARE @slice VARCHAR(8000);
SELECT @pos = 1;
IF LEN(@CSVString) < 1 OR @CSVString IS NULL RETURN;... | Use `IN`:
```
SELECT *
FROM your_table
WHERE word IN ('cat', 'dog')
``` | Select * from table where column = (any value from a comma delimited string) | [
"",
"sql",
"sql-server",
""
] |
I have written one query to group the tax items, if tax is null, i dont want to display the tax name. How to do this? Please check my sql server statement:
```
SELECT
'CENTRAL EXCISE DUTY' AS 'TaxName',
SUM(TaxAmount) AS 'Tax'
FROM
PMT_InvoiceTaxAttribute
WHERE
InvoiceID = 100
AND Tax... | Since you're using SQL Server, you can simplify it somewhat using a common table expression and just eliminate the rows you don't want using `HAVING` at the end;
```
WITH cte AS (
SELECT
CASE WHEN TaxAttributeName LIKE '%CST%' THEN 'CST'
WHEN TaxAttributeName LIKE '%VAT%' THEN 'VAT'
WHEN TaxA... | Try this:
```
SELECT * FROM (
SELECT
'CENTRAL EXCISE DUTY' AS 'TaxName',
SUM(TaxAmount) AS 'Tax'
FROM
PMT_InvoiceTaxAttribute
WHERE
InvoiceID = 100
AND TaxAttributeName NOT LIKE '%IBR%'
AND TaxAttributeName NOT LIKE '%CST%'
AND TaxAttributeName NOT LIKE '%VAT%'
UNION
SELECT
... | Group by using LIKE Operator and ignore NULL value | [
"",
"sql",
"sql-server",
"sql-server-2008-r2",
"group-by",
"sql-like",
""
] |
I'm trying to analyze the contents of a string. If it has a punctuation mixed in the word I want to replace them with spaces.
For example, If Johnny.Appleseed!is:a\*good&farmer is entered as an input then it should say there are 6 words, but my code only sees it as 0 words. I'm not sure how to remove an incorrect char... | # Simple loop based solution:
```
strs = "Johnny.Appleseed!is:a*good&farmer"
lis = []
for c in strs:
if c.isalnum() or c.isspace():
lis.append(c)
else:
lis.append(' ')
new_strs = "".join(lis)
print new_strs #print 'Johnny Appleseed is a good farmer'
new_strs.split() #prints [... | Here's a one-line solution that doesn't require importing any libraries.
It replaces non-alphanumeric characters (like punctuation) with spaces, and then `split`s the string.
Inspired from "[Python strings split with multiple separators](https://stackoverflow.com/questions/1059559/python-strings-split-with-multiple-... | Trying to count words in a string | [
"",
"python",
"string",
"list",
"function",
"loops",
""
] |
My code is:
```
Criteria criteriaA = getHibernateSession().createCriteria(entityA.class, "aaa");
Criteria criteriaB = criteriaA.createCriteria("entityB").setResultTransformer(CriteriaSpecification.DISTINCT_ROOT_ENTITY); // It seems that the result transformer don't affect the code...
criteriaA.add( -- some restrictio... | As mabi suggested I reply to my questions to post my solution:
---- SOLVED -----
I changed the way I was organizing the query: I've create a detached criteria for the many-side entity and retrieve the other entity with a subquery:
```
DetachedCriteria criteriaA = DetachedCriteria.forClass(EntityA.class, "aaa");
crit... | <http://ora-01791.ora-code.com/> says:
> In this context, all ORDER BY items must be constants, SELECT list
> expressions, or expressions whose operands are constants or SELECT
> list expressions
I hazard a guess that you/hibernate don't select `date`. If you do, can you add the generated SQL to the question? | ORA-01791 on Hibernate Query | [
"",
"sql",
"hibernate",
""
] |
My query:
```
SELECT sites.siteName, sites.siteIP, history.date
FROM sites INNER JOIN
history ON sites.siteName = history.siteName
ORDER BY siteName,date
```
First part of the output:
How can I remove the duplicates in `siteName` column? I wa... | This is where the window function `row_number()` comes in handy:
```
SELECT s.siteName, s.siteIP, h.date
FROM sites s INNER JOIN
(select h.*, row_number() over (partition by siteName order by date desc) as seqnum
from history h
) h
ON s.siteName = h.siteName and seqnum = 1
ORDER BY s.siteName, h.da... | From your example it seems reasonable to assume that the `siteIP` column is determined by the `siteName` column (that is, each site has only one `siteIP`). If this is indeed the case, then there is a simple solution using `group by`:
```
select
sites.siteName,
sites.siteIP,
max(history.date)
from sites
inner joi... | Eliminating duplicate values based on only one column of the table | [
"",
"sql",
"sql-server",
"distinct",
"inner-join",
"duplicates",
""
] |
My code below works great, however, if I select '1', the code will run the if statement and print "success" but it will also run the else statement and exit. How can I stop the else statement running if the user selects 1,2 or 3?
Thanks!
```
print "\nWelcome to the tool suite.\nWhich tool would you like to use?\n"
pr... | You want the `elif` construct.
```
if choice == "1":
...
elif choice == "2":
...
else: # choice != "1" and choice != "2"
...
```
Otherwise, the different `if` statements are disconnected from each other. I've added a blank line for emphasis:
```
if choice == "1":
...
if choice == "2":
...
else: ... | You're looking for `elif`
```
if choice == "1":
execfile("lot.py")
print ("success")
elif choice == "2":
#execfile("spade.py")
print ("success")
elif choice == "3":
#execfile("spkf.py")
print ("success")
elif choice == "i":
print "Google Maps is awesome.\n"
print "SPADE\n"
print ... | If else statement - how to skip past else? | [
"",
"python",
"if-statement",
""
] |
I'm trying to create a file .txt and save the information that the user gives and also open the file in python
i'm having trouble in create the file
here is my code
```
from Tkinter import *
raiz = Tk()
frame = Frame(raiz)
def cadastro():
form = Toplevel(raiz)
Label(form, text='Nome: ').grid(column=0, row=... | Here's the code, I redesigned it to meet your requirements. Feedback would be much appreciated
```
from Tkinter import *
raiz = Tk()
frame = Frame(raiz)
out = []
def cadastro():
form = Toplevel(raiz)
Label(form, text='Nome: ').grid(column=0, row=0, sticky=E)
Label(form, text='Celular: ').grid(column=0, ... | You can use the [open built-in](http://docs.python.org/2/library/functions.html#open) to get a file object with writing permissions, and then fill the content using the [write function](http://docs.python.org/2/library/stdtypes.html#file.write):
```
file = open('<FILENAME>.txt', 'w')
file.write('first line\n')
file.wr... | Python: how to create a file .txt and record information in it | [
"",
"python",
""
] |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.