
Prompt stringlengths 10 31k | Chosen stringlengths 3 29.4k | Rejected stringlengths 3 51.1k | Title stringlengths 9 150 | Tags listlengths 3 7 |
|---|---|---|---|---|
I have a MySQL commands:
```
CREATE DATABASE IF NOT EXISTS courses;
USE courses
CREATE TABLE IF NOT EXISTS teachers(
id INT(10) UNSIGNED PRIMARY KEY NOT NULL AUTO_INCREMENT,
name VAR_CHAR(50) NOT NULL,
addr VAR_CHAR(255) NOT NULL,
phone INT NOT NULL,
);
```
When I run it, I get an error:
```
ERROR ... | It is `varchar` and not `var_char`
```
CREATE DATABASE IF NOT EXISTS courses;
USE courses;
CREATE TABLE IF NOT EXISTS teachers(
id INT(10) UNSIGNED PRIMARY KEY NOT NULL AUTO_INCREMENT,
name VARCHAR(50) NOT NULL,
addr VARCHAR(255) NOT NULL,
phone INT NOT NULL
);
```
You should use a SQL tool to visua... | MySQL doesn't accept using reserved words such as 'name' on column names.
Therefore, to avoid this problem you could use back-ticks(`). This way, MySQL will treat them as column names rather than reserved keywords.
Try this:
Use back-ticks for NAME
```
CREATE TABLE `teachers` (
`id` int(10) unsigned NOT NULL AUTO... | ERROR 1064 (42000): You have an error in your SQL syntax; | [
"",
"mysql",
"sql",
""
] |
I know that the "select record corresponding to the maximum value for a field" has been exhaustively answered, but I was wondering why nobody suggested using an ORDER BY clause to get the right row.
For example, I have this table:
```
| other_field | target_field |
| 1 | 15 |
| 2 | 25 ... | Yes.
It actually has to sort every record before it can return any data. It's highly inefficient. It will return what you want, but not in the best possible way. Aggregate functions tend to do it much better, and much quicker.
With your current query, once you reached a much higher data load, it would take ages to pr... | 1. If you need single value from one or more than one tables then you have to go for Max and GroupBy
2. if you are only one table and requires multiple columns then it is ok to use Order By Desc.
3. if you again need a single value from single table then MAX is preferred here too.
I hope you got my points | SQL getting record for maximum value: why not use "ORDER BY"? | [
"",
"sql",
"max",
"sql-order-by",
""
] |
I apologize for the confusing title, I can't figure out the proper wording for this question. Instead, I'll just give you the background info and the goal:
This is in a table where a person may or may not have multiple rows of data, and those rows may contain the same value for the `activity_id`, or may not. Each row ... | I would do:
```
SELECT first_name, last_name, COUNT(DISTINCT activity_id)
FROM <table_name>
GROUP BY first_name, last_name
HAVING COUNT(DISTINCT activity_id) > 0;
``` | I'll build through the logic with you. First, lets find all people that have more than one entry:
Unique list of name + activity ID:
```
select first_name, last_name,activity_id, count(1)
from yourtable
group by first_name, last_name,activity_id
```
Now we'll turn that into a subquery and look for users with more th... | SELECT Only Records With Duplicate (Column A || Column B) But Different (Column C) Values | [
"",
"mysql",
"sql",
"oracle",
""
] |
I want to get the email address part of a string.
For example if the string is
> "your name(your@name.com)" aaa@bbb.com
then I want to get only
> aaaa@bbb.com
basically if I can remove the string within
> ""
then it does the trick. I am using below regular expression with `REGEXP_SUBSTR`
```
REGEXP_SUBSTR('"your... | You can simply indicate that the match must occur at the end of the string, using `$` anchor.
```
with t1(col) as(
select '"your name(your@name.com)" aaa@bbb.com' from dual
)
select regexp_substr(col, '[[:alnum:]._%-]+@[[:alnum:]._%-]+\.com$') as res
from t1
```
Result:
```
RES
-----------
aaa@bbb.com
``` | You probably need something more along the lines of:
```
REGEXP_SUBSTR('"your name(abc@dd.com)" aaa@bbb.com','[A-Z0-9._%-]+@[A-Z0-9.-]+\.[A-Z]{2,4}')
```
Things like `[.]` doesnt really make sense, dot matches any character and the square brackets is a kind of "OR" statement where any character inside can go in that ... | Regular Expression in Oracle with REGEXP_SUBSTR | [
"",
"sql",
"regex",
"oracle",
""
] |
Is it possible to return the result of two function calls in a select statement?
I have the below TSQL snipped that accepts two csv string which I want to insert into a temp table in order. `dbo.Split` takes the string and returns a table of values.
**Snippet**
```
DECLARE @MeasureCategoryIDs as nvarchar(100)
DECLAR... | ```
INSERT INTO #tmpMeasureCats(MeasureCatID, SnapshotID)
select t1.value, t2.value
from
(SELECT value, row_number() over (order by (select 1)) rn FROM dbo.Split(',',@MeasureCategoryIDs)) t1
join
(SELECT value, row_number() over (order by (select 1)) rn FROM dbo.Split(',',@SnapshotIDs)) t2
on t1.rn = t2.rn
``` | Assuming your functions are working as expected
```
INTO #tmpMeasureCats
SELECT
A.value as 'MeasureCat',
B.value as 'Snapshot'
FROM
dbo.Split(',',@MeasureCategoryIDs) A,
dbo.Split(',',@SnapshotIDs) B
``` | TSQL : Return the results of two functions in a single select statement | [
"",
"sql",
"sql-server-2008",
"t-sql",
"function",
"csv",
""
] |
I have two tables.
```
Table1
ID Text
Table2
ID ParentID Text
```
I am trying to join to the same table twice using 2 different columns. I want all the rows where Table1.ID = Table2.ID as well as all the rows where Table1.ID = Table2.ParentID. I've tried the following but it returns no rows. When I run the ... | You're only getting the records where Table 1 is both a Parent ID and an ID... maybe you want:
```
SELECT
* FROM Table 1
JOIN Table2 2 on 2.ID = Table1.ID
UNION
SELECT
* FROM Table 1
JOIN Table2 22 on 22.ParentID = Table1.ID
```
Or potentially UNION ALL? | You could try this query:
```
SELECT
*
FROM
TABLE1,
TABLE2
WHERE
TABLE1.ID = TABLE2.ID
OR
TABLE1.ID = TABLE2.ParentID
``` | Joining to Same Column but Getting No Rows | [
"",
"sql",
"sql-server-2008",
""
] |
In a procedure I have statements like below
```
declare @mnth int
select @mnth=month(cast('08/12/2013' as datetime))
if( @mnth<7)
begin
--some statements
end
else
begin
--some other statements
end
```
I am getting error
> Incorrect syntax near the keyword 'else'.
I can't understand what is wrong. Please help | Have you really entered some statements in between the `begin` and `end` statements? Because I'm pretty sure the error message will vanish once there is something to begin with.
Side note: This probably should have been a comment rather than an answer, but I can't comment yet and I think it will solve the problem (if... | There should be some actual code inside begin/end, I guess you only have comments there. | Error in if else condition TSQL | [
"",
"sql",
"sql-server",
"t-sql",
"sql-server-2005",
""
] |
In building a web app recently, I started thinking about the information returned from a query I was making:
Find the user information and (for simplicity sake) the associated phone numbers tied to this user. Something as simple as:
```
SELECT a.fname, a.lname, b.phone
FROM users a
JOIN users_phones b
ON (a.us... | A query with a `JOIN` may be slower than two independent queries. It really depends on the type of access you're doing.
For your example, I'd go with the two query approach. These queries could be executed in parallel, they could be cached, and there's no real reason to `JOIN` other than for arbitrary presentation con... | I think that really depends on your use case. In the example you gave, it seems to make sense to return it as two queries, especially if you're passing that info back to a mobile device where you want to make sure you send them as little data as possible (not everyone has unlimited data.....)
I'd probably stick a DIST... | Is it ever "ok" to use multiple queries instead of one? | [
"",
"mysql",
"sql",
"database",
"join",
""
] |
I have a table with fields `id` (primary key) and `fid`. I want to get the record where `id` matches a particular value, as well as all related records that have its same `fid` value.
I can do this:
```
SELECT * FROM mytable
WHERE fid = (SELECT TOP 1 fid FROM mytable WHERE id = 'somevalue')
```
But I don't want the... | Based on your revision, the problem seems to be "select all rows where `id` has a certain value and all other rows with the `id` matches "somevalue" and the `fid` is not null.
The following captures this logic:
```
SELECT t.*
FROM mytable t left outer join
(SELECT TOP 1 fid
FROM mytable
WHERE id = '... | I'm not certain I understand your question, but I'll take a stab at it. What I think you're asking is if you can select all records from one table where either the id or fid fields equal a particular value, but you don't want the related fields if the particular value you're searching on equals an empty guid value. If ... | SQL statement to conditionally select related records | [
"",
"sql",
"sql-server",
""
] |
i have the following tables:
**TABLE: teachers:**
> teacherID
> teacherName
**TABLE: students:**
> studentID
> studentName
> teacherID
> advisorID
so, usually, i know i can get a single row per student, with their teachers name using an INNER JOIN.
but in this case - the advisor and tacher - are from the ... | This lists students with the names of their teachers and advisors if any, in alpha order of student, without either (a) the teacher or (b) the advisor having to exist. If you want only where those names exist, change the respective join to an INNER join.
```
SELECT s.studentname as [Student], t.teachername as [Teacher... | You can join to the same table more than once, just give it a different alias for each join, and name your fields in a descriptive enough way. Use a left join if there might not be a link, but if a student always has both a teacher and an advisor, a straight join should be fine.
Something like this:
```
select s.stud... | Multiple joins onto same table | [
"",
"sql",
"sql-server",
""
] |
I have a column of data that's `varchar(50)`. A sample data point reads "31-Dec-2001".
Is it possible to convert this into `DateTime`? I use SQL Server 2008. Thanks. | ```
CREATE TABLE T
(
X VARCHAR(50) NOT NULL
);
INSERT INTO T VALUES ('31-Dec-2001');
SET LANGUAGE ENGLISH;
ALTER TABLE T ALTER COLUMN X DATETIME NOT NULL;
``` | Yes it is!!
```
select convert(datetime,'31-Dec-2001')
``` | How to convert a varchar(50) into DateTime in SQL? | [
"",
"sql",
"sql-server",
"sql-server-2008",
""
] |
I have the following table
* quizId is the ID of a quiz in the db
* userId corresponds to the user who took up the quiz with the respective quizId
```
quizId | userId
1 | 9
1 | 10
1 | 11
2 | 11
3 | 11
```
* Now, consider the userId to be 9.
* I need a query that wil... | The simplest to understand query is:
```
select *
from quiz
where id not in (
select quiz_id
from user_quiz
where user_id = 9)
```
A more advanced way would be:
```
select *
from quiz q
left join user_quiz uq
on uq.quiz_id = q.id
and uq.user_id = 9
where uq.user_id is null
```
The join version may perfo... | You also need to use the table where the quizes are stored. If you take the quizId from the quizLog table, you will only see the ones that someone already have taken, so new quizes would never show up.
You can make a left join on the quizLog table, and get the quizes where there is no match.
```
select q.quizId
from ... | How to find a column with respect to another column in the same table? | [
"",
"mysql",
"sql",
""
] |
I have an application running in different cities. Each city has a server with different host name (IP ADDRESS). My Application connects to a database using the connectionString configuration from the config file like the sample below:
```
<add name="SAC_NG.My.MySettings.db_SACConnectionString" connectionString="Data... | I suggest you do as Mr. MarkAnswer suggests first:
Set up three connection strings with appropriate names that indicate to you which city they are for.
After that is done, you can have the user select the city (from a Dropdownlist or Radiobuttonlist for instance) and store it in a `session` variable, and in accordance... | Add ipaddress of your server with instance of sql server to the data source..
```
example: 192.168.1.251\PISDEV
```
Create Different connection strings for different ip..
IN the code behind try to get the country and choose the connection based on the selected country..
(If you are not clear about ip and instance j... | Use config file to connect in different database sql server Application in .NET | [
"",
".net",
"sql",
"sql-server",
""
] |
I Have a problem with oracle split query.
While splitting comma separated data into multiple rows using connect by and regular expression in oracle query I am getting more **duplicate rows**. for example actually my table having 150 rows in that one two rows having comma separated strings so overall i have to get only... | Finally I came up with this answer
```
WITH CTE AS (SELECT 'a,b,c,d,e' temp, 1 slno FROM DUAL
UNION
SELECT 'f,g' temp, 2 slno FROM DUAL
UNION
SELECT 'h' temp, 3 slno FROM DUAL)
SELECT TRIM(REGEXP_SUBSTR(temp, '[^,]+', 1, level)), slno
FROM CTE
CONNECT BY level <=... | Try like this,
```
WITH CTE AS (SELECT 'a,b,c,d,e' temp,1 slno FROM DUAL
UNION
SELECT 'f,g',2 from dual
UNION
SELECT 'h',3 FROM DUAL)
SELECT regexp_substr (temp, '[^,]+', 1, rn)temp, slno
FROM cte
CROSS JOIN
(
SELECT ROWNUM rn
... | oracle -- Split multiple comma separated values in oracle table to multiple rows | [
"",
"sql",
"regex",
"oracle",
"split",
""
] |
I been practicing queries, and my current scenario is to find the nearest Saturday for a given date. After i got the logic down, i came up with a, whats looks like a long and messy query. And I was wondering if there is a way to simplify this.
Here's my query
```
DECLARE @DATE DATE
SET @DATE ='2013-09-13'
IF ... | Here's my hint without answering, as you requested:
Consider date manipulation, using current date (you can use `GETDATE()` or your date variable), `DATEADD()` and `DATEDIFF()` can be used to write this in a couple lines.
If you just want to simplify your method you could use a `CASE` statement:
```
DECLARE @date DA... | Try this:
```
select dateAdd(dd,7-DATEPART(dw,getDate()),GETDATE())
```
**datePart(dw,...)** returns day of the week for current date.
**7 - that number**, returns number of days until Saturday
Add the result to the date to get the next Saturday...
Similar logic if you need to go back to previous Saturday
Sql Fid... | How to find the Nearest (day of the week) for a given date | [
"",
"sql",
"sql-server-2008-r2",
""
] |
I have a news tables as follows, when editing news I would like to see the original version of the news and edited versions of news by all the users how do i make database table structure for that ?
```
Table news
News id, title, headline, content, date, user
``` | The long answer is to learn about Time-Oriented Database Applications, there's a [web site](http://www.cs.arizona.edu/~rts/publications.html) that has an [eBook](http://www.cs.arizona.edu/~rts/tdbbook.pdf) about it.
The short version is to either have another table for the history or change you existing table to allow... | I’d go with pretty much identical table structure for history.
Table NewsHistory
News\_History\_ID, News id, Revision, title, headline, content, date, user
News\_ID would reference the latest version of the news in news table
Revision would be used to make tracking easier
What you can do is to create UPDATE trigger ... | Database structure for edited news | [
"",
"sql",
"sql-server",
""
] |
I am trying to SUM two CASE functions that I just created in my query. I need both of these columns to return in my result set, but also need the sum of the two columns to return in another column as 'DegreeDays.' I tried the SUM function, but to no avail, and I tried a simple a 'HeatingDegreeDays + CoolingDegreeDays A... | One way is to simply make your existing query into a [derived table](http://www.sqlteam.com/article/using-derived-tables-to-calculate-aggregate-values):
```
SELECT a.HeatingDegreeDays,
a.CoolingDegreeDays,
a.HeatingDegreeDays + a.CoolingDegreeDays as DegreeDays
FROM
(
SELECT
CASE
WHEN TempLow... | You can repeat the formulas:
```
,CASE
WHEN TempLow > 60.5 THEN 0
WHEN ((TempHigh + TempLow)/2) > 60.5 THEN ((60.5-TempLow)/4)
WHEN TempHigh >= 60.5 THEN (((60.5 - TempLow)/2)-((TempHigh-TempLow)/4))
WHEN TempHigh < 60.5 THEN (60.5-(TempHigh... | SUM two CASE functions | [
"",
"sql",
"sql-server",
""
] |
I've been scouring the internet trying to find an answer to this but I am coming up empty handed. I was wondering if there is a function that acts as an opposite to the `nvl` function. Something like this:
```
UPDATE transaction_review
SET "function use if null"(review1,review2) = 'Yellow',
"function use if ... | If I understand you correctly try do use **[coalesce](http://www.techonthenet.com/oracle/functions/coalesce.php)** function as below
```
UPDATE transaction_review
set review1 = coalesce(review1,'Yellow'),
review2 = coalesce(review2,'Audit')
WHERE ACCOUNT = '11111111'
``` | Try NVL2 command in plSQL.
> The NVL2 function accepts three parameters. If the first parameter
> value is not null it returns the value in the second parameter. If the
> first parameter value is null, it returns the third parameter. | Function that is opposite of nvl | [
"",
"sql",
"oracle",
""
] |
Basically I have the following in one table (only the first 25 rows) and I get it by doing this simple query.
```
select * from SampleDidYouBuy
order by MemberID, SampleID, DidYouBuy
SampleDidYouBuyID SampleID MemberID DidYouBuy DateAdded
-----------------------------------------------------------------
121... | Updated:
```
select a.MemberId,
count(distinct a.SampleId) as unique_nos
from SampleDidYouBuy a
where a.DIdYouBuy = 0
and not exists (select 1
from SampleDidYouBuy b
where b.MemberId = a.MemberId
and b.SampleId = a.SampleId
... | Well, the simiplication of your problem is to count unique MemberId
```
SELECT COUNT(*) FROM (
SELECT * FROM SampleDidYouBuy
WHERE SampleID = {YourSampleID}
GROUP BY MemberID
) AS sample;
``` | Counting and Excluding based on conditions | [
"",
"mysql",
"sql",
"count",
""
] |
I'm getting the following error:
**#1064 - You have an error in your SQL syntax; check the manual that corresponds to your MySQL server version for the right syntax to use near 'JOIN product\_catalog ON product\_catalog.entity\_id**
As a result of the following query:
```
SELECT sales_order.created_at , order_item.o... | Please make sure that `WHERE` condition must be after all `JOIN`
```
SELECT sales_order.created_at , order_item.order_id, sales_order.increment_id, SUM(order_item.qty_ordered) AS qty_ordered , COUNT( * )
FROM order_item
JOIN sales_order
ON sales_order.entity_id = order_item.order_id
JOIN product_catalog
ON product... | `JOIN...ON...` clause it's also section to input condition so you don't need `where` clause, just add `AND` instead.
```
SELECT sales_order.created_at , order_item.order_id, sales_order.increment_id,
SUM(order_item.qty_ordered) AS qty_ordered , COUNT( * )
FROM order_item
JOIN sales_order ON sales_orde... | MySQL throwing error on second JOIN | [
"",
"mysql",
"sql",
"join",
"syntax-error",
"inner-join",
""
] |
This query returns missing right parenthesis although when I run the inside query it runs fine.
```
select t.id
from
(select
v.id,
max(c.image_type_id),
max(vp.x),
max(vp.y),
max(vp.z)
FROM
v,
vp,
c,
WHERE v.id = vp.id
AND v.id = c.id
group by v.id;) t
``` | Remove semicolon `;` and `,`
```
SELECT t.id
FROM
(SELECT
v.id,
max(c.image_type_id),
max(vp.x),
max(vp.y),
max(vp.z)
FROM
v,
vp,
c // HERE the comma
WHERE v.id = vp.id
AND v.id = c.id
GROUP BY v.id) t // HERE the semicolon
``` | Just remove semicolon and last comma. Try to run below code.
```
select t.id
from
(select
v.id,
max(c.image_type_id),
max(vp.x),
max(vp.y),
max(vp.z)
FROM
v,
vp,
c
WHERE v.id = vp.id
AND v.id = c.id
group by v.id) t
``` | Missing right parenthesis subquery | [
"",
"sql",
""
] |
I have a date column in a table. The date column is in varchar. I want to identify a particular date range from that date column. My query is like this:
```
SELECT *
FROM [003 AccptReg].[dbo].[SysData1]
WHERE [RegDate_Sys] > '18 jul 2013'
```
But the result is not giving accurate result, i.e. it gives dates which ar... | The problem is that you have the date as a `varchar`, and doesn't convert it to a date when you are doing the comparison. The database doesn't know that you see the data as dates, and will simply compare them as strings, so for example `'2 jan 1736'` will be larger than `'18 jul 2013'` because `2` comes after `1`.
The... | For date column, you should compare as **DATE**
```
select * from [003 AccptReg].[dbo].[SysData1]
where CAST([RegDate_Sys] AS DATE) > CAST('18 jul 2013' AS DATE)
``` | Need to identify number that is higher than a given date | [
"",
"sql",
"sql-server",
"date",
""
] |
I have a small select query which picks data from a table as per the parameter passed to a procedure.
```
DECLARE @flgParam bit
```
.
.
```
SELECT *
FROM tablename
WHERE flgRequired like <If @flgparam is 0 then 1 or zero , Else 1>
```
what is the best way to construct the where clause | A bit rough, but it should work, based on requirements:
```
select
S.itemname
,S.flgrequired
from
sample S
where
(S.flgRequired >= @flgParam)
```
[Tested on sqlfiddle](http://sqlfiddle.com/#!3/fb559/3). | I'm thinking something like this:
```
SELECT *
from tablename
where @flgparam is null or @flgcolumnval = @flgparam;
```
@flgparam is declared as a bit, so it can only take on the values of `NULL`, `0`, and `1`.
EDIT:
I'm trying to understand the logic. Adapted for the right names:
```
SELECT *
from sample
where (@... | SELECT statement having where clause with dynamic condition | [
"",
"sql",
"sql-server",
"select",
""
] |
I have a table Item and I want to get the minimum price of the Item for the particular id
**Table Item:**
```
Id Price1 Price2 Price3
1 10 20 30
2 20 30 40
```
According to the above example, the minimum price... | One approach could be like this:
```
SELECT Id, MIN(Price) FROM (
SELECT Id, Price1 As Price FROM Table1
UNION ALL
SELECT Id, Price2 As Price FROM Table1
UNION ALL
SELECT Id, Price3 As Price FROM Table1
) As AllValues
GROUP BY Id
```
This works even if there are `null` values. Here is the [working demo... | Two similar solutions, using **[`APPLY`](http://technet.microsoft.com/en-us/library/ms175156%28v=sql.90%29.aspx)** operator:
```
SELECT t.Id,
MIN(m.Price)
FROM
tableX AS t
CROSS APPLY
( SELECT Price = Price1 UNION
SELECT Price2 UNION
SELECT Price3
) AS m
GROUP BY t.Id ;
SELECT t... | How to get the minimum value from the columns | [
"",
"sql",
"sql-server-2008",
"sql-server-2005",
""
] |
How can I get all the system stored procedures listed by MS SQL Server (2012) using an SQL query? | `sysobjects` is deprecated. You can use
```
SELECT QUOTENAME(SCHEMA_NAME(schema_id)) + '.' + QUOTENAME(name)
FROM sys.all_objects
WHERE type = 'P'
AND is_ms_shipped = 1
``` | ```
SELECT sch.name + '.' + obj.name
FROM sysobjects obj, sys.schemas sch
WHERE obj.type = 'P'
AND sch.schema_id = obj.uid
AND sch.name = 'sys'
--AND obj.name like '%my_search_string%'--use this for filtering
ORDER BY sch.name + '.' + obj.name
``` | Query returning all system stored procedures listed by MS SQL Server | [
"",
"sql",
"sql-server",
"sql-server-2012",
""
] |
I want swap two records in sql server for example

How can i do it? | You can do it in one statement with `JOIN` like this
```
UPDATE t1
SET t1.id = t2.id
FROM table1 t1 JOIN table1 t2
ON (t1.id = 1 AND t2.id = 2)
OR (t1.id = 2 AND t2.id = 1)
```
Output after update:
```
| ID | NAME | FAMILY |
|----|------|--------|
| 1 | Mary | Simson |
| 2 | Jame | Ander |
```
Here ... | in the case that ID is `identity` you could use a combined solution between @Vaibs\_Cool and @user814064
something like this
```
DECLARE @aID INT, @bID INT
SELECT @aID = 123, @bID = 987
;WITH ToSwap AS
(
SELECT CASE WHEN id = @aID THEN @bID ELSE @aID END AS id, [Name], [Family]
FROM YourTable
WHERE id IN... | how can I swap two records in sql server with script | [
"",
"sql",
"sql-server-2008",
""
] |
i have column name [car\_no] i want to rename it....
I am thinking like this :
```
exec sp_rename 'add_duty_slip.[car_no]' , 'car_no', 'column'
```
but it didn't work.
thanks | Your code runs like a charm. See [this fiddle](http://sqlfiddle.com/#!3/d89cb/1).
But using the same name for both old and new names won't do anything.
With using a different name for both (i.e. actually renaming the column), like :
```
exec sp_rename 'add_duty_slip.[car_no]' , 'car_no1', 'column'
```
works well to... | This would help you.
```
sp_RENAME 'TableName.[OldColumnName]' , '[NewColumnName]', 'COLUMN'
```
Also, Since, both old name and new names are the same, you are unable to notice the change even after you run your code. | I want to rename column name in sql server | [
"",
"sql",
"sql-server",
""
] |
I have Products, from many Brands, which a User can favorite (many-to-many) and also the User can follow Brands. And for the homepage I need all the products which the user has added to favorites and the products from Brands the User follows.
I have came with the following SQL query, which however, works not as expect... | One 'simple' approach (just modifying your existing query) could be to turn both of your `INNER JOIN`s into `LEFT JOIN`s and check that `at least one of the two joined successfully` in the `WHERE` clause...
```
SELECT
*
FROM
products
LEFT JOIN
favorites
ON products.id = favorites.favorable_id
AND favori... | Try to replace the
```
INNER JOIN followings ON products.merchant_id = followings.followable_id
```
with
```
left JOIN followings ON favorites.favorable_id = followings.followable_id
``` | SQL left join between three tables with union | [
"",
"sql",
"postgresql",
"join",
""
] |
Consider this table :
```
dt qnt
---------- -------
1 10
2 -2
3 -4
4 3
5 -1
6 5
```
How do I create a query to get this result? (res is a running total column):
```
dt qnt res
---- ----- -----
1 ... | You can do it using a simple subquery that calculates the sum up to the current row, which should work well on any version of SQL Server;
```
SELECT dt, qnt,
(SELECT SUM(qnt) FROM Table1 ts WHERE ts.dt <= t1.dt) res
FROM Table1 t1
ORDER BY dt;
```
[An SQLfiddle to test with](http://sqlfiddle.com/#!6/0b7c4/1).
If ... | If you are Using sql Server 2012 than you can try like this.
```
Select * ,Sum([qnt]) Over(order by dt) from table1
```
[**Sql Fiddle Demo**](http://sqlfiddle.com/#!6/2341f/1) | Please help me to write this query in SQL Server | [
"",
"sql",
"sql-server",
""
] |
I have a query like this:
```
SELECT *
FROM table1 ref1,
table1 ref2,
table2 ref3,
table2 ref4,
table3
WHERE ref3.a = ref1.b ,
ref4.a = ref2.b ,
ref3.c = f,
ref4.c = d
```
and it works great, it gives me 1 record with all the columns I want.
Two of these columns... | The best way to do that is using table aliases and column aliases as below
for one column:
```
SELECT ref1.frubberducks
FROM table1 ref1,table1 ref2,table2 ref3,table2 ref4,table3
WHERE ref3.a = ref1.b and ref4.a = ref2.b and ref3.c=f and ref4.c=d
```
for two columns with the same name:
```
SELECT ref1.frubberducks... | The best way is to be explicit such as with:
```
SELECT ref1.frubberducks as frubberducks,
ref3.frubberducks as frubberducks_1 ...
```
`select *` means you want everything and you're not overly concerned about where it is in the result set. If you *did* care, you'd be explicitly listing the columns. There are ... | "column ambigiously defined" error | [
"",
"sql",
"oracle",
"name-collision",
""
] |
I ask this question with a bit of sheepishness because I should know the answer. Could someone be kind and explain if and how injection could occur in the following code?
```
<cfquery>
select * from tableName
where fieldName = '#value#'
</cfquery>
```
I'm specifically curious about injection attempts and othe... | > doesn't CF already "magically" do this in CF query tag when you wrap evaluated variables in single quotes?
Yep, it'll convert `'` to `''` for you.
Now guess what SQL you get from this code:
```
<cfset value = "\'; DROP TABLE tableName -- " />
<cfquery>
select * from tableName
where fieldName = '#value#'
<... | **Update:**
While this answers part of your question, [Peter's response](https://stackoverflow.com/a/18797042/104223) is better, in that it directly addresses your question of "Why use cfqueryparam, when CF automatically adds protection by escaping single quotes?". Answer: In short, because the latter does not always ... | ColdFusion Query - Injection Protection | [
"",
"sql",
"coldfusion",
"sql-injection",
"cfml",
""
] |
I've found a number of examples showing how to select a single oldest/newest row from a grouped set, but am having trouble getting the oldest two rows from a data set.
Here's my sample table:
```
CREATE TABLE IF NOT EXISTS `orderTable` (
`customer_id` varchar(10) NOT NULL,
`order_id` varchar(4) NOT NULL,
`date_... | The best (i.e. most performant) approach is to use a User Defined Variable in the query.
```
SELECT tmp.customer_id, tmp.date_added
FROM (
SELECT
customer_id, date_added,
IF (@prev <> customer_id, @rownum := 1, @rownum := @rownum+1 ) rank,
@prev := customer_id
FROM orderTable t
JOIN (SELECT @row... | Your original query should be (use customer\_id in subquery)
```
SELECT customer_id, order_id, date_added
FROM orderTable T1
WHERE (
select count(*) FROM orderTable T2
where T2.customer_id = T1.customer_id AND T2.date_added <= T1.date_added
) <= 2;
```
You can also use variables:
```
SELECT customer_id, order_... | Select oldest two records from group | [
"",
"mysql",
"sql",
"group-by",
"greatest-n-per-group",
""
] |
I have a select statement
```
select
name
,age
from table_employees
where id=@impId;
```
I want to check if age is null than return zero. I tried following but it doesn't work
```
select
name
,age isnull(age,0.00)
from table_employees
where id=@impId;
```
Please let me know how ... | Try this way
```
select
name,age=isnull(age,0.00)
from table_employees
where id=@impId;
```
or
```
select
name,
isnull(age,0.00) as age
from table_employees
where id=@impId;
``` | In SQL Server 2005 or later, you can use the [`COALESCE`](http://msdn.microsoft.com/en-us/library/ms190349.aspx) function for that:
```
SELECT
name
, COALESCE(age, 0) as age
FROM table_employees
WHERE id=@impId
```
The function evaluates its arguments one by one, and returns the first non-`NULL` value. | Returning zeros if null | [
"",
"sql",
"sql-server",
"t-sql",
""
] |
I have a SQL query, where I'm using a subquery in a WHERE clause. I then need to use the same subquery again to compare it to a different column.
I'm assuming there isn't a way for my to access 'emp\_education\_list li' outside of the subquery?
I'm guessing the subquery repetition is redundant. I'm a bit rusty in SQL... | Give this a try,
```
SELECT e.fname, e.lname
FROM employee e
INNER JOIN emp_education_list l
ON e.skillsID = l.skillsID
INNER JOIN
(
SELECT li.educationID, li.edu_level
FROM emp_education_list li
INNER JOIN job j
... | Try this one with `JOIN` i guess proper joining will take care of rest of the conditions
```
SELECT e.fname, e.lname
FROM employee e
JOIN emp_education_list l ON (e.skillsID = l.skillsID)
JOIN job j ON ( j.skillsID = l.skillsID AND j.jobID = 1001)
``` | MySQL Subquery Repetition Avoidance in WHERE/AND | [
"",
"mysql",
"sql",
"subquery",
"reusability",
""
] |
What SQL select query can I use to sort each row and then order the sorted rows?
E.g.: *table tab (c1, c2, c3, c4)*
```
2,5,8,4
2,1,6,7
5,2,9,3
```
The query must give:
```
1,2,6,7
2,3,5,9
2,4,5,8
``` | ```
SELECT
MIN(c1, c2, c3, c4) AS new_c1,
CASE MIN(c1, c2, c3, c4) WHEN c1 THEN MIN(c2, c3, c4)
WHEN c2 THEN MIN(c1, c3, c4)
WHEN c3 THEN MIN(c1, c2, c4)
WHEN c4 THEN MIN(c1, c2, c3)
END AS new_c2,
CASE MAX(c1, c2, c3, c... | It's just somthing to start with, maybe not the most "clean" code, but it will work
```
SELECT CASE WHEN C1 < C2 THEN
CASE WHEN C1 < C3 THEN C1 ELSE C3 END
ELSE
CASE WHEN C2 < C3 THEN C2 ELSE C3 END
END
From YourTable
```
This will select the smallest element in th... | SQL to sort columns within each row and order rows based on this | [
"",
"sql",
"sqlite",
"sorting",
"select",
""
] |
I have a table where I store some items with prices and others items without prices.
I want to select all the items with price but in the otherhand I want to select some items without prices at the same time. Is there any choice to do this?
Right now I have this select statement:
```
SELECT DISTINCT TOP 100 PERCENT ... | If you want to select all items with price > 0 plus the ine with id 000228, the where clause needs to be "price > 0 OR idItem = '000228'" | Try to add `price is null` condition as below
```
SELECT DISTINCT TOP 100 PERCENT idItem, itemDescription, price
FROM myTable
WHERE (price > 0 or price is null) and idItem = '000228'
``` | sql where clause but not for some records | [
"",
"sql",
"sql-server",
"sql-server-2008",
""
] |
Every time I run this and add as an input the words 'yellow' or 'red' or 'blue', the same error appears.
```
set serveroutput on
undefine color1
undefine color2
accept color1 prompt 'Type the 1st primary color: '
accept color2 prompt 'Type the 2nd primary color: '
begin
if &color1 = &color2 then
dbms_output.p... | Try like this,
```
set serveroutput on
undefine color1
undefine color2
accept color1 prompt 'Type the 1st primary color: '
accept color2 prompt 'Type the 2nd primary color: '
BEGIN
IF '&color1' = '&color2' THEN
dbms_output.put_line('&color1'||' plus '||'&color2'||' then '||'&color1');
elsif ('&color1' LIKE... | `&color1` is a substitution variable, sqlplus basically replaces `&color1` with user input contents - which has to be a single-quoted literal here. As long as it is not, your `blue` input is treated as a variable name, which is not defined.
So, you have two options - either to input quoted `'blue'`, `'yellow'` etc. in... | Identifier 'input' must be declared - PL SQL | [
"",
"sql",
"oracle",
"plsql",
""
] |
I have 3 tables (user, item, userlike) and 2 sql queries. How can I unify these two queries?
```
SELECT item.userid, item.id, user.name FROM item
INNER JOIN user ON item.userid = user.id
SELECT userid,itemid, COUNT(*) AS `liked` FROM userlike
WHERE userid=9
GROUP BY itemid
```
I want to know whether a specific use... | You want to use an `OUTER JOIN` for this
```
SELECT i.id itemid, u.id userid, u.name, COALESCE(liked, 0) liked
FROM item i JOIN user u
ON i.userid = u.id LEFT JOIN
(
SELECT itemid, COUNT(*) liked
FROM userlike
WHERE userid = 9
GROUP BY itemid
) l
ON i.id = l.itemid;
```
or
```
SELECT i.id i... | ```
SELECT item.id, item.userid, user.name, userlike.liked
FROM item
JOIN user ON user.id = item.userid
JOIN userlike ON item.id = userlike.itemid
WHERE userlike.liked = 1
GROUP BY item.id
```
**OR**
```
SELECT item.id, item.userid, user.name, userlike.liked
FROM item
JOIN user ON user.id = item.userid
JOIN userlike ... | SQL INNER JOIN and COUNT | [
"",
"mysql",
"sql",
"union",
""
] |
I am tasked to calculate the difference in months and fiscal years from a `NUMBERS` column and a `SHIP_DATES` column. I have trouble converting date or time from character string in the `NUMBERS` columns (`NUMBER_MONTH`), and (`NUMBER_FY`) before the calculations.
Could someone please look? Basically, the issue I have... | When you call [DATEDIFF](http://technet.microsoft.com/en-us/library/ms189794.aspx) the 2nd and 3rd arguments are of type DateTime where you pass strings for the 2nd argument and integers for the 3rd argument.
I think (if i understand what you are trying to do) you should convert the strings to numbers, get rid of the ... | I would try something more along these lines:
```
CREATE TABLE #TEMP
(NUMBERS VARCHAR (20), SHIP_DATES_A DATETIME, SHIP_DATES_B DATETIME, ID INT)
```
Then for testing:
```
INSERT INTO TEMP VALUES ('ABC1006000046', '6/5/2010','7/15/2013', '123')
INSERT INTO TEMP VALUES ('CDS0809000059', '9/8/2008','1/31/2013', '... | Convert Varchar columns to Datetime | [
"",
"sql",
"sql-server",
"t-sql",
""
] |
I'm looking to update multiple rows in PostgreSQL in one statement. Is there a way to do something like the following?
```
UPDATE table
SET
column_a = 1 where column_b = '123',
column_a = 2 where column_b = '345'
``` | You can also use [`update ... from`](https://www.postgresql.org/docs/current/static/sql-update.html) syntax and use a mapping table. If you want to update more than one column, it's much more generalizable:
```
update test as t set
column_a = c.column_a
from (values
('123', 1),
('345', 2)
) as c(column_b... | Based on the solution of @Roman, you can set multiple values:
```
update users as u set -- postgres FTW
email = u2.email,
first_name = u2.first_name,
last_name = u2.last_name
from (values
(1, 'hollis@weimann.biz', 'Hollis', 'Connell'),
(2, 'robert@duncan.info', 'Robert', 'Duncan')
) as u2(id, email, first_na... | Update multiple rows in same query using PostgreSQL | [
"",
"sql",
"postgresql",
""
] |
I'm having difficulties managing the queries like this:
```
SELECT c.id, p.id FROM claim c, procedure p LIMIT 1;
```
This query will return following set:
```
id | id
----+----
49 | 1
```
Is there any way to make it return `c.id` and `p.id` for column names? This one doesn't work:
```
SELECT c.id as c.id, p.id ... | ```
SELECT c.id AS "c.id", p.id AS "p.id" FROM claim c, procedure p LIMIT 1;
```
or simply:
```
SELECT c.id "c.id", p.id "p.id" FROM claim c, procedure p LIMIT 1;
``` | With a proper **naming convention** you would rarely have to deal with this problem to begin with.
I suggest to use something like this instead:
```
CREATE TABLE claim (claim_id serial PRIMARY KEY, ...);
CREATE TABLE procedure (procedure_id serial PRIMARY KEY, ...);
```
`"id"` is a *very bad choice* for a column na... | SELECT statement returning unqualified column names | [
"",
"sql",
"postgresql",
"naming-conventions",
"alias",
""
] |
I have this SQL for retrieving all items
```
SELECT A.item_code,A.description,A.uom, A.open_stock, B.recd_total, C.issue_qty
FROM chem_master as A
LEFT JOIN ( SELECT item_code, sum(recd_qty) as recd_total
from chem_reciepts GROUP BY item_code) as B on A.item_code=B.item_code
LEFT JOIN(SELECT item_code, sum(iss_qty) as... | You can add `having` with the condition you mentioned to your query(at the end of query).
Something like below:
```
HAVING op.stock+recd_total-issue_qty=0
``` | Try this one
```
SELECT q.*, (q.stock+(q.recd_total-q.issue_qty)) as resultant FROM (
SELECT A.item_code,A.description,A.uom, A.open_stock, B.recd_total, C.issue_qty
FROM chem_master as A
LEFT JOIN ( SELECT item_code, sum(recd_qty) as recd_total
from chem_reciepts GROUP BY item_code) as B on A.item_code=B.item_code
LE... | Adding and subtracting sum columns in mysql queries | [
"",
"mysql",
"sql",
""
] |
Is it possible to use a Linux environment variable inside a .sql file? I'm using the copy/select query to write to an output file, and I'll like to put that directory in a variable. So I want to do something like:
```
COPY (SELECT * FROM a)
TO $outputdir/a.csv
```
Outputdir would be set in my environment. Is this pos... | You can store the result of a shell command inside a `psql` variable like this:
```
\set afile `echo "$outputdir/a.csv"`
COPY (SELECT * FROM a) TO :'afile';
```
Another (better in my opinion) solution is to use only `psql` variables, see [this answer of mine about psql variables](https://stackoverflow.com/questions/1... | This appears to work for your use case, provided you single quote the output file name as I mentioned. It will escape any double quotes as well contained within the SQL.
```
psql -c "$(eval echo '"' $(<envvars.sql | sed 's/"/\\"/g') '"')"
```
Of course, note that if your file contains any dollar quoted variables, the... | Using an environment variable in a PSQL script | [
"",
"sql",
"postgresql",
"environment-variables",
""
] |
I think i have a somewhat simple problem but due to my lack of experience in DB modelling and SQL i'm unable to get the right solution,
i can draw the basic concept but i'm having a hard time to implement a solution
Let's say i have some sets A,B and C.
A is inside B
B is inside C
A is the set of the 10 objects wit... | Let me assume that you have a table `t` with a `value` column, and that the labels "A", "B", and "C" are based on these.
```
select t.*
from t left outer join
(select value
from t
where value >= 100
order by value desc
limit 1
) A
on t.value = A.value
where t.value >= 50 and A.va... | May be this query would help:
```
select Col1,Max(Col2) from
(select col1, col2 from TableC
Except
Select col1, col2 from TableA)as A
Group By Col1
```
Here the inner query would only select the records which are there in table A but not in Table C, and then outer query would take the max of those records. | How to query sets and subsets and get a set that doesn't contain the other set | [
"",
"sql",
"set",
""
] |
How can I sum sub-queries data in SQL Server 2008?
In this query I want to sum this `Score` column data in this `CASE` function, where point between rang of number, enough time I try to sum this column it show me error.
Now I want to sum this column `Score` with a `Group by Applicant id`, what's the way I can sum the... | There are several problems
1. Your `WHERE` clause makes no sense
2. To sum scores per applicant use `SUM()` and `GROUP BY` clause
3. To be able to sum values you should return numeric values in `CASE` instead of string literals
4. In your query you have `point` column in your select. But it's not part of `GROUP BY` be... | Have you tried the following:
```
SELECT ApplicantId,point,
SUM(CASE
WHEN point BETWEEN 4.00 AND 4.50 THEN 3
WHEN point BETWEEN 3.5 AND 4.00 THEN 2
END
) [Score]
FROM tblAcademicInfo
WHERE tblAcademicInfo.ApplicantId
GROUP BY ApplicantId, point
``` | How can I sum subqueries data in SQL Server 2008? | [
"",
"sql",
"sql-server-2008-r2",
""
] |
First off, I already know that Windows Firewall is blocking my connection -- I just don't know what to do about it. When I turn WF all the way off, my remote connection works. I already have a Rule to allow incoming requests at port 1433, and it seems that's the right port, but I'm unsure. Now for more details.
I had ... | Here is the list of the ports that SQL Server Features use. Depending on the features/services you use you may need additional ports TCP/UDP opened. Also under server properties > connections > confirm that Allow remote connections to this server is checked. The instructions of remote connection is for 2008, since you ... | A short answer is:
1. SQL Server default instance uses TCP port 1433, unless messed about with (don't do it!). If you only have a default instance, that's the only port you need, I believe - SQL Server clients don't use the browser service to find a default instance.
2. SQL Browser comes into play if named instances a... | Can't connect to SQL 2012 remotely by IP and named instance | [
"",
"sql",
"sql-server",
"windows",
"sql-server-2012",
"windows-firewall",
""
] |
I am using following query to select certain values
```
select
sb.company
,b.id as Id
,bds.id as PId
,brp.bId
from supp b
left outer join sales bds on (bds.sId = b.id)
left outer join tperiod brp on (brp.id = bds.rId)
left outer join tbuyer sb on (sb.id = brp.bId)
where
b.ownerId = @oId;
```
I... | Since you want to select the values based on Owner ID uniqueness, you have use group by clause and give "distinct" in select clause like
```
select distinct
sb.company
,b.id as Id
,bds.id as PId
,brp.bId
from supp b
left outer join sales bds on (bds.sId = b.id)
left outer join tperiod brp on (brp.id = bds... | You need to user GROUP BY on the ownerId, but then you will need to use some aggregate function on all the other fields in the select statment
If you want a unique ownerId and the other related fields are different, SQL needs to know what to display. Do you just want the MAX value on the related fields? You are asking... | Selecting distinct on where clause | [
"",
"sql",
"sql-server",
"sql-server-2008",
"t-sql",
""
] |
I have a table that contains words and an input field to search that table using a live search. Currently, I use the following query to search the table:
```
SELECT word FROM words WHERE word LIKE '%searchstring%' ORDER BY word ASC
```
Is there a way to order the results so that the ones where the string is found at ... | To do it the first way (starts word, in the middle of the word, ends word), try something like this:
```
SELECT word
FROM words
WHERE word LIKE '%searchstring%'
ORDER BY
CASE
WHEN word LIKE 'searchstring%' THEN 1
WHEN word LIKE '%searchstring' THEN 3
ELSE 2
END
```
To do it the second way (position of... | Try this way:
```
SELECT word
FROM words
WHERE word LIKE '%searchstring%'
ORDER BY CASE WHEN word = 'searchstring' THEN 0
WHEN word LIKE 'searchstring%' THEN 1
WHEN word LIKE '%searchstring%' THEN 2
WHEN word LIKE '%searchstring' THEN 3
ELSE 4
... | MySQL order by "best match" | [
"",
"mysql",
"sql",
"sql-order-by",
""
] |
Is it possible to calculate this sales report in one query? I'm not so hot with SQL and having trouble wrapping my head around joins considering the all-inclusive where clause.
TABLES (assume 1-N for foreign keys):
```
TABLE contacts
id
TABLE reservations
id
created_at
contact_id
TABLE reservation_trips
id
reservat... | The main problem is to avoid counting the intermediate levels multiple times. One way to do it is do divide by the number of items at each level.
Another approach, which can be more efficient is to put each level in it's own subquery and then join them all up.
Here's an untested stab at the first method. It might nee... | Give this a whirl, I think it covers it
```
SELECT trip_types.title as trip_type_title,
COUNT(DISTINCT reservations.id) as bookings,
SUM(reservations.commissions) as commissions, distinct reservations,
SUM(reservation_trips.id) as guests, distinct reservation_trips,
SUM(reservation_trips.amount * reservation_trips.q... | Trying to formulate exclusive sql query from all-inclusive where clause | [
"",
"sql",
"join",
"subquery",
""
] |
I'm looking for the best way to count how many rows there are in a large (15 million+ rows) table. The naive way of `select count(*) from table;` is apparently O(n) according to a few older posts I've found on the matter, e.g. <http://osdir.com/ml/sqlite-users/2010-07/msg00437.html>.
Is there a constant time mechanism... | SQLite has a special optimization for `COUNT(*)` without a `WHERE` clause, where it goes through the table's B-tree pages and counts entries without actually loading the records.
However, this still requires that all the table's data (except overflow pages for large records) is visited, so the runtime is still O(n).
S... | as a workaround you could query [ROWID](http://www.sqlite.org/autoinc.html). if you don't delete from the table it'll be accurate otherwise it will be high
```
select max(rowid) from table
``` | Is count(*) constant time in SQLite, and if not what are alternatives? | [
"",
"sql",
"sqlite",
"count",
""
] |
I am trying to update a table using the following query
```
update at_product A join
(
SELECT atbillfields.billeditemguid,count(*) AS numberOfPeopleBought
,sum(atbillfields.billeditemqty) AS soldquantity
FROM jtbillingtest.at_salesbill atsalesbill
JOIN jtbillingtest.at_billfields atbillfields
ON atsalesbill.b... | Have a look at:
<http://justalittlebrain.wordpress.com/2010/09/15/you-are-using-safe-update-mode-and-you-tried-to-update-a-table-without-a-where-that-uses-a-key-column/>
If you want to update without a where key you must execute
```
SET SQL_SAFE_UPDATES=0;
```
right before your query.
Another option is to rewrite ... | This error means you're operating in safe update mode and therefore you have two options:
* you need to provide a where clause that includes an index for the update to be successful or
* You can disable this feature by doing `SET SQL_SAFE_UPDATES = 0;` | Update query failing with error : 1175 | [
"",
"mysql",
"sql",
""
] |
I have this schema
```
create table t(id int, d date)
insert into t (id, d) values (1, getdate()),
(2, NULL)
```
When doing
```
declare @mindate date
select @mindate = min(d) from t
```
I get the warning
> Null value is eliminated by an aggregate or other SET operation
Why and ... | Mostly you should do nothing about it.
* It is possible to disable the warning by setting `ansi_warnings` off but this has [other effects, e.g. on how division by zero is handled](https://learn.microsoft.com/en-us/sql/t-sql/statements/set-ansi-warnings-transact-sql?view=sql-server-ver15) and can cause failures when yo... | @juergen provided two good answers:
* Suppress the warning using `SET ANSI_WARNINGS OFF`
* Assuming you want to include NULL values and treat them as (say) use `select @mindate = min(isnull(d, cast(0 as datetime))) from t`
However if you want to ignore rows where the d column is null and not concern yourself with the... | Getting warning: Null value is eliminated by an aggregate or other SET operation | [
"",
"sql",
"sql-server",
"settings",
""
] |
I'm using this SQL query to go through a table and search for a customer name and return that row's id and date column:
```
SELECT custName, date, id FROM booking
WHERE custName LIKE '%$s'
OR custName LIKE '$s%'
```
($s being a PHP variable)
If I'm looking for John Dorian, I could input $s as the first name John, or... | How about:
```
SELECT custName, date, id
FROM booking b
INNER JOIN
(
SELECT max(date) MaxDate, custName
FROM booking
WHERE custName LIKE '%$s%'
GROUP BY custName
) bm
ON b.custName = bm.custName
AND b.date = bm.maxDate
WHERE custName LIKE '%$s%'
ORDER BY b.date DESC
``` | 1) You can search and get only one row per customer easily using `DISTINCT` or `GROUP BY`:
```
SELECT DISTINCT custName
FROM booking
WHERE custName LIKE '%$s' OR custName LIKE '$s%';
```
or
```
SELECT custName
FROM booking
WHERE custName LIKE '%$s' OR custName LIKE '$s%'
GROUP BY custName;
```
2) You can get the ma... | SQL SELECT names LIKE $name but not exact same name twice | [
"",
"sql",
"sql-like",
""
] |
I have a table that contains a list of performances. These performances are grouped by production number. What I am trying to do is create a stored procedure that will return the last performance for each production entered. I would like to be able to input the production ids as a list of ids. Below is my procedure so ... | Try the sp\_executesql
```
CREATE PROCEDURE IP_MAX_PERF_DATE
@prod_no nvarchar(500)
AS
BEGIN
SET NOCOUNT ON;
declare @statement nvarchar(1000)
set @statement = N'SELECT [prod_season_no], MAX([perf_dt]) As max_dt FROM [T_PERF] WHERE [prod_season_no] IN (' + @prod_no + ') GROUP By [prod_season_no]'
EXEC sp_executesql ... | generally there are three ways to pass in a list of Ids:
Option 1: use comma separated list and split it in the stored procedure. this requires you to have a split function, or use dynamic sql (not preferred most of the time due to performance problem - at least hard to see the execution plan and you lose the point of... | declaring T-Sql parameter for comma delimited list of integers | [
"",
"sql",
"sql-server",
"t-sql",
""
] |
Here is what I have so far but the results are wrong.
```
SELECT c.CompanyName,
COUNT(o.OrderID) AS [Total Orders],
SUM(
(od.UnitPrice -
(od.UnitPrice * od.Discount))* Quantity) AS [Purchase Total]
FROM Customers AS c,
Orders AS o,
[Order Details] AS od
WHERE c.CustomerID ... | Because Access doesn't have `COUNT(DISTINCT)` then you need to create an inner query.
What this does is compute the sum of each item in an order in the inner query, and then sums up all the order totals for the customer as the purchase total. An individual OrderID will not be counted twice, as `o` and `od` now have a ... | if the problem is because OrderID appears multiple times, try:
```
SELECT c.CompanyName, COUNT(DISTINCT o.OrderID) AS [Total Orders], SUM((od.UnitPrice - (od.UnitPrice * od.Discount)) * Quantity) AS [Purchase Total]
FROM Customers AS c, Orders AS o, [Order Details] AS od
WHERE c.CustomerID = o.CustomerID AND o.OrderID... | Does this SQL statement require a nested SELECT query? | [
"",
"sql",
"ms-access",
""
] |
Relatively new to SQL querying. I can successfully get results from a simple query that shows a customer number and a total dollars invoiced sorted highest dollar amount to lowest. I want to also display the customer name. The customer name, `[Name]`, is in another table along with the customer number but the column na... | ```
SELECT [Bill-to Customer No_], [Invoice Amount] AS amt, [Name]
FROM Table1 t1 JOIN Table2 t2
ON t1.[Bill-to Customer No_] = t2.[No_]
ORDER BY amt DESC;
```
I haven't grasped your column names yet, but hope you get the idea.
***EDIT** : (as per your new query)*
```
SELECT [Sell-to Customer No_], [Name], SUM([Amou... | ```
SELECT
[bill-to Customer No_]
,customer_name
FROM table1 AS a
INNER JOIN table2 AS b on a.[bill-to Customer No_]=b.No_
``` | How to join two sql tables when the common column has different names but information is the same in both tables | [
"",
"sql",
""
] |
I'm trying to create a sub-table from another table of all the last name fields sorted A-Z which have a phone number field that isn't null. I could do this pretty easy with SQL, but I have no clue how to go about running a SQL query within Excel. I'm tempted to import the data into postgresql and just query it there, b... | There are many fine ways to get this done, which others have already suggestioned. Following along the "get Excel data via SQL track", here are some pointers.
1. Excel has the **"Data Connection Wizard"** which allows you to import or link from another data source or even within the very same Excel file.
2. As part of... | Might I suggest giving [QueryStorm](https://www.querystorm.com) a try - it's a plugin for Excel that makes it quite convenient to use SQL in Excel.
[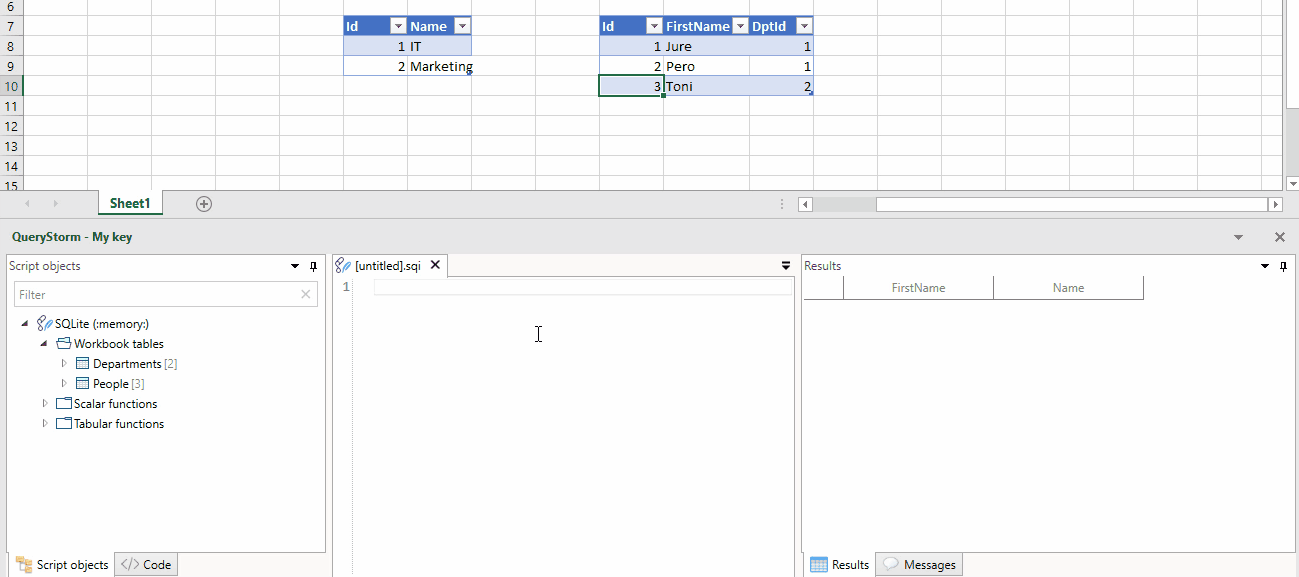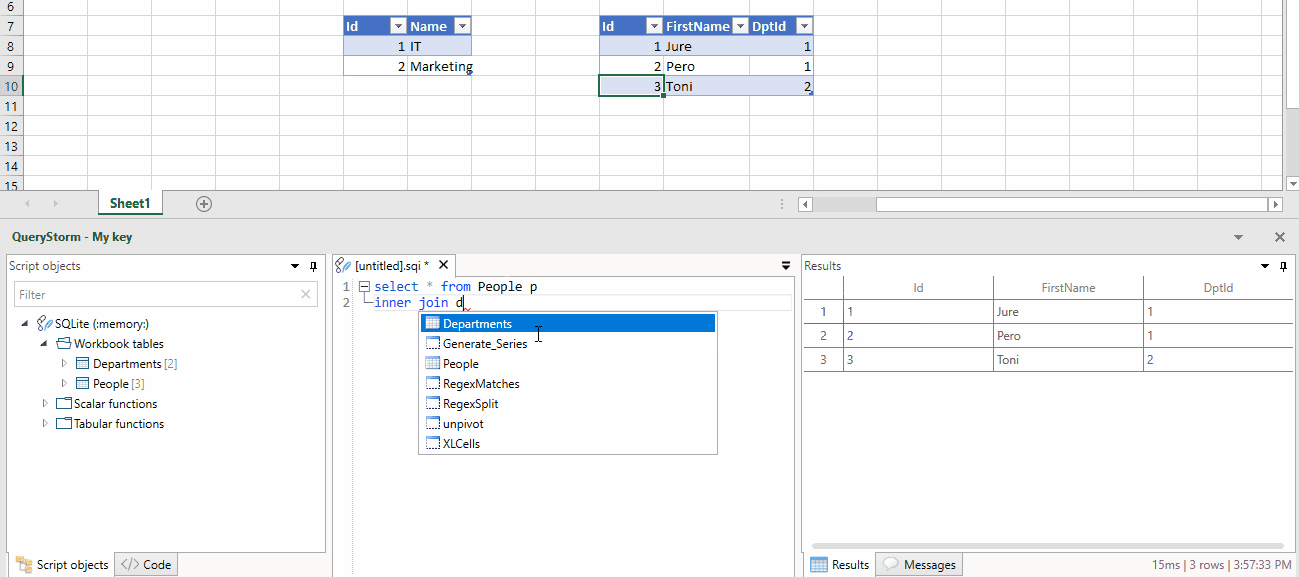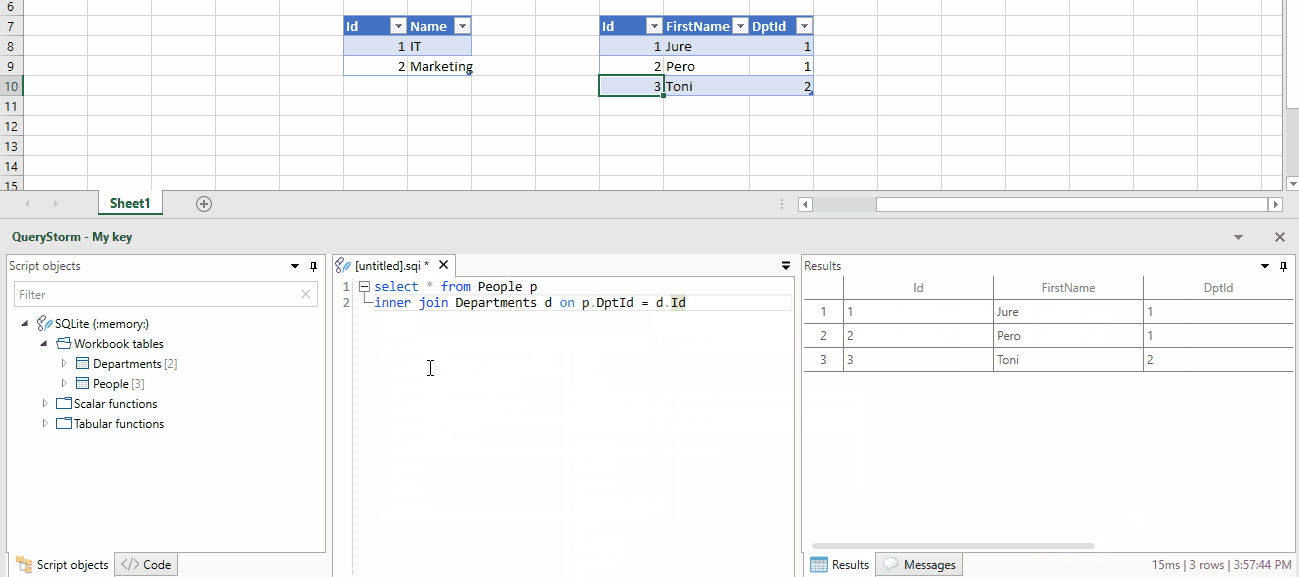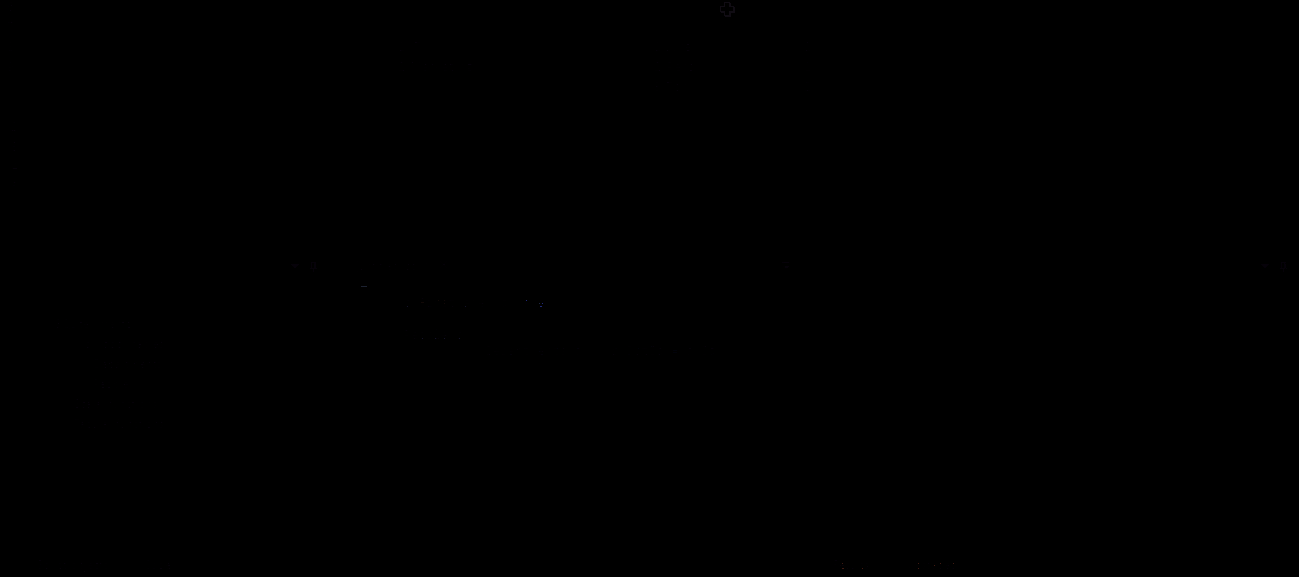](https://i.stack.imgur.com/w2rmT.gif)
In the SQL scripts Excel tables are visible as if... | How to run a SQL query on an Excel table? | [
"",
"sql",
"excel",
"filtering",
""
] |
I've an application that checks recorded waste types. Part of the system allows the user to forecast how much waste they will recycle, and in a report it will list the forecasted waste type with how much was forecast and the actual waste that's been recorded.
The way it works it out is that there is one table called `... | You need an Inner Join between forecastwaste and wastetypes plus a Left Join to wastestream:
```
SELECT ws.wastetype, SUM(ws.recordedweight) totalWeight, SUM(ws.percent) totalPercent, wt.id, wt.category, wt.defrecycling, fw.tonnes
FROM c1skips.forecastwaste fw
JOIN c1skips.wastetypes wt ON (wt.id = fw.wastetype)
LEFT... | I think you need to rewrite that one using joins, then you will be able to use LEFT JOIN. It works the way you need.
The thing I can do in some minutes looks like that:
```
SELECT ws.wastetype, SUM(ws.recordedweight) totalWeight, SUM(ws.percent) totalPercent, wt.id, wt.category, wt.defrecycling, fw.tonnes
FROM w... | Retrieve all records from one table even if a related record can't be found in a related table | [
"",
"mysql",
"sql",
"cakephp-2.0",
""
] |
I've created two datasets.
Dataset1 (from a stored procedure):
```
CREATE PROCEDURE [dbo].[usp_GetPerson](
@Category varchar(20))
AS
BEGIN
SELECT FirstName, LastName, Category
FROM tblPerson
WHERE (Category IN (@Category))
END
```
Dataset2:
```
SELECT DISTINCT Category
FROM tblPerson
`... | The issue when running from an SP using a query like this:
```
SELECT FirstName, LastName, Category
FROM tblPerson
WHERE (Category IN (@Category))
```
where `@Category` is something like `'Cat1,Cat2,Cat3'`
is that the `IN` clause is treating `@Category` as a single string, i.e. one single v... | You can only use IN with static defined within your query. In this cas use =
```
CREATE PROCEDURE [dbo].[usp_GetPerson](
@Category varchar(20))
AS
BEGIN
SELECT FirstName, LastName, Category
FROM tblPerson
WHERE (Category = @Category)
``` | Using Multiple Parameters in SSRS from Stored Procedure Returns Blank | [
"",
"sql",
"stored-procedures",
"reporting-services",
"parameters",
"sql-server-2012",
""
] |
It may seem quit basic but I've not come across this yet and can't figure it out. Say I have two tables of users and in each table is a field 'email\_address'. How can I select all email addresses from both tables as one list? I'll most likely need the DISTINCT keyword since there may be occurrences of the same email a... | ```
select email_address from table1
union
select email_address from table2
```
`UNION` will merge the identical email adresses.
If you wanna keep the duplicates, use `UNION ALL` | Just `UNION` the two tables:
```
SELECT `email_address`
FROM `a`
UNION
SELECT `email_address`
FROM `b`
``` | Selecting 'field_name' from multiple tables in SQL? | [
"",
"mysql",
"sql",
""
] |
First of all, I use:
Windows 7 x64
Oracle Enterprise 11g R2 x32
I have some basic experience with SQL Server and MySQL (more with MySQL). Today I started working with Oracle, and I've been bumping a lot on the way.
The problem I'm having now is that, for some reason, I can't connect to any sys user (sysdba or sysope... | After you log in with 'sqlplus / as sysdba', try changing the password for system by issuing
```
ALTER USER system IDENTIFIED BY abcdef;
```
Then, to make sure, without quitting sqlplus:
```
CONN system/abcdef
```
That should work. After that, you can log on with system/abcdef when you start sqlplus. | The ORA-01994 error happens when you forget to use the orapwd command, and it critical to note that the name of the file must be orapwsid, and you must supply the full path name when using the orapwd command. 'orapwsid' sid is case sensitive. | "Alter user sys identified by" not working | [
"",
"sql",
"oracle",
""
] |
I'll try to explain the type of the query that I want:
Assume I have a table like this:
```
| ID | someID | Number |
|----|--------|--------|
| 1 | 1 | 10 |
| 2 | 1 | 11 |
| 3 | 1 | 14 |
| 4 | 2 | 10 |
| 5 | 2 | 13 |
```
Now, I want to find the someID that have ... | ```
SELECT t1.someId
FROM yourTable t1
WHERE t1.number IN (10,14,11)
GROUP BY t1.someID
HAVING COUNT(DISTINCT t1.ID) = (SELECT COUNT(DISTINCT t2.ID) FROM yourTable t2 WHERE t1.someID=t2.someID)
```
[**Example Fiddle**](http://sqlfiddle.com/#!2/0269c/5) | ```
select someID
from yourtable
where number in (10,11,14)
and not exists (select * from yourtable t2 where number not in(10,11,14)
and t2.someid=yourtable.someid)
group by someID
having count(distinct ID) = 3
```
Where `3` is the number of items you are querying for | SELECT query with cross rows WHERE statement | [
"",
"sql",
"sql-server",
""
] |
I have 1 table called `accounts` and another one called `level_points`
Basically the idea is to determine what is the minimum amount of points you need to be X level.
Account Structure
`id`, `name`.. etc. `points`
Level\_Points Structure
`level`, `points`
Values in here such as
```
(1, 5)
(2, 10)
(3, 15)
```
I'... | Try something like this:
```
SELECT ac.id,
ac.name,
ac.points,
le.level
FROM account ac,
level le
WHERE ac.id = 'x'
AND le.level= (
SELECT level
FROM level_points
WHERE points <= (
SELECT points
FROM accounts
WHERE id = 'x'
... | Try This ..
```
select column1 from table1
inner join table2 on table1.column = table2.column
where table2.column=0
```
Have a look at this
<http://www.w3schools.com/sql/sql_join.asp> | SQL: Join value from another table | [
"",
"mysql",
"sql",
""
] |
I've been banging my head over this problem for the whole day. I'm posting here in hope that someone would be able to help me.
I'm trying to fix a database that has missing values, by adding them.
Let's say we have the following tables:
```
Color with columns (itemId, colorId)
Process with columns (itemId, colorId, ... | ```
SELECT
P.itemId
,C.colorId
,I.iteration
,0 AS rating
FROM
(SELECT DISTINCT itemId FROM Process) P
CROSS JOIN
(SELECT DISTINCT colorId FROM Color) C
CROSS JOIN
(SELECT DISTINCT iteration FROM Process) I
LEFT JOIN
Process E
ON P.itemId = E.itemId
AND C.colorId = E.colorId
AND I.iteration = E.iteration
WHERE E.rating... | `Updated` based on no missing iterations
```
INSERT INTO process (itemId, colorId, iteration, rating)
SELECT p1.itemId, p1.colorId, i.iteration, 0
FROM (SELECT itemId, colorId, MAX(iteration) as max_iteration
FROM process
GROUP BY itemId, colorId
) p1
INNER
JOIN (SELECT DISTINCT iteratio... | SQL insert if missing value | [
"",
"mysql",
"sql",
""
] |
Alright, this is a relativly simple question that I just need confirmation on. I am pretty sure I know the answer, but I need expert validation because I have OCD.
Anyways, I am wondering what the difference is between just a simple Inner Join Statement
and simply using the where clause to set the primary keys of the ... | Is the same!
look at these two tables:
```
CREATE TABLE table1 (
id INT,
name VARCHAR(20)
);
CREATE TABLE table2 (
id INT,
name VARCHAR(20)
);
```
The execution plan for the query using the inner join:
```
-- with inner join
EXPLAIN PLAN FOR
SELECT * FROM table1 t1
INNER JOIN table2 t2 ON t1.id = t2.id;
... | Yes, using the format you provided works fine for INNER JOINS.
But what to do when you get to LEFT/RIGHT JOINS? Then you cannot use the joining conditions in the where clause like that.
Now if I am not mistaken, the old school syntax would be somethine like
```
=* for LEFT JOIN
```
and
```
*= for RIGHT JOIN
```
Y... | SQL Primary Key/Table Joining | [
"",
"sql",
"sql-server",
"join",
"inner-join",
""
] |
I'm using PostgreSQL 9.2.
I have table containing time of some devices getting out of service.
```
+----------+----------+---------------------+
| event_id | device | time |
+----------+----------+---------------------+
| 1 | Switch4 | 2013-09-01 00:01:00 |
| 2 | Switch1 | 2013-09-01... | [SQL Fiddle](http://sqlfiddle.com/#!12/25dfc/7)
```
select
event_id, device, ts,
floor(extract(epoch from ts) / 180) as group
from t
order by ts
```
It is possible to make the group number a sequence starting at 1 using a window function but it is a not small cost that I don't know if is necessary. This is it... | [SQLFiddle](http://sqlfiddle.com/#!12/25dfc/4)
```
with u as (
select
*,
extract(epoch from ts - lag(ts) over(order by ts))/ 60 > 180 or lag(ts) over(order by ts) is null as test
from
t
)
select *, sum(test::int) over(order by ts) from u
``` | Group by floating date range | [
"",
"sql",
"postgresql",
"grouping",
"window-functions",
"group-by",
""
] |
I am passing 3 parameters into my stored procedure: `@Time, @DeptID, @Value`.
1. `@Time` is representing: 1=past 24hours, 2=past week, 3=past month, 4=past year
2. `@DeptID` is the ID of the various departments
3. `@Value` 1=Sort by Low, 2=Sort by High
Here is my current code:
```
DECLARE @SQL VARCHAR(MAX)
SET @SQL ... | I rewrote your code to not use dynamic SQL:
```
SELECT S.ID,
S.[Description],
D.Department,
S.Value,
S.[Date]
FROM Suggestions S
INNER JOIN Department D
ON D.ID = S.DeptID
WHERE Approved =1
AND (@Time = 0
OR (@Time = 1 AND [Date] >= DATEADD(DAY, -1, GETDATE()))
O... | Not sure I agree with all of your dynamic SQL but why not just check if the order by clause is already in the SQL String and if it is just add the additional parameter otherwise add the entire clause. You can do this using CharIndex.
I would also suggest only adding the DESC at the very end just before you execute the... | How can I change the ORDER BY clause depending on the parameters that are passed into the stored procedure | [
"",
"sql",
"sql-server",
"stored-procedures",
"sql-order-by",
"dynamic-sql",
""
] |
I have a MySql table with a 'Order' field but when a record gets deleted a gap appears
how can i update my 'Order' field sequentially ?
If possible in one query 1 1
```
id.........order
1...........1
5...........2
4...........4
3...........6
5...........8
```
to
```
id.........order
1...........1
5...........2
4....... | In MySQL you can do this:
```
update t join
(select t.*, (@rn := @rn + 1) as rn
from t cross join
(select @rn := 0) const
order by t.`order`
) torder
on t.id = torder.id
set `order` = torder.rn;
```
In most databases, you can also do this with a correlated subquer... | There is no need to re-number or re-order. The table just gives you all your data. If you need it presented a certain way, that is the job of a query.
You don't even need to change the order value in the query either, just do:
```
SELECT * FROM MyTable WHERE mycolumn = 'MyCondition' ORDER BY order;
``` | Reorder a MYSQL table | [
"",
"mysql",
"sql",
"database",
"select",
"sql-order-by",
""
] |
I have a table of items with a 'date\_added' column. What I want to do is select all the items added during the last two weeks. How can I do that?
```
$sql = "SELECT *
FROM iteminfo
WHERE quantity > 0
ORDER BY ID ASC";
// $query = mysql_query($sql);
``` | If you are using MS SQL Server try this code:
```
SELECT tb.date_added
FROM MyTable tb
WHERE tb.date_added > DATEADD(week, -2, GETDATE())
```
For MySQL try:
```
SELECT tb.date_added
FROM MyTable tb
WHERE DATE_ADD(tb.date_added, INTERVAL 2 WEEK) >= NOW();
``` | Basically it depends on database, but you can try something like this:
```
select * from table where date_added > getdate()-14
``` | SQL Query Comparing Date | [
"",
"sql",
"date",
"time",
""
] |
I just think that the answer is false because the foreign key doesn't have `uniqueness` property.
But some people said that it can be in case of self joining the table.
I am new to `SQL`. If its true please explain how and why?
```
Employee table
| e_id | e_name | e_sala | d_id |
|---- |------- |----- |-----... | I think the question is a bit confusing.
If you mean "can foreign key 'refer' to a primary key in the same table?", the answer is a firm yes as some replied. For example, in an employee table, a row for an employee may have a column for storing manager's employee number where the manager is also an employee and hence ... | **This may be a good explanation example**
```
CREATE TABLE employees (
id INTEGER NOT NULL PRIMARY KEY,
managerId INTEGER REFERENCES employees(id),
name VARCHAR(30) NOT NULL
);
INSERT INTO employees(id, managerId, name) VALUES(1, NULL, 'John');
INSERT INTO employees(id, managerId, name) VALUES(2, 1, 'Mike');
```
-... | Can a foreign key refer to a primary key in the same table? | [
"",
"sql",
"foreign-keys",
"primary-key",
""
] |
I'm trying to write a query that queries table Z\_INSUR. I want to find all instances where the same EMP has more than 1 row where the INSUR\_TYPE is M. I want to see all of the EMPs that do this, which is why I added the UNIQUE part to the query. Below is what I've tried so far but it doesn't work. Can someone help me... | ```
SELECT EMP
FROM Z_INSUR
WHERE INSUR_TYPE = 'M'
GROUP BY EMP
HAVING count(*) > 1;
``` | Since you didn't specify, I am going to assume you're using SQL Server.
`select emp from z_insur where insur_type = 'm' group by emp having count(emp) > 1` | SQL Query finding field with multiple rows | [
"",
"sql",
"oracle",
""
] |
I want to perform a query which would look like this in native SQL:
```
SELECT
AVG(t.column) AS average_value
FROM
table t
WHERE
YEAR(t.timestamp) = 2013 AND
MONTH(t.timestamp) = 09 AND
DAY(t.timestamp) = 16 AND
t.somethingelse LIKE 'somethingelse'
GROUP BY
t.somethingelse;
```
If I am try... | You can add [Doctrine extension](https://github.com/beberlei/DoctrineExtensions) so you can use the MySql `YEAR` and `MONTH` statement by adding this configuration if you're on Symfony:
```
doctrine:
orm:
dql:
string_functions:
MONTH: DoctrineExtensions\Query\Mysql\Month
... | In **Symfony 4** you must install [DoctrineExtensions](https://github.com/beberlei/DoctrineExtensions):
```
composer require beberlei/DoctrineExtensions
```
And then edit the doctrine config file (config/packages/doctrine.yaml) as follow:
```
doctrine:
orm:
dql:
string_functions:
... | How can I use SQL's YEAR(), MONTH() and DAY() in Doctrine2? | [
"",
"mysql",
"sql",
"doctrine-orm",
"sql-date-functions",
""
] |
Using LIKE is very common in MySQL. We use it like this: `WHERE field LIKE '%substring%'`. Where we have a substring and field has full string. But what I need is something opposite. I have substrings in field. So, I want that row which contains a substring of my string. Suppose the table is:
```
----+----------------... | You re looking for the [LIKE](http://dev.mysql.com/doc/refman/5.0/en/string-comparison-functions.html#operator_like) operator
> Pattern matching using SQL simple regular expression comparison.
> Returns 1 (TRUE) or 0 (FALSE). If either expr or pat is NULL, the
> result is NULL.
Something like
```
SELECT keyword
FR... | This work fine, using `REGEXP`:
```
SELECT keyword
FROM table
WHERE 'Tell me about admission info' REGEXP keyword;
```
But this work only if `keyword` don't contain *Regular expression*'s escapes...
I.e. This will work fine while `keyword` contain only letters, numbers, spaces and so on. | SELECT MySQL field that contains a substring | [
"",
"mysql",
"sql",
"string",
""
] |
I have a table `USERS` with two columns (`RID`, `USERNAME`)
I am just passing `RID` to get `USERNAME`.
I will pass 4 parameters as User1, User2, User3, User4 which has `RID`
Now I want results like follow:
```
Level1User Level2User Level3User Level4User
ABC DEF GHI JKL
```
I have tried following... | Rewrite it using Scalar Subqueries and you don't have to care about NULLs anymore:
```
SELECT
(SELECT USERNAME FROM [USERS] WHERE RID = @User1RID) AS Level1User,
(SELECT USERNAME FROM [USERS] WHERE RID = @User2RID) AS Level2User,
(SELECT USERNAME FROM [USERS] WHERE RID = @User3RID) AS Level3User,
(SELECT USERN... | You can do this with aggregation:
```
select max(case when u.RID = @User1RID then USERNAME end) as Level1User,
max(case when u.RID = @User2RID then USERNAME end) as Level2User,
max(case when u.RID = @User3RID then USERNAME end) as Level3User,
max(case when u.RID = @User4RID then USERNAME end) as L... | Select Statement with rows as columns | [
"",
"sql",
"sql-server",
"sql-server-2008",
"sql-server-2008-r2",
""
] |
I like to join a temporary table in MySQL which fails, the idea quite simple:
```
CREATE TEMPORARY TABLE temp_table LIKE any_other_table; -- srsly it does not matter which table
(
SELECT p1,p2,p3 FROM temp_table WHERE p4 = 1
) UNION (
SELECT p1,p2,p3 FROM temp_table WHERE p4 = 2
)
```
Any help is greatly appreci... | You cannot refer to a TEMPORARY table more than once in the same query.
Please read the following link
<http://dev.mysql.com/doc/refman/5.5/en/temporary-table-problems.html> | Does this work?
```
SELECT p1, p2, p3
FROM temp_table
WHERE p4 in (1, 2);
```
It is a much simpler way to write the same query.
EDIT:
If by "fail" you mean "doesn't return any rows", then you have a simple problem. `CREATE TABLE LIKE` does not populate the table. It creates a table with the same structure as `any_o... | Join the same table temporary table in MySQL | [
"",
"mysql",
"sql",
"join",
"temp-tables",
""
] |
I am struggling to get my head around this sql.
I have a function that returns a list of items associated with a Bill of Materials BOM.
The result of the sql select
```
SELECT
BOM,
ITEMID,
QTY
FROM boms
WHERE
bom='A'
```
is
```
BOM | ITEMID | QTY
A | ITEMB | 1
A | ITEMC ... | This should return all sales with an exact match, i.e. same itemid and same quantity:
```
SELECT s.salesid
FROM
(
SELECT salesid, itemid, SUM(qtyordered) AS ordered
FROM salesline AS s
GROUP BY salesid, itemid
) AS s
JOIN
boms AS b
ON b.itemid = s.itemid
AND b.QTY = s.ordered
WHERE b.BOM='A'
GROUP BY s... | You can do this aggregation and a `having` clause:
```
select salesid
from salesline sl
group by salesid
having sum(case when itemid = 'ITEMB' then 1 else 0 end) > 0 and
sum(case when itemid = 'ITEMA' then 1 else 0 end) > 0;
```
Each condition in the `having` clause is counting the number of rows with each ite... | sql 2000 select id where multiple row conditions are met | [
"",
"sql",
"sql-server-2000",
""
] |
I am trying to run the following sql server stored procedure, and I am unable to get it to execute. The procedure query is:
```
ALTER PROCEDURE [dbo].[get_StockNavigationReportData]
@startDate VARCHAR(200),
@endDate VARCHAR(200),
@groupBy VARCHAR(200)
AS
BEGIN
SELECT M.VRNOA, M.VRDATE 'DATE', M.REMARKS... | yes you cannot use variable in the order by clause which specify order position.
<http://exacthelp.blogspot.com/2012/03/how-to-use-variable-in-order-by-clause.html>
You should write something like this:
```
ORDER BY
CASE
WHEN @groupBy = 1 THEN VRNOA
WHEN @groupBy = 2 THEN DATE
WHEN @groupBy = 3 THEN REMARKS... | You cannot use a variable in the `order by` clause. Instead, you have to do something like:
```
order by (case when @groupBy = 'VRNOA' then VRNOA
. . .
end)
```
Be careful, though, because if the columns are of different types, either unexpected things might happen or might get another error.... | Sql Server 2008: Strange error in stored procedure | [
"",
"sql",
"sql-server",
"sql-server-2008",
"stored-procedures",
""
] |
Is there any difference between using `SPACE(2) + '|' + SPACE(2)` or just `' | '`? I know the output will be the same but I'm not sure about other aspects... Actually I can't see the point in using SPACE function if there's no difference...
Thanks! | The first difference which comes to my mind is the amount of spaces. Let's say you'd like to write 20 spaces, a word and another 20 spaces:
```
' abcd '
```
How many spaces are there? Much more useful:
```
SPACE(20)+'abcd'+SPACE(20)
```
Isn't it?
There are many cases in which ... | I agree with others who have answered this that SPACE() is useful to indicate the number of spaces used or to add large numbers of spaces.
Using SPACE may also be simpler if you want to generate a fixed-width format file - you can use the data length as a parameter e.g.
```
SELECT
name + SPACE(20-LEN(name))
FROM
... | SQL - Difference between SPACE(2) + '|' + SPACE(2) and ‘ | ‘? | [
"",
"sql",
"sql-server",
""
] |
I Have a procedure executed in SQL Server 2008 R2, the script is:
```
DECLARE @LocalVar SMALLINT = GetLocalVarFunction();
SELECT
[TT].[ID],
[TT].[Title]
FROM [TargetTable] AS [TT]
LEFT JOIN [AcceccTable] AS [AT] ON [AT].[AccessID] = [TT].[ID]
WHERE
(
(@LocalVar = 1 AND ([AT].[Access] = 0 OR [AT].[Access] Is N... | When you use use local variables in `WHERE` filter then it causes **FULL TABLE SCAN**. The value of the local variable is not known to the SQL Server at compile time. hence SQL Server creates an execution plan for the largest scale that is avaliable for that column.
As you have seen that when you pass `1==1` then SQL ... | When you use a local variable in WHERE optimizer doesn't know what to do with it.
You may check this [link](http://connectsql.blogspot.gr/2012/07/sql-server-how-local-variables-can.html)
What you could do in your case is run your query with displaying the actual plan in both cases and see how SQL is treating them. | Increase Execute Duration of Procedure When Using Variables in WhereClause | [
"",
"sql",
"sql-server",
"performance",
"variables",
"stored-procedures",
""
] |
I would like to execute a query that will only show all the string before dash in the particular field.
**For example:**
Original data: `AB-123`
After query: `AB` | You can use [`substr`](http://docs.oracle.com/cd/E11882_01/server.112/e26088/functions181.htm#i87066):
```
SQL> WITH DATA AS (SELECT 'AB-123' txt FROM dual)
2 SELECT substr(txt, 1, instr(txt, '-') - 1)
3 FROM DATA;
SUBSTR(TXT,1,INSTR(TXT,'-')-1)
------------------------------
AB
```
or [`regexp_substr`](http... | I found this simple
```
SELECT distinct
regexp_replace(d.pyid, '-.*$', '') as result
FROM schema.table d;
```
pyID column contains ABC-123, DEF-3454
SQL Result:
ABC
DEF | SQL Query to show string before a dash | [
"",
"sql",
"oracle",
""
] |
I want to select all column values irrespective of NULL as column value.
My problem is when I try to select values using IS NULL I'm getting such records also these having NULL as a value.
```
declare @status varchar(50)=NULL
declare @path varchar(50)= 'India'
select
*
from [vwMYDATA]
where
Path like '%' + @path +... | ```
select
*
from [vwMYDATA]
where
Path like '%' + @path + '%' and
((@status IS NULL )OR (Status = @status or status IS NULL))
``` | You need to change the WHERE clause to a Case statement if you want different actions based on whether the @status varchar is NULL.
```
Select *
From [vwMYDATA]
Where
Path Like Concat('%', @path, '%') And
1 = (
Case When @status Is Null Then 1
When Status = @status Then 1
Else 0
)
`... | How to take all values from SQL table column on condition? | [
"",
"sql",
"sql-server",
"sql-server-2008",
"t-sql",
""
] |
I was trying to find the no of days between 2 dates.
I tried running the below query and ended up with **ORA-30076** error.
Query is,
```
select extract(day from (sysdate - to_date('2009-10-01', 'yyyy-mm-dd')))
from dual
```
Error is,
```
Error at Command Line:1 Column:34
Error report:
SQL Error: ORA-30076: inval... | Subtracting one date from another doesn't return a date, it returns a number that represents the number of days difference so you can't use extract. | `sysdate - to_date('2009-10-01', 'yyyy-mm-dd')` will give the difference **in days** between two dates - there is no need to use `extract` function. Moreover in this situation it would be incorrect usage of `extract` function simply because it would expect expression of date or interval datatype after `from` clause and... | ORA-30076 when trying to find days between dates | [
"",
"sql",
"oracle",
""
] |
a table like this
table
```
|primary_key| project | tag |
| 1 | 2 | 3 |
| 2 | 2 | 0 |
| 3 | 2 | 4 |
| 4 | 2 | 5 |
| 5 | 3 | 0 |
| 6 | 2 | 0 |
```
I want to query project with tag ' (3 and 4) or (0 and 4) and (5 and... | You can join the table to itself and check if every row with tag 3/0 has another row with tag 4.
```
SELECT DISTINCT a.project
FROM table a, table b
WHERE a.project= b.project AND
( a.tag = 3 AND b.tag = 4 ) OR
( a.tag = 0 AND b.tag = 4 )
```
Updated according to the updated question. | You want to do this with aggregation and a `having` clause:
```
select project
from t
group by project
having sum(tag = 0 or tag = 3) > 0 and
sum(tag = 4) > 0;
```
Each `sum()` expression is counting the number of rows where the condition is true. So, the two conditions are saying "there is at least one row wi... | How to query multi 'or' and a and in SQL? | [
"",
"mysql",
"sql",
""
] |
Using SQL Server 2008
**Objective:** Select a series of columns from table1 to insert into table2
**Issue:** In table2 there is one additional column that needs to be inserted that can be derived from a join between table1 and table 3
**Current Code**
```
SELECT
table1.name,
table1.email,
table1.phone,
... | The problem is that you want a correlated subquery. That means that you need to remove `table1` from the subquery:
```
SELECT table1.name, table1.email, table1.phone,
(CASE WHEN table1.status = 'active' THEN 1 ELSE 0 END) AS Active,
(CASE WHEN table1.group_id = 3 THEN 5 ELSE table1.group_id END) AS RoleI... | If you really (really really really) want to use `subquery` instead of `join` your code is quite well. You should change your subquery's `join` as below.
```
SELECT
table1.name,
table1.email,
table1.phone,
CASE WHEN table1.status = 'active' THEN 1 ELSE 0 END AS Active,
CASE WHEN table1.group_id = 3... | How do I add a column derived from a select statement within a select statement? | [
"",
"sql",
"sql-server",
"select",
"insert",
""
] |
What are the practical differences between COALESCE() and ISNULL(,'')?
When avoiding NULL values in SQL concatenations, which one is the best to be used?
Thanks! | > Comparing COALESCE and ISNULL
>
> The ISNULL function and the COALESCE expression have a similar purpose but can behave differently.
>
> 1. Because ISNULL is a function, it is evaluated only once. As described above,
> the input values for the COALESCE expression can be evaluated multiple
> times.
> 2. Data typ... | The main difference is, that `COALESCE` is ANSI-Standard, so you will also find it in other RDBMSs, the other difference is you can give a whole list of values to be checked to `COALESCE` whereas to `ISNULL` you can only pass one. | SQL - Difference between COALESCE and ISNULL? | [
"",
"sql",
"sql-server",
""
] |
Hi I'm working with data depending mostly on the day of the week. Data is formatted in a table
Date - position - count/number.
There are multiple different positions.
I was able to sort my data for a each day of the week using.
```
select MOD(to_char(time, 'J'),7),
sum(COUNT))
from TABLE
wh... | For clarity I will use [subquery factoring](http://www.oracle-developer.net/display.php?id=212). First, select the current weeks data. Next, subquery the sum for the day over the current week. Then, subquery the sum for each day over the past year. Then, average the daily sum of each day for each day of the week. Final... | You can use analytic function for this.
```
select date1, to_char(date1, 'd'),
sum(val) over(partition by to_char(date1, 'd')),
avg(val) over(partition by to_char(date1, 'd')),
sum(val) over(partition by to_char(date1, 'd'))-
avg(val) over(partition by to_char(date1, 'd'))
from table1
ti... | Calculating difference between daily sum and a average for the same day of the week in defined time range. SQL 10g Oracle | [
"",
"sql",
"oracle",
""
] |
I have a stored procedure to load the data from one table to another table.
i need to set the column value of the destination table based on the two values of the select statement, some thing like the below example.
```
insert into table table_name
( value1, value 2,value 3)
select (value 1,value2 ,
case value3
wh... | You were very close:
```
INSERT INTO HumanResources.departmentcopy(DepartmentID, GroupName, Name, temp)
SELECT DepartmentID,
GroupName,
Name,
CASE WHEN DepartmentID = 1 AND Name = 'Engineering and Research'
THEN 'sucessful' ELSE 'unsucessful' END
FROM HumanResources.department
``` | `&&` is not valid in SQL. Use `AND` to append a condition.
```
INSERT INTO HumanResources.departmentcopy( DepartmentID,GroupName,Name,temp)
SELECT DepartmentID,
GroupName,
Name,
CASE
WHEN DepartmentID = 1 AND Name = 'Engineering and Research' THEN 'sucessful'
... | case statement in select query in sql | [
"",
"sql",
"sql-server",
""
] |
Hi I am in need of a script that Updates the rows on a table from another table based on an ID and after that it deletes the from the second table the data it copied.
This are the tables I have
```
Documents
--------
DocumentID(PK)
RealFileName
FileName
ImageDocuments
--------------
ImageDocumentId(PK)
DocumentId(FK... | Use this:
```
UPDATE [dbo].[ImageDocuments]
SET [dbo].[ImageDocuments].[OriginalFileName] = d.FileName,
[dbo].[ImageDocuments].[StorageFileName] = d.RealName
OUTPUT INSERTED.ImageDocumentId
INTO @Ids
FROM [dbo].[ImageDocuments] as fu,
[dbo].[Documents] as d
WHERE fu.DocumentID = d.DocumentID;
DELETE FROM Do... | I think this should work.
As you already copied all rows in ImageDocuments you can safely delete all the DocumentID in Documents
```
UPDATE [dbo].[ImageDocuments]
SET [dbo].[ImageDocuments].[OriginalFileName] = d.FileName,
[dbo].[ImageDocuments].[StorageFileName] = d.RealName
FROM [dbo].[ImageDocu... | How to migrate data to another table | [
"",
"sql",
"sql-server",
""
] |
```
declare @A table (
name varchar(10)
)
declare @B table (
name varchar(10)
)
insert into @A(name) values('A')
insert into @A(name) values('A')
insert into @A(name) values('A')
insert into @A(name) values('B')
insert into @A(name) values('B')
insert into @A(name) values('B')
insert into @A(name) values('B')
i... | New answer, now the requirement has been clarified:
```
;With x as (
Select
name,
row_number() over (partition by name order by name) rn
From
@A
Union
Select
name,
row_number() over (partition by name order by name)
From
@B
)
Insert Into
@C
Select
name
... | If the actual datasets that you need to work with indeed have just one column, I believe [@Laurence's suggestion](https://stackoverflow.com/a/18813654/297408) should perfectly suffice.
However, if they have other columns that need to be returned too and those columns do not have the same data like those you've shown u... | SQL Query for putting highest counters of two tables in one table | [
"",
"sql",
"sql-server",
"t-sql",
""
] |
I'm currently working with SQL Server 2008 R2, and I have only `READ` access to a few tables that house production data.
I'm finding that in many cases, it would be extremely nice if I could run something like the following, and get the total record count back that was affected :
```
USE DB
GO
BEGIN TRANSACTION
UPDA... | I don't think there is a way to bypass SQL Server permissions. And I don't think it's a good idea to develop on production database anyway. It would be much better to have development version of the database you work with.
---
If the number of affected rows is all you need then you can run select instead of update.
... | If you are only after the amount of rows that would be affected with this update, that would be same amount of rows that currently comply to the `WHERE` clause.
So you can just run a `SELECT` statement as such:
```
SELECT COUNT(pType)
FROM Person WHERE pTrackId = 20
AND pWebId LIKE 'rtlr%';
```
And you'd get the r... | SQL Server Update Permissions | [
"",
"sql",
"sql-server-2008",
""
] |
Consider a table entitled 'Calls', that among other things, contains the following columns:
```
CalledNumber | CallBegin
-----------------------------------
004401151234567|10/08/2013 09:06:53
004303111238493|15/09/2013 14:56:29
```
and so on...
How would one go about picking out the hour that, averaged over a dat... | [`DATEPART`](http://msdn.microsoft.com/en-us/library/ms174420.aspx) is what you're looking for:
```
SELECT
DATEPART(hour, CallBegin), COUNT(*) as NumberOfCalls
FROM
Test
WHERE
CallBegin BETWEEN '2013-01-01' AND '2013-12-31'
GROUP BY
DATEPART(hour, CallBegin)
ORDER BY
NumberOfCalls DESC
```
Working... | You can use `DATEPART()` and `CONVERT()`, I'm assuming CallBegin is not stored as datetime:
```
SELECT YEAR(CONVERT(DATETIME,CallBegin,103))'Year'
, DATEPART(quarter,CONVERT(DATETIME,CallBegin,103))'Quarter'
, DATEPART(hour,CONVERT(DATETIME,CallBegin,103))'Hour'
, COUNT(*)
FROM Calls
GROUP BY YEAR(C... | Get hour with highest row count | [
"",
"sql",
"sql-server",
"sql-server-2008",
""
] |
I have a table named `test` in which two fields and there data is listed as below
```
id test_no
--- -------
1 2
2 2
3 2
4 2
5 3
6 3
```
now I want to get maximum `test_no` in my case I wan to get now 3 and 3 (because there are two counts of 3)
so I use this query but it gives me 3 and 2... | Try this way:
```
select `id`,`test_no`
from `tab`
where `test_no` = (
SELECT MAX( `test_no` )
FROM `test`
)
``` | You could try this query:
```
select * from test
where test_no = (select max(test_no) from test)
``` | SQL query to get max id | [
"",
"sql",
""
] |
I have the table `ACCOUNT` of structure as follow:
```
ACCOUNT_ID | ACCOUNT_STATUS|
004460721 | 2 |
042056291 | 5 |
601272065 | 3 |
```
I need to update the three rows at once using one `SELECT` statement such that, the second column will be 5, 3, 2 respectively.
I used... | Ok based on the fiddle you have given i have tried these and it worked for me
```
create table account( account_id number primary key,
account_status varchar2(30));
insert into account values(1, '5');
insert into account values(2, '3');
insert into account values(3, '2');
select * from ac... | try the following
```
update account
set account_status = CASE account_id
WHEN 004460721 then 2
WHEN 042056291 THEN 5
WHEN 601272065 THEN 3
END
WHERE account_id IN (004460721, 042056291, 601272065 )
;
``` | Update multiple rows using CASE WHEN - ORACLE | [
"",
"sql",
"oracle",
""
] |
I was having problem in retrieving from SQL Server so I posted this [question][1]
I did not get any suitable answers. So I have changed the column datatype from `datetime` to `varchar` and now it works fine.
```
SELECT *
FROM test
WHERE (timeStamp BETWEEN '05-09-2013 18:23:57' AND '05-09-2013 18:23:59')
```
But my... | Change datatype of your column to `datetime`. You can do your query IF you'll use datetime instead of varchar in where clause:
```
select *
from test
where timeStamp between convert(datetime, '2013-09-05 18:23:57', 120) and convert(datetime, '2013-09-05 18:23:59', 120)
```
I'm pretty sure it would work even with impl... | Another reason apart from space is this:
**Datetime** has other functions like picking up the day, year, month,hours,minutes,seconds etc so that you don't have to write it for yourself. If you use **varchar** then it will be your responsibility to provide functions for future use. You should use split function to retr... | varchar vs datetime in sql | [
"",
"sql",
"sql-server",
"sql-server-2008",
""
] |
I have used row oriented database design for long time and except for datawarehouse projects and Big data samples, I have not used column oriented database design for OLTP app.
My row oriented table looks like
```
ID, Make, Model, Month, Miles, Cost
1 BMW Z3 12 12000 100
```
Some people in our team advo... | I am having trouble with your terminology. You are describing an EAV structure (standing for Entity-Attribute-Value).
Aside: A "column-oriented" database usually refers to a database that stores each column separately from others (when I learned about databases, this was called "vertical partitioning", but I don't thi... | Source: WIKI
1. Column-oriented organizations are more efficient when an aggregate needs to be computed over many rows but only for a notably smaller subset of all columns of data, because reading that smaller subset of data can be faster than reading all data.
2. Column-oriented organizations are more efficient when ... | Column oriented database vs row oriented database | [
"",
"sql",
"database",
"database-design",
"architecture",
""
] |
Example: I have some `articles` and `comments` and I want to get something like this:
```
[{
title: "Article 1",
content: "Super long article goes here",
comments: [
{ author: "Troll", message: "You suck, Sir!" },
{ author: "SpamBot", message: "http://superawesomething.com/"}
]
},{
title: "... | You can do this, using aggregates and/or subqueries. Something like:
```
select title, content, json_agg(comments.author, comments.message) as comments
from articles
join comments on articles.article_id = comments.article_id
group by article_id;
```
If you need this aggregated into one string/json/something - just w... | Here's a MySQL solution:
```
SELECT CONCAT( '[ { '
,GROUP_CONCAT( CONCAT( 'title: "', REPLACE( a.title, '"', '\"' ), '"'
,', contents: "', REPLACE( a.content, '"', '\"' ), '"'
,', comments: ', a.comments
... | Construct nested object graph from SQL hasmany relationship | [
"",
"mysql",
"sql",
"postgresql",
""
] |
I have 3 tables shown below in MS Access 2010:
Table: **devices**
```
id | device_id | Company | Version | Revision |
-----------------------------------------------
1 | dev_a | Almaras | 1.5.1 | 0.2A |
2 | dev_b | Enigma | 1.5.1 | 0.2A |
3 | dev_c | Almaras | 1.5.1 | 0.2C... | I think is what you want,
```
SELECT a.device_id, a.Company,
b.act_date, b.act_type,
c.bat, c.cycles
FROM ((((devices AS a
INNER JOIN activities AS b
ON a.device_id = b.act_id)
INNER JOIN matrix AS c
ON a.device_id = c.mat_id)
INNER JOIN
(
... | Try
```
SELECT devices.device_id, devices.Company, activities.act_data, activities.act_type, matrix.bat, matrix.cycles
FROM devices
LEFT JOIN activities
ON devices.device_id = activities.act_id
LEFT JOIN matrix
ON devices.device_id = matrix.mat_id;
``` | MS Access SQL query from 3 tables | [
"",
"sql",
"database",
"ms-access",
"vba",
"ms-access-2010",
""
] |
How can I use greater than equal to and less than equal to instead of using `between` in SQL?
I'm checking for date variable in SQL.
I tried like this:
```
Date between coalesce(@fromDate,Date) and coalesce(@toDate,Date)
```
but if user does not enter any of date (fromDate or toDate)
so that I need to convert abov... | ```
IF @fromDate IS NULL
BEGIN
SET @fromDate = '1900-01-01';
END;
IF @toDate IS NULL
BEGIN
SET @toDate = '2099-01-01';
END;
SELECT things
FROM table
WHERE date_field BETWEEN @toDate AND @fromDate;
```
This code will essentially give you an arbitrarily large range to check which *should* give you r... | Try this
```
SELECT Date FROM TableName WHERE Date > @fromDate AND Date < @toDate
``` | Greater than and less than or equal to in SQL | [
"",
"sql",
"sql-server",
"sql-server-2008",
"t-sql",
""
] |
I have a table:
```
select * from tmp_dib;
1360 DIBAKAR SE1
1360 DIBAKAR SE
1361 JAI SE1
1361 JAI SE
1365 NITISH SE1
1365 NITISH SE
```
where `SE1` are the old record and `SE` is new record.
By the below query I am getting the New record.
```
se... | Try this to fetch and delete the old records using rowid.
```
DELETE FROM tmp_dib A WHERE ROWID <
(SELECT max(ROWID) FROM tmp_dib b WHERE A.ID=b.ID);
``` | Wouldn't you reference the third column, as opposed to using the id's?
You haven't specified what the column names are but I'll assume it's called Column3
```
DELETE TMP_DIB
WHERE Column3 = 'SE1'
``` | how to fetch and delete old duplicate records from table in sql | [
"",
"sql",
"oracle",
""
] |
I need some help with an SQL query, im a bit rusty with this. The Wordpress database im using is set up like this.
```
post_id, meta_key, meta_value
33, opt_in, 1
33, email, john@hotmail.com
```
how can i collect all email address' where the opt in has the value of '1', the post\_id is what matches the two rows. I ha... | You can do it with JOIN
```
SELECT p2.meta_value email
FROM wp_postmeta p1 JOIN wp_postmeta p2
ON p1.post_id = p2.post_id
AND p1.meta_key = 'opt_in'
AND p2.meta_key = 'email'
WHERE p1.meta_value = 1
```
If you were to have
```
| POST_ID | META_KEY | META_VALUE |
|---------|----------|------------... | i think what you need is the `meta_value` field, not `post_id`
```
SELECT meta_value
FROM wp_postmeta
WHERE meta_key = 'email' AND
post_id = (SELECT post_id
FROM wp_postmeta
WHERE meta_key = 'opt_in' AND
meta_value = 1)
``` | SQL for the wordpress database | [
"",
"sql",
""
] |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.