
Prompt stringlengths 10 31k | Chosen stringlengths 3 29.4k | Rejected stringlengths 3 51.1k | Title stringlengths 9 150 | Tags listlengths 3 7 |
|---|---|---|---|---|
I´m trying to write a query of the `Top 10` occurrences of a column in my database. But I don´t want to see it in a group by mode.
I have a database with 40000 rows and with 20 columns, and I want to write a query that returns x rows with the top 10 occurrences in one specific column.
When I use this:
```
Select top... | You can use something like this:
```
;WITH Top10Distinct AS
(
SELECT DISTINCT TOP 10 YourColumn
FROM dbo.YourTable
ORDER BY YourColumn DESC
)
SELECT *
FROM dbo.YourTable tbl
INNER JOIN Top10Distinct cte ON tbl.YourColumn = cte.YourColumn
```
The CTE first fetches the `TOP 10 DISTINCT` values for `YourColu... | ```
you could use row_number()/rank()/dense_rank () depending on the requirement
```
ex :
```
with cte as
(
select name,ROW_NUMBER() over (id order by id) as rn
);
select * from cte where rn <=10
```
this outputs you 10 rows | SQL Server : TOP 10 query by occurrence without using group by | [
"",
"sql",
"sql-server",
""
] |
I want to use Group By for the rows of one column only, let me explain how.
**My Query:-**
```
SELECT
m.name AS brand,
opv.name AS model,
opv.product_condition AS condition,
(AVG(opv.final_price + opv.overhead_cost)) AS cost,
opv.product_color AS color,
COUNT(m.name) as quantity
FROM `order` o... | It is not clear from your question what you are trying to do. It is clear that you are using a confusing nonstandard MySQL extension to `GROUP BY`. You should read this part of the MySQL manual.
<http://dev.mysql.com/doc/refman/5.5/en/group-by-extensions.html>
The thing to keep in mind about SQL is that the hard part... | If you want a row for each color (as well as your other group conditions) but an avg that ignores color, have to do it in 2 steps: get the average, then list the average for each color. You can do it with 2 queries, or by making the AVG a subquery.
I don't recommended the subquery as it is very inefficient. For any si... | Group By for rows of one column only | [
"",
"mysql",
"sql",
""
] |
I have the following simplified tables:
**tblOrders**
```
orderID date
---------------------
1 2013-10-04
2 2013-10-05
3 2013-10-06
```
**tblOrderLines**
```
lineID orderID ProductCategory
--------------------------------------
1 1 10
2 1 3... | You can use exists for this
```
Select o.*
From tblOrders o
Where exists (
Select 1
From tblOrderLines ol
Where ol.ProductCategory = 10
And ol.OrderId = o.OrderId
)
``` | This should do:
```
SELECT *
FROM tblOrders O
WHERE EXISTS(SELECT 1 FROM tblOrderLines
WHERE ProductCategory = 10
AND OrderID = O.OrderID)
``` | Get orders where order lines meet certain requirements | [
"",
"sql",
"sql-server",
""
] |
I have two tables A and B
```
date Fruit_id amount
date_1 1 5
date_1 2 1
date_2 1 2
....
date Fruit_id amount
date_1 1 2
date_1 3 2
date_2 5 1
....
```
and a id\_table C
fruit\_id fruit
1 apple
....
And... | Tested this with your data and it seems to work. You want to use a full outer join in order to include all fruits and dates from A and B :)
```
SELECT C.Name
, COALESCE(A.Date, B.Date)
, COALESCE(A.Amount, 0)
, COALESCE(B.Amount, 0)
FROM C
JOIN (A FULL OUTER JOIN B ON B.FruitID = A.FruitID AND B.Da... | Try
```
select A.date, C.fruitname, A.amount, B.amount
from A,B,C
where
A.date = B.date
and A.fruitid = B.fruitid
and A.fruitid = C.fruitid
order by A.fruitid
``` | join on several conditions | [
"",
"sql",
"oracle",
"join",
""
] |
I'm using Oracle 11g, I need help trying to figure out how to match a string of any length of 0s. But it should contain only 0s.
```
i.e.
0 - Valid
00 - Valid
0000 - Valid
0010000 - Invalid
000000000- Valid
```
Been trying to find some help on this, but to no avail. | It looks like you can use [regular expressions](http://docs.oracle.com/cd/B28359_01/appdev.111/b28424/adfns_regexp.htm#i1007663) in your query, like so:
```
SELECT ID FROM table WHERE REGEXP_LIKE(zeroes, '^0+$')
``` | Assuming that the column only has numbers, then you might want to try and `CAST` it to an `INT`:
```
SELECT *
FROM YourTable
WHERE CAST(YourColumn AS INT) = 0
``` | How to match one and/or more than one 0s in SQL? | [
"",
"sql",
"oracle11g",
""
] |
Just need some advice here. Because I have a table that has 45,000 rows. What I did is I export the table as a multiple INSERT command. But the estimated time is too long. Which is faster to load in the sql? A rows that is exported as CSV or rows that exported as a multiple INSERT command? | `LOAD DATA INFILE` is the fastest.
hello, so you are dumping table by your own program. if loading speed is important. please consider belows:
* ensure that multiple `INSERT INTO .. VALUES (...), (...)`
* Disable INDEX before loading, enable after loading. This is faster.
* `LOAD DATA INFILE` is super faster than mul... | `INSERT` is faster, because you are skip parsing of csv.
If your table at `MyISAM`, you can copy files: `*.frm`, `*.myi`, `*.myd` and this migration will be faster. | Which is faster to load CSV file or multiple INSERT commands in MySQL? | [
"",
"mysql",
"sql",
""
] |
I have a column `ID` which is auto increment and another column `Request_Number`
In `Request_Number` i want to insert something like `"ISD0000"+ID` value...
e.g For the first record it should `ID 1` and Request\_Number "`ISD000001`"
How to achieve this? | You can use a computed column:
```
create table T
(
ID int identity primary key check (ID < 1000000),
Request_Number as 'ISD'+right('000000'+cast(ID as varchar(10)), 6)
)
```
Perhaps you also need a check constraint so you don't overflow. | If you have your table definition already in place you can alter the column and add Computed column marked as persisted as:
```
ALTER TABLE tablename drop column Request_Number;
ALTER TABLE tablename add Request_Number as 'ISD00000' + CAST(id AS VARCHAR(10)) PERSISTED ;
```
If computed column is not marked as persis... | Getting identity value while inserting | [
"",
"sql",
"sql-server",
""
] |
I have a Microsoft Access table that has only one column that contains URLs. I need to check and see if a URL DOES NOT EXIST in that table. What is the best way to do this? | A simple select with `COUNT` should do the trick:
```
SELECT COUNT(*)
FROM myTableWithUrl
WHERE URL='http://www.stackoverflow.com'
```
This query will always return a single row with one integer column. Zero indicates that the said URL is not present; any other number indicates that the URL is there.
The query may g... | I would go with
```
select count(*) records
from yourtable
where url = something
``` | Determine if Value Is Not In Database Column | [
"",
"sql",
"vb.net",
"ms-access",
""
] |
I have a database containing tables using foreign keys to indicate relationships among them. In one table I have 2 columns..
1 is id (foreign key) and other contains friendsids (foreign key from friends table).
Either I can put the friends on separate rows:
```
| id | friendsids |
... | Forget about splitting in PHP. What you are doing is a so-called mapping-table, and it really should be 1:1. That allows you to
* easily INSERT IGNORE to add a mapping w/o checking if it already exists,
* easily DELETE a mapping w/o checking if it already exists,
* easily COUNT(\*) the number of friends,
* easily JOIN... | The rules of database normalization dictates that you only have `1` value in `1` field. This is so you can access any single value with the correct primary key, rather than have to do some ugly code to split up the string returned.
Whenever you're designing a database, you should always keep the normalization rules in... | How to model one-to-many relationship in database | [
"",
"sql",
"database-design",
""
] |
My question is: How do I show the name of each artist which has recorded at least one title at a studio where the band: "The Bullets" have recorded?
I have formulated the following query:
```
select ar.artistname, ti.titleid from artists ar
where exists
(
select 0
from titles ti where ti.artistid = ar.artistid
and ex... | Maybe like this?
```
select ArtistName from Artists where ArtistID in (
select ArtistID from Tracks where StudioID in (
select StudioID from Tracks where ArtistID in (
select ArtistId from Artists where ArtistName='The Bullets'
)
)
)
```
I don't see why do you think `having` is needed. | The studio(s) where the bullets recorded
```
SELECT StudioID
FROM Sudios S
JOIN Tracks T ON S.StudioID = S.StudioID
JOIN Artists A ON T.ArtistID = A.ArtistID AND A.ArtistName = 'The Bullets'
```
Every Artist who recorded there
```
SELECT A1.ArtistName, A1.City
FROM Artist A1
JOIN Tracks T1 ON T1.ArtistID = A2.Artist... | SQL Subquery using HAVING COUNT | [
"",
"mysql",
"sql",
""
] |
I have a dataset I need to build for number of visits per month for particular user. I have a SQL table which contains these fields:
* **User** nvarchar(30)
* **DateVisit** datetime
What I want to achieve now is to get all the visits grouped by month for each user, something like at the picture:
. | Dynamic length on number format in to_number Oracle SQL | [
"",
"sql",
"oracle",
"nls",
""
] |
How to do UPDATE and INSERT in two different table with a field with the same name/value with one line only? | I'm not aware of a way to do so for inserts or standard SQL, but in MySQL, you can update two tables at once using a `JOIN`;
```
UPDATE table_a a
JOIN table_b b
ON a.id=b.id
SET a.value = a.value+1, b.value = b.value-1
WHERE a.id=1;
```
[An SQLfiddle to test with](http://sqlfiddle.com/#!2/43858/1). | You just can't do that.
You can maybe use a trigger on the `INSERT`'s statement table to `UPDATE` the second table or the other way around.
Other than that you have to use two different statements. | UPDATE and INSERT in two different table with a field with the same name/value | [
"",
"mysql",
"sql",
""
] |
Sometimes I need to alter the number of filters in WHERE clause and I'm looking for suggestions to do it best.
Here is a scenario:
Table1 (Col1, Col2, Col3)
Col1 contains unique id.
Col2 contains numbers 0 thru 1000, non-unique.
Col3 contains letters of alphabet A thru Z, non-unique.
I have a StoredProc1 that t... | ```
StoredProc1
@filter DataType
as
begin
DECLARE @Sql NVARCHAR(MAX);
SET @Sql = N'select Col1, Col2, Col3
from Table1 WHERE 1 = 1 '
+ CASE WHEN @filter = 1 THEN N' AND Col2 = @Param or Col2 = ''A'''
ELSE N' AND Col2 = @Filter' END
EXECUTE sp_executesql @Sql
... | ```
StoredProc1 ( @filter ) as
begin
select col1, col2, col3
from Table1
where Col2 = @filter or (@filter = '1' and Col2 = 'A')
end
```
You're going to lose performance no matter what solution you're choosing. Dynamic SQL will potentially need to be compiled every time. Your "branch" method works fine. | SQL alter number of filters in where clause | [
"",
"sql",
"sql-server",
"t-sql",
"stored-procedures",
"where-clause",
""
] |
I have following sample data:
```
ID Name Street Number Code
100 John Street1 1 1234
130 Peter Street1 2 1234
135 Bob Street2 1 5678
141 Alice Street5 3 5678
160 Sara Street1 3 3456
```
Now I need a Query to return only the last rec... | You can identify which codes are unique with a query which uses `GROUP BY` and `HAVING`.
```
SELECT [Code]
FROM YourTable
GROUP BY [Code]
HAVING Count(*) = 1;
```
To get full rows which match those unique `[Code]` values, join that query back to your table.
```
SELECT y.*
FROM
YourTable AS y
INNER JOIN
(... | Thanks to HansUp, this is my final query now:
```
SELECT
A.*
FROM
(T_NEEDED AS A
INNER JOIN
(
SELECT
CODE
FROM
T_NEEDED
GROUP BY
CODE
HAVING
Count(*) = 1
) AS B
ON
A.CODE = B.CODE)
LEFT OUTER JOIN
T_UNNEEDED AS C
ON
A.ID = C.ID
WHERE
C.ID ... | Select only records with distinct values in a certain row | [
"",
"sql",
"ms-access",
"duplicates",
"distinct",
"ms-access-2010",
""
] |
```
row | P_NO | B_NAME
1 | 123 | ABC ELEC
2 | 123 | ABC ELEC
3 | 123 | ABC ELEC
4 | 123 | ABC TRANSPORT
5 | 123 | ABC CONTRACTORS
6 | 124 | ABC STATIONARY
7 | 125 | ABC ELEC
8 | 126 | ABC ELEC
```
I'm very new in SQL.
How can I select only the P\_NO and B\_NAME where... | [updated]
what you are looking for is this:
```
select p_no
, b_name
from Uhura.dbo.test
where p_no in (select p_no
from Uhura.dbo.test
group by
p_no
having count(distinct b_name) > 1)
group by
p_no
, b_name
```
it counts ... | try this ...
```
SELECT
P_NO,
B_NAME
FROM
table_name1
WHERE P_NO IN
(SELECT
P_NO
FROM
table_name1
GROUP BY P_NO
HAVING COUNT(P_NO) > 1)
``` | SQL - Group By Distinct | [
"",
"sql",
"sql-server",
"group-by",
"sql-server-2012",
""
] |
I have a table that stores costs for consumables.
```
consumable_cost_id consumable_type_id from_date cost
1 1 01/01/2000 £10.95
2 2 01/01/2000 £5.95
3 3 01/01/2000 £1.98
24 3 ... | You were very close. This seems to work for me:
```
SELECT cc.*
FROM
consumable_cost AS cc
INNER JOIN
(
SELECT
Max(consumable_cost_id) AS max_id,
consumable_type_id,
from_date
FROM consumable_cost
GROUP BY consumable_type_id, from_date
) AS... | ```
SELECT * FROM consumable_cost
GROUP by consumable_type_id, from_date
ORDER BY cost DESC;
``` | How do I select records with max from id column if two of three other fields are identical | [
"",
"sql",
"ms-access-2007",
""
] |
Is it possible to drop all NOT NULL constraints from a table in one go?
I have a big table with a lot of NOT NULL constraints and I'm searching for a solution that is faster than dropping them separately. | You can group them all in the same alter statement:
```
alter table tbl alter col1 drop not null,
alter col2 drop not null,
…
```
---
You can also retrieve the list of relevant columns from the catalog, if you feel like writing a [do block](http://www.postgresql.org/docs/current/stati... | ALTER TABLE table\_name ALTER COLUMN column\_name [SET NOT NULL| DROP NOT NULL] | How to drop all NOT NULL constraints from a PostgreSQL table in one go | [
"",
"sql",
"postgresql",
"constraints",
"sql-drop",
"notnull",
""
] |
I'm in the process of designing a database structure for an application that I wish to develop, and I'm stuck wondering how I can design an Entity (I'm using Chen's notation) such that it can be extended by the end user through the program interface.
For example, the software I plan to write is a recipe book/nutrition... | For this particular application I would model it as below:
Ingredients are the basic things you need to make a recipe.
```
ingredients
id unsigned int(P)
name varchar(15)
...
+----+-----------+-----+
| id | name | ... |
+----+-----------+-----+
| 1 | Flour | ... |
| 2 |... | Assuming that your additional properties are in the same units, you can do it with a couple of extra tables.
```
table custom_field
-----------------
id
name
table ingredient_custom_field
----------------------------
id
ingredient_id
custom_field_id
custom_value
```
This assumes that the custom fields belong to ingr... | How can I model a database such that a given entity is extensible? | [
"",
"sql",
"database-design",
"entity-relationship",
""
] |
I am having a strange issue with a simple select query and unable to find what is happening. I am using below sql to fetch some records from a customer table. My query is as follows.
```
SELECT `C`.* FROM `customers` AS `C` WHERE `C`.`typeId`!=9 ORDER BY C.name ASC
```
My table structure is as follows
```
|id|name|t... | try out this...
```
SELECT `C`.*
FROM `customers` AS `C`
WHERE `C`.`typeId`!=9
OR `C`.`typeId` IS NULL
ORDER BY C.name ASC
``` | Try this
> SELECT `C`.\* FROM `customers` AS `C` WHERE `C`.`typeId`!=9 OR `C`.`typeId` IS NULL ORDER BY C.name ASC | MySql rows with NULL values are not retriving in select query | [
"",
"mysql",
"sql",
""
] |
I have a table "person", an associative table "person\_vaccination" and a table "vaccination".
I want to get the person who has missing vaccinations but so far I only got it to work when I have the id.
```
SELECT vac.VACCINATION_Name
FROM VACCINATION vac
WHERE vac.VACCINATION_NUMBER NOT IN
(SELECT v.VACCINATION_NUMBE... | [SQL Fiddle](http://sqlfiddle.com/#!4/c6ae5f/7)
**Oracle 11g R2 Schema Setup**:
```
CREATE TABLE VACCINATION ( VACCINATION_NUMBER, VACCINATION_NAME ) AS
SELECT 1, 'Vac 1' FROM DUAL
UNION ALL SELECT 2, 'Vac 2' FROM DUAL
UNION ALL SELECT 3, 'Vac 3' FROM DUAL
UNION ALL SELECT 4, 'Vac 4' FROM DUAL;
CREATE TABL... | Instead of an INNER JOIN, you should use LEFT JOIN.
Take a look at this link: <http://www.w3schools.com/sql/sql_join_left.asp> | SQL - Select what is not in second table from assocciative | [
"",
"sql",
"oracle",
""
] |
I was wondering if there is a way to select a column by using a SQL variable. Eg. Table is -
ID, Name, Address
```
DECLARE @Column varchar(25)
SET @Column = 'Name' -- This can be another column also
SELECT @Column
FROM MyTable
```
This shows me 'Name' as many times as there are rows in my table.
Is it even possible t... | Sql is currently interpreting your variable as a string.
[From a previous answer on stack overflow:](https://stackoverflow.com/a/12896225/2171102)
```
DECLARE @Column varchar(25)
SET @Column = 'Name' -- This can be another column also
SET @sqlText = N'SELECT ' + @Column + ' FROM MyTable'
EXEC (@sqlText)
``` | Can do this with dynamic SQL:
```
DECLARE @Column varchar(25)
,@sql VARCHAR(MAX)
SET @Column = 'Name' -- This can be another column also
SET @sql = 'SELECT '+@Column+'
FROM MyTable
'
EXEC (@sql)
```
You can test your dynamic sql queries by changing `EXEC` to `PRINT` to make sure each of... | Select a column using a variable? | [
"",
"sql",
"sql-server",
"sql-server-2005",
""
] |
here is my serial table.it has more than 1000 records.its with start number and end number.but between numbers not exist.
i need to add all number [start/between & end numbers] records in another temp table **number by number**
like below
**EXIST TABLE**
```
select concat(CARD_BULK_CODE,start_serial) startserial,conc... | Just write some PL/SQL - iterate through your table and insert rows in the temp table.
```
declare
l_start number;
l_end number;
begin
for r_rec in (select to_number(concat(card_bulk_code, start_serial)) startserial
, to_number(concat(card_bulk_code, end_serial)) endserial
... | One way to do it without resorting to plsql
```
WITH ranges AS
(
SELECT CONCAT(CARD_BULK_CODE, start_serial) startserial,
CONCAT(CARD_BULK_CODE, end_serial) endserial
FROM TSR_BULK_CARD_SERIALS
),
numbers(n) AS (
SELECT 0 n
FROM dual
UNION ALL
SELECT n + 1
FROM numbers
WHERE n <=
(
... | How to get Numbers in number range by PL-Sql .? | [
"",
"sql",
"oracle",
"plsql",
""
] |
I have a table of students.
and a table of teachers.
SOME of the students (not all) will have a teacher assigned to them.
this is controlled in a 3rd table, matching those students with their teachers, via the studentID and teacherID
what i need the SQL to do, is to `LEFT OUTER JOIN` onto the 3rd table, which is then... | You don't use an `INNER JOIN` but only another `LEFT JOIN`.
Think of tblStudents as your base. You want to get all of them, not filter anything out, and only attach optional info.
With the first left join, you attach a first info
Student -> TeacherAssignment
The TeacherAssignment can be null or not null.
Now you o... | ```
SELECT firstname, teacherlastName
FROM tblstudents
left outer join
( select * from
[tblStudentRakazot] A INNER JOIN tblteachers B
ON A.teacherid = B.teacherID)AS C
ON tblstudents.studentid = C.studentID
``` | LEFT OUTER JOIN with INNER JOIN | [
"",
"sql",
"sql-server",
""
] |
I am trying to calculate the average number of pests in a Town who are using the same Variety of crops..
```
DistrictName | TownName | CropName |Pests
Rawalpindi | pindi | CIM 506 | 3.3
Rawalpindi | pindi | CIM 506 | 3.8
Rawalpindi | Muree ... | As mentioned, the problem is that you refer to a column that's not available in that scope.
Altogether there's not even a good reason to use such a contrived query. This should work just as well, and is more readable:
```
SELECT T.DistrictName, T.TownName, T.VarietyOfCrop, avg(cast(T.Pests as float))
FROM FinalTable2... | The reason this gives you an error is because you gave the expression `cast(PestPopulation1 as float)` an alias `Pests`.
You should use that alias in your outer query, like this:
```
SELECT T.DistrictName, T.TownName, T.VarietyOfCrop, avg(T.Pests)
FROM (
SELECT DistrictName, TownName,VarietyOfCrop, cast(PestPopul... | Sql Calculate Average | [
"",
"sql",
"sql-server",
"sql-server-2008",
""
] |
I wonder if it is possible to make query like following one.
I have a table that contains `id` and `value`.
Exapmle:
```
table EXAMPLE
|id | value |
| 1 | 65|
| 2 | 13|
| 3 | 22|
```
What I want is to make query that returns the set like this:
```
|id ... | You'll have to calculate the overall average separately and force a cross join:
[SQL Fiddle](http://sqlfiddle.com/#!2/6f51e/4)
```
select
id,
value,
avgValue,
avgValue - value as Diff
from
table1
cross join
(
select
avg(value) as AvgValue
from
table1
) t2... | I think this would do it. You need to group in order to do you aggregate functions.
```
SELECT id, value, (SELECT AVG(value) FROM example GROUP BY id) AS average,
average - value AS diff
FROM example
GROUP BY id
HAVING value < average;
``` | Difference between value and avg(value) | [
"",
"mysql",
"sql",
""
] |
I have 3 textfields where user types table name and 2 column names which need to be merged.
How should I merge (combine) 2 column values into 1?
I use oracle 11g enterprise | concatenate?
```
select col1 || ' ' || col2 from tablex
``` | This is a very vague requirement. Concatenate the values maybe?
```
insert into sometable( Column1 )
values ( Column1 || Column2 );
```
If you need to specify the table name to INSERT into, then you will need to use dynamic SQL to achieve this. Would you need to specify the target column name as well? This example as... | How to merge (combine) 2 columns into 1 in oracle? | [
"",
"sql",
"oracle",
"merge",
""
] |
I have this SQL query
```
1 : show tables
2 : desc tablename
```
But this doesn't seem to be the syntax in the derby.
How to write these queries in derby ??
I want to check the schema of a table whether its primary key or not.
How to check that in websphere | Strictly speaking, this isn't SQL. Rather, these are IJ commands, and must be processed by the IJ tool.
Here's the documentation for "describe": <http://db.apache.org/derby/docs/10.10/tools/rtoolsijcomrefdescribe.html>
And here's the documentation for "show tables": <http://db.apache.org/derby/docs/10.10/tools/rtools... | Show tables via a query (**no IJ**):
```
select st.tablename from sys.systables st LEFT OUTER join sys.sysschemas ss on (st.schemaid = ss.schemaid) where ss.schemaname ='APP'
```
Show columns via a query (**no IJ**):
```
select * from sys.syscolumns where referenceid = (select tableid from sys.systables where table... | how to describe and show table in DERBY DB? | [
"",
"sql",
"database",
"derby",
""
] |
I am trying search two columns in a table, ie title and description. but I want to search title first and then description. so all rows that matches title comes first and all rows that matches description comes second
can I implement this using a single SQL query ? | You can also use a case statement so it doesn't have to go through the whole table twice.
```
SELECT col1,col2,col3,
Case
WHEN title LIKE '%searchQuery%' THEN 0
WHEN description LIKE '%searchQuery%' THEN 1
END
AS ord
FROM table1
WHERE ord is not null
ORDER BY ord;
``` | I suppose this should be efficient
```
SELECT COLA
(
SELECT TITLE AS COLA, 'T' AS IND
FROM TABLE
UNION ALL
SELECT DESCRIPTION AS COLA, 'D' AS IND
FROM TABLE
)
ORDER BY COLA, IND DESC
``` | mysql : search two columns : one column first then second column | [
"",
"mysql",
"sql",
"database",
""
] |
I have the following connection string(get from a property of sql server):
```
Data Source=(LocalDB)\v11.0;AttachDbFilename=C:\Users\myUser\Desktop\adoBanche\Banche\bin\Debug\banche.mdf;Integrated Security=True;Connect Timeout=30
```
I don't understand what mean `Timeout=30`. Someone could explain what means? | That is the timeout to **create** the connection, NOT a timeout for commands executed **over** that connection.
See for instance <http://www.connectionstrings.com/all-sql-server-connection-string-keywords/>
(note that the property is "Connect Timeout" (or "Connection Timeout"), not just "Timeout")
---
From the comme... | > **Connection Timeout=30** means that the database server has 30 seconds to establish a connection.
**Connection Timeout** specifies the time limit (in seconds), within which the connection to the specified server must be made, otherwise an exception is thrown i.e. It specifies how long you will allow your program to... | What is "Connect Timeout" in sql server connection string? | [
"",
"sql",
"sql-server",
""
] |
I came across below code today.
```
SELECT StaffGroup.*
FROM StaffGroup
LEFT OUTER JOIN StaffByGroup
ON StaffByGroup.StaffGroupId = StaffGroup.StaffGroupId
INNER JOIN StaffMember
ON StaffMember.StaffMemberId = StaffByGroup.StaffMemberId
WHERE StaffByGroup.StaffGroupId IS NULL
```
The main table `StaffGroup` is... | This query looks fundamentally flawed - I guess what was originally intended is
```
SELECT StaffGroup.*
FROM StaffGroup
LEFT OUTER JOIN
(SELECT * FROM StaffByGroup
INNER JOIN StaffMember
ON StaffMember.StaffMemberId = StaffByGroup.StaffMemberId) StaffByGroup
ON StaffByGroup.StaffGroupId = StaffGroup.StaffGr... | Actually you are missing one concept:
The main table `StaffGroup` is being `LEFT Joined` with `StaffByGroup` table and then this creates a `virtual table` say `VT1` with all records from StaffGroup and matching records from StaffByGroup based on your match/filter condition in `ON` predicate.Then not StaffByGroup table ... | When would you INNER JOIN a LEFT JOINed table / | [
"",
"sql",
"sql-server",
""
] |
What are the general storage and performance differences between the below two tables if their only difference is `nvarchar(50)` vs. `nvarchar(max)` and the strings in each field range from 1 to 50 characters? This is in SQL Server 2005.
**TABLE 1**
```
firstname nvarchar (50)
lastname nvarchar (50)
username nvarchar... | If you are guaranteed to have strings between 1 and 50 characters, then the same query run across strings of up-to-length X will run faster using varchar(X) vs. varchar(MAX). Additionally, you can't create an index on a varchar(MAX) field.
Once your rows have values above 8000 characters in length, then there are addi... | First and foremost, you won't be able to create indexes on the (max) length columns. So if you are going to store searchable data, ie., if these columns are going to be part of the WHERE predicate, you may not be able to improve the query performance. You may need to consider FullText Search and indexes on these column... | Implications of nvarchar (50) vs nvarchar (max) | [
"",
"sql",
"sql-server",
"database",
"sql-server-2005",
""
] |
*edit*
I've realised that my question really has two parts:
* How do I group by time periods, and
* [How do I select a particular row in a group?](https://stackoverflow.com/q/3800551/1084416).
[One of the answers](https://stackoverflow.com/a/7630564/1084416) to the second question uses Postgres' [SELECT DISTINCT ON]... | I can offer you this solution:
```
with t (tstamp, stat) as(
values
( current_timestamp, 'stat1'),
( current_timestamp - interval '50' second, 'stat2'),
( current_timestamp - interval '100' second, 'stat3'),
( current_timestamp - interval '150' second, 'stat4'),
( ... | Okay another try :)
I tried it with my AdventureWorks DB from Microsoft. I took some other datatypes but it should work with datetimeoffset or similar datetimes too.
So i tried it with a loop. While your timestamp is less than NOW, select for me the data between your timestamp and the timestamp plus the interval size... | Get most recent data to a periodic timestamp | [
"",
"sql",
"postgresql",
"datetime",
"select",
""
] |
I have three tables: `userProfile`, `loginTimes`, `orders`.
I am trying get each user's profile row, his last login time, and his last order row.
Here's my query:
```
Select u.*, t.loginTime, orders.* From userProfiles u
Inner Join
(Select userId, MAX(time) loginTime From loginTimes Group By userID) t
On u.userI... | OP I think this is the query you are going for, this still requires 2 subqueries, but I don't believe your original query functioned as intended.
You could remove the `loginTimes` subquery, and use `MAX(loginTime)` in the outer `SELECT` list, but then you'd need to `GROUP BY` every field in the `order` table, which is... | I believe this will do:
```
SELECT u.userID
,u.otherColumn
,MAX(t.time) AS loginTime
,MAX(o.enterDate) AS orderDate
FROM userProfiles u
JOIN loginTimes t ON t.userID = u.userID
JOIN orders o ON o.userID = u.userID
GROUP BY u.userID, u.otherColumn
```
For every other column in userProfiles you add to... | Transform sub-queries to joins | [
"",
"mysql",
"sql",
"sql-server",
""
] |
I want to import over 1GB size `sql` file to `MySQL` database in localhost `WAMP/phpmyadmin`. But `phpmyadmin` UI doesn't allow to import such big file.
What are the possible ways to do that such as any `SQL` query to import .sql file ?
Thanks | I suspect you will be able to import 1 GB file through phpmyadmin But you can try by increasing the following value in php.ini and restart the wamp.
```
post_max_size=1280M
upload_max_filesize=1280M
max_execution_time = 300 //increase time as per your server requirement.
```
You can also try below command from comman... | **Step 1:**
Find the `config.inc.php` file located in the phpmyadmin directory. In my case it is located here:
```
C:\wamp\apps\phpmyadmin3.4.5\config.inc.php
```
Note: phymyadmin3.4.5 folder name is different in different version of wamp
**Step 2:**
Find the line with `$cfg['UploadDir']` on it and update it to:
``... | How to Import 1GB .sql file to WAMP/phpmyadmin | [
"",
"mysql",
"sql",
"phpmyadmin",
"wamp",
""
] |
Not sure about the correct words to ask this question, so I will break it down.
I have a table as follows:
```
date_time | a | b | c
```
Last 4 rows:
```
15/10/2013 11:45:00 | null | 'timtim' | 'fred'
15/10/2013 13:00:00 | 'tune' | 'reco' | null
16/10/2013 12:00:00 | 'abc' | null | null
16/10/2013 13:00:00... | This should work but keep in mind **it is an uggly solution**
```
select * from
(select dt from
(select rank() over (order by ctid desc) idx, dt
from sometable ) cx
where idx = 1) dtz,
(
select a from
(select rank() over (order by ctid desc) idx, a
from sometable where a is not null ) ax
where idx = 1) az,
(
sele... | ### Order of rows
The "last row" and the sort order would need to be defined unambiguously. There is no natural order in a set (or a table). I am assuming `ORDER BY ts`, where ts is the timestamp column.
Like [@Jorge pointed out in his comment](https://stackoverflow.com/users/460557/jorge-campos): If `ts` is not `UN... | Retrieve last known value for each column of a row | [
"",
"sql",
"postgresql",
"null",
"postgresql-9.2",
"window-functions",
""
] |
In SQL, is there any way to run multiple SELECT statements simultaneously, then join the results? Most examples that I've seen on the internet seem to involve the SELECT statements being run in sequential fashion, followed by JOINs and other statements.
An example of the code would look something like this:
```
SELEC... | No, Oracle does not perform them at the same time. The closest that it comes to that is parallel query, in which stages of a single query can be apportioned across multiple parallel query sessions automatically and the results combined by a query coordinator session.
You might try combining the logic of multiple queri... | It can be all done in a single query without joins or subqueries:
```
SELECT ks,
COUNT(*) AS '# Tasks',
SUM(CASE WHEN Age > Palt THEN 1 ELSE 0 END) AS '# Late'
FROM Table
GROUP BY ks
```
As a possible performance improvement it worth trying to create a composite `(ks, Age, Palt)` index | How to Run Two Slow SQL SELECT Statements Simultaneously | [
"",
"sql",
"oracle",
"plsql",
""
] |
Suppose I have a table like this
```
| id_grupo | nombre |
|:---------|----------------:|
| 1 | Emprendedores 1 |
| 2 | Emprendedores 2 |
| 3 | Emprendedoras 1 |
| 4 | Emprendedoras 2 |
| 5 | Los amigos 1 |
| 6 | Los amigos 2 |
| 7... | How about the following:
```
SELECT CASE
WHEN RIGHT(nombre, 1) BETWEEN '0' AND '9' THEN
LEFT(nombre, Length(nombre) - 2)
ELSE nombre
END AS nombrechecked,
Group_concat(id_grupo)
FROM grupos
GROUP BY 1
```
Here is the [**SQL Fiddle**](http://sqlfiddle.com/#!9/89fb9/2/... | If items to cut are numbers only and they are always separated by a space:
```
SELECT CASE nombre REGEXP '[0-9]$'
WHEN 1 THEN REVERSE (SUBSTR(REVERSE(nombre),
INSTR(REVERSE(nombre),' '))) ELSE nombre END grupo,
GROUP_CONCAT(id_grupo)
FROM grupos
GROUP BY grupo;... | Group by similar string | [
"",
"mysql",
"sql",
"group-by",
"case",
""
] |
I have the following SQL:
```
select <misc things>
from pluspbillline
left outer join workorder
on workorder.siteid=pluspbillline.siteid
and workorder.wonum = pluspbillline.refwo
and workorder.orgid = pluspbillline.orgid
left outer join ticket
on ticket.ticketid = pluspbillline.ticketid
and tick... | I'm not sure what's causing Oracle SQL Developer to give the error. But I'm putting this comment here to format it properly.
A join graph might look something like this
```
pluspbillline ------+----< workorder
|
+----< ticket
|
+--... | I got this as well. I'm not exactly sure how to articulate it but the error seems to be based on the logical flow of the code.
Essentially because you mention the table `pluspbillline` before `workorder` I think it expects the join to be `on pluspbillline.siteid=workorder.siteid` etc.
It seems that the order of the c... | SQL Developer "disconnected from the rest of the join graph" | [
"",
"sql",
"db2",
"oracle-sqldeveloper",
""
] |
I have a table name `Companies` with `372370` records.
And there is only one row which has `CustomerNo = 'YP20324'`.
I an running following query and its taking so much time I waited 5 minutes and it was still running. I couldn't figure out where is the problem.
```
UPDATE Companies SET UserDefined3 = 'Unzustellbar ... | You don't have triggers on update on that table?
Do you have a cascade foreign key based on that column?
Are you sure of the performance of your server? try to take a look of the memory, cpu first when you execute the query (for example on a 386 with 640mb i could understand it's slow :p)
And for the locks, you can r... | Try adding an index on the field you are using in your `WHERE` clause:
```
CREATE INDEX ix_CompaniesCustomerNo ON Companies(CustomerNo);
```
Also check if there are other active queries which might block the update. | Sql Server 2008 Update query is taking so much time | [
"",
"sql",
"sql-server",
"sql-server-2008",
""
] |
I am trying to update every row in order\_item. Status is a newly created column, and must have the latest value from the order\_update table. One item can have several updates.
I am using PostgreSQL 9.1
I have this update sql.
The table `order_item` has 800K records.
The table `order_update` has 5Mil records.
`... | My educated guess: this will be *substantially* faster.
```
UPDATE order_item i
SET status = u.production_stage
FROM (
SELECT DISTINCT ON (1)
order_item_id, production_stage
FROM order_update
ORDER BY 1, id DESC
) u
WHERE i.id = u.order_item_id
AND i.status IS DISTINCT FROM u.productio... | It will help if you have an index in order\_update on the Id that includes order\_item\_id and production\_stage.
Other than that, this is fairly straightforward. Using a temporary table instead of a subquery might be an option, but I don't see much else that can be improved. | Update query on big table slow | [
"",
"sql",
"postgresql",
"sql-update",
"greatest-n-per-group",
"postgresql-performance",
""
] |
How to drop columns from a SQL Server temp table if exists from a list?
Something like:
```
DECLARE @cols AS NVARCHAR(MAX)
@cols will have value like [first_name], [last_name], .....
So @cols = '[first_name], [last_name], .....'
```
Now
```
ALTER TABLE #my_tables
DROP COLUMN @cols
```
How to ... | I agree with CRAFTY DBA: you should be passing these values in as a table-valued parameter, not as a comma-separated list. But that doesn't really change the problem: you still to generate all of the `DROP COLUMN` commands dynamically, whether the column names are parsed from a CSV using a table-valued function, or pul... | You can just use dynamic SQL; however, watch out for SQL Injection.
I would pass @cols as a parameter to a stored procedure.
The body of the procedure would be below.
```
-- Declare local variables
DECLARE @STMT NVARCHAR(MAX);
-- Create the stmt
SET @STMT = 'ALTER TABLE #my_tables DROP COLUMN ' + @cols;
-- Execute... | Drop columns from a #temp table based on CSV input parameter | [
"",
"sql",
"sql-server",
""
] |
Maybe I am missing something. I am trying to do a pretty simple select statement. The logic I want is that if two columns (ActivityDate and CreateDate) equal eachother AND ONE OR THE OTHER ours column and the DoubleBookedHours column are zero it should be returned:
```
SELECT *
FROM DailyTaskHours
WHERE ActivityDate =... | You were performing just the opposite. By using `!` you are saying anything but 0. Also, there is no need to use the parenthesis in your where clause.
```
SELECT *
FROM DailyTaskHours
WHERE ActivityDate = CreateDate
AND Hours = 0
AND DoubleBookedHours = 0
```
IF you want those returned that don't have both `Hours... | It should be:
```
--test data
DECLARE @DailyTaskHours AS TABLE (ActivityDate datetime, CreateDate datetime, [Hours] int, DoubleBookedHours int)
INSERT INTO @DailyTaskHours VALUES ('01 Jan 2012','01 Jan 2012',0,1)
INSERT INTO @DailyTaskHours VALUES ('01 Jan 2012','01 Jan 2012',0,0)
--query
SELECT *
FROM @DailyTaskHour... | WHERE clause not grouping as expected | [
"",
"sql",
"sql-server",
""
] |
I need to sum-up the amount in 2 tables (c1, c2) linked n:1 to table a. The problem is: It would be greate if I could do it in just 1 query, because the real situation is a bit more complicated ;-) I brought it down to this testcase:
```
create table a (
`id` int(10) unsigned NOT NULL, KEY(id)
) ENGINE=InnoDB;
create... | One possible answer is:
```
SELECT (select SUM(c1.amount) from c1 where c1.a = a.id) as c1_amount,
(select SUM(c2.amount) from c2 where c2.a = a.id) as c2_amount
FROM a
WHERE a.id = 1;
```
[Link to SQL Fiddle](http://www.sqlfiddle.com/#!2/51431/1)
BTW - Thanks for putting in the data and create scripts. Tha... | ```
SELECT a.*
, SUM(CASE WHEN b.source = 'c1' THEN amount END) c1_ttl
, SUM(CASE WHEN b.source = 'c2' THEN amount END) c2_ttl
FROM a
JOIN
(
SELECT *,'c1' source FROM c1 UNION SELECT *,'c2' FROM c2
) b
ON b.a = a.id;
+----+--------+--------+
| id | c1_ttl | c2_ttl |
+----+-------... | MySql: JOIN and SUM from different tables | [
"",
"mysql",
"sql",
"distinct",
""
] |
Ho to export MySQL table structure as text version table?
I mean something like this:
```
+-----------+-----------+------+-----+-------------------+-----------------------------+
| Field | Type | Null | Key | Default | Extra |
+-----------+-----------+------+-----+------------... | you could accomplish that with 3 ways.
* DESC : ease of use
* SHOW CREATE TABLE : ease of create new table with another table's same schema
* information\_schema : difficult to use, but powerful.
**1. using DESCRIBE**
```
DESC $DB_NAME.$TBL_NAME;
sample output
mysql> DESC jsheo_test.test;
+--------+-------------+--... | you can SELECT some fields and store them in a OUTFILE with this command:
> SELECT \* FROM table\_name INTO OUTFILE 'textile.txt' | How to generate SQL table structure as a text table? | [
"",
"mysql",
"sql",
"database",
"structure",
""
] |
I am trying to find which customer has the most transactions. Transaction table has an foreign key that identifies each transaction with a customer. What I currently is the following code:
```
WITH Customers as (
SELECT
[CustName] as 'Customer',
[TRANSACTION].[CustID] as 'Total # of Transactions'
F... | Your inner table just returns `CustID` as a total number of transactions? You need to start by finding the total count for each customer. Also for a column you can use `[Name]`, when you use apostrophes it thinks you are comparing a string. If you want to return all customers with the highest count, you could use this:... | First select customers and transaction count.
Then select the largest one.
Them limit your select to that item.
Work you way from the inside out.
```
SELECT *
FROM Customers
WHERE CustID =
(
SELECT TOP 1 CustID
FROM (SELECT CustID, COUNT(*) AS TCOUNT
FROM TRANSACTIONS
GROUP BY CustID) T
ORDER... | Using COUNT with MAX in SQL | [
"",
"sql",
"sql-server-2012",
""
] |
I want to get the most recent older value from one hour ago in my data but when I execute this query
```
SELECT locid, value
FROM table2
WHERE date_sub(t_stamp, interval 1 hour)
and locid = '2815'
order by t_stamp desc
```
I get all the values. How can I fix this?
The output should be
```
locid | value
2815 | ... | The Following query will get the current hour and subtract one from it and then compare it to the hour of `t_stamp`.
```
SELECT locid, value
FROM table2
WHERE DATE(t_stamp) = DATE(CURRENT_DATE)
AND HOUR(t_stamp) = HOUR(CURRENT_TIME) -1
AND locid = '2815'
ORDER BY t_stamp desc
LIMIT 1
```
Or the following query might... | Simply add a LIMIT to your query to return only the first row.
```
SELECT locid, value
FROM table2
WHERE date_sub(t_stamp, interval 1 hour)
and locid = '2815'
order by t_stamp desc limit 1
``` | Get most recent older value from one hour ago in mysql | [
"",
"mysql",
"sql",
"time",
""
] |
The query I really need to execute is follows:
```
SELECT u.points
(SELECT COUNT(1) FROM (SELECT 1 FROM checkin c INNER JOIN wineries w ON w.id = c.winery_id WHERE c.user_id = u.id GROUP BY region_id) b) as states_visited
FROM users u
GROUP BY u.id
ORDER BY points DESC
```
However, this causes the... | Why do you need the double nesting? And if the `id` is the primary key of table `user`, you don't need the `GROUP BY` either:
```
SELECT u.points,
(SELECT COUNT(1) FROM reviews WHERE user_id = u.id) AS review_count
FROM users AS u
-- GROUP BY u.id
ORDER BY points DESC ;
```
You could also `GROUP B... | It seems like you can do what you want with a simpe table join
```
SELECT u.id AS `id`, u.points AS `points`, COUNT(r.review_id) AS `review_count` /* or whatever the id record for reviews table is */
FROM users AS u
INNER JOIN reviews AS r
ON u.id = r.user_id
GROUP BY `id`
ORDER BY `points` DESC
``` | MySQL - Referencing outer table value from double nested subquery | [
"",
"mysql",
"sql",
"subquery",
""
] |
i have 4 tables
```
1. the first table(d_cities) for cities // related with the next table by country_id
CityId |CountryID |RegionID |City |Latitude|Longitude
2. the second table(d_country) for countries
CountryId|Country
3. the third table(ip2location_db11) for ip
ip_from|ip_to |country_code|country... | ```
INSERT INTO ip_relations (CityId,CountryID,ip_from,ip_to)
SELECT
d_cities.CityId,
d_cities.CountryID,
ip2location_db11.ip_from,
ip2location_db11.ip_to
FROM d_cities
INNER JOIN d_country ON d_cities.CountryID = d_country.CountryId
INNER JOIN ip2location_db11 ON ip2location_db11.country_name = d_country.Coun... | first, i am not sure why do you design table like this.maybe you could change them like below:
```
d_cities: city_id | country_id | region_id |city | latitude| longitude
d_country: country_id | country
ip2location_db11: ip_from | ip_to | country_code | city_id
```
pS: I am not very sure what does country\_code m... | how to Populating table with data returned from 3 joins tables | [
"",
"mysql",
"sql",
""
] |
I'm designing a database and can't figure out how to model referential integrity.
I have the following tables
```
CREATE TABLE Groups
(
GroupId INT PRIMARY KEY,
GroupName VARCHAR(50)
)
CREATE TABLE GroupMembers
(
GroupId INT NOT NULL,
MemberId INT NOT NULL,
MemberName VARCHAR(50),
CONSTRAINT pk_GroupMember PRIMARY K... | You could put GroupId into MissionRollAssignments and then add two constraints as follows:
```
ALTER TABLE MissionRollAssignments
ADD CONSTRAINT fk1 FOREIGN KEY (GroupId, Memberid)
REFERENCES GroupMembers (GroupId, Memberid);
ALTER TABLE MissionRollAssignments
ADD CONSTRAINT fk2 FOREIGN KEY (GroupId, MissionId)
R... | You should use Foreign Keys to reinforce this, eg Mission.GroupId should refer to Group.GroupId. | Referential integrity over table portion | [
"",
"sql",
"sql-server",
"database",
"database-design",
""
] |
```
INSERT INTO kid_progress_Backup (userid)
SELECT id
FROM users1
WHERE id>770
```
I am a newbie but I copied and pasted then tried on my sqlite tables.
id is the autoincrement so maybe there is a problem there. I also tried changing id and using another column but that doesnt work either.
An error didnt even pop up-... | Your problem may be occurred, because there are **some other fields** in **kid\_progress\_Backup**, **which can't be NULL and does not have default values**.
If you use SQLite, then you should use INSERT OR REPLACE statement for your case. So, you will not need an UPDATE. But you should define PRIMARY KEY or UNIQUE IN... | Try this SQL Query
```
SET IDENTITY_INSERT kid_progress_Backup ON
INSERT INTO kid_progress_Backup (userid)
SELECT id
FROM users1
WHERE id>770
SET IDENTITY_INSERT kid_progress_Backup OFF
``` | INSERT INTO SELECT FROM doesnt work. Not even an error | [
"",
"sql",
"sqlite",
"insert",
""
] |
What does Go want for the second param in this SQL query.
I am trying to use the `IN` lookup in postgres.
```
stmt, err := db.Prepare("SELECT * FROM awesome_table WHERE id= $1 AND other_field IN $2")
rows, err := stmt.Query(10, ???)
```
What I really want:
```
SELECT * FROM awesome_table WHERE id=10 AND other_field ... | Query just takes varargs to replace the params in your sql
so, in your example, you would just do
```
rows, err := stmt.Query(10)
```
say, this and that of your second example were dynamic, then you'd do
```
stmt, err := db.Prepare("SELECT * FROM awesome_table WHERE id=$1 AND other_field IN ($2, $3)")
rows, err := s... | It looks like you may be using the [pq driver](https://github.com/lib/pq). `pq` recently added Postgres-specific Array support via [pq.Array](https://godoc.org/github.com/lib/pq#Array) (see [pull request 466](https://github.com/lib/pq/pull/466)). You can get what you want via:
```
stmt, err := db.Prepare("SELECT * FRO... | How to execute an IN lookup in SQL using Golang? | [
"",
"sql",
"go",
""
] |
Invoices Table
```
invoice_id invoice_date
------------ --------------
1 2013-11-27
2 2013-10-09
3 2013-09-12
```
Orders Table
```
order_id invoice_id product quantity total
--------- ---------- --------- --------- -------
1 1 Produ... | I think you want to use PIVOT here ...
Try this:
```
WITH tmp
AS
(
SELECT orders.products,
DATEPART(Year, invoices.invoice_date) Year,
DATEPART(Month, invoices.invoice_date) Month,
SUM(orders.total) [Total]
FROM invoices INNER JOIN orders ON invoices.invoice_id = orders.invoice_id
GROUP BY
... | One way to do it is with Cases:
```
Select
O.product,
Sum(Case
When DATEPART(M, I.invoice_Date) = 9 Then O.total
Else 0
End) as Month9,
Sum(Case
When DATEPART(M, I.invoice_Date) = 10 Then O.total
Else 0
End) as Month10,
Sum(Case
When DATEPART(M, I.invoic... | JOIN, GROUP BY AND SUM in single Query | [
"",
"sql",
"sql-server",
""
] |
```
SELECT first_name, last_name
FROM employees
WHERE REGEXP_LIKE (first_name, '^Ste(v|ph)en$');
```
The following query returns the first and last names for those employees with a first name of Steven or Stephen (where first\_name begins with Ste and ends with en and in between is either v or ph)
is there a call tha... | How about `MINUS`
```
SELECT *
FROM employees
WHERE REGEXP_LIKE( first_name , '^Ste([[:alpha:]])+en$')
MINUS
SELECT *
FROM employees
WHERE REGEXP_LIKE( first_name , '^Ste(v|ph)en$');
```
and this too:
```
WITH t AS
( SELECT 'Stezen' first_name FROM dual
UNION ALL
SELECT 'Steven' FROM dual
UNION A... | Two options:
1. The first query uses two `REGEXP_LIKE` tests: one regular expression to generically match; and one for excluding the invalid matches.
2. The second query uses `REGEXP_SUBSTR` to testfor a generic match and extract the sub-group of the match and then tests to see whether it should be exluded.
The third... | Oracle SQL REGEX_LIKE | [
"",
"sql",
"oracle",
""
] |
So let's say I have the following tables Person and Wage. It's a 1-N relation, where a person can have more then one wage.
```
**Person**
id
name
**Wage**
id
person_id
amount
effective_date
```
Now, I want to query a list of all persons and their latest wages. I can get the results by doing the following query:
```... | Proper indexing would probably make your version work efficiently (that is, an index on `wages(person_id, effective_date)`).
The following produces the same results with a single subquery:
```
SELECT p.*, w.amount, w.effective_date
from person p left outer join
(select person_id, max(effective_date) as maxdate
... | Subqueries can be a good solution like Sam S mentioned in his answer but it really depends on the subquery, the dbms you are using, and your indexes. See this question and answers for a good discussion on the performance of subqueries vs. joins: [Join vs. sub-query](https://stackoverflow.com/questions/2577174/join-vs-s... | MySQL alternative to using a subquery | [
"",
"mysql",
"sql",
""
] |
I am trying to use a stored procedure that has many possible where clauses. What I have for the stored procedure now returns "Incorrect syntax near the keyword 'from'" as an error.
```
Select @SQL = 'SELECT Table1.Col1, Table2.Col2
FROM Table1
INNER JOIN Table2 on Table1.Col1 = Table2.Col1
WHERE ' + @where
Exec(@SQL... | Could your issue be that you need to double quote all of your literals?
```
'Table1.Col1 = ''Apples'' OR Table1.Col1 = ''BANNANAS'' OR Table2.Col2 = ''CHOCOLATE'''
``` | Here is an alternative solution.
It's not "dynamic sql", but it is flexible and "cleaner" IMHO.
```
Use Northwind
GO
declare @holder table (ProductName nvarchar(40))
Insert into @holder (ProductName )
select
'Chai' union all select 'Chang' union all select 'Aniseed Syrup'
SELECT
[ProductID]
,[Produ... | Variable as Where clause in stored procedure | [
"",
"sql",
"sql-server",
"stored-procedures",
""
] |
I have Ran below query
```
DECLARE @temp TABLE(Id int identity(1,1), name varchar(20))
INSERT INTO @temp (name)
select name from sys.tables
```
The above query is working fine with out any issues in one machine. But i ran the another machine it throu... | This means one machine has table names that are all less than 20 characters, but the machine it doesn't work on has table names that are longer than 20 characters.
Change the size of your `name` column to `nvarchar(255)`; you can go all the way up to 4000 if you still have trouble.
```
DECLARE @temp TABLE(Id int iden... | As Raj states the datatype for a column name in SQL Server is SYSNAME, therefore just use this as it is both backward and forward compatible:
```
DECLARE @temp TABLE(Id int identity(1,1), name sysname)
INSERT INTO @temp (name)
select name from sys.tables
```
See [What is SYSNAME data type in SQL Server?](https://stac... | Need resolution for this below code issue | [
"",
"sql",
"sql-server",
"sql-server-2008",
""
] |
I am creating a table with `name` as a column such that there are multiple rows with same name and corresponding to every name there are other values (columns).
I have to design the table such that there are two set of values **default** and **latest**. So user may enquire to get either default/latest set and may edit... | > Is there a better approach to do this apart from keeping a flag ??
Typically a default setting will be show by a flag column but not information about the latest.
To store latest information a table will include 2 additional timestamp columns: **Created** and **Modified** (and you might have two additional columns ... | > Is there a better approach to do this apart from keeping a flag ?? Am i doing it wrong??
If you can't distinguish "default" data from "latest" data any other way, you have to either add a column or add a table.
But I don't understand why you'd choose to use an integer the way you're using one. You're representing t... | Database Table design issue? | [
"",
"mysql",
"sql",
"database",
""
] |
The following is an example of the text I want to create a function to query against:
```
"!PRINTSERVER.PAR
$MODE=QUIET
$DEBUG=N
$LOG_FILE=[file path]
$PRINTER_LIST=
-ACCOUNTS_LASER,\\print02\Accounts_Laser,winspool,Ne34:
-BE_PRINTER01,\\print01\BE_Printer01,winspool,Ne03:
-CUSTSERV_PRINTER,\\print01\CS_Laser,winspool... | Thanks to everyone who posted suggestions. I have used some of the sql in the answers below to create a function that solves my issue.
```
create or replace function get_printer_path (l_printer_name in varchar2)
return varchar2
is
p_printer_path varchar2(5000);
cursor temp is
select
regexp_replace(dbms_xmlg... | ### Regex
```
'^(.*?' || 'ACCOUNTS_LASER' || ',)([^,]+)(.*)$'
```
### Flags
```
n
```
### Description
```
^(.*?<Printer name goes here>',)([^,]+)(.*)$
```
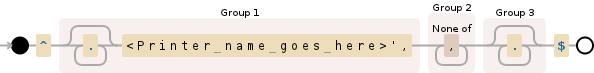
### Recipe
```
-- INIT
create table test (input clob);
insert into test... | Oracle SQL: Return text in string based on search of string | [
"",
"sql",
"regex",
"oracle",
"plsql",
"substring",
""
] |
First, I would like to mention that I already checked all other asked questions, and none of it is similar to mine, so I don't think it's a duplicate.
I have two table tables, "Article\_tbl" with more than 300,000 rows so far and "ArticleZone\_tbl" with almost the same rows count.
"Article\_tbl" Contains a Identity p... | You could try creating an [Indexed View](http://msdn.microsoft.com/en-us/library/ms191432.aspx) on the two tables:
```
CREATE VIEW dbo.YourIndexedView
WITH SCHEMABINDING
AS
SELECT az.ArticleID,
az.ChannnelID,
az.ZoneID,
a.LastEditDate,
a.LastEditDateTime,
... | As you say "Same query with "Over(Order by Article\_tbl.ArticleID asc)" is taking 40ms", no doubt that you have an index missing. You should study the query plan (include actual execution plan button in SSMS)
One index with all fields covering your OVER(ORDER BY..) may give you good results.
ArticleId is implictly here... | ROW_NUMBER() Performance optimization | [
"",
"sql",
"sql-server",
""
] |
I have a procedure which returns the error:
> Must declare the table variable "@PropIDs".
But it is followed with the message:
> (123 row(s) affected)
The error appears when I execute it with
```
EXEC [dbo].[GetNeededProperties] '1,3,5,7,2,12', '06/28/2013', 'TT'
```
But works fine when
```
EXEC [dbo].[GetNeeded... | The issue is that you're mixing up dynamic SQL with non-dynamic SQL.
Firstly - the reason it works when you put NULL into @NotNeededWPRNs is because when that variable is NULL, your @ProductsSQL becomes NULL.
WHat you need to do is either make your @PropsIDs table a non-table variable and either a temporary table or ... | Change you code to :
```
Declare @ProductsSQL nvarchar(max);
SET @ProductsSQL = 'DECLARE @PropIDs TABLE
(ID bigint);
Insert into @PropIDs (ID)
SELECT [WPRN] FROM [dbo].[Properties] WHERE(WPRN in (' + @NotNeededWPRNs + '))'
exec sp_executesql @ProductsSQL
```
Table variable declared outside the dynamic SQL will not b... | "Must declare the table variable "@name"" in stored procedure | [
"",
"sql",
"sql-server",
""
] |
I have a question regarding fetch data in the form of table. i have a table with a single row now i just want amount increased on the basis on given logic..
like
```
1st row amount=1200,
2nd row amount=1320(1200+120),
3rd row amount=1452(1320+132)
```
logic is 10% add with previous amount
My table is
```
Sno - Nam... | This has exactly the same limitation as WadimX's answer, but it'll do 100 rows. To produce your example output given your input table (which I'll refer to as `example`):
```
;WITH nums AS
(SELECT 1 AS RowNum, Name, Amount
FROM (SELECT Name, Amount FROM example) s
UNION ALL
SELECT RowNum + 1 As RowNum, N... | ```
WITH COUNTER(RN)
AS
(
SELECT ROW_NUMBER() OVER(ORDER BY object_id)
FROM sys.objects
),
A(RN, value)
AS
(
SELECT CAST(1 as bigint),
CAST(1200 as decimal(20, 0))
UNION ALL
SELECT COUNTER.RN,
CAST(A.value*1.1 as decimal... | Increased amount of each row in sql | [
"",
"sql",
"sql-server",
"sql-server-2008",
""
] |
I have a stored procedure which is supposed to return a result set from a table filtered according to parameters provided.
**UPDATE**
```
alter procedure Proc_CheckExchange
@Flag varchar(3),
@symbol varchar(13)=null,
@exchange char(3)=null,
@limit money=null,
@chargerate numeric(18... | What you could do is to rewrite your stored proc using dynamic SQL and include parts of `where` clause only if parameters are defined, e.g. replace the body with
```
declare @sql nvarchar(max)
set @sql = N'select * from Tbl_StampDutyException1 where 1 = 1'
if len(isnull(@exchange, '')) > 0
set @sql = @sql + N' an... | I think that a good solution would be this one
```
SELECT * from dbo.Clients
WHERE
(@param1 IS NULL OR field1 = @param1)
AND (@param2 IS NULL OR field2 = @param2)
```
With this approach the statement will not be re-processed (execution plan) by the server every time you execute the query. | What is the best approach to filter data in SQL (Dynamic Query)? | [
"",
"sql",
"sql-server",
"t-sql",
"stored-procedures",
""
] |
Hi I have a need to store hundreds if not thousands of elements in the database as XML. I will not index anything in the XML field. I will simply select certain elements within the xml. I would like to know if there is any performance penalty for simply selecting fields in the XML. Here is example XML that will be stor... | Based on my experience on XML in SQL Server Xml datatype, and on [Indexes on XML Data Type Columns](http://technet.microsoft.com/en-us/library/ms191497%28v=sql.100%29.aspx) (the whole section deserves thorough reading)
> Will there be a performance penalty for simply selecting 10 or more
> fields from the XML column ?... | [BEGIN EDIT]
jbl's direct answers to your questions, and Terror.Blade's answer re' XML being better than NVARCHAR(MAX) both make sense (I upvoted them :).
My experience was without storing an XML schema in SQL Server (Terror.Blade's tip), and without indexing (jbl gave the most, re' that)... but I'm leaving my answ... | Does SQL server 2008 XML data type have performance issues | [
"",
"sql",
"sql-server",
"xml",
"sql-server-2008",
""
] |
There are 2 tables. Person and Account. There is a 1:n dependency (via ID) so a person could have n accounts. The Person has an email adress. The change should be, that the email adress will be an attribute in Account Table.
So i created a new attribute email for the account.
How can i move or copy all the email addre... | Try it this way
```
UPDATE account a
SET email =
(
SELECT email
FROM person
WHERE person_id = a.person_id
)
WHERE EXISTS
(
SELECT *
FROM person
WHERE person_id = a.person_id
);
```
Here is **[SQLFiddle](http://sqlfiddle.com/#!4/6d90c/1)** demo | First of all, there is no need to do such copy task.
Its always better to maintain a Primary Key & Foreign key in table.
Still if you want to copy, try something like this.
```
SELECT TMP.EMAIL INTO ACCOUNT AS 'A' FROM
(SELECT P.EMAIL FROM PERSON AS 'P') AS TMP
WHERE A.ID = P.ID
```
Hope, this is what you want. | SQL Move Attribute to another table | [
"",
"sql",
"database",
"oracle11g",
""
] |
How do I get the row count of a Cursor without using `moveToFirst()`?
(Is it possible to do .getCount() without doing .moveToFirst() ???)
**Logcat**
> 11-29 13:37:40.370: E/SQLiteLog(8459): (11) database corruption at
> line 62665 of [00bb9c9ce4]
>
> 11-29 13:37:40.370: E/SQLiteLog(8459): (11) statement aborts at 44... | Done by myself by doing the backup of the db | Use .getCount function to get the row count
```
Cursor.getCount()
``` | Reading row count from Cursor | [
"",
"android",
"sql",
"database",
"cursor",
""
] |
I have a ASP.NET page which have details in below manner.
```
Date OfficerID DutyID
25-NOV-13 2 666
26-NOV-13 2 666
27-NOV-13 2 666
28-NOV-13 2 666
29-NOV-13 2 666
30-NOV-13 2 666
01-DEC-13 2 666
02-DEC-13 2 523
`... | Write below code to handle dynamic query on previous and next button click event :
```
protected void PrevioseButton_Click(object sender, EventArgs e)
{
var sqlQuery = this.GenerateQuery(false);
this.BindGrid(sqlQuery);
}
protected void NextButton_Click(object sender, EventArgs e)
{
var sqlQuery = this.Ge... | On the button click event, try this:
```
DataTable table = new DataTable();
string connectionString = GetConnectionString();
if (Session["sysdate"] == null || string.IsNullOrEmpty(Session["sysdate"].ToString()))
Session["sysdate"] = "-18";
else
Session["sysdate"] = "+ " + (Convert.ToInt32(Session["sysdate"]) ... | Changing the parameter in sql query of ASP.NET page - with button_click event, sql query in every button click | [
"",
"asp.net",
"sql",
"iterator",
"logic",
"code-behind",
""
] |
In one of my table I store user details when ever he login into it.
I want to get repeated occurrence count of each user. Means user x,y,z has logged in how many times.
```
SELECT count( id )
FROM user_stat
GROUP BY id
```
this just gives count value.
```
1 id varchar(64) latin1_swedish_ci Ye... | > select count(login\_id),login\_id from `table_name` group by login\_id;
```
Here login_id means users_login_id. try it
``` | If you want user info with count that how many time user logged in try below qry.
Try this :-
```
SELECT count( id ),username,id
FROM user_stat
GROUP BY id
```
You will may add more column if you want. | Getting count of repeated record occurrence in table | [
"",
"mysql",
"sql",
""
] |
I'm learning C# and some SQL server, and now i am trying to get information from my small database.
I have two tables: `Movie` and `MovieHandler`.
In the table Movie, i have `MovieCodeLable`, which is a uniqe number, and the `Title` of the movie.
In the MovieHandler table, i have `MovieCodeLable` which is the same a... | Your JOIN is wrong and your ON clause is incomplete. The JOIN should involve the names of the 2 tables that you are joining, which in this case is Movie and MovieHandler The ON should be expression of format A = B. So your query should be:
```
SELECT Title
FROM Movie
JOIN MovieHandler
ON ... | You need to specify both JOIN fields
```
SELECT Title
FROM Movie
JOIN MovieHandler
ON Movie.MovieCodeLable = MovieHandler.MovieCodeLable
WHERE InStore = 0
``` | How should I JOIN my tables? | [
"",
"sql",
"sql-server",
"sql-server-2008",
"join",
""
] |
I am using 3-4 tables and using autoincrement on the primaryk ey in all of them. I want all of the tables to start with 1
For example `student` table id starts from 1, and `Registration` table starts from 1.
Right now what happens auto increments start with the last id of student table. For e.g LastRow ID in student ... | As Einav said this subject is to be handled with caution!
If your student table is empty and you are trying to reset the counters because of testing, or because of a yearly wipe down of the database etc. then you can use the [DBCC CHECKIDENT](http://technet.microsoft.com/en-us/library/ms176057.aspx) command(if you are... | If you have some values already (tables not empty) then this is not possible. You could empty all your tables and run [DBCC CHECKIDENT command](http://msdn.microsoft.com/en-us/library/ms176057.aspx) to reset the value of your autoincrement primary key and restart from 1.
```
DBCC CHECKIDENT ("YourTableNameHere", RESEE... | SQL Server Auto-increment | [
"",
"sql",
"sql-server-2008",
""
] |
I have a table full of prices, items, and dates. An example of this is:
```
AA, 1/2/3024, 1.22
AA, 1/3/3024, 1.23
BB, 1/2/3024, 4.22
BB, 1/3/3024, 4.23
```
Within the data there are only two rows per price, and they are ordered by date. How would I condense this data set into a single product row showing the differen... | ```
select product,
sales_date,
current_price - prev_price as diff
from (
select product,
sales_date,
price as current_price,
lag(price) over (partition by product order by sales_date) as prev_price,
row_number() over (partition by product order by sales_date desc) a... | Since `there are only two rows per price`, this can be *much* simpler and faster:
```
SELECT n.item, n.price - o.price AS diff, n.price / o.price AS ratio
FROM price n -- "new"
JOIN price o USING (item) -- "old"
WHERE n.day > o.day;
```
[**->SQLfiddle**](http://sqlfiddle.com/#!15/c3b12/1)
Thi... | Aggregation function to get the difference or ratio of two rows in order | [
"",
"sql",
"postgresql",
"aggregate-functions",
"greatest-n-per-group",
"window-functions",
""
] |
I have a table which looks like this -
```
Id AttributeName AttributeValue
A1 Atr1 A1V1
A1 Atr2 A1V2
A1 Atr3 A1V3
A2 Atr1 A2V1
A2 Atr2 A2V2
A2 Atr3 A3V3
```
Each ID in this table has the exact same attributes, ie ATR1, ATR2, ATR3. The values o... | Just to expand on the other answers, the PIVOT function requires some type of aggregation. Since the value that you want to convert from a row into a column is a string, then you are limited to using either the `max()` or `min()` aggregate function.
While [@Muhammed Ali's](https://stackoverflow.com/a/20253383/426671) ... | ```
DECLARE @MyTable TABLE
(Id varchar(25),
AttributeName varchar(30),
AttributeValue varchar(30))
-- Load Sample Data
INSERT INTO @MyTable VALUES ('A1', 'Atr1', 'A1V1')
INSERT INTO @MyTable VALUES ('A1', 'Atr2', 'A1V2')
INSERT INTO @MyTable VALUES ('A1', 'Atr3', 'A1V3')
INSERT INTO @MyTable VALUES ('A2', 'Atr1', 'A2... | Cannot pivot table with my query? | [
"",
"sql",
"sql-server",
"sql-server-2005",
"pivot",
""
] |
I have a table and I want to filter result from same table. Here is a sample.
```
STUDENT_ID | SCHOOL_YEAR |
-----------+-------------+
747 | 20122013 |
747 | 20132014 |
748 | 20122013 |
749 | 20122013 |
749 | 20132014 |
750 | 20122013 |
751 | 20112012... | Minus is the easy way:
```
select student_id
from tbl
where school_year = '20122013'
minus
select student_id
from tbl
where school_year = '20132014';
STUDENT_ID
----------
748
750
```
You could also do this with an "anti-join":
```
select a.student_id
from tbl a
left outer join tbl b
on a... | For very large data sets you'd probably want to avoid the implicit and unnecessary distinct on a minus, and use a NOT IN or NOT EXISTS:
```
select student_id
from tbl
where school_year = '20122013' and
student_id not in (
select student_id
from tbl
where school_year = '20132014'... | Filter from same table in Oracle | [
"",
"mysql",
"sql",
"oracle",
""
] |
Is there any way to select records if top clause parameter is null?
```
DECLARE @count FLOAT = 0;
Select @count = count from tblDetails
SELECT TOP(@count) from tblCompany
```
If @count var is null than i want to select all records from tblCompany. | ```
DECLARE @count FLOAT = 0;
Select @count = count(1) from tblDetails
IF @count > 0
BEGIN
SELECT TOP(@intRecords) * from tblCompany
END
ELSE
BEGIN
SELECT * FROM tblCompany
END
```
If you do not want to write the query twice - although only one will get executed, you can try this:
```
DECLARE @count FLOAT = 0;
... | When facing situations like this one, I love using SQL [Rank](http://technet.microsoft.com/en-us/library/ms176102.aspx).
In the query below I assumed you have an `ID` column, but you can replace it with any other column for choosing the criteria for what would be considered to be the top columns:
```
DECLARE @count F... | Is there any way to select records if top clause parameter is null? | [
"",
"sql",
"sql-server",
""
] |
**The UI design** for storing event and event meta data is

**SQL TABLE DESIGN** is
```
CREATE TABLE [dbo].[EVENTS]
([ID] [int] IDENTITY(1,1) NOT NULL,
[Name] [nvarchar](255) NOT NULL)
```
and
```
CREATE TABLE [dbo].[EVENTS_META](
[ID] [int] IDEN... | Your first step is to get your event start dates with each event, and the repeat interval, to do this you can use:
```
SELECT EventID = e.ID,
e.Name,
StartDateTime = DATEADD(SECOND, rs.Meta_Value, '19700101'),
RepeatInterval = ri.Meta_Value
FROM dbo.Events e
INNER JOIN dbo.Events_... | The following will generate events based on StartEvent and MEta description with a CTE.
Change the values for MaxDate and MaxEvents according to parameters values.
```
declare @MaxDate datetime = convert(datetime,'12/2/2014', 101);
declare @MaxEvents integer= 200;
; With
-- number generator by power of 2
n2... | Display next event date | [
"",
"sql",
"sql-server",
"sql-server-2008",
""
] |
I am struggling with a database design, this is what I have so far.
Here are the problems.
1. I need to introduce a new user type (conglomeration manager), and they will have visibility of groups of companies (a conglomeration). A conglomeration manager can have multipl... | Well here is another try. I still think
* you shouldn't worry too much about that receive\_emails field, as explained in my other answer.
* you don't have to split users into user kinds.
What you are worried about in 2 is the dependencies. Dependencies are usually not a problem, but you are very strict in your id bas... | Extend users!
Like extending a class you can create a new table "Managers" with more columns and a FK to users.
So you can create a relational table between Managers and companies.
If you want a better control over that conglomerate entity, create the Conglomerate table and make a FK to managers, so you create a rel... | Incorporate additional requirements into a legacy database design | [
"",
"mysql",
"sql",
"database",
"database-design",
""
] |
In SQL Server 2008, If I have a table like this.
```
Date NoOfCases
--------------------
2013-11-27 1
2013-11-28 2
2013-11-29 1
2013-11-30 3
```
And I want the previous sum to be added to the next row's value. That means that the output should be like this:
```
Date AccumulatedNoOfCases... | You could do a join on same table, with the date being smaller or equal.
```
select t1.date, sum(t2.NoOfCases) as AccumulatedNoOfCases
from Table1 t1
join Table1 t2 on t2.Date <= t1.Date
group by t1.date
```
[SqlFiddle](http://sqlfiddle.com/#!6/5a30c/10)
With count, i would use a cte for simplicity
```
with cnt as ... | You didn't say what version of SQL Server you are using. If it is 2012, you can do something like
```
SELECT
t1.date, sum(t1.NoOfCases) OVER (ORDER BY t1.date) AS AccumulatedNoOfCases
FROM Table1 t1
``` | Accumulate rows in SQL: summarizing previous values and new grouped by date | [
"",
"sql",
"sql-server",
"sql-server-2008",
"select",
""
] |
I have two tables:
```
Shop_Products
Shop_Products_Egenskaber_Overruling
```
I want to select all records in Shop\_Products\_Egenskaber\_Overruling which has a related record in
Shop\_Products. This Means a record with an equal ProductNum.
This Works for me with the statement below, but I don't think a CROSS JOIN ... | You are actually looking for an INNER JOIN.
```
SELECT
SO.*,
SPEO.*
FROM SHOP_PRODUCTS SP
INNER JOIN Shop_Products_Egenskaber_Overruling SPEO
ON SP.ProductNum = SPEO.ProductNum
```
This will have improved performance over your CROSS-JOIN, because the condition to look for records with equal Pro... | You can do it that way but not sure it will ensure an optimization
```
SELECT Shop_Products.*, Shop_Products_Egenskaber_Overruling.*
FROM Shop_Products
INNER JOIN Shop_Products_Egenskaber_Overruling on Shop_Products.ProductNum = Shop_Products_Egenskaber_Overruling.ProductNum
``` | Optimize SQL select query with join | [
"",
"mysql",
"sql",
"sql-server",
"t-sql",
""
] |
I used the sql code in vb.net
```
SELECT [Table1 Query].[amel_code], [Table1 Query].[kala_code], Sum([Table1 Query].
[SumOfqty]) AS SumOfSumOfqty FROM(
SELECT Table1.amel_code,
Table1.amani_code,
Table1.kala_code,
Sum(Table1.qty) AS SumOfqty
FROM Table1
GROUP BY Table1.amel_code,
Table1.a... | You need to remove semicolon at the end of the nested query, and add an alias to it:
```
SELECT [Table1 Query].[amel_code], [Table1 Query].[kala_code], Sum([Table1 Query].[SumOfqty]) AS SumOfSumOfqty
FROM (
SELECT Table1.amel_code,
Table1.amani_code,
Table1.kala_code,
Sum(Table1.qty) AS SumOfqty
F... | This is what you are missing:
1) Give an alias `Table1 Query` to a nested query. The error says: It is not able to identify what `[Table1 Query]` is for. so you have to give that alias to a sub query.
```
SELECT [Table1 Query].[amel_code], [Table1 Query].[kala_code], Sum([Table1 Query].[SumOfqty]) AS SumOfSumOfqty
F... | Incorrect syntax near the keyword 'SELECT'. Incorrect syntax near ')' | [
"",
"sql",
"syntax",
""
] |
I am trying to select data from one table
and insert the data into another table
```
SELECT ticker FROM tickerdb;
```
Using OracleSql I am trying to
get the ticker symbol "GOOG" from the tickerdb table,
and insert the t.ticker into the stockdb table.
select from tickerdb table --> insert into quotedb ta... | From the oracle documentation, the below query explains it better
```
INSERT INTO tbl_temp2 (fld_id)
SELECT tbl_temp1.fld_order_id
FROM tbl_temp1 WHERE tbl_temp1.fld_order_id > 100;
```
You can read this [link](http://docs.oracle.com/cd/E17952_01/refman-5.1-en/insert-select.html)
Your query would be as follows
```
... | You can use
```
insert into <table_name> select <fieldlist> from <tables>
``` | select from one table, insert into another table oracle sql query | [
"",
"sql",
"oracle",
"select",
"insert",
""
] |
```
id refid date1 date2 nextdate
5 10 2008-02-21 2009-02-21 004/2008
6 10 2009-02-09 2010-02-09 002/2009
7 10 2010-02-08 2011-02-08 001/2010
10 11 2007-02-15 2008-02-15 002/2007
11 11 2008-02-21 2009-02-21 001/200... | This might do what you want, if I understand your question correctly:
```
SELECT *
FROM datatable
WHERE refid IN (SELECT DISTINCT refid
FROM datatable
WHERE date2 > '20140101')
```
The subquery gives back all distinct *refid* values for which a date2 exists that i... | This is quite basic but if I've understood you correctly:
```
DELETE FROM tableName
WHERE date2 < '2014-01-01' AND NOT (refid IS NULL)
```
**Edit**
As stated in the comment below I possibly misunderstood the following part of the question to mean that the entries needed deleting.
> Remove all rows with refid where... | Filter data with query | [
"",
"sql",
"sql-server-2008",
"filtering",
""
] |
In this table i have four column
```
id state_id state add_time
1 10 1 1385461144
2 12 3 1385461144
3 14 2 1385461144
4 12 5 1385461264
5 10 2 1385461264
```
i want to get latest records by last field (... | There are 2 approaches to get the results you're looking for.
Left join solution:
```
SELECT t1.* FROM t t1
LEFT JOIN t t2
ON t1.state_id = t2.state_id AND t1.add_time < t2.add_time
WHERE t2.add_time IS NULL
```
Fiddle [here](http://sqlfiddle.com/#!2/94393/1).
Subquery solution:
```
SELECT t1.* FROM t t1
JOIN (
... | while you're at it to test which one is faster, here's another one to try
<http://sqlfiddle.com/#!2/760c73/13/0>
```
SELECT id,state_id,state,add_time
FROM t t1
WHERE NOT EXISTS
(SELECT 1
FROM t t2
WHERE t2.state_id = t1.state_id
AND t2.add_time > t1.add_time);
``` | mysql get latest records by timestamp without subquery | [
"",
"mysql",
"sql",
"timestamp",
"greatest-n-per-group",
""
] |
how can I extract the folder name of a filepath sitting right before the filename?
Example:
```
declare @a varchar(200)
set @a = '/path/to/category1/filename.txt'
select right(@a, charindex('/', reverse(@a)) - 1)
```
this returns filename.txt - In another column I now want to get the "category1" folder name.
If the ... | Based on your example code, you can extract the last folder name with the following snippet
```
declare @a varchar(200), @b varchar(200), @c varchar(200)
set @a = '/path/to/category1/filename.txt'
set @b = right(@a, charindex('/', reverse(@a)) - 1)
set @c = replace(@a, '/' + @b, '')
select right(@c, charindex('/', rev... | Alternative method below:
```
declare @a varchar(200)
set @a = '/path/to/category1/filename.txt'
select reverse(
SUBSTRING(reverse(@a),
charindex('/', reverse(@a)) + 1 ,
CHARINDEX('/',reverse(@a),charindex('/', reverse(@a))+ 1) - charindex('/', reverse(@a)) -1)
)
`... | Extract folder name right before filename from filepath | [
"",
"sql",
"sql-server",
"t-sql",
"sql-server-2012",
""
] |
I'm trying to create a select query that returns the most recent record from the table based on date. Basically whichever row's `[Date]` field is closest to the current date.
Sample Data:
```
ID Content Date
--------------------------------------------
1 1050 Test Values 2013-11-27 10:46:24.... | You could try the following query:
```
SELECT TOP 1 *
FROM Table
ORDER BY [Date] DESC
``` | Or, if you want your query to work on any DBMS (not just SQL Server), use [ANSI SQL](http://en.wikipedia.org/wiki/SQL:2011):
```
select * from t order by Date desc limit 1
```
or
```
select * from t where Date = (select max(Date) from t)
``` | Select most recent record based on date | [
"",
"sql",
"sql-server",
""
] |
I have a MySQL table which looks like this:
```
-----
| 1 |
-----
| 3 |
-----
| 7 |
-----
| . |
-----
| . |
-----
| . |
-----
| n |
-----
```
is it possible to select from this table to have something like this:
```
----------
| 1 || 3 |
----------
| 3 || 7 |
----------
| 7 || . |
----------
| . || . |
----------
| ... | I guess, below query is nearest what you want with MySQL
```
mysql> select * from num;
+------+
| a |
+------+
| 1 |
| 3 |
| 7 |
| 11 |
| 17 |
+------+
mysql> select @prev:=a FROM num ORDER BY a ASC LIMIT 1,1;
+----------+
| @prev:=a |
+----------+
| 3 |
+----------+
1 row in set (0.00 sec)
my... | Relational data has no concept of row-numbers or row-ordering, so "shifting by 1 row" is not possible using (standard) SQL. If your table contains a field "rownumber" you could use a self-join:
```
SELECT t1.field, t2.field
FROM mytable t1 join mytable t2 on(t1.rownumber = t2.rownumber+1)
```
But as BenM stated: ju... | Mysql select from table shifting one column | [
"",
"mysql",
"sql",
""
] |
I'm not so good with SQL, so help me please.
In my stored procedure I'm getting a parameter.
Then, based on this parameter I want to get ID from another table and put this ID into my another variable, but the problem is that ID could be multiple based on this parameter.
```
DECLARE @RateID int;
SET @RateID = (
Se... | You may want to try it like this:
```
DECLARE @RateID int;
SET @RateID = (
Select Top 1 [dbo].[Rate].RateID
from [dbo].[Rate]
Where [dbo].[Rate].Rate = 160
)
```
As in your present query there may be the case that you table has more than 1 row which satisfies the condition `Rate = 160`, so the `se... | If you only want the first result you can do
```
Select TOP 1 [dbo].[Rate].RateID
```
in place of
```
Select [dbo].[Rate].RateID
``` | How to set into variable 1st value from subquery result in SQL | [
"",
"mysql",
"sql",
"sql-server",
""
] |
I have table with multiple rows which will contain the data in the following manner
```
col1 col2
100 - 1
100 - 0
102 - 1
102 - 0
103 - 1
```
I need to write a query to fetch the row (103-1). Means the query should return rows that do not have corresponding pair of records(xxx-1,xxx-0). | ```
select col1, max(col2) as col2
from your_table
group by col1
having count(distinct col2) = 1
``` | Try this:
```
select *
from your_table a
where not exists (select 1
from your_table b
where b.col1 = a.col1
and b.col2 != a.col2)
```
Here is an example [sql fiddle](http://www.sqlfiddle.com/#!4/9f1e6/4) | How to retrieve rows from table based on column value(0,1) | [
"",
"sql",
"oracle",
""
] |
I have a small database for a retail scenario, within this I have a field called "Dispatched" which is a bool to indicate if the item has been dispatched yet. This is of course as 1 and 0, I have attempted a simple CASE WHEN to make 1 display as Yes and 0 as No.
My full query is:
```
SELECT
orders.OrdersID,
stock.I... | You are missing with `,` after `address.Country` therefore you are getting syntax error try this one
```
SELECT
orders.OrdersID,
stock.ItemName,
basket.Quantity,
customer.FirstName,
customer.LastName,
address.AddressLine1,
address.AddressLine2,
address.TownOrCity,
address.Postcode,
address.Country,
(CASE WH... | Put backticks:
```
AS `basket.Dispatched`
``` | SQL CASE WHEN issue, Query not running at all | [
"",
"mysql",
"sql",
"case",
"case-when",
""
] |
I'm using SQL Server. I find myself doing complex queries in the WHERE clause with the following syntax:
```
SELECT ..
WHERE StudentID IS NULL OR StudentID NOT IN (SELECT StudentID from Students)
```
was wondering if there's a better approach/more cleaner way to replace it with because this is a small example of the ... | Alain was close, except the studentID2 column is associated with the courses table. Additionally, this is joining each studentID column to an instance of the students table and the final WHERE is testing if EITHER of the student ID's fail, so even if Student1 is valid and still fails on Student2, it will capture the co... | this is not a sure shot but i have had experience that this is better performer than the question one:
```
SELECT CourseID from Courses WHERE
Courses.StudentID NOT exists (SELECT 1 FROM Students where Students.StudentID=nvl(Courses.StudentID,-1));
```
Also Create an index on StudentId in the Students Table.
And if y... | Optimizing WHERE clause SQL query | [
"",
"sql",
"sql-server",
"where-clause",
""
] |
I have a MySQL query which I'm running to return users and a count of their corresponding training results from an additional table, typically these are being displayed in the app front end 50 results at a time, however with this many results the query has become very slow.
Thing are infinitely better if I append the ... | Try something like
```
SELECT users.email, COUNT(r.result_id) as results
FROM users
INNER JOIN users_groups ON users_groups.user_id=users.id
INNER JOIN programmes_results r on ((r.client_id=users.client_id) AND (r.email=users.email))
WHERE users.client_id='130' AND users_groups.group_id IN (5)
group by users.email
ORD... | I suspect the problem is you don't have the right index on programmes\_results. You need a single index that covers both client\_id and email, having two separate indexes won't help very much, because it will only be able to use one of them, say, client\_id and then have to scan all matching rows for ones that have the... | MySQL subquery to count user results in another table is sloooooooow | [
"",
"mysql",
"sql",
"subquery",
""
] |
I have a select result like this:
```
from_loc | to_loc |
-------------------------
A | B
------------------------
B | C
------------------------
B | A
------------------------
```
How can I eliminate duplicates from the table which means occurrence of **A to B** and **B to A** m... | I didn't tested this solution but it could have a better performance (less logical reads):
```
DECLARE @MyTable TABLE
(
from_loc VARCHAR(100) NOT NULL,
to_loc VARCHAR(100) NOT NULL
);
INSERT @MyTable (from_loc, to_loc) VALUES ('A', 'B');
INSERT @MyTable (from_loc, to_loc) VALUES ('B', 'C');
INSERT @MyTa... | Perhaps with this `CASE` in `ROW_NUMBER`:
```
WITH CTE AS(
SELECT from_loc, to_loc,
rn = row_Number() Over (Partition By CASE WHEN from_loc > to_loc
Then to_loc + '|' + from_loc
Else from_loc + '|' + to_loc END
... | Eliminating duplicate combinations from result | [
"",
"sql",
"sql-server",
""
] |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.