
Prompt stringlengths 10 31k | Chosen stringlengths 3 29.4k | Rejected stringlengths 3 51.1k | Title stringlengths 9 150 | Tags listlengths 3 7 |
|---|---|---|---|---|
Using SQL Server 2012, I have a classification table that is something like this:
```
prodName class1min class1max class2min class2max class3min class3max
---------------------------------------------------------------------------------
prod A 1.5 1.8 1.8 2.1 2.1 ... | You can unpivot the data and then perform the comparison. Since you are using SQL Server 2012, then you can easily unpivot the `min`/`max` columns in sets using CROSS APPLY:
```
select prodname, class, [min], [max]
from yourtable
cross apply
(
values
('class1', class1min, class1max),
('class2', class2min, cl... | Since there are only three possible classes, you can accomplish this quite simply with a `CASE` expression:
```
DECLARE @Prod VARCHAR(32) = 'Prod B', @val DECIMAL(10,2) = 4.1;
SELECT [Class] = CASE WHEN @val <= class1max THEN 'Class1'
WHEN @val > class3Min THEN 'Class3' ELSE 'Class2' END
FROM dbo.tableName
WHERE ... | Classify Value Within Max/Min Columns in SQL | [
"",
"sql",
"sql-server",
"t-sql",
"sql-server-2012",
"unpivot",
""
] |
I am suffering from a situation where a user has changed his mobile network and subscribed our service but their mobile number is same. So, for his old subscription I have his old mobile network and for his new subscription, I have his new mobile network record.
For example
```
4474123456 subscribed gamesClub usin... | I think you need to use `GROUP BY/HAVING`:
```
SELECT MobileNo
FROM MobileUsers
GROUP BY MobileNo
HAVING COUNT(DISTINCT networkname) > 1 -- MORE THAN ONE NETWORK
```
If you then need to get all records back for these mobile numbers, you would need to put the above in a subquery and join back to it:
```
SELECT ... | You need to use a subquery.
```
Select userunique, mobileno, subscription, networkname, subscribedDate
From MobileUsers as t1
Where exists
(
SELECT *
FROM MobileUsers as t2
WHERE t2.mobileno=t1.mobileno and t1.networkname<>t2.networkname
)
``` | SQL Query To Display Mobile number that are registered in Different Mobile Network | [
"",
"mysql",
"sql",
"database",
""
] |
I've been working on a 'simple' problem all day and its driving me mad. I'm sure I am missing something obvious; however no amount of searching is helping me.
I have a 1 row data table such as; (Table\_1)
```
Person_1 Person_2 Person_3
PersonID ABC DEF G... | Since you can't change the design, here's the code to retrieve what you want:
```
SELECT Person_1 = a.Work_Done
, Person_2 = b.Work_Done
, Person_3 = c.Work_Done
FROM Table1 t
JOIN Table2 a ON t.Person_1 = a.Person_ID
JOIN Table2 b ON t.Person_2 = b.Person_ID
JOIN Table2 c ON t.Person_3 = c.Person_ID
```
Mul... | ```
SELECT *
FROM
(
SELECT unpvt.Person_Type, b.Work_Done
FROM Table_1 a
UNPIVOT ( Person_ID FOR Person_Type IN (a.[Person_1], a.[Person_2], a.[Person_3]) ) unpvt
JOIN Table_2 b ON unpvt.Person_ID = b.Person_ID
) c
PIVOT ( MAX(c.Work_Done) FOR c.Person_Type IN ([Person_1], [Person_2], [Person_... | TSQL 'Lookup' Function - Confused | [
"",
"sql",
"sql-server",
"t-sql",
"vlookup",
""
] |
I need to return an array of a category where a particular item of which it `has_many`, has a `.count >= 2`
I know this sytax is wrong, but I'm trying to figure out the correct way, any tips??
`Model.where(model.has_many_relationship_item.count >= 2) ??`
Thanks in advance!! | Category.joins(:items).group("cateogry.id").having("COUNT(items.id) >= 2") | The only way I know how to do this is:
```
Model.joins(:items).group('models.id').having('count(items.id) >= 2')
```
assuming (for example) the class of the related model is `Item` | Rails postgres query - Model.where(model.has_many_relationship_item.count >= 2)? | [
"",
"sql",
"ruby-on-rails",
"postgresql",
"relational-database",
""
] |
My problem is the following.
I want to `SELECT` the minimum of a years list and display another row of my table.
An example:
```
SELECT MIN(Year)
FROM table -> Searching for the lowest year.
```
and then I want it to display the `Winners` of the first year.
Is there a way to do this in just one line? | ```
select winner from table where year in (select min(year) from table)
``` | You need to do a self-JOIN between table and itself (I suppose you want to do it in a single *statement*, not a single *line*):
```
SELECT A.*
FROM table AS A
JOIN ( SELECT MIN(Year) AS Year FROM table ) AS B
ON (A.Year = B.Year);
```
This assumes that there is only one record per minimum-year in every gr... | SELECT a variable as condition and display another one | [
"",
"sql",
"sql-server",
"t-sql",
"select",
""
] |
I have created a Stored Procedure
```
CREATE PROCEDURE GetAllRecords()
BEGIN
SELECT * FROM my_table;
END //
```
Now I want to add a parameter to this Stored Procedure like this :
```
CREATE PROCEDURE GetAllRecords(id1 INT(4))
BEGIN
SELECT * FROM my_table WHERE `id` = id1;
END //
```
... | You have drop procedure first and then re-create it
```
DROP PROCEDURE IF EXISTS GetAllRecords;
CREATE PROCEDURE GetAllRecords(IN _id INT)
SELECT *
FROM my_table WHEREid = _id;
```
And since you're using the only statement in your procedure you can ditch `BEGIN ... END` block and use a usual delimiter.
In cas... | Delete the procedure
```
drop procecdure GetAllRecords//
```
And recreate it
```
CREATE PROCEDURE GetAllRecords(id1 INT(4)) ...
``` | Edit a Stored Procedure using ALTER? | [
"",
"mysql",
"sql",
"stored-procedures",
""
] |
I Have to create a table currencies
```
CREATE TABLE currencies (
from_currency CHAR(30) NOT NULL,
ExchRate REAL NOT NULL,
to_currency CHAR(30) NOT NULL,
PRIMARY KEY (from_currency),
FOREIGN KEY (to_currency) REFERENCES currencies(from_currency)
)
```
I h... | You should either create a composite primary key as a pair of 2 currencies is uniquely identifying a record for you.
```
CREATE TABLE currencies (
from_currency CHAR(30) NOT NULL,
ExchRate REAL NOT NULL,
to_currency CHAR(30) NOT NULL,
PRIMARY KEY (from_currency, to_currency)
)
`... | You are not storing a currency, but rather a pair of currencies.
```
CREATE TABLE currency_exchange_rates (
from_currency CHAR(30) NOT NULL,
to_currency CHAR(30) NOT NULL,
ExchRate REAL NOT NULL,
PRIMARY KEY (from_currency,to_currency),
)
```
I would also sugges... | I have been assigned a project for currency exchange rate IN SQL . How to save exchange rates for currencies? | [
"",
"sql",
""
] |
```
select *
from tableA
order by cast(columnA as int), column B.
```
This is my current query script. There is a scenario where there column A is null. And result rows where column A is null are pushed to the end.
Is there a way such that if columnA is null, put the rows before other rows where columnA is not null... | Something along these lines should work if your dbms supports standard SQL.
```
select (case when columnA is null then 0 else 1 end) as sort_order, *
from tableA
order by sort_order, columnA, columnB;
``` | Try like below... it will help you....
```
SELECT * FROM tableA ORDER BY (CASE WHEN columnA IS NULL THEN 1 ELSE 0 END) DESC,
CAST(columnA as int), column B
```
It display the NULL results before NOT NULL Results | sql query where null results get placed first | [
"",
"sql",
""
] |
Here I want to get sorted rows as **3,4,5,1,2,6,7,8,9** based on status or based on its description,
```
Status Description
1 New
2 Hold
3 Counter-Proposed
4 Partial-Counter-Proposed
5 Confirmed
6 Partial response Accept
7 Respone Accept
8 Response Reject
9 Cancelled
```
I tried with union all by se... | ```
select Status, Description
from Status
order by case when Status in (3,4,5) then 1 else 2 end, Status
``` | @RedFilters answer works.
However, you could argue that there is a missing column on Status. You should consider adding a column to Status to represent which "set" the status is in. Then you can join from your main table to Status, and sort by this new column.
This way, you would not have to remember to update any co... | Oracle SQL Custom sorting | [
"",
"sql",
"oracle",
""
] |
I added a new column to an already existing table, I just need to get data into this new column...I assume I can use a variant of the insert command, yet I do not know how to specify the column name and then how to order the values going into the new column. | Ok, after some conversation through the comments lets go to an answer.
I suppose your table is something like `id, name, age, dateBirth, etc fields`. But whoever create this table forget to add the gender for the registries. As you said that the new column is an `sex enum('m', 'f')` you will have to update every regis... | you have to use `update` command, `insert` is for adding new rows.
```
update myTABLE set NewColumn = ?
``` | inserting data into a new column of an already exsisting table | [
"",
"mysql",
"sql",
""
] |
I need to get the count of records which have Id as 11 and 12 separate. Then i have to group them by period (which is 1,2,3,4,5) and divide each ID with their corresponding group.
i.e (count of ID=11 with period 1) / (count of ID=12 with period 1)
I have tried this. But this just gives me a count of each. How can i di... | The Having count .. is to avoid a division by 0
```
SELECT count(SK_PatientID) as pNum
, count(case when SK_MetricID = 11 then 0 end) / count(case when SK_MetricID = 12 then 0 end)
, SK_MetricDatePeriod
FROM [MetricValues]
WHERE SK_MetricID In (11, 12)
GROUP BY SK_MetricDatePeriod
... | Not a full answer but it wouldn't let me comment.
Wouldn't it be easier to select your original query into a working table and then Divide pNum where MetricPeriod = MetricPeriod
If you are just looking for an average across every MetricID you could just sum you pnum of each occurence of period and then divid by the t... | count and divide two columns of the same table in sql | [
"",
"sql",
"t-sql",
""
] |
> ERROR 1064 (42000): You have an error in your SQL syntax; check the manual that
> corresponds to your MySQL server version for the right syntax to use near '(sele
> ct ifnull(count(tbl\_Product.manufactureId),0)
> from tbl\_product where manu' at line 5
```
create procedure ManufactureCheckForDelete(p_manufactureid ... | You need to use = operator to assign the result from query
```
set p_id (select ifnull(count(tbl_Product.manufactureId),0)
^^ here
from tbl_product where manufactureId = p_manufactureId
) ;
set p_id= (select ifnull(count(tbl_Product.manufactureId),0)
^^ here
from tbl_product where... | Your error says you have a space in `select`
> ...syntax to use near '**(sele ct** ifnull...
And you are missing a `=` before the select.
```
set p_id = (select ...
^-------------here
``` | Error 1064 in procedure | [
"",
"mysql",
"sql",
""
] |
I just came up with an idea for a piece of code to show all the distinct values for each column, and count how many records for each. I want the code to loop through all columns.
Here's what I have so far... I'm new to SQL so bear with the noobness :)
Hard code:
```
select [Sales Manager], count(*)
from [BT].[d... | You can use dynamic SQL and get all the column names for a table. Then build up the script:
```
Declare @sql varchar(max) = ''
declare @tablename as varchar(255) = 'test'
select @sql = @sql + 'select [' + c.name + '],count(*) as ''' + c.name + ''' from [' + t.name + '] group by [' + c.name + '] order by 2 desc; '
f... | This is a bit of an XY answer, but if you don't mind hardcoding the column names, I suggest you do just that, and avoid dynamic SQL - and the loop - entirely. Dynamic SQL is generally considered the last resort, opens you up to security issues (SQL injection attacks) if not careful, and can often be slower if queries a... | Looping through column names with dynamic SQL | [
"",
"sql",
"loops",
"dynamic",
""
] |
I need to select all distinct combinations of 2 columns: region and make, as well as select a sum for each of these combinations for the total column.
Lets say I have 4 columns
```
ID Region Make total
1 E blue 2
2 E red 1
3 E blue 1
4 W green 2
5 W ... | You can use `group by`to calculate sum based on distinct combinations of columns you specified after the group by class
```
Select Region,Make,SUM(total) as total from table1 group by Region,Make
``` | Try this:
```
select Region, Make, sum(total)
from table1
group by Region, Make
``` | SQL Select distinct combinations of columns and sum | [
"",
"sql",
"sql-server",
"sum",
""
] |
In my case there are orders and order positions. Each order position has a quantity. For example:
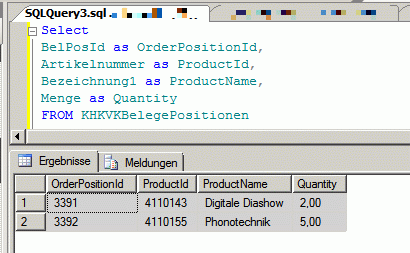
But now I need a single row for each "position element". This is the output I want:

ALTER TABLE dbo.numbers
ADD
CONSTRAINT pk_numbers PRIMARY KEY CLUSTERED (number)
WITH FILLFACTOR = 100
GO
INSERT INTO dbo.numbers (number)
SELECT (a.number * 256) + b.number As number
FROM (
SELECT number... | You can use that script which doesn't require any external tables:
```
SELECT t.quantity,
n.num
FROM table10 t
INNER JOIN (SELECT Row_number()
OVER(
ORDER BY object_id) num
FROM sys.all_objects) n
ON t.... | How to multiply a single row with a number from column in sql | [
"",
"sql",
"sql-server",
""
] |
I have the tables shown below.
```
Table1
Field1 Field2
ID111 1,500
ID112 100
ID111 250
ID114 50
ID114 20
Table2
Field1 Field3
ID111 Chris
ID112 Mary
ID114 John
```
What I'd like to have is the result shown below.
```
ID111 Chris 1,750
ID112 Mary 100
ID114 John 70
```
I've already achieved this... | This should suffice-
```
SELECT t1.firld1, t2.field3,
sum(t1.CTotal) as cTotal
FROM table1 t1 INNER JOIN table2 t2
ON t1.field1 = t2.field1
GROUP BY t1.field1, t2.field3
```
Whatever columns you are selecting in your `SELECT` statement that are not an aggregate function (i.e., the columns that... | As Blorgbear and Matt Welch said, you need to include all columns that are not in an aggregate function in the group by.
The reason for this is that you are trying to tell it to sum one value, but not what to put in the other columns.
Think about the data you have in the other two columns, how does it know to show 10... | SQL Inner Join with Group By | [
"",
"sql",
"group-by",
"sum",
"inner-join",
""
] |
[SQL FIDDLE](http://sqlfiddle.com/#!2/5715f/2)
I have it's table definition :
```
CREATE TABLE `table2` (
`id` INT NOT NULL,
`varchardata` VARCHAR(45) NULL,
`intdata` INT(10) NULL,
PRIMARY KEY (`id`));
```
Data :
```
INSERT INTO `table2` (`id`, `varchardata`, `intdata`) VALUES ('1', '12', '12');
INSERT INTO... | Try this:
```
SELECT *
FROM table2
ORDER BY IF(CAST(varchardata AS SIGNED) = 0, 99999, CAST(varchardata AS SIGNED));
```
Check the [**SQL FIDDLE DEMO**](http://sqlfiddle.com/#!2/5715f/16)
**OUTPUT**
```
| ID | VARCHARDATA | INTDATA |
|----|-------------|---------|
| 8 | 3 | 3 |
| 10 | 6... | Another way of doing it to correctly treat `0` (distinguish it from non-numeric values)
```
SELECT id, varchardata, intdata
FROM
(
SELECT id, varchardata, intdata, varchardata REGEXP '[0-9]' is_numeric
FROM table2
) q
ORDER BY is_numeric DESC, 1 * varchardata
```
Output:
```
| ID | VARCHARDATA | INTDATA ... | Is it possible to sort varchar data in ascending order that have mix value? | [
"",
"mysql",
"sql",
"sorting",
"select",
"sql-order-by",
""
] |
I need to determine if I should insert data into theDate or theDate2 column based on data in the processDate column from the table being selected from. I am unable to use a column in a CASE statement however (I am getting an error when trying to run the code below), and I can't find a solution to this. How can I do thi... | If both theDate and theDate2 can be determined by the flag processDate then do it in your select rather than in the insert. Assuming that the columns are nullable (as your CASE in the INSERT clause seems to indicate they are mutually exclusive, then I'd be inclined to do something like;
```
INSERT INTO tableOne (th... | The proper syntax for an insert is
```
insert into table
(field1, field2, etc)
select field3, field4, etc
from somewhere
```
I have no idea if this will work, but you can try:
```
insert into tableOne
(case when processDate <> '' then theDate else Date2 end)
select sdate
from #table2
``` | Determining column to use in INSERT statement based on data in the table being selected from | [
"",
"sql",
"sql-server-2008",
""
] |
I have a row with date column in my table:
```
date1 = 2013-12-11 00:00:00.000
```
And I want to compare it with date:
```
date2 = 11.12.2013 0:00:00
```
I do:
```
SELECT *
FROM ServiceOrder
WHERE CreateDateTime <= '11.12.2013 0:00:00'
```
And I am expecting that as a result I get a row with `date1` but I don't ... | So it is a bit tricky to convert your format because it is too specific and ms sql doesn't have easy date format functions to do it. so here is an way to convert your entire date:
```
SELECT *
FROM ServiceOrder
WHERE CreateDateTime <= (
select convert(datetime,
c... | Use this. You need to convert the string into datetime for right comparison. And also use the correct format number here 104
```
SELECT *
FROM ServiceOrder
WHERE CreateDateTime<=CONVERT(datetime,'11.12.2013 0:00:00', 104)
```
And the better practice is that to take a variable and use that in query instead of convert... | How to compare dates in SQL Server? | [
"",
"sql",
"sql-server",
""
] |
i am having one table name student detail which containing following columns and data's
```
NAME MARK2 MARK3 SID MARK1
Timmy 85 95 123 25
GSJD 75 95 25 69
FBKSD 88 75 27 96
```
i was trying to get sum the values of mark... | ```
select (mark1+mark2+mark3) as mark_sum
from studentdetail
where mark1=96
``` | In Mysql you can do like this:
```
select mark1,mark2,mark3,(mark1 +mark2+mark3) as Total from studentdetail where mark1=96;
``` | how to sum only a specific row in a table | [
"",
"mysql",
"sql",
""
] |
I tried decrying other answers, no luck, hence asking.
I have one table and few more similar to this for other year
Here is the table structure
```
--------------------------------
STATUS | Year | Company Name
--------------------------------
Certified | 2010 | Google
Cert-Denied | 2010 | Google
Denied ... | The COUNT is only returning the COUNT for the status that he finds for Microsoft. And those are Denied and Wthdrawn. You have to feed the query all the statuses and COUNT the occurrences of all of them. The ones that don't appear will in the table will be left with 0:
```
SELECT a.STATUS,
SUM(CASE
WHEN... | A fairly straight forward way is to get all distinct statuses and `LEFT JOIN` with the table to get the counts;
```
SELECT a.status, COUNT(b.status) cnt
FROM (SELECT DISTINCT status FROM Table1) a
LEFT JOIN Table1 b
ON a.status = b.status
AND b.`Company name`='Microsoft'
GROUP BY a.status
```
[An SQLfiddle to test... | MySQL Group by - Get columns with zero count | [
"",
"mysql",
"sql",
""
] |
I have crated two table one is cutomer and other one is ord
```
select * from customers;
```
Customer table
```
1 101 jun 23 yyyy 15000
2 102 jas 24 zzzz 10000
3 103 fat 20 kkkk 20000
4 104 jini 40 llll 30000
5 105 michael 30 dddd 25000
6 106 das 25 hhhh 10000
7 107 vijay 2... | `group by c.name, c.salary` with `sum(salary)` is what you want:
```
select c.name, c.salary, sum(o.amount )
from CUSTOMERS c
inner join ord o on c.id=o.customer_id
group by c.name, c.salary;
``` | try this if it will work.
```
select c.name,c.salary,sum(o.amount)
from CUSTOMERS c
inner join ord o
on c.id=o.customer_id
group by 1,2;
```
Thanks. | Please help me to solve this | [
"",
"sql",
"oracle",
""
] |
This is the result of my query, but it doesn't order correctly. I want to order by the last 2 characters. The result should be: `Fa0/10` below `Fa0/9`.
```
Fa0/1
Fa0/10
Fa0/11
Fa0/12
Fa0/2
Fa0/3
Fa0/4
Fa0/5
Fa0/6
Fa0/7
Fa0/8
Fa0/9
Gi0/1
Gi0/2
Null0
Vlan1
```
My query:
```
SELECT inft.port FROM interfaces AS intf ORD... | Try this:
```
SELECT port
FROM interfaces
ORDER BY SUBSTRING_INDEX(port, '/', 1), CAST(SUBSTRING_INDEX(port, '/', -1) AS SIGNED)
```
Check the [**SQL FIDDLE DEMO**](http://sqlfiddle.com/#!2/fde72/8)
**OUTPUT**
```
| PORT |
|--------|
| Fa0/1 |
| Fa0/2 |
| Fa0/3 |
| Fa0/4 |
| Fa0/5 |
| Fa0/6 |
| Fa0/7 |
|... | Why you need `+ 0` ?? Simply remove it and it will work.
```
SELECT port FROM interfaces ORDER BY RIGHT(port, 2)
```
[SQL Fiddle Demo](http://www.sqlfiddle.com/#!3/01d40/7)
Output:
```
PORT
------------
Fa0/1
Gi0/1
Gi0/2
Fa0/2
Fa0/3
Fa0/4
Fa0/5
Fa0/6
Fa0/7
Fa0/8
Fa0/9
Fa0/10
Fa0/11
Fa0/12
Null0
Vlan1
``` | Order by last 2 characters string | [
"",
"mysql",
"sql",
"select",
"sql-order-by",
""
] |
Consider there are three database say `D1, D2, D3`. And two tables `T1, T2` in each database.
Table `T1` has two columns `C1, C2`. Table `T2` has three columns `C3, C4, C5`.
Now we have six table. The records in each database are different.
**Database structure:**
```
D1:
------
T1 T2
D2:
------
T1 T2
D3:
---... | You can run a query like this (SQL Server version below, other dbs are similar):
```
Select 'db1' as db, 'T1' as table from db1.dbo.T1 where 'Some_value' in (C1, C2)
union all
Select 'db1' as db, 'T2' as table from db1.dbo.T1 where 'Some_value' in (C3, C4, C5)
union all
Select 'db2' as db, 'T1' as table from db2.dbo.T... | try this query in oracle, you can use `val` as variable :
```
select Tab1.* from
(Select 'D1' as DataBase,D1.T1.* from D1.T1
UNION ALL
Select 'D2' as DataBase,D2.T1.* from D2.T1
UNION ALL
Select 'D3' as DataBase,D3.T1.* from D3.T1) Tab1,
(select 'Some_value' as val from dual)Tab2
WHERE
Tab1.C1 = Tab2.val;
``` | Find the database in which a particular record is available | [
"",
"sql",
"sql-server",
"database",
"oracle",
""
] |
I need a query to find Inspection/Component that did not get a "Rating 6" record. I'll be inserting new records so that all Inspection/Component have a "Rating 6" record along with what ever other ratings they may have.
Consider the following data: 57646, 57652 and 57657 are **not** correct because they are missing th... | ```
SELECT *
FROM YourTable A
WHERE NOT EXISTS(SELECT 1 FROM YourTable
WHERE InspectionID = A.InspectionID
AND ComponentID = A.ComponentID
AND RatingTypeID = 6)
``` | ```
SELECT A.InspectionID FROM MyTable AS A
LEFT OUTER JOIN MyTable AS B
ON A.InspectionID = B.InspectionID AND B.RatingTypeID = 6
WHERE B.InspectionID IS NULL
``` | TSQL: Find required missing records | [
"",
"sql",
"sql-server-2008",
"t-sql",
""
] |
How get results without grouping it?
My table
```
id user_id amount currency_id type status
5 2 2.00 1 0 0
6 3 3.00 1 0 0
4 1 1.00 1 0 0
7 4 4.00 1 0 0
8 5 3.00 1 1 0
```
I do the following select
```
SELECT id, user_id, amount, currency_id, SUM( amount ) ... | If your intent is to return individual records that meet this criteria AND sum them up and you don't actually need the SUM value as a field on every row (not sure why you would), then I would suggest looking at the `GROUP BY ... WITH ROLLUP` modifier. It works like this:
```
SELECT id, user_id, SUM(amount) AS `amounts... | You can do join
```
SELECT id,
user_id,
amount,
currency_id,
a.totalAmount
FROM market
CROSS JOIN
(
SELECT SUM(amount) totalAmount
FROM market
WHERE amount <=3
AND type = 0
AND stat... | SELECT without grouping | [
"",
"mysql",
"sql",
"database",
""
] |
I'm fairly new to SQL and I'm trying to get my head around the following problem - I'm attempting to get a list of products broken down so we can see how many of each one has been sold every year
I have two tables; Orders (which contains JobNum and Date) and Products (with JobNum, Fig, Fype, Size and Quantity fields).... | Although I have not specifically used dbase since about 1986, I am guessing they have implemented a common IIF() functionality as other languages. I am more used to FoxPro/Visual Foxpro historically, but here is the basis of what you need, and if you are using Visual Foxpro OleDB, you should be fine.
What is happening... | You may use a subquery as a column. For instance:
```
SELECT t0.*, (SELECT COUNT(*) FROM t1 WHERE YEAR(date_fld)=2002) AS y2002, (SELECT COUNT(*) FROM t1 WHERE YEAR(date_fld)=2003) AS y2003 FROM t0
``` | Getting product quantities broken down annually | [
"",
"sql",
"dbase",
""
] |
I had one single table that had lots of problems. I was saving data separated by commas in some fields, and afterwards I wasn't able to search them. Then, after search the web and find a lot of solutions, I decided to separate some tables.
That one table I had, became 5 tables.
First table is called agendamentos\_dia... | I agree with @Strawberry about the ids, but normally it is the Hibernate mapping type that do this. If you are not using Hibernate to design your tables you should take the ID out from agendamento\_tecnico and agendamento\_veiculos. That way you garantee the unicity. If you don't wanna do that create a unique key on th... | Better is subjective, there's no right answer.
My natural instinct would be to break that schedule table up even more.
Looks like data about the technician and the client is duplicated.
There again you might have made a decisions to de-normalise for perfectly valid reasons.
Doubt you'll find anyone on here who disag... | A more efficient way to store data in MySQL using more than one table | [
"",
"mysql",
"sql",
"database",
""
] |
I know that this question has been asked many times but could not find what I needed.
I have this column "Order" which contains data in the following format. `'xxx,yyy,zzzz'`
Now when I do my `select` statement I need to populate 3 columns by splitting this one
E.G.
```
Select Name,
Surname,
FirstCommaColu... | I've change the function name so it won't overlapped in what the `Split()` function really does.
Here is the code:
```
CREATE FUNCTION dbo.GetColumnValue(
@String varchar(8000),
@Delimiter char(1),
@Column int = 1
)
returns varchar(8000)
as
begin
declare @idx int
declare @slice varchar(8000)
select @... | ```
Declare @str as Varchar(100) = '10|20|30|40|500|55'
Declare @delimiter As Varchar(1)='|'
Declare @Temp as Table ( item varchar(100))
Declare @i as int=0
Declare @j as int=0
Set @j = (Len(@str) - len(REPLACE(@str,@delimiter,'')))
While @i < = @j
Begin
if @i < @j
Begin
Insert into @Temp
Values(SUBS... | Split function by comma in SQL Server 2008 | [
"",
"sql",
"sql-server-2008",
"t-sql",
"split",
""
] |
I want to create a stored procedure to insert a new row in a table 'dbo.Terms'
```
CREATE PROCEDURE dbo.terms
@Term_en NVARCHAR(50) = NULL ,
@Createdate DATETIME = NULL ,
@Writer NVARCHAR(50) = NULL ,
@Term_Subdom... | I presume you want to insert the values cat etc into the table; to do that you need to use the values from your procedures variables. I wouldn't call your procedure the same name as your table it will get all kinds of confusing; you can find some good resources for naming standards (or crib from [Adventureworks](https:... | Here is how to set your defaults for parameters in your proc:
```
CREATE PROCEDURE dbo.terms
@Term_en NVARCHAR(50) = 'Cat',
@Createdate DATETIME = '2013-12-12',
@Writer NVARCHAR(50) = 'Fadi',
@Term_Subdomain NVARCHAR(50) = 'English'
AS
BEGIN
SET NOCOUNT... | Create a stored procedure to insert new data into a table | [
"",
"sql",
"sql-server",
"stored-procedures",
""
] |
I have a table like below

From the above table I Need to select adjacent values from val3 column based on Number column
I Need output like below :
 | ```
WITH T1
AS (SELECT *,
DENSE_RANK() OVER (PARTITION BY [Number] ORDER BY [Val3]) - [Val3] AS Grp
FROM YourTable),
T2
AS (SELECT *,
COUNT(*) OVER (PARTITION BY [Number], Grp) AS Cnt
FROM T1)
SELECT [Number],
[Val1],
[Val2],
[Val... | An ugly solution would be:
```
select d.number, d.val1, d.val2, d.val3 from table d
where exists
(select * from table t
where t.number = d.number
--and t.val1 = d.val1
--and t.val2 = d.val2
and (t.val3 = d.val3 - 1 or t.val3 = d.val3 + 1))
``` | How to find adjacent values in a column based on another column value in Sql | [
"",
"sql",
"sql-server",
"sql-server-2008",
""
] |
I do not understand the following (returns numbers of comments for articles with the newest ones dates):
```
SELECT `id_comment`,COUNT(*) AS `number`, MAX(`date`) AS `newest`
FROM `page_comments`
WHERE TO_DAYS( NOW() )-TO_DAYS(`date`) < 90
GROUP BY `id_comment`
ORDER BY `count` DESC,`newest` DESC
```
I dont unders... | I am just explaining it to the ground.
**MAX()** - An aggregate function(Works over the group of data).
If **""group by""** clause is **NOT** specified, the database implicitly groups the data(column specified) considering the entire result set as group.
If specified, it just groups the data(column) in the group log... | You described the behavior yourself quite correctly already: `it automatically takes only the max for the given group`.
If you group, you do it (per usual) on every column in the result set, that is not aggregated (not using `COUNT`, `SUM`, `MIN`, `MAX`...)
That way you get distinct values for all non aggregated colu... | How does the aggregation function work with group by | [
"",
"sql",
"group-by",
""
] |
Lets say I have the below data, the last column keyword is nothing but the combination of the other 4 cols.
```
╔════╦══════╦════════════╦═════════╦════════════╦════════════════════════════════╗
║ ID ║ Name ║ Add1 ║ Add2 ║ Add3 ║ Keyword ║
╠════╬══════╬════════════╬═════════╬═════... | The part `... WHERE ID IN ( ...) ...` will just do a 'yes or no' check, but you want counting. That has to be done with a JOIN.
Try this:
```
SELECT TABA.*, COUNT(sub.ID) AS FREQUENCY FROM TABA JOIN
(
(SELECT ID FROM TABA WHERE KEYWORD LIKE '%WASHINGTON%')
UNION ALL
(SELECT ID FROM TABA WHERE KEYWORD LIKE '%JOHN%... | Why not to do a simplified version without that subqueries:
```
SELECT ID, Name, Add1, Add2, Add3, COUNT(*) AS FREQUENCY
FROM TABA
WHERE ID IN
(SELECT ID
FROM TABA
WHERE KEYWORD LIKE '%WASHINGTON%'
OR KEYWORD LIKE '%JOHN%'
OR KEYWORD LIKE '%PEAPACK%')
GROUP BY ID, Nam... | Get number of times keyword is present | [
"",
"sql",
"sql-server",
""
] |
I am using a script to do a query in sqlplus, but i have a problem when i trying to export to a file
I have this in my sqlplus:
```
spool hits.csv
SET NEWPAGE NONE
SET PAGESIZE 0
SET SPACE 0
SET LINESIZE 100
SET ECHO OFF
SET FEEDBACK OFF
SET VERIFY OFF
SET HEADING OFF
SET MARKUP HTML OFF SPOOL OFF
SET TERMOUT OFF
SET... | SQL\*Plus is clunky in this regard. You can do:
```
select camp1 || '|' || camp2 || '|' || camp3 || '|' || camp4 from table;
```
Which will do what you want, but can be unwieldy for large select lists. | ```
set linesize 30000 -- sufficiently large
```
solves the problem. | sqlplus, export the query in 1 column, and disordered | [
"",
"sql",
"database",
"oracle",
"sqlplus",
""
] |
Say that I have two tables T and T1
T
```
id p o
1 47 1
2 48 2
3 49 25
```
T1
```
id p o
1 47 1
2 42 2
3 47 25
```
I am looking to insert rows from T1 into T if `count(T1.p)>1`
T
```
id p o
1 47 1
2 48 2
3 49 25
1 ... | To get those values into T you will have to find out who they are in T1 and JOIN them with T1 again, to get the right number of rows:
```
INSERT INTO T (id, p, o)
SELECT TT.*
FROM T1 TT
INNER JOIN (
SELECT id, p1, l
FROM T1
GROUP BY p1
HAVING COUNT(*) > 1
) a ON a.p1 = TT.p1;
```
`sqlfiddle demo`
How this ... | ```
insert into T SELECT T1.id , T1.p1,T1.l FROM T1
GROUP BY t1.p1
HAVING COUNT(t1.p1)>1
```
<http://www.sqlfiddle.com/#!2/75c8e/1>
Use dml on the left side | Mysql using count in query | [
"",
"mysql",
"sql",
""
] |
I have ended up with a peculiar problem. I am not able to find out the root cause of the issue. Please help.
please create a table by executing below scripts
```
CREATE TABLE Employee_salary (ID INT,emp_name VARCHAR(50),Salary INT)
INSERT INTO Employee_salary VALUES(1,'Dolu',15000)
INSERT INTO Employee_salary VALUES... | Please try below query from lowest salary:
```
SELECT Top 1 emp_name, salary from Employee_salary order by salary
```
and
```
SELECT Top 1 emp_name, salary from Employee_salary order by salary desc
```
for highest salary.
If there are more than one employee with same salary, try:
```
SELECT Top 1 WITH TIES emp_na... | tried below query for min and max salary records.
```
-- For Max
SELECT emp_name, salary from Employee_salary where salary = (SELECT Max(salary) from Employee_salary)
-- For Min
SELECT emp_name, salary from Employee_salary where salary = (SELECT Min(salary) from Employee_salary)
``` | Lowest salaried employee sql server - not working with MIN function | [
"",
"sql",
"sql-server",
""
] |
TBL\_condition
```
ID CONDITION
1 AAA
2 BBB
3 CCC
```
When I hit this query:
```
SELECT CONDITION FROM TBL_condition
```
It says:
> ERROR 1064 (42000): You have an error in your SQL syntax; check the manual that corresponds to your MySQL server version for the right syntax to use near 'cond... | try using backticks (`) around CONDITION :
```
SELECT `CONDITION` FROM `TBL_condition`;
```
Condition is a term used by mysql. read more on this site: <http://forums.mysql.com/read.php?101,40643,40643> | CONDITION is reserved word in mysql <http://dev.mysql.com/doc/refman/5.0/en/reserved-words.html>
try like this
```
SELECT `CONDITION` FROM TBL_condition
``` | SELECT Query Not Working when selecting particular column 'condition' | [
"",
"mysql",
"sql",
"select",
""
] |
i'm afraid to use User forms data to query the database for user login, since the company has only 20 employees, I'm thinking of this function but I'm no sure if this still a easy code to crack for any no so good hacker user
```
Private Function VerifyCredentials(ByVal User As String, ByVal Password As String) As Bool... | You are just storing plain text password. Once your database is compromised, you do not have time to notify users.
You need to store hashed password with salt. Although, it can still be cracked (it takes times) but you still have sometime to notify users to change the password.
For ASP.Net, the easiest way will be to... | Let the database filter for you.
Change the query to
```
"Select UserName, UserPassword from tblUsers
WHERE UserName = " & Trim(User) & " AND UserPassword = " & Trim(Password)
```
And then, if there is some result the authentication is correct, and if there's no result, obviusly you have to return false, so simply do... | UserName and UserPassword Verification function | [
"",
"asp.net",
"sql",
"vb.net",
""
] |
I've searched for this answer on Stackoverflow and I haven't been able to get any of the posted solutions to work for me.
I have two tables:
```
builds:
build_id (INT)
status_id (INT)
created (INT)
```
And
```
statuses:
status_id (INT)
name (VARCHAR)
description (VARCHAR)
```
I'd like to have a query that will ret... | I ended up making this work by joining in a separate calendar table similar to what was suggested in this post: [SQL left joining multiple tables](https://stackoverflow.com/questions/9722801/sql-left-joining-multiple-tables)
Here is the full query:
```
"SELECT
allRecords.date,
allRecords.Name,
( SELECT
... | Try:
```
SELECT FROM_UNIXTIME(created, '%Y-%m-%d') as date,
COUNT(builds.status_id) as count,
statuses.name
FROM builds
RIGHT JOIN statuses on builds.status_id=statuses.status_id
GROUP BY date, name;
```
or maybe:
```
SELECT FROM_UNIXTIME(created, '%Y-%m-%d') as date,
SUM(CASE WHEN builds.statu... | MySQL count return 0 instead of no records | [
"",
"mysql",
"sql",
""
] |
This is a seemingly simple thing to do but I can't find any reference to it. I want to add a customized field to my select statement if the value of another field is null. In the below I want to create a field named 'IMPACT' that shows a value of 'Y' if the LOCATION\_ACCOUNT\_ID field in the subquery is null. How do I ... | Use `CASE` instead of `IF`:
```
SELECT
FIRST_NAME,
LAST_NAME,
ULTIMATE_PARENT_NAME,
CASE WHEN LOCATION_ACCOUNT_ID IS NULL THEN 'Y' ELSE '' END AS IMPACT
FROM (
SELECT DISTINCT
A.FIRST_NAME,
A.LAST_NAME,
B.LOCATION_ACCOUNT_ID,
A.ULTIMATE_PARENT_NAME
FROM ACTIVE... | Use a [case](http://docs.oracle.com/cd/B19306_01/server.102/b14200/expressions004.htm) statement:
```
SELECT FIRST_NAME,
LAST_NAME,
ULTIMATE_PARENT_NAME,
CASE WHEN Location_Account_ID IS NULL THEN 'Y' ELSE '' END AS IMPACT
FROM (
SELECT DISTINCT A.FIRST_NAME,
A.LAST_NAME,
B.LOCATION_ACCOUNT_ID,
A.U... | Create custom field in SELECT if other field is null | [
"",
"sql",
"oracle",
""
] |
Let's say I have a table called EmployeeInfo like following:
```
Name Hours StartTime Date
John Smith 8 8:00 2013-12-11
John Smith 7 7:00 2013-12-10
John Smith 9 6:00 2013-12-09
Tom Smith ... | ```
DECLARE @t TABLE
(
Name VARCHAR(50),
Hours INT,
StartTime TIME,
Date1 DATE
)
INSERT INTO @t
SELECT 'John Smith', 8, '8:00', '2013-12-11' UNION ALL
SELECT 'John Smith', 7, '7:00', '2013-12-10' UNION ALL
SELECT 'John SMITH', 9, '6:00', '2013-12-09' UNION ALL
SELECT 'Tom S... | A cleaner solution than the accepted answer
```
SELECT e1.Name, e1.Hours HoursToday, e2.HoursWeekly, e1.StartTime, e2.Date
FROM EmployeeInfo e1
JOIN (
SELECT Name, MAX(Date) Date, SUM(Hours) HoursWeekly
FROM EmployeeInfo
WHERE Date >= CONVERT(DATE, GETDATE() - 7)
GROUP BY Name
HAVING MAX(Date) >= C... | How to select a specific row from the table with one column as a sum of values of other rows? | [
"",
"sql",
"sql-server",
"sql-server-2012",
""
] |
I am using SQL Server 2008 and I have the following query:
```
SELECT [Id] FROM [dbo].[Products] WHERE [dbo].GetNumOnOrder([Id]) = 0
```
With the following "GetNumOnOrder" Scalar-valued function:
```
CREATE FUNCTION [dbo].[GetNumOnOrder]
(
@ProductId INT
)
RETURNS INT
AS
BEGIN
DECLARE @NumOnOrder INT
SE... | If you have the rights to add indexes to the tables (and dependant on the version of SQL Server you are using), I would investigate what performance gain adding the following would have:-
```
create index newindex1 on PurchaseOrders (id)
include (StatusId);
create index newindex2 on PurchaseOrderDetails (Purchase... | If you still want to use a function and can not live without it, use a in-line table value version. It is a-lot faster. Check out these articles from some experts.
<http://aboutsqlserver.com/2011/10/23/sunday-t-sql-tip-inline-vs-multi-statement-table-valued-functions/>
<http://dataeducation.com/scalar-functions-inlin... | T-SQL Calling Scalar Function in Where Speed | [
"",
"sql",
"sql-server",
"t-sql",
""
] |
I need to show count of job application for last 12 months based on & need to group them also based on Job Application dates
I tried following it generates error as shown below.
```
SELECT
COUNT(MONTH(ApplicationDate) AS VARCHAR(2)) + '-' + CAST(YEAR(ApplicationDate) AS VARCHAR(4)) AS Total,
ApplicationDate
... | How about this one?
```
SELECT
COUNT(*) AS Total,
(CAST(MONTH(ApplicationDate) AS VARCHAR(2)) + '-' + CAST(YEAR(ApplicationDate) AS VARCHAR(4))) as ApplicationDate
FROM
[Jobs]
GROUP BY
(CAST(MONTH(ApplicationDate) AS VARCHAR(2)) + '-' + CAST(YEAR(ApplicationDate) AS VARCHAR... | You need to try something like this to get one row for each month/year that contains the count of applications for that month/year:
```
SELECT
MONTH(ApplicationDate),
YEAR(ApplicationDate),
COUNT(*)
FROM
dbo.[Jobs]
GROUP BY
YEAR(ApplicationDate),
MONTH(ApplicationDate)
ORDER BY
YEAR(Application... | SQL query to count based on MM-YYYY part of date | [
"",
"sql",
"sql-server",
"sql-server-2008",
""
] |
I need to return a value (0) if nothing is found in an SQL call.
Here is what i have (edited/simplified to make more sense out of context), this is baing called from the codebehind.
```
sql1 = "INSERT INTO [Xtr_MenuItems]([menu_order])
values(1 + (select max(menu_order) from [Xtr_MenuItems]))
```
SO into database i... | Try this:
```
sql1 = "INSERT INTO [Xtr_MenuItems]([menu_order])
values(1 + ISNULL((select max(menu_order) from [Xtr_MenuItems]),0))
```
I used ISNULL function where if the result of query is null returns 0 | Instead of `values`, you could use `select` straight away:
```
insert Xtr_MenuItems
(menu_order)
select 1 + isnull(max(menu_order),0)
from Xtr_MenuItems
``` | Return an integer if nothing is found (TSQL ASP.NET VB) | [
"",
"asp.net",
"sql",
"vb.net",
"t-sql",
""
] |
I have a table that has a column (cat\_name). Some are strings followed by numbers and others are just plain strings. I like to arrange it by putting all strings starting with 'Level' first.
**Desired output:**
* Level 1 Items
* Level 2 Items
* Level 3 Items
* Level 5 Items
* Level 10 Items
* Level 12 Items
* Level 2... | Try with:
```
SELECT * FROM category
ORDER BY (CASE WHEN cat_name LIKE 'Level%' THEN 0
ELSE 1
END)ASC,
LEFT(cat_name,LOCATE(' ',cat_name)), CAST(SUBSTRING(cat_name,LOCATE(' ',cat_name)+1) AS SIGNED),
cat_name ASC
```
It's to do with the order of statements within your `ORDER BY` | You also can use something like this -
```
SELECT * FROM category
ORDER BY
IF(cat_name REGEXP '^(Level )[0-9]+( Items)$', 0, 1),
TRIM(LEADING 'Level ' FROM cat_name)*1,
cat_name
``` | SQL sort string with numbers certain pattern first | [
"",
"mysql",
"sql",
"sql-order-by",
"case",
""
] |
After create a Stored Procedure in a Table " dbo.terms" to insert a data in it using this code:
```
CREATE PROCEDURE dbo.terms
@Term_en NVARCHAR(50) = NULL ,
@Createdate DATETIME = NULL ,
@Writer NVARCHAR(50) = NULL ,
... | To add more rows you can use SELECTED table.
This is a special table populated with rows inserted in your transaction.
An example is:
```
INSERT INTO dbo.term_prop VALUES
SELECT * FROM inserted
```
So you mustn't use FOR EACH ROW.
The correct definition of your trigger will be
```
CREATE TRIGGER triggername O... | Wow, I am still surprised that triggers are given a **bad wrap**! I wrote a dozen articles on them a long time ago ...
Like anything in life, the use of triggers depends on the situation.
1 - Trigger are great to track DDL changes. Who changed that table?
<http://craftydba.com/?p=2015>
2 - Triggers can track DML ch... | Create a Trigger to insert a rows in another table | [
"",
"sql",
"sql-server",
"datatrigger",
""
] |
I have a Table (call it `A_table`) in a database (call it `A_db`) in Microsoft SQL Server Management Studio, and there are 10 rows.
I have another database (call it `B_db`), and it has a Table (call it `B_table`), which has the same column settings as `A_table` has. But the `B_table` is empty.
What I want:
* **Copy*... | Quick and Easy way:
1. Right click database
2. Point to `tasks` `In SSMS 2017 you need to ignore step 2 - the generate scripts options is at the top level of the context menu` Thanks to [Daniel](https://stackoverflow.com/users/5740181/daniel-elkington) for the comment to update.
3. Select `generate scripts`
4. Click n... | I know this is an old question, but victorio also asked if there are any other options to copy data from one table to another. There is a very short and fast way to insert all the records from one table to another (which might or might not have similar design).
If you dont have identity column in table B\_table:
```
... | How to export all data from table to an insertable sql format? | [
"",
"sql",
"sql-server",
"copy",
"export",
"ssms",
""
] |
I have the following trigger created for when the value of a specific column is detected:
```
ALTER TRIGGER [dbo].[trCompletedDate] ON [dbo].[Record]
FOR UPDATE AS BEGIN
IF(UPDATE(Completed))
UPDATE Record SET Completed_Date=DATEADD(hh, 7, GETDATE())
FROM Record
INNER JOIN Inserted ON Record.[ID]= Inserted.[ID]
WHER... | ```
UPDATE Record SET Completed_Date =
CASE WHEN Record.Completed = 1 THEN
DATEADD(hh, 7, GETDATE())
ELSE
--Somethin else
END
FROM Record
INNER JOIN Inserted ON Record.[ID]= Inserted.[ID]
``` | You can use a [CASE](http://technet.microsoft.com/en-us/library/ms181765.aspx) statement:
```
UPDATE Record
SET Completed_Date =
CASE Record.Completed WHEN 1 THEN DATEADD(hh, 7, GETDATE())
WHEN 0 THEN SOMETHINGELSE END
FROM Record
INNER JOIN Inserted ON Record.[ID]= Inserted.[ID]
WHERE... | sql trigger IF statement | [
"",
"sql",
"sql-server-2008",
"triggers",
""
] |
I have table with user transactions.I need to select users who made total transactions more than 100 000 in a single day.Currently what I'm doing is gather all user ids and execute
```
SELECT sum ( amt ) as amt from users where date = date("Y-m-d") AND user_id=id;
```
for each id and checking weather the amt > 100k o... | This will do:
```
SELECT sum ( amt ) as amt, user_id from users
where date = date("Y-m-d")
GROUP BY user_id
HAVING sum ( amt ) > 1; ' not sure what Lakh is
``` | What about filtering the record 1st and then applying sum like below
```
select SUM(amt),user_id from (
SELECT amt,user_id from users where user_id=id date = date("Y-m-d")
)tmp
group by user_id having sum(amt)>100000
``` | Suggest an optimised mysql query | [
"",
"mysql",
"sql",
"query-optimization",
""
] |
I'm using MSSQL server 2008 and have two tables `forms` and `employees`.
`forms` contains all forms completed by employees, e.g.
```
[id][employeeId][formId]
```
There are only ever 6 types of forms each with their own id. How would I construct a query to list each employee with each type of form and whether they ha... | You can group by the employee ID and "count" the number of instances of each form type:
```
SELECT employeeid,
SUM(CASE WHEN f.ID = 1 THEN 1 ELSE 0 END) formType1,
SUM(CASE WHEN f.ID = 2 THEN 1 ELSE 0 END) formType2,
SUM(CASE WHEN f.ID = 3 THEN 1 ELSE 0 END) formType3,
SUM(CASE WHEN f.ID = 4 THEN 1 EL... | Maybe this could do the trick
```
SELECT emp.[employeeName], form1.formId as formType1, form2.formId as formType2, form3.formId as formType3, form4.formId as formType4, form5.formId as formType5, form6.formId as formType6
FROM [database_name].dbo.[employees] as emp
RIGHT OUTER JOIN [database_name].dbo.[form] as form... | SQL query select each type of form per employee | [
"",
"sql",
"sql-server",
"database",
""
] |
my question is regarding the existance of records in a table. How could i get a resulting list which really notifies if the record i'm looking for des or does not exist ?
I mean, i know i can check for what does exist with a query like
```
SELECT field FROM table WHERE unique_field IN (value1, value2)
```
And that wi... | Use `EXISTS()`, it stops searching for more rows when there's a hit, so you won't have much overhead when searching big tables.
```
SELECT 'value1' AS unique_field, EXISTS(SELECT 1 FROM your_table WHERE unique_field = 'value1') AS 'exists'
UNION ALL
SELECT 'value2' AS unique_field, EXISTS(SELECT 1 FROM your_table WHE... | You can also do this using a "reference" table for the values:
```
select ref.val,
(exists (select 1 from table t where t.unique_field = ref.val)) as `exists`
from (select 'value1' as val union all
select 'value2' as val
) ref;
```
You can also phrase this as a `left outer join`:
```
select ref.val... | Check records existance in MYSQL | [
"",
"mysql",
"sql",
""
] |
This should be a simple one but I am having trouble with it. I want to create dynamic seperated list from a table that I have. Example:
Table:
```
Email
Person1@address.com
Person2@address.com
```
End result should give me
Person1@address.com;person2@address.com
I am not sure what the right method would be to get ... | This should give back the desired results:
```
SELECT STUFF((SELECT ';'+ Email AS [text()] FROM Person FOR XML PATH('')),1,1,'');
```
<http://sqlfiddle.com/#!3/c3fac/3> | ```
declare @emailstring varchar(max) = ''
select @emailstring = @emailstring + email + ';'
from tablename
set @emailstring = left(@emailstring,len(@emailstring)-1)
``` | Creating a CSV list from a sql table | [
"",
"sql",
"t-sql",
""
] |
I have two tables:
```
Table A with system values
------------------------
id | val_1 | val_2 |
------------------------
1 | 11 | 22 |
------------------------
Table B with user values
-----------------------
uid | set | val_3 |
-----------------------
21 | 1 | 11 |
----------------------... | Do an update using a JOIN:-
```
UPDATE TableB
CROSS JOIN TableA
SET TableB.val_3 = CASE WHEN TableB.`set` = 1 THEN TableA.val_1 ELSE TableB.`set` = 2 THEN TableA.val_2 END
WHERE TableA.id=1
AND TableB.`set` IN (1,2)
``` | Try this:
```
UPDATE TableB
SET val3 =
CASE set
WHEN 1 THEN (SELECT val1 FROM TableA WHERE id=1)
WHEN 2 THEN (SELECT val2 FROM TableA WHERE id=1)
END
``` | Update table depending on value without overlapping field names | [
"",
"mysql",
"sql",
"if-statement",
"sql-update",
"case",
""
] |
I have a table which has a `primary key` with `varchar` data type. And another table with `foreign key` as `varchar` datatype.
I am making a `join` statement using this pair of `varchar` datatype. Though I am dealing with few number of rows (say hunderd rows), it is taking `60ms`. But when the system will finally be d... | > Should I create a new column with a number datatype in both the table and join the table to reduce the time taken by the SQL Query.?
If you're in a position where you can change the design of the database with ease then yes, your Primary Key should be an integer. Unless there is a really good reason to have an FK as... | You should use the correct data type for that data that you are representing -- any dubious theoretical performance gains are secondary to the overhead of having to deal with data conversions.
It's really impossible to say what that is based on the question, but most cases are rather obvious. Where they are not obviou... | SQL - performance in varchar vs. int | [
"",
"mysql",
"sql",
"sql-server",
"database",
"oracle",
""
] |
One thing struck in my head about mysql/sqlserver i.e **delete/ truncate**
Which one is better and faster ?
where to use delete?
where to use truncate? | **DELETE**
1. DELETE is a DML Command.
2. DELETE statement is executed using a row lock, each row in the table is locked for deletion.
3. We can specify filters in where clause
4. It deletes specified data if where condition exists.
5. Delete activates a trigger because the operation are logged individually.
6. Slower... | ## Difference
The most important difference is DELETE operations are transaction-safe and logged, which means DELETE can be rolled back. TRUNCATE cannot be done inside a transaction and can’t be rolled back. Because TRUNCATE is not logged recovering a mistakenly TRUNCATEd table is a much bigger problem than recovering... | comparison of truncate vs delete in mysql/sqlserver | [
"",
"mysql",
"sql",
"sql-server",
""
] |
I am running a file upload process to upload files to a db. The web server and the SQL server are different machines. I am attempting to use an SQL OPENROWSET to upload an excel file, but I cannot determine how to get the file onto the other machine. Is there a way to set up a shared drive that the web server can save ... | Using the OPENROWSET means that SQL qill access files using the service account. This account must be used to access share drive, as stated here [Using SQL Credential to Open a file with OpenRowSet](https://stackoverflow.com/questions/20613475/using-sql-credential-to-open-a-file-with-openrowset). | I am also trying the same thing by uploading the file in FTP and trying to access it. But i didn't get any progress from last 2 weeks.
And i had found may other alternatives like coping the files in another server and share the folder with out user name & password. then we can able to access it by giving the
\\folder\... | Save and access file from shared drive | [
"",
"sql",
"iis",
"active-directory",
"directory",
""
] |
I am working with SQL Server 2008
If I have a Table as such:
```
Code Value
-----------------------
4 240
4 299
4 210
2 NULL
2 3
6 30
6 80
6 10
4 240
2 30
```
How can I find the median AND group by the Code column please?
To get a resultset like this:
```
Code M... | The solution using rank works nicely when you have an odd number of members in each group, i.e. the median exists within the sample, where you have an even number of members the rank method will fall down, e.g.
```
1
2
3
4
```
The median here is 2.5 (i.e. half the group is smaller, and half the group is larger) but t... | SQL Server does not have a function to calculate medians, but you could use the ROW\_NUMBER function like this:
```
WITH RankedTable AS (
SELECT Code, Value,
ROW_NUMBER() OVER (PARTITION BY Code ORDER BY VALUE) AS Rnk,
COUNT(*) OVER (PARTITION BY Code) AS Cnt
FROM MyTable
)
SELECT Code, Value
... | How to find the SQL medians for a grouping | [
"",
"sql",
"sql-server",
"t-sql",
"group-by",
"median",
""
] |
[Sqlite does not support the use of indexes in queries based around a NOT IN clause](http://www.sqlite.org/optoverview.html).
Is it possible to logically rewrite a query like the following in such a way that it will only use the operators listed at the link above?
The query:
```
Select *
From table
Where table-colum... | ```
Select A.*
From table a
left join table2 b
on a.table-column = b.table-column
WHERE b.table-column is null
``` | Use a [LEFT JOIN as described in section 6](http://www.sqlite.org/optoverview.html).
SQLFiddle with sample data [here](http://www.sqlfiddle.com/#!5/0cc76/1). Expand *View Execution Plan* to confirm that the original query does a table scan, while the LEFT JOIN query uses the index. | Is it possible to rewrite a NOT IN query to use indexes? | [
"",
"sql",
"sqlite",
""
] |
I have a table with a column price for each product, now its already have the values, but i want to add +10$ to each product. Is there any way to update the entire row with addition.
I am not getting how to give the increment value here
```
update mytable set price=
``` | Try this. If your price field is numeric(int,float) type..
```
update mytable set price = price + 10
``` | Just an update to @a\_horse\_with\_no\_name's answer
`update mytable
set price = NVL(price,0) + 10;`
NULL + 10 is null (Atleast in oracle). | updating entire row by adding values in sql | [
"",
"mysql",
"sql",
""
] |
Hi and thanks in advance for your time.
I have to solve this specific problem.
and I have following table of stamps
```
idStamp idCustomer uptoW uptoD price
----------- ----------- ----------- ----------- -----------
218 4 2200 690 205
218 4 1700 ... | I believe one way of doing what you want is ordering the results by the *exceeding area*, and then taking the first row.
Something like that:
```
-- Test schema, based on S Koppenol answer:
CREATE TABLE stamps (
[idStamp] INT,
[idCustomer] INT,
[uptoW] INT,
[uptoD] INT,
[price] M... | You could add `uptoD >= DESIRED_VALUE` to the validation.
For example:
```
SELECT Distinct(UptoW) FROM [stamps]
WHERE uptoW=(SELECT MIN(uptoW)
FROM [stamps]
WHERE uptoW >= 1600-1 AND uptoD >= 640 AND idStamp = 218 AND idCustomer = 4);
```
This would give you:
```
UPTOW
1700
```
But you could simplify further and d... | Retrieve closest upper values | [
"",
"sql",
"sql-server",
"database",
""
] |
In a MySQL table there are two columns: user and score.
How can I get a table with the second maximum scores of each user? And the maximum of these second maximums?
In other words, I could have this table:
```
User | Score
X 50
Y 74
X 9
X 12
Y 21
```
I want to get a table with the second ma... | ```
DROP TABLE IF EXISTS scores;
CREATE TABLE scores(id INT NOT NULL AUTO_INCREMENT PRIMARY KEY,user CHAR(1) NOT NULL,score INT NOT NULL,INDEX(user,score));
INSERT INTO scores (user,score)
VALUES
('X',50),
('Y',74),
('X',9),
('X',12),
('Y',21);
SELECT x.*
FROM scores x
JOIN scores y
ON y.user = x.user
... | **All the entries without the `MAX` for each user:**
```
SELECT t1.user, t1.score FROM t t1,
(SELECT t2.user, t2.score FROM t t2 WHERE t2.score =
(SELECT MAX(t3.score) FROM t t3 WHERE t2.user = t3.user)) t4
WHERE t1.user = t4.user AND t1.score <> t4.score
GROUP BY t1.user DESC ORDER BY t1.user, t1.scor... | MySQL second maximums of each user | [
"",
"mysql",
"sql",
""
] |
I'm using mysql. And here is one table, which I made for example:
> <http://sqlfiddle.com/#!2/0ca23/1>
In this table I've got fields:
`Country`, `City`, `Resource`, `Volume`, `other`
I need to **SELECT** records which contains **MAX** value of `Volume` field of each `Resource` each `City` each `Country`.
I've tried ... | Check this updated Fiddle of yours: <http://sqlfiddle.com/#!2/0ca23/4>
```
SELECT temp.*
FROM temp
JOIN
(SELECT `Country`, `City`, `Resource`, MAX(`Volume`) AS MaxVol
FROM `temp`
GROUP BY `Country`, `City`, `Resource`) t
ON temp.country = t.country
AND temp.city = t.city
AND temp.resource = t.reso... | Since you're not grouping on the `other` column, MySQL will give you a random value from within the group. In fact, other RDBMS such as SQL Server does not even allow you to SELECT a column on which you don't have an aggregate function or a group by.
So the solution, in your case, depends on what you want to return fo... | Find records with MAX value in each | [
"",
"mysql",
"sql",
"group-by",
"max",
"greatest-n-per-group",
""
] |
**This is my database table tbl\_rate**
```
delimiter $$
CREATE TABLE `tbl_rate` (
`Rate_ID` int(11) NOT NULL AUTO_INCREMENT,
`Route_ID` int(11) NOT NULL,
`From_LocationID` int(11) NOT NULL,
`To_LocationID` int(11) NOT NULL,
`Normal_Rate` double NOT NULL,
`Discounted_Rate` double NOT NULL,
PRIMARY KEY (... | If you want to use a subquery in `DELETE` with the same table you're deleting from all you have to do is to wrap your query in additional outer select
```
DELETE
FROM tbl_rate
WHERE Rate_ID IN
(
SELECT Rate_ID
FROM
(
SELECT Rate_ID... --- Your original query goes here
) q
);
```
Here is **[SQLFidd... | ```
DELETE FROM tbl_rate WHERE
From_LocationID NOT IN(
select
a.Route_LocationID from_loc_id
from tbl_route a
inner join tbl_route b on a.Route_ID = b.Route_ID and a.Route_Seq < b.Route_Seq and a.Route_ID = 3
inner join tbl_location la on la.Location_ID = a.Route_LocationID
inner join tbl_location lb on lb.L... | MySQL Delete From Select | [
"",
"mysql",
"sql",
""
] |
So I have two payment tables that I want to compare in a Oracle SQL DB. I want to compare the the total payments using the location and invoice and total payments. It's more comlex then this but basically it is:
```
select
tbl1.location,
tbl1.invoice,
Sum(tbl1.payments),
Sum(tbl2.payments)
From
tbl1 ... | You can use the `With` statement to create the two querys and join then as you said. I will put just the sintaxe and if you need more help just ask. Thats because you didn't provide full details on your tables. So I will just guess on my answer.
```
WITH tmpTableA as (
select
tbl1.location,
... | Sorry, my first answer was wrong. Thank you for providing the sqlfiddle, MT0.
The point that i missed is that you need to sum up the payments on each table first, so there's only one line left in each, then join them. This is what MT0 does in his statements.
If you want a solution that looks more "symmetric", try:
`... | Left outer join on aggregate queries | [
"",
"sql",
"oracle",
"aggregate",
"cartesian",
""
] |
Lets say I have this table:
```
ID|Username|Mood |color
-------------------------
1 |User1 |Sad |red
2 |User1 |Happy |red
3 |User1 |Mad |red
4 |User1 |Scared |green
5 |User1 |Sad |green
6 |User2 |Sad |purple
7 |User2 |Happy |red
8 |User3 |Mad |blue
9 |User4 |Scared |green... | You seem to be looking for a simple group by:
```
SELECT MIN(id), username, mood FROM table
GROUP BY username, mood
```
Now, note this won't return `user2` with both ids `5` and `6` but rather `6` and `7`.
This query returns all the unique `username, mood` pairs and whenever a duplicated pair is found it is discarde... | It's really unclear what you want, however one of these should hopefully help:
To get rows that are unique, use `DISTINCT`:
```
select distinct *
from mytable
```
To get only users that have only one mood:
```
select * from mytable
where id in (
select id
from mytable
group by id
having count(*) = 1... | Is it possible to count and/or return unique values from an SQL database? | [
"",
"sql",
""
] |
I would like to know how to update a table, with values from another table, by the trick is I need to set a limit because I have thousands of rows to update, and PHPmyadmin can't handle that load. ( I dont have direct access to the server )
My table structure looks like this
**wp\_postmeta**
`meta_id,
post_id,
meta_... | You can try it this way
```
UPDATE wp_postmeta t JOIN
(
SELECT p.meta_id, m.newmap
FROM wp_postmeta p JOIN wp_map m
ON p.meta_value = m.oldmap
ORDER BY p.meta_id
LIMIT 100
) s
ON t.meta_id = s.meta_id
SET t.meta_value = s.newmap;
```
Here is **[SQLFiddle](http://sqlfiddle.com/#!2/47c4... | It's rather unconventional , but it should help you in a pinch
```
SET @tmp_c = 0;
UPDATE
table1
INNER JOIN table2 ON table1.id = table2.id
INNER JOIN table3 ON table2.id = table3.id
SET
table1.remove_date = NOW() - INTERVAL 5 MONTH
WHERE
table1.active = 1
AND
(IF (table1.active = 1, @tmp_c := @tmp_c +... | MySQL update join with limit | [
"",
"mysql",
"sql",
"join",
"phpmyadmin",
""
] |
I want to be able to return a list of unique Ids in a child table that do not contain certain rows.
My table looks similar to:
```
Id Name
1 X
1 Y
1 Z
2 A
2 B
2 C
3 X
3 B
3 Z
```
I want to write a SQL query like
```
SELECT Id
FROM table t
WHERE UPPER(t.Name) IN ('X', 'Y', 'Z')
OR UPPER(t.N... | You want to find all rows that do not contain X, Y, Z or A, B, C. You can do this with aggregation and a having clause:
```
select id
from t
group by name
having not ((sum(case when Name = 'X' then 1 else 0 end) > 0 and
sum(case when Name = 'Y' then 1 else 0 end) > 0 and
sum(case when Name = ... | [SQL Fiddle](http://sqlfiddle.com/#!4/e708c/1)
**Oracle 11g R2 Schema Setup**:
```
CREATE TABLE tbl ( Id NUMBER(1), Name VARCHAR2(1) );
INSERT INTO tbl VALUES ( 1, 'X' );
INSERT INTO tbl VALUES ( 1, 'Y' );
INSERT INTO tbl VALUES ( 1, 'Z' );
INSERT INTO tbl VALUES ( 2, 'A' );
INSERT INTO tbl VALUES ( 2, 'B... | How to determine if certain combinations of rows exist in table | [
"",
"sql",
"sql-server",
"oracle",
""
] |
```
DECLARE @sample varchar(1)
insert into tblSample (Column1) values(@sample)
```
then not passing any values to @sample.
I want to insert whenever I call the stored procedure even though the parameter is not supplied. Thanks | You can simply add default value NULL for parameter of SP. But make sure that your table allow NULL value in that column. If you will not pass any value to parameter then it will take NULL as default like below :
```
CREATE PROCEDURE TestProc (@sample varchar(1) = NULL)
AS
BEGIN
insert into tblSample (Column1) val... | why you will want to insert even if no parameter is supplied ?
what is the exACT REQUIREMENT ? | Is it possible to insert to table even though the parameter is not supplied? sql | [
"",
"sql",
"sql-server",
"t-sql",
""
] |
I have a table where the customers of a company are listed each month. If 4 new customers are added and none leaves, there would thus be added 4 more rows to the table, than what was added the month before. I thought I could identify these 4 new customers by the following code, but it returns 0 rows.
```
SELECT Variab... | This is not an attempt to answer your question. This is a demonstration of how to make your query run faster.
While intuitive and database agnostic, this construct,
```
where somefield not in (subquery goes here)
```
is slow. Here is something that has the same logic as your query, but will run faster.
```
SELECT V... | I am not sure if I understand you correctly, since pieces of information are missing.
However, this is how you would output all customers, who are new in this month:
```
SELECT Variable1
FROM Table1
WHERE DateVariable >= '20131201'
```
If you need to check last month's customers, your query would look like this:
``... | SQL Server - Identify new entries | [
"",
"sql",
"sql-server",
""
] |
I have such **SupplierLangs** table:
*ID, SupplierId, SrcLngId, TrgLngId*
it contains data like this:
```
1, 1000, 1, 2
2, 1000, 1, 3
3, 1000, 1, 4
4, 1000, 2, 3
5, 1000, 2, 4
6, 1001, 1, 2
7, 1001, 1, 4
8, 1001, 2, 4
9, 1002, 3, 4
```
when **Languages** table look like this:
*ID, LangName*
```
1, En
2, De
3, Fr
4,... | I found proper query ( but I use temporary table ) - is it a solution without it ?
```
select distinct sr.SrcLngId, sr.SupplierId
into #myTable99
from SupplierLangs sl
select SrcLngId, count(SrcLngId) as [count] from #myTable99 temp
group by SrcLngId
drop table #myTable99
```
Thanks all for theirs reply! | TRY THIS
```
SELECT Count(DISTINCT supplierid)
FROM supplierlangs
WHERE supplierid IN (SELECT sr.supplierid
FROM supplierlangs sr
--where sr.SrcLngId = 1 --Remove this
GROUP BY sr.supplierid)
HAVING Count(DISTINCT supplierid) > 0 --this wil... | How to count results from groupped subquery | [
"",
"sql",
"sql-server",
""
] |
I know you can set user [profiles](https://stackoverflow.com/questions/1914286/oracle-set-query-timeout) or set a general timeout for query.
But I wish to set timeout to a specific query inside a procedure and catch the exception, something like :
```
begin
update tbl set col = v_val; --Unlimited time
del... | No, you can not set a timeout in pl/sql. You could use a host language for this in which you embed your sql and pl/sql. | You could do:
```
select * from tbl for update wait 10; --This example will wait 10 seconds. Replace 10 with number of seconds to wait
```
Then, the select will attempt to lock the specified rows, but if it's unsuccessful after n seconds, it will throw an "ORA-30006: resource busy; acquire with WAIT timeout expired"... | How to set timeout for anonoymous block or query in plsql? | [
"",
"sql",
"oracle",
"plsql",
"oracle11g",
""
] |
Hi I'm kinda new to mssql, I'm used to Oracle. I'm trying to delete a specific row from a subquery but mssql doens't really like subqueries.
Here is the query:
```
DELETE FROM (SELECT *, ROW_NUMBER() OVER (PARTITION BY column1 ORDER BY column1) row FROM randomtable) a
WHERE a.row = 1
```
Is there a way to get this t... | You were nearly there
```
DELETE a
FROM (SELECT *,
ROW_NUMBER() OVER (PARTITION BY column1 ORDER BY column1) row
FROM randomtable) a
WHERE a.row = 1
```
Though I prefer the CTE syntax
```
WITH a
AS (SELECT *,
ROW_NUMBER() OVER (PARTITION BY column1 ORDER BY column1) r... | You didn't specify the table alias in what you wanted to delete from.
```
DELETE a FROM (SELECT *, ROW_NUMBER() OVER (PARTITION BY column1 ORDER BY column1) row FROM randomtable) a
WHERE a.row = 1
``` | How to get DELETE FROM [QUERY] to work? | [
"",
"sql",
"sql-server",
"sql-server-2008",
""
] |
I have two simple tables:
`OrderStatus` and `OrderStage` that have a single primary key integer column of `OrderStatusID` and `OrderStageID` respectively. Each table returns about 5 rows.
What I'm trying to do is make a SELECT statement which counts the number of orders per OrderStatusID and OrderStageID combination.... | I am sure there are slicker ways to write it for SQL Server 2012, but essentially do a `CROSS JOIN` to get all possible combinations of status and stage (ie 25 rows). *Then* do an outer join back to `orders` to get the counts for each combination:
[SQL Fiddle](http://sqlfiddle.com/#!3/dd0d6/1)
\*\* Generally best to ... | If you want to display `0` where none exist, you can create a driver table that consists of all combinations, and join to that:
```
SELECT driver.*,SUM(CASE WHEN o.OrderStatusID IS NOT NULL THEN 1 ELSE 0 END)AS OrderCount
FROM (SELECT *
FROM (SELECT DISTINCT OrderStatusID FROM Orders) a
,(SELECT DIST... | Best way to loop through all possible combinations across multiple tables? | [
"",
"sql",
"sql-server",
"coldfusion",
"sql-server-2012",
""
] |
I am trying to normalize my database. I have broken out all redundant data and is now joining and inserting the new data. I have been porting 1 million rows at a time and that have worked well up until now. Now a million rows takes days instead of minutes, and it seam to be stuck on reading many many millions of rows a... | As many people pointed out, since this was a read problem, I broke the SELECT query down and tested the query minus one join at the time, I was expecting the huge URL table/keys to be the problem but soon found that the main problem was a corrupt table/index on the keyword table. I don't know how this could happen but ... | Try removing the GROUP BY and ORDER BY clauses, they are heavy to process and do not seem to add any value.
If there are indexes on table bbointra\_normalized.entry, try removing these temporarily since it is a heavy process to update the indexes when inserting many rows. | SELECT reads 50 000 rows/s for days never INSERTS | [
"",
"mysql",
"sql",
"database-design",
"database-migration",
""
] |
I have a table in sql database [dbo].[ClockInClockOut] with 3 columns: [UserId], ClockInClockOutTypeId], [CreatedDate]. I need to show the data like
```
UserName CreatedDate TimeIn TimeOut
abc 12/31/2013 13:19:51 13:22:37
xyz 1/31/2013 14:19:51 15:19:51
```
I am doing this i... | You need to join `ClockInClockOut` back to itself for the second of the times, not [union the results](http://en.wikipedia.org/wiki/Union_%28SQL%29#UNION_operator).
I'd do something similar to
```
SELECT
u.UserName,
CONVERT(VARCHAR(20), c1.[CreatedDate], 101) as [Date],
CONVERT(VARCHAR(20), c1.[CreatedDate], 1... | **Test Data**
```
DECLARE @ClockInClockOut TABLE
([UserId] INT, [ClockInClockOutTypeId] SMALLINT, [CreatedDate] DATETIME)
INSERT INTO @ClockInClockOut
VALUES
(1,1,'2013-12-10 09:42:08.603'),
(1,2,'2013-12-10 16:42:08.603'),
(1,1,'2013-12-11 16:42:08.603'),
(1,2,'2013-12-11 18:42:08.603'),
(2,1,'2013-12-12 09:42:08.... | How to use union in sql? | [
"",
"sql",
"join",
"union",
""
] |
Is there a way to input multiple values in a single parameter of a scalar-valued function in SQL Server 2008 R2 and have it filter data by that parameter using both values?
For example I would like to do the following
```
SET @Salesperson='BILL' OR 'MOSES'
SELECT Sum(SalesDollars)
FROM Invoices
WHERE... | You need to use table-valued parameters. Look it up on [technet](http://technet.microsoft.com/en-us/library/bb510489.aspx) or [msdn](http://msdn.microsoft.com/en-us/library/bb675163%28v=vs.110%29.aspx)
Best part of it that your table-valued parameters can have multiple columns.
*Note however that you have to define T... | This could be done this way:
```
SET @Salesperson='BILL,MOSES'
SELECT *
FROM YourTable
WHERE Invoices.Salesperson IN (SELECT * FROM dbo.split(@Salesperson,','))
```
[This is how](https://stackoverflow.com/questions/10581772/how-to-split-a-comma-separated-value-to-columns) you split the values. | Multiple values in a single parameter of a scalar function | [
"",
"sql",
"sql-server",
"parameters",
"filtering",
"user-defined-functions",
""
] |
I have the following job table:
```
job_id | is_full_time | is_short_term
1 | 0 | 0
2 | 0 | 1
3 | 1 | 0
4 | 1 | 1
```
I have the following query and I'm getting results in 4 rows.
```
SELECT is_full_time, is_short_term,
COUNT(CASE ... | In general this template works well for these situations:
```
SELECT SUM(FT_Long) as FT_Long, SUM(FT_Short) AS FT_Short, SUM(PT_Long) AS PT_Long, SUM(PT_Short) AS PT_Short
FROM
(
SELECT is_full_time, is_short_term,
COUNT(CASE WHEN is_full_time = 1 AND is_short_term = 0 THEN 1 ELSE NULL END) AS FT_Long,
COUNT(C... | You can safely remove the `GROUP BY` and `SUM` the row instead of counting them
```
SELECT
SUM(CASE WHEN is_full_time = 1 AND is_short_term = 0 THEN 1 ELSE NULL END) AS FT_Long,
SUM(CASE WHEN is_full_time = 1 AND is_short_term = 1 THEN 1 ELSE NULL END) AS FT_Short,
SUM(CASE WHEN is_full_time = 0 AND is_sh... | SQL Group By - Return results as Single Row instead of Multiple (Flatten results) | [
"",
"sql",
"group-by",
"flatten",
""
] |
```
DELETE FROM Table1
INNER JOIN View1 ON Table1.ID = View1.ID
WHERE Table1.ID = View1.ID;
```
error is SQL command not ended properly | How you do this depends on the dialect of SQL. Here is a method that should work in any database:
```
DELETE FROM Table1
WHERE Table1.Id in (select Id from View1);
``` | Specify the table where you want to delete the records,
```
DELETE Table1 -- <== this will delete records from Table1
FROM Table1
INNER JOIN Table2 ON Table1.ID = Table2.ID
WHERE Table1.ID = Table2.ID;
``` | How to delete a row from a table using a join SQL | [
"",
"sql",
""
] |
I have the following database structure:
```
FieldID|Year|Value
a|2011|sugar
a|2012|salt
a|2013|pepper
b|2011|pepper
b|2012|pepper
b|2013|pepper
c|2011|sugar
c|2012|salt
c|2013|salt
```
now I would like to run a query that counts the number of fields for every item in the particular year looking something like this:
... | A1ex07's answer is fine. However, in MySQL, I prefer this formulation:
```
SELECT Value,
sum(`Year` = 2011) AS cnt2011,
sum(`Year` = 2012) AS cnt2012,
sum(`Year` = 2013) AS cnt2013
FROM t
GROUP BY value;
```
The use of `count( . . . )` produces the correct answer, but only because the `els... | You can do pivoting :
```
SELECT `Value`,
COUNT(CASE WHEN `Year` = 2011 THEN FieldID END) AS cnt2011,
COUNT(CASE WHEN `Year` = 2012 THEN FieldID END) AS cnt2012,
COUNT(CASE WHEN `Year` = 2013 THEN FieldID END) AS cnt2013
FROM `Table`
GROUP BY `Value`
``` | mysql query split column into m | [
"",
"mysql",
"sql",
""
] |
Postgres 8.4 and greater databases contain common tables in `public` schema and company specific tables in `company` schema.
`company` schema names always start with `'company'` and end with the company number.
So there may be schemas like:
```
public
company1
company2
company3
...
companynn
```
An application al... | It depends on what you want to test ***exactly***.
### Information schema?
To find "whether the table exists" (*no matter who's asking*), querying the information schema (`information_schema.tables`) is **incorrect**, strictly speaking, because ([per documentation](https://www.postgresql.org/docs/current/infoschema-t... | Perhaps use [information\_schema](http://www.postgresql.org/docs/8.4/interactive/infoschema-tables.html):
```
SELECT EXISTS(
SELECT *
FROM information_schema.tables
WHERE
table_schema = 'company3' AND
table_name = 'tableincompany3schema'
);
``` | How to check if a table exists in a given schema | [
"",
"sql",
"database",
"postgresql",
"information-schema",
"search-path",
""
] |
I am trying to write a select statement with a right join (to clients), that will find a specific value in the join table - but ONLY if that is the most recent value for each client (ignoring blanks and nulls).
```
Clients
Id Name
0 John Doe
1 Frank Smith
2 Sue Smith
3 John Smith
... | Please try this
```
SELECT activity.id AS activityid
, activity.type
, activity.date
, clients.id AS clientid
, clients.name
FROM activity
LEFT JOIN activity AS other_activities
ON activity.ClientID = other_activities.ClientID
AND activity.date < other_activities.date
LEFT JOIN clients
ON acti... | This will get you the most recent Activity of type 500 and the client of that activity
```
SELECT * FROM
(SELECT *
FROM activity
WHERE type=500
ORDER BY date DESC
LIMIT 1) a
LEFT JOIN
clients c
ON (a.clientid = c.id)
```
of if you only want the result if it's the most recent activity and ... | mySQL Query - select join if latest record in join table contains a specific value | [
"",
"mysql",
"sql",
"join",
""
] |
I'm using SQL Server 2008. I have a problem where I need to get the top 2 records in a group determined by 2 columns `Code` and `Period`, that will then be inserted to another table.
Here is a sample table:
```
Code | Period | Dept | DeptWorkPartSum
001 2013-11 D1 53
001 2013-11 D2 33
0... | A simple approach is using a `CTE` with `ROW_NUMBER` ranking function:
```
WITH CTE AS
(
SELECT Code,Period,Dept,DeptWorkPartSum,
RN = ROW_NUMBER() OVER (PARTITION BY Code,Period, Dept
ORDER BY DeptWorkPartSum)
FROM dbo.TableName
)
SELECT Code,Period,Dept,DeptWorkP... | ```
SELECT Code, Period, Dept, DeptWorkPartSum
FROM (
SELECT Code, Period, Dept, DeptWorkPartSum
,ROW_NUMBER ( ) OVER ( PARTITION BY Code, Period, Dept ORDER BY DeptWorkPartSum DESC) r
FROM table) q
WHERE r <= 2
``` | SQL Server : how to select top 2 records of the same group? | [
"",
"sql",
"sql-server",
"sql-server-2008",
""
] |
I have these three statements:
```
select count (distinct vid) as SUM_OF_SEC from pdalis where pid in(500,504);
select sum (amount*paidperitem) SUM_OF_A from pdalis where pid = 501 ;
select sum(amount * paidperitem) SUM_OF_P from pdalis where pid IN (500,504);
```
How do i combine all of them into 3 side by side colu... | Try This by Subquery
```
select count (distinct vid) as SUM_OF_SEC ,(select sum (amount*paidperitem) from pdalis where pid = 501 ;) AS SUM_OF_A , (select sum(amount * paidperitem) from pdalis where pid IN (500,504);) as SUM_OF_P from pdalis where pid in(500,504);
``` | Try like this.
```
SELECT TMP1.SUM_OF_SEC, TMP2.SUM_OF_A, TMP3.SUM_OF_P FROM
(select count (distinct vid) as SUM_OF_SEC from pdalis where pid in(500,504)) AS TMP1,
(select sum (amount*paidperitem) as SUM_OF_A from pdalis where pid = 501 ) AS TMP2,
(select sum(amount * paidperitem) as SUM_OF_P from pdalis where pid IN... | How do i combine multiple select statements in separate columns? | [
"",
"sql",
"join",
""
] |
I have a question that I'm hoping you can help with. I've been trying to think of a way to display data in a manner that I'm looking for, without much success. Basically, the data is laid out as follows:
example of data:
```
UID | Name | Action | Parent_UID | Date | Category | Item
1 | John | Delete ... | There were a few issues:
* [`UID`](http://docs.oracle.com/cd/E11882_01/server.112/e26088/functions223.htm#SQLRF06153) is a system function which uniquely identifies the session user - if you want to use it as a column name then you have to enclose it in double quotes `""`;
* `DATE` is a datatype and is a [reserved wor... | I think you need to change your connect by to be
CONNECT BY UID=PRIOR PARENT\_UID
also check that indexes exist
For these fields. One on uud+parent\_uid
Should do the trick
Also to show hierarcy in your results you can use the
Level in your select list which will show the depth. | Hierarchial SQL Query in Oracle | [
"",
"sql",
"oracle",
""
] |
I have one table, structure is given below:-
```
Where i_status means
i_status 0 = Active
i_status 1 = Archived
i_status 2 = Deleted
and fk_replaced_by_id contains the active records id that will be considered parent record.
Table structure is
id--completion_date--i_status--fk_replaced_by_id
1 --15-Dec-2013 --0 ... | First, to force all "DELETED" records at the end (and this is not supporting deleted with parent reference), do a case/when... or with MySQL an IF() in this case
if( i\_status = 2, 2, 1 )
Stating if the i\_status = 2 (deleted), I want all of them sorted in SECOND GROUP, everything else goes in FIRST GROUP.
Now, to h... | Try to order by parent, than statuses and date in the last, like this:
```
SELECT *
FROM assessments
ORDER BY i_status ASC, fk_replaced_by_id ASC, i_completion_date DESC
```
I don't know what is your parent column, you don't tell us. | MySql Query - Need 'ORDER BY' option for conditions based | [
"",
"mysql",
"sql",
""
] |
Given a table like this:
```
SESS_CODE YEAR Count ID
---- ---- ---- ----
D 2014 1 51
W 2014 1 51
2014 2 51
O 2014 1 52
W 2014 1 52
2014 2 52
D 2014 2 53
O ... | [SQL Fiddle](http://sqlfiddle.com/#!4/e3ade/10)
**Oracle 11g R2 Schema Setup**:
```
CREATE TABLE Data ( SESS_CODE, YEAR, "Count", ID ) AS
SELECT 'D', 2014, 1, 51 FROM DUAL
UNION ALL SELECT 'W', 2014, 1, 51 FROM DUAL
UNION ALL SELECT NULL, 2014, 2, 51 F... | Try this:
```
select *
from Table T1
where SESS_CODE = 'D'
and not exists (select *
from Table T2
where T1.Id = T2.Id
and T2.SESS_CODE != 'D')
``` | Select rows where a certain value doesn't exist | [
"",
"sql",
"oracle",
"select",
""
] |
Im writing a database for some kind of university and there is a table named
> Contact\_Assign
> Its parameters are:
```
Is_Instructor UD_BOOLEAN NOT NULL,
Is_TeacherAssistant UD_BOOLEAN NOT NULL,
Is_Student UD_BOOLEAN NOT NULL,
Registration_ID UD_ID NOT NULL,
Contact_ID UD_ID NO... | If you are only generating one row, you could use something as simple as:
```
SELECT CAST(ROUND(RAND(),0) AS BIT)
```
However, if you are generating more than one row, `RAND()` will evaluate to the same value for every row, so please see [Martin Smith's answer](https://stackoverflow.com/a/20597328/61305). | You can use
```
CRYPT_GEN_RANDOM(1) % 2
```
The advantages over `RAND` are that it is stronger cryptographically (you may not care) and that if inserting multiple rows it is re-evaluated for each row.
```
DECLARE @T TABLE(
B1 BIT,
B2 BIT);
INSERT INTO @T
SELECT TOP 10 CRYPT_GEN_RANDOM(1)%2,
CAST(R... | How to generate random boolean value in sql server 2008? | [
"",
"sql",
"sql-server",
"sql-server-2008-r2",
""
] |
this is my first time posting here and I am a basic SQL user and need help.
I have a `varchar` column that stores data like below:
```
Year.Docid
2007.000000001
2007.000000002
2007.000000003
2007.000000004
2007.000000005
2007.000000006
```
I need to join this data to another table that does not have all the zeros af... | If the format is fixed, i.e. `YYYY.NNNNNNNNN`, you could just get the last 9 characters, convert them to `int`, convert the result back to `varchar` and concatenate back to the first 5 characters:
```
LEFT([Year.Docid], 5) + CAST(CAST(RIGHT([Year.Docid], 9) AS int) AS varchar(10))
```
However, it would make more sens... | To turn the long format into the short format:
```
SELECT LEFT('2007.000000001',5) + CAST(CAST(RIGHT('2007.000000001',LEN('2007.000000001')-5) AS int)AS VARCHAR)
```
...
To use that in a join:
```
SELECT
...
FROM
TABLE_1 T1
INNER JOIN TABLE_2 T2
ON LEFT(T1.pk,5) + CAST(CAST(RIGHT(T1.pk,LEN(T1.pk)-5) AS int... | I need to remove leading zeros after a decimal point | [
"",
"sql",
"sql-server",
"t-sql",
"sql-server-2012",
""
] |
I'm creating a website for my and am struggling with the SQL parts, below are two separate statements I am struggling with, if you know what could be the problem with any of them id appreciate it.
This is the statement
```
readsql = "SELECT * FROM Gallery WHERE <%=GalleryRs ("img_USERID")%> = <%=session ("usr_ID")%>"... | Try
```
readsql = "SELECT * FROM Gallery WHERE "& GalleryRs("img_USERID")&" = "& session("usr_ID")
```
<%= %> makes no sense within an asp code block. It's for when you want to embed an asp variable within your html code - the "=" sign is shorthand for Response.Write - eg
```
<h1><%= pagetitle %></h1>
```
Also note... | Your select sql should look like this when it gets to the database:
```
select *
from Gallery
where img_UserId = something
```
You are sending:
```
select *
from Gallery
where <%= etc
```
Your field name does not include <%. Look at why you are using a variable there. Unless the field in your where clause is not t... | SQL with asp classic | [
"",
"sql",
"ms-access",
"asp-classic",
""
] |
EDIT after @NealB solution: the @NealB's solution is very very fast comparated with [any another one](https://stackoverflow.com/q/18033115#answers), and **dispenses this new question about "add a constraint to improve performance"**. The @NealB's not need any improve, have *O(n)* time and is very simple.
---
The prob... | An SQL only soulution appears to be a bit of a problem here. With the help of some procedural
programming on top of SQL the solution appears to be failry simple and efficient. Here is a brief outline
of a solution as could be implemented using any procedural language invoking SQL.
Declare table `R` with primary key `I... | I suggest you check this and use some
general-purpose language for solving it.
<http://en.wikipedia.org/wiki/Disjoint-set_data_structure>
Traverse the graph, maybe run DFS or BFS from each node,
then use this disjoint set hint. I think this should work. | How to label a big set of “transitive groups” with a constraint? | [
"",
"sql",
"algorithm",
""
] |
Given different machines with sql server. All of them have the same databases. The only difference between these db's is their name. It could be two names, let's say 'DB1' and 'DB2'.
I need to check, which name is used on the given machine and create a function over it. The function is pretty big, it has at least 50 s... | No, that won't work. With only two possible database you may be better off with an `if`:
```
DECLARE @dbName VARCHAR(20)
SET @dbName = CASE WHEN DB_ID('DB1') IS NULL THEN 'DB2' ELSE 'DB1' END;
IF @dbName = 'DB1'
SELECT * FROM DB1.dbo.testtable;
ELSE
SELECT * FROM DB2.dbo.testtable;
```
If you want to run AL... | You can use dynamic SQL:
```
DECLARE @dbName VARCHAR(20)
SET @dbName = 'DB2'
IF DB_ID('DB1') IS NOT NULL
SET @dbName = 'DB1'
DECLARE @SQL NVARCHAR(100)
SET @SQL = N'SELECT * FROM ' + @dbName + N'.dbo.testtable'
EXEC sp_executesql @SQL
``` | How to check which database exists and use it in the function? | [
"",
"sql",
"sql-server",
"database",
""
] |
I've been using Toad for more than a year now without problems. All of a sudden the table autocomplete feature has ceased working. No settings have been changed, and I've clean installed a new TOAD version, yet the problem persists.
The image below shows autocomplete defaulting into view IN\_INSTRUMENT in schema MCDM.... | I've found the solution to this problem. The issue was a corrupt configuration file. For anyone else with the same problem, this is how I fixed mine:
1. Backup your *appdata* folder - you can find its location in *options -> general -> application data*.
2. Create a new set of user files using *Utilities -> Copy User ... | Under View > Toad Options > Editor > Code Assist > Toad Insight Objects, checking Synonyms (in addition to Public Synonyms) worked for me. | Toad: Table Autocomplete Functionality Not Working | [
"",
"sql",
"oracle",
"autocomplete",
"toad",
"code-assist",
""
] |
Such a query as in the title would look like this I guess:
```
select * from table t where (t.k1='apple' and t.k2='pie') or (t.k1='strawberry' and t.k2='shortcake')
... --10000 more key pairs here
```
This looks quite verbose to me. Any better alternatives? (Currently using SQLite, might use MYSQL/Oracle.) | You can use for example this on Oracle, i assume that if you use regular concatenate() instead of Oracle's || on other DB, it would work too (as it is simply just a string comparison with the IN list). Note that such query might have suboptimal execution plan.
```
SELECT *
FROM
TABLE t
WHERE
t.k1||','||t.k2 IN ('a... | Don't be afraid of verbose syntax. Concatenation tricks can easily mess up the selectivity estimates or even prevent the database from using indexes.
Here is another syntax that may or may not work in your database.
```
select *
from table t
where (k1, k2) in(
('apple', 'pie')
,('stra... | One select for multiple records by composite key | [
"",
"sql",
""
] |
i have list of 100 students with there total marks and names.Based on this mark give rank to each students.
i need to find the names of those students whose rank between 10th rank to 20th rank.
students having rank 10,11,12...20 in the ascending order. | Try this:
```
SELECT studentName FROM studentTable ORDER BY totalMarks DESC LIMIT 10, 10;
``` | try this:
```
SELECT <name> FROM <tablename>
WHERE <rankfieldname> BETWEEN 10 AND 20
``` | sql query to get the student name with rank between 10 and 20 out of 100 students? | [
"",
"mysql",
"sql",
"select",
"limit",
"ranking",
""
] |
I have a trouble with joining three SQL tables. For simply think there are 3 table called A, B and C. the table A contains data about attendance such as shift id, date. Other two tables contain data of each shift such as in time, out time. Data of a particular shift can be only included in one table.
table A
```
shif... | I think `UNION` could help you.
```
SELECT 'FROM A', A.shift_id, B.in_time, B.out_time
FROM A INNER JOIN B ON A.shift_id = B.shift_id
UNION ALL
SELECT 'FROM B', A.shift_id, C.in_time, '00:00'
FROM A INNER JOIN C ON A.shift_id = C.shift_id
``` | Assuming shift\_id is foreign key for table B and C, i.e. you don't need to verify if shift\_id is present in table A
```
SELECT
shift_id, in_time, out_time
FROM
B
UNION
SELECT
shift_id, in_time,'00:00' as out_time
FROM
C
```
else
```
SELECT
shift_id, in_time, out_time
FROM
B WHERE... | SQL joining three tables | [
"",
"mysql",
"sql",
""
] |

I try to get this query to work.
It seems to work until I join the albums table, when all of the data disappears.
Can someone please explain?

 and the 1NF in the process. On top of that, your key is not minimal (so to speak).
Instead, keep two separate fields: ID and CITY.
ID **alone** is the primary key. In your own words, ... | That is not good database design. You really should have a separate column for the city in your table. If you have many cities, the cities should perhaps be in their own table. What you are trying to do is overly complex and although 'everything is possible', I would not recommend it. | Autoincrement ID with a prefix | [
"",
"mysql",
"sql",
"database-design",
""
] |
I have two tables. `T1` has `t1field1` and `t1field2`, and `T2` has `t2field1` and `t2field2`.
I want to remove all records from `T2`, if `t2field1` value does not exist in `t1field1`
```
+----------+----------+
| t1field1 | t1field2 |
+----------+----------+
| 1 | x |
| 5 | y |
| 6 ... | Try this:
```
DELETE t2
FROM t2 LEFT JOIN t1 ON t1.t1field1 = t2.t2field1
WHERE t1.t1field1 IS NULL
```
**OR**
```
DELETE FROM t2 WHERE t2.t2field1 NOT IN (SELECT t1.t1field1 FROM t1)
``` | ```
delete t2
from t2
left join t1 on t1.t1field1 = t2.field1
where t1.field1 is null
``` | Remove records from table, if its specific value does not appears in another table | [
"",
"mysql",
"sql",
"join",
"sql-delete",
"notin",
""
] |
I am very new to SQL. I have done some basic "select from where ..." queries but I struggle with my current project.
Lets say this is my source table:
```
Project Involved
1 Harald
1 Kerstin
1 Peter
1 Christian
1 Lisa
1 Linda
2 Sören
2 ... | You can solve this in many ways, but here is the primary way I would solve it... but start simply for what projects LISA is associated with... This prevents looking at what could be 1000s of projects / people but if Lisa is only associated with 5 (or 2 in this case), why query against all of them..
```
Select
p1... | I've named table as person, so this is the example
```
SELECT
p1.project
FROM
person p1,
person p2
WHERE
p1.name = 'Harald'
AND p2.name = 'Lisa'
AND p1.project = p2.project
``` | Beginner Help: Looking for Member Names in diffrent projects to see in which projects they are working together | [
"",
"mysql",
"sql",
"database",
""
] |
I saw some people here have kind the same problem that I have now... but nothing has helped me with :/
I've a table Test with 2 columns. A date and an integer value.
And I need the average every N records.
For instance
```
Date | Info
2013-01-01 | 210
2013-01-02 | 213
2013-01-03 | 214
2013-01-05 | 197
... | [SQLFiddle](http://sqlfiddle.com/#!2/fd2ff/16/0)
```
SELECT date,info,(select avg(info) from
(select date,info,@row1:=@row1+1 as row
from test,(SELECT @row1:=0)r
order by date desc
)wrn1
where wrn1.row between wrn2.start and wr... | You can use a correlated subquery for this. If you want up to `n` days including and after the current date, then this will work:
```
select date, info,
(select avg(t2.info)
from test t2
where datediff(t.date, t2.date) < n and
t2.date >= t.date
) as avginfo
from test t;
```
... | Get the average of each N groups | [
"",
"mysql",
"sql",
"group-by",
"average",
""
] |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.