
html_url stringlengths 51 51 | title stringlengths 9 280 | comments stringlengths 63 24.7k | body stringlengths 51 58.6k | comments length int64 16 1.45k | text stringlengths 186 59.1k |
|---|---|---|---|---|---|
https://github.com/huggingface/datasets/issues/5833 | Unable to push dataset - `create_pr` problem | Based on the number of reactions (https://github.com/huggingface/datasets/issues/5833#issuecomment-1586521001), many users have issues debugging this. @Wauplin Maybe a more informative error can be thrown in `hfh` if a token's role is insufficient for an op. WDYT? | ### Describe the bug
I can't upload to the hub the dataset I manually created locally (Image dataset). I have a problem when using the method `.push_to_hub` which asks for a `create_pr` attribute which is not compatible.
### Steps to reproduce the bug
here what I have:
```python
dataset.push_to_hub("agomberto/Fr... | 34 | Unable to push dataset - `create_pr` problem
### Describe the bug
I can't upload to the hub the dataset I manually created locally (Image dataset). I have a problem when using the method `.push_to_hub` which asks for a `create_pr` attribute which is not compatible.
### Steps to reproduce the bug
here what I have:
... |
https://github.com/huggingface/datasets/issues/5833 | Unable to push dataset - `create_pr` problem | Yes indeed. I created an issue some time ago about it: https://github.com/huggingface/huggingface_hub/issues/1653. I'll prioritize it more and let you know. Thanks for the ping. | ### Describe the bug
I can't upload to the hub the dataset I manually created locally (Image dataset). I have a problem when using the method `.push_to_hub` which asks for a `create_pr` attribute which is not compatible.
### Steps to reproduce the bug
here what I have:
```python
dataset.push_to_hub("agomberto/Fr... | 24 | Unable to push dataset - `create_pr` problem
### Describe the bug
I can't upload to the hub the dataset I manually created locally (Image dataset). I have a problem when using the method `.push_to_hub` which asks for a `create_pr` attribute which is not compatible.
### Steps to reproduce the bug
here what I have:
... |
https://github.com/huggingface/datasets/issues/5833 | Unable to push dataset - `create_pr` problem | Hey everyone :wave: The error message has been fixed to be more informative. As mentioned in https://github.com/huggingface/datasets/issues/5833#issuecomment-1586521001, the n°1 reason why this is happening is that a `read` token has been used instead of `write`. The fix has being shipped on the server meaning that you... | ### Describe the bug
I can't upload to the hub the dataset I manually created locally (Image dataset). I have a problem when using the method `.push_to_hub` which asks for a `create_pr` attribute which is not compatible.
### Steps to reproduce the bug
here what I have:
```python
dataset.push_to_hub("agomberto/Fr... | 100 | Unable to push dataset - `create_pr` problem
### Describe the bug
I can't upload to the hub the dataset I manually created locally (Image dataset). I have a problem when using the method `.push_to_hub` which asks for a `create_pr` attribute which is not compatible.
### Steps to reproduce the bug
here what I have:
... |
https://github.com/huggingface/datasets/issues/5833 | Unable to push dataset - `create_pr` problem | @Wauplin Reopening it. Indeed, the above error message is thrown if pushing to an **existing** repo with a `read` token. However, if the repo does not exist and needs to be created (by calling `create_repo` in `push_to_hub`), then passing a `read` token will raise the following:
```python
HTTPError: 403 Client Error:... | ### Describe the bug
I can't upload to the hub the dataset I manually created locally (Image dataset). I have a problem when using the method `.push_to_hub` which asks for a `create_pr` attribute which is not compatible.
### Steps to reproduce the bug
here what I have:
```python
dataset.push_to_hub("agomberto/Fr... | 140 | Unable to push dataset - `create_pr` problem
### Describe the bug
I can't upload to the hub the dataset I manually created locally (Image dataset). I have a problem when using the method `.push_to_hub` which asks for a `create_pr` attribute which is not compatible.
### Steps to reproduce the bug
here what I have:
... |
https://github.com/huggingface/datasets/issues/5833 | Unable to push dataset - `create_pr` problem | > However, if the repo does not exist and needs to be created (by calling create_repo in push_to_hub), then passing a read token will raise the following:
This seems to be a different issue than the one reported above right? Still agree that a more informative message would be nice. Can you open an issue on moon-lan... | ### Describe the bug
I can't upload to the hub the dataset I manually created locally (Image dataset). I have a problem when using the method `.push_to_hub` which asks for a `create_pr` attribute which is not compatible.
### Steps to reproduce the bug
here what I have:
```python
dataset.push_to_hub("agomberto/Fr... | 73 | Unable to push dataset - `create_pr` problem
### Describe the bug
I can't upload to the hub the dataset I manually created locally (Image dataset). I have a problem when using the method `.push_to_hub` which asks for a `create_pr` attribute which is not compatible.
### Steps to reproduce the bug
here what I have:
... |
https://github.com/huggingface/datasets/issues/4936 | vivos (Vietnamese speech corpus) dataset not accessible | If you need an example of a small audio datasets, I just created few hours ago a speech dataset with only 300MB of compressed audio files https://huggingface.co/datasets/indonesian-nlp/librivox-indonesia. It works also with streaming (@albertvillanova helped me adding this functionality) :-) | ## Describe the bug
VIVOS data is not accessible anymore, neither of these links work (at least from France):
* https://ailab.hcmus.edu.vn/assets/vivos.tar.gz (data)
* https://ailab.hcmus.edu.vn/vivos (dataset page)
Therefore `load_dataset` doesn't work.
## Steps to reproduce the bug
```python
ds = load_dat... | 39 | vivos (Vietnamese speech corpus) dataset not accessible
## Describe the bug
VIVOS data is not accessible anymore, neither of these links work (at least from France):
* https://ailab.hcmus.edu.vn/assets/vivos.tar.gz (data)
* https://ailab.hcmus.edu.vn/vivos (dataset page)
Therefore `load_dataset` doesn't work.
... |
https://github.com/huggingface/datasets/issues/3621 | Consider adding `ipywidgets` as a dependency. | Hi! We use `tqdm` to display progress bars, so I suggest you open this issue in their repo. | When I install `datasets` in a fresh virtualenv with jupyterlab I always see this error.
```
ImportError: IProgress not found. Please update jupyter and ipywidgets. See https://ipywidgets.readthedocs.io/en/stable/user_install.html
```
It's a bit of a nuisance, because I need to run shut down the jupyterlab ser... | 18 | Consider adding `ipywidgets` as a dependency.
When I install `datasets` in a fresh virtualenv with jupyterlab I always see this error.
```
ImportError: IProgress not found. Please update jupyter and ipywidgets. See https://ipywidgets.readthedocs.io/en/stable/user_install.html
```
It's a bit of a nuisance, beca... |
https://github.com/huggingface/datasets/issues/3621 | Consider adding `ipywidgets` as a dependency. | It depends on how you use `tqdm`, no?
Doesn't this library import via;
```
from tqdm.notebook import tqdm
``` | When I install `datasets` in a fresh virtualenv with jupyterlab I always see this error.
```
ImportError: IProgress not found. Please update jupyter and ipywidgets. See https://ipywidgets.readthedocs.io/en/stable/user_install.html
```
It's a bit of a nuisance, because I need to run shut down the jupyterlab ser... | 19 | Consider adding `ipywidgets` as a dependency.
When I install `datasets` in a fresh virtualenv with jupyterlab I always see this error.
```
ImportError: IProgress not found. Please update jupyter and ipywidgets. See https://ipywidgets.readthedocs.io/en/stable/user_install.html
```
It's a bit of a nuisance, beca... |
https://github.com/huggingface/datasets/issues/3621 | Consider adding `ipywidgets` as a dependency. | Hi! Sorry for the late reply. We import `tqdm` as `from tqdm.auto import tqdm`, which should be equal to `from tqdm.notebook import tqdm` in Jupyter. | When I install `datasets` in a fresh virtualenv with jupyterlab I always see this error.
```
ImportError: IProgress not found. Please update jupyter and ipywidgets. See https://ipywidgets.readthedocs.io/en/stable/user_install.html
```
It's a bit of a nuisance, because I need to run shut down the jupyterlab ser... | 25 | Consider adding `ipywidgets` as a dependency.
When I install `datasets` in a fresh virtualenv with jupyterlab I always see this error.
```
ImportError: IProgress not found. Please update jupyter and ipywidgets. See https://ipywidgets.readthedocs.io/en/stable/user_install.html
```
It's a bit of a nuisance, beca... |
https://github.com/huggingface/datasets/issues/3621 | Consider adding `ipywidgets` as a dependency. | Any objection if I make a PR that checks if the widgets library is installed beforehand? | When I install `datasets` in a fresh virtualenv with jupyterlab I always see this error.
```
ImportError: IProgress not found. Please update jupyter and ipywidgets. See https://ipywidgets.readthedocs.io/en/stable/user_install.html
```
It's a bit of a nuisance, because I need to run shut down the jupyterlab ser... | 16 | Consider adding `ipywidgets` as a dependency.
When I install `datasets` in a fresh virtualenv with jupyterlab I always see this error.
```
ImportError: IProgress not found. Please update jupyter and ipywidgets. See https://ipywidgets.readthedocs.io/en/stable/user_install.html
```
It's a bit of a nuisance, beca... |
https://github.com/huggingface/datasets/issues/5305 | Dataset joelito/mc4_legal does not work with multiple files | Thanks for reporting @JoelNiklaus.
Please note that since we moved all dataset loading scripts to the Hub, the issues and pull requests relative to specific datasets are directly handled on the Hub, in their Community tab. I'm transferring this issue there: https://huggingface.co/datasets/joelito/mc4_legal/discussio... | ### Describe the bug
The dataset https://huggingface.co/datasets/joelito/mc4_legal works for languages like bg with a single data file, but not for languages with multiple files like de. It shows zero rows for the de dataset.
joelniklaus@Joels-MacBook-Pro ~/N/P/C/L/p/m/mc4_legal (main) [1]> python test_mc4_legal.... | 54 | Dataset joelito/mc4_legal does not work with multiple files
### Describe the bug
The dataset https://huggingface.co/datasets/joelito/mc4_legal works for languages like bg with a single data file, but not for languages with multiple files like de. It shows zero rows for the de dataset.
joelniklaus@Joels-MacBook-Pr... |
https://github.com/huggingface/datasets/issues/6787 | TimeoutError in map | From my current understanding, this timeout is only used when we need to get the results.
One of:
1. All tasks are done
2. One worker died
Your function should work fine and it's definitely a bug if it doesn't. | ### Describe the bug
```python
from datasets import Dataset
def worker(example):
while True:
continue
example['a'] = 100
return example
data = Dataset.from_list([{"a": 1}, {"a": 2}])
data = data.map(worker)
print(data[0])
```
I'm implementing a worker function whose runtime will de... | 40 | TimeoutError in map
### Describe the bug
```python
from datasets import Dataset
def worker(example):
while True:
continue
example['a'] = 100
return example
data = Dataset.from_list([{"a": 1}, {"a": 2}])
data = data.map(worker)
print(data[0])
```
I'm implementing a worker function w... |
https://github.com/huggingface/datasets/issues/6787 | TimeoutError in map | When one of the `map`'s worker processes crashes, the linked code re-raises an error from the crash and returns it to the caller.
If your question is how to limit the time of long-running tasks/worker processes, such functionality doesn't exist in `datasets` (yet), which means you need to implement it yourself.
E... | ### Describe the bug
```python
from datasets import Dataset
def worker(example):
while True:
continue
example['a'] = 100
return example
data = Dataset.from_list([{"a": 1}, {"a": 2}])
data = data.map(worker)
print(data[0])
```
I'm implementing a worker function whose runtime will de... | 152 | TimeoutError in map
### Describe the bug
```python
from datasets import Dataset
def worker(example):
while True:
continue
example['a'] = 100
return example
data = Dataset.from_list([{"a": 1}, {"a": 2}])
data = data.map(worker)
print(data[0])
```
I'm implementing a worker function w... |
https://github.com/huggingface/datasets/issues/6787 | TimeoutError in map | > From my current understanding, this timeout is only used when we need to get the results.
>
> One of:
>
> 1. All tasks are done
> 2. One worker died
>
> Your function should work fine and it's definitely a bug if it doesn't.
thanks for responding! can you reproduce the stuck with the above example code? | ### Describe the bug
```python
from datasets import Dataset
def worker(example):
while True:
continue
example['a'] = 100
return example
data = Dataset.from_list([{"a": 1}, {"a": 2}])
data = data.map(worker)
print(data[0])
```
I'm implementing a worker function whose runtime will de... | 61 | TimeoutError in map
### Describe the bug
```python
from datasets import Dataset
def worker(example):
while True:
continue
example['a'] = 100
return example
data = Dataset.from_list([{"a": 1}, {"a": 2}])
data = data.map(worker)
print(data[0])
```
I'm implementing a worker function w... |
https://github.com/huggingface/datasets/issues/6787 | TimeoutError in map | > When one of the `map`'s worker processes crashes, the linked code re-raises an error from the crash and returns it to the caller.
>
> If your question is how to limit the time of long-running tasks/worker processes, such functionality doesn't exist in `datasets` (yet), which means you need to implement it yourself... | ### Describe the bug
```python
from datasets import Dataset
def worker(example):
while True:
continue
example['a'] = 100
return example
data = Dataset.from_list([{"a": 1}, {"a": 2}])
data = data.map(worker)
print(data[0])
```
I'm implementing a worker function whose runtime will de... | 224 | TimeoutError in map
### Describe the bug
```python
from datasets import Dataset
def worker(example):
while True:
continue
example['a'] = 100
return example
data = Dataset.from_list([{"a": 1}, {"a": 2}])
data = data.map(worker)
print(data[0])
```
I'm implementing a worker function w... |
https://github.com/huggingface/datasets/issues/6787 | TimeoutError in map | > thanks for responding! However, I don't think we should use signal in the context of multiprocessing since sometimes it will crash one process and raise the following error
The above code has `try/except` to catch the error from the handler. Or do you get an error other than `TimeoutError`? | ### Describe the bug
```python
from datasets import Dataset
def worker(example):
while True:
continue
example['a'] = 100
return example
data = Dataset.from_list([{"a": 1}, {"a": 2}])
data = data.map(worker)
print(data[0])
```
I'm implementing a worker function whose runtime will de... | 50 | TimeoutError in map
### Describe the bug
```python
from datasets import Dataset
def worker(example):
while True:
continue
example['a'] = 100
return example
data = Dataset.from_list([{"a": 1}, {"a": 2}])
data = data.map(worker)
print(data[0])
```
I'm implementing a worker function w... |
https://github.com/huggingface/datasets/issues/6787 | TimeoutError in map | > > thanks for responding! However, I don't think we should use signal in the context of multiprocessing since sometimes it will crash one process and raise the following error
>
> The above code has `try/except` to catch the error from the handler. Or do you get an error other than `TimeoutError`?
yup, it will r... | ### Describe the bug
```python
from datasets import Dataset
def worker(example):
while True:
continue
example['a'] = 100
return example
data = Dataset.from_list([{"a": 1}, {"a": 2}])
data = data.map(worker)
print(data[0])
```
I'm implementing a worker function whose runtime will de... | 81 | TimeoutError in map
### Describe the bug
```python
from datasets import Dataset
def worker(example):
while True:
continue
example['a'] = 100
return example
data = Dataset.from_list([{"a": 1}, {"a": 2}])
data = data.map(worker)
print(data[0])
```
I'm implementing a worker function w... |
https://github.com/huggingface/datasets/issues/6075 | Error loading music files using `load_dataset` | This code behaves as expected on my local machine or in Colab. Which version of `soundfile` do you have installed? MP3 requires `soundfile>=0.12.1`. | ### Describe the bug
I tried to load a music file using `datasets.load_dataset()` from the repository - https://huggingface.co/datasets/susnato/pop2piano_real_music_test
I got the following error -
```
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
File "/home/susnato/anaconda3/en... | 23 | Error loading music files using `load_dataset`
### Describe the bug
I tried to load a music file using `datasets.load_dataset()` from the repository - https://huggingface.co/datasets/susnato/pop2piano_real_music_test
I got the following error -
```
Traceback (most recent call last):
File "<stdin>", line 1, ... |
https://github.com/huggingface/datasets/issues/4074 | Error in google/xtreme_s dataset card | Hi @wranai, thanks for reporting.
Please note that the information about language families and groups is taken form the original paper: [XTREME-S: Evaluating Cross-lingual Speech Representations](https://arxiv.org/abs/2203.10752).
If that information is wrong, feel free to contact the paper's authors to suggest t... | **Link:** https://huggingface.co/datasets/google/xtreme_s
Not a big deal but Hungarian is considered an Eastern European language, together with Serbian, Slovak, Slovenian (all correctly categorized; Slovenia is mostly to the West of Hungary, by the way).
| 74 | Error in google/xtreme_s dataset card
**Link:** https://huggingface.co/datasets/google/xtreme_s
Not a big deal but Hungarian is considered an Eastern European language, together with Serbian, Slovak, Slovenian (all correctly categorized; Slovenia is mostly to the West of Hungary, by the way).
Hi @wranai, thanks fo... |
https://github.com/huggingface/datasets/issues/4152 | ArrayND error in pyarrow 5 | Where do we bump the required pyarrow version? Any inputs on how I fix this issue? | As found in https://github.com/huggingface/datasets/pull/3903, The ArrayND features fail on pyarrow 5:
```python
import pyarrow as pa
from datasets import Array2D
from datasets.table import cast_array_to_feature
arr = pa.array([[[0]]])
feature_type = Array2D(shape=(1, 1), dtype="int64")
cast_array_to_feature(a... | 16 | ArrayND error in pyarrow 5
As found in https://github.com/huggingface/datasets/pull/3903, The ArrayND features fail on pyarrow 5:
```python
import pyarrow as pa
from datasets import Array2D
from datasets.table import cast_array_to_feature
arr = pa.array([[[0]]])
feature_type = Array2D(shape=(1, 1), dtype="int64... |
https://github.com/huggingface/datasets/issues/4152 | ArrayND error in pyarrow 5 | We need to bump it in `setup.py` as well as update some CI job to use pyarrow 6 instead of 5 in `.circleci/config.yaml` and `.github/workflows/benchmarks.yaml` | As found in https://github.com/huggingface/datasets/pull/3903, The ArrayND features fail on pyarrow 5:
```python
import pyarrow as pa
from datasets import Array2D
from datasets.table import cast_array_to_feature
arr = pa.array([[[0]]])
feature_type = Array2D(shape=(1, 1), dtype="int64")
cast_array_to_feature(a... | 25 | ArrayND error in pyarrow 5
As found in https://github.com/huggingface/datasets/pull/3903, The ArrayND features fail on pyarrow 5:
```python
import pyarrow as pa
from datasets import Array2D
from datasets.table import cast_array_to_feature
arr = pa.array([[[0]]])
feature_type = Array2D(shape=(1, 1), dtype="int64... |
https://github.com/huggingface/datasets/issues/3952 | Checksum error for glue sst2, stsb, rte etc datasets | Hi, @ravindra-ut.
I'm sorry but I can't reproduce your problem:
```python
In [1]: from datasets import load_dataset
In [2]: ds = load_dataset("glue", "sst2")
Downloading builder script: 28.8kB [00:00, 11.6MB/s] ... | ## Describe the bug
Checksum error for glue sst2, stsb, rte etc datasets
## Steps to reproduce the bug
```python
>>> nlp.load_dataset('glue', 'sst2')
Downloading and preparing dataset glue/sst2 (download: 7.09 MiB, generated: 4.81 MiB, post-processed: Unknown sizetotal: 11.90 MiB) to
Downloading: 100%|████████... | 179 | Checksum error for glue sst2, stsb, rte etc datasets
## Describe the bug
Checksum error for glue sst2, stsb, rte etc datasets
## Steps to reproduce the bug
```python
>>> nlp.load_dataset('glue', 'sst2')
Downloading and preparing dataset glue/sst2 (download: 7.09 MiB, generated: 4.81 MiB, post-processed: Unknown ... |
https://github.com/huggingface/datasets/issues/6363 | dataset.transform() hangs indefinitely while finetuning the stable diffusion XL | I think the code hangs on the `accelerator.main_process_first()` context manager exit. To verify this, you can append a print statement to the end of the `accelerator.main_process_first()` block.
If the problem is in `with_transform`, it would help if you could share the error stack trace printed when you interr... | ### Describe the bug
Multi-GPU fine-tuning the stable diffusion X by following https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/README_sdxl.md hangs indefinitely.
### Steps to reproduce the bug
accelerate launch train_text_to_image_sdxl.py --pretrained_model_name_or_path=$MODEL_NAME --... | 53 | dataset.transform() hangs indefinitely while finetuning the stable diffusion XL
### Describe the bug
Multi-GPU fine-tuning the stable diffusion X by following https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/README_sdxl.md hangs indefinitely.
### Steps to reproduce the bug
accelerate l... |
https://github.com/huggingface/datasets/issues/6363 | dataset.transform() hangs indefinitely while finetuning the stable diffusion XL | @mariosasko yes the problem seems to be to exit from accelerator.main_process_first(). Is there any known problem? | ### Describe the bug
Multi-GPU fine-tuning the stable diffusion X by following https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/README_sdxl.md hangs indefinitely.
### Steps to reproduce the bug
accelerate launch train_text_to_image_sdxl.py --pretrained_model_name_or_path=$MODEL_NAME --... | 16 | dataset.transform() hangs indefinitely while finetuning the stable diffusion XL
### Describe the bug
Multi-GPU fine-tuning the stable diffusion X by following https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/README_sdxl.md hangs indefinitely.
### Steps to reproduce the bug
accelerate l... |
https://github.com/huggingface/datasets/issues/6363 | dataset.transform() hangs indefinitely while finetuning the stable diffusion XL | NCCL debug info I get below output, if it helps.
```
11/09/2023 13:36:44 - INFO - __main__ - Distributed environment: MULTI_GPU Backend: nccl
Num processes: 2
Process index: 1
Local process index: 1
Device: cuda:1
Mixed precision type: fp16
Detected kernel version 5.4.0, which is below the recommended mini... | ### Describe the bug
Multi-GPU fine-tuning the stable diffusion X by following https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/README_sdxl.md hangs indefinitely.
### Steps to reproduce the bug
accelerate launch train_text_to_image_sdxl.py --pretrained_model_name_or_path=$MODEL_NAME --... | 620 | dataset.transform() hangs indefinitely while finetuning the stable diffusion XL
### Describe the bug
Multi-GPU fine-tuning the stable diffusion X by following https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/README_sdxl.md hangs indefinitely.
### Steps to reproduce the bug
accelerate l... |
https://github.com/huggingface/datasets/issues/6363 | dataset.transform() hangs indefinitely while finetuning the stable diffusion XL | I don't know what the issue was, but after going through the thread here I loved the issue with https://github.com/huggingface/accelerate/issues/314#issuecomment-1565259831 | ### Describe the bug
Multi-GPU fine-tuning the stable diffusion X by following https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/README_sdxl.md hangs indefinitely.
### Steps to reproduce the bug
accelerate launch train_text_to_image_sdxl.py --pretrained_model_name_or_path=$MODEL_NAME --... | 20 | dataset.transform() hangs indefinitely while finetuning the stable diffusion XL
### Describe the bug
Multi-GPU fine-tuning the stable diffusion X by following https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/README_sdxl.md hangs indefinitely.
### Steps to reproduce the bug
accelerate l... |
https://github.com/huggingface/datasets/issues/6142 | the-stack-dedup fails to generate | It seems that some parquet files have additional columns.
I ran a scan and found that two files have the additional `__id__` column:
1. `hf://datasets/bigcode/the-stack-dedup/data/numpy/data-00000-of-00001.parquet`
2. `hf://datasets/bigcode/the-stack-dedup/data/omgrofl/data-00000-of-00001.parquet`
We should o... | ### Describe the bug
I'm getting an error generating the-stack-dedup with datasets 2.13.1, and with 2.14.4 nothing happens.
### Steps to reproduce the bug
My code:
```
import os
import datasets as ds
MY_CACHE_DIR = "/home/ubuntu/the-stack-dedup-local"
MY_TOKEN="my-token"
the_stack_ds = ds.load_dataset("... | 37 | the-stack-dedup fails to generate
### Describe the bug
I'm getting an error generating the-stack-dedup with datasets 2.13.1, and with 2.14.4 nothing happens.
### Steps to reproduce the bug
My code:
```
import os
import datasets as ds
MY_CACHE_DIR = "/home/ubuntu/the-stack-dedup-local"
MY_TOKEN="my-token"
... |
https://github.com/huggingface/datasets/issues/6142 | the-stack-dedup fails to generate | The files have been fixed ! I'm closing this one but feel free to re-open if you still have the issue | ### Describe the bug
I'm getting an error generating the-stack-dedup with datasets 2.13.1, and with 2.14.4 nothing happens.
### Steps to reproduce the bug
My code:
```
import os
import datasets as ds
MY_CACHE_DIR = "/home/ubuntu/the-stack-dedup-local"
MY_TOKEN="my-token"
the_stack_ds = ds.load_dataset("... | 21 | the-stack-dedup fails to generate
### Describe the bug
I'm getting an error generating the-stack-dedup with datasets 2.13.1, and with 2.14.4 nothing happens.
### Steps to reproduce the bug
My code:
```
import os
import datasets as ds
MY_CACHE_DIR = "/home/ubuntu/the-stack-dedup-local"
MY_TOKEN="my-token"
... |
https://github.com/huggingface/datasets/issues/8075 | `.batch()` error on formatted datasets | Hi ! Good catch :) Since table-formatted iterable datasets have an Arrow path (i.e. they have `.iter_arrow()`) I guess a simple fix would be to make `.batch()` make the dataset arrow-formatted and use a `batch_arrow_fn` in that case (instead of the current `_batch_fn` that expects dictionaries). It would also be better... | The `.batch()` method currently assumes the input (batch) is always a dictionary, which causes errors when it isn't. This can happen with formatted datasets, since formats like `"pyarrow"`, `"pandas"` (only affects `IterableDataset`), and `"polars"` return tables/dataframes instead of dictionaries.
For example:
```pyt... | 57 | `.batch()` error on formatted datasets
The `.batch()` method currently assumes the input (batch) is always a dictionary, which causes errors when it isn't. This can happen with formatted datasets, since formats like `"pyarrow"`, `"pandas"` (only affects `IterableDataset`), and `"polars"` return tables/dataframes instea... |
https://github.com/huggingface/datasets/issues/8075 | `.batch()` error on formatted datasets | Yes, and a similar approach can be used for the `Dataset` case: temporarily switching to the `"arrow"` format, running the batched `.map()` (which should also be much faster since it avoids Python ↔ Arrow conversions), and then restoring the original format. | The `.batch()` method currently assumes the input (batch) is always a dictionary, which causes errors when it isn't. This can happen with formatted datasets, since formats like `"pyarrow"`, `"pandas"` (only affects `IterableDataset`), and `"polars"` return tables/dataframes instead of dictionaries.
For example:
```pyt... | 41 | `.batch()` error on formatted datasets
The `.batch()` method currently assumes the input (batch) is always a dictionary, which causes errors when it isn't. This can happen with formatted datasets, since formats like `"pyarrow"`, `"pandas"` (only affects `IterableDataset`), and `"polars"` return tables/dataframes instea... |
https://github.com/huggingface/datasets/issues/3761 | Know your data for HF hub | Hi @Muhtasham you should take a look at https://huggingface.co/blog/data-measurements-tool and accompanying demo app at https://huggingface.co/spaces/huggingface/data-measurements-tool
We would be interested in your feedback. cc @meg-huggingface @sashavor @yjernite | **Is your feature request related to a problem? Please describe.**
Would be great to see be able to understand datasets with the goal of improving data quality, and helping mitigate fairness and bias issues.
**Describe the solution you'd like**
Something like https://knowyourdata.withgoogle.com/ for HF hub | 26 | Know your data for HF hub
**Is your feature request related to a problem? Please describe.**
Would be great to see be able to understand datasets with the goal of improving data quality, and helping mitigate fairness and bias issues.
**Describe the solution you'd like**
Something like https://knowyourdata.withgoo... |
https://github.com/huggingface/datasets/issues/6675 | Allow image model (color conversion) to be specified as part of datasets Image() decode | It would be a great addition indeed :)
This can be implemented the same way we have `sampling_rate` for Audio(): we just add a new parameter to the Image() type and take this parameter into account in `Image.decode_example`
EDIT: adding an example of how it can be used:
```python
ds = ds.cast_column("image", ... | ### Feature request
Typical torchvision / torch Datasets in image applications apply color conversion in the Dataset portion of the code as part of image decode, separately from the image transform stack. This is true for PIL.Image where convert is usually called in dataset, for native torchvision https://pytorch.or... | 54 | Allow image model (color conversion) to be specified as part of datasets Image() decode
### Feature request
Typical torchvision / torch Datasets in image applications apply color conversion in the Dataset portion of the code as part of image decode, separately from the image transform stack. This is true for PIL.Ima... |
https://github.com/huggingface/datasets/issues/5220 | Implicit type conversion of lists in to_pandas | I think this behavior comes from PyArrow:
```python
import pyarrow as pa
t = pa.table({"a": [[0]]})
t.to_pandas().a.values[0]
# array([0])
```
I believe this has to do with zero-copy: you can get a pandas DataFrame without copying the buffers from arrow, and therefore end up with numpy arrays. | ### Describe the bug
```
ds = Dataset.from_list([{'a':[1,2,3]}])
ds.to_pandas().a.values[0]
```
Results in `array([1, 2, 3])` -- a rather unexpected conversion of types which made downstream tools expecting lists not happy.
### Steps to reproduce the bug
See snippet
### Expected behavior
Keep the original typ... | 47 | Implicit type conversion of lists in to_pandas
### Describe the bug
```
ds = Dataset.from_list([{'a':[1,2,3]}])
ds.to_pandas().a.values[0]
```
Results in `array([1, 2, 3])` -- a rather unexpected conversion of types which made downstream tools expecting lists not happy.
### Steps to reproduce the bug
See snippe... |
https://github.com/huggingface/datasets/issues/5534 | map() breaks at certain dataset size when using Array3D | Hi! This code works for me locally or in Colab. What's the output of `python -c "import pyarrow as pa; print(pa.__version__)"` when you run it inside your environment? | ### Describe the bug
`map()` magically breaks when using a `Array3D` feature and mapping it. I created a very simple dummy dataset (see below). When filtering it down to 95 elements I can apply map, but it breaks when filtering it down to just 96 entries with the following exception:
```
Traceback (most recent cal... | 28 | map() breaks at certain dataset size when using Array3D
### Describe the bug
`map()` magically breaks when using a `Array3D` feature and mapping it. I created a very simple dummy dataset (see below). When filtering it down to 95 elements I can apply map, but it breaks when filtering it down to just 96 entries with t... |
https://github.com/huggingface/datasets/issues/5534 | map() breaks at certain dataset size when using Array3D | Thanks for looking into this!
The output of `python -c "import pyarrow as pa; print(pa.__version__)"` is:
```
11.0.0
```
I did the following to setup the environment:
```
conda create -n datasets_debug python=3.9
conda activate datasets_debug
pip install datasets==2.9.0
```
I just tested this on another... | ### Describe the bug
`map()` magically breaks when using a `Array3D` feature and mapping it. I created a very simple dummy dataset (see below). When filtering it down to 95 elements I can apply map, but it breaks when filtering it down to just 96 entries with the following exception:
```
Traceback (most recent cal... | 60 | map() breaks at certain dataset size when using Array3D
### Describe the bug
`map()` magically breaks when using a `Array3D` feature and mapping it. I created a very simple dummy dataset (see below). When filtering it down to 95 elements I can apply map, but it breaks when filtering it down to just 96 entries with t... |
https://github.com/huggingface/datasets/issues/5818 | Ability to update a dataset | In this case, I think we can avoid the `PermissionError` by unpacking the underlying `ConcatenationTable` and saving only the newly added data blocks (in new files). | ### Feature request
The ability to load a dataset, add or change something, and save it back to disk.
Maybe it's possible, but I can't work out how to do it, e.g. this fails:
```py
import datasets
dataset = datasets.load_from_disk("data/test1")
dataset = dataset.add_item({"text": "A new item"})
dataset.sav... | 26 | Ability to update a dataset
### Feature request
The ability to load a dataset, add or change something, and save it back to disk.
Maybe it's possible, but I can't work out how to do it, e.g. this fails:
```py
import datasets
dataset = datasets.load_from_disk("data/test1")
dataset = dataset.add_item({"text":... |
https://github.com/huggingface/datasets/issues/5818 | Ability to update a dataset | Thanks @stevhliu and @mariosasko , so saving to individual files then loading them later, concatenating again and saving again is the recommended way. Good to know.
Question that I hope doesn't sound rude: is this sort of thing (processing a dataset that doesn't fit in memory) outside of `datasets`'s core area of fo... | ### Feature request
The ability to load a dataset, add or change something, and save it back to disk.
Maybe it's possible, but I can't work out how to do it, e.g. this fails:
```py
import datasets
dataset = datasets.load_from_disk("data/test1")
dataset = dataset.add_item({"text": "A new item"})
dataset.sav... | 89 | Ability to update a dataset
### Feature request
The ability to load a dataset, add or change something, and save it back to disk.
Maybe it's possible, but I can't work out how to do it, e.g. this fails:
```py
import datasets
dataset = datasets.load_from_disk("data/test1")
dataset = dataset.add_item({"text":... |
https://github.com/huggingface/datasets/issues/5672 | Pushing dataset to hub crash | Hi ! It's been fixed by https://github.com/huggingface/datasets/pull/5598. We're doing a new release tomorrow with the fix and you'll be able to push your 100k images ;)
Basically `push_to_hub` used to fail if the remote repository already exists and has a README.md without dataset_info in the YAML tags.
In the m... | ### Describe the bug
Uploading a dataset with `push_to_hub()` fails without error description.
### Steps to reproduce the bug
Hey there,
I've built a image dataset of 100k images + text pair as described here https://huggingface.co/docs/datasets/image_dataset#imagefolder
Now I'm trying to push it to the hub b... | 56 | Pushing dataset to hub crash
### Describe the bug
Uploading a dataset with `push_to_hub()` fails without error description.
### Steps to reproduce the bug
Hey there,
I've built a image dataset of 100k images + text pair as described here https://huggingface.co/docs/datasets/image_dataset#imagefolder
Now I'm t... |
https://github.com/huggingface/datasets/issues/5672 | Pushing dataset to hub crash | Hi @lhoestq ,
What version of datasets library fix this case? I am using the last `v2.10.1` and I get the same error. | ### Describe the bug
Uploading a dataset with `push_to_hub()` fails without error description.
### Steps to reproduce the bug
Hey there,
I've built a image dataset of 100k images + text pair as described here https://huggingface.co/docs/datasets/image_dataset#imagefolder
Now I'm trying to push it to the hub b... | 23 | Pushing dataset to hub crash
### Describe the bug
Uploading a dataset with `push_to_hub()` fails without error description.
### Steps to reproduce the bug
Hey there,
I've built a image dataset of 100k images + text pair as described here https://huggingface.co/docs/datasets/image_dataset#imagefolder
Now I'm t... |
https://github.com/huggingface/datasets/issues/5989 | Set a rule on the config and split names | in this case we need to decide what to do with the existing datasets with white space characters (there shouldn't be a lot of them I think) | > should we actually allow characters like spaces? maybe it's better to add validation for whitespace symbols and directly in datasets and raise
https://github.com/huggingface/datasets-server/issues/853
| 27 | Set a rule on the config and split names
> should we actually allow characters like spaces? maybe it's better to add validation for whitespace symbols and directly in datasets and raise
https://github.com/huggingface/datasets-server/issues/853
in this case we need to decide what to do with the existing datasets wi... |
https://github.com/huggingface/datasets/issues/5143 | DownloadManager Git LFS support | Hey ! Actually it works, just pass the right URL ;)
The URL must be the one with “/resolve/”
e.g. https://huggingface.co/datasets/imagenet-1k/resolve/main/data/test_images.tar.gz
You can even pass a relative path to the dl_manager instead, like `dl_manager.download("data/test_images.tar.gz")` | ### Feature request
Maybe I'm mistaken but the `DownloadManager` does not support extracting git lfs files out of the box right?
Using `dl_manager.download()` or `dl_manager.download_and_extract()` still returns lfs files afaict.
Is there a good way to write a dataset loading script for a repo with lfs files?
##... | 34 | DownloadManager Git LFS support
### Feature request
Maybe I'm mistaken but the `DownloadManager` does not support extracting git lfs files out of the box right?
Using `dl_manager.download()` or `dl_manager.download_and_extract()` still returns lfs files afaict.
Is there a good way to write a dataset loading scrip... |
https://github.com/huggingface/datasets/issues/5750 | Fail to create datasets from a generator when using Google Big Query | `from_generator` expects a generator function, not a generator object, so this should work:
```python
from datasets import Dataset
from google.cloud import bigquery
client = bigquery.Client()
def gen()
# Perform a query.
QUERY = (
'SELECT name FROM `bigquery-public-data.usa_names.usa_1910_20... | ### Describe the bug
Creating a dataset from a generator using `Dataset.from_generator()` fails if the generator is the [Google Big Query Python client](https://cloud.google.com/python/docs/reference/bigquery/latest). The problem is that the Big Query client is not pickable. And the function `create_config_id` tries t... | 70 | Fail to create datasets from a generator when using Google Big Query
### Describe the bug
Creating a dataset from a generator using `Dataset.from_generator()` fails if the generator is the [Google Big Query Python client](https://cloud.google.com/python/docs/reference/bigquery/latest). The problem is that the Big Quer... |
https://github.com/huggingface/datasets/issues/5750 | Fail to create datasets from a generator when using Google Big Query | @mariosasko your code was incomplete, so I tried to fix it:
```py
from datasets import Dataset
from google.cloud import bigquery
client = bigquery.Client()
def gen():
# Perform a query.
QUERY = (
'SELECT name FROM `bigquery-public-data.usa_names.usa_1910_2013` '
'WHERE state = "T... | ### Describe the bug
Creating a dataset from a generator using `Dataset.from_generator()` fails if the generator is the [Google Big Query Python client](https://cloud.google.com/python/docs/reference/bigquery/latest). The problem is that the Big Query client is not pickable. And the function `create_config_id` tries t... | 128 | Fail to create datasets from a generator when using Google Big Query
### Describe the bug
Creating a dataset from a generator using `Dataset.from_generator()` fails if the generator is the [Google Big Query Python client](https://cloud.google.com/python/docs/reference/bigquery/latest). The problem is that the Big Quer... |
https://github.com/huggingface/datasets/issues/5750 | Fail to create datasets from a generator when using Google Big Query | It does matter: this function expects a generator function, as stated in the docs.
This should work:
```python
from datasets import Dataset
from google.cloud import bigquery
def gen():
client = bigquery.Client()
# Perform a query.
QUERY = (
'SELECT name FROM `bigquery-public-data.usa_na... | ### Describe the bug
Creating a dataset from a generator using `Dataset.from_generator()` fails if the generator is the [Google Big Query Python client](https://cloud.google.com/python/docs/reference/bigquery/latest). The problem is that the Big Query client is not pickable. And the function `create_config_id` tries t... | 128 | Fail to create datasets from a generator when using Google Big Query
### Describe the bug
Creating a dataset from a generator using `Dataset.from_generator()` fails if the generator is the [Google Big Query Python client](https://cloud.google.com/python/docs/reference/bigquery/latest). The problem is that the Big Quer... |
https://github.com/huggingface/datasets/issues/5750 | Fail to create datasets from a generator when using Google Big Query | Thank you @mariosasko . Your last code is working indeed. Curiously, the important detail here was to wrap the client instantiation within the generator itself. If the line `client = bigquery.Client()` is moved outside, then the error is back.
I see now also your point in regard to the generator being a generator fu... | ### Describe the bug
Creating a dataset from a generator using `Dataset.from_generator()` fails if the generator is the [Google Big Query Python client](https://cloud.google.com/python/docs/reference/bigquery/latest). The problem is that the Big Query client is not pickable. And the function `create_config_id` tries t... | 62 | Fail to create datasets from a generator when using Google Big Query
### Describe the bug
Creating a dataset from a generator using `Dataset.from_generator()` fails if the generator is the [Google Big Query Python client](https://cloud.google.com/python/docs/reference/bigquery/latest). The problem is that the Big Quer... |
https://github.com/huggingface/datasets/issues/6604 | Transform fingerprint collisions due to setting fixed random seed | I don't think the PR fixes the root cause, since it still relies on the `random` library which will often have its seed fixed. I think the builtin `uuid.uuid4()` is a better choice: https://docs.python.org/3/library/uuid.html | ### Describe the bug
The transform fingerprinting logic relies on the `random` library for random bits when the function is not hashable (e.g. bound methods as used in `trl`: https://github.com/huggingface/trl/blob/main/trl/trainer/dpo_trainer.py#L356). This causes collisions when the training code sets a fixed random... | 34 | Transform fingerprint collisions due to setting fixed random seed
### Describe the bug
The transform fingerprinting logic relies on the `random` library for random bits when the function is not hashable (e.g. bound methods as used in `trl`: https://github.com/huggingface/trl/blob/main/trl/trainer/dpo_trainer.py#L356).... |
https://github.com/huggingface/datasets/issues/6221 | Support saving datasets with custom formatting | Not a fan of pickling this sort of stuff either.
Note that users can also share the code in their dataset documentation. | Requested in https://discuss.huggingface.co/t/using-set-transform-on-a-dataset-leads-to-an-exception/53036.
I am not sure if supporting this is the best idea for the following reasons:
>For this to work, we would have to pickle a custom transform, which means the transform and the objects it references need to be... | 22 | Support saving datasets with custom formatting
Requested in https://discuss.huggingface.co/t/using-set-transform-on-a-dataset-leads-to-an-exception/53036.
I am not sure if supporting this is the best idea for the following reasons:
>For this to work, we would have to pickle a custom transform, which means the tra... |
https://github.com/huggingface/datasets/issues/4003 | ASSIN2 dataset checksum bug | Using latest code, I am still facing the issue.
```python
(base) vimos@vimosmu ➜ ~ ipython
Python 3.6.7 | packaged by conda-forge | (default, Nov 6 2019, 16:19:42)
Type 'copyright', 'credits' or 'license' for more information
IPython 7.11.1 -- An enhanced Interactive Python. Type '?' for help.
In [1]: from... | ## Describe the bug
Checksum error after trying to load the [ASSIN 2 dataset](https://huggingface.co/datasets/assin2).
`NonMatchingChecksumError` triggered by calling `load_dataset("assin2")`.
Similar to #3952 , #3942 , #3941 , etc.
```
----------------------------------------------------------------------... | 264 | ASSIN2 dataset checksum bug
## Describe the bug
Checksum error after trying to load the [ASSIN 2 dataset](https://huggingface.co/datasets/assin2).
`NonMatchingChecksumError` triggered by calling `load_dataset("assin2")`.
Similar to #3952 , #3942 , #3941 , etc.
```
------------------------------------------... |
https://github.com/huggingface/datasets/issues/4003 | ASSIN2 dataset checksum bug | That's true. Steps to reproduce the bug on Google Colab:
```
git clone https://github.com/huggingface/datasets.git
cd datasets
pip install -e .
python -c "from datasets import load_dataset; print(load_dataset('assin2')['train'][0])"
```
However the dataset will load without any problems if you just install v... | ## Describe the bug
Checksum error after trying to load the [ASSIN 2 dataset](https://huggingface.co/datasets/assin2).
`NonMatchingChecksumError` triggered by calling `load_dataset("assin2")`.
Similar to #3952 , #3942 , #3941 , etc.
```
----------------------------------------------------------------------... | 58 | ASSIN2 dataset checksum bug
## Describe the bug
Checksum error after trying to load the [ASSIN 2 dataset](https://huggingface.co/datasets/assin2).
`NonMatchingChecksumError` triggered by calling `load_dataset("assin2")`.
Similar to #3952 , #3942 , #3941 , etc.
```
------------------------------------------... |
https://github.com/huggingface/datasets/issues/4003 | ASSIN2 dataset checksum bug | Right indeed ! Let me open a PR to fix this.
The dataset_infos.json file that stores some metadata about the dataset to download (and is used to verify it was correctly downloaded) hasn't been updated correctly | ## Describe the bug
Checksum error after trying to load the [ASSIN 2 dataset](https://huggingface.co/datasets/assin2).
`NonMatchingChecksumError` triggered by calling `load_dataset("assin2")`.
Similar to #3952 , #3942 , #3941 , etc.
```
----------------------------------------------------------------------... | 36 | ASSIN2 dataset checksum bug
## Describe the bug
Checksum error after trying to load the [ASSIN 2 dataset](https://huggingface.co/datasets/assin2).
`NonMatchingChecksumError` triggered by calling `load_dataset("assin2")`.
Similar to #3952 , #3942 , #3941 , etc.
```
------------------------------------------... |
https://github.com/huggingface/datasets/issues/4003 | ASSIN2 dataset checksum bug | Not sure what the status of this is, but personally I am still getting this error, with glue. | ## Describe the bug
Checksum error after trying to load the [ASSIN 2 dataset](https://huggingface.co/datasets/assin2).
`NonMatchingChecksumError` triggered by calling `load_dataset("assin2")`.
Similar to #3952 , #3942 , #3941 , etc.
```
----------------------------------------------------------------------... | 18 | ASSIN2 dataset checksum bug
## Describe the bug
Checksum error after trying to load the [ASSIN 2 dataset](https://huggingface.co/datasets/assin2).
`NonMatchingChecksumError` triggered by calling `load_dataset("assin2")`.
Similar to #3952 , #3942 , #3941 , etc.
```
------------------------------------------... |
https://github.com/huggingface/datasets/issues/5794 | CI ZeroDivisionError | Hello!
This issue seems to have been fixed in https://github.com/huggingface/transformers/pull/24049
I was looking for my first issue to work on when I noticed this; not sure if there is a specific protocol for suggesting to close an issue. | Sometimes when running our CI on Windows, we get a ZeroDivisionError:
```
FAILED tests/test_metric_common.py::LocalMetricTest::test_load_metric_frugalscore - ZeroDivisionError: float division by zero
```
See for example:
- https://github.com/huggingface/datasets/actions/runs/4809358266/jobs/8560513110
- https:/... | 38 | CI ZeroDivisionError
Sometimes when running our CI on Windows, we get a ZeroDivisionError:
```
FAILED tests/test_metric_common.py::LocalMetricTest::test_load_metric_frugalscore - ZeroDivisionError: float division by zero
```
See for example:
- https://github.com/huggingface/datasets/actions/runs/4809358266/jobs/... |
https://github.com/huggingface/datasets/issues/5406 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | Hi ! I just tested locally and or colab and it works fine for 2.9 on `sst2`.
Also the code that is shown in your stack trace is not present in the 2.9 source code - so I'm wondering how you installed `datasets` that could cause this ? (you can check by searching for `[0:{label_ids[-1] + 1}]` in the [2.9 codebase](ht... | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 76 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ca... |
https://github.com/huggingface/datasets/issues/5406 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | For what it's worth, I've also gotten this error on 2.9.0, and I've tried uninstalling an reinstalling
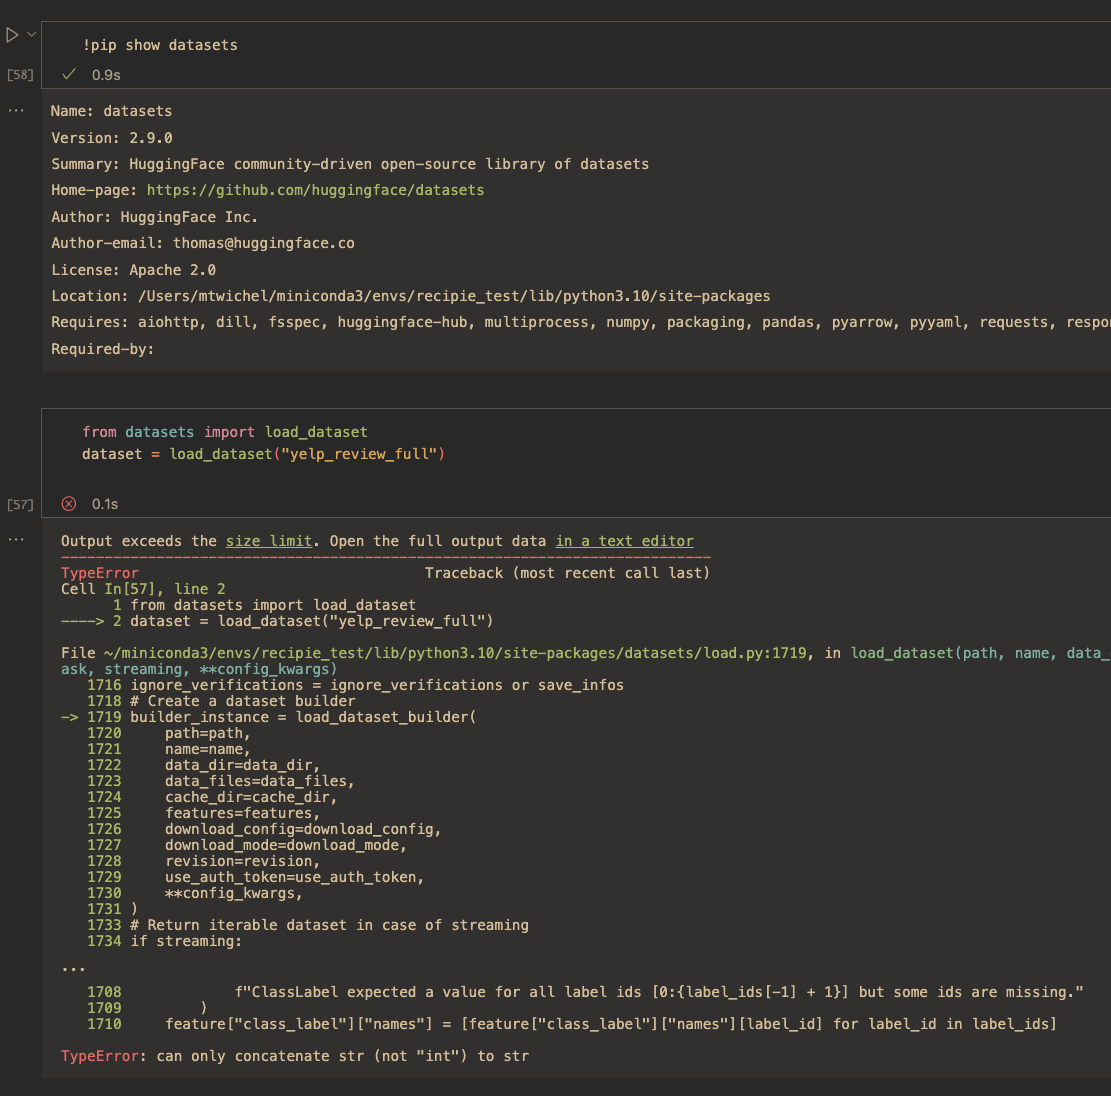
I'm very new to this package (I was following this tutorial: https://h... | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 54 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ca... |
https://github.com/huggingface/datasets/issues/5406 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | @ntrpnr @mtwichel Did you install `datasets` with conda ?
I suspect that `datasets` 2.9 on conda still have this issue for some reason. When I install `datasets` with `pip` I don't have this error. | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 34 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ca... |
https://github.com/huggingface/datasets/issues/5406 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | > @ntrpnr @mtwichel Did you install datasets with conda ?
I did yeah, I wonder if that's the issue | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 19 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ca... |
https://github.com/huggingface/datasets/issues/5406 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | I just checked on conda at https://anaconda.org/HuggingFace/datasets/files
and everything looks fine, I got
```python
f"ClassLabel expected a value for all label ids [0:{int(label_ids[-1]) + 1}] but some ids are missing."
```
as expected in features.py line 1760 (notice the "int()") to not have the TypeError.
... | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 70 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ca... |
https://github.com/huggingface/datasets/issues/5406 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | Could you also try this in your notebook ? In case your python kernel doesn't match the `pip` environment in your shell
```python
import datasets; datasets.__version__
```
and
```
!which python
```
```python
import sys; sys.executable
``` | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 37 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ca... |
https://github.com/huggingface/datasets/issues/5406 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | Mmmm, just a potential clue:
Where are you running your Python code? Is it the Spyder IDE?
I have recently seen some users reporting conflicting Python environments while using Spyder...
Maybe related:
- #5487 | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 34 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ca... |
https://github.com/huggingface/datasets/issues/5406 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | Other potential clue:
- Had you already imported `datasets` before pip-updating it? You should first update datasets, before importing it. Otherwise, you need to restart the kernel after updating it. | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 30 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ca... |
https://github.com/huggingface/datasets/issues/5406 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | I installed `datasets` with Conda using `conda install datasets` and got this issue.
Then I tried to reinstall using
`
conda install -c huggingface -c conda-forge datasets
`
The issue is now fixed. | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 33 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ca... |
https://github.com/huggingface/datasets/issues/7793 | Cannot load dataset, fails with nested data conversions not implemented for chunked array outputs | Hey @neevparikh,
Thanks for reporting this! I can reproduce the issue and have identified the root cause.
Problem: The metr-evals/malt-public dataset contains deeply nested conversation data that exceeds PyArrow's 16MB chunk limit. When PyArrow tries to read it in chunks, it hits a fundamental limitation: "Nested data ... | ### Describe the bug
Hi! When I load this dataset, it fails with a pyarrow error. I'm using datasets 4.1.1, though I also see this with datasets 4.1.2
To reproduce:
```
import datasets
ds = datasets.load_dataset(path="metr-evals/malt-public", name="irrelevant_detail")
```
Error:
```
Traceback (most recent call las... | 152 | Cannot load dataset, fails with nested data conversions not implemented for chunked array outputs
### Describe the bug
Hi! When I load this dataset, it fails with a pyarrow error. I'm using datasets 4.1.1, though I also see this with datasets 4.1.2
To reproduce:
```
import datasets
ds = datasets.load_dataset(path="... |
https://github.com/huggingface/datasets/issues/5880 | load_dataset from s3 file system through streaming can't not iterate data | This sounds related to #5281.
Can you try passing `storage_options=s3_client.storage_options` instead passing it to `use_auth_token=` ? | ### Describe the bug
I have a JSON file in my s3 file system(minio), I can use load_dataset to get the file link, but I can't iterate it
<img width="816" alt="image" src="https://github.com/huggingface/datasets/assets/59083384/cc0778d3-36f3-45b5-ac68-4e7c664c2ed0">
<img width="1144" alt="image" src="https://github.c... | 16 | load_dataset from s3 file system through streaming can't not iterate data
### Describe the bug
I have a JSON file in my s3 file system(minio), I can use load_dataset to get the file link, but I can't iterate it
<img width="816" alt="image" src="https://github.com/huggingface/datasets/assets/59083384/cc0778d3-36f3-45... |
https://github.com/huggingface/datasets/issues/5880 | load_dataset from s3 file system through streaming can't not iterate data | I tried `storage_options` before, but it doesn't work, I checked our source code and I found that we even didn't pass this parameter to the following process. if I use `storage_options` instead of `use_auth_token`, then I also need to change another place of the code. the last line of `streaming_download_manager.py`. o... | ### Describe the bug
I have a JSON file in my s3 file system(minio), I can use load_dataset to get the file link, but I can't iterate it
<img width="816" alt="image" src="https://github.com/huggingface/datasets/assets/59083384/cc0778d3-36f3-45b5-ac68-4e7c664c2ed0">
<img width="1144" alt="image" src="https://github.c... | 70 | load_dataset from s3 file system through streaming can't not iterate data
### Describe the bug
I have a JSON file in my s3 file system(minio), I can use load_dataset to get the file link, but I can't iterate it
<img width="816" alt="image" src="https://github.com/huggingface/datasets/assets/59083384/cc0778d3-36f3-45... |
https://github.com/huggingface/datasets/issues/5880 | load_dataset from s3 file system through streaming can't not iterate data | Cloud storage support is still experimental indeed and you can expect some bugs.
I think we need to pass the storage options anywhere use_auth_token is passed in indeed. Let me know if you'd be interested in contributing a fix ! | ### Describe the bug
I have a JSON file in my s3 file system(minio), I can use load_dataset to get the file link, but I can't iterate it
<img width="816" alt="image" src="https://github.com/huggingface/datasets/assets/59083384/cc0778d3-36f3-45b5-ac68-4e7c664c2ed0">
<img width="1144" alt="image" src="https://github.c... | 40 | load_dataset from s3 file system through streaming can't not iterate data
### Describe the bug
I have a JSON file in my s3 file system(minio), I can use load_dataset to get the file link, but I can't iterate it
<img width="816" alt="image" src="https://github.com/huggingface/datasets/assets/59083384/cc0778d3-36f3-45... |
https://github.com/huggingface/datasets/issues/5880 | load_dataset from s3 file system through streaming can't not iterate data | Oh, that's great, I really like to fix it. because datasets is really useful and most of our projects need to use it, but we can store our data on the internet due to security reasons. fix it not only make our own work more efficient but also can benefit others who use it. | ### Describe the bug
I have a JSON file in my s3 file system(minio), I can use load_dataset to get the file link, but I can't iterate it
<img width="816" alt="image" src="https://github.com/huggingface/datasets/assets/59083384/cc0778d3-36f3-45b5-ac68-4e7c664c2ed0">
<img width="1144" alt="image" src="https://github.c... | 54 | load_dataset from s3 file system through streaming can't not iterate data
### Describe the bug
I have a JSON file in my s3 file system(minio), I can use load_dataset to get the file link, but I can't iterate it
<img width="816" alt="image" src="https://github.com/huggingface/datasets/assets/59083384/cc0778d3-36f3-45... |
https://github.com/huggingface/datasets/issues/7102 | Slow iteration speeds when using IterableDataset.shuffle with load_dataset(data_files=..., streaming=True) | Hi @lajd , I was skeptical about how we are saving the shards each as their own dataset (arrow file) in the script above, and so I updated the script to try out saving the shards in a few different file formats. From the experiments I ran, I saw binary format show significantly the best performance, with arrow and pa... | ### Describe the bug
When I load a dataset from a number of arrow files, as in:
```
random_dataset = load_dataset(
"arrow",
data_files={split: shard_filepaths},
streaming=True,
split=split,
)
```
I'm able to get fast iteration speeds when iterating over the dataset without shuffling.
... | 534 | Slow iteration speeds when using IterableDataset.shuffle with load_dataset(data_files=..., streaming=True)
### Describe the bug
When I load a dataset from a number of arrow files, as in:
```
random_dataset = load_dataset(
"arrow",
data_files={split: shard_filepaths},
streaming=True,
split=spl... |
https://github.com/huggingface/datasets/issues/7102 | Slow iteration speeds when using IterableDataset.shuffle with load_dataset(data_files=..., streaming=True) | update: I was able to reproduce the issue you described -- but ONLY if I do
```
random_dataset = random_dataset.with_format("numpy")
```
If I do this, I see similar numbers as what you reported. If I do not use numpy format, parquet and arrow are about 17 iterations per second regardless of whether or not we s... | ### Describe the bug
When I load a dataset from a number of arrow files, as in:
```
random_dataset = load_dataset(
"arrow",
data_files={split: shard_filepaths},
streaming=True,
split=split,
)
```
I'm able to get fast iteration speeds when iterating over the dataset without shuffling.
... | 99 | Slow iteration speeds when using IterableDataset.shuffle with load_dataset(data_files=..., streaming=True)
### Describe the bug
When I load a dataset from a number of arrow files, as in:
```
random_dataset = load_dataset(
"arrow",
data_files={split: shard_filepaths},
streaming=True,
split=spl... |
https://github.com/huggingface/datasets/issues/7914 | [ROCm] please install 'torchcodec' | I was able to install torchcodec by building it from source and have put together a PR: https://github.com/vllm-project/vllm/pull/31323
Still I think it would make this framework more robust to add at least one fallback lib (that is more widely used) in place should torchcodec installation fail or library is not found... | ### Describe the bug
Datasets library is widely used by many Python packages. Naturally, it is a requirement on many platforms. This includes vLLM for ROCm. During audio dataset tests, there is an exception triggered:
```python
def decode_example(
self, value: dict, token_per_repo_id: Optional[dict[str, Un... | 51 | [ROCm] please install 'torchcodec'
### Describe the bug
Datasets library is widely used by many Python packages. Naturally, it is a requirement on many platforms. This includes vLLM for ROCm. During audio dataset tests, there is an exception triggered:
```python
def decode_example(
self, value: dict, token... |
https://github.com/huggingface/datasets/issues/7914 | [ROCm] please install 'torchcodec' | `datasets` doesn't even use the GPU acceleration features of `torchcodec` by default, so if `torchcodec` could still be installed but without GPU acceleration that would be great already (not just for ROCm but for any non-NVDEC compatible hardware) | ### Describe the bug
Datasets library is widely used by many Python packages. Naturally, it is a requirement on many platforms. This includes vLLM for ROCm. During audio dataset tests, there is an exception triggered:
```python
def decode_example(
self, value: dict, token_per_repo_id: Optional[dict[str, Un... | 38 | [ROCm] please install 'torchcodec'
### Describe the bug
Datasets library is widely used by many Python packages. Naturally, it is a requirement on many platforms. This includes vLLM for ROCm. During audio dataset tests, there is an exception triggered:
```python
def decode_example(
self, value: dict, token... |
https://github.com/huggingface/datasets/issues/6058 | laion-coco download error | This can also mean one of the files was not downloaded correctly.
We log an erroneous file's name before raising the reader's error, so this is how you can find the problematic file. Then, you should delete it and call `load_dataset` again.
(I checked all the uploaded files, and they seem to be valid Parquet file... | ### Describe the bug
The full trace:
```
/home/bian/anaconda3/envs/sd/lib/python3.10/site-packages/datasets/load.py:1744: FutureWarning: 'ignore_verifications' was de
precated in favor of 'verification_mode' in version 2.9.1 and will be removed in 3.0.0.
You can remove this warning by passing 'verification_mode=no... | 67 | laion-coco download error
### Describe the bug
The full trace:
```
/home/bian/anaconda3/envs/sd/lib/python3.10/site-packages/datasets/load.py:1744: FutureWarning: 'ignore_verifications' was de
precated in favor of 'verification_mode' in version 2.9.1 and will be removed in 3.0.0.
You can remove this warning by pas... |
https://github.com/huggingface/datasets/issues/3490 | Does datasets support load text from HDFS? | Hi ! `datasets` currently supports reading local files or files over HTTP. We may add support for other filesystems (cloud storages, hdfs...) at one point though :) | The raw text data is stored on HDFS due to the dataset's size is too large to store on my develop machine,
so I wander does datasets support read data from hdfs? | 27 | Does datasets support load text from HDFS?
The raw text data is stored on HDFS due to the dataset's size is too large to store on my develop machine,
so I wander does datasets support read data from hdfs?
Hi ! `datasets` currently supports reading local files or files over HTTP. We may add support for other filesyste... |
https://github.com/huggingface/datasets/issues/3679 | Download datasets from a private hub | Hi ! For information one can set the environment variable `HF_ENDPOINT` (default is `https://huggingface.co`) if they want to use a private hub.
We may need to coordinate with the other libraries to have a consistent way of changing the hub endpoint | In the context of a private hub deployment, customers would like to use load_dataset() to load datasets from their hub, not from the public hub. This doesn't seem to be configurable at the moment and it would be nice to add this feature.
The obvious workaround is to clone the repo first and then load it from local s... | 41 | Download datasets from a private hub
In the context of a private hub deployment, customers would like to use load_dataset() to load datasets from their hub, not from the public hub. This doesn't seem to be configurable at the moment and it would be nice to add this feature.
The obvious workaround is to clone the rep... |
https://github.com/huggingface/datasets/issues/6364 | ArrowNotImplementedError: Unsupported cast from string to list using function cast_list | You can use the following code to load this CSV with the list values preserved:
```python
from datasets import load_dataset
import ast
converters = {
"contexts" : ast.literal_eval,
"ground_truths" : ast.literal_eval,
}
ds = load_dataset("csv", data_files="golden_dataset.csv", converters=converters)
... | Hi,
I am trying to load a local csv dataset(similar to explodinggradients_fiqa) using load_dataset. When I try to pass features, I am facing the mentioned issue.
CSV Data sample(golden_dataset.csv):
Question | Context | answer | groundtruth
"what is abc?"... | 38 | ArrowNotImplementedError: Unsupported cast from string to list using function cast_list
Hi,
I am trying to load a local csv dataset(similar to explodinggradients_fiqa) using load_dataset. When I try to pass features, I am facing the mentioned issue.
CSV Data sample(golden_dataset.csv):
Question | ... |
https://github.com/huggingface/datasets/issues/4013 | Cannot preview "hazal/Turkish-Biomedical-corpus-trM" | Hi @hazalturkmen, thanks for reporting.
Note that your dataset repository does not contain any loading script; it only contains a data file named `tr_article_2`.
When there is no loading script but only data files, the `datasets` library tries to infer how to load the data by looking at the data file extensions. ... | ## Dataset viewer issue for '*hazal/Turkish-Biomedical-corpus-trM'
**Link:** *https://huggingface.co/datasets/hazal/Turkish-Biomedical-corpus-trM*
*I cannot see the dataset preview.*
```
Server Error
Status code: 400
Exception: HTTPError
Message: 403 Client Error: Forbidden for url: https://h... | 151 | Cannot preview "hazal/Turkish-Biomedical-corpus-trM"
## Dataset viewer issue for '*hazal/Turkish-Biomedical-corpus-trM'
**Link:** *https://huggingface.co/datasets/hazal/Turkish-Biomedical-corpus-trM*
*I cannot see the dataset preview.*
```
Server Error
Status code: 400
Exception: HTTPError
Message:... |
https://github.com/huggingface/datasets/issues/6120 | Lookahead streaming support? | In which format is your dataset? We could expose the `pre_buffer` flag for Parquet to use PyArrow's background thread pool to speed up loading. | ### Feature request
From what I understand, streaming dataset currently pulls the data, and process the data as it is requested.
This can introduce significant latency delays when data is loaded into the training process, needing to wait for each segment.
While the delays might be dataset specific (or even mappi... | 24 | Lookahead streaming support?
### Feature request
From what I understand, streaming dataset currently pulls the data, and process the data as it is requested.
This can introduce significant latency delays when data is loaded into the training process, needing to wait for each segment.
While the delays might be da... |
https://github.com/huggingface/datasets/issues/5914 | array is too big; `arr.size * arr.dtype.itemsize` is larger than the maximum possible size in Datasets | > Was a fix for this identified?
Hi @pranav-sridhar
Have you encountered a similar issue with this dataset?
I’ve modified the dataset construction script to address the problem. Feel free to use this updated version to avoid the issue.
[Ericwang/samromur_children_test](https://huggingface.co/datasets/Ericwang/... | ### Describe the bug
When using the `filter` or `map` function to preprocess a dataset, a ValueError is encountered with the error message "array is too big; arr.size * arr.dtype.itemsize is larger than the maximum possible size."
Detailed error message:
Traceback (most recent call last):
File "data_processing... | 40 | array is too big; `arr.size * arr.dtype.itemsize` is larger than the maximum possible size in Datasets
### Describe the bug
When using the `filter` or `map` function to preprocess a dataset, a ValueError is encountered with the error message "array is too big; arr.size * arr.dtype.itemsize is larger than the maximum p... |
https://github.com/huggingface/datasets/issues/6109 | Problems in downloading Amazon reviews from HF | Thanks for reporting, @610v4nn1.
Indeed, the source data files are no longer available. We have contacted the authors of the dataset and they report that Amazon has decided to stop distributing the multilingual reviews dataset.
We are adding a notification about this issue to the dataset card.
See: https://hug... | ### Describe the bug
I have a script downloading `amazon_reviews_multi`.
When the download starts, I get
```
Downloading data files: 0%| | 0/1 [00:00<?, ?it/s]
Downloading data: 243B [00:00, 1.43MB/s]
Downloading data files: 100%|██████████| 1/1 [00:01<00:00, 1.54s/it]
Extracting data files: 100%... | 49 | Problems in downloading Amazon reviews from HF
### Describe the bug
I have a script downloading `amazon_reviews_multi`.
When the download starts, I get
```
Downloading data files: 0%| | 0/1 [00:00<?, ?it/s]
Downloading data: 243B [00:00, 1.43MB/s]
Downloading data files: 100%|██████████| 1/1 [00:01... |
https://github.com/huggingface/datasets/issues/6109 | Problems in downloading Amazon reviews from HF | For those willing to transform the csv files from Kaggle into Huggingface datasets for their NLP course (exercise on summarisation), you can use this code on Google Collab:
`from datasets import load_dataset
import pandas as pd
from datasets import Dataset, DatasetDict
# Load your CSV previously downloaded fi... | ### Describe the bug
I have a script downloading `amazon_reviews_multi`.
When the download starts, I get
```
Downloading data files: 0%| | 0/1 [00:00<?, ?it/s]
Downloading data: 243B [00:00, 1.43MB/s]
Downloading data files: 100%|██████████| 1/1 [00:01<00:00, 1.54s/it]
Extracting data files: 100%... | 157 | Problems in downloading Amazon reviews from HF
### Describe the bug
I have a script downloading `amazon_reviews_multi`.
When the download starts, I get
```
Downloading data files: 0%| | 0/1 [00:00<?, ?it/s]
Downloading data: 243B [00:00, 1.43MB/s]
Downloading data files: 100%|██████████| 1/1 [00:01... |
https://github.com/huggingface/datasets/issues/4632 | 'sort' method sorts one column only | Hi ! `ds.sort()` does sort the full dataset, not just one column:
```python
from datasets import *
ds = Dataset.from_dict({"foo": [3, 2, 1], "bar": ["c", "b", "a"]})
print(d.sort("foo").to_pandas()
# foo bar
# 0 1 a
# 1 2 b
# 2 3 c
```
What made you think it was not the case ? Did you ex... | The 'sort' method changes the order of one column only (the one defined by the argument 'column'), thus creating a mismatch between a sample fields. I would expect it to change the order of the samples as a whole, based on the 'column' order. | 67 | 'sort' method sorts one column only
The 'sort' method changes the order of one column only (the one defined by the argument 'column'), thus creating a mismatch between a sample fields. I would expect it to change the order of the samples as a whole, based on the 'column' order.
Hi ! `ds.sort()` does sort the full datas... |
https://github.com/huggingface/datasets/issues/4632 | 'sort' method sorts one column only | Hi! thank you for your quick reply!
I wanted to sort the `cnn_dailymail` dataset by the length of the labels (num of characters). I added a new column to the dataset (`ds.add_column`) with the lengths and then sorted by this new column. Only the new length column was sorted, the reset left in their original order. | The 'sort' method changes the order of one column only (the one defined by the argument 'column'), thus creating a mismatch between a sample fields. I would expect it to change the order of the samples as a whole, based on the 'column' order. | 56 | 'sort' method sorts one column only
The 'sort' method changes the order of one column only (the one defined by the argument 'column'), thus creating a mismatch between a sample fields. I would expect it to change the order of the samples as a whole, based on the 'column' order.
Hi! thank you for your quick reply!
I wa... |
https://github.com/huggingface/datasets/issues/3272 | Make iter_archive work with ZIP files | Hi ! Sure this is open for any contributor. If you're interested feel free to self-assign this issue to you by commenting `#self-assign`. Then if you have any question or if I can help, feel free to ping me.
To begin with, feel free to take a look at both implementations of `iter_archive` for local downloads and for... | Currently users can use `dl_manager.iter_archive` in their dataset script to iterate over all the files of a TAR archive.
It would be nice if it could work with ZIP files too ! | 103 | Make iter_archive work with ZIP files
Currently users can use `dl_manager.iter_archive` in their dataset script to iterate over all the files of a TAR archive.
It would be nice if it could work with ZIP files too !
Hi ! Sure this is open for any contributor. If you're interested feel free to self-assign this issue to ... |
https://github.com/huggingface/datasets/issues/7772 | Error processing scalar columns using tensorflow. | Using tf.convert_to_tensor works fine:
```
import tensorflow as tf
start_pos = tf.convert_to_tensor(train_ds['start_positions'], dtype=tf.int64)
start_pos = tf.reshape(start_pos, [-1, 1])
```
Alternatively, using the built-in to_tf_dataset also avoids the issue:
```
train_tf = train_ds.to_tf_dataset(
columns=[... | `datasets==4.0.0`
```
columns_to_return = ['input_ids','attention_mask', 'start_positions', 'end_positions']
train_ds.set_format(type='tf', columns=columns_to_return)
```
`train_ds`:
```
train_ds type: <class 'datasets.arrow_dataset.Dataset'>, shape: (1000, 9)
columns: ['question', 'sentences', 'answer', 'str_idx', 'en... | 38 | Error processing scalar columns using tensorflow.
`datasets==4.0.0`
```
columns_to_return = ['input_ids','attention_mask', 'start_positions', 'end_positions']
train_ds.set_format(type='tf', columns=columns_to_return)
```
`train_ds`:
```
train_ds type: <class 'datasets.arrow_dataset.Dataset'>, shape: (1000, 9)
columns: ... |
https://github.com/huggingface/datasets/issues/7772 | Error processing scalar columns using tensorflow. | ```
start_pos = tf.convert_to_tensor(self._train_ds['start_positions'], dtype=tf.int64)
File "/home/khteh/.local/share/virtualenvs/pAIthon-GaqEDHQT/lib/python3.13/site-packages/tensorflow/python/util/traceback_utils.py", line 153, in error_handler
raise e.with_traceback(filtered_tb) from None
File "/home/kh... | `datasets==4.0.0`
```
columns_to_return = ['input_ids','attention_mask', 'start_positions', 'end_positions']
train_ds.set_format(type='tf', columns=columns_to_return)
```
`train_ds`:
```
train_ds type: <class 'datasets.arrow_dataset.Dataset'>, shape: (1000, 9)
columns: ['question', 'sentences', 'answer', 'str_idx', 'en... | 60 | Error processing scalar columns using tensorflow.
`datasets==4.0.0`
```
columns_to_return = ['input_ids','attention_mask', 'start_positions', 'end_positions']
train_ds.set_format(type='tf', columns=columns_to_return)
```
`train_ds`:
```
train_ds type: <class 'datasets.arrow_dataset.Dataset'>, shape: (1000, 9)
columns: ... |
https://github.com/huggingface/datasets/issues/4453 | Dataset Viewer issue for Yaxin/SemEval2015 | I understand that the issue is that a remote file (URL) is being loaded as a local file. Right @albertvillanova @lhoestq?
```
Message: [Errno 2] No such file or directory: 'https://raw.githubusercontent.com/YaxinCui/ABSADataset/main/SemEval2015Task12Corrected/train/restaurants_train.xml'
``` | ### Link
_No response_
### Description
_No response_
### Owner
_No response_ | 32 | Dataset Viewer issue for Yaxin/SemEval2015
### Link
_No response_
### Description
_No response_
### Owner
_No response_
I understand that the issue is that a remote file (URL) is being loaded as a local file. Right @albertvillanova @lhoestq?
```
Message: [Errno 2] No such file or directory: 'https://raw.... |
https://github.com/huggingface/datasets/issues/4453 | Dataset Viewer issue for Yaxin/SemEval2015 | `xml.dom.minidom.parse` is not supported in streaming mode. I opened a PR here to fix it:
https://huggingface.co/datasets/Yaxin/SemEval2015/discussions/1
Please review the PR @WithYouTo and let me know if it works ! | ### Link
_No response_
### Description
_No response_
### Owner
_No response_ | 29 | Dataset Viewer issue for Yaxin/SemEval2015
### Link
_No response_
### Description
_No response_
### Owner
_No response_
`xml.dom.minidom.parse` is not supported in streaming mode. I opened a PR here to fix it:
https://huggingface.co/datasets/Yaxin/SemEval2015/discussions/1
Please review the PR @WithYouTo and l... |
https://github.com/huggingface/datasets/issues/3851 | Load audio dataset error | Hi @lemoner20, thanks for reporting.
I'm sorry but I cannot reproduce your problem:
```python
In [1]: from datasets import load_dataset, load_metric, Audio
...: raw_datasets = load_dataset("superb", "ks", split="train")
...: print(raw_datasets[0]["audio"])
Downloading builder script: 30.2kB [00:00, 13.0MB... | ## Load audio dataset error
Hi, when I load audio dataset following https://huggingface.co/docs/datasets/audio_process and https://github.com/huggingface/datasets/tree/master/datasets/superb,
```
from datasets import load_dataset, load_metric, Audio
raw_datasets = load_dataset("superb", "ks", split="train")
prin... | 178 | Load audio dataset error
## Load audio dataset error
Hi, when I load audio dataset following https://huggingface.co/docs/datasets/audio_process and https://github.com/huggingface/datasets/tree/master/datasets/superb,
```
from datasets import load_dataset, load_metric, Audio
raw_datasets = load_dataset("superb", "... |
https://github.com/huggingface/datasets/issues/3851 | Load audio dataset error | @albertvillanova Thanks for your reply. The environment info below
## Environment info
- `datasets` version: 1.18.3
- Platform: Linux-4.19.91-007.ali4000.alios7.x86_64-x86_64-with-debian-buster-sid
- Python version: 3.6.12
- PyArrow version: 6.0.1 | ## Load audio dataset error
Hi, when I load audio dataset following https://huggingface.co/docs/datasets/audio_process and https://github.com/huggingface/datasets/tree/master/datasets/superb,
```
from datasets import load_dataset, load_metric, Audio
raw_datasets = load_dataset("superb", "ks", split="train")
prin... | 27 | Load audio dataset error
## Load audio dataset error
Hi, when I load audio dataset following https://huggingface.co/docs/datasets/audio_process and https://github.com/huggingface/datasets/tree/master/datasets/superb,
```
from datasets import load_dataset, load_metric, Audio
raw_datasets = load_dataset("superb", "... |
https://github.com/huggingface/datasets/issues/3851 | Load audio dataset error | Thanks @lemoner20,
I cannot reproduce your issue in datasets version 1.18.3 either.
Maybe redownloading the data file may work if you had already cached this dataset previously. Could you please try passing "force_redownload"?
```python
raw_datasets = load_dataset("superb", "ks", split="train", download_mode="f... | ## Load audio dataset error
Hi, when I load audio dataset following https://huggingface.co/docs/datasets/audio_process and https://github.com/huggingface/datasets/tree/master/datasets/superb,
```
from datasets import load_dataset, load_metric, Audio
raw_datasets = load_dataset("superb", "ks", split="train")
prin... | 40 | Load audio dataset error
## Load audio dataset error
Hi, when I load audio dataset following https://huggingface.co/docs/datasets/audio_process and https://github.com/huggingface/datasets/tree/master/datasets/superb,
```
from datasets import load_dataset, load_metric, Audio
raw_datasets = load_dataset("superb", "... |
https://github.com/huggingface/datasets/issues/3851 | Load audio dataset error | @albertvillanova, you can actually reproduce the error if you reach the cell `common_voice_train[0]["path"]` of this [notebook](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/Fine_Tune_XLSR_Wav2Vec2_on_Turkish_ASR_with_%F0%9F%A4%97_Transformers.ipynb#scrollTo=_0kRndSvqaKk). Error gets s... | ## Load audio dataset error
Hi, when I load audio dataset following https://huggingface.co/docs/datasets/audio_process and https://github.com/huggingface/datasets/tree/master/datasets/superb,
```
from datasets import load_dataset, load_metric, Audio
raw_datasets = load_dataset("superb", "ks", split="train")
prin... | 29 | Load audio dataset error
## Load audio dataset error
Hi, when I load audio dataset following https://huggingface.co/docs/datasets/audio_process and https://github.com/huggingface/datasets/tree/master/datasets/superb,
```
from datasets import load_dataset, load_metric, Audio
raw_datasets = load_dataset("superb", "... |
https://github.com/huggingface/datasets/issues/3851 | Load audio dataset error | @jvel07, thanks for reporting and finding a solution.
Maybe we could tell @patrickvonplaten about the version pinning issue in his notebook. | ## Load audio dataset error
Hi, when I load audio dataset following https://huggingface.co/docs/datasets/audio_process and https://github.com/huggingface/datasets/tree/master/datasets/superb,
```
from datasets import load_dataset, load_metric, Audio
raw_datasets = load_dataset("superb", "ks", split="train")
prin... | 21 | Load audio dataset error
## Load audio dataset error
Hi, when I load audio dataset following https://huggingface.co/docs/datasets/audio_process and https://github.com/huggingface/datasets/tree/master/datasets/superb,
```
from datasets import load_dataset, load_metric, Audio
raw_datasets = load_dataset("superb", "... |
https://github.com/huggingface/datasets/issues/7574 | Missing multilingual directions in IWSLT2017 dataset's processing script | cool ! I pinged the owners of the dataset on HF to merge your PRs :) | ### Describe the bug
Hi,
Upon using `iwslt2017.py` in `IWSLT/iwslt2017` on the Hub for loading the datasets, I am unable to obtain the datasets for the language pairs `de-it`, `de-ro`, `de-nl`, `it-de`, `nl-de`, and `ro-de` using it. These 6 pairs do not show up when using `get_dataset_config_names()` to obtain the ... | 16 | Missing multilingual directions in IWSLT2017 dataset's processing script
### Describe the bug
Hi,
Upon using `iwslt2017.py` in `IWSLT/iwslt2017` on the Hub for loading the datasets, I am unable to obtain the datasets for the language pairs `de-it`, `de-ro`, `de-nl`, `it-de`, `nl-de`, and `ro-de` using it. These 6 pa... |
https://github.com/huggingface/datasets/issues/5631 | Custom split names | Hi!
You can also use names other than "train", "validation" and "test". As an example, check the [script](https://huggingface.co/datasets/mozilla-foundation/common_voice_11_0/blob/e095840f23f3dffc1056c078c2f9320dad9ca74d/common_voice_11_0.py#L139) of the Common Voice 11 dataset. | ### Feature request
Hi,
I participated in multiple NLP tasks where there are more than just train, test, validation splits, there could be multiple validation sets or test sets. But it seems currently only those mentioned three splits supported. It would be nice to have the support for more splits on the hub. (curren... | 24 | Custom split names
### Feature request
Hi,
I participated in multiple NLP tasks where there are more than just train, test, validation splits, there could be multiple validation sets or test sets. But it seems currently only those mentioned three splits supported. It would be nice to have the support for more splits ... |
https://github.com/huggingface/datasets/issues/5777 | datasets.load_dataset("code_search_net", "python") : NotADirectoryError: [Errno 20] Not a directory | Note:
I listed the datasets and grepped around to find what appears to be an alternative source for this:
raw_datasets = load_dataset("espejelomar/code_search_net_python_10000_examples", "python") | ### Describe the bug
While checking out the [tokenizer tutorial](https://huggingface.co/course/chapter6/2?fw=pt), i noticed getting an error while initially downloading the python dataset used in the examples.
The [collab with the error is here](https://colab.research.google.com/github/huggingface/notebooks/blob/ma... | 23 | datasets.load_dataset("code_search_net", "python") : NotADirectoryError: [Errno 20] Not a directory
### Describe the bug
While checking out the [tokenizer tutorial](https://huggingface.co/course/chapter6/2?fw=pt), i noticed getting an error while initially downloading the python dataset used in the examples.
The [c... |
https://github.com/huggingface/datasets/issues/5777 | datasets.load_dataset("code_search_net", "python") : NotADirectoryError: [Errno 20] Not a directory | Thanks for reporting, @jason-brian-anderson.
Yes, this is a known issue: the [CodeSearchNet](https://github.com/github/CodeSearchNet) repo has been archived (Apr 11, 2023) and their source data files are no longer accessible in their S3: e.g. https://s3.amazonaws.com/code-search-net/CodeSearchNet/v2/python.zip gives... | ### Describe the bug
While checking out the [tokenizer tutorial](https://huggingface.co/course/chapter6/2?fw=pt), i noticed getting an error while initially downloading the python dataset used in the examples.
The [collab with the error is here](https://colab.research.google.com/github/huggingface/notebooks/blob/ma... | 60 | datasets.load_dataset("code_search_net", "python") : NotADirectoryError: [Errno 20] Not a directory
### Describe the bug
While checking out the [tokenizer tutorial](https://huggingface.co/course/chapter6/2?fw=pt), i noticed getting an error while initially downloading the python dataset used in the examples.
The [c... |
https://github.com/huggingface/datasets/issues/5777 | datasets.load_dataset("code_search_net", "python") : NotADirectoryError: [Errno 20] Not a directory | This issue is fixed because we are hosting the CodeSearchNet data files in the Hugging Face Hub. See: https://huggingface.co/datasets/code_search_net/discussions/7 | ### Describe the bug
While checking out the [tokenizer tutorial](https://huggingface.co/course/chapter6/2?fw=pt), i noticed getting an error while initially downloading the python dataset used in the examples.
The [collab with the error is here](https://colab.research.google.com/github/huggingface/notebooks/blob/ma... | 19 | datasets.load_dataset("code_search_net", "python") : NotADirectoryError: [Errno 20] Not a directory
### Describe the bug
While checking out the [tokenizer tutorial](https://huggingface.co/course/chapter6/2?fw=pt), i noticed getting an error while initially downloading the python dataset used in the examples.
The [c... |
https://github.com/huggingface/datasets/issues/5777 | datasets.load_dataset("code_search_net", "python") : NotADirectoryError: [Errno 20] Not a directory | Thanks @hamelsmu for the Zenodo link. I am adding it to the dataset card on the Hugging Face Hub, so that the community knows about this "official" source data. I guess this link is not well known, because some community members already hosted an "unofficial" version of the data on Zenodo as well: https://zenodo.org/re... | ### Describe the bug
While checking out the [tokenizer tutorial](https://huggingface.co/course/chapter6/2?fw=pt), i noticed getting an error while initially downloading the python dataset used in the examples.
The [collab with the error is here](https://colab.research.google.com/github/huggingface/notebooks/blob/ma... | 54 | datasets.load_dataset("code_search_net", "python") : NotADirectoryError: [Errno 20] Not a directory
### Describe the bug
While checking out the [tokenizer tutorial](https://huggingface.co/course/chapter6/2?fw=pt), i noticed getting an error while initially downloading the python dataset used in the examples.
The [c... |
https://github.com/huggingface/datasets/issues/7073 | CI is broken for convert_to_parquet: Invalid rev id: refs/pr/1 404 error causes RevisionNotFoundError | Any recent change in the API backend rejecting parameter `revision="refs/pr/1"` to `HfApi.preupload_lfs_files`?
```
f"{endpoint}/api/{repo_type}s/{repo_id}/preupload/{revision}"
https://hub-ci.huggingface.co/api/datasets/__DUMMY_TRANSFORMERS_USER__/test-dataset-5188a8-17219154347516/preupload/refs%2Fpr%2F1.
Inval... | See: https://github.com/huggingface/datasets/actions/runs/10095313567/job/27915185756
```
FAILED tests/test_hub.py::test_convert_to_parquet - huggingface_hub.utils._errors.RevisionNotFoundError: 404 Client Error. (Request ID: Root=1-66a25839-31ce7b475e70e7db1e4d44c2;b0c8870f-d5ef-4bf2-a6ff-0191f3df0f64)
Revision N... | 24 | CI is broken for convert_to_parquet: Invalid rev id: refs/pr/1 404 error causes RevisionNotFoundError
See: https://github.com/huggingface/datasets/actions/runs/10095313567/job/27915185756
```
FAILED tests/test_hub.py::test_convert_to_parquet - huggingface_hub.utils._errors.RevisionNotFoundError: 404 Client Error. (Re... |
https://github.com/huggingface/datasets/issues/7073 | CI is broken for convert_to_parquet: Invalid rev id: refs/pr/1 404 error causes RevisionNotFoundError | I have temporarily fixed the CI with:
- #7074
However, the underlying issue must be fixed and #7074 must be reverted. | See: https://github.com/huggingface/datasets/actions/runs/10095313567/job/27915185756
```
FAILED tests/test_hub.py::test_convert_to_parquet - huggingface_hub.utils._errors.RevisionNotFoundError: 404 Client Error. (Request ID: Root=1-66a25839-31ce7b475e70e7db1e4d44c2;b0c8870f-d5ef-4bf2-a6ff-0191f3df0f64)
Revision N... | 21 | CI is broken for convert_to_parquet: Invalid rev id: refs/pr/1 404 error causes RevisionNotFoundError
See: https://github.com/huggingface/datasets/actions/runs/10095313567/job/27915185756
```
FAILED tests/test_hub.py::test_convert_to_parquet - huggingface_hub.utils._errors.RevisionNotFoundError: 404 Client Error. (Re... |
https://github.com/huggingface/datasets/issues/7073 | CI is broken for convert_to_parquet: Invalid rev id: refs/pr/1 404 error causes RevisionNotFoundError | Hmm does it do the preupload call before creating the ref cc @Wauplin ?
(in that case it should do a preupload call on the base branch with `?create_pr=1`) | See: https://github.com/huggingface/datasets/actions/runs/10095313567/job/27915185756
```
FAILED tests/test_hub.py::test_convert_to_parquet - huggingface_hub.utils._errors.RevisionNotFoundError: 404 Client Error. (Request ID: Root=1-66a25839-31ce7b475e70e7db1e4d44c2;b0c8870f-d5ef-4bf2-a6ff-0191f3df0f64)
Revision N... | 29 | CI is broken for convert_to_parquet: Invalid rev id: refs/pr/1 404 error causes RevisionNotFoundError
See: https://github.com/huggingface/datasets/actions/runs/10095313567/job/27915185756
```
FAILED tests/test_hub.py::test_convert_to_parquet - huggingface_hub.utils._errors.RevisionNotFoundError: 404 Client Error. (Re... |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.