
html_url stringlengths 51 51 | title stringlengths 9 280 | comments stringlengths 63 24.7k | body stringlengths 51 58.6k | comments length int64 16 1.45k | text stringlengths 186 59.1k |
|---|---|---|---|---|---|
https://github.com/huggingface/datasets/issues/3920 | 'datasets.features' is not a package | Hi @Arij-Aladel,
You are using a very old version of our library `datasets`: 1.8.0
Current version is 2.0.0 (and the previous one was 1.18.4)
Please, try to update `datasets` library and check if the problem persists:
```shell
/env/bin/pip install -U datasets | @albertvillanova
python 3.9
os: ubuntu 20.04
In conda environment
torch installed by
```/env/bin/pip install torch==1.9.0+cu111 torchvision==0.10.0+cu111 torchaudio==0.9.0 -f https://download.pytorch.org/whl/torch_stable.html```
datasets package is installed by
```
/env/bin/pip install datasets==1.8.... | 41 | 'datasets.features' is not a package
@albertvillanova
python 3.9
os: ubuntu 20.04
In conda environment
torch installed by
```/env/bin/pip install torch==1.9.0+cu111 torchvision==0.10.0+cu111 torchaudio==0.9.0 -f https://download.pytorch.org/whl/torch_stable.html```
datasets package is installed by
```
... |
https://github.com/huggingface/datasets/issues/3920 | 'datasets.features' is not a package | The problem I can no I have build my project on this version and old version on transformers. I have preprocessed the data again to use it. Thank for your reply | @albertvillanova
python 3.9
os: ubuntu 20.04
In conda environment
torch installed by
```/env/bin/pip install torch==1.9.0+cu111 torchvision==0.10.0+cu111 torchaudio==0.9.0 -f https://download.pytorch.org/whl/torch_stable.html```
datasets package is installed by
```
/env/bin/pip install datasets==1.8.... | 31 | 'datasets.features' is not a package
@albertvillanova
python 3.9
os: ubuntu 20.04
In conda environment
torch installed by
```/env/bin/pip install torch==1.9.0+cu111 torchvision==0.10.0+cu111 torchaudio==0.9.0 -f https://download.pytorch.org/whl/torch_stable.html```
datasets package is installed by
```
... |
https://github.com/huggingface/datasets/issues/3401 | Add Wikimedia pre-processed datasets | As we are planning to stop using Apache Beam (our `datasets.BeamBasedBuilder`) for the generation of some datasets (including [Wikipedia](https://huggingface.co/datasets/wikipedia/blob/main/wikipedia.py)), I have been working on [wikimedia/wikipedia](https://huggingface.co/datasets/wikimedia/wikipedia) to:
- Port the ... | ## Adding a Dataset
- **Name:** Add pre-processed data to:
- *wikimedia/wikipedia*: https://huggingface.co/datasets/wikimedia/wikipedia
- *wikimedia/wikisource*: https://huggingface.co/datasets/wikimedia/wikisource
- **Description:** Add pre-processed data to the Hub for all languages
- **Paper:** *link to the... | 147 | Add Wikimedia pre-processed datasets
## Adding a Dataset
- **Name:** Add pre-processed data to:
- *wikimedia/wikipedia*: https://huggingface.co/datasets/wikimedia/wikipedia
- *wikimedia/wikisource*: https://huggingface.co/datasets/wikimedia/wikisource
- **Description:** Add pre-processed data to the Hub for all... |
https://github.com/huggingface/datasets/issues/4840 | Dataset Viewer issue for darragh/demo_data_raw3 | do you have an idea of why it can occur @huggingface/datasets? The dataset consists of a single parquet file. | ### Link
https://huggingface.co/datasets/darragh/demo_data_raw3
### Description
```
Exception: ValueError
Message: Arrow type extension<arrow.py_extension_type<pyarrow.lib.UnknownExtensionType>> does not have a datasets dtype equivalent.
```
reported by @NielsRogge
### Owner
No | 19 | Dataset Viewer issue for darragh/demo_data_raw3
### Link
https://huggingface.co/datasets/darragh/demo_data_raw3
### Description
```
Exception: ValueError
Message: Arrow type extension<arrow.py_extension_type<pyarrow.lib.UnknownExtensionType>> does not have a datasets dtype equivalent.
```
reported by @... |
https://github.com/huggingface/datasets/issues/4840 | Dataset Viewer issue for darragh/demo_data_raw3 | Thanks for reporting @severo.
I'm not able to reproduce that error. I get instead:
```
FileNotFoundError: [Errno 2] No such file or directory: 'orix/data/ChiSig/唐合乐-9-3.jpg'
```
Which pyarrow version are you using? Mine is 6.0.1. | ### Link
https://huggingface.co/datasets/darragh/demo_data_raw3
### Description
```
Exception: ValueError
Message: Arrow type extension<arrow.py_extension_type<pyarrow.lib.UnknownExtensionType>> does not have a datasets dtype equivalent.
```
reported by @NielsRogge
### Owner
No | 34 | Dataset Viewer issue for darragh/demo_data_raw3
### Link
https://huggingface.co/datasets/darragh/demo_data_raw3
### Description
```
Exception: ValueError
Message: Arrow type extension<arrow.py_extension_type<pyarrow.lib.UnknownExtensionType>> does not have a datasets dtype equivalent.
```
reported by @... |
https://github.com/huggingface/datasets/issues/4840 | Dataset Viewer issue for darragh/demo_data_raw3 | Apparently, there is something weird with that Parquet file: its schema is:
```
images: extension<arrow.py_extension_type<pyarrow.lib.UnknownExtensionType>>
```
I have forced a right schema:
```python
from datasets import Features, Image, load_dataset
features = Features({"images": Image()})
ds = datasets.l... | ### Link
https://huggingface.co/datasets/darragh/demo_data_raw3
### Description
```
Exception: ValueError
Message: Arrow type extension<arrow.py_extension_type<pyarrow.lib.UnknownExtensionType>> does not have a datasets dtype equivalent.
```
reported by @NielsRogge
### Owner
No | 97 | Dataset Viewer issue for darragh/demo_data_raw3
### Link
https://huggingface.co/datasets/darragh/demo_data_raw3
### Description
```
Exception: ValueError
Message: Arrow type extension<arrow.py_extension_type<pyarrow.lib.UnknownExtensionType>> does not have a datasets dtype equivalent.
```
reported by @... |
https://github.com/huggingface/datasets/issues/7156 | interleave_datasets resets shuffle state | It also does preserve `split_by_node`, so in the meantime you should call `shuffle` or `split_by_node` AFTER `interleave_datasets` or `concatenate_datasets` | ### Describe the bug
```
import datasets
import torch.utils.data
def gen(shards):
yield {"shards": shards}
def main():
dataset = datasets.IterableDataset.from_generator(
gen,
gen_kwargs={'shards': list(range(25))}
)
dataset = dataset.shuffle(buffer_size=1)
dataset... | 19 | interleave_datasets resets shuffle state
### Describe the bug
```
import datasets
import torch.utils.data
def gen(shards):
yield {"shards": shards}
def main():
dataset = datasets.IterableDataset.from_generator(
gen,
gen_kwargs={'shards': list(range(25))}
)
dataset = da... |
https://github.com/huggingface/datasets/issues/3773 | Checksum mismatch for the reddit_tifu dataset | @albertvillanova Thank you for the fast response! However I am still getting the same error:
Downloading: 2.23kB [00:00, ?B/s]
Traceback (most recent call last):
File "C:\Users\Anna\PycharmProjects\summarization\main.py", line 17, in <module>
dataset = load_dataset('reddit_tifu', 'long')
File "C:\Users\A... | ## Describe the bug
A checksum occurs when downloading the reddit_tifu data (both long & short).
## Steps to reproduce the bug
reddit_tifu_dataset = load_dataset('reddit_tifu', 'long')
## Expected results
The expected result is for the dataset to be downloaded and cached locally.
## Actual results
File "... | 112 | Checksum mismatch for the reddit_tifu dataset
## Describe the bug
A checksum occurs when downloading the reddit_tifu data (both long & short).
## Steps to reproduce the bug
reddit_tifu_dataset = load_dataset('reddit_tifu', 'long')
## Expected results
The expected result is for the dataset to be downloaded and ... |
https://github.com/huggingface/datasets/issues/3773 | Checksum mismatch for the reddit_tifu dataset | Hi @anna-kay, I'm sorry I didn't clearly explain the details to you:
- the error has been fixed in our `master` branch on GitHub: https://github.com/huggingface/datasets/commit/8ae21bf6a77175dc803ce2f1b93d18b8fbf45586
- the fix will not be accessible to users in PyPI until our next release of the `datasets` library
... | ## Describe the bug
A checksum occurs when downloading the reddit_tifu data (both long & short).
## Steps to reproduce the bug
reddit_tifu_dataset = load_dataset('reddit_tifu', 'long')
## Expected results
The expected result is for the dataset to be downloaded and cached locally.
## Actual results
File "... | 79 | Checksum mismatch for the reddit_tifu dataset
## Describe the bug
A checksum occurs when downloading the reddit_tifu data (both long & short).
## Steps to reproduce the bug
reddit_tifu_dataset = load_dataset('reddit_tifu', 'long')
## Expected results
The expected result is for the dataset to be downloaded and ... |
https://github.com/huggingface/datasets/issues/3656 | checksum error subjqa dataset | Hi @RensDimmendaal,
I'm sorry but I can't reproduce your bug:
```python
In [1]: from datasets import load_dataset
...: ds = load_dataset("subjqa", "electronics")
Downloading builder script: 9.15kB [00:00, 4.10MB/s] ... | ## Describe the bug
I get a checksum error when loading the `subjqa` dataset (used in the transformers book).
## Steps to reproduce the bug
```python
from datasets import load_dataset
subjqa = load_dataset("subjqa","electronics")
```
## Expected results
Loading the dataset
## Actual results
```
---... | 174 | checksum error subjqa dataset
## Describe the bug
I get a checksum error when loading the `subjqa` dataset (used in the transformers book).
## Steps to reproduce the bug
```python
from datasets import load_dataset
subjqa = load_dataset("subjqa","electronics")
```
## Expected results
Loading the dataset
... |
https://github.com/huggingface/datasets/issues/3656 | checksum error subjqa dataset | Thanks checking!
You're totally right. I don't know what's changed, but I'm glad it's working now!
| ## Describe the bug
I get a checksum error when loading the `subjqa` dataset (used in the transformers book).
## Steps to reproduce the bug
```python
from datasets import load_dataset
subjqa = load_dataset("subjqa","electronics")
```
## Expected results
Loading the dataset
## Actual results
```
---... | 16 | checksum error subjqa dataset
## Describe the bug
I get a checksum error when loading the `subjqa` dataset (used in the transformers book).
## Steps to reproduce the bug
```python
from datasets import load_dataset
subjqa = load_dataset("subjqa","electronics")
```
## Expected results
Loading the dataset
... |
https://github.com/huggingface/datasets/issues/6506 | Incorrect test set labels for RTE and CoLA datasets via load_dataset | As this is a specific issue of the "glue" dataset, I have transferred it to the dataset Discussion page: https://huggingface.co/datasets/glue/discussions/15
Let's continue the discussion there! | ### Describe the bug
The test set labels for the RTE and CoLA datasets when loading via datasets load_dataset are all -1.
Edit: It appears this is also the case for every other dataset except for MRPC (stsb, sst2, qqp, mnli (both matched and mismatched), qnli, wnli, ax). Is this intended behavior to safeguard the t... | 25 | Incorrect test set labels for RTE and CoLA datasets via load_dataset
### Describe the bug
The test set labels for the RTE and CoLA datasets when loading via datasets load_dataset are all -1.
Edit: It appears this is also the case for every other dataset except for MRPC (stsb, sst2, qqp, mnli (both matched and misma... |
https://github.com/huggingface/datasets/issues/4413 | Dataset Viewer issue for ett | Thanks for reporting @dgcnz.
I have checked that the dataset works fine in streaming mode.
Additionally, other datasets containing timestamps are properly rendered by the viewer: https://huggingface.co/datasets/blbooks
I have tried to force the refresh of the preview, but the endpoint is not responsive: Connec... | ### Link
https://huggingface.co/datasets/ett
### Description
Timestamp is not JSON serializable.
```
Status code: 500
Exception: Status500Error
Message: Type is not JSON serializable: Timestamp
```
### Owner
No | 48 | Dataset Viewer issue for ett
### Link
https://huggingface.co/datasets/ett
### Description
Timestamp is not JSON serializable.
```
Status code: 500
Exception: Status500Error
Message: Type is not JSON serializable: Timestamp
```
### Owner
No
Thanks for reporting @dgcnz.
I have checke... |
https://github.com/huggingface/datasets/issues/4413 | Dataset Viewer issue for ett | I've just resent the refresh of the preview to the new endpoint, without success.
CC: @severo | ### Link
https://huggingface.co/datasets/ett
### Description
Timestamp is not JSON serializable.
```
Status code: 500
Exception: Status500Error
Message: Type is not JSON serializable: Timestamp
```
### Owner
No | 16 | Dataset Viewer issue for ett
### Link
https://huggingface.co/datasets/ett
### Description
Timestamp is not JSON serializable.
```
Status code: 500
Exception: Status500Error
Message: Type is not JSON serializable: Timestamp
```
### Owner
No
I've just resent the refresh of the preview t... |
https://github.com/huggingface/datasets/issues/7357 | Python process aborded with GIL issue when using image dataset | The issue seems to come from `pyarrow`, I opened an issue on their side at https://github.com/apache/arrow/issues/45214 | ### Describe the bug
The issue is visible only with the latest `datasets==3.2.0`.
When using image dataset the Python process gets aborted right before the exit with the following error:
```
Fatal Python error: PyGILState_Release: thread state 0x7fa1f409ade0 must be current when releasing
Python runtime state: f... | 16 | Python process aborded with GIL issue when using image dataset
### Describe the bug
The issue is visible only with the latest `datasets==3.2.0`.
When using image dataset the Python process gets aborted right before the exit with the following error:
```
Fatal Python error: PyGILState_Release: thread state 0x7fa1f... |
https://github.com/huggingface/datasets/issues/7357 | Python process aborded with GIL issue when using image dataset | If you want to use latest version over 3.1.0, a temporary fix is to modify datasets/packaged_modules/parquet/parquet.py
```diff
with open(file, "rb") as f:
- parquet_fragment = ds.ParquetFileFormat().make_fragment(f)
- if parquet_fragment.row_groups:
- batch_size = self.config.batch_size or parquet_f... | ### Describe the bug
The issue is visible only with the latest `datasets==3.2.0`.
When using image dataset the Python process gets aborted right before the exit with the following error:
```
Fatal Python error: PyGILState_Release: thread state 0x7fa1f409ade0 must be current when releasing
Python runtime state: f... | 79 | Python process aborded with GIL issue when using image dataset
### Describe the bug
The issue is visible only with the latest `datasets==3.2.0`.
When using image dataset the Python process gets aborted right before the exit with the following error:
```
Fatal Python error: PyGILState_Release: thread state 0x7fa1f... |
https://github.com/huggingface/datasets/issues/7261 | Cannot load the cache when mapping the dataset | @zhangn77 Hi ,have you solved this problem? I encountered the same issue during training. Could we discuss it? | ### Describe the bug
I'm training the flux controlnet. The train_dataset.map() takes long time to finish. However, when I killed one training process and want to restart a new training with the same dataset. I can't reuse the mapped result even I defined the cache dir for the dataset.
with accelerator.main_process_... | 18 | Cannot load the cache when mapping the dataset
### Describe the bug
I'm training the flux controlnet. The train_dataset.map() takes long time to finish. However, when I killed one training process and want to restart a new training with the same dataset. I can't reuse the mapped result even I defined the cache dir for... |
https://github.com/huggingface/datasets/issues/7703 | [Docs] map() example uses undefined `tokenizer` — causes NameError | I've submitted PR #7704 which adds documentation to clarify the behavior of `map()` when returning `None`. | ## Description
The current documentation example for `datasets.Dataset.map()` demonstrates batched processing but uses a `tokenizer` object without defining or importing it. This causes an error every time it's copied.
Here is the problematic line:
```python
# process a batch of examples
>>> ds = ds.map(lambda examp... | 16 | [Docs] map() example uses undefined `tokenizer` — causes NameError
## Description
The current documentation example for `datasets.Dataset.map()` demonstrates batched processing but uses a `tokenizer` object without defining or importing it. This causes an error every time it's copied.
Here is the problematic line:
`... |
https://github.com/huggingface/datasets/issues/7427 | Error splitting the input into NAL units. | First time I see this error :/ maybe it's an issue with your version of `multiprocess` and `dill` ? Make sure they are compatible with `datasets` | ### Describe the bug
I am trying to finetune qwen2.5-vl on 16 * 80G GPUS, and I use `LLaMA-Factory` and set `preprocessing_num_workers=16`. However, I met the following error and the program seem to got crush. It seems that the error come from `datasets` library
The error logging is like following:
```text
Convertin... | 26 | Error splitting the input into NAL units.
### Describe the bug
I am trying to finetune qwen2.5-vl on 16 * 80G GPUS, and I use `LLaMA-Factory` and set `preprocessing_num_workers=16`. However, I met the following error and the program seem to got crush. It seems that the error come from `datasets` library
The error lo... |
https://github.com/huggingface/datasets/issues/7427 | Error splitting the input into NAL units. | > First time I see this error :/ maybe it's an issue with your version of `multiprocess` and `dill` ? Make sure they are compatible with `datasets`
any recommendation for `multiprocess` and `dill` | ### Describe the bug
I am trying to finetune qwen2.5-vl on 16 * 80G GPUS, and I use `LLaMA-Factory` and set `preprocessing_num_workers=16`. However, I met the following error and the program seem to got crush. It seems that the error come from `datasets` library
The error logging is like following:
```text
Convertin... | 33 | Error splitting the input into NAL units.
### Describe the bug
I am trying to finetune qwen2.5-vl on 16 * 80G GPUS, and I use `LLaMA-Factory` and set `preprocessing_num_workers=16`. However, I met the following error and the program seem to got crush. It seems that the error come from `datasets` library
The error lo... |
https://github.com/huggingface/datasets/issues/3676 | `None` replaced by `[]` after first batch in map | It looks like this is because of this behavior in pyarrow:
```python
import pyarrow as pa
arr = pa.array([None, [0]])
reconstructed_arr = pa.ListArray.from_arrays(arr.offsets, arr.values)
print(reconstructed_arr.to_pylist())
# [[], [0]]
```
It seems that `arr.offsets` can reconstruct the array properly, but... | Sometimes `None` can be replaced by `[]` when running map:
```python
from datasets import Dataset
ds = Dataset.from_dict({"a": range(4)})
ds = ds.map(lambda x: {"b": [[None, [0]]]}, batched=True, batch_size=1, remove_columns=["a"])
print(ds.to_pandas())
# b
# 0 [None, [0]]
# 1 [[], [0]]
# ... | 89 | `None` replaced by `[]` after first batch in map
Sometimes `None` can be replaced by `[]` when running map:
```python
from datasets import Dataset
ds = Dataset.from_dict({"a": range(4)})
ds = ds.map(lambda x: {"b": [[None, [0]]]}, batched=True, batch_size=1, remove_columns=["a"])
print(ds.to_pandas())
# ... |
https://github.com/huggingface/datasets/issues/3676 | `None` replaced by `[]` after first batch in map | The offsets don't have nulls because they don't include the validity bitmap from `arr.buffers()[0]`, which is used to say which values are null and which values are non-null.
Though the validity bitmap also seems to be wrong:
```python
bin(int(arr.buffers()[0].hex(), 16))
# '0b10'
# it should be 0b110 - 1 corres... | Sometimes `None` can be replaced by `[]` when running map:
```python
from datasets import Dataset
ds = Dataset.from_dict({"a": range(4)})
ds = ds.map(lambda x: {"b": [[None, [0]]]}, batched=True, batch_size=1, remove_columns=["a"])
print(ds.to_pandas())
# b
# 0 [None, [0]]
# 1 [[], [0]]
# ... | 158 | `None` replaced by `[]` after first batch in map
Sometimes `None` can be replaced by `[]` when running map:
```python
from datasets import Dataset
ds = Dataset.from_dict({"a": range(4)})
ds = ds.map(lambda x: {"b": [[None, [0]]]}, batched=True, batch_size=1, remove_columns=["a"])
print(ds.to_pandas())
# ... |
https://github.com/huggingface/datasets/issues/3676 | `None` replaced by `[]` after first batch in map | FYI the behavior is the same with:
- `datasets` version: 1.18.3
- Platform: Linux-5.8.0-50-generic-x86_64-with-debian-bullseye-sid
- Python version: 3.7.11
- PyArrow version: 6.0.1
but not with:
- `datasets` version: 1.8.0
- Platform: Linux-4.18.0-305.40.2.el8_4.x86_64-x86_64-with-redhat-8.4-Ootpa
- Python ... | Sometimes `None` can be replaced by `[]` when running map:
```python
from datasets import Dataset
ds = Dataset.from_dict({"a": range(4)})
ds = ds.map(lambda x: {"b": [[None, [0]]]}, batched=True, batch_size=1, remove_columns=["a"])
print(ds.to_pandas())
# b
# 0 [None, [0]]
# 1 [[], [0]]
# ... | 57 | `None` replaced by `[]` after first batch in map
Sometimes `None` can be replaced by `[]` when running map:
```python
from datasets import Dataset
ds = Dataset.from_dict({"a": range(4)})
ds = ds.map(lambda x: {"b": [[None, [0]]]}, batched=True, batch_size=1, remove_columns=["a"])
print(ds.to_pandas())
# ... |
https://github.com/huggingface/datasets/issues/3676 | `None` replaced by `[]` after first batch in map | Thanks for the insights @PaulLerner !
I found a way to workaround this issue for the code example presented in this issue.
Note that empty lists will still appear when you explicitly `cast` a list of lists that contain None values like [None, [0]] to a new feature type (e.g. to change the integer precision). In t... | Sometimes `None` can be replaced by `[]` when running map:
```python
from datasets import Dataset
ds = Dataset.from_dict({"a": range(4)})
ds = ds.map(lambda x: {"b": [[None, [0]]]}, batched=True, batch_size=1, remove_columns=["a"])
print(ds.to_pandas())
# b
# 0 [None, [0]]
# 1 [[], [0]]
# ... | 87 | `None` replaced by `[]` after first batch in map
Sometimes `None` can be replaced by `[]` when running map:
```python
from datasets import Dataset
ds = Dataset.from_dict({"a": range(4)})
ds = ds.map(lambda x: {"b": [[None, [0]]]}, batched=True, batch_size=1, remove_columns=["a"])
print(ds.to_pandas())
# ... |
https://github.com/huggingface/datasets/issues/3676 | `None` replaced by `[]` after first batch in map | Hi! I feel like I’m missing something in your answer, *what* is the workaround? Is it fixed in some `datasets` version? | Sometimes `None` can be replaced by `[]` when running map:
```python
from datasets import Dataset
ds = Dataset.from_dict({"a": range(4)})
ds = ds.map(lambda x: {"b": [[None, [0]]]}, batched=True, batch_size=1, remove_columns=["a"])
print(ds.to_pandas())
# b
# 0 [None, [0]]
# 1 [[], [0]]
# ... | 21 | `None` replaced by `[]` after first batch in map
Sometimes `None` can be replaced by `[]` when running map:
```python
from datasets import Dataset
ds = Dataset.from_dict({"a": range(4)})
ds = ds.map(lambda x: {"b": [[None, [0]]]}, batched=True, batch_size=1, remove_columns=["a"])
print(ds.to_pandas())
# ... |
https://github.com/huggingface/datasets/issues/3676 | `None` replaced by `[]` after first batch in map | `pa.ListArray.from_arrays` returns empty lists instead of None values. The workaround I added inside `datasets` simply consists in not using `pa.ListArray.from_arrays` :)
Once this PR [here ](https://github.com/huggingface/datasets/pull/4282)is merged, we'll release a new version of `datasets` that currectly returns... | Sometimes `None` can be replaced by `[]` when running map:
```python
from datasets import Dataset
ds = Dataset.from_dict({"a": range(4)})
ds = ds.map(lambda x: {"b": [[None, [0]]]}, batched=True, batch_size=1, remove_columns=["a"])
print(ds.to_pandas())
# b
# 0 [None, [0]]
# 1 [[], [0]]
# ... | 69 | `None` replaced by `[]` after first batch in map
Sometimes `None` can be replaced by `[]` when running map:
```python
from datasets import Dataset
ds = Dataset.from_dict({"a": range(4)})
ds = ds.map(lambda x: {"b": [[None, [0]]]}, batched=True, batch_size=1, remove_columns=["a"])
print(ds.to_pandas())
# ... |
https://github.com/huggingface/datasets/issues/6791 | `add_faiss_index` raises ValueError: not enough values to unpack (expected 2, got 1) | I realized I was passing a string column to this instead of float. Is it possible to add a warning or error to prevent users from falsely believing there's a bug? | ### Describe the bug
Calling `add_faiss_index` on a `Dataset` with a column argument raises a ValueError. The following is the trace
```python
214 def replacement_add(self, x):
215 """Adds vectors to the index.
216 The index must be trained before vectors can be added to it.
217 Th... | 31 | `add_faiss_index` raises ValueError: not enough values to unpack (expected 2, got 1)
### Describe the bug
Calling `add_faiss_index` on a `Dataset` with a column argument raises a ValueError. The following is the trace
```python
214 def replacement_add(self, x):
215 """Adds vectors to the index.
... |
https://github.com/huggingface/datasets/issues/6791 | `add_faiss_index` raises ValueError: not enough values to unpack (expected 2, got 1) | Hello!
I agree that we could add some safeguards around the type of `ds[column]`. At least for FAISS, we need the column to be made of embeddings as FAISS doesn't perform the embeddings itself.
I can propose a PR sometime this week. | ### Describe the bug
Calling `add_faiss_index` on a `Dataset` with a column argument raises a ValueError. The following is the trace
```python
214 def replacement_add(self, x):
215 """Adds vectors to the index.
216 The index must be trained before vectors can be added to it.
217 Th... | 42 | `add_faiss_index` raises ValueError: not enough values to unpack (expected 2, got 1)
### Describe the bug
Calling `add_faiss_index` on a `Dataset` with a column argument raises a ValueError. The following is the trace
```python
214 def replacement_add(self, x):
215 """Adds vectors to the index.
... |
https://github.com/huggingface/datasets/issues/3269 | coqa NonMatchingChecksumError | Hi @ZhaofengWu, thanks for reporting.
Unfortunately, I'm not able to reproduce your bug:
```python
In [1]: from datasets import load_dataset
In [2]: ds = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.91MB/s]
Downloading: 1.79kB [00:00, 1.79MB/s]
Using custom data configuration default
Downloading and p... | ```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... | 180 | coqa NonMatchingChecksumError
```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... |
https://github.com/huggingface/datasets/issues/3269 | coqa NonMatchingChecksumError | I'm getting the same error in two separate environments:
```
- `datasets` version: 1.15.1
- Platform: Linux-5.4.0-84-generic-x86_64-with-debian-bullseye-sid
- Python version: 3.7.11
- PyArrow version: 6.0.0
```
```
- `datasets` version: 1.15.1
- Platform: macOS-10.16-x86_64-i386-64bit
- Python version: 3.9.... | ```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... | 43 | coqa NonMatchingChecksumError
```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... |
https://github.com/huggingface/datasets/issues/3269 | coqa NonMatchingChecksumError | I'm sorry, but don't get to reproduce the error in the Linux environment.
@mariosasko @lhoestq can you reproduce it? | ```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... | 19 | coqa NonMatchingChecksumError
```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... |
https://github.com/huggingface/datasets/issues/3269 | coqa NonMatchingChecksumError | I also can't reproduce the error on Windows/Linux (tested both the master and the `1.15.1` version). | ```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... | 16 | coqa NonMatchingChecksumError
```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... |
https://github.com/huggingface/datasets/issues/3269 | coqa NonMatchingChecksumError | Maybe the file had issues during the download ? Could you try to delete your cache and try again ?
By default the downloads cache is at `~/.cache/huggingface/datasets/downloads`
Also can you check if you have a proxy that could prevent the download to succeed ? Are you able to download those files via your browser ... | ```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... | 56 | coqa NonMatchingChecksumError
```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... |
https://github.com/huggingface/datasets/issues/3269 | coqa NonMatchingChecksumError | I got the same error in a third environment (google cloud) as well. The internet for these three environments are all different so I don't think that's the reason.
```
- `datasets` version: 1.12.1
- Platform: Linux-5.11.0-1022-gcp-x86_64-with-glibc2.31
- Python version: 3.9.7
- PyArrow version: 6.0.0
```
I delet... | ```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... | 380 | coqa NonMatchingChecksumError
```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... |
https://github.com/huggingface/datasets/issues/3269 | coqa NonMatchingChecksumError | I can run your notebook fine, but if I create one myself, it has that error: https://colab.research.google.com/drive/107GIdhrauPO6ZiFDY7G9S74in4qqI2Kx?usp=sharing.
It's so funny -- it's like whenever you guys run it it's fine but whenever I run it it fails, whatever the environment is. | ```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... | 41 | coqa NonMatchingChecksumError
```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... |
https://github.com/huggingface/datasets/issues/3269 | coqa NonMatchingChecksumError | I guess it must be some connection issue: the data owner may be blocking requests coming from your country or IP range... | ```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... | 22 | coqa NonMatchingChecksumError
```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... |
https://github.com/huggingface/datasets/issues/3269 | coqa NonMatchingChecksumError | I mean, I don't think google colab sends the connection from my IP. Same applies to google cloud. | ```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... | 18 | coqa NonMatchingChecksumError
```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... |
https://github.com/huggingface/datasets/issues/3269 | coqa NonMatchingChecksumError | Hello, I am having the same error with @ZhaofengWu first with "social bias frames" dataset. As I found this report, I tried also "coqa" and it fails as well.
I test this on Google Colab.
```
- `datasets` version: 1.15.1
- Platform: Linux-5.4.104+-x86_64-with-Ubuntu-18.04-bionic
- Python version: 3.7.12
- Py... | ```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... | 82 | coqa NonMatchingChecksumError
```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... |
https://github.com/huggingface/datasets/issues/3269 | coqa NonMatchingChecksumError | Hi, still not able to reproduce the issue with `coqa`. If you still have this issue, could you please run these additional commands ?
```python
>>> import os
>>> from hashlib import md5
>>> from datasets.utils import DownloadManager, DownloadConfig
>>> path = DownloadManager(download_config=DownloadConfig(use_etag... | ```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... | 169 | coqa NonMatchingChecksumError
```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... |
https://github.com/huggingface/datasets/issues/3269 | coqa NonMatchingChecksumError | ```
>>> import os
>>> from hashlib import md5
>>> from datasets.utils import DownloadManager, DownloadConfig
>>> path = DownloadManager(download_config=DownloadConfig(use_etag=False)).download("https://nlp.stanford.edu/data/coqa/coqa-dev-v1.0.json") # it returns the cached file
>>> os.path.getsize(path)
222
>>>... | ```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... | 114 | coqa NonMatchingChecksumError
```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... |
https://github.com/huggingface/datasets/issues/3269 | coqa NonMatchingChecksumError | `wget https://nlp.stanford.edu/data/coqa/coqa-dev-v1.0.json` does work. So I suspect there might be some problem in `datasets`' networking code? Can you give me some snippet that simulates how `datasets` requests the resource which I can run on my end? | ```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... | 36 | coqa NonMatchingChecksumError
```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... |
https://github.com/huggingface/datasets/issues/3269 | coqa NonMatchingChecksumError | Ok This is an issue with the server that hosts the data at `https://nlp.stanford.edu/nlp/data` that randomly returns 503 (by trying several times it also happens on my side), hopefully it can be fixed soon. I'll try to reach the people in charge of hosting the data | ```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... | 46 | coqa NonMatchingChecksumError
```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... |
https://github.com/huggingface/datasets/issues/3269 | coqa NonMatchingChecksumError | You're right. I just opened a PR that would show this error if it happens again:
```python
ConnectionError: Couldn't reach https://nlp.stanford.edu/data/coqa/coqa-dev-v1.0.json (error 503)
``` | ```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... | 24 | coqa NonMatchingChecksumError
```
>>> from datasets import load_dataset
>>> dataset = load_dataset("coqa")
Downloading: 3.82kB [00:00, 1.26MB/s] ... |
https://github.com/huggingface/datasets/issues/7268 | load_from_disk | Hello, It's an interesting issue here. I have the same problem, I have a local dataset and I want to push the dataset to the hub but huggingface does a copy of it.
```py
from datasets import load_dataset
dataset = load_dataset("webdataset", data_files="/media/works/data/*.tar") # copy here
dataset.push_to_hub("... | ### Describe the bug
I have data saved with save_to_disk. The data is big (700Gb). When I try loading it, the only option is load_from_disk, and this function copies the data to a tmp directory, causing me to run out of disk space. Is there an alternative solution to that?
### Steps to reproduce the bug
when trying ... | 56 | load_from_disk
### Describe the bug
I have data saved with save_to_disk. The data is big (700Gb). When I try loading it, the only option is load_from_disk, and this function copies the data to a tmp directory, causing me to run out of disk space. Is there an alternative solution to that?
### Steps to reproduce the bu... |
https://github.com/huggingface/datasets/issues/7268 | load_from_disk | Is there any update on this issue? I found the same behavior too.
My datasets version is `2.13.2` | ### Describe the bug
I have data saved with save_to_disk. The data is big (700Gb). When I try loading it, the only option is load_from_disk, and this function copies the data to a tmp directory, causing me to run out of disk space. Is there an alternative solution to that?
### Steps to reproduce the bug
when trying ... | 18 | load_from_disk
### Describe the bug
I have data saved with save_to_disk. The data is big (700Gb). When I try loading it, the only option is load_from_disk, and this function copies the data to a tmp directory, causing me to run out of disk space. Is there an alternative solution to that?
### Steps to reproduce the bu... |
https://github.com/huggingface/datasets/issues/7798 | Audio dataset is not decoding on 4.1.1 | Previously (datasets<=3.6.0), audio columns were decoded automatically when accessing a row. Now, for performance reasons, audio decoding is lazy by default: you just see the file path unless you explicitly cast the column to Audio.
Here’s the fix (following the current [datasets audio docs](https://huggingface.co/doc... | ### Describe the bug
The audio column remain as non-decoded objects even when accessing them.
```python
dataset = load_dataset("MrDragonFox/Elise", split = "train")
dataset[0] # see that it doesn't show 'array' etc...
```
Works fine with `datasets==3.6.0`
Followed the docs in
- https://huggingface.co/docs/dataset... | 75 | Audio dataset is not decoding on 4.1.1
### Describe the bug
The audio column remain as non-decoded objects even when accessing them.
```python
dataset = load_dataset("MrDragonFox/Elise", split = "train")
dataset[0] # see that it doesn't show 'array' etc...
```
Works fine with `datasets==3.6.0`
Followed the docs in ... |
https://github.com/huggingface/datasets/issues/7798 | Audio dataset is not decoding on 4.1.1 | @haitam03-yo's comment is right that the data is not decoded by default anymore indeed, but here is how it works in practice now:
From `datasets` v4, audio data are read as [AudioDecoder](https://meta-pytorch.org/torchcodec/0.4/generated/torchcodec.decoders.AudioDecoder.html) objects from torchcodec. This doesn't deco... | ### Describe the bug
The audio column remain as non-decoded objects even when accessing them.
```python
dataset = load_dataset("MrDragonFox/Elise", split = "train")
dataset[0] # see that it doesn't show 'array' etc...
```
Works fine with `datasets==3.6.0`
Followed the docs in
- https://huggingface.co/docs/dataset... | 62 | Audio dataset is not decoding on 4.1.1
### Describe the bug
The audio column remain as non-decoded objects even when accessing them.
```python
dataset = load_dataset("MrDragonFox/Elise", split = "train")
dataset[0] # see that it doesn't show 'array' etc...
```
Works fine with `datasets==3.6.0`
Followed the docs in ... |
https://github.com/huggingface/datasets/issues/7798 | Audio dataset is not decoding on 4.1.1 | To resolve this, you need to explicitly cast the audio column to the Audio feature. This will decode the audio data and make it accessible as an array. Here is the corrected code snippet
from datasets import load_dataset, Audio
# Load your dataset
dataset = load_dataset("MrDragonFox/Elise", split="train")
# Explici... | ### Describe the bug
The audio column remain as non-decoded objects even when accessing them.
```python
dataset = load_dataset("MrDragonFox/Elise", split = "train")
dataset[0] # see that it doesn't show 'array' etc...
```
Works fine with `datasets==3.6.0`
Followed the docs in
- https://huggingface.co/docs/dataset... | 111 | Audio dataset is not decoding on 4.1.1
### Describe the bug
The audio column remain as non-decoded objects even when accessing them.
```python
dataset = load_dataset("MrDragonFox/Elise", split = "train")
dataset[0] # see that it doesn't show 'array' etc...
```
Works fine with `datasets==3.6.0`
Followed the docs in ... |
https://github.com/huggingface/datasets/issues/6726 | Profiling for HF Filesystem shows there are easy performance gains to be made | Oh I forgot to mention you can also cache resolve_pattern, and that seemed to also substantially improves things, if you want to load a dataset twice for whatever reason. | ### Describe the bug
# Let's make it faster
First, an evidence...

Figure 1: CProfile for loading 3 files from cerebras/SlimPajama-627B train split, and 3 files from test split using streaming=True. X axis is 1106... | 29 | Profiling for HF Filesystem shows there are easy performance gains to be made
### Describe the bug
# Let's make it faster
First, an evidence...

Figure 1: CProfile for loading 3 files from cerebras/SlimPajama-627B... |
https://github.com/huggingface/datasets/issues/3334 | Integrate Polars library | Polars has grown rapidly in popularity over the last year - could you consider integrating the Polars functionality again?
I don't think the "custom" implementation should be a barrier, it still conforms to the Arrow specification | Check potential integration of the Polars library: https://github.com/pola-rs/polars
- Benchmark: https://h2oai.github.io/db-benchmark/
CC: @thomwolf @lewtun
| 36 | Integrate Polars library
Check potential integration of the Polars library: https://github.com/pola-rs/polars
- Benchmark: https://h2oai.github.io/db-benchmark/
CC: @thomwolf @lewtun
Polars has grown rapidly in popularity over the last year - could you consider integrating the Polars functionality again?
I do... |
https://github.com/huggingface/datasets/issues/3334 | Integrate Polars library | Is there some direction regarding this from the HF team @lewtun ? Can conversion from polars to HF dataset be implemented with limited/zero copy? So, something like ``Dataset.from_polars()`` and ``Dataset.to_polars()`` like you mentioned. Happy to contribute if I can get some pointers on how this may be implemented. | Check potential integration of the Polars library: https://github.com/pola-rs/polars
- Benchmark: https://h2oai.github.io/db-benchmark/
CC: @thomwolf @lewtun
| 48 | Integrate Polars library
Check potential integration of the Polars library: https://github.com/pola-rs/polars
- Benchmark: https://h2oai.github.io/db-benchmark/
CC: @thomwolf @lewtun
Is there some direction regarding this from the HF team @lewtun ? Can conversion from polars to HF dataset be implemented with lim... |
https://github.com/huggingface/datasets/issues/3334 | Integrate Polars library | > Hi, is there any updates? Thanks!
The feature has been there for a bit 😊 You can call `dataset.to_polars()` (on a `Dataset`, not a `DatasetDict`). The issue can be closed, I guess! @lhoestq | Check potential integration of the Polars library: https://github.com/pola-rs/polars
- Benchmark: https://h2oai.github.io/db-benchmark/
CC: @thomwolf @lewtun
| 34 | Integrate Polars library
Check potential integration of the Polars library: https://github.com/pola-rs/polars
- Benchmark: https://h2oai.github.io/db-benchmark/
CC: @thomwolf @lewtun
> Hi, is there any updates? Thanks!
The feature has been there for a bit 😊 You can call `dataset.to_polars()` (on a `Dataset`,... |
https://github.com/huggingface/datasets/issues/6242 | Data alteration when loading dataset with unspecified inner sequence length | While this issue may seem specific, it led to a silent problem in my workflow that took days to diagnose. If this feature is not intended to be supported, an error should be raised when encountering this configuration to prevent such issues. | ### Describe the bug
When a dataset saved with a specified inner sequence length is loaded without specifying that length, the original data is altered and becomes inconsistent.
### Steps to reproduce the bug
```python
from datasets import Dataset, Features, Value, Sequence, load_dataset
# Repository ID
repo_id... | 42 | Data alteration when loading dataset with unspecified inner sequence length
### Describe the bug
When a dataset saved with a specified inner sequence length is loaded without specifying that length, the original data is altered and becomes inconsistent.
### Steps to reproduce the bug
```python
from datasets import ... |
https://github.com/huggingface/datasets/issues/6242 | Data alteration when loading dataset with unspecified inner sequence length | Thanks for reporting! This is a MRE:
```python
import pyarrow as pa
from datasets.table import cast_array_to_feature
from datasets import Sequence, Value
data = [
[[1.0, 2.0, 3.0], [4.0, 5.0, 6.0]],
[[7.0, 8.0, 9.0], [10.0, 11.0, 12.0]],
]
arr = pa.array(data, pa.list_(pa.list_(pa.float32(), 3)))
ca... | ### Describe the bug
When a dataset saved with a specified inner sequence length is loaded without specifying that length, the original data is altered and becomes inconsistent.
### Steps to reproduce the bug
```python
from datasets import Dataset, Features, Value, Sequence, load_dataset
# Repository ID
repo_id... | 52 | Data alteration when loading dataset with unspecified inner sequence length
### Describe the bug
When a dataset saved with a specified inner sequence length is loaded without specifying that length, the original data is altered and becomes inconsistent.
### Steps to reproduce the bug
```python
from datasets import ... |
https://github.com/huggingface/datasets/issues/5317 | `ImageFolder` performs poorly with large datasets | Hi ! ImageFolder is made for small scale datasets indeed. For large scale image datasets you better group your images in TAR archives or Arrow/Parquet files. This is true not just for ImageFolder loading performance, but also because having millions of files is not ideal for your filesystem or when moving the data arou... | ### Describe the bug
While testing image dataset creation, I'm seeing significant performance bottlenecks with imagefolders when scanning a directory structure with large number of images.
## Setup
* Nested directories (5 levels deep)
* 3M+ images
* 1 `metadata.jsonl` file
## Performance Degradation Point... | 186 | `ImageFolder` performs poorly with large datasets
### Describe the bug
While testing image dataset creation, I'm seeing significant performance bottlenecks with imagefolders when scanning a directory structure with large number of images.
## Setup
* Nested directories (5 levels deep)
* 3M+ images
* 1 `metadata... |
https://github.com/huggingface/datasets/issues/5317 | `ImageFolder` performs poorly with large datasets | @lhoestq Thanks!
Perhaps it'd be worth adding a note on the documentation that `ImageFolder` is not intended for large datasets? This limitation is not intuitively obvious to someone who has not used it before, I think. | ### Describe the bug
While testing image dataset creation, I'm seeing significant performance bottlenecks with imagefolders when scanning a directory structure with large number of images.
## Setup
* Nested directories (5 levels deep)
* 3M+ images
* 1 `metadata.jsonl` file
## Performance Degradation Point... | 36 | `ImageFolder` performs poorly with large datasets
### Describe the bug
While testing image dataset creation, I'm seeing significant performance bottlenecks with imagefolders when scanning a directory structure with large number of images.
## Setup
* Nested directories (5 levels deep)
* 3M+ images
* 1 `metadata... |
https://github.com/huggingface/datasets/issues/5317 | `ImageFolder` performs poorly with large datasets | Thanks for the feedback @salieri! I opened #5329 to make it clear `ImageFolder` is not intended for large datasets. Please feel free to comment if you have any other feedback! 🙂 | ### Describe the bug
While testing image dataset creation, I'm seeing significant performance bottlenecks with imagefolders when scanning a directory structure with large number of images.
## Setup
* Nested directories (5 levels deep)
* 3M+ images
* 1 `metadata.jsonl` file
## Performance Degradation Point... | 31 | `ImageFolder` performs poorly with large datasets
### Describe the bug
While testing image dataset creation, I'm seeing significant performance bottlenecks with imagefolders when scanning a directory structure with large number of images.
## Setup
* Nested directories (5 levels deep)
* 3M+ images
* 1 `metadata... |
https://github.com/huggingface/datasets/issues/3580 | Bug in wiki bio load | +1, here's the error I got:
```
>>> from datasets import load_dataset
>>>
>>> load_dataset("wiki_bio")
Downloading: 7.58kB [00:00, 4.42MB/s]
Downloading: 2.71kB [00:00, 1.30MB/s]
Using custom data configuration default
Downloading and preparing dataset wiki_bio/default (download: 318.53 MiB, generated: 736.9... |
wiki_bio is failing to load because of a failing drive link . Can someone fix this ?
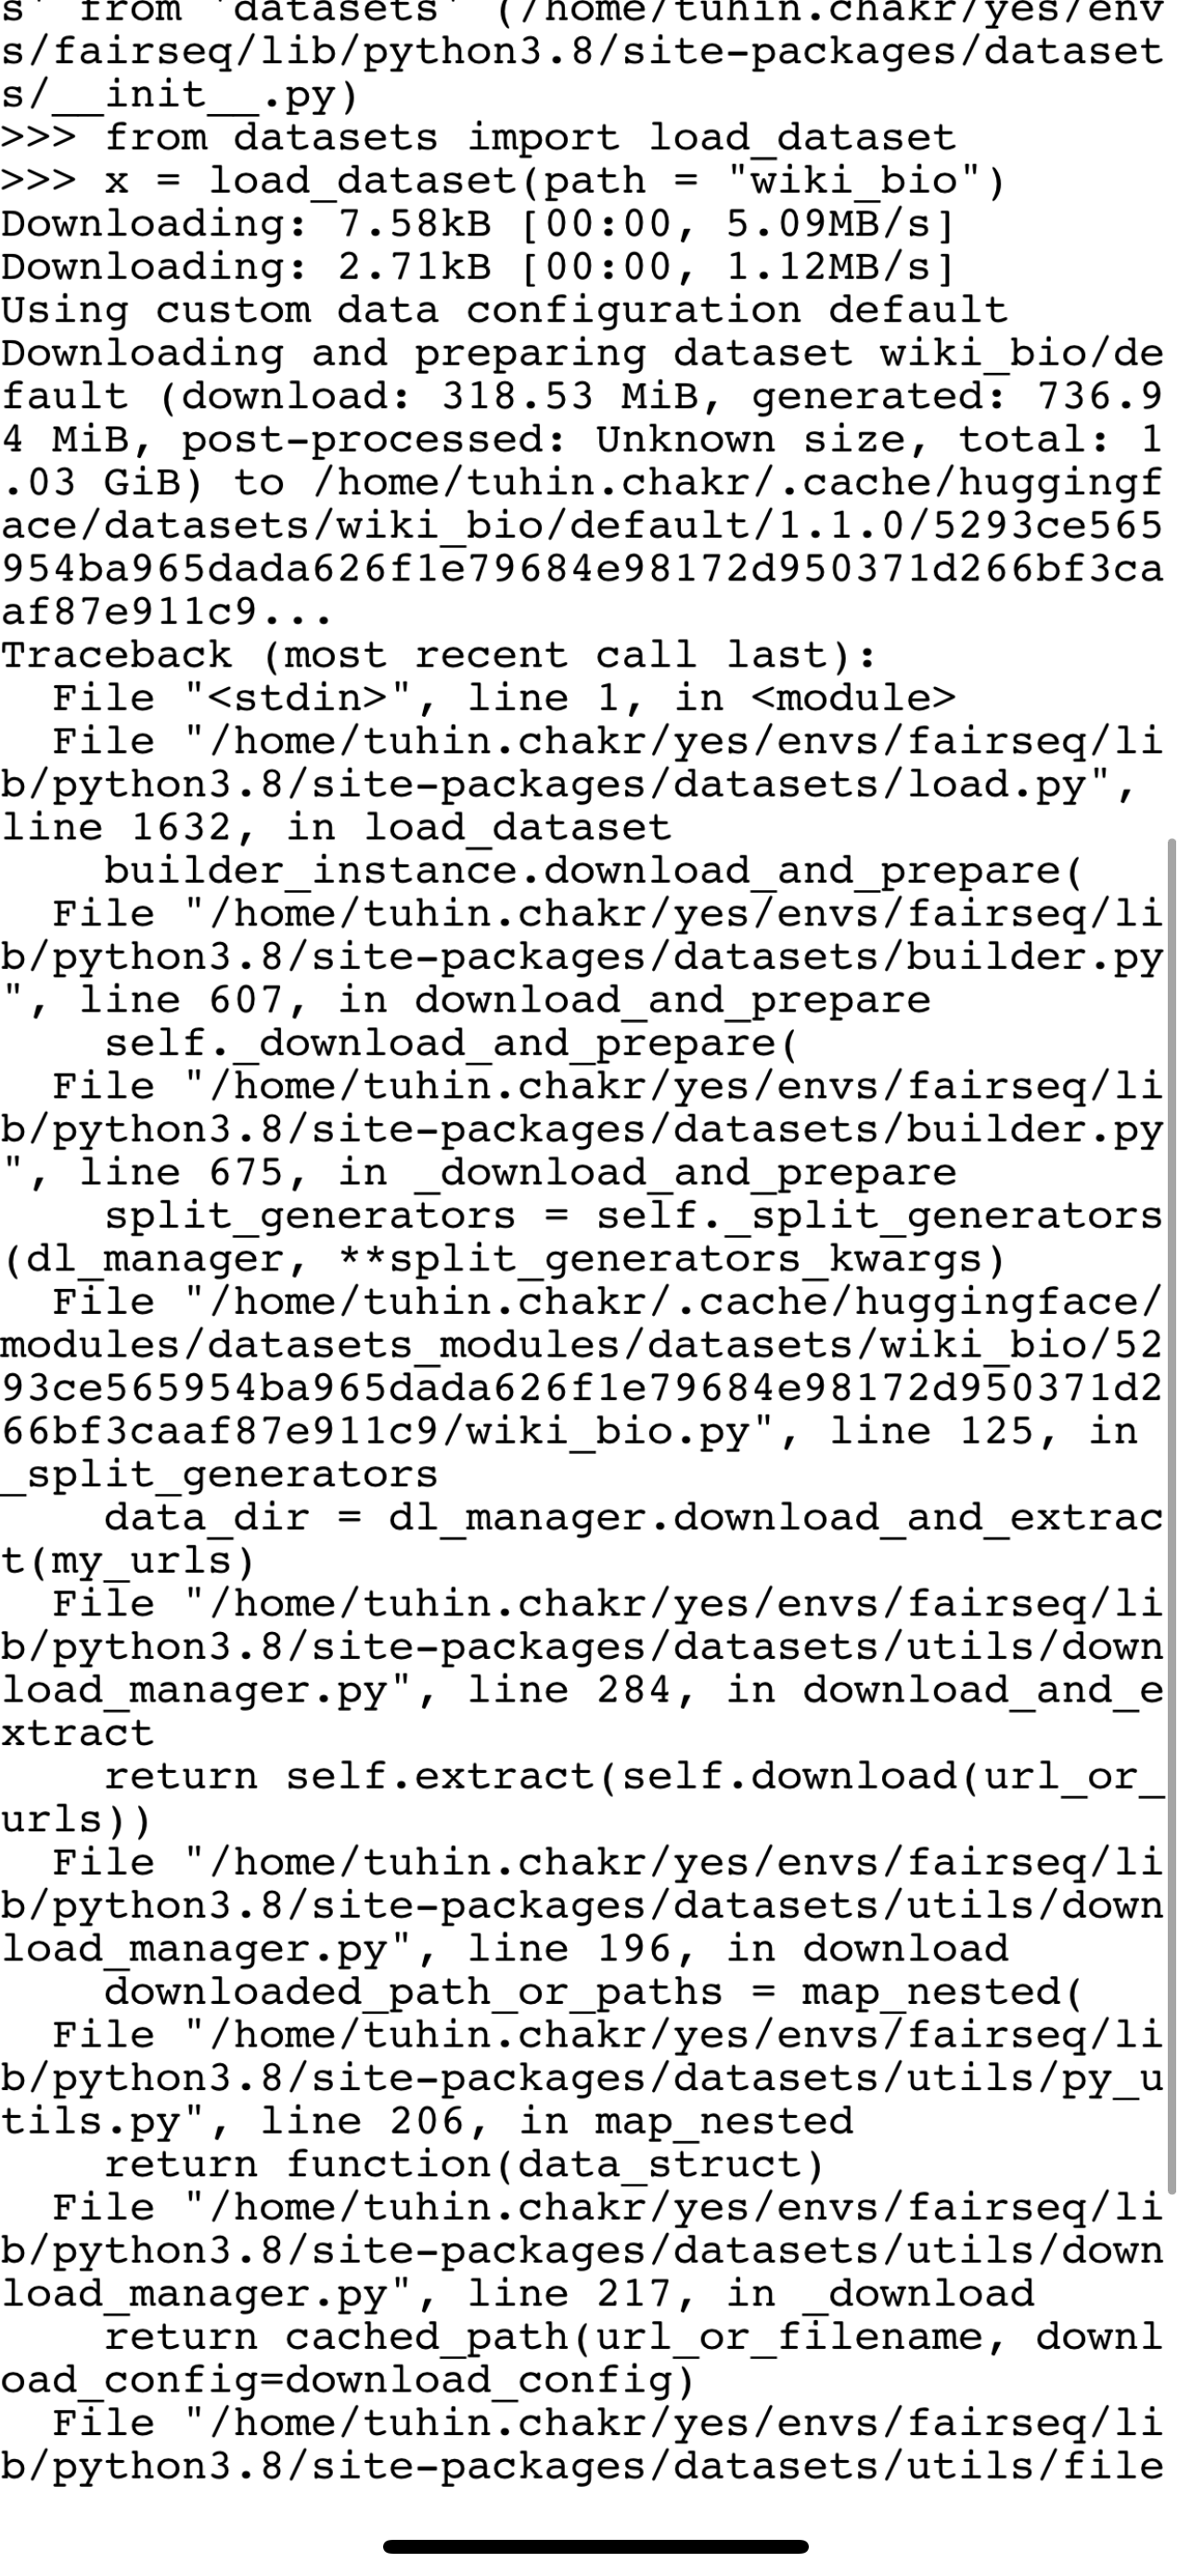


 from here: https://github.com/DavidGrangier/wikipedia-biography-dataset |
wiki_bio is failing to load because of a failing drive link . Can someone fix this ?


 |
wiki_bio is failing to load because of a failing drive link . Can someone fix this ?



dataset = dataset.with_format("numpy")
print(d... | ### Describe the bug
Previously it was possible to access a whole column that was e.g. in numpy format via `with_format` by indexing the column. Now this possibility seems to be gone with the new Column() class. As far as I see, this makes working on a whole column (in-memory) more complex, i.e. normalizing an in-memo... | 49 | Release 4.0.0 breaks usage patterns of with_format
### Describe the bug
Previously it was possible to access a whole column that was e.g. in numpy format via `with_format` by indexing the column. Now this possibility seems to be gone with the new Column() class. As far as I see, this makes working on a whole column (i... |
https://github.com/huggingface/datasets/issues/4730 | Loading imagenet-1k validation split takes much more RAM than expected | My bad, `482 * 418 * 50000 * 3 / 1000000 = 30221 MB` ( https://stackoverflow.com/a/42979315 ).
Meanwhile `256 * 256 * 50000 * 3 / 1000000 = 9830 MB`. We are loading the non-cropped images and that is why we take so much RAM. | ## Describe the bug
Loading into memory the validation split of imagenet-1k takes much more RAM than expected. Assuming ImageNet-1k is 150 GB, split is 50000 validation images and 1,281,167 train images, I would expect only about 6 GB loaded in RAM.
## Steps to reproduce the bug
```python
from datasets import... | 45 | Loading imagenet-1k validation split takes much more RAM than expected
## Describe the bug
Loading into memory the validation split of imagenet-1k takes much more RAM than expected. Assuming ImageNet-1k is 150 GB, split is 50000 validation images and 1,281,167 train images, I would expect only about 6 GB loaded in R... |
https://github.com/huggingface/datasets/issues/7510 | Incompatibile dill version (0.3.9) in datasets 2.18.0 - 3.5.0 | Hi ! We can bump `dill` to 0.3.9 if we make sure it's deterministic and doesn't break the caching mechanism in `datasets`.
Would you be interested in opening a PR ? Then we can run the CI to see if it works | ### Describe the bug
Datasets 2.18.0 - 3.5.0 has a dependency on dill < 0.3.9. This causes errors with dill >= 0.3.9.
Could you please take a look into it and make it compatible?
### Steps to reproduce the bug
1. Install setuptools >= 2.18.0
2. Install dill >=0.3.9
3. Run pip check
4. Output:
ERROR: pip's dependenc... | 42 | Incompatibile dill version (0.3.9) in datasets 2.18.0 - 3.5.0
### Describe the bug
Datasets 2.18.0 - 3.5.0 has a dependency on dill < 0.3.9. This causes errors with dill >= 0.3.9.
Could you please take a look into it and make it compatible?
### Steps to reproduce the bug
1. Install setuptools >= 2.18.0
2. Install d... |
https://github.com/huggingface/datasets/issues/7510 | Incompatibile dill version (0.3.9) in datasets 2.18.0 - 3.5.0 | There are probably some usage of internal functions from `dill` that we'll need to update in `datasets`
If you run `pytest tests/test_fingerprint.py` you should already have a good idea of what works and what doesn't.
But feel free to open a PR anyway, this way we can run the full CI and see the results
| ### Describe the bug
Datasets 2.18.0 - 3.5.0 has a dependency on dill < 0.3.9. This causes errors with dill >= 0.3.9.
Could you please take a look into it and make it compatible?
### Steps to reproduce the bug
1. Install setuptools >= 2.18.0
2. Install dill >=0.3.9
3. Run pip check
4. Output:
ERROR: pip's dependenc... | 55 | Incompatibile dill version (0.3.9) in datasets 2.18.0 - 3.5.0
### Describe the bug
Datasets 2.18.0 - 3.5.0 has a dependency on dill < 0.3.9. This causes errors with dill >= 0.3.9.
Could you please take a look into it and make it compatible?
### Steps to reproduce the bug
1. Install setuptools >= 2.18.0
2. Install d... |
https://github.com/huggingface/datasets/issues/7510 | Incompatibile dill version (0.3.9) in datasets 2.18.0 - 3.5.0 | Created pull request: [LINK](https://github.com/huggingface/datasets/pull/7535)
Tried to run tests by using command you have send and got few errors:
 | ### Describe the bug
Datasets 2.18.0 - 3.5.0 has a dependency on dill < 0.3.9. This causes errors with dill >= 0.3.9.
Could you please take a look into it and make it compatible?
### Steps to reproduce the bug
1. Install setuptools >= 2.18.0
2. Install dill >=0.3.9
3. Run pip check
4. Output:
ERROR: pip's dependenc... | 19 | Incompatibile dill version (0.3.9) in datasets 2.18.0 - 3.5.0
### Describe the bug
Datasets 2.18.0 - 3.5.0 has a dependency on dill < 0.3.9. This causes errors with dill >= 0.3.9.
Could you please take a look into it and make it compatible?
### Steps to reproduce the bug
1. Install setuptools >= 2.18.0
2. Install d... |
https://github.com/huggingface/datasets/issues/7510 | Incompatibile dill version (0.3.9) in datasets 2.18.0 - 3.5.0 | Thanks for running the test ! So it appears we have two issues to fix:
1. 'log' is not defined: it seems an internal `dill` function has disappeared, so we should adapt the `datasets` code that was using it
2. there are some hashes mismatches, which means `dill` doesn't seem to output the same dump when passed the same... | ### Describe the bug
Datasets 2.18.0 - 3.5.0 has a dependency on dill < 0.3.9. This causes errors with dill >= 0.3.9.
Could you please take a look into it and make it compatible?
### Steps to reproduce the bug
1. Install setuptools >= 2.18.0
2. Install dill >=0.3.9
3. Run pip check
4. Output:
ERROR: pip's dependenc... | 76 | Incompatibile dill version (0.3.9) in datasets 2.18.0 - 3.5.0
### Describe the bug
Datasets 2.18.0 - 3.5.0 has a dependency on dill < 0.3.9. This causes errors with dill >= 0.3.9.
Could you please take a look into it and make it compatible?
### Steps to reproduce the bug
1. Install setuptools >= 2.18.0
2. Install d... |
https://github.com/huggingface/datasets/issues/4112 | ImageFolder with Grayscale images dataset | Hi! Replacing:
```python
transformed_dataset = dataset.with_transform(transforms)
transformed_dataset.set_format(type="torch", device="cuda")
```
with:
```python
def transform_func(examples):
examples["image"] = [transforms(img).to("cuda") for img in examples["image"]]
return examples
transformed_... | Hi, I'm facing a problem with a grayscale images dataset I have uploaded [here](https://huggingface.co/datasets/ChainYo/rvl-cdip) (RVL-CDIP)
I'm getting an error while I want to use images for training a model with PyTorch DataLoader. Here is the full traceback:
```bash
AttributeError: Caught AttributeError in D... | 89 | ImageFolder with Grayscale images dataset
Hi, I'm facing a problem with a grayscale images dataset I have uploaded [here](https://huggingface.co/datasets/ChainYo/rvl-cdip) (RVL-CDIP)
I'm getting an error while I want to use images for training a model with PyTorch DataLoader. Here is the full traceback:
```bash
... |
https://github.com/huggingface/datasets/issues/4112 | ImageFolder with Grayscale images dataset | Ok thanks a lot for the code snippet!
I love the way `datasets` is easy to use but it made it really long to pre-process all the images (400.000 in my case) before training anything. `ImageFolder` from pytorch is faster in my case but force me to have the images on my local machine.
I don't know how to speed up t... | Hi, I'm facing a problem with a grayscale images dataset I have uploaded [here](https://huggingface.co/datasets/ChainYo/rvl-cdip) (RVL-CDIP)
I'm getting an error while I want to use images for training a model with PyTorch DataLoader. Here is the full traceback:
```bash
AttributeError: Caught AttributeError in D... | 68 | ImageFolder with Grayscale images dataset
Hi, I'm facing a problem with a grayscale images dataset I have uploaded [here](https://huggingface.co/datasets/ChainYo/rvl-cdip) (RVL-CDIP)
I'm getting an error while I want to use images for training a model with PyTorch DataLoader. Here is the full traceback:
```bash
... |
https://github.com/huggingface/datasets/issues/4112 | ImageFolder with Grayscale images dataset | You can pass `ignore_verifications=True` in `load_dataset` to skip checksum verification, which takes a lot of time if the number of files is large. We will consider making this the default behavior. | Hi, I'm facing a problem with a grayscale images dataset I have uploaded [here](https://huggingface.co/datasets/ChainYo/rvl-cdip) (RVL-CDIP)
I'm getting an error while I want to use images for training a model with PyTorch DataLoader. Here is the full traceback:
```bash
AttributeError: Caught AttributeError in D... | 31 | ImageFolder with Grayscale images dataset
Hi, I'm facing a problem with a grayscale images dataset I have uploaded [here](https://huggingface.co/datasets/ChainYo/rvl-cdip) (RVL-CDIP)
I'm getting an error while I want to use images for training a model with PyTorch DataLoader. Here is the full traceback:
```bash
... |
https://github.com/huggingface/datasets/issues/6851 | load_dataset('emotion') UnicodeDecodeError | I met the same problem, here is my code:
```
from datasets import load_dataset
ds_name = "togethercomputer/RedPajama-Data-1T"
ds = load_dataset(ds_name, download_mode=DownloadMode.FORCE_REDOWNLOAD)
```
And output error is:
```
Traceback (most recent call last):
File "/home/yatorho/doc/projs/TransformerEngi... | ### Describe the bug
**emotions = load_dataset('emotion')**
_UnicodeDecodeError: 'utf-8' codec can't decode byte 0x8b in position 1: invalid start byte_
### Steps to reproduce the bug
load_dataset('emotion')
### Expected behavior
succese
### Environment info
py3.10
transformers 4.41.0.dev0
datasets 2.... | 118 | load_dataset('emotion') UnicodeDecodeError
### Describe the bug
**emotions = load_dataset('emotion')**
_UnicodeDecodeError: 'utf-8' codec can't decode byte 0x8b in position 1: invalid start byte_
### Steps to reproduce the bug
load_dataset('emotion')
### Expected behavior
succese
### Environment info
py3.... |
https://github.com/huggingface/datasets/issues/6851 | load_dataset('emotion') UnicodeDecodeError | > I met the same problem, here is my code:
>
> ```
> from datasets import load_dataset
>
> ds_name = "togethercomputer/RedPajama-Data-1T"
> ds = load_dataset(ds_name, download_mode=DownloadMode.FORCE_REDOWNLOAD)
> ```
>
> And output error is:
>
> ```
> Traceback (most recent call last):
> File "/home... | ### Describe the bug
**emotions = load_dataset('emotion')**
_UnicodeDecodeError: 'utf-8' codec can't decode byte 0x8b in position 1: invalid start byte_
### Steps to reproduce the bug
load_dataset('emotion')
### Expected behavior
succese
### Environment info
py3.10
transformers 4.41.0.dev0
datasets 2.... | 170 | load_dataset('emotion') UnicodeDecodeError
### Describe the bug
**emotions = load_dataset('emotion')**
_UnicodeDecodeError: 'utf-8' codec can't decode byte 0x8b in position 1: invalid start byte_
### Steps to reproduce the bug
load_dataset('emotion')
### Expected behavior
succese
### Environment info
py3.... |
https://github.com/huggingface/datasets/issues/7766 | cast columns to Image/Audio/Video with `storage_options` | > ### Feature request
> Allow `storage_options` to be passed in
>
> 1. `cast` related operations (e.g., `cast_columns, cast`)
> 2. `info` related reading (e.g., `from_dict, from_pandas, from_polars`) together with `info.features`
>
> import datasets
>
> image_path = "s3://bucket/sample.png"
> dataset = datasets.Data... | ### Feature request
Allow `storage_options` to be passed in
1. `cast` related operations (e.g., `cast_columns, cast`)
2. `info` related reading (e.g., `from_dict, from_pandas, from_polars`) together with `info.features`
```python3
import datasets
image_path = "s3://bucket/sample.png"
dataset = datasets.Dataset.from_d... | 122 | cast columns to Image/Audio/Video with `storage_options`
### Feature request
Allow `storage_options` to be passed in
1. `cast` related operations (e.g., `cast_columns, cast`)
2. `info` related reading (e.g., `from_dict, from_pandas, from_polars`) together with `info.features`
```python3
import datasets
image_path = "... |
https://github.com/huggingface/datasets/issues/5088 | load_datasets("json", ...) don't read local .json.gz properly | Hi @junwang-wish, thanks for reporting.
Unfortunately, I'm not able to reproduce the bug. Which version of `datasets` are you using? Does the problem persist if you update `datasets`?
```shell
pip install -U datasets
``` | ## Describe the bug
I have a local file `*.json.gz` and it can be read by `pandas.read_json(lines=True)`, but cannot be read by `load_datasets("json")` (resulting in 0 lines)
## Steps to reproduce the bug
```python
fpath = '/data/junwang/.cache/general/57b6f2314cbe0bc45dda5b78f0871df2/test.json.gz'
ds_panda = Da... | 34 | load_datasets("json", ...) don't read local .json.gz properly
## Describe the bug
I have a local file `*.json.gz` and it can be read by `pandas.read_json(lines=True)`, but cannot be read by `load_datasets("json")` (resulting in 0 lines)
## Steps to reproduce the bug
```python
fpath = '/data/junwang/.cache/general... |
https://github.com/huggingface/datasets/issues/5088 | load_datasets("json", ...) don't read local .json.gz properly | Thanks @albertvillanova I updated `datasets` from `2.5.1` to `2.5.2` and tested copying the `json.gz` to a different directory and my mind was blown:
```python
fpath = '/data/junwang/.cache/general/57b6f2314cbe0bc45dda5b78f0871df2/test.json.gz'
ds_panda = DatasetDict(
test=Dataset.from_pandas(
pd.rea... | ## Describe the bug
I have a local file `*.json.gz` and it can be read by `pandas.read_json(lines=True)`, but cannot be read by `load_datasets("json")` (resulting in 0 lines)
## Steps to reproduce the bug
```python
fpath = '/data/junwang/.cache/general/57b6f2314cbe0bc45dda5b78f0871df2/test.json.gz'
ds_panda = Da... | 189 | load_datasets("json", ...) don't read local .json.gz properly
## Describe the bug
I have a local file `*.json.gz` and it can be read by `pandas.read_json(lines=True)`, but cannot be read by `load_datasets("json")` (resulting in 0 lines)
## Steps to reproduce the bug
```python
fpath = '/data/junwang/.cache/general... |
https://github.com/huggingface/datasets/issues/3374 | NonMatchingChecksumError for the CLUE:cluewsc2020, chid, c3 and tnews | Seems like the issue still exists,:
`Downloading and preparing dataset clue/chid (download: 127.15 MiB, generated: 259.71 MiB, post-processed: Unknown size, total: 386.86 MiB) to /mnt/cache/tanhaochen/.cache/huggingface/datasets/clue/chid/1.0.0/e55b490cb7809dcd8db31b9a87119f2e2ec87cdc060da8a9ac070b070ca3e379...
Trace... | Hi, it seems like there are updates in cluewsc2020, chid, c3 and tnews, since i could not load them due to the checksum error. | 80 | NonMatchingChecksumError for the CLUE:cluewsc2020, chid, c3 and tnews
Hi, it seems like there are updates in cluewsc2020, chid, c3 and tnews, since i could not load them due to the checksum error.
Seems like the issue still exists,:
`Downloading and preparing dataset clue/chid (download: 127.15 MiB, generated: 259.71 ... |
https://github.com/huggingface/datasets/issues/6558 | OSError: image file is truncated (1 bytes not processed) #28323 | You can add
```python
from PIL import ImageFile
ImageFile.LOAD_TRUNCATED_IMAGES = True
```
after the imports to be able to read truncated images. | ### Describe the bug
```
---------------------------------------------------------------------------
OSError Traceback (most recent call last)
Cell In[24], line 28
23 return example
25 # Filter the dataset
26 # filtered_dataset = dataset.filter(contains_number... | 22 | OSError: image file is truncated (1 bytes not processed) #28323
### Describe the bug
```
---------------------------------------------------------------------------
OSError Traceback (most recent call last)
Cell In[24], line 28
23 return example
25 # Filter the data... |
https://github.com/huggingface/datasets/issues/7549 | TypeError: Couldn't cast array of type string to null on webdataset format dataset | seems to get fixed by explicitly adding `dataset_infos.json` like this
```json
{
"default": {
"description": "Image dataset with tags and ratings",
"citation": "",
"homepage": "",
"license": "",
"features": {
"image": {
"dtype": "image",
"_type": "Image"
},
"json... | ### Describe the bug
```python
from datasets import load_dataset
dataset = load_dataset("animetimm/danbooru-wdtagger-v4-w640-ws-30k")
```
got
```
File "/home/ubuntu/miniconda3/lib/python3.10/site-packages/datasets/arrow_writer.py", line 626, in write_batch
arrays.append(pa.array(typed_sequence))
File "pyarro... | 126 | TypeError: Couldn't cast array of type string to null on webdataset format dataset
### Describe the bug
```python
from datasets import load_dataset
dataset = load_dataset("animetimm/danbooru-wdtagger-v4-w640-ws-30k")
```
got
```
File "/home/ubuntu/miniconda3/lib/python3.10/site-packages/datasets/arrow_writer.py", ... |
https://github.com/huggingface/datasets/issues/7549 | TypeError: Couldn't cast array of type string to null on webdataset format dataset | The root cause is that the webdataset builder infers types from the first 5 examples only, so a JSON field that is null/empty in all of them gets frozen as arrow `null` and the first real value fails the cast — the inference now keeps scanning examples until every field has a concrete type. Fix in #8267.
| ### Describe the bug
```python
from datasets import load_dataset
dataset = load_dataset("animetimm/danbooru-wdtagger-v4-w640-ws-30k")
```
got
```
File "/home/ubuntu/miniconda3/lib/python3.10/site-packages/datasets/arrow_writer.py", line 626, in write_batch
arrays.append(pa.array(typed_sequence))
File "pyarro... | 57 | TypeError: Couldn't cast array of type string to null on webdataset format dataset
### Describe the bug
```python
from datasets import load_dataset
dataset = load_dataset("animetimm/danbooru-wdtagger-v4-w640-ws-30k")
```
got
```
File "/home/ubuntu/miniconda3/lib/python3.10/site-packages/datasets/arrow_writer.py", ... |
https://github.com/huggingface/datasets/issues/3990 | Improve AutomaticSpeechRecognition task template | There is an open PR to do that: #3364. I just haven't had time to finish it... | **Is your feature request related to a problem? Please describe.**
[AutomaticSpeechRecognition task template](https://github.com/huggingface/datasets/blob/master/src/datasets/tasks/automatic_speech_recognition.py) is outdated as it uses path to audiofile as an audio column instead of a Audio feature itself (I guess it... | 17 | Improve AutomaticSpeechRecognition task template
**Is your feature request related to a problem? Please describe.**
[AutomaticSpeechRecognition task template](https://github.com/huggingface/datasets/blob/master/src/datasets/tasks/automatic_speech_recognition.py) is outdated as it uses path to audiofile as an audio col... |
https://github.com/huggingface/datasets/issues/3990 | Improve AutomaticSpeechRecognition task template | > There is an open PR to do that: #3364. I just haven't had time to finish it...
😬 thanks... | **Is your feature request related to a problem? Please describe.**
[AutomaticSpeechRecognition task template](https://github.com/huggingface/datasets/blob/master/src/datasets/tasks/automatic_speech_recognition.py) is outdated as it uses path to audiofile as an audio column instead of a Audio feature itself (I guess it... | 20 | Improve AutomaticSpeechRecognition task template
**Is your feature request related to a problem? Please describe.**
[AutomaticSpeechRecognition task template](https://github.com/huggingface/datasets/blob/master/src/datasets/tasks/automatic_speech_recognition.py) is outdated as it uses path to audiofile as an audio col... |
https://github.com/huggingface/datasets/issues/7345 | Different behaviour of IterableDataset.map vs Dataset.map with remove_columns | Good catch ! Do you think you can open a PR to fix this issue ? | ### Describe the bug
The following code
```python
import datasets as hf
ds1 = hf.Dataset.from_list([{'i': i} for i in [0,1]])
#ds1 = ds1.to_iterable_dataset()
ds2 = ds1.map(
lambda i: {'i': i+1},
input_columns = ['i'],
remove_columns = ['i']
)
list(ds2)
```
produces
```python
[{'i': ... | 16 | Different behaviour of IterableDataset.map vs Dataset.map with remove_columns
### Describe the bug
The following code
```python
import datasets as hf
ds1 = hf.Dataset.from_list([{'i': i} for i in [0,1]])
#ds1 = ds1.to_iterable_dataset()
ds2 = ds1.map(
lambda i: {'i': i+1},
input_columns = ['i'],
... |
https://github.com/huggingface/datasets/issues/6392 | `push_to_hub` is not robust to hub closing connection | Hi! We made some improvements to `push_to_hub` to make it more robust a couple of weeks ago but haven't published a release in the meantime, so it would help if you could install `datasets` from `main` (`pip install https://github.com/huggingface/datasets`) and let us know if this improved version of `push_to_hub` reso... | ### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/admin/home-piraka9011/.virtualenvs/w2v2/lib/python3.8/... | 86 | `push_to_hub` is not robust to hub closing connection
### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/... |
https://github.com/huggingface/datasets/issues/6392 | `push_to_hub` is not robust to hub closing connection | The update helped push more data.
However it still crashed a little later:
```
Traceback (most recent call last):
File "/admin/home-piraka9011/.virtualenvs/w2v2/lib/python3.8/site-packages/huggingface_hub/utils/_errors.py", line 270, in hf_raise_for_status
response.raise_for_status()
File "/admin/home-p... | ### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/admin/home-piraka9011/.virtualenvs/w2v2/lib/python3.8/... | 223 | `push_to_hub` is not robust to hub closing connection
### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/... |
https://github.com/huggingface/datasets/issues/6392 | `push_to_hub` is not robust to hub closing connection | I think the previous implementation was actually better: it pushes to the hub every shard. So if it fails, as long as the shards have the same checksum, it will skip the ones that have been pushed.
The implementation in `main` pushes commits at the end, so when it fails, there are no commits and therefore restarts f... | ### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/admin/home-piraka9011/.virtualenvs/w2v2/lib/python3.8/... | 312 | `push_to_hub` is not robust to hub closing connection
### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/... |
https://github.com/huggingface/datasets/issues/6392 | `push_to_hub` is not robust to hub closing connection | There's a new error from the hub now:
```
Pushing dataset shards to the dataset hub: 49%|████▉ | 128/261 [11:38<12:05, 5.45s/it]
Traceback (most recent call last):
File "/admin/home-piraka9011/.virtualenvs/w2v2/lib/python3.8/site-packages/huggingface_hub/utils/_errors.py", line 270, in hf_raise_for_status
... | ### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/admin/home-piraka9011/.virtualenvs/w2v2/lib/python3.8/... | 225 | `push_to_hub` is not robust to hub closing connection
### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/... |
https://github.com/huggingface/datasets/issues/6392 | `push_to_hub` is not robust to hub closing connection | > think the previous implementation was actually better: it pushes to the hub every shard. So if it fails, as long as the shards have the same checksum, it will skip the ones that have been pushed.
>
>The implementation in main pushes commits at the end, so when it fails, there are no commits and therefore restarts ... | ### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/admin/home-piraka9011/.virtualenvs/w2v2/lib/python3.8/... | 178 | `push_to_hub` is not robust to hub closing connection
### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/... |
https://github.com/huggingface/datasets/issues/6392 | `push_to_hub` is not robust to hub closing connection | But I agree that the `500 Server Error` returned by the Hub is annoying. Earlier today, I also got it on a small 5GB dataset (with 500 MB shards).
@Wauplin @julien-c Is there something we can do about this? | ### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/admin/home-piraka9011/.virtualenvs/w2v2/lib/python3.8/... | 39 | `push_to_hub` is not robust to hub closing connection
### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/... |
https://github.com/huggingface/datasets/issues/6392 | `push_to_hub` is not robust to hub closing connection | @mariosasko can't do much if AWS raises a HTTP 500 unfortunately (we are simply pushing data to a S3 bucket).
What we can do is to add a retry mechanism in the multi-part upload logic here: https://github.com/huggingface/huggingface_hub/blob/c972cba1fecb456a7b3325cdd1fdbcc425f21f94/src/huggingface_hub/lfs.py#L370 :con... | ### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/admin/home-piraka9011/.virtualenvs/w2v2/lib/python3.8/... | 38 | `push_to_hub` is not robust to hub closing connection
### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/... |
https://github.com/huggingface/datasets/issues/6392 | `push_to_hub` is not robust to hub closing connection | > That code already retries the request using http_backoff, no?
Currently only on HTTP 503 by default. We should add 500 as well (and hope it is a transient error from AWS) | ### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/admin/home-piraka9011/.virtualenvs/w2v2/lib/python3.8/... | 32 | `push_to_hub` is not robust to hub closing connection
### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/... |
https://github.com/huggingface/datasets/issues/6392 | `push_to_hub` is not robust to hub closing connection | Opened a PR to retry in case S3 raises HTTP 500. Will also retry on any `ConnectionError` (connection reset by peer, connection lost,...). Hopefully this should make the upload process more robust to transient errors. | ### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/admin/home-piraka9011/.virtualenvs/w2v2/lib/python3.8/... | 35 | `push_to_hub` is not robust to hub closing connection
### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/... |
https://github.com/huggingface/datasets/issues/6392 | `push_to_hub` is not robust to hub closing connection | I still get the same error, using `push_to_hub`. Using `git lfs` and pushing the files solved it for me. | ### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/admin/home-piraka9011/.virtualenvs/w2v2/lib/python3.8/... | 19 | `push_to_hub` is not robust to hub closing connection
### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/... |
https://github.com/huggingface/datasets/issues/6392 | `push_to_hub` is not robust to hub closing connection | @BEpresent the fix has not been released yet. You can expect a release of `huggingface_hub` (with this fix) today or tomorrow :) | ### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/admin/home-piraka9011/.virtualenvs/w2v2/lib/python3.8/... | 22 | `push_to_hub` is not robust to hub closing connection
### Describe the bug
Like to #6172, `push_to_hub` will crash if Hub resets the connection and raise the following error:
```
Pushing dataset shards to the dataset hub: 32%|███▏ | 54/171 [06:38<14:23, 7.38s/it]
Traceback (most recent call last):
File "/... |
https://github.com/huggingface/datasets/issues/5638 | xPath to implement all operations for Path | I think https://github.com/fsspec/universal_pathlib is the project you are looking for.
`xPath` has the methods often used in dataset scripts, and `mkdir` is not one of them (`dl_manager`'s role is to "interact" with the file system, so using `mkdir` is discouraged). | ### Feature request
Current xPath implementation is a great extension of Path in order to work with remote objects. However some methods such as `mkdir` are not implemented correctly. It should instead rely on `fsspec` methods, instead of defaulting do `Path` methods which only work locally.
### Motivation
I'm using... | 40 | xPath to implement all operations for Path
### Feature request
Current xPath implementation is a great extension of Path in order to work with remote objects. However some methods such as `mkdir` are not implemented correctly. It should instead rely on `fsspec` methods, instead of defaulting do `Path` methods which on... |
https://github.com/huggingface/datasets/issues/5638 | xPath to implement all operations for Path | Right is there a difference between UPath and xPath? Typically is xPath less well implemented compared to Upath, ie missing some implementations of some methods? Or are there methods in xPath that are not implemented with UPath? | ### Feature request
Current xPath implementation is a great extension of Path in order to work with remote objects. However some methods such as `mkdir` are not implemented correctly. It should instead rely on `fsspec` methods, instead of defaulting do `Path` methods which only work locally.
### Motivation
I'm using... | 37 | xPath to implement all operations for Path
### Feature request
Current xPath implementation is a great extension of Path in order to work with remote objects. However some methods such as `mkdir` are not implemented correctly. It should instead rely on `fsspec` methods, instead of defaulting do `Path` methods which on... |
https://github.com/huggingface/datasets/issues/5638 | xPath to implement all operations for Path | `xPath` is an internal component (it doesn't have a leading underscore in the name, but it should) not meant to be used outside of `datasets`, and it's only tested on HTTP URLs, not S3.
| ### Feature request
Current xPath implementation is a great extension of Path in order to work with remote objects. However some methods such as `mkdir` are not implemented correctly. It should instead rely on `fsspec` methods, instead of defaulting do `Path` methods which only work locally.
### Motivation
I'm using... | 34 | xPath to implement all operations for Path
### Feature request
Current xPath implementation is a great extension of Path in order to work with remote objects. However some methods such as `mkdir` are not implemented correctly. It should instead rely on `fsspec` methods, instead of defaulting do `Path` methods which on... |
https://github.com/huggingface/datasets/issues/5638 | xPath to implement all operations for Path | Okay I understand that xPath won't support my usecase. What I was perhaps getting to is why not use UPath in `datasets` instead of `xPath` if UPath seems to have strictly more robust implementations. | ### Feature request
Current xPath implementation is a great extension of Path in order to work with remote objects. However some methods such as `mkdir` are not implemented correctly. It should instead rely on `fsspec` methods, instead of defaulting do `Path` methods which only work locally.
### Motivation
I'm using... | 34 | xPath to implement all operations for Path
### Feature request
Current xPath implementation is a great extension of Path in order to work with remote objects. However some methods such as `mkdir` are not implemented correctly. It should instead rely on `fsspec` methods, instead of defaulting do `Path` methods which on... |
https://github.com/huggingface/datasets/issues/5638 | xPath to implement all operations for Path | It seems like `universal_pathlib` does not support `fsspec` URL chaining (`::` is the chaining symbol) and "compression" filesystems (e.g., `zip`), but this is what we need to access and stream files from within an archive (e.g., we want to stream URLs such as this one: `zip://data.parquet::https://www.dummyurl.com/arc... | ### Feature request
Current xPath implementation is a great extension of Path in order to work with remote objects. However some methods such as `mkdir` are not implemented correctly. It should instead rely on `fsspec` methods, instead of defaulting do `Path` methods which only work locally.
### Motivation
I'm using... | 46 | xPath to implement all operations for Path
### Feature request
Current xPath implementation is a great extension of Path in order to work with remote objects. However some methods such as `mkdir` are not implemented correctly. It should instead rely on `fsspec` methods, instead of defaulting do `Path` methods which on... |
https://github.com/huggingface/datasets/issues/5895 | The dir name and split strings are confused when loading ArmelR/stack-exchange-instruction dataset | Thanks for reporting, @DongHande.
I think the issue is caused by the metadata in the dataset card: in the header of the `README.md`, they state that the dataset has 4 splits ("finetune", "reward", "rl", "evaluation").
```yaml
splits:
- name: finetune
num_bytes: 6674567576
num_examples: 300000... | ### Describe the bug
When I load the ArmelR/stack-exchange-instruction dataset, I encounter a bug that may be raised by confusing the dir name string and the split string about the dataset.
When I use the script "datasets.load_dataset('ArmelR/stack-exchange-instruction', data_dir="data/finetune", split="train", ... | 122 | The dir name and split strings are confused when loading ArmelR/stack-exchange-instruction dataset
### Describe the bug
When I load the ArmelR/stack-exchange-instruction dataset, I encounter a bug that may be raised by confusing the dir name string and the split string about the dataset.
When I use the script "d... |
https://github.com/huggingface/datasets/issues/7141 | Older datasets throwing safety errors with 2.21.0 | same observation. I even downgraded `datasets==2.20.0` and `huggingface_hub==0.23.5` leading me to believe it's an issue on the server.
any known workarounds?
| ### Describe the bug
The dataset loading was throwing some safety errors for this popular dataset `wmt14`.
[in]:
```
import datasets
# train_data = datasets.load_dataset("wmt14", "de-en", split="train")
train_data = datasets.load_dataset("wmt14", "de-en", split="train")
val_data = datasets.load_dataset(... | 21 | Older datasets throwing safety errors with 2.21.0
### Describe the bug
The dataset loading was throwing some safety errors for this popular dataset `wmt14`.
[in]:
```
import datasets
# train_data = datasets.load_dataset("wmt14", "de-en", split="train")
train_data = datasets.load_dataset("wmt14", "de-en",... |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.