
html_url stringlengths 51 51 | title stringlengths 9 280 | comments stringlengths 63 24.7k | body stringlengths 51 58.6k | comments length int64 16 1.45k | text stringlengths 186 59.1k |
|---|---|---|---|---|---|
https://github.com/huggingface/datasets/issues/6985 | AttributeError: module 'pyarrow.lib' has no attribute 'ListViewType' | but now i cant run test, so i remove it, ERROR: Could not find a version that satisfies the requirement pyarrow.parquet (from versions: none)
ERROR: No matching distribution found for pyarrow.parquet will still running but will tell you this | ### Describe the bug
I have been struggling with this for two days, any help would be appreciated. Python 3.10
```
from setfit import SetFitModel
from huggingface_hub import login
access_token_read = "cccxxxccc"
# Authenticate with the Hugging Face Hub
login(token=access_token_read)
# Load the models fr... | 39 | AttributeError: module 'pyarrow.lib' has no attribute 'ListViewType'
### Describe the bug
I have been struggling with this for two days, any help would be appreciated. Python 3.10
```
from setfit import SetFitModel
from huggingface_hub import login
access_token_read = "cccxxxccc"
# Authenticate with the Hug... |
https://github.com/huggingface/datasets/issues/6985 | AttributeError: module 'pyarrow.lib' has no attribute 'ListViewType' | I did most of the suggestions above and I still got the error, but after restarting my computer the error was fixed | ### Describe the bug
I have been struggling with this for two days, any help would be appreciated. Python 3.10
```
from setfit import SetFitModel
from huggingface_hub import login
access_token_read = "cccxxxccc"
# Authenticate with the Hugging Face Hub
login(token=access_token_read)
# Load the models fr... | 22 | AttributeError: module 'pyarrow.lib' has no attribute 'ListViewType'
### Describe the bug
I have been struggling with this for two days, any help would be appreciated. Python 3.10
```
from setfit import SetFitModel
from huggingface_hub import login
access_token_read = "cccxxxccc"
# Authenticate with the Hug... |
https://github.com/huggingface/datasets/issues/5877 | Request for text deduplication feature | The "exact match" deduplication will be possible when we resolve https://github.com/huggingface/datasets/issues/2514 (first, https://github.com/apache/arrow/issues/30950 needs to be addressed on the Arrow side). In the meantime, you can use Polars or DuckDB (e.g., via [datasets-sql](https://github.com/mariosasko/datase... | ### Feature request
It would be great if there would be support for high performance, highly scalable text deduplication algorithms as part of the datasets library.
### Motivation
Motivated by this blog post https://huggingface.co/blog/dedup and this library https://github.com/google-research/deduplicate-text-datase... | 47 | Request for text deduplication feature
### Feature request
It would be great if there would be support for high performance, highly scalable text deduplication algorithms as part of the datasets library.
### Motivation
Motivated by this blog post https://huggingface.co/blog/dedup and this library https://github.com/... |
https://github.com/huggingface/datasets/issues/5877 | Request for text deduplication feature | I have been using polars to remove duplicates but it would be nice to do it directly in pyarrow.
For example,
1. Read dataset with pyarrow
2. Use scan_pyarrow_dataset() with Polars to create a LazyFrame
3. Use sort and unique to remove duplicates based on a subset of columns
4. Convert to table and save data w... | ### Feature request
It would be great if there would be support for high performance, highly scalable text deduplication algorithms as part of the datasets library.
### Motivation
Motivated by this blog post https://huggingface.co/blog/dedup and this library https://github.com/google-research/deduplicate-text-datase... | 104 | Request for text deduplication feature
### Feature request
It would be great if there would be support for high performance, highly scalable text deduplication algorithms as part of the datasets library.
### Motivation
Motivated by this blog post https://huggingface.co/blog/dedup and this library https://github.com/... |
https://github.com/huggingface/datasets/issues/5877 | Request for text deduplication feature | Hi
see this new release from hf [datatrove](https://github.com/huggingface/datatrove)
DataTrove is a library to process, filter and deduplicate text data at a very large scale. It provides a set of prebuilt commonly used processing blocks with a framework to easily add custom functionality | ### Feature request
It would be great if there would be support for high performance, highly scalable text deduplication algorithms as part of the datasets library.
### Motivation
Motivated by this blog post https://huggingface.co/blog/dedup and this library https://github.com/google-research/deduplicate-text-datase... | 42 | Request for text deduplication feature
### Feature request
It would be great if there would be support for high performance, highly scalable text deduplication algorithms as part of the datasets library.
### Motivation
Motivated by this blog post https://huggingface.co/blog/dedup and this library https://github.com/... |
https://github.com/huggingface/datasets/issues/7804 | Support scientific data formats | Please add the support for `Zarr`! That's what we use in the Bioimaging community. It is crucial, because raw upload of a *single* bio image can take _terrabytes in memory_!
The python library would be `bioio` or `zarr`:
- [ ] Zarr: `bioio` or `zarr`
See a [Zarr example](https://ome.github.io/ome-ngff-validator/?sour... | List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format | 51 | Support scientific data formats
List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format
Pl... |
https://github.com/huggingface/datasets/issues/7804 | Support scientific data formats | @stefanches7 `zarr` is already usable with the hf hub as an array store. See this example from the [docs](https://huggingface.co/docs/huggingface_hub/en/guides/hf_file_system):
```python
import numpy as np
import zarr
embeddings = np.random.randn(50000, 1000).astype("float32")
# Write an array to a repo
with zarr.op... | List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format | 83 | Support scientific data formats
List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format
@s... |
https://github.com/huggingface/datasets/issues/7804 | Support scientific data formats | @cakiki I think some tiling capabilities, as well as metadata / labels handling. Consult ome-zarr doc here: https://ome-zarr.readthedocs.io/en/stable/python.html
Visualization would be the cherry on the top.
cc @joshmoore @lubianat @St3V0Bay: curious what you think | List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format | 34 | Support scientific data formats
List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format
@c... |
https://github.com/huggingface/datasets/issues/7804 | Support scientific data formats | A support for BIDS it would be perfect, I think it's possible to do all the biosinal can be done with mne. There's a cool community for decoding brain signals, and now with EMG. The new META bracelet EMG is saving things in BIDS.
I can help to interface, coding and try to make this happen. I am available at hugging fa... | List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format | 76 | Support scientific data formats
List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format
A ... |
https://github.com/huggingface/datasets/issues/7804 | Support scientific data formats | If you give me the OK, I'll create the PR to make everything for a Biosignal Reader logic, I already studied the nilabel PR :) | List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format | 25 | Support scientific data formats
List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format
If... |
https://github.com/huggingface/datasets/issues/7804 | Support scientific data formats | That would be an amazing addition ! Feel free to ping me in your PR for review or if you have questions / if I can help | List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format | 27 | Support scientific data formats
List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format
Th... |
https://github.com/huggingface/datasets/issues/7804 | Support scientific data formats | @bruAristimunha @lhoestq I've recalled a gold of a resource for BIDS: https://openneuro.org/
Do you think there is a data-easy way to make those visible here on HuggingFace? Afaik they use `datalad` to fetch the data. Maybe the best way is to leave OpenNeuro as-is, not connecting it to HuggingFace at all - just an ide... | List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format | 58 | Support scientific data formats
List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format
@b... |
https://github.com/huggingface/datasets/issues/7804 | Support scientific data formats | I know an "easy" way to create interoperability with all biosignal datasets from OpenNeuro =)
For biosignal data, we can use [EEGDash](https://eegdash.org/) to create a Pytorch dataset, which automates fetch, lazy read, and converts to a pytorch dataset.
I have a question about the best serialization for a Hugging ... | List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format | 66 | Support scientific data formats
List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format
I ... |
https://github.com/huggingface/datasets/issues/7804 | Support scientific data formats | I can explain it publicly too, but I think a short 5-minute conversation would be better than many, many texts to explain the details. | List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format | 24 | Support scientific data formats
List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format
I ... |
https://github.com/huggingface/datasets/issues/7804 | Support scientific data formats | It's ok to have discussions in one place here (or in a separate issue if it's needed) - I also generally check github more often than discord ^^' | List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format | 28 | Support scientific data formats
List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format
It... |
https://github.com/huggingface/datasets/issues/7804 | Support scientific data formats | Hi @bruAristimunha @lhoestq any way we could proceed on this?
I see someone posted a Nifti vizualization PR: https://github.com/huggingface/datasets/pull/7874 - I think it would be a shame if we couldn't accompany that by a neat way to import BIDS Nifti! | List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format | 40 | Support scientific data formats
List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format
Hi... |
https://github.com/huggingface/datasets/issues/7804 | Support scientific data formats | @stefanches7 author of #7874 here, would be open to expand the current support to BIDS as well after having a brief look.
Maybe having a brief call over Discord (my username: TobiasPitters on the huggingface discord server) might help sorting things out, since I am not familiar with BIDS. So getting an understanding o... | List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format | 61 | Support scientific data formats
List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format
@s... |
https://github.com/huggingface/datasets/issues/7804 | Support scientific data formats | Hey!!
From a bids perspective, I can provide full support for all biosignal types (EEG, iEEG, MEG, EMG). BIDS is a well-established contract format; I believe we can design something that supports the entire medical domain. I think it just requires a few details to be aligned.
From my perspective, the tricky part is ... | List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format | 101 | Support scientific data formats
List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format
He... |
https://github.com/huggingface/datasets/issues/7804 | Support scientific data formats | had a discussion with @neurolabusc and here's a quick wrap-up:
- BIDS support would be huge (@bruAristimunha would be great if we could catch up on that)
- DICOM support as well, but that might be harder due to a lot of variety in how headers are handled, vendor specifics etc. So to have a reliable pipeline to intera... | List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format | 138 | Support scientific data formats
List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format
ha... |
https://github.com/huggingface/datasets/issues/7804 | Support scientific data formats | Hi @CloseChoice and @bruAristimunha, glad to meet you both! We could appoint a call; I am currently moving to a new job, so the time slots are limited, but let's connect over Discord and see what we could do.
* BIDS: our hackathon team @zuazo @ekarrieta @lakshya16157 put up a BIDS format converter: https://huggingface... | List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format | 78 | Support scientific data formats
List of formats and libraries we can use to load the data in `datasets`:
- [ ] DICOMs: pydicom
- [x] NIfTIs: nibabel
- [ ] WFDB: wfdb
cc @zaRizk7 for viz
Feel free to comment / suggest other formats and libs you'd like to see or to share your interest in one of the mentioned format
Hi... |
https://github.com/huggingface/datasets/issues/6777 | .Jsonl metadata not detected | @mariosasko it says metadata.csv not found
<img width="1150" alt="image" src="https://github.com/huggingface/datasets/assets/81643693/3754980c-6185-4413-88fa-b499bcdd4195">
dataset = load_dataset('/dataset',metadata.csv)
| workspace
|| source code
| dataset
| |-- images
| |-- metadata.csv
| |-- metadata.js... | ### Describe the bug
Hi I have the following directory structure:
|--dataset
| |-- images
| |-- metadata1000.csv
| |-- metadata1000.jsonl
| |-- padded_images
Example of metadata1000.jsonl file
{"caption": "a drawing depicts a full shot of a black t-shirt with a triangular pattern on the front there is a white... | 113 | .Jsonl metadata not detected
### Describe the bug
Hi I have the following directory structure:
|--dataset
| |-- images
| |-- metadata1000.csv
| |-- metadata1000.jsonl
| |-- padded_images
Example of metadata1000.jsonl file
{"caption": "a drawing depicts a full shot of a black t-shirt with a triangular pattern ... |
https://github.com/huggingface/datasets/issues/6777 | .Jsonl metadata not detected | Loading more than one image per row with `imagefolder` is not supported currently. You can subscribe to https://github.com/huggingface/datasets/issues/5760 to see when it will be.
Instead, you can load the dataset with `Dataset.from_generator`:
```python
import json
from datasets import Dataset, Value, Image, Fea... | ### Describe the bug
Hi I have the following directory structure:
|--dataset
| |-- images
| |-- metadata1000.csv
| |-- metadata1000.jsonl
| |-- padded_images
Example of metadata1000.jsonl file
{"caption": "a drawing depicts a full shot of a black t-shirt with a triangular pattern on the front there is a white... | 93 | .Jsonl metadata not detected
### Describe the bug
Hi I have the following directory structure:
|--dataset
| |-- images
| |-- metadata1000.csv
| |-- metadata1000.jsonl
| |-- padded_images
Example of metadata1000.jsonl file
{"caption": "a drawing depicts a full shot of a black t-shirt with a triangular pattern ... |
https://github.com/huggingface/datasets/issues/6777 | .Jsonl metadata not detected | hi Thanks for sharing this, Actually I was trying with a webdataset format of the data as well and it did'nt work. Could you share how i can create Dataset object from webdataset format of this data? | ### Describe the bug
Hi I have the following directory structure:
|--dataset
| |-- images
| |-- metadata1000.csv
| |-- metadata1000.jsonl
| |-- padded_images
Example of metadata1000.jsonl file
{"caption": "a drawing depicts a full shot of a black t-shirt with a triangular pattern on the front there is a white... | 37 | .Jsonl metadata not detected
### Describe the bug
Hi I have the following directory structure:
|--dataset
| |-- images
| |-- metadata1000.csv
| |-- metadata1000.jsonl
| |-- padded_images
Example of metadata1000.jsonl file
{"caption": "a drawing depicts a full shot of a black t-shirt with a triangular pattern ... |
https://github.com/huggingface/datasets/issues/4677 | Random 400 Client Error when pushing dataset | I am having the same issue. Even the simple example from the documentation gives me the 400 Error
> from datasets import load_dataset
>
> dataset = load_dataset("stevhliu/demo")
> dataset.push_to_hub("processed_demo")
`requests.exceptions.HTTPError: 400 Client Error: Bad Request for url: https://huggingfa... | ## Describe the bug
When pushing a dataset, the client errors randomly with `Bad Request for url:...`.
At the next call, a new parquet file is created for each shard.
The client may fail at any random shard.
## Steps to reproduce the bug
```python
dataset.push_to_hub("ORG/DATASET", private=True, branch="main")
... | 77 | Random 400 Client Error when pushing dataset
## Describe the bug
When pushing a dataset, the client errors randomly with `Bad Request for url:...`.
At the next call, a new parquet file is created for each shard.
The client may fail at any random shard.
## Steps to reproduce the bug
```python
dataset.push_to_hub... |
https://github.com/huggingface/datasets/issues/3704 | OSCAR-2109 datasets are misaligned and truncated | Hi @adrianeboyd, thanks for reporting.
There is indeed a bug in that community dataset:
Line:
```python
metadata_and_text_files = list(zip(metadata_files, text_files))
```
should be replaced with
```python
metadata_and_text_files = list(zip(sorted(metadata_files), sorted(text_files)))
```
I am going to c... | ## Describe the bug
The `oscar-corpus/OSCAR-2109` data appears to be misaligned and truncated by the dataset builder for subsets that contain more than one part and for cases where the texts contain non-unix newlines.
## Steps to reproduce the bug
A few examples, although I'm not sure how deterministic the par... | 51 | OSCAR-2109 datasets are misaligned and truncated
## Describe the bug
The `oscar-corpus/OSCAR-2109` data appears to be misaligned and truncated by the dataset builder for subsets that contain more than one part and for cases where the texts contain non-unix newlines.
## Steps to reproduce the bug
A few examples... |
https://github.com/huggingface/datasets/issues/3704 | OSCAR-2109 datasets are misaligned and truncated | That fix is part of it, but it's clearly not the only issue.
I also already contacted the OSCAR creators, but I reported it here because it looked like huggingface members were the main authors in the git history. Is there a better place to have reported this? | ## Describe the bug
The `oscar-corpus/OSCAR-2109` data appears to be misaligned and truncated by the dataset builder for subsets that contain more than one part and for cases where the texts contain non-unix newlines.
## Steps to reproduce the bug
A few examples, although I'm not sure how deterministic the par... | 48 | OSCAR-2109 datasets are misaligned and truncated
## Describe the bug
The `oscar-corpus/OSCAR-2109` data appears to be misaligned and truncated by the dataset builder for subsets that contain more than one part and for cases where the texts contain non-unix newlines.
## Steps to reproduce the bug
A few examples... |
https://github.com/huggingface/datasets/issues/3704 | OSCAR-2109 datasets are misaligned and truncated | Hello,
We've had an issue that could be linked to this one here: https://github.com/oscar-corpus/corpus/issues/15.
I have been spot checking the source (`.txt`/`.jsonl`) files for a while, and have not found issues, especially in the start/end of corpora (but I conceed that more integration testing would be neces... | ## Describe the bug
The `oscar-corpus/OSCAR-2109` data appears to be misaligned and truncated by the dataset builder for subsets that contain more than one part and for cases where the texts contain non-unix newlines.
## Steps to reproduce the bug
A few examples, although I'm not sure how deterministic the par... | 118 | OSCAR-2109 datasets are misaligned and truncated
## Describe the bug
The `oscar-corpus/OSCAR-2109` data appears to be misaligned and truncated by the dataset builder for subsets that contain more than one part and for cases where the texts contain non-unix newlines.
## Steps to reproduce the bug
A few examples... |
https://github.com/huggingface/datasets/issues/3704 | OSCAR-2109 datasets are misaligned and truncated | I'm happy to move the discussion to the other repo!
Merely sorting the files only **maybe** fixes the processing of the first part. If the first part contains non-unix newlines, it will still be misaligned/truncated, and all the following parts will be truncated with incorrect text offsets and metadata due the offse... | ## Describe the bug
The `oscar-corpus/OSCAR-2109` data appears to be misaligned and truncated by the dataset builder for subsets that contain more than one part and for cases where the texts contain non-unix newlines.
## Steps to reproduce the bug
A few examples, although I'm not sure how deterministic the par... | 55 | OSCAR-2109 datasets are misaligned and truncated
## Describe the bug
The `oscar-corpus/OSCAR-2109` data appears to be misaligned and truncated by the dataset builder for subsets that contain more than one part and for cases where the texts contain non-unix newlines.
## Steps to reproduce the bug
A few examples... |
https://github.com/huggingface/datasets/issues/3704 | OSCAR-2109 datasets are misaligned and truncated | Hi @Uinelj, This is a total noobs question but how can I integrate that bugfix into my code? I reinstalled the datasets library this time from source. Should that have fixed the issue? I am still facing the misalignment issue. Do I need to download the dataset from scratch? | ## Describe the bug
The `oscar-corpus/OSCAR-2109` data appears to be misaligned and truncated by the dataset builder for subsets that contain more than one part and for cases where the texts contain non-unix newlines.
## Steps to reproduce the bug
A few examples, although I'm not sure how deterministic the par... | 49 | OSCAR-2109 datasets are misaligned and truncated
## Describe the bug
The `oscar-corpus/OSCAR-2109` data appears to be misaligned and truncated by the dataset builder for subsets that contain more than one part and for cases where the texts contain non-unix newlines.
## Steps to reproduce the bug
A few examples... |
https://github.com/huggingface/datasets/issues/3704 | OSCAR-2109 datasets are misaligned and truncated | Sorry @norakassner for the late reply.
There are indeed several issues creating the misalignment, as @adrianeboyd cleverly pointed out:
- https://huggingface.co/datasets/oscar-corpus/OSCAR-2109/commit/3cd7e95aa1799b73c5ea8afc3989635f3e19b86b fixed one of them
- but there are still others to be fixed | ## Describe the bug
The `oscar-corpus/OSCAR-2109` data appears to be misaligned and truncated by the dataset builder for subsets that contain more than one part and for cases where the texts contain non-unix newlines.
## Steps to reproduce the bug
A few examples, although I'm not sure how deterministic the par... | 34 | OSCAR-2109 datasets are misaligned and truncated
## Describe the bug
The `oscar-corpus/OSCAR-2109` data appears to be misaligned and truncated by the dataset builder for subsets that contain more than one part and for cases where the texts contain non-unix newlines.
## Steps to reproduce the bug
A few examples... |
https://github.com/huggingface/datasets/issues/3704 | OSCAR-2109 datasets are misaligned and truncated | Normally, the issues should be fixed now:
- Fix offset initialization for each file: https://huggingface.co/datasets/oscar-corpus/OSCAR-2109/commit/1ad9b7bfe00798a9258a923b887bb1c8d732b833
- Disable default universal newline support: https://huggingface.co/datasets/oscar-corpus/OSCAR-2109/commit/0c2f307d3167f03632f50... | ## Describe the bug
The `oscar-corpus/OSCAR-2109` data appears to be misaligned and truncated by the dataset builder for subsets that contain more than one part and for cases where the texts contain non-unix newlines.
## Steps to reproduce the bug
A few examples, although I'm not sure how deterministic the par... | 35 | OSCAR-2109 datasets are misaligned and truncated
## Describe the bug
The `oscar-corpus/OSCAR-2109` data appears to be misaligned and truncated by the dataset builder for subsets that contain more than one part and for cases where the texts contain non-unix newlines.
## Steps to reproduce the bug
A few examples... |
https://github.com/huggingface/datasets/issues/3704 | OSCAR-2109 datasets are misaligned and truncated | Thanks for the updates!
The purist in me would still like to have the rstrip not strip additional characters from the original text (unicode whitespace mainly in practice, I think), but the differences are extremely small in practice and it doesn't actually matter for my current task:
```python
text = "".join([t... | ## Describe the bug
The `oscar-corpus/OSCAR-2109` data appears to be misaligned and truncated by the dataset builder for subsets that contain more than one part and for cases where the texts contain non-unix newlines.
## Steps to reproduce the bug
A few examples, although I'm not sure how deterministic the par... | 56 | OSCAR-2109 datasets are misaligned and truncated
## Describe the bug
The `oscar-corpus/OSCAR-2109` data appears to be misaligned and truncated by the dataset builder for subsets that contain more than one part and for cases where the texts contain non-unix newlines.
## Steps to reproduce the bug
A few examples... |
https://github.com/huggingface/datasets/issues/6149 | Dataset.from_parquet cannot load subset of columns | Looks like this regression was introduced in `datasets==2.13.0` (`2.12.0` could load a subset of columns)
This does not appear to be fixed by https://github.com/huggingface/datasets/pull/6045 (bug still exists on `main`) | ### Describe the bug
When using `Dataset.from_parquet(path_or_paths, columns=[...])` and a subset of columns, loading fails with a variant of the following
```
ValueError: Couldn't cast
a: int64
-- schema metadata --
pandas: '{"index_columns": [], "column_indexes": [], "columns": [{"name":' + 273
to
{'a': V... | 29 | Dataset.from_parquet cannot load subset of columns
### Describe the bug
When using `Dataset.from_parquet(path_or_paths, columns=[...])` and a subset of columns, loading fails with a variant of the following
```
ValueError: Couldn't cast
a: int64
-- schema metadata --
pandas: '{"index_columns": [], "column_ind... |
https://github.com/huggingface/datasets/issues/6111 | raise FileNotFoundError("Directory {dataset_path} is neither a `Dataset` directory nor a `DatasetDict` directory." ) | This should work: `load_dataset("path/to/downloaded_repo")`
`load_from_disk` is intended to be used on directories created with `Dataset.save_to_disk` or `DatasetDict.save_to_disk` | ### Describe the bug
For researchers in some countries or regions, it is usually the case that the download ability of `load_dataset` is disabled due to the complex network environment. People in these regions often prefer to use git clone or other programming tricks to manually download the files to the disk (for exa... | 17 | raise FileNotFoundError("Directory {dataset_path} is neither a `Dataset` directory nor a `DatasetDict` directory." )
### Describe the bug
For researchers in some countries or regions, it is usually the case that the download ability of `load_dataset` is disabled due to the complex network environment. People in these ... |
https://github.com/huggingface/datasets/issues/6111 | raise FileNotFoundError("Directory {dataset_path} is neither a `Dataset` directory nor a `DatasetDict` directory." ) | > This should work: `load_dataset("path/to/downloaded_repo")`
>
> `load_from_disk` is intended to be used on directories created with `Dataset.save_to_disk` or `DatasetDict.save_to_disk`
Thanks for your help. This works. | ### Describe the bug
For researchers in some countries or regions, it is usually the case that the download ability of `load_dataset` is disabled due to the complex network environment. People in these regions often prefer to use git clone or other programming tricks to manually download the files to the disk (for exa... | 26 | raise FileNotFoundError("Directory {dataset_path} is neither a `Dataset` directory nor a `DatasetDict` directory." )
### Describe the bug
For researchers in some countries or regions, it is usually the case that the download ability of `load_dataset` is disabled due to the complex network environment. People in these ... |
https://github.com/huggingface/datasets/issues/4477 | Dataset Viewer issue for fgrezes/WIESP2022-NER | https://huggingface.co/datasets/fgrezes/WIESP2022-NER
The error:
```
Message: Couldn't find a dataset script at /src/services/worker/fgrezes/WIESP2022-NER/WIESP2022-NER.py or any data file in the same directory. Couldn't find 'fgrezes/WIESP2022-NER' on the Hugging Face Hub either: FileNotFoundError: Unable... | ### Link
_No response_
### Description
_No response_
### Owner
_No response_ | 152 | Dataset Viewer issue for fgrezes/WIESP2022-NER
### Link
_No response_
### Description
_No response_
### Owner
_No response_
https://huggingface.co/datasets/fgrezes/WIESP2022-NER
The error:
```
Message: Couldn't find a dataset script at /src/services/worker/fgrezes/WIESP2022-NER/WIESP2022-NER.py or any... |
https://github.com/huggingface/datasets/issues/4477 | Dataset Viewer issue for fgrezes/WIESP2022-NER | Apparently it finds `scoring-scripts/compute_seqeval.py` which matches `**eval*`, a regex that detects a test split. We should probably improve the regex because it's not supposed to catch this kind of files. It must also only check for files with supported extensions: txt, csv, png etc. | ### Link
_No response_
### Description
_No response_
### Owner
_No response_ | 44 | Dataset Viewer issue for fgrezes/WIESP2022-NER
### Link
_No response_
### Description
_No response_
### Owner
_No response_
Apparently it finds `scoring-scripts/compute_seqeval.py` which matches `**eval*`, a regex that detects a test split. We should probably improve the regex because it's not supposed to catch th... |
https://github.com/huggingface/datasets/issues/3369 | [Audio] Allow resampling for audio datasets in streaming mode | This requires implementing `cast_column` for iterable datasets, it could be a very nice addition !
<s>It can also be useful to be able to disable the audio/image decoding for the dataset viewer (see PR https://github.com/huggingface/datasets/pull/3430) cc @severo </s>
EDIT: actually following https://github.com/hug... | Many audio datasets like Common Voice always need to be resampled. This can very easily be done in non-streaming mode as follows:
```python
from datasets import load_dataset
ds = load_dataset("common_voice", "ab", split="test")
ds = ds.cast_column("audio", Audio(sampling_rate=16_000))
```
However in strea... | 50 | [Audio] Allow resampling for audio datasets in streaming mode
Many audio datasets like Common Voice always need to be resampled. This can very easily be done in non-streaming mode as follows:
```python
from datasets import load_dataset
ds = load_dataset("common_voice", "ab", split="test")
ds = ds.cast_column(... |
https://github.com/huggingface/datasets/issues/3369 | [Audio] Allow resampling for audio datasets in streaming mode | Just to clarify a bit. This feature is **always** needed when using the common voice dataset in streaming mode. So I think it's quite important | Many audio datasets like Common Voice always need to be resampled. This can very easily be done in non-streaming mode as follows:
```python
from datasets import load_dataset
ds = load_dataset("common_voice", "ab", split="test")
ds = ds.cast_column("audio", Audio(sampling_rate=16_000))
```
However in strea... | 25 | [Audio] Allow resampling for audio datasets in streaming mode
Many audio datasets like Common Voice always need to be resampled. This can very easily be done in non-streaming mode as follows:
```python
from datasets import load_dataset
ds = load_dataset("common_voice", "ab", split="test")
ds = ds.cast_column(... |
https://github.com/huggingface/datasets/issues/5744 | [BUG] With Pandas 2.0.0, `load_dataset` raises `TypeError: read_csv() got an unexpected keyword argument 'mangle_dupe_cols'` | Thanks for reporting, @keyboardAnt.
We haven't noticed any crash in our CI tests. Could you please indicate specifically the `load_dataset` command that crashes in your side, so that we can reproduce it? | The `load_dataset` function with Pandas `1.5.3` has no issue (just a FutureWarning) but crashes with Pandas `2.0.0`.
For your convenience, I opened a draft Pull Request to fix it quickly: https://github.com/huggingface/datasets/pull/5745
---
* The FutureWarning mentioned above:
```
FutureWarning: the 'mangle_... | 32 | [BUG] With Pandas 2.0.0, `load_dataset` raises `TypeError: read_csv() got an unexpected keyword argument 'mangle_dupe_cols'`
The `load_dataset` function with Pandas `1.5.3` has no issue (just a FutureWarning) but crashes with Pandas `2.0.0`.
For your convenience, I opened a draft Pull Request to fix it quickly: https:... |
https://github.com/huggingface/datasets/issues/5744 | [BUG] With Pandas 2.0.0, `load_dataset` raises `TypeError: read_csv() got an unexpected keyword argument 'mangle_dupe_cols'` | I am still getting this bug with the latest pandas and datasets lib installed. Anyone else?
```
from datasets import load_dataset
dataset = load_dataset("csv", data_files={"train":"/kaggle/working/train.csv", "test":"/kaggle/working/test.csv"})
print(dataset)
-----------------------------------------------... | The `load_dataset` function with Pandas `1.5.3` has no issue (just a FutureWarning) but crashes with Pandas `2.0.0`.
For your convenience, I opened a draft Pull Request to fix it quickly: https://github.com/huggingface/datasets/pull/5745
---
* The FutureWarning mentioned above:
```
FutureWarning: the 'mangle_... | 396 | [BUG] With Pandas 2.0.0, `load_dataset` raises `TypeError: read_csv() got an unexpected keyword argument 'mangle_dupe_cols'`
The `load_dataset` function with Pandas `1.5.3` has no issue (just a FutureWarning) but crashes with Pandas `2.0.0`.
For your convenience, I opened a draft Pull Request to fix it quickly: https:... |
https://github.com/huggingface/datasets/issues/5744 | [BUG] With Pandas 2.0.0, `load_dataset` raises `TypeError: read_csv() got an unexpected keyword argument 'mangle_dupe_cols'` | Edit: Sorry, I found that our version is 2.2.1. Please ignore the following comment. This issue was already solved by this line:
https://github.com/huggingface/datasets/blob/bf02cff8d70180a9e89328961ded9e3d8510fd22/src/datasets/packaged_modules/csv/csv.py#L18
> This issue still exists as you can see in version 2.14... | The `load_dataset` function with Pandas `1.5.3` has no issue (just a FutureWarning) but crashes with Pandas `2.0.0`.
For your convenience, I opened a draft Pull Request to fix it quickly: https://github.com/huggingface/datasets/pull/5745
---
* The FutureWarning mentioned above:
```
FutureWarning: the 'mangle_... | 181 | [BUG] With Pandas 2.0.0, `load_dataset` raises `TypeError: read_csv() got an unexpected keyword argument 'mangle_dupe_cols'`
The `load_dataset` function with Pandas `1.5.3` has no issue (just a FutureWarning) but crashes with Pandas `2.0.0`.
For your convenience, I opened a draft Pull Request to fix it quickly: https:... |
https://github.com/huggingface/datasets/issues/3832 | Making Hugging Face the place to go for Graph NNs datasets | It will be indeed really great to add support to GNN datasets. Big :+1: for this initiative. | Let's make Hugging Face Datasets the central hub for GNN datasets :)
**Motivation**. Datasets are currently quite scattered and an open-source central point such as the Hugging Face Hub would be ideal to support the growth of the GNN field.
What are some datasets worth integrating into the Hugging Face hub?
In... | 17 | Making Hugging Face the place to go for Graph NNs datasets
Let's make Hugging Face Datasets the central hub for GNN datasets :)
**Motivation**. Datasets are currently quite scattered and an open-source central point such as the Hugging Face Hub would be ideal to support the growth of the GNN field.
What are some ... |
https://github.com/huggingface/datasets/issues/3832 | Making Hugging Face the place to go for Graph NNs datasets | @napoles-uach identifies the [TUDatasets](https://chrsmrrs.github.io/datasets/) (A collection of benchmark datasets for graph classification and regression).
Added to the Tasks in the initial issue. | Let's make Hugging Face Datasets the central hub for GNN datasets :)
**Motivation**. Datasets are currently quite scattered and an open-source central point such as the Hugging Face Hub would be ideal to support the growth of the GNN field.
What are some datasets worth integrating into the Hugging Face hub?
In... | 22 | Making Hugging Face the place to go for Graph NNs datasets
Let's make Hugging Face Datasets the central hub for GNN datasets :)
**Motivation**. Datasets are currently quite scattered and an open-source central point such as the Hugging Face Hub would be ideal to support the growth of the GNN field.
What are some ... |
https://github.com/huggingface/datasets/issues/3832 | Making Hugging Face the place to go for Graph NNs datasets | Great initiative! Let's keep this issue for these 3 datasets, but moving forward maybe let's create a new issue per dataset :rocket: great work @napoles-uach and @omarespejel! | Let's make Hugging Face Datasets the central hub for GNN datasets :)
**Motivation**. Datasets are currently quite scattered and an open-source central point such as the Hugging Face Hub would be ideal to support the growth of the GNN field.
What are some datasets worth integrating into the Hugging Face hub?
In... | 27 | Making Hugging Face the place to go for Graph NNs datasets
Let's make Hugging Face Datasets the central hub for GNN datasets :)
**Motivation**. Datasets are currently quite scattered and an open-source central point such as the Hugging Face Hub would be ideal to support the growth of the GNN field.
What are some ... |
https://github.com/huggingface/datasets/issues/3673 | `load_dataset("snli")` is different from dataset viewer | Yes, we decided to replace the encoded label with the corresponding label when possible in the dataset viewer. But
1. maybe it's the wrong default
2. we could find a way to show both (with a switch, or showing both ie. `0 (neutral)`).
| ## Describe the bug
The dataset that is downloaded from the Hub via `load_dataset("snli")` is different from what is available in the dataset viewer. In the viewer the labels are not encoded (i.e., "neutral", "entailment", "contradiction"), while the downloaded dataset shows the encoded labels (i.e., 0, 1, 2).
Is t... | 43 | `load_dataset("snli")` is different from dataset viewer
## Describe the bug
The dataset that is downloaded from the Hub via `load_dataset("snli")` is different from what is available in the dataset viewer. In the viewer the labels are not encoded (i.e., "neutral", "entailment", "contradiction"), while the downloaded d... |
https://github.com/huggingface/datasets/issues/3673 | `load_dataset("snli")` is different from dataset viewer | Hi @severo,
Thanks for clarifying.
I think this default is a bit counterintuitive for the user. However, this is a personal opinion that might not be general. I think it is nice to have the actual (non-encoded) labels in the viewer. On the other hand, it would be nice to match what the user sees with what they g... | ## Describe the bug
The dataset that is downloaded from the Hub via `load_dataset("snli")` is different from what is available in the dataset viewer. In the viewer the labels are not encoded (i.e., "neutral", "entailment", "contradiction"), while the downloaded dataset shows the encoded labels (i.e., 0, 1, 2).
Is t... | 103 | `load_dataset("snli")` is different from dataset viewer
## Describe the bug
The dataset that is downloaded from the Hub via `load_dataset("snli")` is different from what is available in the dataset viewer. In the viewer the labels are not encoded (i.e., "neutral", "entailment", "contradiction"), while the downloaded d... |
https://github.com/huggingface/datasets/issues/3673 | `load_dataset("snli")` is different from dataset viewer | Thanks for the 👍 in https://github.com/huggingface/datasets/issues/3673#issuecomment-1029008349 @mariosasko @gary149 @pietrolesci, but as I proposed various solutions, it's not clear to me which you prefer. Could you write your preferences as a comment?
_(note for myself: one idea per comment in the future)_ | ## Describe the bug
The dataset that is downloaded from the Hub via `load_dataset("snli")` is different from what is available in the dataset viewer. In the viewer the labels are not encoded (i.e., "neutral", "entailment", "contradiction"), while the downloaded dataset shows the encoded labels (i.e., 0, 1, 2).
Is t... | 41 | `load_dataset("snli")` is different from dataset viewer
## Describe the bug
The dataset that is downloaded from the Hub via `load_dataset("snli")` is different from what is available in the dataset viewer. In the viewer the labels are not encoded (i.e., "neutral", "entailment", "contradiction"), while the downloaded d... |
https://github.com/huggingface/datasets/issues/3673 | `load_dataset("snli")` is different from dataset viewer | As I am working with seq2seq, I prefer having the label in string form rather than numeric. So the viewer is fine and the underlying dataset should be "decoded" (from int to str). In this way, the user does not have to search for a mapping `int -> original name` (even though is trivial to find, I reckon). Also, encodin... | ## Describe the bug
The dataset that is downloaded from the Hub via `load_dataset("snli")` is different from what is available in the dataset viewer. In the viewer the labels are not encoded (i.e., "neutral", "entailment", "contradiction"), while the downloaded dataset shows the encoded labels (i.e., 0, 1, 2).
Is t... | 69 | `load_dataset("snli")` is different from dataset viewer
## Describe the bug
The dataset that is downloaded from the Hub via `load_dataset("snli")` is different from what is available in the dataset viewer. In the viewer the labels are not encoded (i.e., "neutral", "entailment", "contradiction"), while the downloaded d... |
https://github.com/huggingface/datasets/issues/3673 | `load_dataset("snli")` is different from dataset viewer | I like the idea of "0 (neutral)". The label name can even be greyed to make it clear that it's not part of the actual item in the dataset, it's just the meaning. | ## Describe the bug
The dataset that is downloaded from the Hub via `load_dataset("snli")` is different from what is available in the dataset viewer. In the viewer the labels are not encoded (i.e., "neutral", "entailment", "contradiction"), while the downloaded dataset shows the encoded labels (i.e., 0, 1, 2).
Is t... | 33 | `load_dataset("snli")` is different from dataset viewer
## Describe the bug
The dataset that is downloaded from the Hub via `load_dataset("snli")` is different from what is available in the dataset viewer. In the viewer the labels are not encoded (i.e., "neutral", "entailment", "contradiction"), while the downloaded d... |
https://github.com/huggingface/datasets/issues/3673 | `load_dataset("snli")` is different from dataset viewer | Proposals by @gary149. Which one do you prefer? Please vote with the thumbs
- 👍
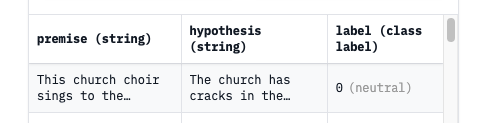
- 👎
` is different from what is available in the dataset viewer. In the viewer the labels are not encoded (i.e., "neutral", "entailment", "contradiction"), while the downloaded dataset shows the encoded labels (i.e., 0, 1, 2).
Is t... | 20 | `load_dataset("snli")` is different from dataset viewer
## Describe the bug
The dataset that is downloaded from the Hub via `load_dataset("snli")` is different from what is available in the dataset viewer. In the viewer the labels are not encoded (i.e., "neutral", "entailment", "contradiction"), while the downloaded d... |
https://github.com/huggingface/datasets/issues/3673 | `load_dataset("snli")` is different from dataset viewer | It's [live](https://huggingface.co/datasets/glue/viewer/cola/train):
<img width="1126" alt="Capture d’écran 2022-02-14 à 10 26 03" src="https://user-images.githubusercontent.com/1676121/153836716-25f6205b-96af-42d8-880a-7c09cb24c420.png">
Thanks all for the help to improve the UI! | ## Describe the bug
The dataset that is downloaded from the Hub via `load_dataset("snli")` is different from what is available in the dataset viewer. In the viewer the labels are not encoded (i.e., "neutral", "entailment", "contradiction"), while the downloaded dataset shows the encoded labels (i.e., 0, 1, 2).
Is t... | 21 | `load_dataset("snli")` is different from dataset viewer
## Describe the bug
The dataset that is downloaded from the Hub via `load_dataset("snli")` is different from what is available in the dataset viewer. In the viewer the labels are not encoded (i.e., "neutral", "entailment", "contradiction"), while the downloaded d... |
https://github.com/huggingface/datasets/issues/6133 | Dataset is slower after calling `to_iterable_dataset` | It's roughly the same code between the two so we can expected roughly the same speed, could you share a benchmark ? | ### Describe the bug
Can anyone explain why looping over a dataset becomes slower after calling `to_iterable_dataset` to convert to `IterableDataset`
### Steps to reproduce the bug
Any dataset after converting to `IterableDataset`
### Expected behavior
Maybe it should be faster on big dataset? I only test on small... | 22 | Dataset is slower after calling `to_iterable_dataset`
### Describe the bug
Can anyone explain why looping over a dataset becomes slower after calling `to_iterable_dataset` to convert to `IterableDataset`
### Steps to reproduce the bug
Any dataset after converting to `IterableDataset`
### Expected behavior
Maybe it... |
https://github.com/huggingface/datasets/issues/7217 | ds.map(f, num_proc=10) is slower than df.apply | Hi ! `map()` reads all the columns and writes the resulting dataset with all the columns as well, while df.column_name.apply only reads and writes one column and does it in memory. So this is speed difference is actually expected.
Moreover using multiprocessing on a dataset that lives in memory (from_pandas uses the... | ### Describe the bug
pandas columns: song_id, song_name
ds = Dataset.from_pandas(df)
def has_cover(song_name):
if song_name is None or pd.isna(song_name):
return False
return 'cover' in song_name.lower()
df['has_cover'] = df.song_name.progress_apply(has_cover)
ds = ds.map(lambda x: {'has_cov... | 172 | ds.map(f, num_proc=10) is slower than df.apply
### Describe the bug
pandas columns: song_id, song_name
ds = Dataset.from_pandas(df)
def has_cover(song_name):
if song_name is None or pd.isna(song_name):
return False
return 'cover' in song_name.lower()
df['has_cover'] = df.song_name.progress_ap... |
https://github.com/huggingface/datasets/issues/7217 | ds.map(f, num_proc=10) is slower than df.apply | Isn't there a way to do memory mapping with the in-memory dataset without saving it to disk? | ### Describe the bug
pandas columns: song_id, song_name
ds = Dataset.from_pandas(df)
def has_cover(song_name):
if song_name is None or pd.isna(song_name):
return False
return 'cover' in song_name.lower()
df['has_cover'] = df.song_name.progress_apply(has_cover)
ds = ds.map(lambda x: {'has_cov... | 17 | ds.map(f, num_proc=10) is slower than df.apply
### Describe the bug
pandas columns: song_id, song_name
ds = Dataset.from_pandas(df)
def has_cover(song_name):
if song_name is None or pd.isna(song_name):
return False
return 'cover' in song_name.lower()
df['has_cover'] = df.song_name.progress_ap... |
https://github.com/huggingface/datasets/issues/7217 | ds.map(f, num_proc=10) is slower than df.apply | Maybe saving it to a memory-mapped filesystem? It'd be like a trick to make datasets save to "disk" but actually it's memory. But it feels like there should be a better "automatic" way provided by `datasets`. | ### Describe the bug
pandas columns: song_id, song_name
ds = Dataset.from_pandas(df)
def has_cover(song_name):
if song_name is None or pd.isna(song_name):
return False
return 'cover' in song_name.lower()
df['has_cover'] = df.song_name.progress_apply(has_cover)
ds = ds.map(lambda x: {'has_cov... | 36 | ds.map(f, num_proc=10) is slower than df.apply
### Describe the bug
pandas columns: song_id, song_name
ds = Dataset.from_pandas(df)
def has_cover(song_name):
if song_name is None or pd.isna(song_name):
return False
return 'cover' in song_name.lower()
df['has_cover'] = df.song_name.progress_ap... |
https://github.com/huggingface/datasets/issues/7527 | Auto-merge option for `convert-to-parquet` | Alternatively, there could be an option to switch from submitting PRs to just committing changes directly to `main`. | ### Feature request
Add a command-line option, e.g. `--auto-merge-pull-request` that enables automatic merging of the commits created by the `convert-to-parquet` tool.
### Motivation
Large datasets may result in dozens of PRs due to the splitting mechanism. Each of these has to be manually accepted via the website.
... | 18 | Auto-merge option for `convert-to-parquet`
### Feature request
Add a command-line option, e.g. `--auto-merge-pull-request` that enables automatic merging of the commits created by the `convert-to-parquet` tool.
### Motivation
Large datasets may result in dozens of PRs due to the splitting mechanism. Each of these ha... |
https://github.com/huggingface/datasets/issues/7527 | Auto-merge option for `convert-to-parquet` | Why not, I'd be in favor of `--merge-pull-request` to call `HfApi().merge_pull_request()` at the end of the conversion :) feel free to open a PR if you'd like | ### Feature request
Add a command-line option, e.g. `--auto-merge-pull-request` that enables automatic merging of the commits created by the `convert-to-parquet` tool.
### Motivation
Large datasets may result in dozens of PRs due to the splitting mechanism. Each of these has to be manually accepted via the website.
... | 27 | Auto-merge option for `convert-to-parquet`
### Feature request
Add a command-line option, e.g. `--auto-merge-pull-request` that enables automatic merging of the commits created by the `convert-to-parquet` tool.
### Motivation
Large datasets may result in dozens of PRs due to the splitting mechanism. Each of these ha... |
https://github.com/huggingface/datasets/issues/3425 | Getting configs names takes too long | It looks like it's currently calling `HfFileSystem.ls()` ~8 times at the root and for each subdirectory:
- ""
- "en.noblocklist"
- "en.noclean"
- "en"
- "multilingual"
- "realnewslike"
Currently `ls` is slow because it iterates on all the files inside the repository.
An easy optimization would be to cache t... |
## Steps to reproduce the bug
```python
from datasets import get_dataset_config_names
get_dataset_config_names("allenai/c4")
```
## Expected results
I would expect to get the answer quickly, at least in less than 10s
## Actual results
It takes about 45s on my environment
## Environment info
- `d... | 76 | Getting configs names takes too long
## Steps to reproduce the bug
```python
from datasets import get_dataset_config_names
get_dataset_config_names("allenai/c4")
```
## Expected results
I would expect to get the answer quickly, at least in less than 10s
## Actual results
It takes about 45s on my envir... |
https://github.com/huggingface/datasets/issues/7624 | #Dataset Make "image" column appear first in dataset preview UI | Hi ! It should follow the same order as the order of the keys in the metadata file | Hi!
#Dataset
I’m currently uploading a dataset that includes an `"image"` column (PNG files), along with some metadata columns. The dataset is loaded from a .jsonl file. My goal is to have the "image" column appear as the first column in the dataset card preview UI on the :hugs: Hub.
However, at the moment, the `"im... | 18 | #Dataset Make "image" column appear first in dataset preview UI
Hi!
#Dataset
I’m currently uploading a dataset that includes an `"image"` column (PNG files), along with some metadata columns. The dataset is loaded from a .jsonl file. My goal is to have the "image" column appear as the first column in the dataset card... |
https://github.com/huggingface/datasets/issues/7624 | #Dataset Make "image" column appear first in dataset preview UI | Hi! Thank you for your answer.
As you said it, I I forced every key in every JSON to have an order using `collections. OrderedDict` in Python. Now, it works!
TY | Hi!
#Dataset
I’m currently uploading a dataset that includes an `"image"` column (PNG files), along with some metadata columns. The dataset is loaded from a .jsonl file. My goal is to have the "image" column appear as the first column in the dataset card preview UI on the :hugs: Hub.
However, at the moment, the `"im... | 31 | #Dataset Make "image" column appear first in dataset preview UI
Hi!
#Dataset
I’m currently uploading a dataset that includes an `"image"` column (PNG files), along with some metadata columns. The dataset is loaded from a .jsonl file. My goal is to have the "image" column appear as the first column in the dataset card... |
https://github.com/huggingface/datasets/issues/7927 | Using Stateful Dataloader with Split Dataset By Node and DCP for DDP | Does it need to be pickled?
```python
def load_state_dict(self, state_dict):
hf_state = pickle.loads(state_dict["data"])
self.train_dataset.load_state_dict(hf_state)
def state_dict(self):
return {"data": pickle.dumps(self.train_dataset.state_dict())}
``` | ### Describe the bug
I am trying to determine how to save and load the Stateful Dataloader State with DCP and Split Dataset by Node for DDP.
Currently, I am running into the issue where I am receiving a slow resume.
```
Neither dataset nor iter(dataset) defines state_dict/load_state_dict so we are naively fast-forwar... | 20 | Using Stateful Dataloader with Split Dataset By Node and DCP for DDP
### Describe the bug
I am trying to determine how to save and load the Stateful Dataloader State with DCP and Split Dataset by Node for DDP.
Currently, I am running into the issue where I am receiving a slow resume.
```
Neither dataset nor iter(data... |
https://github.com/huggingface/datasets/issues/7927 | Using Stateful Dataloader with Split Dataset By Node and DCP for DDP | Pickling seems to have resolved the issue but it is not clear at all to me why this is necessary | ### Describe the bug
I am trying to determine how to save and load the Stateful Dataloader State with DCP and Split Dataset by Node for DDP.
Currently, I am running into the issue where I am receiving a slow resume.
```
Neither dataset nor iter(dataset) defines state_dict/load_state_dict so we are naively fast-forwar... | 20 | Using Stateful Dataloader with Split Dataset By Node and DCP for DDP
### Describe the bug
I am trying to determine how to save and load the Stateful Dataloader State with DCP and Split Dataset by Node for DDP.
Currently, I am running into the issue where I am receiving a slow resume.
```
Neither dataset nor iter(data... |
https://github.com/huggingface/datasets/issues/7927 | Using Stateful Dataloader with Split Dataset By Node and DCP for DDP | > Does it need to be pickled?
>
> def load_state_dict(self, state_dict):
> hf_state = pickle.loads(state_dict["data"])
> self.train_dataset.load_state_dict(hf_state)
>
> def state_dict(self):
> return {"data": pickle.dumps(self.train_dataset.state_dict())}
Hii, your pickling solution ... | ### Describe the bug
I am trying to determine how to save and load the Stateful Dataloader State with DCP and Split Dataset by Node for DDP.
Currently, I am running into the issue where I am receiving a slow resume.
```
Neither dataset nor iter(dataset) defines state_dict/load_state_dict so we are naively fast-forwar... | 134 | Using Stateful Dataloader with Split Dataset By Node and DCP for DDP
### Describe the bug
I am trying to determine how to save and load the Stateful Dataloader State with DCP and Split Dataset by Node for DDP.
Currently, I am running into the issue where I am receiving a slow resume.
```
Neither dataset nor iter(data... |
https://github.com/huggingface/datasets/issues/7055 | WebDataset with different prefixes are unsupported | Since `datasets` uses is built on Arrow to store the data, it requires each sample to have the same columns.
This can be fixed by specifyign in advance the name of all the possible columns in the `dataset_info` in YAML, and missing values will be `None` | ### Describe the bug
Consider a WebDataset with multiple images for each item where the number of images may vary: [example](https://huggingface.co/datasets/bigdata-pw/fashion-150k)
Due to this [code](https://github.com/huggingface/datasets/blob/87f4c2088854ff33e817e724e75179e9975c1b02/src/datasets/packaged_modules... | 46 | WebDataset with different prefixes are unsupported
### Describe the bug
Consider a WebDataset with multiple images for each item where the number of images may vary: [example](https://huggingface.co/datasets/bigdata-pw/fashion-150k)
Due to this [code](https://github.com/huggingface/datasets/blob/87f4c2088854ff33e81... |
https://github.com/huggingface/datasets/issues/7055 | WebDataset with different prefixes are unsupported | Thanks. This currently doesn't work for WebDataset because there's no `BuilderConfig` with `features` and in turn `_info` is missing `features=self.config.features`. I'll prepare a PR to fix this.
Note it may be useful to add the [expected format of `features`](https://github.com/huggingface/datasets/blob/16fa4421f4... | ### Describe the bug
Consider a WebDataset with multiple images for each item where the number of images may vary: [example](https://huggingface.co/datasets/bigdata-pw/fashion-150k)
Due to this [code](https://github.com/huggingface/datasets/blob/87f4c2088854ff33e817e724e75179e9975c1b02/src/datasets/packaged_modules... | 45 | WebDataset with different prefixes are unsupported
### Describe the bug
Consider a WebDataset with multiple images for each item where the number of images may vary: [example](https://huggingface.co/datasets/bigdata-pw/fashion-150k)
Due to this [code](https://github.com/huggingface/datasets/blob/87f4c2088854ff33e81... |
https://github.com/huggingface/datasets/issues/7055 | WebDataset with different prefixes are unsupported | Oh good catch ! thanks
> Note it may be useful to add the [expected format of features](https://github.com/huggingface/datasets/blob/16fa4421f44b22bbbc607f379a93f45af468d1fc/src/datasets/features/features.py#L1757) to the documentation for [Buil](https://huggingface.co/docs/datasets/repository_structure#builder-para... | ### Describe the bug
Consider a WebDataset with multiple images for each item where the number of images may vary: [example](https://huggingface.co/datasets/bigdata-pw/fashion-150k)
Due to this [code](https://github.com/huggingface/datasets/blob/87f4c2088854ff33e817e724e75179e9975c1b02/src/datasets/packaged_modules... | 30 | WebDataset with different prefixes are unsupported
### Describe the bug
Consider a WebDataset with multiple images for each item where the number of images may vary: [example](https://huggingface.co/datasets/bigdata-pw/fashion-150k)
Due to this [code](https://github.com/huggingface/datasets/blob/87f4c2088854ff33e81... |
https://github.com/huggingface/datasets/issues/7055 | WebDataset with different prefixes are unsupported | Actually I just tried with `datasets` on the `main` branch and having `features` defined in `dataset_info` worked for me
```python
>>> list(load_dataset("/Users/quentinlhoest/tmp", streaming=True, split="train"))
[{'txt': 'hello there\n', 'other': None}]
```
where `tmp` contains data.tar with "hello there\n" in ... | ### Describe the bug
Consider a WebDataset with multiple images for each item where the number of images may vary: [example](https://huggingface.co/datasets/bigdata-pw/fashion-150k)
Due to this [code](https://github.com/huggingface/datasets/blob/87f4c2088854ff33e817e724e75179e9975c1b02/src/datasets/packaged_modules... | 80 | WebDataset with different prefixes are unsupported
### Describe the bug
Consider a WebDataset with multiple images for each item where the number of images may vary: [example](https://huggingface.co/datasets/bigdata-pw/fashion-150k)
Due to this [code](https://github.com/huggingface/datasets/blob/87f4c2088854ff33e81... |
https://github.com/huggingface/datasets/issues/7055 | WebDataset with different prefixes are unsupported | If you review the changes in #7060 you'll note that `features` are not passed to `DatasetInfo`.
In your case the features are being extracted by [this code](https://github.com/huggingface/datasets/blob/e83d6fa574710fcb44e341087239d2687183f62b/src/datasets/packaged_modules/webdataset/webdataset.py#L72-L98).
Try wi... | ### Describe the bug
Consider a WebDataset with multiple images for each item where the number of images may vary: [example](https://huggingface.co/datasets/bigdata-pw/fashion-150k)
Due to this [code](https://github.com/huggingface/datasets/blob/87f4c2088854ff33e817e724e75179e9975c1b02/src/datasets/packaged_modules... | 111 | WebDataset with different prefixes are unsupported
### Describe the bug
Consider a WebDataset with multiple images for each item where the number of images may vary: [example](https://huggingface.co/datasets/bigdata-pw/fashion-150k)
Due to this [code](https://github.com/huggingface/datasets/blob/87f4c2088854ff33e81... |
https://github.com/huggingface/datasets/issues/7055 | WebDataset with different prefixes are unsupported | Note for anyone else who encounters this issue, every dataset type except folder-based types supported features in the [documented](https://huggingface.co/docs/datasets/repository_structure#builder-parameters) manner; [Arrow](https://github.com/huggingface/datasets/blob/e83d6fa574710fcb44e341087239d2687183f62b/src/data... | ### Describe the bug
Consider a WebDataset with multiple images for each item where the number of images may vary: [example](https://huggingface.co/datasets/bigdata-pw/fashion-150k)
Due to this [code](https://github.com/huggingface/datasets/blob/87f4c2088854ff33e817e724e75179e9975c1b02/src/datasets/packaged_modules... | 44 | WebDataset with different prefixes are unsupported
### Describe the bug
Consider a WebDataset with multiple images for each item where the number of images may vary: [example](https://huggingface.co/datasets/bigdata-pw/fashion-150k)
Due to this [code](https://github.com/huggingface/datasets/blob/87f4c2088854ff33e81... |
https://github.com/huggingface/datasets/issues/7055 | WebDataset with different prefixes are unsupported | Thanks for explaining. I see the Dataset Viewer is still failing - I'll update `datasets` in the Viewer to fix this | ### Describe the bug
Consider a WebDataset with multiple images for each item where the number of images may vary: [example](https://huggingface.co/datasets/bigdata-pw/fashion-150k)
Due to this [code](https://github.com/huggingface/datasets/blob/87f4c2088854ff33e817e724e75179e9975c1b02/src/datasets/packaged_modules... | 21 | WebDataset with different prefixes are unsupported
### Describe the bug
Consider a WebDataset with multiple images for each item where the number of images may vary: [example](https://huggingface.co/datasets/bigdata-pw/fashion-150k)
Due to this [code](https://github.com/huggingface/datasets/blob/87f4c2088854ff33e81... |
https://github.com/huggingface/datasets/issues/4829 | Misalignment between card tag validation and docs | (Note that the doc is aligned with the hub validation rules, and the "ground truth" is the hub validation rules given that they apply to all datasets, not just the canonical ones) | ## Describe the bug
As pointed out in other issue: https://github.com/huggingface/datasets/pull/4827#discussion_r943536284
the validation of the dataset card tags is not aligned with its documentation: e.g.
- implementation: `license: List[str]`
- docs: `license: Union[str, List[str]]`
They should be aligned.
... | 32 | Misalignment between card tag validation and docs
## Describe the bug
As pointed out in other issue: https://github.com/huggingface/datasets/pull/4827#discussion_r943536284
the validation of the dataset card tags is not aligned with its documentation: e.g.
- implementation: `license: List[str]`
- docs: `license: Un... |
https://github.com/huggingface/datasets/issues/4829 | Misalignment between card tag validation and docs | Instead of our own implementation, we now use `huggingface_hub`'s `DatasetCardData`, which has the correct type hint, so I think we can close this issue. | ## Describe the bug
As pointed out in other issue: https://github.com/huggingface/datasets/pull/4827#discussion_r943536284
the validation of the dataset card tags is not aligned with its documentation: e.g.
- implementation: `license: List[str]`
- docs: `license: Union[str, List[str]]`
They should be aligned.
... | 24 | Misalignment between card tag validation and docs
## Describe the bug
As pointed out in other issue: https://github.com/huggingface/datasets/pull/4827#discussion_r943536284
the validation of the dataset card tags is not aligned with its documentation: e.g.
- implementation: `license: List[str]`
- docs: `license: Un... |
https://github.com/huggingface/datasets/issues/5539 | IndexError: invalid index of a 0-dim tensor. Use `tensor.item()` in Python or `tensor.item<T>()` in C++ to convert a 0-dim tensor to a number | Hi! The `set_transform` does not apply a custom formatting transform on a single example but the entire batch, so the fixed version of your transform would look as follows:
```python
from datasets import load_dataset
import torch
dataset = load_dataset("lambdalabs/pokemon-blip-captions", split='train')
def t(bat... | ### Describe the bug
When dataset contains a 0-dim tensor, formatting.py raises a following error and fails.
```bash
Traceback (most recent call last):
File "<path>/lib/python3.8/site-packages/datasets/formatting/formatting.py", line 501, in format_row
return _unnest(formatted_batch)
File "<path>/lib/py... | 78 | IndexError: invalid index of a 0-dim tensor. Use `tensor.item()` in Python or `tensor.item<T>()` in C++ to convert a 0-dim tensor to a number
### Describe the bug
When dataset contains a 0-dim tensor, formatting.py raises a following error and fails.
```bash
Traceback (most recent call last):
File "<path>/lib/p... |
https://github.com/huggingface/datasets/issues/5539 | IndexError: invalid index of a 0-dim tensor. Use `tensor.item()` in Python or `tensor.item<T>()` in C++ to convert a 0-dim tensor to a number | > Hi! The `set_transform` does not apply a custom formatting transform on a single example but the entire batch, so the fixed version of your transform would look as follows:
>
> ```python
> from datasets import load_dataset
> import torch
>
> dataset = load_dataset("lambdalabs/pokemon-blip-captions", split='tr... | ### Describe the bug
When dataset contains a 0-dim tensor, formatting.py raises a following error and fails.
```bash
Traceback (most recent call last):
File "<path>/lib/python3.8/site-packages/datasets/formatting/formatting.py", line 501, in format_row
return _unnest(formatted_batch)
File "<path>/lib/py... | 104 | IndexError: invalid index of a 0-dim tensor. Use `tensor.item()` in Python or `tensor.item<T>()` in C++ to convert a 0-dim tensor to a number
### Describe the bug
When dataset contains a 0-dim tensor, formatting.py raises a following error and fails.
```bash
Traceback (most recent call last):
File "<path>/lib/p... |
https://github.com/huggingface/datasets/issues/6195 | Force to reuse cache at given path | realized that need to pass the path at `cache_file_name` like
```python
tokenized_datasets = raw_datasets["train"].map(
tokenize_function,
batched=True,
num_proc=data_args.preprocessing_num_workers,
remove_columns=[text_column_name],
... | ### Describe the bug
I have run the official example of MLM like:
```bash
python run_mlm.py \
--model_name_or_path roberta-base \
--dataset_name togethercomputer/RedPajama-Data-1T \
--dataset_config_name arxiv \
--per_device_train_batch_size 10 \
--preprocessing_num_workers 20 ... | 32 | Force to reuse cache at given path
### Describe the bug
I have run the official example of MLM like:
```bash
python run_mlm.py \
--model_name_or_path roberta-base \
--dataset_name togethercomputer/RedPajama-Data-1T \
--dataset_config_name arxiv \
--per_device_train_batch_size 10 \
... |
https://github.com/huggingface/datasets/issues/6195 | Force to reuse cache at given path | Thank you so much! I went through a lot of issues before finding similar experiences here. I have to say that the [docs](https://huggingface.co/docs/datasets/v2.11.0/en/package_reference/main_classes#datasets.Dataset.map) of `.map()` is really misleading, probably making people think that just assigning the file name t... | ### Describe the bug
I have run the official example of MLM like:
```bash
python run_mlm.py \
--model_name_or_path roberta-base \
--dataset_name togethercomputer/RedPajama-Data-1T \
--dataset_config_name arxiv \
--per_device_train_batch_size 10 \
--preprocessing_num_workers 20 ... | 42 | Force to reuse cache at given path
### Describe the bug
I have run the official example of MLM like:
```bash
python run_mlm.py \
--model_name_or_path roberta-base \
--dataset_name togethercomputer/RedPajama-Data-1T \
--dataset_config_name arxiv \
--per_device_train_batch_size 10 \
... |
https://github.com/huggingface/datasets/issues/4422 | Cannot load timit_asr data set | @bhaddow we have also made a fix so that you don't have to convert to uppercase the file extensions of the LDC data.
Would you mind checking if it works OK now for you and reporting if there are any issues? Thanks. | ## Describe the bug
I am trying to load the timit_asr data set. I have tried with a copy from the LDC, and a copy from deepai. In both cases they fail with a "duplicate key" error. With the LDC version I have to convert the file extensions all to upper-case before I can load it at all.
## Steps to reproduce the bug... | 42 | Cannot load timit_asr data set
## Describe the bug
I am trying to load the timit_asr data set. I have tried with a copy from the LDC, and a copy from deepai. In both cases they fail with a "duplicate key" error. With the LDC version I have to convert the file extensions all to upper-case before I can load it at all.
... |
https://github.com/huggingface/datasets/issues/4422 | Cannot load timit_asr data set | Hi @albertvillanova -It loads fine on a copy of the data from deepai - although I have to remove the copies of the .WAV files (with extension .WAV,wav). On a copy of the data that was obtained from the LDC, the glob still fails to find the files. The LDC copy looks like it was copied from CD, in 2004, so the structure... | ## Describe the bug
I am trying to load the timit_asr data set. I have tried with a copy from the LDC, and a copy from deepai. In both cases they fail with a "duplicate key" error. With the LDC version I have to convert the file extensions all to upper-case before I can load it at all.
## Steps to reproduce the bug... | 70 | Cannot load timit_asr data set
## Describe the bug
I am trying to load the timit_asr data set. I have tried with a copy from the LDC, and a copy from deepai. In both cases they fail with a "duplicate key" error. With the LDC version I have to convert the file extensions all to upper-case before I can load it at all.
... |
https://github.com/huggingface/datasets/issues/4422 | Cannot load timit_asr data set | Ah, if I change the train/ and test/ directories to TRAIN/ and TEST/ then it works! | ## Describe the bug
I am trying to load the timit_asr data set. I have tried with a copy from the LDC, and a copy from deepai. In both cases they fail with a "duplicate key" error. With the LDC version I have to convert the file extensions all to upper-case before I can load it at all.
## Steps to reproduce the bug... | 16 | Cannot load timit_asr data set
## Describe the bug
I am trying to load the timit_asr data set. I have tried with a copy from the LDC, and a copy from deepai. In both cases they fail with a "duplicate key" error. With the LDC version I have to convert the file extensions all to upper-case before I can load it at all.
... |
https://github.com/huggingface/datasets/issues/4422 | Cannot load timit_asr data set | Thanks for your investigation and report, @bhaddow. I'm adding another fix for the TRAIN/train and TEST/test directory names. | ## Describe the bug
I am trying to load the timit_asr data set. I have tried with a copy from the LDC, and a copy from deepai. In both cases they fail with a "duplicate key" error. With the LDC version I have to convert the file extensions all to upper-case before I can load it at all.
## Steps to reproduce the bug... | 18 | Cannot load timit_asr data set
## Describe the bug
I am trying to load the timit_asr data set. I have tried with a copy from the LDC, and a copy from deepai. In both cases they fail with a "duplicate key" error. With the LDC version I have to convert the file extensions all to upper-case before I can load it at all.
... |
https://github.com/huggingface/datasets/issues/5669 | Almost identical datasets, huge performance difference | Hi!
The first dataset stores images as bytes (the "image" column type is `datasets.Image()`) and decodes them as `PIL.Image` objects and the second dataset stores them as variable-length lists (the "image" column type is `datasets.Sequence(...)`)), so I guess going from `arrow bytes -> NumPy -> decoding as PIL.Imag... | ### Describe the bug
I am struggling to understand (huge) performance difference between two datasets that are almost identical.
### Steps to reproduce the bug
# Fast (normal) dataset speed:
```python
import cv2
from datasets import load_dataset
from torch.utils.data import DataLoader
dataset = load_dataset(... | 104 | Almost identical datasets, huge performance difference
### Describe the bug
I am struggling to understand (huge) performance difference between two datasets that are almost identical.
### Steps to reproduce the bug
# Fast (normal) dataset speed:
```python
import cv2
from datasets import load_dataset
from torch.... |
https://github.com/huggingface/datasets/issues/5669 | Almost identical datasets, huge performance difference | Thanks, @mariosasko. I could not understand why a (decoded) sequence should be MUCH slower than an encoded image (that must be decoded every time). At any rate, I tried you suggestion. It made the `map` step to run extremely slow (consumes all the 16GB of memory and starts swapping)
I tried also the easiest (as I se... | ### Describe the bug
I am struggling to understand (huge) performance difference between two datasets that are almost identical.
### Steps to reproduce the bug
# Fast (normal) dataset speed:
```python
import cv2
from datasets import load_dataset
from torch.utils.data import DataLoader
dataset = load_dataset(... | 254 | Almost identical datasets, huge performance difference
### Describe the bug
I am struggling to understand (huge) performance difference between two datasets that are almost identical.
### Steps to reproduce the bug
# Fast (normal) dataset speed:
```python
import cv2
from datasets import load_dataset
from torch.... |
https://github.com/huggingface/datasets/issues/5669 | Almost identical datasets, huge performance difference | Correction: the `beans` dataset stores the image file paths, not the bytes.
For your use case, I think it makes more sense to use `with_tranform` than `map` and lazily decode images with `cv2.imread` when indexing an example/batch:
```python
import cv2
def transform(batch):
batch["image2"] = np.stack([cv2... | ### Describe the bug
I am struggling to understand (huge) performance difference between two datasets that are almost identical.
### Steps to reproduce the bug
# Fast (normal) dataset speed:
```python
import cv2
from datasets import load_dataset
from torch.utils.data import DataLoader
dataset = load_dataset(... | 55 | Almost identical datasets, huge performance difference
### Describe the bug
I am struggling to understand (huge) performance difference between two datasets that are almost identical.
### Steps to reproduce the bug
# Fast (normal) dataset speed:
```python
import cv2
from datasets import load_dataset
from torch.... |
https://github.com/huggingface/datasets/issues/5669 | Almost identical datasets, huge performance difference | This is incorrect.
Did you try to run it? dataset[0] returns a tensor of numbers. dataset2[0]
returns the same tensor, but after a few long seconds. Looping over a
thousand of images cannot take 15 minutes.
On Fri, 24 Mar 2023 at 19:28 Mario Šaško ***@***.***> wrote:
> Correction: the beans dataset stores the imag... | ### Describe the bug
I am struggling to understand (huge) performance difference between two datasets that are almost identical.
### Steps to reproduce the bug
# Fast (normal) dataset speed:
```python
import cv2
from datasets import load_dataset
from torch.utils.data import DataLoader
dataset = load_dataset(... | 147 | Almost identical datasets, huge performance difference
### Describe the bug
I am struggling to understand (huge) performance difference between two datasets that are almost identical.
### Steps to reproduce the bug
# Fast (normal) dataset speed:
```python
import cv2
from datasets import load_dataset
from torch.... |
https://github.com/huggingface/datasets/issues/5669 | Almost identical datasets, huge performance difference | I updated the transform with the NumPy -> PyTorch conversion.
I'm sharing the entire code:
```python
import cv2
import numpy as np
import datasets
import torch
from datasets import load_dataset
from torch.utils.data import DataLoader
dataset = load_dataset("beans", split="train")
def transform(batch):
... | ### Describe the bug
I am struggling to understand (huge) performance difference between two datasets that are almost identical.
### Steps to reproduce the bug
# Fast (normal) dataset speed:
```python
import cv2
from datasets import load_dataset
from torch.utils.data import DataLoader
dataset = load_dataset(... | 97 | Almost identical datasets, huge performance difference
### Describe the bug
I am struggling to understand (huge) performance difference between two datasets that are almost identical.
### Steps to reproduce the bug
# Fast (normal) dataset speed:
```python
import cv2
from datasets import load_dataset
from torch.... |
https://github.com/huggingface/datasets/issues/5669 | Almost identical datasets, huge performance difference | Thanks, @mariosasko
My question remain unanswered though. Why is the `map`ed dataset so slow? My understanding is that a dataset of numpy arrays should be must faster than a dataset that has to decode images into numpy arrays every time one accesses an item. | ### Describe the bug
I am struggling to understand (huge) performance difference between two datasets that are almost identical.
### Steps to reproduce the bug
# Fast (normal) dataset speed:
```python
import cv2
from datasets import load_dataset
from torch.utils.data import DataLoader
dataset = load_dataset(... | 44 | Almost identical datasets, huge performance difference
### Describe the bug
I am struggling to understand (huge) performance difference between two datasets that are almost identical.
### Steps to reproduce the bug
# Fast (normal) dataset speed:
```python
import cv2
from datasets import load_dataset
from torch.... |
https://github.com/huggingface/datasets/issues/5927 | `IndexError` when indexing `Sequence` of `Array2D` with `None` values | Easy fix would be to add:
```python
null_indices -= np.arange(len(null_indices))
```
before L279, but I'm not sure it's the most intuitive way to fix it. | ### Describe the bug
Having `None` values in a `Sequence` of `ArrayND` fails.
### Steps to reproduce the bug
```python
from datasets import Array2D, Dataset, Features, Sequence
data = [
[
[[0]],
None,
None,
]
]
feature = Sequence(Array2D((1, 1), dtype="int64"))
dataset =... | 25 | `IndexError` when indexing `Sequence` of `Array2D` with `None` values
### Describe the bug
Having `None` values in a `Sequence` of `ArrayND` fails.
### Steps to reproduce the bug
```python
from datasets import Array2D, Dataset, Features, Sequence
data = [
[
[[0]],
None,
None,
... |
https://github.com/huggingface/datasets/issues/3638 | AutoTokenizer hash value got change after datasets.map | This issue was original reported at https://github.com/huggingface/transformers/issues/14931 and It seems like this issue also occur with other AutoClass like AutoFeatureExtractor. | ## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import load_dataset
from datasets.fingerprint import Hasher
tok... | 20 | AutoTokenizer hash value got change after datasets.map
## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import loa... |
https://github.com/huggingface/datasets/issues/3638 | AutoTokenizer hash value got change after datasets.map | Thanks for moving the issue here !
I wasn't able to reproduce the issue on my env (the hashes stay the same):
```
- `transformers` version: 1.15.0
- `tokenizers` version: 0.10.3
- `datasets` version: 1.18.1
- `dill` version: 0.3.4
- Platform: Linux-4.19.0-18-cloud-amd64-x86_64-with-debian-10.11
- Python versi... | ## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import load_dataset
from datasets.fingerprint import Hasher
tok... | 106 | AutoTokenizer hash value got change after datasets.map
## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import loa... |
https://github.com/huggingface/datasets/issues/3638 | AutoTokenizer hash value got change after datasets.map | I found the issue: the tokenizer has something inside it that changes.
Before the call, `tokenizer._tokenizer.truncation` is None, and after the call it changes to this for some reason:
```
{'max_length': 512, 'strategy': 'longest_first', 'stride': 0}
```
Does anybody know why calling the tokenizer would chang... | ## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import load_dataset
from datasets.fingerprint import Hasher
tok... | 56 | AutoTokenizer hash value got change after datasets.map
## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import loa... |
https://github.com/huggingface/datasets/issues/3638 | AutoTokenizer hash value got change after datasets.map | `tokenizer.encode(..)` does not accept argument like max_length, strategy or stride.
In `tokenizers` you have to modify the tokenizer state by setting various `TruncationParams` (and/or `PaddingParams`).
However, since this is modifying the state, you need to mutably borrow the tokenizer (a rust concept). The key p... | ## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import load_dataset
from datasets.fingerprint import Hasher
tok... | 271 | AutoTokenizer hash value got change after datasets.map
## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import loa... |
https://github.com/huggingface/datasets/issues/3638 | AutoTokenizer hash value got change after datasets.map | Thanks a lot for the explanation !
I think if we set these 2 dicts at initialization time it would be amazing already
Shall we open an issue in `transformers` to ask for these dictionaries to be set when the tokenizer is instantiated ?
> Edit: Another option would be to override the default hash function, but I ... | ## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import load_dataset
from datasets.fingerprint import Hasher
tok... | 127 | AutoTokenizer hash value got change after datasets.map
## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import loa... |
https://github.com/huggingface/datasets/issues/3638 | AutoTokenizer hash value got change after datasets.map | A hack we could have in the `datasets` lib would be to call the tokenizer before hashing it in order to set all its parameters correctly - but it sounds a lot like a hack and I'm not sure this can work in the long run | ## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import load_dataset
from datasets.fingerprint import Hasher
tok... | 46 | AutoTokenizer hash value got change after datasets.map
## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import loa... |
https://github.com/huggingface/datasets/issues/3638 | AutoTokenizer hash value got change after datasets.map | Fully agree with everything you said.
I think the best course of action is creating an issue in `transformers`. I can start the work on this.
I think the code changes are fairly simple. Making a sound test + not breaking other stuff might be different :D | ## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import load_dataset
from datasets.fingerprint import Hasher
tok... | 47 | AutoTokenizer hash value got change after datasets.map
## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import loa... |
https://github.com/huggingface/datasets/issues/3638 | AutoTokenizer hash value got change after datasets.map | It should be noted that this problem also occurs in other AutoClasses, such as AutoFeatureExtractor, so I don't think handling it in Datasets is a long-term practice either. | ## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import load_dataset
from datasets.fingerprint import Hasher
tok... | 28 | AutoTokenizer hash value got change after datasets.map
## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import loa... |
https://github.com/huggingface/datasets/issues/3638 | AutoTokenizer hash value got change after datasets.map | > I think the best course of action is creating an issue in `transformers`. I can start the work on this.
@Narsil Hi, I reopen this issue in `transformers` https://github.com/huggingface/transformers/issues/14931 | ## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import load_dataset
from datasets.fingerprint import Hasher
tok... | 30 | AutoTokenizer hash value got change after datasets.map
## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import loa... |
https://github.com/huggingface/datasets/issues/3638 | AutoTokenizer hash value got change after datasets.map | Here is @Narsil comment from https://github.com/huggingface/transformers/issues/14931#issuecomment-1074981569
> # TL;DR
> Call the function once on a dummy example beforehand will fix it.
>
> ```python
> tokenizer("Some", "test", truncation=True)
> ```
>
> # Long answer
> If I remember the last status, it's ... | ## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import load_dataset
from datasets.fingerprint import Hasher
tok... | 213 | AutoTokenizer hash value got change after datasets.map
## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import loa... |
https://github.com/huggingface/datasets/issues/3638 | AutoTokenizer hash value got change after datasets.map | Is there an easy solution for setting both num_proc and padding/truncation for fast tokenizer or caching just not a thing in this case? | ## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import load_dataset
from datasets.fingerprint import Hasher
tok... | 23 | AutoTokenizer hash value got change after datasets.map
## Describe the bug
AutoTokenizer hash value got change after datasets.map
## Steps to reproduce the bug
1. trash huggingface datasets cache
2. run the following code:
```python
from transformers import AutoTokenizer, BertTokenizer
from datasets import loa... |
https://github.com/huggingface/datasets/issues/7159 | JSON lines with missing struct fields raise TypeError: Couldn't cast array | Hello,
I have still the same issue when loading the dataset with the new version:
[https://huggingface.co/datasets/wikimedia/structured-wikipedia/discussions/5](https://huggingface.co/datasets/wikimedia/structured-wikipedia/discussions/5)
I have downloaded and unzipped the wikimedia/structured-wikipedia dataset ... | JSON lines with missing struct fields raise TypeError: Couldn't cast array of type.
See example: https://huggingface.co/datasets/wikimedia/structured-wikipedia/discussions/5
One would expect that the struct missing fields are added with null values. | 83 | JSON lines with missing struct fields raise TypeError: Couldn't cast array
JSON lines with missing struct fields raise TypeError: Couldn't cast array of type.
See example: https://huggingface.co/datasets/wikimedia/structured-wikipedia/discussions/5
One would expect that the struct missing fields are added with nu... |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.