
markdown stringlengths 0 1.02M | code stringlengths 0 832k | output stringlengths 0 1.02M | license stringlengths 3 36 | path stringlengths 6 265 | repo_name stringlengths 6 127 |
|---|---|---|---|---|---|
Communicate Results **Task 9:** Create a DataFrame `submission` whose index is the same as `X_test` and that has one column `'status_group'` with your predictions. Next, save this DataFrame as a CSV file and upload your submissions to our competition site. **Note:** Check the `sample_submission.csv` file on the compet... | submission = ... | _____no_output_____ | MIT | module3-cross-validation/LS_DS_223_assignment.ipynb | tbbcoach/DS-Unit-2-Kaggle-Challenge |
Semantic Image Clustering**Author:** [Khalid Salama](https://www.linkedin.com/in/khalid-salama-24403144/)**Date created:** 2021/02/28**Last modified:** 2021/02/28**Description:** Semantic Clustering by Adopting Nearest neighbors (SCAN) algorithm. IntroductionThis example demonstrates how to apply the [Semantic Cluste... | from collections import defaultdict
import random
import numpy as np
import tensorflow as tf
import tensorflow_addons as tfa
from tensorflow import keras
from tensorflow.keras import layers
import matplotlib.pyplot as plt
from tqdm import tqdm | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Prepare the data | num_classes = 10
input_shape = (32, 32, 3)
(x_train, y_train), (x_test, y_test) = keras.datasets.cifar10.load_data()
x_data = np.concatenate([x_train, x_test])
y_data = np.concatenate([y_train, y_test])
print("x_data shape:", x_data.shape, "- y_data shape:", y_data.shape)
classes = [
"airplane",
"automobile"... | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Define hyperparameters | target_size = 32 # Resize the input images.
representation_dim = 512 # The dimensions of the features vector.
projection_units = 128 # The projection head of the representation learner.
num_clusters = 20 # Number of clusters.
k_neighbours = 5 # Number of neighbours to consider during cluster learning.
tune_encoder... | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Implement data preprocessingThe data preprocessing step resizes the input images to the desired `target_size` and appliesfeature-wise normalization. Note that, when using `keras.applications.ResNet50V2` as thevisual encoder, resizing the images into 255 x 255 inputs would lead to more accurate resultsbut require a lon... | data_preprocessing = keras.Sequential(
[
layers.experimental.preprocessing.Resizing(target_size, target_size),
layers.experimental.preprocessing.Normalization(),
]
)
# Compute the mean and the variance from the data for normalization.
data_preprocessing.layers[-1].adapt(x_data) | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Data augmentationUnlike simCLR, which randomly picks a single data augmentation function to apply to an inputimage, we apply a set of data augmentation functions randomly to the input image.(You can experiment with other image augmentation techniques by following the [data augmentation tutorial](https://www.tensorflow... | data_augmentation = keras.Sequential(
[
layers.experimental.preprocessing.RandomTranslation(
height_factor=(-0.2, 0.2), width_factor=(-0.2, 0.2), fill_mode="nearest"
),
layers.experimental.preprocessing.RandomFlip(mode="horizontal"),
layers.experimental.preprocessing.Rand... | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Display a random image | image_idx = np.random.choice(range(x_data.shape[0]))
image = x_data[image_idx]
image_class = classes[y_data[image_idx][0]]
plt.figure(figsize=(3, 3))
plt.imshow(x_data[image_idx].astype("uint8"))
plt.title(image_class)
_ = plt.axis("off") | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Display a sample of augmented versions of the image | plt.figure(figsize=(10, 10))
for i in range(9):
augmented_images = data_augmentation(np.array([image]))
ax = plt.subplot(3, 3, i + 1)
plt.imshow(augmented_images[0].numpy().astype("uint8"))
plt.axis("off") | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Self-supervised representation learning Implement the vision encoder |
def create_encoder(representation_dim):
encoder = keras.Sequential(
[
keras.applications.ResNet50V2(
include_top=False, weights=None, pooling="avg"
),
layers.Dense(representation_dim),
]
)
return encoder
| _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Implement the unsupervised contrastive loss |
class RepresentationLearner(keras.Model):
def __init__(
self,
encoder,
projection_units,
num_augmentations,
temperature=1.0,
dropout_rate=0.1,
l2_normalize=False,
**kwargs
):
super(RepresentationLearner, self).__init__(**kwargs)
se... | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Train the model | # Create vision encoder.
encoder = create_encoder(representation_dim)
# Create representation learner.
representation_learner = RepresentationLearner(
encoder, projection_units, num_augmentations=2, temperature=0.1
)
# Create a a Cosine decay learning rate scheduler.
lr_scheduler = keras.experimental.CosineDecay(
... | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Plot training loss | plt.plot(history.history["loss"])
plt.ylabel("loss")
plt.xlabel("epoch")
plt.show() | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Compute the nearest neighbors Generate the embeddings for the images | batch_size = 500
# Get the feature vector representations of the images.
feature_vectors = encoder.predict(x_data, batch_size=batch_size, verbose=1)
# Normalize the feature vectores.
feature_vectors = tf.math.l2_normalize(feature_vectors, -1) | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Find the *k* nearest neighbours for each embedding | neighbours = []
num_batches = feature_vectors.shape[0] // batch_size
for batch_idx in tqdm(range(num_batches)):
start_idx = batch_idx * batch_size
end_idx = start_idx + batch_size
current_batch = feature_vectors[start_idx:end_idx]
# Compute the dot similarity.
similarities = tf.linalg.matmul(current... | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Let's display some neighbors on each row | nrows = 4
ncols = k_neighbours + 1
plt.figure(figsize=(12, 12))
position = 1
for _ in range(nrows):
anchor_idx = np.random.choice(range(x_data.shape[0]))
neighbour_indicies = neighbours[anchor_idx]
indices = [anchor_idx] + neighbour_indicies.tolist()
for j in range(ncols):
plt.subplot(nrows, nc... | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
You notice that images on each row are visually similar, and belong to similar classes. Semantic clustering with nearest neighbours Implement clustering consistency lossThis loss tries to make sure that neighbours have the same clustering assignments. |
class ClustersConsistencyLoss(keras.losses.Loss):
def __init__(self):
super(ClustersConsistencyLoss, self).__init__()
def __call__(self, target, similarity, sample_weight=None):
# Set targets to be ones.
target = tf.ones_like(similarity)
# Compute cross entropy loss.
lo... | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Implement the clusters entropy lossThis loss tries to make sure that cluster distribution is roughly uniformed, to avoidassigning most of the instances to one cluster. |
class ClustersEntropyLoss(keras.losses.Loss):
def __init__(self, entropy_loss_weight=1.0):
super(ClustersEntropyLoss, self).__init__()
self.entropy_loss_weight = entropy_loss_weight
def __call__(self, target, cluster_probabilities, sample_weight=None):
# Ideal entropy = log(num_cluster... | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Implement clustering modelThis model takes a raw image as an input, generated its feature vector using the trainedencoder, and produces a probability distribution of the clusters given the feature vectoras the cluster assignments. |
def create_clustering_model(encoder, num_clusters, name=None):
inputs = keras.Input(shape=input_shape)
# Preprocess the input images.
preprocessed = data_preprocessing(inputs)
# Apply data augmentation to the images.
augmented = data_augmentation(preprocessed)
# Generate embedding representatio... | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Implement clustering learnerThis model receives the input `anchor` image and its `neighbours`, produces the clustersassignments for them using the `clustering_model`, and produces two outputs:1. `similarity`: the similarity between the cluster assignments of the `anchor` image andits `neighbours`. This output is fed t... |
def create_clustering_learner(clustering_model):
anchor = keras.Input(shape=input_shape, name="anchors")
neighbours = keras.Input(
shape=tuple([k_neighbours]) + input_shape, name="neighbours"
)
# Changes neighbours shape to [batch_size * k_neighbours, width, height, channels]
neighbours_res... | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Train model | # If tune_encoder_during_clustering is set to False,
# then freeze the encoder weights.
for layer in encoder.layers:
layer.trainable = tune_encoder_during_clustering
# Create the clustering model and learner.
clustering_model = create_clustering_model(encoder, num_clusters, name="clustering")
clustering_learner = c... | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Plot training loss | plt.plot(history.history["loss"])
plt.ylabel("loss")
plt.xlabel("epoch")
plt.show() | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Cluster analysis Assign images to clusters | # Get the cluster probability distribution of the input images.
clustering_probs = clustering_model.predict(x_data, batch_size=batch_size, verbose=1)
# Get the cluster of the highest probability.
cluster_assignments = tf.math.argmax(clustering_probs, axis=-1).numpy()
# Store the clustering confidence.
# Images with the... | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Let's compute the cluster sizes | clusters = defaultdict(list)
for idx, c in enumerate(cluster_assignments):
clusters[c].append((idx, cluster_confidence[idx]))
for c in range(num_clusters):
print("cluster", c, ":", len(clusters[c])) | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Notice that the clusters have roughly balanced sizes. Visualize cluster imagesDisplay the *prototypes*—instances with the highest clustering confidence—of each cluster: | num_images = 8
plt.figure(figsize=(15, 15))
position = 1
for c in range(num_clusters):
cluster_instances = sorted(clusters[c], key=lambda kv: kv[1], reverse=True)
for j in range(num_images):
image_idx = cluster_instances[j][0]
plt.subplot(num_clusters, num_images, position)
plt.imshow(x... | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
Compute clustering accuracyFirst, we assign a label for each cluster based on the majority label of its images.Then, we compute the accuracy of each cluster by dividing the number of image with themajority label by the size of the cluster. | cluster_label_counts = dict()
for c in range(num_clusters):
cluster_label_counts[c] = [0] * num_classes
instances = clusters[c]
for i, _ in instances:
cluster_label_counts[c][y_data[i][0]] += 1
cluster_label_idx = np.argmax(cluster_label_counts[c])
correct_count = np.max(cluster_label_coun... | _____no_output_____ | Apache-2.0 | examples/vision/ipynb/semantic_image_clustering.ipynb | YassineYousfi/keras-io |
ANN | X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.3)
model = keras.Sequential([
keras.layers.Flatten(input_shape=(X.shape[1], X.shape[2])),
keras.layers.Dense(512, activation='relu'),
keras.layers.Dense(256, activation='relu'),
keras.layers.Dense(64, activation='relu'),
kera... | _____no_output_____ | Apache-2.0 | model_13.ipynb | Zxavy/Genre-Classifier |
CNN | X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.25)
X_train, X_validation, y_train, y_validation = train_test_split(X_train, y_train, test_size=0.2)
X_train = X_train[..., np.newaxis]
X_validation = X_validation[..., np.newaxis]
X_test = X_test[..., np.newaxis]
X_train.shape
input_shap... |
Real Genre : 7
Predicted Genre: 7
Real Genre : 1
Predicted Genre: 1
Real Genre : 8
Predicted Genre: 3
Real Genre : 1
Predicted Genre: 1
Real Genre : 6
Predicted Genre: 6
Real Genre : 1
Predicted Genre: 1
Real Genre : 0
Predicted Genre: 0
Real Genre : 5
Predicted Genre: 5
Real Ge... | Apache-2.0 | model_13.ipynb | Zxavy/Genre-Classifier |
Notebook 3 - Advanced Data StructuresSo far, we have seen numbers, strings, and lists. In this notebook, we will learn three more data structures, which allow us to organize data. The data structures are `tuple`, `set`, and `dict` (dictionary). TuplesA tuple is like a list, but is immutable, meaning that it cannot b... | tup = (1,'a',[1,2])
tup
print(tup[1])
print(tup[2][0])
tup[1] = 3
# We can turn a list into a tuple, and visa versa
print(list(tup))
print(tuple(list(tup)))
# We can have a tuple with a single item
single_tup = (1,)
print(single_tup) | _____no_output_____ | MIT | intro_to_python/3_Advanced_Data_Structures_Incomplete.ipynb | siqitoday/mban22_software_tools |
SetsWe consider the `set` data structure. The `set` is thought of similarly to how it is defined in mathematics: it is unordered, and has no duplicates. Let's contrast with the data structures we have seen thus far.* A `list` is an ordered, mutable collection of items* A `tuple` is an ordered, immutable collection of ... | some_numbers = [0,2,1,1,2]
my_set = set(some_numbers) # create a set out of the numbers
print(my_set) | _____no_output_____ | MIT | intro_to_python/3_Advanced_Data_Structures_Incomplete.ipynb | siqitoday/mban22_software_tools |
We observed that, by turning a list into a set, we automatically removed the duplicates. This idea will work on any collection. | my_string = 'aabbccda'
my_set = set(my_string)
print(my_set)
'a' in my_set
'a' in my_set and 'e' not in my_set | _____no_output_____ | MIT | intro_to_python/3_Advanced_Data_Structures_Incomplete.ipynb | siqitoday/mban22_software_tools |
Suppose we wanted to remove `'a'` from `my_set`, but don't know the syntax for it. Fortunately, there is built-in help features.* Typing `my_set.` lists different member functions of `my_set`.* The function `help(my_set)` also lists different functions, along with explanations. | my_set.
help(my_set) | _____no_output_____ | MIT | intro_to_python/3_Advanced_Data_Structures_Incomplete.ipynb | siqitoday/mban22_software_tools |
Dictionaries These are *very* useful!Given $n$ values, a list `l` store $n$ values, which can be accessed by `l[i]` for each $i = 0,\ldots,n-1$. A *dictionary* is a data structure that allows us to access values by general types of keys. This is useful in designing efficient algorithms and writing simple code. | # Create a dictionary of produce and their prices
product_prices = {}
# Add produce and prices to the dictionary
product_prices['apple'] = 2
product_prices['banana'] = 2
product_prices['carrot'] = 3
# View the dictionary
print(product_prices)
| _____no_output_____ | MIT | intro_to_python/3_Advanced_Data_Structures_Incomplete.ipynb | siqitoday/mban22_software_tools |
Dictionaries behave in ways similar to a list. | # Print the price of a banana
print(product_prices['banana'])
# Check if 'banana' is a key in the dictionary.
print('banana' in product_prices)
# Check if `donut` is a key in the dictonary.
print('donut' in product_prices) | _____no_output_____ | MIT | intro_to_python/3_Advanced_Data_Structures_Incomplete.ipynb | siqitoday/mban22_software_tools |
Dictionaries allow us to access their keys and values directly. | # View the keys of the dictionary
produce = product_prices.keys()
print(produce)
# The keys are a list
type(produce)
# Using list comprehensions, we can find all produce that
# have 6 characters in their name.
print([name for name in product_prices if len(name) == 6])
# Python knows that we want to iterate through the... | _____no_output_____ | MIT | intro_to_python/3_Advanced_Data_Structures_Incomplete.ipynb | siqitoday/mban22_software_tools |
Dictionaries don't have to be indexed by strings. It can be indexed by numbers. | my_dict = {1: 5, 'abc': '123'}
print(my_dict) | _____no_output_____ | MIT | intro_to_python/3_Advanced_Data_Structures_Incomplete.ipynb | siqitoday/mban22_software_tools |
Dictionaries can be created in several ways. We have seen two so far.* Creating an empty dictionary with `{}`, then adding (key,value) pairs, one at a time.* Creating an dictionary at once as `{key1:val1, key2:val2, ...}`There are more ways to create dictionaries, that are convenient in different situations. We will se... | # Create a dictionary, with a key of i^2 and a value of i for each i in 0,...,1000
squared_numbers = {i**2: i for i in range(10)}
print(81 in squared_numbers)
print(squared_numbers[81])
names = ['alice','bob','cindy']
sports = [['Archery', 'Badmitton'], ['Archery', 'Curling'], ['Badmitton', 'Diving']]
# Create a dict... | _____no_output_____ | MIT | intro_to_python/3_Advanced_Data_Structures_Incomplete.ipynb | siqitoday/mban22_software_tools |
Mount Google Drive (Works only on Google Colab) | from google.colab import drive
drive.mount('/content/gdrive') | Go to this URL in a browser: https://accounts.google.com/o/oauth2/auth?client_id=947318989803-6bn6qk8qdgf4n4g3pfee6491hc0brc4i.apps.googleusercontent.com&redirect_uri=urn%3aietf%3awg%3aoauth%3a2.0%3aoob&response_type=code&scope=email%20https%3a%2f%2fwww.googleapis.com%2fauth%2fdocs.test%20https%3a%2f%2fwww.googleapis.c... | MIT | MODEST_Museum_Dataset_Statistics.ipynb | shan18/MODEST-Museum-Dataset |
Import Packages | import os
import numpy as np
import pandas as pd
from zipfile import ZipFile
from PIL import Image
from tqdm.autonotebook import tqdm
from IPython.display import display
from IPython.display import Image as Dimage | /usr/local/lib/python3.6/dist-packages/ipykernel_launcher.py:7: TqdmExperimentalWarning: Using `tqdm.autonotebook.tqdm` in notebook mode. Use `tqdm.tqdm` instead to force console mode (e.g. in jupyter console)
import sys
| MIT | MODEST_Museum_Dataset_Statistics.ipynb | shan18/MODEST-Museum-Dataset |
Define PathsDefine paths of all the required directories | # Root path of the dataset
ROOT_DATA_DIR = '/content/gdrive/My Drive/modest_museum_dataset.zip' | _____no_output_____ | MIT | MODEST_Museum_Dataset_Statistics.ipynb | shan18/MODEST-Museum-Dataset |
Data VisualizationLet's visualize some of the foreground and background images | def make_grid(images_list, height=140, margin=8, aspect_ratio=False):
"""Combine Images to form a grid.
Args:
images (list): List of PIL images to display in grid.
height (int): Height to which the image will be resized.
margin (int): Amount of padding between the images in grid.
... | _____no_output_____ | MIT | MODEST_Museum_Dataset_Statistics.ipynb | shan18/MODEST-Museum-Dataset |
Data StatisticsLet's calculate mean, standard deviation and total number of images for each type of image category. MeanMean is calculated using the formula where, `sum of the terms` represents a pixel value and `number of terms` represents the total number of pixels across all the images. Standard DeviationStandard ... | def statistics(filename, channel_num, filetype):
"""Calculates data statistics
Args:
path (str): Path of the directory for which statistics is to be calculated
Returns:
Mean, standard deviation, number of images
"""
counter = 0
mean = []
std = []
images = [] # store PI... | _____no_output_____ | MIT | MODEST_Museum_Dataset_Statistics.ipynb | shan18/MODEST-Museum-Dataset |
Statistics for Background images | # Background
print('Calculating statistics for Backgrounds...')
bg_mean, bg_std, bg_counter, bg_dim, bg_images = statistics(ROOT_DATA_DIR, 3, 'bg')
# Display
print('Background Images:')
make_grid(bg_images, margin=30)
print('Data Statistics for Background images')
stats = {
'Statistics': ['Mean', 'Standard deviati... | Data Statistics for Background images
| MIT | MODEST_Museum_Dataset_Statistics.ipynb | shan18/MODEST-Museum-Dataset |
Statistics for Background-Foreground images | # Background-Foreground
print('Calculating statistics for Background-Foreground Images...')
bg_fg_mean, bg_fg_std, bg_fg_counter, bg_fg_dim, bg_fg_image = statistics(ROOT_DATA_DIR, 3, 'bg_fg')
# Display
print('Background-Foreground Images:')
make_grid(bg_fg_image, margin=30)
print('Data Statistics for Background-Foregr... | Data Statistics for Background-Foreground images
| MIT | MODEST_Museum_Dataset_Statistics.ipynb | shan18/MODEST-Museum-Dataset |
Statistics for Background-Foreground Masks | #Foreground-Background Masks
print('Calculating statistics for Foreground-Background Masks...')
bg_fg_mask_mean, bg_fg_mask_std, bg_fg_mask_counter, bg_fg_mask_dim, bg_fg_mask_images = statistics(ROOT_DATA_DIR, 1, 'bg_fg_mask')
# Display
print('Background-Foreground Masks:')
make_grid(bg_fg_mask_images, margin=30, aspe... | Data Statistics for Background-Foreground Masks images
| MIT | MODEST_Museum_Dataset_Statistics.ipynb | shan18/MODEST-Museum-Dataset |
Statistics for Background-Foreground Depth Maps | #Foreground-Background Depth Map
print('Calculating statistics for Foreground-Background Depth Map...')
depth_mean, depth_std, depth_counter, depth_dim, depth_images = statistics(ROOT_DATA_DIR, 1, 'bg_fg_depth_map')
# Display
print('Background-Foreground Depth Maps:')
make_grid(depth_images, margin=30)
print('Data Stat... | _____no_output_____ | MIT | MODEST_Museum_Dataset_Statistics.ipynb | shan18/MODEST-Museum-Dataset |
Pandas Contents- [Pandas](Pandas) - [Overview](Overview) - [Series](Series) - [DataFrames](DataFrames) - [On-Line Data Sources](On-Line-Data-Sources) - [Exercises](Exercises) - [Solutions](Solutions) In addition to what’s in Anaconda, this lecture will need the fol... | !pip install --upgrade pandas-datareader | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Overview[Pandas](http://pandas.pydata.org/) is a package of fast, efficient data analysis tools for Python.Its popularity has surged in recent years, coincident with the riseof fields such as data science and machine learning.Here’s a popularity comparison over time against STATA, SAS, and [dplyr](https://dplyr.tidyve... | %matplotlib inline
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
plt.rcParams["figure.figsize"] = [10,8] # Set default figure size
import requests | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
SeriesTwo important data types defined by pandas are `Series` and `DataFrame`.You can think of a `Series` as a “column” of data, such as a collection of observations on a single variable.A `DataFrame` is an object for storing related columns of data.Let’s start with Series | s = pd.Series(np.random.randn(4), name='daily returns')
s | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Here you can imagine the indices `0, 1, 2, 3` as indexing four listedcompanies, and the values being daily returns on their shares.Pandas `Series` are built on top of NumPy arrays and support many similaroperations | s * 100
np.abs(s) | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
But `Series` provide more than NumPy arrays.Not only do they have some additional (statistically oriented) methods | s.describe() | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
But their indices are more flexible | s.index = ['AMZN', 'AAPL', 'MSFT', 'GOOG']
s | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Viewed in this way, `Series` are like fast, efficient Python dictionaries(with the restriction that the items in the dictionary all have the sametype—in this case, floats).In fact, you can use much of the same syntax as Python dictionaries | s['AMZN']
s['AMZN'] = 0
s
'AAPL' in s | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
DataFramesWhile a `Series` is a single column of data, a `DataFrame` is several columns, one for each variable.In essence, a `DataFrame` in pandas is analogous to a (highly optimized) Excel spreadsheet.Thus, it is a powerful tool for representing and analyzing data that are naturally organized into rows and columns, ... | df = pd.read_csv('https://raw.githubusercontent.com/QuantEcon/lecture-python-programming/master/source/_static/lecture_specific/pandas/data/test_pwt.csv')
type(df)
df | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
We can select particular rows using standard Python array slicing notation | df[2:5] | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
To select columns, we can pass a list containing the names of the desired columns represented as strings | df[['country', 'tcgdp']] | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
To select both rows and columns using integers, the `iloc` attribute should be used with the format `.iloc[rows, columns]` | df.iloc[2:5, 0:4] | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
To select rows and columns using a mixture of integers and labels, the `loc` attribute can be used in a similar way | df.loc[df.index[2:5], ['country', 'tcgdp']] | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Let’s imagine that we’re only interested in population (`POP`) and total GDP (`tcgdp`).One way to strip the data frame `df` down to only these variables is to overwrite the dataframe using the selection method described above | df = df[['country', 'POP', 'tcgdp']]
df | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Here the index `0, 1,..., 7` is redundant because we can use the country names as an index.To do this, we set the index to be the `country` variable in the dataframe | df = df.set_index('country')
df | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Let’s give the columns slightly better names | df.columns = 'population', 'total GDP'
df | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Population is in thousands, let’s revert to single units | df['population'] = df['population'] * 1e3
df | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Next, we’re going to add a column showing real GDP per capita, multiplying by 1,000,000 as we go because total GDP is in millions | df['GDP percap'] = df['total GDP'] * 1e6 / df['population']
df | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
One of the nice things about pandas `DataFrame` and `Series` objects is that they have methods for plotting and visualization that work through Matplotlib.For example, we can easily generate a bar plot of GDP per capita | ax = df['GDP percap'].plot(kind='bar')
ax.set_xlabel('country', fontsize=12)
ax.set_ylabel('GDP per capita', fontsize=12)
plt.show() | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
At the moment the data frame is ordered alphabetically on the countries—let’s change it to GDP per capita | df = df.sort_values(by='GDP percap', ascending=False)
df | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Plotting as before now yields | ax = df['GDP percap'].plot(kind='bar')
ax.set_xlabel('country', fontsize=12)
ax.set_ylabel('GDP per capita', fontsize=12)
plt.show() | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
On-Line Data SourcesPython makes it straightforward to query online databases programmatically.An important database for economists is [FRED](https://research.stlouisfed.org/fred2/) — a vast collection of time series data maintained by the St. Louis Fed.For example, suppose that we are interested in the [unemployment ... | r = requests.get('http://research.stlouisfed.org/fred2/series/UNRATE/downloaddata/UNRATE.csv') | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
If there’s no error message, then the call has succeeded.If you do get an error, then there are two likely causes1. You are not connected to the Internet — hopefully, this isn’t the case. 1. Your machine is accessing the Internet through a proxy server, and Python isn’t aware of this. In the second case, you can eith... | url = 'http://research.stlouisfed.org/fred2/series/UNRATE/downloaddata/UNRATE.csv'
source = requests.get(url).content.decode().split("\n")
source[0]
source[1]
source[2] | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
We could now write some additional code to parse this text and store it as an array.But this is unnecessary — pandas’ `read_csv` function can handle the task for us.We use `parse_dates=True` so that pandas recognizes our dates column, allowing for simple date filtering | data = pd.read_csv(url, index_col=0, parse_dates=True) | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
The data has been read into a pandas DataFrame called `data` that we can now manipulate in the usual way | type(data)
data.head() # A useful method to get a quick look at a data frame
pd.set_option('precision', 1)
data.describe() # Your output might differ slightly | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
We can also plot the unemployment rate from 2006 to 2012 as follows | ax = data['2006':'2012'].plot(title='US Unemployment Rate', legend=False)
ax.set_xlabel('year', fontsize=12)
ax.set_ylabel('%', fontsize=12)
plt.show() | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Note that pandas offers many other file type alternatives.Pandas has [a wide variety](https://pandas.pydata.org/pandas-docs/stable/user_guide/io.html) of top-level methods that we can use to read, excel, json, parquet or plug straight into a database server. Using pandas_datareader to Access DataThe maker of pandas ha... | from pandas_datareader import wb
govt_debt = wb.download(indicator='GC.DOD.TOTL.GD.ZS', country=['US', 'AU'], start=2005, end=2016).stack().unstack(0)
ind = govt_debt.index.droplevel(-1)
govt_debt.index = ind
ax = govt_debt.plot(lw=2)
ax.set_xlabel('year', fontsize=12)
plt.title("Government Debt to GDP (%)")
plt.show(... | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
The [documentation](https://pandas-datareader.readthedocs.io/en/latest/index.html) provides more details on how to access various data sources. Exercises Exercise 1With these imports: | import datetime as dt
from pandas_datareader import data | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Write a program to calculate the percentage price change over 2019 for the following shares: | ticker_list = {'INTC': 'Intel',
'MSFT': 'Microsoft',
'IBM': 'IBM',
'BHP': 'BHP',
'TM': 'Toyota',
'AAPL': 'Apple',
'AMZN': 'Amazon',
'BA': 'Boeing',
'QCOM': 'Qualcomm',
'KO': 'Coca-Cola'... | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Here’s the first part of the program | def read_data(ticker_list,
start=dt.datetime(2019, 1, 2),
end=dt.datetime(2019, 12, 31)):
"""
This function reads in closing price data from Yahoo
for each tick in the ticker_list.
"""
ticker = pd.DataFrame()
for tick in ticker_list:
prices = data.DataReader(tick, 'y... | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Complete the program to plot the result as a bar graph like this one: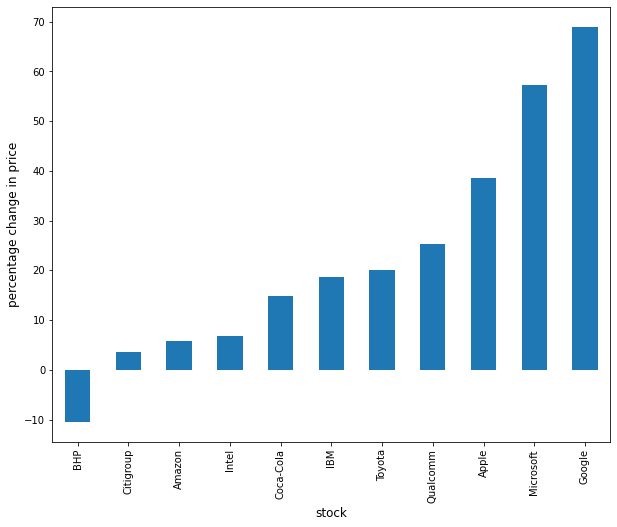 Exercise 2Using the method `read_data` introduced ... | indices_list = {'^GSPC': 'S&P 500',
'^IXIC': 'NASDAQ',
'^DJI': 'Dow Jones',
'^N225': 'Nikkei'} | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Complete the program to show summary statistics and plot the result as a time series graph like this one: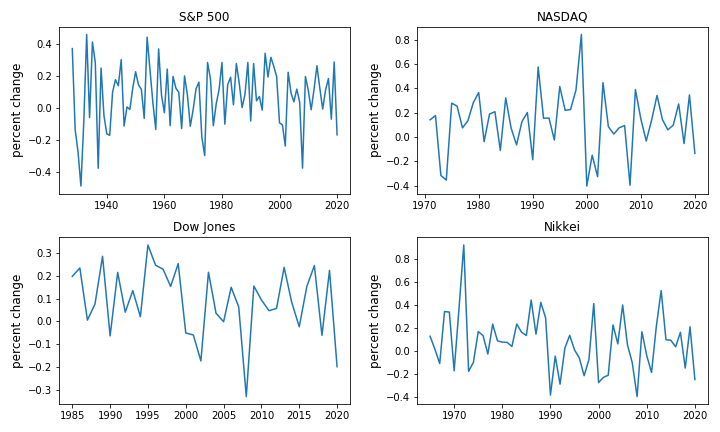 Soluti... | p1 = ticker.iloc[0] #Get the first set of prices as a Series
p2 = ticker.iloc[-1] #Get the last set of prices as a Series
price_change = (p2 - p1) / p1 * 100
price_change | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Alternatively you can use an inbuilt method `pct_change` and configure it toperform the correct calculation using `periods` argument. | change = ticker.pct_change(periods=len(ticker)-1, axis='rows')*100
price_change = change.iloc[-1]
price_change | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Then to plot the chart | price_change.sort_values(inplace=True)
price_change = price_change.rename(index=ticker_list)
fig, ax = plt.subplots(figsize=(10,8))
ax.set_xlabel('stock', fontsize=12)
ax.set_ylabel('percentage change in price', fontsize=12)
price_change.plot(kind='bar', ax=ax)
plt.show() | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Exercise 2Following the work you did in [Exercise 1](pd-ex1), you can query the data using `read_data` by updating the start and end dates accordingly. | indices_data = read_data(
indices_list,
start=dt.datetime(1928, 1, 2),
end=dt.datetime(2020, 12, 31)
) | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Then, extract the first and last set of prices per year as DataFrames and calculate the yearly returns such as: | yearly_returns = pd.DataFrame()
for index, name in indices_list.items():
p1 = indices_data.groupby(indices_data.index.year)[index].first() # Get the first set of returns as a DataFrame
p2 = indices_data.groupby(indices_data.index.year)[index].last() # Get the last set of returns as a DataFrame
returns =... | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Next, you can obtain summary statistics by using the method `describe`. | yearly_returns.describe() | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Then, to plot the chart | fig, axes = plt.subplots(2, 2, figsize=(10, 8))
for iter_, ax in enumerate(axes.flatten()): # Flatten 2-D array to 1-D array
index_name = yearly_returns.columns[iter_] # Get index name per iteration
ax.plot(yearly_returns[index_name]) # Plot pct change of yearly returns per in... | _____no_output_____ | BSD-3-Clause | tests/project/ipynb/pandas.ipynb | QuantEcon/sphinx-tojupyter |
Also other distance metrics are present, such as chebyshev, minkowski, mahalanobis, haversine, hamming, canberra, braycurtis and many more. | minkowski_distance(x=[7,6,3,-1], y=[0,3,4,5], p_value=3) | _____no_output_____ | MIT | Old/Group_asgnt (1).ipynb | Rick-Mackenbach/DPA-Group-Assignment |
Anna KaRNNaIn this notebook, I'll build a character-wise RNN trained on Anna Karenina, one of my all-time favorite books. It'll be able to generate new text based on the text from the book.This network is based off of Andrej Karpathy's [post on RNNs](http://karpathy.github.io/2015/05/21/rnn-effectiveness/) and [implem... | import time
from collections import namedtuple
import numpy as np
import tensorflow as tf | _____no_output_____ | MIT | intro-to-rnns/Anna_KaRNNa_Solution.ipynb | ys3x/deep-learning |
First we'll load the text file and convert it into integers for our network to use. Here I'm creating a couple dictionaries to convert the characters to and from integers. Encoding the characters as integers makes it easier to use as input in the network. | with open('anna.txt', 'r') as f:
text=f.read()
vocab = sorted(set(text))
vocab_to_int = {c: i for i, c in enumerate(vocab)}
int_to_vocab = dict(enumerate(vocab))
encoded = np.array([vocab_to_int[c] for c in text], dtype=np.int32) | _____no_output_____ | MIT | intro-to-rnns/Anna_KaRNNa_Solution.ipynb | ys3x/deep-learning |
Let's check out the first 100 characters, make sure everything is peachy. According to the [American Book Review](http://americanbookreview.org/100bestlines.asp), this is the 6th best first line of a book ever. | text[:100] | _____no_output_____ | MIT | intro-to-rnns/Anna_KaRNNa_Solution.ipynb | ys3x/deep-learning |
And we can see the characters encoded as integers. | encoded[:100] | _____no_output_____ | MIT | intro-to-rnns/Anna_KaRNNa_Solution.ipynb | ys3x/deep-learning |
Since the network is working with individual characters, it's similar to a classification problem in which we are trying to predict the next character from the previous text. Here's how many 'classes' our network has to pick from. | len(vocab) | _____no_output_____ | MIT | intro-to-rnns/Anna_KaRNNa_Solution.ipynb | ys3x/deep-learning |
Making training mini-batchesHere is where we'll make our mini-batches for training. Remember that we want our batches to be multiple sequences of some desired number of sequence steps. Considering a simple example, our batches would look like this:We start with our text encoded as integers in one long array in `encode... | def get_batches(arr, batch_size, n_steps):
'''Create a generator that returns batches of size
batch_size x n_steps from arr.
Arguments
---------
arr: Array you want to make batches from
batch_size: Batch size, the number of sequences per batch
n_steps: Number of seq... | _____no_output_____ | MIT | intro-to-rnns/Anna_KaRNNa_Solution.ipynb | ys3x/deep-learning |
Now I'll make my data sets and we can check out what's going on here. Here I'm going to use a batch size of 10 and 50 sequence steps. | batches = get_batches(encoded, 10, 50)
x, y = next(batches)
print('x\n', x[:10, :10])
print('\ny\n', y[:10, :10]) | x
[[31 64 57 72 76 61 74 1 16 0]
[ 1 57 69 1 70 71 76 1 63 71]
[78 65 70 13 0 0 3 53 61 75]
[70 1 60 77 74 65 70 63 1 64]
[ 1 65 76 1 65 75 11 1 75 65]
[ 1 37 76 1 79 57 75 0 71 70]
[64 61 70 1 59 71 69 61 1 62]
[26 1 58 77 76 1 70 71 79 1]
[76 1 65 75 70 7 76 13 1 48]
[ 1 75 57 65 60 1 ... | MIT | intro-to-rnns/Anna_KaRNNa_Solution.ipynb | ys3x/deep-learning |
If you implemented `get_batches` correctly, the above output should look something like ```x [[55 63 69 22 6 76 45 5 16 35] [ 5 69 1 5 12 52 6 5 56 52] [48 29 12 61 35 35 8 64 76 78] [12 5 24 39 45 29 12 56 5 63] [ 5 29 6 5 29 78 28 5 78 29] [ 5 13 6 5 36 69 78 35 52 12] [63 76 12 5 18 52 1 76 5 58] [3... | def build_inputs(batch_size, num_steps):
''' Define placeholders for inputs, targets, and dropout
Arguments
---------
batch_size: Batch size, number of sequences per batch
num_steps: Number of sequence steps in a batch
'''
# Declare placeholders we'll feed into... | _____no_output_____ | MIT | intro-to-rnns/Anna_KaRNNa_Solution.ipynb | ys3x/deep-learning |
LSTM CellHere we will create the LSTM cell we'll use in the hidden layer. We'll use this cell as a building block for the RNN. So we aren't actually defining the RNN here, just the type of cell we'll use in the hidden layer.We first create a basic LSTM cell with```pythonlstm = tf.contrib.rnn.BasicLSTMCell(num_units)``... | def build_lstm(lstm_size, num_layers, batch_size, keep_prob):
''' Build LSTM cell.
Arguments
---------
keep_prob: Scalar tensor (tf.placeholder) for the dropout keep probability
lstm_size: Size of the hidden layers in the LSTM cells
num_layers: Number of LSTM layers
... | _____no_output_____ | MIT | intro-to-rnns/Anna_KaRNNa_Solution.ipynb | ys3x/deep-learning |
RNN OutputHere we'll create the output layer. We need to connect the output of the RNN cells to a full connected layer with a softmax output. The softmax output gives us a probability distribution we can use to predict the next character.If our input has batch size $N$, number of steps $M$, and the hidden layer has $L... | def build_output(lstm_output, in_size, out_size):
''' Build a softmax layer, return the softmax output and logits.
Arguments
---------
x: Input tensor
in_size: Size of the input tensor, for example, size of the LSTM cells
out_size: Size of this softmax layer
... | _____no_output_____ | MIT | intro-to-rnns/Anna_KaRNNa_Solution.ipynb | ys3x/deep-learning |
Training lossNext up is the training loss. We get the logits and targets and calculate the softmax cross-entropy loss. First we need to one-hot encode the targets, we're getting them as encoded characters. Then, reshape the one-hot targets so it's a 2D tensor with size $(M*N) \times C$ where $C$ is the number of class... | def build_loss(logits, targets, lstm_size, num_classes):
''' Calculate the loss from the logits and the targets.
Arguments
---------
logits: Logits from final fully connected layer
targets: Targets for supervised learning
lstm_size: Number of LSTM hidden units
nu... | _____no_output_____ | MIT | intro-to-rnns/Anna_KaRNNa_Solution.ipynb | ys3x/deep-learning |
OptimizerHere we build the optimizer. Normal RNNs have have issues gradients exploding and disappearing. LSTMs fix the disappearance problem, but the gradients can still grow without bound. To fix this, we can clip the gradients above some threshold. That is, if a gradient is larger than that threshold, we set it to t... | def build_optimizer(loss, learning_rate, grad_clip):
''' Build optmizer for training, using gradient clipping.
Arguments:
loss: Network loss
learning_rate: Learning rate for optimizer
'''
# Optimizer for training, using gradient clipping to control exploding gradients
... | _____no_output_____ | MIT | intro-to-rnns/Anna_KaRNNa_Solution.ipynb | ys3x/deep-learning |
Build the networkNow we can put all the pieces together and build a class for the network. To actually run data through the LSTM cells, we will use [`tf.nn.dynamic_rnn`](https://www.tensorflow.org/versions/r1.0/api_docs/python/tf/nn/dynamic_rnn). This function will pass the hidden and cell states across LSTM cells app... | class CharRNN:
def __init__(self, num_classes, batch_size=64, num_steps=50,
lstm_size=128, num_layers=2, learning_rate=0.001,
grad_clip=5, sampling=False):
# When we're using this network for sampling later, we'll be passing in
# one characte... | _____no_output_____ | MIT | intro-to-rnns/Anna_KaRNNa_Solution.ipynb | ys3x/deep-learning |
HyperparametersHere I'm defining the hyperparameters for the network. * `batch_size` - Number of sequences running through the network in one pass.* `num_steps` - Number of characters in the sequence the network is trained on. Larger is better typically, the network will learn more long range dependencies. But it take... | batch_size = 100 # Sequences per batch
num_steps = 100 # Number of sequence steps per batch
lstm_size = 512 # Size of hidden layers in LSTMs
num_layers = 2 # Number of LSTM layers
learning_rate = 0.001 # Learning rate
keep_prob = 0.5 # Dropout keep probability | _____no_output_____ | MIT | intro-to-rnns/Anna_KaRNNa_Solution.ipynb | ys3x/deep-learning |
Time for trainingThis is typical training code, passing inputs and targets into the network, then running the optimizer. Here we also get back the final LSTM state for the mini-batch. Then, we pass that state back into the network so the next batch can continue the state from the previous batch. And every so often (se... | epochs = 20
# Print losses every N interations
print_every_n = 50
# Save every N iterations
save_every_n = 200
model = CharRNN(len(vocab), batch_size=batch_size, num_steps=num_steps,
lstm_size=lstm_size, num_layers=num_layers,
learning_rate=learning_rate)
saver = tf.train.Saver(max_t... | _____no_output_____ | MIT | intro-to-rnns/Anna_KaRNNa_Solution.ipynb | ys3x/deep-learning |
Saved checkpointsRead up on saving and loading checkpoints here: https://www.tensorflow.org/programmers_guide/variables | tf.train.get_checkpoint_state('checkpoints') | _____no_output_____ | MIT | intro-to-rnns/Anna_KaRNNa_Solution.ipynb | ys3x/deep-learning |
SamplingNow that the network is trained, we'll can use it to generate new text. The idea is that we pass in a character, then the network will predict the next character. We can use the new one, to predict the next one. And we keep doing this to generate all new text. I also included some functionality to prime the ne... | def pick_top_n(preds, vocab_size, top_n=5):
p = np.squeeze(preds)
p[np.argsort(p)[:-top_n]] = 0
p = p / np.sum(p)
c = np.random.choice(vocab_size, 1, p=p)[0]
return c
def sample(checkpoint, n_samples, lstm_size, vocab_size, prime="The "):
samples = [c for c in prime]
model = CharRNN(len(voca... | _____no_output_____ | MIT | intro-to-rnns/Anna_KaRNNa_Solution.ipynb | ys3x/deep-learning |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.