
markdown stringlengths 0 1.02M | code stringlengths 0 832k | output stringlengths 0 1.02M | license stringlengths 3 36 | path stringlengths 6 265 | repo_name stringlengths 6 127 |
|---|---|---|---|---|---|
Concat the Dataframes | try:
df_associations = pd.concat(df_frames)
display(df_associations)
except:
print("No items or transactions meet the user requirements!") | _____no_output_____ | MIT | .ipynb_checkpoints/Apriori_Algo-checkpoint.ipynb | MichaelWoo-git/Apriori_Algorithm_from_Scratch |
Making sure that user parameters are met for confidence | try:
df_associations = df_associations[df_associations['confidence'] >= confidence_percent]
display(df_associations)
except:
print("No items or transactions meet the user requirements!") | _____no_output_____ | MIT | .ipynb_checkpoints/Apriori_Algo-checkpoint.ipynb | MichaelWoo-git/Apriori_Algorithm_from_Scratch |
Formatting the Dataframe Final | try:
df_final = df_associations.reset_index().drop(['index','support_sing'],axis=1)
df_final.columns = ["Association","Support","Confidence"]
except:
print("No items or transactions meet the user requirements!") | _____no_output_____ | MIT | .ipynb_checkpoints/Apriori_Algo-checkpoint.ipynb | MichaelWoo-git/Apriori_Algorithm_from_Scratch |
Final Associations | try:
print("Store Name: "+ str(ns(int(store_num))))
print("\nFinal Associations that meet the user standards....")
print("Support: " + str(support_percent) + "%" + "\t" + "Confidence: " + str(confidence_percent) + '%')
#this will display the max column width so we can see the associations involved....
... | _____no_output_____ | MIT | .ipynb_checkpoints/Apriori_Algo-checkpoint.ipynb | MichaelWoo-git/Apriori_Algorithm_from_Scratch |
Neural Transfer Input images | %matplotlib inline
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
import torch.optim as optim
from PIL import Image
import matplotlib.pyplot as plt
import torchvision.transforms as transforms
import torchvision.models as models
import copy
np.random.seed(37)
torch.manual_seed... | _____no_output_____ | CC-BY-4.0 | sphinx/pytorch-intro/source/neural-transfer.ipynb | oneoffcoder/books |
Loss functions Content loss | class ContentLoss(nn.Module):
def __init__(self, target,):
super(ContentLoss, self).__init__()
# we 'detach' the target content from the tree used
# to dynamically compute the gradient: this is a stated value,
# not a variable. Otherwise the forward method of the criterion
#... | _____no_output_____ | CC-BY-4.0 | sphinx/pytorch-intro/source/neural-transfer.ipynb | oneoffcoder/books |
Style loss | def gram_matrix(input):
a, b, c, d = input.size() # a=batch size(=1)
# b=number of feature maps
# (c,d)=dimensions of a f. map (N=c*d)
features = input.view(a * b, c * d) # resise F_XL into \hat F_XL
G = torch.mm(features, features.t()) # compute the gram product
# we 'normalize' the value... | _____no_output_____ | CC-BY-4.0 | sphinx/pytorch-intro/source/neural-transfer.ipynb | oneoffcoder/books |
Model | device = get_device()
cnn = models.vgg19(pretrained=True).features.to(device).eval() | _____no_output_____ | CC-BY-4.0 | sphinx/pytorch-intro/source/neural-transfer.ipynb | oneoffcoder/books |
Normalization | class Normalization(nn.Module):
def __init__(self, mean, std):
super(Normalization, self).__init__()
# .view the mean and std to make them [C x 1 x 1] so that they can
# directly work with image Tensor of shape [B x C x H x W].
# B is batch size. C is number of channels. H is height ... | _____no_output_____ | CC-BY-4.0 | sphinx/pytorch-intro/source/neural-transfer.ipynb | oneoffcoder/books |
Loss | content_layers_default = ['conv_4']
style_layers_default = ['conv_1', 'conv_2', 'conv_3', 'conv_4', 'conv_5']
def get_style_model_and_losses(cnn, normalization_mean, normalization_std,
style_img, content_img,
content_layers=content_layers_default,
... | _____no_output_____ | CC-BY-4.0 | sphinx/pytorch-intro/source/neural-transfer.ipynb | oneoffcoder/books |
Optimizer | def get_input_optimizer(input_img):
# this line to show that input is a parameter that requires a gradient
optimizer = optim.LBFGS([input_img.requires_grad_()])
return optimizer | _____no_output_____ | CC-BY-4.0 | sphinx/pytorch-intro/source/neural-transfer.ipynb | oneoffcoder/books |
Transfer | import warnings
from collections import namedtuple
RESULTS = namedtuple('RESULTS', 'run style content')
results = []
def run_style_transfer(cnn, normalization_mean, normalization_std,
content_img, style_img, input_img, num_steps=600,
style_weight=1000000, content_weight=1... | [10/600] Style Loss 5683.9438, Content Loss 28.085737228393555
[20/600] Style Loss 1513.7101, Content Loss 32.92472839355469
[30/600] Style Loss 839.8792, Content Loss 33.72367477416992
[40/600] Style Loss 495.5242, Content Loss 33.512489318847656
[50/600] Style Loss 356.6638, Content Loss 33.42991256713867
[60/600] St... | CC-BY-4.0 | sphinx/pytorch-intro/source/neural-transfer.ipynb | oneoffcoder/books |
Results | x = [r.run for r in results]
y1 = [r.style for r in results]
y2 = [r.content for r in results]
fig, ax1 = plt.subplots(figsize=(10, 5))
color = 'tab:red'
ax1.plot(x, y1, color=color)
ax1.set_ylabel('Style Loss', color=color)
ax1.tick_params(axis='y', labelcolor=color)
color = 'tab:blue'
ax2 = ax1.twinx()
ax2.plot(x,... | _____no_output_____ | CC-BY-4.0 | sphinx/pytorch-intro/source/neural-transfer.ipynb | oneoffcoder/books |
Visualize | plt.figure()
imshow(output, title='Output Image')
# sphinx_gallery_thumbnail_number = 4
plt.ioff()
plt.show() | _____no_output_____ | CC-BY-4.0 | sphinx/pytorch-intro/source/neural-transfer.ipynb | oneoffcoder/books |
Lab: Working with a real world data-set using SQL and Python IntroductionThis notebook shows how to work with a real world dataset using SQL and Python. In this lab you will:1. Understand the dataset for Chicago Public School level performance 1. Store the dataset in an Db2 database on IBM Cloud instance1. Retrieve m... | %load_ext sql
# Enter the connection string for your Db2 on Cloud database instance below
# %sql ibm_db_sa://my-username:my-password@my-hostname:my-port/my-db-name
%sql ibm_db_sa:// | _____no_output_____ | MIT | lab work/Lab5--Practice Querying real world datasets.ipynb | Mstoned/Database-and-SQL |
Query the database system catalog to retrieve table metadata You can verify that the table creation was successful by retrieving the list of all tables in your schema and checking whether the SCHOOLS table was created | # type in your query to retrieve list of all tables in the database for your db2 schema (username)
#In Db2 the system catalog table called SYSCAT.TABLES contains the table metadata
%sql SELECT * from SYSCAT.TABLES where TABNAME = 'SCHOOLS'
#OR
%sql select TABSCHEMA, TABNAME, CREATE_TIME from SYSCAT.TABLES where TABSC... | _____no_output_____ | MIT | lab work/Lab5--Practice Querying real world datasets.ipynb | Mstoned/Database-and-SQL |
Query the database system catalog to retrieve column metadata The SCHOOLS table contains a large number of columns. How many columns does this table have? | #In Db2 the system catalog table called SYSCAT.COLUMNS contains the column metadata
%sql SELECT COUNT(*) FROM SYSCAT.COLUMNS WHERE TABNAME = 'SCHOOLS'
#Correct answer: 78 | _____no_output_____ | MIT | lab work/Lab5--Practice Querying real world datasets.ipynb | Mstoned/Database-and-SQL |
Now retrieve the the list of columns in SCHOOLS table and their column type (datatype) and length. | %sql SELECT COLNAME, TYPENAME, LENGTH FROM SYSCAT.COLUMNS WHERE TABNAME = 'SCHOOLS'
#OR
%sql SELECT DISTINCT(NAME), COLTYPE, LENGTH FROM SYSIBM.SYSCOLUMNS WHERE TABNAME = 'SCHOOLS' | _____no_output_____ | MIT | lab work/Lab5--Practice Querying real world datasets.ipynb | Mstoned/Database-and-SQL |
Questions1. Is the column name for the "SCHOOL ID" attribute in upper or mixed case?1. What is the name of "Community Area Name" column in your table? Does it have spaces?1. Are there any columns in whose names the spaces and paranthesis (round brackets) have been replaced by the underscore character "_"? Problems Pr... | %sql select count(*) from SCHOOLS where "Elementary, Middle, or High School" = 'ES'
#Correct answer: 462 | _____no_output_____ | MIT | lab work/Lab5--Practice Querying real world datasets.ipynb | Mstoned/Database-and-SQL |
Problem 2 What is the highest Safety Score? | %sql SELECT MAX("Safety_Score") AS MAX_SAFETY FROM SCHOOLS
#Correct answer: 99 | _____no_output_____ | MIT | lab work/Lab5--Practice Querying real world datasets.ipynb | Mstoned/Database-and-SQL |
Problem 3 Which schools have highest Safety Score? | %sql SELECT NAME_OF_SCHOOL FROM SCHOOLS WHERE "Safety_Score" = 99
#OR
%sql SELECT NAME_OF_SCHOOL FROM SCHOOLS WHERE "Safety_Score" = (SELECT MAX("Safety_Score") FROM SCHOOLS) | _____no_output_____ | MIT | lab work/Lab5--Practice Querying real world datasets.ipynb | Mstoned/Database-and-SQL |
Problem 4 What are the top 10 schools with the highest "Average Student Attendance"? | %sql SELECT NAME_OF_SCHOOL, Average_Student_Attendance FROM SCHOOLS ORDER BY Average_Student_Attendance DESC LIMIT 10 | _____no_output_____ | MIT | lab work/Lab5--Practice Querying real world datasets.ipynb | Mstoned/Database-and-SQL |
Problem 5 Retrieve the list of 5 Schools with the lowest Average Student Attendance sorted in ascending order based on attendance | %sql SELECT NAME_OF_SCHOOL, Average_Student_Attendance FROM SCHOOLS ORDER BY Average_Student_Attendance LIMIT 5 | _____no_output_____ | MIT | lab work/Lab5--Practice Querying real world datasets.ipynb | Mstoned/Database-and-SQL |
Problem 6 Now remove the '%' sign from the above result set for Average Student Attendance column | %sql SELECT NAME_OF_SCHOOL, REPLACE(Average_Student_Attendance, '%', '') FROM SCHOOLS ORDER BY Average_Student_Attendance LIMIT 5 | _____no_output_____ | MIT | lab work/Lab5--Practice Querying real world datasets.ipynb | Mstoned/Database-and-SQL |
Problem 7 Which Schools have Average Student Attendance lower than 70%? | %sql SELECT NAME_OF_SCHOOL, Average_Student_Attendance FROM SCHOOLS WHERE CAST(REPLACE(Average_Student_Attendance, '%', '') AS DOUBLE) < 70
#OR
%sql SELECT NAME_OF_SCHOOL, Average_Student_Attendance FROM SCHOOLS WHERE DECIMAL(REPLACE(Average_Student_Attendance, '%', '')) < 70 ORDER BY Average_Student_Attendance | _____no_output_____ | MIT | lab work/Lab5--Practice Querying real world datasets.ipynb | Mstoned/Database-and-SQL |
Problem 8 Get the total College Enrollment for each Community Area | %sql SELECT COMMUNITY_AREA_NAME, SUM(COLLEGE_ENROLLMENT) AS TOTAL_ENROLLMENT FROM SCHOOLS GROUP BY COMMUNITY_AREA_NAME | _____no_output_____ | MIT | lab work/Lab5--Practice Querying real world datasets.ipynb | Mstoned/Database-and-SQL |
Problem 9 Get the 5 Community Areas with the least total College Enrollment sorted in ascending order | %sql SELECT COMMUNITY_AREA_NAME, SUM(COLLEGE_ENROLLMENT) AS TOTAL_ENROLLMENT FROM SCHOOLS GROUP BY COMMUNITY_AREA_NAME ORDER BY TOTAL_ENROLLMENT LIMIT 5 | _____no_output_____ | MIT | lab work/Lab5--Practice Querying real world datasets.ipynb | Mstoned/Database-and-SQL |
검색wihle loop 를 이용한 선형 검색 | from typing import Any,List
def linear_search_while(lst:List, value:Any) -> int:
i = 0
while i != len(lst) and lst[i] != value:
i += 1
if i == len(lst):
return -1
else:
return 1
l = [1,2,3,4,5,6,7,8,9]
linear_search_while(l,9)
def linear_search_for(lst:List, value:Any) -> int:
... | _____no_output_____ | Apache-2.0 | python/.ipynb_checkpoints/0107_search_sort-checkpoint.ipynb | gilwoong-kang/education.cloudsecurity |
이진 검색반절씩 줄여나가며 탐색하는 방법 | def binary_search(lst:list,value:Any) -> int:
i = 0
j = len(lst)-1
while i != j+1:
m = (i+j)//2
if lst[m]<v:
i = m+1
else:
j=m-1
if 0<= i< len(lst) and lst[i]==i:
return i
else :
return -1
if __name__ == '_... | _____no_output_____ | Apache-2.0 | python/.ipynb_checkpoints/0107_search_sort-checkpoint.ipynb | gilwoong-kang/education.cloudsecurity |
Selection sort - 선택정렬정렬되지 않은 부분 전체를 순회하며 가장 작은 값을 찾아 정렬된 부분 우측에 위치시킨다. 이것을 모든 값이 정렬될 때까지 반복한다. n길이의 선형 자료형을 n번 반복하게 되므로 n^2 | def selection_sort(l:list):
for i in range(len(l)):
idx = l.index(min(l[i:]),i)
dummy = l[i]
l[i] = l[idx]
l[idx] = dummy
return l
l = [7,16,3,25,2,6,1,7,3]
print(selection_sort(l)) | [1, 2, 3, 3, 6, 7, 7, 16, 25]
| Apache-2.0 | python/.ipynb_checkpoints/0107_search_sort-checkpoint.ipynb | gilwoong-kang/education.cloudsecurity |
Insertion sort - 삽입정렬전체를 순회하며 현재 값이 정렬된 부분에서 올바른 위치에 삽입하는 방식. | # 기 정렬된 영역에 L[:b+1] 내 올바른 위치에 L[b]를 삽입
def insert(L: list, b: int) -> None:
i = b
while i != 0 and L[i - 1] >= L[b]:
i = i - 1
value = L[b]
del L[b]
L.insert(i, value)
def insertion_sort(L: list) -> None:
i = 0
while i != len(L):
insert(L, i)
i = i + 1
L = [ 3... | [3, 4, 6, -1, 2, 5]
[-1, 2, 3, 4, 5, 6]
| Apache-2.0 | python/.ipynb_checkpoints/0107_search_sort-checkpoint.ipynb | gilwoong-kang/education.cloudsecurity |
Merge sort - 병합정렬 | # 2개의 리스트를 하나의 정렬된 리스트로 반환
def merge(L1: list, L2: list) -> list:
newL = []
i1 = 0
i2 = 0
# [ 1, 1, 2, 3, 4, 5, 6, 7 ]
# [ 1, 3, 4, 6 ] [ 1, 2, 5, 7 ]
# i1
# i2
while i1 != len(L1) and i2 != len(L2):
if L1[i1] <= L2[i2]:... | 10 0.0 0.0 0.0 0.0
1000 16.5 37.0 4.1 0.1
2000 54.9 141.1 12.2 0.2
3000 130.2 321.6 15.0 0.4
4000 217.9 592.7 20.7 0.5
5000 357.6 871.0 26.0 0.7
10000 1450.2 3544.8 55.7 1.5
| Apache-2.0 | python/.ipynb_checkpoints/0107_search_sort-checkpoint.ipynb | gilwoong-kang/education.cloudsecurity |
객체지향 프로그래밍```isinstance(object,class)``` 해당 객체가 클래스에 해당하는지 아닌지를 반환. | from typing import List,Any
class Book:
def num_authors(self) -> int:
return len(self.authors)
def __init__(self,title:str,authors:List[str],publisher:str,isbn:str,price:float) : # 생성자.
self.title = title
self.authors = authors[:] # [:] 를 적지 않고 직접 넘겨주면 참조형식이기 때문에 외부... | aaa
bbb
ccc
3
Title : My book
Authors : ['aaa', 'bbb', 'ccc']
True
| Apache-2.0 | python/.ipynb_checkpoints/0107_search_sort-checkpoint.ipynb | gilwoong-kang/education.cloudsecurity |
레퍼런스 타입을 넘겨줄때 값을 참조하는 형식이 아닌 값을 직접 받는 형식으로 취하게 해야 한다. 캡슐화 : 데이터와 그 데이터를 사용하는 코드를 한곳에 넣고 정확히 어떻게 동작하는ㄴ지 상세한 내용은 숨기는 것 다형성 : 하나 이상의 형태를 갖는 것. 어떤 변수를 포함하는 표현식이 변수가 참조하는 객체의 타입에 따라 서로 다른 일을 하는 것 상속 : 새로운 클래스는 부모 클래스(object 클래스 또는 사용자 정의 속성을 상속) | class Member:
def __init__(self,name:str,address:str,email:str):
self.name = name
self.address = address
self.email = email
class Faculty(Member):
def __init__(self,name:str,address:str,email:str,faculty_num:str):
super().__init__(name,address,email)
self.faculty... | (AMMONIA, ((N, 0.257, -0.363, 0.2, (H, 0.257, 0.727, 0.2, (H, 0.771, -0.727, 1.09, (H, 0.771, -0.727, -0.69))
| Apache-2.0 | python/.ipynb_checkpoints/0107_search_sort-checkpoint.ipynb | gilwoong-kang/education.cloudsecurity |
Steps to generate a visualization of the data: - Import the SQL database into Pandas. | import pandas as pd
from sqlalchemy import create_engine
from config import ppwd
import matplotlib.pyplot as plt
import scipy.stats as sts | _____no_output_____ | ADSL | EmployeeSQL/EmployeePy.ipynb | luiserojas74/sql-challenge |
- Configure connection to postgres | username='postgres'
password=ppwd
port=5432
database='Employee_DB'
connection_str = f"postgresql://{username}:{password}@localhost:{port}/{database}"
engine = create_engine(connection_str)
connection = engine.connect() | _____no_output_____ | ADSL | EmployeeSQL/EmployeePy.ipynb | luiserojas74/sql-challenge |
- Read tables from postgres | titles_df = pd.read_sql("SELECT * FROM titles", connection)
titles_df
salaries_df = pd.read_sql("SELECT * FROM salaries", connection)
salaries_df
employees_df = pd.read_sql("SELECT * FROM employees", connection)
employees_df | _____no_output_____ | ADSL | EmployeeSQL/EmployeePy.ipynb | luiserojas74/sql-challenge |
- Create a histogram to visualize the most common salary ranges for employees. | salaries=salaries_df['salary']
plt.hist(salaries)
plt.title('Most common salary ranges for employees')
plt.xlabel('Salaries')
plt.ylabel('Counts')
plt.show() | _____no_output_____ | ADSL | EmployeeSQL/EmployeePy.ipynb | luiserojas74/sql-challenge |
- Join three tables | merged_df = pd.merge(employees_df, salaries_df, on="emp_no")
merged_df = pd.merge(merged_df, titles_df, left_on="emp_title_id", right_on="title_id")
merged_df | _____no_output_____ | ADSL | EmployeeSQL/EmployeePy.ipynb | luiserojas74/sql-challenge |
- Determine average salary by title | avg_salary_df = merged_df.groupby("title").mean()['salary'].round(1).reset_index()
avg_salary_df | _____no_output_____ | ADSL | EmployeeSQL/EmployeePy.ipynb | luiserojas74/sql-challenge |
- Create a bar chart of average salary by title. | y_axis = avg_salary_df['salary']
x_axis = avg_salary_df['title']
plt.xticks(rotation=60)
plt.title('Average salary by title')
plt.xlabel('Title')
plt.ylabel('Avg. Salary')
my_plt=plt.bar(x_axis, y_axis, color='g', alpha=0.5, align="center") | _____no_output_____ | ADSL | EmployeeSQL/EmployeePy.ipynb | luiserojas74/sql-challenge |
Access DB2 on Cloud using PythonEstimated time needed: **15** minutes ObjectivesAfter completing this lab you will be able to:- Create a table- Insert data into the table- Query data from the table- Retrieve the result set into a pandas dataframe- Close the database connection **Notice:** Please follow t... | import ibm_db | _____no_output_____ | MIT | IBM Professional Certificates/Databases and SQL for Data Science with Python/3-1-2-Querying.ipynb | Bezhuang/LearnCS |
When the command above completes, the `ibm_db` library is loaded in your notebook. Task 2: Identify the database connection credentialsConnecting to dashDB or DB2 database requires the following information:- Driver Name- Database name - Host DNS name or IP address - Host port- Connection protocol- User ID... | #Replace the placeholder values with the actuals for your Db2 Service Credentials
dsn_driver = "{IBM DB2 ODBC DRIVER}"
dsn_database = "database" # e.g. "BLUDB"
dsn_hostname = "hostname" # e.g.: "dashdb-txn-sbox-yp-dal09-04.services.dal.bluemix.net"
dsn_port = "port" # e.g. "5000... | _____no_output_____ | MIT | IBM Professional Certificates/Databases and SQL for Data Science with Python/3-1-2-Querying.ipynb | Bezhuang/LearnCS |
Task 3: Create the database connectionIbm_db API uses the IBM Data Server Driver for ODBC and CLI APIs to connect to IBM DB2 and Informix.Create the database connection | #Create database connection
#DO NOT MODIFY THIS CELL. Just RUN it with Shift + Enter
dsn = (
"DRIVER={0};"
"DATABASE={1};"
"HOSTNAME={2};"
"PORT={3};"
"PROTOCOL={4};"
"UID={5};"
"PWD={6};").format(dsn_driver, dsn_database, dsn_hostname, dsn_port, dsn_protocol, dsn_uid, dsn_pwd)
try:
con... | _____no_output_____ | MIT | IBM Professional Certificates/Databases and SQL for Data Science with Python/3-1-2-Querying.ipynb | Bezhuang/LearnCS |
Task 4: Create a table in the databaseIn this step we will create a table in the database with following details: | #Lets first drop the table INSTRUCTOR in case it exists from a previous attempt
dropQuery = "drop table INSTRUCTOR"
#Now execute the drop statment
dropStmt = ibm_db.exec_immediate(conn, dropQuery) | _____no_output_____ | MIT | IBM Professional Certificates/Databases and SQL for Data Science with Python/3-1-2-Querying.ipynb | Bezhuang/LearnCS |
Dont worry if you get this error:If you see an exception/error similar to the following, indicating that INSTRUCTOR is an undefined name, that's okay. It just implies that the INSTRUCTOR table does not exist in the table - which would be the case if you had not created it previously.Exception: [IBM][CLI Driver][DB2/LI... | #Construct the Create Table DDL statement
createQuery = "create table INSTRUCTOR(ID INTEGER PRIMARY KEY NOT NULL, FNAME VARCHAR(20), LNAME VARCHAR(20), CITY VARCHAR(20), CCODE CHAR(2))"
#Execute the statement
createStmt = ibm_db.exec_immediate(conn,createQuery) | _____no_output_____ | MIT | IBM Professional Certificates/Databases and SQL for Data Science with Python/3-1-2-Querying.ipynb | Bezhuang/LearnCS |
Click here for the solution```pythoncreateQuery = "create table INSTRUCTOR(ID INTEGER PRIMARY KEY NOT NULL, FNAME VARCHAR(20), LNAME VARCHAR(20), CITY VARCHAR(20), CCODE CHAR(2))"createStmt = ibm_db.exec_immediate(conn,createQuery)``` Task 5: Insert data into the tableIn this step we will insert some rows of data into... | #Construct the query
insertQuery = "insert into INSTRUCTOR values (1, 'Rav', 'Ahuja', 'TORONTO', 'CA')"
#execute the insert statement
insertStmt = ibm_db.exec_immediate(conn, insertQuery) | _____no_output_____ | MIT | IBM Professional Certificates/Databases and SQL for Data Science with Python/3-1-2-Querying.ipynb | Bezhuang/LearnCS |
Click here for the solution```pythoninsertQuery = "insert into INSTRUCTOR values (1, 'Rav', 'Ahuja', 'TORONTO', 'CA')"insertStmt = ibm_db.exec_immediate(conn, insertQuery)``` Now use a single query to insert the remaining two rows of data | #Inerts the remaining two rows of data
insertQuery2 = "insert into INSTRUCTOR values (2, 'Raul', 'Chong', 'Markham', 'CA'), (3, 'Hima', 'Vasudevan', 'Chicago', 'US')"
#execute the statement
insertStmt2 = ibm_db.exec_immediate(conn, insertQuery2) | _____no_output_____ | MIT | IBM Professional Certificates/Databases and SQL for Data Science with Python/3-1-2-Querying.ipynb | Bezhuang/LearnCS |
Click here for the solution```pythoninsertQuery2 = "insert into INSTRUCTOR values (2, 'Raul', 'Chong', 'Markham', 'CA'), (3, 'Hima', 'Vasudevan', 'Chicago', 'US')"insertStmt2 = ibm_db.exec_immediate(conn, insertQuery2)``` Task 6: Query data in the tableIn this step we will retrieve data we inserted into the INSTRUCTOR... | #Construct the query that retrieves all rows from the INSTRUCTOR table
selectQuery = "select * from INSTRUCTOR"
#Execute the statement
selectStmt = ibm_db.exec_immediate(conn, selectQuery)
#Fetch the Dictionary (for the first row only)
ibm_db.fetch_both(selectStmt) | _____no_output_____ | MIT | IBM Professional Certificates/Databases and SQL for Data Science with Python/3-1-2-Querying.ipynb | Bezhuang/LearnCS |
Click here for the solution```pythonConstruct the query that retrieves all rows from the INSTRUCTOR tableselectQuery = "select * from INSTRUCTOR"Execute the statementselectStmt = ibm_db.exec_immediate(conn, selectQuery)Fetch the Dictionary (for the first row only)ibm_db.fetch_both(selectStmt)``` | #Fetch the rest of the rows and print the ID and FNAME for those rows
while ibm_db.fetch_row(selectStmt) != False:
print (" ID:", ibm_db.result(selectStmt, 0), " FNAME:", ibm_db.result(selectStmt, "FNAME")) | _____no_output_____ | MIT | IBM Professional Certificates/Databases and SQL for Data Science with Python/3-1-2-Querying.ipynb | Bezhuang/LearnCS |
Click here for the solution```pythonFetch the rest of the rows and print the ID and FNAME for those rowswhile ibm_db.fetch_row(selectStmt) != False: print (" ID:", ibm_db.result(selectStmt, 0), " FNAME:", ibm_db.result(selectStmt, "FNAME"))``` Bonus: now write and execute an update statement that changes the Rav's... | updateQuery = "update INSTRUCTOR set CITY='MOOSETOWN' where FNAME='Rav'"
updateStmt = ibm_db.exec_immediate(conn, updateQuery)) | _____no_output_____ | MIT | IBM Professional Certificates/Databases and SQL for Data Science with Python/3-1-2-Querying.ipynb | Bezhuang/LearnCS |
Click here for the solution```pythonupdateQuery = "update INSTRUCTOR set CITY='MOOSETOWN' where FNAME='Rav'"updateStmt = ibm_db.exec_immediate(conn, updateQuery))``` Task 7: Retrieve data into PandasIn this step we will retrieve the contents of the INSTRUCTOR table into a Pandas dataframe | import pandas
import ibm_db_dbi
#connection for pandas
pconn = ibm_db_dbi.Connection(conn)
#query statement to retrieve all rows in INSTRUCTOR table
selectQuery = "select * from INSTRUCTOR"
#retrieve the query results into a pandas dataframe
pdf = pandas.read_sql(selectQuery, pconn)
#print just the LNAME for first ro... | _____no_output_____ | MIT | IBM Professional Certificates/Databases and SQL for Data Science with Python/3-1-2-Querying.ipynb | Bezhuang/LearnCS |
Once the data is in a Pandas dataframe, you can do the typical pandas operations on it. For example you can use the shape method to see how many rows and columns are in the dataframe | pdf.shape | _____no_output_____ | MIT | IBM Professional Certificates/Databases and SQL for Data Science with Python/3-1-2-Querying.ipynb | Bezhuang/LearnCS |
Task 8: Close the ConnectionWe free all resources by closing the connection. Remember that it is always important to close connections so that we can avoid unused connections taking up resources. | ibm_db.close(conn) | _____no_output_____ | MIT | IBM Professional Certificates/Databases and SQL for Data Science with Python/3-1-2-Querying.ipynb | Bezhuang/LearnCS |
Building a Machine Translation System with Forte OverviewThis tutorial will walk you through the steps to build a machine translation system with Forte. Forte allows users to breaks down complex problems into composable pipelines and enables inter-operations across tasks through a unified data format. With Forte, it... | !pip install forte==0.2.0 forte.nltk transformers==4.16.2 torch==1.7.0 requests sentencepiece | _____no_output_____ | Apache-2.0 | docs/notebook_tutorial/tutorial_MT_with_forte.ipynb | bhaskar2443053/forte |
Start with the Reader Overview* **How to read data from source** * **How to create a simple pipeline** * How to maintain and store the input data* How to process data in pipeline* How to handle new practical requestsIn this section, you will learn* What is a reader and why we need it* How to compose a simple pi... | from forte import Pipeline
from forte.data.readers import TerminalReader
pipeline: Pipeline = Pipeline() | _____no_output_____ | Apache-2.0 | docs/notebook_tutorial/tutorial_MT_with_forte.ipynb | bhaskar2443053/forte |
All pipelines need a reader to read and parse input data. To make our pipeline read queries from the user’s command-line terminal, use the `TerminalReader` class provided by Forte. `TerminalReader` transforms the user’s query into a DataPack object, which is a unified data format for NLP that makes it easy to connect d... | pipeline.set_reader(TerminalReader()) | _____no_output_____ | Apache-2.0 | docs/notebook_tutorial/tutorial_MT_with_forte.ipynb | bhaskar2443053/forte |
To run the pipeline consisting of the single `TerminalReader`, call `process_dataset` which will return an iterator of DataPack objects. The second line in the following code snippet retrieves the first user query from the TerminalReader. | pipeline.initialize()
datapack = next(pipeline.process_dataset())
print(datapack.text) | _____no_output_____ | Apache-2.0 | docs/notebook_tutorial/tutorial_MT_with_forte.ipynb | bhaskar2443053/forte |
DataPack Overview* **How to read data from source** * How to create a simple pipeline * **How to maintain and store the input data*** How to process data in pipeline* How to handle new practical requestsIn this section, you will learn* What is a DataPack object and why we need itForte helps demystify data lineag... | from fortex.nltk.nltk_processors import NLTKSentenceSegmenter
pipeline.add(NLTKSentenceSegmenter()) | _____no_output_____ | Apache-2.0 | docs/notebook_tutorial/tutorial_MT_with_forte.ipynb | bhaskar2443053/forte |
When we run the pipeline, the `NLTKSentenceSegmenter` processor will split the user query into sentences and store them back to the DataPack created by TerminalReader. The code snippet below shows how to get all the sentences from the first query.
for sent in next(pipeline.process_dataset()).get(Sentence):
print(sent.text) | _____no_output_____ | Apache-2.0 | docs/notebook_tutorial/tutorial_MT_with_forte.ipynb | bhaskar2443053/forte |
Ontology Overview* How to read data from source* **How to process data in pipeline** * How to perform sentence segmentation * **How to annotate and query the data** * How to translate the input text with a pre-trained model * How to manage multiple data objects* How to handle new practical requestsIn this ... | from dataclasses import dataclass
from forte.data.ontology.top import Annotation
from typing import Optional
@dataclass
class Article(Annotation):
language: Optional[str]
def __init__(self, pack, begin: int, end: int):
super().__init__(pack, begin, end)
self.language: Optional[str] = None | _____no_output_____ | Apache-2.0 | docs/notebook_tutorial/tutorial_MT_with_forte.ipynb | bhaskar2443053/forte |
Below is a simple example showing how we can query sentences through the new ontology we just create: | from forte.data import DataPack
sentences = [
"Do you want to get better at making delicious BBQ?",
"You will have the opportunity, put this on your calendar now.",
"Thursday, September 22nd join World Class BBQ Champion, Tony Balay from Lonestar Smoke Rangers."
]
datapack: DataPack = DataPack()
# Add sen... | _____no_output_____ | Apache-2.0 | docs/notebook_tutorial/tutorial_MT_with_forte.ipynb | bhaskar2443053/forte |
In our previous example, we have the following ontologies inheritance. Sentence and Article both inherit from Annotation which is used to represent text data. In Article, we have `langauge` field to represent the text language.:
"""
Translate the input text and output to a file.
"""
def initi... | _____no_output_____ | Apache-2.0 | docs/notebook_tutorial/tutorial_MT_with_forte.ipynb | bhaskar2443053/forte |
* Initialization of needed components: * Users need to consider initializing all needed NLP components for the inference task such as tokenizer and model. * Users also need to specify all configuration in `configs`, a dictionary-like object that specifies configurations of all components such as model name. * MT ... | input_string: str = ' '.join(sentences)
pipeline: Pipeline = Pipeline[DataPack]()
pipeline.set_reader(StringReader())
pipeline.add(NLTKSentenceSegmenter())
pipeline.add(MachineTranslationProcessor())
pipeline.initialize()
for datapack in pipeline.process_dataset([input_string]):
for article in datapack.get(Article)... | _____no_output_____ | Apache-2.0 | docs/notebook_tutorial/tutorial_MT_with_forte.ipynb | bhaskar2443053/forte |
Ontology in DataPackHere we provide an illustration so that users can better understand the internal storage of DataPack. As we can see, text data, sentence and articles, are stored as span in `Annotations`. Their text data can be easily and efficiently retrieved by their spans.:
"""
Translate the input text and output to a file.
"""
def initialize(self, resources, configs):
super().in... | _____no_output_____ | Apache-2.0 | docs/notebook_tutorial/tutorial_MT_with_forte.ipynb | bhaskar2443053/forte |
Then `MachineTranslationMPProcessor` writes the output sentence into a target DataPack. 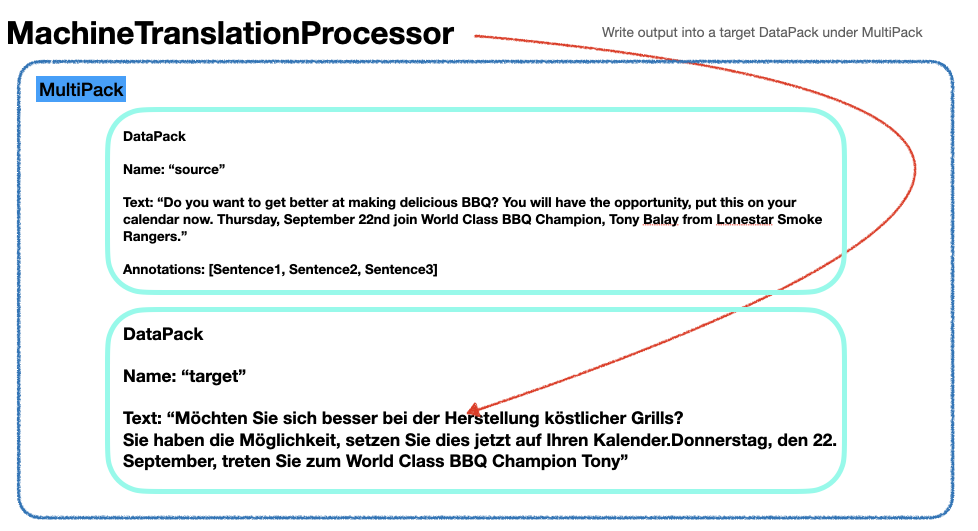 Now let's try to create a new pipeline that utilizes `MultiPack` to manage text in different languages. | nlp: Pipeline = Pipeline[DataPack]()
nlp.set_reader(StringReader())
nlp.add(NLTKSentenceSegmenter())
nlp.add(MultiPackBoxer(), config={"pack_name": "source"})
nlp.add(MachineTranslationMPProcessor(), config={
"pretrained_model": "t5-small"
})
nlp.initialize()
for multipack in nlp.process_dataset([input_string]):
... | _____no_output_____ | Apache-2.0 | docs/notebook_tutorial/tutorial_MT_with_forte.ipynb | bhaskar2443053/forte |
Ontology in MultiPackFor comparison, here is an illustration of the internal storage of MultiPack. We can see that MultiPack wraps one source DataPack and one target DataPack. Article spans are based on two separate DataPack text.:
def initialize(self, resources, configs):
super().initialize(resources, configs)
self._parser = ForteHTMLParser()
def _process(self, input_pack: Mu... | _____no_output_____ | Apache-2.0 | docs/notebook_tutorial/tutorial_MT_with_forte.ipynb | bhaskar2443053/forte |
Now we are able to create a translation management system by inserting the two processors introduced above into our previous machine translation pipeline. | # Pipeline with HTML handling
pipeline: Pipeline = Pipeline[DataPack]()
pipeline.set_reader(StringReader())
pipeline.add(MultiPackBoxer(), config={"pack_name": "raw"})
pipeline.add(HTMLTagCleaner())
pipeline.add(
NLTKSentenceSegmenter(),
selector=NameMatchSelector(),
selector_config={"select_name": "source"... | _____no_output_____ | Apache-2.0 | docs/notebook_tutorial/tutorial_MT_with_forte.ipynb | bhaskar2443053/forte |
SelectorIn the code snippet above, we utilize a `NameMatchSelector` to select one specific DataPack from the MultiPack based on its reference name `select_name`. This allows `NLTKSentenceSegmenter` to process only the specified DataPack. Replace our MT model with online translation API Overview* How to read data from ... | # You can get your own API key by following the instructions in https://docs.microsoft.com/en-us/azure/cognitive-services/translator/
api_key = input("Enter your API key here:")
import requests
import uuid
class OnlineMachineTranslationMPProcessor(MultiPackProcessor):
"""
Translate the input text and output to... | _____no_output_____ | Apache-2.0 | docs/notebook_tutorial/tutorial_MT_with_forte.ipynb | bhaskar2443053/forte |
Save the whole pipeline with save() Overview* How to read data from source* How to process data in pipeline* **How to handle new practical requests** * How to handle structures like HTML data * How to replace the translation model with remote translation services * **How to save and load the pipeline**In thi... | import os
save_path: str = os.path.join(os.path.dirname(os.path.abspath('')), "pipeline.yml")
nlp.save(save_path)
with open(save_path, 'r') as f:
print(f.read()) | _____no_output_____ | Apache-2.0 | docs/notebook_tutorial/tutorial_MT_with_forte.ipynb | bhaskar2443053/forte |
Now that the pipeline is saved, we can try to re-load the pipeline to see if it still functions as expect. | new_nlp: Pipeline = Pipeline()
new_nlp.init_from_config_path(save_path)
new_nlp.initialize()
for multipack in new_nlp.process_dataset([input_string]):
print("Source Text: " + multipack.get_pack("source").text)
print("\nTarget Text: " + multipack.get_pack("target").text) | _____no_output_____ | Apache-2.0 | docs/notebook_tutorial/tutorial_MT_with_forte.ipynb | bhaskar2443053/forte |
Let's get some JSON data from the web - both a point layer and a polygon GeoJson dataset with some population data. | states = geopandas.read_file(
'https://rawcdn.githack.com/PublicaMundi/MappingAPI/master/data/geojson/us-states.json',
driver='GeoJSON'
)
cities = geopandas.read_file(
'https://d2ad6b4ur7yvpq.cloudfront.net/naturalearth-3.3.0/ne_50m_populated_places_simple.geojson',
driver='GeoJSON'
) | _____no_output_____ | MIT | examples/plugin-Search.ipynb | artnikitin/folium |
And take a look at what our data looks like: | states.describe() | _____no_output_____ | MIT | examples/plugin-Search.ipynb | artnikitin/folium |
Look how far the minimum and maximum values for the density are from the top and bottom quartile breakpoints! We have some outliers in our data that are well outside the meat of most of the distribution. Let's look into this to find the culprits within the sample. | states_sorted = states.sort_values(by='density', ascending=False)
states_sorted.head(5).append(states_sorted.tail(5))[['name','density']] | _____no_output_____ | MIT | examples/plugin-Search.ipynb | artnikitin/folium |
Looks like Washington D.C. and Alaska were the culprits on each end of the range. Washington was more dense than the next most dense state, New Jersey, than the least dense state, Alaska was from Wyoming, however. Washington D.C. has a has a relatively small land area for the amount of people that live there, so it mak... | min, max = states['density'].quantile([0.05,0.95]).apply(lambda x: round(x, 2))
mean = round(states['density'].mean(),2)
print(f"Min: {min}", f"Max: {max}", f"Mean: {mean}", sep="\n\n") | Min: 8.54
Max: 1040.2
Mean: 402.5
| MIT | examples/plugin-Search.ipynb | artnikitin/folium |
This looks better. Our min and max values for the colorscale are much closer to the mean value now. Let's run with these values, and make a colorscale. I'm just going to use a sequential light-to-dark color palette from the [ColorBrewer](http://colorbrewer2.org/type=sequential&scheme=Purples&n=5). | colormap = branca.colormap.LinearColormap(
colors=['#f2f0f7','#cbc9e2','#9e9ac8','#756bb1','#54278f'],
index=states['density'].quantile([0.2,0.4,0.6,0.8]),
vmin=min,
vmax=max
)
colormap.caption="Population Density in the United States"
colormap
| _____no_output_____ | MIT | examples/plugin-Search.ipynb | artnikitin/folium |
Let's narrow down these cities to United states cities, by using GeoPandas' spatial join functionality between two GeoDataFrame objects, using the Point 'within' Polygon functionality. | us_cities = geopandas.sjoin(cities, states, how='inner', op='within')
pop_ranked_cities = us_cities.sort_values(
by='pop_max',
ascending=False
)[
[
'nameascii',
'pop_max',
'geometry'
]
].iloc[:20] | _____no_output_____ | MIT | examples/plugin-Search.ipynb | artnikitin/folium |
Ok, now we have a new GeoDataFrame with our top 20 populated cities. Let's see the top 5. | pop_ranked_cities.head(5) | _____no_output_____ | MIT | examples/plugin-Search.ipynb | artnikitin/folium |
Alright, let's build a map! | m = folium.Map(location=[38,-97], zoom_start=4)
style_function = lambda x: {
'fillColor': colormap(x['properties']['density']),
'color': 'black',
'weight':2,
'fillOpacity':0.5
}
stategeo = folium.GeoJson(
states,
name='US States',
style_function=style_function,
tooltip=folium.GeoJsonT... | _____no_output_____ | MIT | examples/plugin-Search.ipynb | artnikitin/folium |
NumPy Tutorial: Data analysis with Python[Source](https://www.dataquest.io/blog/numpy-tutorial-python/)NumPy is a commonly used Python data analysis package. By using NumPy, you can speed up your workflow, and interface with other packages in the Python ecosystem, like scikit-learn, that use NumPy under the hood. NumP... | import csv
with open("winequality-red.csv", 'r') as f:
wines = list(csv.reader(f, delimiter=";"))
# print(wines[:3])
headers = wines[0]
wines_only = wines[1:]
# print the headers
print(headers)
# print the 1st row of data
print(wines_only[0])
# print the 1st three rows of data
print(wines_only[:3]) | [['7.4', '0.7', '0', '1.9', '0.076', '11', '34', '0.9978', '3.51', '0.56', '9.4', '5'], ['7.8', '0.88', '0', '2.6', '0.098', '25', '67', '0.9968', '3.2', '0.68', '9.8', '5'], ['7.8', '0.76', '0.04', '2.3', '0.092', '15', '54', '0.997', '3.26', '0.65', '9.8', '5']]
| MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
The data has been read into a list of lists. Each inner list is a row from the ssv file. As you may have noticed, each item in the entire list of lists is represented as a string, which will make it harder to do computations.As you can see from the table above, we've read in three rows, the first of which contains colu... | # calculate average wine quality with a loop
qualities = []
for row in wines[1:]:
qualities.append(float(row[-1]))
sum(qualities) / len(wines[1:])
# calculate average wine quality with a list comprehension
qualities = [float(row[-1]) for row in wines[1:]]
sum(qualities) / len(wines[1:]) | _____no_output_____ | MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
Although we were able to do the calculation we wanted, the code is fairly complex, and it won't be fun to have to do something similar every time we want to compute a quantity. Luckily, we can use NumPy to make it easier to work with our data. Numpy 2-Dimensional ArraysWith NumPy, we work with multidimensional arrays.... | import numpy as np
np.set_printoptions(precision=2) # set the output print precision for readability
# create the numpy array skipping the headers
wines = np.array(wines[1:], dtype=np.float)
# If we display wines, we'll now get a NumPy array:
print(type(wines), wines)
# We can check the number of rows and columns in o... | _____no_output_____ | MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
Alternative NumPy Array Creation MethodsThere are a variety of methods that you can use to create NumPy arrays. It's useful to create an array with all zero elements in cases when you need an array of fixed size, but don't have any values for it yet. To start with, you can create an array where every element is zero. ... | empty_array = np.zeros((3, 4))
empty_array | _____no_output_____ | MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
Creating arrays full of random numbers can be useful when you want to quickly test your code with sample arrays. You can also create an array where each element is a random number using ```numpy.random.rand```. | np.random.rand(2, 3) | _____no_output_____ | MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
Using NumPy To Read In FilesIt's possible to use NumPy to directly read ```csv``` or other files into arrays. We can do this using the ```numpy.genfromtxt``` function. We can use it to read in our initial data on red wines.In the below code, we:* Use the ``` genfromtxt ``` function to read in the ``` winequality-red.c... | wines = np.genfromtxt("winequality-red.csv", delimiter=";", skip_header=1)
wines | _____no_output_____ | MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
Wines will end up looking the same as if we read it into a list then converted it to an array of ```floats```. NumPy will automatically pick a data type for the elements in an array based on their format. Indexing NumPy ArraysWe now know how to create arrays, but unless we can retrieve results from them, there isn't a... | wines[2, 3]
wines[2][3] | _____no_output_____ | MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
Since we're working with a 2-dimensional array in NumPy we specify 2 indexes to retrieve an element. * The first index is the row, or **axis 1**, index* The second index is the column, or **axis 2**, index Any element in wines can be retrieved using 2 indexes. | # rows 1, 2, 3 and column 4
wines[0:3, 3]
# all rows and column 3
wines[:, 2] | _____no_output_____ | MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
Just like with ```list``` slicing, it's possible to omit the 0 to just retrieve all the elements from the beginning up to element 3: | # rows 1, 2, 3 and column 4
wines[:3, 3] | _____no_output_____ | MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
We can select an entire column by specifying that we want all the elements, from the first to the last. We specify this by just using the colon ```:```, with no starting or ending indices. The below code will select the entire fourth column: | # all rows and column 4
wines[:, 3] | _____no_output_____ | MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
We selected an entire column above, but we can also extract an entire row: | # row 4 and all columns
wines[3, :] | _____no_output_____ | MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
If we take our indexing to the extreme, we can select the entire array using two colons to select all the rows and columns in wines. This is a great party trick, but doesn't have a lot of good applications: | wines[:, :] | _____no_output_____ | MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
Assigning Values To NumPy ArraysWe can also use indexing to assign values to certain elements in arrays. We can do this by assigning directly to the indexed value: | # assign the value of 10 to the 2nd row and 6th column
print('Before', wines[1, 4:7])
wines[1, 5] = 10
print('After', wines[1, 4:7]) | Before [ 0.1 25. 67. ]
After [ 0.1 10. 67. ]
| MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
We can do the same for slices. To overwrite an entire column, we can do this: | # Overwrites all the values in the eleventh column with 50.
print('Before', wines[:, 9:12])
wines[:, 10] = 50
print('After', wines[:, 9:12]) | Before [[ 0.56 9.4 5. ]
[ 0.68 9.8 5. ]
[ 0.65 9.8 5. ]
...
[ 0.75 11. 6. ]
[ 0.71 10.2 5. ]
[ 0.66 11. 6. ]]
After [[ 0.56 50. 5. ]
[ 0.68 50. 5. ]
[ 0.65 50. 5. ]
...
[ 0.75 50. 6. ]
[ 0.71 50. 5. ]
[ 0.66 50. 6. ]]
| MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
1-Dimensional NumPy ArraysSo far, we've worked with 2-dimensional arrays, such as wines. However, NumPy is a package for working with multidimensional arrays. One of the most common types of multidimensional arrays is the **1-dimensional array**, or **vector**. As you may have noticed above, when we sliced wines, we r... | third_wine = wines[3,:]
third_wine | _____no_output_____ | MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
We can retrieve individual elements from ```third_wine``` using a single index. | # display the second item in third_wine
third_wine[1] | _____no_output_____ | MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
Most NumPy functions that we've worked with, such as ```numpy.random.rand```, can be used with multidimensional arrays. Here's how we'd use ```numpy.random.rand``` to generate a random vector: | np.random.rand(3) | _____no_output_____ | MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
Previously, when we called ```np.random.rand```, we passed in a shape for a 2-dimensional array, so the result was a 2-dimensional array. This time, we passed in a shape for a single dimensional array. The shape specifies the number of dimensions, and the size of the array in each dimension. A shape of ```(10,10)``` wi... | year_one = [
[500,505,490], # 1st quarter
[810,450,678], # 2nd quarter
[234,897,430], # 3rd quarter
[560,1023,640] # 4th quarter
] | _____no_output_____ | MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
We can retrieve the earnings from January by calling ``` year_one[0][0] ```. If we want the results for a whole quarter, we can call ``` year_one[0] ``` or ``` year_one[1] ```. We now have a 2-dimensional array, or matrix. But what if we now want to add the results from another year? We have to add a third dimension: | earnings = [
[ # year 1
[500,505,490], # year 1, 1st quarter
[810,450,678], # year 1, 2nd quarter
[234,897,430], # year 1, 3rd quarter
[560,1023,640] # year 1, 4th quarter
],
[ # year =2
[600,605,490], # ... | _____no_output_____ | MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
We can retrieve the earnings from January of the first year by calling ``` earnings[0][0][0] ```. We now need three indexes to retrieve a single element. A three-dimensional array in NumPy is much the same. In fact, we can convert earnings to an array and then get the earnings for January of the first year: | earnings = np.array(earnings)
# year 1, 1st quarter, 1st month (January)
earnings[0,0,0]
# year 2, 3rd quarter, 1st month (July)
earnings[1,2,0]
# we can also find the shape of the array
earnings.shape | _____no_output_____ | MIT | lectures/Week 05 - Data Processing and Visualization Part 2/02 - NumPy Data analysis.ipynb | xiangyuzeng/data-focused-python |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.