
markdown stringlengths 0 1.02M | code stringlengths 0 832k | output stringlengths 0 1.02M | license stringlengths 3 36 | path stringlengths 6 265 | repo_name stringlengths 6 127 |
|---|---|---|---|---|---|
Neural Networks in PyMC3 estimated with Variational Inference(c) 2016 by Thomas Wiecki Current trends in Machine LearningThere are currently three big trends in machine learning: **Probabilistic Programming**, **Deep Learning** and "**Big Data**". Inside of PP, a lot of innovation is in making things scale using **Va... | %matplotlib inline
import pymc3 as pm
import theano.tensor as T
import theano
import sklearn
import numpy as np
import matplotlib.pyplot as plt
import seaborn as sns
sns.set_style('white')
from sklearn import datasets
from sklearn.preprocessing import scale
from sklearn.cross_validation import train_test_split
from skl... | _____no_output_____ | BSD-3-Clause | pymc3/bayesian_neural_network_wiecki.ipynb | jackbenn/probabilistic-programming-intro |
Model specificationA neural network is quite simple. The basic unit is a [perceptron](https://en.wikipedia.org/wiki/Perceptron) which is nothing more than [logistic regression](http://pymc-devs.github.io/pymc3/notebooks/posterior_predictive.htmlPrediction). We use many of these in parallel and then stack them up to ge... | # Trick: Turn inputs and outputs into shared variables.
# It's still the same thing, but we can later change the values of the shared variable
# (to switch in the test-data later) and pymc3 will just use the new data.
# Kind-of like a pointer we can redirect.
# For more info, see: http://deeplearning.net/software/th... | _____no_output_____ | BSD-3-Clause | pymc3/bayesian_neural_network_wiecki.ipynb | jackbenn/probabilistic-programming-intro |
That's not so bad. The `Normal` priors help regularize the weights. Usually we would add a constant `b` to the inputs but I omitted it here to keep the code cleaner. Variational Inference: Scaling model complexityWe could now just run a MCMC sampler like [`NUTS`](http://pymc-devs.github.io/pymc3/api.htmlnuts) which wo... | %%time
with neural_network:
# Run ADVI which returns posterior means, standard deviations, and the evidence lower bound (ELBO)
v_params = pm.variational.advi(n=50000) | Average ELBO = -167.9: 100%|██████████| 50000/50000 [00:17<00:00, 2860.61it/s]
Finished [100%]: Average ELBO = -138.57
| BSD-3-Clause | pymc3/bayesian_neural_network_wiecki.ipynb | jackbenn/probabilistic-programming-intro |
< 40 seconds on my older laptop. That's pretty good considering that NUTS is having a really hard time. Further below we make this even faster. To make it really fly, we probably want to run the Neural Network on the GPU.As samples are more convenient to work with, we can very quickly draw samples from the variational ... | with neural_network:
trace = pm.variational.sample_vp(v_params, draws=5000) | 100%|██████████| 5000/5000 [00:00<00:00, 12175.62it/s]
| BSD-3-Clause | pymc3/bayesian_neural_network_wiecki.ipynb | jackbenn/probabilistic-programming-intro |
Plotting the objective function (ELBO) we can see that the optimization slowly improves the fit over time. | plt.plot(v_params.elbo_vals)
plt.ylabel('ELBO')
plt.xlabel('iteration') | _____no_output_____ | BSD-3-Clause | pymc3/bayesian_neural_network_wiecki.ipynb | jackbenn/probabilistic-programming-intro |
Now that we trained our model, lets predict on the hold-out set using a posterior predictive check (PPC). We use [`sample_ppc()`](http://pymc-devs.github.io/pymc3/api.htmlpymc3.sampling.sample_ppc) to generate new data (in this case class predictions) from the posterior (sampled from the variational estimation). | # Replace shared variables with testing set
ann_input.set_value(X_test)
ann_output.set_value(Y_test)
# Creater posterior predictive samples
ppc = pm.sample_ppc(trace, model=neural_network, samples=500)
# Use probability of > 0.5 to assume prediction of class 1
pred = ppc['out'].mean(axis=0) > 0.5
fig, ax = plt.subplo... | Accuracy = 94.6%
| BSD-3-Clause | pymc3/bayesian_neural_network_wiecki.ipynb | jackbenn/probabilistic-programming-intro |
Hey, our neural network did all right! Lets look at what the classifier has learnedFor this, we evaluate the class probability predictions on a grid over the whole input space. | grid = np.mgrid[-3:3:100j,-3:3:100j]
grid_2d = grid.reshape(2, -1).T
X, Y = grid
dummy_out = np.ones(grid.shape[1], dtype=np.int8)
ann_input.set_value(grid_2d)
ann_output.set_value(dummy_out)
# Creater posterior predictive samples
ppc = pm.sample_ppc(trace, model=neural_network, samples=500) | 100%|██████████| 500/500 [00:04<00:00, 113.79it/s]
| BSD-3-Clause | pymc3/bayesian_neural_network_wiecki.ipynb | jackbenn/probabilistic-programming-intro |
Probability surface | cmap = sns.diverging_palette(250, 12, s=85, l=25, as_cmap=True)
fig, ax = plt.subplots(figsize=(10, 6))
contour = ax.contourf(X, Y, ppc['out'].mean(axis=0).reshape(100, 100), cmap=cmap)
ax.scatter(X_test[pred==0, 0], X_test[pred==0, 1])
ax.scatter(X_test[pred==1, 0], X_test[pred==1, 1], color='r')
cbar = plt.colorbar(c... | _____no_output_____ | BSD-3-Clause | pymc3/bayesian_neural_network_wiecki.ipynb | jackbenn/probabilistic-programming-intro |
Uncertainty in predicted valueSo far, everything I showed we could have done with a non-Bayesian Neural Network. The mean of the posterior predictive for each class-label should be identical to maximum likelihood predicted values. However, we can also look at the standard deviation of the posterior predictive to get a... | cmap = sns.cubehelix_palette(light=1, as_cmap=True)
fig, ax = plt.subplots(figsize=(10, 6))
contour = ax.contourf(X, Y, ppc['out'].std(axis=0).reshape(100, 100), cmap=cmap)
ax.scatter(X_test[pred==0, 0], X_test[pred==0, 1])
ax.scatter(X_test[pred==1, 0], X_test[pred==1, 1], color='r')
cbar = plt.colorbar(contour, ax=ax... | _____no_output_____ | BSD-3-Clause | pymc3/bayesian_neural_network_wiecki.ipynb | jackbenn/probabilistic-programming-intro |
We can see that very close to the decision boundary, our uncertainty as to which label to predict is highest. You can imagine that associating predictions with uncertainty is a critical property for many applications like health care. To further maximize accuracy, we might want to train the model primarily on samples f... | from six.moves import zip
# Set back to original data to retrain
ann_input.set_value(X_train)
ann_output.set_value(Y_train)
# Tensors and RV that will be using mini-batches
minibatch_tensors = [ann_input, ann_output]
minibatch_RVs = [out]
# Generator that returns mini-batches in each iteration
def create_minibatch(d... | _____no_output_____ | BSD-3-Clause | pymc3/bayesian_neural_network_wiecki.ipynb | jackbenn/probabilistic-programming-intro |
While the above might look a bit daunting, I really like the design. Especially the fact that you define a generator allows for great flexibility. In principle, we could just pool from a database there and not have to keep all the data in RAM. Lets pass those to `advi_minibatch()`: | %%time
with neural_network:
# Run advi_minibatch
v_params = pm.variational.advi_minibatch(
n=50000, minibatch_tensors=minibatch_tensors,
minibatch_RVs=minibatch_RVs, minibatches=minibatches,
total_size=total_size, learning_rate=1e-2, epsilon=1.0
)
with neural_network:
trac... | _____no_output_____ | BSD-3-Clause | pymc3/bayesian_neural_network_wiecki.ipynb | jackbenn/probabilistic-programming-intro |
As you can see, mini-batch ADVI's running time is much lower. It also seems to converge faster.For fun, we can also look at the trace. The point is that we also get uncertainty of our Neural Network weights. | pm.traceplot(trace); | _____no_output_____ | BSD-3-Clause | pymc3/bayesian_neural_network_wiecki.ipynb | jackbenn/probabilistic-programming-intro |
This notebook is broken into two sections, firstly an introduction to the NumPy package and secondly a breakdown of the NumPy random package. The NumPy Package What is it?NumPy is a Python package used for scientific computing. Often cited as a fundamental package in this area, this is for good reason. It provides a hi... | import numpy as np | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
From here let's create an array of values that represent distances eg. in metres | mvalues = [45.26, 10.9, 26.3, 80.5, 24.1, 66.1, 19.8, 3.0, 8.8, 132.5] | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
Great, now let's do some NumPy stuff on that. We're going to turn our array of values into a one-dimensional NumPy array and print it to the screen. | M = np.array(mvalues)
print(M) | [ 45.26 10.9 26.3 80.5 24.1 66.1 19.8 3. 8.8 132.5 ]
| MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
Now let's say that we wanted to convert all of our values in metres to centimetres. This is easily achieved using a NumPy array and scalar multiplication. | print(M*100) | [ 4526. 1090. 2630. 8050. 2410. 6610. 1980. 300. 880. 13250.]
| MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
If we print out M again you can see that the values have not been changed. | print(M) | [ 45.26 10.9 26.3 80.5 24.1 66.1 19.8 3. 8.8 132.5 ]
| MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
Now if you wanted to do the same thing using standard Python, as shown below, then hopefully you can clearly see the advantage in using NumPy instead. | mvalues = [ i*100 for i in mvalues]
print(mvalues) | [4526.0, 1090.0, 2630.0, 8050.0, 2410.0, 6609.999999999999, 1980.0, 300.0, 880.0000000000001, 13250.0]
| MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
The values for mvalues have also all been permanently changed now, whereas we didn't need to alter them when using NumPy Earlier I explained that NumPy provides the ndarray object. "M" is an instance of the class ```numpy.ndarray```, proven below: | type(M) | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
The NumPy Random Package The NumPy random package is used for sampling and generating random data. Across this section I've split the descriptions and examples into 4 sections: Simple Random Data Permutations Distributions Random GeneratorIn order to use the random package the name of package must be speci... | import numpy as np
np.random.rand(3,3) | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
randn `numpy.random.randn` Returns a sample (or samples) from the “standard normal” distribution.A standard normal distribution is a normal distribution where the average value is 0, and the variance is 1. When the function is provided a positive "int_like or int-convertible arguments", randn generates an array of spe... | import numpy as np
np.random.randn(3,2) | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
Additional computations can be added for greater specificity | np.random.randn(3,2) + 8 | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
randint `numpy.random.randint` Returns random integers from low (inclusive) to high (exclusive).the parameters for ```randint``` are **(low, high=None, size=None, dtype='l')*** **low and high** simply refer to the lowest and highest numbers that can be drawn from the distribution,* **size** refers to the output shape,... | import numpy as np
np.random.randint(5, size=(4, 4)) | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
`randint` is often used for more simple operations eg. generate a random number between 1-10 | np.random.randint(1,10) | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
random_integers `numpy.random.random_integers` Returns random integers of type np.int from the “discrete uniform” distribution in the closed interval [low, high].`random_integers` is similar to ```randint```, only for the closed interval [low, high]. 0 is the lowest value if high is omitted when using `random_integers... | import numpy as np
x = 5 * np.random.random_sample((250, 250)) + 0
x | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
Below is a plot of the interval above which shows the continuous uniform distribution produced by `random_sample`, in the form of a histogram | # Import matplot in order to generate a histogram
import matplotlib.pyplot as plt
# Define the amount of bins (series of intervals) for the histogram
num_bins = [0,1,2,3,4,5]
# Plot and display the histogram
n, bins, patches = plt.hist(x, num_bins, facecolor = 'green', alpha = 0.8)
plt.show() | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
random, ranf and sample An interesting point to note is the homogeniety between the `random_sample`, `random`, `ranf` and `sample` functions. As noted in the official NumPy documentation, all of these functions, "Return random floats in the half-open interval [0.0, 1.0)."To prove that the functions are the same and... | np.random.random_sample is np.random.random
np.random.random_sample is np.random.ranf
np.random.random_sample is np.random.sample | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
choice`numpy.random.choice` Generates a random sample from a given 1-D array. If you use a ndarray as the input then a random number will be selected from the elements provided. This may be useful for situations where you have a large pool of numbers to choose from and need a random selection eg. | import numpy as np
j = [2,4,9,125,3,19,8,62,1004,203]
# Convert array to a NumPy array
o = np.array(j)
# Output a random choice
np.random.choice(o) | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
The sample assumes a uniform distribution over all entries, however, if we wanted to change this and account for different probabilities we can use a parameter to set the probability for each individual entry. Remember that probability must add up to 1. | import numpy as np
# Apply probabilities for each individual entry
np.random.choice(o, p = [0.1, 0.025, 0.025, 0.025, 0.025, 0.1, 0.1, 0.3, 0.2, 0.1]) | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
bytes `numpy.random.bytes` This a useful function that simply return a string of bytes of given length eg. | import numpy as np
# Output a string of 15 random bytes
np.random.bytes(15) | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
Permutations This definition from Wikipedia explains nicely what a permutation is: In mathematics, the notion of permutation relates to the act of arranging all the members of a set into some sequence or order, or if the set is already ordered, rearranging its elements, a process called permuting. The n... | import numpy as np
# Create an array of values between 0-15, reshape to 4x4 array
arr = np.arange(16).reshape((4,4))
# Shuffle the array
np.random.shuffle(arr)
arr
| _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
But what if I want to shuffle a 2D array? If this is the case then you can use the `ravel` function to flatten a multi-dimensional array like so: | # Create the NumPy array
e = np.array([[20,30,40],[50,60,70],[80,90,100]])
e
# Flatten the array, shuffle and output result
np.random.shuffle(e.ravel())
e | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
permutation`numpy.random.permutation` Randomly permutes a sequence or returns a permuted range of values. In the case the the value is an array, `permutation` will copy and shuffle the elements randomly. If x is an integer, np.arange(x) is called and randomly permuted. | import numpy as np
# Return a random permutation from an array of values in the range of 0-5
# (np.arange uses the half-open interval of [0,1))
np.random.permutation(6)
# Return a shuffled copy of the permutation of the array
np.random.permutation([1, 4, 9, 12, 15])
# Permute
arr = np.arange(4).reshape((2, 2))
np.ra... | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
DistributionsThe distribution of a statistical data set (or a population) is a listing or function showing all the possible values (or intervals) of the data and how often they occur. When a distribution of categorical data is organized, you see the number or percentage of individuals in each group. When a distributio... | # Import required packages
import matplotlib.pyplot as plt
import numpy as np
# Set the mean and standard deviation
mu, sigma = 100, 3
#
s = np.random.normal(mu, sigma, 30000)
#
count, bins, ignored = plt.hist(s, 25, density=True, color='blue')
# Plot a line that shows the probability density function for the nor... | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
The Binomial Distribution`np.random.binomial`It can be used to obtain the number of successes from N Bernoulli trials. Samples are drawn from a binomial distribution with specified parameters, n trials and p probability of success where n an integer >= 0 and p is in the interval [0,1]. (n may be input as a floa... | import numpy as np
import matplotlib.pyplot as plt
# Import the Seaborn package for graphing
import seaborn as sb
# Number of trials, probability of each trial
n, p = 100, .1
# Generate binomial distribution
s = np.random.binomial(n, p, 30000)
# Plot the graph with Seaborn
ax = sb.distplot(s,
kde=F... | /anaconda3/lib/python3.6/site-packages/matplotlib/axes/_axes.py:6462: UserWarning: The 'normed' kwarg is deprecated, and has been replaced by the 'density' kwarg.
warnings.warn("The 'normed' kwarg is deprecated, and has been "
| MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
What I've shown here is that a binomial distribution is very different from a normal distribution, and yet if the sample size is large enough, the shapes will be quite similar as can be seen here. I used 30,000 as the size of both distributions and both produced a bell shaped curve.The main difference between the two i... | import matplotlib.pyplot as plt
import numpy as np
# shape and mode
a, m = 3., 2.
# Calculate original pareto
s = (np.random.pareto(a, 1000) + 1) * m
count, bins, _ = plt.hist(s, 100, density=True, color="blue")
fit = a*m**a / bins**(a+1)
plt.plot(bins, max(count)*fit/max(fit), linewidth=2, color='red')
plt.show() | _____no_output_____ | MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
Random Generators RandomState`numpy.random.RandomState` The container for the Mersenne Twister pseudo-random number generator. This class is what is primarily used in NumPy to generate random numbers. If no seed is provided, the generator will try to use the system clock as a seed. seed`numpy.random.seed`We can use `s... | import numpy as np
# Set seed
np.random.seed(25)
# Generate random numbers
a = np.random.rand(5)
# Change seed
np.random.seed(55)
# Generate random numbers again
b = np.random.rand(5)
# Output results
print("a: ", a)
print("b: ", b) | a: [0.87012414 0.58227693 0.27883894 0.18591123 0.41110013]
b: [0.09310829 0.97165592 0.48385998 0.2425227 0.53112383]
| MIT | numpy-random.ipynb | mattshiel/emerging-technologies |
1.1 Getting started Prerequisites InstallationThis tutorial requires **signac**, so make sure to install the package before starting.The easiest way to do so is using conda:```$ conda config --add channels conda-forge``````$ conda install signac```or pip:```pip install signac --user```Please refer to the [documentatio... | import signac | _____no_output_____ | BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
We start by removing all data which might be left-over from previous executions of this tutorial. | %rm -rf projects/tutorial/workspace | _____no_output_____ | BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
A minimal exampleFor this tutorial we want to compute the volume of an ideal gas as a function of its pressure and thermal energy using the ideal gas equation$p V = N kT$, where$N$ refers to the system size, $p$ to the pressure, $kT$ to the thermal energy and $V$ is the volume of the system. | def V_idg(N, kT, p):
return N * kT / p | _____no_output_____ | BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
We can execute the complete study in just a few lines of code.First, we initialize the project directory and get a project handle: | import signac
project = signac.init_project(name="TutorialProject", root="projects/tutorial") | _____no_output_____ | BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
We iterate over the variable of interest *p* and construct a complete state point *sp* which contains all the meta data associated with our data.In this simple example the meta data is very compact, but in principle the state point may be highly complex.Next, we obtain a *job* handle and store the result of the calcula... | for p in 0.1, 1.0, 10.0:
sp = {"p": p, "kT": 1.0, "N": 1000}
job = project.open_job(sp)
job.document["V"] = V_idg(**sp) | _____no_output_____ | BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
We can then examine our results by iterating over the data space: | for job in project:
print(job.sp.p, job.document["V"]) | 0.1 10000.0
10.0 100.0
1.0 1000.0
| BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
That's it....Ok, there's more...Let's have a closer look at the individual components. The BasicsThe **signac** data management framework assists the user in managing the data space of individual *projects*.All data related to one or multiple projects is stored in a *workspace*, which by default is a directory called `... | print(project.root_directory())
print(project.workspace()) | notebooks/projects/tutorial
notebooks/projects/tutorial/workspace
| BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
The core idea is to tightly couple state points, unique sets of parameters, with their associated data.In general, the parameter space needs to contain all parameters that will affect our data.For the ideal gas that is a 3-dimensional space spanned by the thermal energy *kT*, the pressure *p* and the system size *N*.Th... | job = project.open_job({"p": 1.0, "kT": 1.0, "N": 1000}) | _____no_output_____ | BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
The *job* handle tightly couples our input parameters (*p*, *kT*, *N*) with the storage location of the output data.You can inspect both the input parameters and the storage location explicitly: | print(job.statepoint())
print(job.workspace()) | {'p': 1.0, 'kT': 1.0, 'N': 1000}
notebooks/projects/tutorial/workspace/ee617ad585a90809947709a7a45dda9a
| BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
For convenience, a job's *state point* may also be accessed via the short-hand `sp` attribute.For example, to access the pressure value `p` we can use either of the two following expressions: | print(job.statepoint()["p"])
print(job.sp.p) | 1.0
1.0
| BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
Each *job* has a **unique id** representing the state point.This means opening a job with the exact same input parameters is guaranteed to have the **exact same id**. | job2 = project.open_job({"kT": 1.0, "N": 1000, "p": 1.0})
print(job.id, job2.id) | ee617ad585a90809947709a7a45dda9a ee617ad585a90809947709a7a45dda9a
| BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
The *job id* is used to uniquely identify data associated with a specific state point.Think of the *job* as a container that is used to store all data associated with the state point.For example, it should be safe to assume that all files that are stored within the job's workspace directory are tightly coupled to the j... | print(job.workspace()) | notebooks/projects/tutorial/workspace/ee617ad585a90809947709a7a45dda9a
| BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
Let's store the volume calculated for each state point in a file called `V.txt` within the job's workspace. | import os
fn_out = os.path.join(job.workspace(), "V.txt")
with open(fn_out, "w") as file:
V = V_idg(**job.statepoint())
file.write(str(V) + "\n") | _____no_output_____ | BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
Because this is such a common pattern, **signac** signac allows you to short-cut this with the `job.fn()` method. | with open(job.fn("V.txt"), "w") as file:
V = V_idg(**job.statepoint())
file.write(str(V) + "\n") | _____no_output_____ | BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
Sometimes it is easier to temporarily switch the *current working directory* while storing data for a specific job.For this purpose, we can use the `Job` object as [context manager](https://docs.python.org/3/reference/compound_stmts.htmlwith).This means that we switch into the workspace directory associated with the jo... | with job:
with open("V.txt", "w") as file:
file.write(str(V) + "\n") | _____no_output_____ | BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
Another alternative to store light-weight data is the *job document* as shown in the minimal example.The *job document* is a persistent JSON storage file for simple key-value pairs. | job.document["V"] = V_idg(**job.statepoint())
print(job.statepoint(), job.document) | {'p': 1.0, 'kT': 1.0, 'N': 1000} {'V': 1000.0}
| BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
Since we are usually interested in more than one state point, the standard operation is to iterate over all variable(s) of interest, construct the full state point, get the associated job handle, and then either just initialize the job or perform the full operation. | for pressure in 0.1, 1.0, 10.0:
statepoint = {"p": pressure, "kT": 1.0, "N": 1000}
job = project.open_job(statepoint)
job.document["V"] = V_idg(**job.statepoint()) | _____no_output_____ | BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
Let's verify our result by inspecting the data. | for job in project:
print(job.statepoint(), job.document) | {'p': 0.1, 'kT': 1.0, 'N': 1000} {'V': 10000.0}
{'p': 10.0, 'kT': 1.0, 'N': 1000} {'V': 100.0}
{'p': 1.0, 'kT': 1.0, 'N': 1000} {'V': 1000.0}
| BSD-3-Clause | notebooks/signac_101_Getting_Started.ipynb | sbkashif/signac-examples |
Sequences BasicsExample, some code and a lot of inspiration taken from: https://machinelearningmastery.com/how-to-develop-lstm-models-for-time-series-forecasting/ | import matplotlib.pyplot as plt
%matplotlib inline
import matplotlib as mpl
mpl.rcParams['figure.figsize'] = (20, 8)
try:
# %tensorflow_version only exists in Colab.
%tensorflow_version 2.x
except Exception:
pass
import tensorflow as tf
print(tf.__version__) | 2.2.0
| MIT | notebooks/tf-intro/2020-01-rnn-basics.ipynb | DJCordhose/ml-workshop |
Univariate Sequencesjust one variable per time step ChallengeWe have a known series of events, possibly in time and you want to know what is the next event. Like this[10, 20, 30, 40, 50, 60, 70, 80, 90] | # univariate data preparation
import numpy as np
# split a univariate sequence into samples
def split_sequence(sequence, n_steps):
X, y = list(), list()
for i in range(len(sequence)):
# find the end of this pattern
end_ix = i + n_steps
# check if we are beyond the sequence
if end_ix > len(sequence)-1:
bre... | _____no_output_____ | MIT | notebooks/tf-intro/2020-01-rnn-basics.ipynb | DJCordhose/ml-workshop |
Converting shapes* one of the most frequent, yet most tedious steps* match between what you have and what an interface needs* expected input of RNN: 3D tensor with shape (samples, timesteps, input_dim)* we have: (samples, timesteps)* reshape on np arrays can do all that | # reshape from [samples, timesteps] into [samples, timesteps, features]
n_features = 1
X = X.reshape((X.shape[0], X.shape[1], n_features))
X
import tensorflow as tf
from tensorflow import keras
from tensorflow.keras.layers import Dense, LSTM, GRU, SimpleRNN, Bidirectional
from tensorflow.keras.models import Sequential,... | _____no_output_____ | MIT | notebooks/tf-intro/2020-01-rnn-basics.ipynb | DJCordhose/ml-workshop |
Let's try this on a few examples | # this does not look too bad
X_sample = np.array([[10, 20, 30], [70, 80, 90]]).astype(np.float32)
X_sample = X_sample.reshape((X_sample.shape[0], X_sample.shape[1], n_features))
X_sample
y_pred = model.predict(X_sample)
y_pred
def predict(model, samples, n_features=1):
input = np.array(samples).astype(np.float32)
i... | _____no_output_____ | MIT | notebooks/tf-intro/2020-01-rnn-basics.ipynb | DJCordhose/ml-workshop |
Exercise* go through the notebook as it is* Try to improve the model * Change the number of values used as input * Change activation function * More nodes? less nodes? * What else might help improving the results? STOP HERE Input and output of an RNN layer | # https://keras.io/layers/recurrent/
# input: (samples, timesteps, input_dim)
# output: (samples, units)
# let's have a look at the actual output for an example
rnn_layer = model.get_layer("RNN_Input")
model_stub = Model(inputs = model.input, outputs = rnn_layer.output)
hidden = predict(model_stub, [[10, 20, 30]])
hid... | _____no_output_____ | MIT | notebooks/tf-intro/2020-01-rnn-basics.ipynb | DJCordhose/ml-workshop |
What do we see?* each unit (50) has a single output* as a sidenote you nicely see the RELU nature of the output* so the timesteps of the input are lost* we are only looking at the final output* still with each timestep, the layer does produce a unique output we could potentially use We need to look into RNNs a bit mo... | _____no_output_____ | MIT | notebooks/tf-intro/2020-01-rnn-basics.ipynb | DJCordhose/ml-workshop | |
SOP036 - Install kubectl command line interface===============================================Steps----- Common functionsDefine helper functions used in this notebook. | # Define `run` function for transient fault handling, suggestions on error, and scrolling updates on Windows
import sys
import os
import re
import json
import platform
import shlex
import shutil
import datetime
from subprocess import Popen, PIPE
from IPython.display import Markdown
retry_hints = {} # Output in stder... | _____no_output_____ | MIT | Big-Data-Clusters/CU6/Public/content/install/sop036-install-kubectl.ipynb | gantz-at-incomm/tigertoolbox |
Install Kubernetes CLITo get the latest version number for `kubectl` for Windows, open thisfile:- https://storage.googleapis.com/kubernetes-release/release/stable.txtNOTE: For Windows, `kubectl.exe` is installed in the folder containingthe `python.exe` (`sys.executable`), which will be in the path fornotebooks run i... | import os
import sys
import platform
from pathlib import Path
if platform.system() == "Darwin":
run('brew update')
run('brew install kubernetes-cli')
elif platform.system() == "Windows":
path = Path(sys.executable)
cwd = os.getcwd()
os.chdir(path.parent)
run('curl -L https://storage.googleapis... | _____no_output_____ | MIT | Big-Data-Clusters/CU6/Public/content/install/sop036-install-kubectl.ipynb | gantz-at-incomm/tigertoolbox |
Fastai Mnist sample (for binder)- (adapted from fastai v3 https://github.com/fastai/course-v3/blob/master/nbs/dl1/lesson1-pets.ipynb) In this lesson we will build our first image classifier from scratch. Let's dive in!Every notebook starts with the following three lines; they ensure that any edits to libraries you mak... | %reload_ext autoreload
%autoreload 2
%matplotlib inline | _____no_output_____ | MIT | notebooks/fastai/fastai-mnist-sample.ipynb | DevScope/ai-lab |
We import all the necessary packages. We are going to work with the [fastai V1 library](http://www.fast.ai/2018/10/02/fastai-ai/) which sits on top of [Pytorch 1.0](https://hackernoon.com/pytorch-1-0-468332ba5163). The fastai library provides many useful functions that enable us to quickly and easily build neural netwo... | from fastai.vision import *
from fastai.metrics import error_rate
bs = 64
# bs = 16 # uncomment this line if you run out of memory even after clicking Kernel->Restart | _____no_output_____ | MIT | notebooks/fastai/fastai-mnist-sample.ipynb | DevScope/ai-lab |
Looking at the data We are going to use the `untar_data` function to which we must pass a URL as an argument and which will download and extract the data. | help(untar_data) | Help on function untar_data in module fastai.datasets:
untar_data(url:str, fname:Union[pathlib.Path, str]=None, dest:Union[pathlib.Path, str]=None, data=True, force_download=False) -> pathlib.Path
Download `url` to `fname` if it doesn't exist, and un-tgz to folder `dest`.
| MIT | notebooks/fastai/fastai-mnist-sample.ipynb | DevScope/ai-lab |
We'll use MNIST sample version, with two classes: 3 and 7 | path = untar_data(URLs.MNIST_SAMPLE); path
path.ls() | _____no_output_____ | MIT | notebooks/fastai/fastai-mnist-sample.ipynb | DevScope/ai-lab |
Binder/docker/fastai changes | #Binder doesn't allow for GPU, switch to CPU
defaults.device = 'cpu'
data = ImageDataBunch.from_folder(path)
data
data.show_batch(rows=3, figsize=(7,6))
print(data.classes)
len(data.classes),data.c | ['3', '7']
| MIT | notebooks/fastai/fastai-mnist-sample.ipynb | DevScope/ai-lab |
Training Now we will start training our model. We will use a [convolutional neural network](http://cs231n.github.io/convolutional-networks/) backbone and a fully connected head with a single hidden layer as a classifier. We will train for 2 epochs (2 cycles through all our data). | learn = create_cnn(data, models.resnet18, metrics=[accuracy])
learn.model
learn.fit_one_cycle(2)
learn.save('stage-1') | _____no_output_____ | MIT | notebooks/fastai/fastai-mnist-sample.ipynb | DevScope/ai-lab |
Results | interp = ClassificationInterpretation.from_learner(learn)
losses,idxs = interp.top_losses()
len(data.valid_ds)==len(losses)==len(idxs)
interp.plot_top_losses(9, figsize=(15,11))
doc(interp.plot_top_losses)
interp.plot_confusion_matrix(figsize=(12,12), dpi=60)
interp.most_confused(min_val=2) | _____no_output_____ | MIT | notebooks/fastai/fastai-mnist-sample.ipynb | DevScope/ai-lab |
*Data Science Unit 4 Sprint 3 Assignment 1* Recurrent Neural Networks and Long Short Term Memory (LSTM)It is said that [infinite monkeys typing for an infini... | import sys
import numpy
from keras.models import Sequential
from keras.layers import Dense
from keras.layers import Dropout
from keras.layers import LSTM
from keras.callbacks import ModelCheckpoint
from keras.utils import np_utils
# load ascii text and covert to lowercase
filename = "content/shakespeare.txt"
raw_text =... | ----------------------------------------
Iteration 1
Epoch 1/1
49280/1859890 [..............................] - ETA: 19:51 - loss: 1.5709 | MIT | module1-rnn-and-lstm/LS_DS_431_RNN_and_LSTM_Assignment.ipynb | nchibana/DS-Unit-4-Sprint-3-Deep-Learning |
훈련된 모형의 저장과 복원*모형을 훈련한 후 모형을 저장하고 애플리케이션에 필요할 때 이를 다시 복원 할 수 있어야 한다.* 모형을 피클(pickle)로 저장한다.* 피클이란? 파이썬 객체 자체를 binary 파일로 저장하는 것을 말한다.*사이킷런에는 피클 기능을 확장한 joblib 모듈을 제공한다.* 주의 할 점 – 저장된 모델이 사이킷런 버전 간에 호환되지 않는지 주의해야 한다. 피클을 사용하기 때문에 버전이 맞지 않으면 로드시 에러가 발생한다. | from sklearn.ensemble import RandomForestClassifier
from sklearn import datasets
import joblib
iris = datasets.load_iris()
features = iris.data
target = iris.target
classifier = RandomForestClassifier()
model = classifier.fit(features, target) | _____no_output_____ | MIT | 06Model_Save_Load/Model_Save_Load.ipynb | aonekoda/Sklearn |
Model save | joblib.dump(model, 'model.pkl') | _____no_output_____ | MIT | 06Model_Save_Load/Model_Save_Load.ipynb | aonekoda/Sklearn |
Model Load | loaded_model = joblib.load("model.pkl")
print(loaded_model)
new_obs = [[5.2, 3.2, 1.1, 0.1]]
loaded_model.predict(new_obs) | _____no_output_____ | MIT | 06Model_Save_Load/Model_Save_Load.ipynb | aonekoda/Sklearn |
Basics | print("Hello World!")
# This is comment!
bread=10
print(bread)
bread=input()
bread
43+5
'43'+5 | _____no_output_____ | MIT | day-1/session-2.ipynb | vchrombie/da-python |
**Find out the reason behind the above error.****Tip**: Copy the error and search in [Google](https://www.google.com/). | 8
8+3 | _____no_output_____ | MIT | day-1/session-2.ipynb | vchrombie/da-python |
Data Types Integers: -2, -1, 0, 1, 2, 3, 4, 5Floating-point numbers: -1.25, -1.0, --0.5, 0.0, 0.5, 1.0, 1.25Strings: 'a', 'aa', 'aaa', 'Hello!', '11 cats' **Math Operations** | #Addition
2+3
#Subtraction
8-3
#Multiplication
2*4
#Division
42/10
# Exponent
2**4
#Modulus/Remainder
42%10
#Floored Quotient
42//10 | _____no_output_____ | MIT | day-1/session-2.ipynb | vchrombie/da-python |
**Note**: The precedence rule is BODMAS.The ** operator is evaluated first; the *, /, //, and % operators are evaluated next, from left to right; and the + and - operators are evaluated last (also from left to right). You can use parentheses to override the usual precedence if you need to. | 2 + 3 * 6
(2 + 3) * 6
48565878 * 578453
2 ** 8
23 / 7
23 // 7
23 % 7
#extra spaces? no problem
#python is chill :P
2 + 2
(5 - 1) * ((7 + 1) / (3 - 1)) | _____no_output_____ | MIT | day-1/session-2.ipynb | vchrombie/da-python |
Explanation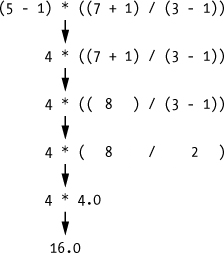 | 5 +
42 + 5 + * 2 | _____no_output_____ | MIT | day-1/session-2.ipynb | vchrombie/da-python |
The operations applicable for integers are also applicable for floating numbers too. | bread=10
bread
print(bread)
butter=3
bread+butter
print(bread+butter)
bread=bread+2
bread
bread++ | _____no_output_____ | MIT | day-1/session-2.ipynb | vchrombie/da-python |
**Note**: Coding in python is entirely different from c/cpp. Strings | msg='Hello'
msg
print(msg)
msg='Goodbye'
print(msg)
len(msg)
print(len(msg))
msg+1
msg+'1'
msg+str(1) | _____no_output_____ | MIT | day-1/session-2.ipynb | vchrombie/da-python |
Variable Names**Valid** ✔️balancecurrentBalance current_balance _spamSPAMaccount4----**Invalid** ❌'hello' (special characters like ' are not allowed)current-balance (hyphens are not allowed)4account (can’t begin with a number)42 (can’t begin with a number)current balance (spaces are not allowed)total_$um (special char... | #INPUT: Hi! :)
msg=input()
print(msg)
print(type(msg))
#INPUT: 12
msg=input()
print(msg)
print(type(msg))
#integer input
#INPUT : 12
msg=int(input())
print(msg)
print(type(msg))
#change the datatype
msg=str(msg)
print(msg)
print(type(msg))
print(int(msg)+1)
print(float(msg)+1)
print(int(7.7))
print(int(7.7) + 1) | 8
| MIT | day-1/session-2.ipynb | vchrombie/da-python |
Please understand this small program | print('Hello world!')
print('What is your name?') # ask for their name
myName = input()
print('It is good to meet you, ' + myName)
print('The length of your name is:')
print(len(myName))
print('What is your age?') # ask for their age
myAge = input()
print('You will be ' + str(int(myAge) + 1) + ' in a year.') | Hello world!
What is your name?
Venu
It is good to meet you, Venu
The length of your name is:
4
What is your age?
21
You will be 22 in a year.
| MIT | day-1/session-2.ipynb | vchrombie/da-python |
Task 1Write a program for polling booth. It should ask a name, his age and ask for vote (NDA/UPA). Flow Control | print(True, False)
print(1,0) | True False
1 0
| MIT | day-1/session-2.ipynb | vchrombie/da-python |
Operators | #equal to
2==3
#not equal to
2!=3
#greater than
2>3
#less than
2<3
#less/greater than equal to
print(2>=3)
print(2<=3)
1==True
print('hello' == 'hello')
print('hello' == 'Hello')
True!=False
42==42.0
42=='42'
bread=21
bread>10 | _____no_output_____ | MIT | day-1/session-2.ipynb | vchrombie/da-python |
Binary and Boolean Operations | True and True
False or False
not False | _____no_output_____ | MIT | day-1/session-2.ipynb | vchrombie/da-python |
Conditional Statements | if(4<5):
print("Yo!")
bread=int(input())
if(bread>10):
print("I have 10+ bread")
elif(bread==10):
print("I have exactly 10 bread")
else:
print("I have less than 10 bread")
if(True):
print("This is how you overide a conditional statement.")
if(False):
print("This will not print anything.")
if(inp... | False
This will print anything.
| MIT | day-1/session-2.ipynb | vchrombie/da-python |
You may be wondering why the above code worked. It worked because `input()` always take the input as *string* format not *boolen* format.You can convert it into *boolean* by modifying it as `bool(input())` | bread=12
if(bread):
print("Every value other than 0 is considered as True")
bread=0
if(bread):
print("I told you already. :P") | Every value other than 0 is considered as True
| MIT | day-1/session-2.ipynb | vchrombie/da-python |
Taks 2Implement this following flowchart Take the initial values as```pythonname='Dracula'age=4000```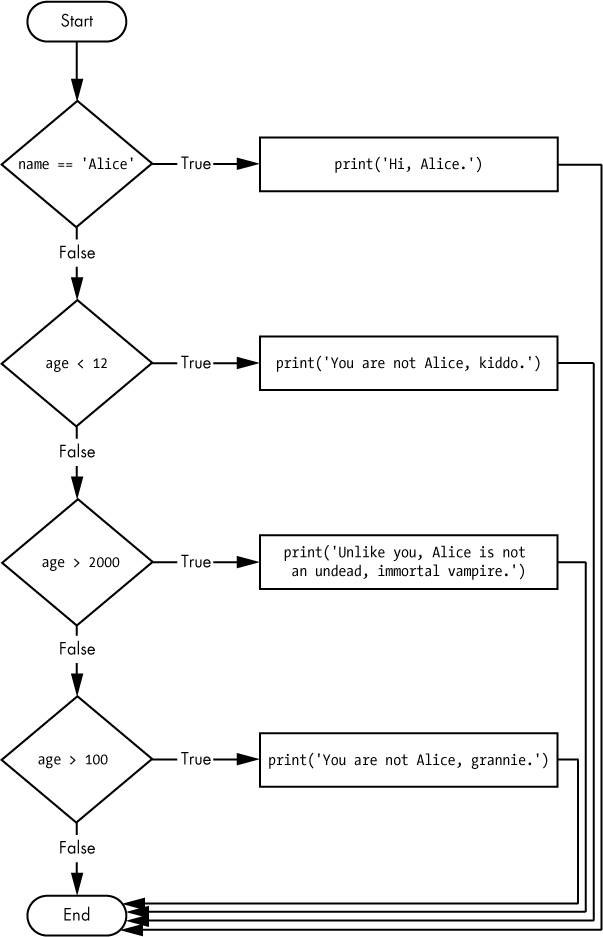 Loops `while` | bread=0
while(bread<5):
print("need more bread")
bread=bread+1
"""
while True:
print("This is an infinite loop!!")
""" | _____no_output_____ | MIT | day-1/session-2.ipynb | vchrombie/da-python |
Please have a look at the below code and understand it. | name = ''
while name != 'your name':
print('Please type your name.')
name = input()
print('Thank you!') | Please type your name.
Venu
Please type your name.
Venu
Please type your name.
ugh, stop it
Please type your name.
ok, i got this
Please type your name.
your name
Thank you!
| MIT | day-1/session-2.ipynb | vchrombie/da-python |
The above code will ask your input again and again until you give `your name` as input. You can build infinite loops accordingly.The below code is a re-written version of the above. You can control infinite loops with valid `break` statements. | while True:
print('Please type your name.')
name = input()
if name == 'your name':
break
print('Thank you!') | Please type your name.
Venu
Please type your name.
your name
Thank you!
| MIT | day-1/session-2.ipynb | vchrombie/da-python |
The keyword `continue` skips all the statements which are below itself. Look at the following | bread=0
while(bread<5):
print("bread added")
bread=bread+1
if(bread<3):
print("I am hungry.")
continue
print("I need more bread.") | bread added
I am hungry.
bread added
I am hungry.
bread added
bread added
bread added
| MIT | day-1/session-2.ipynb | vchrombie/da-python |
`for` | for i in range(3):
print("I need "+str(i)+" bread.")
#sum of n natural numbers program
total=0
n=int(input("Enter the n: "))
for i in range(n+1):
total=total+i
print(total) | Enter the n: 5
15
| MIT | day-1/session-2.ipynb | vchrombie/da-python |
**Note**: You can actually use a `while` loop to do the same thing as a `for` loop; `for` loops are just more concise. `starting`, `stopping` and `stepping` arguments in `for` loop | for i in range(0,10):
print(i)
for i in range(0,10,3):
print(i) | 0
3
6
9
| MIT | day-1/session-2.ipynb | vchrombie/da-python |
Task 3Write a program for polling booth. It should ask a name, his age and ask for vote (NDA/UPA/Others). It should verify your age too. You need to ask for vote untill you see no voters left. Have seperate counters for the parties and increase the counter accordingly. Importing Modules Python comes with many set of ... | #importing a module normally
import random
for i in range(5):
print(random.randint(1, 10))
#importing a module using an object
import random as rd
for i in range(5):
print(rd.randint(1, 10))
#importing one function from that module
#here, other functions of that module doesn't work
from random import randin... | 9
5
9
2
9
| MIT | day-1/session-2.ipynb | vchrombie/da-python |
Functions | def getBread():
print("bread!")
print("bread!!!")
getBread()
getBread()
getBread()
def getBread(number):
print("I want "+str(number)+" bread.")
getBread(3)
getBread(5)
getBread(8)
getBread() | I want 8 bread.
| MIT | day-1/session-2.ipynb | vchrombie/da-python |
**Error**: python is not like C/C++. You can define only one funtion with one name. You cannot differentiate with arguments. | def makeItEven(n):
return n*2
result=makeItEven(3)
print(result)
result=makeItEven(2)
print(result)
def makeItEven(n):
return n*2
print(makeItEven(3))
print(makeItEven(2)) | 6
4
| MIT | day-1/session-2.ipynb | vchrombie/da-python |
`None` represents absence of any value. | def getNothing():
return
getNothing()
print(getNothing())
def getNone():
return None
getNone()
print(getNone()) | None
| MIT | day-1/session-2.ipynb | vchrombie/da-python |
**Fact**: Behind the scenes, Python adds return `None` to the end of any function definition with no return statement. This is similar to how a `while` or `for` loop implicitly ends with a continue statement. Scope (Global and Local) | def getDosa():
dosa=8
getDosa()
print(dosa) | _____no_output_____ | MIT | day-1/session-2.ipynb | vchrombie/da-python |
**Error**: The above error is because the variable `dosa` is defined only fro the `getDosa` function and out of the defined scope, a variable cannot be used. | dosa=3
def getDosa():
print("dosa=",dosa)
getDosa()
print(dosa)
dosa=3
def getDosa():
dosa=8
print("dosa=",dosa)
getDosa()
print("dosa=",dosa)
def getDosa():
global dosa
dosa=8
print("dosa=",dosa)
getDosa()
print("dosa=",dosa)
def getDosa():
print("dosa=",dosa)
dosa=8 ... | _____no_output_____ | MIT | day-1/session-2.ipynb | vchrombie/da-python |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.