
instruction stringlengths 0 29.8k ⌀ |
|---|
Not sure if this is the right StackExchange site, but back in college (20 years ago) I took a _Digital Systems Design_ class where we learned how to reverse engineer a boolean function to meet the requirements set forth in a logic table.
If I recall correctly, the logic table looked _something_ like this:
```
Inpu... |
Algorithm or method for reverse engineering boolean function from a logic table |
|algorithms|logic|boolean-algebra| |
I think that this is equivalent to the problem of scheduling jobs on multiple identical processors in a way that minimizes makespan (when the last job finishes).
This has been shown to be an NP-Hard problem:
> Minimizing the maximum completion time ($P||{\displaystyle C_{\max }}C_{\max }$) is NP-hard even for ide... |
Not sure if this is the right StackExchange site, but back in college (20 years ago) I took a _Digital Systems Design_ class where we learned how to reverse engineer a boolean function to meet the requirements set forth in a logic table.
If I recall correctly, the logic table looked _something_ like this:
```
Inpu... |
Method for simplifying complex logic tables |
null |
I'll rewrite `cong` in terms of `replace`. This should also explain how replace works along the way.
We have `(= X a b)` and want to produce `(= Y f(a) f(b))`.
But notice that we already have `(= Y f(a) f(a))` from `(same f(a))`.
So ideally we want to replace the second `a` in `(= Y f(a) f(a))` with
a `b`. `repla... |
null |
A minimum expression $min(x_1, x_2)$ can be transformed by introducing a new variable $m$ replacing the expression and adding the following formula to the set of boolean combinations of (in/dis)equalities:
$(m \leq x_1) \land (m \leq x_2) \land ((m \geq x_1) \vee (m \geq x_2))$
The resulting problem is solved by ... |
null |
This is a quote from the book, "The Three-Body Problem" (page 112 in the paperback):
> He remembered taking a class in information theory as a third-year student in college. The professor had put up two pictures: One was the famous Song Dynasty painting [Along the River During the Qinming Festival][1] , full of fine... |
Comparing the entropy of a painting to a photograph |
|entropy| |
null |
Our professor has solved an example for us. They's taught us it's incorrect to use a quantifier (`exists` or `forall`) with a variable that's already bound on the left side of the pipe (`|`, meaning "such that"). He's done that in his example solution. Can quantifiers be used on variables bound on the left side of the ... |
Can quantifiers be used on variables bound on the left side of the pipe in Tuple Relational Calculus? |
null |
It sounds debatable to me. I could imagine a sense in which the quote might be correct, and another sense in which the quote might be considered incorrect.
One perspective would be: how many bits does it take to compress the image, using (perfect, ideal) lossless compression. Then I'm not sure how that would turn ... |
It sounds debatable to me. I could imagine a sense in which the quote might be correct, and another sense in which the quote might be considered incorrect.
One perspective would be: how many bits does it take to compress the image, using (perfect, ideal) lossless compression. Then I'm not sure how that would turn ... |
null |
No, they are not the same thing. They share similarities, in that they are both brain inspired approaches. But this is where the similarities end.
To avoid going into too much detail, I'll explain it with this analogy:
Imagine you're a civilization trying to figure out flight and you're presented with an airplane... |
Good question.
Suppose we have a positive function $T(n)$ such that
$$T(n) = a \cdot T\left(\frac{n}{b}\right) + f(n)$$
with $a \geq 1, b > 1$. You are referring to case $1$ of [Master's theorem](https://en.wikipedia.org/wiki/Master_theorem_(analysis_of_algorithms)):
$\qquad$ If $f \in O( n^{\log_b (a) - \... |
Someone who was explaining to me the master theorem said that for the case 1, we compare the $n^{\log_b(a)}$ and $f(n)$. If the growth rate of $n^{\log_b(a)}$ is greater than the growth rate of $f(n)$ then we subtract an epsilon to have this equality:
$$f(n) = O(n^{(\log_ba) - \epsilon})$$
My question is, doesn't t... |
Why not $O(n^{\log_ba})$ instead $O(n^{(\log_ba) - \epsilon})$ for case 1 of Master Theorem? |
null |
Good question.
Suppose we have a positive function $T(n)$ such that
$$T(n) = a \cdot T\left(\frac{n}{b}\right) + f(n)$$
with $a \geq 1, b > 1$. You are referring to case $1$ of [Master's theorem](https://en.wikipedia.org/wiki/Master_theorem_(analysis_of_algorithms)):
$\qquad$ If $f \in O( n^{\log_b (a) - \... |
Good question.
Suppose we have a positive function $T(n)$ such that
$$T(n) = a \cdot T\left(\frac{n}{b}\right) + f(n)$$
with $a \geq 1, b > 1$. You are referring to case $1$ of [the master theorem](https://en.wikipedia.org/wiki/Master_theorem_(analysis_of_algorithms)):
$\qquad$ If $f \in O( n^{\log_b (a) -... |
Why not $O(n^{\log_ba})$ for case 1 of the Master Theorem instead of $O(n^{(\log_ba) - \epsilon})$? |
null |
Whenever you think you have solved the two general problems, there is only 1 thing you need to do to find the problem.
Take every step of your algorithm and treat it as the final step before a permanent network failure. Does a general end up dead? Then you haven't solved it.
You say once A receives confirmation h... |
Whenever you think you have solved the two general problems, there is only 1 thing you need to do to find the problem.
Take every step of your algorithm and treat it as the final step before a permanent network failure. Does a general end up dead? Then you haven't solved it.
You say once A receives confirmation h... |
Whenever you think you have solved the two general problems, there is only 1 thing you need to do to find why your solution is wrong.
Take every step of your algorithm and treat it as the final step before a permanent network failure. Does a general end up dead? Then you haven't solved it.
You say once A receives... |
Whenever you think you have solved the two general problems, there is only 1 thing you need to do to find why your solution is wrong.
Take every step s_1...s_n of your algorithm and treat it as the final step before a permanent network failure. Does a general end up dead if any step s_i is the final step before tota... |
You can never go from an uncertainty to a certainty. The two generals problem is one where the only action that can be taken (sending a message) is an uncertain one.
If we changed the problems to have certainties then it's solvable. Like if general A had a portal that with 100% certainty a messenger can walk through... |
You can never go from an uncertainty to a certainty. The two generals problem is one where the only action that can be taken (sending a message) is an uncertain one.
If we changed the problems to have certainties then it's solvable. Like if general A had a portal that with 100% certainty a messenger can walk through... |
null |
Whenever you think you have solved the two general problems, there is only 1 thing you need to do to find why your solution is wrong.
Take every step s_1...s_n of your algorithm and treat it as the final step before a permanent network failure. Does a general end up dead if any step s_i is the final step before tota... |
Whenever you think you have solved the two general problems, there is only 1 thing you need to do to find why your solution is wrong.
Take every step s_1...s_n of your algorithm and treat it as the final step before a permanent network failure. Does a general end up dead if any step s_i is the final step before tota... |
Whenever you think you have solved the two general problems, there is only 1 thing you need to do to find why your solution is wrong.
Take every step s_1...s_n of your algorithm and treat it as the final step before a permanent network failure. Does a general end up dead if any step s_i is the final step before tota... |
Good question.
Suppose we have a positive function $T(n)$ such that
$$T(n) = a \cdot T\left(\frac{n}{b}\right) + f(n)$$
with $a \geq 1, b > 1$. You are referring to case $1$ of [the master theorem](https://en.wikipedia.org/wiki/Master_theorem_(analysis_of_algorithms)):
$\qquad$ If $f \in O( n^{\log_b (a) -... |
null |
Given a series `{an}` of length `n`, let `s(l, r)` be the difference between the largest and smallest numbers in the interval `[l, r]`.
Ask for the product of all `s(l, r)`.
For example, given `{1, 2, 4}` and `3`, the result should be `6`
This is my implementation with `O(n^2)`. I'm trying to find a solution les... |
Product of All the Possible Ranges in All Series |
|algorithms|time-complexity|c|c++| |
Given a series `{an}` of length `n`, let `s(l, r)` be the difference between the largest and smallest numbers in the interval `[l, r]`.
Ask for the product of all `s(l, r)`.
The formula for the result would be 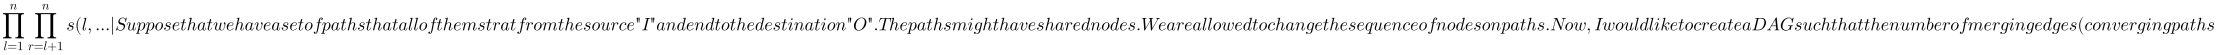 are minimized. The number ... |
Directed Acyclic Graph with minimized merging nodes |
|algorithms|graphs|optimization|dag| |
Suppose that we have a set of paths that all of them strat from the source "I" and end to the destination "O". The paths might have shared nodes. We are allowed to change the sequence of nodes on paths. Now, I would like to create a DAG such that the number of merging edges (converging paths) are minimized. The number ... |
Suppose that we have a set of paths that all of them strat from the source "I" and end to the destination "O". The paths might have shared nodes. We are allowed to change the sequence of nodes on paths. Now, I would like to create a DAG such that the number of merging edges (converging paths) are minimized. The number ... |
Suppose that we have a set of paths that all of them strat from the source "I" and end to the destination "O". The paths might have shared nodes. We are allowed to change the sequence of nodes on paths. Now, I would like to create a DAG such that the number of merging edges (converging paths) are minimized. The number ... |
Given $x \leq y$, find a sum $y_1+y_2+...+y_n$ where $y_i \leq x$ and $y_{i-1} \geq y_i$ for $1 \leq i \leq n$ and $y_n$ is maximised.
For example, given $x = 5$ and $y=17$, an optimal solution would be $17=5+4+4+4$ |
Given x <= y, find a sum adding to y such that all elements are <= x and the final element is maximised |
|algorithms|greedy-algorithms| |
Given x <= y, find a sum adding to y such that all elements are <= x and increasing and the final element is maximised |
Given x <= y, find a sum adding to y such that all elements are <= x and decreasing and the final element is maximised |
null |
Given is a prime signature $S$ and an integer $x$. The task is to count how many integers $n$ exist such that $n \leq x$, and if $n = p_1^{k_1}p_2^{k_2}p_3^{k_3}p_4^{k_4}...$ then $S = (k_1,k_2,k_3,...)$. Let $C(S,x)$ be that count.
For example, if $S = (3,1,1)$ and $x=1000$ then there are $21$ such integers, being ... |
Counting integers $n \leq x$ with a given prime signature |
|algorithms|time-complexity|optimization|discrete-mathematics|primes| |
null |
An even simpler method is to consider that:
- For the first few messages, both generals know to refrain.
- For the later messages, both generals know to attack.
- Between these two states, each general will get a message and move from the first state to the second.
But if communication is cut off when only one of... |
null |
Notice that you can restrict yourself to solutions such that $y_1 - y_n \le 1$ (otherwise you can iteratively move one unit from a term with value $y_1$ to a term with value $y_n$).
Suppose now that you choose to break the sum into $n$ terms (which might not be feasible).
Then the only such solution uses $y \bmod n... |
I have a large list of strings with associated values. I need to do a fast lookup into the list by the string prefix, but also by the string's ordinal within the list. For example,
string,value,ordinal
--------------------
alice, 10, 0
bob, 99, 1
carol, 32, 2
search_by_prefix("bo... |
Compressed string lookup by name or ordinal |
|finite-automata|data-compression|string-matching| |
null |
Consider Morton Encoding (https://en.wikipedia.org/wiki/Z-order_curve). It's pretty easy to implement, simpler than most two-dimensional indexes, and works pretty well.
What does "closest segment" mean? Are you just looking for the single segment endpoint closest to your target point? Or do both ends of the segment ... |
You have almost proved the language is not regular using Pumping Lemma,
In the last step where you pump up the string you get
$$xy^2z = xyyz=0^{p-1}001^{p+1}$$ $$=0^{p+1}1^{p+1}$$
which does not belong to the language L, this contradicts your assumption that the language is regular, So the Given language is no... |
Given a series `{an}` of length `n`, let `s(l, r)` be the difference between the largest and smallest numbers in the interval `[l, r]`.
Ask for the product of all `s(l, r)`.
The formula for the result would be $\displaystyle{{\prod_{l=1}^{n-1}}{\prod_{r=l+1}^n}s(l,r)}$.
For example, given `{1, 2, 4}` and `3`, th... |
I have a randomized recursive algorithm which expected running time is $T(n)$. In particular, the recursion looks like this: $$ T(n) \leq \mathcal cn + R ,$$ where $R$ is a recursive term that depends on $T(n-i)$ for some values of $i$, and $c$ is some constant. I want to add a procedure to this algorithm that samples ... |
Analysis of this randomized recursive algorithm |
|algorithm-analysis|recursion|randomized-algorithms|randomness| |
Given a sequence $a_1,\ldots,a_n$, we want to compute
$$\prod_{\ell=1}^{n-1} \prod_{r=\ell+1}^n (\max(a_\ell,\ldots,a_r) - \min(a_\ell,\ldots,a_r)).$$
For example, given $1, 2, 4$, the result should be $6$, which is $(2-1)\cdot (4-1)\cdot (4-2)$.
I know how to solve this in $O(n^2)$ by computing the inner produc... |
|algorithms|time-complexity| |
Product of all possible ranges in a sequence |
If the probability for resampling is $p(n)$, then the running time satisfies
$$
T(n) \leq Cn + R + p(n) \cdot d g(n).
$$ |
Expected runtime of recursive algorithm with optional part |
|algorithm-analysis|recursion|randomized-algorithms| |
A reasonable approach is to build two data structures, one optimized for prefix-based search and one optimized for ordinal-based lookup.
For prefix-based search, a [trie](https://en.wikipedia.org/wiki/Trie) is the natural data structure. It might not be very compressed, either, due to number of pointers it requires... |
Given is a prime signature $S$ and an integer $x$. The task is to count how many integers $n$ exist such that $n \leq x$, and if $n = p_1^{k_1}p_2^{k_2}p_3^{k_3}p_4^{k_4}...$ then $S = (k_1,k_2,k_3,...)$. Let $C(S,x)$ be that count.
For example, if $S = (3,1,1)$ and $x=1000$ then there are $21$ such integers, being ... |
You can use [this sheet][1]. It has a lot of handy formulas and some definitions.
You can also use [Wikipedia's list of mathematical symbols][2] propsed by Kyle Jones in comments.
There is also [Worfram MathWorld][3] which is a great resource, but you need to know what are you looking for.
When it comes to pri... |
null |
I have a large list of strings with associated values. I need to do a fast lookup into the list by the string prefix, but also by the string's ordinal within the list. For example,
string,value,ordinal
--------------------
alice, 10, 0
bob, 99, 1
carol, 32, 2
search_by_prefix("bo... |
What you have thought is not a bad start. However, more arguments are needed to establish the proposition.
------
Given $n$ items, we can insert all of them into the priority queue and then extract almost min $n$ times to obtain a list of all items. Unfortunately, the obtained list is not sorted unless the minimu... |
if we define halting problem as follows
$
\begin{align*}
h(m,n) &=
\begin{cases}
1 & if\;program\;m\;halts\;on\;input\;n \\
0 & otherwise \\
\end{cases}
\end{align*}
$
and we have a solution for $f$
$
\begin{align*}
f(m,n) &=
\begin{cases}
undefined & if\;m=n \\
... |
Can we solve the halting problem if we allow TM to print it's output and go into a loop? |
|turing-machines|halting-problem| |
null |
Let $P(X,Y)$ and $Q(X,Y)$ be two bivariate polynomials of degree at most $n$.
Using $O(n^2)$ FFTs, we can compute the product $PQ$ in time $O(n^3\log n)$.
**Q:** Is there a faster algorithm to compute $PQ$? |
Complexity of multiplying bivariate polynomials of degree n |
|polynomials|multiplication| |
Here is a complicated approach that might offer a modest improvement for values of $x$ of the size mentioned in your comment, when you want to compute $C(S,x)$ for many different $S$ and the same $x$:
----
Let me focus first on the case where $S$ has the form $S=(\cdots,1,1)$.
Let $f(u,v)$ be the number of int... |
It suffices to describe how to evaluate $P(\omega^u,\omega^v)$ at the roots of unity. Suppose $P(X,Y)=\sum_{i,j} a_{i,j} X^i Y^j$. Let
$$F_{b,c}(X,Y) = \sum_{i,j} a_{2i+b,2j+c} X^i Y^j$$
where the sum is over all $i,j$ with $i\le n/2, j \le n/2$. Then
$$P(X,Y) = F_{0,0}(X^2, Y^2) + Y F_{0,1}(X^2, Y^2) + X F... |
null |
According to the [computer organization and design RISC-V 2nd edition 2020](https://www.elsevier.com/books/computer-organization-and-design-risc-v-edition/patterson/978-0-12-820331-6), section 1.5, the following table states that ISA affects clock rate.
| Hardware or software component | Affects what? | How? |
|--... |
The affect of the ISA on clock rate and CPI is not simple. The amount of work needed to decode the instruction and perform the operation can vary among instructions. If more work (that can not be done in parallel) needs to be done to process an instruction, then either the pipeline must be made longer or the pipeline s... |
null |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.