
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
jupyter/nbgrader | jupyter | 1,060 | Link to course services for teachers/TA's in their Jupyterhub user-home. | I notice some teachers/TA's want a link in their users home to their service where the nbgrader course is managed. Instead they have to remember and write their path /services/{course-id}
I want them to be able to see their course either as a menu-list in the toolbar or under the Assignments tab.
In #1040 multip... | closed | 2019-01-07T23:33:11Z | 2019-06-01T12:00:37Z | https://github.com/jupyter/nbgrader/issues/1060 | [
"enhancement"
] | sigurdurb | 5 |
custom-components/pyscript | jupyter | 387 | Persons doesnt have device_trackers | In the home-assistant UI, you can set a list of device trackers on a person. Those seams to be, based on what I can find in https://github.com/home-assistant/core/blob/dev/homeassistant/components/person/__init__.py#L401-L414 not available normally.. But they are still there in the code refeered by `device_trackers` on... | closed | 2022-08-23T20:45:06Z | 2022-08-23T21:02:40Z | https://github.com/custom-components/pyscript/issues/387 | [] | xeor | 1 |
aimhubio/aim | tensorflow | 2,374 | UI hangon searching for runs | ## 🐛 Bug
<!-- A clear and concise description of what the bug is. -->
Unable to display runs or any kind of information from Aim running on a remote server.
The /runs page is stuck on "Searching over runs..." with "34 of 34 checked ------ 33 matched run(s)"
There's an error in the console log:
> encoder.... | closed | 2022-11-22T16:11:38Z | 2022-11-24T17:03:02Z | https://github.com/aimhubio/aim/issues/2374 | [
"type / bug",
"help wanted",
"phase / ready-to-go",
"area / Web-UI"
] | Natlem | 5 |
d2l-ai/d2l-en | data-science | 1,676 | Fomula 2.4.11 does not make sense | 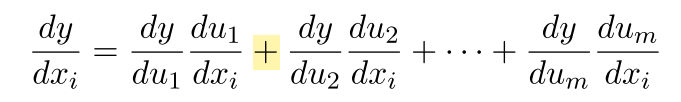
This formula is in the ["calculus" section](https://github.com/d2l-ai/d2l-en/blob/83ecc03a240f1e30dc36dd53083b1d5914391bcc/chapter_preliminaries/calculus.md) -> "Chain Rule". If we remove those $du_i$, it ... | closed | 2021-03-16T15:57:58Z | 2021-03-20T04:43:57Z | https://github.com/d2l-ai/d2l-en/issues/1676 | [] | Banyc | 2 |
ultralytics/ultralytics | deep-learning | 19,549 | YOLO11 segmentation mask post process problem | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
This is my yolo11 segmentation mask post process, but result is not good.
B... | closed | 2025-03-06T09:32:22Z | 2025-03-10T19:42:49Z | https://github.com/ultralytics/ultralytics/issues/19549 | [
"question",
"segment"
] | nomi30701 | 12 |
TracecatHQ/tracecat | pydantic | 931 | Cannot add JSONB value to lookup table via UI | Expected object got string.
<img width="1153" alt="Image" src="https://github.com/user-attachments/assets/a9379b63-57fb-447f-ad73-d2b108fbac89" /> | open | 2025-03-07T03:01:25Z | 2025-03-17T20:24:19Z | https://github.com/TracecatHQ/tracecat/issues/931 | [
"bug",
"good first issue"
] | topher-lo | 8 |
axnsan12/drf-yasg | rest-api | 581 | Enable sponsorship of the project | I am trying to live my values, and want to set up donating $30-$50/mo to the various tools that give me such a lucrative profession. I would like to give this project a couple bucks a month. Should sponsorship via github be enabled? Via Flattr? | open | 2020-04-22T20:54:57Z | 2025-03-07T12:13:58Z | https://github.com/axnsan12/drf-yasg/issues/581 | [
"triage"
] | bwarren2 | 0 |
holoviz/colorcet | plotly | 118 | remove pyct / param dependency | in #84 explicit `param` dependency was removed, but since `pyct` is still a dependency, which requires `param`, there is still a param reliance.
it seems that pyct is only being used for command-line use, so maybe it can be moved to optional dependencies | closed | 2024-01-11T15:36:44Z | 2024-03-15T13:53:46Z | https://github.com/holoviz/colorcet/issues/118 | [] | Jhsmit | 2 |
xinntao/Real-ESRGAN | pytorch | 552 | Video Super Resolution error | [concat @ 00000174645a62c0] No files to concat
results/input_vidlist.txt: Invalid data found when processing input
inference: 0sub_video [00:03, ?sub_video/s] | open | 2023-01-14T14:04:21Z | 2023-06-10T18:54:39Z | https://github.com/xinntao/Real-ESRGAN/issues/552 | [] | PrateekPal641 | 2 |
coqui-ai/TTS | pytorch | 3,807 | [Bug] Training XTTSv2 with DDP leads to weird training lags | ### Describe the bug
Hello, training XTTSv2 leads to weird training lags with using DDP - training gets stuck with no errors
x6 RTX a6000 and 512GB RAM
Here is monitoring GPU load graph. Purple - gpu0, green - gpu1 (all the rest GPUs behave like gpu1)
:
File "C:\ProgramData\Anaconda3\lib\site-packages\numpy\core\__init__.py", line 16, in <module>
from . import multiarray
ImportError: DLL load failed: 找不到指定的模块。
During handling of the above exception, another exception occurred:
Traceback (most recent call last):
File... | closed | 2021-11-18T13:59:45Z | 2022-04-03T04:02:02Z | https://github.com/babysor/MockingBird/issues/221 | [] | onesecplus6 | 2 |
jina-ai/serve | machine-learning | 5,487 | Invoke Flow like a pipeline | **Describe your proposal/problem**
<!-- A clear and concise description of what the proposal is. -->
I want to invoke jina api like a image pipeline.
Because the executor may cost too many time, I add a kafka producer at the end of flow to notify handle success
So I don't need the http response
**I wish that http ... | closed | 2022-12-05T10:34:46Z | 2022-12-07T14:45:34Z | https://github.com/jina-ai/serve/issues/5487 | [] | big-thousand | 23 |
graphql-python/graphene-django | django | 464 | Graphene Django is incompatible with django-filters 2.0.0 | When using graphene-django along with `django-filter` 2.0.0 I get an error trying to use the graphql endpoint.
A brief example:
```
class Query(object):
projects = DjangoFilterConnectionField(
MyProjectNode, filterset_class=MyProjectFilterSet)
```
This is the error:
```
`GrapheneMyProjectFilt... | closed | 2018-07-13T14:31:24Z | 2018-09-05T23:22:37Z | https://github.com/graphql-python/graphene-django/issues/464 | [] | synasius | 8 |
piskvorky/gensim | machine-learning | 2,710 | Distributed LDA Connection refused - Dispatcher host is always 127.0.0.1 | ## Problem description
I am trying to run the distributed LDA on multiple machines. Following this tutorial: https://radimrehurek.com/gensim/models/lda_worker.html
Setup is working but once I run the distributed lda I get the following error:
 and found no similar bug report.
### Ultralytics YOLO Component
Train
### Bug
My pc specs and software configuration is stated below!
**ISSUE:**
if train and val using default configura... | open | 2025-03-05T03:56:45Z | 2025-03-05T21:21:26Z | https://github.com/ultralytics/ultralytics/issues/19524 | [
"documentation"
] | mgi24 | 4 |
tensorflow/tensor2tensor | deep-learning | 980 | Bug - one little mistake in asr_transformer.ipynb | ### Description
There is an little mistake in asr_transformer.ipynb
In the 4th code block we can find:
def decode(integers):
integers = list(np.squeeze(integers))
if 1 in integers:
integets = integers[:integers.index(1)]
return encoders["targets"].decode(np.squeeze(integers))
where "**integets**... | closed | 2018-08-08T09:30:35Z | 2018-08-09T06:54:04Z | https://github.com/tensorflow/tensor2tensor/issues/980 | [] | Qiaoxl | 0 |
babysor/MockingBird | deep-learning | 130 | need at least one array to concatenate | 上传合成报错 need at least one array to concatenate | closed | 2021-10-09T11:01:03Z | 2021-10-16T08:55:38Z | https://github.com/babysor/MockingBird/issues/130 | [] | 07bug | 2 |
thunlp/OpenPrompt | nlp | 312 | ERROR: tokenizer_wrapper is None | I am getting this tokeniser
`---> [86](vscode-notebook-cell:?execution_count=2&line=86) probabilities, predicted_labels = predict_medical_concept_relevance(metadata)
[87](vscode-notebook-cell:?execution_count=2&line=87) print("Probabilities:", probabilities)
[88](vscode-notebook-cell:?execution_count=2&... | open | 2024-06-15T19:36:49Z | 2024-06-15T19:36:49Z | https://github.com/thunlp/OpenPrompt/issues/312 | [] | komi786 | 0 |
ARM-DOE/pyart | data-visualization | 1,403 | Unable to create fully transparent map in pyart | Hello,
I am trying to create a fully transparent map in pyart, however, none of the commands work to hide the image border, the division between states and the coastal division that is automatically plotted by pyart, as indicated by the red arrows on the map.
I'm attaching the code and hdf file of the radar I'm u... | closed | 2023-03-20T14:03:37Z | 2023-03-20T14:17:44Z | https://github.com/ARM-DOE/pyart/issues/1403 | [] | gabrielcassol | 0 |
blb-ventures/strawberry-django-plus | graphql | 80 | @gql.django.mutation passing `input_type` to StrawberryField | Tried to use `@gql.django.mutation` even though it is not documented anywhere - `DjangoMutationField` does not consume `input_type` argument and passes it to `StraweberryField` which does not have such init args.
```python
@gql.django.mutation(directives=[HasPerm("core.add_ep_server")])
def ep_server_create(self... | closed | 2022-07-13T10:12:01Z | 2022-07-16T14:42:38Z | https://github.com/blb-ventures/strawberry-django-plus/issues/80 | [] | ManiacMaxo | 2 |
globaleaks/globaleaks-whistleblowing-software | sqlalchemy | 4,055 | Upgrade info | ### Proposal
after updating via script the logos are:
-f install.log
Reading package lists...
Building dependency tree...
Reading state information...
globalaks is already the newest version (4.15.3).
The following packages were automatically installed and are no longer required:
libflashrom1 libftdi1-2
Use... | closed | 2024-04-22T15:32:24Z | 2024-04-22T15:39:12Z | https://github.com/globaleaks/globaleaks-whistleblowing-software/issues/4055 | [] | astar24e | 1 |
Anjok07/ultimatevocalremovergui | pytorch | 1,219 | error | Last Error Received:
Process: VR Architecture
If this error persists, please contact the developers with the error details.
Raw Error Details:
RuntimeError: "cuDNN error: CUDNN_STATUS_NOT_INITIALIZED"
Traceback Error: "
File "UVR.py", line 6638, in process_start
File "separate.py", line 1055, in sepe... | open | 2024-03-01T22:38:30Z | 2024-03-01T22:38:30Z | https://github.com/Anjok07/ultimatevocalremovergui/issues/1219 | [] | regularmilkyman | 0 |
huggingface/datasets | computer-vision | 6,488 | 429 Client Error | Hello, I was downloading the following dataset and after 20% of data was downloaded, I started getting error 429. It is not resolved since a few days. How should I resolve it?
Thanks
Dataset:
https://huggingface.co/datasets/cerebras/SlimPajama-627B
Error:
`requests.exceptions.HTTPError: 429 Client Error: Too M... | open | 2023-12-11T15:06:01Z | 2024-06-20T05:55:45Z | https://github.com/huggingface/datasets/issues/6488 | [] | sasaadi | 2 |
rthalley/dnspython | asyncio | 656 | update.add() doesn't work with nuitka compiler | Hello. This is my first issue description on Github.
I have sample code **update_test.py**:
```
import dns.query
import dns.update
SERVER_IP = "192.168.1.110"
def add(u):
u.add("google.com", 8600, "CNAME", ".")
def delete(u):
u.delete("google.com")
if __name__ == '__main__':
update ... | closed | 2021-04-05T20:26:22Z | 2021-04-06T20:56:25Z | https://github.com/rthalley/dnspython/issues/656 | [] | lukasfazik | 7 |
iperov/DeepFaceLab | machine-learning | 5,202 | Training XSeg doesn't continue, doesn't error. | ## Expected behavior
After going through extraction and basic XSeg editing, I'm trying to run the XSeg_train.bat.
The first iteration kicks off pretty fast.
Expected: Continue training after first step or throw an error.
## Actual behavior
Script hangs indefinitely (let it run for 12-14 hours) after output... | closed | 2020-12-17T16:49:18Z | 2023-04-12T12:44:38Z | https://github.com/iperov/DeepFaceLab/issues/5202 | [] | jarviscodes | 9 |
axnsan12/drf-yasg | django | 230 | Support for examples | Wondering if there's any plan for supporting examples in serializer Fields? This is pretty important if you intend people to use your API effectively, and can dramatically increase an API's ease of use.
An easy place to implement this would be by using the `initial` field.
I recognize that this is fairly straight... | open | 2018-10-15T21:20:40Z | 2025-03-07T12:16:42Z | https://github.com/axnsan12/drf-yasg/issues/230 | [
"triage"
] | agethecoolguy | 4 |
deezer/spleeter | tensorflow | 33 | [Feature] Provide SavedModels of pretrained models | Can you provide SavedModels of pretrained models (with the `saved_model.pb`file)? | closed | 2019-11-06T07:07:56Z | 2019-12-23T17:00:02Z | https://github.com/deezer/spleeter/issues/33 | [
"enhancement",
"feature"
] | JeffreyCA | 5 |
LibrePhotos/librephotos | django | 681 | Sort out the High CVE vulnerabilities? | **Describe the enhancement you'd like**
Possibly as a result of #680 there are a lot of components with vulnerabilities, a decent number of which are flagged as HIGH/CRITICAL and have fixes available. Incrementing the version on these would make for a more secure docker image
being installed.
**Describe why this ... | closed | 2022-11-21T17:24:46Z | 2023-01-02T11:04:59Z | https://github.com/LibrePhotos/librephotos/issues/681 | [
"enhancement"
] | techie2000 | 1 |
TheKevJames/coveralls-python | pytest | 132 | Add automatic release generation | from @TheKevJames
>Let's combine this with automatic release generation. As a reference, I do this for a personal project here: https://github.com/TheKevJames/jarvis/blob/master/circle.yml#L47 | closed | 2017-01-08T21:55:01Z | 2018-08-24T02:38:27Z | https://github.com/TheKevJames/coveralls-python/issues/132 | [] | goanpeca | 0 |
facebookresearch/fairseq | pytorch | 5,000 | don't mbart-large-50-many-to-many-mmt support translate chinese to Turkish?? |
#### Code
from transformers import MBartForConditionalGeneration, MBart50TokenizerFast
article_cn = "生活就像一块巧克力"
model = MBartForConditionalGeneration.from_pretrained("facebook/mbart-large-50-many-to-many-mmt")
tokenizer = MBart50TokenizerFast.from_pretrained("facebook/mbart-large-50-many-to-many-mmt")
... | open | 2023-03-01T03:56:36Z | 2023-03-01T03:57:10Z | https://github.com/facebookresearch/fairseq/issues/5000 | [
"question",
"needs triage"
] | graciechen | 0 |
neuml/txtai | nlp | 356 | SQLite JSON support not built into Python Windows builds < 3.9 | JSON1 support is built into Windows Python builds starting with 3.9 - see this commit: https://github.com/python/cpython/commit/58d6f2ee3aeb699156d4784acccd2910d27982e7
If errors regarding json_extract are encountered, upgrading to Python 3.9+ on Windows is the easiest solution. There are links on StackOverflow wher... | closed | 2022-10-10T12:11:13Z | 2022-10-11T12:07:00Z | https://github.com/neuml/txtai/issues/356 | [
"bug"
] | davidmezzetti | 1 |
strawberry-graphql/strawberry | django | 3,079 | Mypy crashes after updating pydantic to > 2.0 ver | Hello. I have updated pydantic to version > 2.0. After found problems with mypy
```
.\common\graphql\pagination.py:29: error: INTERNAL ERROR -- Please try using mypy master on GitHub:
https://mypy.readthedocs.io/en/stable/common_issues.html#using-a-development-mypy-build
If this issue continues with mypy master, ... | closed | 2023-09-07T06:02:29Z | 2025-03-20T15:56:21Z | https://github.com/strawberry-graphql/strawberry/issues/3079 | [
"bug"
] | barbarrista | 2 |
pallets-eco/flask-sqlalchemy | flask | 382 | create model error: AttributeError: Neither 'Column' object nor 'Comparator' object has an attribute 'Column' | **But the code do I delete lines 19-21 is completely correct.**
**Please help me, thank you**
## env:
**centos 6.4 x86**
**python 2.7.10**
libs:
```
Flask==0.10.1
Flask-SQLAlchemy==2.1
itsdangerous==0.24
Jinja2==2.8
MarkupSafe==0.23
MySQL-python==1.2.5
redis==2.10.5
SQLAlchemy==1.0.12
Werkzeug==0.11.4
wheel==0.24.0
`... | closed | 2016-03-08T06:43:15Z | 2020-12-05T21:31:04Z | https://github.com/pallets-eco/flask-sqlalchemy/issues/382 | [] | jos666 | 1 |
Urinx/WeixinBot | api | 79 | cant send msg into groups | cant send msg into groups
| open | 2016-08-19T07:30:23Z | 2016-08-19T07:30:23Z | https://github.com/Urinx/WeixinBot/issues/79 | [] | csrgxtu | 0 |
laughingman7743/PyAthena | sqlalchemy | 30 | query succeds with correct answer, but a botocore.errorfactory.InvalidRequestException error message is logged | #I am using PyAthena to query the recently released CommonCrawl parquet archives as described in
http://commoncrawl.org/2018/03/index-to-warc-files-and-urls-in-columnar-format/
I set up and tested my indes as described in the above article
I then test the same query as in the article using PyAthena:
``` python... | closed | 2018-03-27T05:06:44Z | 2018-04-04T08:33:22Z | https://github.com/laughingman7743/PyAthena/issues/30 | [] | mhlr | 4 |
marshmallow-code/marshmallow-sqlalchemy | sqlalchemy | 626 | Q. `Pluck` fields not serializing in nested relationship | I got an issue where `Pluck` fields are not serializing correctly in a nested relationship.
This is an example related with my question:
I found `screw_size` and `screw_total` are serializing correctly, but `test_screw_size` and `test_screw_total` (which use Pluck) are not being included in the serialized output.
... | closed | 2025-01-03T07:23:23Z | 2025-01-12T05:54:02Z | https://github.com/marshmallow-code/marshmallow-sqlalchemy/issues/626 | [
"question"
] | noeunkim | 2 |
aiortc/aiortc | asyncio | 511 | Video stream missing frames | Hello, I am trying to send images from the server, and then receive & access each frame from the client side.
I am using modified code from your examples `server` and `videostream-cli`.
However I seem to be missing several frames.
My code is as below:
server: As the examples instructed, I am generating videos and... | closed | 2021-03-18T03:00:02Z | 2021-03-19T06:18:40Z | https://github.com/aiortc/aiortc/issues/511 | [
"invalid"
] | wildcat5566 | 5 |
google-deepmind/graph_nets | tensorflow | 132 | "exclude_self_edges" in "broadcast_sender_nodes_to_edges" and "SentEdgesToNodesAggregator" etc | Hello,
I am currently working on a model to process Documents as graphs.
The idea is to use the resulting node embeddings from the graph convolution as a sequence on wich I can perform sequence labeling to extract certain labels.
Maybe I have an overcomplicated approach, so feel free to question it :)
But since I w... | closed | 2020-12-15T10:46:17Z | 2020-12-15T21:11:01Z | https://github.com/google-deepmind/graph_nets/issues/132 | [] | Pol-Zeimet | 4 |
InstaPy/InstaPy | automation | 5,904 | Traceback (most recent call last): | C:\Users\alper\PycharmProjects\instabot\venv\Scripts\python.exe C:/Users/alper/PycharmProjects/instabot/main.py
InstaPy Version: 0.6.11
._. ._. ._. ._. ._. ._. ._. ._. ._.
Workspace in use: "C:/Users/alper/InstaPy"
Traceback (most recent call last):
File "C:/Users/alper/PycharmProjects/instabot/main.py... | closed | 2020-11-16T11:16:32Z | 2020-12-02T00:19:37Z | https://github.com/InstaPy/InstaPy/issues/5904 | [
"question"
] | alperglcoglu | 5 |
learning-at-home/hivemind | asyncio | 34 | Move dummy Server to a separate process in tests | Currently for testing purposes we create hivemind.Server in a background thread for each test. It seems that CUDA initialization happens somewhere in this thread, so we can't have two tests using server communication in a single file (otherwise we have CUDA initialization error).
A better testing strategy would be ... | closed | 2020-04-08T08:32:41Z | 2020-06-28T14:29:10Z | https://github.com/learning-at-home/hivemind/issues/34 | [
"bug"
] | mryab | 1 |
glumpy/glumpy | numpy | 129 | What caused err 1281? | Hi,
Thanks for reading and happy new year!
I am trying to use glumpy in one of my layer in my network,
and I may have several instances of this layer in the network.
And I always get the message says when I implementing this layer and have to write it in an ugly way:
```
GLError: GLError(
err = 1281,
d... | closed | 2017-12-27T16:28:35Z | 2019-12-27T08:53:35Z | https://github.com/glumpy/glumpy/issues/129 | [] | liyi14 | 7 |
axnsan12/drf-yasg | django | 255 | Duplicated model-names results in duplication of api-documentation | I have a django project which includes multiple applications and in some of those, there are models which have the same name as in other applications, e.g.
- /catalog/**product** and /procurement/**product**
- /catalog/**category** and /procurement/**category**
When accessing the API end-points directly, I do get... | closed | 2018-11-22T10:58:56Z | 2018-11-23T07:34:02Z | https://github.com/axnsan12/drf-yasg/issues/255 | [] | tobiasgardner | 2 |
dynaconf/dynaconf | django | 867 | RecursionError: maximum recursion depth exceeded | **Describe the bug**
Unintended Dynaconf behavior when explicitly setting `lowercase_read=False` and defining `SECRET_KEY` for a Django project.
**To Reproduce**
Steps to reproduce the behavior:
```
# project structure
.
├── manage.py
├── poetry.lock
├── pyproject.toml
├── settings.toml
└── src
├── ... | closed | 2023-02-14T11:58:02Z | 2023-07-13T19:11:07Z | https://github.com/dynaconf/dynaconf/issues/867 | [
"bug"
] | mohsen-eng74 | 1 |
hyperspy/hyperspy | data-visualization | 2,598 | Ambiguity in docs about ORPCA and RPCA | From the docs:
> Finally, online RPCA includes two alternatives methods
But then the code examples use RPCA, and not ORPCA:
```python
> s.decomposition(algorithm="RPCA",
> output_dimension=3,
> method="SGD",
> subspace_learning_rate=1.1)
```
Do the SGD method... | closed | 2020-12-10T10:07:15Z | 2021-04-20T22:56:39Z | https://github.com/hyperspy/hyperspy/issues/2598 | [
"type: bug",
"affects: documentation",
"good first PR"
] | thomasaarholt | 2 |
chatopera/Synonyms | nlp | 97 | 请问相似度平滑的原理是什么? | 我测试了下,添加相似度平滑的函数后,召回率反而降低了。 | open | 2019-11-29T02:01:29Z | 2021-03-10T09:37:20Z | https://github.com/chatopera/Synonyms/issues/97 | [] | hongshengxin | 1 |
holoviz/panel | plotly | 7,465 | Cell Focus Resets on TAB Press in Tabulator When Styles Are Active | <!--
Thanks for contacting us! Please read and follow these instructions carefully, then you can delete this introductory text. Note that the issue tracker is NOT the place for usage questions and technical assistance; post those at [Discourse](https://discourse.holoviz.org) instead. Issues without the required informa... | open | 2024-11-06T07:28:08Z | 2024-11-06T07:28:08Z | https://github.com/holoviz/panel/issues/7465 | [] | krishanunayak | 0 |
keras-team/autokeras | tensorflow | 847 | AutoKeras 1.0 still much slower than 0.4 on Google Colab | I reported this problem before as issue #834. This issue was closed 3 days ago, however I just tested it and the problem doesn't seem to be solved. Because I cannot reopen my old issue I open a new one. To reproduce the problem see the code in #834.
As a side note: doesn't Github send notifications when an issue is ... | closed | 2019-12-02T09:04:19Z | 2019-12-04T23:32:04Z | https://github.com/keras-team/autokeras/issues/847 | [] | m-pescador | 1 |
adamerose/PandasGUI | pandas | 100 | Plugin support | As user base grows, features will be needed for domain specific applications. Some might clutter the interface, while other features might require many external dependencies. In order to not try to be jack of all trades and also reduce the support burden on pandasgui itself, a `plugin architecture` would provide a way ... | closed | 2021-02-18T18:23:27Z | 2021-06-16T08:17:43Z | https://github.com/adamerose/PandasGUI/issues/100 | [
"enhancement"
] | fdion | 1 |
ckan/ckan | api | 8,201 | The CSRF token is not correctly applied in the Bootstrap 3 'Add Collaborator' page | ## CKAN version
CKAN 2.10.X
## Describe the bug
The misplaced CSRF token leads to the `400 Bad Request The CSRF token is missing.` error in the Bootstrap 3 'Add Collaborator' page.
### Steps to reproduce
Navigate to `/dataset/collaborators/<dataset_name>/new` and add a user as a collaborator.
### Expe... | open | 2024-04-29T03:13:26Z | 2024-04-30T15:58:37Z | https://github.com/ckan/ckan/issues/8201 | [] | u10313335 | 2 |
psf/requests | python | 6,531 | How can I translate a page to English when scraping with requests python | I'm trying to scrape the site [roca](https://roca.com.br/imovel/locacao/casas/sao-carlos/jardim-sao-carlos/66857?hl=en). This page is in Portuguese language, but I want to have translated into English so that I can capture English content when scraping with requests.
I have tried doing the below option of using Acce... | closed | 2023-09-17T06:55:39Z | 2024-09-17T00:03:35Z | https://github.com/psf/requests/issues/6531 | [] | Kamal-Moha | 1 |
deeppavlov/DeepPavlov | tensorflow | 1,371 | File Share: Versioning for Models | # Problems
* We don't know what each particular file is for (because of lack of naming conventions & controlled versioning)
* Lack of access control
# Requirements
* files should be controlled by versions
* file names should conform to naming conventions
* access control should be enforced
* S3 API support
... | closed | 2021-01-12T11:19:53Z | 2021-03-15T14:26:32Z | https://github.com/deeppavlov/DeepPavlov/issues/1371 | [] | danielkornev | 6 |
pytest-dev/pytest-django | pytest | 1,136 | How to change environment variable before django settings will be initialized? | I try to use this, but in fact settings var that was initialized in docker container doesn't change.
conftest.py
```
@pytest.hookimpl(tryfirst=True)
def pytest_load_initial_conftests(early_config, parser, args):
os.environ["CH_BASE_OF_URL"] = 'https://api.cowho.com'
```
settings.py
```
CH_BASE_URL = os... | open | 2024-08-30T18:37:21Z | 2025-01-07T13:09:03Z | https://github.com/pytest-dev/pytest-django/issues/1136 | [] | mihalt | 2 |
paperless-ngx/paperless-ngx | django | 9,465 | [BUG] Latest Docker Container does not start and fails to connect to redis | ### Description
Creation of Paperless docker container "paperlessngx/paperless-ngx" cannot start in portainer.io on my ASUSTOR. It seams that Redis is missing in the container. The logfiles says:
Paperless-ngx docker container starting...
Creating directory /usr/src/paperless/data/index
mkdir: created directory '/usr... | closed | 2025-03-23T10:33:53Z | 2025-03-23T12:14:48Z | https://github.com/paperless-ngx/paperless-ngx/issues/9465 | [
"not a bug"
] | Sharqbyte | 1 |
WeblateOrg/weblate | django | 14,105 | Strings containing only punctuation or symbols used as glossary terms are not highlighted in the source field if they are at the beginning of a source word | ### Describe the issue
Some strings containing only (perhaps consecutive?) punctuation or symbols used as glossary terms are not highlighted in the source field if they are at the beginning of a source word, but are highlighted at the end of a source word.
I am not sure if this is really necessary. But some users do ... | open | 2025-03-04T16:08:31Z | 2025-03-17T13:44:27Z | https://github.com/WeblateOrg/weblate/issues/14105 | [
"enhancement",
"undecided",
"Area: UX"
] | Geeyun-JY3 | 2 |
babysor/MockingBird | deep-learning | 466 | 算我求各位的了别用那狗💩百度云了 | 传个其它网盘不香吗?干嘛非得用这狗💩百度云呢?
我现在看到百度云盘图标我就犯恶心
巨恶心的那种
非得用网盘那也有一堆可代替的
[天翼云盘](https://cloud.189.cn)也稳
[蓝奏云](https://www.lanzou.com/)也好用得一比
| closed | 2022-03-20T13:57:04Z | 2022-10-30T17:29:53Z | https://github.com/babysor/MockingBird/issues/466 | [] | Shaun-Fong | 6 |
mckinsey/vizro | pydantic | 194 | Convert warnings into errors in tests | Currently our tests show any deprecation warnings raised during running but these are easy to miss and I expect everyone ignores them (I do anyway). Let's get stricter about this so (a) we don't miss future deprecations in our dependencies that could break us and (b) our users aren't bothered by deprecation warnings.
... | closed | 2023-12-06T10:07:28Z | 2023-12-14T11:51:12Z | https://github.com/mckinsey/vizro/issues/194 | [] | antonymilne | 0 |
keras-team/keras | pytorch | 20,809 | Tensorboard not working with Trainer Pattern | I'm using the Keras Trainer pattern as illustrated [here](https://keras.io/examples/keras_recipes/trainer_pattern/). The issue when using this pattern is that when you use Tensorboard only the top level weights are being recorded.
The reason for this is that `Tensorboard` is recording the weights for the all the laye... | open | 2025-01-24T09:58:16Z | 2025-02-27T17:18:14Z | https://github.com/keras-team/keras/issues/20809 | [
"stat:awaiting keras-eng",
"type:Bug"
] | GeraudK | 7 |
Kanaries/pygwalker | pandas | 639 | [BUG] pygwalker seems to cache columns is streamlit when used with multiple dataframes | **Describe the bug**
When trying to use pygwalker with streamlit and changing the dataframes feeded to the same pygwalker instance, it seems that some data of the old dataframes still lingers in pygwalker's memory. For example if I have dataframe 1 with columns [A, B, C] and dataframe 2 with columns [D, E, F] and firs... | closed | 2024-10-09T09:51:06Z | 2024-10-10T12:32:46Z | https://github.com/Kanaries/pygwalker/issues/639 | [
"bug"
] | nixetheus | 5 |
PokeAPI/pokeapi | graphql | 347 | Documentation API endpoints missing trailing forward slash | #### api/v2/pokemon/{id or name} should be api/v2/pokemon/{id or name}/
Some HTTP client doesn't follow redirect by default so this could potentially cause issues? And it's probably better if the user requests the correct endpoints in the first place instead of following redirects | closed | 2018-08-29T03:24:45Z | 2018-09-22T03:02:17Z | https://github.com/PokeAPI/pokeapi/issues/347 | [] | tien | 2 |
JaidedAI/EasyOCR | machine-learning | 890 | Wrong English wording recognizing G -> 6 | <img width="94" alt="image" src="https://user-images.githubusercontent.com/25415402/203794052-99e4abb7-a0b3-4a1e-b368-330cb954bca6.png">
When run a page recognizing job, 120852G will be recognized as ... | open | 2022-11-24T13:21:51Z | 2022-12-01T03:21:19Z | https://github.com/JaidedAI/EasyOCR/issues/890 | [] | CapitaineNemo | 1 |
JoeanAmier/TikTokDownloader | api | 5 | 我想获取某个作者首页的所有视频列表要怎么做? | 比如:https://www.douyin.com/user/MS4wLjABAAAAPCnTQLqza4Xqu-uO7KZHcKuILkO7RRz2oapyOC04AQ0
她的抖音个人首页大概有一二十个视频,我能通过接口一次性获取或者分批拿到这些视频列表吗?我只要视频列表即可~

| closed | 2023-06-21T08:25:20Z | 2023-06-22T08:26:37Z | https://github.com/JoeanAmier/TikTokDownloader/issues/5 | [] | 2424004764 | 3 |
hankcs/HanLP | nlp | 1,341 | 添加分析字典时,词频输入项应如何理解并实际应用 | <!--
注意事项和版本号必填,否则不回复。若希望尽快得到回复,请按模板认真填写,谢谢合作。
-->
## 注意事项
请确认下列注意事项:
* 我已仔细阅读下列文档,都没有找到答案:
- [首页文档](https://github.com/hankcs/HanLP)
- [wiki](https://github.com/hankcs/HanLP/wiki)
- [常见问题](https://github.com/hankcs/HanLP/wiki/FAQ)
* 我已经通过[Google](https://www.google.com/#newwindow=1&q=HanLP)和[issue区检... | closed | 2019-12-06T02:46:59Z | 2020-01-01T10:48:03Z | https://github.com/hankcs/HanLP/issues/1341 | [
"ignored"
] | sxgkwei | 4 |
PokeAPI/pokeapi | api | 1,226 | 403 forbidden on https://pokeapi.co/api/v2/move/{id} | I'm experiencing a strange behavior on the `move/{id}` calls. Out of nowhere the call to get `grass-pledge` (https://pokeapi.co/api/v2/move/grass-pledge) stopped working, returning `403`. I noticed that it would do the same by using the id (https://pokeapi.co/api/v2/move/520). It would only work by adding a trailing sl... | closed | 2025-03-21T18:47:40Z | 2025-03-21T22:33:09Z | https://github.com/PokeAPI/pokeapi/issues/1226 | [] | s-pozzebon | 2 |
tflearn/tflearn | tensorflow | 723 | how to retrain my own image classifier using Alexnet model? | I use alexnet to train my own image classifier, the image structure is like this:
ROOT_FOLDER -> SUBFOLDER_0 (CLASS 0) -> CLASS0_IMG1.jpg
-> CLASS0_IMG2.jpg -> ...
-> SUBFOLDER_1 (CLASS 1) -> CLASS1_IMG1.jpg -> ...
-> ...
and the labels are the subfolders' name. I just want to i... | open | 2017-04-23T10:39:58Z | 2018-05-31T09:00:46Z | https://github.com/tflearn/tflearn/issues/723 | [] | willduan | 3 |
paperless-ngx/paperless-ngx | machine-learning | 7,554 | [BUG] Merging PDF + PNG omits PNG | ### Description
When attempting to merge a PDF-based document with another document that resulted from a PNG upload the merge process finishes without reporting any obvious error, but the resulting "merged" PDF is missing the page from the PNG-based document. No error is visible from the web frontend.
Working aroun... | closed | 2024-08-27T08:57:28Z | 2024-09-27T03:08:17Z | https://github.com/paperless-ngx/paperless-ngx/issues/7554 | [
"not a bug"
] | ginkel | 3 |
huggingface/datasets | deep-learning | 6,553 | Cannot import name 'load_dataset' from .... module ‘datasets’ | ### Describe the bug
use python -m pip install datasets to install
### Steps to reproduce the bug
from datasets import load_dataset
### Expected behavior
it doesn't work
### Environment info
datasets version==2.15.0
python == 3.10.12
linux version I don't know?? | closed | 2024-01-03T08:18:21Z | 2024-02-21T00:38:24Z | https://github.com/huggingface/datasets/issues/6553 | [] | ciaoyizhen | 2 |
wkentaro/labelme | computer-vision | 689 | [BUG] How to drag/edit the rectangle? | **Describe the bug**
I change the order in the Polygon Labels Dialog since I want to drag the small rectangle, but the original rectangle is still there (which should be removed), so there are two identical rectangles on the image.
**Screenshots**
 register_forward_hook [NestedUserFunctionVariable()] {} | ### 🐛 Describe the bug
AOTI compiling and exporting https://github.com/cvlab-kaist/Chrono I had this issue in the log related to `register_forward_hook`
### Error logs
[error.log](https://github.com/user-attachments/files/19212384/error.log)
### Versions
2.6.0 and nightly
cc @chauhang @penguinwu @voznesenskym @E... | open | 2025-03-12T15:00:41Z | 2025-03-19T01:18:07Z | https://github.com/pytorch/pytorch/issues/149047 | [
"triaged",
"oncall: pt2",
"module: dynamo"
] | bhack | 4 |
ranaroussi/yfinance | pandas | 1,847 | Missing option chain data | ### Describe bug
Missing actual option chain data.
### Simple code that reproduces your problem
``` python
import yfinance as yf
msft = yf.Ticker("MSFT")
opt = msft.options
print(opt)
opt = msft.option_chain('2024-12-20')
print(opt)
```
### Debug log
```
Traceback (most recent call last):
..... | closed | 2024-02-01T21:16:19Z | 2024-06-09T15:03:56Z | https://github.com/ranaroussi/yfinance/issues/1847 | [] | bigiman | 16 |
flaskbb/flaskbb | flask | 543 | flaskbb.cfg ignored on some circumstances | In case of using uwsgi FlaskBB does ignored flaskbb.cfg silentently, which may end up in a (security) nightmare.
Assuming following flaskbb.ini and installation of FlaskBB with venv.
```
[uwsgi]
base = /home/flaskbb
venv = /home/flaskbb/.venv
pythonpath = %(base)
socket = 127.0.0.1:30002
module = wsgi
callab... | closed | 2019-11-24T13:17:43Z | 2021-09-17T17:47:10Z | https://github.com/flaskbb/flaskbb/issues/543 | [] | ip6li | 6 |
horovod/horovod | tensorflow | 3,602 | Support custom data loaders in KerasEstimator | Currently, the Spark integration for PyTorchLightning [TorchEstimator supports customizable data_modules](https://github.com/horovod/horovod/blob/9d56c5a6d55e9619e100d19480a11952d116f4b3/horovod/spark/lightning/estimator.py#L109-L110), but the [RemoteTrainer for the KerasEstimator is hard-coded to use petastorm](https:... | closed | 2022-07-13T23:04:33Z | 2022-09-01T04:00:09Z | https://github.com/horovod/horovod/issues/3602 | [
"enhancement"
] | leewyang | 0 |
errbotio/errbot | automation | 1,636 | Can't Install Errbot in Virtual Environment because of `dulwich` installation issue | **Describe the bug**
I am unable to install errbot in a python 3.9 virtual environment. I get the following output:
```bash
Building wheels for collected packages: dulwich
Building wheel for dulwich (setup.py) ... error
error: subprocess-exited-with-error
× python setup.py bdist_wheel did not run succ... | closed | 2023-03-28T14:47:02Z | 2023-03-28T15:53:29Z | https://github.com/errbotio/errbot/issues/1636 | [
"type: bug"
] | areed1192 | 4 |
apache/airflow | python | 47,297 | BigQuery traceability labels were not available while using TaskGroup | ### Apache Airflow Provider(s)
google
### Versions of Apache Airflow Providers
apache-airflow-providers-google==12.0.0
### Apache Airflow version
2.9.3
### Operating System
Ubuntu
### Deployment
Virtualenv installation
### Deployment details
_No response_
### What happened
BigQueryInsertJobOperator set tra... | closed | 2025-03-03T10:36:40Z | 2025-03-14T20:35:09Z | https://github.com/apache/airflow/issues/47297 | [
"kind:bug",
"provider:google",
"area:providers",
"good first issue"
] | jacgeo | 9 |
seleniumbase/SeleniumBase | web-scraping | 2,164 | Colorama refactoring for Windows users | ## Colorama refactoring for Windows users
Windows users may experience performance degradation if `colorama.init(autoreset=True)` gets called multiple times.
To get around this, SeleniumBase should instead call `colorama.just_fix_windows_console()` (Added in https://github.com/tartley/colorama/pull/352).
`colo... | closed | 2023-10-06T19:17:00Z | 2023-10-06T21:41:15Z | https://github.com/seleniumbase/SeleniumBase/issues/2164 | [
"enhancement"
] | mdmintz | 1 |
scikit-optimize/scikit-optimize | scikit-learn | 1,195 | Question: How to initialize a model in 4D search space, but run trials in only 2D for the first 100 trials through ask-tell interface. Then expand to 4D. | Use case: quickly search the 2D space and evaluate ability to minimize a loss function while holding 2 of the variables constant. After finding the Pareto front of 2D space, allow the model to search full space to see if a better point exists.
How would I do this? I am running batched ask-tell with checkpointing of... | open | 2023-11-30T23:34:36Z | 2023-11-30T23:34:36Z | https://github.com/scikit-optimize/scikit-optimize/issues/1195 | [] | GregorySchwing | 0 |
xinntao/Real-ESRGAN | pytorch | 70 | Single GPU training | How do I use a single GPU for training? I delete the distributed code during training and still report an error | open | 2021-09-05T10:44:10Z | 2021-09-07T02:46:06Z | https://github.com/xinntao/Real-ESRGAN/issues/70 | [] | victor-szf | 1 |
hbldh/bleak | asyncio | 1,380 | Pairing Issues w/ the BlueZ Backend | * bleak version: 0.20.0, 0.21.0a1 (latest dev)
* Python version: 3.10.6
* Operating System: Ubuntu 22.04 (kernel v5.19)
* BlueZ version (`bluetoothctl -v`) in case of Linux: 5.64
### Description
Unable to pair Bose LE Sport Earbuds w/ the bleak client. Have no issues connecting or reading characteristics w/ th... | open | 2023-07-27T16:42:44Z | 2023-10-16T14:36:39Z | https://github.com/hbldh/bleak/issues/1380 | [] | hosse005 | 2 |
deepspeedai/DeepSpeed | pytorch | 6,837 | nv-nightly CI test failure | The Nightly CI for https://github.com/microsoft/DeepSpeed/actions/runs/12267136529 failed.
| closed | 2024-12-08T00:28:48Z | 2024-12-11T18:36:40Z | https://github.com/deepspeedai/DeepSpeed/issues/6837 | [
"ci-failure"
] | github-actions[bot] | 0 |
amdegroot/ssd.pytorch | computer-vision | 217 | what is the job of detections.pkl? | open | 2018-08-14T02:55:28Z | 2018-08-14T02:55:28Z | https://github.com/amdegroot/ssd.pytorch/issues/217 | [] | isalirezag | 0 | |
jupyter/nbviewer | jupyter | 491 | LaTeX rendering badly in Windows 10 via Edge & Firefox, on github rendered notebooks only | I cannot reproduce this personally.
A user of my notebooks reports that if he uses nbviewer to view my notebooks in Windows 10 using either the Edge or firefox browsers all of the latex equations render incorrectly (screen capture attached). Chrome renders it accurately. This only started happening recently - of cours... | closed | 2015-08-26T16:16:59Z | 2018-07-16T01:51:09Z | https://github.com/jupyter/nbviewer/issues/491 | [
"type:Bug",
"tag:GitHub",
"status:Inactive"
] | rlabbe | 13 |
recommenders-team/recommenders | machine-learning | 2,131 | [ASK] The Training using a GPU is very slow for NCF model | I've set up an virtual environment based on the following commands:
!conda install -c conda-forge cudatoolkit=11.2 cudnn=8.1
!pip install recommenders[gpu]
Moreover I've added the following commands in the code:
tf.debugging.set_log_device_placement(True)
gpus = tf.config.experimental.list_physical_devices('GP... | closed | 2024-07-15T12:39:44Z | 2024-12-27T06:30:10Z | https://github.com/recommenders-team/recommenders/issues/2131 | [
"help wanted"
] | orrimoch | 1 |
chrieke/prettymapp | streamlit | 21 | Addresses | When I enter an address and submit, it runs for a few seconds and nothing happens | closed | 2022-12-13T09:14:31Z | 2022-12-18T19:28:28Z | https://github.com/chrieke/prettymapp/issues/21 | [] | PhilipViljoen | 1 |
blb-ventures/strawberry-django-plus | graphql | 143 | Optimizier omits slicing of connection query set | I have been trying to figure out why some of my queries are painfully slow. This happens when I traverse a reverse foreign key relation through django related managers.
In my query I limit the number of instances `LeafModel` to be fetched to a small number (e.g. one) because the list might be huge. The query return... | closed | 2022-11-19T10:47:17Z | 2023-06-15T21:35:31Z | https://github.com/blb-ventures/strawberry-django-plus/issues/143 | [
"enhancement"
] | oleo65 | 2 |
keras-team/keras | pytorch | 20,039 | Keras distributed fine tuning - TypeError: ModelParallel | I am trying to fine tune gemma 2 using model parallelism on TPU. Reference notebook - https://colab.research.google.com/drive/1bEivD7tSwbFMtPbNEcZxilZvN_dGzgbU?usp=sharing
I am getting the below error when I trying to configure ModelParallel on Keras distribution.
`model_parallel = keras.distribution.ModelParalle... | closed | 2024-07-24T13:11:16Z | 2024-07-26T17:36:15Z | https://github.com/keras-team/keras/issues/20039 | [
"stat:awaiting response from contributor",
"Gemma"
] | ranasaurus9 | 2 |
strawberry-graphql/strawberry | fastapi | 3,608 | Support of Geometry Scalars | <!--- Provide a general summary of the changes you want in the title above. -->
The Strawberry Django integration provides geometry scalars such as `Polygon`, `Point`, etc (https://github.com/strawberry-graphql/strawberry-django/blob/main/strawberry_django/fields/types.py#L339). Are there any plans to implement these ... | closed | 2024-08-30T09:07:13Z | 2025-03-20T15:56:50Z | https://github.com/strawberry-graphql/strawberry/issues/3608 | [] | tokr-bit | 2 |
plotly/dash | dash | 2,329 | Allow currency format for dcc.Input of type='number' | **Describe the solution you'd like**
Allow currency format for dcc.Input while keeping the value type as number and the arrows to increase/decrease it.
**Describe alternatives you've considered**
Clientside circular callback that updates the value format based on [this JS solution](https://stackoverflow.com/questi... | open | 2022-11-21T14:46:30Z | 2024-08-13T19:22:53Z | https://github.com/plotly/dash/issues/2329 | [
"feature",
"P3"
] | celia-lm | 0 |
clovaai/donut | computer-vision | 18 | Are "valid_line" and "meta" keys required for training? | I noticed in the cordv2 dataset there is "valid_line", "meta", and other keys in the jsonl dictionary.
Are these used/required during training for document parsing, or are they ignored by the system as it is not strictly gt_parse? | closed | 2022-08-10T06:46:55Z | 2022-08-10T06:54:44Z | https://github.com/clovaai/donut/issues/18 | [] | finnthedawg | 1 |
chatanywhere/GPT_API_free | api | 70 | 购买了api如何查询剩余额度 | 如题,在商城没有看到有关说明 | closed | 2023-07-27T16:20:01Z | 2024-01-10T11:26:00Z | https://github.com/chatanywhere/GPT_API_free/issues/70 | [] | yj920 | 2 |
google-research/bert | tensorflow | 1,038 | BERT throws error with batch size = 1. | I am trying to use BERT to classify entire documents (12000 tokens). I decided to tackle this by using BERT as a sentence encoder and pass each encoded sentence to a CNN. Is this a good approach?
I get the below error when I set a batch of 1. It seems bert is batch sensitive. Is this the case?
Please advise.
Thank ... | open | 2020-03-22T18:09:45Z | 2020-03-22T18:09:45Z | https://github.com/google-research/bert/issues/1038 | [] | nectario | 0 |
piccolo-orm/piccolo | fastapi | 707 | Piccolo doesn't handle duplicate entries automatically for in .add_m2m | ### Discussed in https://github.com/piccolo-orm/piccolo/discussions/683
<div type='discussions-op-text'>
<sup>Originally posted by **Drapersniper** November 21, 2022</sup>
```py
class Track(Table):
track_id = BigInt(primary_key=True)
class Playlist(Table):
id = BigInt(primary_key=True)
track... | open | 2022-12-05T11:36:24Z | 2023-05-03T15:55:34Z | https://github.com/piccolo-orm/piccolo/issues/707 | [] | Drapersniper | 7 |
eralchemy/eralchemy | sqlalchemy | 49 | 1.2.5 AttributeError: 'Namespace' object has no attribute 'x' | With 1.2.5
```
bash-3.2$ eralchemy -v
Traceback (most recent call last):
File "/usr/local/bin/eralchemy", line 11, in <module>
load_entry_point('ERAlchemy==1.2.5', 'console_scripts', 'eralchemy')()
File "/usr/local/Cellar/eralchemy/1.2.5/libexec/lib/python2.7/site-packages/eralchemy/main.py", line 37, in ... | closed | 2018-02-25T05:21:30Z | 2018-02-25T09:26:56Z | https://github.com/eralchemy/eralchemy/issues/49 | [] | ilovezfs | 2 |
aiortc/aiortc | asyncio | 842 | New release | Hello!
Would be lovely with a new release that contains the `aioice` bump to 0.8.0 for TURN over TCP fix. It's already on main, so just a tag and publish to PyPI is needed.
Thanks, Erik | closed | 2023-03-30T07:54:02Z | 2023-04-01T18:15:24Z | https://github.com/aiortc/aiortc/issues/842 | [] | eerimoq | 2 |
explosion/spaCy | nlp | 12,411 | Displacy visualiser only sometimes shows labels | In many cases, I do not see the label at the beginning of a span in displacy. This should not be an issue with a particular label since I sometimes see it when using different text examples.
Is there something I should look out for to avoid this?
```
colors = {#omitted in this example}
options = {"spans_key": ... | open | 2023-03-13T21:15:01Z | 2023-04-20T14:14:12Z | https://github.com/explosion/spaCy/issues/12411 | [
"feat / visualizers"
] | goonhoon | 8 |
pydata/xarray | numpy | 9,987 | Improved docs for zarr encoding options. | ### What is your issue?
Hi
I'm been trying to set zarr encoding options from xarray. (zarr3)
Figuring out how to do this isn't straightforward. It wasn't too hard to get this working for most zarr compressors, but getting it working for array-to-bytes codecs - ZFPY and PCodec was rather harder. (the 2 ArrayBytesCo... | open | 2025-01-26T14:54:38Z | 2025-03-03T03:17:04Z | https://github.com/pydata/xarray/issues/9987 | [
"topic-documentation",
"topic-zarr"
] | benritchie | 8 |
junyanz/pytorch-CycleGAN-and-pix2pix | computer-vision | 1,587 | Pix2pix segmentation soft labels (expected hard labels) | Hi!
I am trying to use pix2pix model for an image translation task from a 3 channel input to a 1 channel semantic segmentation mask. I trained the model and tested it on a test set.
I have provided hard label ground truth segmentations (as real_B).
Still, in the results folder, the real_B image (and the fake_B i... | closed | 2023-07-10T10:12:30Z | 2023-07-12T12:46:58Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/1587 | [] | MihaelaCroitor | 1 |
cleanlab/cleanlab | data-science | 512 | Reduce warnings from unit tests | Unit tests currently produce these warnings, which we should get rid of.
```
=============================== warnings summary ===============================
tests/test_filter_count.py::test_confidence_thresholds_multilabel
/home/runner/work/cleanlab/cleanlab/cleanlab/internal/validation.py:194: VisibleDeprecationWa... | closed | 2022-10-31T00:51:49Z | 2022-11-04T15:30:24Z | https://github.com/cleanlab/cleanlab/issues/512 | [
"code improvement"
] | jwmueller | 0 |
suitenumerique/docs | django | 127 | ✅e2e bot on preprod | ## Feature Request
When we push to preprod, we would like to have the e2e bot asserting that everything is OK.
To start we could trigger our bot manually, so the checkup will be in conjunction with a human inspection.
We could as well trigger it from the CI: https://github.com/numerique-gouv/impress/blob/ce61a... | open | 2024-07-04T10:22:02Z | 2025-03-14T09:24:15Z | https://github.com/suitenumerique/docs/issues/127 | [
"enhancement",
"CI",
"feature"
] | AntoLC | 2 |
biolab/orange3 | data-visualization | 6,694 | TypeError: unable to convert a Python 'Shape' object to a C++ 'Shape' instance | <!--
Thanks for taking the time to report a bug!
If you're raising an issue about an add-on (i.e., installed via Options > Add-ons), raise an issue in the relevant add-on's issue tracker instead. See: https://github.com/biolab?q=orange3
To fix the bug, we need to be able to reproduce it. Please answer the following... | closed | 2024-01-05T02:12:49Z | 2024-01-22T10:05:55Z | https://github.com/biolab/orange3/issues/6694 | [
"bug report"
] | foongminwong | 4 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.