
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
Urinx/WeixinBot | api | 221 | root[10113] DEBUG retcode: -1, selector: -1 | 成功获取联系人信息后
系统一直持续出现:
2017-08-09 07:49:17 Yannch root[10113] DEBUG retcode: -1, selector: -1
2017-08-09 07:49:29 Yannch root[10113] DEBUG retcode: -1, selector: -1
。。。
这个正常吗?也能收消息 | open | 2017-08-09T05:58:08Z | 2017-08-09T05:58:08Z | https://github.com/Urinx/WeixinBot/issues/221 | [] | yangezheng | 0 |
cobrateam/splinter | automation | 333 | Chrome full screen tests fail | Only on my local. Not sure why. This is a placeholder while I research.
| closed | 2014-07-24T20:55:39Z | 2019-06-30T15:06:12Z | https://github.com/cobrateam/splinter/issues/333 | [
"NeedsInvestigation"
] | dustinfarris | 1 |
Morizeyao/GPT2-Chinese | nlp | 73 | 如何做限定体裁的生成 | 对于生成古诗,怎么生成限定体裁的古诗?比如七言绝句,七言律诗?如何在一个模型中控制生成?如果分开训练成2个模型,显得挺繁琐。我看官方的示例中是有限定体裁的生成例子的。 | closed | 2019-09-30T06:35:23Z | 2019-10-06T04:26:09Z | https://github.com/Morizeyao/GPT2-Chinese/issues/73 | [] | MrRace | 1 |
OFA-Sys/Chinese-CLIP | nlp | 203 | 请问可以开源出来预训练阶段的200M中文image-text数据吗? | rt | closed | 2023-09-08T07:32:18Z | 2023-09-15T07:13:37Z | https://github.com/OFA-Sys/Chinese-CLIP/issues/203 | [] | xyw7 | 1 |
taverntesting/tavern | pytest | 265 | Value mismatch in body with nested json | Based on below response I'm trying to validate the **first_name: "Eve"** but I'm confused about how to do it. I checked the documentation twice and did not found samples to help me out.
```json
{
"page": 2,
"per_page": 3,
"total": 12,
"total_pages": 4,
"data": [
{
"id"... | closed | 2019-02-11T04:13:45Z | 2019-04-10T17:04:41Z | https://github.com/taverntesting/tavern/issues/265 | [] | varayal | 8 |
microsoft/hummingbird | scikit-learn | 744 | ONNXMLGather breaks tests | [failed runner](https://github.com/microsoft/hummingbird/actions/runs/7227155960/job/19694227010)
todo investigate: `ValueError: Unsupported conversion for operator ONNXMLGather`
```
=========================== short test summary info ===========================
FAILED tests/test_backends.py::TestBackends::test... | closed | 2023-12-15T22:00:06Z | 2024-01-02T19:16:07Z | https://github.com/microsoft/hummingbird/issues/744 | [] | ksaur | 2 |
ultralytics/ultralytics | python | 18,709 | model.val(data="yolo_seg/data.yaml", split='val', save_json=True)生成的 .json文件乱码 | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and found no similar bug report.
### Ultralytics YOLO Component
_No response_
### Bug

like this.... | open | 2025-01-16T09:30:14Z | 2025-01-21T15:25:22Z | https://github.com/ultralytics/ultralytics/issues/18709 | [
"segment"
] | ggyybb | 9 |
brightmart/text_classification | nlp | 52 | License? | I'm guessing that this code is intended to be open sourced otherwise it wouldn't be here, but is there a particular license that you'd like to choose for your work? | closed | 2018-05-08T05:30:25Z | 2018-05-11T06:39:53Z | https://github.com/brightmart/text_classification/issues/52 | [] | slremy | 1 |
httpie/cli | python | 1,614 | AssertionError when trying to POST with bearer auth | ## Checklist
- [X] I've searched for similar issues.
- [X] I'm using the latest version of HTTPie.
---
## Minimal reproduction code and steps
```
/Users/Khayet https POST --auth-type bearer --auth $TOKEN "https://example.org"
```
## Current result
```
Traceback (most recent call last):
File "/opt/homebrew/bin/h... | open | 2025-01-29T09:33:44Z | 2025-02-04T17:02:05Z | https://github.com/httpie/cli/issues/1614 | [
"bug",
"new"
] | Khayet | 1 |
graphql-python/graphene-sqlalchemy | sqlalchemy | 354 | Apply linting or formatting tool to all source code | Let's apply a linting or formatting tool such as [black](https://github.com/psf/black) or [yapf](https://github.com/google/yapf) for better readability.
I guess we need another requirements config file or just add another config option in setup.py if we apply one of them. | closed | 2022-07-17T07:37:37Z | 2023-05-29T00:44:00Z | https://github.com/graphql-python/graphene-sqlalchemy/issues/354 | [] | fregataa | 3 |
ultrafunkamsterdam/undetected-chromedriver | automation | 2,124 | Cookies inserting | This was already there but the fix posted under the post didnt work at all the thing is for example using get_cookies function works perfectly fine throught cdp however pushing the cookies throught set_cookies - await tab.send(cdp.storage.set_cookies(bpcookie)) does not work at all nothing changes no error appears | closed | 2025-01-28T15:14:30Z | 2025-01-28T18:37:02Z | https://github.com/ultrafunkamsterdam/undetected-chromedriver/issues/2124 | [] | PowerfullPower | 0 |
Gerapy/Gerapy | django | 121 | gerapy init 初始化时出错 | 在win环境下,gerapy init 初始化时出错提示:SyntaxError: Non-UTF-8 code starting with
修复代码:gerapy-script.py文件首行加上`# -*- coding:utf-8 -*-`
麻烦修复 | closed | 2019-10-18T18:08:17Z | 2019-11-20T19:26:29Z | https://github.com/Gerapy/Gerapy/issues/121 | [
"bug"
] | eflydata | 1 |
robotframework/robotframework | automation | 4,389 | Pabot and Data Driver optimization | I have 10k test cases in excel and used Data driver test template with optimize_pabot=Binary. Am using pabot for parallel execution with 10 processes but in the result I see pabot form 59 executions. Could u pls help me understand how the optimize_pabot options are working?? Though I initiated 10 processes i see 59 exe... | closed | 2022-07-05T08:12:10Z | 2022-07-06T20:11:10Z | https://github.com/robotframework/robotframework/issues/4389 | [] | appusri9 | 1 |
huggingface/transformers | python | 36,051 | [generate] generate not working gradient_checkpointing=True | ### System Info
```
transformers==4.37.2
peft==0.13.1
accelerate==0.21.0
deepspeed==0.12.6
torch==2.1.2+cu118
```
### Who can help?
@zucchini-nlp @ArthurZucker
### Information
- [ ] The official example scripts
- [x] My own modified scripts
### Tasks
- [ ] An officially supported task in the `examples` fold... | closed | 2025-02-05T15:00:39Z | 2025-02-06T14:16:32Z | https://github.com/huggingface/transformers/issues/36051 | [
"bug",
"Generation"
] | alcompa | 7 |
streamlit/streamlit | python | 10,550 | Discrepancy of selectbox value in AppTest | ### Checklist
- [x] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar issues.
- [x] I added a very descriptive title to this issue.
- [x] I have provided sufficient information below to help reproduce this issue.
### Summary
Hi, great project - keep up the great work!
... | open | 2025-02-27T22:12:38Z | 2025-03-03T14:02:33Z | https://github.com/streamlit/streamlit/issues/10550 | [
"type:enhancement"
] | ams1 | 4 |
ultralytics/yolov5 | deep-learning | 13,392 | Jetson Orin Nano JetPack 5.1.3 install latest yolov5, RuntimeError: Couldn't load custom C++ ops | ### Search before asking
- [X] I have searched the YOLOv5 [issues](https://github.com/ultralytics/yolov5/issues) and [discussions](https://github.com/ultralytics/yolov5/discussions) and found no similar questions.
### Question
I followed readme and all seems fine:
When I run with object detection command, I got ... | closed | 2024-10-29T08:09:47Z | 2024-11-01T08:51:36Z | https://github.com/ultralytics/yolov5/issues/13392 | [
"question",
"dependencies",
"detect"
] | lida2003 | 16 |
AirtestProject/Airtest | automation | 782 | airtestIDE打印中文,提示编码错误 | 使用airtestIDE打印中文,提示编码错误
python版本:3.6
电脑设备:mac mini
airtestIDE版本:1.2.3
使用各种方法,都无法解决,用pycharm执行都没问题的,求解决
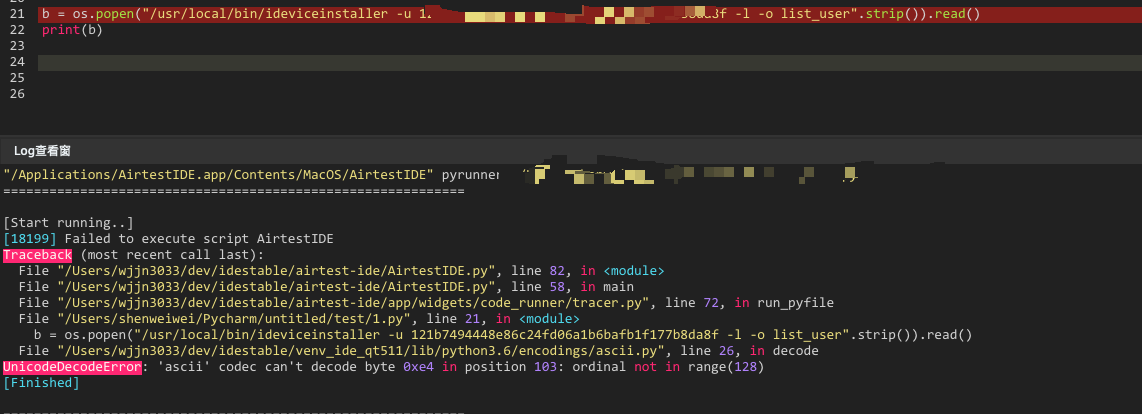
| open | 2020-08-11T08:43:09Z | 2020-08-18T12:22:40Z | https://github.com/AirtestProject/Airtest/issues/782 | [] | vivian12 | 7 |
miguelgrinberg/flasky | flask | 397 | How can I achieve this structure? | How can I achieve this structure?
<img width="249" alt="wx20181128-172947 2x" src="https://user-images.githubusercontent.com/16076835/49143545-37844900-f336-11e8-80b3-4b22f77ad754.png"> | closed | 2018-11-28T09:52:22Z | 2018-12-04T09:07:18Z | https://github.com/miguelgrinberg/flasky/issues/397 | [] | acodercat | 4 |
graphdeco-inria/gaussian-splatting | computer-vision | 471 | Zooming out the splats become large and blocky | If I zoom out in SIBR the splats become large and blocky, they don't seem to visibly scale with distance. Is there a way to correct this?
https://github.com/graphdeco-inria/gaussian-splatting/assets/106480554/4ceef97f-c577-4dee-9cea-3d6a1752569d
| closed | 2023-11-15T14:23:42Z | 2024-12-31T17:43:48Z | https://github.com/graphdeco-inria/gaussian-splatting/issues/471 | [] | henrypearce4D | 2 |
zihangdai/xlnet | nlp | 13 | Can't load model in GCS directly | When I wanted to run the model on TPU, I used "gs://..." replace the ${LARGE_DIR}. But it turns out the IOError.
`Traceback (most recent call last):
File "run_classifier.py", line 903, in <module>
tf.app.run()
File "/usr/local/lib/python2.7/dist-packages/tensorflow/python/platform/app.py", line 125, in run
... | closed | 2019-06-21T09:41:29Z | 2019-06-22T07:48:50Z | https://github.com/zihangdai/xlnet/issues/13 | [] | yokinglou | 11 |
encode/databases | sqlalchemy | 174 | Strange issues when using memoize/cache and refreshing | Hello there.
I am running into a strange error when using memoize type caching for db calls (to mariadb).
I am trying to keep db connections down, so I am trying to only open a connection when needed.
This is with using aiocache, but getting essentially the same thing when using py-memoize.
This is what I am ... | open | 2020-03-13T17:53:58Z | 2024-09-02T14:19:47Z | https://github.com/encode/databases/issues/174 | [] | ghedb | 2 |
jupyter-incubator/sparkmagic | jupyter | 631 | [BUG] Build docker compose error using master branch | **Describe the bug**
Trying to build the images of the master branch.
Getting the error
`/apps/build/spark/build/mvn: line 159: 972 Killed "${MVN_BIN}" -DzincPort=${ZINC_PORT} "$@"`
Using docker on windows 10.
**To Reproduce**
Clone the master branch.
Exec docker-compose build. | closed | 2020-02-14T11:53:34Z | 2020-02-19T08:36:15Z | https://github.com/jupyter-incubator/sparkmagic/issues/631 | [] | celoibarros | 2 |
PaddlePaddle/PaddleHub | nlp | 2,261 | ace2p模型无法转onnx | 欢迎您反馈PaddleHub使用问题,非常感谢您对PaddleHub的贡献!
在留下您的问题时,辛苦您同步提供如下信息:
- 版本、环境信息
1)PaddleHub2.3.1和PaddlePaddle2.3.2
2)系统环境:ubuntu20.04,python3.8.10
ace2p模型转onnx时,有算子不支持,如conv,好像说是paddle2onnx只支持paddlepaddle2.0以上的模型转onnx,ace2p的模型是1.x的。请问能否提供paddle2.x版本的ace2p模型,或者训练代码。谢谢
| open | 2023-06-02T02:00:24Z | 2024-02-26T04:59:29Z | https://github.com/PaddlePaddle/PaddleHub/issues/2261 | [] | jstzwjr | 0 |
DistrictDataLabs/yellowbrick | scikit-learn | 1,155 | v1.3.post1 release | - [x] Branch release-1.3.post1 off of develop
- [x] Do version bump (update version listed in yellowbrick/version.py, tests/__init__.py)
- [x] Run tests
- [x] Create change log/release notes
- [x] Review documentation build
- [x] Merge into `master`
- [x] Push release to PyPI (`python setup.py sdist bdist... | closed | 2021-02-13T19:55:14Z | 2021-02-13T20:54:43Z | https://github.com/DistrictDataLabs/yellowbrick/issues/1155 | [] | rebeccabilbro | 0 |
snarfed/granary | rest-api | 101 | add appropriate content-type headers for XML feed | When I view a granary feed in chrome, I see a lot of text. When I view other feeds, chrome renders it as an XML tree.
I see granary sets a content-type header of `text/xml` which I would have thought would work, but on a feed that looks right in the browser I see that the content type is `application/xml`.
Compar... | closed | 2017-01-21T20:26:06Z | 2017-01-22T02:44:48Z | https://github.com/snarfed/granary/issues/101 | [] | aaronpk | 1 |
getsentry/sentry | python | 86,898 | User Feedback marked as Resolved due to inactivity | See:
https://sentry.sentry.io/feedback/?alert_rule_id=15574919&alert_type=issue&feedbackSlug=javascript%3A6275674037&mailbox=resolved¬ification_uuid=5a0729d4-2b8d-402f-a7e4-09a080db5d64&project=11276&query=MAUI&referrer=feedback_list_page&statsPeriod=90d

I used your described method of using docker image here https://github.com/FujiwaraChoki/MoneyPrinter/issues/140. and I can see containers are running without any issue.

# This works
# SQL Query is: SELECT ARRAY['a', 'b', 'c']
query = sql.select([
array(['a', 'b', 'c'])
])
value = await database.fetch_v... | open | 2021-02-18T21:57:21Z | 2021-02-18T21:57:46Z | https://github.com/encode/databases/issues/292 | [] | snazzyfox | 0 |
kubeflow/katib | scikit-learn | 1,754 | Recent metrics filter change broke metrics collection for non-scientific values | /kind bug
**What steps did you take and what happened:**
The DefaultFilter value for the File Metrics Collector was recently changed to fix issues parsing scientific notation values but with the change multi digit number values are no longer parsed correctly and are truncated at the first digit.
**What did you e... | closed | 2021-12-01T17:22:34Z | 2021-12-01T23:22:04Z | https://github.com/kubeflow/katib/issues/1754 | [
"priority/p0",
"kind/bug"
] | RDarrylR | 2 |
iMerica/dj-rest-auth | rest-api | 474 | "CSRF failed: CSRF token missing." when trying to log in | In a hybrid site with an HTML UI and REST client, it is common to have CSRF enabled to protect website visitors from malicious activity.
https://stackoverflow.com/a/26639895/1191545
However, when enabling `dj-rest-auth` and trying to make `POST` requests to endpoints, such as `login/`, Django is producing CSRF e... | closed | 2023-01-28T16:45:08Z | 2023-01-28T17:49:30Z | https://github.com/iMerica/dj-rest-auth/issues/474 | [] | brylie | 1 |
OWASP/Nettacker | automation | 595 | multi threading issue | Hi,
1. There is an issue with the queues. When a request is dependent on another request, all queued requests will constantly check for the same variable in the temp events of the database. So we need to generate those requests after the variable is available and stop consuming the CPU.
2. if threads of one subproc... | open | 2022-09-24T16:24:32Z | 2024-04-06T21:44:43Z | https://github.com/OWASP/Nettacker/issues/595 | [
"bug"
] | Ali-Razmjoo | 2 |
lepture/authlib | django | 249 | Support both authorization code with and without PKCE? | We are using Authlib on out project Udata to authenticate third party app, most of them by authorization code.
We are implementing the PKCE flow. We would like to be able to support both authorization code with and without PKCE, in order for existing apps to continue working, and new ones to use PKCE.
Is this actua... | closed | 2020-07-10T09:30:46Z | 2020-07-13T08:34:29Z | https://github.com/lepture/authlib/issues/249 | [] | quaxsze | 2 |
ludwig-ai/ludwig | computer-vision | 3,937 | Remove default target modules for Gemma once it's updated in PEFT | https://github.com/ludwig-ai/ludwig/pull/3936 | closed | 2024-02-21T21:32:16Z | 2024-07-26T21:41:30Z | https://github.com/ludwig-ai/ludwig/issues/3937 | [
"llm"
] | arnavgarg1 | 1 |
wandb/wandb | data-science | 8,609 | [Q]: ERROR failed to upsert bucket: returned error 403 Forbidden | ### Ask your question
Hello,
I am a new using wanb. I want to experiment tracking by using wandb and executing python commands. However I get this error.
How to solve this error?
wandb: Currently logged in as: bassfaye10. Use `wandb login --relogin` to force relogin
wandb: ERROR failed to upsert bucket: returned erro... | closed | 2024-10-14T09:46:55Z | 2024-10-18T11:36:54Z | https://github.com/wandb/wandb/issues/8609 | [
"ty:question"
] | bassfaye | 7 |
postmanlabs/httpbin | api | 385 | Bearer authentication endpoint | A endpoint that returns status `401 Unauthorized ` with the response header `WWW-Authenticate: Bearer`.
It should expect the request header `Authorization` with a value of `Bearer …`. | closed | 2017-09-24T19:29:31Z | 2018-04-26T17:51:15Z | https://github.com/postmanlabs/httpbin/issues/385 | [] | vanillajonathan | 0 |
graphql-python/graphene-mongo | graphql | 198 | graphene-mongo not compatible with graphql-server due to GraphQLResolveInfo.context handling | ### Error description
Running the tutorial application at https://graphene-mongo.readthedocs.io/en/latest/tutorial.html with `graphql-server[flask]` instead of `Flask-GraphQL` installed results in the following error being returned
```json
{
"errors": [
{
"message": "'dict' object has no attribute '... | closed | 2022-04-25T23:06:01Z | 2023-04-13T23:15:41Z | https://github.com/graphql-python/graphene-mongo/issues/198 | [] | leonardwellthy | 1 |
aleju/imgaug | machine-learning | 747 | any plan to support video? | any plan to support video augmentation? | open | 2021-02-09T21:15:54Z | 2021-02-09T21:15:54Z | https://github.com/aleju/imgaug/issues/747 | [] | seyeeet | 0 |
pytest-dev/pytest-xdist | pytest | 1,178 | INTERNALERROR> assert not crashitem, (crashitem, node) randomly occurs | OS: ubuntu
requirements:
```
Package Version
--------------------------------- ------------------
aiobotocore 2.12.3
aiohappyeyeballs 2.4.0
aiohttp 3.10.5
aioitertools 0.7.1
aiosignal ... | closed | 2025-02-12T08:10:55Z | 2025-02-12T14:36:56Z | https://github.com/pytest-dev/pytest-xdist/issues/1178 | [] | lupanlpb | 5 |
pydantic/pydantic-settings | pydantic | 151 | No validation feedback for nested models | My env:
```
pydantic==2.3.0
pydantic-settings==2.0.3
```
Python 3.10.9
It looks like the behaviour for validating the nested `BaseSettings` model is not expected.
This is an example of expected behaviour. No nested models here:
```py
# script.py
from pydantic_settings import BaseSettings
class ... | closed | 2023-08-24T12:12:38Z | 2023-09-04T11:24:43Z | https://github.com/pydantic/pydantic-settings/issues/151 | [
"unconfirmed"
] | adam-pawluczuk | 1 |
vitalik/django-ninja | rest-api | 857 | Getting objects by id of authenticated user | I am using ninja with authentication and now want to retrieve objects of the authenticated user.
I get an error that I'm not able to fix. The api wants me to pass a valid user_id, however I already to that (I confirmed it returns the correct value and this also works in other functions)
What am I missing here or wh... | closed | 2023-09-16T11:44:57Z | 2024-01-22T11:39:07Z | https://github.com/vitalik/django-ninja/issues/857 | [] | kimdre | 3 |
nteract/papermill | jupyter | 623 | Need fix for recent GCFS changes | ## Build Issue
<!-- A clear and concise description of what the bug is. -->
GCS dependencies moving forward need a patch for papermill to be able to use the new version of the library.
See: https://github.com/nteract/papermill/actions/runs/1069848310 | closed | 2021-07-29T05:45:20Z | 2021-08-31T04:07:46Z | https://github.com/nteract/papermill/issues/623 | [
"bug",
"help wanted"
] | MSeal | 0 |
darrenburns/pytest-clarity | pytest | 25 | Assertions in other files are not diffed | Assertions raised from outside the test file are not diffed. Here's an example.
Is this a failure in [pytest_assertrepr_compare](https://docs.pytest.org/en/7.1.x/reference/reference.html#pytest.hookspec.pytest_assertrepr_compare) maybe?
Baseline - beautiful.
```python
def test_diff():
assert {"1": 1} ... | closed | 2022-12-16T22:29:19Z | 2022-12-16T22:43:23Z | https://github.com/darrenburns/pytest-clarity/issues/25 | [] | reergymerej | 1 |
polarsource/polar | fastapi | 4,829 | "Pay What You Want" should be more encouraging | ### Discussed in https://github.com/orgs/polarsource/discussions/4826
<div type='discussions-op-text'>
<sup>Originally posted by **sindresorhus** January 14, 2025</sup>
Gumroad:

Polar:

[rank2]: File "/share/home/xxx/miniconda3/envs/qwen2_vl_FT/lib/python3.10/site-packages/deepspeed/runtime/zero/stage3.py", line 980, in _... | open | 2024-12-12T02:59:34Z | 2024-12-13T10:43:50Z | https://github.com/deepspeedai/DeepSpeed/issues/6857 | [
"bug",
"training"
] | tdtgi | 2 |
home-assistant/core | asyncio | 140,800 | No `event_id` for Unifi doorbell ring events | ### The problem
I have long had notification automations for by doorbell, both for doorbell ring and package detection.
Several months ago the ring notification stopped working, as the `event_id` attribute for returns `None` rather than a proper event ID. The package notifications continue to work as intended.
```yam... | open | 2025-03-17T12:47:28Z | 2025-03-20T19:45:30Z | https://github.com/home-assistant/core/issues/140800 | [
"integration: unifiprotect"
] | deiger | 2 |
xzkostyan/clickhouse-sqlalchemy | sqlalchemy | 95 | Multiple FINAL clause support | **Describe the bug**
It's not possible to control `FINAL` rendering with JOINs.
```
sql
CREATE TABLE test_int2 (x Int32, sign Int8) ENGINE = CollapsingMergeTree(sign) ORDER BY tuple();
```
Query examples:
```sql
select x from test_int2 as a final join test_int2 as b final on a.x = b.x;
```
```sql
sel... | open | 2020-05-25T19:56:36Z | 2022-07-05T18:54:14Z | https://github.com/xzkostyan/clickhouse-sqlalchemy/issues/95 | [
"bug"
] | xzkostyan | 1 |
dynaconf/dynaconf | flask | 1,170 | [RFC] Add option to strip the env var prefix from config in settings files | **Is your feature request related to a problem? Please describe.**
I prefer to have the env var names exactly match the names used in the config file and application code.
**Describe the solution you'd like**
- Add a param to the dynaconf config that is off by default (e.g. something like `settings_files_strip_pre... | open | 2024-08-12T19:01:22Z | 2024-08-13T15:27:52Z | https://github.com/dynaconf/dynaconf/issues/1170 | [
"Not a Bug",
"RFC"
] | taranlu-houzz | 3 |
mlflow/mlflow | machine-learning | 14,455 | Mark `iternal` as a typo of `internal` | ### Summary
To address https://github.com/mlflow/mlflow/pull/14450#discussion_r1942071959, add `iternal` to the typo list:
```
diff --git a/pyproject.toml b/pyproject.toml
index aa6bb2aa3..82c83d53b 100644
--- a/pyproject.toml
+++ b/pyproject.toml
@@ -294,6 +294,7 @@ fpr = "fpr" # false positive rate
gam = "gam" ... | closed | 2025-02-05T03:24:57Z | 2025-02-05T09:59:45Z | https://github.com/mlflow/mlflow/issues/14455 | [
"good first issue",
"has-closing-pr"
] | harupy | 3 |
joeyespo/grip | flask | 99 | Markdown cannot contain not latin-1 characters | Markdown cannot be rendered if markdown file has not latin-1 chacters(Japanese characters, emoji etc).
For example, README.md is here
```
⌘
```
```
% grip --version
Grip 3.1.0
% grip README.md
```
And I accessed http://localhost:5000 then I got following error(and stack trace)
```
builtins.UnicodeEncodeError
Unic... | closed | 2015-02-23T23:15:13Z | 2015-02-24T14:04:31Z | https://github.com/joeyespo/grip/issues/99 | [
"bug"
] | syohex | 2 |
pydata/bottleneck | numpy | 8 | Segmentation fault with Cython 0.14.1 but not 0.13 | Segmentation fault with Cython 0.14.1 but not 0.13.
See this thread: http://groups.google.com/group/cython-users/browse_thread/thread/23f373a65a2a6391
Fixed with commit 89bad25a9cea6a1153e7
| closed | 2011-03-04T22:39:21Z | 2011-03-04T22:39:42Z | https://github.com/pydata/bottleneck/issues/8 | [
"bug"
] | kwgoodman | 0 |
zappa/Zappa | django | 454 | [Migrated] Added Angular 4 example | Originally from: https://github.com/Miserlou/Zappa/issues/1211 by [miguel3010](https://github.com/miguel3010)
<!--
Before you submit this PR, please make sure that you meet these criteria:
* Did you read the [contributing guide](https://github.com/Miserlou/Zappa/#contributing)?
* If this is a non-trivial comm... | closed | 2021-02-20T08:35:04Z | 2022-07-16T07:32:25Z | https://github.com/zappa/Zappa/issues/454 | [] | jneves | 1 |
zihangdai/xlnet | nlp | 40 | corpus_info_path can't be found in train_gpu.py | closed | 2019-06-24T05:40:14Z | 2020-03-03T07:49:06Z | https://github.com/zihangdai/xlnet/issues/40 | [] | xiguashuiguo | 1 | |
PokemonGoF/PokemonGo-Bot | automation | 5,792 | Optimal config to avoid detection? | Anyone want to share their config to avoid captcha and other bot detection methods? | closed | 2016-11-08T15:24:39Z | 2016-11-14T20:08:33Z | https://github.com/PokemonGoF/PokemonGo-Bot/issues/5792 | [] | trippyhat | 2 |
predict-idlab/plotly-resampler | data-visualization | 196 | Cannot install plotly resampler in fresh python 3.10 conda environment. | Python 3.10.10
pip 23.0.1
I am getting this error:
```
Building wheels for collected packages: plotly-resampler
WARNING: Building wheel for plotly-resampler failed: [Errno 38] Function not implemented: '/home/jovyan/.cache/pip'
Failed to build plotly-resampler
ERROR: Could not build wheels for plotly-resam... | closed | 2023-04-19T21:55:57Z | 2023-04-20T16:40:03Z | https://github.com/predict-idlab/plotly-resampler/issues/196 | [] | sorenwacker | 0 |
microsoft/qlib | machine-learning | 1,747 | How to predict the stock price in the future (such as the next week)? | By default, it can only predict and backtest to the same day (trading day). How can I predict the stock price in the future (such as the next week/month)? thanks.
默认只能预测、回测到当天(交易日),请问:如何预测未来时间(比如未来一周/一月)的股价了?谢谢。
For example
These configurations are not working and it still ends on February 8th (the previous tradin... | open | 2024-02-16T07:28:10Z | 2024-07-01T12:59:56Z | https://github.com/microsoft/qlib/issues/1747 | [
"bug"
] | ghyzx | 2 |
slackapi/python-slack-sdk | asyncio | 1,509 | `CheckboxesElement` within `ActionsBlock` silently fails to render when `initial_options` does not exactly match a given `Option` in the element's `options` list | I'm building a form that gets pushed onto a modal's view. One of the blocks within that form is an [`ActionsBlock`](https://slack.dev/python-slack-sdk/api-docs/slack_sdk/models/blocks/index.html#slack_sdk.models.blocks.ActionsBlock), and within that block is a [`CheckboxesElement`](https://slack.dev/python-slack-sdk/ap... | closed | 2024-06-14T18:08:51Z | 2024-06-14T21:07:20Z | https://github.com/slackapi/python-slack-sdk/issues/1509 | [] | macintacos | 2 |
deepset-ai/haystack | machine-learning | 9,076 | In SuperComponent utils update `_is_compatible(type1, type2)` to return the common type | In SuperComponents during the validation of an `input_mapping` provided by a user we check if the types of the combined inputs are compatible using the `_is_compatible` utility function. `_is_compatible` works by checking if the two types have some overlapping common type rather than using strict type validation.
This... | open | 2025-03-20T07:15:04Z | 2025-03-21T14:29:14Z | https://github.com/deepset-ai/haystack/issues/9076 | [
"P2"
] | sjrl | 0 |
pallets-eco/flask-sqlalchemy | sqlalchemy | 884 | Exception when setting sa_url.query default due to immutable type | ### Expected Behavior
The below should be successful
```python
sa_url.query.setdefault("charset", "utf8")
```
### Actual Behavior
The following exception is thrown: AttributeError: 'sqlalchemy.cimmutabledict.immutabledict' object has no attribute 'setdefault'
You can see the full traceback on Travis her... | closed | 2020-11-04T08:38:55Z | 2020-12-05T19:58:17Z | https://github.com/pallets-eco/flask-sqlalchemy/issues/884 | [] | failys | 2 |
benbusby/whoogle-search | flask | 520 | [BUG] Internal server error for some image searches when View Image option is enabled | **Describe the bug**
Certain image searches result in an Internal Server Error when the environment variable `WHOOGLE_CONFIG_VIEW_IMAGE=1` is set. The bug occurs due to a footer that is added to the bottom of the image search results on the Google website:
> Some results may have been removed under data protection ... | closed | 2021-11-02T20:56:18Z | 2021-11-02T22:22:24Z | https://github.com/benbusby/whoogle-search/issues/520 | [
"bug"
] | fabianschilling | 0 |
TencentARC/GFPGAN | deep-learning | 65 | RuntimeError: Error(s) in loading state_dict for GFPGANv1: | I train the model on my own dataset. However, when I inference image, the error happens and I don't know the reason for this

| open | 2021-09-17T04:16:32Z | 2021-09-27T06:46:51Z | https://github.com/TencentARC/GFPGAN/issues/65 | [] | ntquyen11 | 7 |
ionelmc/pytest-benchmark | pytest | 230 | HTML reports | Feature request
Hi Team ,
When we use pytest benchmark with CI solutions like Jenkins , If we have option of saving results in HTML or exporting the results into image will be easier for end user to see results.
Currently we need to go through console output to see results or export it to json (looking through jso... | open | 2022-11-25T04:50:49Z | 2023-11-17T15:15:55Z | https://github.com/ionelmc/pytest-benchmark/issues/230 | [] | nirupbbnk | 1 |
xuebinqin/U-2-Net | computer-vision | 141 | Keras model | Can you upload this model to be opened with keras? Using CPU if possible. Because converting your pytorch model to keras fails when trying to predict using CPU only. | open | 2021-01-05T22:36:58Z | 2021-01-12T16:32:59Z | https://github.com/xuebinqin/U-2-Net/issues/141 | [] | AzazelHD | 1 |
ShishirPatil/gorilla | api | 920 | [BFCL] Change multi-turn evals to single-turn from "ground truth" state | **Describe the issue**
Currently, multi-turn evals function as follows:
1. A sequence of user turns is predefined for each sample
2. Each user turn has an expected set of functions to have been called
3. Multi-turn generation is run as follows:
a. Feed user turn 1 to model
b. Parse response from model
c. Execute tool c... | open | 2025-02-26T16:25:35Z | 2025-02-26T16:25:35Z | https://github.com/ShishirPatil/gorilla/issues/920 | [] | jgreer013 | 0 |
davidsandberg/facenet | tensorflow | 718 | ROC on casia | Hi.
I ran the 20170512-110547 model that was until recently provided here on the LFW test and got good results.
Then I ran the same model on a random selection of 1000 "same" and 1000 "different" pairs taken from casia. This time I got only 0.785 true-positive at 0.001 false positive.
Does it make sense to get such ... | open | 2018-04-23T15:54:12Z | 2018-04-25T17:40:33Z | https://github.com/davidsandberg/facenet/issues/718 | [] | arsenal2006 | 2 |
exaloop/codon | numpy | 289 | gcc: error: unrecognized command line option ‘-no-pie’ | Hello,
Getting error:
gcc: error: unrecognized command line option ‘-no-pie’
Using : codon build -release codon.py
Any advise | closed | 2023-03-24T08:42:14Z | 2024-11-09T20:03:37Z | https://github.com/exaloop/codon/issues/289 | [] | darklord1807 | 4 |
trevorstephens/gplearn | scikit-learn | 219 | Survival of the fittest | Darwinian evolution assumes the fittest survive. However, gplearn mutates whatever program(s) is(are) selected for the tournament, removing the parent from the population, even if the parent is fitter than the offspring.
I think it would be advantageous to first reproduce each program selected for the tournament, a... | closed | 2021-02-01T19:16:56Z | 2021-02-01T23:09:15Z | https://github.com/trevorstephens/gplearn/issues/219 | [
"enhancement"
] | rll2021 | 3 |
ultralytics/ultralytics | pytorch | 19,100 | TOTALLY WRONG `AssertionError: ERROR` | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and found no similar bug report.
### Ultralytics YOLO Component
Export
### Bug
So, I was having a ridiculously hard time trying deploy a YOLO model using OpenVINO without Torch.
The mai... | closed | 2025-02-06T12:05:28Z | 2025-02-07T03:05:25Z | https://github.com/ultralytics/ultralytics/issues/19100 | [
"exports"
] | sangoi-exe | 4 |
newpanjing/simpleui | django | 6 | list_filter | 在list_filter中,好像不能按时间过滤 | closed | 2019-02-27T02:52:06Z | 2019-03-01T10:30:29Z | https://github.com/newpanjing/simpleui/issues/6 | [] | LehongWei | 2 |
sherlock-project/sherlock | python | 1,578 | Add --list-sites argument to list all supported sites | <!--
######################################################################
WARNING!
IGNORING THE FOLLOWING TEMPLATE WILL RESULT IN ISSUE CLOSED AS INCOMPLETE
######################################################################
-->
## Checklist
<!--
Put x into all boxes (like this [x]) once you have... | closed | 2022-10-22T14:58:09Z | 2023-02-04T17:26:52Z | https://github.com/sherlock-project/sherlock/issues/1578 | [
"enhancement"
] | guiszk | 4 |
polyaxon/traceml | plotly | 14 | Patch level went down? | Hi, I am trying to get `pandas-summary` working, and had version 0.0.41 installed. I ran into the issue fixed by #11/#12, so I tried to upgrade. It seems like the version was changed to 0.0.5 with https://github.com/mouradmourafiq/pandas-summary/commit/42227d51d8d458ebce7090db971259565fb6ccdf
When I try to upgrade t... | closed | 2018-06-21T20:42:06Z | 2021-11-21T18:17:09Z | https://github.com/polyaxon/traceml/issues/14 | [] | panozzaj | 0 |
mljar/mljar-supervised | scikit-learn | 687 | LightGBM causes Optuna to go out of memory and crash | I was wondering if there was a way to batch the inputs when using Optuna or reduce the load on it.
Optuna seems to go out of memory and crash on google colab when I try to run it on my big dataset. This is observed only when using LightGBM, but other models seem to work fine. | open | 2023-12-13T14:48:14Z | 2023-12-14T20:30:29Z | https://github.com/mljar/mljar-supervised/issues/687 | [] | AkshayNovacene | 2 |
RayVentura/ShortGPT | automation | 28 | Make the tts work with tiktok id | . | closed | 2023-07-20T09:24:17Z | 2023-07-20T16:18:27Z | https://github.com/RayVentura/ShortGPT/issues/28 | [] | dolev765 | 1 |
gunthercox/ChatterBot | machine-learning | 1,874 | Ubuntu Corpus Training error on windows | Hi,
I am trying to implement ubuntu corpus trainer on my code, however I'm getting the following error:
Traceback (most recent call last):
File "<string>", line 1, in <module>
File "C:\Users\sbhat\AppData\Local\Programs\Python\Python37\lib\multiprocessing\spawn.py", line 105, in spawn_main
exitcode = _m... | open | 2019-11-22T15:40:03Z | 2021-01-03T08:06:44Z | https://github.com/gunthercox/ChatterBot/issues/1874 | [] | neilkerman | 2 |
nteract/papermill | jupyter | 205 | Add Azure Blob Storage backend | I would like to use `papermill` but store my notebooks on Azure Blob Storage. To achieve this, I think all it needs is implementing the same interface as done for S3 in `s3.py` and then registering it with `papermill_io.register("wasb://", WASBHandler)`? | closed | 2018-09-13T15:19:19Z | 2018-11-27T00:14:38Z | https://github.com/nteract/papermill/issues/205 | [
"enhancement",
"question"
] | xhochy | 2 |
tensorpack/tensorpack | tensorflow | 1,168 | Training picture normalization Settings | How to set the training image size | closed | 2019-04-28T01:46:37Z | 2019-05-03T18:36:31Z | https://github.com/tensorpack/tensorpack/issues/1168 | [
"unrelated"
] | junxiaoge | 1 |
opengeos/leafmap | jupyter | 327 | 'No such comm' Warnings | <!-- Please search existing issues to avoid creating duplicates. -->
### Environment Information
- leafmap version: 0.14.0
- jupyterlab version = 3.5.0
- notebook = 6.5.2-e60ab42
- Python version: 3.10.6
Available kernels:
python3 /home/....venv/share/jupyter/kernels/pyth... | closed | 2022-12-06T14:20:45Z | 2022-12-06T17:51:57Z | https://github.com/opengeos/leafmap/issues/327 | [
"bug"
] | Insighttful | 5 |
FactoryBoy/factory_boy | django | 616 | TransactionManagementError | #### Description
After upgrade my huge project from **Python2.7/Django1.8** to **Python3.7/Django2.2.1** I got the following error while I ran my tests. And I supposed that is blame of FactoryBoy (latest version).
#### To Reproduce
When I run my pytest command I just get a waterfall with all my tests getting the ... | closed | 2019-06-10T11:42:35Z | 2024-01-07T13:06:07Z | https://github.com/FactoryBoy/factory_boy/issues/616 | [
"NeedInfo",
"Django"
] | rafagarciac | 4 |
shibing624/text2vec | nlp | 144 | 请教bge用自己数据微调的问题 | 非常棒的开源项目。正好适配目前碰到的一个场景(主要是一些短语匹配的任务),有注意到最新发布的https://huggingface.co/shibing624/text2vec-bge-large-chinese模型在短文本区分度上提升明显,因此想尝试基于这个模型在自己的数据上微调。想实现的目标类似于: 「GMV」能匹配上「销售额」,「pv」能匹配上「访问量」这种需求。因此想请教下作者这块的训练方式,是否可以按下述方式来进行:
1. 基于开源的这版模型在 [SimCLUE](https://github.com/CLUEbenchmark/SimCLUE)这类数据集上做有监督的finetune (因为看到总结这个数据集的数据质量较... | closed | 2023-11-29T11:48:53Z | 2023-11-30T11:41:57Z | https://github.com/shibing624/text2vec/issues/144 | [
"question"
] | LanceLuoyuan | 3 |
scikit-learn/scikit-learn | python | 30,099 | Inconsistency between lars_path documentation and behavior in code | ### Describe the issue linked to the documentation
While using the `lars_path` function from the `sklearn.linear_model` module, I came across a confusing behavior that seems to contradict the documentation.
According to the [documentation for `lars_path`](https://scikit-learn.org/dev/modules/generated/sklearn.linea... | closed | 2024-10-18T12:08:56Z | 2024-10-29T11:41:29Z | https://github.com/scikit-learn/scikit-learn/issues/30099 | [
"Documentation"
] | xie00059 | 1 |
apache/airflow | machine-learning | 47,620 | Add support to configure log level for task-sdk logs | ### Apache Airflow version
main (development)
### If "Other Airflow 2 version" selected, which one?
_No response_
### What happened?
The log level is hardcoded as "DEBUG" with no configurations to change the value resulting in debug logs in the task logs. This should be configurable preferably through logging->log... | closed | 2025-03-11T14:34:28Z | 2025-03-13T16:16:45Z | https://github.com/apache/airflow/issues/47620 | [
"kind:bug",
"area:logging",
"kind:feature",
"area:core",
"area:task-execution-interface-aip72",
"affected_version:3.0.0beta"
] | tirkarthi | 0 |
miguelgrinberg/flasky | flask | 355 | url_for() in unittest | It seems that we have to push `app.test_request_context` ( or set `SERVER_NAME` ) before using `url_for()` in tests, otherwise you will get the error below:
```pytb
RuntimeError: Application was not able to create a URL adapter for request independent URL generation. You might be able to fix this by setting the SERVE... | closed | 2018-05-14T02:18:54Z | 2018-06-09T00:33:07Z | https://github.com/miguelgrinberg/flasky/issues/355 | [
"question"
] | greyli | 2 |
pydantic/pydantic-ai | pydantic | 533 | Cannot get gemini model to return None using pydanticAI | I am trying to create the return type of a pydantic model to be an integer or None from the prompt. However, setting the return as None causes an error with a gemini model
```py
from pydantic_ai import Agent
from pydantic import BaseModel
from pydantic_ai.models.vertexai import VertexAIModel
class AgeModel(Bas... | closed | 2024-12-23T10:53:06Z | 2024-12-24T09:36:07Z | https://github.com/pydantic/pydantic-ai/issues/533 | [
"bug"
] | DataMonsterBoy | 4 |
piskvorky/gensim | machine-learning | 3,234 | Update release instructions | https://github.com/RaRe-Technologies/gensim/wiki/Maintainer-page is out of date
- We don't use gensim-wheels repo anymore - everything happens in the main gensim repo
- Wheel building is less of a pain now - GHA takes care of most things
- Some release scripts appear out of date, e.g. prepare.sh
- A general descr... | open | 2021-09-14T13:45:07Z | 2021-09-14T13:45:17Z | https://github.com/piskvorky/gensim/issues/3234 | [
"documentation",
"housekeeping"
] | mpenkov | 0 |
Kludex/mangum | fastapi | 77 | How to connect with Django app? | Hi there,
I'm trying to get a better idea of what using Mangum usage looks like with a Django application. I've looked at the example, but don't really understand how that translates to pointing to a Django application.
More specifically, what does `app` in
```
handler = Mangum(app, enable_lifespan=False)
... | closed | 2019-12-16T16:13:20Z | 2020-05-11T15:24:21Z | https://github.com/Kludex/mangum/issues/77 | [
"docs"
] | levinotik | 7 |
CorentinJ/Real-Time-Voice-Cloning | tensorflow | 393 | can't open demo_toolbox.py | Whenever i try to open demo_toolbox.py, this happens:
```
UserWarning: Unable to import 'webrtcvad'. This package enables noise removal and is recommended.
warn("Unable to import 'webrtcvad'. This package enables noise removal and is recommended.")
2020-07-02 10:10:33.214892: I tensorflow/stream_executor/platfo... | closed | 2020-07-02T00:52:19Z | 2020-07-03T17:52:55Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/393 | [] | TheAwesomeYT | 4 |
vitalik/django-ninja | django | 335 | Django Ninja + GeoDjango | Currently using GeoDjango's custom fields breaks Django ninja with the following error:
```
Exception in thread django-main-thread:
...
< Omitted for brevity >
...
File "/opt/pysetup/.venv/lib/python3.9/site-packages/ninja/orm/fields.py", line 121, in get_schema_field
python_type = TYPES[internal_type]
Key... | open | 2022-01-25T17:25:53Z | 2024-08-13T23:01:29Z | https://github.com/vitalik/django-ninja/issues/335 | [] | Jonesus | 5 |
fastapi/sqlmodel | fastapi | 379 | Different response model behaviour on Mac vs Ubuntu when joining tables | ### First Check
- [X] I added a very descriptive title to this issue.
- [X] I used the GitHub search to find a similar issue and didn't find it.
- [X] I searched the SQLModel documentation, with the integrated search.
- [X] I already searched in Google "How to X in SQLModel" and didn't find any information.
- [X... | open | 2022-07-17T17:08:51Z | 2022-08-25T00:31:05Z | https://github.com/fastapi/sqlmodel/issues/379 | [
"question"
] | HenryDashwood | 2 |
davidsandberg/facenet | tensorflow | 648 | How to obtain only Facial Keypoints coordinates? | Hello, i'm quite new with TF and i'm so much interested with this project.
Is possible to obtain the 68 facial keypoints (like openface) from a random face image? how can i train the machine for this purpose?
Thank you
D | closed | 2018-02-19T11:27:52Z | 2018-04-01T21:22:23Z | https://github.com/davidsandberg/facenet/issues/648 | [] | AeonDave | 1 |
scrapy/scrapy | python | 6,636 | Reactor info logged twice | #6374 added a second `log_reactor_info()` call to `scrapy.crawler.Crawler._apply_settings()` so in some cases (including just `scrapy shell -s TWISTED_REACTOR="twisted.internet.asyncioreactor.AsyncioSelectorReactor"`) the info is logged twice:
```
2025-01-28 23:27:11 [scrapy.utils.log] DEBUG: Using reactor: twisted.in... | closed | 2025-01-28T18:29:48Z | 2025-02-06T10:47:41Z | https://github.com/scrapy/scrapy/issues/6636 | [
"bug",
"logging"
] | wRAR | 0 |
StackStorm/st2 | automation | 5,975 | packs.setup_virtualenv getting failed | Hi,
I have install stackstorm HA K8s in AKS Cluster everything is working fine but when i login into UI after i try to install packs it got fail reason below in screenshot and content
Here is custom st2 packs i have used this one and i have applied to 3 and i have also configure pv,pvc and its bound but still pac... | closed | 2023-05-09T16:05:11Z | 2023-05-24T20:57:07Z | https://github.com/StackStorm/st2/issues/5975 | [] | mohdrashid1 | 1 |
microsoft/nni | tensorflow | 4,882 | Web UI cannot show default metric when training large lightgbm model | **Describe the issue**:
Web UI cannot show default metric when training lightgbm model with more than 700 n_estimators

**Environment**:
- NNI version:2.6
- Training service (local|remote|pai... | closed | 2022-05-23T13:05:31Z | 2022-06-15T02:55:15Z | https://github.com/microsoft/nni/issues/4882 | [
"support",
"WebUI"
] | ANFANGERMI | 3 |
SALib/SALib | numpy | 453 | PAWN raises error on empty slices | The implementation of PAWN currently errors out if it hits an empty region. Patch to be submitted shortly. | closed | 2021-07-18T00:39:45Z | 2021-08-14T06:51:38Z | https://github.com/SALib/SALib/issues/453 | [] | ConnectedSystems | 0 |
vllm-project/vllm | pytorch | 14,406 | [Bug]: pipeline-parallel not working properly with QwQ model on TPU v4 | ### Your current environment
Your current environment
INFO 03-04 15:53:31 [init.py:253] Automatically detected platform tpu.
Collecting environment information...
PyTorch version: 2.7.0.dev20250304+cpu
Is debug build: False
CUDA used to build PyTorch: None
ROCM used to build PyTorch: N/A
OS: Ubuntu 22.04.2 LTS (x86_6... | open | 2025-03-07T05:04:01Z | 2025-03-07T05:04:01Z | https://github.com/vllm-project/vllm/issues/14406 | [
"bug"
] | flyingblackshark | 0 |
coleifer/sqlite-web | flask | 110 | SQLite built-in math functions(such as ln()) is not supported? |
Hi, first of all.
Thanks for maintaining this wonderful open source project. It's helpful a lot.
Um... the problem I have is following:
In terminal, below query is okay.
```SQL
SELECT ln(1 + change_in_price/close_price)
FROM stock_price WHERE short_code='005930'
AND base_date='2022-01-10'
```
 subclass that represents a (N, 2) tensor.
It can be used to represent points, and should be affected by the augmentation pipelines as such (for example, [RandomRotation... | open | 2024-11-13T08:53:15Z | 2024-12-17T13:55:06Z | https://github.com/pytorch/vision/issues/8728 | [] | Alexandre-SCHOEPP | 3 |
allure-framework/allure-python | pytest | 98 | Capture stdout in pytest plugin | [//]: # (
. Note: for support questions, please use Stackoverflow or Gitter**.
. This repository's issues are reserved for feature requests and bug reports.
.
. In case of any problems with Allure Jenkins plugin** please use the following repository
. to create an issue: https://github.com/jenkinsci/allure-plugi... | closed | 2017-07-12T10:59:00Z | 2020-05-18T19:24:52Z | https://github.com/allure-framework/allure-python/issues/98 | [
"theme:pytest",
"theme:behave",
"theme:core",
"work:backlog",
"type:enhancement"
] | sseliverstov | 3 |
man-group/arctic | pandas | 99 | intermittent test failure in 3.4 | See https://travis-ci.org/manahl/arctic/jobs/103143033
For an unknown reason this test fails periodically in Python 3.4. Usually a re-run will pass.
in test_ts_write_pandas[tickstore]
```
read = tickstore_lib.read('SYM', columns=None)
> assert_frame_equal(read, data, check_names=False)
tests/integratio... | closed | 2016-01-28T22:13:07Z | 2016-03-29T17:17:24Z | https://github.com/man-group/arctic/issues/99 | [] | bmoscon | 1 |
autokey/autokey | automation | 80 | Impossible to install autokey-py3 in Kubuntu 17.04 | ## Classification:
Crash/Hang/Data Loss
## Reproducibility:
Always
## Summary
How can I install autokey-py3 on Kubuntu 17.04?
## Steps to Reproduce
1. I do this : I downloded the deb files from the TESTING ppa(autokey-common and autokey-qt), and installed it(dpkg -i), but autokey hangs. (Applicatio... | closed | 2017-04-27T07:38:00Z | 2023-02-28T19:56:32Z | https://github.com/autokey/autokey/issues/80 | [] | nemonein | 10 |
seleniumbase/SeleniumBase | pytest | 3,060 | Getting : start error X11 display failed! Will use regular xvfb! | I have currently built an application that runs on Linux Ubuntu that does not have a GUI and regarding this situation for full protection I am not using Headless Mode and adding **incognito=True** and also for X11 display for Linux machines I added : **xvfb=True**. However, when I run the program I get this --> **start... | closed | 2024-08-28T11:17:37Z | 2024-08-28T11:56:23Z | https://github.com/seleniumbase/SeleniumBase/issues/3060 | [
"duplicate",
"question",
"UC Mode / CDP Mode"
] | Orbiszeus | 1 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.