
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
sammchardy/python-binance | api | 855 | ValueError: check_hostname requires server_hostname | **Describe the bug**
I can't connect client, but I use the v2rayN proxy client on my PC. When I try to visit https://api.binance.com/api/v3/ping through my browser, It shows ‘{}’.
But I try to run the following code, It prints "not existed".
So what should I do?
```
import socket
try:
socket.gethostbynam... | open | 2021-05-15T12:32:06Z | 2021-05-16T01:38:41Z | https://github.com/sammchardy/python-binance/issues/855 | [] | ZhangGang12 | 2 |
reloadware/reloadium | pandas | 183 | pydevd_process_net_command.py this file frequently wrong as UnicodeDecodeError | def _on_run(self):
read_buffer = ""
try:
while not self.killReceived:
try:
r = self.sock.recv(1024)
except:
if not self.killReceived:
traceback.print_exc()
self... | open | 2024-02-26T17:26:45Z | 2024-02-26T17:26:45Z | https://github.com/reloadware/reloadium/issues/183 | [] | fangplu | 0 |
reiinakano/xcessiv | scikit-learn | 54 | Add train and test error | Hi, it would be nice to display train and test error so we can evaluate easier if a model is overfitting.
Very nice work so far.
Thanks | closed | 2018-01-20T20:35:52Z | 2018-01-21T01:17:55Z | https://github.com/reiinakano/xcessiv/issues/54 | [] | fses91 | 1 |
globaleaks/globaleaks-whistleblowing-software | sqlalchemy | 3,301 | Image type JPG in logos | Hi! I cannot upload a logo in JPG to a tenant. Should they work as a logo type?
Software version used is 4.10.14.
**Steps to reproduce the behavior:**
1. Go to 'main configuration' at a tenant site
2. Click on edit in the logo field and upload an image in jpg type
3. See that the image doesn't function and do... | closed | 2022-10-24T08:06:11Z | 2022-11-04T17:36:31Z | https://github.com/globaleaks/globaleaks-whistleblowing-software/issues/3301 | [] | evariitta | 2 |
graphistry/pygraphistry | pandas | 40 | "See palette definitions" link broken in docs | http://pygraphistry.readthedocs.org/en/latest/graphistry.html has several links to https://github.com/graphistry/pygraphistry/blob/master/graphistry.com/palette.html which doesn't exist.
| closed | 2015-11-13T15:57:10Z | 2015-11-14T00:04:01Z | https://github.com/graphistry/pygraphistry/issues/40 | [] | tdhopper | 1 |
roboflow/supervision | machine-learning | 768 | DetectionDataset.as_coco having annotation id collision between splits | ### Search before asking
- [X] I have searched the Supervision [issues](https://github.com/roboflow/supervision/issues) and found no similar bug report.
### Bug
When exporting a YOLOv8 formatted dataset to COCO format (using the attached code), the JSON files associated with each split uses its own sequence for ass... | open | 2024-01-23T12:26:22Z | 2024-01-26T08:45:09Z | https://github.com/roboflow/supervision/issues/768 | [
"bug"
] | adbcode | 4 |
tflearn/tflearn | data-science | 327 | set sentence delimeters | How can I set sentence delimeters in csv files?
It is needed because the LSTM(or RNN) layer might access the data of the sencence before this one.
And, the examples are only using 'sentence' to input.(labeling per each sentence.)
I want to label each word in sentence.
How can I deal with this problem, without seque... | closed | 2016-09-03T08:33:21Z | 2016-09-30T14:20:49Z | https://github.com/tflearn/tflearn/issues/327 | [] | changukshin | 0 |
tflearn/tflearn | tensorflow | 760 | Train on GPU, infer on CPU | Hi
Say I trained a network using the GPU and tflearn.
How can I later run "model.predict(...)", while using the CPUs instead of the GPU?
Thanks
Dedi | open | 2017-05-16T10:27:24Z | 2017-05-16T11:43:08Z | https://github.com/tflearn/tflearn/issues/760 | [] | DediGadot | 1 |
numba/numba | numpy | 9,544 | Numba 0.60.0rc1 Checklist | ## Numba 0.60.0rc1
* [x] Merge to main.
- [x] #9274
- [x] #9454
- [x] #9482
- [x] https://github.com/numba/numba/pull/9549
* [x] Check Numba's version support table documentation. Update via PR if
needed.
* [x] https://github.com/numba/numba/pull/9559
* [x] Review deprecation schedule... | closed | 2024-04-24T15:57:35Z | 2024-06-11T12:44:02Z | https://github.com/numba/numba/issues/9544 | [
"Task"
] | stuartarchibald | 12 |
xuebinqin/U-2-Net | computer-vision | 241 | 使用过程中遇到的问题和想法 | 同学你好!
我花了两天时间阅读你的论文和代码,收获巨大。我认为不论是模型还是论文,质量都非常的高。模型的构思太巧妙了,论文的逻辑也非常清晰,而且实验做的很扎实。非常感谢你的分享,同时也向你学习!
我在使用你提供的u2net模型权重进行预测时,出现了下面这种情况

 than the loss in later layers(2.0), i'm curious that if the quantization is failed due to a large avg loss?
And for experience, what magnitude of avg loss is good for a quantization model? | closed | 2024-04-26T00:36:31Z | 2024-07-31T10:04:18Z | https://github.com/AutoGPTQ/AutoGPTQ/issues/649 | [] | ehuaa | 7 |
huggingface/pytorch-image-models | pytorch | 1,162 | [FEATURE] Adding a column to CSVs to sort by architecture type | For certain contexts, it is interesting to look at only convolution-based models (and/or compare to attention-based architectures). To facilitate this, there could be an optional column in the [CSV](https://github.com/rwightman/pytorch-image-models/blob/master/results/results-imagenet.csv) files.
E.g., this column ... | closed | 2022-03-02T20:46:44Z | 2023-08-30T05:14:48Z | https://github.com/huggingface/pytorch-image-models/issues/1162 | [
"enhancement"
] | rasbt | 3 |
strawberry-graphql/strawberry | graphql | 3,551 | (Relay) Output ID instead of GlobalID in GraphQL schema | Request to output the `ID` scalar instead of `GlobalID`, while generating the GraphQL schema
My understanding is that `GlobalID` was meant to be an internal helper that resolves nodes, but ended up being a custom scalar.
<!--- Provide a general summary of the changes you want in the title above. -->
<!--- This ... | open | 2024-06-28T04:17:46Z | 2025-03-20T15:56:46Z | https://github.com/strawberry-graphql/strawberry/issues/3551 | [] | aryaniyaps | 6 |
pydata/pandas-datareader | pandas | 915 | Sandbox api not being considered | I'm using sandboxed (test) data from IEX which is being pulled from https://sandbox.iexapis.com and
the `pandas_datareader()` function isn't taking those in consideration. I've looked at the code and in the array or list
of expected sources `sandbox.iexapi.com` is missing hence can't be used. | open | 2021-10-30T07:41:45Z | 2021-10-30T07:41:45Z | https://github.com/pydata/pandas-datareader/issues/915 | [] | codinghedgehog-python | 0 |
521xueweihan/HelloGitHub | python | 2,415 | 【开源自推】MBBS论坛-无依赖一键启动的全功能论坛 | ## 推荐项目
<!-- 这里是 HelloGitHub 月刊推荐项目的入口,欢迎自荐和推荐开源项目,唯一要求:请按照下面的提示介绍项目。-->
<!-- 点击上方 “Preview” 立刻查看提交的内容 -->
<!--仅收录 GitHub 上的开源项目,请填写 GitHub 的项目地址-->
- 项目地址:https://github.com/linfaxin/MBBS
<!--请从中选择(C、C#、C++、CSS、Go、Java、JS、Kotlin、Objective-C、PHP、Python、Ruby、Rust、Swift、其它、书籍、机器学习)-->
- 类别:JS
<!--请用 ... | open | 2022-11-04T09:05:17Z | 2022-11-23T06:56:57Z | https://github.com/521xueweihan/HelloGitHub/issues/2415 | [
"JavaScript 项目"
] | linfaxin | 0 |
iMerica/dj-rest-auth | rest-api | 147 | Minimal example for SPA implementation of social login | First of all many thanks for the great work! I am dedicated to use this package for project I'm working on. However, I have spent a few days now trying to understand the code of allauth and this package in order to build a simple social auth REST API for a SPA app (Angular) and I just fail to understand how a social lo... | open | 2020-09-20T15:58:18Z | 2021-02-02T19:32:54Z | https://github.com/iMerica/dj-rest-auth/issues/147 | [
"documentation",
"help wanted"
] | nimame | 3 |
STVIR/pysot | computer-vision | 577 | 多GPU训练问题 | 您好,请问多个GPU训练相比于单个GPU训练,除了训练速度提升外,对训练完成后模型的跟踪精度有影响吗? | open | 2022-07-14T03:30:03Z | 2023-03-27T04:56:37Z | https://github.com/STVIR/pysot/issues/577 | [] | lsy15554400368 | 1 |
xmu-xiaoma666/External-Attention-pytorch | pytorch | 2 | How is the reproduced performance? | Hi, it's a great and concise reimplementation of MLP works. Meanwhile, I'm wondering how is the performance of reimplemented version compares to the reported performance of the manuscripts? It would be very appreciated if you could show the results of the experiment.
| open | 2021-05-31T03:28:04Z | 2021-05-31T03:33:33Z | https://github.com/xmu-xiaoma666/External-Attention-pytorch/issues/2 | [] | CheerM | 1 |
docarray/docarray | pydantic | 917 | docs: code snippet needed: Document construct | The [construct page](https://docarray.jina.ai/fundamentals/document/construct/#unknown-attributes-handling) doesn't have a code snippet for `unknown_fields_handler`
Note: Please leave snippet as comment, don't fix directly. I'm working on docs right now and don't want merge conflicts | closed | 2022-12-08T13:39:08Z | 2023-04-22T09:38:29Z | https://github.com/docarray/docarray/issues/917 | [] | alexcg1 | 0 |
mitmproxy/mitmproxy | python | 7,340 | mitmproxy incorrectly upgrades http to https | #### Problem Description
I have the following use case:
* If a request made to a certain domain, then return a static webpage.
* All other HTTP traffic should be forwarded to an upstream proxy through mitmproxy.
I use the following command to start the proxy:
`mitmproxy -m upstream:https://<upstream-proxy-I... | closed | 2024-11-22T21:45:55Z | 2024-12-03T23:40:36Z | https://github.com/mitmproxy/mitmproxy/issues/7340 | [
"kind/triage"
] | m7Rahm | 2 |
pallets-eco/flask-sqlalchemy | sqlalchemy | 1,242 | When using the aliased method for tables, the like method encounters precision issues, and during join operations, there is a possibility of field loss. | <!--
When setting aliases for the database, using the 'like' fuzzy search on its fields will lead to incorrect precision.
Additionally, when using aliases for tables, performing a join operation with other tables using foreign key fields (I am unsure if this is a crucial triggering condition) will result in an error.... | closed | 2023-07-31T12:52:57Z | 2023-08-15T00:53:20Z | https://github.com/pallets-eco/flask-sqlalchemy/issues/1242 | [] | cansustar | 0 |
modin-project/modin | data-science | 6,897 | Groupby tests on MPI are failing | If you would run:
```
MODIN_ENGINE=unidist MODIN_CPUS=2 mpiexec -n 1 python -m pytest modin/pandas/test/test_groupby.py::test_groupby_sort[True-True] -v
```
You would get this error:
```
modin/pandas/test/test_groupby.py::test_groupby_sort[True-True] Traceback (most recent call last):
File "<string>", line 1, ... | closed | 2024-01-31T13:33:08Z | 2024-01-31T15:28:30Z | https://github.com/modin-project/modin/issues/6897 | [
"Testing 📈",
"P0",
"unidist"
] | dchigarev | 0 |
dmlc/gluon-nlp | numpy | 787 | Port XLNet to gluonnlp | https://github.com/zihangdai/xlnet
https://arxiv.org/abs/1906.08237
| closed | 2019-06-20T20:52:54Z | 2019-10-16T22:48:53Z | https://github.com/dmlc/gluon-nlp/issues/787 | [
"enhancement"
] | eric-haibin-lin | 2 |
autokey/autokey | automation | 303 | expand abbreviations even after ' or ( | ## Classification:
Feature
## Reproducibility:
Always
## Version
**AutoKey version**: Gtk 0.95.1 (also occurs in 0.95.6 with GTK and Qt front ends)
**Installed via**: (PPA, pip3, …): Kubuntu package
**Linux Distribution**: Kubuntu 18.04
## Summary
Abbreviations don't expand after the «'»,... | open | 2019-08-11T09:22:17Z | 2020-04-03T11:40:27Z | https://github.com/autokey/autokey/issues/303 | [
"bug",
"phrase expansion",
"autokey triggers"
] | DoctorSubtilis | 12 |
encode/apistar | api | 80 | Browsable API | Because, well, y'know.
It's kinda our baby. | closed | 2017-04-20T14:31:20Z | 2018-09-25T14:48:28Z | https://github.com/encode/apistar/issues/80 | [
"Baseline feature"
] | tomchristie | 3 |
rougier/numpy-100 | numpy | 125 | There is a wrong answer in 16 | Two answers are given to 16, one is using np.pad and the second is using indexing.
```
Z = np.ones((5,5))
Z = np.pad(Z, pad_width=1, mode='constant', constant_values=0)
print(Z)
# Using fancy indexing
Z[:, [0, -1]] = 0
Z[[0, -1], :] = 0
print(Z)
```
But the first one **adds** a new border and the secon... | open | 2020-06-18T08:44:28Z | 2020-09-15T07:55:06Z | https://github.com/rougier/numpy-100/issues/125 | [] | atomAltera | 7 |
dsdanielpark/Bard-API | api | 62 | image not displayed | query: "give me an image of maa Saraswati"
when I pass this query to Bard via API, following is the response:
'Sure, here is an image of Maa Saraswati.\n[Image of Maa Saraswati]'
however, when I give this same query to Bard via the chat, it shows me a relevant image
please help resolve this | closed | 2023-06-14T04:04:57Z | 2023-06-15T08:48:31Z | https://github.com/dsdanielpark/Bard-API/issues/62 | [] | MohitSM18 | 0 |
kornia/kornia | computer-vision | 2,083 | Implement `VectorType` and subclass `Vector2` / `Vector3` | we need to possibly add later again `VectorType` and subclass `Vector2` / `Vector3`
_Originally posted by @edgarriba in https://github.com/kornia/kornia/pull/1987#discussion_r1047025707_
| open | 2022-12-13T11:38:37Z | 2022-12-13T11:38:37Z | https://github.com/kornia/kornia/issues/2083 | [] | edgarriba | 0 |
PaddlePaddle/models | nlp | 5,222 | 运行3d_version里面的pointrcnn模型编译自定义的op出错。 | 直接在ai stuidio下运行,paddle版本2.0.0-rc.post101,gcc version 7.5.0 (Ubuntu 7.5.0-3ubuntu1~16.04),按照pointrcnn模型的GitHub教程来,运行 sh make.sh,报以下错误,
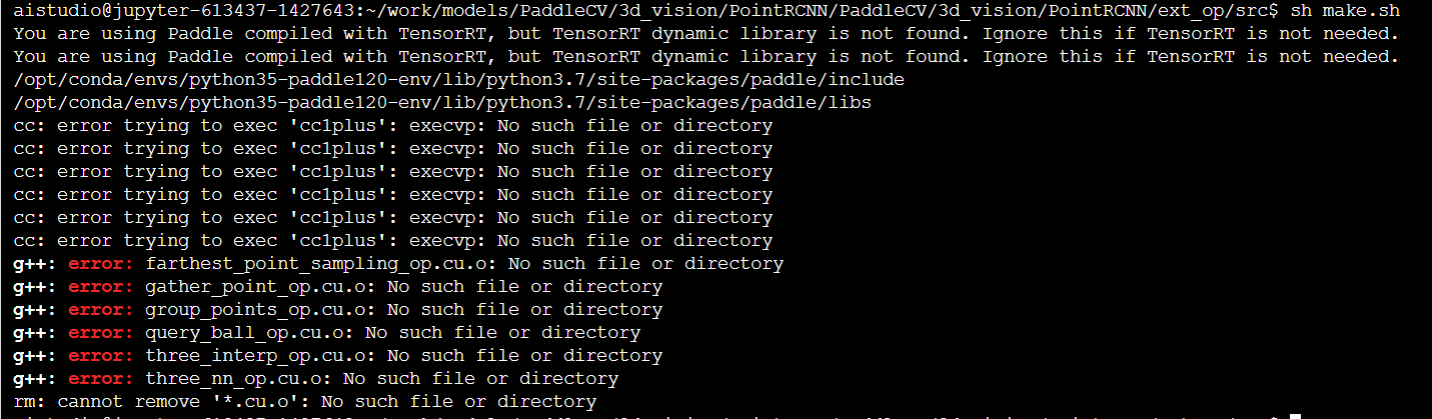,网上百度过觉得是gcc 和g++版本不一致的问题,终端查看g++是这样子的

.add(so.Bar(), so.Hist(), so.Dodge())
)
```

For now we can workaround by setting `... | open | 2022-08-28T11:48:03Z | 2022-09-01T10:36:01Z | https://github.com/mwaskom/seaborn/issues/2981 | [
"rough-edge",
"objects-move"
] | mwaskom | 0 |
python-restx/flask-restx | flask | 370 | Swagger: Path parameter generated outside of request method | It seems like the definition of path parameter in swagger is generated outside of request method. On the other hand, for query parameters it's inside of the method. Swagger 2.0 specification indicates that they both should be generated inside request method - https://swagger.io/docs/specification/describing-parameters/... | open | 2021-08-27T09:59:12Z | 2021-08-27T09:59:12Z | https://github.com/python-restx/flask-restx/issues/370 | [
"bug"
] | mkurdzie | 0 |
PaddlePaddle/PaddleNLP | nlp | 9,716 | paddle-pipelines安装问题 | ### 软件环境
```Markdown
- paddlepaddle:
- paddlepaddle-gpu:
- paddlenlp:
```
### 重复问题
- [X] I have searched the existing issues
### 错误描述
```Markdown
[Bug]: 在AI studio中folk项目PaddleNLP Pipelines带你十分钟搭建检索系统时安装paddle-pipelines时,提示依赖包需要安装typing_extensions版本为5.6但是paddle-pipelines本身的requirement要求是5.5版本,而且paddle-piplines... | closed | 2024-12-29T13:55:58Z | 2025-03-15T00:21:34Z | https://github.com/PaddlePaddle/PaddleNLP/issues/9716 | [
"bug",
"stale"
] | aishuwei | 2 |
Kludex/mangum | asyncio | 181 | Bug - handler.body returns a str resulting in TypeError: a bytes-like object is required, not 'str' | First this bug was introduced post 0.11.0 when the handlers were refactored.
**Traceback**
```
Exception in 'http' protocol.
--
Traceback (most recent call last):
File "/function/src/mangum/mangum/protocols/http.py", line 81, in run
await app(self.request.scope, self.receive, self.send)
File "/usr/local/lib/p... | closed | 2021-04-15T20:29:48Z | 2021-04-17T05:49:20Z | https://github.com/Kludex/mangum/issues/181 | [
"bug"
] | nathanglover | 1 |
TvoroG/pytest-lazy-fixture | pytest | 33 | Lazy fixtures not working at all | I had a few lazy fixtures loaded in some of my tests like this:
```
@pytest.mark.parametrize('user_group', [
pytest.lazy_fixture('user_group_national_manager'),
pytest.lazy_fixture('user_group_regional_manager'),
pytest.lazy_fixture('user_group_lwi_staff')
])
```
Now, when the test... | closed | 2019-01-09T12:35:20Z | 2019-01-10T09:07:53Z | https://github.com/TvoroG/pytest-lazy-fixture/issues/33 | [] | brian-barba-hernandez | 8 |
kymatio/kymatio | numpy | 712 | JTFS laundry | @lostanlen and I bulleted two threads; I'll organize unresolved points here. List probably incomplete, will update
### Unanswered (may add to Todo)
None
### Todo
- [ ] 1. move implementation notes?
- [ ] 2. performance guide?
- [ ] 3. rebase into `new-dev`?
- [ ] 4. merge `axis=None` fix in `Unified... | closed | 2021-04-07T11:33:21Z | 2022-05-30T15:20:47Z | https://github.com/kymatio/kymatio/issues/712 | [
"enhancement"
] | OverLordGoldDragon | 0 |
babysor/MockingBird | pytorch | 292 | 纯小白,虚心求教几个问题 | 1.工具箱打开的音频文件应该选择什么?是任意音频还是别的?
2.训练了50k左右,polt图一直都是一条横线,并未呈现对角线趋势。
3.目录中wav里面生成的音频声音听起来类似无线电信号很差的那种感觉,但可以勉强辨别内容。
4.工具箱生成的声音则是完全一个音节从头到尾一直念,而且完全无法辨别,机械音严重
5.我拿来训练的素材大概有800条短句音频,都是纯单人人声的,是数量不够还是音频质量不行呢?
虚心求教,谢谢 | closed | 2021-12-25T00:25:04Z | 2022-01-03T12:19:40Z | https://github.com/babysor/MockingBird/issues/292 | [] | anyfdj | 2 |
apache/airflow | data-science | 47,200 | Not able to view task logs with KE when deployed using helm chart | **Apache Airflow version**
3.0.0b1
**If "Other Airflow 2 version" selected, which one?**
No response
**What happened?**
**How to reproduce**
1. Create a deployment using breeze k8s
2. Try running dags
3. Check tasks logs
**Logs**
```
*** Attempting to fetch logs from pod tutorial-taskflow-api-load-zd9hqrqu th... | closed | 2025-02-28T08:01:54Z | 2025-03-01T03:33:53Z | https://github.com/apache/airflow/issues/47200 | [
"area:logging",
"kind:meta",
"priority:critical",
"affected_version:3.0.0beta"
] | vatsrahul1001 | 0 |
netbox-community/netbox | django | 18,448 | Ruff missing some previous pycodestyle caught errors | ### Proposed Changes
We need to come up with a way to catch some of the more common formatting errors we see within our codebase.
### Justification
Previously pycodestyle would catch E121, E126, E131, and E203. Unfortunately Ruff is not catching these | open | 2025-01-21T16:22:03Z | 2025-01-24T14:59:20Z | https://github.com/netbox-community/netbox/issues/18448 | [
"type: housekeeping",
"status: under review"
] | DanSheps | 0 |
Miserlou/Zappa | flask | 1,349 | uncaught exception in StopIteration (similar to #960) | My app appears to work, but instead of returning a result to the browser, I get
`"{u'message': u'An uncaught exception happened while servicing this request. You can investigate this with the `zappa tail` command.', u'traceback': ['Traceback (most recent call last):\\n', ' File \"/var/task/handler.py\", line 452, i... | closed | 2018-01-12T18:47:13Z | 2018-04-06T21:18:59Z | https://github.com/Miserlou/Zappa/issues/1349 | [
"non-bug"
] | teledyn | 6 |
hankcs/HanLP | nlp | 961 | data中缺少segment文件夹? | <!--
注意事项和版本号必填,否则不回复。若希望尽快得到回复,请按模板认真填写,谢谢合作。
-->
## 注意事项
请确认下列注意事项:
* 我已仔细阅读下列文档,都没有找到答案:
- [首页文档](https://github.com/hankcs/HanLP)
- [wiki](https://github.com/hankcs/HanLP/wiki)
- [常见问题](https://github.com/hankcs/HanLP/wiki/FAQ)
* 我已经通过[Google](https://www.google.com/#newwindow=1&q=HanLP)和[issue区检... | closed | 2018-09-06T13:23:26Z | 2018-09-13T09:32:08Z | https://github.com/hankcs/HanLP/issues/961 | [
"question"
] | TianFengshou | 6 |
AUTOMATIC1111/stable-diffusion-webui | deep-learning | 15,584 | [Bug]: AttributeError: 'NoneType' object has no attribute 'lowvram' | ### Checklist
- [X] The issue exists after disabling all extensions
- [ ] The issue exists on a clean installation of webui
- [ ] The issue is caused by an extension, but I believe it is caused by a bug in the webui
- [X] The issue exists in the current version of the webui
- [ ] The issue has not been reported ... | closed | 2024-04-21T12:03:21Z | 2024-06-08T12:04:40Z | https://github.com/AUTOMATIC1111/stable-diffusion-webui/issues/15584 | [
"bug-report"
] | mertayd0 | 5 |
strawberry-graphql/strawberry | django | 2,959 | Can not use Union with custom Strawberry types inside a generic type. | When trying to return union type of custom types, the schema generator fails.
## Describe the Bug
Two custom types declared, and one that contains the union of them.
```python
T = TypeVar("T")
@strawberry.type
class MySubType:
data: str
@strawberry.type
class MySubType2:
data: int
@strawb... | open | 2023-07-17T13:49:06Z | 2025-03-20T15:56:18Z | https://github.com/strawberry-graphql/strawberry/issues/2959 | [
"bug"
] | anwitars | 1 |
tensorpack/tensorpack | tensorflow | 883 | what is the exactly eviroment of Fasterrcnn example runs on? | Hi Yuxin Wu,
I tried to run your FasterRcnn example on the below setting ,the total cost and wd cost are all nan
tensorpack: 0.8.8(from source)
tensorflow: 1.10.0
python: 3.6
Than I tried anathoer envriroment which is as below, and the code work now. I have no idea why it fail in the newest version.
tensorpa... | closed | 2018-09-02T01:32:55Z | 2018-09-06T20:07:54Z | https://github.com/tensorpack/tensorpack/issues/883 | [
"unrelated"
] | AlgoHunt | 5 |
TracecatHQ/tracecat | pydantic | 265 | [FEATURE IDEA] Handle expected exceptions gracefully in workflows | **Is your feature request related to a problem? Please describe.**
The current architecture for actions does not give a way to allow the user to determine what to do when a "failure" occurs. The current design is good enough for 500 errors where the failure is unexpected, but we're using raise_for_status in a lot of ... | closed | 2024-07-24T00:02:16Z | 2024-11-06T01:17:54Z | https://github.com/TracecatHQ/tracecat/issues/265 | [
"enhancement",
"frontend",
"engine",
"priority:medium"
] | mattdurant | 5 |
s3rius/FastAPI-template | asyncio | 126 | Adding an admin panel option when setting up the template | Hey 👋🏽
What are opinions on adding an option to add an admin panel/dashboard which just displays the db tables set up in the template?
The dashboard would be served separately
Thinking about options such as:
- https://github.com/fastapi-admin/fastapi-admin (seems like the more appropriate choice but never... | open | 2022-10-05T14:07:24Z | 2023-01-12T15:43:32Z | https://github.com/s3rius/FastAPI-template/issues/126 | [] | haffi96 | 7 |
biolab/orange3 | numpy | 6,701 | Orange not connecting to internet to update add-ons | <!--
Thanks for taking the time to report a bug!
If you're raising an issue about an add-on (i.e., installed via Options > Add-ons), raise an issue in the relevant add-on's issue tracker instead. See: https://github.com/biolab?q=orange3
To fix the bug, we need to be able to reproduce it. Please answer the following... | closed | 2024-01-09T18:53:59Z | 2024-02-26T08:16:28Z | https://github.com/biolab/orange3/issues/6701 | [
"bug report"
] | flogistof | 4 |
jessevig/bertviz | nlp | 3 | Using the attention to summarize a document | I've been looking for a tool which can give me some type of token-based extractive summarization to solve an especially interesting problem in the Competitive Debate community. I think that this tool will help me solve it.
I've wanted to create a neural network which summarizes texts by using a "highlighter", that ... | closed | 2019-02-13T06:14:05Z | 2020-01-16T16:18:33Z | https://github.com/jessevig/bertviz/issues/3 | [] | Hellisotherpeople | 2 |
serengil/deepface | deep-learning | 1,144 | FaceNet model has InceptionResNetV1 backbone instead of InceptionResNetV2 | In the backbone of model, model name is incorrectly mentioned as v2 instead of v1: https://github.com/serengil/deepface/blob/master/deepface/basemodels/Facenet.py#L100
As i confirmed from its training documentation, we are using v1: https://sefiks.com/2018/09/03/face-recognition-with-facenet-in-keras/
Besides, re... | closed | 2024-03-26T16:20:14Z | 2024-03-28T18:40:41Z | https://github.com/serengil/deepface/issues/1144 | [
"documentation"
] | serengil | 1 |
StratoDem/sd-material-ui | dash | 729 | Providing initial Picker value causes inconsistent timezone behavior | ## Description
Thanks for providing this awesome library! Below is the issue I'm experiencing, and I tried to provide as much initial research/info as possible hoping that's helpful.
**Issue**
When passing an initial value to the Picker, it appears that it takes the server default timezone and displays a diffe... | closed | 2021-07-01T13:40:34Z | 2021-07-29T13:06:33Z | https://github.com/StratoDem/sd-material-ui/issues/729 | [] | MCBoarder289 | 3 |
geopandas/geopandas | pandas | 2,504 | BUG: CPLE_AppDefinedError: SQLite error on SELECT, cannot read the dbf/shp after installing in a separate environment - | - [OK ] I have checked that this issue has not already been reported.
- [ OK] I have confirmed this bug exists on the latest version of geopandas.
- [ ] (optional) I have confirmed this bug exists on the main branch of geopandas.
---
```
import os
import re
import zipfile
import numpy as np
import matplo... | closed | 2022-07-21T15:22:17Z | 2022-07-22T05:34:27Z | https://github.com/geopandas/geopandas/issues/2504 | [
"installation"
] | AI-Tax | 6 |
ScrapeGraphAI/Scrapegraph-ai | machine-learning | 6 | Make the tests | In the section tests | closed | 2024-01-31T08:19:55Z | 2024-02-13T15:11:08Z | https://github.com/ScrapeGraphAI/Scrapegraph-ai/issues/6 | [
"tests"
] | VinciGit00 | 0 |
automl/auto-sklearn | scikit-learn | 928 | Cannot fit using a new classifier | After adding the MLPClassifier component as mentioned [here](https://automl.github.io/auto-sklearn/master/examples/example_extending_classification.html), I am unable to fit the model. Here's the output that I am getting: '[(1.000000, MyDummyClassifier(configuration=1, init_params=None, random_state=None)),\n]'
... | closed | 2020-08-21T05:26:52Z | 2021-05-22T01:58:44Z | https://github.com/automl/auto-sklearn/issues/928 | [
"bug"
] | svsaraf112 | 8 |
koxudaxi/datamodel-code-generator | fastapi | 1,450 | Unique items should be allowed as list in Pydantic v2 | **Describe the bug**
When Pydantic v2 is used, i.e., `--output-model-type pydantic_v2.BaseModel`, any field tagged with unique items will always be created as set. Where it is understandable to use set to ensure unique items, there is a distinct difference between set and list. Some important ones are:
* Set does not... | closed | 2023-07-25T02:18:28Z | 2023-08-09T15:34:07Z | https://github.com/koxudaxi/datamodel-code-generator/issues/1450 | [
"bug"
] | xu-cheng | 4 |
geopandas/geopandas | pandas | 2,561 | DOC: fix doc build failing with pydata-sphinx-theme 0.10.1 | `make html` fails with below error when using **pydata-sphinx-theme** 0.10.1
```
Theme error:
An error happened in rendering the page about.
Reason: KeyError('self')
make: *** [html] Error 2
```
re-create in a highly cut down env
```
import os, shutil
from pathlib import Path
from sphinx.cmd.build import... | closed | 2022-09-23T16:26:01Z | 2022-10-15T09:47:15Z | https://github.com/geopandas/geopandas/issues/2561 | [
"upstream issue"
] | rraymondgh | 2 |
kizniche/Mycodo | automation | 1,107 | PI Camera: Cannot stop Video Stream, Frontend Crashed when taking photo | Issue:
I cannot stop a live stream (PiCamera) and when taking a photo (raspistill) with Pi HQ Camera the Web GUI just hangs and after a while returns Bad Gateway Error. The live stream also does not display in the Web GUI and the 'stop stream' button doesn't work.
After this I cannot access the Web GUI again, but... | closed | 2021-10-26T20:03:51Z | 2022-02-06T21:42:57Z | https://github.com/kizniche/Mycodo/issues/1107 | [] | jacopienaar | 1 |
globaleaks/globaleaks-whistleblowing-software | sqlalchemy | 4,095 | Update new version 4.14.8 to 4.15.5 | ### Discussed in https://github.com/orgs/globaleaks/discussions/4091
<div type='discussions-op-text'>
<sup>Originally posted by **esperti** June 3, 2024</sup>
Hi
I am trying to update the version of Globaleaks to 4.15.5 from 4.14.8, following the steps outlined in the documentation. When executing the command ... | closed | 2024-06-05T05:08:51Z | 2024-06-05T06:57:19Z | https://github.com/globaleaks/globaleaks-whistleblowing-software/issues/4095 | [] | esperti | 2 |
microsoft/nni | deep-learning | 4,832 | 'BatchNorm2d' does not match 'BatchNorm1d' | config_list = [{
'total_sparsity': 0.5,
'op_types': ['BatchNorm1d'],
'max_sparsity_per_layer': 0.9
}]
traced_optimizer = nni.trace(torch.optim.Adam)(model_train.parameters(), lr=0.01, weight_decay=5e-4)
pruner = SlimPruner(model_train, config_list, trainer, traced_optimizer, cr... | open | 2022-05-03T09:18:50Z | 2022-05-05T01:50:49Z | https://github.com/microsoft/nni/issues/4832 | [] | daixiangzi | 1 |
junyanz/pytorch-CycleGAN-and-pix2pix | deep-learning | 1,248 | Issue with combine_A_and_B | Hello!
I tried to combine A and B, having two separated sets including train,test and val. But I get this error:

If I try it with --no_multiprocessing it does not produce anything. I was wondering what... | open | 2021-03-09T16:32:10Z | 2024-09-30T02:30:53Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/1248 | [] | sinievanderben | 9 |
biolab/orange3 | pandas | 6,692 | Is there a limit to the number of algorithm widgets that should be run in a single workflow? | <!--
This is neither a bug report nor a feature request. We are using Orange for Kaggle competitions. To accomplish this we are adjusting every algorithm in multiple ways (HPO) leading to 100+ algorithms (widgets) per workflow. We have noticed that when we have a large number of widgets in a workflow the performance r... | closed | 2024-01-04T17:17:43Z | 2024-01-05T09:07:48Z | https://github.com/biolab/orange3/issues/6692 | [] | rehoyt | 1 |
MycroftAI/mycroft-core | nlp | 2,622 | Default play_* system settings on picroft are hard coded to device 0,0 | ## Introduction
Have been using mycroft on a Linux system for a while, switching to the lower power picroft on raspberry pi. The installation was fairly smooth, however I've run into a bit of "awkward" defaults resulting in lost hours until I figured out all the audio configuration components.
Hoping to walk us ... | closed | 2020-06-20T13:41:45Z | 2024-09-08T08:35:16Z | https://github.com/MycroftAI/mycroft-core/issues/2622 | [] | fermulator | 8 |
apify/crawlee-python | web-scraping | 814 | Ensure compatibility with pydantic-settings v2.7 | The workaround for https://github.com/apify/crawlee-python/issues/146 is not working in `pydantic-settings` v2.7+.
This construction is problematic:
```python
Configuration(
crawlee_storage_dir=str(tmp_path), # type: ignore[call-arg]
# ...
)
```
This constrution is used on many places in tests, e.g. for `Con... | open | 2024-12-13T13:47:11Z | 2025-01-20T11:34:21Z | https://github.com/apify/crawlee-python/issues/814 | [
"t-tooling"
] | vdusek | 0 |
PrefectHQ/prefect | data-science | 17,017 | Validation error when using anonymous volumes | ### Bug summary
It looks like Prefect's validation doesn't allow anonymous volumes. This is my volume configuration:
<img width="548" alt="Image" src="https://github.com/user-attachments/assets/8f91b48e-a923-4745-8a32-be386c68368f" />
That throws the following Validation error:
```
19:30:34.753 | ERROR | prefect.... | closed | 2025-02-06T19:46:55Z | 2025-02-07T01:07:56Z | https://github.com/PrefectHQ/prefect/issues/17017 | [
"bug"
] | anze3db | 2 |
influxdata/influxdb-client-python | jupyter | 236 | Drop a Bucket and Create a Bucket | Are there commands to drop a bucket and to create a bucket from the Python API, similar to the functions drop_database and create_catabase in the influxClient Version 1,8? | closed | 2021-04-24T14:52:45Z | 2024-06-25T18:04:42Z | https://github.com/influxdata/influxdb-client-python/issues/236 | [
"question"
] | yareblo | 6 |
deezer/spleeter | tensorflow | 520 | Cannot allocat | <!-- PLEASE READ THIS CAREFULLY :
- Any issue which does not respect following template or lack of information will be considered as invalid and automatically closed
- First check FAQ from wiki to see if your problem is not already known
-->
## Description
<!-- Give us a clear and concise description of the bu... | open | 2020-11-18T09:09:45Z | 2020-11-20T14:19:53Z | https://github.com/deezer/spleeter/issues/520 | [
"bug",
"invalid"
] | chenny2020 | 1 |
huggingface/text-generation-inference | nlp | 2,560 | Image for arm64 (Macbook Pro) | ### System Info
Which image should I use on Macbook Pro? I can't find arm64 image. Please see the below error I'm having:
```
1 warning found (use docker --debug to expand):
- InvalidBaseImagePlatform: Base image ghcr.io/huggingface/text-generation-inference:sha-f3c5d7d@sha256:7c169c536de65dbdb867302aedf9ad0a747... | open | 2024-09-24T19:07:25Z | 2024-10-18T11:16:53Z | https://github.com/huggingface/text-generation-inference/issues/2560 | [] | arsentievalex | 1 |
davidsandberg/facenet | computer-vision | 559 | Questions about the set of batch_size and epoch_size | Hi david,
I notice that you set batch_size=90 and epoch_size=1000 in the training and iterates about 80 times totally, but the whole number of images used for training is about 490k, so I dont know whether every image is used 80×90×1000/490k=14 times ?
What's more, I train on my own dataset which contains 9000 images... | closed | 2017-11-29T14:45:53Z | 2017-11-30T14:17:08Z | https://github.com/davidsandberg/facenet/issues/559 | [] | zzw1123 | 1 |
sinaptik-ai/pandas-ai | data-science | 1,559 | Regarding httpx client configuration AzureOpenAI | Hi Team,
I tried httpx client configuration for http_client parameter in AzureOpenAI and set ssl verification to false. But still it does not configure it and get SSL CERT verification failed on chatting with Agent. With AzureOpenAI from openai the httpx client configuration works. Any workaround for the same?
Thanks... | closed | 2025-01-29T17:44:26Z | 2025-01-30T17:42:44Z | https://github.com/sinaptik-ai/pandas-ai/issues/1559 | [] | prasum | 1 |
dgtlmoon/changedetection.io | web-scraping | 2,546 | changedetection.io subscription api missing | Hello,
I signed-up through [changedetection.io](http://changedetection.io/) but I can't seem to push a website for tracking. I am using https://lemonade.changedetection.io/api/v1/watch
but it returned 404 | closed | 2024-08-05T02:08:24Z | 2024-08-05T08:45:50Z | https://github.com/dgtlmoon/changedetection.io/issues/2546 | [
"triage"
] | sidnetopia | 2 |
ets-labs/python-dependency-injector | flask | 323 | Achieving DI during run time | I have a python CLI application toolkit that other apps can use through a docker image. I want to use this library to achieve DI. I want to understand how to achieve DI during run time as my toolkit needs to read the YAML configuration from the application, perform some operations, and then decide which path to take. F... | closed | 2020-11-10T23:15:04Z | 2020-11-12T20:53:53Z | https://github.com/ets-labs/python-dependency-injector/issues/323 | [
"question"
] | tellmeaboutcode | 5 |
explosion/spaCy | machine-learning | 13,459 | spacy Transformers shows 0 in Losses_trf while training |
Hi,
Actually, I am using spacy_trf to train my custom NER model. Trained with RoBERTa and to predict 13 entities which is related to automobile industry. Please find the metrics of training pipeline and config.cfg below for your reference. After training, I could see 0's in LOSS TRANSFORMER and some numbers in LOS... | closed | 2024-04-26T09:32:51Z | 2024-05-15T10:53:47Z | https://github.com/explosion/spaCy/issues/13459 | [
"usage",
"training",
"feat / ner",
"feat / transformer"
] | VK-T | 1 |
redis/redis-om-python | pydantic | 678 | `redis.client.Pipeline` is not imported correctly | [Here](https://github.com/redis/redis-om-python/blob/82406f0dbf3c271f327b49917321ba0dc1624143/aredis_om/model/model.py#L1509) and possibly in many other places the `Pipeline` symbol is not imported correctly, because `redis.client` is not imported and only `redis` is.
I believe this is mostly a type-checking issue and ... | open | 2025-02-10T13:17:35Z | 2025-02-10T13:17:35Z | https://github.com/redis/redis-om-python/issues/678 | [] | sashkent3 | 0 |
zappa/Zappa | flask | 1,137 | Update front page docs to include Python 3.9 support | ## Context
It appears Zappa supports [supports 3.9](https://github.com/zappa/Zappa/pull/1026) but front page doesn't mention that. This made me think twice about using this wonderful framework. Maybe I am wrong?
Also, when filing this Issue there is this statement in the issue generator itself:
"<!- Also, please m... | closed | 2022-06-14T13:48:59Z | 2022-07-16T05:16:34Z | https://github.com/zappa/Zappa/issues/1137 | [
"documentation"
] | nicholashughes | 1 |
roboflow/supervision | pytorch | 899 | Cannot import certain packages | ### Search before asking
- [X] I have searched the Supervision [issues](https://github.com/roboflow/supervision/issues) and found no similar feature requests.
### Question
In the collab; even after updation the errors looks like this.
`---------------------------------------------------------------------------
At... | closed | 2024-02-14T04:16:50Z | 2024-02-14T04:20:13Z | https://github.com/roboflow/supervision/issues/899 | [
"question"
] | NandiniLReddy | 0 |
mwaskom/seaborn | data-science | 2,782 | No simple way to access statistics of central tendency and bootstrap confidence intervals from e.g., catplot, lineplot | I wasn't able to find a way to access the resulting statistics of central tendency and confidence intervals in catplot, lineplot etc. These results should be accessible. If I'm going to report a confidence interval or a p-value for a statistical test, I'd prefer to show the confidence intervals from the same bootstrap ... | closed | 2022-04-24T08:45:55Z | 2022-04-24T11:55:49Z | https://github.com/mwaskom/seaborn/issues/2782 | [] | Riley16 | 1 |
netbox-community/netbox | django | 17,777 | Updating datasource from git repo fails: "No module named 'dulwich'" | ### Deployment Type
Self-hosted
### Triage priority
N/A
### NetBox Version
4.1.4
### Python Version
3.10
### Steps to Reproduce
Configure a new data source of the type "Git"
Update the data source by clicking the "Sync" button
### Expected Behavior
The job should complete without error... | closed | 2024-10-16T15:48:55Z | 2024-10-16T16:01:06Z | https://github.com/netbox-community/netbox/issues/17777 | [] | fallenfuzz | 0 |
seleniumbase/SeleniumBase | pytest | 3,219 | ModuleNotFoundError: No module named 'seleniumbase.undetected.cdp_driver' | ### `ModuleNotFoundError: No module named 'seleniumbase.undetected.cdp_driver'`
There's a missing line in `packages` in `pyproject.toml`. I will have that fixed shortly...
Was working for me because I was working from a cloned SeleniumBase repo, which has all the folders.
But it wouldn't be shipped to PyPI if it... | closed | 2024-10-24T12:43:04Z | 2024-10-24T14:14:37Z | https://github.com/seleniumbase/SeleniumBase/issues/3219 | [
"bug",
"UC Mode / CDP Mode"
] | mdmintz | 1 |
microsoft/nni | data-science | 5,540 | getting cude_cores:Function Not Found | **Describe the issue**:
The nni process is not running with nni3.0b1. I also tried a more stable nni versions (2.10 and 2.8)
I get the following error:
```root@9be40a2183c3:/app# nnictl create --config config.yml
Traceback (most recent call last):
File "/usr/local/bin/nnictl", line 8, in <module>
sys.exit(p... | open | 2023-05-04T11:12:48Z | 2023-05-17T02:08:53Z | https://github.com/microsoft/nni/issues/5540 | [] | TayyabaZainab0807 | 8 |
ploomber/ploomber | jupyter | 620 | ploomber examples into local directory | When running !ploomber examples -n guides/spec-api-python -o . it outputs an error:
Local copy does not exist...
Cloning into '/root/.ploomber/projects'...
remote: Enumerating objects: 416, done.
remote: Counting objects: 100% (416/416), done.
remote: Compressing objects: 100% (335/335), done.
remote: Total 416... | closed | 2022-02-27T15:12:49Z | 2022-05-08T18:00:33Z | https://github.com/ploomber/ploomber/issues/620 | [
"good first issue"
] | idomic | 3 |
aleju/imgaug | machine-learning | 109 | Chance of no augmentation being applied | It seems there's always a chance of no augmentation applied. Is it possible to make sure that at least 1 random augmentation is applied? | open | 2018-03-20T06:32:32Z | 2019-03-05T00:41:18Z | https://github.com/aleju/imgaug/issues/109 | [] | CMCDragonkai | 5 |
zappa/Zappa | django | 810 | [Migrated] Slow Cold Starts Becasue App Code Loaded Inside of Lambda Handler | Originally from: https://github.com/Miserlou/Zappa/issues/1974 by [ElMoselYEE](https://github.com/ElMoselYEE)
## Context
For my Flask + Zappa setup, I noticed that the app code gets loaded inside of the lambda_handler. This prevents us from taking advantage of the bumped up horsepower that Amazon providers for free ... | closed | 2021-02-20T12:51:55Z | 2022-08-19T08:49:20Z | https://github.com/zappa/Zappa/issues/810 | [] | jneves | 1 |
junyanz/pytorch-CycleGAN-and-pix2pix | computer-vision | 1,504 | After training, the line of the generated images is very bold | Using the default config, i test and get the generated images below:
<img width="436" alt="image" src="https://user-images.githubusercontent.com/11350088/200770789-ae87d1ec-6b9a-4885-be9f-0a1bb697b67a.png">
I do not know why. And I have cleaned the dataset. Can you give me some suggestions on how to solve such prob... | open | 2022-11-09T07:53:52Z | 2022-11-14T03:22:28Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/1504 | [] | zccoder | 2 |
ultralytics/ultralytics | machine-learning | 18,967 | cannot find coco.yaml | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and found no similar bug report.
### Ultralytics YOLO Component
Other
### Bug
## I use Windows 11 Home ##
. This causes collisions when the training code sets a fixed random... | closed | 2024-01-19T06:32:25Z | 2024-01-26T15:05:35Z | https://github.com/huggingface/datasets/issues/6604 | [] | normster | 2 |
explosion/spaCy | machine-learning | 13,489 | phrasematcher attr='LOWER' fails initialization when used in a pipeline | <!-- NOTE: For questions or install related issues, please open a Discussion instead. -->
## How to reproduce the behaviour
Using the example provided in https://spacy.io/usage/processing-pipelines#custom-components-attributes for RESCountriesComponents.
Update the matcher to the following:
self.matcher = Phra... | closed | 2024-05-14T15:29:43Z | 2024-06-14T00:02:41Z | https://github.com/explosion/spaCy/issues/13489 | [] | larrymccutchan | 3 |
CorentinJ/Real-Time-Voice-Cloning | pytorch | 983 | How to train from scratch | Hey, I must say your project is very helpful. Could you please mention the process of training over any dataset from scratch or how to make changes in synthesizer/vcoder layers? As when I execute the demo, I can upload the voice and synthesize and vecode as well. the dataset option is not enabeled there? So, I am confu... | open | 2022-01-14T14:47:12Z | 2022-01-19T12:33:17Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/983 | [] | rabbia970 | 1 |
thunlp/OpenPrompt | nlp | 235 | 'PromptForGeneration' object has no attribute 'can_generate' | Hi,
I'm trying to replicate the tutorial on Conditional Generation using T5-base model and I encountered error in the `evaluation()` function of tutorial and the error is following:
`'PromptForGeneration' object has no attribute 'can_generate'`
Any help on this will be appreciated | closed | 2023-01-27T02:01:34Z | 2023-02-04T15:07:12Z | https://github.com/thunlp/OpenPrompt/issues/235 | [] | chiranthans23 | 0 |
ultralytics/ultralytics | deep-learning | 19,101 | Can I train in yolo8 custom dataset the include different size of images? 2048X2048 and 1536X2048? | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
Can I train in yolo8 custom dataset the include different size of images? 20... | open | 2025-02-06T14:38:02Z | 2025-02-06T15:31:29Z | https://github.com/ultralytics/ultralytics/issues/19101 | [
"question",
"detect"
] | roy-orfaig | 2 |
aleju/imgaug | machine-learning | 202 | uint16 SegmentationMapOnImage | I think it is quite common to encode masks using uint16, therefore I would suggest to enable this format for the `SegmentationMapOnImage` class.
It seems like this format is not supported yet: https://github.com/aleju/imgaug/blob/69ac72ef4f2b9d5de62c7813dcf3427ca4a604b5/imgaug/imgaug.py#L4814 | closed | 2018-11-07T00:47:56Z | 2019-01-06T15:25:21Z | https://github.com/aleju/imgaug/issues/202 | [
"enhancement",
"TODO"
] | martinruenz | 2 |
Lightning-AI/pytorch-lightning | data-science | 20,199 | LightningCLI: --help argument given after the subcommand fails | ### Bug description
I'm trying to use LightningCLI to configure my code from the command line but LightningCLI is seeming to have trouble parsing the default logger of the trainer when I run the following:
```
python test.py fit -h
```
However, just running the command without the -h flag works.
### What ve... | open | 2024-08-14T04:24:17Z | 2024-11-08T09:01:45Z | https://github.com/Lightning-AI/pytorch-lightning/issues/20199 | [
"bug",
"needs triage",
"ver: 2.4.x"
] | nisar2 | 5 |
freqtrade/freqtrade | python | 10,960 | Hyperliquid - rate limit because of stoploss_on_exchange | ## Describe your environment
* Operating system: linux
* Python Version: 3.12
* CCXT version: 4.4.31
* Freqtrade Version: docker-2024.11-dev-f545274a
## Describe the problem:
Hyperliquid turns out to be a bit restrictive with limits. I'm hitting this because stoploss_on_exchange and related API calls. Releva... | closed | 2024-11-19T21:56:40Z | 2024-11-21T20:07:48Z | https://github.com/freqtrade/freqtrade/issues/10960 | [
"CCXT"
] | gaardiolor | 10 |
huggingface/transformers | python | 36,254 | Is T5 model supported with HQQ quantization ? (AttributeError: 'HQQLinear' object has no attribute 'weight') | ### System Info
- `transformers` version: 4.48.2
- Platform: Linux-6.8.0-52-generic-x86_64-with-glibc2.35
- Python version: 3.11.11
- Huggingface_hub version: 0.28.1
- Safetensors version: 0.5.2
- Accelerate version: 1.3.0
- Accelerate config: - compute_environment: LOCAL_MACHINE
- distributed_type: NO
- mixed_prec... | open | 2025-02-18T11:42:54Z | 2025-03-04T22:30:12Z | https://github.com/huggingface/transformers/issues/36254 | [
"bug"
] | szwagros | 6 |
dask/dask | scikit-learn | 11,155 | 'SeriesGroupBy' object has no attribute 'nunique_approx' | Please add 'nunique_approx' feature for 'SeriesGroupBy' object
| closed | 2024-05-30T09:22:32Z | 2024-08-12T20:46:21Z | https://github.com/dask/dask/issues/11155 | [
"needs info"
] | LeilaGold | 7 |
fastapi-users/fastapi-users | asyncio | 362 | Cannot Import from fastapi_users.db for Tortoise | Hi, i am a newbie trying to do learn how to use fastapi-users.
Following the example here [https://frankie567.github.io/fastapi-users/configuration/full_example/](https://frankie567.github.io/fastapi-users/configuration/full_example/), i was able to run with sqlalchemy and not tortoise orm
from fastapi_users.db i... | closed | 2020-10-10T09:34:12Z | 2020-10-10T17:08:12Z | https://github.com/fastapi-users/fastapi-users/issues/362 | [] | ihsanmohamad | 1 |
ray-project/ray | python | 51,466 | CI test windows://python/ray/tests:test_runtime_env_working_dir is consistently_failing | CI test **windows://python/ray/tests:test_runtime_env_working_dir** is consistently_failing. Recent failures:
- https://buildkite.com/ray-project/postmerge/builds/8965#0195aa97-1a6b-4f53-baac-e7b5018ef3ba
- https://buildkite.com/ray-project/postmerge/builds/8965#0195aa03-5c4e-451d-8c5b-c68039336cc5
DataCaseName-win... | closed | 2025-03-18T20:55:26Z | 2025-03-19T21:54:32Z | https://github.com/ray-project/ray/issues/51466 | [
"bug",
"triage",
"core",
"flaky-tracker",
"ray-test-bot",
"ci-test",
"weekly-release-blocker",
"stability"
] | can-anyscale | 4 |
onnx/onnxmltools | scikit-learn | 216 | Coreml to onnx conversion : conversion succeeded but incorrect value on inference | I am trying to convert a coreml model to onnx. The conversion succeeded but predict using winml doesn't give the same values of output as coreml.
I am doing the same proprocessing for onnx that I am doing for coreml before feeding the input. The coreml model gives the correct output , while onnx outputs much lower ... | closed | 2019-01-23T01:51:37Z | 2019-02-06T19:33:25Z | https://github.com/onnx/onnxmltools/issues/216 | [] | deovrat | 1 |
graphql-python/graphene | graphql | 1,396 | v3 upgrade documentation? | Similar to https://github.com/graphql-python/graphene/blob/master/UPGRADE-v2.0.md, is there a guide to upgrading to v3 from v2? I cannot seem to find any information beyond the list of changes from the GH release: https://github.com/graphql-python/graphene/releases/tag/v3.0.0
| closed | 2021-12-09T13:16:39Z | 2022-08-27T18:38:12Z | https://github.com/graphql-python/graphene/issues/1396 | [
"✨ enhancement"
] | mattbasta | 3 |
labmlai/annotated_deep_learning_paper_implementations | pytorch | 253 | Question about RoPE code | I found here exist a difference in rope implementation mostly on permutation. Does this difference not affect the final result ? I'm not quite sure what I'm thinking. Sincerely ask for your advice : )
Paper version should be:
![image](https://github.com/labmlai/annotated_deep_learning_paper_implementations/assets/... | closed | 2024-05-11T09:59:51Z | 2025-03-22T18:34:28Z | https://github.com/labmlai/annotated_deep_learning_paper_implementations/issues/253 | [
"question"
] | rangehow | 4 |
erdewit/ib_insync | asyncio | 432 | ib.connect timeout | I'm just getting my feet wet with the IB API and trying to use ib_insync. Just trying to run one of the recipes on the ib_insync doc site that simply gathers historical Tesla data and it will not connect.
I have coded successfully other apps using the native IB API and it connects, so I proved that it's not my sy... | closed | 2022-01-25T22:22:22Z | 2022-01-26T01:01:25Z | https://github.com/erdewit/ib_insync/issues/432 | [] | raenrfm | 1 |
iperov/DeepFaceLab | machine-learning | 725 | Crash when renaming a model | ## Expected behavior
When renaming a model, the program should succeed without any issue.
## Actual behavior
When renaming a model, the program crashes.
## Steps to reproduce
1. Create a new model named: ```Pretrain - LIAEHD Female```
2. After training the model, save and exit.
3. Execute Script 6 to ... | closed | 2020-04-20T21:43:53Z | 2022-12-09T01:56:00Z | https://github.com/iperov/DeepFaceLab/issues/725 | [] | spiceygas | 2 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.