
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
prkumar/uplink | rest-api | 105 | JSON Converter not converting | The following example gives this output:
> <class 'requests.models.Response'>
> Ran 2 tests in 0.743s
> OK
> <class 'requests.models.Response'>
Expected output:
> <class '....JokeSchema'>
> Ran 2 tests in 0.743s
> OK
> <class '....JokeSchema'>
Am I missing something here? Or is this a bug?
```
... | closed | 2018-08-17T21:25:36Z | 2018-10-09T20:21:33Z | https://github.com/prkumar/uplink/issues/105 | [
"Question"
] | mindrunner | 33 |
nschloe/tikzplotlib | matplotlib | 414 | scatter plot ignores marker sizes | MWE:
This bit of code plots open circles of a fixed but non-default size:
```
import matplotlib.pyplot as plt
from tikzplotlib import get_tikz_code
max_marker_size = 300
fig, ax = plt.subplots()
ax.scatter(
[1, 2, 3], [5, 7, 1],
s=[max_marker_size]*3,
facecolors='none', edgecolors='black', linew... | open | 2020-06-06T18:26:08Z | 2023-11-14T10:34:01Z | https://github.com/nschloe/tikzplotlib/issues/414 | [] | jgmakin | 4 |
lukas-blecher/LaTeX-OCR | pytorch | 285 | Slow training | Hi, I'm having a very strange problem here with slow training with my own training data. I've looked up the reason for this because the data is slow to load, on average it takes over 10 seconds to load data for 256 images, is there a particularly good solution? Or do I need to change the custom dataset to a dataloader?... | open | 2023-06-25T03:09:31Z | 2023-06-26T07:13:33Z | https://github.com/lukas-blecher/LaTeX-OCR/issues/285 | [] | with-him777 | 2 |
mars-project/mars | pandas | 3,188 | [BUG] Ray executor fetch slice failed | <!--
Thank you for your contribution!
Please review https://github.com/mars-project/mars/blob/master/CONTRIBUTING.rst before opening an issue.
-->
**Describe the bug**
A clear and concise description of what the bug is.
```python
_____________________________________________________________________________... | closed | 2022-07-12T11:34:36Z | 2022-07-28T03:35:26Z | https://github.com/mars-project/mars/issues/3188 | [
"type: bug",
"mod: ray integration"
] | fyrestone | 0 |
pytest-dev/pytest-qt | pytest | 128 | Assert none of a set of signals are emitted | I'd like to be able to assert that none of a set of signals are emitted, so it would be nice if `qtbot.assertNotEmitted` could take a list. Or is there some API for this I'm missing?
At the moment I'm doing
``` python
def test_set_name_same():
project = Project()
project.setName('Some name')
assert proje... | closed | 2016-04-20T07:34:11Z | 2016-04-20T07:57:42Z | https://github.com/pytest-dev/pytest-qt/issues/128 | [] | estan | 2 |
encode/apistar | api | 363 | Is this project alive? | Hello, we are developing a new API by minimal viable product concept, that may be used later in production, and i'm interested in trying apistar for this purpose.
So the question is: will this project be maintained or actively developed by Tom or some "core" team? I have checked insights and noticed that there was 1... | closed | 2017-11-22T20:40:26Z | 2017-11-22T20:46:48Z | https://github.com/encode/apistar/issues/363 | [] | asyncee | 2 |
microsoft/nni | data-science | 4,988 | Error: tuner_command_channel: Tuner loses responsive | **Describe the issue**:
`Error: tuner_command_channel: Tuner loses responsive` raised when training and then all processes exit.
**Environment**:
- NNI version:latest released
- Training service (local|remote|pai|aml|etc):Local
- Client OS:CentOS
- Python version:3.7.13
- PyTorch/TensorFlow version: No frame... | closed | 2022-07-06T02:22:32Z | 2022-08-06T09:29:31Z | https://github.com/microsoft/nni/issues/4988 | [
"bug",
"external contributor"
] | Sunny-Island | 11 |
matterport/Mask_RCNN | tensorflow | 2,853 | could anybody help? | 
| open | 2022-07-11T04:06:21Z | 2022-07-14T08:58:23Z | https://github.com/matterport/Mask_RCNN/issues/2853 | [] | STRUGGLE1999 | 2 |
biolab/orange3 | data-visualization | 6,963 | Selected lines in Line plot should show metadata | <!--
Thanks for taking the time to submit a feature request!
For the best chance at our team considering your request, please answer the following questions to the best of your ability.
-->
**What's your use case?**
<!-- In other words, what's your pain point? -->
<!-- Is your request related to a problem, or ... | open | 2024-12-20T14:54:36Z | 2025-01-10T16:54:36Z | https://github.com/biolab/orange3/issues/6963 | [] | kaimikael | 1 |
ultrafunkamsterdam/undetected-chromedriver | automation | 820 | We need you back Leon! | Hi Ultrafunkamsterdam, you have created such a useful tool for thousands of developers around the world. Please consider continuing your project! | closed | 2022-09-23T02:09:43Z | 2024-02-08T02:52:47Z | https://github.com/ultrafunkamsterdam/undetected-chromedriver/issues/820 | [] | gigacodr | 27 |
dynaconf/dynaconf | flask | 470 | Add the ability to load only a specified list of keys from envvars | **Describe the bug**
Migrating from other configuration systems I'd need to configure `envvar_prefix` to empty string (`""`) so I can load any environment variable I used before. But it doesn't seem to work with _dynaconf_.
**To Reproduce**
Steps to reproduce the behavior:
1. Create a basic dynaconf configurati... | closed | 2020-11-11T12:08:19Z | 2020-11-19T02:25:27Z | https://github.com/dynaconf/dynaconf/issues/470 | [
"enhancement",
"help wanted",
"question",
"RFC",
"Docs",
"good first issue",
"HIGH"
] | odiroot | 11 |
robotframework/robotframework | automation | 5,316 | Build and Test for Linux/ARM64 | ## Description
For aarch64 platform, I have built " Robot Framework " from source.
## Steps
Following STEPS (https://github.com/robotframework/robotframework#installation) were used for the building and installation:
~~~
sudo apt update
sudo apt install build-essential cmake git wget –y
get h... | open | 2025-01-16T05:37:04Z | 2025-01-16T13:21:49Z | https://github.com/robotframework/robotframework/issues/5316 | [] | odidev | 1 |
pydantic/logfire | pydantic | 150 | Log exceptions and maybe other events in the console | (Copy of https://linear.app/pydantic/issue/PYD-794/log-exceptions-and-maybe-other-events-in-the-console)
Encountered again here: https://pydanticlogfire.slack.com/archives/C06EDRBSAH3/p1715088823604819
For example this:
```python
import logfire
logfire.configure(console=logfire.ConsoleOptions(verbose=True)... | closed | 2024-05-07T13:41:54Z | 2024-05-13T15:57:23Z | https://github.com/pydantic/logfire/issues/150 | [] | alexmojaki | 0 |
apache/airflow | machine-learning | 48,145 | Inconsistent DAG fileloc when importing variables from another DAG file | ### Apache Airflow version
Other Airflow 2 version (please specify below)
### If "Other Airflow 2 version" selected, which one?
2.10.2
### What happened?
When importing a variable to a DAG from another DAG file, the fileloc of the imported DAG sometimes changes when parsing occurs. This happens inconsistently, but... | open | 2025-03-23T21:28:28Z | 2025-03-23T21:30:45Z | https://github.com/apache/airflow/issues/48145 | [
"kind:bug",
"area:core",
"area:UI",
"needs-triage"
] | Ibraitas | 1 |
chezou/tabula-py | pandas | 142 | Problems with the module extracting two or more tables | [example.pdf](https://github.com/chezou/tabula-py/files/3061284/example.pdf)
[example2.pdf](https://github.com/chezou/tabula-py/files/3061288/example2.pdf)
The trouble is that the module tends to have failure when i try to extract multiple tables from pdf files. Sometimes doesn´t appear the entire information or in... | closed | 2019-04-09T23:22:17Z | 2019-04-10T04:25:06Z | https://github.com/chezou/tabula-py/issues/142 | [] | edsilvaf | 1 |
CorentinJ/Real-Time-Voice-Cloning | deep-learning | 319 | Short Phrase Workaround? location of specific words in seconds | So as other people have mentioned here, the spectrogram synthesis struggles with short phrases. One workaround is that if you lengthen your text to something that takes 6 seconds or so to say, you can do much better, then manually crop out the filler text. However, has anyone had luck doing that in an automated way? (... | closed | 2020-04-12T14:37:56Z | 2020-06-01T18:24:53Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/319 | [] | sunnybala | 3 |
MaartenGr/BERTopic | nlp | 1,713 | Llama 2: Representation Model | In the documentation, it mentioned that:
_By default, four of the most representative documents will be passed to [DOCUMENTS]. These documents are selected by calculating their similarity (through c-TF-IDF representations) with the main c-TF-IDF representation of the topics. The four best matching documents per topi... | open | 2023-12-24T07:33:38Z | 2023-12-28T10:20:46Z | https://github.com/MaartenGr/BERTopic/issues/1713 | [] | Keamww2021 | 4 |
WZMIAOMIAO/deep-learning-for-image-processing | pytorch | 714 | faster rcnn换backbone的问题 | **System information**
UP你好,我参照视频讲backbone替换成efficientnet,当我使用官方的efficientnet时可以运行,但是用up提供的efficientnet时,出现错误,错误定位到efficientnet代码里drop_path函数的random_tensor = keep_prob + torch.rand(shape, dtype=x.dtype, device=x.device)这一行。我使用的torch是1.11.0,torchvision是0.12.0, cu113
**Error info / logs**
TypeError: rand() received ... | open | 2023-01-16T13:28:40Z | 2023-01-16T13:28:40Z | https://github.com/WZMIAOMIAO/deep-learning-for-image-processing/issues/714 | [] | fpgajames | 0 |
huggingface/peft | pytorch | 2,321 | [Warning] `Merge lora module to 4-bit linear may get different generations` | ### System Info
peft 0.14.0
transformers 4.48.0
bitsandbytes 0.45.0
### Who can help?
@BenjaminBossan @sayakpaul
### Information
- [ ] The official example scripts
- [X] My own modified scripts
### Tasks
- [ ] An officially supported task in the `examples` folder
- [ ] My own task or dataset (give details belo... | open | 2025-01-11T20:27:54Z | 2025-03-06T15:30:07Z | https://github.com/huggingface/peft/issues/2321 | [] | steveepreston | 15 |
keras-team/keras | machine-learning | 20,189 | Keras different versions have numerical deviations when using pretrain model | The following code will have output deviations between Keras 3.3.3 and Keras 3.5.0.
```python
#download model
from modelscope import snapshot_download
base_path = 'q935499957/Qwen2-0.5B-Keras'
import os
dir = 'models'
try:
os.mkdir(dir)
except:
pass
model_dir = snapshot_download(base_path,local_dir=d... | closed | 2024-08-30T11:21:08Z | 2024-08-31T07:38:23Z | https://github.com/keras-team/keras/issues/20189 | [] | pass-lin | 2 |
AirtestProject/Airtest | automation | 803 | 模拟器支持录屏吗 | @yimelia
模拟器运行脚本支持录屏吗?
我连接模拟器,并在运行命令后加--recording,控制台有报错,录屏无法生存,报错截图如下
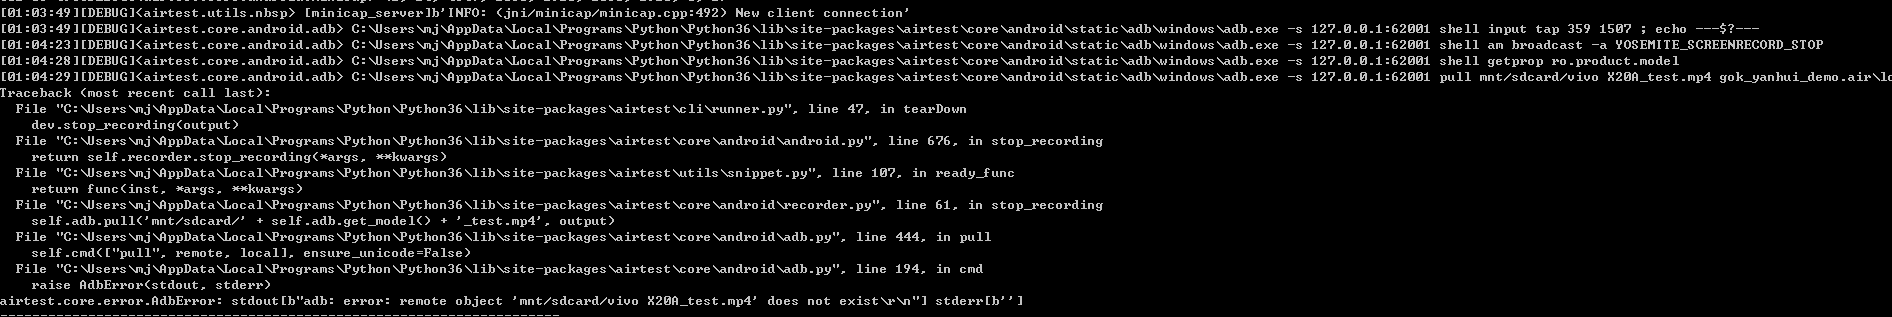
**python 版本:** `python3.6`
**airtest 版本:** `1.1.4`
**设备:**
夜神模拟器6.5.0.1
**其他相关环境信息**
windows7 64位
| closed | 2020-09-16T17:17:29Z | 2020-10-21T02:46:43Z | https://github.com/AirtestProject/Airtest/issues/803 | [] | ymdhtt | 1 |
littlecodersh/ItChat | api | 901 | Invalid URL: http://7xrip4.com1.z0.glb.clouddn.com/shiyanlou/itchat/2/main.py | 链接为 https://itchat.readthedocs.io/zh/latest/tutorial/tutorial0/
在第**七、代码获取**的你可以在**这里**下载。 | open | 2020-02-01T07:49:47Z | 2020-02-01T07:49:47Z | https://github.com/littlecodersh/ItChat/issues/901 | [] | JiaxiangBU | 0 |
pallets-eco/flask-wtf | flask | 119 | Access CsrfProtect instance from Blueprints. | I am wanting to exempt a route in my blueprint, but requires importing the CsrfProtect instance from my main module where Flask is also instantiated and the Blueprint is imported into. I end up with a circular import (main module imports Blueprint, Blueprint imports from main module to get csrf instance, circular impor... | closed | 2014-03-27T18:25:26Z | 2021-05-27T00:57:36Z | https://github.com/pallets-eco/flask-wtf/issues/119 | [] | nobane | 2 |
jupyter/nbviewer | jupyter | 664 | got 400: bad request to git repo with LFS enabled | My jupyter notebook renders ok on github, but not on nbviewer. I got error "400: Bad Request".
My notebook is here:
https://github.com/tarokiritani/in-vivo-wcr/blob/master/electrophysiology.ipynb | open | 2017-01-20T13:58:25Z | 2019-09-12T22:38:47Z | https://github.com/jupyter/nbviewer/issues/664 | [
"type:Enhancement",
"tag:Provider"
] | tarokiritani | 6 |
tiangolo/uvicorn-gunicorn-fastapi-docker | fastapi | 54 | Don't work on rpi | Hi, testing the image on a rpi3 won't work, I use the example from "how to use" and fail by exec format.
```
root@raspberrypi:~/uvicorn# tree
├── app
│ └── main.py
└── Dockerfile
root@raspberrypi:~/uvicorn# docker build -t myimage .
Sending build context to Docker daemon 3.584kB
Step 1/4 : FROM tiangolo/... | closed | 2020-07-23T16:15:20Z | 2020-12-08T17:51:22Z | https://github.com/tiangolo/uvicorn-gunicorn-fastapi-docker/issues/54 | [] | dubcl | 2 |
dynaconf/dynaconf | flask | 973 | Use Validator default value when validation fails? | Is there a way to reset/use the default value of a Validator fails to validate? I don't want to prevent my program from loading but if there's garbage in the settings file, I want to use a proper value like the default provided in Validator definition.
Thanks for this great module BTW and for the help! | open | 2023-08-02T20:13:20Z | 2024-07-01T09:58:02Z | https://github.com/dynaconf/dynaconf/issues/973 | [
"question",
"Docs",
"typed_dynaconf"
] | morpheus65535 | 5 |
Evil0ctal/Douyin_TikTok_Download_API | fastapi | 222 | [BUG] Docker部署请求失败 | 本地运行了几个月之后,最近就无法访问了,同样的链接,在wtf域名的80可以解析,docker的80会显示:
获取视频ID失败!
Input value: https://v.douyin.com/iyr9xcb/
本地Docker8000的API也无法正常运行了。
大佬你的80是可以用的,但https://api.douyin.wtf又开始500了。
是不是我IP被ban了?:( | closed | 2023-07-11T10:13:07Z | 2023-08-20T04:53:58Z | https://github.com/Evil0ctal/Douyin_TikTok_Download_API/issues/222 | [
"help wanted"
] | Ora2 | 3 |
Gozargah/Marzban | api | 1,305 | Marzban Front-End High Resource Usage | Run any web browser, Go to your Marzban panel, Open 'Host Settings' or 'Edit user' box

What is your opinion about it? is it normal or something is wrong?
\* I did not noticed it first, some tg users reported it and i did test... | open | 2024-09-06T12:11:23Z | 2024-09-14T15:52:12Z | https://github.com/Gozargah/Marzban/issues/1305 | [
"Bug",
"Frontend",
"P1",
"In Progress"
] | fodhelper | 5 |
gradio-app/gradio | deep-learning | 10,751 | blocks doc load js parameter description error | ### Describe the bug
Doc Bug:https://www.gradio.app/docs/gradio/blocks#blocks-load
After I try this js parameter, I think the description of js parameter should be:
Optional frontend js method to run before running 'fn'. Input arguments for js method are values of 'inputs' and 'outputs', return should be a list of v... | open | 2025-03-07T07:30:50Z | 2025-03-07T07:30:50Z | https://github.com/gradio-app/gradio/issues/10751 | [
"bug"
] | JinhaoPlus | 0 |
litestar-org/litestar | asyncio | 3,057 | Enhancement: Only generate example once when `Parameter(examples=[...])` is specified for path arg and its schema | ### Description
Explained below.
### MCVE
```python
import json
from litestar import Litestar, post
from litestar.openapi.spec import Example
from litestar.params import Parameter
@post("/{path_arg:str}")
def endpoint(
path_arg: str = Parameter(examples=[Example(value="EXAMPLE_VALUE")]),
) ->... | open | 2024-02-01T13:25:01Z | 2025-03-20T15:54:23Z | https://github.com/litestar-org/litestar/issues/3057 | [
"Enhancement",
"Help Wanted :sos:",
"area/openapi"
] | tuukkamustonen | 4 |
lepture/authlib | django | 169 | v0.13, django client: lazy-loading server metadata breaks logout flows | **Describe the bug**
Version 0.13 intoduces lazy loading of server metadata on first auth request, but this breaks logout flows for some OIDC providers (in my case, Keycloak).
Consider this logout view (django):
```
def logout(request):
""" log user out of django and redirect to the Keycloak logout url, so... | closed | 2019-11-17T17:53:57Z | 2020-02-11T14:06:38Z | https://github.com/lepture/authlib/issues/169 | [
"bug",
"good first issue",
"documentation"
] | kurtgn | 1 |
FujiwaraChoki/MoneyPrinter | automation | 85 | Critical Security Vulnerability: Heap-based Buffer Overflow in Pillow Library (CVE-2023-4863) | **Describe the bug**
A critical security vulnerability has been identified in the Pillow library, specifically a heap-based buffer overflow in the ReadHuffmanCodes() function. This vulnerability could potentially allow an attacker to craft a special WebP lossless file, triggering the buffer overflow and leading to arb... | closed | 2024-02-08T15:20:33Z | 2024-02-08T15:24:13Z | https://github.com/FujiwaraChoki/MoneyPrinter/issues/85 | [] | SandeepVashishtha | 0 |
onnx/onnx | pytorch | 6,087 | Move onnx/examples to /examples | The examples folder should not belong to the onnx/ package folder. | closed | 2024-04-15T03:24:19Z | 2024-07-18T20:22:12Z | https://github.com/onnx/onnx/issues/6087 | [] | justinchuby | 0 |
huggingface/text-generation-inference | nlp | 2,480 | Feature Request: Support for LLaMa 3.1 built-in tools | LLaMa 3.1 can use what is called built-in tools. These built-in tools are signaled to the executor by the special token `<python_tag>`, also they are not user-defined JSON tools. On top of that there is a new `iphython` role to signal tool results to the model.
Reference: https://llama.meta.com/docs/model-cards-and-p... | open | 2024-08-30T15:37:41Z | 2024-09-20T21:22:02Z | https://github.com/huggingface/text-generation-inference/issues/2480 | [] | martinigoyanes | 3 |
deepspeedai/DeepSpeed | pytorch | 6,806 | [BUG] Getting "SymIntArrayRef expected to contain only concrete integers" error when > 1 GPU | **Describe the bug**
When training on 8 GPUs on a single instance, there seems to be some obscure error, which results in NCCL communication timeout. Seems to always fail on the last step of the first epoch.
We are able to train the model with Deepspeed against a single GPU. This error seems to only surface when using... | open | 2024-11-28T21:46:58Z | 2024-11-28T23:00:49Z | https://github.com/deepspeedai/DeepSpeed/issues/6806 | [
"bug",
"training"
] | rileyhun | 0 |
KevinMusgrave/pytorch-metric-learning | computer-vision | 436 | Don't make recordable attributes dynamic | This seemed like a good idea when used with record-keeper, but it complicates things if you're not using record-keeper | closed | 2022-02-28T19:00:20Z | 2023-01-29T04:14:05Z | https://github.com/KevinMusgrave/pytorch-metric-learning/issues/436 | [
"enhancement"
] | KevinMusgrave | 0 |
babysor/MockingBird | deep-learning | 27 | 训练模型时显存爆了 | `Variable._execution_engine.run_backward(RuntimeError: CUDA out of memory. Tried to allocate 88.00 MiB (GPU 0; 4.00 GiB totalcapacity; 2.68 GiB already allocated; 0 bytes free; 2.85 GiB reserved in total by PyTorch)`
能不能提供一个调batch_size的参数? 我目前用的显卡显存只有4G(GTX1050Ti),默认参数正常训练时经常爆掉显存....
| closed | 2021-08-21T12:41:13Z | 2021-10-01T03:19:57Z | https://github.com/babysor/MockingBird/issues/27 | [] | cronfox | 11 |
HumanSignal/labelImg | deep-learning | 397 | Windows10 can't open the software these days |
Windows10 can't open the software these days | closed | 2018-11-21T01:07:28Z | 2018-12-03T07:12:40Z | https://github.com/HumanSignal/labelImg/issues/397 | [] | huaxv | 0 |
pydantic/pydantic-settings | pydantic | 103 | mypy complains about settings object | ### Initial Checks
- [X] I confirm that I'm using Pydantic V2 installed directly from the `main` branch, or equivalent
### Description
Mypy complains about my settings object.
```
$ mypy pydampy
pydampy/config.py:3: error: Cannot find implementation or library stub for module named "pydantic_settings" [i... | closed | 2023-07-05T07:03:11Z | 2023-07-05T11:01:26Z | https://github.com/pydantic/pydantic-settings/issues/103 | [
"unconfirmed"
] | sr-verde | 8 |
plotly/dash-table | plotly | 545 | case insensitive filtering | As discussed in https://community.plot.ly/t/case-insensitive-filter-search-for-dash-datatables/26258 | closed | 2019-08-14T17:20:55Z | 2021-09-16T17:12:43Z | https://github.com/plotly/dash-table/issues/545 | [
"dash-type-enhancement",
"dash-stage-in_review"
] | chriddyp | 10 |
ymcui/Chinese-LLaMA-Alpaca-2 | nlp | 558 | 微调后的lora模块 | ### 提交前必须检查以下项目
- [X] 请确保使用的是仓库最新代码(git pull),一些问题已被解决和修复。
- [X] 我已阅读[项目文档](https://github.com/ymcui/Chinese-LLaMA-Alpaca-2/wiki)和[FAQ章节](https://github.com/ymcui/Chinese-LLaMA-Alpaca-2/wiki/常见问题)并且已在Issue中对问题进行了搜索,没有找到相似问题和解决方案。
- [X] 第三方插件问题:例如[llama.cpp](https://github.com/ggerganov/llama.cpp)、[LangChain](https://g... | closed | 2024-04-05T02:55:53Z | 2024-05-01T22:04:56Z | https://github.com/ymcui/Chinese-LLaMA-Alpaca-2/issues/558 | [
"stale"
] | ymourenya | 9 |
wkentaro/labelme | deep-learning | 837 | [BUG] | **Describe the bug**
GUI does not pop up, only icon of gui
Message from Terminal:
[INFO ] init:get_config:70 - Loading config file from:
- Labelme Version [4.2.7]
| closed | 2021-02-11T08:50:35Z | 2022-06-25T04:48:03Z | https://github.com/wkentaro/labelme/issues/837 | [] | rikutar | 0 |
noirbizarre/flask-restplus | flask | 508 | How to document/model a POST endpoint with a plain raw body? | I'm trying to create a POST endpoint where the payload is just plain raw text. I can't seem to find a way to do so.
Essentially what I'd like is a swagger/flask-restplus way to handle the following curl command:
```
curl -X POST http://example.com/my/endpoint \
-d hello world
```
It looks like the proper swag... | open | 2018-08-06T23:03:25Z | 2019-01-11T14:26:37Z | https://github.com/noirbizarre/flask-restplus/issues/508 | [] | AndyMan1 | 1 |
cvat-ai/cvat | computer-vision | 9,073 | Getting Jobs from Task Using API takes long time |
Hello, I am trying to get the jobID from task, i created an empty task first and then post my file to it using code below.
```
files[f"client_files[{0}]"] = (
image_name + ".png",
encoded_image,
)
task_url = self.cvat_client.api_map.make_endpoint_url(
self.cvat_client.api_cl... | closed | 2025-02-06T16:23:10Z | 2025-02-18T12:42:40Z | https://github.com/cvat-ai/cvat/issues/9073 | [
"question"
] | saad-abdullah62 | 4 |
dynaconf/dynaconf | flask | 603 | [bug] Use of the format marker occurs before overriding values through an environment variable | I'm not sure if this is a bug, but such logic is not described:
in `settings.toml` with setting `environments=True`:
```
[default.database]
DB_HOST = "127.0.0.1"
DB_PORT = "5432"
DB_ADDRES = "@format {this.database.DB_HOST}:{this.database.DB_PORT}"
```
Then, if the value `DB_PORT` will be overridden using the... | closed | 2021-06-24T10:57:07Z | 2023-07-13T19:11:01Z | https://github.com/dynaconf/dynaconf/issues/603 | [
"bug",
"duplicate",
"LazyIssue"
] | artctv | 1 |
tradingstrategy-ai/web3-ethereum-defi | pytest | 88 | Uniswap V3 swap doesn't show up in API documentation | The [Uniswap V3 swap code exists](https://github.com/tradingstrategy-ai/web3-ethereum-defi/blob/master/eth_defi/uniswap_v3/swap.py) and works, however the documentation for it doesn't show up.
https://web3-ethereum-defi.readthedocs.io/api/index.html | closed | 2023-02-15T16:00:38Z | 2023-02-18T09:58:16Z | https://github.com/tradingstrategy-ai/web3-ethereum-defi/issues/88 | [] | pbharrin | 1 |
deepspeedai/DeepSpeed | pytorch | 6,896 | prterun noticed that process rank 7 with PID 0 on node gpu0304 exited on signal 6 (Aborted). | the setup is the same as https://github.com/microsoft/DeepSpeed/issues/6895#issue-2748924102
```
../aten/src/ATen/native/cuda/Indexing.cu:1290: indexSelectLargeIndex: block: [949,0,0], thread: [62,0,0] Assertion `srcIndex < srcSelectDimSize` failed.
../aten/src/ATen/native/cuda/Indexing.cu:1290: indexSelectLargeIndex:... | closed | 2024-12-19T00:18:44Z | 2025-01-31T18:56:45Z | https://github.com/deepspeedai/DeepSpeed/issues/6896 | [] | fabiogeraci | 3 |
google/seq2seq | tensorflow | 150 | Link pre-trained models from docs | Would you please consider linking pre-trained models for each of the configurations in https://github.com/google/seq2seq/tree/master/example_configs from the docs?
Lots of exploratory research involves fine-tuning an existing model, looking at output, applying a model in a new way, etc. So, lots of people are really... | open | 2017-04-06T21:08:28Z | 2017-05-04T13:01:53Z | https://github.com/google/seq2seq/issues/150 | [] | papajohn | 3 |
MycroftAI/mycroft-core | nlp | 2,567 | dialog_renderer None if valid dialog directory does not exist | ## Issue:
If a Skill does not have a valid `dialog` or `locale` directory, and attempts to speak some dialog using strings within the Skill eg
```
self.speak_dialog('say something')
```
then the method fails as the `dialog_renderer` has not been assigned:
```
File "/home/kris/mycroft-core/mycroft/skills/mycr... | closed | 2020-05-06T02:17:37Z | 2020-09-15T12:40:44Z | https://github.com/MycroftAI/mycroft-core/issues/2567 | [
"help wanted"
] | krisgesling | 2 |
simple-login/app | flask | 832 | Double-encrypted PGP emails with attachments gets garbled in Thunderbird | ## Prerequisites
- [X] I have searched open and closed issues to make sure that the bug has not yet been reported.
## Bug report
**Describe the bug**
Attachments are not properly handed in Thunderbird (shows as 0 bytes files) when the default mailbox in SimpleLogin is set up with a public PGP key to encrypt all... | open | 2022-03-07T10:13:33Z | 2022-03-21T17:20:52Z | https://github.com/simple-login/app/issues/832 | [] | ta4563321 | 4 |
lux-org/lux | jupyter | 110 | Error displaying widget: model not found | Hey Team Lux,
i just installed Lux and the nbextension as described in the Qiuck install section to explore its capabilities and ran into the following error message after hitting the "Toggle Pandas/Lux" button.
 Model for Time Series Forecasting | ## Proposal to Integrate IBM Granite Tiny Time Mixer (TTM) into AutoGluon Time Series Module
### Description
I propose adding support for the **IBM Granite Tiny Time Mixer (TTM)** model to the `timeseries` module of **AutoGluon**. TTM is a lightweight, pre-trained model specifically designed for multivariate time... | closed | 2024-12-16T18:47:33Z | 2024-12-21T07:55:45Z | https://github.com/autogluon/autogluon/issues/4740 | [
"enhancement"
] | Killer3048 | 0 |
deepset-ai/haystack | nlp | 8,964 | `ChatMessage.to_openai_dict_format()` ignores the `name` field | **Describe the bug**
`Chat Message`s have an optional `name` field which is handled by `ChatMessage.from_openai_dict_format()` but ignored by `ChatMessage.to_openai_dict_format()`.
**Expected behavior**
I would expect the name to be transmitted to the LLM.
**FAQ Check**
- [x] Have you had a look at [our new FAQ page]... | closed | 2025-03-04T16:07:25Z | 2025-03-05T09:29:38Z | https://github.com/deepset-ai/haystack/issues/8964 | [
"type:bug"
] | richardpaulhudson | 1 |
SALib/SALib | numpy | 559 | multiprocessing does not work with PyCharm console | As first reported by @morrowcj
> @ConnectedSystems, resource monitor confirmed that the parallel evaluator works as expected when run in a terminal. However, I have been unsuccessful getting it to run in pycharm. I'll start a new issue for that.
> Edit: never mind, this is a Pycharm issue. I can't run any code us... | open | 2023-03-21T07:42:18Z | 2023-03-22T16:02:11Z | https://github.com/SALib/SALib/issues/559 | [
"bug"
] | ConnectedSystems | 1 |
chainer/chainer | numpy | 7,785 | Flaky test: `chainerx_tests/unit_tests/routines_tests/test_arithmetic.py::test_TrueDivide` | https://jenkins.preferred.jp/job/chainer/job/chainer_pr/1624/TEST=CHAINERX_chainerx-py3,label=mn1-p100/console
```
11:51:15 FAIL repo/tests/chainerx_tests/unit_tests/routines_tests/test_arithmetic.py::test_TrueDivide_param_79_{in_dtypes=('float16', 'float16'), out_dtype='float16', in_shapes=((1, 1, 1), (2, 3, 4)), in... | closed | 2019-07-22T03:55:19Z | 2019-08-28T07:55:27Z | https://github.com/chainer/chainer/issues/7785 | [
"cat:test",
"prio:high"
] | niboshi | 3 |
modin-project/modin | pandas | 6,771 | `Series.cumsum` failed with the following error: `ValueError: assignment destination is read-only` | Modin: b8323b5f46e25d257c08f55745c018197f7530f5
```python
import modin.pandas as pd
pd.Series([1, 2, 3], dtype="Int64").cumsum() # <- ValueError: assignment destination is read-only
``` | closed | 2023-11-27T18:20:24Z | 2023-11-28T12:00:27Z | https://github.com/modin-project/modin/issues/6771 | [
"bug 🦗",
"P1"
] | anmyachev | 0 |
lepture/authlib | flask | 2 | Version 0.2 | I'm planning to finish all features at Version 0.5. Version 0.2 will still focus on the client part, and we will start the implementation of server/provider from Version 0.3.
- [x] Finish Django Client
- [x] Documentation on Django Client
- [x] Simple OpenID Connect support (id_token parsing)
- [x] Documentation ... | closed | 2017-11-18T06:54:09Z | 2017-11-25T12:34:43Z | https://github.com/lepture/authlib/issues/2 | [
"client",
"in future"
] | lepture | 1 |
lepture/authlib | django | 408 | authorize_access_token broken POST? | Hello, I'm really not sure if it is a bug, but when I am trying to use authorize_access_token there is no params in POST body, as I understand they are sending in a new TCP packet (see a tcpdump picture)?
```
oauth = OAuth()
oauth.register(
'zoom',
client_id=os.environ['ZOOM_CLIENT_ID'],
client_secr... | closed | 2021-12-04T07:35:07Z | 2022-03-15T10:28:31Z | https://github.com/lepture/authlib/issues/408 | [
"bug"
] | akam-it | 2 |
ultralytics/ultralytics | python | 18,687 | YOLOv8 detection head intuitive feature specialization (e.g., small/medium/large object focus) | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/ultralytics/ultralytics/discussions) and found no similar questions.
### Question
I have repeatedly read and observed that in the case of YOLOv3, the d... | open | 2025-01-14T19:59:12Z | 2025-01-15T18:15:15Z | https://github.com/ultralytics/ultralytics/issues/18687 | [
"question",
"detect"
] | leethologica | 4 |
davidsandberg/facenet | computer-vision | 948 | Pre-trained models (20170512-110547) VS Pre-trained models (20180402-114759) | Hello, David! First of all, thank you very much for sharing the pre-training model, which is very helpful to my learning.I just tested your new version of pre-training model (20180402-114759), but to my surprise, the effect is very poor. It doesn't work as well as the older version (20170512-110547).Can you help me?
T... | open | 2019-01-05T10:08:35Z | 2020-10-10T04:09:02Z | https://github.com/davidsandberg/facenet/issues/948 | [] | tensorflowt | 8 |
postmanlabs/httpbin | api | 558 | Is it possible to set a response header to httpbin by passing a parameter? | I deploys multiple httpbin instances in my GKE cluster, and each httpbin is running in a pod.
A client is sending requests that could reach any of the httpbin pods. By checking the response, I need to know that response is sent by which httpbin, and it would be helpful if I can set a unique response header to differen... | closed | 2019-06-11T00:25:53Z | 2019-09-05T05:03:45Z | https://github.com/postmanlabs/httpbin/issues/558 | [] | JimmyCYJ | 1 |
feature-engine/feature_engine | scikit-learn | 275 | [Feat]: Mutual Information in SmartCorrelatedSelection method | **Is your feature request related to a problem? Please describe.**
Mutual Information help identifies different type of relationships between variables, not only linear relationships like Pearson or monotonic relations like spearman.
**Describe the solution you'd like**
[SmartCorrelatedSelection](https://gith... | closed | 2021-06-22T22:18:08Z | 2021-07-14T06:30:35Z | https://github.com/feature-engine/feature_engine/issues/275 | [] | TremaMiguel | 6 |
gradio-app/gradio | data-science | 10,279 | [Image] - Image is not rendered completely | ### Describe the bug
If I load a 2 Megapixel image into the component it is not rendered correctly, only halfway and I get an error in the log. I need to keep the component area at 300x300.
### Have you searched existing issues? 🔎
- [X] I have searched and found no existing issues
### Reproduction
```python
imp... | closed | 2025-01-02T20:30:07Z | 2025-01-31T03:25:42Z | https://github.com/gradio-app/gradio/issues/10279 | [
"bug"
] | elismasilva | 3 |
gee-community/geemap | streamlit | 1,393 | It is not possible to select layers in menu | <!-- Please search existing issues to avoid creating duplicates. -->
### Environment Information
Please run the following code on your computer and share the output with us so that we can better debug your issue:
```python
import geemap
geemap.Report()
```
:
datetime_after = DateTime(required=False, default_value=datetime.min)
datetime_before =... | open | 2020-12-08T09:39:35Z | 2023-07-13T03:42:17Z | https://github.com/graphql-python/graphene/issues/1293 | [
"🐛 bug"
] | lookpl | 1 |
horovod/horovod | tensorflow | 3,606 | torch.utils.ffi was removed but is still used in horovod | **Environment:**
1. Framework: PyTorch
2. Framework version: 1.12.0
3. Horovod version: 0.25.0
4. MPI version: OpenMPI 4.1.4
5. CUDA version: N/A
6. NCCL version: N/A
7. Python version: 3.9.13
8. Spark / PySpark version: N/A
9. Ray version: N/A
10. OS and version: macOS 12.4
11. GCC version: Apple Clang 13.1... | closed | 2022-07-16T07:08:51Z | 2022-08-11T07:09:57Z | https://github.com/horovod/horovod/issues/3606 | [
"bug"
] | adamjstewart | 2 |
lepture/authlib | flask | 391 | Allow passing in additional header to the JWT client assertion | I'd like to pass in addtional JWT headers into the client assertion, such as the `kid` so the recipient of the token can find the corresponding key at the registered JWKS endpoint.
**Describe the solution you'd like**
When setting up an `PrivateKeyJWT()` instance to register as client auth method, I'd like to pas... | closed | 2021-09-28T10:29:59Z | 2021-10-18T12:18:16Z | https://github.com/lepture/authlib/issues/391 | [] | janwijbrand | 1 |
ultrafunkamsterdam/undetected-chromedriver | automation | 1,683 | Issue: Script Deleting and Redownloading undetected-chromedriver Every Run - How to Resolve? | Every time I run my script, it deletes the already downloaded 'undetected-chromedriver' and downloads it again. How can I solve this issue? | open | 2023-11-25T13:28:27Z | 2024-01-23T04:13:43Z | https://github.com/ultrafunkamsterdam/undetected-chromedriver/issues/1683 | [] | eem1r | 5 |
healthchecks/healthchecks | django | 288 | Request: Ability to clone or duplicate a check | I'm creating checks for a bunch of servers. It would be nice if I could just clone or duplicate them instead of modifying the schedules and other values over and over. | closed | 2019-09-17T13:22:30Z | 2019-11-02T02:10:05Z | https://github.com/healthchecks/healthchecks/issues/288 | [] | ScottBeeson | 5 |
developmentseed/lonboard | data-visualization | 715 | [BUG] apply_categorical_cmap TypeError when passing pandas categories | ## Context
What results were you expecting? <br/>
Expected results are for `apply_categorical_cmap()` to return a color object that I could pass to `PathLayer.from_geopandas()`.
In version 0.9.2 the `apply_categorical_cmap()` function worked with the following call: `apply_categorical_cmap(df[attribute_to_map], cmap)... | open | 2024-12-03T18:31:05Z | 2024-12-05T16:29:52Z | https://github.com/developmentseed/lonboard/issues/715 | [
"bug"
] | z-clement | 2 |
iperov/DeepFaceLab | machine-learning | 5,729 | . | closed | 2023-09-27T13:59:04Z | 2023-09-27T14:03:56Z | https://github.com/iperov/DeepFaceLab/issues/5729 | [] | qqq490962996 | 0 | |
NullArray/AutoSploit | automation | 1,205 | Unhandled Exception (f53536a44) | Autosploit version: `4.0`
OS information: `Linux-4.19.0-6-amd64-x86_64-with-MX-19-patito_feo`
Running context: `autosploit.py`
Error mesage: `[Errno 2] No such file or directory: '/home/Dylan/Documents/AutoSploit/hosts.txt'`
Error traceback:
```
Traceback (most recent call):
File "/home/Dylan/Documents/AutoSploit/lib/... | closed | 2019-11-14T21:22:52Z | 2019-12-03T01:15:23Z | https://github.com/NullArray/AutoSploit/issues/1205 | [
"bug"
] | AutosploitReporter | 0 |
pandas-dev/pandas | pandas | 61,166 | ENH: Enable nsmallest/nlargest on object dtype | Is it possible to implement method DataFrame.nsorted that equivalent to `df.sort_values(by=["col1", "col2"], ascending=[True, False]).head(k)`, but with time complexity O(n log k)? I know about `nlargest` and `nsmallest` methods but unfortunately they work only with numeric columns.
Example:
```python
df.nsorted(k=6, ... | open | 2025-03-22T10:36:03Z | 2025-03-24T06:18:00Z | https://github.com/pandas-dev/pandas/issues/61166 | [
"Enhancement",
"Filters",
"Sorting"
] | Gri72 | 4 |
plotly/dash | dash | 2,270 | [BUG] Callback is called twice |
My environment:
dash 2.6.2
dash-core-components 2.0.0
dash-html-components 2.0.0
dash-renderer 0.23.0
dash-table 5.0.0
dash-bio 1.0.2
- OS: Mac OS Monterey
- Browser: Chrome
**Describe the bug**
I created a dash app with a drop down, a scattergram and a clu... | closed | 2022-10-13T01:18:02Z | 2022-10-26T02:35:44Z | https://github.com/plotly/dash/issues/2270 | [] | guosijia | 1 |
ploomber/ploomber | jupyter | 781 | Missing example in SQLUpload task | We're missing examples [here](https://docs.ploomber.io/en/latest/api/_modules/tasks/ploomber.tasks.SQLUpload.html#ploomber.tasks.SQLUpload)
- [ ] Add spec api example
- [ ] add python API example
- [ ] link to ETL example (which uses SQLUpload) | closed | 2022-05-17T16:45:31Z | 2022-09-06T01:57:26Z | https://github.com/ploomber/ploomber/issues/781 | [] | edublancas | 0 |
LibreTranslate/LibreTranslate | api | 518 | Migrate to Podman | Long term I'd be nice to use podman instead of docker since they are fully open source. | open | 2023-10-19T16:55:10Z | 2023-10-19T16:55:10Z | https://github.com/LibreTranslate/LibreTranslate/issues/518 | [
"enhancement"
] | pierotofy | 0 |
huggingface/transformers | python | 36,548 | Facing issue while getting model from Rag,pretrained | **Code**
`# Initialize the tokenizer and model
model_name = "facebook/rag-token-nq"
tokenizer = RagTokenizer.from_pretrained(model_name)
model = RagTokenForGeneration.from_pretrained(model_name)
# Initialize the retriever
retriever = RagRetriever.from_pretrained(model_name)
# Tokeniza... | open | 2025-03-05T03:18:44Z | 2025-03-05T03:18:44Z | https://github.com/huggingface/transformers/issues/36548 | [] | MAHESH18TECH | 0 |
graphql-python/graphene-django | django | 1,414 | Return object instead of string for FK field in SerializerMutation in Graphene Django | I have two models `ProjectType` and `Project` as follows
```
class ProjectType(Base):
name = models.CharField(max_length=100, unique=True)
class Meta:
db_table = 'project_types'
def __str__(self):
return self.name
class Project(Base):
name = models.CharField(max_length=1... | open | 2023-05-26T19:05:19Z | 2023-05-26T19:05:19Z | https://github.com/graphql-python/graphene-django/issues/1414 | [
"✨enhancement"
] | thomas-arun | 0 |
deeppavlov/DeepPavlov | nlp | 812 | Dialogue Bot for goal-oriented task issue. | from deeppavlov import build_model, configs
bot1 = build_model(configs.go_bot.gobot_dstc2, download=True)
----------------------------------------------------------------------
2019-04-22 06:18:37.365 INFO in 'deeppavlov.core.data.utils'['utils'] at line 63: Downloading from http://files.deeppavlov.ai/datasets/dst... | closed | 2019-04-22T06:23:36Z | 2019-04-23T08:33:43Z | https://github.com/deeppavlov/DeepPavlov/issues/812 | [] | Pem14604 | 2 |
pandas-dev/pandas | python | 60,485 | DOC: Closed parameter not intuitively documented in DataFrame.rolling | ### Pandas version checks
- [x] I have checked that the issue still exists on the latest versions of the docs on `main` [here](https://pandas.pydata.org/docs/dev/)
### Location of the documentation
https://pandas.pydata.org/pandas-docs/dev/reference/api/pandas.DataFrame.rolling.html
### Documentation prob... | closed | 2024-12-03T19:33:08Z | 2025-02-08T12:52:16Z | https://github.com/pandas-dev/pandas/issues/60485 | [
"Docs",
"Window"
] | caballerofelipe | 7 |
ultralytics/ultralytics | computer-vision | 19,474 | train a YOLO11n model on the Open Images V7 dataset | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
when I train a YOLO11n model on the Open Images V7 dataset,I encountered the... | closed | 2025-02-28T08:00:23Z | 2025-03-01T20:38:43Z | https://github.com/ultralytics/ultralytics/issues/19474 | [
"question",
"fixed",
"detect"
] | 1623021453 | 3 |
taverntesting/tavern | pytest | 462 | external functions in test | Hi, I'm new to Tavern and the languages associated with it. I'm hoping someone can help me with a problem I'm having when adding a function to a test...
**sub-domain-generator.py**
```
import random
username = "tuser"
number = random.randint(1, 10000000)
def sub_domain_generator():
sub_domain = usernam... | closed | 2019-10-10T12:10:37Z | 2019-10-22T09:21:56Z | https://github.com/taverntesting/tavern/issues/462 | [] | ghost | 2 |
strawberry-graphql/strawberry | django | 2,951 | The page debug-toolbar on documentation website is broken | <!--- Provide a general summary of the changes you want in the title above. -->
This page does not exist:
https://strawberry-graphql.github.io/strawberry-graphql-django/guides/debug-toolbar/
However, it's being referenced from Django Strawbery + page.
<!--- Anything on lines wrapped in comments like these... | closed | 2023-07-14T13:44:05Z | 2025-03-20T15:56:18Z | https://github.com/strawberry-graphql/strawberry/issues/2951 | [
"info-needed"
] | polinom | 2 |
dantaki/vapeplot | matplotlib | 7 | Tests of vapeplot | Hi, I just wonder if you are planning to have some tests for vapeplot.
I think it would be good to have some tests.
However, I don't have an idea about what tests can be done for vapeplot.
If you have a idea, I would like to help. | closed | 2018-02-22T15:40:52Z | 2018-02-22T17:36:15Z | https://github.com/dantaki/vapeplot/issues/7 | [
"enhancement"
] | hsiaoyi0504 | 1 |
taverntesting/tavern | pytest | 648 | Switch to use jsonschema (or a library that can export jsonschema) instead of pykwalify | There are a few issues (eg https://github.com/taverntesting/tavern/issues/385 ) which are very hard to do without manually writing a lot of validation code because pykwalify can't do what we need it to do
If jsonschema is used instead of pykwalify we can also let people point to it in their pycharm setup so intellij... | closed | 2021-02-20T12:01:45Z | 2021-06-06T16:19:46Z | https://github.com/taverntesting/tavern/issues/648 | [] | michaelboulton | 0 |
koaning/scikit-lego | scikit-learn | 441 | [FEATURE] Zero-Inflated Regressor | Hi again!
I propose a meta estimator for dealing with zero-inflated datasets, i.e. where the labels y are zero quite often. The use-case is there since there is a large literature about zero-inflated Poisson models for counting, for example, as in [the paper "Predicting property damage from tornadoes with zero-infla... | closed | 2021-03-02T12:49:06Z | 2021-04-07T07:41:59Z | https://github.com/koaning/scikit-lego/issues/441 | [
"enhancement"
] | Garve | 3 |
AutoGPTQ/AutoGPTQ | nlp | 299 | [BUG] Installation fails due to AttributeError in setup.py on MacOS | **Describe the bug**
I attempted to install `auto-gptq` on my MacBook Pro running macOS and encountered an error related to the package's setup.py. The script seems to be attempting to extract the CUDA version from PyTorch, which results in an AttributeError.
**Hardware details**
OS: macOS [Ventura 13.5 (22G74)]
... | closed | 2023-08-29T07:01:00Z | 2023-10-26T16:19:45Z | https://github.com/AutoGPTQ/AutoGPTQ/issues/299 | [
"bug"
] | nashid | 1 |
errbotio/errbot | automation | 712 | Response from err-salt diverted to private message though config.py not set to divert. | Since this started after fixing #711, I thought it may be related. Reverting my change to config.py did not change this behavior.
# Config.py
```
# A list of commands which should be responded to in private, even if
# the command was given in a MUC. For example:
#DIVERT_TO_PRIVATE = ('help', 'about', 'status')
DIVERT_... | closed | 2016-04-09T19:18:23Z | 2016-04-09T22:26:46Z | https://github.com/errbotio/errbot/issues/712 | [] | jakosky | 1 |
streamlit/streamlit | data-visualization | 9,944 | `y_min` and `y_max` not correctly honored in `*ChartColumn`. Input Values not clamped, if value range outside y limits defined in `column_config` | ### Checklist
- [X] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar issues.
- [X] I added a very descriptive title to this issue.
- [X] I have provided sufficient information below to help reproduce this issue.
### Summary
The scale in `LineChartColumn` and `B... | open | 2024-11-28T14:54:44Z | 2024-11-29T22:41:29Z | https://github.com/streamlit/streamlit/issues/9944 | [
"type:enhancement",
"feature:st.column_config"
] | jonasViehweger | 2 |
keras-team/keras | pytorch | 20,220 | MultiHeadAttention is using unoptimised einsum equations | ERROR: type should be string, got "https://github.com/keras-team/keras/blob/v3.5.0/keras/src/layers/attention/multi_head_attention.py#L737 is building einsum equation for query, key, values\r\nit's building equations of the form `abc,cde-->abde`, which does dot product b/n last axis of first matrix, and first axis of last matrix. The last axis is data is stored in sequence in memory, but first axis data (for second matrix) is stored in fragmented way. This leads to inefficiencies in call method (in einsum calculation). Added tests to showcase the behaviour (tested on Google colab T4 GPU). We can see that `abc,cde-->abde` `abc,dce-->abde` and `abc,dec-->abde` are equivalent, but their performance difference is significant for large matrices. The equation `abc,dec-->abde` wins here due to data locality. \r\nFor large matrices the performance benefit will be around 50%. \r\n<img width=\"691\" alt=\"image\" src=\"https://github.com/user-attachments/assets/d7f5ba5b-abb7-42a0-9bfb-448e8d81e53b\">\r\nFor small matrices, the performance difference is not significant at all.\r\n<img width=\"689\" alt=\"image\" src=\"https://github.com/user-attachments/assets/1888580d-6db4-4d71-9b09-0cc00c4dd73e\">\r\n" | closed | 2024-09-06T08:54:49Z | 2024-09-09T22:22:15Z | https://github.com/keras-team/keras/issues/20220 | [
"type:Bug"
] | tendulkar | 5 |
apify/crawlee-python | web-scraping | 266 | Final doc & readme polishing | These items are currently blocked but should be resolved before the public launch (8. 7.).
### TODO
- [x] Replace all occurrences of `apify.github.io/crawlee-python` with `crawlee.dev/python` in `README.md` once the redirect works.
- [x] Link the API documentation to appropriate sections in `README.md` once API ... | closed | 2024-07-02T15:03:30Z | 2024-08-22T08:58:16Z | https://github.com/apify/crawlee-python/issues/266 | [
"documentation",
"t-tooling"
] | vdusek | 0 |
ray-project/ray | machine-learning | 51,274 | [core][gpu-objects] Object contains multiple tensors and/or mix of CPU data and GPU tensors | ### Description
Object contains multiple tensors and/or mix of CPU data and GPU tensors (right now it only supports direct return of a tensor).
Update to P0 to support veRL's DataProto.
### Use case
_No response_ | open | 2025-03-11T22:11:06Z | 2025-03-20T06:46:03Z | https://github.com/ray-project/ray/issues/51274 | [
"enhancement",
"P0",
"core",
"gpu-objects"
] | kevin85421 | 0 |
httpie/cli | api | 950 | https://httpie.org/docs typo? | > Use --offline to construct HTTP requests without sending them anywhere. With --offline, HTTPie builds a request based on the specified options and arguments, prints it to stdout, and then exists.
Should read "exits"? | closed | 2020-07-02T17:06:47Z | 2020-07-16T20:47:40Z | https://github.com/httpie/cli/issues/950 | [] | turkeyphant | 0 |
pydantic/logfire | fastapi | 60 | Sudden URRLIb error when I use model_dump_json() | ### Description
Hi there,
I'm using logfire with Instructor to extract some values from a given image. I'm getting a strange error message as seen below when my script executes as seen below.
```
requests.exceptions.ReadTimeout: HTTPSConnectionPool(host='logfire-api.pydantic.dev', port=443): Read timed out. (... | closed | 2024-05-01T05:10:50Z | 2024-05-01T05:36:18Z | https://github.com/pydantic/logfire/issues/60 | [
"bug"
] | ivanleomk | 2 |
cvat-ai/cvat | tensorflow | 8,269 | A question about importing task dataset with cvat format in v2.16.1 | When I import a CVAT dataset, there is a mismatch between images and labels.
for example, `annotations.xml` like this:
```
<annotations>
<meta>
<task>
<name>default</name>
<subset>train</subset>
<labels>
<label>
<name>A</name>
</label>
<label>
<name>B</name>
</label>
<labels>
</task>
</meta>
<imag... | open | 2024-08-07T07:08:11Z | 2024-08-07T07:08:11Z | https://github.com/cvat-ai/cvat/issues/8269 | [] | dzcmingdi | 0 |
CorentinJ/Real-Time-Voice-Cloning | pytorch | 1,288 | the output only one second why | The code returns for one second and does not complete the text. Can anyone help me? | open | 2024-02-19T08:45:11Z | 2024-03-08T13:19:30Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/1288 | [] | Aladdin30 | 1 |
encode/databases | asyncio | 559 | Unable to connect to database in docker | I am running my fastapi applicaiton inside docker container on ec2 server where my mysql database also present. I am accessing mysql from the application inside the container. When I check the docker logs, it contain connection errors . I have provided the portion of call stack below
```
Call stack:
File "main.p... | closed | 2023-07-11T12:15:40Z | 2023-07-11T17:11:39Z | https://github.com/encode/databases/issues/559 | [] | Priyansh2 | 0 |
graphql-python/graphene-django | graphql | 985 | Wrong supported python versions in PyPi metadata | According to [the test configuration](https://github.com/graphql-python/graphene-django/blob/c00203499b00d40a696a092ab3c64759eddad0f8/.github/workflows/tests.yml#L10-L15) it looks like graphene-django:
1. Supports Python 3.7, 3.8.
2. Does not support Python 3.4, 3.5.
But [the metadata](https://github.com/graphql-p... | closed | 2020-06-08T06:33:21Z | 2020-06-10T16:41:12Z | https://github.com/graphql-python/graphene-django/issues/985 | [
"🐛bug"
] | AndreyMZ | 1 |
ageitgey/face_recognition | machine-learning | 627 | Miss classifications by spectacles | * face_recognition version:1.2.3
* Python version:3.5
* Operating System:Ubuntu
### Description
issues with persons wearing spectacles
### What I Did
I had trained a model for persons without spectacles. while running the model there are miss classifications with the same person with spectacles.
I assume... | open | 2018-09-21T11:28:18Z | 2018-09-21T11:28:18Z | https://github.com/ageitgey/face_recognition/issues/627 | [] | hemanthkumar3111 | 0 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.