
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
kubeflow/katib | scikit-learn | 2,062 | delete ns label validation | /kind bug
the metrics collector sidecar injection is in job level for now,so the ns label validation should be removed?
https://github.com/kubeflow/katib/blob/master/pkg/webhook/v1beta1/experiment/validation_webhook.go#L83
| closed | 2022-12-14T08:00:54Z | 2022-12-26T01:52:08Z | https://github.com/kubeflow/katib/issues/2062 | [
"kind/bug"
] | zhixian82 | 0 |
ultrafunkamsterdam/undetected-chromedriver | automation | 1,272 | "Change your password" popup | I used the following piece of code, but no use , i still see the pop up

` returns a new CFG with an equivalent language to `G`, but in normal form. However, if `G` is already in Chomsky normal form, then it returns `None`.
Here's an example:
```
>>> import nltk.grammar
>>> G = nltk.gr... | closed | 2019-11-03T06:55:47Z | 2019-11-14T03:14:17Z | https://github.com/nltk/nltk/issues/2454 | [] | jacobdweightman | 1 |
AutoViML/AutoViz | scikit-learn | 51 | Unable to Hide Plots | Setting verbose=2 does not hide the plots from being shown in either python script or python notebook. | closed | 2021-11-04T19:30:33Z | 2021-11-08T18:35:56Z | https://github.com/AutoViML/AutoViz/issues/51 | [] | AustinCaudill | 3 |
apify/crawlee-python | automation | 643 | Incompatibility with Type-Dependent Code: | If you have code that depends on evaluating types immediately—such as functions performing validation or conditional logic based on type hints—it will not work as expected with deferred annotations. The deferred annotations are only evaluated as strings, which may lead to subtle bugs if the code implicitly relies on im... | closed | 2024-11-02T15:24:40Z | 2024-11-04T09:02:04Z | https://github.com/apify/crawlee-python/issues/643 | [
"t-tooling"
] | mgunawardhana | 1 |
MycroftAI/mycroft-core | nlp | 2,728 | Wake word tester isn't functional | Running current dev branch the wake_word test seems to be broken. A missing implementation of duration_to_bytes makes the test crash but even with that fixed the trigger rate is very low. This is probably related to the refactoring done in PR #2589
To see the issue add data to `test/wake_word/data/with_wake_word` an... | closed | 2020-10-22T09:15:25Z | 2024-09-08T08:32:55Z | https://github.com/MycroftAI/mycroft-core/issues/2728 | [
"Type: Bug - complex"
] | forslund | 1 |
supabase/supabase-py | flask | 518 | Need to access custom schemas through Client, or make them public via API or UI | **Describe the bug**
All schemas cannot be accessed via ClientOptions
**To Reproduce**
Steps to reproduce the behavior:
1. Create a schema in supabase UI
2. Try to access that schema using supabase-py
**Expected behavior**
You will not be able to access any schema created in Supabase UI through the supabase-py... | closed | 2023-08-15T15:53:49Z | 2023-09-15T16:59:07Z | https://github.com/supabase/supabase-py/issues/518 | [] | yaminivibha | 2 |
tiangolo/uvicorn-gunicorn-fastapi-docker | pydantic | 3 | Debug mode? | Trying to figure out how to turn on auto-reloading (e.g. debug mode) while using docker. I develop in the docker container by volume mounting the app directory into the docker container so any changes I make to the code are available immediately inside the running docker container. I can't figure out how to start debug... | closed | 2019-02-19T18:51:07Z | 2022-08-17T13:07:48Z | https://github.com/tiangolo/uvicorn-gunicorn-fastapi-docker/issues/3 | [] | wshayes | 8 |
onnx/onnx | machine-learning | 6,737 | How to Insert High-Dimensional Matrix data without Protobuf Read Errors | # Bug Report
### Is the issue related to model conversion?
No, this issue is not related to model conversion. It occurs during the process of modifying an existing ONNX model by inserting nodes.
### Describe the bug
I encountered an issue when trying to insert multiple nodes with high-dimensional matrices into an ONN... | open | 2025-02-28T03:41:59Z | 2025-03-23T17:57:11Z | https://github.com/onnx/onnx/issues/6737 | [
"question"
] | zhudianGG | 11 |
pyppeteer/pyppeteer | automation | 21 | Choose a CI for builds | It looks like we have both TravisCI and Appveyor both have configs in this project. IMO, there's little benefit to having to CIs, and it just adds bloat and maintenance overhead (feel free to correct me if I'm wrong here). | closed | 2020-02-23T08:23:11Z | 2020-03-05T05:59:23Z | https://github.com/pyppeteer/pyppeteer/issues/21 | [
"enhancement",
"after-2.1.1"
] | Mattwmaster58 | 2 |
Lightning-AI/pytorch-lightning | deep-learning | 19,731 | Expected all tensors to be on the same device... using quantized model with deepspeed zero3 | ### Bug description
Got
**RuntimeError: Expected all tensors to be on the same device, but found at least two devices, cuda:1 and cuda:0! (when checking argument for argument index in method wrapper_CUDA__index_select)**
File "/home/root/miniforge3/envs/torch2/lib/python3.9/site-packages/torch/nn/functional.py... | open | 2024-04-03T12:52:31Z | 2024-09-11T05:02:41Z | https://github.com/Lightning-AI/pytorch-lightning/issues/19731 | [
"bug",
"needs triage"
] | sanghyuk-choi | 5 |
pydata/xarray | pandas | 9,807 | Memory leak when opening a DataArray and closing it again with the threading scheduler | ### What happened?
I am using xr.open_dataarray() with chunks and do some simple computation. After that 800mb of RAM is used, no matter whether I close the file explicitly, delete the xarray objects or invoke the Python garbage collector.
What seems to work: do not use the threading Dask scheduler. The issue does ... | open | 2024-11-21T11:16:38Z | 2024-11-21T11:16:38Z | https://github.com/pydata/xarray/issues/9807 | [
"bug",
"needs triage"
] | lumbric | 0 |
pallets-eco/flask-wtf | flask | 521 | 'REMEMBER_COOKIE_HTTPONLY' causes "The CSRF tokens do not match" on mobile Firefox | I've noticed that when enabling 'REMEMBER_COOKIE_HTTPONLY' within the config dict, it causes "The CSRF tokens do not match" in a POST request specifically for mobile Firefox. ~~Non-mobile works just fine, as does Chromium.~~ Those appear to also be affected.
<!--
Describe how to replicate the bug.
Include a mini... | open | 2022-05-23T14:08:56Z | 2023-10-22T01:18:06Z | https://github.com/pallets-eco/flask-wtf/issues/521 | [
"csrf"
] | Lvl4Sword | 1 |
davidsandberg/facenet | tensorflow | 652 | How can I classifier multiple faces in a image? | I am using the script classifier_me.py I got error like this:
Traceback (most recent call last):
File "src/classifier_me.py", line 130, in <module>
classify(args, pnet, rnet, onet)
File "src/classifier_me.py", line 42, in classify
emb_array[start_index:end_index, :] = sess.run(embeddings, feed_dict=f... | open | 2018-02-27T02:42:42Z | 2018-02-27T02:42:42Z | https://github.com/davidsandberg/facenet/issues/652 | [] | jackzhang402 | 0 |
deepinsight/insightface | pytorch | 1,966 | if feature x can be normalized to any number (s) because cosine similarity not depends on it, why don't we just use s=1 for simply? | open | 2022-04-08T08:33:14Z | 2022-04-08T08:33:14Z | https://github.com/deepinsight/insightface/issues/1966 | [] | fancoltran | 0 | |
mwaskom/seaborn | data-visualization | 3,774 | Pointplot error bars do not respect rasterized=True | Using v0.13.2, I was making a pointplot with many points. To save space on the figure, I was passing `searbon.pointplot(rasterized=True,...)`, but the svg was still extremely large. It turns out that the rasterized keyword only gets passed to the scatter portion of the call, and the error bars were plotted as vector gr... | closed | 2024-10-28T11:35:05Z | 2024-10-28T13:11:52Z | https://github.com/mwaskom/seaborn/issues/3774 | [] | ASLeonard | 3 |
matplotlib/matplotlib | data-science | 29,671 | [ENH]: Add long names for markers | ### Problem
Suggested in https://github.com/matplotlib/matplotlib/issues/29646#issuecomment-2669941908
In addition to the single-char (and in rare cases int) marker definitions, we should also support long names `"o"` -> `"circle"`. These long names should be supported wherever the short mnemonics are, with the excep... | open | 2025-02-24T11:33:07Z | 2025-02-28T00:17:22Z | https://github.com/matplotlib/matplotlib/issues/29671 | [
"New feature"
] | timhoffm | 4 |
robotframework/robotframework | automation | 4,658 | "Get Binary File" keyword consumes high memory | "`Get Binary File`" keyword consumes high memory in proportional to the size of the file passed as input to it.
File size of approximately ~270MB is used as an input. Below is the memory consumption (~12GB) shown as reference:
."
Is is the case or do we n... | closed | 2017-11-02T10:22:21Z | 2017-11-13T13:21:54Z | https://github.com/ClimbsRocks/auto_ml/issues/347 | [] | PaulVanDev | 4 |
drivendataorg/cookiecutter-data-science | data-science | 402 | Proposal to add UV as dependency manager option | Hi team! Great work with this template! As a newbie it is very educational to find CCDS and the good practices proposed in the blog.
I would like to propose the addition of UV by Astral as an option for dependecy management. It is lightning fast compared to Conda, Pipenv and others. I lack the technical expertise to... | closed | 2024-12-15T09:31:53Z | 2024-12-16T05:10:34Z | https://github.com/drivendataorg/cookiecutter-data-science/issues/402 | [] | MiguelLopezVirues | 0 |
marcomusy/vedo | numpy | 1,096 | Reusing intersection points | Hello,
I have a 3D mesh and a plane. I can draw the intersection line by using the contour returned by intersect_with and it works lovely.
But I want to reuse the contour for further calculations. When I try to turn the contour into a Tube(contour.vertices) the sequence of points is not always correct and I tend to g... | closed | 2024-04-15T12:01:25Z | 2024-06-13T18:39:36Z | https://github.com/marcomusy/vedo/issues/1096 | [] | IsabellaPa | 2 |
thomaxxl/safrs | rest-api | 54 | Data in resource linkage objects for relationships is null | Hi! I am loving your project here. I am using it extensively and find it massively useful, so kudos to you!
I am wondering if you have some guidance here. I have an ORM generated from flask-sqlacodegen, including relationships with backrefs.
When I am querying on the base object, I do see the relationships appea... | closed | 2020-03-06T19:32:49Z | 2020-03-06T19:41:31Z | https://github.com/thomaxxl/safrs/issues/54 | [] | mleiter94 | 1 |
pytest-dev/pytest-django | pytest | 943 | Test suite fails using pytest-django 4.4 and pytest 6.2.4 | The package on GNU Guix previously built successfully using:
```
dependencies: python-django@3.2.5 python-pytest-xdist@2.1.0 python-pytest@6.1.2
+ python-setuptools-scm@3.4.3
```
But after updating just pytest to 6.2.4, there are already these failures:
```
=========================== short test summary info... | closed | 2021-08-28T19:50:20Z | 2023-10-26T20:07:59Z | https://github.com/pytest-dev/pytest-django/issues/943 | [] | Apteryks | 1 |
NullArray/AutoSploit | automation | 758 | Divided by zero exception28 | Error: Attempted to divide by zero.28 | closed | 2019-04-19T16:00:24Z | 2019-04-19T16:38:06Z | https://github.com/NullArray/AutoSploit/issues/758 | [] | AutosploitReporter | 0 |
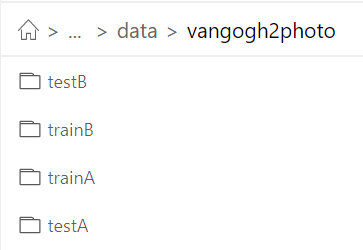
PaddlePaddle/models | computer-vision | 4,721 | No such file or directory: './data/vangogh2photo/trainA.txt' | 这个trainA.txt文件该去哪里找呢?下载过来的数据集只有4个图像文件
| closed | 2020-06-28T06:39:12Z | 2020-06-28T07:28:50Z | https://github.com/PaddlePaddle/models/issues/4721 | [] | shaunhurryup | 1 |
coqui-ai/TTS | python | 2,788 | [Bug] error while training the vits on vctk | ### Describe the bug
I am trying to run the [vits training script](https://github.com/coqui-ai/TTS/blob/dev/recipes/vctk/yourtts/train_yourtts.py) and the script can't find the sample files.
### To Reproduce
Here is the colab file to reproduce the error
https://colab.research.google.com/drive/18490QG6J-1i... | closed | 2023-07-23T18:38:51Z | 2023-09-14T06:19:42Z | https://github.com/coqui-ai/TTS/issues/2788 | [
"bug",
"wontfix"
] | RaiAmanRai | 1 |
cvat-ai/cvat | pytorch | 8,699 | Cannot access analytics page (502 Bad Gateway) | ### Actions before raising this issue
- [X] I searched the existing issues and did not find anything similar.
- [X] I read/searched [the docs](https://docs.cvat.ai/docs/)
### Steps to Reproduce
1. Open CVAT
2. Click on Analytics button
3. Get 502 Bad Gateway error
### Expected Behavior
Analytics page should lo... | closed | 2024-11-14T11:29:59Z | 2024-11-14T13:10:01Z | https://github.com/cvat-ai/cvat/issues/8699 | [
"bug"
] | PAmerikanos | 1 |
hack4impact/flask-base | flask | 158 | Re-enable form submit when password strength check not needed | At the non-admin user "Account Settings" > "Change email address" page, the "Update email" form submit is disabled due to the "check_password" macro (line 5) not finding the "new_password" `{{ field }}` passed to it from "manage.html" (line 52).
A short-term patch would be to add a line to re-enable the form submit ... | closed | 2018-03-20T05:02:14Z | 2018-05-02T18:27:57Z | https://github.com/hack4impact/flask-base/issues/158 | [] | tonyin | 0 |
deezer/spleeter | tensorflow | 577 | Dealing with audio errors on a 1 core 2g cloud server, Segmentation fault | Hello, because I am a Chinese whose English is not very good, so my text is translated by using translation tools.
I use a cloud server to run this project. But it seems that you can only deal with visual audio, and you will make mistakes when you import the audio.
I'm using conda and the audio file I'm processing is ... | open | 2021-02-14T06:07:07Z | 2023-08-12T03:57:20Z | https://github.com/deezer/spleeter/issues/577 | [] | plwd2022 | 2 |
RayVentura/ShortGPT | automation | 116 | ❓ [Question]: ERROR : Valueerror : tuple.index(x): x not in tuple | ### Your Question
ERROR : Valueerror : tuple.index(x): x not in tuple
Traceback Info : File "/content/ShortGPT/gui/ui_tab_short_automation.py", line 103, in create_short for step_num, step_info in shortEngine.makeContent(): File "/content/ShortGPT/shortGPT/engine/abstract_content_engine.py", line 74, in makeContent s... | open | 2023-11-16T08:11:53Z | 2023-11-16T08:11:53Z | https://github.com/RayVentura/ShortGPT/issues/116 | [
"question"
] | merolaika | 0 |
ScrapeGraphAI/Scrapegraph-ai | machine-learning | 277 | Does the framework have cookie authentication login for more useful information? | I use this framework to crawl the content of some websites, but authentication is required
| closed | 2024-05-21T05:18:16Z | 2024-05-21T07:20:42Z | https://github.com/ScrapeGraphAI/Scrapegraph-ai/issues/277 | [] | wrench1997 | 1 |
gradio-app/gradio | data-visualization | 10,427 | Column headers wrap to two lines with a single character in `gr.Dataframe` | ### Describe the bug
When using `gr.Dataframe` with many columns and column names that are longer than the table data itself, the column headers for the second column onward wrap to two lines, with only one character on the second line.
### Have you searched existing issues? 🔎
- [x] I have searched and found no ex... | closed | 2025-01-24T08:28:23Z | 2025-02-06T12:03:20Z | https://github.com/gradio-app/gradio/issues/10427 | [
"bug",
"💾 Dataframe"
] | hysts | 0 |
chatanywhere/GPT_API_free | api | 132 | gpt-3.5-turbo-16k速度很慢,包括带日期的 | `openai.api_base = "https://api.chatanywhere.com.cn"
response = openai.ChatCompletion.create(
model = "gpt-3.5-turbo-16k",
messages = messages
)
`
付费key
调用gpt-3.5-turbo-16k时生成的结果非常慢,大于1分钟
我发现后面带日期的api也会回复很慢
| closed | 2023-11-13T09:12:07Z | 2023-11-13T10:29:57Z | https://github.com/chatanywhere/GPT_API_free/issues/132 | [] | YJSoooooo | 0 |
LibreTranslate/LibreTranslate | api | 307 | Translate File Using Curl Fails | Hello and thanks to all developers on this project.
Using:
$`curl -X POST --silent --show-error -F source=en -F target=id -F file='test.txt' http://127.0.0.1:5000/translate_file`
I get the following error:
127.0.0.1 - - [07/Sep/2022 21:00:03] "POST /translate_file HTTP/1.1" 400 -
{"error":"The browser (or pr... | closed | 2022-09-07T13:02:21Z | 2023-05-30T21:45:34Z | https://github.com/LibreTranslate/LibreTranslate/issues/307 | [
"possible bug"
] | nobicycle | 1 |
ultralytics/yolov5 | machine-learning | 13,381 | Implementing image text recognition and automatic conversion based on YOLOv5 combined with AI technology | ### Search before asking
- [X] I have searched the YOLOv5 [issues](https://github.com/ultralytics/yolov5/issues) and found no similar feature requests.
### Description
The ability to automatically recognize and convert text from images into text or even images will greatly enhance the efficiency of intelligent syst... | open | 2024-10-24T17:03:33Z | 2024-11-09T13:14:27Z | https://github.com/ultralytics/yolov5/issues/13381 | [
"enhancement"
] | 1259xcdh | 2 |
encode/databases | asyncio | 272 | Memory leak with asyncpg, for SQLAlchemy generic functions | ## Summary
The `postgres` backend includes a cache for result processors, which makes the library to leak memory when some specific SQLAlchemy generic functions are used.
## Description
The `_result_processors` dictionary is used as a global cache: https://github.com/encode/databases/blob/8cd551436cf39f3db29... | closed | 2020-12-09T20:36:18Z | 2021-03-13T15:53:35Z | https://github.com/encode/databases/issues/272 | [] | adamantike | 3 |
Johnserf-Seed/TikTokDownload | api | 425 | 小白求助!!! | [ 错误 ]:HTTPConnectionPool(host='47.115.200.238', port=80): Max retries exceeded with url: /xg/path?url=sec_user_id=MS4wLjABAAAAoh3-GNimLQTbYbPB-TvbCXS7o530IPa6VNhMykrcT5A%26count=35%26max_cursor=0%26aid=1128%26version_name=23.5.0%26device_platform=android%26os_version=2333 (Caused by NewConnectionError('<urllib3.conn... | closed | 2023-05-06T06:16:28Z | 2023-05-06T06:17:56Z | https://github.com/Johnserf-Seed/TikTokDownload/issues/425 | [
"故障(bug)",
"额外求助(help wanted)",
"无效(invalid)"
] | FigoY | 1 |
JaidedAI/EasyOCR | machine-learning | 924 | How much speed will be improved by changing from Tesla T4 G1 to RTX 3090 G2? | Running Esayocr on a Tesla T4 G1 Cloud Server takes 5.67s on average.
How much speed will be improved by changing from Tesla T4 G1 to RTX 3090 G2? | closed | 2023-01-06T03:05:39Z | 2023-03-06T06:13:31Z | https://github.com/JaidedAI/EasyOCR/issues/924 | [] | Seo-Hyung-San | 0 |
samuelcolvin/watchfiles | asyncio | 100 | Version 0.8 breaks --ignore-paths CLI option | After upgrading to 0.8 I got the following error
```
[15:25:04] watching "/app" and reloading "celery.__main__.main" on changes...
'import warnings' failed; traceback:
KeyboardInterrupt
/venv/lib/python3.10/site-packages/kombu/utils/compat.py:82: DeprecationWarning: SelectableGroups dict interface is deprecated. U... | closed | 2022-03-16T15:29:02Z | 2022-03-21T14:00:47Z | https://github.com/samuelcolvin/watchfiles/issues/100 | [] | kevinvalk | 2 |
OFA-Sys/Chinese-CLIP | computer-vision | 95 | Chinese-CLIP是如何修改context length的?How does Chinese-CLIP change the context length? | 我看到cn-clip是能够修改tokenizer的context length,但是我没有找到相关的代码是如何实现这个的。
在clip中,tokenizer的max context length为77,因为text-encoder在训练的时候就是如此。所以我想问一下,cn-clip是如何做到的呢?具体的代码又是在哪?
I see that cn-clip is able to modify the context length of the tokenizer, but I can't find the relevant code to implement this.
In clip, the tokenizer ... | closed | 2023-04-28T11:56:21Z | 2023-05-27T14:42:55Z | https://github.com/OFA-Sys/Chinese-CLIP/issues/95 | [] | DengXianqi | 2 |
vitalik/django-ninja | pydantic | 1,087 | Is there a way to access extra keys of the query? | I'm trying to access extra keys of the query.
I have a minimal reproducible example here:
https://github.com/Vulwsztyn/django-ninja-testing/tree/extra_keys_in_query_test
the important part is:
```
class UserSchema(Schema):
model_config = ConfigDict(extra='allow') <-- this is how I tried to make the extra ke... | open | 2024-02-18T13:07:47Z | 2024-02-26T17:10:05Z | https://github.com/vitalik/django-ninja/issues/1087 | [] | Vulwsztyn | 5 |
open-mmlab/mmdetection | pytorch | 11,137 | How to increase the number of FPN layers in Grounding-DINO | open | 2023-11-07T09:20:01Z | 2023-11-07T09:22:39Z | https://github.com/open-mmlab/mmdetection/issues/11137 | [] | CDchenlin | 1 | |
Esri/arcgis-python-api | jupyter | 1,720 | Readability and navigability of the API reference | **Is your feature request related to a problem? Please describe.**
It is difficult to navigate the API reference and to know what are all of the methods and properties available to a class.
For example, in the image below, I can search for the FeatureLayer class and it would be extremely helpful if there were an addi... | closed | 2023-11-20T19:10:41Z | 2024-10-01T10:28:22Z | https://github.com/Esri/arcgis-python-api/issues/1720 | [
"enhancement"
] | avstjohn | 8 |
ultralytics/ultralytics | machine-learning | 19,660 | C++inference using android | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
May you guys provide a ncnn inference demo for C++ using yolov8 -seg? or a a... | closed | 2025-03-12T08:12:48Z | 2025-03-13T02:37:57Z | https://github.com/ultralytics/ultralytics/issues/19660 | [
"enhancement",
"question",
"segment"
] | Keven-Don | 2 |
developmentseed/lonboard | jupyter | 282 | Warn on more than 255 (256?) layers | deck picking will stop after 255 layers. Note that each parquet chunk is rendered as one layer. I hit this when testing rendering all of california msft buildings! 11M buildings | open | 2023-12-01T22:12:09Z | 2024-03-14T01:12:51Z | https://github.com/developmentseed/lonboard/issues/282 | [] | kylebarron | 2 |
liangliangyy/DjangoBlog | django | 627 | 删除分类之后, 归档页(/archives.html)还是会显示该分类 | <!--
如果你不认真勾选下面的内容,我可能会直接关闭你的 Issue。
提问之前,建议先阅读 https://github.com/ruby-china/How-To-Ask-Questions-The-Smart-Way
-->
**我确定我已经查看了** (标注`[ ]`为`[x]`)
- [x] [DjangoBlog的readme](https://github.com/liangliangyy/DjangoBlog/blob/master/README.md)
- [x] [配置说明](https://github.com/liangliangyy/DjangoBlog/blob/master/bin... | closed | 2023-01-06T02:38:11Z | 2023-01-06T02:39:10Z | https://github.com/liangliangyy/DjangoBlog/issues/627 | [] | ddhh8023 | 0 |
chainer/chainer | numpy | 8,316 | Flaky test: tests/chainerx_tests/unit_tests/routines_tests/test_indexing.py::test_WhereScalar | ERROR: type should be string, got "https://jenkins.preferred.jp/job/chainer/job/chainer_pr/2333/TEST=CHAINERX_chainerx-py3,label=mn1-p100/console\r\nOccured in #8295.\r\n\r\n```\r\n02:08:50 E chainer.testing.function_link.FunctionTestError: backward is not implemented correctly\r\n02:08:50 E \r\n02:08:50 E (caused by)\r\n02:08:50 E AssertionError: check_backward failed (eps=0.001 atol=0.003 rtol=0.003)\r\n02:08:50 E inputs[0]:\r\n02:08:50 E array([[[-0.23791504]]], shape=(1, 1, 1), dtype=float16, device='cuda:0')\r\n02:08:50 E grad_outputs[0]:\r\n02:08:50 E array([[[-0.6118164 , 0.07135010, -0.61572266, 0.82958984],\r\n02:08:50 E [-0.65429688, 0.42480469, -0.97509766, 0.78759766],\r\n02:08:50 E [-0.10968018, -0.18200684, -0.03485107, 0.41577148]],\r\n02:08:50 E \r\n02:08:50 E [[0.42919922, 0.48120117, -0.28271484, -0.88623047],\r\n02:08:50 E [-0.04434204, 0.46533203, 0.23522949, 0.87060547],\r\n02:08:50 E [0.09375 , 0.24719238, -0.72753906, -0.01543427]]], shape=(2, 3, 4), dtype=float16, device='cuda:0')\r\n02:08:50 E directions[0]:\r\n02:08:50 E array([[[-1.]]], shape=(1, 1, 1), dtype=float64, device='cuda:0')\r\n02:08:50 E gradients (numeric): array(-0.21189117, shape=(), dtype=float64, device='cuda:0')\r\n02:08:50 E gradients (backward): array(-0.20703125, shape=(), dtype=float64, device='cuda:0')\r\n02:08:50 E \r\n02:08:50 E x: numeric gradient, y: backward gradient\r\n02:08:50 E Not equal to tolerance rtol=0.003, atol=0.003\r\n02:08:50 E \r\n02:08:50 E Mismatch: 100%\r\n02:08:50 E Max absolute difference: 0.00485992\r\n02:08:50 E Max relative difference: 0.02347435\r\n02:08:50 E x: array(-0.211891)\r\n02:08:50 E y: array(-0.207031)\r\n02:08:50 E \r\n02:08:50 E assert_allclose failed: \r\n02:08:50 E shape: () ()\r\n02:08:50 E dtype: float64 float64\r\n02:08:50 E i: (0,)\r\n02:08:50 E x[i]: -0.21189117431640686\r\n02:08:50 E y[i]: -0.20703125\r\n02:08:50 E relative error[i]: 0.023474351415097287\r\n02:08:50 E absolute error[i]: 0.004859924316406861\r\n02:08:50 E relative tolerance * |y[i]|: 0.00062109375\r\n02:08:50 E absolute tolerance: 0.003\r\n02:08:50 E total tolerance: 0.00362109375\r\n02:08:50 E x: -0.21189117\r\n02:08:50 E y: -0.20703125\r\n```" | closed | 2019-10-23T17:45:27Z | 2019-11-13T09:49:53Z | https://github.com/chainer/chainer/issues/8316 | [
"cat:test",
"prio:high",
"pr-ongoing"
] | asi1024 | 2 |
kubeflow/katib | scikit-learn | 2,143 | Experiment with Argo Workflow fails to collect reported metrics | /kind bug
**What steps did you take and what happened:**
I created an Experiment with Argo Workflow as trialSpec. A minimal reproducible example of the Experiment yaml is below, along with the picture of the results. The trials do report the metrics (the logs of "metrics-and-logger-collector" container says so). Th... | closed | 2023-04-04T22:05:08Z | 2023-12-14T00:18:58Z | https://github.com/kubeflow/katib/issues/2143 | [
"kind/bug",
"lifecycle/stale"
] | pedrovgp | 22 |
wandb/wandb | tensorflow | 8,956 | [Bug]: WandB trying to register LoraConfig - not JSON serializable | ### Describe the bug
Hi all,
I am running a custom transformer (llava-style) based on Llama2 using PEFT, QLORA and FSDP.
It is runnable, but I get a strange error coming from WandB, where it seems to be trying to log the LoraConfig, which as a ListConfig is not json serializable.
If someone has any info, I would be v... | open | 2024-11-27T14:49:06Z | 2024-11-29T11:33:04Z | https://github.com/wandb/wandb/issues/8956 | [
"a:sdk",
"c:sdk:config"
] | v-bosch | 1 |
Asabeneh/30-Days-Of-Python | numpy | 652 | Python | open | 2025-03-16T15:16:11Z | 2025-03-16T15:16:11Z | https://github.com/Asabeneh/30-Days-Of-Python/issues/652 | [] | rayanenfi04 | 0 | |
jonaswinkler/paperless-ng | django | 1,278 | Starting to use paperless, added two files are missing | I installed paperless-ng on docker with docker-compose on my qnap, here the docker-compose
```
paperless:
image: jonaswinkler/paperless-ng:latest
container_name: paperless
restart: unless-stopped
depends_on:
- db
- broker
ports:
- 8600:8000
healthcheck:
te... | closed | 2021-09-02T18:56:20Z | 2021-09-04T00:28:10Z | https://github.com/jonaswinkler/paperless-ng/issues/1278 | [] | balajeek | 2 |
CorentinJ/Real-Time-Voice-Cloning | pytorch | 356 | lack of documentation, setup failure | multiple errors, not worth mentioning them. if someone got it to work on windows please share python version, requirments versions and additional installed software. project seems outdated | closed | 2020-06-07T14:13:24Z | 2020-07-04T17:23:42Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/356 | [] | marshonhuckleberry | 4 |
dynaconf/dynaconf | django | 660 | [RFC] Add a dynaconf show command to view a single setting | **Is your feature request related to a problem? Please describe.**
It would be nice to have a `dynconf show` command to display information for a single setting.
**Describe the solution you'd like**
```
$ dynaconf show MEDIA_ROOT
Name: MEDIA_ROOT
Type: str
Value: /var/lib/dynaconf/media
Location: /etc/dynacon... | closed | 2021-09-22T13:12:37Z | 2021-09-22T15:39:52Z | https://github.com/dynaconf/dynaconf/issues/660 | [
"Not a Bug",
"RFC"
] | daviddavis | 3 |
AUTOMATIC1111/stable-diffusion-webui | pytorch | 15,554 | [Bug]: TimeoutError/error code: 2/Couldn't install torch | ### Checklist
- [X] The issue exists after disabling all extensions
- [X] The issue exists on a clean installation of webui
- [X] The issue is caused by an extension, but I believe it is caused by a bug in the webui
- [X] The issue exists in the current version of the webui
- [ ] The issue has not been reported before... | open | 2024-04-17T17:30:24Z | 2024-09-25T18:42:18Z | https://github.com/AUTOMATIC1111/stable-diffusion-webui/issues/15554 | [
"bug-report"
] | Madbat1 | 12 |
Evil0ctal/Douyin_TikTok_Download_API | fastapi | 453 | [BUG] /api/tiktok/web/fetch_user_post似乎不稳定,大部分request返回400异常,少量正常返回 | ***发生错误的平台?***
TikTok
***发生错误的端点?***
/api/tiktok/web/fetch_user_post
***提交的输入值?***
```
curl -X 'GET' \
'https://douyin.wtf/api/tiktok/web/fetch_user_post?secUid=MS4wLjABAAAAc3fcft7gNrSCKZHgxxgVHF8etoZtwJJ0iyXSnSXkmXp4eL-yefgevtg2jFX7OLMO&cursor=0&count=20&coverFormat=2' \
-H 'accept: application/j... | closed | 2024-07-17T09:03:53Z | 2024-07-18T09:43:29Z | https://github.com/Evil0ctal/Douyin_TikTok_Download_API/issues/453 | [
"BUG"
] | scn0901 | 2 |
biolab/orange3 | data-visualization | 6,031 | "Select Row" widget improvement | The "Select Row" widget needs a little improvement. It currently lacks a multiple selection filter.
Let's suppose we have a feature "Licence Plate No.", and a list of numbers to extract. The widget allows us to insert just an "Equals" filter, accepting only 1 value. If we put several "Equals", they are in AND, so noth... | closed | 2022-06-19T15:51:01Z | 2025-03-23T15:55:37Z | https://github.com/biolab/orange3/issues/6031 | [] | hydrastarmaster | 6 |
assafelovic/gpt-researcher | automation | 629 | Support for different Embeddings other than OpenAI | Due to the fact, that OpenAI chose to not accept prepaid-creditcards anymore. (This is a microsoft-thing...)
I cannot use the OpenAI-API anymore.
Langchain is automatically used to use the Embeddings from OpenAI.
Ich am providing gpt-researcher the OPENROUTER-API key in order to access GPT-4o from there.
Unfort... | closed | 2024-06-24T20:19:59Z | 2025-02-01T15:33:56Z | https://github.com/assafelovic/gpt-researcher/issues/629 | [] | mmuyakwa | 6 |
JaidedAI/EasyOCR | deep-learning | 1,010 | AssertionError: datasets should not be an empty iterable | Hi!
I'm training the model with "en_sample", which given in the tutorial.
1. I splitted "en_sample" into "en_train_filtered" and "en_val" (both contains images and .csv) in "all_data"
P.S. I tried to place only raw "en_sample" folder and tried to rename the first folder to "en_filtered" also
2. Follow... | open | 2023-05-08T21:43:37Z | 2023-08-03T15:35:05Z | https://github.com/JaidedAI/EasyOCR/issues/1010 | [] | yerssaintlaurent | 2 |
HumanSignal/labelImg | deep-learning | 468 | where is the origin of coordinates? | when i mark the annotations in the image, where is the origin coordinate( the point that x=0 and y=0) of the annotations?
i am confused, anyone can help me? | closed | 2019-05-11T15:44:52Z | 2019-06-02T14:06:51Z | https://github.com/HumanSignal/labelImg/issues/468 | [] | russell-li | 3 |
Kanaries/pygwalker | plotly | 24 | Embedding directly in html | So I would love to use pygwalker in my project which is currently serving the data analytics through a simple flask server. Is there any easy way already available? | closed | 2023-02-22T09:32:43Z | 2023-02-24T08:34:09Z | https://github.com/Kanaries/pygwalker/issues/24 | [] | DeastinY | 4 |
junyanz/pytorch-CycleGAN-and-pix2pix | deep-learning | 985 | train the pix2pix that it's slow! | What parameter need I to modification for speeding trianging? | closed | 2020-04-09T10:30:22Z | 2020-04-22T10:33:28Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/985 | [] | HiIcy | 8 |
pandas-dev/pandas | pandas | 60,489 | BUG: pd.DataFrame incorrectly aligns Series with mismatched DatetimeIndex after resample (Pandas 2.2.3) | ### Pandas version checks
- [X] I have checked that this issue has not already been reported.
- [X] I have confirmed this bug exists on the [latest version](https://pandas.pydata.org/docs/whatsnew/index.html) of pandas.
- [ ] I have confirmed this bug exists on the [main branch](https://pandas.pydata.org/docs/dev/ge... | closed | 2024-12-04T07:01:25Z | 2025-03-19T05:21:34Z | https://github.com/pandas-dev/pandas/issues/60489 | [
"Bug",
"Datetime"
] | labodyn | 5 |
d2l-ai/d2l-en | pytorch | 2,562 | PyTorch Colab of Chapter 13.5 is having an IndexError | Chapter 13.5 Training on Multiple GPUs
13.5.5. Distributing Data
IndexError: list index out of range

| closed | 2023-10-29T05:44:06Z | 2023-12-31T06:43:35Z | https://github.com/d2l-ai/d2l-en/issues/2562 | [
"question"
] | gab-chen | 2 |
mars-project/mars | scikit-learn | 2,872 | Implements `{DataFrame,Series}.{combine,combine_first}` | Mars lacks pandas API `combine` and `combine_first` to combine two source frames / series into one single result. | open | 2022-03-25T08:47:01Z | 2022-03-25T08:47:01Z | https://github.com/mars-project/mars/issues/2872 | [
"type: feature",
"mod: dataframe",
"Hacktoberfest",
"task: medium"
] | wjsi | 0 |
microsoft/nni | pytorch | 5,350 | . | closed | 2023-02-14T11:44:10Z | 2023-02-15T10:20:42Z | https://github.com/microsoft/nni/issues/5350 | [] | Nafees-060 | 6 | |
horovod/horovod | machine-learning | 3,670 | UnicodeDecodeError in horovod | **Environment:**
1. Framework: TensorFlow
2. Framework version: 2.7
3. Horovod version: 0.23
4. MPI version: None
5. CUDA version: 11.4
6. NCCL version: 11.4
7. Python version: 3.6.8
8. Spark / PySpark version:
9. Ray version:
10. OS and version:
11. GCC version: 8.3.1
12. CMake version: 3.23.3
**Bug ... | closed | 2022-08-27T11:21:05Z | 2022-08-29T17:54:53Z | https://github.com/horovod/horovod/issues/3670 | [
"bug"
] | yinciki | 0 |
pykaldi/pykaldi | numpy | 231 | Plda score | Hi dears
I want to use Kaldi pre-train speaker verification models.
suppose I have two arrays or something else that contain ivectors of two voice (e.g. a=[1,1,1] b=[2,2,2]) and I want to compute plda score between them using Kaldi pre-train model (e.g. plda_scor(a,b)).
Is it possible to use pykaldi for that purpose... | closed | 2020-08-15T06:16:20Z | 2022-03-10T14:15:41Z | https://github.com/pykaldi/pykaldi/issues/231 | [] | lalimili6 | 1 |
Anjok07/ultimatevocalremovergui | pytorch | 1,031 | UVR processing error | i'm using Intel i5 3570 CPU. 8 GB RAM and GT 1030 installed. I'm facing an error which says "low memory"
Last Error Received:
Process: Ensemble Mode
The application was unable to allocate enough system memory to use this model.
Please do the following:
1. Restart this application.
2. Ensure any ... | open | 2023-12-18T18:26:40Z | 2023-12-18T18:26:40Z | https://github.com/Anjok07/ultimatevocalremovergui/issues/1031 | [] | Suju19 | 0 |
itamarst/eliot | numpy | 351 | Further improvements to log_call | * [x] Don't log `self` for now (or maybe just blow up when added to methods/classmethods?)
* [x] Log full path (__module__ + __qualname__?) on Python 3 at least
* [x] Construction-time error if include_args doesn't match actual args. | closed | 2019-01-02T17:18:51Z | 2019-01-02T18:00:09Z | https://github.com/itamarst/eliot/issues/351 | [] | itamarst | 0 |
PokeAPI/pokeapi | graphql | 562 | Pokemon evolution data is incorrect | Can pokemon api provide a correct evolution chain as a array of objects that would help in implementing the evolution chain in projects.
| closed | 2021-01-23T06:57:50Z | 2021-01-29T09:42:14Z | https://github.com/PokeAPI/pokeapi/issues/562 | [
"invalid",
"needs more info"
] | Abhijeetrkushwaha | 2 |
tensorflow/tensor2tensor | deep-learning | 1,700 | Questions About PE in Transformer | I have questions about the **positional encoding** method used in **Transformer** for machine translation tasks. There are two sinusoid functions being used, both sin and cos. I wonder
(i) why do need to separate the odd and even dimensions?
(ii) why do both of sin and cos needed instead of only one of them?
Looki... | open | 2019-09-12T10:44:19Z | 2019-09-12T10:44:19Z | https://github.com/tensorflow/tensor2tensor/issues/1700 | [] | listenviolet | 0 |
streamlit/streamlit | streamlit | 10,611 | `st.chat_input` does not expand to accommodate a multiline placeholder like it does for a multiline prompt | ### Checklist
- [x] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar issues.
- [x] I added a very descriptive title to this issue.
- [x] I have provided sufficient information below to help reproduce this issue.
### Summary
If you type a long prompt (or multiline promp... | open | 2025-03-03T18:39:27Z | 2025-03-03T19:09:21Z | https://github.com/streamlit/streamlit/issues/10611 | [
"type:bug",
"status:confirmed",
"priority:P3",
"feature:st.chat_input"
] | sfc-gh-dmatthews | 1 |
LibreTranslate/LibreTranslate | api | 468 | EPUB file translation broken | It sounds like Epub file translation is broken. EPUB translation is done by [Argos Translate Files](https://github.com/LibreTranslate/argos-translate-files).
https://community.libretranslate.com/t/file-translation/366 | closed | 2023-07-23T13:22:14Z | 2023-08-05T22:58:10Z | https://github.com/LibreTranslate/LibreTranslate/issues/468 | [
"bug",
"good first issue"
] | PJ-Finlay | 1 |
BeanieODM/beanie | pydantic | 855 | distiinct() missing in every find query | ### Discussed in https://github.com/roman-right/beanie/discussions/854
<div type='discussions-op-text'>
<sup>Originally posted by **gaurav25122000** February 6, 2024</sup>
Find queries should either support chaining of distinct or have a param that returns the distinct value which can be chained further into co... | open | 2024-02-06T14:06:49Z | 2024-12-08T21:53:21Z | https://github.com/BeanieODM/beanie/issues/855 | [
"feature request"
] | gaurav25122000 | 1 |
mkhorasani/Streamlit-Authenticator | streamlit | 75 | Question: where I can find new password after I clicked "forgot_password" | Hi,
Thank you for creating this powerful Authenticator tool. I have a question about 'Forgot password' widget. After I submitted my forgot password request by username, where I can find the new generated random password? I did not receive an email to my account about new password information. The config.yaml file's ... | closed | 2023-07-17T19:07:35Z | 2023-07-18T13:38:31Z | https://github.com/mkhorasani/Streamlit-Authenticator/issues/75 | [] | yuxuan7z | 4 |
PaddlePaddle/models | nlp | 5,343 | resource unavailable | the following resource is no longer available,
https://github.com/PaddlePaddle/models/blob/develop/PaddleCV/image_classification/data/ILSVRC2012/download_imagenet2012.sh | closed | 2021-09-15T09:10:07Z | 2022-06-24T02:17:34Z | https://github.com/PaddlePaddle/models/issues/5343 | [] | kuizhiqing | 0 |
huggingface/text-generation-inference | nlp | 3,038 | VRAM usage increases in version 3.1.0 | ### System Info
Using the 3.1.0 docker container in an AWS g6.12xlarge instance. `--env` output:
```
2025-02-19T17:51:35.116359Z INFO text_generation_launcher: Runtime environment:
Target: x86_64-unknown-linux-gnu
Cargo version: 1.84.0
Commit sha: 463228ebfc444f60fa351da34a2ba158af0fe9d8
Docker label: sha-463228e
nvi... | open | 2025-02-19T18:31:38Z | 2025-02-19T18:31:38Z | https://github.com/huggingface/text-generation-inference/issues/3038 | [] | aW3st | 0 |
ymcui/Chinese-BERT-wwm | tensorflow | 5 | Sina Weibo数据的具体划分方式是怎样的 | Sina Weibo数据的具体划分方式是怎样的,是否能够提供已划分数据 | closed | 2019-06-21T06:46:12Z | 2019-06-21T07:29:49Z | https://github.com/ymcui/Chinese-BERT-wwm/issues/5 | [] | ak47-1234 | 1 |
fbdesignpro/sweetviz | data-visualization | 78 | Add number and prct of negative values to feature information | I would like to create a PR for adding the number of negative values to the base statistics. In addition, if I am right, the number of zeroes is also not displayed.
The output of the implementation would look like this:

Then I run the following command:
... | closed | 2023-10-10T12:20:57Z | 2024-02-29T17:46:52Z | https://github.com/graphdeco-inria/gaussian-splatting/issues/304 | [] | Relif-me | 6 |
wkentaro/labelme | computer-vision | 477 | Video annotation saving on custom data | @latticetower @ompugao @rogerthat94 @serycjon THanks for the wonderful feature , i have few queries
1. I have followed the instructions mentioned in the example which works fine
2. on custom video i am able to convert it to the images but when i start the annotation in first frame how will is progress it to the s... | closed | 2019-08-28T11:09:04Z | 2020-01-27T01:32:38Z | https://github.com/wkentaro/labelme/issues/477 | [] | abhigoku10 | 4 |
streamlit/streamlit | data-visualization | 10,649 | Preserve `st.column_config.Column` visibility restrictions in the UI | ### Checklist
- [x] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar feature requests.
- [x] I added a descriptive title and summary to this issue.
### Summary
Thanks to #10264 we can hide/unhide columns directly from the UI but I have two concerns (one subjective and ... | open | 2025-03-05T10:12:27Z | 2025-03-21T17:06:01Z | https://github.com/streamlit/streamlit/issues/10649 | [
"type:enhancement",
"feature:st.dataframe",
"feature:st.data_editor",
"feature:st.column_config"
] | VERBOSE-01 | 3 |
raphaelvallat/pingouin | pandas | 25 | Contingency: Cochran–Mantel–Haenszel test | `pg.chi2_cmh` also requires a `stratify` parameter.
Sources to study:
* https://en.wikipedia.org/wiki/Cochran%E2%80%93Mantel%E2%80%93Haenszel_statistics
* http://www.biostathandbook.com/cmh.html
* http://rcompanion.org/rcompanion/b_10.html
* https://www.statisticshowto.datasciencecentral.com/cochran-mantel-haens... | closed | 2019-05-09T18:55:31Z | 2019-09-28T19:06:03Z | https://github.com/raphaelvallat/pingouin/issues/25 | [
"feature request :construction:"
] | arthurpaulino | 1 |
deepfakes/faceswap | machine-learning | 977 | Dockerfiles outdated |
Crash report:
`root@19e13ca3b3aa:/srv/faceswap# python faceswap.py -h
Setting Faceswap backend to CPU
Traceback (most recent call last):
File "faceswap.py", line 11, in <module>
raise Exception("This program requires at least python3.6")
Exception: This program requires at least python3.6
`
Bug
The c... | closed | 2020-02-26T15:48:35Z | 2020-03-29T17:30:02Z | https://github.com/deepfakes/faceswap/issues/977 | [] | wardVD | 3 |
onnx/onnx | scikit-learn | 6,123 | Incorrect input names for quantize/dequantize ONNX backend node tests | # Bug Report
### Is the issue related to model conversion?
<!-- If the ONNX checker reports issues with this model then this is most probably related to the converter used to convert the original framework model to ONNX. Please create this bug in the appropriate converter's GitHub repo (pytorch, tensorflow-onnx, sk... | closed | 2024-05-02T22:32:00Z | 2024-05-03T16:32:57Z | https://github.com/onnx/onnx/issues/6123 | [
"bug"
] | adrianlizarraga | 1 |
holoviz/panel | matplotlib | 7,302 | I like the idea of using Slides for simple, linear workflows. | I like the idea of using Slides for simple , linear workflows. Could slides be added dynamically if native templates were composed of Panel components, as mentioned [here](https://github.com/holoviz/panel/issues/7248 )? | closed | 2024-09-19T23:51:00Z | 2024-09-25T10:03:38Z | https://github.com/holoviz/panel/issues/7302 | [] | Coderambling | 0 |
thp/urlwatch | automation | 714 | Feature request: Add proxy field support for reporter | open | 2022-07-17T08:48:09Z | 2022-07-22T11:20:55Z | https://github.com/thp/urlwatch/issues/714 | [] | snowman | 1 | |
dynaconf/dynaconf | django | 1,189 | [docs] Docs are wrong about list merge behavior | The default behavior for list merging is appending, but docs example shows an insert at beginning behavior.
E.g in test: https://github.com/dynaconf/dynaconf/blob/b23dac456fbc382b6b9f58624c44162c0fd957d8/tests_functional/legacy/dynaconf_merge/app.py
https://www.dynaconf.com/merging/#merging-existing-data-structur... | open | 2024-10-17T12:56:01Z | 2024-10-17T13:28:10Z | https://github.com/dynaconf/dynaconf/issues/1189 | [
"Docs"
] | pedro-psb | 0 |
python-restx/flask-restx | api | 223 | Swagger (paths) operations doesn't open | ### **Expected Behavior**
Open operations after click.
### **Actual Behavior**
After click on operations, nothing happen, just had send me a console error:

### **Error Messages/Stack Trace**
Doe... | open | 2020-09-10T00:50:08Z | 2021-02-03T19:13:42Z | https://github.com/python-restx/flask-restx/issues/223 | [
"bug"
] | uricholiveira | 8 |
hanwenlu2016/web-ui | pytest | 12 | 切换iframe在自动化执行里面怎么添加 | 元素定位中经常遇到iframe,想把切iframe加入到web_exe中,大神啥时候更新考虑下~ | closed | 2021-12-03T05:22:22Z | 2022-02-25T09:25:45Z | https://github.com/hanwenlu2016/web-ui/issues/12 | [] | 19863333636 | 3 |
cvat-ai/cvat | computer-vision | 8,964 | [Create from backup] UnboundLocalError: local variable 'source' referenced before assignment | ### Actions before raising this issue
- [x] I searched the existing issues and did not find anything similar.
- [x] I read/searched [the docs](https://docs.cvat.ai/docs/)
### Steps to Reproduce
Uploading the following backup zip file on the CVAT task page "Create from backup" button. This will results in an error
`... | closed | 2025-01-17T23:08:23Z | 2025-01-20T07:22:43Z | https://github.com/cvat-ai/cvat/issues/8964 | [
"bug"
] | JedMoutahir | 1 |
ranaroussi/yfinance | pandas | 1,285 | Failed to download indices. | Hi!
I got into trouble when I tried to download S&P500 Index history. The code for S&P500 in Yahoo Finance is ^GSPC, am I right? However I could download stocks like Apple, Amazon successfully. I don't know what is going on. Could you tell me how to fix it? Thanks a lot!
 change in opacity | Leave a faint path or trace in animation. | closed | 2017-01-06T20:37:11Z | 2017-01-06T20:57:22Z | https://github.com/ContextLab/hypertools/issues/59 | [] | lucywowen | 1 |
simple-login/app | flask | 2,187 | Domain Unavailable After Mailbox Deletion | ## Prerequisites
- [ X ] I have searched open and closed issues to make sure that the bug has not yet been reported.
## Bug report
**Describe the bug**
When trying to add a new domain, a message of "example.com already used in a SimpleLogin mailbox" even though the mailbox was deleted and there are no other mai... | open | 2024-08-18T09:52:05Z | 2025-02-04T20:00:19Z | https://github.com/simple-login/app/issues/2187 | [] | nadsnir | 2 |
newpanjing/simpleui | django | 163 | 配置admindocs后不显示doc连接 | **bug描述**
简单的描述下遇到的bug:
配置admindocs后不显示doc连接
**重现步骤**
1.在INSTALLED_APPS内添加django.contrib.admindocs
2.在urlpatterns内添加url(r'^admin/doc/',include('django.contrib.admindocs.urls'))。确保它处于r'^admin/'条目之前
3.安装Python的docutils模块(http://docutils.sf.net/)(pip3 install docutils)
**环境**
1.操作系统:MacOS 10.14.6
2.python版本... | closed | 2019-09-30T07:28:01Z | 2019-10-28T02:57:37Z | https://github.com/newpanjing/simpleui/issues/163 | [
"bug"
] | eshxcmhk | 0 |
Textualize/rich | python | 2,907 | [BUG] Styled text wraps incorrectly after capture | - [ ] I've checked [docs](https://rich.readthedocs.io/en/latest/introduction.html) and [closed issues](https://github.com/Textualize/rich/issues?q=is%3Aissue+is%3Aclosed) for possible solutions.
- [ ] I can't find my issue in the [FAQ](https://github.com/Textualize/rich/blob/master/FAQ.md).
**Describe the bug**
... | closed | 2023-03-27T13:26:23Z | 2023-03-27T14:35:09Z | https://github.com/Textualize/rich/issues/2907 | [
"Needs triage"
] | nedbat | 5 |
seleniumbase/SeleniumBase | pytest | 3,036 | proxies in multi_threading is not working on Ubuntu in Seleniumbase Driver - Cannot reuse ChromeOptions Object | I have been building a large scraper that requires me to use multi-threading I have been struggling a lot and recently I saw Michael Mintz video on youtube [ Undetectable Automation 2 - with SeleniumBase UC Mode (Python)](https://www.youtube.com/watch?v=2pTpBtaE7SQ) where he presented this code inside I changed it a bi... | closed | 2024-08-18T15:18:58Z | 2024-08-19T14:07:02Z | https://github.com/seleniumbase/SeleniumBase/issues/3036 | [
"self-resolved",
"UC Mode / CDP Mode"
] | AdilMughal2126 | 3 |
huggingface/datasets | pandas | 6,605 | ELI5 no longer available, but referenced in example code | Here, an example code is given:
https://huggingface.co/docs/transformers/tasks/language_modeling
This code + article references the ELI5 dataset.
ELI5 is no longer available, as the ELI5 dataset page states: https://huggingface.co/datasets/eli5
"Defunct: Dataset "eli5" is defunct and no longer accessible due to u... | closed | 2024-01-19T10:21:52Z | 2024-02-01T17:58:23Z | https://github.com/huggingface/datasets/issues/6605 | [] | drdsgvo | 1 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.