
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
TvoroG/pytest-lazy-fixture | pytest | 38 | 0.5.2 problem with pytest-asyncio | I made a PR to upgrade pytest-lazy-fixture 0.4.2 to 0.5.2.
- PR: https://github.com/youknowone/ring/pull/106
- CI: https://travis-ci.org/youknowone/ring/jobs/518829292
It worked with 0.4.2 but doesn't work with 0.5.2 anymore. Any idea?
The errors are refering about event loop
```
E RuntimeError: Task ... | closed | 2019-04-11T15:48:33Z | 2019-04-20T04:37:59Z | https://github.com/TvoroG/pytest-lazy-fixture/issues/38 | [] | youknowone | 4 |
keras-team/keras | machine-learning | 20,363 | How i can import a CRF layer in the latest version of keras 3? | closed | 2024-10-16T13:55:37Z | 2024-10-18T20:52:38Z | https://github.com/keras-team/keras/issues/20363 | [
"type:support",
"stat:awaiting response from contributor"
] | Und3r1ine | 3 | |
junyanz/pytorch-CycleGAN-and-pix2pix | deep-learning | 1,478 | Pix2pix Colab code does not work for me | Hi,
I follow the code from the colaboratory as below.

But it says that it cannot find the file or directory as below.

Have you any idea of the fix?
Thanks for your reply.
Regards | closed | 2021-02-19T10:20:47Z | 2023-07-31T01:58:45Z | https://github.com/alirezamika/autoscraper/issues/51 | [] | regisbaillieul | 2 |
Kanaries/pygwalker | plotly | 510 | Would it be possbile to walk it with Datatable.frame type in the future? | https://github.com/h2oai/datatable
It has higher performance reading and manipulating big csv data than pandas/polars/modin. But I can't walk this datatable.frame type. | open | 2024-04-01T17:59:46Z | 2024-04-02T06:55:41Z | https://github.com/Kanaries/pygwalker/issues/510 | [
"Vote if you want it",
"proposal"
] | plusmid | 1 |
bregman-arie/devops-exercises | python | 161 | DevOps-SRE | closed | 2021-09-26T17:25:59Z | 2021-09-26T18:15:53Z | https://github.com/bregman-arie/devops-exercises/issues/161 | [] | theycallmejc | 0 | |
ultralytics/yolov5 | machine-learning | 12,546 | Hello author, I would like to use multiple machines and multiple cards for training in a Windows environment. What do I need to do? | ### Search before asking
- [X] I have searched the YOLOv5 [issues](https://github.com/ultralytics/yolov5/issues) and [discussions](https://github.com/ultralytics/yolov5/discussions) and found no similar questions.
### Question
Hello author, I would like to use multiple machines and multiple cards for training in a ... | closed | 2023-12-23T07:56:20Z | 2024-02-05T00:21:17Z | https://github.com/ultralytics/yolov5/issues/12546 | [
"question",
"Stale"
] | yxl23 | 7 |
ScrapeGraphAI/Scrapegraph-ai | machine-learning | 528 | Refactoring of prompts | Remove all the prompts inside the helpers folder and move it to a new folder called prompts
| closed | 2024-08-10T09:46:53Z | 2024-08-11T12:54:51Z | https://github.com/ScrapeGraphAI/Scrapegraph-ai/issues/528 | [] | VinciGit00 | 2 |
pydantic/pydantic-settings | pydantic | 132 | Environment variable parsing exception | ## Description
When I set the variable type to `str | None`, it uses `json.loads()` to parse the environment variable, so the variable type will change from `str` to `int` type, and this exception is thrown.
Although setting to `str` type can avoid the problem, I think this is a bug that can be fixed.
Thx. ^_^... | closed | 2023-07-24T10:02:17Z | 2023-07-24T15:08:04Z | https://github.com/pydantic/pydantic-settings/issues/132 | [] | YongJie-Xie | 4 |
pallets-eco/flask-sqlalchemy | sqlalchemy | 999 | Add type hints | Hello all,
did you already consider to add type hints to your code? SQLAlchemy does this with https://github.com/sqlalchemy/sqlalchemy2-stubs.
Thanks,
Kai | closed | 2021-09-10T07:39:36Z | 2021-09-26T00:07:33Z | https://github.com/pallets-eco/flask-sqlalchemy/issues/999 | [] | kasium | 2 |
vanna-ai/vanna | data-visualization | 409 | Question about embeddings of DDL, SQL matched against Query | Hi,
Thanks for sharing this work. I had a question, which might be naive, I did not get how we get expected embeddings of DDL or SQL if we match it against natural language Query? Can anyone please shed some light on it? As per the base class of vanna, we first get the similar embeddings matched against stored (or her... | closed | 2024-05-05T14:48:53Z | 2024-05-05T19:28:17Z | https://github.com/vanna-ai/vanna/issues/409 | [] | sourabh-patil | 0 |
aimhubio/aim | data-visualization | 2,672 | Aim UI does not open at all within Jupyterlab notebook with `%loadext` | ## 🐛 Bug
<!-- A clear and concise description of what the bug is. -->
When trying the [documented steps](https://aimstack.readthedocs.io/en/latest/using/jupyter_notebook_ui.html) to open the AIM UI on jupyter on my local laptop, it fails with an error.
### To reproduce
<!-- Reproduction steps. -->
Insta... | open | 2023-04-22T03:46:32Z | 2023-08-01T13:57:03Z | https://github.com/aimhubio/aim/issues/2672 | [
"type / bug",
"help wanted",
"area / integrations"
] | adivekar-utexas | 2 |
Anjok07/ultimatevocalremovergui | pytorch | 1,247 | MemoryError: "Unable to allocate 2.66 GiB for an array with shape (2, 673, 265119) and data type complex64" |
Last Error Received:
Process: VR Architecture
If this error persists, please contact the developers with the error details.
Raw Error Details:
MemoryError: "Unable to allocate 2.66 GiB for an array with shape (2, 673, 265119) and data type complex64"
Traceback Error: "
File "UVR.py", line 6638, in pro... | open | 2024-03-20T11:59:48Z | 2024-03-20T11:59:48Z | https://github.com/Anjok07/ultimatevocalremovergui/issues/1247 | [] | yanhexiong | 0 |
dinoperovic/django-salesman | rest-api | 18 | Stock Handling | I'm looking to implement stock handling for order s/ basket items - handling the stock is fine the problem I'm having is catching basket quantity changes to adjust stock levels, any ideas or suggestions on doing this? | open | 2022-04-25T14:09:41Z | 2022-05-09T08:31:51Z | https://github.com/dinoperovic/django-salesman/issues/18 | [
"enhancement"
] | IncreaseComputers | 8 |
jupyter/nbviewer | jupyter | 321 | Bad Json file on gist | Hi Ive been trying to access one of my json files via nbviewer stored on a private github gist. It had 21 days ago worked from any computer. Since then my work computer burnt out and I am using a new one. However I didn't think this would affect the gist. Could you please let me know if there is an issue with using gis... | closed | 2014-08-06T14:16:23Z | 2014-08-11T00:53:58Z | https://github.com/jupyter/nbviewer/issues/321 | [] | donedeal-kaspar | 3 |
charlesq34/pointnet | tensorflow | 182 | Problems in predicting own data in sem seg | Please check the edit history for the modified script, they have been deleted for the reading convenience.
Please DO NOT reply to this topic again!
- ### I modified the script as follow to process my own data:
1. I use text file as input, not npy file. But the data forms are same in .txt and .npy.
2. Th... | closed | 2019-05-20T06:30:48Z | 2021-09-21T05:16:06Z | https://github.com/charlesq34/pointnet/issues/182 | [] | RollingIsland | 21 |
tflearn/tflearn | tensorflow | 254 | Continue running the DNN until convergence | Hi,
I'd like to continue running my model until the loss functions reaches a threshold or stops converging instead of using a predefined epoch number. How can I do that?
| open | 2016-08-02T21:15:31Z | 2016-08-03T00:13:43Z | https://github.com/tflearn/tflearn/issues/254 | [] | sauberf | 1 |
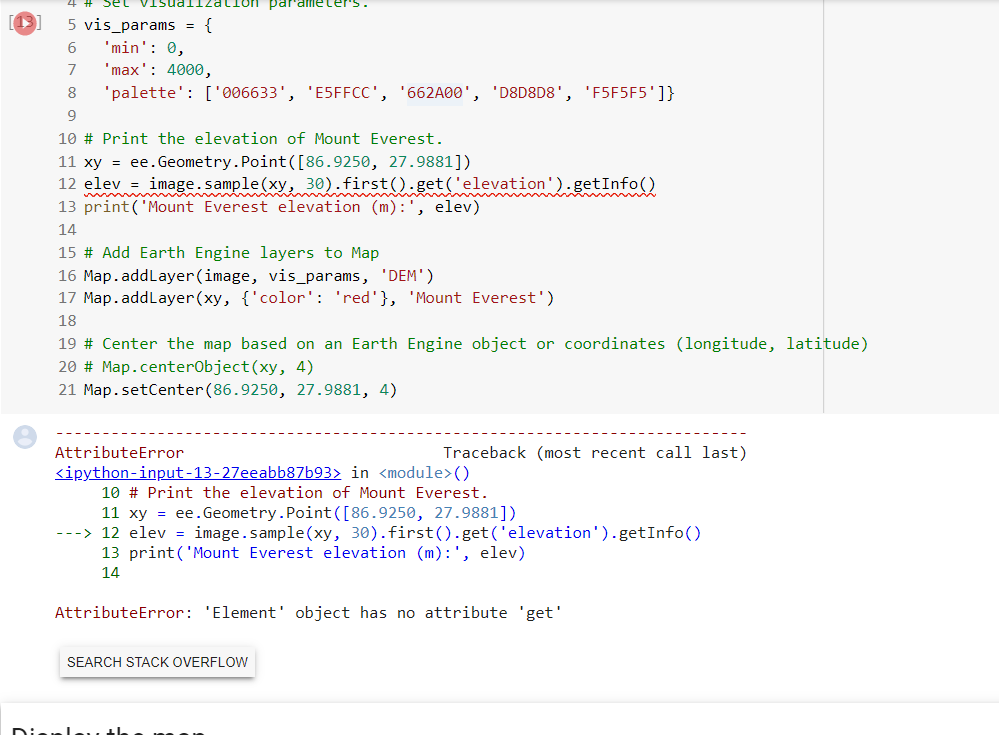
Sanster/IOPaint | pytorch | 525 | Pillow>=10.0.0, but you have pillow 9.5.0 which is incompatible. | pip's dependency resolver does not currently take into account all the packages that are installed. This behaviour is the source of the following dependency conflicts.
paddleocr 2.7.3 requires opencv-python<=4.6.0.66, but you have opencv-python 4.9.0.80 which is incompatible.
paddleocr 2.7.3 requires Pillow>=10.0.0,... | closed | 2024-05-14T02:42:39Z | 2024-12-27T02:00:18Z | https://github.com/Sanster/IOPaint/issues/525 | [
"stale"
] | xy5613003 | 2 |
Lightning-AI/pytorch-lightning | machine-learning | 20,274 | `strict = False` does not work when the checkpoint is distributed | ### Bug description
When loading a sharded checkpoint with:
```python
fabric.load(ckpt_path, state, strict = False)
```
the `_distributed_checkpoint_load` function called in the `FSDPStrategy` will raise an error if a checkpoint misses a key from the model in `state`, which should not be the case as `strict = Fals... | open | 2024-09-11T16:36:26Z | 2024-10-10T01:50:05Z | https://github.com/Lightning-AI/pytorch-lightning/issues/20274 | [
"bug",
"needs triage",
"ver: 2.4.x"
] | NathanGodey | 1 |
keras-team/keras | tensorflow | 20,216 | Call on an Embedding model doesnt produce the same result for keras 2 and keras 3 models | When trying to get the same result from a keras 2 and keras 3 models I noticed that there were some differences so I investigated further with this test that failed on the assertion:
```
def test_keras2_and_keras3_model_using_embddings(self):
keras3_model = model_examples.build_embedding_keras3_model()
... | closed | 2024-09-05T13:32:06Z | 2024-09-10T07:45:02Z | https://github.com/keras-team/keras/issues/20216 | [
"type:support"
] | markomitos | 5 |
pytest-dev/pytest-selenium | pytest | 203 | Most Elegant Way to have Multiple Browser Configs In one test ? | I'm having trouble trying to integrate your pytest-selenium into my testing suite. What I want to do is utilise the firefox and chrome options fixtures when initialising each driver but I want them to both run when I use the selenium directive. That is if I had this test:
```
def test_site(selenium):
selenium.... | closed | 2018-12-05T04:29:02Z | 2019-02-28T14:46:42Z | https://github.com/pytest-dev/pytest-selenium/issues/203 | [] | thomascrha | 8 |
saulpw/visidata | pandas | 2,712 | Visidata wants Parquet files to have extension .parquet and will fail on .pq extension | Just something I noticed today and figured potentially worthwhile to call out and have searchable here in the issues. Seems like `.parquet` is the norm but there is some `.pq` usage out there in the wild as well. https://github.com/RandomFractals/vscode-data-preview/issues/13#issuecomment-788081494 | closed | 2025-02-27T22:14:00Z | 2025-02-27T22:14:59Z | https://github.com/saulpw/visidata/issues/2712 | [] | zachvalenta | 0 |
LAION-AI/Open-Assistant | python | 2,823 | Export script for inference chats | We need chat deletion (#2582) and data opt out (#2580) first. | closed | 2023-04-21T22:12:05Z | 2023-05-05T09:51:43Z | https://github.com/LAION-AI/Open-Assistant/issues/2823 | [
"inference"
] | olliestanley | 0 |
art049/odmantic | pydantic | 364 | 怎么排序 | # Bug
我想根据前端传递的字符串进行排序,结果文档里只能使用模型的字段进行排序。
我想用Model[key]的方式获取字段,结果报错:"type 'DictType' is not subscriptable"
orderObject.order = “createTime”
sort=DictType[orderObject.order]
"type 'DictType' is not subscriptable"
### Current Behavior
... _Steps to reproduce the bug_ ...
### Expected behavior
... ... | closed | 2023-09-01T07:56:25Z | 2024-03-22T13:33:52Z | https://github.com/art049/odmantic/issues/364 | [
"bug"
] | f754699 | 1 |
streamlit/streamlit | data-visualization | 10,553 | `st.dataframe(styler)` and `st.table(styler)` raise an `AttributeError` when using `styler.set_tooltips()` | ### Checklist
- [x] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar issues.
- [x] I added a very descriptive title to this issue.
- [x] I have provided sufficient information below to help reproduce this issue.
### Summary
`st.dataframe(styler)` and `st.table(styler)`... | closed | 2025-02-28T05:47:02Z | 2025-03-04T20:03:51Z | https://github.com/streamlit/streamlit/issues/10553 | [
"type:enhancement",
"feature:st.dataframe",
"feature:st.table"
] | JosephMarinier | 3 |
RomelTorres/alpha_vantage | pandas | 148 | What's the oldest data I can get by using aplpha vantage? | Hi,
I'm wondering what's the oldest data I can get by using alpha vantage python api?
Best,
Melvin | closed | 2019-09-29T21:26:59Z | 2020-06-27T02:18:07Z | https://github.com/RomelTorres/alpha_vantage/issues/148 | [] | MelvinYYY | 9 |
graphdeco-inria/gaussian-splatting | computer-vision | 737 | how to get the center of model | the output file is only contain the information of all splats,but the information of the whole model does not exist,such as the center or the axial direction of the 3DGS model. So,when i put it in unity,some operations have encountered difficulties.
the picture shows that the transform's center is far away from the ... | open | 2024-04-03T09:54:19Z | 2024-04-03T09:54:19Z | https://github.com/graphdeco-inria/gaussian-splatting/issues/737 | [] | auindoeee | 0 |
ResidentMario/missingno | pandas | 123 | should geopandas be listed in setup.py? | Hi
As we can see, geopandas is used as dependency in source code as a must. But when I use "pip install missingno", it seems geopandas is not installed automatically. So I am wondering if geopandas should be listed explicitly in setup.py?

│ │ Coordinates:
│ │ * x (x) int64 32B 10 20 30 40
│ │ * y (y) datetime64[ns] 40B 2000-01-01 2000-01... | closed | 2024-09-03T22:46:38Z | 2024-10-06T14:58:29Z | https://github.com/pydata/xarray/issues/9427 | [
"topic-DataTree",
"io"
] | aladinor | 0 |
modelscope/modelscope | nlp | 538 | GridVLP 有能在gpu跑的版本吗 | 目前好像只能使用cpu做预测?
| closed | 2023-09-14T07:53:29Z | 2024-07-04T01:51:37Z | https://github.com/modelscope/modelscope/issues/538 | [
"Stale"
] | xxxyyycc | 7 |
ydataai/ydata-profiling | pandas | 1,729 | Support for visualizations with chinese characters | ### Current Behaviour
Objective: To resolve the issue of displaying Chinese characters in Seaborn and WordCloud.
I modified visualisation\context.py by adding a new value 'Microsoft YaHei' to the font.sans-serif list.
I also modified seaborn\rcmod.py by adding 'Microsoft YaHei' to the font.sans-serif list.
At this poi... | open | 2025-03-14T08:57:35Z | 2025-03-14T17:25:59Z | https://github.com/ydataai/ydata-profiling/issues/1729 | [
"feature request 💬"
] | patrickstar231 | 0 |
MaartenGr/BERTopic | nlp | 1,777 | Question about topics in topic_distribution | When I print out topic_info from the model (with get_topic_info()), there are a bunch of files in topic -1 which I want to filter out. I was going to do this by creating a mask with the topic_distrubution you get when running approximate_distribution() but the distribution_matrix seems to have 1 less topic columns when... | open | 2024-01-30T13:34:28Z | 2024-02-01T13:28:53Z | https://github.com/MaartenGr/BERTopic/issues/1777 | [] | carlHIda | 1 |
google-research/bert | nlp | 1,229 | BERT pretraining: [SEP] vs. Segment Embeddings? | I’m confused about the differences between the intent of the [SEP] tokens and Segment Embeddings applied to the input of BERT during pretraining.
As far as I’ve understood, the [SEP] tokens are inserted between sentence A and B to enable the model’s ability to distinguish between the two sentences for BERTs Next-Sen... | open | 2021-05-19T13:32:36Z | 2021-05-19T13:32:36Z | https://github.com/google-research/bert/issues/1229 | [] | velixo | 0 |
nolar/kopf | asyncio | 1,088 | Namespace deletion is stuck when using namespace selector startup mode | ### Long story short
When running a kopf operator with namespace selector AND deleting this namespace that contains a resource with a finalizer: kopf may not call the delete handler method.
Deleting the namespace stops the watch-stream for this namespace before the resources contained in that namespace get the chan... | open | 2024-01-10T15:21:34Z | 2024-01-10T15:26:24Z | https://github.com/nolar/kopf/issues/1088 | [
"bug"
] | nicolasadeo | 1 |
floodsung/Deep-Learning-Papers-Reading-Roadmap | deep-learning | 11 | Suggestion for Computational Biology Part | I think these repositories are worth looking at
- https://github.com/gokceneraslan/awesome-deepbio (Especially this one I find really useful)
- https://github.com/pimentel/deep_learning_papers
| open | 2016-10-21T21:17:22Z | 2016-10-21T21:17:22Z | https://github.com/floodsung/Deep-Learning-Papers-Reading-Roadmap/issues/11 | [] | eneskemalergin | 0 |
facebookresearch/fairseq | pytorch | 5,550 | Skip some tokens | İs there a way to skip some words in translation, I tried to wrap some words with some placeholders $$$skipping words$$, I also tried to creat enumerated placeholders so that i can change them after translation (1_1_1, <1>,<2>,....). I also tried to give numbers. directly Like 11111111, 11111112, ... but None of them w... | open | 2024-10-11T16:38:04Z | 2024-10-11T16:38:04Z | https://github.com/facebookresearch/fairseq/issues/5550 | [] | ekmekovski | 0 |
zappa/Zappa | django | 366 | [Migrated] Feature request - new setting to enable "Log full requests/responses data" | Originally from: https://github.com/Miserlou/Zappa/issues/923 by [danielwhatmuff](https://github.com/danielwhatmuff)
API gateway has an option for "Log full requests/responses data". This is useful for debugging, to see HTTP headers etc. Be cool to have this as an option which could be enabled for dev/test environment... | closed | 2021-02-20T08:27:30Z | 2024-04-13T15:36:46Z | https://github.com/zappa/Zappa/issues/366 | [
"enhancement",
"no-activity",
"auto-closed"
] | jneves | 2 |
Evil0ctal/Douyin_TikTok_Download_API | api | 590 | [Feature request] 视频中的音频下载 | 请问是否有直接下载音频的API接口,我翻了文档,只有下载视频的接口。但是我看返回的信息里其实是有mp3对应的地址的,请问是否可以直接下载对应的音频呢?
目前如果我下载视频后还需要使用ffe来转成音频,如果能直接下载音频就方便很多了
| open | 2025-03-17T02:10:26Z | 2025-03-17T04:21:39Z | https://github.com/Evil0ctal/Douyin_TikTok_Download_API/issues/590 | [
"enhancement"
] | rayleighzhongrui | 2 |
ultrafunkamsterdam/undetected-chromedriver | automation | 1,407 | How to use proxy with authentication [oxylabs]? | Hello. How I can use proxy with authentication with undetected-chromedriver?
I tried using seleniumwire, but it fails to target the website.
Any other solution? | closed | 2023-07-20T21:29:41Z | 2023-07-26T17:08:28Z | https://github.com/ultrafunkamsterdam/undetected-chromedriver/issues/1407 | [] | pedrofnts | 5 |
piskvorky/gensim | data-science | 3,599 | Gensim functions should accept pathlib.Path objects | I got this error after 2 days of training:
```
Traceback (most recent call last):
File "/data/orlando/home/ndavid/miniconda3/envs/embedding/lib/python3.12/site-packages/gensim/utils.py", line 763, in save
_pickle.dump(self, fname_or_handle, protocol=pickle_pro... | open | 2025-01-29T08:04:55Z | 2025-02-11T11:28:32Z | https://github.com/piskvorky/gensim/issues/3599 | [] | DavidNemeskey | 4 |
lepture/authlib | flask | 459 | Provide a UserInfo endpoint implementation | I've succesfully implemented an OAuth2/OIDC provider using authlib. But now stumbled upon a issue where a clients is not able to actually use the id_token (in addition to the access token, it can only use one token at a time). This shouldn't be an issue, as there's always the userinfo endpoint that can be read using th... | open | 2022-05-16T12:46:34Z | 2025-02-21T08:53:16Z | https://github.com/lepture/authlib/issues/459 | [
"feature request",
"server"
] | jaap3 | 1 |
ClimbsRocks/auto_ml | scikit-learn | 171 | Add space to logging for missing values being removed from y values | pointed out by @bendearborn, whom I will work on this PR with :) | closed | 2017-03-12T00:45:50Z | 2017-04-04T19:38:22Z | https://github.com/ClimbsRocks/auto_ml/issues/171 | [] | ClimbsRocks | 1 |
gee-community/geemap | jupyter | 317 | colab cell breaks @ Add Earth Engine data | Friendly bug report, the colab has an issue with adding the earth engine data.
Also is it possible to skip the auth part so we can use show our map to people more easily?
| closed | 2021-02-21T07:30:58Z | 2021-02-28T16:13:38Z | https://github.com/gee-community/geemap/issues/317 | [
"bug"
] | Niko-La | 1 |
xinntao/Real-ESRGAN | pytorch | 693 | Does inference_realsgran_video.py or inference_realsgran_video_fast.py support multi-gpu? | It appears as though when I use --gpu-id (or -g, --g) it errors out. | closed | 2023-09-29T02:09:08Z | 2023-09-30T15:47:28Z | https://github.com/xinntao/Real-ESRGAN/issues/693 | [] | cbroker1 | 1 |
feder-cr/Jobs_Applier_AI_Agent_AIHawk | automation | 1,070 | [BUG]: Manual Interaction in an Automated Job Application System | ### Describe the bug
The AI, designed as an automated job application system, currently requires manual interaction, which contradicts its intended purpose. The system is expected to handle tasks autonomously, but manual steps are unnecessarily introduced, undermining its utility and efficiency. Steps to Reproduce I... | open | 2025-01-20T18:26:33Z | 2025-01-20T18:28:21Z | https://github.com/feder-cr/Jobs_Applier_AI_Agent_AIHawk/issues/1070 | [
"bug"
] | krixx646 | 0 |
pytorch/pytorch | python | 149,837 | Intermittent "AssertionError: can only test a child process" Warning with PyTorch DataLoader on Colab | ### 🐛 Describe the bug
Description
I'm encountering an intermittent warning when training a model on Colab using PyTorch. The warning arises during the shutdown of DataLoader worker processes and reads:
```
Exception ignored in: <function _MultiProcessingDataLoaderIter.__del__ at ...>
...
AssertionError: can only te... | open | 2025-03-24T01:18:56Z | 2025-03-24T18:44:29Z | https://github.com/pytorch/pytorch/issues/149837 | [
"module: multiprocessing",
"module: dataloader",
"triaged"
] | n3than | 0 |
ray-project/ray | machine-learning | 51,387 | [Train] Add support for NeMo Megatron strategy with lightning | ### Description
Similar to the [deepspeed lightning strategy with ray](https://docs.ray.io/en/latest/train/api/doc/ray.train.lightning.RayDeepSpeedStrategy.html#ray.train.lightning.RayDeepSpeedStrategy) I would like to integrate with the NeMo framework to use ray to manage feeding data to and orchestrating MegatronStr... | open | 2025-03-14T21:52:34Z | 2025-03-18T17:12:06Z | https://github.com/ray-project/ray/issues/51387 | [
"enhancement",
"triage",
"train"
] | sam-h-bean | 0 |
nvbn/thefuck | python | 1,391 | Ubuntu installation instructions no longer work | On Ubuntu 23.04 I get the following error when I try `pip3 install thefuck --user`
```
error: externally-managed-environment
× This environment is externally managed
╰─> To install Python packages system-wide, try apt install
python3-xyz, where xyz is the package you are trying to
install.
If... | open | 2023-07-25T20:44:08Z | 2024-04-10T12:17:51Z | https://github.com/nvbn/thefuck/issues/1391 | [] | rzach | 3 |
feder-cr/Jobs_Applier_AI_Agent_AIHawk | automation | 102 | Aı chatot for cv | closed | 2024-08-28T09:27:53Z | 2024-08-28T10:25:22Z | https://github.com/feder-cr/Jobs_Applier_AI_Agent_AIHawk/issues/102 | [] | Ozcanaktan | 0 | |
aimhubio/aim | tensorflow | 3,293 | Metric Explorer > Group Max is --. How do I display the metric value? | ## 🐛 Bug
The "Group Max" doesn't appear, so i can't see anything unless I click to drill in:


### To reproduce
I have groups of 1 becau... | open | 2025-02-19T01:32:41Z | 2025-02-28T15:56:53Z | https://github.com/aimhubio/aim/issues/3293 | [
"type / bug",
"help wanted"
] | bryanwhiting | 1 |
PeterL1n/BackgroundMattingV2 | computer-vision | 7 | foreground residual | First thank you for the great work you shared, I have a question. What is the foreground residual and what is it for? | closed | 2020-12-18T09:17:55Z | 2020-12-20T21:07:26Z | https://github.com/PeterL1n/BackgroundMattingV2/issues/7 | [] | rgbd-zml | 2 |
serengil/deepface | machine-learning | 679 | Redundant condition on functions.extract_faces() | https://github.com/serengil/deepface/blob/ab8470f96f4d7d4575e110464fb83f94c99fa503/deepface/commons/functions.py#L130
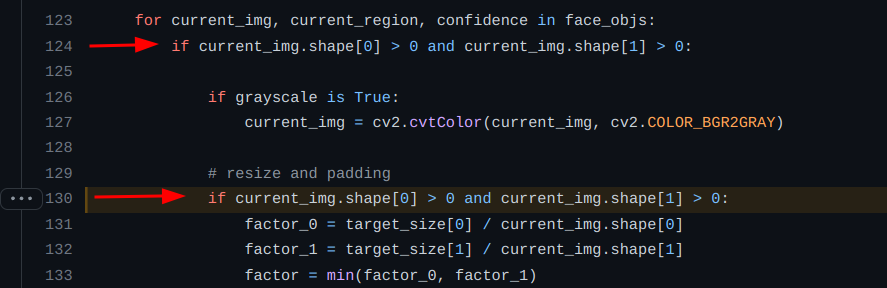
Isn't this `if` redundant? The same condition is checked on the outer `if`, so at this... | closed | 2023-02-20T22:53:56Z | 2023-12-08T22:22:05Z | https://github.com/serengil/deepface/issues/679 | [
"enhancement"
] | wyalves | 2 |
biolab/orange3 | numpy | 6,711 | Predictions should have output with annotated data | **What's your use case?**
1. Train a model, test it in Predictions.
2. In Predictions, select all rows for which the predicted probability of the positive outcome is above certain threshold.
3. Feed *the entire data set* into Distributions (or another widget) to analyze predicted vs. actual class distributions by ... | closed | 2024-01-22T10:25:22Z | 2024-02-07T09:43:41Z | https://github.com/biolab/orange3/issues/6711 | [] | janezd | 0 |
microsoft/unilm | nlp | 751 | Layoutlmv3 LayoutLMv3ForSequenceClassification not working | Hi,
Thanks for release and sharing LayoutlmV3.
I am trying out LayoutLMV3. LayoutLMv3ForTokenClassification works as expected, but LayoutLMv3ForSequenceClassification does not train. I noticed there is a difference between v2 and v3 implementations for LayoutLMv3ForSequenceClassification below.
v2: there are 3... | closed | 2022-06-09T07:28:23Z | 2024-03-27T17:54:22Z | https://github.com/microsoft/unilm/issues/751 | [] | cwei-bgl | 13 |
mars-project/mars | pandas | 3,272 | [BUG] Ray executor run test_classification.test__check_targets may raise KeyError | <!--
Thank you for your contribution!
Please review https://github.com/mars-project/mars/blob/master/CONTRIBUTING.rst before opening an issue.
-->
mars/learn/metrics/tests/test_classification.py::test__check_targets[multiclass-y22-multiclass-y15]
```python
mars/learn/metrics/tests/test_classification.py:137... | closed | 2022-10-09T11:31:45Z | 2022-10-13T03:42:10Z | https://github.com/mars-project/mars/issues/3272 | [
"type: bug",
"mod: ray integration"
] | fyrestone | 0 |
horovod/horovod | deep-learning | 3,190 | Refactor ElasticRayExecutor as part of RayExecutor | Currently, `ElasticRayExecutor` is implemented as a separate class from the normal `RayExecutor`, but this doesn't need to be the case. If we instead add the `ElasticRayExecutor` params to the `RayExecutor` constructor, we can dynamically create an autoscaling worker topology when the user provides `min_workers` or `ma... | closed | 2021-10-01T21:28:11Z | 2021-11-17T07:05:10Z | https://github.com/horovod/horovod/issues/3190 | [
"enhancement"
] | tgaddair | 0 |
deepinsight/insightface | pytorch | 2,503 | Is there any plan to provide 256model? | Is there any plan to provide 256model? | open | 2023-12-31T08:31:28Z | 2023-12-31T08:31:28Z | https://github.com/deepinsight/insightface/issues/2503 | [] | ifredom | 0 |
scikit-learn/scikit-learn | machine-learning | 30,736 | `randomized_svd` incorrect for complex valued matrices | ### Describe the bug
The `randomized_svd` utility function accepts complex valued inputs without error, but the result is inconsistent with `scipy.linalg.svd`.
### Steps/Code to Reproduce
```python
import numpy as np
from scipy import linalg
from sklearn.utils.extmath import randomized_svd
rng = np.random.RandomSta... | open | 2025-01-30T01:40:26Z | 2025-02-04T10:51:40Z | https://github.com/scikit-learn/scikit-learn/issues/30736 | [
"Bug"
] | clane9 | 0 |
marshmallow-code/flask-marshmallow | sqlalchemy | 77 | Schema.jsonify takes dump(...).data | Marshmallow (at least 3.0.0b8) has an implementation of `Schema.dump` that contains a dict of serialized data. However, flask-marshmallow's `Schema.jsonify` tries to take its `data` attribute. (See [source](https://github.com/marshmallow-code/flask-marshmallow/blob/7208b900ecdac881d272378c4ef1482741fe7b9b/flask_marshma... | closed | 2018-04-19T20:08:34Z | 2018-05-15T17:28:24Z | https://github.com/marshmallow-code/flask-marshmallow/issues/77 | [] | jcassee | 2 |
sinaptik-ai/pandas-ai | data-science | 904 | Any useful way to add RAG into PandasAI | ### 🚀 The feature
In order to make sure the PandasAI can generate better code and more accurate results, I have prepared vector database that ready to retrieve. However, I noticed that PandasAI currently are not feature support the RAG. Is any substitute way to let me retrieve my data then give them to PandasAI?
##... | closed | 2024-01-28T03:43:52Z | 2024-04-15T18:51:23Z | https://github.com/sinaptik-ai/pandas-ai/issues/904 | [] | Tu-Zhenzhao | 8 |
jina-ai/serve | machine-learning | 5,425 | fix: update opentelemetry-instrumentation-grpc to v0.35b0 |
Release [v0.35b0](https://github.com/open-telemetry/opentelemetry-python-contrib/releases/tag/v0.35b0) has support for grpc aio client and server implementations. We can remove the custom implementations in the `instrumentation` package. | closed | 2022-11-22T08:42:47Z | 2022-11-22T11:29:09Z | https://github.com/jina-ai/serve/issues/5425 | [] | girishc13 | 0 |
pandas-dev/pandas | python | 60,504 | BUG: concatenation is allowing duplicate columns when axis=1 | ### Pandas version checks
- [X] I have checked that this issue has not already been reported.
- [X] I have confirmed this bug exists on the [latest version](https://pandas.pydata.org/docs/whatsnew/index.html) of pandas.
- [X] I have confirmed this bug exists on the [main branch](https://pandas.pydata.org/docs/... | closed | 2024-12-06T05:52:50Z | 2024-12-08T14:20:14Z | https://github.com/pandas-dev/pandas/issues/60504 | [
"Bug",
"Reshaping"
] | Sakethsreeram7 | 8 |
dynaconf/dynaconf | flask | 397 | Python | closed | 2020-08-23T15:43:33Z | 2020-08-24T16:19:38Z | https://github.com/dynaconf/dynaconf/issues/397 | [
"question"
] | Vaibhav624 | 0 | |
junyanz/pytorch-CycleGAN-and-pix2pix | computer-vision | 1,495 | Expected epoch duration for multi-GPU (4x v100, batch 16) | Per this statement: "I've found that a batch size of 16 fits onto 4 V100s and can finish training an epoch in ~**90s**". However, my own test finds that epoch duration around **330s**. Other than setting batch_size to 16 and gpu_ids _> 0,1,2,3, what can be done to speed up the training to the expected 90s/epoch? The da... | closed | 2022-10-14T22:36:12Z | 2022-10-18T22:35:05Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/1495 | [] | spinoza1791 | 1 |
KaiyangZhou/deep-person-reid | computer-vision | 455 | Reranking Consume way too much memory space especially for MSMT17 dataset | Hi. I am trying to apply reranking on the MSMT17 dataset, which is one of the largest datasets for person reid. However, when I apply rerank it consumes way too much memory space and RAM gets exceeded due to many images in both query and gallery sets. I don't have extremely powerful resources with plenty of RAM space. ... | open | 2021-08-22T11:26:02Z | 2021-08-22T11:26:02Z | https://github.com/KaiyangZhou/deep-person-reid/issues/455 | [] | FatimaZulfiqar | 0 |
fastapi/sqlmodel | fastapi | 319 | Specifying SQL Server column data type, similar to dtype in pd.to_sql() | ### First Check
- [X] I added a very descriptive title to this issue.
- [X] I used the GitHub search to find a similar issue and didn't find it.
- [X] I searched the SQLModel documentation, with the integrated search.
- [X] I already searched in Google "How to X in SQLModel" and didn't find any information.
- [X] I al... | open | 2022-04-29T07:08:40Z | 2024-05-16T20:26:32Z | https://github.com/fastapi/sqlmodel/issues/319 | [
"question"
] | HansOlavMyklebust | 1 |
alteryx/featuretools | data-science | 2,634 | percent_change fails on top of aggregation primitives | [A clear and concise description of what the bug is.]
The transform primitive percent_change fails to work on top of an aggregation primitive, returning NaN or seemingly arbitrary results.
#### Code Sample, a copy-pastable example to reproduce your bug.
These are the transactions:
transaction_id | customer_id |... | open | 2023-11-16T09:27:00Z | 2023-11-16T09:27:00Z | https://github.com/alteryx/featuretools/issues/2634 | [
"bug"
] | enfeizhan | 0 |
developmentseed/lonboard | jupyter | 469 | Improve attribution | closed | 2024-04-19T00:13:35Z | 2024-09-24T19:41:50Z | https://github.com/developmentseed/lonboard/issues/469 | [] | kylebarron | 1 | |
httpie/cli | rest-api | 1,299 | --offline not being recognized | ## Checklist
- [X] I've searched for similar issues.
- [X] I'm using the latest version of HTTPie.
---
OS: Ubuntu 20.04 LTS
## Minimal reproduction code and steps
1. `pip3 install httpie`
2. `http google.com --offline`
## Current result
`http: error: unrecognized arguments: --offline`
…
## Ex... | closed | 2022-02-15T01:16:18Z | 2022-08-04T14:53:36Z | https://github.com/httpie/cli/issues/1299 | [
"not-a-bug"
] | igorcafe | 9 |
christabor/flask_jsondash | flask | 102 | Consider making the project a full featured app vs. a blueprint with more features | This is an open-ended discussion. The desire is to make deployment and usage simple and straightforward, while making it a full-featured application that is simply configured and deployed.
PROS:
* Easier handling of more involved ACLs/RBAC
* Query control and connecting to engines (ala superset)
* Proxy-able en... | open | 2017-05-03T22:56:24Z | 2017-05-03T22:59:23Z | https://github.com/christabor/flask_jsondash/issues/102 | [
"enhancement",
"new feature"
] | christabor | 0 |
plotly/jupyter-dash | dash | 14 | Run jupyter-dash with Jupyterlab2.x + JupyterHub + Kubernetes | Regarding #2, not sure which server proxy it is referring to. Can you point me to the link to the documentation?
Hi @rdelubi,
This issue is specifically concerning Colab, because Colab isn't a standard Jupyter front-end. For regular JupyterHub, it should be enough to:
1. Make sure the `jupyterlab-dash` extensi... | open | 2020-05-26T19:09:25Z | 2023-06-22T04:59:52Z | https://github.com/plotly/jupyter-dash/issues/14 | [] | rdelubi | 16 |
widgetti/solara | fastapi | 219 | Component/Markdown copy content to clipboard | If I am dynamically generating code blocks or markdown, it would be great to have a way to push data to clipboard. If this feature already exists, do we have an example of this? | open | 2023-07-26T19:33:37Z | 2023-07-26T20:22:27Z | https://github.com/widgetti/solara/issues/219 | [] | stikkireddy | 1 |
httpie/cli | rest-api | 1,533 | Docs: Ubuntu/Debian installation script gives error | At [Ubuntu/Debian installation instructions](https://httpie.io/docs/cli/debian-and-ubuntu), the step 2 command
`sudo echo "deb [arch=amd64 signed-by=/usr/share/keyrings/httpie.gpg] https://packages.httpie.io/deb ./" > /etc/apt/sources.list.d/httpie.list`
gives the following error
 or [here](https://medium.com/@tapassd94/smape-vs-mape-f2249cbd4ad5)) produces a zero division if the test data contains actual values that are zero.
Yet Predictions and Test &... | open | 2025-02-27T12:58:35Z | 2025-03-06T18:20:53Z | https://github.com/biolab/orange3/issues/7041 | [
"bug",
"needs discussion",
"snack"
] | wvdvegte | 1 |
widgetti/solara | flask | 837 | [Breaking change] Feature request: Align `solara.Select` & `solara.SelectMultiple` API with standard vue parameter names | `solara.Select{Multiple}` uses custom parameter names of `values`/`all_values`, when it might make more sense to use `value` and `items`.
For reference, consider the `v-select` widget:
> [items](https://vuetifyjs.com/en/api/v-select/#props-items)
> Can be an array of objects or strings. By default objects should... | open | 2024-10-25T17:28:35Z | 2024-10-25T17:28:35Z | https://github.com/widgetti/solara/issues/837 | [] | ntjess | 0 |
deeppavlov/DeepPavlov | nlp | 1,118 | Changing start_message in sever_config.json does not change message in Telegram bot | I built the telegram bot as described in the tutorials. It works fine and gives me context driven inferences to my questions. However, changing the "start_message" and "help_message" entries in the server_config.json file does not change anything in the bot. How can I edit my telegram bot accordingly? Thank you! | closed | 2020-01-16T09:01:45Z | 2020-05-06T09:37:16Z | https://github.com/deeppavlov/DeepPavlov/issues/1118 | [] | ghost | 3 |
matplotlib/matplotlib | data-visualization | 29,578 | [Bug]: button event key error when using %matplotlib widget in jupyter lab | ### Bug summary
Python 3.11
import ipympl
import ipywidgets
import matplotlib
print("ipympl:", ipympl.__version__)
print("ipywidgets:", ipywidgets.__version__)
print("matplotlib:", matplotlib.__version__)
ipympl: 0.9.3
ipywidgets: 8.1.5
matplotlib: 3.10.0
%matplotlib widget
import matplotlib.pyplot as plt
fig, ax ... | closed | 2025-02-04T18:10:10Z | 2025-02-04T18:36:00Z | https://github.com/matplotlib/matplotlib/issues/29578 | [
"status: duplicate",
"backend: ipympl"
] | GanshengT | 1 |
ghtmtt/DataPlotly | plotly | 173 | Data-defined property overrides do not work in layout | The data-defined color/size/width overrides do not work when used in a layout. They work as expected in a normal chart (outside of layout designer). The feature subset filter works in both.
Replacing in the plot factory (e.g. for color)
```
default_value = QColor(self.settings.properties['in_color'])
value, _ =... | closed | 2019-12-06T09:42:28Z | 2019-12-28T05:44:14Z | https://github.com/ghtmtt/DataPlotly/issues/173 | [] | SGroe | 5 |
sqlalchemy/alembic | sqlalchemy | 498 | Confusing upgrade log | **Migrated issue, originally created by Samuel Carlsson ([@vidstige](https://github.com/vidstige))**
As a new user I would like to be impressed by alembic. However, upon first meeting alembic, it emitts the following confusing info logging. I don't really know how this is relevant to me. Perhaps these messages could b... | closed | 2018-06-16T07:55:01Z | 2018-06-28T09:42:33Z | https://github.com/sqlalchemy/alembic/issues/498 | [
"bug",
"wontfix",
"command interface"
] | sqlalchemy-bot | 6 |
huggingface/datasets | computer-vision | 6,796 | CI is broken due to hf-internal-testing/dataset_with_script | CI is broken for test_load_dataset_distributed_with_script. See: https://github.com/huggingface/datasets/actions/runs/8614926216/job/23609378127
```
FAILED tests/test_load.py::test_load_dataset_distributed_with_script[None] - assert False
+ where False = all(<generator object test_load_dataset_distributed_with_scr... | closed | 2024-04-10T06:56:02Z | 2024-04-12T09:02:13Z | https://github.com/huggingface/datasets/issues/6796 | [
"bug"
] | albertvillanova | 4 |
strawberry-graphql/strawberry | django | 3,134 | Add documentation for provided federated schema directives | Strawberry helpfully provides a bunch of federated schema directives we can use:
https://github.com/strawberry-graphql/strawberry/blob/628e4980b50e317cf99999aef052b8bb095370df/strawberry/federation/schema_directives.py
There's no reference to the provided directives in documentation, so I didn't even know they exis... | closed | 2023-10-05T13:59:37Z | 2025-03-20T15:56:24Z | https://github.com/strawberry-graphql/strawberry/issues/3134 | [] | bradleyoesch | 2 |
ymcui/Chinese-BERT-wwm | tensorflow | 75 | About the learning rate of RoBerta in the finetuning stage? | Can you provide the best learning rate for different tasks with Roberta? I can not find this in the technical report. | closed | 2019-11-19T02:43:59Z | 2019-11-19T02:55:27Z | https://github.com/ymcui/Chinese-BERT-wwm/issues/75 | [] | zhengwsh | 1 |
AirtestProject/Airtest | automation | 400 | Please check if iOS app installation method is correct. | This will cause an iOS app install error. Please let me know how.
from airtest.core.ios improt *
install_app("/Users/username/Downloads/aaa.ipa") | closed | 2019-05-13T06:33:56Z | 2019-05-13T06:36:21Z | https://github.com/AirtestProject/Airtest/issues/400 | [] | JJunM | 1 |
tensorflow/tensor2tensor | deep-learning | 1,122 | Return_beams in Decode-hparams slows Performance by a Factor 7 | ### Description
When decoding and allowing for beam search (e.g. with beam size 4) the model takes about 1 sec for results. When doing so with decode_hparams return_beams enabled the model needs 7 sec.
Any idea why that is?
The beam-search happens in both szenarios. Why then does one szenario take 7 times as... | open | 2018-10-09T14:16:23Z | 2018-10-09T14:16:23Z | https://github.com/tensorflow/tensor2tensor/issues/1122 | [] | friesel | 0 |
yeongpin/cursor-free-vip | automation | 69 | 🔄 重置機器ID... ℹ️ 檢查配置文件... ❌ 無法讀取或寫入配置文件,請檢查文件權限 ❌ 保存賬戶信息失敗 | 
请问如何解决呢 | closed | 2025-02-16T01:24:19Z | 2025-02-16T01:29:07Z | https://github.com/yeongpin/cursor-free-vip/issues/69 | [] | szsyzx | 0 |
voxel51/fiftyone | computer-vision | 5,459 | [BUG] "Not Found" when running "fo.launch_app()" - maybe due to version 1.4.0 | I encountered two issues while using FiftyOne on Windows 11:
1. When launching the app with fo.launch_app(), the browser opens to http://localhost:5151 but shows a black screen with a "Not Found" error.

2. After uninstalling ve... | open | 2025-02-03T13:19:13Z | 2025-02-14T18:04:14Z | https://github.com/voxel51/fiftyone/issues/5459 | [
"bug"
] | lejrn | 7 |
huggingface/datasets | deep-learning | 6,808 | Make convert_to_parquet CLI command create script branch | As proposed by @severo, maybe we should add this functionality as well to the CLI command to convert a script-dataset to Parquet. See: https://github.com/huggingface/datasets/pull/6795#discussion_r1562819168
> When providing support, we sometimes suggest that users store their script in a script branch. What do you th... | closed | 2024-04-15T06:46:07Z | 2024-04-17T08:38:19Z | https://github.com/huggingface/datasets/issues/6808 | [
"enhancement"
] | albertvillanova | 0 |
dpgaspar/Flask-AppBuilder | flask | 1,814 | ERROR - Error returning OAuth user info | We are trying to use Okta Oauth for Airflow authentication, but we are unbale to login to the airlow applicaion
**Environment**
Flask-Appbuilder version: 3.2.2
Authlib : 0.15.5
Airflow Version: apache/airflow:2.1.0-python3.8
**Describe the expected results**
Okta OAuth should be able to authenticate and r... | closed | 2022-03-10T04:31:05Z | 2024-04-01T13:34:47Z | https://github.com/dpgaspar/Flask-AppBuilder/issues/1814 | [] | iammsa | 16 |
CorentinJ/Real-Time-Voice-Cloning | pytorch | 603 | Is it possible to input our mic voice instead of text? | I think it would be cool to have my voice as input processed in real time to make it sound like another voice. | closed | 2020-11-22T12:44:25Z | 2020-11-22T17:40:38Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/603 | [] | BabylonianAngel | 1 |
sgl-project/sglang | pytorch | 4,385 | [Feature] integrate flash-attention | ### Checklist
- [ ] 1. If the issue you raised is not a feature but a question, please raise a discussion at https://github.com/sgl-project/sglang/discussions/new/choose Otherwise, it will be closed.
- [ ] 2. Please use English, otherwise it will be closed.
### Motivation
similar with https://github.com/sgl-project/... | open | 2025-03-13T10:50:36Z | 2025-03-18T05:39:22Z | https://github.com/sgl-project/sglang/issues/4385 | [
"high priority"
] | zhyncs | 1 |
junyanz/pytorch-CycleGAN-and-pix2pix | deep-learning | 887 | Preprocess None on pix2pix | I am working with images 400x600, and trained a resnet6 pix2pix with --preprocess None. The output images are 200x600, and it is the left cropped image from the former 400x600 image, even though I specify --preprocess None during testing. Any help? | open | 2019-12-23T10:16:12Z | 2019-12-30T04:34:29Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/887 | [] | brunoaibanez | 1 |
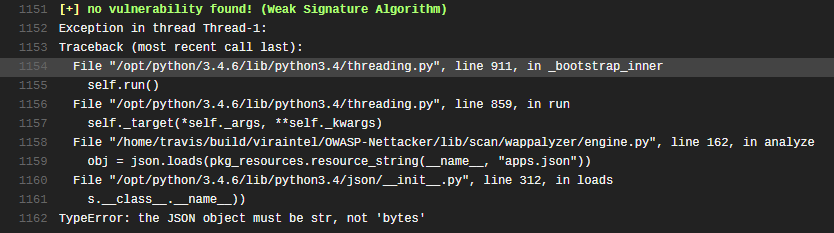
OWASP/Nettacker | automation | 94 | Error in threading (python 3.4, 3.5) | Error Fetched from Travis CI
_________________
"os": "linux",
**Python Version**: "3.4","3.5"

/usr/local/lib/python3.6/dist-packages/tensorflow/py... | open | 2018-08-09T05:13:56Z | 2021-05-28T15:47:53Z | https://github.com/minimaxir/textgenrnn/issues/63 | [] | anguslou | 1 |
miguelgrinberg/microblog | flask | 312 | super(Class, self) -> super() | https://github.com/miguelgrinberg/microblog/blob/8f43aadd412cd141effccedf1cfe2bff4e0d1f0d/app/forms.py#L41
Hi Miguel,
many many thanks for creating this absolute masterpiece of tutorial! I cannot tell you how much I appreciate all the work and time put into it. You are the real MVP!
I'm trying to give back to ... | closed | 2021-11-24T22:20:34Z | 2023-12-03T10:55:40Z | https://github.com/miguelgrinberg/microblog/issues/312 | [
"enhancement"
] | TimoRJensen | 5 |
BeanieODM/beanie | asyncio | 119 | Init TimeSeries Collections | Hello,
How to create TimeSeries Collection ?
https://docs.mongodb.com/manual/core/timeseries-collections/#create-a-time-series-collection
The mongo query as exemple:
```
db.createCollection(
"weather24h",
{
timeseries: {
timeField: "timestamp",
metaField: "metadata",
granularit... | open | 2021-09-24T22:17:52Z | 2025-02-04T14:47:04Z | https://github.com/BeanieODM/beanie/issues/119 | [
"feature request"
] | acrozes | 4 |
drivendataorg/cookiecutter-data-science | data-science | 328 | Add Python 3.12 support | - [x] Update tests
- [x] Update pyproject.toml | closed | 2023-10-09T20:48:52Z | 2024-01-31T17:55:01Z | https://github.com/drivendataorg/cookiecutter-data-science/issues/328 | [] | chrisjkuch | 4 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.