
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
dask/dask | numpy | 11,376 | Slicing an array on the last chunk of an axis duplicates the number of chunks | <!-- Please include a self-contained copy-pastable example that generates the issue if possible.
Please be concise with code posted. See guidelines below on how to provide a good bug report:
- Craft Minimal Bug Reports http://matthewrocklin.com/blog/work/2018/02/28/minimal-bug-reports
- Minimal Complete Verifiab... | closed | 2024-09-06T01:07:30Z | 2024-09-06T01:44:39Z | https://github.com/dask/dask/issues/11376 | [
"needs triage"
] | josephnowak | 3 |
flasgger/flasgger | api | 14 | Allow spec inheritance for yaml | A yaml file should be able to inherit from parent
| closed | 2016-01-11T21:31:51Z | 2017-03-30T01:35:53Z | https://github.com/flasgger/flasgger/issues/14 | [] | rochacbruno | 1 |
mithi/hexapod-robot-simulator | dash | 7 | Experiment with different user interfaces for pose control | Based on experience,
it is better if you can write the value you want directly
rather than finding where exactly in the slider is that value. | closed | 2020-02-19T04:29:36Z | 2020-04-01T08:32:20Z | https://github.com/mithi/hexapod-robot-simulator/issues/7 | [
"feature request"
] | mithi | 2 |
graphql-python/graphql-core | graphql | 95 | Implement specifiedBy directive merged into graphql-js | As per issue [#649](https://github.com/graphql/graphql-spec/pull/649) and the [merged pr](https://github.com/graphql/graphql-js/pull/2276) the reference implementation now includes a new directive.
I understand that this lib is intended as a 1 to 1 port to graphql-js so perhaps we should consider including it.
If not p... | closed | 2020-05-29T00:50:10Z | 2020-05-29T14:30:13Z | https://github.com/graphql-python/graphql-core/issues/95 | [] | Ambro17 | 2 |
labmlai/annotated_deep_learning_paper_implementations | machine-learning | 131 | About DDPM q_sample why is the official implementation different from this code? | Thanks for releasing the detailed implementation.
I checked official [DDPM](https://github.com/hojonathanho/diffusion/blob/1e0dceb3b3495bbe19116a5e1b3596cd0706c543/diffusion_tf/diffusion_utils.py#L188) and [DDIM](https://github.com/ermongroup/ddim/blob/51cb290f83049e5381b09a4cc0389f16a4a02cc9/functions/denoising.py#... | closed | 2022-06-30T07:38:58Z | 2022-07-17T04:03:23Z | https://github.com/labmlai/annotated_deep_learning_paper_implementations/issues/131 | [
"question"
] | ryhhtn | 1 |
unionai-oss/pandera | pandas | 1,133 | check_output/check_input/check_io support for DataFrameModel | #### Question about pandera
Why, insofar as the types are concerned, doesn't the `check_output`-decorator support `DataFrameModel`?
This code will give the correct error at runtime,
```python
import pandera as pa
import pandas as pd
from pandera.typing import DataFrame, Series
from pandera.decorators impo... | open | 2023-03-22T08:01:44Z | 2023-03-23T13:15:27Z | https://github.com/unionai-oss/pandera/issues/1133 | [
"enhancement",
"help wanted"
] | filipallberg | 2 |
dropbox/PyHive | sqlalchemy | 446 | Unable to connect to Azure HDinsight Hive DB using PyHive python | Hello
I am new to Hive and bigdata.
I am trying to connect to Azure Hdinsight Hive DB using PyHive from last 2 days but unable to connect.
Code :-
--------------------------------------------------------------------------------------------------------------------------------------
from pyhive import hive
impo... | open | 2023-03-06T11:54:18Z | 2023-03-06T11:54:18Z | https://github.com/dropbox/PyHive/issues/446 | [] | Vikrant1020 | 0 |
lepture/authlib | flask | 143 | Non-Compliant refresh token params | The documentation states: "If you find a non standard OAuth 2 services, and you can’t fix it. Please report it in GitHub issues." So here is mine, found when integrating with a Ruby on Rail app:
When refreshing a token, the spec (https://tools.ietf.org/html/rfc6749#section-6) only asks for grant_type, refres_token a... | closed | 2019-08-15T21:19:52Z | 2019-08-17T14:04:47Z | https://github.com/lepture/authlib/issues/143 | [] | yclybouw | 1 |
supabase/supabase-py | fastapi | 860 | missing await in async create_client on 2.5.2 and up | # Bug report
## Describe the bug
The async `create_client` function uses an async function (`AsyncClient.create`) without awaiting it, leading to the return of a double-nested coroutine that needs two await calls to get to the client. The signature mismatches the actually returned type.
Users who try using the... | closed | 2024-07-16T16:23:39Z | 2024-07-16T19:10:51Z | https://github.com/supabase/supabase-py/issues/860 | [
"bug"
] | realChesta | 4 |
sinaptik-ai/pandas-ai | data-science | 833 | Polars DataFrame | ### System Info
from pandasai import SmartDataframe
import polars as pl
from langchain.chat_models import ChatOpenAI
import config as co
llm = ChatOpenAI(temperature=0, model_name=co.model_name, openai_api_key=co.openai_api_key, openai_api_base=co.openai_api_base)
df = pl.DataFrame({
"country": ["United ... | closed | 2023-12-22T05:45:47Z | 2024-06-01T00:19:41Z | https://github.com/sinaptik-ai/pandas-ai/issues/833 | [] | Rainismer | 1 |
christabor/flask_jsondash | flask | 63 | Use c3.load to reload data instead of re-generating in c3js | For performance and transition animations.
| closed | 2016-10-24T18:50:48Z | 2017-07-11T17:34:10Z | https://github.com/christabor/flask_jsondash/issues/63 | [
"enhancement",
"performance"
] | christabor | 2 |
alpacahq/alpaca-trade-api-python | rest-api | 65 | How to parse api.submit_order() response | The response after submitting api.submit_order() returns a data type 'entity.Order'.
I can't figure out how to parse this object to extract information, such as, 'client_order_id'.
api.list_orders() has a similar issue in that it puts these objects into a list.
Is there some other method I should be using to o... | closed | 2019-04-28T14:43:14Z | 2019-06-17T01:52:44Z | https://github.com/alpacahq/alpaca-trade-api-python/issues/65 | [] | Jacyle | 3 |
keras-team/keras | data-science | 20,031 | How to handle grayscale images when using fine-tune with VGG16? | Hi keras team!
I am trying to use pre trained VGG16 with SRGAN and grayscale images when I use the VGG16 in this way:
```
def build_vgg():
input_shape = (256, 256, 3)
# Load a pre-trained VGG19 model trained on 'Imagenet' dataset
vgg = VGG19(weights="imagenet",include_top=False,
inpu... | closed | 2024-07-23T12:36:33Z | 2024-08-29T01:57:37Z | https://github.com/keras-team/keras/issues/20031 | [
"type:support",
"stat:awaiting response from contributor",
"stale"
] | mearcla | 6 |
SALib/SALib | numpy | 25 | Strange sample | Hi,
first: thanks for this library! (I'm using it for SA of building simulation models.)
I have a question regarding the Morris sampling strategy. I'm using v0.2 (but had the same issues before).
I use the following code to create a sample, and then visualize my sample (not all dependencies included, but you can get... | closed | 2014-12-08T14:47:44Z | 2014-12-08T16:52:05Z | https://github.com/SALib/SALib/issues/25 | [] | saroele | 5 |
pandas-dev/pandas | python | 60,803 | BUG: Most recent conda-forge package limited to python 3.9? | ### Pandas version checks
- [x] I have checked that this issue has not already been reported.
- [x] I have confirmed this bug exists on the [latest version](https://pandas.pydata.org/docs/whatsnew/index.html) of pandas.
- [x] I have confirmed this bug exists on the [main branch](https://pandas.pydata.org/docs/dev/ge... | closed | 2025-01-27T23:33:33Z | 2025-01-30T21:10:40Z | https://github.com/pandas-dev/pandas/issues/60803 | [
"Bug",
"Build"
] | schorlton-bugseq | 9 |
noirbizarre/flask-restplus | flask | 462 | Swagger UI assumes body payload when using api_ns.expect(model) for HTTP GET handler | Looking through the the [docs](http://flask-restplus.readthedocs.io/en/stable/swagger.html), there's an example of setting a model as an expected input to the get request handler, and to me it would be reasonable to assume that restplus would use this model to validate query string parameters as it's the only place tha... | open | 2018-06-04T13:42:22Z | 2019-12-23T04:56:27Z | https://github.com/noirbizarre/flask-restplus/issues/462 | [] | mr-tabasco | 5 |
exaloop/codon | numpy | 492 | module imports don't seem to work | Imports do not seem to work on a basic python project.
It is common for a python project to be packaged as a module. In order for imports to work correctly, typically the entry point script is a very basic python file that imports the main function from a module.
For example, my directory:
```
- root/
- a... | closed | 2023-10-19T03:46:28Z | 2023-11-10T23:22:56Z | https://github.com/exaloop/codon/issues/492 | [] | nhumrich | 3 |
robinhood/faust | asyncio | 689 | Compatibility with asgiref.sync | ## Checklist
- [x] I have included information about relevant versions
- [x] I have verified that the issue persists when using the `master` branch of Faust.
## Steps to reproduce
I'd like to use the Django ORM to save some data into Postgres. Django [recommends using asgiref's `sync_to_async`](https://docs.d... | open | 2020-11-17T20:23:53Z | 2023-04-05T11:19:31Z | https://github.com/robinhood/faust/issues/689 | [] | fcurella | 1 |
deepset-ai/haystack | pytorch | 8,241 | Update tests in core integration: llama cpp | closed | 2024-08-15T14:26:14Z | 2024-08-19T13:20:17Z | https://github.com/deepset-ai/haystack/issues/8241 | [
"P1"
] | shadeMe | 1 | |
GibbsConsulting/django-plotly-dash | plotly | 179 | Add Dash classifier to PyPi config | Classifier now [available](https://github.com/pypa/warehouse/issues/6273) | closed | 2019-10-27T17:59:00Z | 2019-10-28T03:52:55Z | https://github.com/GibbsConsulting/django-plotly-dash/issues/179 | [] | GibbsConsulting | 0 |
flasgger/flasgger | rest-api | 240 | Deploy 0.9.1 to http://flasgger.pythonanywhere.com | As an aside to this - I have been mucking with some pythonanywhere scripting. There are quite a few limitations to be aware of, but provided you are willing to do some initial manual set-up, it is possible to fashion a semi CI/CD from Travis to pythonanywhere. So it would be possible to host a flasgger-master.pythona... | closed | 2018-09-13T04:47:10Z | 2018-09-14T01:03:10Z | https://github.com/flasgger/flasgger/issues/240 | [
"pythonanywhere",
"demo_app"
] | javabrett | 4 |
hzwer/ECCV2022-RIFE | computer-vision | 243 | Which .py include RIFE-Large? | Hi, I am so exciting about your work!
I want to know where is the RIFE-Large(2T2R)?
Thanks! | closed | 2022-04-04T10:12:29Z | 2022-04-13T03:57:23Z | https://github.com/hzwer/ECCV2022-RIFE/issues/243 | [] | silenye | 7 |
explosion/spaCy | machine-learning | 13,586 | Issue template link points to wrong address | <!-- Describe the problem or suggestion here. If you've found a mistake and you know the answer, feel free to submit a pull request straight away: https://github.com/explosion/spaCy/pulls -->
## Which page or section is this issue related to?
### CONTRIBUTING.md
Under the "Submitting Issues" section of the Contrib... | open | 2024-08-01T20:06:17Z | 2024-08-01T20:14:07Z | https://github.com/explosion/spaCy/issues/13586 | [] | samrxh | 0 |
youfou/wxpy | api | 426 | 微信个人号API 可以看下这个wkteam.gitbook.io,2017年前只要没登录过网页版微信的 用不了wxpy哦~ | 看下这个即可wkteam.gitbook.io | closed | 2019-11-25T02:57:12Z | 2019-12-04T02:37:23Z | https://github.com/youfou/wxpy/issues/426 | [] | 2048537793 | 0 |
onnx/onnxmltools | scikit-learn | 406 | NameError: name 'FloatTensorType' is not defined | I have defined the FloatTensorType
is there a different module to import FloatTensorType for xgboost to onnx conversion
First I convert the sklearn randomforest model, it worked, next I convert the xgbclassifier from xgboost, it throws the FloatTensorType not defined,
I tried
from onnxmltools.convert.common.data... | closed | 2020-07-10T09:19:12Z | 2020-07-10T23:11:20Z | https://github.com/onnx/onnxmltools/issues/406 | [] | hanzigs | 1 |
marcomusy/vedo | numpy | 1,017 | Mesh intersect_with_line irregular processing time | Hello,
I'm using vedo for a project of mine, where I have an optimization problem that requires finding a point on the intersection of a vedo mesh with a line. This optimization is called thousands of times and the bottleneck of the processing time seems to be finding the intersection of the line with the mesh.
Th... | open | 2024-01-15T09:55:17Z | 2024-01-15T14:32:55Z | https://github.com/marcomusy/vedo/issues/1017 | [] | Cryaaa | 2 |
tensorflow/tensor2tensor | machine-learning | 1,068 | tensor2tensor CNN_Dailymail32k summarization bug | ### Description
The data generation for the CNN_Dailymail32k problem fails due to a unicode related error when writing to file.
...
### Environment information
$ nvidia-smi (within docker container)
Sun Sep 16 10:32:31 2018
+-----------------------------------------------------------------------------+... | open | 2018-09-16T11:02:07Z | 2018-09-16T11:02:07Z | https://github.com/tensorflow/tensor2tensor/issues/1068 | [] | Littlenova | 0 |
pytest-dev/pytest-xdist | pytest | 792 | Environment variable to specify number of workers for "auto" | Would you accept a PR to read an environment variable when determining what `-n auto` means?
Concrete use case:
We're trying to make testing easier in Fedora RPM builds, where one should ideally use a somewhat obscure macro (`%{_smp_build_ncpus}`) for the best number of processes on a builder machine, but many pack... | closed | 2022-07-12T09:22:21Z | 2022-10-24T12:33:20Z | https://github.com/pytest-dev/pytest-xdist/issues/792 | [
"enhancement"
] | encukou | 3 |
igorbenav/FastAPI-boilerplate | sqlalchemy | 5 | Dbdiagram after making repository public | <img width="739" alt="dbdiagram" src="https://github.com/igormagalhaesr/FastAPI-boilerplate/assets/43156212/0531a62d-7740-4c2a-9fd7-7f349cffdc8e">
| closed | 2023-10-10T20:13:35Z | 2023-11-21T00:36:43Z | https://github.com/igorbenav/FastAPI-boilerplate/issues/5 | [] | igorbenav | 3 |
mjhea0/flaskr-tdd | flask | 70 | Database Setup Test | There appears to be an issue with the test_database function. The guide claims that the test should pass, however the function is looking for the file in the tests directory but it does not exist there as it is in the parent directory.
def test_database():
assert Path("flaskr.db").is_file()
My current direct... | closed | 2021-01-05T13:37:05Z | 2022-06-03T16:49:00Z | https://github.com/mjhea0/flaskr-tdd/issues/70 | [] | clifford-b | 1 |
graphql-python/graphene-django | graphql | 1,524 | Could not import 'myapp.schema.schema' for Graphene setting 'SCHEMA'. ModuleNotFoundError: No module named 'urllib3.packages.six.moves'. |
* **What is the current behavior?**
when tunning server and visiting the site, I get the error :
Could not import 'framework.schema.schema' for Graphene setting 'SCHEMA'. ModuleNotFoundError: No module named 'urllib3.packages.six.moves'.
the related setting part is:
GRAPHENE = {
'SCHEMA': 'framework.sc... | closed | 2024-06-07T02:07:15Z | 2024-06-07T02:22:42Z | https://github.com/graphql-python/graphene-django/issues/1524 | [
"🐛bug"
] | hazho | 1 |
bendichter/brokenaxes | matplotlib | 34 | Using colorbars | Creating a plot with e.g.
```
fig = plt.figure()
bax = brokenaxes(xlims=x_lims)
tcf = bax.tricontourf(x_total, y_total, z_total)
```
works fine. However adding the colorbar doesn't. bax.tricontourf seems to return a list of all the different plots. Passing just one to colorbar
`fig.colorbar(tcf[0])`
works... | open | 2019-06-03T12:06:46Z | 2019-07-16T16:24:17Z | https://github.com/bendichter/brokenaxes/issues/34 | [] | MrLalelu | 3 |
jumpserver/jumpserver | django | 14,761 | [Question] jumpserver 3.10.10 版本通过 helm 升级到 3.10.11组件 chen 报错 | ### 产品版本
3.10.10
### 版本类型
- [X] 社区版
- [ ] 企业版
- [ ] 企业试用版
### 安装方式
- [ ] 在线安装 (一键命令安装)
- [ ] 离线包安装
- [ ] All-in-One
- [ ] 1Panel
- [X] Kubernetes
- [ ] 源码安装
### 环境信息
kubenetes v1.28.0
jumpserver v3.10.10
### 🤔 问题描述
$ helm upgrade --install jms-k8s jumpserver/jumpserver -n jumpserver -f values.yaml
Releas... | closed | 2025-01-03T14:42:39Z | 2025-02-21T09:12:12Z | https://github.com/jumpserver/jumpserver/issues/14761 | [
"🤔 Question"
] | l-duan | 1 |
sunscrapers/djoser | rest-api | 271 | Wrong Error message. | I'm getting the same error message when the credentials are invalid and when the account is not active. I don't understand why the INACTIVE_ACCOUNT_ERROR is not being raised.
``
curl -X POST http://127.0.0.1:8000/auth/token/create/ --data 'email=adam@gmail.com&password=nottherealone'
{"auth_token":"11c05aade9a7765... | closed | 2018-03-20T15:24:55Z | 2023-03-09T16:04:17Z | https://github.com/sunscrapers/djoser/issues/271 | [] | adamshamsudeen | 2 |
davidsandberg/facenet | tensorflow | 1,203 | Degradation of validation accuracy | Hi,
I have pruned 5% of filters from the facenet model having least l1 norm and calculated the validation accuracy for pruned model on lwf dataset, i am getting 6%
In order to resolve this i assigned zero to the pruned filters and did not prune those filters, with this change i am getting 96% vaidation accuracy.
... | open | 2021-06-29T08:24:20Z | 2021-06-29T08:24:20Z | https://github.com/davidsandberg/facenet/issues/1203 | [] | Sheethal00 | 0 |
microsoft/nni | tensorflow | 5,648 | no module named nni.algorithms.compression | **Describe the issue**:
from nni.algorithms.compression.v2.pytorch import TorchEvaluator gives an import error: no module named nni.algorithms.compression
I have nni 999.dev0 version installed on my jetson orin
**Environment**:
- NNI version: 999.dev0
| open | 2023-07-20T15:51:02Z | 2023-08-11T06:57:02Z | https://github.com/microsoft/nni/issues/5648 | [] | ankitknitj | 2 |
ultralytics/ultralytics | deep-learning | 19,809 | The evaluation metrics of the YOLO segmentation model are inconsistent with those of the COCO API. | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
While using COCO API to evaluate the metrics of the YOLOv11 segmentation mod... | open | 2025-03-21T04:11:53Z | 2025-03-24T00:23:00Z | https://github.com/ultralytics/ultralytics/issues/19809 | [
"question",
"segment"
] | czheyutao | 4 |
huggingface/datasets | numpy | 6,864 | Dataset 'rewardsignal/reddit_writing_prompts' doesn't exist on the Hub | ### Describe the bug
The dataset `rewardsignal/reddit_writing_prompts` is missing in Huggingface Hub.
### Steps to reproduce the bug
```
from datasets import load_dataset
prompt_response_dataset = load_dataset("rewardsignal/reddit_writing_prompts", data_files="prompt_responses_full.csv", split='train[:80%]... | closed | 2024-05-03T06:03:30Z | 2024-05-06T06:36:42Z | https://github.com/huggingface/datasets/issues/6864 | [] | vinodrajendran001 | 1 |
awesto/django-shop | django | 748 | Support for multiple CatalogListCMSApp instances | Hi,
I have a configuration with two products. These two products should be separated for this reason i have made two instances of `CatalogListCMSApp`. It seems django CMS supports this behavior. I can connect pages to applications. But i have different situation in admin page. I see pages as categories only for the ... | closed | 2018-09-08T10:23:02Z | 2018-10-05T09:34:33Z | https://github.com/awesto/django-shop/issues/748 | [] | dismine | 10 |
tensorpack/tensorpack | tensorflow | 570 | Bug:(maybe) can't install by 'pip install -U git+https://github.com/ppwwyyxx/tensorpack.git' | I can not install tensorpack using
`pip install -U git+https://github.com/ppwwyyxx/tensorpack.git`
and
`pip install -U git+https://github.com/ppwwyyxx/tensorpack.git --user`
does't work.
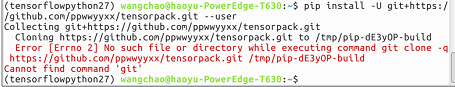
Finally, I ... | closed | 2017-12-26T03:42:48Z | 2018-05-30T20:59:30Z | https://github.com/tensorpack/tensorpack/issues/570 | [] | chaow94 | 2 |
Gerapy/Gerapy | django | 235 | Fix code scanning alert - Full server-side request forgery | <!-- Warning: The suggested title contains the alert rule name. This can expose security information. -->
Tracking issue for:
- [ ] https://github.com/Gerapy/Gerapy/security/code-scanning/29
| open | 2022-04-12T04:02:31Z | 2022-04-12T04:02:31Z | https://github.com/Gerapy/Gerapy/issues/235 | [] | Germey | 0 |
StackStorm/st2 | automation | 6,167 | old pytz version | ## SUMMARY
st2 uses old version of pytz, witch makes it incompatible with other package(e.g. recurring-ical-events==2.1.3)
### STACKSTORM VERSION
```
st2 --version
st2 3.9dev, on Python 3.9.18
```
##### OS, environment, install method
Debian GNU/Linux 11 (bullseye)
Docker
pip
## Steps to reproduce ... | open | 2024-03-17T14:57:37Z | 2024-03-17T14:57:37Z | https://github.com/StackStorm/st2/issues/6167 | [] | zoifar | 0 |
voila-dashboards/voila | jupyter | 881 | Bqplot.PanZoom zoom doesn't work in jupyter notebook and voila | **Describe the bug**
Dear bqplot and voila developers,
Not sure if this is a `bplot` problem or a `voila` issue, starting posting here to seek for feedback.
The _zoom_ functionality from the `bqplot.Panzoom` interaction widget doesn't seem to work in a `notebook` context or in `voila`.
It's possible to _pan_ and ... | closed | 2021-05-05T08:55:55Z | 2021-05-05T09:14:08Z | https://github.com/voila-dashboards/voila/issues/881 | [] | sntgluca | 3 |
MaxHalford/prince | scikit-learn | 73 | color labels raise error | Hello,
I am trying to do a PCA on my dataset, it works fine unless I try to use the color_labels argument. If I only use `labels=my_labels` it works.
Any idea of how I can solve this ? (It also works with the iris dataset however I can find no difference of object types or format with my own dataset.)
Here is the ... | closed | 2019-08-01T10:59:52Z | 2023-02-27T11:45:47Z | https://github.com/MaxHalford/prince/issues/73 | [
"needs investigating"
] | AntoineHo | 4 |
deepset-ai/haystack | nlp | 8,356 | Rename internal mentions of `from_socket` and `to_socket` to `sender_socket` and `receiver_socket` | The internal data of the `Pipeline` graph stores some informations about its edges, like the name of the inputs and outputs of the connected Components.
In [newer parts](https://github.com/deepset-ai/haystack/blob/3016c5ca93b2532836f3ffd2d4bd31114e8ddfa3/haystack/core/component/types.py#L48) of the code like in `Inp... | open | 2024-09-11T15:39:09Z | 2025-01-10T09:28:22Z | https://github.com/deepset-ai/haystack/issues/8356 | [
"type:refactor",
"topic:DX",
"P3"
] | silvanocerza | 0 |
benbusby/whoogle-search | flask | 1,100 | [BUG] Docker Container Going "Unhealthy" and Whoogle Stops working Every Day or Two | After upgrading to v0.8.4, about 1-2 days after starting the docker container, the status goes "Unhealthy" and Whoogle's webpage stops loading/container seemingly is completely not responding until I restart it. Then status is "Healthy" again until 1-2 days later where it fails yet again. The logs in docker for the con... | open | 2023-11-19T15:56:30Z | 2024-12-30T12:33:20Z | https://github.com/benbusby/whoogle-search/issues/1100 | [
"bug"
] | ilovepancakes95 | 16 |
nerfstudio-project/nerfstudio | computer-vision | 3,073 | Camera Optimizer has different pose adjustments when applied to Raybundle and Camera. | Hi developers,
I found a pretty tricky computation inconsistency issue on `camera_optimizer`'s `apply_to_*` functions:
https://github.com/nerfstudio-project/nerfstudio/blob/babf57718c75e7d04f1b977f035db67c02a9c20a/nerfstudio/cameras/camera_optimizers.py#L148-L168
The rotation and translation shown in the above... | closed | 2024-04-13T03:41:30Z | 2024-05-29T14:08:56Z | https://github.com/nerfstudio-project/nerfstudio/issues/3073 | [] | nexuslrf | 4 |
koxudaxi/datamodel-code-generator | fastapi | 2,097 | merge generated structure based on version and apiversion/kind structure | we generate datamodels from a folder structure
"--input-file-type",
"openapi",
"--input",
".",
"--output-model-type",
"pydantic_v2.BaseModel",
"--target-python-version",
"3.12",
"--use-field-description",
"--output",
"models".
the output looks like... | open | 2024-10-02T18:35:48Z | 2024-10-28T18:46:36Z | https://github.com/koxudaxi/datamodel-code-generator/issues/2097 | [] | haarchri | 0 |
miguelgrinberg/python-socketio | asyncio | 825 | hello, I want to know how to send msg that from rabbitmq to client with python socketio, can give me a example? thanks a lot | **Is your feature request related to a problem? Please describe.**
A clear and concise description of what the problem is. Ex. I'm always frustrated when [...]
**Describe the solution you'd like**
A clear and concise description of what you want to happen.
**Describe alternatives you've considered**
A clear an... | closed | 2021-12-02T06:18:42Z | 2021-12-02T10:44:54Z | https://github.com/miguelgrinberg/python-socketio/issues/825 | [] | flyyabelle | 1 |
WZMIAOMIAO/deep-learning-for-image-processing | deep-learning | 536 | Swin Transformer在Stanford Car数据集上不收敛 | Swin Transformer实现非常好,代码清晰易读,比官方代码易于学习使用。我用Swin Transformer中flower_photos数据集,训练效果非常好。
但是我换成Stanford Car数据集,其共有8841张图片,共有196个类别,训练了几十个epoch,发现只有0.5%左右的精度,一直涨不上去,这是由于什么原因造成的?怎么解决?
Stanford Car数据集:http://ai.stanford.edu/~jkrause/cars/car_dataset.html | closed | 2022-04-25T03:46:09Z | 2022-04-25T03:47:20Z | https://github.com/WZMIAOMIAO/deep-learning-for-image-processing/issues/536 | [] | yt7589 | 0 |
thp/urlwatch | automation | 211 | notify more than one Telegram chat id | I tried this:
```
report:
telegram:
bot_token: '#'
chat_id: '#'
enabled: true
telegram:
bot_token: '#'
chat_id: '#'
enabled: true
```
But it didn't worked for both chat_id, it just sent the notification to the last one. There's any way I can notify both ... | closed | 2018-03-01T17:27:56Z | 2018-10-23T18:51:43Z | https://github.com/thp/urlwatch/issues/211 | [] | yleyvag | 1 |
Josh-XT/AGiXT | automation | 703 | ValueError: too many values to unpack (expected 2) | ### Description
When i click "Interact", choose "Learning", choose agent, method from URL, enter the URL, push "Learn from URL", after few minutes, error appears
```
ValueError: too many values to unpack (expected 2)
Traceback:
File "/home/mihai/.local/lib/python3.10/site-packages/streamlit/runtime/scriptrunner... | closed | 2023-06-13T04:46:30Z | 2023-06-13T15:58:53Z | https://github.com/Josh-XT/AGiXT/issues/703 | [
"type | report | bug",
"needs triage"
] | mongolu | 3 |
opengeos/leafmap | plotly | 540 | 74_map_tiles_to_geotiff.ipynb |
### Environment Information
https://leafmap.org/notebooks/74_map_tiles_to_geotiff/ - opened on colab
### Description
got error by running the notebook and using OSM as basemap.
### What I Did
added a bbox on the map: [1.909, 47.9013, 1.9118, 47.9024]
changed the source basemap (to default == OSM)
... | closed | 2023-09-11T13:03:56Z | 2023-09-11T14:32:14Z | https://github.com/opengeos/leafmap/issues/540 | [
"bug"
] | sandorkonya | 3 |
pydata/xarray | numpy | 10,070 | extract_zarr_variable_encoding requires an optional argument | ### What happened?
The function `xr.backends.zarr.extract_zarr_variable_encoding` says that it's `region` argument is optional, but when it is not given, the function fails. It seems the code expects some iterable of the same length as the number of chunks.
### What did you expect to happen?
Whatever `region=None` ... | closed | 2025-02-21T23:24:17Z | 2025-02-25T17:05:34Z | https://github.com/pydata/xarray/issues/10070 | [
"bug",
"needs triage"
] | aulemahal | 2 |
gradio-app/gradio | data-science | 9,999 | Error in Browser-Console: heartbeat/nsi77w2je2 net::ERR_INCOMPLETE_CHUNKED_ENCODING 200 | ### Describe the bug
We deploy our gradio-Chatbot with AWS App Runner.
On App Runner, there is a 120s timeout:
> There is a total of 120 seconds request timeout limit on the HTTP requests. The 120 seconds include the time the application takes to read the request, including the body, and complete writing the HTTP... | open | 2024-11-19T15:22:38Z | 2025-02-28T14:09:31Z | https://github.com/gradio-app/gradio/issues/9999 | [
"bug",
"cloud"
] | machnicole | 0 |
huggingface/datasets | pandas | 7,447 | Epochs shortened after resuming mid-epoch with Iterable dataset+StatefulDataloader(persistent_workers=True) | ### Describe the bug
When `torchdata.stateful_dataloader.StatefulDataloader(persistent_workers=True)` the epochs after resuming only iterate through the examples that were left in the epoch when the training was interrupted. For example, in the script below training is interrupted on step 124 (epoch 1) when 3 batches ... | closed | 2025-03-12T21:41:05Z | 2025-03-14T17:26:59Z | https://github.com/huggingface/datasets/issues/7447 | [] | dhruvdcoder | 5 |
hyperspy/hyperspy | data-visualization | 2,489 | read spectrum | I'm trying to read in an spc spectrum but get the error below. I'm using the following versions let me know if you need more info:
mac osx 10.13.6
python 3.6.1
hyperspy==1.6.0
hyperspy-gui-ipywidgets==1.3.0
hyperspy-gui-traitsui==1.3.0
numba==0.49.0
numpy==1.18.5
Traceback (most recent call last):
File "... | closed | 2020-08-20T19:39:10Z | 2020-08-21T15:38:13Z | https://github.com/hyperspy/hyperspy/issues/2489 | [] | woodg07 | 7 |
piskvorky/gensim | machine-learning | 2,906 | Add 32/64-bit reporting to issue template | It's be useful if the issue template also requested whether the local Python is a 32-bit or 64-bit executable. Adding this line to the "Please provide the output of" code should be enough:
```python
import struct; print(8 * struct.calcsize("P"))
``` | closed | 2020-07-29T18:37:04Z | 2020-07-29T22:14:54Z | https://github.com/piskvorky/gensim/issues/2906 | [
"housekeeping"
] | gojomo | 3 |
onnx/onnx | deep-learning | 5,828 | Pytorch to ONNX export: Unexpected reduction in model size. | I am attempting to convert a PyTorch text detection model to ONNX, but I am experiencing unexpected behavior during the export process. The size of the exported ONNX model is significantly reduced from the original PyTorch model (15 MB to 7 MB), and the inferences from the ONNX model are not as accurate as the PyTorch ... | closed | 2023-12-28T20:10:35Z | 2024-01-01T17:02:10Z | https://github.com/onnx/onnx/issues/5828 | [
"question",
"topic: converters"
] | Ashish0091 | 1 |
onnx/onnx | machine-learning | 6,168 | Any operation to convert "Tile" to "Slice" | I am working on some Low-Rank Adaptation (LoRA) models, in which two set of `torch.nn.Parameters` are initialized and then multiplied into a complete weight matrix of Conv/Attention during inference.
I noticed that, the weight of original Conv is converted into `Slice` type, while the torch.nn.Parameters designed f... | closed | 2024-06-11T07:29:08Z | 2024-07-10T05:41:22Z | https://github.com/onnx/onnx/issues/6168 | [
"question"
] | zw-xxx | 2 |
ets-labs/python-dependency-injector | flask | 577 | Resource from an overridden container is still initialized | I have attempted to override the entire container for test purposes and realized that even though I have replaced all the resources with dummy ones, the original resources were still being initialized. To better visualize this, see a test case below that is currently failing on latest master:
```python
def test_ove... | open | 2022-03-31T17:34:58Z | 2022-04-06T08:07:40Z | https://github.com/ets-labs/python-dependency-injector/issues/577 | [] | kjagiello | 2 |
open-mmlab/mmdetection | pytorch | 11,429 | MM-Grounding DINO训练过程中显存增加 | 您好,我训练过程中发现MM-Grounding DINO显存在不断增加,我清楚Randomchoice resize可能是导致这个原因,但是为何batchsize=2,memory=12866,3090的24GB显存会溢出呢。我看训练过程中GPU的memory不断增加,这是什么原因? | open | 2024-01-25T12:28:54Z | 2024-06-21T03:49:16Z | https://github.com/open-mmlab/mmdetection/issues/11429 | [] | zkyseu | 8 |
holoviz/panel | jupyter | 7,727 | Tabulator: indexing exception when editing Cell on Header FILTERED table if pagination=remote | <!--
Thanks for contacting us! Please read and follow these instructions carefully, then you can delete this introductory text. Note that the issue tracker is NOT the place for usage questions and technical assistance; post those at [Discourse](https://discourse.holoviz.org) instead. Issues without the required informa... | open | 2025-02-23T15:03:57Z | 2025-03-11T14:30:34Z | https://github.com/holoviz/panel/issues/7727 | [
"component: tabulator"
] | jgriessler | 0 |
huggingface/datasets | numpy | 6,881 | AttributeError: module 'PIL.Image' has no attribute 'ExifTags' | When trying to load an image dataset in an old Python environment (with Pillow-8.4.0), an error is raised:
```Python traceback
AttributeError: module 'PIL.Image' has no attribute 'ExifTags'
```
The error traceback:
```Python traceback
~/huggingface/datasets/src/datasets/iterable_dataset.py in __iter__(self)
1... | closed | 2024-05-08T06:33:57Z | 2024-07-18T06:49:30Z | https://github.com/huggingface/datasets/issues/6881 | [
"bug"
] | albertvillanova | 3 |
explosion/spacy-course | jupyter | 125 | Wrong word segmentation in chinese course | The sentence is just splited by character.
```
# 导入spacy并创建中文nlp对象
import spacy
nlp = spacy.blank("zh")
# 处理文本
doc = nlp("我喜欢老虎和狮子。")
# 遍历打印doc中的内容
for i, token in enumerate(doc):
print(i, token.text)
# 截取Doc中"老虎"的部分
laohu = doc[2:3]
print(laohu.text)
# 截取Doc中"老虎和狮子"的部分(不包括"。")
laohu_he_sh... | open | 2022-03-07T07:40:19Z | 2022-03-07T08:15:43Z | https://github.com/explosion/spacy-course/issues/125 | [] | placebokkk | 1 |
unit8co/darts | data-science | 2,306 | Support for adding static covariates included in each row of time series | I am confused by how the incorporation of covariates is supposed to work with the TimeSeries class.
I am trying to forecast weather data and for each row in my dataset, I have several of the target variables that I am predicting (temperature, humidity, etc.) and each row also has the covariates hour of day, day of yea... | closed | 2024-04-08T19:02:38Z | 2024-04-11T06:29:01Z | https://github.com/unit8co/darts/issues/2306 | [
"question"
] | chododom | 3 |
mars-project/mars | scikit-learn | 2,632 | Implements fill methods in GroupBy | **Is your feature request related to a problem? Please describe.**
Mars now lack fill methods in GroupBy objects:
* [ ] [`GroupBy.bfill`](https://pandas.pydata.org/docs/reference/api/pandas.core.groupby.GroupBy.bfill.html#)
* [ ] [`GroupBy.ffill`](https://pandas.pydata.org/docs/reference/api/pandas.core.groupby.Gr... | closed | 2022-01-15T13:37:28Z | 2022-01-25T06:22:53Z | https://github.com/mars-project/mars/issues/2632 | [
"good first issue",
"mod: dataframe",
"pr welcome"
] | wjsi | 0 |
robotframework/robotframework | automation | 4,613 | Make Robot Framework compatible with `zipapp` | Hi,
as just shown at the open space after applying some small changes, we can have zipapps that do contain a viable robotframework installation.
There is a pull request for this feature.
https://github.com/robotframework/robotframework/pull/4612
Best regards,
Franz
| closed | 2023-01-18T16:00:02Z | 2023-05-04T20:18:31Z | https://github.com/robotframework/robotframework/issues/4613 | [
"enhancement",
"priority: high",
"beta 1",
"acknowledge",
"pr",
"effort: medium"
] | franzhaas | 3 |
moshi4/pyCirclize | data-visualization | 47 | Some modifications in my link circos | Dear Mr. Moshi4 and team,
Thank you for your help in the previous discussion.
I would like to ask about some modifications to my picture. I really apologize for the many questions at this time.
1. How to change the orientation of the label, for example, "J2" to the vertical position? because it shows overlap... | closed | 2023-12-30T08:43:53Z | 2024-05-03T02:33:49Z | https://github.com/moshi4/pyCirclize/issues/47 | [
"question"
] | Zymeth0211 | 9 |
dmlc/gluon-cv | computer-vision | 1,297 | Unable to Download faster_rcnn_fpn_syncbn_resnest269_coco model | While loading model using following code -
`net = gcv.model_zoo.get_model('faster_rcnn_fpn_syncbn_resnest269_coco', pretrained=True)`
I'm getting an error like this -
Traceback (most recent call last):
File "detect.py", line 11, in <module>
net = gcv.model_zoo.get_model('faster_rcnn_fpn_syncbn_resnest26... | closed | 2020-05-10T18:48:34Z | 2021-05-22T06:40:53Z | https://github.com/dmlc/gluon-cv/issues/1297 | [
"Stale"
] | MayurDeshmukh10 | 2 |
horovod/horovod | pytorch | 3,189 | Horovod Timeline & Scalability | **Environment:**
1. Framework: (TensorFlow, Keras)
2. Framework version: Tensorflow-gpu 2.1.0 / Keras 2.3.1
3. Horovod version: 0.21.3
4. MPI version: OpenMPI 4.1.1 / MPI API 3.1.0
5. CUDA version: 10.1
6. NCCL version: 2.5.7.1
7. Python version: 3.7
8. Spark / PySpark version:
9. Ray version:
10. OS and vers... | closed | 2021-10-01T09:55:26Z | 2022-12-02T17:10:42Z | https://github.com/horovod/horovod/issues/3189 | [
"wontfix"
] | SHEELE41 | 2 |
healthchecks/healthchecks | django | 928 | README at Docker Hub is outdated | https://hub.docker.com/r/healthchecks/healthchecks is outdated as it references sqlite rather than PostgreSQL. | closed | 2023-12-14T13:36:15Z | 2023-12-15T12:06:43Z | https://github.com/healthchecks/healthchecks/issues/928 | [] | huyz | 4 |
lexiforest/curl_cffi | web-scraping | 19 | curl_cffi.CurlError: Failed to perform, ErrCode: 92, Reason: 'HTTP/2 stream 0 was not closed cleanly: PROTOCOL_ERROR (err 1)' | Hi,
Im getting this error when I perform post requests via http2 protocal website. For the website using http1 the post requests is work fine. Is there any way to work around the issue?
curl_cffi.CurlError: Failed to perform, ErrCode: 92, Reason: 'HTTP/2 stream 0 was not closed cleanly: PROTOCOL_ERROR (err 1)'
| closed | 2023-03-06T20:15:18Z | 2023-04-12T12:59:53Z | https://github.com/lexiforest/curl_cffi/issues/19 | [] | lpk-zzz | 4 |
huggingface/pytorch-image-models | pytorch | 2,407 | [BUG] FileNotFoundError from checkpoint_saver.py. | **Describe the bug**
After creating checkpoint 0, 1, and 2, pytorch-image-models/timm/utils/checkpoint_saver.py hits a FileNotFoundError, apparently looking to move a checkpoint that doesn't exist. This stops the training.
**To Reproduce**
Steps to reproduce the behavior:
1. Using 4xL40S
2. Using variables, e.g., `ran... | closed | 2025-01-14T21:31:19Z | 2025-01-24T18:24:11Z | https://github.com/huggingface/pytorch-image-models/issues/2407 | [
"bug"
] | meg-huggingface | 7 |
labmlai/annotated_deep_learning_paper_implementations | machine-learning | 205 | Stride = 2 only for the first block of the entire ResNet | According to this row, ResNet is created only with one convolution with stride = 2:
https://github.com/labmlai/annotated_deep_learning_paper_implementations/blame/ec3c7366b7c7a763b0c06a6f703ded6bc2267638/labml_nn/resnet/__init__.py#L288
Is it ok? | open | 2023-08-16T08:49:28Z | 2023-08-16T08:49:28Z | https://github.com/labmlai/annotated_deep_learning_paper_implementations/issues/205 | [] | PavelShtykov | 0 |
microsoft/unilm | nlp | 863 | Is there a plan for pre-trained models of LayoutLMv2, LayoutLMv3 made available for commercial use? | Hi,
Thanks for sharing great performance models of LayoutLM series. The question was raised in #352 , but it has not got an answer. So may I ask if there is a plan for pre-trained models of LayoutLMv2, LayoutLMv3 to be made available for commercial use at some time in the future?

print(record.id)
```
mypy gives the following error: `Mypy: "Record" has no attribute "id" [attr-defined]`
Is there a way to set up mypy to work... | open | 2024-01-17T16:12:04Z | 2024-01-17T16:12:04Z | https://github.com/encode/databases/issues/579 | [] | conservative-dude | 0 |
alpacahq/alpaca-trade-api-python | rest-api | 171 | Update Polygon last trade and last quote to use v2 | closed | 2020-03-26T14:48:30Z | 2020-12-23T21:06:09Z | https://github.com/alpacahq/alpaca-trade-api-python/issues/171 | [] | nickjohnson22 | 3 | |
FactoryBoy/factory_boy | django | 561 | 'Options' object has no attribute 'pre_declarations' is too ambiguous | #### The problem
Typo incorrectly specifying the Model for a Factory.
#### Proposed solution
Check if any specified factories are actually Models, in which case give a more clear error message.
#### Extra notes
Thanks for the good work on this neat lib!
| closed | 2019-01-30T01:10:09Z | 2020-12-31T15:58:07Z | https://github.com/FactoryBoy/factory_boy/issues/561 | [
"BadMagic"
] | claysauruswrecks | 9 |
kennethreitz/records | sqlalchemy | 181 | Could records support asyncio? | DB connection is an IO intensive operation,could records support asyncio to connect to many db machines asynchronously? | open | 2019-05-24T09:53:25Z | 2019-05-24T09:53:25Z | https://github.com/kennethreitz/records/issues/181 | [] | leafonsword | 0 |
MilesCranmer/PySR | scikit-learn | 34 | Mutable default arguments | `pysr.pysr` has some mutable default arguments, which is a bug. | closed | 2021-03-04T14:21:13Z | 2021-03-04T20:26:44Z | https://github.com/MilesCranmer/PySR/issues/34 | [
"bug",
"implemented"
] | patrick-kidger | 2 |
deepinsight/insightface | pytorch | 2,729 | mfr test server failed | http://iccv21-mfr.com/ | open | 2025-02-21T01:41:46Z | 2025-03-06T08:13:22Z | https://github.com/deepinsight/insightface/issues/2729 | [] | yeluohuazhifou | 3 |
deepspeedai/DeepSpeed | pytorch | 6,482 | Deep Speed Optimizer index out of range during Training | Hi I am trying to fine tune my llama model using DeepSpeed, accelerate and SFTTrainer along with QLORA. I have already pretrained my LLama model.
During the pretraining, I used DeepSpeed and Peft as well with no problem.
However now I am loading my base model and the PEFT adapter and try to fine tune my model I get ... | open | 2024-09-04T08:36:11Z | 2024-10-28T09:41:09Z | https://github.com/deepspeedai/DeepSpeed/issues/6482 | [
"bug",
"training"
] | manitadayon | 1 |
Significant-Gravitas/AutoGPT | python | 9,056 | No error message when submitting an agent for review but the form isn't filled out correctly | <img src="https://uploads.linear.app/a47946b5-12cd-4b3d-8822-df04c855879f/2b8fcb30-f309-4e10-a9fb-ba1a5667f1aa/f9e8b49c-50e1-46ff-9be6-28fa9d7c2e5a?signature=eyJhbGciOiJIUzI1NiIsInR5cCI6IkpXVCJ9.eyJwYXRoIjoiL2E0Nzk0NmI1LTEyY2QtNGIzZC04ODIyLWRmMDRjODU1ODc5Zi8yYjhmY2IzMC1mMzA5LTRlMTAtYTlmYi1iYTFhNTY2N2YxYWEvZjllOGI0OWMtN... | closed | 2024-12-18T17:57:38Z | 2025-01-03T06:00:42Z | https://github.com/Significant-Gravitas/AutoGPT/issues/9056 | [] | ntindle | 0 |
yt-dlp/yt-dlp | python | 11,882 | yt-dlp downloads broken video stream from YouTube | ### DO NOT REMOVE OR SKIP THE ISSUE TEMPLATE
- [X] I understand that I will be **blocked** if I *intentionally* remove or skip any mandatory\* field
### Checklist
- [X] I'm reporting that yt-dlp is broken on a **supported** site
- [X] I've verified that I have **updated yt-dlp to nightly or master** ([update instruc... | closed | 2024-12-23T04:10:32Z | 2024-12-23T04:56:40Z | https://github.com/yt-dlp/yt-dlp/issues/11882 | [
"question"
] | TCH68k | 4 |
tortoise/tortoise-orm | asyncio | 1,425 | QuerySet .sql() function gives query with random column order | **Describe the bug**
While calling .sql function on QuerySet the columns in the query are not consistent for different Tortoise instances.
In one call we get different order and different one in another call (if call goes to different Tortoise instance).
**To Reproduce**
Run .sql() function in API call and chec... | closed | 2023-07-14T16:11:15Z | 2023-07-19T02:14:25Z | https://github.com/tortoise/tortoise-orm/issues/1425 | [] | AGOPIREDDY12 | 3 |
apify/crawlee-python | web-scraping | 707 | Add a guide for deployment to Google cloud | https://crawlee.dev/docs/deployment/gcp-cheerio | open | 2024-11-18T10:47:18Z | 2025-03-06T09:45:34Z | https://github.com/apify/crawlee-python/issues/707 | [
"documentation",
"t-tooling"
] | janbuchar | 2 |
sinaptik-ai/pandas-ai | data-visualization | 747 | Translate all docs to pt-br | ### 🚀 The feature
Translate all docs to pt-br to expand the use of PandasAI. Each doc will be a task inside this issue.
### Motivation, pitch
I'm a lusophone (Portuguese speaker) and want to facilitate pandas AI use for non-English speakers.
### Alternatives
As alternatives, there could be translations ... | closed | 2023-11-12T16:23:22Z | 2024-06-01T00:20:17Z | https://github.com/sinaptik-ai/pandas-ai/issues/747 | [] | HenriqueAJNB | 4 |
mlfoundations/open_clip | computer-vision | 510 | How do I load the pretrained weights of `google/vit-large-patch32-224-in21k` into `VisionTransformer`? | How do I load the pretrained weights of `google/vit-large-patch32-224-in21k` into `VisionTransformer`?
I want to do some research on ViT, and I need my changes to be visible in both ViT and CLIP's ViT.
Should I load the model weights using HuggingFace, and then manually update the state dict of OpenCLIP's VisionT... | closed | 2023-04-26T16:15:52Z | 2023-05-12T19:03:11Z | https://github.com/mlfoundations/open_clip/issues/510 | [] | NightMachinery | 6 |
neuml/txtai | nlp | 49 | Add zero-shot based similarity pipeline | Currently, the embeddings model is used for calculating similarity. The Labels model backed by Hugging Face's zero shot classifier has shown an impressive level of accuracy in labelling text.
Evaluate if this pipeline can be used to perform similarity comparisons. In this case, the input sections would be a list of... | closed | 2021-01-05T17:04:59Z | 2021-05-13T15:05:39Z | https://github.com/neuml/txtai/issues/49 | [] | davidmezzetti | 0 |
jmcnamara/XlsxWriter | pandas | 878 | Bug: Can't set permissions for "+"/ "-" buttons on rows with level > 0 | ### Current behavior
I am trying to add a grouping in my excel file where permissions are needed. I have marked the whole sheet as unlocked following [this stack overflow post ](https://stackoverflow.com/questions/40885097/xlsxwriter-lock-only-specific-cells). I am the trying to use `set_row` to define a level and the... | closed | 2022-06-14T06:24:59Z | 2022-06-20T23:21:09Z | https://github.com/jmcnamara/XlsxWriter/issues/878 | [
"question",
"awaiting user feedback"
] | teddy-ruby | 3 |
pyjanitor-devs/pyjanitor | pandas | 601 | [INF] Add pre-commit hooks to repository | Pre-commit hooks are a great way to push code style checks to the development machine, so that they automatically happen and thus we don't have to wait for the CI system to finish to discover that it failed only on code style.
I will add in instructions to get started with `pre-commit`, so that a bunch of checks a... | closed | 2019-10-29T16:47:04Z | 2019-10-29T23:21:42Z | https://github.com/pyjanitor-devs/pyjanitor/issues/601 | [] | ericmjl | 1 |
strawberry-graphql/strawberry | fastapi | 3,543 | Feature: Default GraphQL Enums from Python Enums. | <!--- Provide a general summary of the changes you want in the title above. -->
<!--- This template is entirely optional and can be removed, but is here to help both you and us. -->
<!--- Anything on lines wrapped in comments like these will not show up in the final text. -->
## Feature Request Type
- [ ] Cor... | closed | 2024-06-19T16:22:44Z | 2025-03-20T15:56:46Z | https://github.com/strawberry-graphql/strawberry/issues/3543 | [] | nrbnlulu | 4 |
Lightning-AI/pytorch-lightning | data-science | 20,503 | The breadcrumb navigation is wrong. | ### 📚 Documentation
<img width="795" alt="image" src="https://github.com/user-attachments/assets/de127acf-a716-48ad-af97-70c8018c9c77" />
As shown in above image.
cc @lantiga @borda | open | 2024-12-19T05:30:14Z | 2025-01-09T07:43:42Z | https://github.com/Lightning-AI/pytorch-lightning/issues/20503 | [
"bug",
"docs"
] | slgxmh | 2 |
MaartenGr/BERTopic | nlp | 2,163 | Visualization doesn't show up on Jupyter Lab | ### Have you searched existing issues? 🔎
- [X] I have searched and found no existing issues
### Desribe the bug
<img width="926" alt="Screenshot 2024-10-02 at 5 58 25 PM" src="https://github.com/user-attachments/assets/f883e254-d870-4942-838a-d62059a92033">
Hi, I'm using Jupyter Lab and am visualizing topic... | closed | 2024-10-03T01:02:06Z | 2024-10-18T21:13:08Z | https://github.com/MaartenGr/BERTopic/issues/2163 | [
"bug"
] | liuzz10 | 3 |
sqlalchemy/alembic | sqlalchemy | 1,623 | Autogenerate detects removed and added ForeignKeys, when using naming_convention | **Describe the bug**
When trying to autogenerate my second migration (just adding some fields to another table), I'm getting
```
INFO [alembic.autogenerate.compare] Detected removed foreign key (project_id)(id) on table abbreviations
INFO [alembic.autogenerate.compare] Detected added foreign key (project_id)(id) on t... | closed | 2025-03-13T12:19:15Z | 2025-03-13T15:28:26Z | https://github.com/sqlalchemy/alembic/issues/1623 | [
"postgresql",
"cant reproduce"
] | Filaton | 7 |
graphql-python/graphene-sqlalchemy | sqlalchemy | 73 | Import error after updating graphene-sqlalchemy (and graphene) to 2.0.dev | Simply importing SQLAlchemyObjectType causes a failure:
```
In [1]: from graphene_sqlalchemy import SQLAlchemyObjectType
---------------------------------------------------------------------------
NameError Traceback (most recent call last)
<ipython-input-1-a0d050cc2bfb> in <modul... | closed | 2017-08-29T19:23:02Z | 2023-02-25T06:59:07Z | https://github.com/graphql-python/graphene-sqlalchemy/issues/73 | [] | mojochao | 5 |
modelscope/modelscope | nlp | 693 | cv_HRN_head-reconstruction,我在使用社区提供的示例时候,并没有跑出社区的效果。 |
import os
import cv2
from modelscope.models.cv.face_reconstruction.utils import write_obj
from modelscope.outputs import OutputKeys
from modelscope.pipelines import pipeline
from modelscope.utils.constant import Tasks
def save_results(result, save_root):
os.makedirs(save_root, exist_ok=True)
# e... | closed | 2023-12-25T07:47:44Z | 2024-06-10T01:52:26Z | https://github.com/modelscope/modelscope/issues/693 | [
"Stale"
] | zgp123-wq | 5 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.