
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
pydata/xarray | numpy | 9,425 | idxmin / idxmax is not parallel friendly | ### Discussed in https://github.com/pydata/xarray/discussions/9421
<div type='discussions-op-text'>
<sup>Originally posted by **KBodolai** September 2, 2024</sup>
Hi there! I have a question about the chunking behaviour when using idxmin / idxmax for a chunked array.
What is the expected behaviour for the ch... | closed | 2024-09-03T15:45:23Z | 2024-12-18T16:05:49Z | https://github.com/pydata/xarray/issues/9425 | [
"topic-dask",
"topic-chunked-arrays"
] | dcherian | 2 |
huggingface/datasets | pandas | 6,622 | multi-GPU map does not work | ### Describe the bug
Here is the code for single-GPU processing: https://pastebin.com/bfmEeK2y
Here is the code for multi-GPU processing: https://pastebin.com/gQ7i5AQy
Here is the video showing that the multi-GPU mapping does not work as expected (there are so many things wrong here, it's better to watch the 3-min... | closed | 2024-01-27T20:06:08Z | 2024-02-08T11:18:21Z | https://github.com/huggingface/datasets/issues/6622 | [] | kopyl | 1 |
pennersr/django-allauth | django | 3,417 | Question about account/migrations/0005_... | Hi there,
this is my first issue here, so please close, if there is another/better place to post such a question.
I have updated a project to use django-allauth 0.55.2 this week. In my /.venv/lib/python3.11/site-packages there is no "allauth/account/migrations/0005_emailaddress_idx_upper_email.py" migration file,... | closed | 2023-09-07T04:59:53Z | 2023-09-07T11:36:14Z | https://github.com/pennersr/django-allauth/issues/3417 | [
"FIXME"
] | afuetterer | 5 |
microsoft/nni | data-science | 5,022 | restserver does not response when using frameworkcontroller | **Describe the issue**:
Hi I am running the example using frameworkcontroller, but somehow I always have timeout when making request to the restserver, it seems like it hangs up somewhere (I also tried using Postman to send request to "GET /check-status" and the restserver doesn't seem to response). The web interface ... | closed | 2022-07-26T17:23:21Z | 2022-08-12T15:12:15Z | https://github.com/microsoft/nni/issues/5022 | [
"user raised",
"support",
"Framework Support"
] | hviet2603 | 1 |
deeppavlov/DeepPavlov | tensorflow | 1,291 | AttributeError: 'NoneType' object has no attribute 'form' в kbqa_cb_rus | Запускаю модель kbqa для русского языка
```
from deeppavlov import configs, build_model
kbqa_model = build_model(configs.kbqa.kbqa_cq_rus, download=False)
ans = input()
print(kbqa_model([ans]))
```
Один вопрос (а именно "на каком месте Россия по площади территории?") из ~50 проверенных приводит к ошибке:
... | closed | 2020-08-07T04:06:34Z | 2023-07-06T12:14:15Z | https://github.com/deeppavlov/DeepPavlov/issues/1291 | [
"bug"
] | prshir | 2 |
rthalley/dnspython | asyncio | 682 | dns.ttl.MAX_TTL is wrong, discarding valid answers |
The value for dns.ttl.MAX_TTL in ttl.py is currently set to 2147483647 while in fact it should be 4294967295.
A bit further down in the code it's getting clear that it's in principle just a simple off-by-one error:
```
if total < 0 or total > MAX_TTL:
raise BadTTL("TTL should be between 0 and 2^31... | closed | 2021-09-10T20:50:44Z | 2021-09-10T22:41:32Z | https://github.com/rthalley/dnspython/issues/682 | [] | mutax | 2 |
jowilf/starlette-admin | sqlalchemy | 591 | Enhancement: Allow sorting, limiting of related fields | **Is your feature request related to a problem? Please describe.**
There is no way to custom sort and limit the display of the related fields.
**Describe the solution you'd like**
There should be a configuration option in the model to allow sorting and limiting the related fields
**Describe alternatives you've... | open | 2024-10-14T14:41:03Z | 2024-10-14T14:41:03Z | https://github.com/jowilf/starlette-admin/issues/591 | [
"enhancement"
] | essenciary | 0 |
ydataai/ydata-profiling | data-science | 1,504 | AttributeError: 'FileDataContext' object has no attribute 'create_expectation_suite' | ### Current Behaviour
AttributeError: 'FileDataContext' object has no attribute 'create_expectation_suite'
[Related to this issue](https://docs.greatexpectations.io/docs/changelog/#01549): "[MAINTENANCE] Change all instances of create_expectation_suite to add_expectation_suite in tests, docs, and source code ([#711... | closed | 2023-11-15T10:39:05Z | 2024-02-13T09:33:33Z | https://github.com/ydataai/ydata-profiling/issues/1504 | [
"maintance 🛠️"
] | hkristof03 | 0 |
deepfakes/faceswap | deep-learning | 954 | Return code 3221225620 when start training a new model | *Note: For general usage questions and help, please use either our [FaceSwap Forum](https://faceswap.dev/forum)
or [FaceSwap Discord server](https://discord.gg/FC54sYg). General usage questions are liable to be closed without
response.*
**Crash reports MUST be included when reporting bugs.**
**Describe the bug... | closed | 2019-12-13T03:16:59Z | 2020-09-27T00:07:38Z | https://github.com/deepfakes/faceswap/issues/954 | [] | lmst2 | 3 |
pytorch/vision | computer-vision | 8,538 | scipy.ndimage.find_objects GPU implementation | ### 🚀 The feature
This function a basic building block of any biomedical or even manufacturing image analysis application.
Given an image containing multiple objects, say ~1000-10,000 objects, it provides the bounding box of each object.
It gives a list of tuple of slices of coordinates of labelled objects/cel... | open | 2024-07-18T22:00:39Z | 2024-07-29T19:54:32Z | https://github.com/pytorch/vision/issues/8538 | [] | kazemSafari | 2 |
iperov/DeepFaceLab | machine-learning | 5,569 | Can 3000 Series work on 4000 Series? | Anyone who bought can anwser? | open | 2022-10-13T17:34:17Z | 2023-06-08T23:00:14Z | https://github.com/iperov/DeepFaceLab/issues/5569 | [] | MuranishiKun | 2 |
joouha/euporie | jupyter | 11 | StdinNotImplementedError: raw_input was called, but this frontend does not support input requests. | I just tried using `%debug`, however encountering the following
```python
│ │
│ /Users/yingzhu_/miniconda3/envs/python38/lib/python3.8/site-packages/IPython/core/ultratb │
│ .py:1266 in debugger ... | closed | 2021-05-15T15:35:52Z | 2022-01-08T10:34:46Z | https://github.com/joouha/euporie/issues/11 | [] | yingzhu146 | 3 |
svc-develop-team/so-vits-svc | pytorch | 118 | [Help]: 模型解析时报错:'NoneType' object has no attribute 'lower' | ### 请勾选下方的确认框。
- [X] 我已仔细阅读[README.md](https://github.com/svc-develop-team/so-vits-svc/blob/4.0/README_zh_CN.md)和[wiki中的Quick solution](https://github.com/svc-develop-team/so-vits-svc/wiki/Quick-solution)。
- [X] 我已通过各种搜索引擎排查问题,我要提出的问题并不常见。
- [X] 我未在使用由第三方用户提供的一键包/环境包。
### 系统平台版本号
Windows11 22H2
### GPU 型号
GTX 1660... | closed | 2023-04-03T12:33:00Z | 2023-04-09T14:37:56Z | https://github.com/svc-develop-team/so-vits-svc/issues/118 | [
"help wanted"
] | C-zZz-K | 5 |
robinhood/faust | asyncio | 450 | Offset not advancing (consumer and producer) in version 1.8.1 | ## Checklist
- [x] I have included information about relevant versions
- [x] I have verified that the issue persists when using the `master` branch of Faust.
## Steps to reproduce
I just run the example producer ("simple faust app" from the readme) and get the warnings below.
I created a repo to reproduce ... | closed | 2019-10-19T11:09:07Z | 2019-10-28T20:21:07Z | https://github.com/robinhood/faust/issues/450 | [] | fr-ser | 0 |
errbotio/errbot | automation | 1,257 | Errbot unable to read from XML stream | In order to let us help you better, please fill out the following fields as best you can:
### I am...
* [ ] Reporting a bug
* [ ] Suggesting a new feature
* [✓ ] Requesting help with running my bot
* [ ] Requesting help writing plugins
* [ ] Here about something else
### I am running...
* Errbot version... | closed | 2018-10-09T02:06:17Z | 2018-10-10T22:06:31Z | https://github.com/errbotio/errbot/issues/1257 | [] | thakral729 | 2 |
RobertCraigie/prisma-client-py | pydantic | 733 | RepeatedScalarContainer protobuf error when combining find_many + where-in | <!--
Thanks for helping us improve Prisma Client Python! 🙏 Please follow the sections in the template and provide as much information as possible about your problem, e.g. by enabling additional logging output.
See https://prisma-client-py.readthedocs.io/en/stable/reference/logging/ for how to enable additional log... | open | 2023-03-24T04:26:58Z | 2023-03-24T11:31:20Z | https://github.com/RobertCraigie/prisma-client-py/issues/733 | [] | anthonykrivonos | 1 |
coqui-ai/TTS | deep-learning | 2,745 | [Bug] KeyError with Tortoise and custom speaker directory | ### Describe the bug
The docs do not have proper documentation on how to run Tortoise. They immediately throw a KeyError upon attempted use.
### To Reproduce
1. Download the following file and unzip it somewhere (contains sample files):
[jfk.zip](https://github.com/coqui-ai/TTS/files/11974023/jfk.zip)
2. ... | closed | 2023-07-07T02:36:25Z | 2024-01-31T21:29:35Z | https://github.com/coqui-ai/TTS/issues/2745 | [
"bug"
] | tazz4843 | 5 |
vimalloc/flask-jwt-extended | flask | 428 | how to retrieve csrf_refresh_token using javascript | This is not really an issue, this is just something that I can't figure out.
I am using javascript `fetch()` (with `credentials: 'same-origin'` or `credentials: 'include'`) and when posting to my /login endpoint I can see `csrf_refresh_token` and `refresh_token_cookie` (httpOnly) in DevTools response cookies (I get ... | closed | 2021-05-15T17:02:19Z | 2021-05-16T01:51:07Z | https://github.com/vimalloc/flask-jwt-extended/issues/428 | [] | copocaneta | 4 |
miguelgrinberg/Flask-SocketIO | flask | 1,232 | Flask-socketIO audio streaming not emiting the signals | **Flask-socketIO with gunicorn workers**
I have created a streaming application where the MEAN stack based web-application will be sending a continuous audio stream to the API written in flask-socketIO.
if I use gunicorn for deployment with one worker (only master) it is working fine where the flask-socketIO API is... | closed | 2020-04-03T19:19:53Z | 2020-04-04T17:32:06Z | https://github.com/miguelgrinberg/Flask-SocketIO/issues/1232 | [
"question"
] | sherwin7 | 4 |
graphql-python/graphene-sqlalchemy | sqlalchemy | 182 | singledispatch is not necessary for python_version >= Python3.4 | I am using Python 3.7 and the attempt to install singledispatch is causing my build to break. I believe the way to resolve this issue is by using [conditional dependencies](https://hynek.me/articles/conditional-python-dependencies/) as outlined in [PEP 508](https://www.python.org/dev/peps/pep-0508/). I will follow up w... | closed | 2019-01-22T21:14:42Z | 2023-02-24T14:56:35Z | https://github.com/graphql-python/graphene-sqlalchemy/issues/182 | [
"bug",
":eyes: more info needed"
] | smfoote | 5 |
piskvorky/gensim | data-science | 3,114 | AttributeError: 'KeyedVectors' object has no attribute 'next_index' | #### Problem description
I try to add new vectors to a given model.
#### Steps/code/corpus to reproduce
Relevant traceback:
```
File "d:\projekte\foo\source\backend\venv\lib\site-packages\gensim\models\keyedvectors.py", line 458, in add_vector
target_index = self.next_index
AttributeError: 'KeyedVector... | closed | 2021-04-11T19:44:43Z | 2022-03-18T14:10:52Z | https://github.com/piskvorky/gensim/issues/3114 | [] | LostInDarkMath | 4 |
davidsandberg/facenet | computer-vision | 320 | Restoring session for multiple use in the same process | Hi,
I triying to load the facenet model at start, and later, after some events and preprocessing use that restored session to get the embeddings. I'm experimenting with your model, so I'll ready to create my own models and use it without problems.
self.sess = tf.Session()
# This just res... | closed | 2017-06-07T20:03:15Z | 2017-12-22T10:35:46Z | https://github.com/davidsandberg/facenet/issues/320 | [] | xolott | 3 |
modelscope/data-juicer | data-visualization | 192 | [docs] construct the "bad" data exhibition | closed | 2024-01-19T09:39:31Z | 2024-02-07T03:54:33Z | https://github.com/modelscope/data-juicer/issues/192 | [
"documentation"
] | HYLcool | 0 | |
gee-community/geemap | jupyter | 302 | Add a palette module | This palette module will provide some common palettes (e.g., ndvi, ndwi, dem) that can be used to visualize Earth Engine data. | closed | 2021-02-16T16:47:52Z | 2021-02-23T15:58:47Z | https://github.com/gee-community/geemap/issues/302 | [
"Feature Request"
] | giswqs | 1 |
comfyanonymous/ComfyUI | pytorch | 6,361 | Expected all tensors to be on the same device, but found at least two devices, cuda:0 and cpu! (when checking argument for argument weight in method wrapper_CUDA__native_layer_norm) | ### Expected Behavior
Newbie.
It used to work well. I think this is happening after updating comfyui.
I don't know where it went wrong. I want to know a solution.
### Actual Behavior
Stop on ksampler in progress.
### Steps to Reproduce
[05_face swap.json](https://github.com/user-attachments/files/18313185/05_fa... | closed | 2025-01-06T03:38:06Z | 2025-01-06T12:54:36Z | https://github.com/comfyanonymous/ComfyUI/issues/6361 | [
"duplicate",
"Potential Bug"
] | ryujongsu | 3 |
nolar/kopf | asyncio | 135 | [PR] Restrict kubernetes client library to version 9.x.x | > <a href="https://github.com/nolar"><img align="left" height="50" src="https://avatars0.githubusercontent.com/u/544296?v=4"></a> A pull request by [nolar](https://github.com/nolar) at _2019-07-04 14:09:14+00:00_
> Original URL: https://github.com/zalando-incubator/kopf/pull/135
> Merged by [nolar](https://githu... | closed | 2020-08-18T19:57:06Z | 2020-08-23T20:47:09Z | https://github.com/nolar/kopf/issues/135 | [
"bug",
"archive"
] | kopf-archiver[bot] | 0 |
jumpserver/jumpserver | django | 14,362 | [Feature] 请问产研有没有考虑集成系统监控平台(类似蓝鲸)。 | ### 产品版本
v4
### 版本类型
- [X] 社区版
- [X] 企业版
- [X] 企业试用版
### 安装方式
- [ ] 在线安装 (一键命令安装)
- [X] 离线包安装
- [ ] All-in-One
- [X] 1Panel
- [ ] Kubernetes
- [ ] 源码安装
### ⭐️ 需求描述
希望实现JumpServer既可以连接资产,又可以对纳管的资产进行系统性能监控(比如内存和磁盘资源)。这样会对用户来说更加方便,对堡垒机的粘性也加大。
### 解决方案
考虑集成开源的其他平台比如Zabbix来实现以上需求。
### 补充信息
没有 | closed | 2024-10-25T02:46:13Z | 2024-10-25T07:00:00Z | https://github.com/jumpserver/jumpserver/issues/14362 | [
"⏳ Pending feedback",
"⭐️ Feature Request"
] | jializhu | 1 |
koxudaxi/datamodel-code-generator | fastapi | 2,057 | Valid JSON Schema results in error due to `additionalProperties` set to `false` | **Describe the bug**
When running `datamodel-codegen` for any files that have `additionalProperties` set to `false`, the tool throws an exception. See the full debug output below:
```
Modified var:.. key = 'additionalProperties'
Modified var:.. model = False
13:26:28.368505 line 1792... | open | 2024-08-05T15:39:16Z | 2024-11-24T14:57:47Z | https://github.com/koxudaxi/datamodel-code-generator/issues/2057 | [
"bug"
] | will-ockmore | 0 |
mwaskom/seaborn | data-visualization | 2,764 | `kdeplot` raises `LinAlgError singular matrix` for time lag plot | Similar to #1502
I am trying to create a time-lag plot of a series of data. This plots the data series unshifted on the x axis, and the same data series shifted by one place on the y axis. Basically, I want the KDE/contour equivalent to this:
```python
series = sns.load_dataset('taxis').fare.dropna()
ax.hist2d(... | closed | 2022-03-17T19:18:44Z | 2022-03-17T23:37:07Z | https://github.com/mwaskom/seaborn/issues/2764 | [] | MarcelRobitaille | 4 |
python-security/pyt | flask | 189 | [Question] Can I install in windows? If can, how to install it? | open | 2018-11-28T01:34:06Z | 2018-12-08T14:23:12Z | https://github.com/python-security/pyt/issues/189 | [] | possleave | 1 | |
mars-project/mars | scikit-learn | 2,430 | Allow using md.loc to set values | <!--
Thank you for your contribution!
Please review https://github.com/mars-project/mars/blob/master/CONTRIBUTING.rst before opening an issue.
-->
**Is your feature request related to a problem? Please describe.**
For now, I cannot use md.loc for setting values. For example, I tried df.loc[:, 'column_name'] = ... | open | 2021-09-06T05:01:17Z | 2022-03-04T03:54:46Z | https://github.com/mars-project/mars/issues/2430 | [
"type: feature",
"mod: dataframe",
"prio: high"
] | ZYLi24 | 1 |
huggingface/transformers | tensorflow | 36,363 | 目前使用Ktransformers进行DEEPSEEK-R1满血版和4bit量化版模型进行推理,推理速度有多少tokens/s?对应的计算资源配置分别是多少? | 目前使用Ktransformers进行DEEPSEEK-R1满血版和4bit量化版模型进行推理,推理速度有多少tokens/s?对应的计算资源配置分别是多少?
目前本地部署测试能跑4bit量化版和Q2_K量化版,但推理速度只有不到0.1tokens/s,,(...o0^0o...),使用的配置如下:
GPU:tesla A10 24G X 2
CPU:Intel(R) Xeon(R) Platinum 8352V CPU @ 2.10GHz X 100(--cpu_infer 100,支持AVX-512,不支持AMX)
MemTotal:256G
磁盘:12T (15000rpm gpt-1.00 partitioned parti... | open | 2025-02-24T03:30:06Z | 2025-02-24T03:33:54Z | https://github.com/huggingface/transformers/issues/36363 | [] | William-Cai123 | 0 |
davidsandberg/facenet | tensorflow | 275 | Validate with MegaFace Challenge dataset | Hello, I have downloaded MegaFace challenge data for evaluating face recognition, both Identification and Verification problem.
I think testing result on LFW is not enough because 2 reasons:
1. LFW test only for verfication problem
2. LFW is not big dataset
MegaFace challenge provide large dataset for testing fa... | closed | 2017-05-15T08:33:01Z | 2020-06-04T07:32:24Z | https://github.com/davidsandberg/facenet/issues/275 | [] | se7oluti0n | 19 |
MaartenGr/BERTopic | nlp | 1,439 | Topic Representation using open source LLMs | Hi,
I was playing around the Topic Representation using LLMs. I do find extremely useful the usage of ChatGPT as a summarizer of documents/topics. I was wondering if one can use open source LLMs (such as the new Llama2) to basically perform the same task that chatGPT does within Bertopic. Is there any example, guidan... | closed | 2023-07-28T21:33:07Z | 2023-07-29T17:53:13Z | https://github.com/MaartenGr/BERTopic/issues/1439 | [] | MattePogra | 0 |
CorentinJ/Real-Time-Voice-Cloning | deep-learning | 750 | Is there any difference between Pytorch and tensorflow outputs? | Although my question might look idiotic, I apologize in advance to ask. But, I want to know either there is any difference in outputs generated with PyTorch and Tensorflow or not. I have tried and used Tensorflow implementation. I just want to know if there is any difference using Pytorch version in generated outputs. | closed | 2021-05-02T15:15:53Z | 2021-05-03T05:36:23Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/750 | [] | Sba-Stuff | 2 |
pyppeteer/pyppeteer | automation | 109 | question: `browser.on` | is there a way to implement in `pyppeteer` the following `puppeteer` functionality?
```node
browser.on('targetchanged', target => console.log(target.url()));
```
it's quite useful to track the URLs visited by a headless execution.
I searched among the [`browser` stuff](https://pyppeteer.github.io/pyppeteer/refer... | closed | 2020-05-14T22:27:42Z | 2020-05-14T22:33:39Z | https://github.com/pyppeteer/pyppeteer/issues/109 | [] | piramiday | 1 |
matplotlib/matplotlib | matplotlib | 29,263 | [Bug]: mypy failures in CI | ### Bug summary
Mypy has started reporting errors without any obvious changes on our side.
### Code for reproduction
Any current CI run. E.g. https://github.com/matplotlib/matplotlib/actions/runs/12233488667/job/34120690881?pr=29052
### Actual outcome
```
lib/matplotlib/pylab.py:48: error: Name "fft" ... | closed | 2024-12-09T11:30:57Z | 2024-12-10T06:45:35Z | https://github.com/matplotlib/matplotlib/issues/29263 | [] | timhoffm | 3 |
huggingface/datasets | pandas | 7,059 | None values are skipped when reading jsonl in subobjects | ### Describe the bug
I have been fighting against my machine since this morning only to find out this is some kind of a bug.
When loading a dataset composed of `metadata.jsonl`, if you have nullable values (Optional[str]), they can be ignored by the parser, shifting things around.
E.g., let's take this example
... | open | 2024-07-22T13:02:42Z | 2024-07-22T13:02:53Z | https://github.com/huggingface/datasets/issues/7059 | [] | PonteIneptique | 0 |
plotly/dash | plotly | 2,870 | whitespace on DataTable when merge_duplicate_headers= True | **Describe your context**
To reproduce run the following. Toggle `merge_duplicate_headers= True`
```
import dash
import pandas as pd
import dash_design_kit as ddk
from dash import dash_table
data = {
"indication": ["Indication 1", "Indication 2"],
"y1-450-mg-iv": [100, 200],
"y1-900-mg-iv": [1... | closed | 2024-05-29T17:05:15Z | 2024-10-17T17:55:31Z | https://github.com/plotly/dash/issues/2870 | [
"bug",
"dash-data-table",
"sev-4",
"P3"
] | e-wallace | 0 |
microsoft/unilm | nlp | 1,620 | Possible TrOCR License Conflict | I see that the TrOCR code is licensed via the [MIT](https://github.com/microsoft/unilm/blob/master/LICENSE).
However, the [paper](https://arxiv.org/pdf/2109.10282) mentions the model is trained on the [IAM handwriting Database](https://fki.tic.heia-fr.ch/databases/iam-handwriting-database) and its terms of use specifi... | open | 2024-09-05T18:00:45Z | 2024-10-30T20:04:22Z | https://github.com/microsoft/unilm/issues/1620 | [] | ezra-quemuel | 1 |
yzhao062/pyod | data-science | 490 | SOD is (possibly) delivering wrong results | The shared nearest neighbors implementation in SOD leads to questionable results, probably because of a race condition in the [parallel snn implementation](https://github.com/yzhao062/pyod/blob/c4aecd1dbd19b7386514d1af8978115a2dab695a/pyod/models/sod.py#L17). The parallel snn leads to different results compared to the ... | open | 2023-03-23T08:04:15Z | 2023-03-27T19:05:01Z | https://github.com/yzhao062/pyod/issues/490 | [] | davnn | 2 |
openapi-generators/openapi-python-client | fastapi | 924 | Won't generate client for JSON formatted API with tabs | **Describe the bug**
Running
```
openapi-python-client generate --url https://raw.githubusercontent.com/wikimedia/mediawiki-extensions-Wikibase/e45d4f725e25a95ec2b034238fd3736f19053a16/repo/rest-api/specs/openapi.json
```
gives me the error
```
Error(s) encountered while generating, client was not creat... | open | 2024-01-02T04:31:31Z | 2024-01-03T06:00:24Z | https://github.com/openapi-generators/openapi-python-client/issues/924 | [] | derenrich | 3 |
scikit-optimize/scikit-optimize | scikit-learn | 987 | TypeError: __init__() got an unexpected keyword argument 'iid' | I'm facing an issue while initiating the BayesSearchCV object,
```python
from sklearn.ensemble import RandomForestClassifier
from skopt import BayesSearchCV
from skopt.space import Real, Categorical, Integer
clf = RandomForestClassifier()
search_space = {
"bootstrap": Categorical([True]),
"max... | closed | 2021-01-21T13:39:38Z | 2021-02-06T16:28:12Z | https://github.com/scikit-optimize/scikit-optimize/issues/987 | [] | omkarudawant | 4 |
fastapi/sqlmodel | pydantic | 62 | Docs are missing info on how to enable inline errors(configure pyright) (at least in VSCode they are not automatic) | ### First Check
- [X] I added a very descriptive title to this issue.
- [X] I used the GitHub search to find a similar issue and didn't find it.
- [X] I searched the SQLModel documentation, with the integrated search.
- [X] I already searched in Google "How to X in SQLModel" and didn't find any information.
- [X] I al... | open | 2021-08-31T11:47:09Z | 2021-08-31T15:44:36Z | https://github.com/fastapi/sqlmodel/issues/62 | [
"feature"
] | toinbis | 3 |
man-group/arctic | pandas | 544 | Improve store get_info with collection data for VersionStore | We need to improve the available meta-data we keep for the data usage of a given library.
Extend capabilities of get_info with :
- collection size
- size of old versions
- size of orphaned segments
- last access time the collection was accessed
- number (maybe size) of versions accessed each day
The user may... | open | 2018-04-20T13:00:12Z | 2018-04-20T13:03:05Z | https://github.com/man-group/arctic/issues/544 | [
"enhancement",
"hackathon",
"hard",
"feature"
] | dimosped | 1 |
jupyter-incubator/sparkmagic | jupyter | 388 | Allow overrides for mutual authentication and hostname when using kerberos auth | When using Kerberos auth with a server behind a CNAME or load balancer it is necessary to set the hostname_override setting in the kerberos auth object passed to requests.
It is also nice to be able to set the mutual authentication option to OPTIONAL as this is not always supported.
Currently there is no nice w... | open | 2017-07-27T14:29:50Z | 2017-07-27T18:33:03Z | https://github.com/jupyter-incubator/sparkmagic/issues/388 | [
"help wanted"
] | jameshgibson | 1 |
inducer/pudb | pytest | 479 | Unlike vim itself, the "vim" theme doesn't work in dark terminals | closed | 2021-10-29T03:47:33Z | 2021-10-29T03:49:32Z | https://github.com/inducer/pudb/issues/479 | [] | inducer | 1 | |
gevent/gevent | asyncio | 1,937 | Why I am getting this error: gevent.exceptions.BlockingSwitchOutError: Impossible to call blocking function in the event loop callback? | * gevent version: 22.10.2
* Python version: 3.9
* Operating System: Linux x86_64 5.10.127+
### Description:
Why I'm getting this error after upgrading the Sqlachemy, Flask and Werkzeug to the latest version. This makes the APIs taking high response time and even showing 500 ISE. This is an intermittent issue bu... | open | 2023-03-10T17:31:50Z | 2023-03-10T17:31:50Z | https://github.com/gevent/gevent/issues/1937 | [] | pjain05 | 0 |
deezer/spleeter | deep-learning | 861 | Performance is low on our custom data | Hi, we are currently training Spleeter using two classes: the machine class and the noise class. For training purposes, we are providing three classes as input: the machine class, the noise class, and a mix of both classes. Each class consists of 360 voices. However, despite conducting eight experiments, we have not ob... | open | 2023-07-13T08:12:59Z | 2023-08-04T10:45:58Z | https://github.com/deezer/spleeter/issues/861 | [
"question"
] | habib1402 | 2 |
junyanz/pytorch-CycleGAN-and-pix2pix | pytorch | 1,154 | Question about using other optimizers | If I want to try out other optimizers like SGD with momentum would I just need to change line 68 & 69 in pix2pix_model.py?
Or is some of the code buildt around using Adam specifically?
` # initialize optimizers; schedulers will be automatically created by function <BaseModel.setup>`
` self.optimizer_G = torch.opti... | closed | 2020-10-02T16:37:19Z | 2020-10-07T16:12:13Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/1154 | [] | JohanRaniseth | 1 |
quantumlib/Cirq | api | 6,550 | Incorrect Numeric Expression Syntax in QASM Export | **Description of the issue**
<img width="892" alt="image" src="https://github.com/quantumlib/Cirq/assets/68288688/049befc0-bf57-464f-b4a5-2e8d010c17c0">
The `to_qasm` method exports numeric expressions in a format not fully compliant with the [OpenQASM 2.0 specification](https://arxiv.org/abs/1707.03429). Express... | closed | 2024-04-05T05:12:33Z | 2024-11-20T23:35:17Z | https://github.com/quantumlib/Cirq/issues/6550 | [
"kind/bug-report",
"triage/accepted",
"area/interop",
"area/qasm"
] | p51lee | 3 |
apify/crawlee-python | web-scraping | 816 | How to economize on RAM when starting a crawl with a large list of urls? | A very long list of starting URLs consumes a significant amount of RAM throughout the crawler's runtime. I tried converting the get_urls() function into a generator, but the crawler.run() method did not accept it. What is the recommended approach?
```python
import asyncio
from crawlee.playwright_crawler import Pla... | closed | 2024-12-15T04:27:22Z | 2025-01-15T13:26:33Z | https://github.com/apify/crawlee-python/issues/816 | [
"t-tooling"
] | matecsaj | 5 |
aiogram/aiogram | asyncio | 855 | The correct keyword argument name of setup() is “python_requires” instead of “requires_python” | I found the keyword argument **requires_python** is set in the function **setup()**. However, it will not work and will not be reflected in the METADATA. The correct keyword argument should be **python_requires**.
Way to improve:
modify **setup()** in **setup.py,**, remove **requires_python**, and add **python_requ... | closed | 2022-03-01T01:57:53Z | 2022-03-05T00:34:53Z | https://github.com/aiogram/aiogram/issues/855 | [
"docs",
"confirmed"
] | PyVCEchecker | 4 |
alteryx/featuretools | scikit-learn | 2,405 | [refactor] PerformanceWarning: DataFrame is highly fragmented during DFS | During the Deep Feature Synthesis python outputs the following warning:
> python3.9/site-packages/featuretools/computational_backends/feature_set_calculator.py:819: **PerformanceWarning:** DataFrame is highly fragmented. This is usually the result of calling `frame.insert` many times, which has poor performance. Con... | closed | 2022-12-15T09:59:44Z | 2023-01-18T16:54:09Z | https://github.com/alteryx/featuretools/issues/2405 | [
"bug"
] | mqtt-halogenki | 1 |
huggingface/transformers | tensorflow | 36,291 | Cryptic error when using AutoTokenizer with SentencePiece tokenizers without sentencepiece installed | ### System Info
- `transformers` version: 4.49.0
- Platform: Linux-5.15.167.4-microsoft-standard-WSL2-x86_64-with-glibc2.31
- Python version: 3.10.13
- Huggingface_hub version: 0.29.0
- Safetensors version: 0.4.2
- Accelerate version: not installed
- Accelerate config: not found
- DeepSpeed version: not installed
- Py... | open | 2025-02-19T23:31:53Z | 2025-03-19T14:13:08Z | https://github.com/huggingface/transformers/issues/36291 | [
"bug"
] | yifanmai | 2 |
2noise/ChatTTS | python | 268 | what is the set up/install to be used to test and install this in google colab? | what is the set up/install to be used to test and install this in google colab?
this stuff looks awesome!
carl
| closed | 2024-06-05T15:20:32Z | 2024-07-28T04:01:20Z | https://github.com/2noise/ChatTTS/issues/268 | [
"stale"
] | silvacarl2 | 3 |
dmlc/gluon-cv | computer-vision | 1,268 | scores is not optional in gluoncv.utils.viz.cv_plot_keypoints()/plot_keypoints() | Documentation https://gluon-cv.mxnet.io/api/utils.html#gluoncv.utils.viz.cv_plot_keypoints says it is optional.
It should be optional as documented.
TypeError: cv_plot_keypoints() missing 1 required positional argument: 'scores' | closed | 2020-04-24T12:31:00Z | 2021-05-30T06:59:55Z | https://github.com/dmlc/gluon-cv/issues/1268 | [
"Stale"
] | ssandler-cat | 1 |
numpy/numpy | numpy | 27,902 | BUG: `np.dot` result changes based on shape when the input contains `nan` | ### Describe the issue:
`np.dot` result changes based on shape when the inputs contains`nan`
### Reproduce the code example:
```python
import numpy as np
print(np.dot(np.array([[np.nan]]), np.array(0.)))
print(np.dot(np.array([[np.nan, np.nan]]), np.array(0.)))
```
### Error message:
```shell
[[nan]]
[[0. 0.... | open | 2024-12-04T02:56:21Z | 2024-12-06T03:41:14Z | https://github.com/numpy/numpy/issues/27902 | [
"00 - Bug"
] | AnonymousPlayer2000 | 5 |
wkentaro/labelme | computer-vision | 836 | [BUG] LabelMe crashes when clicking on rectangle, while holding shift | **Describe the bug**
Clicking on rectangle while holding shift results in crash with assertionError.
```
File "/user/folder/site-packages/labelme/shape.py", line 140, in paint
assert len(self.points) in [1, 2]
AssertionError
57292 abort labelme batch_fr_5 --nodata --labels labels.txt
```
**To Reprodu... | closed | 2021-02-10T17:04:43Z | 2023-04-05T15:01:16Z | https://github.com/wkentaro/labelme/issues/836 | [
"issue::bug",
"priority: high"
] | Armandgrd | 1 |
InstaPy/InstaPy | automation | 5,911 | TypeError: target_list() missing 1 required positional argument: 'file' | <!-- Did you know that we have a Discord channel ? Join us: https://discord.gg/FDETsht -->
<!-- Is this a Feature Request ? Please, check out our Wiki first https://github.com/timgrossmann/InstaPy/wiki -->
## Expected Behavior
adding people from your friends list
## Current Behavior
Traceback (most recent call las... | closed | 2020-11-18T09:55:17Z | 2021-01-10T14:34:30Z | https://github.com/InstaPy/InstaPy/issues/5911 | [
"wontfix"
] | SergeyHat | 2 |
PeterL1n/BackgroundMattingV2 | computer-vision | 152 | Split foreground in skin and suit | HI @PeterL1n and thank you for this amazing repo
I tried your models and results are great, so thank you so much for sharing the code! I would like to use it for a project of mine where given an image and the background I have to classify: body parts (people skin) and a specific suit designed by us.
In order t... | open | 2021-09-10T13:47:20Z | 2021-09-10T13:47:20Z | https://github.com/PeterL1n/BackgroundMattingV2/issues/152 | [] | fabiozappo | 0 |
Esri/arcgis-python-api | jupyter | 1,650 | batch_geocode drops geometries when first feature in response has none | **Describe the bug**
The `batch_geocode` function has an edge case where it will return a FeatureSet with no geometries (Shape field) for any of the input addresses. This happens when some of the addresses are empty strings, but is likely non-deterministic due to the bug being dependent on the response from the geocod... | closed | 2023-09-07T22:10:27Z | 2023-09-18T08:14:37Z | https://github.com/Esri/arcgis-python-api/issues/1650 | [
"bug"
] | cflann | 1 |
tflearn/tflearn | data-science | 267 | How to load pre-trained weights in finetuning.py | Dear all :
I have a confuse of loading pre-trained weights in finetuning.py, model.load('mypath')
What is format of 'mypath' ? I had loaded vgg16 pre-trained model in https://github.com/tflearn/models,
but appeared error in model.load('vgg16.tflearn').
The error information is long and takes some information about ... | open | 2016-08-11T01:20:08Z | 2017-11-20T20:05:45Z | https://github.com/tflearn/tflearn/issues/267 | [] | larsonwu0220 | 15 |
xonsh/xonsh | data-science | 5,489 | Colorize stderr | I've notices that in every my xonsh script I want to have accent to stderr.
It will be cool to have shell feature to show stdout and stderr using colors.
Example (the yellow line is stderr):
<img width="318" alt="image" src="https://github.com/xonsh/xonsh/assets/1708680/b55a862b-5581-4058-8e20-1ffd358c687f">
... | open | 2024-06-11T12:57:06Z | 2024-06-17T11:01:40Z | https://github.com/xonsh/xonsh/issues/5489 | [
"good first issue",
"stdout",
"priority-medium"
] | anki-code | 0 |
marimo-team/marimo | data-visualization | 3,264 | Number inputs don't correctly reset with button use | ### Describe the bug
When trying to reset mo.ui.numbers with a reset button, the value correctly resets but the number displayed in the number field remains unchanged.
### Environment
{
"marimo": "0.10.6",
"OS": "Darwin",
"OS Version": "24.1.0",
"Processor": "arm",
"Python Version": "3.10.6",
"Binaries"... | closed | 2024-12-20T22:58:49Z | 2024-12-23T17:04:19Z | https://github.com/marimo-team/marimo/issues/3264 | [
"bug"
] | tdrueter | 0 |
numba/numba | numpy | 9,043 | Feature Request: include `numba-rvsdg` as a soft dependency | The Numba team has been working on a new library called numba-rvsdg: https://github.com/numba/numba-rvsdg (please view the repository for more information). The 0.58 release is scheduled to include numba-rvsdg as a soft dependency. That is to say: it is optional and as a user I can install and elect to use the library,... | closed | 2023-06-27T11:19:11Z | 2023-08-16T09:35:52Z | https://github.com/numba/numba/issues/9043 | [
"Task",
"highpriority",
"feature_request"
] | esc | 2 |
allenai/allennlp | nlp | 5,243 | ValueError while parsing the input file for OpenIE model | I am using the Docker container for predicting the triple using the pretrained OpenIE model. While running the container I get this error
"ValueError: unable to parse C:/Users/a01thoma/Downloads/ClausIE-datasets/ClausIE-datasets/test.json as a URL or as a local path" (https://github.com/allenai/allennlp/blob/7a5106d54... | closed | 2021-06-04T04:27:46Z | 2021-06-05T07:49:59Z | https://github.com/allenai/allennlp/issues/5243 | [] | AntoThomasK03 | 3 |
automl/auto-sklearn | scikit-learn | 1,381 | Category Coalescence | Hi, does anyone know what Category Coalescence is and how to put it on a Pipeline when building the top model? | closed | 2022-01-27T22:54:58Z | 2022-02-01T14:10:45Z | https://github.com/automl/auto-sklearn/issues/1381 | [] | cristobalny | 3 |
microsoft/nni | pytorch | 4,789 | RuntimeError: Incorrect final result: the final result should be float/int, or a dict which has a key named "default" whose value is float/int. | **RuntimeError: Incorrect final result: the final result should be float/int, or a dict which has a key named "default" whose value is float/int.**:
**Environment**:Ubuntu20
- NNI version:2.7
- Training service (local|remote|pai|aml|etc):local
- Client OS:
- Server OS (for remote mode only):
- Python versio... | closed | 2022-04-21T03:54:10Z | 2022-04-21T08:21:35Z | https://github.com/microsoft/nni/issues/4789 | [] | ly0303521 | 3 |
gradio-app/gradio | data-science | 10,085 | gradio-client: websockets is out of date | ### Describe the bug
The latest websockets is 14.1. gradio-client requires <13.0 >=10.0
https://github.com/gradio-app/gradio/blob/main/client/python/requirements.txt#L6
I can work around it by creating a fork.
### Have you searched existing issues? 🔎
- [X] I have searched and found no existing issues
### ... | closed | 2024-11-30T00:10:26Z | 2024-12-02T20:02:53Z | https://github.com/gradio-app/gradio/issues/10085 | [
"bug"
] | btakita | 0 |
junyanz/pytorch-CycleGAN-and-pix2pix | computer-vision | 849 | Cycle gan is symmetry,why the performance of B to A is wrose than A to B? | Cycle gan is symmetry,why the performance of B to A is wrose than A to B? | closed | 2019-11-19T08:31:44Z | 2019-11-30T20:25:22Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/849 | [] | zjuxiaobaiq | 5 |
serengil/deepface | deep-learning | 1,133 | API Endpoint /represent fails with 400 for array of img URLs | ### Description
Using an array of `img` items via the API endpoint `represent` responds with the following error
```
{
"error": "Exception while representing: img must be numpy array or str but it is <class 'list'>"
}
```
#### Steps to Reproduce
1. Pull repo
2. Build the image
`docker build -t de... | closed | 2024-03-22T09:43:58Z | 2024-03-22T22:31:40Z | https://github.com/serengil/deepface/issues/1133 | [
"invalid"
] | lounging-lizard | 2 |
littlecodersh/ItChat | api | 882 | 登录不上啊 | 登录不上了,提示不符合 | closed | 2019-12-09T08:43:37Z | 2023-11-16T12:48:07Z | https://github.com/littlecodersh/ItChat/issues/882 | [] | 2048537793 | 0 |
unit8co/darts | data-science | 2,390 | [BUG] TorchMetrics loop implementation isn't compatible with stateful metrics | **Describe the bug**
Current metrics loop isn't valid for stateful metrics.
Current metrics calculation boils down to:
1. Do metrics's forward on the batch 2. Mean the batch results at the end of epoch/evaluation.
This breaks the logic of the metrics' that shouldn't be computed per batch. E.g. My custom metric... | closed | 2024-05-20T18:32:45Z | 2024-05-27T21:30:12Z | https://github.com/unit8co/darts/issues/2390 | [
"improvement"
] | tRosenflanz | 1 |
CorentinJ/Real-Time-Voice-Cloning | pytorch | 738 | cuda out of memory | 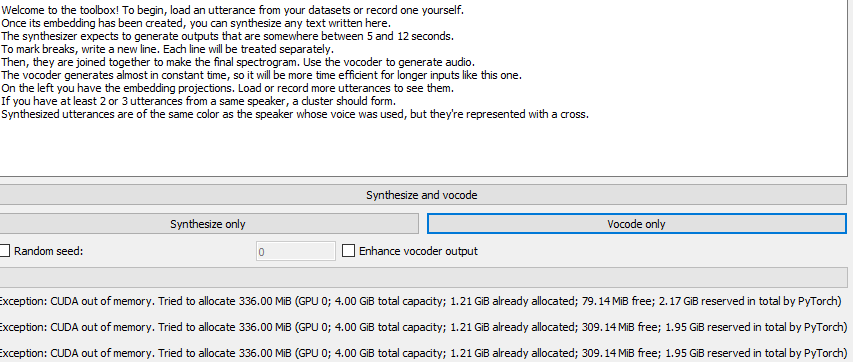
i did some research but still couldn't get how to deal with this error into my head? any idea what i need to avoid? | closed | 2021-04-16T21:36:44Z | 2021-04-20T02:57:18Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/738 | [] | jackthenewbie | 3 |
gunthercox/ChatterBot | machine-learning | 1,541 | Possible to apply multilingual within a bot? | Hello! Thanks for making chatterbot that helps my project a lot.
I am writing a bot that will link to various IM platforms. I want to let the users choose and set either English or Chinese in the future. I would like to know if it’s possible to apply 2 languages within a bot?
This is my very first project and my prog... | closed | 2018-12-29T08:00:31Z | 2019-11-11T11:23:07Z | https://github.com/gunthercox/ChatterBot/issues/1541 | [] | herboratory | 4 |
vitalik/django-ninja | rest-api | 1,105 | Documentation - link the schema article to the error article | At first, thanks for your product! I really like its vibe)
**Is your feature request related to a problem? Please describe.**
Several times I was faced with problem of finding necessary data in documentation.
It's hard to find the article about error handling and specifiyng it in response schema.
This article -... | closed | 2024-03-11T06:24:45Z | 2024-04-24T11:33:01Z | https://github.com/vitalik/django-ninja/issues/1105 | [] | rappongy | 0 |
huggingface/datasets | numpy | 7,022 | There is dead code after we require pyarrow >= 15.0.0 | There are code lines specific for pyarrow versions < 15.0.0.
However, we require pyarrow >= 15.0.0 since the merge of PR:
- #6892
Those code lines are now dead code and should be removed. | closed | 2024-07-03T08:52:57Z | 2024-07-03T09:17:36Z | https://github.com/huggingface/datasets/issues/7022 | [
"maintenance"
] | albertvillanova | 0 |
keras-team/keras | python | 20,455 | Inconsistent warning using MultiHeadAttention with Masking | Hello, when I try to use `MultiHeadAttention` (which supports masking), I get the following warning:
```
/opt/conda/envs/trdm/lib/python3.11/site-packages/keras/src/layers/layer.py:915: UserWarning: Layer 'query' (of type EinsumDense) was passed an input with a mask attached to it. However, this layer does not suppor... | closed | 2024-11-06T13:39:06Z | 2024-11-06T22:00:14Z | https://github.com/keras-team/keras/issues/20455 | [] | fdtomasi | 2 |
huggingface/datasets | machine-learning | 6,884 | CI is broken after jax-0.4.27 release: AttributeError: 'jaxlib.xla_extension.DeviceList' object has no attribute 'device' | After jax-0.4.27 release (https://github.com/google/jax/releases/tag/jax-v0.4.27), our CI is broken with the error:
```Python traceback
AttributeError: 'jaxlib.xla_extension.DeviceList' object has no attribute 'device'. Did you mean: 'devices'?
```
See: https://github.com/huggingface/datasets/actions/runs/8997488... | closed | 2024-05-08T07:01:47Z | 2024-05-08T09:35:17Z | https://github.com/huggingface/datasets/issues/6884 | [
"bug"
] | albertvillanova | 0 |
nvbn/thefuck | python | 1,035 | Windows cmd support | Is anyone working on support for windows cmd? If not, I'd like to try and start working on it. Similar to #626.
| open | 2020-01-17T04:04:55Z | 2022-09-07T04:56:39Z | https://github.com/nvbn/thefuck/issues/1035 | [] | Svaught598 | 3 |
marshmallow-code/apispec | rest-api | 632 | How to document schema fields? | Hope this is not a too stupid question but I'm struggling to get this to work.
How would I document individual fields of a marshmallow schema? Class attributes do not have docstrings directly attached to it.
| closed | 2021-01-26T15:42:58Z | 2021-06-04T20:51:27Z | https://github.com/marshmallow-code/apispec/issues/632 | [
"question"
] | bkircher | 2 |
aws/aws-sdk-pandas | pandas | 2,686 | Iceberg partitioning based on transformed DataFrame columns not supported? | ### Describe the bug
I was hoping that something like `partition_cols=["user_id", "month(ts)"]` would work nicely in `athena.to_iceberg`, but I end up with a `KeyError` noting that `"month(ts)"` doesn't exist in the DataFrame. However, the table is created properly based on the output of `athena.show_create_table`.
#... | closed | 2024-02-22T21:02:34Z | 2024-03-01T17:03:33Z | https://github.com/aws/aws-sdk-pandas/issues/2686 | [
"bug"
] | petebachant | 5 |
explosion/spaCy | machine-learning | 13,707 | numpy requirements/compatibility | I noticed that conda-forge is struggling with some of the current numpy specifications to the point that they're having to patch the requirements (https://github.com/conda-forge/thinc-feedstock/pull/123).
To improve this and restore numpy v1 compatibility, could you consider using numpy's suggested build+install req... | open | 2024-12-05T09:13:23Z | 2024-12-16T06:31:18Z | https://github.com/explosion/spaCy/issues/13707 | [] | adrianeboyd | 2 |
neuml/txtai | nlp | 68 | Add translation pipeline | Add pipeline that can translate text | closed | 2021-03-17T18:53:41Z | 2021-05-13T15:07:26Z | https://github.com/neuml/txtai/issues/68 | [] | davidmezzetti | 0 |
pydantic/pydantic | pydantic | 11,577 | `alias_generator` no longer affects examples | ### Initial Checks
- [x] I confirm that I'm using Pydantic V2
### Description
This sample code works with `pydantic-core` version `2.29.0`, but not `2.31.1` or any of the later versions. The `alias_generator` appears to be ignored for the examples, and an example is generated with `str_field` instead of `strField`.
... | closed | 2025-03-18T16:53:40Z | 2025-03-20T13:36:05Z | https://github.com/pydantic/pydantic/issues/11577 | [
"bug V2"
] | oscar-broman | 1 |
flasgger/flasgger | flask | 371 | execute does not show responses | When I run the execute in the Swagger UI generated by flasgger, the server does run the route and returns JSON, but flassger UI doesn't show the response.
What do I need to do to get the UI to show the response | closed | 2020-03-12T14:28:20Z | 2020-04-15T11:50:57Z | https://github.com/flasgger/flasgger/issues/371 | [] | shapiro2 | 2 |
vitalik/django-ninja | rest-api | 790 | Externalize the FilterSchemas on OpenAPI documentation | Hello @vitalik! Thanks for this great project!
We are using Django Ninja to develop our retail application.
We are using the Python FilterSchema class, as described in the documentation section below:
https://django-ninja.rest-framework.com/guides/input/filtering/
On the frontend, we are using the "openapi-... | closed | 2023-07-12T13:02:53Z | 2023-07-14T12:45:38Z | https://github.com/vitalik/django-ninja/issues/790 | [] | joaoflaviosantos | 5 |
python-restx/flask-restx | flask | 416 | Can't specified api doc body for a different input | ### ***** **BEFORE LOGGING AN ISSUE** *****
- Is this something you can **debug and fix**? Send a pull request! Bug fixes and documentation fixes are welcome.
- Please check if a similar issue already exists or has been closed before. Seriously, nobody here is getting paid. Help us out and take five minutes to make... | open | 2022-02-25T14:06:22Z | 2022-02-25T14:06:22Z | https://github.com/python-restx/flask-restx/issues/416 | [
"bug"
] | plenzjr | 0 |
FactoryBoy/factory_boy | sqlalchemy | 329 | A simple MyFactory.create() actually not saving in DB? (Django) | Hello,
I just gave a try to factory_boy, and it fails to actually save my model in DB.
Here's my model:
```
# myapp.models.py
from custom_user.models import AbstractEmailUser
class User(AbstractEmailUser):
class Meta:
verbose_name = _(u'Utilisateur')
```
Here's my factory:
```
# myapp.... | closed | 2016-11-25T21:57:48Z | 2019-07-09T09:47:01Z | https://github.com/FactoryBoy/factory_boy/issues/329 | [
"Q&A",
"Django"
] | ppython | 5 |
flairNLP/flair | nlp | 3,559 | [Feature]: Pin torch>=2.x to use torch.compile | ### Problem statement
Get benefits from features of torch>=2.x
### Solution
Pin torch version to >=2.x to use torch.compile on models
### Additional Context
_No response_ | open | 2024-10-25T09:18:31Z | 2025-02-15T17:30:02Z | https://github.com/flairNLP/flair/issues/3559 | [
"feature"
] | mauryaland | 1 |
chatopera/Synonyms | nlp | 68 | ImportError when there's "utils" model | # description
This has been resolved in pull#34 https://github.com/huyingxi/Synonyms/pull/34.
But in the most recent commits, this change is reverted and import will not work when there is utils package.
## current
## expected
# solution
# environment
* version:
The commit hash (`git rev-parse HEAD... | closed | 2018-09-07T02:46:21Z | 2020-10-01T11:39:56Z | https://github.com/chatopera/Synonyms/issues/68 | [] | tcqiuyu | 1 |
iperov/DeepFaceLab | deep-learning | 5,657 | 这个怎么用?我是初学者 | open | 2023-04-09T23:48:23Z | 2023-06-18T03:40:33Z | https://github.com/iperov/DeepFaceLab/issues/5657 | [] | pxl750217 | 5 | |
pytest-dev/pytest-html | pytest | 428 | Investigate if we need to add a linter for Read the Docs | ~Read the docs may or may not perform sufficient linting for us. The purpose of this card is to investigate our linting options and add a linter if needed~
I did some research and found that we can still use `rst-lint`, but we need to allow the following two directives:
- `automodule`
- `toctree`
The above can ... | open | 2020-12-17T04:06:13Z | 2020-12-21T05:21:47Z | https://github.com/pytest-dev/pytest-html/issues/428 | [
"Infrastructure",
"code quality"
] | gnikonorov | 0 |
A3M4/YouTube-Report | seaborn | 25 | A tiny issue in code | code in report.py
```python
Wed = html.dataframe_heatmap('Wed')
Thu = html.dataframe_heatmap('Wed')
Fri = html.dataframe_heatmap('Fri')
Sat = html.dataframe_heatmap('Fri')
```
may be
```python
Wed = html.dataframe_heatmap('Wed')
Thu = html.dataframe_heatmap('Thu')
Fri = html.dataframe_heatmap('Fri')
Sat = h... | closed | 2019-12-23T03:42:39Z | 2019-12-24T09:41:02Z | https://github.com/A3M4/YouTube-Report/issues/25 | [] | ESWZY | 1 |
jofpin/trape | flask | 119 | Looking for the session | Hi guys, good work both jofpin & DJCHICKEN4.
I want to say that now after updating to the last version and session recognition works.
When I try to capture the credentials of a target sessions, it makes a phishing page but the connection is lost at that point, this is the log from the ssh
[*] A user has been con... | open | 2018-12-07T11:27:12Z | 2018-12-07T21:51:37Z | https://github.com/jofpin/trape/issues/119 | [] | Sara123984 | 6 |
litestar-org/litestar | pydantic | 3,840 | Bug: WebSocket connection fails due to 'GET' method being sent instead of None (Litestar expects None) | ### Description
When using Litestar with Socketify as the ASGI server for handling WebSocket connections, I encountered a MethodNotAllowedException with the following traceback. The error seems to stem from the fact that Socketify is sending a 'GET' method in the ASGI scope, whereas Litestar expects the method to be N... | closed | 2024-10-25T08:24:42Z | 2025-03-20T15:55:01Z | https://github.com/litestar-org/litestar/issues/3840 | [
"Bug :bug:"
] | gangstand | 3 |
okken/pytest-check | pytest | 173 | Version 2.2.3 broke interaction with pytest-reportlog (INTERNALERROR) | Pytest-check 2.2.3 seems to have introduced a change that causes an internal error when combined with pytest-reportlog. This seems like it might be related to #155.
Steps to reproduce:
- `pip install pytest==8.3.4 pytest-check==2.4.1 pytest-reportlog==0.4.0` (these are latest at time of writing)
- Create a file `testi... | closed | 2025-01-28T08:21:55Z | 2025-02-09T18:22:55Z | https://github.com/okken/pytest-check/issues/173 | [
"enhancement"
] | bmerry | 2 |
joeyespo/grip | flask | 276 | #grip-class anchor is undefined in the README | Many places in the `README.md` link to https://github.com/joeyespo/grip#grip-class, but the `#grip-class` anchor doesn't seem to exist. | closed | 2018-07-06T22:05:26Z | 2018-07-08T20:02:34Z | https://github.com/joeyespo/grip/issues/276 | [
"bug",
"docs",
"readme"
] | jacebrowning | 1 |
jina-ai/serve | machine-learning | 5,454 | create FastAPIBaseGateway | Create a FastAPIBaseGateway where the user just needs to implement a fast API app.
All the rest (setting up, running and shutting down the server) is automatically handled
Also make sure the HTTPGateway inherits from it instead of the BaseGateway | closed | 2022-11-25T13:15:07Z | 2022-11-28T16:34:46Z | https://github.com/jina-ai/serve/issues/5454 | [] | JoanFM | 0 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.