
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
ultralytics/yolov5 | pytorch | 12,560 | How to convert from json format with Polygon labels to YOLOv7 instance segmentation Without Roboflow? | ### Search before asking
- [X] I have searched the YOLOv5 [issues](https://github.com/ultralytics/yolov5/issues) and [discussions](https://github.com/ultralytics/yolov5/discussions) and found no similar questions.
### Question
Epoch GPU_mem box_loss seg_loss obj_loss cls_loss Instances S... | closed | 2023-12-31T02:01:30Z | 2024-10-20T19:35:41Z | https://github.com/ultralytics/yolov5/issues/12560 | [
"question",
"Stale"
] | Yuanchihwei | 7 |
aidlearning/AidLearning-FrameWork | jupyter | 81 | 模拟的鼠标 | 移动端有一个模拟的鼠标是不是方便一些啊 | closed | 2020-02-23T09:21:25Z | 2020-02-24T06:10:40Z | https://github.com/aidlearning/AidLearning-FrameWork/issues/81 | [] | swithun-liu | 1 |
mitmproxy/pdoc | api | 185 | pydoc expands os.environ dictionary -> security issue | We had a function that pydoc documented:
def cfg_get_env(env=os.environ):
Except 'pydoc' did not document 'env=os.environ' but expanded the content of 'os.environ' which is a security issue. | closed | 2019-03-27T20:11:19Z | 2021-01-19T14:47:11Z | https://github.com/mitmproxy/pdoc/issues/185 | [] | osynge | 1 |
keras-team/keras | data-science | 20,134 | datas_adapters:is_tf_dataset should also support DistributedDatasetsFromFunction | Please update to support `ds = strategy.distribute_datasets_from_function(fn, options=input_options)`:
```
def is_tf_dataset(x):
if hasattr(x, "__class__"):
for parent in x.__class__.__mro__:
if parent.__name__ in (
"DatasetV2",
"DistributedDataset",
... | closed | 2024-08-19T13:12:57Z | 2025-01-31T23:23:30Z | https://github.com/keras-team/keras/issues/20134 | [
"type:support"
] | rivershah | 3 |
roboflow/supervision | deep-learning | 1,301 | overlay_image() function | ### Search before asking
- [X] I have searched the Supervision [issues](https://github.com/roboflow/supervision/issues) and found no similar bug report.
### Bug
The `overlay_image` function used in the `CropAnnotator` class [here](https://github.com/roboflow/supervision/blob/f00dcede1a2e0e3bca0f403ed4a0d23e16cde937... | closed | 2024-06-21T17:32:20Z | 2024-07-01T11:32:32Z | https://github.com/roboflow/supervision/issues/1301 | [
"bug"
] | Bhavay-2001 | 1 |
davidsandberg/facenet | tensorflow | 990 | I followed Validate on LFW but can't align images | ```
Total number of images: 13233
Number of successfully aligned images: 0
```
I found this error after below command. I followed to set the datasets and routes.
```
for N in {1..4}; do \
python src/align/align_dataset_mtcnn.py \
~/datasets/lfw/raw \
~/datasets/lfw/lfw_mtcnnpy_160 \
--image_size 160 \
--ma... | open | 2019-03-13T07:04:48Z | 2019-03-13T07:06:23Z | https://github.com/davidsandberg/facenet/issues/990 | [] | bicsu | 0 |
waditu/tushare | pandas | 1,662 | 财务数据重复 | 财务数据类中,财报数据会重复输出两行
如:
pro.fina_indicator(ts_code=‘600519.SH’, start_date=‘20200101’, end_date=‘20220601’)
pro.income(ts_code=‘600519.SH’, start_date=‘20200101’, end_date=‘20220601’)
ID:518101 | open | 2022-06-30T19:01:01Z | 2022-08-09T14:11:26Z | https://github.com/waditu/tushare/issues/1662 | [] | haonan18 | 1 |
ivy-llc/ivy | numpy | 28,461 | Fix Ivy Failing Test: paddle - creation.arange | To-Do List: https://github.com/unifyai/ivy/issues/27501 | open | 2024-03-01T10:51:53Z | 2024-03-01T10:51:53Z | https://github.com/ivy-llc/ivy/issues/28461 | [
"Sub Task"
] | marvlyngkhoi | 0 |
jwkvam/bowtie | plotly | 247 | move example code towards convention of global app | For dynamic layouts, the app will need to be global or at least the views will be. I would rather not confuse the matter and encourage the app to be global. As a side benefit, users can then use the `listen` decorator instead of the `subscribe` function which should be more readable. This may also allow us to be more c... | closed | 2018-10-03T15:34:11Z | 2018-10-13T05:43:18Z | https://github.com/jwkvam/bowtie/issues/247 | [
"enhancement",
"user experience"
] | jwkvam | 1 |
marshmallow-code/marshmallow-sqlalchemy | sqlalchemy | 205 | Typo in "Basic Schema 2" recipe? | ```
class BaseOpts(ModelSchemaOpts):
def __init__(self, meta):
if not hasattr(meta, "sql_session"):
meta.sqla_session = Session
super(BaseOpts, self).__init__(meta)
```
Should the 3rd line be `if not hasattr(meta, "sqla_session"):`? | closed | 2019-04-29T21:16:07Z | 2019-04-30T02:13:33Z | https://github.com/marshmallow-code/marshmallow-sqlalchemy/issues/205 | [] | MattF-NSIDC | 1 |
jpadilla/django-rest-framework-jwt | django | 145 | Custom Payload Fields | It'd be nice to have a setting to set which fields are returned in the token. For instance, I like to use non-sequential user_ids.
| open | 2015-08-13T20:31:31Z | 2019-03-06T14:06:49Z | https://github.com/jpadilla/django-rest-framework-jwt/issues/145 | [] | Miserlou | 16 |
keras-team/keras | tensorflow | 20,700 | ValueError: creating distributed tf.Variable with aggregation=MEAN and a non-floating dtype is not supported, please use a different aggregation or dtype | It happens while using [keras-models](https://keras.io/api/applications/) in kaggle tpu. | closed | 2024-12-28T18:31:33Z | 2024-12-31T04:22:19Z | https://github.com/keras-team/keras/issues/20700 | [] | innat | 2 |
jupyter/nbviewer | jupyter | 789 | Edge Detection tutorial with non-square images (R) | It would be really nice to have the tutorial for image that are not square, i.e., of size n x m pixels instead of n x n. | closed | 2018-08-13T12:48:27Z | 2019-11-21T22:28:11Z | https://github.com/jupyter/nbviewer/issues/789 | [
"type:Question",
"tag:Upstream"
] | emma-cwi | 1 |
influxdata/influxdb-client-python | jupyter | 387 | query data with specified precision | 1. write data to the database with nanosecond precision (OK)
2. query data with default nanosecond precision (OK)
3. try to add parameter epoch set to `s` to get data with `unix_s` precision based on [docs](https://docs.influxdata.com/influxdb/v1.3/guides/querying_data/#timestamp-format)
so my code:
```
...
... | closed | 2021-12-28T11:05:50Z | 2022-01-03T08:19:38Z | https://github.com/influxdata/influxdb-client-python/issues/387 | [
"question",
"wontfix"
] | ebrahimkarimi | 1 |
FactoryBoy/factory_boy | sqlalchemy | 770 | Installation fails depending on locale | A CI system just failed when installing factory_boy while I could install it locally. Turns out the locale makes a difference:
```
(venv) ➜ /tmp LC_ALL=C pip install --force factory_boy
Collecting factory_boy
Using cached https://files.pythonhosted.org/packages/e4/ca/ad899f91979352aa06b9a35b5ca436adfa978292483... | closed | 2020-08-13T07:30:43Z | 2020-08-21T07:49:18Z | https://github.com/FactoryBoy/factory_boy/issues/770 | [
"Bug",
"NeedInfo",
"Packaging"
] | choeger | 7 |
brightmart/text_classification | nlp | 73 | a01_FastText | Hi,
In data_util_zhihu.py:
def create_voabulary(simple=None,word2vec_model_path='zhihu-word2vec-title-desc.bin-100',name_scope='')
but your data is zhihu-word2vec-title-desc.bin-100.txt, should I add the .txt to the path, but if I do this, it will have other errors | closed | 2018-07-23T09:54:54Z | 2018-11-20T19:35:14Z | https://github.com/brightmart/text_classification/issues/73 | [] | chenting0324 | 1 |
horovod/horovod | tensorflow | 3,687 | Support custom data loaders in TorchEstimator | Follow-up to #3602, to add support for customizable data modules/loaders in the TorchEstimator. | closed | 2022-09-08T15:28:18Z | 2023-02-01T06:17:20Z | https://github.com/horovod/horovod/issues/3687 | [
"enhancement"
] | leewyang | 0 |
albumentations-team/albumentations | machine-learning | 1,805 | [Benchmark] Add Augmentor to bechmark | closed | 2024-06-19T23:22:19Z | 2024-10-27T21:44:17Z | https://github.com/albumentations-team/albumentations/issues/1805 | [
"benchmark"
] | ternaus | 1 | |
Avaiga/taipy | data-visualization | 2,473 | Create notification groups | ### Description
If a Taipy GUI application creates several notifications with the same identifier, only the first one shows up. That's the way it is implemented in the component that is used. That may be a problem.
Solving this problem may let us provide a new feature: notification groups.
The idea would be that a us... | closed | 2025-03-03T10:13:31Z | 2025-03-05T12:03:54Z | https://github.com/Avaiga/taipy/issues/2473 | [
"📈 Improvement",
"🖰 GUI",
"🟨 Priority: Medium"
] | FabienLelaquais | 0 |
pytorch/vision | machine-learning | 8,238 | pytest 8 has issues with `pytest.warns` | Some of our tests that use `pytest.warns` started failing with `pytest 8` which was released a few days ago.
I'm just opening this issue for reference and to add as a TODO.
https://github.com/pytorch/vision/actions/runs/7694476421/job/20965356912?pr=7990
```
2024-01-29T10:34:47.7500403Z FAILED test/test_extende... | open | 2024-01-29T10:49:53Z | 2024-01-29T10:52:21Z | https://github.com/pytorch/vision/issues/8238 | [] | NicolasHug | 0 |
qubvel-org/segmentation_models.pytorch | computer-vision | 259 | How to use fwiou metrics? | Thanks @qubvel . I learned a lot from this project. But I am not understand how to calculcate the fwiou based on iou in this work(confusion_matrix is not used) | closed | 2020-09-20T16:38:41Z | 2022-02-21T01:50:49Z | https://github.com/qubvel-org/segmentation_models.pytorch/issues/259 | [
"Stale"
] | skyqwe123 | 4 |
huggingface/transformers | pytorch | 36,020 | [generate] handle attention mask (encoder + cross attention) for encoder decoder models | ### Feature request
For encoder-decoder autoregressive models attention masks, we follow the convention (cf [here](https://github.com/huggingface/transformers/blob/9d2056f12b66e64978f78a2dcb023f65b2be2108/src/transformers/generation/utils.py#L1958C67-L1959C119)):
`attention_mask` → applies to the encoder
`decoder_att... | closed | 2025-02-03T15:03:30Z | 2025-02-03T16:56:03Z | https://github.com/huggingface/transformers/issues/36020 | [
"Feature request"
] | eustlb | 4 |
PaddlePaddle/models | nlp | 5,240 | tracking 评估报错 | 地址:https://github.com/PaddlePaddle/models/tree/develop/PaddleCV/tracking#%E5%BC%80%E5%A7%8B%E6%B5%8B%E8%AF%95
执行代码:
`!python eval_benchmark.py -d VOT2018 -tr ATOMnet_ep0040_models -te atom.default_vot -e 40`
后报错:
```
=> Evaluating: ATOMnet_ep0040_models.epoch40
loading VOT2018: 100%|██████████████████████████... | open | 2021-01-28T01:25:35Z | 2021-11-05T03:54:56Z | https://github.com/PaddlePaddle/models/issues/5240 | [
"bug"
] | iceriver97 | 2 |
dmlc/gluon-cv | computer-vision | 1,163 | Yolo3 train: weighted specific class targeted | Hi,
I have train **Yolo3** with custom dataset and custom classes (only **5 classes**). It works fine but now I would like to train my model adding a weight (in loss function by example), but only for one class.
I have seen that we can add a scalar global weight to the loss function but it is not what I am looking fo... | closed | 2020-01-28T08:32:18Z | 2021-06-07T07:04:42Z | https://github.com/dmlc/gluon-cv/issues/1163 | [
"Stale"
] | MBocchi | 4 |
man-group/arctic | pandas | 96 | Does arctic support query? I want to fetch data of some stock between a start time and a end time. | New to arctic.
I want to do some backtests in a specific time range. So I have to fetch data between a start time and a end time.
Many thanks.
| closed | 2016-01-28T07:11:44Z | 2016-02-01T07:02:39Z | https://github.com/man-group/arctic/issues/96 | [] | huaiweicheng | 6 |
scrapy/scrapy | python | 6,106 | Remove deprecated code moved to itemloaders | Deprecated in 2.3.0.
* scrapy.utils.misc.extract_regex()
* scrapy.loader.common
* scrapy.loader.processors | closed | 2023-10-17T19:12:02Z | 2023-10-18T10:52:31Z | https://github.com/scrapy/scrapy/issues/6106 | [
"good first issue",
"cleanup"
] | wRAR | 0 |
ultralytics/ultralytics | computer-vision | 19,680 | how can I run model.val() AND get the individual predictions in the results? | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
I'm posting this mostly to get the AI generated response.
This can be nicel... | closed | 2025-03-13T15:10:35Z | 2025-03-13T18:16:49Z | https://github.com/ultralytics/ultralytics/issues/19680 | [
"question"
] | luizwritescode | 2 |
hankcs/HanLP | nlp | 1,152 | HanLP.parseDependency 1024问题 | 您好,sentence = HanLP.parseDependency(doc)会报如下错误:
jpype._jexception.ArrayIndexOutOfBoundsExceptionPyRaisable: java.lang.ArrayIndexOutOfBoundsException: Index 1032 out of bounds for length 1024
请问能有办法扩展长度么? | closed | 2019-04-16T10:11:46Z | 2020-01-01T10:50:07Z | https://github.com/hankcs/HanLP/issues/1152 | [
"ignored"
] | cwj | 1 |
coqui-ai/TTS | pytorch | 4,140 | Batch processing for inference | For now I can only use xtts_v2 with batch_size=1, which in serving mode is quite slow. Can you support batch processing for inference?
| closed | 2025-01-27T05:56:46Z | 2025-03-08T05:47:01Z | https://github.com/coqui-ai/TTS/issues/4140 | [
"wontfix",
"feature request"
] | lhr-30 | 1 |
unionai-oss/pandera | pandas | 1,853 | Add "example" capability to pyspark based data schemas | **Is your feature request related to a problem? Please describe.**
- We use spark for all our heavy data wrangling
- we want to use pandera to generate test / fake data
**Describe the solution you'd like**
an ability to use `.example(size=20)` also with pyspark based schemas
**Describe alternatives you've cons... | open | 2024-11-13T10:18:44Z | 2024-11-13T10:18:44Z | https://github.com/unionai-oss/pandera/issues/1853 | [
"enhancement"
] | pascalwhoop | 0 |
junyanz/pytorch-CycleGAN-and-pix2pix | deep-learning | 1,270 | --n_epochs and --n_epochs_decay if --lr_policy != linear | Hi,
I have tried to understand the relationship between --n_epochs, --n_epochs_decay and --lr_policy.
As I understand it, in default, the lr is not changed for--n_epochs and then linearly decreased to zero by --n_epochs_decay. Does that mean the lr is zero after the last epoch (which would make continuing trainin... | open | 2021-04-08T17:59:16Z | 2021-04-08T17:59:16Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/1270 | [] | lizard24 | 0 |
rthalley/dnspython | asyncio | 154 | Problems when -OO optimisation used | in version 1.13 the following two lines are causing problems when optimization is used as docstrings are stripped.
"/usr/lib/python2.7/site-packages/dns/exception.py", line 124,
"/usr/lib/python2.7/site-packages/dns/resolver.py", line 83,
TypeError: 'NoneType' object has no attribute '**getitem**'
| closed | 2016-05-12T09:40:00Z | 2016-05-12T16:47:32Z | https://github.com/rthalley/dnspython/issues/154 | [
"Bug"
] | IstvanZakar | 1 |
deepfakes/faceswap | machine-learning | 1,400 | error when install setup.py | *Note: For general usage questions and help, please use either our [FaceSwap Forum](https://faceswap.dev/forum)
or [FaceSwap Discord server](https://discord.gg/FC54sYg). General usage questions are liable to be closed without
response.*
**Crash reports MUST be included when reporting bugs.**
`
(faceswap) taoz... | closed | 2024-09-08T16:16:00Z | 2024-09-09T08:07:27Z | https://github.com/deepfakes/faceswap/issues/1400 | [] | taozhiyuai | 1 |
pydantic/FastUI | fastapi | 365 | give me sample code for CRUD simple | i search you docs about event . i experiment like this not work
can you give me sample about counter increment , or todo list
```
from fastapi import FastAPI
from fastapi.responses import HTMLResponse
from fastui import FastUI, AnyComponent, prebuilt_html, components as c
from fastui.events import PageEvent
... | open | 2024-11-11T04:59:03Z | 2024-11-11T04:59:03Z | https://github.com/pydantic/FastUI/issues/365 | [] | joesandiroz2 | 0 |
Johnserf-Seed/TikTokDownload | api | 603 | [Feature]支持同城视频解析 | 同城视频有个链接可以一次性获取10到15个随机视频 https://aweme-hl.snssdk.com/aweme/v1/nearby/feed/?,能不能搞个功能,允许做数据分析。 | open | 2023-11-17T17:22:37Z | 2023-11-17T17:22:37Z | https://github.com/Johnserf-Seed/TikTokDownload/issues/603 | [] | lanchengkai | 0 |
codertimo/BERT-pytorch | nlp | 56 | chooses 15% of token | From paper, it mentioned
> Instead, the training data generator chooses 15% of tokens at random, e.g., in the sentence my
> dog is hairy it chooses hairy.
It means that 15% of token will be choose for sure.
From https://github.com/codertimo/BERT-pytorch/blob/master/bert_pytorch/dataset/dataset.py#L68,
for ... | open | 2019-02-22T23:15:07Z | 2019-04-08T13:27:15Z | https://github.com/codertimo/BERT-pytorch/issues/56 | [
"good first issue"
] | makcedward | 1 |
widgetti/solara | fastapi | 1,019 | --env-file option for 'solara run' command doesn't do anything | Upon reviewing the code at the following code snippet:
https://github.com/widgetti/solara/blob/8947be4d7ddbc891017e89d6a463a94f8ac0c355/solara/__main__.py#L274
I discovered that the variable `env_file` is not utilized within the `run()` function.
## Expected Behaviour
Load the `.env` file located at the specified p... | open | 2025-03-17T21:59:26Z | 2025-03-18T17:41:26Z | https://github.com/widgetti/solara/issues/1019 | [] | SeoulSKY | 0 |
LAION-AI/Open-Assistant | python | 3,012 | Implement functionality for limiting initial prompts per user | Consider how best to do this | open | 2023-05-02T09:33:47Z | 2023-05-18T16:30:19Z | https://github.com/LAION-AI/Open-Assistant/issues/3012 | [
"backend"
] | olliestanley | 6 |
mljar/mercury | data-visualization | 56 | add login view for pro users | The UI code for pro users will ba available in the main repo.
The backend code for pro (commercial users) is in the separate repo, available only with a license. | closed | 2022-03-08T16:29:24Z | 2022-03-14T07:57:28Z | https://github.com/mljar/mercury/issues/56 | [
"enhancement"
] | pplonski | 1 |
vvbbnn00/WARP-Clash-API | flask | 135 | [Feature request] 能否支持sing-box订阅? | **为了更快地定位问题并减少不必要的麻烦,请在发起issue前检查是否已有相关issue存在,
谢谢!**
**📜 检查表**
- [ ] 我已了解目前issue主要处理`bug`和接收`feature request`
,其他类型的问题(如操作、配置问题,客户端问题等)应发布在[discussions](https://github.com/vvbbnn00/WARP-Clash-API/discussions)
中,否则该issue可能被关闭。
- [ ] 我已核实该`feature request`尚未在其他issue中被提及。
- [ ] 【可选】针对该`Feature Request`
... | closed | 2024-03-08T11:49:01Z | 2024-03-08T18:30:39Z | https://github.com/vvbbnn00/WARP-Clash-API/issues/135 | [] | PullGuy | 1 |
HIT-SCIR/ltp | nlp | 147 | model加载失败, linux master 3.3.1 model 3.3.0 | root@cpc:/opt/ltp/ltp/bin# ./ltp_test --input ./input --postagger-model ../ltp_data/pos.model
[INFO] 2016-01-08 10:48:57 Loading segmentor model from "ltp_data/cws.model" ...
[ERROR] 2016-01-08 10:48:57 /opt/ltp/ltp/src/ltp/LTPResource.cpp: line 50: LoadSegmentorResource(): Failed to load segmentor model
[ERROR] 2016-... | closed | 2016-01-08T02:52:13Z | 2016-01-24T11:03:00Z | https://github.com/HIT-SCIR/ltp/issues/147 | [] | CodingLionDargon | 1 |
widgetti/solara | fastapi | 528 | Theme toggle button dark mode becomes invisible with colored app bar | Toggling the theme button to dark mode, the button becomes invisible because it picks up the primary colour, but in case the app bar already has the primary colour it is invisible.
https://github.com/widgetti/solara/assets/743508/ebedd4ab-82b9-49b7-ab03-94e37e9f0c34
With AppBar created as:
```
v.AppBar(
... | closed | 2024-02-28T16:22:04Z | 2024-03-11T09:09:35Z | https://github.com/widgetti/solara/issues/528 | [] | mangecoeur | 2 |
paperless-ngx/paperless-ngx | machine-learning | 7,931 | [BUG] Error Making POST Document Call with Custom Fields | ### Description
I attempted to send a POST request to the Paperless API to create a new document with custom fields and values, but I received a 404 Bad Request error.
### Steps to reproduce
curl --location 'https://paperless.domain.com/api/documents/post_document/' \
--header 'Authorization: Token ' \
--for... | closed | 2024-10-15T12:28:31Z | 2024-10-15T13:31:13Z | https://github.com/paperless-ngx/paperless-ngx/issues/7931 | [
"not a bug"
] | aakashbashyal21 | 0 |
jupyter/nbviewer | jupyter | 401 | python and ruby ipynb in nbviewer cannot be displayed | These two links below seem not working. The ijulia example can be opened still though. I tried other ipython notebook link saved and all links not working so far.
http://nbviewer.ipython.org/github/ipython/ipython/blob/2.x/examples/Index.ipynb
http://nbviewer.ipython.org/github/minad/iruby/blob/master/IRuby-Example.ip... | closed | 2015-01-29T16:17:11Z | 2015-01-30T10:18:01Z | https://github.com/jupyter/nbviewer/issues/401 | [] | wushengzhong | 1 |
Anjok07/ultimatevocalremovergui | pytorch | 1,165 | Have a bug. How to fix it? | Last Error Received:
Process: Ensemble Mode
If this error persists, please contact the developers with the error details.
Raw Error Details:
RuntimeException: "[ONNXRuntimeError] : 6 : RUNTIME_EXCEPTION : Exception during initialization: D:\a\_work\1\s\onnxruntime\core\providers\cuda\cuda_call.cc:122 onnxru... | open | 2024-02-11T00:58:48Z | 2024-02-11T00:58:48Z | https://github.com/Anjok07/ultimatevocalremovergui/issues/1165 | [] | esqy9 | 0 |
miguelgrinberg/python-socketio | asyncio | 905 | Upgrade to bidict 0.22 to benefit from huge performance boost | In order to benefit from the huge performance improvement of bidict in version 0.22 which is key to python-socketio server for broadcasting messaging, it would be worth upgrading to bidict version 0.22 https://bidict.readthedocs.io/en/main/changelog.html
It will mean the end of support for Python 3.6, which reached en... | closed | 2022-04-01T08:55:34Z | 2022-07-16T11:13:57Z | https://github.com/miguelgrinberg/python-socketio/issues/905 | [
"question"
] | danlg | 1 |
huggingface/datasets | nlp | 7,097 | Some of DownloadConfig's properties are always being overridden in load.py | ### Describe the bug
The `extract_compressed_file` and `force_extract` properties of DownloadConfig are always being set to True in the function `dataset_module_factory` in the `load.py` file. This behavior is very annoying because data extracted will just be ignored the next time the dataset is loaded.
See this im... | open | 2024-08-09T18:26:37Z | 2024-08-09T18:26:37Z | https://github.com/huggingface/datasets/issues/7097 | [] | ductai199x | 0 |
aleju/imgaug | machine-learning | 231 | seq.to_deterministic() augments images and bounding boxes differently if an image has no corresponding bounding box | For example, if i augment a list of numpy images and a corresponding list of ia.BoundingBoxesOnImage:
```
seq = iaa.Sequential(
[iaa.Fliplr(0.5),
iaa.Affine(
rotate=(-30, 30),
mode='edge')
],
random_order=True
)
seq_det = seq.to_deterministic()... | open | 2019-01-15T06:41:11Z | 2019-02-05T20:05:50Z | https://github.com/aleju/imgaug/issues/231 | [] | sun-yitao | 2 |
Kav-K/GPTDiscord | asyncio | 438 | [BUG] response timeout when indexing | **Describe the bug**
Unable to index document or link in /index chat
**To Reproduce**
Steps to reproduce the behaviour:
1. /index chat
2. Insert document or website link in chat per instructions
3. Wait 10 minutes
4. See error
**Expected behaviour**
Expect the bot to be able to index the document or website | open | 2023-11-27T20:15:33Z | 2023-12-02T01:11:56Z | https://github.com/Kav-K/GPTDiscord/issues/438 | [
"bug"
] | whisperdrive | 2 |
ionelmc/pytest-benchmark | pytest | 176 | Stuck with errors related to % sign for --benchmark-compare-fail | Hello, first of all thanks for this great tool :)
I am stuck in a kind of deadlock situation I can't seem to resolve, maybe I am missing something obvious.
For instance I have the following:
```
# setup.cfg
[tool:pytest]
addopts = --benchmark-compare-fail=min:6%
```
Naturally it works fine with `pytest`.
... | closed | 2020-07-02T08:56:57Z | 2023-06-03T17:26:16Z | https://github.com/ionelmc/pytest-benchmark/issues/176 | [] | trubesv | 0 |
onnx/onnx | scikit-learn | 6,182 | Shape inference check fails with external data. | # Bug Report
### Is the issue related to model conversion?
Related to it.
### Describe the bug
Consider the following code snippet (I am using `torch` for ease of model definition. This will reproduce with pure `onnx` as well):
```
import torch
import onnx
class Linear(torch.nn.Module):
def __ini... | closed | 2024-06-14T15:09:13Z | 2024-07-18T20:05:17Z | https://github.com/onnx/onnx/issues/6182 | [
"bug"
] | stswidwinski | 4 |
gradio-app/gradio | data-science | 10,712 | No module named `gradio._simple_templates` | ### Describe the bug
When launching my app, I get the following error. However, this happens only in a specific environment as described in the system info below.
```shell
Traceback (most recent call last):
File "/root/app/package/webapp.py", line 11, in <module>
import gradio as gr
File "/usr/local/lib/... | closed | 2025-03-03T08:24:10Z | 2025-03-06T02:56:47Z | https://github.com/gradio-app/gradio/issues/10712 | [
"bug",
"pending clarification"
] | anirbanbasu | 3 |
davidsandberg/facenet | tensorflow | 574 | Alignment Fail | Hi, everyone.
Following the tutorial [Validate on LFW](https://github.com/davidsandberg/facenet/wiki/Validate-on-lfw). Only 8 of the faces can be aligned, all of the other faces can not be detected correctly. I checked the file align_dataset_mtcnn.py, and found that at the line below, for almost all of the fail face... | closed | 2017-12-08T18:10:23Z | 2018-04-01T21:19:17Z | https://github.com/davidsandberg/facenet/issues/574 | [] | GarrettLee | 1 |
dmlc/gluon-cv | computer-vision | 934 | src/imperative/imperative.cc:81: Operator _cvimresize is not implemented for GPU. | Yolov3 CPU mode is fine for inference, but the GPU mode appeared following error:
`[02:28:35] src/imperative/imperative.cc:81: Operator _cvimresize is not implemented for GPU.
Stack trace:
[bt] (0) /usr/local/lib/python3.6/dist-packages/mxnet/libmxnet.so(+0x5c07bb) [0x7fc666c0c7bb]
[bt] (1) /usr/local/lib/pytho... | closed | 2019-09-10T02:41:54Z | 2020-11-20T16:21:54Z | https://github.com/dmlc/gluon-cv/issues/934 | [] | xiaohujecky | 2 |
MilesCranmer/PySR | scikit-learn | 618 | Prior of the model | Hi,
Thanks for you answer last time. It really helps! I still have a small question here. Is there any prior distribution when combining these operators randomly? I'm not familiar with genetic programming, while I'm doing some work with model selection, which needs complexity of parameters if we use methods like AIC a... | closed | 2024-05-05T02:09:19Z | 2024-05-05T03:25:35Z | https://github.com/MilesCranmer/PySR/issues/618 | [] | CatYukino | 0 |
google/seq2seq | tensorflow | 256 | Want to develop Seq2Seq models but dont want to use Seq2Seq interface | Hi,
I actually just want to be able to develop a RNN in TF which uses the previous timestep's prediction as the next timestep's input, so if anyone can suggest a better way than please pray tell, but otherwise i've been directed to Seq2Seq to do this.
Am i able to use individual Seq2Seq methods and classes with m... | open | 2017-06-14T12:04:48Z | 2017-06-14T12:04:48Z | https://github.com/google/seq2seq/issues/256 | [] | fjshields1221 | 0 |
nok/sklearn-porter | scikit-learn | 84 | Is there any plan to support RandomForestRegressor? | Thanks | open | 2021-09-20T18:44:39Z | 2022-11-30T21:06:29Z | https://github.com/nok/sklearn-porter/issues/84 | [
"question",
"new feature"
] | michelsanner | 11 |
hyperspy/hyperspy | data-visualization | 3,325 | ROI pointer | There have been some attempts (https://github.com/hyperspy/hyperspy/pull/1668 and https://github.com/hyperspy/hyperspy/pull/2292) to implement ROI pointer for the navigator - even if this is an obvious feature to have, this hasn't happened yet!
Originally, the navigator pointer was implemented before ROI and events we... | open | 2024-03-02T12:58:31Z | 2024-03-12T13:09:21Z | https://github.com/hyperspy/hyperspy/issues/3325 | [] | ericpre | 3 |
flasgger/flasgger | api | 242 | Conflicting files due to installation of examples | There is a file conflict between flasgger and micawber, because both install files into the too generic path name examples.
For reference, please see [this Arch Linux bug](https://bugs.archlinux.org/task/60006) and this [bug with micawber](https://github.com/coleifer/micawber/issues/83).
As a solution, micawber and... | closed | 2018-09-15T06:30:08Z | 2018-09-18T00:56:36Z | https://github.com/flasgger/flasgger/issues/242 | [
"bug"
] | dvzrv | 2 |
custom-components/pyscript | jupyter | 349 | Trying to pass data to Notion, works fine from PyCharm. Occurring error: RuntimeError: Blocking calls must be done in the executor or a separate thread | Hello,
I'm trying to pass information from Home Assistant to Notion. In PyCharm everything works,
when I try to execute this code via Pyscript I get an exception. It runs until the last line, this is where the exception gets thrown.
(requests.post(url, headers=headers, data=data))
Python version:
- Python 3.... | closed | 2022-05-21T11:50:19Z | 2022-05-22T07:08:49Z | https://github.com/custom-components/pyscript/issues/349 | [] | Critycal1 | 1 |
fastapi/sqlmodel | fastapi | 523 | What is the purpose of parse_obj's second argument: "update"? | ### First Check
- [X] I added a very descriptive title to this issue.
- [X] I used the GitHub search to find a similar issue and didn't find it.
- [X] I searched the SQLModel documentation, with the integrated search.
- [X] I already searched in Google "How to X in SQLModel" and didn't find any information.
- [X] I al... | open | 2023-01-03T21:53:54Z | 2024-03-04T20:59:03Z | https://github.com/fastapi/sqlmodel/issues/523 | [
"question"
] | zmievsa | 2 |
d2l-ai/d2l-en | pytorch | 2,608 | Can't install d2l 1.0.3 on python 3.12.4 | The D2L Package version 1.0.3 requires numpy 1.23.5. Python 3.12.4/pip 24.1 consider it(numpy 1.23.5) depreciated and does not conclude the installation. It's needed to update the D2L package to depend on numpy 2.0.0. I'm waiting for it.
Regards. | open | 2024-06-25T09:40:51Z | 2025-02-11T13:12:20Z | https://github.com/d2l-ai/d2l-en/issues/2608 | [] | TheJeffah | 8 |
plotly/dash-core-components | dash | 233 | Use of git tags | Hi, I package dash for conda and it would be very helpful if git tags were used to tag releases. It is difficult to match which pypi release corresponds with which changes in the codebase without them. | closed | 2018-07-12T12:04:32Z | 2018-11-28T21:13:15Z | https://github.com/plotly/dash-core-components/issues/233 | [] | moorepants | 3 |
jschneier/django-storages | django | 637 | boto3 settings can't be configured when using django-storages settings | Hi,
Recently had an issue where i had to rebuild my local environment. in doing so, for some reason django-storages and boto3 aren't working anymore. Any ideas as to why?
(I had custom locations for the Media and Static following these instructions: https://www.caktusgroup.com/blog/2014/11/10/Using-Amazon-S3-to-s... | closed | 2018-12-18T22:26:51Z | 2019-09-11T06:58:19Z | https://github.com/jschneier/django-storages/issues/637 | [
"s3boto"
] | danielsailes | 1 |
encode/apistar | api | 209 | Support exceptions for all relevant HTTP status codes | I notice that `exceptions.py` is rather sparse. It would be nice to have access to the full suite of 4xx and 5xx codes (and probably a few more like 301).
I'm happy to do the legwork for this and submit a PR, but thought there might be reasons why so many were left off, so I'll wait for your reply before doing so. | closed | 2017-06-12T23:44:37Z | 2017-06-15T08:08:12Z | https://github.com/encode/apistar/issues/209 | [] | ex-nerd | 3 |
InstaPy/InstaPy | automation | 6,805 | Can I please get a working sample, every sample I created just logs in and navigates then ends the session | PS C:\Users\<Computer>\Desktop\Work\Xpose\Python> python -u "c:\Users\<Computer>\Desktop\Work\Xpose\Python\any.py"
InstaPy Version: 0.6.16
._. ._. ._. ._. ._. ._. ._. ._. ._.
Workspace in use: "C:/Users/<Computer>/InstaPy"
OOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOO
INFO [2024-04-11 23:04:16] [... | open | 2024-04-12T04:28:59Z | 2024-04-12T04:28:59Z | https://github.com/InstaPy/InstaPy/issues/6805 | [] | thegreatref | 0 |
LAION-AI/Open-Assistant | python | 2,891 | Monospace font does not render Morse code correctly (and will have other issues). | The monospace font used by the web client cannot render Morse code properly. The dots are sometimes rendered level with the dashes (in the middle, like a multiply operator), and other times, level with the line (at the bottom, like a period).
<img width="609" alt="Screenshot 2023-04-24 at 23 55 03" src="https://user... | open | 2023-04-24T22:52:04Z | 2023-04-27T09:13:03Z | https://github.com/LAION-AI/Open-Assistant/issues/2891 | [
"website",
"UI/UX"
] | 7ombie | 0 |
ultrafunkamsterdam/undetected-chromedriver | automation | 1,247 | Controlling a UC session with phpwebdriver | My goal is to run Undetected-Chromedriver sessions in Python and then take control of the browser with php and phpwebdriver.
I start by running the following code in Python:
```python
import undetected_chromedriver as uc
import time
options = uc.ChromeOptions()
options.debugger_address = "127.0.0.1:5444"... | open | 2023-05-10T02:16:49Z | 2024-12-05T13:22:33Z | https://github.com/ultrafunkamsterdam/undetected-chromedriver/issues/1247 | [] | torzak | 7 |
pallets-eco/flask-wtf | flask | 455 | OWASP Guidance: prefer Origin header over Referer header when Identifying Source Origin | CSRF protection in `csrf.py` should prefer Origin header over Referer header if the former is available when checking `same_site()`.
- [OWASP Guidance on the topic](https://cheatsheetseries.owasp.org/cheatsheets/Cross-Site_Request_Forgery_Prevention_Cheat_Sheet.html#identifying-source-origin-via-originreferer-heade... | open | 2021-06-28T21:32:56Z | 2023-07-25T21:47:37Z | https://github.com/pallets-eco/flask-wtf/issues/455 | [] | gsmethells | 2 |
vllm-project/vllm | pytorch | 15,363 | [Usage]: Async engine batch request no usage | ### Your current environment
Hi i have and it does not handle batch requests correctly. The example in the documents is for only one request:
https://docs.vllm.ai/en/latest/api/engine/async_llm_engine.html
engine.async( [prompt1] )->[gen1] not engine.async( [prompt1, prompt2, prompt3] )->[gen1,gen2,gen3].
I dont se... | closed | 2025-03-23T19:12:48Z | 2025-03-23T19:21:59Z | https://github.com/vllm-project/vllm/issues/15363 | [
"usage"
] | tiger241 | 0 |
miguelgrinberg/python-socketio | asyncio | 423 | How to make socket.io Client keep listening to Node.js server messages? | Hi, I got a problem with socket.io communication between a Python client with a Node.js server:
1) I got a localhost Node.js Server (using express library) that retrieves an access token through the Spotify Web API after a login authentication;
2) The Node,js Server emit this token through a socket (socket.io) to t... | closed | 2020-02-06T12:34:22Z | 2020-04-10T14:14:30Z | https://github.com/miguelgrinberg/python-socketio/issues/423 | [
"question"
] | DvDream | 7 |
jazzband/django-oauth-toolkit | django | 610 | should contributions require review? | I note that there seem to be some PRs (for example #606) that are merged by the contributor without a review by someone else. Shouldn't there be at least one other reviewer's approval before a PR is merged?
| closed | 2018-06-26T14:07:38Z | 2018-06-26T16:24:12Z | https://github.com/jazzband/django-oauth-toolkit/issues/610 | [
"question"
] | n2ygk | 2 |
Lightning-AI/pytorch-lightning | pytorch | 19,816 | Metrics logged by self.log and metric.compute() are different | ### Bug description
When testing my model, I am logging my F-1 metric every step using `self.log('f1_metric', self.f1_metric.compute(), on_epoch=True, on_step=False)`.
At the end of the epoch, I found that `self.trainer.logged_metrics['f1_metric']` and `self.f1_metric.compute()` have two different values. This s... | closed | 2024-04-25T19:49:05Z | 2024-04-26T23:41:19Z | https://github.com/Lightning-AI/pytorch-lightning/issues/19816 | [
"bug",
"needs triage"
] | mfoglio | 1 |
biolab/orange3 | scikit-learn | 6,436 | balance dataset | Balancing a dataset between target categories is a common best practice.
Currently, my approach follows that of the data sampling documentation for over/under-sampling: select rows, send the over-represented category (matching data) to a data sampler, then concatenate the downsampled data with the under-represented ... | open | 2023-04-26T21:42:36Z | 2023-11-11T08:40:20Z | https://github.com/biolab/orange3/issues/6436 | [
"meal"
] | jthornbrue | 1 |
cupy/cupy | numpy | 8,402 | `ndimage.gaussian_filter` does not have a `radius` argument | ### Description
`scipy.ndimage.gaussian_filter1d` and `gaussian_filter` accept a `radius` keyword, https://github.com/scipy/scipy/blob/v1.14.0/scipy/ndimage/_filters.py#L277, which the `cupyx.scipy.ndimage` analogs do not.
### Additional Information
_No response_ | open | 2024-06-29T10:36:28Z | 2024-07-01T05:34:32Z | https://github.com/cupy/cupy/issues/8402 | [
"contribution welcome",
"cat:feature",
"prio:medium"
] | ev-br | 0 |
jupyter-book/jupyter-book | jupyter | 1,660 | Including sphinx_book_theme in extensions breaks templates_path | ### Describe the bug
**context**
According to the [Sphinx Templating documentation](https://www.sphinx-doc.org/en/master/templating.html), it is possible to override a theme template by placing a template with the same name in `templates_path`:
> Templates with the same name in the [templates_path](https://www.sph... | closed | 2022-03-08T14:55:33Z | 2022-07-15T07:48:28Z | https://github.com/jupyter-book/jupyter-book/issues/1660 | [
"bug",
":label: sphinx-book-theme"
] | joh | 6 |
mars-project/mars | scikit-learn | 2,585 | [BUG] TimeoutError: Timeout in request queue | When fetching dataframe to local, when chunks is greater than 200, following errors happen:
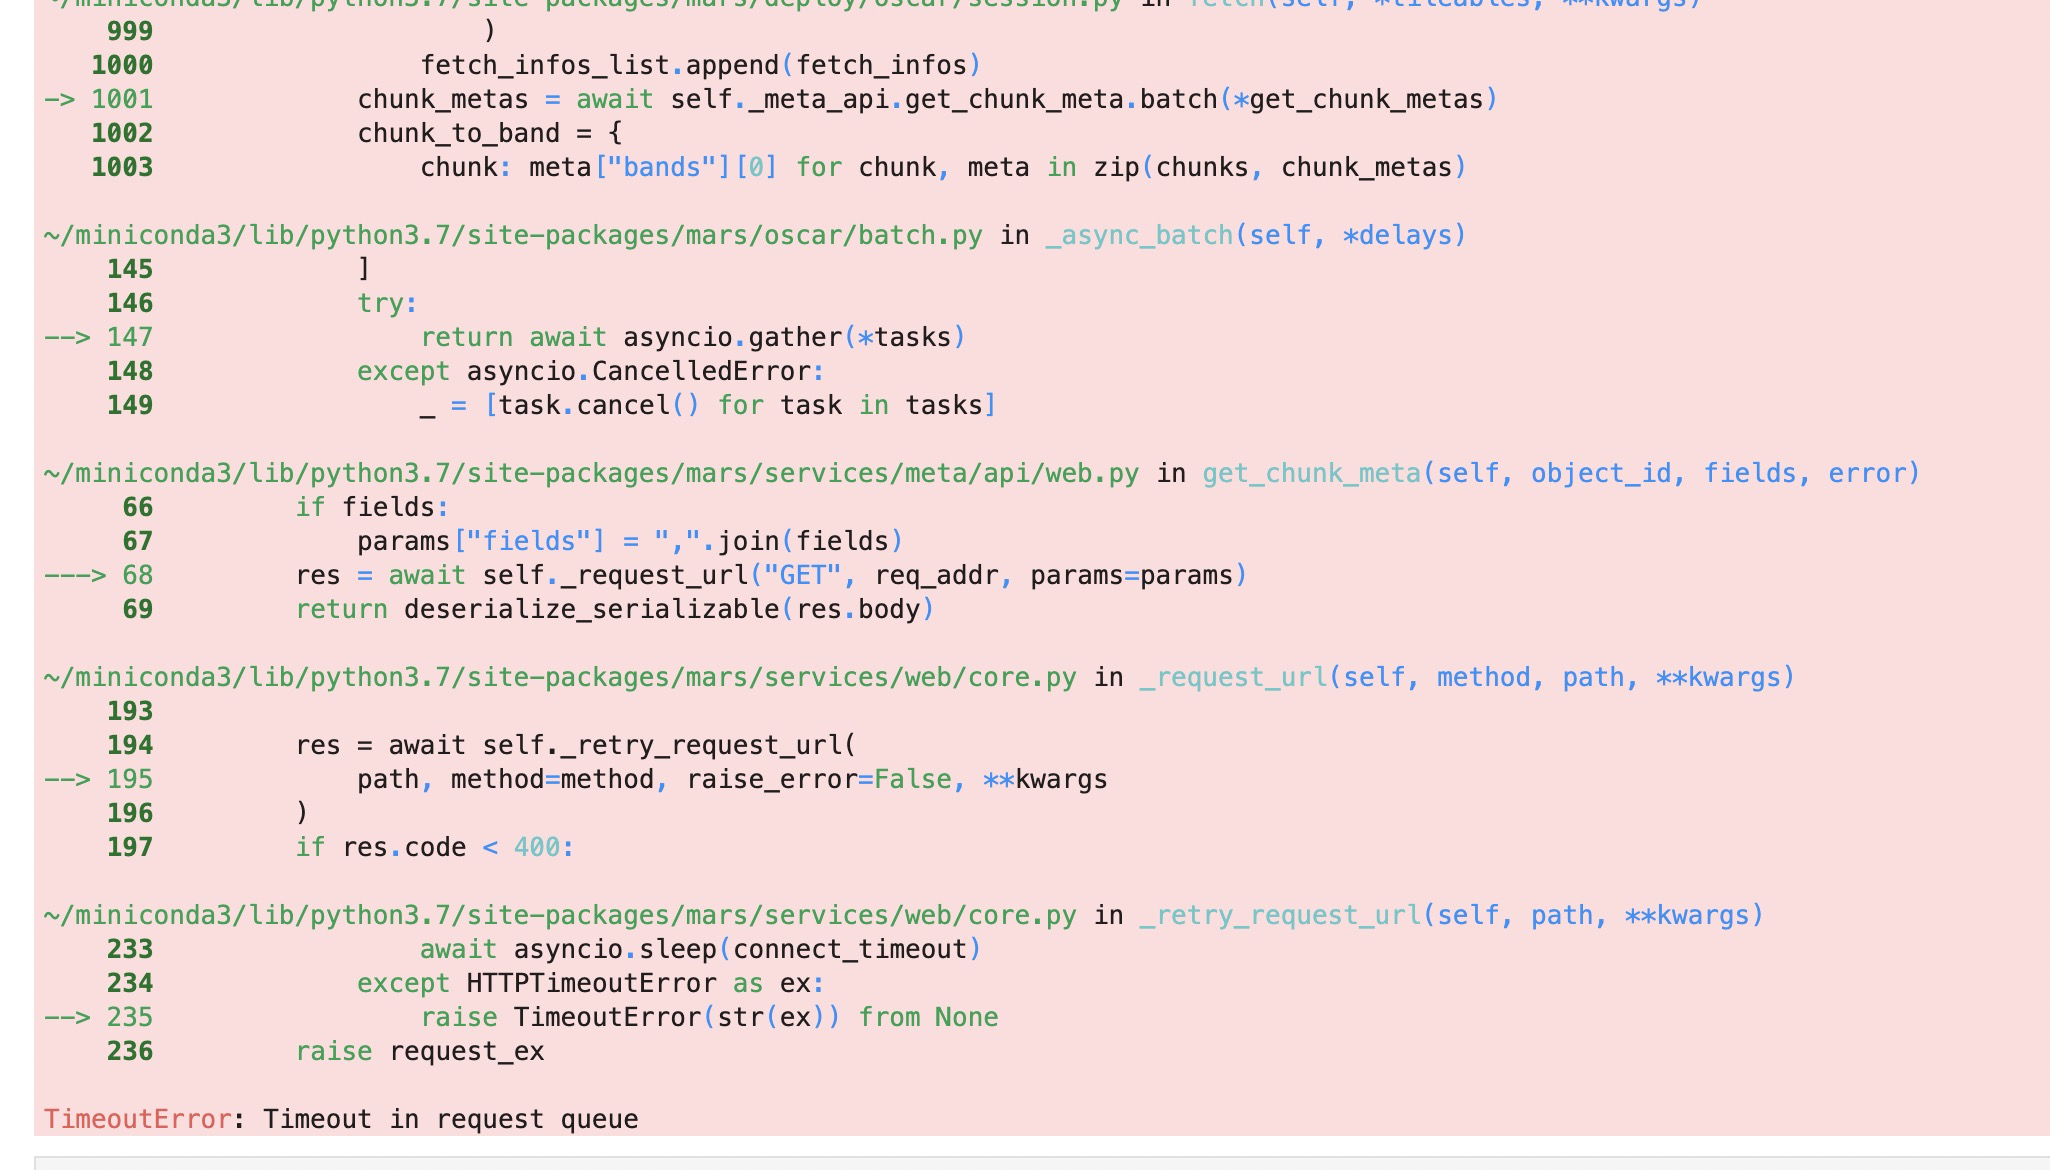 | open | 2021-11-25T10:35:52Z | 2021-11-25T10:35:52Z | https://github.com/mars-project/mars/issues/2585 | [] | chaokunyang | 0 |
HIT-SCIR/ltp | nlp | 188 | 如何自定义分词模型,具体命令是什么,能否给个实例? | closed | 2016-10-24T09:34:56Z | 2016-12-14T03:26:06Z | https://github.com/HIT-SCIR/ltp/issues/188 | [
"user-questions"
] | struggleToDawn | 7 | |
CorentinJ/Real-Time-Voice-Cloning | python | 667 | Dataset option is blur(not usable) in GUI | 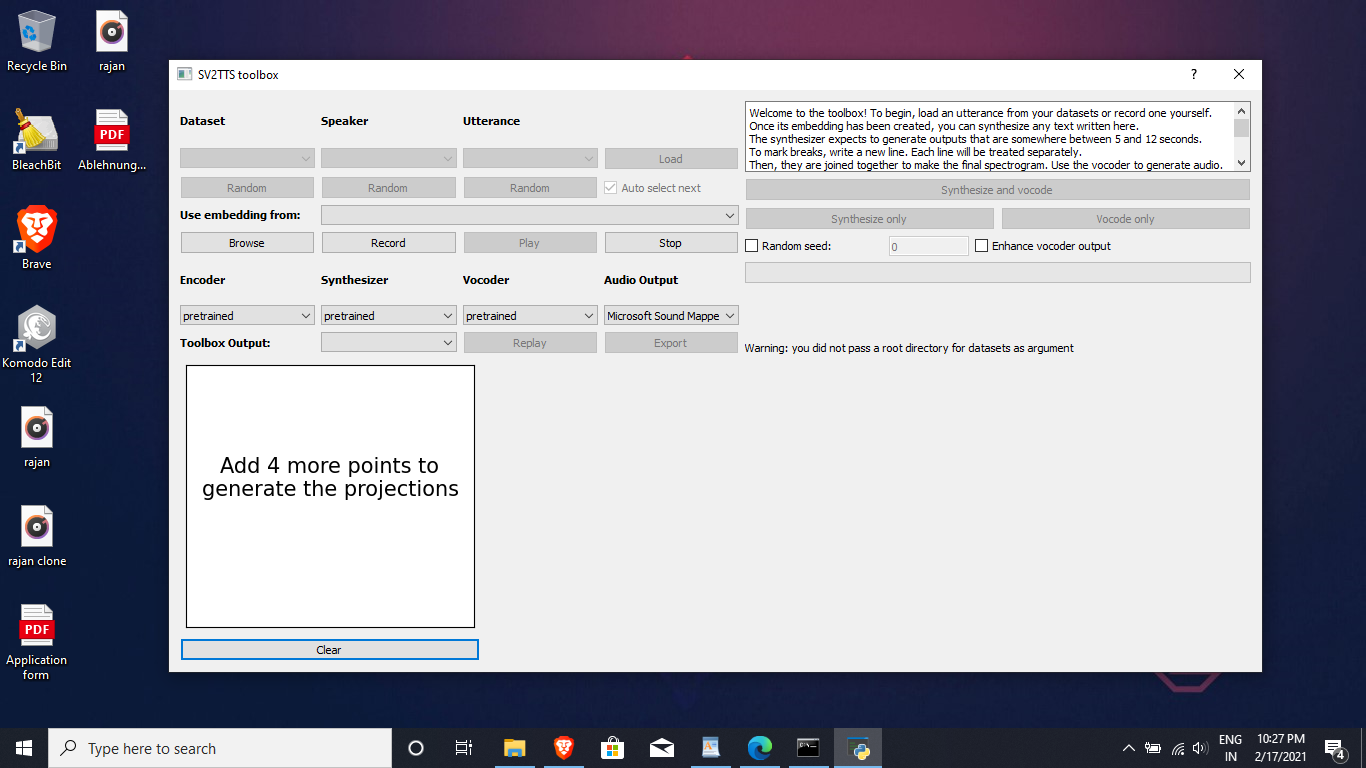
How to enable dataset option ? It is not usable in GUI. Where to extract data sets? <dataset_root> means any folder ? | closed | 2021-02-17T18:30:13Z | 2021-02-17T20:23:42Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/667 | [] | clonereal | 1 |
robinhood/faust | asyncio | 523 | Tables fail to recover from changelog when specifying `changelog_topic` | ## Checklist
- [x] I have included information about relevant versions
- [ ] I have verified that the issue persists when using the `master` branch of Faust.
## Steps to reproduce
I first manually created the topic with the correct number of partitions to match the stream I was iterating over, and enable comp... | open | 2020-02-03T13:57:26Z | 2020-08-18T14:39:51Z | https://github.com/robinhood/faust/issues/523 | [] | deed02392 | 4 |
Layout-Parser/layout-parser | computer-vision | 217 | No work | Thank you for your great work.
this is my code:
```python
import layoutparser as lp
import cv2
model = lp.PaddleDetectionLayoutModel('lp://PubLayNet/ppyolov2_r50vd_dcn_365e/config')
image = cv2.imread("paper-image.jpg")
layout = model.detect(image)
lp.draw_box(image, layout, box_width=3).show()
```
i noti... | open | 2024-08-30T07:58:17Z | 2024-08-30T07:58:17Z | https://github.com/Layout-Parser/layout-parser/issues/217 | [
"bug"
] | jmu201621143028 | 0 |
noirbizarre/flask-restplus | flask | 345 | HTTPException handling not working | Using the latest Restplus from pypi. 0.10.1.
It claims in the documentation (http://flask-restplus.readthedocs.io/en/stable/errors.html#httpexception-handling) that all werkzeug HTTPExceptions are automatically handled and converted to JSON, but I find this to not be the case.
e.g. if I raise an "Unauthorized" from... | open | 2017-11-02T18:11:55Z | 2017-11-02T18:11:55Z | https://github.com/noirbizarre/flask-restplus/issues/345 | [] | fgblomqvist | 0 |
nltk/nltk | nlp | 2,552 | Contraction does not work for the word 'ill' and wrongly converting it into 'I will' | Input: He is to step down at the end of the week due to **ill** health
Output: He is to step down at the end of the week due to **I will** health
Have a look at below sample code:
#!pip install contractions
import contractions
text = He is to step down at the end of the week due to ill health
contractions.f... | closed | 2020-06-08T08:36:46Z | 2020-06-08T15:12:59Z | https://github.com/nltk/nltk/issues/2552 | [] | vsaifi | 4 |
tflearn/tflearn | data-science | 494 | About finetuned | I trained a model of ResNet on ImageNet and get a model file. I use the model file to finetune ResNet for Oxford102, but the network doesn't converge. The loss is between [4.63,4.65]. Here is my code:
```python
resize_pics = (227,227,3)
# Data loading
X, Y = image_preloader('102flowers/train_256.txt',image_shape=re... | open | 2016-12-04T09:46:04Z | 2016-12-06T02:06:05Z | https://github.com/tflearn/tflearn/issues/494 | [] | huyangc | 1 |
holoviz/panel | plotly | 6,972 | Inconsistent Button/FileDownload Icon location | The icon for FileDownload is justified to the left, while the icon for Button is next to the words.
<img width="1338" alt="image" src="https://github.com/user-attachments/assets/923fa53e-d2c8-4e3f-9b56-4f15dcdd617f">
```python
import panel as pn
pn.extension()
download = pn.widgets.FileDownload(icon="cloud",... | closed | 2024-07-11T22:20:46Z | 2024-07-14T15:33:46Z | https://github.com/holoviz/panel/issues/6972 | [] | ahuang11 | 1 |
serengil/deepface | deep-learning | 1,016 | In version 0.0.84 the "region field is calculated incorrectly | closed | 2024-02-10T05:16:41Z | 2024-02-10T09:05:09Z | https://github.com/serengil/deepface/issues/1016 | [
"invalid"
] | AleksMx | 0 | |
piskvorky/gensim | nlp | 2,657 | Tweak placeholders | Continued from https://github.com/RaRe-Technologies/gensim/pull/2654
Point each placeholder to its corresponding tutorial. | open | 2019-10-29T08:43:15Z | 2019-10-29T08:43:22Z | https://github.com/piskvorky/gensim/issues/2657 | [
"documentation"
] | mpenkov | 0 |
PaddlePaddle/models | computer-vision | 4,993 | 进程被杀 | 您好,我在paddlepaddle1.8.4编译时进程被杀掉了,具体什么原因

| open | 2020-12-08T04:13:41Z | 2020-12-09T09:13:28Z | https://github.com/PaddlePaddle/models/issues/4993 | [] | qdd1234 | 1 |
gradio-app/gradio | deep-learning | 10,028 | The Gradio client CDN option doesn't work | ### Describe the bug
[According to the docs](https://www.gradio.app/docs/js-client#installation), the CDN version should just work, but it doesn't
<img width="941" alt="gradioclient" src="https://github.com/user-attachments/assets/2ab5097a-117f-4bc0-81c6-d396a0628dc1">
### Have you searched existing issues? 🔎
-... | open | 2024-11-24T01:34:20Z | 2024-11-24T01:34:20Z | https://github.com/gradio-app/gradio/issues/10028 | [
"bug"
] | cocktailpeanut | 0 |
sinaptik-ai/pandas-ai | pandas | 1,017 | Split CodeExecution logic unit into 2 | ### 🚀 The feature
We introduced pipelines a while ago to have more granular and single-purpose logic units that can be combined to create complex LLM-based workflows. However, some steps like the CodeExecution as still too big.
We should split it into 2:
- CodeCleaning: takes care of all the security concerns, ha... | closed | 2024-03-09T19:21:32Z | 2024-03-26T00:31:51Z | https://github.com/sinaptik-ai/pandas-ai/issues/1017 | [
"enhancement"
] | gventuri | 0 |
ploomber/ploomber | jupyter | 693 | improve use case in docs | this section: https://docs.ploomber.io/en/latest/user-guide/configuration.html#managing-multiple-pipelines
suggests that training/serving pipelines are a good use case for multiple `env.yaml` but it's actually not a great example. if a user has more than one pipeline in the same project and they don't have many elem... | open | 2022-03-30T19:24:00Z | 2022-03-30T19:24:00Z | https://github.com/ploomber/ploomber/issues/693 | [] | edublancas | 0 |
iterative/dvc | machine-learning | 10,246 | Azure Blob Storage: DVC uses (wrong) environment variable instead of SAS token | # Bug Report
## Azure Blob Storage: DVC uses (wrong) environment variable instead of SAS token
## Description
If my environment variables contains a variable named `AZURE_STORAGE_ACCOUNT_KEY` (not related to the DVC Azure Blob Storage), `dvc pull` fails with message `"Authentication error"` or `"ERROR: unexpec... | closed | 2024-01-18T15:05:07Z | 2024-01-19T08:57:25Z | https://github.com/iterative/dvc/issues/10246 | [] | SoCrespo | 3 |
jowilf/starlette-admin | sqlalchemy | 384 | Enhancement: add "request" as a parameter in the method get_list_query | **Is your feature request related to a problem? Please describe.**
I am developing a feature that requires filtering my relationships based on a specific column.
The relationship is such that 1 post can have N categories. When I am on my category page.
I want to select posts where the **status is "published" and... | closed | 2023-11-06T10:00:31Z | 2024-01-29T17:52:19Z | https://github.com/jowilf/starlette-admin/issues/384 | [
"enhancement"
] | whchi | 3 |
jessevig/bertviz | nlp | 138 | broken link in the "about" section | At the top right of the repo's webpage, it has the link -
https://towardsdatascience.com/deconstructing-bert-part-2-visualizing-the-inner-workings-of-attention-60a16d86b5c1
This gives a 404.
The wayback machine shows what it used to be -
https://web.archive.org/web/20241031010442/https://towardsdatascience.com/dec... | open | 2025-02-14T00:37:25Z | 2025-02-14T00:37:25Z | https://github.com/jessevig/bertviz/issues/138 | [] | zenfish | 0 |
ClimbsRocks/auto_ml | scikit-learn | 125 | Lack of milestones and tags for bugs relevancy/importance/difficultiness | Hi Preston,
- Currently I am able to see many issues opened, but not being assigned to/part of any milestones.
- Do you have any plans for upcoming release?
- Also I feel there is a need of tags assigned to each issue to make sure newbies get started easily and existing contributors to select issues to work on.
- As ... | closed | 2016-10-19T16:12:26Z | 2017-06-07T16:14:22Z | https://github.com/ClimbsRocks/auto_ml/issues/125 | [] | vishnumani2009 | 2 |
BeanieODM/beanie | pydantic | 283 | Syntax for finding document not passing flake8 | Hi,
I am trying to search document with a field that is boolean
Code:
```python
plan = await Plan.find_one(Plan.active == True)
```
But flake8 is showing `comparison to True should be 'if cond is True:' or 'if cond:'flake8(E712)`
If I change `==` to `is`, then I won't be able to retrieve document that matches th... | closed | 2022-06-09T23:00:23Z | 2023-01-21T02:29:35Z | https://github.com/BeanieODM/beanie/issues/283 | [
"Stale"
] | ponty33 | 3 |
howie6879/owllook | asyncio | 89 | 渲染网页时遇到个错误 | 
| open | 2020-05-28T17:15:48Z | 2020-05-28T17:16:10Z | https://github.com/howie6879/owllook/issues/89 | [] | x-haose | 1 |
smarie/python-pytest-cases | pytest | 86 | Improve ids for pytest parametrize | Current id generation strategy in parametrize plus seems suboptimal. Consider this:
```python
import pytest
from pytest_cases import parametrize_plus, pytest_fixture_plus, fixture_ref
@pytest.fixture
def a():
return 'A', 'AA'
@pytest_fixture_plus
@pytest.mark.parametrize('arg', [1, 2])
def b(arg):
... | closed | 2020-05-27T07:21:57Z | 2020-05-31T15:43:58Z | https://github.com/smarie/python-pytest-cases/issues/86 | [
"enhancement"
] | smarie | 1 |
Textualize/rich | python | 3,098 | [REQUEST] format `requests.structures.CaseInsensitiveDict` | Rich pretty-prints dictionaries, but not yet `requests`'s `requests.structures.CaseInsensitiveDict`. Given the ubiquity of the package, perhaps it's worthwhile including it.
MWE:
```python
import requests
from rich import print
res = requests.get("https://google.com/")
print(type(res.headers))
print()
p... | open | 2023-08-23T16:11:57Z | 2023-08-23T19:44:01Z | https://github.com/Textualize/rich/issues/3098 | [
"Needs triage"
] | nschloe | 2 |
fastapi-users/fastapi-users | fastapi | 10 | Setup package configuration | closed | 2019-10-16T05:12:00Z | 2019-10-17T10:18:21Z | https://github.com/fastapi-users/fastapi-users/issues/10 | [
"enhancement"
] | frankie567 | 0 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.