
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
benbusby/whoogle-search | flask | 1,113 | [FEATURE] Allow for a much bigger blocklist | <!--
DO NOT REQUEST UI/THEME/GUI/APPEARANCE IMPROVEMENTS HERE
THESE SHOULD GO IN ISSUE #60
REQUESTING A NEW FEATURE SHOULD BE STRICTLY RELATED TO NEW FUNCTIONALITY
-->
**Describe the feature you'd like to see added**
Sadly I got limited by the size of the cookie when I tried to, but I have a list of 1 000 + SEO... | open | 2024-01-26T18:32:17Z | 2024-01-26T18:32:17Z | https://github.com/benbusby/whoogle-search/issues/1113 | [
"enhancement"
] | garfieldairlines | 0 |
jupyter-book/jupyter-book | jupyter | 1,785 | Thumbnail Galleries support | ### Context
Need something like <https://nbsphinx.readthedocs.io/en/0.8.9/subdir/gallery.html>.
Collect a group of jupyter notebook and a cell's output as gallery image.
### Proposal
_No response_
### Tasks and updates
_No response_ | open | 2022-07-21T03:03:32Z | 2022-07-21T03:03:34Z | https://github.com/jupyter-book/jupyter-book/issues/1785 | [
"enhancement"
] | PaleNeutron | 1 |
dpgaspar/Flask-AppBuilder | rest-api | 2,115 | Custom add_form template création issues | Hello!
I'm new in development and am facing some issue about customisation.
I'm trying to upload file and I want to perform a lot of customisation like remove uuid automatically generated for filename so that the file upload process save the original filename in the db and the upload_folder. I somehow figure out how... | open | 2023-09-20T01:00:33Z | 2023-09-20T01:00:33Z | https://github.com/dpgaspar/Flask-AppBuilder/issues/2115 | [] | Romia25 | 0 |
skforecast/skforecast | scikit-learn | 679 | ForecasterAutoReg Error On .fit() | Hey all, getting an error when fitting forecaster autoreg. Currently enrolled in timeseries forecasting course and when i download their notebook it works perfectly. Super stumped on this one...
[ml_forecasting_1.pdf](https://github.com/JoaquinAmatRodrigo/skforecast/files/15215205/ml_forecasting_1.pdf)
| closed | 2024-05-06T01:30:35Z | 2024-08-19T01:45:01Z | https://github.com/skforecast/skforecast/issues/679 | [
"bug"
] | jrodenberg0 | 14 |
lepture/authlib | django | 1 | Features Checklist | Authlib features and their statuses.
## Client
- [x] OAuth1Session, compatible with requests-oauthlib
- [x] OAuth2Session, compatible with requests-oauthlib
- [x] OAuthClient, a mixed client for OAuth 1 and OAuth 2
- [x] Flask integration
- [x] Django integration
- [x] OpenID Connect `id_token` parsing
##... | closed | 2017-11-11T02:49:06Z | 2021-04-15T15:59:57Z | https://github.com/lepture/authlib/issues/1 | [] | lepture | 8 |
LAION-AI/Open-Assistant | machine-learning | 2,758 | Add the date of a answer as context to the dataset | I see quite often that answers are heavily dependent on the date, but people don't include that into their answers.
For Example:
Question:
> How old is Barack Obama?
Answer:
> BO is 61 years old ....
It would be good to add the date of the answer as metadata to it wouldn't it? What is the data format of ... | open | 2023-04-19T14:47:46Z | 2023-04-20T10:48:00Z | https://github.com/LAION-AI/Open-Assistant/issues/2758 | [
"feature",
"data"
] | stefangrotz | 2 |
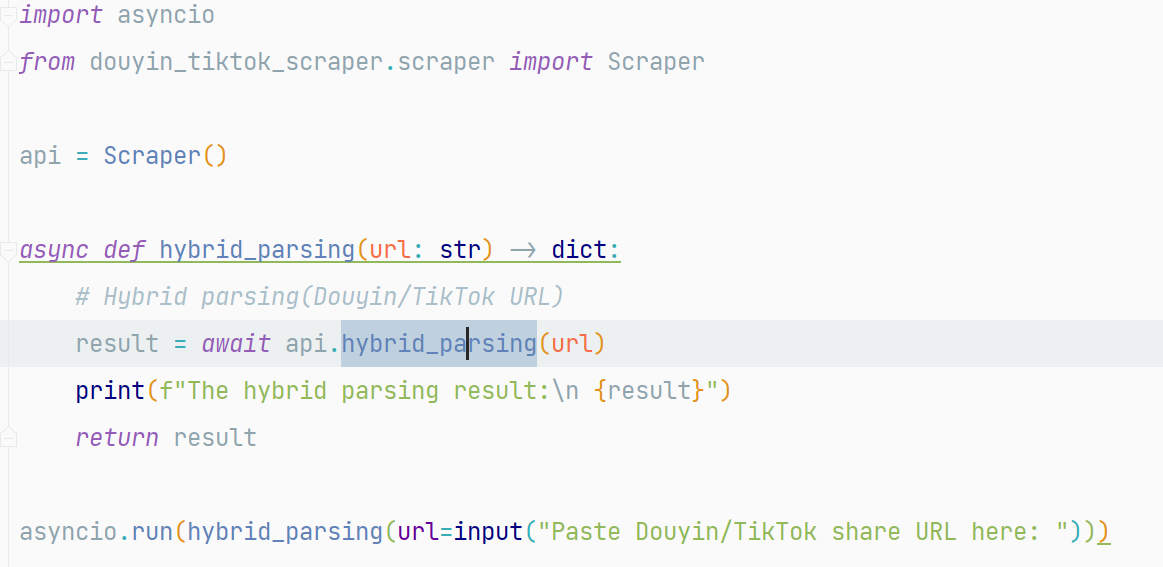
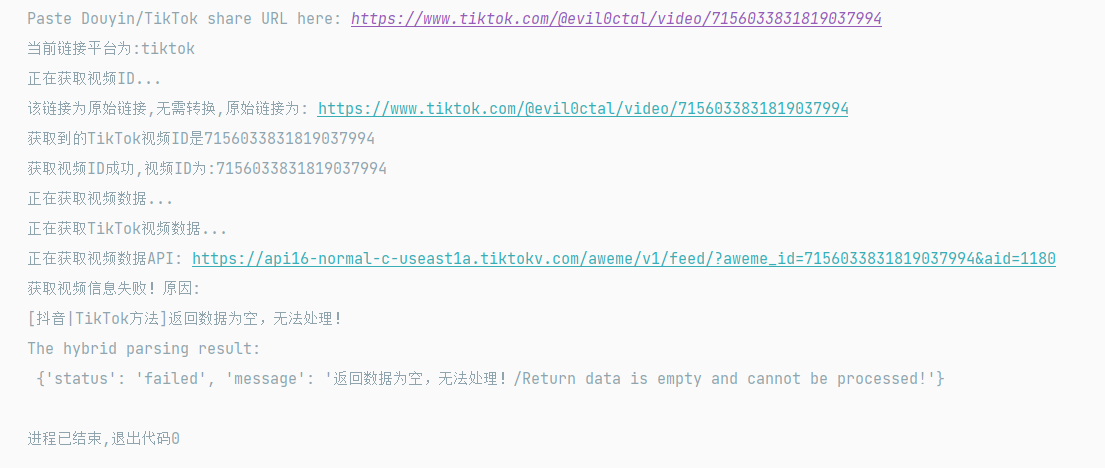
Evil0ctal/Douyin_TikTok_Download_API | api | 280 | [BUG] 升级到最新版3.1.8无法解析抖音 | ***发生错误的平台?***
抖音
***发生错误的端点?***
Web APP
***提交的输入值?***
```
2.53 H@V.Lw 04/12 vSY:/ 复制打开抖音,看看# 脱口秀 # 聊天 # 脱口秀# 聊天 这事还是有很深根源的。 https://v.douyin.com/ieWnGEWa/
```
***是否有再次尝试?***
是,发生错误后X时间后错误依旧存在。
***你有查看本项目的自述文件或接口文档吗?***
```
Traceback (most recent call last):
File "/root/.local/lib/pyth... | closed | 2023-09-26T12:21:52Z | 2023-09-26T12:41:20Z | https://github.com/Evil0ctal/Douyin_TikTok_Download_API/issues/280 | [
"BUG"
] | lifei6671 | 0 |
pydantic/pydantic-core | pydantic | 1,335 | Make better union validation decisions based on `extra` behavior | For example:
```py
class ModelA(BaseModel):
pass
class ModelB(BaseModel, extra='allow'):
pass
TypeAdapter(ModelA | ModelB).validate_python({'x': 1})
#> ModelA()
```
Is the current behavior, but that doesn't seem like the best decision.
See https://github.com/pydantic/pydantic-core/pull/1332 ... | open | 2024-06-19T18:37:45Z | 2024-08-28T17:22:31Z | https://github.com/pydantic/pydantic-core/issues/1335 | [
"bug"
] | sydney-runkle | 7 |
home-assistant/core | asyncio | 141,151 | Can't disable WORK AREA by Switch in Home Assistant | ### The problem
When i try to disable a work area by switching the switch in the home assistant GUI i get an error "failed to preform the action switch/turn_off. 0) and the switch switchs back to on.
allthoug when the work area is off and i turn it on, it works.
The log is in the attachment.
thanks for all.
### W... | closed | 2025-03-22T21:50:52Z | 2025-03-23T21:19:18Z | https://github.com/home-assistant/core/issues/141151 | [
"integration: husqvarna_automower"
] | flighter18 | 1 |
PrefectHQ/prefect | automation | 17,373 | Variable templating in deployment yaml should not be instantiated before any flow run | ### Describe the current behavior
There should be option to not instantiate the prefect variable into values on deployment of flow definition. In the context of remote job execution, I think Prefect Variable is used for values that is dynamic, so it make no sense that it comes a constant values before any Prefect job ... | open | 2025-03-05T00:59:25Z | 2025-03-05T00:59:46Z | https://github.com/PrefectHQ/prefect/issues/17373 | [
"enhancement"
] | atomic | 0 |
autogluon/autogluon | scikit-learn | 4,492 | Support for custom cross-validation strategies, e.g., forward chaining for temporally ordered tabular data | Hi AutoGluon team,
I'm using TabularPredictor for temporally ordered tabular data and need more flexible cross-validation options. The current CV methods and "groups" parameter don't suffice for many time-based scenarios.
Standard k-fold CV can cause data leakage with ordered data.
As far as I can tell, I'm unab... | open | 2024-09-25T16:30:30Z | 2024-11-25T23:04:35Z | https://github.com/autogluon/autogluon/issues/4492 | [
"enhancement",
"help wanted",
"module: tabular"
] | willadamskeane | 2 |
thp/urlwatch | automation | 22 | Only report on persistent changes | I'm finding that I'm getting a lot of false positives. urlwatch detects changes in a webpage in a particular run. In the next run, it detects a complete reversion of these changes. I see this on multiple websites, with different sections of the page. I'm not sure what is causing it, but it might be due to corrupted inc... | closed | 2015-08-16T23:16:42Z | 2019-04-12T15:14:35Z | https://github.com/thp/urlwatch/issues/22 | [] | protist | 7 |
marshmallow-code/apispec | rest-api | 77 | Separate plugins into separate packages? | It might be beneficial from a maintenance perspective to have the bundled plugins, e.g. apispec.ext.marshmallow and apispec.ext.flask, exist as separate packages. That would allow them to have their own release cycles independent of apispec core, which is currently pretty stable.
Feedback welcome.
| closed | 2016-05-21T18:15:39Z | 2017-03-06T02:56:04Z | https://github.com/marshmallow-code/apispec/issues/77 | [
"feedback welcome"
] | sloria | 1 |
python-gino/gino | asyncio | 146 | Docs | Tutorials
- [x] tutorial (fantix)
- [x] FastAPI tutorial (fantix)
How-To Guides
- [x] schema (fantix)
- [x] transaction (fantix)
- [x] crud
- [x] relationship (fantix)
- [x] FAQ
Explanation
- [x] engine (fantix)
- [x] why (fantix)
- [ ] GINO from scratch | open | 2018-02-26T07:29:55Z | 2020-05-05T16:57:12Z | https://github.com/python-gino/gino/issues/146 | [
"task"
] | fantix | 2 |
scikit-optimize/scikit-optimize | scikit-learn | 352 | Support qEI | In cases where the cost of n parallelized f()'s is lower than that of n sequential f()'s, the acquisition function u() can return q>1 points and the next evaluation of f()'s can take place at q points simultaneously. One such acquisition function, the multi-points expected improvements a.k.a. qEI(), have been studied i... | open | 2017-04-12T04:09:57Z | 2017-04-19T05:23:59Z | https://github.com/scikit-optimize/scikit-optimize/issues/352 | [
"New feature",
"Major",
"Research"
] | yangvz | 5 |
tensorlayer/TensorLayer | tensorflow | 625 | Failed: TensorLayer (92f30261) | *Sent by Read the Docs (readthedocs@readthedocs.org). Created by [fire](https://fire.fundersclub.com/).*
---
| TensorLayer build #7203482
---
| 
---
| Build Failed for TensorLayer (1.5.4)
---
You can find out more about this failure here:
... | closed | 2018-05-17T07:59:47Z | 2018-05-17T08:00:32Z | https://github.com/tensorlayer/TensorLayer/issues/625 | [] | fire-bot | 0 |
deepspeedai/DeepSpeed | machine-learning | 7,157 | [BUG] AttributeError: module 'deepspeed' has no attribute 'init_inference' | `Loading checkpoint shards: 100%|██████████████████| 3/3 [00:03<00:00, 1.09s/it]
Traceback (most recent call last):
File "/media/mldadmin/home/s123mdg31_11/HeteroDefense/deepspeed_demo.py", line 34, in <module>
llm_pipe = init_llm()
File "/media/mldadmin/home/s123mdg31_11/HeteroDefense/deepspeed_demo.py", line... | open | 2025-03-20T13:13:32Z | 2025-03-20T13:13:32Z | https://github.com/deepspeedai/DeepSpeed/issues/7157 | [
"bug",
"deepspeed-chat"
] | Gaop970222 | 0 |
tensorlayer/TensorLayer | tensorflow | 273 | change all `print` in the library and tutorials to logger | closed | 2018-01-06T13:47:28Z | 2018-01-06T14:56:50Z | https://github.com/tensorlayer/TensorLayer/issues/273 | [] | lgarithm | 1 | |
marshmallow-code/flask-smorest | rest-api | 488 | How do I use swagger plugins with flask-smorest? | My team is asking for the top bar to be shown at the top of the swagger page. Right now all we see are the graphics in the upper left.
How do I tell flask-smorest I want to use the swagger plugins when the page is created?
They want to see this.

### Is your feature request related to a problem? Please describe.
I often need to merge two different classes, such as "Team Player A" and "Team ... | open | 2024-10-14T11:53:14Z | 2024-10-14T11:53:14Z | https://github.com/cvat-ai/cvat/issues/8540 | [
"enhancement"
] | sharmanvarun | 0 |
saulpw/visidata | pandas | 2,356 | Allow specifying on CLI the number of lines to load from a file | If I have a large file, certainly I can just HEAD it to get the lines I want. I'd love to run the following:
vd -n100000 filename.csv
and have visidata simply open the first 100,000 records of the file. I know I can ctrl-c to stop along the way on a large file but that's not consistently stopping in the same plac... | closed | 2024-03-20T17:49:07Z | 2024-10-02T05:18:54Z | https://github.com/saulpw/visidata/issues/2356 | [
"wishlist",
"wish granted"
] | jwnacnud | 1 |
pytest-dev/pytest-qt | pytest | 258 | AttributeError: attribute '__signature__' of 'type' objects is not writable | After upgrading to Python 3.7.3, some of my tests have started to fail.
```
=============================================================================== FAILURES ===============================================================================
______________________________________________________________ Default... | closed | 2019-04-19T10:17:08Z | 2019-05-11T05:39:17Z | https://github.com/pytest-dev/pytest-qt/issues/258 | [] | henriquegemignani | 5 |
shashankvemuri/Finance | pandas | 33 | Numpy | Hello - I'm new to python so very basic question; I downloaded the libraries but when I go to run any of them, I get an error message that says 'No module named Numpy'
I'm using Visual Studio to as my IDE. Where am I going wrong? | closed | 2024-03-28T23:10:48Z | 2024-10-20T00:07:02Z | https://github.com/shashankvemuri/Finance/issues/33 | [] | Newtopython0 | 0 |
Nemo2011/bilibili-api | api | 137 | 【漏洞】{获取专栏内容时显示列表超出范围} | **Python 版本: 3.9.12
**模块版本:14.0.0.rc
**运行环境: Windows
**模块路径:bilibili_api.article`
**解释器:pypi
**报错信息:**
```
Traceback (most recent call last):
File "G:\bilizhuanlanshoucang\venv\main.py", line 114, in <module>
sync(main())
File "G:\bilizhuanlanshoucang\venv\lib\site-packages\bilibili_api\u... | closed | 2023-01-13T15:21:58Z | 2023-01-15T12:41:13Z | https://github.com/Nemo2011/bilibili-api/issues/137 | [] | scp23328 | 9 |
jpadilla/django-rest-framework-jwt | django | 251 | Django 1.10 support | I've started migration of my project to Django 1.10 so far I found some issues on test suite when running Django 1.10, I've updated some of the tests, but some of them are still failing.. I'll re work on this later but if someone already started giving support to Django 1.10 this is a good start [1]
[1] https://github... | closed | 2016-08-09T22:27:16Z | 2016-09-28T16:05:15Z | https://github.com/jpadilla/django-rest-framework-jwt/issues/251 | [] | angvp | 3 |
microsoft/nni | pytorch | 4,766 | I have meet an unknown error when I try the mnist nas example. | **Describe the issue**:
[2022-04-13 19:34:12] INFO (nni.experiment/MainThread) Creating experiment, Experiment ID: cau4bj2g
[2022-04-13 19:34:12] INFO (nni.experiment/MainThread) Connecting IPC pipe...
[2022-04-13 19:34:13] INFO (nni.experiment/MainThread) Starting web server...
[2022-04-13 19:34:15] INFO (nni.ex... | closed | 2022-04-13T12:26:26Z | 2022-09-09T03:12:35Z | https://github.com/microsoft/nni/issues/4766 | [
"Training Service"
] | sun-tao | 2 |
NullArray/AutoSploit | automation | 1,117 | . | Autosploit version: `3.1.2`
OS information: `Darwin-17.4.0-x86_64-i386-64bit`
Running context: `autosploit.py -H 7 -C ******* 127.0.0.1 9076 -e --whitelist ./hosts.txt -f etc/json/default_modules.json`
Error mesage: `ASDFSDFGSADGFASDFG`
Error traceback:
```
Traceback (most recent call):
File "/Users/admin/bin/python/a... | closed | 2019-06-27T18:16:32Z | 2019-06-27T18:17:13Z | https://github.com/NullArray/AutoSploit/issues/1117 | [] | AutosploitReporter | 1 |
indico/indico | flask | 6,457 | CERN logo in footer is low-res/blurry | 
| closed | 2024-07-28T01:10:28Z | 2024-08-06T12:36:28Z | https://github.com/indico/indico/issues/6457 | [
"enhancement",
"trivial"
] | avivace | 2 |
chatanywhere/GPT_API_free | api | 102 | 这个错误是由于使用了不支持的功能(embeddings)而导致的请求被限制。GPT-3.5-turbo 引擎不支持嵌入功能。[Enhancement] | **Is your feature request related to a problem? Please describe.**
A clear and concise description of what the problem is. Ex. I'm always frustrated when [...]
**Describe the solution you'd like**
A clear and concise description of what you want to happen.
**Describe alternatives you've considered**
A clear an... | closed | 2023-09-25T04:08:18Z | 2023-10-04T05:46:36Z | https://github.com/chatanywhere/GPT_API_free/issues/102 | [] | zxyy123 | 1 |
yzhao062/pyod | data-science | 299 | Bug : Single Class label |
bug with single class label.
bug in site-packages\pyod\models/base.py
Line 347
```
bug code
self._classes = len(np.unique(y))
Correct code :
if y is not None:
check_classification_targets(y)
self._classes = max(2, len(np.unique(y)) )
... | open | 2021-04-15T14:04:17Z | 2021-04-15T14:04:17Z | https://github.com/yzhao062/pyod/issues/299 | [] | arita37 | 0 |
vitalik/django-ninja | rest-api | 531 | [BUG] Optional Enum labelled as required in OpenAPI Schema | **Problem**
When using an `Enum` (or django `Choices`) class as a path, query, or form value, it is marked as required in the OpenAPI docs, despite being typed with `Optional` or `| None`, and having None set as the default.
The endpoint itself works as it should though, if the enum is not present the value is `Non... | open | 2022-08-17T06:49:25Z | 2022-08-18T02:22:12Z | https://github.com/vitalik/django-ninja/issues/531 | [] | OtherBarry | 2 |
LibrePhotos/librephotos | django | 603 | Can't access original photo through web UI, can only access thumbnail | ## 🐛 Bug Report
[ ] I am including my log files in zip format.
[*] I have looked for similar issues among all the former issues including closed ones.
### What Operating system and version is LibrePhotos running on:
64-bit Raspberry Pi OS 11
### What architecture is LibrePhotos running on:
ARM
### How i... | closed | 2022-08-12T05:42:50Z | 2022-09-06T17:24:09Z | https://github.com/LibrePhotos/librephotos/issues/603 | [
"bug"
] | yassendobrev | 9 |
rio-labs/rio | data-visualization | 184 | [BUG]: `rio.Switcher` Display Issue with `rio.Text` overflow="wrap" | ### Describe the bug
The `rio.Switcher` component does not open correctly and occupies excessive space when its content is a `rio.Text` component with `overflow="wrap"`. Works as expected with `overflow="nowrap"` and `overflow="ellipsize"`.
### Steps to Reproduce
```python
class MyExample(rio.Component):
... | closed | 2024-12-01T07:58:41Z | 2024-12-03T14:01:21Z | https://github.com/rio-labs/rio/issues/184 | [
"bug"
] | Sn3llius | 0 |
huggingface/diffusers | deep-learning | 10,120 | memory consumption of dreambooth+SD3 | Hi, I am running dreambooth SD3 with a single A100 GPU, I reduced resolution to 256; but it still need more memory than a single A100 has? I am wondering is this huge memory consumption normal?
```
!python train_dreambooth_sd3.py \
--pretrained_model_name_or_path="stabilityai/stable-diffusion-3-medium-diffusers"... | closed | 2024-12-04T19:39:04Z | 2025-01-27T01:30:18Z | https://github.com/huggingface/diffusers/issues/10120 | [
"bug",
"stale",
"training"
] | KolvacS-W | 5 |
jadore801120/attention-is-all-you-need-pytorch | nlp | 53 | Dropout when predicting | Shouldn't we set dropout prob to 0.0 during prediction?
I notice that in SubLayers.py line 27, the attn_dropout was not set for ScaledDotProductAttention | closed | 2018-06-05T13:27:05Z | 2018-08-25T17:43:03Z | https://github.com/jadore801120/attention-is-all-you-need-pytorch/issues/53 | [] | ColdEyeLampr | 1 |
modelscope/data-juicer | streamlit | 341 | How to download the YoukuMPLUG video dataset? | the modelscope newestlib unable to download it any more.
Alos, is there a simple way to download the videos? | closed | 2024-07-04T14:59:34Z | 2024-09-01T09:31:58Z | https://github.com/modelscope/data-juicer/issues/341 | [
"help wanted",
"stale-issue"
] | lucasjinreal | 10 |
Evil0ctal/Douyin_TikTok_Download_API | web-scraping | 184 | [BUG] 视频抓取失败 | 之前都是好用的,今早一试,失败了。
| closed | 2023-03-26T01:56:37Z | 2023-03-26T04:26:42Z | https://github.com/Evil0ctal/Douyin_TikTok_Download_API/issues/184 | [
"BUG"
] | moo611 | 1 |
mage-ai/mage-ai | data-science | 5,268 | [BUG] Error deleting files during dynamic blocks | ### Mage version
0.9.72
### Describe the bug
Dynamic blocs don't act well in Windows, any pipeline that create more that 50+ blocks had a variation of these errors:
`PermissionError: [WinError 5] Access is denied: '(PATH)/.mage_data\\artemis\\pipelines\\pipeline_name\\.variables\\186\\20240524T143124_597217\\fun... | open | 2024-07-15T09:57:35Z | 2024-10-09T18:57:00Z | https://github.com/mage-ai/mage-ai/issues/5268 | [
"bug",
"dynamic block"
] | lyosonernes | 0 |
TencentARC/GFPGAN | deep-learning | 61 | Training with clean version | Hi,
Thanks for your amazing work. I wonder that if it is possible to train with the GFPGAN clean? Also could you please release the pretrained weight for the stylegan clean?
Thank you | closed | 2021-09-11T04:30:22Z | 2021-09-11T06:23:12Z | https://github.com/TencentARC/GFPGAN/issues/61 | [] | HarukiYqM | 0 |
plotly/dash | flask | 3,230 | document type checking for Dash apps | we want `pyright dash` to produce few (or no) errors - we should add a note saying we are working toward this goal to the documentation, while also explaining that `pyright dash` does currently produce errors and that piecemal community contributions are very welcome. | closed | 2025-03-20T16:01:18Z | 2025-03-21T17:40:33Z | https://github.com/plotly/dash/issues/3230 | [
"documentation",
"P1"
] | gvwilson | 0 |
flasgger/flasgger | api | 518 | Query params validation with openApi v3 | I am trying to add a validation on my routes with` swag_from`. I want to use an existing `.yaml`, and for the validation I need to add a validation scheme.
This is how my route is configured in `api.yaml`:
```
paths:
/user/suggestions:
get:
summary: Returns search suggestions for user
oper... | open | 2022-02-03T13:22:34Z | 2022-02-03T13:22:34Z | https://github.com/flasgger/flasgger/issues/518 | [] | ritabiniash | 0 |
deepspeedai/DeepSpeed | deep-learning | 5,667 | Getting parameters of embeddings (safe_get_local_fp32_param)and setting the weight of embeddings (safe_set_local_fp32_param) does not work (bug?). | Hello, we have recently been trying to use FGM to train LLM but have encountered difficulties about deepspeed. We would greatly appreciate your generous assistance.
Here are the describe of FGM:
```
For each x in embedding:
1. Compute the forward loss and perform backward propagation to **obtain gradients**... | open | 2024-06-17T04:04:45Z | 2024-07-01T21:32:48Z | https://github.com/deepspeedai/DeepSpeed/issues/5667 | [] | Git-Shaw | 1 |
plotly/dash-bio | dash | 772 | Feature request: Support for string type chromosome column in `ManhattanPlot` | **Description**
Currently the chromosome column specified with `dash_bio.ManhattanPlot(chrm='<The column of chromosome>')` does not support non-numeric types.
**To Reproduce**
Python code:
```python
import dash_bio
plotly_demo_manhattan_path: Path = Path("../dev/data/plotly_manhattan_data.csv")
plotly_demo_man... | open | 2024-08-28T10:11:34Z | 2024-08-28T10:45:02Z | https://github.com/plotly/dash-bio/issues/772 | [] | LawrenceLiu023 | 1 |
marcomusy/vedo | numpy | 304 | addButton in vtkWidget | Hello,
I have created plotter in a pyqt widget, like
`self.vp = Plotter(qtWidget=self.vtkWidget)`
and tried to generate a button using vp.addButton.
`self.vp.addButton(self.parameters_reset, states=['Reset'], pos=[0.125, 0.875])`
```
def parameters_reset(self):
print('test')
```
I can see the but... | closed | 2021-01-29T20:49:33Z | 2022-01-11T14:00:39Z | https://github.com/marcomusy/vedo/issues/304 | [
"bug"
] | Tai-Hsien | 1 |
quasarstream/python-ffmpeg-video-streaming | dash | 104 | set limit output size | set limit output size | closed | 2022-12-22T18:54:44Z | 2023-04-09T10:24:36Z | https://github.com/quasarstream/python-ffmpeg-video-streaming/issues/104 | [] | POLYFAY | 1 |
custom-components/pyscript | jupyter | 395 | GitHub URL as a package: "Ignoring because it is not a valid package" | Hi. Wanted to highlight that requiring a package that is a URL fails with
```
DEBUG (SyncWorker_0) [custom_components.pyscript] Ignoring 'git+https://github.com/ALERTua/aioedgeos.git@master' because it is not a valid package
``` | closed | 2022-09-22T14:41:03Z | 2023-09-22T09:25:47Z | https://github.com/custom-components/pyscript/issues/395 | [] | ALERTua | 1 |
plotly/dash | flask | 2,651 | rangeslider indicator markers don't update dynamically on range adjustments | I have a range slider that is dynamically updated with its values and bounds being changed depending on user thresholds. When I adjust the bounds for the slider but keep the low and high value the same, the markers don't update their positions accordingly:
For example, with the current range slider layout:
:
> This specification defines a logout mechanism that uses direct back-channel communication between the OP and RPs being logged out; this differs from front-channel logout mechanism... | open | 2023-07-03T15:56:52Z | 2025-02-20T20:37:16Z | https://github.com/lepture/authlib/issues/560 | [
"spec",
"feature request"
] | azmeuk | 2 |
sigmavirus24/github3.py | rest-api | 950 | How to use 2FA and tokens | Until recently, I did:
```py
def auth_with_pw():
auth = github3.authorize(name, pw, …, two_factor_callback=two_factor_callback)
[store auth.token]
return github3.GitHub(token=auth.token)
def auth():
if token_file.is_file():
return github3.GitHub(token=token_file.read_text())
els... | closed | 2019-06-24T11:55:58Z | 2021-11-02T10:58:19Z | https://github.com/sigmavirus24/github3.py/issues/950 | [] | flying-sheep | 3 |
sinaptik-ai/pandas-ai | data-science | 1,173 | Enable custom code injection before the LLM code runs | ### 🚀 The feature
Right now it's tough to add some additional code on top of the code generated by LLM.
So, enhancing the code pipeline to allow users to add their custom code on top of LLM's code will help customize the response generated by LLM and PandasAI.
### Motivation, pitch
I am facing a library import iss... | closed | 2024-05-23T13:45:00Z | 2024-08-30T16:06:13Z | https://github.com/sinaptik-ai/pandas-ai/issues/1173 | [
"enhancement"
] | satyamj3 | 2 |
cleanlab/cleanlab | data-science | 1,157 | consider cleanvision's near duplicates too in Datalab near duplicates analysis | currently Datalab just ignores cleanvision's near duplicate checks, which are based on hashing. Ideally we could take some union of the methods for near duplicate detection. | open | 2024-06-20T17:19:56Z | 2024-12-25T19:51:19Z | https://github.com/cleanlab/cleanlab/issues/1157 | [
"needs triage",
"help-wanted"
] | jwmueller | 0 |
huggingface/datasets | numpy | 6,984 | Convert polars DataFrame back to datasets | ### Feature request
This returns error.
```python
from datasets import Dataset
dsdf = Dataset.from_dict({"x": [[1, 2], [3, 4, 5]], "y": ["a", "b"]})
Dataset.from_polars(dsdf.to_polars())
```
ValueError: Arrow type large_list<item: int64> does not have a datasets dtype equivalent.
### Motivation
When datasets... | closed | 2024-06-19T11:38:48Z | 2024-08-12T14:43:46Z | https://github.com/huggingface/datasets/issues/6984 | [
"enhancement"
] | ljw20180420 | 1 |
jupyter/nbgrader | jupyter | 1,580 | Enable the ReadTheDocs PR Preview | The ReadTheDocs PR Preview feature is really useful to automatically build the docs when a new PR is opened.
We should consider enabling it for this repo. This would make reviewing documentation changes easier without having to build the changes locally. For example for https://github.com/jupyter/nbgrader/pull/1577 ... | closed | 2022-05-11T13:41:40Z | 2022-05-18T11:32:55Z | https://github.com/jupyter/nbgrader/issues/1580 | [
"documentation"
] | jtpio | 5 |
robotframework/robotframework | automation | 4,799 | [API] Add task-related classes into RF API | Currently, in the Robot Framework API, the Task section and task-related settings do not have their own entity, but they are just a test-related classes instances. See documentation [here](https://robot-framework.readthedocs.io/en/stable/_modules/robot/parsing/model/blocks.html#TestCaseSection).
For example, the onl... | open | 2023-06-19T08:52:04Z | 2023-12-20T00:01:29Z | https://github.com/robotframework/robotframework/issues/4799 | [
"enhancement",
"priority: medium"
] | mnojek | 2 |
tableau/server-client-python | rest-api | 753 | Filter applied in get() returns 400065: Bad Request | I'm trying to filter by name a user, group or project, I'm getting following error message.
400065: Bad Request
The filter query contains a key which is not recognized for this api version.
**Environment:**
**server-client-python version:** 0.14.0
**server version**: 3.2 (Not working in any version from 2.... | closed | 2020-12-04T15:49:37Z | 2020-12-10T17:38:58Z | https://github.com/tableau/server-client-python/issues/753 | [] | ludwigrubio | 4 |
twopirllc/pandas-ta | pandas | 222 | watchlist error spawn_main - resolved, need if __name__ == '__main__': | I use Pycharm, not Juypter.
I ran your example.


| closed | 2021-02-08T21:14:34Z | 2021-02-08T23:40:20Z | https://github.com/twopirllc/pandas-ta/issues/222 | [
"duplicate"
] | karenjh2 | 1 |
huggingface/datasets | pandas | 7,010 | Re-enable raising error from huggingface-hub FutureWarning in CI | Re-enable raising error from huggingface-hub FutureWarning in CI, which was disabled by PR:
- #6876
Note that this can only be done once transformers releases the fix:
- https://github.com/huggingface/transformers/pull/31007 | closed | 2024-06-28T07:23:40Z | 2024-06-28T12:19:30Z | https://github.com/huggingface/datasets/issues/7010 | [
"maintenance"
] | albertvillanova | 0 |
globaleaks/globaleaks-whistleblowing-software | sqlalchemy | 4,150 | Wrong Tag Dockerhub | ### What version of GlobaLeaks are you using?
v4.15.6
### What browser(s) are you seeing the problem on?
Chrome, Microsoft Edge
### What operating system(s) are you seeing the problem on?
Windows
### Describe the issue
I think the tag on the docker hub page is wrong: https://hub.docker.com/r/globaleaks/globaleak... | closed | 2024-08-09T09:35:13Z | 2024-08-09T11:19:05Z | https://github.com/globaleaks/globaleaks-whistleblowing-software/issues/4150 | [
"T: Bug"
] | cdftrew | 1 |
matplotlib/mplfinance | matplotlib | 495 | mplfinance savefig MemoryError | Hi, Happy new year!
MplFinance very nice! It brings great convenience to my work! Thank you for your hard work!
However, when savfig several times, a memory error occurs, The current test is an error after savfig 9 pictures in succession,as shown in the figure below:
 and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
I am using python 3.6.9 version and i need to load best.pt of yolo11n model ... | open | 2025-02-10T07:58:16Z | 2025-02-10T10:50:24Z | https://github.com/ultralytics/ultralytics/issues/19155 | [
"question",
"dependencies"
] | Gcc1012 | 2 |
modin-project/modin | pandas | 7,164 | aggregation operations not working with many groups | Hi, I'm new to `modin.pandas`, I'm trying to perform several aggregation operations on groups which were splitted from a dataframe using `df.groupby()`. The aggregation util works fine when I have less number of groups but fails to perform when it has more than 1000 groups.
To give an idea of the code using an example... | open | 2024-04-10T12:38:40Z | 2024-04-12T19:39:55Z | https://github.com/modin-project/modin/issues/7164 | [
"question ❓",
"External"
] | abhi211199 | 1 |
influxdata/influxdb-client-python | jupyter | 578 | Error executing multiprocessing example | examples/import_data_set_multiprocessing.py
https://github.com/influxdata/influxdb-client-python/blob/master/examples/import_data_set_multiprocessing.py
Error executing multiprocessing example are reactivex upgrade.
```
Unexpected error: 'Future' object is not iterable
Traceback (most recent call last):
... | closed | 2023-05-24T05:36:46Z | 2024-08-12T19:23:49Z | https://github.com/influxdata/influxdb-client-python/issues/578 | [] | apogre | 2 |
mitmproxy/mitmproxy | python | 7,305 | Supports for exports .saz file | #### Problem Description
Fiddler flow exports use the .saz file. In Console Game on Xbox development, We need to analyze the saz file to submit the game. Microsoft only provided the analyzer for the saz file, so we hope mitmproxy can export saz files directly.
NOTE. We cannot use Fiddler to capture the HTTPS flow... | open | 2024-11-05T05:21:14Z | 2024-11-05T05:21:14Z | https://github.com/mitmproxy/mitmproxy/issues/7305 | [
"kind/feature"
] | gougougougougou | 0 |
jazzband/django-oauth-toolkit | django | 585 | Refreshing a revoked access token throws an error 500 | When you revoke an access token and try to refresh it afterwards, you end up with an error 500.
This seems to be related to the `get_original_scopes` method of `oauth2_provider/oauth2_validators.py` which tries to retrieve the access token related to the refresh token. However, since it was revoked, it no longer exi... | open | 2018-04-21T19:18:57Z | 2021-03-15T22:16:23Z | https://github.com/jazzband/django-oauth-toolkit/issues/585 | [] | Maximilien-R | 14 |
floodsung/Deep-Learning-Papers-Reading-Roadmap | deep-learning | 80 | Import into EndNote | If the citations can be import into EndNote directly, it would be more helpful.
Thank you. | open | 2017-11-11T04:43:29Z | 2017-11-11T04:43:29Z | https://github.com/floodsung/Deep-Learning-Papers-Reading-Roadmap/issues/80 | [] | xiaoxuduan | 0 |
openapi-generators/openapi-python-client | rest-api | 338 | Add support for recursively defined schemas | **Describe the bug**
I tried to create a python client from an OpenApi-Spec with the command `openapi-python-client generate --path secret_server_openapi3.json`. Then I got multple warnings:
- invalid data in items of array settings
- Could not find reference in parsed models or enums
- Cannot parse response for st... | closed | 2021-02-17T13:27:58Z | 2022-11-12T17:49:54Z | https://github.com/openapi-generators/openapi-python-client/issues/338 | [
"✨ enhancement",
"🐲 here there be dragons"
] | sp-schoen | 13 |
alteryx/featuretools | data-science | 2,415 | Remove numpy restriction in featuretools[spark] install when possible | In PR #2414, numpy was restricted to `<1.24.0` when installing the `featuretools[spark]` requirements due to an incompatibility between `pyspark` and `numpy==1.24.0` (likely due to pysparks' use of numpy aliases in which were removed in 1.24.0). Once pyspark is updated to work with numpy 1.24.0 we should remove the up... | closed | 2022-12-19T14:58:32Z | 2024-05-10T15:05:01Z | https://github.com/alteryx/featuretools/issues/2415 | [] | thehomebrewnerd | 1 |
kornia/kornia | computer-vision | 2,231 | We don't have tests for all functions | ## 🚀 Feature
`denormalize_pixel_coordinates3d`
`normalize_pixel_coordinates3d` are not in tests.
`normalize_pixel_coordinates3d` is used in https://github.com/kornia/kornia/blob/6d4f83cae02129b7f49acf022561711cd937e8b8/kornia/geometry/subpix/spatial_soft_argmax.py#L432 though.
We might have other functions... | closed | 2023-02-25T16:20:45Z | 2023-09-22T08:11:43Z | https://github.com/kornia/kornia/issues/2231 | [
"help wanted",
"code heatlh :pill:"
] | ducha-aiki | 5 |
Morizeyao/GPT2-Chinese | nlp | 180 | 请问作者--length长度最多只能设置为1023,再大就报错,该怎么解决 | 如果把--length设置为1024就会报错“the size of the tensor a (1025) must match the size of tensor b (1024) at non-singleton dimension 3” | closed | 2020-11-01T12:06:39Z | 2021-01-11T08:50:57Z | https://github.com/Morizeyao/GPT2-Chinese/issues/180 | [] | githubleung | 0 |
marimo-team/marimo | data-visualization | 3,237 | tooltip clipped inside container | ### Describe the bug
Following the example on tooltips: https://docs.marimo.io/api/markdown/?h=tooltip#tooltips
I found that the tooltip becomes clipped inside the container. I need to manually add padding to the cell containing the tooltipped element.
This becomes a problem, in particular when using grid layout, wh... | open | 2024-12-19T15:11:58Z | 2025-01-18T04:25:21Z | https://github.com/marimo-team/marimo/issues/3237 | [
"bug",
"help wanted"
] | mrdobalina2k | 1 |
Evil0ctal/Douyin_TikTok_Download_API | api | 199 | tiktok视频总是获取信息失败,部署在docker里也还是失败 |
运行结果:
纯小白,是这样运行吗😭😭😭 | closed | 2023-05-02T14:18:40Z | 2023-05-07T06:30:56Z | https://github.com/Evil0ctal/Douyin_TikTok_Download_API/issues/199 | [
"BUG"
] | CCLCK | 1 |
junyanz/pytorch-CycleGAN-and-pix2pix | pytorch | 666 | docker container not compatible with master branch | Hi there,
I'm trying to train a CycleGAN model on my universities machine learning cluster.
To run your code I'm using the docker container you provided. When running I get an error stating module "abc" was not found. I guess the docker container is running python 2.7?
I tried using the torch0.3.1 branch with wh... | closed | 2019-06-05T17:52:21Z | 2020-02-22T09:29:53Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/666 | [] | Peetee06 | 6 |
clovaai/donut | nlp | 137 | multi gpus, validation error in training stage | I tried finetuning DONUT on RVLCDIP with 8 V100 GPUs. It occurs error when validation in training stage as follows.
RuntimeError: All input tensors must be on the same device. Received cuda:2 and cuda:0
how can i fix it? thanks for your help~ | open | 2023-02-09T11:06:49Z | 2023-02-09T11:06:49Z | https://github.com/clovaai/donut/issues/137 | [] | CCchenxiaoxue | 0 |
QingdaoU/OnlineJudge | django | 473 | 前端二次开发,dish文件夹整合到后端之后,前端界面的效果部分发生变化,如何解决 | 标签处做了颜色调整,整合到后端后颜色又变回去了 | open | 2024-08-19T03:35:31Z | 2024-09-06T06:52:23Z | https://github.com/QingdaoU/OnlineJudge/issues/473 | [] | garry-jay | 2 |
Miserlou/Zappa | flask | 2,132 | Zappa Slack appears to be closed by default. | ## Context
I'm interested in Zappa development, so I followed the Slack link. The Slack appears to be closed by default and requires an invite from an administrator.
## Expected Behavior
I would like to join the Zappa Slack.
## Actual Behavior
I cannot join the Zappa Slack.
## Possible Fix
Adjust the Slack... | open | 2020-07-03T07:25:01Z | 2020-08-23T18:09:17Z | https://github.com/Miserlou/Zappa/issues/2132 | [] | jonatkinson | 2 |
python-restx/flask-restx | api | 218 | Docstring For Each Method | **Ask a question**
Hello everyone,
I would like to ask everyone about how to document the function (each method).
For example, for this `get` method, the documentation format is followed by Google Docstring. However, Swagger could not render properly the templates.
```
def get(self,command):
"""Examp... | open | 2020-09-06T01:43:22Z | 2020-10-13T12:29:15Z | https://github.com/python-restx/flask-restx/issues/218 | [
"question"
] | leviethung2103 | 1 |
biolab/orange3 | data-visualization | 6,229 | Qt6: stored OWRank settings are incompatible | <!--
Thanks for taking the time to report a bug!
If you're raising an issue about an add-on (i.e., installed via Options > Add-ons), raise an issue in the relevant add-on's issue tracker instead. See: https://github.com/biolab?q=orange3
To fix the bug, we need to be able to reproduce it. Please answer the following... | closed | 2022-11-29T14:34:56Z | 2023-02-09T09:02:30Z | https://github.com/biolab/orange3/issues/6229 | [
"bug",
"snack"
] | markotoplak | 0 |
nikitastupin/clairvoyance | graphql | 35 | TypeError: 'NoneType' object is not subscriptable | ```
Traceback (most recent call last):
File "/usr/lib/python3.8/runpy.py", line 194, in _run_module_as_main
return _run_code(code, main_globals, None,
File "/usr/lib/python3.8/runpy.py", line 87, in _run_code
exec(code, run_globals)
File "/home/skroggur/clairvoyance/clairvoyance/__main__.py", line 1... | closed | 2022-06-17T20:15:00Z | 2024-08-26T19:25:09Z | https://github.com/nikitastupin/clairvoyance/issues/35 | [] | skroggur | 4 |
pydantic/logfire | pydantic | 433 | `WITHIN GROUP` query syntax | @@frankie567:
I just tried with this new database engine and it's clearly day-and-night in terms of performance. We struggled before to load our dashboards for timespans > 3 hours; now it's able to load 30 days span pretty quickly. Really great move 👏
I've an existing query that's no longer compatible. The goal... | closed | 2024-09-18T17:16:26Z | 2024-10-15T09:11:44Z | https://github.com/pydantic/logfire/issues/433 | [] | samuelcolvin | 7 |
apache/airflow | automation | 47,392 | AIP-38 Add link to the `view_url` in the UI and display the bundle version | ### Body
Most likely in the `Code` tab. Display the bundle version as well as a link to the bundle_url if defined.
### Committer
- [x] I acknowledge that I am a maintainer/committer of the Apache Airflow project. | closed | 2025-03-05T15:09:22Z | 2025-03-06T14:48:02Z | https://github.com/apache/airflow/issues/47392 | [
"kind:meta",
"priority:high",
"area:UI",
"AIP-38",
"AIP-65: DAG history in UI",
"affected_version:3.0.0beta"
] | pierrejeambrun | 0 |
teamhide/fastapi-boilerplate | sqlalchemy | 15 | What does Propagation for Transactional do? | I wasn't able to find usages of it, what is its intended purpose? | closed | 2022-12-21T01:21:36Z | 2022-12-21T12:56:23Z | https://github.com/teamhide/fastapi-boilerplate/issues/15 | [] | mastercoms | 3 |
Morizeyao/GPT2-Chinese | nlp | 141 | RuntimeError: CUDA error: CUBLAS_STATUS_ALLOC_FAILED when calling `cublasCreate(handle)` | 您好,可否请教下,下面报错的原因是什么
File "train.py", line 202, in main
outputs = model.forward(input_ids=batch_inputs, labels=batch_inputs)
File "/home/nlp/anaconda3/envs/py36/lib/python3.6/site-packages/transformers/modeling_gpt2.py", line 533, in forward
head_mask=head_mask)
File "/home/nlp/anaconda3/envs/py36/l... | open | 2020-04-10T12:33:55Z | 2021-07-05T13:13:12Z | https://github.com/Morizeyao/GPT2-Chinese/issues/141 | [] | shjliqian | 8 |
mlfoundations/open_clip | computer-vision | 931 | segmentation fault | My programs crash with a segmentation fault when trying to initialize a model with `create_model_and_transforms` on an Intel Mac. I have tried different devices (cpu, mps) and different models - the crash always happens when positional embeddings get initialized (i.e. `transformer.py:475` or `modified_resnet.py:61`)
... | closed | 2024-08-28T16:55:54Z | 2024-10-22T15:37:13Z | https://github.com/mlfoundations/open_clip/issues/931 | [] | vadim0x60 | 2 |
ymcui/Chinese-BERT-wwm | nlp | 41 | 显存不够问题 | 请问一下,如果机器显存只有32G,或者更小,batch_size无法设置过高的情况下有没有折中的解决方法,谢谢 | closed | 2019-09-12T01:25:25Z | 2019-10-21T10:59:48Z | https://github.com/ymcui/Chinese-BERT-wwm/issues/41 | [] | sunyilgdx | 2 |
ading2210/poe-api | graphql | 18 | ModuleNotFoundError: No module named 'poe' | I installed these requirements:
pip3 install poe-client
pip3 install poe-api
Getting this error:
poe-api\examples>temporary_message.py
Traceback (most recent call last):
File "D:\poe-api\examples\temporary_message.py", line 1, in <module>
import poe
ModuleNotFoundError: No module named 'poe' | closed | 2023-04-06T12:01:28Z | 2023-07-23T07:09:42Z | https://github.com/ading2210/poe-api/issues/18 | [
"bug"
] | CRCODE22 | 8 |
sinaptik-ai/pandas-ai | pandas | 1,421 | can`t display chinese in charts | ### System Info
OS : ubuntu or win10
python 3.10.11
pandasai 2.3.0
### 🐛 Describe the bug
i am using PandasAI with streamlit,but output charts can`t display chinese correctly, i`v search issues, someone said it`s the font problem, but i don`t know where to put the font settings code
`plt.rcParams["font.s... | closed | 2024-11-04T02:30:03Z | 2025-02-16T14:14:38Z | https://github.com/sinaptik-ai/pandas-ai/issues/1421 | [
"bug"
] | phoenixor | 11 |
yzhao062/pyod | data-science | 527 | Which algorithms support ‘Semi-supervised Novelty Detection’? | Hi everyone:
In 'outlier-detection-101'(https://pyod.readthedocs.io/en/latest/relevant_knowledge.html#outlier-detection-101), it said this package support 'Unsupervised Outlier Detection' and 'Semi-supervised Novelty Detection'.
I need 'Semi-supervised Novelty Detection', whose training data consists only of observ... | open | 2023-09-05T05:23:29Z | 2023-09-05T05:23:29Z | https://github.com/yzhao062/pyod/issues/527 | [] | hzf125521 | 0 |
ultralytics/yolov5 | deep-learning | 13,335 | Error running in windows 11 with python 3.12 virtual env | ### Search before asking
- [X] I have searched the YOLOv5 [issues](https://github.com/ultralytics/yolov5/issues) and found no similar bug report.
### YOLOv5 Component
_No response_
### Bug
File "c:\Code\gradioapps\mfgappsv1\.venv\Lib\site-packages\torch\hub.py", line 599, in _load_local
model = entry(*args, ... | open | 2024-09-27T13:49:04Z | 2024-10-27T13:30:35Z | https://github.com/ultralytics/yolov5/issues/13335 | [
"bug"
] | balakreshnan | 5 |
Lightning-AI/pytorch-lightning | pytorch | 20,643 | convert_zero_checkpoint_to_fp32_state_dict fails with torch 2.6.0 due to weights_only default change | ### Bug description
With the release of torch 2.6.0, the default behavior of `torch.load` has changed and the `weights_only` argument now defaults to `True`. This change affects the `convert_zero_checkpoint_to_fp32_state_dict` function for converting a DeepSpeed checkpoint, leading to the following error when loading ... | open | 2025-03-14T13:29:35Z | 2025-03-14T13:31:44Z | https://github.com/Lightning-AI/pytorch-lightning/issues/20643 | [
"bug",
"needs triage",
"ver: 2.5.x"
] | championsnet | 0 |
Gozargah/Marzban | api | 1,522 | add support for hysteria2 | add support for hysteria2 | closed | 2024-12-16T01:57:12Z | 2024-12-16T07:18:33Z | https://github.com/Gozargah/Marzban/issues/1522 | [
"Duplicate"
] | kaikanertan | 0 |
stanfordnlp/stanza | nlp | 445 | mwt training always breaks at epoch - 33 | **Describe the bug**
I tried to train Stanza for Tamil, and mwt training always (tried with different data set) breaks at 33rd epoch.
Log:
2020-08-20 09:24:11: step 360/1100 (epoch 33/100), loss = 0.286464 (0.054 sec/batch), lr: 0.001000
Evaluating on dev set...
epoch 33: train_loss = 0.271402, dev_score = 0.9390
... | closed | 2020-08-20T04:17:29Z | 2021-01-27T17:27:18Z | https://github.com/stanfordnlp/stanza/issues/445 | [
"fixed on dev"
] | sarves | 2 |
open-mmlab/mmdetection | pytorch | 11,498 | Clarification on why i should finetune groundingdino | so groundingdino is a zero shot object detection model right? so if i fine tune classes for my custom data and then run inference on my custom data (has not been seen during training) then is it still zero shot? like because it learned the classes for my dataset and i run inference on similar data(but still has not bee... | open | 2024-02-26T06:08:03Z | 2024-02-26T06:22:45Z | https://github.com/open-mmlab/mmdetection/issues/11498 | [] | hnyll | 0 |
mlfoundations/open_clip | computer-vision | 642 | how is force_image_size performed? | closed | 2023-09-20T07:42:40Z | 2023-09-24T03:58:12Z | https://github.com/mlfoundations/open_clip/issues/642 | [] | yxchng | 2 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.