
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
strawberry-graphql/strawberry | fastapi | 3,288 | Malformed request with `operationName` that isn't in `query` gives 500 error: `Can't get GraphQL operation type` | ## Describe the Bug
Strawberry throws an uncaught `RuntimeError("Can't get GraphQL operation type")` resulting in a 500 server error for a request that provides an `operationName` that isn't in the `query`, e.g.
```json
{
"query":"query test { example }",
"operationName":"different"
}
```
This is an i... | open | 2023-12-13T04:37:19Z | 2025-03-20T15:56:31Z | https://github.com/strawberry-graphql/strawberry/issues/3288 | [
"bug"
] | huonw | 1 |
OFA-Sys/Chinese-CLIP | nlp | 52 | Got OrtException when deploy ONNX model to Android | Hello your team,
I followed the guide here: https://github.com/OFA-Sys/Chinese-CLIP/blob/master/deployment.md and success get the ONNX model that list below:
vit-b-16.txt.fp32.onnx 391 MB
vit-b-16.txt.fp16.onnx 2.27 MB
vit-b-16.img.fp32.onnx 332 MB
vit-b-16.img.fp16.onnx 3.34 MB
vit-b-16.txt.fp16.onnx.extra_fil... | closed | 2023-02-09T07:59:43Z | 2023-05-30T09:11:26Z | https://github.com/OFA-Sys/Chinese-CLIP/issues/52 | [] | zxixia | 11 |
BeanieODM/beanie | asyncio | 339 | [DEV] Black not listed in dev-dependencies | `pyproject.toml` includes a section for `tool.black` but does not appear to list `black` as a `dev-dependency`?
[I assume this is by mistake via the contributing doc](https://roman-right.github.io/beanie/development/#setting-up-the-development-environment):
> To run commands like pytest or black you have to run t... | closed | 2022-09-02T02:37:33Z | 2022-09-13T13:15:39Z | https://github.com/BeanieODM/beanie/issues/339 | [] | qw-in | 2 |
amidaware/tacticalrmm | django | 1,415 | Welcome email for new users. | I think with the configuration of the mail settings it would be great to have the option to send a user a 'Welcome email' with their credentials/token so they're able to login to the RMM without requiring external methods of communication. | open | 2023-01-25T16:47:38Z | 2023-01-26T13:36:41Z | https://github.com/amidaware/tacticalrmm/issues/1415 | [
"enhancement"
] | Kieranwest | 0 |
polakowo/vectorbt | data-visualization | 681 | How to view the total net value trend of the entire strategy | pf = vbt.Portfolio.from_orders( close=close , size =size , price=open, init_cash='autoalign', fees=0.001, slippage=0.001) In this strategy I have multiple assets, and I give the order size for each asset at each point in time. I use pf.stats() ,but the result is an average measure of the performance of each asset,I w... | closed | 2024-01-15T13:57:56Z | 2024-03-16T10:51:23Z | https://github.com/polakowo/vectorbt/issues/681 | [] | happy-mint | 2 |
JaidedAI/EasyOCR | pytorch | 596 | Import easyocr : No module named 'easyocr' | I installed pytorch using this code
`!pip install torch==1.8.1+cpu torchvision==0.9.1+cpu torchaudio===0.8.1 -f https://download.pytorch.org/whl/torch_stable.html`
then i installed easyocr using `!pip install easyocr` command
not able to import the easyocr module even after re-starting the kernal `import easyocr`
... | closed | 2021-11-21T18:33:44Z | 2022-08-07T05:01:22Z | https://github.com/JaidedAI/EasyOCR/issues/596 | [] | Sanjaygowda66 | 4 |
matplotlib/matplotlib | data-science | 28,898 | [Bug]: Matplotlib font error for negative data | ### Bug summary
When using a combination of text.usetex: True, font.family: 'serif', font.serif = 'Times', attempting to plot negative data results in a LookupError of the required font
### Code for reproduction
```Python
import matplotlib.pyplot as plt
plt.rcParams['text.usetex'] = True
plt.rcParams['font.famil... | closed | 2024-09-27T07:54:07Z | 2024-09-27T14:28:45Z | https://github.com/matplotlib/matplotlib/issues/28898 | [
"topic: text/usetex",
"topic: text/fonts"
] | JeltevL | 1 |
ymcui/Chinese-BERT-wwm | tensorflow | 55 | 微调roberta large需要什么样的配置 | closed | 2019-10-15T03:26:28Z | 2019-10-16T00:00:39Z | https://github.com/ymcui/Chinese-BERT-wwm/issues/55 | [] | xiongma | 2 | |
seleniumbase/SeleniumBase | web-scraping | 2,169 | New feature: Mobile Mode + UC Mode, together! | ## New feature: Mobile Mode + UC Mode, together!
Up until now, you can run tests in Mobile Mode **OR** UC Mode, but not both at the same time. I think I finally figured out a way to make both modes work together...
<img width="1175" alt="Screenshot 2023-10-08 at 11 15 31 PM" src="https://github.com/seleniumbase/S... | closed | 2023-10-09T01:11:30Z | 2023-10-10T19:56:01Z | https://github.com/seleniumbase/SeleniumBase/issues/2169 | [
"enhancement",
"UC Mode / CDP Mode"
] | mdmintz | 1 |
graphdeco-inria/gaussian-splatting | computer-vision | 224 | Splatting sequential data | Do you think splatting will work well with sequential data? If not, what adjustments do you think should be added to that?
When the new parts of the scene are revealed over time, it will be problematic to initialize those new Gaussians and optimize them without spoiling the old frames. At the same time, optimizing ... | closed | 2023-09-22T14:49:38Z | 2024-04-10T16:53:11Z | https://github.com/graphdeco-inria/gaussian-splatting/issues/224 | [] | VladimirYugay | 5 |
chaos-genius/chaos_genius | data-visualization | 853 | Add a restart policy to docker compose services | ## Description
Chaos Genius services do not restart if the docker daemon or the system restart due to any reason.
A few scenarios where this could occur
- Underlying hardware is degraded so AWS would ask us to stop and start instance.
- When you want to change instance type you need to stop server and start aga... | closed | 2022-03-29T09:42:41Z | 2022-04-11T06:18:37Z | https://github.com/chaos-genius/chaos_genius/issues/853 | [] | varunp2k | 0 |
alteryx/featuretools | data-science | 2,638 | Update ruff to 0.1.6 and use ruff linter/formatter | closed | 2023-12-07T15:35:52Z | 2023-12-07T16:30:18Z | https://github.com/alteryx/featuretools/issues/2638 | [] | gsheni | 0 | |
gee-community/geemap | streamlit | 802 | kernel error | I created an environment with the instructions provided on geemap.org using mamba, only thing I changed was the name of the environment from "gee to TSSenv"
- geemap version: 0.10.1
- Python version: 3.8
- Operating System: Windows 10
### Description
I can't run any code , when I get in jupyter noteboo... | closed | 2021-12-08T15:38:20Z | 2021-12-08T22:32:16Z | https://github.com/gee-community/geemap/issues/802 | [
"bug"
] | REvilo-code | 2 |
sinaptik-ai/pandas-ai | data-science | 1,178 | Field descriptions not seemed by used by agent and connector | ### System Info
2.0.43
Windows/Linux
### 🐛 Describe the bug
I use field descriptions for agent but the responses seem to indicate that these are not used.
Eg:- i listed a field as "UTC" timezone but the code still tries to convert to utc for that field
```
{
"datetime_utc": "column representing the starting... | closed | 2024-05-27T18:56:34Z | 2024-09-02T16:06:25Z | https://github.com/sinaptik-ai/pandas-ai/issues/1178 | [
"bug"
] | metalshanked | 1 |
ansible/awx | django | 15,730 | Unable to install AWX on Docker. | ### Please confirm the following
- [X] I agree to follow this project's [code of conduct](https://docs.ansible.com/ansible/latest/community/code_of_conduct.html).
- [X] I have checked the [current issues](https://github.com/ansible/awx/issues) for duplicates.
- [X] I understand that AWX is open source software provide... | open | 2025-01-03T17:27:12Z | 2025-01-22T18:32:34Z | https://github.com/ansible/awx/issues/15730 | [
"type:bug",
"component:ui",
"community"
] | bhargavtejad | 3 |
gto76/python-cheatsheet | python | 60 | More elegant way to calculate the product of the elements | In python 3.8 there is a more elegant way to calculate the product of the elements.
Instead of
`product_of_elems = functools.reduce(lambda out, el: out * el, <collection>)`
it can be done like this
`product_of_elems = math.prod(<collection>)` | closed | 2020-07-27T22:44:38Z | 2020-08-14T23:36:50Z | https://github.com/gto76/python-cheatsheet/issues/60 | [] | mariosasko | 2 |
yunjey/pytorch-tutorial | pytorch | 34 | [DCGAN] Deep Convolutional Generative Adversarial Network | When I follow the tutorials to train this network, I can not get effective image results. What should I do??
I made the following modifications
# Save the sampled images
fake_images = fake_images.view(fake_images.size(0), 3, 32, 32)
torchvision.utils.save_image(fake_images.data, './sample/fake_samples_%d.png... | closed | 2017-05-20T09:09:09Z | 2017-06-03T08:46:50Z | https://github.com/yunjey/pytorch-tutorial/issues/34 | [] | FYXX | 6 |
dsdanielpark/Bard-API | nlp | 282 | Check out this Bard/Gemini project. | https://github.com/HanaokaYuzu/Gemini-API
it has virtually everything working, even image gen... maybe can adapt some of your code to do the same.
| closed | 2024-02-18T14:02:29Z | 2024-03-05T08:23:41Z | https://github.com/dsdanielpark/Bard-API/issues/282 | [] | raymerjacque | 2 |
cvat-ai/cvat | computer-vision | 8,356 | Unable to Log In to CVAT Main Webpage After Restarting Windows 11 | ### Actions before raising this issue
- [X] I searched the existing issues and did not find anything similar.
- [X] I read/searched [the docs](https://docs.cvat.ai/docs/)
### Steps to Reproduce
_No response_
### Expected Behavior
I am unable to log in to the CVAT main webpage, even though I was able to log in and ... | closed | 2024-08-27T13:54:59Z | 2024-08-28T04:32:16Z | https://github.com/cvat-ai/cvat/issues/8356 | [
"question"
] | balandongiv | 4 |
geex-arts/django-jet | django | 208 | add a reload button for ajax dashboard modules, and/or auto-refresh | Hi,
I would like to be able to refresh a dashboard module by ajax, but it is not possible easily at the moment.
Is that planned at some point? Would you accept a PR? | open | 2017-04-19T14:40:55Z | 2017-08-15T16:01:32Z | https://github.com/geex-arts/django-jet/issues/208 | [] | millerf | 3 |
paulpierre/RasaGPT | fastapi | 24 | [Errno 13] Permission denied: '/var/lib/pgadmin/sessions' | when i run from ubuntu i have this error in my pgadmin log how do i fix it | open | 2023-05-18T09:13:08Z | 2023-05-30T01:40:42Z | https://github.com/paulpierre/RasaGPT/issues/24 | [] | Boburshoh-oss | 3 |
JaidedAI/EasyOCR | pytorch | 1,317 | requirements.txt with all versions | Because training EasyOcr model without the exact version of libraries and modules is so difficult (not easy), I have prepared a new complete ``` requirement.txt ``` file.
I have trained a new language (Old Persian) from scratch by EasyOcr model which is published on my GitHub repository:
https://github.com/Mel... | open | 2024-10-12T14:48:52Z | 2024-10-14T11:32:04Z | https://github.com/JaidedAI/EasyOCR/issues/1317 | [] | Melanee-Melanee | 1 |
serengil/deepface | machine-learning | 971 | installation error for 0.0.82 | Fails to install from pypi with below error
`ERROR: Exception:
Traceback (most recent call last):
File "/home/ketan/repos/deepface81/deep81/lib/python3.10/site-packages/pip/_internal/cli/base_command.py", line 165, in exc_logging_wrapper
status = run_func(*args)
File "/home/ketan/repos/deepface81/deep81/l... | closed | 2024-01-25T17:14:57Z | 2024-01-25T17:16:23Z | https://github.com/serengil/deepface/issues/971 | [
"dependencies"
] | kkolge | 1 |
sherlock-project/sherlock | python | 1,370 | python3 -m pip install -r requirements.txt | <!--
######################################################################
WARNING!
IGNORING THE FOLLOWING TEMPLATE WILL RESULT IN ISSUE CLOSED AS INCOMPLETE
######################################################################
-->
## Checklist
<!--
Put x into all boxes (like this [x]) once you have completed... | closed | 2022-06-11T18:13:28Z | 2022-07-17T17:49:36Z | https://github.com/sherlock-project/sherlock/issues/1370 | [
"bug"
] | l6xl | 1 |
dadadel/pyment | numpy | 99 | Type is removed from parameter if not in type hints when converting reST docstring | If a type is provided in a reST dosctring for a parameter, it will be removed in the output docstring if not present in the type hint:
```python
def func(param1):
"""Description
:param param1:
:type param1: str
:returns: the return value
"""
pass
```
Will produce:
```diff
# Pat... | closed | 2021-03-09T08:11:15Z | 2021-03-09T08:32:45Z | https://github.com/dadadel/pyment/issues/99 | [] | dadadel | 0 |
scikit-hep/awkward | numpy | 2,867 | attrs do no propagate properly to sub-record arrays | ### Version of Awkward Array
2.5.0
### Description and code to reproduce
```python3
import json
import awkward as ak
import numpy as np
fromjson = {
"class": "RecordArray",
"fields": ["muon"],
"contents": [
{
"class": "ListOffsetArray",
"offsets": "i64",
... | closed | 2023-12-01T22:49:32Z | 2023-12-04T14:39:04Z | https://github.com/scikit-hep/awkward/issues/2867 | [
"bug (unverified)"
] | lgray | 1 |
encode/uvicorn | asyncio | 2,417 | GUnicorn - Uvicorn - Flask - Ansible Playbook fails | ### Initial Checks
- [X] I confirm this was discussed, and the maintainers suggest I open an issue.
- [X] I'm aware that if I created this issue without a discussion, it may be closed without a response.
### Discussion Link
```Text
Let me know how to initiate the discussion, but I provided the details in the descrip... | closed | 2024-08-06T12:18:07Z | 2024-08-06T12:19:17Z | https://github.com/encode/uvicorn/issues/2417 | [] | gitsridhar | 0 |
FactoryBoy/factory_boy | sqlalchemy | 957 | Pass sequence to SubFactory | #### Description
When copying a sequence to a SubFactory, the value of the field on the child factory is always 0.
#### To Reproduce
##### Model / Factory code
```python
class PositionFactory(factory.alchemy.SQLAlchemyModelFactory):
class Meta:
model = models.Position
sqlalchemy_session_... | open | 2022-07-04T11:28:53Z | 2022-09-17T10:05:05Z | https://github.com/FactoryBoy/factory_boy/issues/957 | [
"Q&A",
"NeedInfo"
] | mademovic | 6 |
ageitgey/face_recognition | python | 1,508 | how to get accuration from the processing? | * face_recognition version:
* Python version: 3
* Operating System: windows
### Description
i want to get a accuation from the face recognition processing
but i cant find where the code for get a accuration in your examples
### What I Did
@app.post("/face_recognition")
async def recognize_faces(file: Up... | open | 2023-05-23T05:39:14Z | 2023-12-06T16:38:32Z | https://github.com/ageitgey/face_recognition/issues/1508 | [] | MR-michaelrio | 2 |
ray-project/ray | pytorch | 51,392 | [Data] iter_torch_batches or iter_batches support Sampler and BatchSampler | ### Description
In the training link, it is often encountered that the logic of the sampler is defined by the user.
Is the reason why iter_batches currently does not support the sampler that there is no way to ensure orderliness?
If orderliness is not required and only requires that the groups are together when using... | open | 2025-03-15T02:26:43Z | 2025-03-18T17:12:14Z | https://github.com/ray-project/ray/issues/51392 | [
"enhancement",
"triage",
"data"
] | Jay-ju | 0 |
ray-project/ray | data-science | 51,447 | [Core] http.client.RemoteDisconnected: Remote end closed connection without response | When we tried to start Ray on a single node (with multiple GPUs) to train the model, the following error occurrd. : http.client.RemoteDisconnected: Remote end closed connection without response
We use this script to start Ray:
```
set -x
export NODE_RANK=0
export RAY_MASTER_PORT=6379
export RAY_DASHBOARD_PORT=8265
OU... | open | 2025-03-18T10:21:23Z | 2025-03-19T22:20:24Z | https://github.com/ray-project/ray/issues/51447 | [
"bug",
"P2",
"core"
] | zhaoyuxin2 | 2 |
pydata/pandas-datareader | pandas | 20 | Fama French Factors keys should be descriptive | web.DataReader('F-F_Momentum_Factor', 'famafrench') returns a dict of 1,2 pointing to monthly, annual data.
I believe the dicts should indicate about the data.
https://github.com/pydata/pandas/issues/8842
| closed | 2015-02-09T15:42:16Z | 2015-12-06T20:18:01Z | https://github.com/pydata/pandas-datareader/issues/20 | [] | MichaelWS | 2 |
plotly/jupyter-dash | jupyter | 125 | Installing via conda causes "Plugin 'jupyterlab_dash' is already registered." | When installing via conda (see env.yaml below), and running `jupyter lab build`, then opening JupyterLab, a pop up appears: "Plugin 'jupyterlab_dash' is already registered."
env.yaml
```
name: test
channels:
- numba
- rapidsai
- conda-forge
- nvidia
- defaults
dependencies:
- bokeh
- datasha... | closed | 2023-10-18T03:22:10Z | 2023-11-11T05:02:15Z | https://github.com/plotly/jupyter-dash/issues/125 | [] | jmakov | 2 |
Anjok07/ultimatevocalremovergui | pytorch | 1,500 | 打不开 | 打不开 | open | 2024-08-07T12:18:17Z | 2024-08-07T12:18:17Z | https://github.com/Anjok07/ultimatevocalremovergui/issues/1500 | [] | 258151081 | 0 |
feature-engine/feature_engine | scikit-learn | 439 | add first-timers-welcome badge to readme | Very easy, we need a badge to show that we welcome contributions from first-timers.
The code for the badge can be taken from here:
https://www.firsttimersonly.com/
and it is actually this one:
[](https://ww... | closed | 2022-05-05T14:18:53Z | 2022-05-07T17:59:45Z | https://github.com/feature-engine/feature_engine/issues/439 | [
"first-timers-only"
] | solegalli | 10 |
deepset-ai/haystack | nlp | 8,315 | haystack.utils has issues, can't do imports | **Describe the bug**
I just cannot do imports, Idk whats going on here
**Error message**
ModuleNotFoundError: No module named 'haystack.utils.auth'
**Expected behavior**
A clear and concise description of what you expected to happen.
**Additional context**
Add any other context about the problem here, like... | closed | 2024-09-01T18:27:17Z | 2024-09-03T04:20:12Z | https://github.com/deepset-ai/haystack/issues/8315 | [] | pdwytr | 2 |
exaloop/codon | numpy | 636 | Unit test failed | Compiled v0.18.1 with clang-17 in exaloop/llvm-project, and gfortran-10
```shell
if [ ! -d "llvm-project" ]; then
git clone --depth 1 -b codon https://github.com/exaloop/llvm-project
else
echo "OK: LLVM exists"
fi
if [ ! -d "llvm-project/install" ]; then
export LD_LIBRARY_PATH=/lib/x86_64-linux-gnu:/usr/lib... | open | 2025-03-06T10:33:56Z | 2025-03-10T14:51:02Z | https://github.com/exaloop/codon/issues/636 | [] | MetalOxideSemi | 1 |
tortoise/tortoise-orm | asyncio | 1,635 | DoesNotExist can be more useful | **Is your feature request related to a problem? Please describe.**
When I use the Model.get() method and a DoesNotExist exception occurs because there is no corresponding record in the database, the provided error message is often not specific enough for me to quickly identify which Model is involved. The message "Obj... | closed | 2024-05-31T09:06:09Z | 2024-06-03T06:30:06Z | https://github.com/tortoise/tortoise-orm/issues/1635 | [] | BraveEggTart | 2 |
fastapi/sqlmodel | pydantic | 8 | How to order_by descending? | ### First Check
- [X] I added a very descriptive title to this issue.
- [X] I used the GitHub search to find a similar issue and didn't find it.
- [X] I searched the SQLModel documentation, with the integrated search.
- [X] I already searched in Google "How to X in SQLModel" and didn't find any information.
- [X... | closed | 2021-08-25T03:35:09Z | 2022-03-30T14:39:59Z | https://github.com/fastapi/sqlmodel/issues/8 | [
"question"
] | SunsetOrange | 5 |
gunthercox/ChatterBot | machine-learning | 2,215 | chatterbot and machine learning | hi,
In this issue, I would like to share my concerns about the use of chatterbot with deep learning stuff.
you can comment as you wish, and when I have the time, I will do my best to implement and/or provide a way for others to implement them
* word embedding and sentence similarity
instead of spacy, in the compari... | open | 2021-11-03T20:16:44Z | 2021-11-03T20:16:44Z | https://github.com/gunthercox/ChatterBot/issues/2215 | [] | brightening-eyes | 0 |
automl/auto-sklearn | scikit-learn | 1,279 | User has no way to control dataset size reduction for large datasets and small memory | PR #1250 introduces a more parametrized form of the dataset size reduction for when we deal with large datasets or low memory requirements. However, we have no way for the user to disable or interact with this part of the pipeline.
Potential issues:
* A large dataset of precision `np.float64` or higher, where the p... | closed | 2021-11-03T11:22:56Z | 2022-02-01T14:30:19Z | https://github.com/automl/auto-sklearn/issues/1279 | [
"maintenance"
] | eddiebergman | 1 |
KaiyangZhou/deep-person-reid | computer-vision | 189 | Training accuracy when training with triplet loss | Hi @KaiyangZhou, I have recently been training some triplet loss models, and am achieving good results on the test set. However, I have noticed that during training, the training accuracies are extremely low (when using triplet loss only), even though the performance on the test set is good.
However, when I train u... | closed | 2019-06-12T21:10:52Z | 2019-06-12T22:03:26Z | https://github.com/KaiyangZhou/deep-person-reid/issues/189 | [] | ba305 | 3 |
ymcui/Chinese-LLaMA-Alpaca | nlp | 388 | 响应输出特别慢 | *提示:将[ ]中填入x,表示打对钩。提问时删除这行。只保留符合的选项。*
### 详细描述问题
在AutoDL的V100环境下运行
但输出特别慢,
### 运行截图或日志
### 必查项目(前三项只保留你要问的)
- [√ ] **基础模型**:LLaMA / Alpaca / LLaMA-Plus / Alpaca-Plus
- [ √] **运行系统**: Linux
- [√ ] **问题分类**:llama.cpp
- [√ ] (必选)由于相关依赖频繁更新,请确保按照[Wiki](https://github.com/ymcui/Chinese-LLaMA-Alpaca... | closed | 2023-05-19T05:31:26Z | 2023-05-29T23:50:48Z | https://github.com/ymcui/Chinese-LLaMA-Alpaca/issues/388 | [
"stale"
] | happy-zhangbo | 8 |
microsoft/nni | machine-learning | 5,488 | It is recommended to combine quantification of NNI with onnxruntime | NNI is a great project and its quantification function is very easy.
However, I find that the quantified results can only be converted to tensorrt acceleration for the GPU within the framework of nni. This will be the biggest resistance for developers like mobile or cross-language platforms to choose nni.
So if y... | open | 2023-03-29T07:54:13Z | 2023-03-31T02:35:49Z | https://github.com/microsoft/nni/issues/5488 | [
"feature request"
] | Z-yq | 0 |
Avaiga/taipy | data-visualization | 2,307 | Custom Sorting in Taipy Tables | ### Description:
Currently, Taipy’s built-in tables support basic sorting capabilities. However, there is no direct support for custom-defined sorting strategies. This can be limiting in scenarios where complex or domain-specific sorting logic is required. For example, users may want to sort by a custom metric, sort... | open | 2024-12-06T15:05:04Z | 2024-12-06T15:06:23Z | https://github.com/Avaiga/taipy/issues/2307 | [
"🖰 GUI",
"🟩 Priority: Low",
"✨New feature"
] | FlorianJacta | 0 |
aleju/imgaug | machine-learning | 37 | Data augmentation not working on all my dataset | Hello,
l passed this code `generate_example_images.py ` (in a for loop ) on a dataset of 200.000 images. After that l noticed that not all the images are augmented . For instance , additivegaussian noise for some images it worked perfectly but for other they remained the same. This also apply for other data augmen... | open | 2017-06-04T21:54:11Z | 2017-06-04T22:12:12Z | https://github.com/aleju/imgaug/issues/37 | [] | ahmedmazari-dhatim | 4 |
Sanster/IOPaint | pytorch | 237 | Offline working version without addons installations | I've tried to install it on win7 and win10 with "easy installer", but no luck, many errors while installing.
It will be great to download working version with switching between cpu and gpu option, with all additions needed for python, and python included. Even if it will not update.
| closed | 2023-03-06T23:49:29Z | 2023-03-16T06:48:36Z | https://github.com/Sanster/IOPaint/issues/237 | [] | fewtubefx | 4 |
explosion/spaCy | data-science | 13,232 | Verb characterized as noun in English text | Hello, I've noticed that there are cases where spacy recognizes the root verb correctly in a sentence, but characterizes the verb's token as a noun. Here is an example where the root verb happens to also be a valid noun (of type NNS) in the English language. I've tested and this works in the same way on the _sm, _md an... | closed | 2024-01-12T12:13:50Z | 2024-02-15T00:02:19Z | https://github.com/explosion/spaCy/issues/13232 | [
"lang / en",
"feat / tagger",
"perf / accuracy"
] | dglynos | 2 |
Nike-Inc/koheesio | pydantic | 83 | [FEATURE] Externalize and Expose Test Utilities | ## Is your feature request related to a problem? Please describe.
Currently, the test utilities and fixtures in the `koheesio` library's `conftest.py` files are not easily accessible for engineers who want to write tests in their own pipelines. This limits the reusability and efficiency of the existing test setups, ma... | open | 2024-10-24T07:34:54Z | 2025-02-20T21:24:42Z | https://github.com/Nike-Inc/koheesio/issues/83 | [
"enhancement"
] | dannymeijer | 1 |
idealo/imagededup | computer-vision | 35 | Handle multi picture objects (MPO) | I have a LOT of images (roughly 1/3 of my entire personal library) that register in PIL as MPO. Your code barfs on all of them, but changing image_utils.py line 15 to IMG_FORMATS = ['JPEG', 'PNG', 'BMP', 'MPO'] fixes this.
I didn't want to submit a PR in case you already know this and it causes a headache somewhere ... | closed | 2019-10-05T15:07:02Z | 2019-10-23T09:41:20Z | https://github.com/idealo/imagededup/issues/35 | [
"enhancement"
] | drrelyea | 5 |
aeon-toolkit/aeon | scikit-learn | 2,649 | [ENH] Change `HydraTransformer` output | ### Describe the feature or idea you want to propose
`HydraTransformer` currently returns a Tensor. IMO this should be optional, and by default an alternative data structure such as a numpy array, dataframe or dict (if relevant) should be returned.
### Describe your proposed solution
Add a parameter to `HydraTransfo... | open | 2025-03-18T19:21:54Z | 2025-03-18T23:46:27Z | https://github.com/aeon-toolkit/aeon/issues/2649 | [
"enhancement",
"transformations"
] | MatthewMiddlehurst | 1 |
RobertCraigie/prisma-client-py | pydantic | 943 | Not working with non-ASCII paths in Windows | ## Bug description
When working on Windows, using the latest version of the module, neither `prisma generate` throws an error when there's a non-ASCII character in the path ; for example, a grave accent in the name of a folder.
<details>
<summary>Traceback</summary>
```
Traceback (most recent call last):
... | open | 2024-04-26T20:47:55Z | 2024-05-02T22:58:27Z | https://github.com/RobertCraigie/prisma-client-py/issues/943 | [
"bug/1-repro-available",
"kind/bug"
] | Keiishu | 3 |
gradio-app/gradio | machine-learning | 10,178 | Color selection is buggy in gr.ImageEditor (Fine in 5.6.0, but buggy in 5.7.0) | ### Describe the bug
The `ImageEditor` component's `Brush` color selection is not working properly. The following sample is `5.7.0`, but I have also confirmed the same bug in `5.8.0`.
When the bug occurs, I can only draw in black.
There are no changes to the ImageEditor component itself, so is it possible that a cha... | open | 2024-12-11T10:49:46Z | 2025-01-10T17:42:21Z | https://github.com/gradio-app/gradio/issues/10178 | [
"bug",
"Regression",
"🖼️ ImageEditor"
] | John6666cat | 1 |
CorentinJ/Real-Time-Voice-Cloning | deep-learning | 267 | Create a exe? | Is it possible for you to publish a release as an "exe-file"? | closed | 2020-01-23T12:48:28Z | 2021-10-07T05:27:23Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/267 | [] | starinspace | 22 |
taverntesting/tavern | pytest | 356 | Interpolate string into !include path? | Here is common.yaml:
```
---
name: Common test information
description: Information for docker content_service api
variables:
host: "https://api{tavern.env_vars.API_TEST_SERVICE}/api"
author_dir: "../../data/authors"
alias_dir: "../../data/aliases"
```
When I do this:
```
---
test_name: PUT Creat... | closed | 2019-05-15T19:37:23Z | 2019-05-31T00:17:56Z | https://github.com/taverntesting/tavern/issues/356 | [] | pmneve | 3 |
tensorflow/tensor2tensor | deep-learning | 1,660 | ERROR: (gcloud.compute.instances.create) Could not fetch resource: | ### Description
I am getting this error when running the command in **Commands to generate WikisumCommonCrawl**
`python -m tensor2tensor.data_generators.wikisum.parallel_launch \
--num_instances=1000 \
--cpu=1 --mem=2 \
--name=wikisum-cc-refs \
--log_dir=$BUCKET/logs \
--setup_command="pip install te... | closed | 2019-08-13T14:04:22Z | 2019-09-01T12:12:33Z | https://github.com/tensorflow/tensor2tensor/issues/1660 | [] | SKRohit | 1 |
junyanz/pytorch-CycleGAN-and-pix2pix | pytorch | 1,399 | why is batch size =1 given as default? | @junyanz | open | 2022-03-18T15:02:33Z | 2022-11-20T06:42:12Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/1399 | [] | ucalyptus2 | 1 |
ahmedfgad/GeneticAlgorithmPython | numpy | 109 | How to create a custom population? | I want to create a custom population with each chromosome/solution will be a pandas DataFrame. How should I create `initial_population` values and what should be assigned to `gene_type` attribute? | open | 2022-05-12T11:01:14Z | 2023-02-26T18:48:32Z | https://github.com/ahmedfgad/GeneticAlgorithmPython/issues/109 | [
"question"
] | pritam-dey3 | 1 |
pytorch/pytorch | machine-learning | 149,045 | NotImplementedError: aten::_log_softmax_backward_data with SparseCUDA backend | ### 🐛 Describe the bug
```python
class NDPTrainer(Trainer):
def compute_loss(self, model, inputs, return_outputs=False, num_items_in_batch=None):
input_ids = inputs.pop("input_ids")
attention_mask = inputs.pop("attention_mask")
cnt_list = inputs.pop(
"cnt_list"
)
... | open | 2025-03-12T14:47:42Z | 2025-03-13T15:16:44Z | https://github.com/pytorch/pytorch/issues/149045 | [
"module: sparse",
"triaged"
] | rangehow | 1 |
python-security/pyt | flask | 131 | Write tests for `discover_files` in __main__, update CHANGELOG and root README with -r and targets Documentation | Writing tests and documentation are slightly less fun than writing code, but equally as important.
I'm making slides (and might write more nested READMEs) on the weekends, and working on my open PR on Mon/Wed/Fri after work at the moment, I'm excited for whatever is next though :) | closed | 2018-06-23T18:48:22Z | 2018-07-01T19:26:13Z | https://github.com/python-security/pyt/issues/131 | [] | KevinHock | 3 |
django-cms/django-cms | django | 7,743 | [BUG] Plugin duplicate entry for key cms_plugin_path caused be DB collations | <!--
Please fill in each section below, otherwise, your issue will be closed.
This info allows django CMS maintainers to diagnose (and fix!) your issue
as quickly as possible.
-->
## Description
Plugins are randomly getting a duplicate key for path:
```
django.db.utils.IntegrityError: (1062, "Duplicate en... | closed | 2024-01-07T11:35:44Z | 2024-03-14T14:39:28Z | https://github.com/django-cms/django-cms/issues/7743 | [
"priority: high",
"3.11"
] | aacimov | 41 |
nolar/kopf | asyncio | 150 | Reconciling resources | > <a href="https://github.com/klarose"><img align="left" height="50" src="https://avatars1.githubusercontent.com/u/23175939?v=4"></a> An issue by [klarose](https://github.com/klarose) at _2019-07-15 19:38:33+00:00_
> Original URL: https://github.com/zalando-incubator/kopf/issues/150
>
## Expected Behavio... | open | 2020-08-18T19:57:30Z | 2020-08-23T20:47:52Z | https://github.com/nolar/kopf/issues/150 | [
"enhancement",
"archive"
] | kopf-archiver[bot] | 0 |
Yorko/mlcourse.ai | matplotlib | 601 | Some notebooks are not "executed" when visualized on mlcourse.ai | Need to re-run them, ex. topics 6, 7 and 8
https://mlcourse.ai/articles/topic6-features/
https://mlcourse.ai/articles/topic7-unsupervised/
https://mlcourse.ai/articles/topic8-sgd-vw/ | closed | 2019-06-27T14:56:41Z | 2019-07-27T22:48:09Z | https://github.com/Yorko/mlcourse.ai/issues/601 | [] | Yorko | 0 |
ymcui/Chinese-LLaMA-Alpaca | nlp | 189 | 使用LoRA进行训练时,可训练参数规模较小。 | ### 问前必查项目
- [x] 由于相关依赖频繁更新,请确保按照[Wiki](https://github.com/ymcui/Chinese-LLaMA-Alpaca/wiki)中的相关步骤执行
- [x] 我已阅读[FAQ章节](https://github.com/ymcui/Chinese-LLaMA-Alpaca/wiki/常见问题)并且已在Issue中对问题进行了搜索,没有找到相似问题和解决方案
- [x] 第三方插件问题:例如[llama.cpp](https://github.com/ggerganov/llama.cpp)、[text-generation-webui](https://github.c... | closed | 2023-04-20T10:21:31Z | 2023-05-08T02:50:55Z | https://github.com/ymcui/Chinese-LLaMA-Alpaca/issues/189 | [] | yang9112 | 7 |
Gozargah/Marzban | api | 1,671 | API bug in method "add node" | When creating a new node (both via API and via the interface), the specified usage coefficient will not be applicable, but will always be equal to 1.
However, after creating the node, the coefficient can be changed via Node modify method.
Example:
```python
node_data = {
"name": "Some node",
"address": "8.8.... | closed | 2025-02-20T20:16:20Z | 2025-02-21T14:29:56Z | https://github.com/Gozargah/Marzban/issues/1671 | [] | P1nk-L0rD | 3 |
plotly/dash | data-visualization | 2,889 | clarify instructions for contributing to Dash on Windows | I am trying to create my first contribution to Dash. I work on Windows, but the instructions for setting up the environment on Windows are unclear. Furthermore, one of the internal scripts uses `sh` to execute some scripts, making it impossible to run the `npm build first-build` command via `PowerShell` or a `Command P... | closed | 2024-06-17T08:41:57Z | 2024-08-26T11:37:23Z | https://github.com/plotly/dash/issues/2889 | [
"documentation",
"feature",
"P3"
] | aGitForEveryone | 8 |
Zeyi-Lin/HivisionIDPhotos | fastapi | 92 | 如何更改docker启动端口 | closed | 2024-09-10T09:50:12Z | 2024-09-15T19:52:13Z | https://github.com/Zeyi-Lin/HivisionIDPhotos/issues/92 | [] | beiguoxia | 1 | |
CorentinJ/Real-Time-Voice-Cloning | deep-learning | 1,294 | i am not able to understand ho to run that resiporatory | corentinJ can you mention all the steps for linux ubuntu how to run your real time cloning resiporatory
| open | 2024-03-28T12:51:27Z | 2024-04-19T06:16:04Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/1294 | [] | Lakshbansal124 | 1 |
giotto-ai/giotto-tda | scikit-learn | 108 | KNeighborsGraph "available" in scikit-learn 0.22 as KNeighborsTransformer | #### Description
A novelty of scikit-learn 0.22 is the introduction of the [KNeighborsTransformer](https://scikit-learn.org/stable/modules/generated/sklearn.neighbors.KNeighborsTransformer.html), which implements in the case of single point clouds (rather than collections thereof) exactly what we implemented in graphs... | open | 2019-12-10T21:18:19Z | 2020-09-03T15:23:38Z | https://github.com/giotto-ai/giotto-tda/issues/108 | [
"enhancement",
"discussion"
] | ulupo | 2 |
nschloe/tikzplotlib | matplotlib | 537 | Colorbar not exporting correctly | When I try to use tikzplotlib to gert a plot with a colorbar similar to all the tests given in https://github.com/nschloe/tikzplotlib/blob/main/tests/test_colorbars.py it either returns a .tex with no colorbar in it or something that uses an image of a the colorbar that's slightly offset and not correctly scaled. Is th... | open | 2022-02-18T01:02:00Z | 2022-03-03T15:39:19Z | https://github.com/nschloe/tikzplotlib/issues/537 | [] | finnBsch | 1 |
babysor/MockingBird | pytorch | 79 | UnicodeEncodeError: 'cp950' codec can't encode character '\u2f24' in position 153: illegal multibyte sequence | 在執行 `python vocoder_preprocess.py <datasets_root>` 時遇到的錯誤,上網查詢一下發現是編碼問題,請問我可以更改程式裡的哪部分代碼去解決這個問題呢?
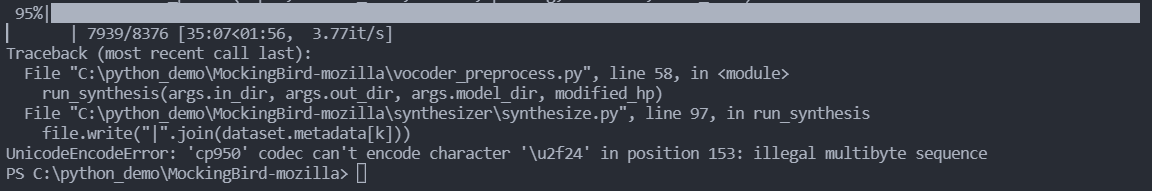
| closed | 2021-09-08T16:08:34Z | 2021-09-09T06:08:09Z | https://github.com/babysor/MockingBird/issues/79 | [] | XiuChen-Liu | 3 |
plotly/dash-table | dash | 406 | DataTable error when combined with dcc.Tabs | I'm getting an error when creating a DataTable in an app that uses tabs. I found a similar issue that was popping up when it was still `dash_table_experiments ` and was able to get a solution to this problem from this [community post](https://community.plot.ly/t/display-tables-in-dash/4707/40). That said, I wasn't cer... | open | 2019-04-02T05:22:00Z | 2020-09-17T19:24:43Z | https://github.com/plotly/dash-table/issues/406 | [
"dash-type-bug",
"dash-stage-backlog",
"size: 2"
] | mbkupfer | 7 |
streamlit/streamlit | data-science | 10,819 | Add a json editor widget | ### Checklist
- [x] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar feature requests.
- [x] I added a descriptive title and summary to this issue.
### Summary
Implement editing functionality for JSON data. The `st.json` command currently only supports viewing JSON dat... | open | 2025-03-18T10:54:28Z | 2025-03-18T10:54:59Z | https://github.com/streamlit/streamlit/issues/10819 | [
"type:enhancement",
"feature:st.json",
"type:possible-component"
] | lukasmasuch | 1 |
lukasmasuch/streamlit-pydantic | pydantic | 7 | Displaying Input Sections in Columns | <!--
Thanks for requesting a feature 🙌 ❤️
Before opening a new issue, please make sure that we do not have any duplicates already open. You can ensure this by searching the issue list for this repository. If there is a duplicate, please close your issue and add a comment to the existing issue instead. Also, be sur... | closed | 2021-08-23T12:10:37Z | 2023-01-17T01:59:03Z | https://github.com/lukasmasuch/streamlit-pydantic/issues/7 | [] | BenediktPrusas | 7 |
dask/dask | numpy | 11,140 | gpuCI failing due to `pytest` warning | `pytest` started emitting a warning on `importorskip` when the library can be found, but raises an error when attempting to import it. We're running into this in gpuCI when attempting to import `cudf`. See, for example, [this gpuCI build](https://gpuci.gpuopenanalytics.com/job/dask/job/dask/job/prb/job/dask-prb/5930/) ... | closed | 2024-05-21T20:37:45Z | 2024-05-23T17:06:09Z | https://github.com/dask/dask/issues/11140 | [
"tests",
"gpu"
] | jrbourbeau | 5 |
PokeAPI/pokeapi | graphql | 322 | Made an example JsFiddle | Didn't really know where to post this so sorry if this is a bad spot (feel free to close the issue). Just thought some people might be interested in this JsFiddle I wrote
https://jsfiddle.net/torcp0r3/8/ | closed | 2018-02-05T15:26:48Z | 2018-02-05T19:10:46Z | https://github.com/PokeAPI/pokeapi/issues/322 | [] | DanLatimer | 1 |
allure-framework/allure-python | pytest | 330 | allure @title | 使用@allure.title("测试") 装饰器时一直提示无title这个属性,当前最新版本是去除了这个属性吗?改成什么了,报告中如图,一堆路径,不好看
| closed | 2018-11-29T01:45:08Z | 2019-01-28T07:19:14Z | https://github.com/allure-framework/allure-python/issues/330 | [] | githublitao | 2 |
ets-labs/python-dependency-injector | flask | 321 | Test example - Parametrize combined with fixtures | This might be more of a python specific question though if there is a different way to connect this it could still be relevant.
**I was looking at this example:**
https://github.com/ets-labs/python-dependency-injector/blob/master/examples/miniapps/flask/githubnavigator/tests.py
```
@pytest.fixture
def app():... | closed | 2020-11-07T07:15:05Z | 2020-11-10T18:17:10Z | https://github.com/ets-labs/python-dependency-injector/issues/321 | [
"question"
] | newtoniumx3 | 3 |
noirbizarre/flask-restplus | flask | 786 | Flatting nested field to array in Flask API | I asked this question on StackOverflow ([here](https://stackoverflow.com/questions/60351530/flatting-nested-field-to-array-in-flask-api)) but didn't get any help there. I'm sure that there is a simple answer to this.
I'm using `flask_restplus` to build an API.
I have two models:
```
model_barcode = api.model(... | open | 2020-03-13T17:05:54Z | 2020-04-18T08:00:44Z | https://github.com/noirbizarre/flask-restplus/issues/786 | [] | datawookie | 1 |
albumentations-team/albumentations | machine-learning | 2,172 | [Feature Request] Add support for obb format for bounding boxes. | Add support for oriented bounding boxes.
https://docs.ultralytics.com/datasets/obb/ | open | 2024-11-29T23:15:19Z | 2024-11-29T23:15:19Z | https://github.com/albumentations-team/albumentations/issues/2172 | [
"enhancement"
] | ternaus | 0 |
piskvorky/gensim | nlp | 3,037 | How does Gensim handling pad index and UNK index in W2V models? | I'm using Gensim for building W2V models and, I didn't find a way for adding a vector for Unkown words or padding parts in Gensim and, I have to do it manually.
I also check the index of 0 in the created embedding and, it is also used for a specific word. This matter could cause a problem for padding words because the... | closed | 2021-01-31T11:30:11Z | 2021-01-31T12:15:38Z | https://github.com/piskvorky/gensim/issues/3037 | [] | FullDataAlchemist | 1 |
lux-org/lux | pandas | 188 | [BUG] Lux read from Pandas dataframe that was retrieved from a SQL database | I see that you are working on enhancing the capabilities of Lux to work with SQL sources. However, the current functionality appears to be limited to some abilities with PostgreSQL. I have observed that if lux is imported but pandas read_SQL is used, a pandas dataframe is instantiated instead of a LuxDataFrame.
Wo... | closed | 2020-12-26T18:55:34Z | 2021-01-09T11:46:55Z | https://github.com/lux-org/lux/issues/188 | [
"bug"
] | compunuke | 4 |
hpcaitech/ColossalAI | deep-learning | 5,768 | [BUG]: Report some errors in test | ### Is there an existing issue for this bug?
- [X] I have searched the existing issues
### 🐛 Describe the bug
1.test_auto_parallel

2.test_analyzer
 given a current clause(3-4 words). Like a seq-seq model. Can anyone help me achieve it using bert? One thing came in my mind is using bert sentence embedding output to LSTMS, any help is appreciated. | open | 2020-10-16T10:23:29Z | 2020-10-16T10:23:29Z | https://github.com/google-research/bert/issues/1160 | [] | SouparnaD | 0 |
ultrafunkamsterdam/undetected-chromedriver | automation | 806 | Works also on Brave Browser and many other Chromium based browsers, some tweaking | Can anyone explain how?
I mean some tweaking could be anything, it's not really that "helpful", thats why I create the issue!
I want to test it with Brave and Microsoft Edge because chrome is very RAM and CPU hungry, | open | 2022-09-03T21:13:49Z | 2025-02-01T20:48:49Z | https://github.com/ultrafunkamsterdam/undetected-chromedriver/issues/806 | [] | ovciina | 4 |
Sanster/IOPaint | pytorch | 311 | [Feature Request] adding an Outpainting option to Lama Cleaner | Lama Cleaner serves me wonderfully.
I would like to suggest adding an Outpainting option to it. This way it will also be possible to expand images and not only work within their framework.
Is this on the to-do list? | open | 2023-05-25T07:12:26Z | 2023-11-14T18:46:38Z | https://github.com/Sanster/IOPaint/issues/311 | [] | ShmuelRonen | 3 |
X-PLUG/MobileAgent | automation | 39 | MobileAgent-v3 怎样引用? | MobileAgent-v3 怎样引用?
这里是引用v2
https://github.com/modelscope/modelscope-agent/blob/master/apps/mobile_agent/run.py
v3 有上面的run.py的demo代码么? | open | 2024-08-01T22:18:14Z | 2024-08-05T03:55:01Z | https://github.com/X-PLUG/MobileAgent/issues/39 | [] | kobeng | 3 |
deezer/spleeter | tensorflow | 91 | only Stem2 working | Successfully installed on a 1-CPU 1G Ram VM, running Ubuntu 19.04.
Ran the example with sample audio file, worked ok.
Uploaded my own audio file (Alison by Elvis Costello, can supply if necessary)
2stem worked ok, 4 and 5 stem failed. Example output shown:
# spleeter separate -i audio_example.mp3 -o output... | closed | 2019-11-14T11:45:59Z | 2019-11-15T08:41:55Z | https://github.com/deezer/spleeter/issues/91 | [
"bug",
"invalid",
"RTMP"
] | waveydavey0 | 2 |
ydataai/ydata-profiling | pandas | 952 | BUGs with pandas-profiling utils package opening and preparing files for ProfileReport() | **Describe the bug**
Error message from a fresh conda environment as suggested on the pandas-profiling documentation:
IndexError: only integers, slices (`:`), ellipsis (`...`), numpy.newaxis (`None`) and integer or boolean arrays are valid indices
The simple website example works...
```
import numpy as n... | closed | 2022-04-10T02:25:32Z | 2022-05-02T02:08:43Z | https://github.com/ydataai/ydata-profiling/issues/952 | [
"bug 🐛"
] | richlysakowski | 4 |
zappa/Zappa | flask | 542 | [Migrated] Pipenv (if desired) | Originally from: https://github.com/Miserlou/Zappa/issues/1435 by [kennethreitz42](https://github.com/kennethreitz42)
Ran the tests, using only the provided `Pipfile.lock` — they mostly passed, so I assume everything is working as intended.
```
Ran 94 tests in 171.589s
FAILED (errors=2)
```
Please dismiss i... | closed | 2021-02-20T12:22:30Z | 2022-07-16T07:13:47Z | https://github.com/zappa/Zappa/issues/542 | [] | jneves | 1 |
modoboa/modoboa | django | 2,719 | Accept-Language header takes precedence over profile language setting | After tinkering with the request headers for a bit, I've found that the `Accept-Language` (if it contains a supported and available translated language) will take precedence over the language actually setup in the modo boa profile.
Removing the header will revert this behaviour, which seems to have been introduced b... | closed | 2022-12-27T19:16:01Z | 2023-02-17T11:27:58Z | https://github.com/modoboa/modoboa/issues/2719 | [
"bug"
] | PatTheMav | 1 |
mirumee/ariadne | graphql | 930 | Purge schema directives misses directives in if no newline | Hello, I'm on the latest ariadne version (0.16) and I'm fairly certain by now that directive support is a bit broken.
Given a schema
```
extend schema @link(url: "https://specs.apollo.dev/federation/v2.0", import: ["@key", "@shareable", "@external"])
directive @banana(format: String) on FIELD_DEFINITION
directi... | closed | 2022-09-19T06:12:16Z | 2022-12-08T17:28:04Z | https://github.com/mirumee/ariadne/issues/930 | [] | Petterhg | 2 |
microsoft/nlp-recipes | nlp | 80 | [BUG] reduce the time of the unit tests | As of now, the unit tests take 25min. We should reduce them | closed | 2019-06-04T11:33:13Z | 2019-07-15T18:46:33Z | https://github.com/microsoft/nlp-recipes/issues/80 | [] | miguelgfierro | 1 |
PokeAPI/pokeapi | graphql | 644 | official_artwork is currently official-artwork | Hi - I was working with the API yesterday and noticed the API began to fail on my end of the application.
I noticed that after going back onto pokeapi.co that the response from a pokemon's official artwork sprite has changed from `official_artwork` to `official-artwork` which was causing the error, not sure if this wa... | closed | 2021-08-25T11:09:15Z | 2021-08-25T14:53:59Z | https://github.com/PokeAPI/pokeapi/issues/644 | [] | OliverHeward | 5 |
nltk/nltk | nlp | 3,027 | Pre commit hook fails | I have setup my development environment as described here: [Setting up a Development Environment](https://github.com/nltk/nltk/blob/develop/CONTRIBUTING.md#setting-up-a-development-environment). This is working so far and I could make changes and tests were running fine. However, when I want to make a commit I get the ... | closed | 2022-07-25T06:37:24Z | 2022-08-01T09:19:21Z | https://github.com/nltk/nltk/issues/3027 | [] | Madnex | 4 |
gradio-app/gradio | machine-learning | 9,866 | File component does not left align in rows in version 5 of Gradio anymore when using scale 0 | ### Describe the bug
In 4.44.1, all components left align in their row.
In 5.x, components _should_ left align in their row. The File component no longer does. See screenshot. Compare the example code in both versions and the bug should be obvious.
I would imagine I could fiddle with the CSS to fix the alignment, ... | closed | 2024-10-29T07:59:58Z | 2024-11-04T17:23:42Z | https://github.com/gradio-app/gradio/issues/9866 | [
"bug"
] | JohnDuncanScott | 0 |
fastapi/sqlmodel | sqlalchemy | 31 | How to deal with Postgres Enum columns? | ### First Check
- [X] I added a very descriptive title to this issue.
- [X] I used the GitHub search to find a similar issue and didn't find it.
- [X] I searched the SQLModel documentation, with the integrated search.
- [X] I already searched in Google "How to X in SQLModel" and didn't find any information.
- [X] I al... | closed | 2021-08-26T09:15:44Z | 2022-09-10T00:13:19Z | https://github.com/fastapi/sqlmodel/issues/31 | [
"question",
"answered"
] | gregsifr | 7 |
lepture/authlib | django | 260 | RFC8414 - Automatically generate the server metadata file | I am not sure if this ticket belongs in github or stackoverflow.
With version `0.14.3` [authlib can load and check](https://docs.authlib.org/en/stable/specs/rfc8414.html) a hand-written oauth-server-metadata file (defined in [RFC8414](https://tools.ietf.org/html/rfc8414)) and let authlib check its validity.
Howev... | open | 2020-08-25T09:10:29Z | 2020-10-14T07:56:16Z | https://github.com/lepture/authlib/issues/260 | [
"server",
"in future"
] | azmeuk | 0 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.