
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
jonaswinkler/paperless-ng | django | 927 | [BUG] Django Python error "date value out of range" | **Describe the bug**
Paperless is not able to consume a specific document. Have roughly imported ~1000 other documents successfully. However this single one stops and produces python error. File is 10 page, 1.2MB pdf with table full of numbers and dates.
**To Reproduce**
Steps to reproduce the behaviour:
1. Place... | closed | 2021-04-17T08:03:28Z | 2021-10-17T20:53:40Z | https://github.com/jonaswinkler/paperless-ng/issues/927 | [] | chris42 | 4 |
graphistry/pygraphistry | jupyter | 620 | [BUG] gfql de-serialization | **Describe the bug**
bug in the gfql de-serialization
**To Reproduce**
Code, including data, than can be run without editing:
```python
from graphistry.compute.chain import Chain
from graphistry import e_undirected, is_in
chain_operations = graphistry.Chain([
e_undirected(hops=1, edge_match={"source":... | closed | 2024-12-18T18:20:07Z | 2024-12-24T05:51:22Z | https://github.com/graphistry/pygraphistry/issues/620 | [
"bug"
] | mj3cheun | 3 |
babysor/MockingBird | pytorch | 517 | 纯小白请教,LOSS到034 | 继续作者75K训练到229
LOSS到034就下不去了
有什么办法吗,现在模型效果还不是很好
问题在哪,应该怎么继续训练? | open | 2022-04-25T02:12:47Z | 2022-04-26T07:12:21Z | https://github.com/babysor/MockingBird/issues/517 | [] | 1239hy | 3 |
piccolo-orm/piccolo | fastapi | 804 | Use path filters in GitHub Actions | If we're just making a minor change to the docs we run all of the unit tests which is time consuming and wasteful.
Using [path filters](https://docs.github.com/en/actions/using-workflows/workflow-syntax-for-github-actions#example-excluding-paths), we can prevent the tests running if only documentation files have cha... | closed | 2023-04-11T14:04:57Z | 2023-04-11T14:58:01Z | https://github.com/piccolo-orm/piccolo/issues/804 | [] | dantownsend | 0 |
pytest-dev/pytest-cov | pytest | 129 | --cov and xdist missing coverage | Running pytest-cov with xdist (`py.test -n auto --cov --cov-report=html`) shows a warning at the end of the test run (`Coverage.py warning: No data was collected`) and reports 26431/73593 covered statements versus running without xdist (`py.test --cov --cov-report=html`) which reports 36879/73593 covered statements.
##... | open | 2016-08-12T17:08:09Z | 2020-11-05T20:17:27Z | https://github.com/pytest-dev/pytest-cov/issues/129 | [] | rouge8 | 31 |
aiortc/aiortc | asyncio | 255 | SDP rfc4145: AIORTC does not support "a=setup" in the session-level section | ```
$ egrep "setup|fingerprint|m=" remoteSDP
a=setup:active
a=fingerprint:sha-256 EF:51:DF:C7:E7:DF:28:BC:AD:2D:CC:C6:6A:00:11:1E:47:CA:FF:99:35:6D:DB:18:D0:18:7D:88:92:D8:14:74
m=audio 57970 RTP/SAVPF 96 0 8
m=video 57970 RTP/SAVPF 99 97
m=video 57970 RTP/SAVPF 99 97
```
```
File "~/.local/lib/python3... | closed | 2020-01-24T03:49:51Z | 2020-02-19T13:34:31Z | https://github.com/aiortc/aiortc/issues/255 | [] | andrews239 | 3 |
hyperspy/hyperspy | data-visualization | 2,605 | Lazy decomposition raises error on mask check | [Noticed by @erh3cq](https://gitter.im/hyperspy/hyperspy?at=5fe024fd63fe0344960c993a)
https://github.com/hyperspy/hyperspy/blob/7bdee7a854a52187a6f78c045184d0d9a783ee51/hyperspy/_signals/lazy.py#L883
The above line should read `if navigation_mask.any() or signal_mask.any()`. There might be more places with a simila... | closed | 2020-12-22T23:21:28Z | 2021-04-20T22:56:40Z | https://github.com/hyperspy/hyperspy/issues/2605 | [
"type: bug",
"good first PR",
"status: fix-submitted"
] | thomasaarholt | 10 |
waditu/tushare | pandas | 1,514 | tushare.pro 网站无法访问 | tushare.pro 网站无法访问,显示502 Bad Gateway,不知道是不是因为在海外访问的原因。 | open | 2021-02-16T00:35:03Z | 2021-02-16T00:35:03Z | https://github.com/waditu/tushare/issues/1514 | [] | cahummus | 0 |
ScottfreeLLC/AlphaPy | pandas | 38 | Error in importing BalanceCascade from imblearn.ensemble | **Describe the bug**
ImportError: cannot import name 'BalanceCascade' from 'imblearn.ensemble' (/opt/conda/lib/python3.7/site-packages/imblearn/ensemble/__init__.py)
**To Reproduce**
Steps to reproduce the behavior:
1. Following instructions from here: https://alphapy.readthedocs.io/en/latest/tutorials/kaggle.htm... | closed | 2020-07-06T08:47:21Z | 2020-08-25T23:48:49Z | https://github.com/ScottfreeLLC/AlphaPy/issues/38 | [
"bug"
] | toko-stephen-leo | 4 |
python-restx/flask-restx | flask | 551 | How do I manually enter the request header Authorization in the Swagger document | **Ask a question**
How do I manually enter the request header Authorization in the Swagger document
**Additional context**
I need the token to carry when verifying the interface
| closed | 2023-07-06T06:19:23Z | 2023-07-11T23:55:44Z | https://github.com/python-restx/flask-restx/issues/551 | [
"question"
] | miaokela | 2 |
pytest-dev/pytest-xdist | pytest | 243 | Add travis cronjob to prevent tests from regressing | Hi,
tests can go stale, especially when not all dependencies etc. are pinned.
To avoid that, it would be sensible to configure a weekly travis (and appveyor?) run on master. | closed | 2017-11-09T16:48:59Z | 2017-11-09T22:30:41Z | https://github.com/pytest-dev/pytest-xdist/issues/243 | [] | criemen | 1 |
tableau/server-client-python | rest-api | 717 | Support for concurrent sessions | Hi,
I'm using the client to refresh multiple extracts via Airflow, the issue is that at a point multiple executions use the client and attempt to refresh an extract. When you sign in to the server, the concurrent run token stops working and then the process fails.
Is there any way to have concurrent server connecti... | open | 2020-11-02T22:56:50Z | 2024-09-20T08:08:52Z | https://github.com/tableau/server-client-python/issues/717 | [
"Server-Side Enhancement",
"docs"
] | gtcourreges | 18 |
LibreTranslate/LibreTranslate | api | 514 | Stack trace during certain translations | ```
[2023-10-09 19:45:09,077] ERROR in app: Exception on /translate [POST]
Traceback (most recent call last):
File "/home/lt/LibreTranslate/.venv/lib/python3.8/site-packages/flask/app.py", line 2525, in wsgi_app
response = self.full_dispatch_request()
File "/home/lt/LibreTranslate/.venv/lib/python3.8/site-... | closed | 2023-10-09T17:45:08Z | 2023-10-10T00:48:04Z | https://github.com/LibreTranslate/LibreTranslate/issues/514 | [
"bug"
] | pierotofy | 0 |
jazzband/django-oauth-toolkit | django | 1,180 | Why Authorization grant type is Authorization code still need with header "Authorization: Basic ${CREDENTIAL}" | I tested django-oauth-toolkit 2.1.0, the **Authorization grant type** is **Authorization code**. and I found out that I have to pass **Authorization header** to get token successfully.
This is a successful request:
<img width="782" alt="1" src="https://user-images.githubusercontent.com/157350/175804023-6137e771-49d... | closed | 2022-06-26T07:23:07Z | 2022-06-26T14:34:09Z | https://github.com/jazzband/django-oauth-toolkit/issues/1180 | [
"question"
] | leench | 2 |
art049/odmantic | pydantic | 304 | [Feature]: Add support for mixing models. | # Feature request
Hey everyone. I recently came across this package and immediately fell in love; In fact, I am using it to build [a pretty damn project](https://github.com/brave-date/brave-date-server). One thing I see is missing and worth adding is the ability to mix multiple models. This is especially useful for ... | open | 2022-11-28T09:50:58Z | 2024-06-27T12:43:13Z | https://github.com/art049/odmantic/issues/304 | [
"enhancement"
] | wiseaidev | 1 |
gto76/python-cheatsheet | python | 107 | Python cheat sheet | closed | 2021-08-29T13:21:37Z | 2022-06-03T02:35:14Z | https://github.com/gto76/python-cheatsheet/issues/107 | [] | AlthafAk | 1 | |
thtrieu/darkflow | tensorflow | 425 | Speed on Titan X | Hi,
What speed can I expect when I run the darkflow YOLOv2 detector with input size 416x416 on Titan X? For me, it is only running at ~30 fps. Is it not supposed to run at 67 fps? Is this normal or am I missing something? I am using yolo-voc.cfg and yolo-voc.weights. | open | 2017-11-10T09:03:11Z | 2018-08-25T09:12:57Z | https://github.com/thtrieu/darkflow/issues/425 | [] | athindran | 13 |
fastapi/sqlmodel | pydantic | 495 | How to reference a foreign key in a table that is in a different (postgres) schema | ### First Check
- [X] I added a very descriptive title to this issue.
- [X] I used the GitHub search to find a similar issue and didn't find it.
- [X] I searched the SQLModel documentation, with the integrated search.
- [X] I already searched in Google "How to X in SQLModel" and didn't find any information.
- [X... | closed | 2022-11-11T11:58:12Z | 2024-04-15T10:15:36Z | https://github.com/fastapi/sqlmodel/issues/495 | [
"question"
] | ivyleavedtoadflax | 4 |
graphql-python/graphene-django | django | 855 | All queries are firing a second request | I'm not totally sure when this problem emerged, but it appears as though Graphene Django is generating a second duplicate request. I'm using Django 3. Here are the steps I've taken to debug:
1. Established that only one http request is sent to my Django server, yet resolvers are fired twice.
2. Set the `graphql` ur... | closed | 2020-01-21T23:53:25Z | 2020-01-29T11:14:47Z | https://github.com/graphql-python/graphene-django/issues/855 | [] | jdgreenberger | 3 |
QingdaoU/OnlineJudge | django | 406 | 容器unhealthy | 阿里云的ubuntu20.04,按照老方法部署的,一开始一切正常,后来就突然oj-backend和judge-server不健康,查看logs看到是nginx报错-1,尝试过多退出。更换机器也是这样,回档就可以健康了。
想问问怎么恢复数据,原来的deploy一拷过去就unhealthy
整机用正常时候的快照回滚了也是unhealthy | open | 2022-03-26T08:13:02Z | 2023-04-30T06:02:04Z | https://github.com/QingdaoU/OnlineJudge/issues/406 | [] | tym2008 | 2 |
stanfordnlp/stanza | nlp | 508 | The Polish mwt model missing but presumably needed | **Describe the bug**
After downloading the Polish (`pl`) model, I try to import it and get the following warning:
```>>> nlp = stanza.Pipeline(lang='pl',
... processors='tokenize,lemma,mwt,pos,depparse')
2020-11-05 09:35:08 WARNING: Can not find mwt: default from official model list. I... | closed | 2020-11-05T07:40:09Z | 2020-11-05T12:16:10Z | https://github.com/stanfordnlp/stanza/issues/508 | [
"bug"
] | macleginn | 2 |
lukas-blecher/LaTeX-OCR | pytorch | 333 | Could not initialize NNPACK! Reason: Unsupported hardware. | + I use pix2tex in my Ubuntu server with cli
```
pix2tex --no-cuda LaTeX\ Equation.png
[W NNPACK.cpp:64] Could not initialize NNPACK! Reason: Unsupported hardware.
[1] 1336 killed... | open | 2023-11-01T01:19:39Z | 2023-11-01T01:19:39Z | https://github.com/lukas-blecher/LaTeX-OCR/issues/333 | [] | xbunax | 0 |
WeblateOrg/weblate | django | 14,114 | Link the `Browse glossary %(name)s` button of the `Glossary` panel to the browse page | ### Describe the problem
Currently, the `Browse glossary %(name)s` button in the upper right corner of the `Glossary` panel in the full editor links to the component page of the corresponding glossary. It’s a bit confusing that users still have to navigate to the language themselves now that they’ve selected the langu... | closed | 2025-03-05T10:32:38Z | 2025-03-10T09:59:17Z | https://github.com/WeblateOrg/weblate/issues/14114 | [
"enhancement",
"Area: UX"
] | Geeyun-JY3 | 1 |
graphdeco-inria/gaussian-splatting | computer-vision | 944 | missing 1 required positional argument: 'projmatrix_raw' | I have installed diff-gaussian-rasterization and simple-knn under the submodules folder, but I still encounter errors when running
Loading Test Cameras [25/08 11:35:05]
Number of points at initialisation : 28332 [25/08 11:35:05]
Training progress: 0%| ... | open | 2024-08-25T03:40:55Z | 2024-08-25T03:40:55Z | https://github.com/graphdeco-inria/gaussian-splatting/issues/944 | [] | yemiaoxuan | 0 |
google-deepmind/graph_nets | tensorflow | 3 | no module name tensorflow_probability | import graph_nets as gp
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
File "/home/bhanuteja/anaconda3/lib/python3.6/site-packages/graph_nets/__init__.py", line 21, in <module>
from graph_nets import blocks
File "/home/desktopname/anaconda3/lib/python3.6/site-packages/graph_nets/... | closed | 2018-10-19T17:00:05Z | 2019-03-10T10:04:36Z | https://github.com/google-deepmind/graph_nets/issues/3 | [
"bug"
] | devbhanu | 6 |
onnx/onnx | deep-learning | 6,646 | bfloat16 to numpy conversion ignores raw_data | # Bug Report
### Description
When a bfloat16 tensor is converted into a `numpy.ndarray`, its `raw_data` contents is not loaded.
### System information
Ubuntu 22.04.3
ONNX version: 1.16.1, 1.17.0
Python version: 3.10.12
PyTorch version: 2.5.1
### Reproduction instructions
A program to generate the model (attached in ... | closed | 2025-01-20T13:31:55Z | 2025-01-28T01:57:03Z | https://github.com/onnx/onnx/issues/6646 | [
"bug"
] | aparpara | 2 |
microsoft/MMdnn | tensorflow | 490 | Fail to convert a TF model to caffe2 or Pytorch | Platform (like ubuntu 16.04/win10): Ubuntu 16.04
Python version: Python 3.5.5
Source framework with version (like Tensorflow 1.4.1 with GPU): Tensorflow 1.10.1 with GPU
Destination framework with version (like CNTK 2.3 with GPU): Caffe2 with CPU / Pytorch 0.4.1 with GPU
Pre-trained model path (webpath or we... | open | 2018-11-06T23:29:36Z | 2020-04-13T08:52:26Z | https://github.com/microsoft/MMdnn/issues/490 | [] | bwang482 | 7 |
Lightning-AI/LitServe | fastapi | 196 | Add support for `response_format` in OpenAI Spec | ## 🚀 Feature
Add support for `response_format` in OpenAI Spec
<!-- A clear and concise description of the feature proposal -->
### Motivation
- [Structured Outputs](https://openai.com/index/introducing-structured-outputs-in-the-api/)
<!-- Please outline the motivation for the proposal. Is your feature request r... | closed | 2024-08-07T06:29:33Z | 2024-08-14T21:40:34Z | https://github.com/Lightning-AI/LitServe/issues/196 | [
"enhancement",
"help wanted"
] | bhimrazy | 2 |
tatsu-lab/stanford_alpaca | deep-learning | 173 | Anyone fine tuned successfully on 1 or 2 GPUs? | I cannot start running the train.py script (on 2 x 4090 gpu)
Got this error:
File ".../alp/lib/python3.10/site-packages/transformers/hf_argparser.py", line 341, in parse_args_into_dataclasses
raise ValueError(f"Some specified arguments are not used by the HfArgumentParser: {remaining_args}")
ValueError: Some ... | closed | 2023-04-02T21:06:51Z | 2023-04-29T18:28:45Z | https://github.com/tatsu-lab/stanford_alpaca/issues/173 | [] | weiddeng | 4 |
fugue-project/fugue | pandas | 343 | Does this require pandas to be installed on cluster nodes? | The docs are extremely obscure, but seem to claim both that pandas functions will run "on spark", but also that pandas will be applied to partitions of data.
So is a function that uses pandas converted to a spark equivalent, or does pandas still execute on cluster nodes?
Getting pandas installed across a spark cluste... | closed | 2022-07-27T01:44:46Z | 2022-08-16T01:02:39Z | https://github.com/fugue-project/fugue/issues/343 | [] | cyberfox1 | 3 |
microsoft/nni | tensorflow | 5,759 | Shivam | **Describe the bug**:
**Environment**:
- NNI version:
- Training service (local|remote|pai|aml|etc):
- Python version:
- PyTorch version:
- Cpu or cuda version:
**Reproduce the problem**
- Code|Example:
- How to reproduce: | open | 2024-03-19T13:07:51Z | 2024-03-19T13:07:51Z | https://github.com/microsoft/nni/issues/5759 | [] | shivaay9673 | 0 |
graphql-python/graphene-django | django | 771 | Support Django 3 | `from django.utils import six` has been removed in Django version 3.
https://github.com/graphql-python/graphene-django/blob/master/graphene_django/settings.py#L18 | closed | 2019-09-10T16:16:27Z | 2019-10-19T19:34:55Z | https://github.com/graphql-python/graphene-django/issues/771 | [] | Siecje | 2 |
jmcnamara/XlsxWriter | pandas | 231 | Typo in 0.6.7 Documentation | P221:
```
worksheet.add_table('B3:F7', {'data' data}),
```
Should read
```
worksheet.add_table('B3:F7', {'data' : data})
```
| closed | 2015-03-18T08:40:39Z | 2015-03-18T19:48:52Z | https://github.com/jmcnamara/XlsxWriter/issues/231 | [
"documentation"
] | SimonHarrisonSH | 2 |
gee-community/geemap | jupyter | 623 | Not getting same interactive map as showing tutorial video | I am getting as given via code
Map = geemap.Map()
Map
we did not get inspector and other tools on map thats why facing problem in adding layers
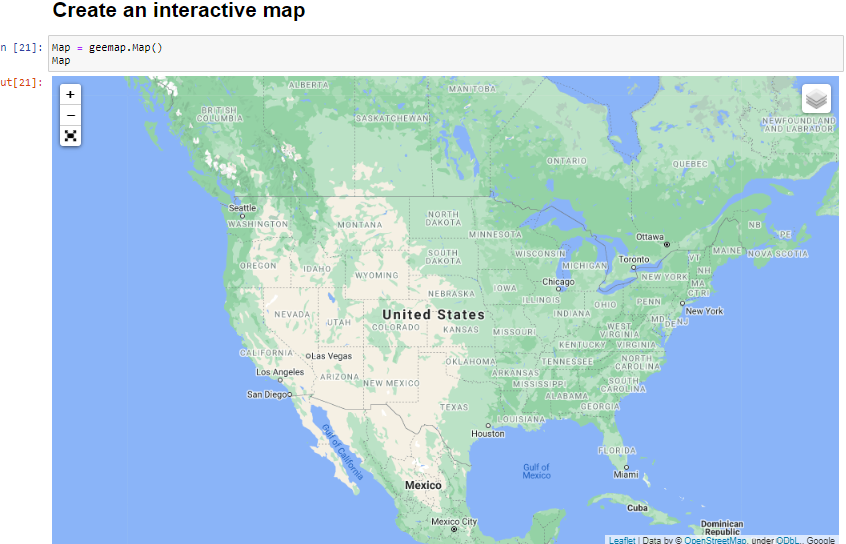
video tutorial show as given
, a one pass stable algorithm, see [here](https://githu... | closed | 2015-03-19T23:23:36Z | 2016-03-23T18:04:44Z | https://github.com/pydata/bottleneck/issues/99 | [] | jaimefrio | 6 |
scrapy/scrapy | web-scraping | 6,640 | FEEDS Exports - cannot output multiple feeds from the same item | ### Description
Cannot output multiple FEEDS for a single item despite the [documentation](https://docs.scrapy.org/en/latest/topics/feed-exports.html#feeds) stating that FEEDS Export supports multiple URI paths per item.
### Steps to Reproduce
1. Run a spider with the following `settings.py` configuration
```
from p... | closed | 2025-01-30T13:19:00Z | 2025-01-30T14:11:27Z | https://github.com/scrapy/scrapy/issues/6640 | [] | kirby-jack | 3 |
ymcui/Chinese-LLaMA-Alpaca-2 | nlp | 334 | 如何并发 同时处理多个用户的会话 | ### 提交前必须检查以下项目
- [X] 请确保使用的是仓库最新代码(git pull),一些问题已被解决和修复。
- [X] 我已阅读[项目文档](https://github.com/ymcui/Chinese-LLaMA-Alpaca-2/wiki)和[FAQ章节](https://github.com/ymcui/Chinese-LLaMA-Alpaca-2/wiki/常见问题)并且已在Issue中对问题进行了搜索,没有找到相似问题和解决方案。
- [X] 第三方插件问题:例如[llama.cpp](https://github.com/ggerganov/llama.cpp)、[LangChain](https://g... | closed | 2023-10-11T08:11:12Z | 2023-11-03T22:04:33Z | https://github.com/ymcui/Chinese-LLaMA-Alpaca-2/issues/334 | [
"stale"
] | zhuyetuo | 3 |
pytest-dev/pytest-flask | pytest | 92 | client.post json doesn't work | Take the official flask doc example: http://flask.pocoo.org/docs/1.0/testing/#testing-json-apis
This works:
```python
with app.test_client() as c:
rv = c.post('/', json={'username': 'flask', 'password': 'secret'})
assert rv.status_code == 200
```
but this with pytest flask client fixture doesn't:... | closed | 2018-12-12T17:38:55Z | 2020-10-19T23:03:31Z | https://github.com/pytest-dev/pytest-flask/issues/92 | [
"waiting",
"needs more info"
] | ailisp | 4 |
dask/dask | scikit-learn | 11,585 | dask.array buggy with pandas multiindex.values / object dtype arrays | <!-- Please include a self-contained copy-pastable example that generates the issue if possible.
Please be concise with code posted. See guidelines below on how to provide a good bug report:
- Craft Minimal Bug Reports http://matthewrocklin.com/blog/work/2018/02/28/minimal-bug-reports
- Minimal Complete Verifiab... | open | 2024-12-05T16:55:49Z | 2025-02-24T02:01:25Z | https://github.com/dask/dask/issues/11585 | [
"array",
"needs attention"
] | dcherian | 9 |
ultralytics/ultralytics | python | 19,529 | Inconsistent Results in Yolov8 prediction | @glenn-jocher
I am training YOLOv8 models on my dataset, and the performance metrics indicate good results. The model generally predicts all objects correctly. However, for certain samples, the model sometimes detects all bounding boxes, and in some cases, it fails to detect all when the same sample is reprocessed.
I... | open | 2025-03-05T07:49:40Z | 2025-03-05T09:00:59Z | https://github.com/ultralytics/ultralytics/issues/19529 | [
"question",
"detect"
] | DANISHFAYAZNAJAR | 4 |
viewflow/viewflow | django | 428 | Radio Buttons don't seem to work in the free plan | Using a forms.RadioSelect() inside a form does not render the radio buttons.
The Server side renders the vf-field-radio-select tag, but seems like the element is not configured in the frontend? | closed | 2024-03-12T06:18:49Z | 2024-03-13T09:13:21Z | https://github.com/viewflow/viewflow/issues/428 | [
"request/bug"
] | simonavril | 1 |
roboflow/supervision | deep-learning | 1,401 | "Failed to create CUDAExecutionProvider" onnxruntime error on Google Colab | ### Search before asking
- [X] I have searched the Supervision [issues](https://github.com/roboflow/supervision/issues) and found no similar feature requests.
### Question
Really appreciate this library and ecosystem!
I'm trying to run the "time_in_zone" example on Google Colab (CUDAExecutionProvider). I pip ins... | closed | 2024-07-25T04:36:07Z | 2024-07-25T09:27:42Z | https://github.com/roboflow/supervision/issues/1401 | [
"question"
] | hkhare42 | 2 |
piskvorky/gensim | data-science | 2,842 | KeyedVectors importing keras instead of tensorflow.keras? | Hello there,
I got a super quick question regarding the function `get_keras_embeddings` of KeyedVectors.py. Is there a reason behind requiring keras package to be installed (specifically referring to [these lines](https://github.com/RaRe-Technologies/gensim/blob/2360459e0014f5db8fc587005933a6399efab435/gensim/models... | closed | 2020-05-16T21:13:49Z | 2020-09-10T02:20:20Z | https://github.com/piskvorky/gensim/issues/2842 | [] | vrmpx | 3 |
pallets-eco/flask-sqlalchemy | sqlalchemy | 1,117 | `KeyError` at `options["url"]` when using `SQLALCHEMY_BINDS` but not `SQLALCHEMY_DATABASE_URI` | Quick traceback:
```
File ".../python3.10/site-packages/flask_sqlalchemy/extension.py", line 314, in init_app
self._apply_driver_defaults(options, app)
File ".../python3.10/site-packages/flask_sqlalchemy/extension.py", line 543, in _apply_driver_defaults
url = sa.engine.make_url(options["url"])
KeyError... | closed | 2022-10-08T00:10:22Z | 2022-10-26T01:43:09Z | https://github.com/pallets-eco/flask-sqlalchemy/issues/1117 | [] | tgross35 | 0 |
seleniumbase/SeleniumBase | web-scraping | 3,257 | AttributeError: 'WebDriver' object has no attribute 'is_cdp_mode_active' (when overriding the driver) | ### AttributeError: 'WebDriver' object has no attribute 'is_cdp_mode_active' (when overriding the driver)
----
This could happen when using one of the [Syntax Formats](https://github.com/seleniumbase/SeleniumBase/blob/master/help_docs/syntax_formats.md) that overrides the `driver`.
This isn't likely to occur b... | closed | 2024-11-14T01:39:33Z | 2024-11-14T21:43:55Z | https://github.com/seleniumbase/SeleniumBase/issues/3257 | [
"bug"
] | mdmintz | 1 |
django-cms/django-cms | django | 7,220 | [BUG] Toolbar issue when on a custom page - structure mode empty when CMS page with the same slug exists. | ## Description
When on a custom App (say /my-url/) with static placeholders, all works fine UNTIL there is a CMS page with a slug matching the custom app is created. Then, structure mode comes up empty.
## Steps to reproduce
1. Create a custom app that uses custom placeholders
2. Test out they work correctly
... | closed | 2022-02-08T09:29:44Z | 2022-09-23T13:18:07Z | https://github.com/django-cms/django-cms/issues/7220 | [] | petrklus | 5 |
microsoft/nlp-recipes | nlp | 65 | [Util] PyTorch data loaders and samplers | add data loading and sampling functionality to be used for PyTorch model training/testing. | closed | 2019-05-22T03:27:18Z | 2019-08-02T12:00:47Z | https://github.com/microsoft/nlp-recipes/issues/65 | [
"util"
] | saidbleik | 4 |
aleju/imgaug | machine-learning | 53 | Generalization : `np.uint8, [0-255]` -> any dtype, range | Hi,
Is it difficult to generalize image augmentations without the restrictions of `np.uint8` and 0-255 ?
I saw in the code that there are some augmentations that have a hard-coded np.clip and astype `np.uint8`.
I started locally to modify test.py to launch tests on float32 data, however tests are not exaustive...... | closed | 2017-08-09T11:30:40Z | 2017-10-19T22:25:37Z | https://github.com/aleju/imgaug/issues/53 | [] | vfdev-5 | 4 |
strawberry-graphql/strawberry | django | 3,424 | Docs re-structure | This is a draft for a better structure for the docs, feel free to come up with suggestions:
1. Getting Started
- Installation
- Editor Setup
- Hello world
2. Core concepts
- ... | open | 2024-03-27T12:56:47Z | 2025-03-20T15:56:39Z | https://github.com/strawberry-graphql/strawberry/issues/3424 | [
"area: docs"
] | patrick91 | 1 |
roboflow/supervision | tensorflow | 1,284 | yolov5 instance segmentation inference | ### Search before asking
- [X] I have searched the Supervision [issues](https://github.com/roboflow/supervision/issues) and found no similar feature requests.
### Description
yolov5 is a detection and 'instance segmentation' model.
so, I think If there is a mask area, I think it should be return.
like below
... | open | 2024-06-16T13:56:14Z | 2024-08-06T07:50:25Z | https://github.com/roboflow/supervision/issues/1284 | [
"enhancement"
] | DrawingProcess | 15 |
BayesWitnesses/m2cgen | scikit-learn | 99 | Support for LightGBM Booster and XGBoost Booster | We're training our LightGBM model outside of python (spark) so we need to load it from a model file before passing it to m2c. I don't believe LightGBM can load directly into `LGBMRegressor` though, it must be loaded into lgb.Booster.
It would be nice if m2cgen supported lgb.Booster
Example
```py
import ligh... | open | 2019-09-27T14:35:01Z | 2023-02-13T13:51:16Z | https://github.com/BayesWitnesses/m2cgen/issues/99 | [
"help wanted"
] | chris-smith-zocdoc | 13 |
microsoft/nni | machine-learning | 5,623 | this is my configlist,i have determined the names of conv modules to be pruned,but it will still prune other conv modules which are not in the op_names list.Why? | config_list = [{
'sparsity': 0.6,
'op_types':['Conv2d'],
'op_names':['conv1',
'layer1.0.conv1.0','layer1.0.conv2.pwconv','layer1.0.conv3.0','layer1.0.downsample.0',
'layer1.1.conv1.0','layer1.1.conv2.pwconv','layer1.1.conv3.0',
'layer1.2.conv1.0','laye... | open | 2023-06-28T14:20:08Z | 2023-06-30T02:37:40Z | https://github.com/microsoft/nni/issues/5623 | [] | yang-ming-uc | 0 |
huggingface/transformers | nlp | 36,651 | Marian RNN conversion support | ### Feature request
Add support for converting Marian Transformer RNN models.
### Motivation
Firefox is doing great work at training new models. Their teacher models are able to be converted to PyTorch models using [existing conversion tooling](https://github.com/huggingface/transformers/blob/main/src/transformers/m... | open | 2025-03-11T22:48:08Z | 2025-03-19T20:44:09Z | https://github.com/huggingface/transformers/issues/36651 | [
"Feature request"
] | FricoRico | 6 |
browser-use/browser-use | python | 568 | Email text input field not clickable | ### Bug Description
When writing an email in Hubspot, the text field for the body of the email is not detected. This leads to the agent clicking somewhere random, supposedly typing and then sending the email without text. I can see the input is detected [Vimium C](https://chromewebstore.google.com/detail/vimium-c-all-... | open | 2025-02-05T09:38:09Z | 2025-02-12T20:28:20Z | https://github.com/browser-use/browser-use/issues/568 | [
"bug"
] | ChrisjanWust | 1 |
luispedro/mahotas | numpy | 15 | Make mahotas work on Python 2.6 to 3.3 without 2to3 | Looking at the output of 2to3, the mahotas code could be made compatible with Python 2.6 to 3.3 with few changes. Most changes are xrange->range. A few import, print and raise statements need to be updated.
This patch works for me on win-amd64, Python 2.6 to 3.3. I could work on a pull request later if there is inter... | closed | 2012-09-01T18:15:46Z | 2012-10-17T08:38:01Z | https://github.com/luispedro/mahotas/issues/15 | [] | cgohlke | 3 |
ivy-llc/ivy | pytorch | 28,120 | Fix Frontend Failing Test: torch - tensor.torch.Tensor.unique | #27498 | closed | 2024-01-30T11:55:50Z | 2024-02-14T08:20:41Z | https://github.com/ivy-llc/ivy/issues/28120 | [
"Sub Task"
] | ogbanugot | 0 |
psf/black | python | 4,540 | Speed up `blib2to3` tokenization using generic python function | **Describe the bug**
`is_fstring_start` using `builtin.any` for prefix matching is too slow and slows down fstring tokenization.
```python
def is_fstring_start(token: str) -> bool:
return builtins.any(token.startswith(prefix) for prefix in fstring_prefix) # using `any` with `<genexpr>` is too slow
```
*... | closed | 2024-12-28T16:23:32Z | 2024-12-30T01:17:51Z | https://github.com/psf/black/issues/4540 | [
"T: bug"
] | moogician | 2 |
horovod/horovod | tensorflow | 4,015 | Stop specific worker in Horovod Elastic | Hi there,
After reading the code and document, I found that there is no design for stopping a specific worker when applying the Horovod Elastic (e.g., when the number of available workers decreases from 4 to 3, I want to stop the worker of rank 1). Is it possible to do so? Code intrusion for user code is ok. | open | 2024-01-08T11:38:04Z | 2024-01-08T11:38:04Z | https://github.com/horovod/horovod/issues/4015 | [
"enhancement"
] | mozizhao | 0 |
ray-project/ray | deep-learning | 51,276 | [core][gpu-objects] Support collective operations | ### Description
Support collective operations of GPU objects such as gather / scatter / all-reduce.
### Use case
_No response_ | open | 2025-03-11T22:43:35Z | 2025-03-11T22:43:51Z | https://github.com/ray-project/ray/issues/51276 | [
"enhancement",
"P2",
"core",
"gpu-objects"
] | kevin85421 | 0 |
gradio-app/gradio | data-visualization | 10,093 | HTTP 307 temporary redirect code not considered OK | ### Describe the bug
HTTP Code `302` is listed in the acceptable HTTP codes for `url_ok`; however, alternative temporary redirect codes `303` and `307` are not included in the list.
https://github.com/gradio-app/gradio/blob/01b919f04b69732fd8adb52f6d156e5683589221/gradio/networking.py#L51-L62
MDN Docs for the ... | closed | 2024-12-02T21:39:32Z | 2024-12-02T22:24:04Z | https://github.com/gradio-app/gradio/issues/10093 | [
"bug"
] | sharon-wang | 0 |
httpie/cli | api | 537 | Collections in httpie? | I'm regular user of Postman, I have there lot of requests in structured collections, is there any recommended option how to store or create 'book' of requests for each project?
Thanks! | open | 2016-11-10T14:47:01Z | 2017-06-27T05:23:32Z | https://github.com/httpie/cli/issues/537 | [] | yangwao | 6 |
dgtlmoon/changedetection.io | web-scraping | 2,254 | [feature] Extract html attribute and make it available as a token for notification | **Version and OS**
0.45.16 on Debian 12 (LXC in Proxmox)
**Is your feature request related to a problem? Please describe.**
No
**Describe the solution you'd like**
When a change is detected, retrieve a specific attribute value given the xpath of the HTML element. Make this value accessible as a token to includ... | open | 2024-03-14T02:05:33Z | 2024-07-12T09:34:58Z | https://github.com/dgtlmoon/changedetection.io/issues/2254 | [
"enhancement"
] | remz1337 | 8 |
amidaware/tacticalrmm | django | 1,652 | Public URL for Linux Deployment | **Is your feature request related to a problem? Please describe.**
Installing the Linux agent requires moving a file to the host I want to deploy. Sometimes I don't have direct access, only a web-ssh or some other means.
**Describe the solution you'd like**
I would like a URL that can be downloaded via either ... | open | 2023-10-13T17:26:25Z | 2023-11-10T18:05:18Z | https://github.com/amidaware/tacticalrmm/issues/1652 | [
"enhancement"
] | jesse2point0 | 0 |
allure-framework/allure-python | pytest | 289 | allure-behave throws FileNotFoundError for 'allure-results\\94b60d9b-8ba2-444b-b8e3-60ea7a1a9dc5-result.json' | Hi I executed my program with command line behave -f allure_behave.formatter:AllureFormatter -o allure_results ./features.
But an error occurred says "_File "C:\Python 3.5\lib\site-packages\allure_commons\logger.py", line 30, in report_item
with io.open(os.path.join(self.__report_dir, filename), 'w', encoding='ut... | closed | 2018-09-05T02:24:23Z | 2019-04-29T08:14:07Z | https://github.com/allure-framework/allure-python/issues/289 | [] | NancyZhangCR | 4 |
deezer/spleeter | deep-learning | 136 | Can't find spleeter | git clone https://github.com/Deezer/spleeter
conda install -c conda-forge spleeter
spleeter separate -i spleeter/audio_example.mp3 -p spleeter:2stems -o output
zsh: command not found: spleeter
The install looked good. What am I missing. | closed | 2019-11-25T07:48:25Z | 2019-11-25T14:23:02Z | https://github.com/deezer/spleeter/issues/136 | [
"bug",
"invalid",
"wontfix"
] | kimaldis | 1 |
keras-rl/keras-rl | tensorflow | 221 | Interfaces for Two Models Fighting against Each Other | There are scenes where two players are involved, and when implementing Environments, we should update the Game (or something else) according to which player is acting. Now the interfaces don't provide such operations... | closed | 2018-07-06T10:52:15Z | 2019-02-10T05:32:22Z | https://github.com/keras-rl/keras-rl/issues/221 | [
"wontfix"
] | eliphatfs | 6 |
exaloop/codon | numpy | 601 | @overlay doesn't play nicely with None | ```python
@overload
def f1(o: NoneType) -> str:
return 'None'
@overload
def f1(o: int) -> str:
return type(o).__name__
@overload
def f1(o: str) -> str:
return type(o).__name__
print(f1(''))
print(f1(0))
print(f1(None))
```
Will fail with `optional is None`. I've found workaround:
```python
@... | closed | 2024-10-23T09:33:42Z | 2025-03-05T20:16:31Z | https://github.com/exaloop/codon/issues/601 | [
"bug"
] | pyhedgehog | 1 |
google-research/bert | nlp | 1,359 | fix | ERROR: type should be string, got "\r\nhttps://github.com/WongKinYiu/yolov7/blob/a4724d55924708b4cee0dacbc875545b4b3abe3f/utils/plots.py#L436\r\n\r\n\r\n```python\r\n# utils/plots.py #L436-L444\r\ndef output_to_keypoint(output):\r\n # Convert model output to target format [batch_id, class_id, x, y, w, h, conf]\r\n targets = []\r\n for i, o in enumerate(output):\r\n kpts = o[:,6:]\r\n o = o[:,:6]\r\n for index, (*box, conf, cls) in enumerate(o.cpu().numpy()):\r\n targets.append([i, cls, *list(*xyxy2xywh(np.array(box)[None])),\r\n conf, *list(kpts.detach().cpu().numpy()[index])])\r\n return np.array(targets)\r\n\r\n```" | open | 2022-08-05T07:51:39Z | 2022-08-05T07:51:39Z | https://github.com/google-research/bert/issues/1359 | [] | meiqicheng | 0 |
mirumee/ariadne | graphql | 578 | on_disconnect websocket handler is not called for all possible disconnects | Currently `on_disonnect` callback is only called while handling `GQL_CONNECTION_TERMINATE` message, but the websocket can be disconnected in other places:
- exception in `handle_websocket_connection_init_message`
- on WebSocketDisconnect in `websocket_server`
Calling on_disconnect in those cases would be very usef... | closed | 2021-05-11T15:46:04Z | 2022-04-12T07:51:32Z | https://github.com/mirumee/ariadne/issues/578 | [
"enhancement",
"help wanted",
"roadmap"
] | martonilles | 6 |
aidlearning/AidLearning-FrameWork | jupyter | 57 | “Segmentation fault” when running commands like “apt update”, “dpkg -i test.deb” | Android Device: Xiaomi 6
Android Version: Android 9 (LineageOS 16.0-20191002-NIGHTLY-sagit)
AidLearning Version: 0.76 (aidlux-09-04.apk)
“Segmentation fault” when trying installing some packages.
Believing this may have something to do with Magisk (To root my device I installed Magisk 19.3 after flashing LineageO... | closed | 2019-10-03T09:00:25Z | 2020-07-29T01:22:55Z | https://github.com/aidlearning/AidLearning-FrameWork/issues/57 | [] | yusanshi | 7 |
huggingface/transformers | pytorch | 36,747 | text-to-video_app | please and thank you?🤗
from transformers import AutoModel
```
#35885
``` | closed | 2025-03-16T06:32:27Z | 2025-03-19T13:50:05Z | https://github.com/huggingface/transformers/issues/36747 | [] | Ninjadeveloper007 | 1 |
ibis-project/ibis | pandas | 10,082 | feat(duckdb): restore or add new method for consuming `pyarrow.dataset` | In #9666 we deprecated the `read_in_memory` method on the DuckDB backend in favor of creating a `memtable` or passing an object directly to `create_table`.
This does leave out `pyarrow.dataset.Dataset`s, which we previously supported via `read_in_memory`. They have a `to_table()` method, but materializing them may ... | closed | 2024-09-10T19:28:43Z | 2024-09-26T10:30:44Z | https://github.com/ibis-project/ibis/issues/10082 | [
"duckdb"
] | gforsyth | 8 |
quasarstream/python-ffmpeg-video-streaming | dash | 50 | custom video representations | **Is your feature request related to a problem? Please describe.**
A clear and concise description of what the problem is. Ex. I'm always frustrated when [...]
**Describe the solution you'd like**
A clear and concise description of what you want to happen.
**Describe alternatives you've considered**
A clear an... | closed | 2020-12-31T04:28:04Z | 2021-03-20T12:33:10Z | https://github.com/quasarstream/python-ffmpeg-video-streaming/issues/50 | [] | markmenezesmm | 2 |
Lightning-AI/pytorch-lightning | deep-learning | 20,614 | Allow max batch size in BatchSizeFinder | ### Description & Motivation
It would be good to be able to configure a maximum batch size for the batch size finder search (both "power" mode and "binsearch" mode) such that when they exceed the limit, the search stops and the result is set to that configured maximum.
For me, this is very useful when training my tran... | open | 2025-03-03T20:46:59Z | 2025-03-03T21:51:13Z | https://github.com/Lightning-AI/pytorch-lightning/issues/20614 | [
"feature",
"needs triage"
] | rmeno12 | 1 |
plotly/dash-component-boilerplate | dash | 12 | TypeError: Cannot read property 'properties' of undefined | Walking through the README from top to bottom, I hit an error with `npm run build:js-dev`:
```
> my-dash-component@0.0.1 build:js-dev /Users/nicolas/plotly/dash-component-boilerplate
> webpack --mode development
/Users/nicolas/plotly/dash-component-boilerplate/node_modules/webpack-cli/bin/config-yargs.js:89
... | closed | 2018-09-26T19:29:43Z | 2021-01-12T09:20:41Z | https://github.com/plotly/dash-component-boilerplate/issues/12 | [] | nicolaskruchten | 9 |
harry0703/MoneyPrinterTurbo | automation | 23 | 提示这个 | NotFoundError: Error code: 404 - {'error': {'message': 'The model gpt-4-turbo-preview does not exist or you do not have access to it. Learn more: https://help.openai.com/en/articles/7102672-how-can-i-access-gpt-4.', 'type': 'invalid_request_error', 'param': None, 'code': 'model_not_found'}}
Traceback:
File "G:\Users\... | closed | 2024-03-18T11:30:32Z | 2024-03-18T11:57:56Z | https://github.com/harry0703/MoneyPrinterTurbo/issues/23 | [] | 125540947 | 1 |
explosion/spaCy | data-science | 12,813 | Spacy Debugger 's log gives different results from Assemble in spacy-llm | ### Discussed in https://github.com/explosion/spaCy/discussions/12812
<div type='discussions-op-text'>
<sup>Originally posted by **innocent-charles** July 10, 2023</sup>
Hello ! i need assistance on spacy-llm. when I use it with GPT-3.5, if the same entity.text is already extracted it won't shown or extracted ag... | closed | 2023-07-10T17:31:57Z | 2023-08-11T00:02:08Z | https://github.com/explosion/spaCy/issues/12813 | [
"duplicate"
] | innocent-charles | 2 |
huggingface/datasets | numpy | 7,373 | Excessive RAM Usage After Dataset Concatenation concatenate_datasets | ### Describe the bug
When loading a dataset from disk, concatenating it, and starting the training process, the RAM usage progressively increases until the kernel terminates the process due to excessive memory consumption.
https://github.com/huggingface/datasets/issues/2276
### Steps to reproduce the bug
```
rom da... | open | 2025-01-16T16:33:10Z | 2025-01-17T08:05:22Z | https://github.com/huggingface/datasets/issues/7373 | [] | sam-hey | 1 |
recommenders-team/recommenders | data-science | 2,024 | [BUG] ImplicitCF failing if not using stratified split | ### Description
ImplicitCF raises an `IndexError` if the user appears in the test dataset but not on the training dataset.
### How do we replicate the issue?
Split a dataset using a method like TimeSeriesSplit or python_chrono_split. I.e: `len(ImplicitCF.interact_status) < len(ImplicitCF.user_idx)`
### Expect... | closed | 2023-10-18T16:52:20Z | 2024-07-23T09:54:31Z | https://github.com/recommenders-team/recommenders/issues/2024 | [
"bug"
] | daviddavo | 8 |
TencentARC/GFPGAN | deep-learning | 27 | using my own pretrained stylegan2 network | Hello :)
Thank you very much for your repo. I got a lot of beatiful photos. :))))
I try to use my own pretrained stylegan from official repo
https://github.com/NVlabs/stylegan2
But I cannot understand how I should use pkl-file, that I have.
I convert it to pt-file by
https://github.com/dvschultz/ai/blob/ma... | closed | 2021-07-27T18:25:29Z | 2021-12-02T05:05:50Z | https://github.com/TencentARC/GFPGAN/issues/27 | [] | MDYLL | 5 |
mljar/mljar-supervised | scikit-learn | 46 | Docs for AutoML api | closed | 2020-04-08T11:28:24Z | 2020-04-09T12:02:18Z | https://github.com/mljar/mljar-supervised/issues/46 | [
"docs"
] | pplonski | 1 | |
giotto-ai/giotto-tda | scikit-learn | 613 | help for extract color image features | hello,I want to extract geometric topological features of color images(RGB three channels) by giotto-tda, but the example for images of handwritten digits have one channel. Can you give me a suggestion about how I can use giotto-tda to extract color image features? | closed | 2021-10-10T07:00:22Z | 2022-02-02T13:29:31Z | https://github.com/giotto-ai/giotto-tda/issues/613 | [
"enhancement"
] | songxinyuty | 2 |
mckinsey/vizro | pydantic | 735 | Replace the use of "provide" with a simpler alternative as per Vale recommendation | Vale recommends use of a simpler alternative to "provide"
<img width="606" alt="image" src="https://github.com/user-attachments/assets/0b724546-86e4-4a8c-8063-496c3fa9b5e4">
Task: Search across Vizro docs (vizro-core and vizro-ai) for instances of provide and replace with discretion.
If there are genuine cases... | closed | 2024-09-23T12:07:11Z | 2024-11-05T13:17:18Z | https://github.com/mckinsey/vizro/issues/735 | [
"Good first issue :baby_chick:",
"hacktoberfest"
] | stichbury | 5 |
cleanlab/cleanlab | data-science | 1,041 | Add internal API reference for datalab adapter modules in docs | <!-- Please be as detailed as possible in your issue. INCLUDE the exact code you are trying to run, if your question is related to code. -->
Include (internal) API reference for the `clenalab.datalab.internal.adapter` modules ([link](https://github.com/cleanlab/cleanlab/tree/master/cleanlab/datalab/internal/adapt... | closed | 2024-03-07T01:29:47Z | 2024-09-05T19:13:40Z | https://github.com/cleanlab/cleanlab/issues/1041 | [
"good first issue",
"trivial-change",
"documentation"
] | elisno | 0 |
suitenumerique/docs | django | 596 | ⬆️ Upgrade Cunningham to v3 | ## Upgrade Request
Upgrade to the last version of Cunnigham.
Then remove the dependency from [renovate.json](https://github.com/suitenumerique/docs/blob/main/renovate.json).
See commit: https://github.com/suitenumerique/docs/commit/929a50b573c1787ffc53bed75e5d1c9631ef008e
| closed | 2025-01-29T16:49:53Z | 2025-03-10T13:34:16Z | https://github.com/suitenumerique/docs/issues/596 | [
"dependencies",
"javascript"
] | AntoLC | 0 |
mkhorasani/Streamlit-Authenticator | streamlit | 257 | Authenticate does not update yaml file | Hi,
Thanks so much for this useful library!
I have got an issue where authenticate() does not automatically update the yaml file (login count, hashing, etc.).
If I use the yaml dump command that works, but then I have to put it at different places in my code.
From your documentation, I read:
13. Updating the ... | open | 2025-02-19T09:57:48Z | 2025-03-04T18:07:07Z | https://github.com/mkhorasani/Streamlit-Authenticator/issues/257 | [
"help wanted"
] | cdebrier | 0 |
tox-dev/tox | automation | 3,026 | I mistook this for the chat client, please ignore. | See title. | closed | 2023-06-05T16:25:27Z | 2023-06-16T01:25:56Z | https://github.com/tox-dev/tox/issues/3026 | [] | Alceris | 3 |
vchaptsev/cookiecutter-django-vue | graphql | 24 | Frontend is not working | After the installation and starting docker-compose i cannot open the app.
When i go to localhost:3000 my browser says. "cannot open / GET"
when i go to localhost:8000 i get folowing error message inside browser console.
``Failed to load resource: the server responded with a status of 404 (Not Found)
localhost/:1... | closed | 2018-04-11T11:37:42Z | 2018-04-12T21:03:46Z | https://github.com/vchaptsev/cookiecutter-django-vue/issues/24 | [
"bug"
] | robert197 | 1 |
huggingface/datasets | pytorch | 6,837 | Cannot use cached dataset without Internet connection (or when servers are down) | ### Describe the bug
I want to be able to use cached dataset from HuggingFace even when I have no Internet connection (or when HuggingFace servers are down, or my company has network issues).
The problem why I can't use it:
`data_files` argument from `datasets.load_dataset()` function get it updates from the serve... | open | 2024-04-25T10:48:20Z | 2025-01-25T16:36:41Z | https://github.com/huggingface/datasets/issues/6837 | [] | DionisMuzenitov | 6 |
httpie/cli | python | 1,458 | Feature Request: Support special-use domain names like localhost. | ## Checklist
- [x] I've searched for similar feature requests. There is an FR from 2015: #373
---
## Enhancement request
HTTPie should resolve special domain names [per RFC6761](https://datatracker.ietf.org/doc/rfc6761/
), unless HTTPie uses a name resolution library that isn't part of the code base. Accor... | open | 2022-12-21T03:25:06Z | 2024-10-30T10:53:39Z | https://github.com/httpie/cli/issues/1458 | [
"enhancement",
"new"
] | joeblubaugh | 2 |
yihong0618/running_page | data-visualization | 556 | 请问GPX中心率记录的颗粒度是? | 您好,非常感谢您的runpage开源项目。在复刻之前有个小问题想咨询您,请问从keep提取下来的gpx文件里面有包含实时的心率记录吗,就是每分钟的心率都包含的,我想对详细的心率记录做数据分析,只是一个平均心率的话不太能满足我的需求。期待您的回复,非常感谢! | closed | 2023-12-01T07:15:38Z | 2023-12-01T08:17:20Z | https://github.com/yihong0618/running_page/issues/556 | [] | wuSaberMaster | 3 |
seleniumbase/SeleniumBase | web-scraping | 2,988 | seleniumbase with proxy error | i write script using seleniumbase and its working fine without proxy ,
but when i use proxy i got this error : selenium.common.exceptions.SessionNotCreatedException: Message: session not created: cannot connect to chrome at 127.0.0.1:41027
code:
from seleniumbase import SB
username = '*****'
password =... | closed | 2024-08-03T03:07:38Z | 2024-08-03T05:01:52Z | https://github.com/seleniumbase/SeleniumBase/issues/2988 | [
"can't reproduce",
"UC Mode / CDP Mode"
] | BEST1AV | 2 |
vvbbnn00/WARP-Clash-API | flask | 104 | [Bug] Surge 订阅链接无法更新,提示 403 | 在 Surge 顶部的订阅链接中使用的 `&secret`,而在下载链接中是 `&key`,可以下载,如果是更新就会提示 403 | closed | 2024-02-29T02:06:48Z | 2024-02-29T06:47:22Z | https://github.com/vvbbnn00/WARP-Clash-API/issues/104 | [
"bug"
] | 63936 | 1 |
nerfstudio-project/nerfstudio | computer-vision | 2,895 | Mipnerf export error | When i try to export poisson from MipNeRF i got an error
Could not find rgb in the model outputs. Please set --rgb_output_name to one of: dict_keys(['rgb_coarse', 'rgb_fine', 'accumulation_coarse', 'accumulation_fine', 'depth_coarse', 'depth_fine'])
| open | 2024-02-10T13:13:27Z | 2024-05-20T06:46:32Z | https://github.com/nerfstudio-project/nerfstudio/issues/2895 | [] | hanjoonwon | 5 |
OFA-Sys/Chinese-CLIP | nlp | 361 | The protocol error while running the build the build_lmdb_dataset.py | I create a custom dataset which contains about 1 million images and their cooresponding text title, when I translate them to the version of lmdb, the error is as below:
Traceback (most recent call last):
File "/code/hexufeng01/Chinese-CLIP/cn_clip/preprocess/build_lmdb_dataset.py", line 50, in <module>
env_... | open | 2024-10-08T09:08:22Z | 2024-10-08T09:08:22Z | https://github.com/OFA-Sys/Chinese-CLIP/issues/361 | [] | darkprices | 0 |
voxel51/fiftyone | computer-vision | 4,831 | [BUG] Maximum depth exceeded (Minified react issue #185) | ### Describe the problem
Hello, thanks for this awesome project !
I've been using fiftyone for a moment, and I have an issue that happens on all of my datasets. Note that all datasets are created with multiple DynamicEmbeddedDocuments, which contain a lot of information.
When I click on an image to open the d... | open | 2024-09-23T17:11:26Z | 2024-09-23T17:11:26Z | https://github.com/voxel51/fiftyone/issues/4831 | [
"bug"
] | Youyoun | 0 |
huggingface/pytorch-image-models | pytorch | 2,125 | [BUG] Scheduler implicitly do not change lr | Hi thanks for the library! https://github.com/huggingface/pytorch-image-models/blob/main/timm/scheduler/scheduler.py says:
> Unlike the builtin PyTorch schedulers, this is intended to be consistently called
> * At the END of each epoch, before incrementing the epoch count, to calculate next epoch's value
> * At th... | closed | 2024-03-24T00:11:13Z | 2024-03-24T00:26:12Z | https://github.com/huggingface/pytorch-image-models/issues/2125 | [
"bug"
] | fzyzcjy | 1 |
dropbox/PyHive | sqlalchemy | 436 | Connection Error(TTransportException) to Hive using SQLAlchemy API | Hi.
I am trying to connect Hive server using PyHive and SQLAlchemy API with SASL as below code:
`ssl_args = {'ssl_cert': 'cacerts.pem'}`
`engine = create_engine("hive://username:password@hivetestserver.com:10000/default?auth=LDAP", connect_args=ssl_args)`
`insp = inspect(engine)`
But it makes error like belo... | open | 2022-04-25T01:39:26Z | 2022-04-25T01:39:26Z | https://github.com/dropbox/PyHive/issues/436 | [] | onlyjiny | 0 |
d2l-ai/d2l-en | computer-vision | 2,428 | Exercise disscusion part is not conresponding after new version. | This book is the best book I have ever read. Compared to the last version, the new version has changed a lot and exercises have changed too. But the exercises discussion part below each notebook has not been updated now. The discussion and answers of friends are not corresponding with the questions now. This problem ma... | open | 2023-01-12T09:00:14Z | 2023-01-12T09:00:14Z | https://github.com/d2l-ai/d2l-en/issues/2428 | [] | qizihaoliuliuliu | 0 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.