
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
alpacahq/alpaca-trade-api-python | rest-api | 518 | [Bug]: using example in readme - assigning get_bars to a dataframe results in key error | ### Is there an existing issue for this?
- [X] I have searched the existing issues
### Current Behavior
this excerpt from the ReadMe results in a key error within pandas:
`api.get_bars("AAPL", TimeFrame.Hour, "2021-06-08", "2021-06-08", adjustment='raw').df`
`Traceback (most recent call last):
File ... | closed | 2021-10-28T20:51:15Z | 2021-10-29T01:21:49Z | https://github.com/alpacahq/alpaca-trade-api-python/issues/518 | [] | captn-bk | 2 |
microsoft/unilm | nlp | 830 | Dose layoutlmv3 have RE task code? | Hi,
I am learning layoutlmv3 model for SER and RE task. But I don't find source code for RE task in the layoutlmv3 folder. Could you please release the layoutlmv3 RE task model head & dataloader code? Thanks!
| closed | 2022-08-20T03:11:59Z | 2022-08-25T05:52:27Z | https://github.com/microsoft/unilm/issues/830 | [] | tonylin52 | 1 |
ageitgey/face_recognition | machine-learning | 1,631 | Spanish Translate | Hello.
This project is fantastic, so I'd like to translate `README.md` into Spanish for the Hispanic comunity can use it.
Could I do it? | open | 2025-03-13T20:38:08Z | 2025-03-13T20:38:08Z | https://github.com/ageitgey/face_recognition/issues/1631 | [] | nextpassword99 | 0 |
pydata/xarray | pandas | 9,479 | Feature: Aggregate using one or more operations over the specified axis. | ### Is your feature request related to a problem?
I'm always frustrated when I need to resample a ds and the resampling method is different for the variables present, i.e. for one variable I want the sum and for the other the mean.
### Describe the solution you'd like
Ideally there would be some functionality simila... | open | 2024-09-11T15:02:06Z | 2024-09-11T16:55:57Z | https://github.com/pydata/xarray/issues/9479 | [
"enhancement",
"topic-groupby"
] | kobebryant432 | 1 |
stanford-oval/storm | nlp | 103 | Support gemini! | **Is there any future update on supporting Gemini?** | closed | 2024-07-28T10:09:39Z | 2024-08-06T15:50:09Z | https://github.com/stanford-oval/storm/issues/103 | [] | amrpyt | 4 |
521xueweihan/HelloGitHub | python | 2,919 | [开源推荐] throttled-py:支持多种策略及存储选项的 Python 限流库 | ### 项目地址
https://github.com/ZhuoZhuoCrayon/throttled-py
### 类别
Python
### 项目标题
支持多种策略及存储选项的 Python 限流库
### 项目描述
* 支持 Redis、内存(线程安全)作为存储后端。
* 支持「固定窗口」「滑动窗口」「令牌桶」「漏桶」「GCRA」作为限流策略。
* 为 Web 服务、IO 密集型提供应对超额流量的保护机制。
### 亮点
* 提供业内通用的各类限流策略实现。
* 线程、并发安全:Redis(基于 Lua 实现限流算法)、In-Memory(基于 RLock)。
* 策略、存储可配置:提供灵活的限流策略、配额... | open | 2025-03-14T13:59:05Z | 2025-03-14T14:01:12Z | https://github.com/521xueweihan/HelloGitHub/issues/2919 | [] | ZhuoZhuoCrayon | 0 |
OpenBB-finance/OpenBB | machine-learning | 6,710 | [🕹️] Create a Risk-Return Tradeoff Model Notebook | # 📄 Task
Provide a working example of how to evaluate risk-return tradeoffs for various asset classes, utilizing OpenBB.
---
### 📋 Requirements:
1. **Template**: Start by copying the [example template notebook](https://github.com/OpenBB-finance/OpenBB/blob/develop/examples/COMMUNITY_EXAMPLE_TEMPLATE.ipy... | closed | 2024-09-30T18:57:33Z | 2024-11-02T07:42:33Z | https://github.com/OpenBB-finance/OpenBB/issues/6710 | [
"🕹️ 300 points"
] | piiq | 14 |
strawberry-graphql/strawberry | asyncio | 3,198 | Integration of SQLAlchemy with Strawberry | Hello,
I have been working with Strawberry GraphQL for a while and I am enjoying the experience and the simplicity it brings to working with GraphQL in Python. I have a query regarding the integration of ORM tools, specifically SQLAlchemy, with Strawberry.
As many projects rely on SQLAlchemy for their database op... | closed | 2023-11-03T16:41:01Z | 2025-03-20T15:56:27Z | https://github.com/strawberry-graphql/strawberry/issues/3198 | [] | DeanNeaht | 2 |
coqui-ai/TTS | python | 3,491 | XTTS Plans for Ukrainian and Romanian Languages | Is there a plan for adding a Ukrainian and Romanian models in XTTS?
| closed | 2024-01-04T22:37:45Z | 2024-02-18T08:58:18Z | https://github.com/coqui-ai/TTS/issues/3491 | [
"wontfix",
"feature request"
] | iprovalo | 2 |
dynaconf/dynaconf | flask | 1,212 | feat: Implement the `@insert` converter | ```bash
export FOO_KEY="@insert 0 value"
```
must call
```
settings.KEY.insert(0, value)
``` | closed | 2024-12-20T18:32:15Z | 2025-01-21T17:13:28Z | https://github.com/dynaconf/dynaconf/issues/1212 | [
"Not a Bug",
"RFC",
"aap"
] | rochacbruno | 0 |
statsmodels/statsmodels | data-science | 8,815 | Autoreg append expected behaviour when new added samples are less than model lags | I am using
https://www.statsmodels.org/dev/generated/statsmodels.tsa.ar_model.AutoRegResults.append.html#statsmodels.tsa.ar_model.AutoRegResults.append
Based on the documentation:
"Append observations to the ones used to fit the model"
So if I have fitted the model over 200 samples with lag=10, I should be... | open | 2023-04-21T12:57:12Z | 2023-04-21T21:33:47Z | https://github.com/statsmodels/statsmodels/issues/8815 | [] | laniakea | 2 |
svc-develop-team/so-vits-svc | deep-learning | 112 | [Help]: 底模训练时长求助 | ### 请勾选下方的确认框。
- [X] 我已仔细阅读[README.md](https://github.com/svc-develop-team/so-vits-svc/blob/4.0/README_zh_CN.md)和[wiki中的Quick solution](https://github.com/svc-develop-team/so-vits-svc/wiki/Quick-solution)。
- [X] 我已通过各种搜索引擎排查问题,我要提出的问题并不常见。
- [X] 我未在使用由第三方用户提供的一键包/环境包。
### 系统平台版本号
Ubuntu
### GPU 型号
3090
### Python... | open | 2023-04-02T07:47:32Z | 2023-04-15T00:53:04Z | https://github.com/svc-develop-team/so-vits-svc/issues/112 | [
"help wanted"
] | FlyToYourMooN | 11 |
junyanz/pytorch-CycleGAN-and-pix2pix | deep-learning | 1,182 | About visdom | I use pytorch-CycleGAN and pix2pix on ubuntu16.04
And I have installed my environment according to enviroment.yml.
But when I use train.py to training the cycleGAN model, I ran into some problems.
(pytorch-CycleGAN-and-pix2pix) youqi@youqi-System-Product-Name:~/anaconda3/pytorch-CycleGAN-and-pix2pix$ python -m vis... | closed | 2020-11-09T18:28:13Z | 2022-03-06T04:04:42Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/1182 | [] | Youqi970124 | 3 |
plotly/plotly.py | plotly | 4,529 | make error messages more helpful when choropleth features and data don't match | I teach [a class](https://python-public-policy.afeld.me/en/columbia/) for students that are new to coding. We use plotly, and I'm happy to have a package that gets students good-looking graphs in so little code.
I introduce plotly's choropleth maps, and have repeatedly run into the issue where the students get confu... | open | 2024-02-23T15:21:54Z | 2024-08-13T13:11:05Z | https://github.com/plotly/plotly.py/issues/4529 | [
"feature",
"P3"
] | afeld | 4 |
nonebot/nonebot2 | fastapi | 2,655 | Plugin: 职场日历 | ### PyPI 项目名
nonebot-plugin-zhichang
### 插件 import 包名
nonebot_plugin_zhichang
### 标签
[]
### 插件配置项
_No response_ | closed | 2024-04-18T08:09:09Z | 2024-05-25T14:57:47Z | https://github.com/nonebot/nonebot2/issues/2655 | [
"Plugin"
] | Priopus | 8 |
streamlit/streamlit | streamlit | 10,647 | Add `show_time` parameter to `st.cache_data` and `st.cache_resource` | ### Checklist
- [x] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar feature requests.
- [x] I added a descriptive title and summary to this issue.
### Summary
[`st.spinner`](https://docs.streamlit.io/develop/api-reference/status/st.spinner) now supports the `show_time... | open | 2025-03-05T09:44:15Z | 2025-03-06T18:50:11Z | https://github.com/streamlit/streamlit/issues/10647 | [
"type:enhancement",
"feature:cache",
"feature:st.spinner"
] | VERBOSE-01 | 3 |
serengil/deepface | deep-learning | 851 | Wearing glasses decrease accuracy of Arcface | I am using model Arcface to get 2 embedding vector of 1 person, with glasses and without glasses (same headpose and condition). Result cosine is 0.4 while using Facenet512 it only 0.19. Is everyone experiencing the same thing? | closed | 2023-10-04T11:16:57Z | 2023-10-04T11:18:44Z | https://github.com/serengil/deepface/issues/851 | [
"question"
] | HoangSang1510 | 1 |
autogluon/autogluon | data-science | 4,162 | [tabular] Add logging of inference throughput of best model at end of fit | [From user](https://www.kaggle.com/competitions/playground-series-s4e5/discussion/499495#2789917): "It wasn't really clear that predict was going to be going for a long time"
I think we can make this a bit better by mentioning at the end of training the estimated inference throughput of the selected best model, whic... | closed | 2024-05-02T22:32:18Z | 2024-05-16T23:53:30Z | https://github.com/autogluon/autogluon/issues/4162 | [
"API & Doc",
"module: tabular"
] | Innixma | 0 |
ymcui/Chinese-LLaMA-Alpaca | nlp | 565 | [window11]平台下现在是否无法使用GPU进行指令精调 | ### 详细描述问题
目前因为deepspeed和nccl两个库无法在win上使用,所以现在在win平台下进行训练是不可行的吗?
### 参考信息
#### 依赖情况(代码类问题务必提供)
|Package | Version|
| ----------- | ----------- |
|transformers| 4.29.1|
|torch | 2.0.1+cu118|
|peft | 0.3.0.dev0|
#### 运行日志或截图
```
Traceback (most recent call l... | closed | 2023-06-11T16:28:18Z | 2023-06-14T16:18:26Z | https://github.com/ymcui/Chinese-LLaMA-Alpaca/issues/565 | [] | AceyKubbo | 3 |
ultralytics/ultralytics | deep-learning | 19,484 | YOLO-World result on Zero-shot Transfer on LVIS Dataset | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
Hi, I am trying to reproduce YOLO-world result on LVIS Dataset. The ultralyt... | open | 2025-02-28T18:09:03Z | 2025-03-01T06:18:20Z | https://github.com/ultralytics/ultralytics/issues/19484 | [
"question",
"detect"
] | KaamComputingNp | 2 |
aimhubio/aim | data-visualization | 2,846 | Aim init fails after fresh install | Hi,
i installed aim via pip. When i try to initialize a new aim repo via `aim init` while i am in the directory `nf_registration,` i get the following error message.:
```
FAILED: Path doesn't exist: '***/nf_registration/storage/migrations'. Please use the 'init' command to create a new scripts folder.
Traceb... | closed | 2023-06-16T08:33:37Z | 2023-06-19T12:34:50Z | https://github.com/aimhubio/aim/issues/2846 | [
"type / question"
] | Tomakko | 3 |
nschloe/tikzplotlib | matplotlib | 82 | linewidth does not change | I set my `lines.linewidth` and `axes.linewidth` of my plot in matplotlibrc and if I save as PDF it works.
However, if I export the figure with `matplotlib2tikz.save`, the in the resulting .tex file the line width is always `thick`.
What am I doing wrong? I am using Matplotlib 1.5 and the example in the readme works.
| closed | 2016-01-07T15:11:03Z | 2016-01-07T16:03:16Z | https://github.com/nschloe/tikzplotlib/issues/82 | [] | haarburger | 2 |
jina-ai/serve | fastapi | 5,353 | Document the common args inheritence from Flow API to Executors and Gateway | Currently, flow API accepts all args of all entities.
These args will be propagated to other entities (gateway, executor) with some occasional exclusion.
We need to document this behavior and document what arguments are excluded | closed | 2022-11-04T17:00:11Z | 2022-12-19T13:07:34Z | https://github.com/jina-ai/serve/issues/5353 | [] | alaeddine-13 | 0 |
LAION-AI/Open-Assistant | python | 2,728 | 500 Internal Server Error nginx/1.23.4 | 500 Internal Server Error
nginx/1.23.4
Alle Dialoge für mehr als eine Stunde geben einen Fehler aus
all dialogs for more than an hour give an error
| closed | 2023-04-18T20:42:36Z | 2023-04-19T00:16:10Z | https://github.com/LAION-AI/Open-Assistant/issues/2728 | [] | buddhadhammaliveexpedition | 1 |
mage-ai/mage-ai | data-science | 5,224 | [BUG] logs deletion silently kills streaming pipelines | ### Mage version
0.9.70
### Describe the bug
I have a the following script which I run once every hour and I have set log retention period to 1h
The scripts seems to work and delete the logs as expected.
However, I noticed that our streaming pipelines creating a huge lag. No error is raised and pipelines shown as ... | open | 2024-06-24T09:28:30Z | 2024-07-08T18:19:44Z | https://github.com/mage-ai/mage-ai/issues/5224 | [
"bug"
] | georgezefko | 0 |
unit8co/darts | data-science | 2,585 | [BUG] TFTExplainer fails for univariate time series predicion with multivariate input | **Describe the bug**
I am currently using Darts TFT implementation for time-series prediction where the input is a multivariate time-series and the output is a univariate time-series. I successfully trained the model and then used TFTExplainer through the following steps. My model uses `past_target`, `historic_future_... | closed | 2024-11-05T04:24:01Z | 2024-11-15T11:27:00Z | https://github.com/unit8co/darts/issues/2585 | [
"bug",
"triage"
] | jainmilan | 1 |
microsoft/nni | pytorch | 5,646 | Speedup RAFT fails | **Describe the bug**:
I'm using https://github.com/princeton-vl/RAFT trained with the pre-trained raft-things.pt.
When speeding up the model I get and error:
File "/usr/local/lib/python3.8/dist-packages/nni/compression/pytorch/speedup/jit_translate.py", line 245, in __call__
result = self.func(*self.positiona... | open | 2023-07-20T13:26:48Z | 2023-08-11T06:56:26Z | https://github.com/microsoft/nni/issues/5646 | [] | akatzi77 | 0 |
oegedijk/explainerdashboard | dash | 105 | Improvement: Ability to use other backends besides Flask f.ex. FastAPI | Hi I'm playing with deployment of ExplainerDashboard. Would it be possible to support other backends besides Flask in the future. F.ex. I want to deploy to GCP and use oauth so I had a previous FastAPI script as a base with implemented oauth. But eventhough I can deploy the ExplainerHub with this although the hub itsel... | closed | 2021-03-30T07:26:41Z | 2023-07-06T14:42:36Z | https://github.com/oegedijk/explainerdashboard/issues/105 | [] | jruokolainen | 10 |
gee-community/geemap | streamlit | 1,275 | Map.to_streamlit() is only showing an empty space in my streamlit app | I have used the following code in my streamlit application
```
#Create an interactive map
Map = geemap.Map(plugin_Draw=True, Draw_export=False)
# Add a basemap
Map.add_basemap("TERRAIN")
# Retrieve Earth Engine dataset
dem = ee.Image("USGS/SRTMGL1_003")
# Set visualization parameters
vis_params = {
"min... | closed | 2022-09-30T01:18:56Z | 2022-09-30T16:42:39Z | https://github.com/gee-community/geemap/issues/1275 | [
"bug"
] | CharlesCodyRoss | 2 |
Yorko/mlcourse.ai | pandas | 664 | jupyter_russian/project_alice/week2_analysis_hypotheses.ipynb Специализация Курсеры | На курсере отличается первый вопрос от указанного в файле. Вместо количества уникальных длин новых разреженных матриц там спрашивается:
Вопрос 1. Каковы длины (число сессий) новых 16 разреженных матриц?
Эти длины нужно вывести в файл через пробел. Проверить можно здесь:
https://www.coursera.org/learn/data-analys... | closed | 2020-04-21T12:16:17Z | 2020-04-21T13:20:09Z | https://github.com/Yorko/mlcourse.ai/issues/664 | [] | eye-shield-77 | 1 |
redis/redis-om-python | pydantic | 75 | Are there the following query methods group_by and aggregate ? | I see in the code we have sort_by in redis-om,[ but (as in .NET)](https://www.youtube.com/watch?v=DnsRTa3dFxo&ab_channel=Redis), do we have:
- group_by ?
- aggregate ?
| closed | 2022-01-06T20:14:15Z | 2022-01-07T12:17:52Z | https://github.com/redis/redis-om-python/issues/75 | [] | therealbazzi | 1 |
jmcarpenter2/swifter | pandas | 202 | swifter.groupby() does not support with dropna=False | I found that the swifter groupby apply chain will encounter the error when trying to sort index, if I set dropna to False for the groupby step.
Here is the error log:
`
Traceback (most recent call last):
File "/paedyl01/disk1/yangyxt/ngs_scripts/acmg_automated_anno.py", line 76, in wrapper
result = func(*a... | open | 2022-09-28T05:52:51Z | 2023-03-24T21:53:28Z | https://github.com/jmcarpenter2/swifter/issues/202 | [
"bug"
] | yangyxt | 5 |
marcomusy/vedo | numpy | 743 | lighting('off') do not work | The code to reproduce my question is:
```
from vedo import Tube, Sphere, show
surf = Sphere(quads=True, res=15)
mesh = surf.tetralize(side=0.025, debug=False).tomesh().lighting('off').alpha(0.01)
show(mesh, axes=1)
```
and the result is:
 and [discussions](https://github.com/ultralytics/yolov5/discussions) and found no similar questions.
### Question
I am trying to detect football players, referees and ball on videos of mounted ca... | closed | 2024-05-10T08:40:59Z | 2024-11-07T22:29:08Z | https://github.com/ultralytics/yolov5/issues/12997 | [
"question",
"Stale"
] | dilwolf | 5 |
aio-libs/aiopg | sqlalchemy | 497 | Cannot (should not?) set isolation level on connection? | I find in the documentation here https://aiopg.readthedocs.io/en/stable/core.html?highlight=isolation_level#aiopg.Connection.isolation_level
`The only value allowed in asynchronous mode value is psycopg2.extensions.ISOLATION_LEVEL_READ_COMMITTED (READ COMMITTED).`
However, I am not able to find in the psycopg2 do... | open | 2018-08-22T17:59:28Z | 2020-07-16T11:07:41Z | https://github.com/aio-libs/aiopg/issues/497 | [] | shanecarey17 | 3 |
microsoft/qlib | machine-learning | 913 | Does the Backtest exclude the stocks at limit up which cannot be bought? 回测模块是否排除了不能购买的涨停股票? | I wonder if the Backtest module has excluded **the stocks at limit up or suspended** ? Because we cannot buy the stocks that reached the limit up or suspened, there might be bias in the backtest result if we don't exclude these stocks. How can I set the **Backtest Configuration** to eliminate the bias?
我想知道回测的时候是否已经... | closed | 2022-02-10T07:07:54Z | 2022-06-19T12:02:23Z | https://github.com/microsoft/qlib/issues/913 | [
"stale"
] | 1eunght | 7 |
oegedijk/explainerdashboard | plotly | 83 | Random uuid generated when selecting tabs with code | Hej,
Because I've built some custom components, I've started to declare what tabs I want to use in code. However, this causes issues with uuids now being generated as name. I've stepped through the code and it seems that name is not being passed into the constructor of the components => shortuuid is being randomed.
... | closed | 2021-02-09T13:25:38Z | 2021-02-25T19:55:22Z | https://github.com/oegedijk/explainerdashboard/issues/83 | [] | carlryn | 7 |
tqdm/tqdm | jupyter | 835 | keras | Incorporate and/or document a `keras.callback.Callback` from https://tqdm.github.io/video/ and https://github.com/bstriner/keras-tqdm
- related to #247, #815, https://github.com/iterative/example-versioning/pull/5 | closed | 2019-11-01T03:49:27Z | 2019-12-20T17:43:47Z | https://github.com/tqdm/tqdm/issues/835 | [
"p3-enhancement 🔥",
"submodule ⊂"
] | casperdcl | 0 |
JaidedAI/EasyOCR | deep-learning | 949 | AttributeError: 'Reader' object has no attribute 'readText' | AttributeError: 'Reader' object has no attribute 'readText' | closed | 2023-02-10T13:18:57Z | 2023-02-10T13:23:24Z | https://github.com/JaidedAI/EasyOCR/issues/949 | [] | Shoichii | 0 |
paperless-ngx/paperless-ngx | machine-learning | 9,231 | [BUG] Archived file name in API request doesn't match real archived file name | ### Description
It seems like the API contains the wrong path to the archived file. The API prints the following output:
```json
{
"count": 1,
"next": null,
"previous": null,
"all": [
200
],
"results": [
{
"id": 200,
"correspondent": 8,
"docu... | closed | 2025-02-26T18:55:03Z | 2025-02-26T21:58:21Z | https://github.com/paperless-ngx/paperless-ngx/issues/9231 | [
"not a bug"
] | TimGoll | 5 |
mckinsey/vizro | data-visualization | 379 | Add documentation about the demo example and clean up `examples` | This is a good issue for someone interested in documentation. It doesn't require any particular knowledge of Vizro but does need an interest in poking through our [examples folder in within `vizro-core` for this repo](https://github.com/mckinsey/vizro/tree/main/vizro-core/examples) to see what is there and write about ... | closed | 2024-03-20T16:21:30Z | 2024-10-09T09:17:44Z | https://github.com/mckinsey/vizro/issues/379 | [
"Help Wanted :pray:",
"Docs :spiral_notepad:",
"Good first issue :baby_chick:"
] | stichbury | 4 |
jina-ai/serve | deep-learning | 5,243 | docs: make Kubernetes more prominent | Currently everything about Kubernetes is contained in one single how-to article.
"Deploy on Kubernetes" should become its own section on the same level as "Flow" and "Hub" etc. for the following reasons:
- It sends a signal that we are cloud native. Right now our kubernetes stuff is hidden away, and seem like an af... | closed | 2022-10-05T11:55:42Z | 2022-10-27T15:11:18Z | https://github.com/jina-ai/serve/issues/5243 | [] | JohannesMessner | 0 |
open-mmlab/mmdetection | pytorch | 11,157 | UnicodeDecodeError: 'utf-8' codec can't decode byte 0xca in position 2: invalid continuation byte | Thanks for your error report and we appreciate it a lot.
**Checklist**
1. I have searched related issues but cannot get the expected help.
2. I have read the [FAQ documentation](https://mmdetection.readthedocs.io/en/latest/faq.html) but cannot get the expected help.
3. The bug has not been fixed in the la... | closed | 2023-11-10T15:16:06Z | 2023-11-11T13:35:11Z | https://github.com/open-mmlab/mmdetection/issues/11157 | [] | 99HU | 0 |
huggingface/transformers | tensorflow | 36,492 | Error at scatter num_items_in_batch in ddp/dp | ### System Info
Name: transformers
Version: 4.46.2
Python 3.11.10
### Who can help?
Hi @muellerzr @SunMarc, thanks in advance.
Trainer in compute loss adds num_items_in_batch as tensor scalar to kwargs, in DDP when kwargs are scattered it throws following error:
`RuntimeError: chunk expects at least a 1-dimensiona... | open | 2025-03-02T06:10:34Z | 2025-03-02T06:15:38Z | https://github.com/huggingface/transformers/issues/36492 | [
"bug"
] | MVPavan | 1 |
SciTools/cartopy | matplotlib | 1,564 | Cartopy reports incorrect longitude bounds when they span international dateline, too few LongitudeLocator gridlines | ### Description
<!-- Please provide a general introduction to the issue/proposal. -->
`GeoAxes.get_extent()` and `Gridliner._axes_domain()` report incorrect longitude bounds when they span the international dateline. The most noticeable effect is that `LongitudeLocator` generates too few longitude gridlines, but I ... | open | 2020-05-18T05:32:24Z | 2020-05-23T00:48:54Z | https://github.com/SciTools/cartopy/issues/1564 | [
"Type: Bug",
"Component: Gridlines"
] | lukelbd | 0 |
LAION-AI/Open-Assistant | machine-learning | 3,325 | Prevent accidental skipping of tasks if input is not empty | Please, *please* add some kind of warning/confirmation when a user starts entering an assistant reply and then presses the Skip button.
It's hard to express how painful it is when you try to compose a good reply for an hour or more and then accidentally press “Skip” and not only lose your work but also the chance to... | closed | 2023-06-07T21:33:59Z | 2023-06-14T20:21:26Z | https://github.com/LAION-AI/Open-Assistant/issues/3325 | [
"website",
"good first issue",
"UI/UX"
] | PurrVirtual | 3 |
developmentseed/lonboard | jupyter | 524 | Automated widget testing | There's now [pytest-ipywidgets](https://pypi.org/project/pytest-ipywidgets/).
See https://github.com/jupyter-widgets/ipywidgets/issues/2934#issuecomment-2109499356. Note that this might still be quite difficult to implement because we need to emulate a GPU as well if we want to render data. I believe deck used some ... | open | 2024-05-14T15:31:55Z | 2024-05-14T15:31:56Z | https://github.com/developmentseed/lonboard/issues/524 | [] | kylebarron | 0 |
keras-team/keras | tensorflow | 20,094 | SVD operation failed when compute_uv=False (TF backend) | ### Problem raised
TensorFlow `tf.linalg.svd()` with compute_uv=False returns a single tensor containing the singular values, and not three tensors "s, u, v" when compute_uv=True.
However, code line 188 in `keras/src/backend/tensorflow/linalg.py` always expects three returned tensors, even if only one is expected w... | closed | 2024-08-07T14:08:57Z | 2024-08-14T15:36:54Z | https://github.com/keras-team/keras/issues/20094 | [
"keras-team-review-pending",
"type:Bug"
] | cofri | 1 |
seanharr11/etlalchemy | sqlalchemy | 58 | ETLAlchemySource for Oracle database | HI,
I am using Oracle 12.1.0.2 as source database.
Installed "pip install cx_Oracle==7.3", can you share me a sample source connection string similar to below mysql for Oracle.
source = ETLAlchemySource("mysql://etlalchemy:etlalchemy@localhost/employees")
Thanks.
| open | 2023-06-12T14:31:59Z | 2023-06-12T15:32:39Z | https://github.com/seanharr11/etlalchemy/issues/58 | [] | lalu121212 | 1 |
HIT-SCIR/ltp | nlp | 37 | src/srl/FeatureExtractor.cpp:257, string + int? | closed | 2013-09-28T07:43:44Z | 2014-03-05T03:51:02Z | https://github.com/HIT-SCIR/ltp/issues/37 | [
"bug"
] | carfly | 0 | |
PokemonGoF/PokemonGo-Bot | automation | 5,793 | Show all Pokemons in Inventory | Right now only the Best pokemon gets displayed. It would be great to see a list of all current pokemon in my inventory, not just the best. | closed | 2016-11-08T16:19:49Z | 2016-11-08T19:52:19Z | https://github.com/PokemonGoF/PokemonGo-Bot/issues/5793 | [] | trippyhat | 0 |
CorentinJ/Real-Time-Voice-Cloning | deep-learning | 1,147 | it,s give the error | 

 servers using the dnspython libraries. But I'm still trying to get the initial python3 code working. For some reason the TSIG keys I am providing are not working.
python3 (both with a python-3:alpine doc... | closed | 2019-03-15T19:30:56Z | 2019-03-17T17:38:01Z | https://github.com/rthalley/dnspython/issues/355 | [] | jforman | 6 |
sanic-org/sanic | asyncio | 3,040 | TypeError: 'type' object is not subscriptable | ### Is there an existing issue for this?
- [x] I have searched the existing issues
### Describe the bug
import error sanic 24.12.0 and python3.8

### Code snippet
```
(3.8) root@debian:~# pip list|grep sanic
sanic ... | closed | 2025-02-17T01:25:38Z | 2025-03-05T13:20:45Z | https://github.com/sanic-org/sanic/issues/3040 | [
"bug"
] | hongweipeng | 2 |
iperov/DeepFaceLab | machine-learning | 694 | Face extraction not working: Failed to load the native TensorFlow runtime | I'm using DeepFaceLab_CUDA_9.2_SSE
I'm trying to extract faces from jpg or png files. When I launch any of the face extraction bat files (in order to extract from either data_src or data_dst), I have this message:
Performing 1st pass...
Running on CPU0.
Exception: Traceback (most recent call last):
File "D:\DF... | closed | 2020-04-04T20:55:59Z | 2020-04-05T14:24:41Z | https://github.com/iperov/DeepFaceLab/issues/694 | [] | fakirmac | 5 |
yuka-friends/Windrecorder | streamlit | 17 | 拆分 webui.py | webui.py 太长,可读性和可维护性都很差,需要拆分成多个文件 | closed | 2023-11-04T10:15:58Z | 2023-11-07T14:25:33Z | https://github.com/yuka-friends/Windrecorder/issues/17 | [
"refactoring"
] | jpswing | 0 |
pallets-eco/flask-wtf | flask | 411 | Unable to set a custom error message for Recaptcha failures | I am probably just doing it wrong but I can't figure this one out.
The default Recaptcha error message seems to be "The response parameter is missing." How do I change it?
I tried what I thought was obvious and it does not work. It never lets the form get past Captcha. Has anyone figured this out?
Here was... | closed | 2020-05-11T18:11:17Z | 2021-11-22T00:39:45Z | https://github.com/pallets-eco/flask-wtf/issues/411 | [
"recaptcha"
] | joegiglio | 2 |
python-gino/gino | sqlalchemy | 575 | How do I Batch Update | * GINO version: 0.8.3
* Python version: 3.6.6
* asyncpg version: 0.19.0
* PostgreSQL version: 11.5
I have the following model:
```
class ProviderHotel(db.Model):
__bind_key__ = 'hotels'
__tablename__ = 'provider_hotels'
id = db.Column(db.Integer, primary_key=True)
provider = db.Column(db.String)
... | closed | 2019-10-18T02:24:44Z | 2019-10-20T05:12:54Z | https://github.com/python-gino/gino/issues/575 | [
"question"
] | nimwijetunga | 10 |
erdewit/ib_insync | asyncio | 457 | SPX value via ticker in real time . | I have the ticker for SPX index . Want to get the current real time value. I am subscribed and can see it in my TWS
Ticker(contract=Index(conId=416904, symbol='SPX', exchange='CBOE', currency='USD', localSymbol='SPX'), time=datetime.datetime(2022, 3, 24, 17, 16, 47, 158314, tzinfo=datetime.timezone.utc), high=4505... | closed | 2022-03-24T18:03:15Z | 2022-03-28T15:19:45Z | https://github.com/erdewit/ib_insync/issues/457 | [] | ravijagan | 2 |
giotto-ai/giotto-tda | scikit-learn | 702 | error in running a tutorial notebook | I am getting some errors running the mapper_quickstart.ipynb notebook in tutorial.
To reproduce just run the ipython notebook.
The cell
```
fig = plot_static_mapper_graph(pipe, data)
fig.show(config={'scrollZoom': True})
```
produces the following errors
```
--------------------------------------------... | open | 2024-09-22T05:13:39Z | 2024-09-22T05:18:41Z | https://github.com/giotto-ai/giotto-tda/issues/702 | [
"bug"
] | beew | 0 |
inducer/pudb | pytest | 494 | Include text-wrapping abilities | While most code is PEP compliant and well within 80 columns, some of it isn't. I was wondering whether PuDB has the ability to wrap code if it exceeds the current width? If not, is this a reasonable feature to include? | open | 2021-12-05T06:36:06Z | 2021-12-05T20:14:37Z | https://github.com/inducer/pudb/issues/494 | [] | nikhilweee | 1 |
keras-team/autokeras | tensorflow | 1,246 | I can not use the method predict on keras model (AutoModel.export_model()) with categorical features | ### Bug Description
When I use the StructuredDataClassifier and I export the model by export_model, I can not use the predict method - model.predict(test_data.to_numpy()) --, because the Keras model can not handle with categorical features. I believe that export_model does not add in the pipeline model the preprocess ... | closed | 2020-07-22T22:36:25Z | 2022-11-25T19:20:24Z | https://github.com/keras-team/autokeras/issues/1246 | [
"bug report",
"wontfix"
] | leandroimail | 7 |
ipython/ipython | jupyter | 14,715 | `@magic_arguments()` always use `%` in help regardless of line/cell magic | Currently the code has
```
# Override the default prefix ('usage') to our % magic escape,
# in a code block.
def add_usage(self, usage, actions, groups, prefix="::\n\n %"):
super(MagicHelpFormatter, self).add_usage(usage, actions, groups, prefix)
```
Which implies when `@magic_arguments()` is use... | open | 2025-02-02T16:30:54Z | 2025-02-02T16:30:54Z | https://github.com/ipython/ipython/issues/14715 | [] | user202729 | 0 |
polarsource/polar | fastapi | 4,549 | SDK: Go | closed | 2024-11-26T22:31:26Z | 2024-12-19T10:00:48Z | https://github.com/polarsource/polar/issues/4549 | [] | birkjernstrom | 1 | |
xinntao/Real-ESRGAN | pytorch | 610 | 出图颈部不正常 | Mac OS, intel cpu i7
```
python inference_realesrgan.py -n RealESRGAN_x4plus -i $HOME/MyWork/51pwn4ai/data/img_47.jpg --face_enhance --fp32
```
<img width="667" alt="image" src="https://user-images.githubusercontent.com/18223385/232033847-d267be97-ec0f-44f3-bf28-f2fbb12d3ab1.png">
| closed | 2023-04-14T11:39:05Z | 2024-01-29T01:55:40Z | https://github.com/xinntao/Real-ESRGAN/issues/610 | [] | hktalent | 2 |
huggingface/diffusers | deep-learning | 10,917 | Is lumina-2.0 script correct? | I wrote a script, based on the one provided [here](https://github.com/huggingface/diffusers/blob/main/examples/dreambooth/train_dreambooth_lora_lumina2.py)
it gets stuck on loss around 0.5, and i think it is a lot, isn't it? | open | 2025-02-27T11:17:00Z | 2025-02-28T15:46:43Z | https://github.com/huggingface/diffusers/issues/10917 | [] | Riko0 | 3 |
PokeAPI/pokeapi | api | 559 | Add a property which lists the Pokémon that can learn a move (separated by leveling up, TM/HM, breeding, etc.) | Maybe I'm not searching hard enough but I don't know how to find the Pokémon that can learn a move, so assuming such a feature doesn't exist, what about adding a property listing the Pokémon that can learn a move, further separated by method of acquiring like TM/HM, leveling up, breeding, etc (Including overlaps like x... | closed | 2021-01-13T23:16:57Z | 2021-01-27T18:29:12Z | https://github.com/PokeAPI/pokeapi/issues/559 | [] | ChrisMGeo | 17 |
inventree/InvenTree | django | 8,708 | [UI] Multifactor token configuration | Multifactor authentication setup is missing in the new admin center:

| closed | 2024-12-18T13:39:50Z | 2025-02-22T00:11:06Z | https://github.com/inventree/InvenTree/issues/8708 | [
"enhancement",
"question",
"security",
"User Interface"
] | SchrodingersGat | 3 |
open-mmlab/mmdetection | pytorch | 11,402 | Lazy Loading support for COCO datasets | **Describe the feature**
It should be possible to lazy load data from COCO format datasets so that only the particular annotations needed at any given time are loaded into RAM.
**Motivation**
Right now there is a "lazy_init" flag for datasets which in theory should prevent the entire dataset from being loaded on i... | open | 2024-01-18T18:08:46Z | 2024-01-18T18:08:46Z | https://github.com/open-mmlab/mmdetection/issues/11402 | [] | h-fernand | 0 |
matplotlib/mplfinance | matplotlib | 37 | output to buffer | i need to save to io.buffer
something like:
```python
buf = io.BytesIO()
mpf.plot(
candles,
type='candle',
mav=(3, 6, 9),
volume=True,
show_nontrading=True,
figratio=(6, 6),
title="Graph",
style='yahoo',
savefig=buf
)
buf.seek(0)
```
| closed | 2020-02-21T04:55:09Z | 2020-03-04T04:19:11Z | https://github.com/matplotlib/mplfinance/issues/37 | [
"enhancement",
"good first issue"
] | rspadim | 3 |
yezz123/authx | pydantic | 459 | 📝 Followup with documentation - External Features | I still support some old features here as an external service, you can help with extending the level of the documentation, such as update for the documentation ( more user-friendly 😞)
## External Features:
- Instrument/profiler - https://authx-v0.yezz.me/configuration/middleware/profiling/
- Redis - https://aut... | closed | 2023-06-01T20:26:14Z | 2023-07-08T15:17:40Z | https://github.com/yezz123/authx/issues/459 | [
"documentation",
"good first issue"
] | yezz123 | 0 |
snarfed/granary | rest-api | 165 | Support mime type for mf2 | When returning mf2 json, return type application/mf2+json instead of application/json | closed | 2019-05-20T12:25:25Z | 2019-05-21T05:22:27Z | https://github.com/snarfed/granary/issues/165 | [] | dshanske | 7 |
harry0703/MoneyPrinterTurbo | automation | 403 | 用了VPN 但是还是提示 你在中国请用VPN | RT | closed | 2024-06-08T22:19:38Z | 2024-06-11T03:37:25Z | https://github.com/harry0703/MoneyPrinterTurbo/issues/403 | [] | enzewow | 1 |
Significant-Gravitas/AutoGPT | python | 9,376 | Reset password page isn't centered | closed | 2025-01-30T12:05:53Z | 2025-01-30T12:51:18Z | https://github.com/Significant-Gravitas/AutoGPT/issues/9376 | [
"platform/frontend"
] | linear[bot] | 0 | |
nonebot/nonebot2 | fastapi | 2,834 | Plugin: exe_code | ### PyPI 项目名
nonebot-plugin-exe-code
### 插件 import 包名
nonebot_plugin_exe_code
### 标签
[]
### 插件配置项
```dotenv
EXE_CODE__USER=["{user_id}"]
EXE_CODE__GROUP=["{group_id}"]
```
| closed | 2024-07-21T06:58:13Z | 2024-07-21T14:57:10Z | https://github.com/nonebot/nonebot2/issues/2834 | [
"Plugin"
] | wyf7685 | 3 |
NullArray/AutoSploit | automation | 617 | Unhandled Exception (4d85ab99e) | Autosploit version: `3.0`
OS information: `Linux-4.18.0-kali2-amd64-x86_64-with-Kali-kali-rolling-kali-rolling`
Running context: `autosploit.py`
Error meesage: `global name 'Except' is not defined`
Error traceback:
```
Traceback (most recent call):
File "/root/work/AutoSploit/autosploit/main.py", line 119, in main
... | closed | 2019-04-02T03:43:47Z | 2019-04-02T20:24:31Z | https://github.com/NullArray/AutoSploit/issues/617 | [] | AutosploitReporter | 0 |
graphdeco-inria/gaussian-splatting | computer-vision | 848 | I like your work very much, I have tilted photography photos on my side and if I train with the original resolution, the training doesn't go on. My setup is RTX4090 and I've tried CPU loading data as well. Do you have any thoughts on this please? | open | 2024-06-13T10:19:36Z | 2024-06-13T10:19:36Z | https://github.com/graphdeco-inria/gaussian-splatting/issues/848 | [] | chenqi13814529300 | 0 | |
opengeos/leafmap | jupyter | 346 | Add rastervision for deep learning | https://github.com/azavea/raster-vision | closed | 2023-01-22T19:51:23Z | 2024-02-06T15:30:28Z | https://github.com/opengeos/leafmap/issues/346 | [
"Feature Request"
] | giswqs | 1 |
gee-community/geemap | streamlit | 682 | Add RivWidthCloud module | RivWidthCloud, or RWC, is an open source software written to automate extracting river centerline and width from remotely sensed images. It was developed for the Google Earth Engine (GEE) platform and developed for both its JavaScript and Python APIs. A complete description of the method can be found in this publicatio... | closed | 2021-09-19T02:21:59Z | 2023-12-06T17:19:26Z | https://github.com/gee-community/geemap/issues/682 | [
"Feature Request"
] | giswqs | 5 |
matplotlib/matplotlib | data-visualization | 29,544 | [Bug]: Logarithmic scale of the y-axis does not work when the range is small | ### Bug summary
I have a decreasing function $y\colon [1,3600] \to \mathbb{R}^+$.
I try to set the logarithmic scale for the y-axis, but if the range of the function is small (i.e., the initial and final value are closeby), then the logarithmic scale does not work and it only prints the linear scale.
### Code for... | closed | 2025-01-29T13:30:16Z | 2025-01-30T20:39:24Z | https://github.com/matplotlib/matplotlib/issues/29544 | [] | TomManMaz | 1 |
3b1b/manim | python | 1,129 | Problema con instalación de cairo | Estaba intentando instalar Cairo, cuando durante el proceso de poner *C:/ users/HP/Downloads>python -m pip install pycairo-1.19.1-cp39-cp39-win_amd64.whl*
me aparece esto:
Error: pycairo-1.19.1-cp39-cp39-win_amd64.whlis not a supported wheel in this platform
Para esto yo ya he intentado con diferentes versiones de ... | open | 2020-06-07T03:48:21Z | 2020-06-13T18:27:16Z | https://github.com/3b1b/manim/issues/1129 | [] | Luminerr | 1 |
apify/crawlee-python | automation | 838 | Add tests for import errors where there is missing extra | ### Problem
- The [test_import_error_handled](https://github.com/apify/crawlee-python/blob/c58e9730d8d09a75923e8aaa90429f802d81a170/tests/unit/parsel_crawler/test_parsel_crawler.py#L233) is currently not functional with the new `crawlee._utils.try_import.ImportWrapper`.
- As a result, the test is marked as skipped... | open | 2024-12-20T17:09:41Z | 2024-12-21T10:06:08Z | https://github.com/apify/crawlee-python/issues/838 | [
"t-tooling"
] | vdusek | 1 |
microsoft/qlib | deep-learning | 923 | Download dataset speed is very slow | ## ❓ Questions and Help
Hello thank you for the great framework.
When i try to download the dataset, the speed is slower than 2k/s, sometimes even 0b/s.
I follow the command as the readme.
/# get 1d data
python scripts/get_data.py qlib_data --target_dir ~/.qlib/qlib_data/cn_data --region cn
/# get 1min data
py... | closed | 2022-02-18T15:34:05Z | 2022-10-21T15:05:44Z | https://github.com/microsoft/qlib/issues/923 | [
"question",
"stale"
] | Sheng1e8 | 7 |
biolab/orange3 | pandas | 6,078 | Renaming learners recomputes scores in test and score | Hi,
I just notice that Orange3 (the latest version at this time), recompute the `Test and Score` widget after applying any type of changes, even for insignificant change (things like renaming a widget..), which is time consuming specially when dealing with a large dataset, another case when opening a project it star... | closed | 2022-07-27T18:44:16Z | 2022-10-07T11:33:55Z | https://github.com/biolab/orange3/issues/6078 | [
"bug"
] | bitsnaps | 3 |
ploomber/ploomber | jupyter | 761 | composing pipelines from multiple pipeline.yaml | it's often useful to break a data analysis pipeline into multiple parts. one use case is when a large team works on the same analysis but it's divided into sub-teams that only work with certain parts of it. Note that this is different from the `import_tasks_from` use case since in that case, we want to re-use logic in ... | closed | 2022-05-13T22:28:01Z | 2022-09-06T01:59:11Z | https://github.com/ploomber/ploomber/issues/761 | [] | edublancas | 0 |
ray-project/ray | data-science | 50,976 | [Ray Core] Ray task error stack trace is incomplete | ### What happened + What you expected to happen
If the error message is too long, it seems that it cannot be fully displayed. Is there a length limit somewhere? Is there an environment variable that can be configured?

### Versi... | closed | 2025-02-28T03:56:51Z | 2025-03-03T03:58:10Z | https://github.com/ray-project/ray/issues/50976 | [
"bug",
"dashboard",
"observability"
] | Moonquakes | 1 |
vastsa/FileCodeBox | fastapi | 59 | 建议新增一个文件预览功能 | 建议新增一个文件预览功能,在文件的下载界面展示文件的预览内容,这样比较好,可以预览这个文件的内容 | open | 2023-03-04T15:27:30Z | 2025-02-06T12:12:42Z | https://github.com/vastsa/FileCodeBox/issues/59 | [
"planned"
] | shier144 | 3 |
numba/numba | numpy | 9,372 | 0.590rc1 changelog missing author issue | Issue with 0.59.0rc1 changelog from discourse thread: https://numba.discourse.group/t/ann-numba-0-59-0rc1-and-llvmlite-0-42-0rc1/2329/4?u=sklam
TODOs:
- [x] manually fix changelog before the next release of 0.59 series https://github.com/numba/numba/pull/9402
- ~[ ] fix the changelog script to account for missin... | closed | 2023-12-15T17:18:20Z | 2024-02-07T20:48:50Z | https://github.com/numba/numba/issues/9372 | [
"Task"
] | sklam | 0 |
explosion/spaCy | machine-learning | 12,310 | Unable to load model on VM, getting error 'utf-8' codec can't decode 0x86 in position 0: UnicodeDecodeError | Hello,guys
I have successfully trained the model using GPU enabled system and now I want this model to be used on my VM.
While performing ``` spacy.load("/Users/home/djnago/model-last")```
getting the error
```
/home/ubuntu/ResumeParser/rParserVenv/lib/python3.10/site-packages/spacy/util.py:877: UserWarnin... | closed | 2023-02-21T09:11:10Z | 2023-02-23T09:04:45Z | https://github.com/explosion/spaCy/issues/12310 | [
"feat / serialize"
] | Anand195 | 0 |
pydantic/pydantic | pydantic | 10,551 | Bug: `TypeError: cannot pickle 'staticmethod' object` with a `Field.default` | ### Initial Checks
- [X] I confirm that I'm using Pydantic V2
### Description
For some reason, I can't use `staticmethod` with the `default` argument for a `Field`
### Example Code
```Python
from collections.abc import Callable
from pydantic import BaseModel, Field
class SomeModel(BaseModel):
... | closed | 2024-10-03T22:45:57Z | 2024-11-11T20:44:16Z | https://github.com/pydantic/pydantic/issues/10551 | [
"bug V2"
] | jamesbraza | 3 |
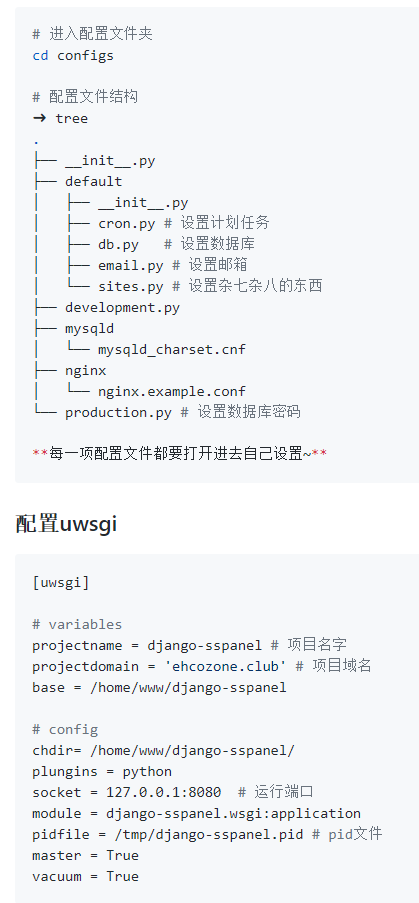
Ehco1996/django-sspanel | django | 154 | 配置文件到底具体怎么配? | 我打开了这些文件,注释看不懂
| closed | 2018-07-19T11:30:04Z | 2018-07-30T03:19:32Z | https://github.com/Ehco1996/django-sspanel/issues/154 | [] | Tomit121017 | 1 |
pyg-team/pytorch_geometric | pytorch | 9,586 | For some indexes, batched_negative_sampling returns a FloatTensor | ### 🐛 Describe the bug
I don't know what exactly causes it, but for some inputs, batched_negative_sampling is returning a tensor of float32, instead of the expected int64 LongTensor
Minimal reproducable example, along with the data which is triggering the error in both .pt and .txt format:
```py
import torch... | open | 2024-08-10T01:01:01Z | 2024-08-10T01:07:01Z | https://github.com/pyg-team/pytorch_geometric/issues/9586 | [
"bug"
] | DoctorDinosaur | 0 |
xorbitsai/xorbits | numpy | 216 | [BUG] `len(df)` returns incorrect result | ### Describe the bug
`len(df)` returns incorrect result.
### To Reproduce
```Python
In [1]: import xorbits.pandas as pd
In [2]: df = pd.read_csv('user.csv')
In [3]: len(df)
Out[3]: 0
```
| closed | 2023-02-15T10:01:18Z | 2023-02-20T05:52:21Z | https://github.com/xorbitsai/xorbits/issues/216 | [
"bug"
] | aresnow1 | 0 |
skforecast/skforecast | scikit-learn | 500 | Refitting forecaster every n iterations during backtesting | suppose we refit the forecaster every n iterations, and predict for k steps, where n < k, then the n+1 time period would be predicted 2 times, n+2 time period would be predicted 3 times, etc. etc.. how would the backtesting plot look here? and how would metrics (e.g. mape) be calculated?
I know 0.9.0 is still unstab... | closed | 2023-07-05T17:01:23Z | 2023-07-11T07:30:08Z | https://github.com/skforecast/skforecast/issues/500 | [
"question"
] | harpreet-s-paul | 2 |
httpie/cli | api | 1,447 | Authorization header not printed when using digest auth | `http -v -A digest -a username:password pie.dev/digest-auth/auth/username/password` doesn't print the Authorization request header
I guess this is challenging because the header is populated in the requests library
***
```sh
> http -v -A digest -a username:password pie.dev/digest-auth/auth/username/password ... | open | 2022-11-03T21:30:42Z | 2022-11-14T10:07:25Z | https://github.com/httpie/cli/issues/1447 | [
"bug",
"new"
] | hickford | 1 |
CorentinJ/Real-Time-Voice-Cloning | python | 326 | A number of errors | hi, I ran in to a number of issues.
Mac, all prerequisites follow as instructed.
Great project, would love to get it to work! Thanks
1.
(base) AIDESORRYALONE:Real-Time-Voice-Cloning-master $ ls
LICENSE.txt synthesizer
README.md synthesizer_preprocess_audio.py
demo_cli.py synthesizer_preprocess_embed... | closed | 2020-04-18T17:27:28Z | 2020-07-04T14:50:30Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/326 | [] | xiu-shi | 3 |
jina-ai/serve | fastapi | 5,912 | Hot reload not working on Windows 10. | **Describe the bug**
It seems like hot reloading is not working on Windows 10 when using the `reload=True` on a Flow or executor as well as when using it on the cli when running `jina flow --uses flow.yml --reload`. I went and created a simple new flow with `jina new test-flow` and then launched the flow with `jina fl... | closed | 2023-06-18T14:55:20Z | 2023-06-20T08:23:56Z | https://github.com/jina-ai/serve/issues/5912 | [] | ZeroCool940711 | 22 |
voila-dashboards/voila | jupyter | 688 | voila can't show math text in voila | The last slider can not show math text (in this case x_value2). Jupyter Notebook shows all sliders correctly. Voila does not.
Cell 1:
```
from ipywidgets import interactive, Label, widgets
def output_sv(slidervalue = 5):
print(slidervalue)
```
Cell 2:
```
interactive_plot=interactive(output_sv, sliderv... | closed | 2020-09-01T13:19:11Z | 2024-10-09T20:54:11Z | https://github.com/voila-dashboards/voila/issues/688 | [] | DohunLee | 5 |
recommenders-team/recommenders | deep-learning | 1,667 | [ASK] How to save the model after training? How to call the saved model, thank you. | How to save the model after training? How to call the saved model, thank you. | open | 2022-03-10T09:22:31Z | 2022-03-11T01:18:03Z | https://github.com/recommenders-team/recommenders/issues/1667 | [
"help wanted"
] | linjianwei888 | 1 |
sngyai/Sequoia | pandas | 24 | 本接口即将停止更新,请尽快使用Pro版接口:https://waditu.com/document/2 | closed | 2021-06-30T10:40:09Z | 2021-06-30T11:40:06Z | https://github.com/sngyai/Sequoia/issues/24 | [] | snail521 | 0 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.