
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
open-mmlab/mmdetection | pytorch | 11,632 | Forced resizing of images before use of RandomCrop negating point of cropping? | Thanks for your error report and we appreciate it a lot.
**Checklist**
1. I have searched related issues but cannot get the expected help.
2. I have read the [FAQ documentation](https://mmdetection.readthedocs.io/en/latest/faq.html) but cannot get the expected help.
3. The bug has not been fixed in the latest v... | open | 2024-04-12T11:09:24Z | 2024-04-12T11:09:43Z | https://github.com/open-mmlab/mmdetection/issues/11632 | [] | Trotts | 0 |
jina-ai/serve | machine-learning | 5,984 | bug: gateway configurations ignored in Flow method- `to_kubernetes_yaml` | **Describe the bug**
Gateway configurations are ignored while ejecting a `Flow` as kubernetes yaml
---
**Describe how you solve it**
Try the below code:
```py
from jina import Flow
f = (
Flow()
.config_gateway(port=12345, protocol="http") \
.add(uses='jinahub+docker://TransformerTorchEncod... | closed | 2023-07-27T18:35:26Z | 2023-07-28T14:22:50Z | https://github.com/jina-ai/serve/issues/5984 | [] | sansmoraxz | 6 |
cvat-ai/cvat | computer-vision | 8,573 | Reducer UPDATE_ANNOTATIONS_SUCCESS, not update the tags ? | ### Actions before raising this issue
- [X] I searched the existing issues and did not find anything similar.
- [X] I read/searched [the docs](https://docs.cvat.ai/docs/)
### Steps to Reproduce
I create an anction similar of updateAnnotationsAsync, I can't dispatch the state, it still has the old values....
```
... | closed | 2024-10-21T17:06:06Z | 2024-10-23T09:31:38Z | https://github.com/cvat-ai/cvat/issues/8573 | [
"question"
] | davy-blavette | 5 |
apify/crawlee-python | automation | 817 | a type hint shortcoming with crawler.run() | Type hinting is a key selling point of this library, yet the following code does not trigger a warning. Only strings should be permitted in the URL list.
```python
from crawlee.playwright_crawler import PlaywrightCrawler
crawler = PlaywrightCrawler()
await crawler.run(["https//example.com", 123, None])
```
| closed | 2024-12-15T04:44:11Z | 2024-12-16T18:39:40Z | https://github.com/apify/crawlee-python/issues/817 | [
"t-tooling"
] | matecsaj | 2 |
giotto-ai/giotto-tda | scikit-learn | 669 | Unexpected Cech persistence result returns | When using `EuclideanCechPersistence` to calculate persistence homology, the return result looks wrong.
test code:
```python
import numpy as np
from gtda.homology import EuclideanCechPersistence
exp_data = np.array([[0,0],[2,0],[0.5,1],[2,-1],[1,-1.2]])
# calc PH
homology_dimensions = [0,1] # 0d and 1d PH ... | open | 2023-05-27T21:51:13Z | 2023-05-28T21:31:07Z | https://github.com/giotto-ai/giotto-tda/issues/669 | [
"enhancement"
] | Alessiacosmos | 0 |
huggingface/pytorch-image-models | pytorch | 2,244 | convnext_tiny model produces outputs that are dependent on the batch size | **Describe the bug**
Usually in a neural network, once we call `model.eval()`, for a given set of inputs, the outputs must be the same. But in the convnext_tiny model, this does not seem to be the case. Its output values depend on the batch size.
**To Reproduce**
```python
import torch
from timm import create_mo... | closed | 2024-07-31T11:29:36Z | 2024-07-31T15:44:41Z | https://github.com/huggingface/pytorch-image-models/issues/2244 | [
"bug"
] | Avishka-Perera | 1 |
gto76/python-cheatsheet | python | 91 | Python-cheat | RomaMolora | closed | 2021-03-30T05:27:46Z | 2021-03-31T04:43:17Z | https://github.com/gto76/python-cheatsheet/issues/91 | [] | RomaMolora | 0 |
aiortc/aiortc | asyncio | 229 | Problem when running setup.py | Hello, I am trying to run **python3 setup.py** on Linux Mint 19.2 and receive this error message:
WARNING: The wheel package is not available.
WARNING: The wheel package is not available.
ERROR: Failed to build one or more wheels
Traceback (most recent call last):
File "/usr/local/lib/python3.6/dist-packages/s... | closed | 2019-11-25T18:48:10Z | 2019-12-02T07:59:54Z | https://github.com/aiortc/aiortc/issues/229 | [] | spectralcodec | 9 |
ploomber/ploomber | jupyter | 696 | Support variables in env.yaml | Compare:
```
data_out_dir = "../output/data"
models_out_dir = "../output/models"
alerts_out_dir = "../output/alerts"
```
vs.
```
out_dir = "../output"
data_out_dir = "{{out_dir}}/data"
models_out_dir = "{{out_dir}}/models"
alerts_out_dir = "{{out_dir}}/alerts"
```
| closed | 2022-03-31T17:52:32Z | 2023-03-27T12:48:13Z | https://github.com/ploomber/ploomber/issues/696 | [
"stash"
] | williewheeler-ms | 11 |
flairNLP/flair | nlp | 2,782 | Combining BERT and other types of embeddings | A while ago I was upset with the embed merging process and suddenly this amazing library pops up.
You are great!
-------------------------
My question:
The flair model can give a representation of any word (it can handle the OOV problem), while the BERT model splits the unknown word into several sub-words.
For e... | closed | 2022-05-19T15:02:12Z | 2022-10-15T21:06:58Z | https://github.com/flairNLP/flair/issues/2782 | [
"question",
"wontfix"
] | AliHaiderAhmad001 | 3 |
wkentaro/labelme | computer-vision | 346 | why labelme 3.10.1 save json so big? | I upgraded labelme to newest version 3.10.1 (I use pip install labelme), and when I annotate the image and save it, I found the json-file is much bigger then the image-file. It is so weird, and load the image's speed is much slower than the previous version.
Thank you! | closed | 2019-03-12T09:51:21Z | 2019-03-20T10:50:03Z | https://github.com/wkentaro/labelme/issues/346 | [] | archwolf118 | 5 |
junyanz/pytorch-CycleGAN-and-pix2pix | deep-learning | 782 | Why did you ignore the InstanceNorm in the first block of Unet? | Could you tell me any reason why do you ignore the instance norm in the fist down-sampling block in the unet? I have added the norm in the block but the performance worst
https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/43521b0e670f5421487d8aaf3675786e177c72e6/models/networks.py#L514 | open | 2019-10-04T14:59:12Z | 2019-10-07T16:44:55Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/782 | [] | John1231983 | 3 |
httpie/cli | python | 774 | JSON keys containing a "@" symbol are hidden | It's especially annoying when dealing with JSON-LD document (by the spec reserved keywords start by a `@`).
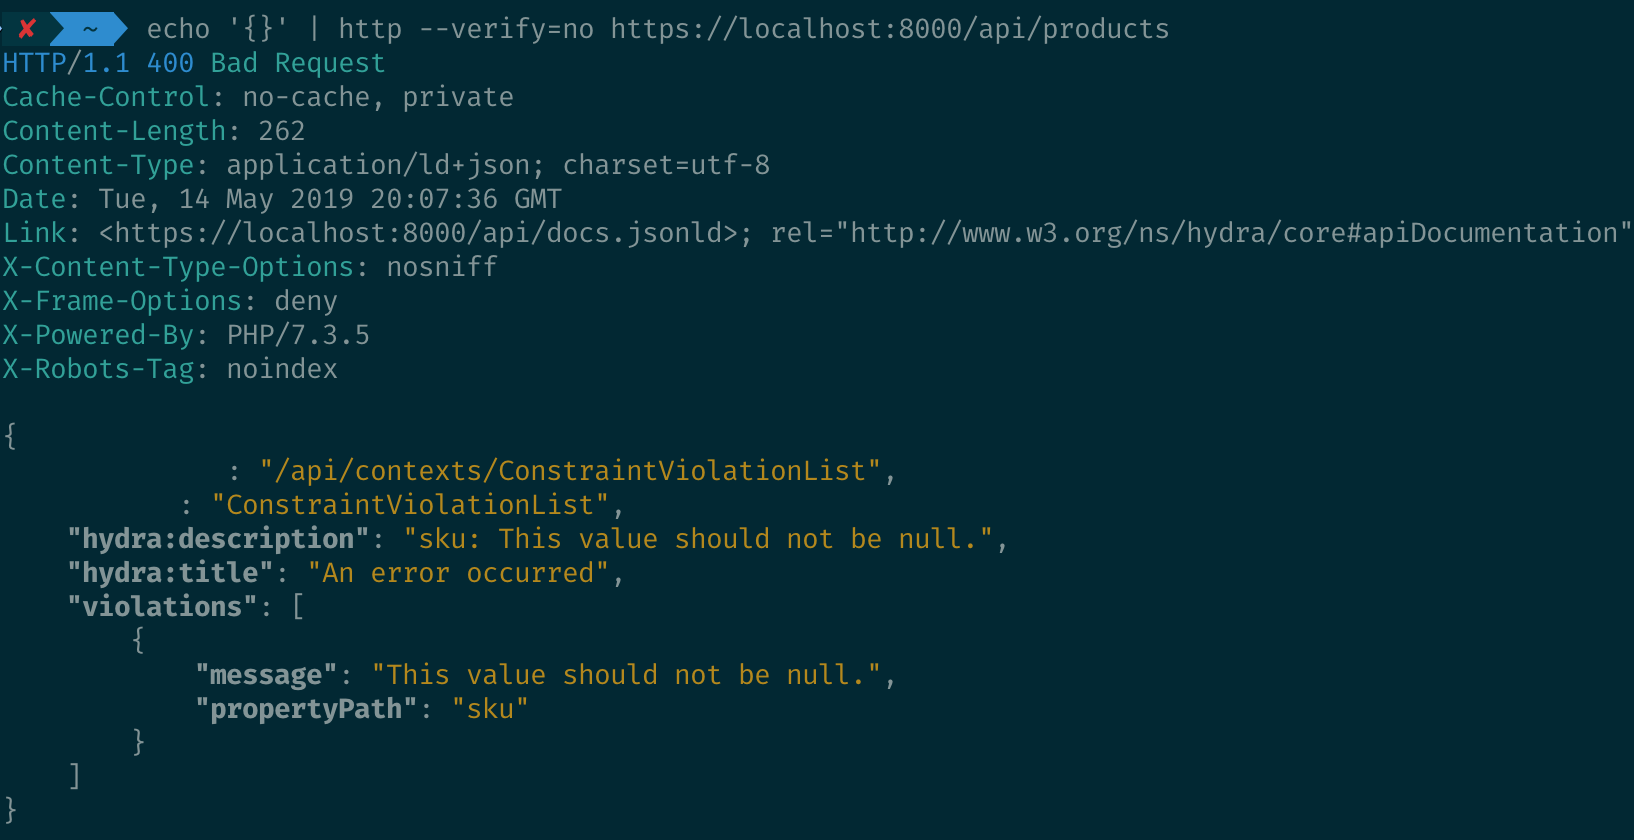
When highlighting:

manger = Str... | closed | 2024-01-15T05:34:36Z | 2024-01-24T10:08:29Z | https://github.com/huggingface/datasets/issues/6588 | [] | d710055071 | 0 |
widgetti/solara | flask | 66 | [Bug] Solara `FigurePlotly` seems to be broken | This code used to work, but now it hangs forever
## Version info
solara 1.10.0
plotly 5.9.0
code
```
import pandas as pd
import solara as sl
import plotly.express as px
@sl.component
def Page():
df = pd.read_csv("conv_intent.csv")
df["text_length"] = df.text.str.len()
df["id"] = list(rang... | closed | 2023-04-12T15:56:59Z | 2024-12-30T15:26:35Z | https://github.com/widgetti/solara/issues/66 | [] | Ben-Epstein | 2 |
OpenBB-finance/OpenBB | python | 6,777 | [🕹️] Write a Article Comparing OpenBB and Other Financial Tools | ### What side quest or challenge are you solving?
Write a Article Comparing OpenBB and Other Financial Tools
### Points
300
### Description
15-October-2024 by Neha Prasad » https://nehaprasad27118.medium.com/openbb-vs-proprietary-financial-tools-the-case-for-open-source-in-finance-9563320ff4cd:
### Provide proof ... | closed | 2024-10-15T06:45:59Z | 2024-10-20T19:01:33Z | https://github.com/OpenBB-finance/OpenBB/issues/6777 | [] | naaa760 | 8 |
davidsandberg/facenet | computer-vision | 918 | 'Logits/BiasAdd:0' not exists | Hi,
I've used the `freeze_graph.py` to freeze a model. The directory of the model contains these files:
> checkpoint
> model-best.ckpt-4.data-00000-of-00001
> model-best.ckpt-7.index
> model-best.ckpt-1.data-00000-of-00001
> model-best.ckpt-4.index
> model-best.ckpt-1.index
> model-best.ckpt-7.data-00000-of... | closed | 2018-11-13T07:35:20Z | 2023-05-31T08:04:35Z | https://github.com/davidsandberg/facenet/issues/918 | [] | modanesh | 1 |
google-research/bert | tensorflow | 930 | FullTokenizer not compatible with tf 2.0 | I'm trying to use FullTokenizer to create my input for my Bert model.
However when I run it I get:
`AttributeError: module tensorflow has no attribute 'gfile'`
I'm using tensorflow 2.0 and it seems that gfile has been moved to the io packed.
tf.io.gfile works for me.
Could we make the FullTokenizer compatible... | open | 2019-11-22T08:18:35Z | 2020-05-22T00:30:10Z | https://github.com/google-research/bert/issues/930 | [] | Jaxing | 5 |
zappa/Zappa | django | 939 | [Migrated] The "zappa update <stage>" command disconnects API Gateway and Lambda function. | Originally from: https://github.com/Miserlou/Zappa/issues/2207 by [hidekuma](https://github.com/hidekuma)
When creating events for scheduling in zappa_settings.json, the API Gateway and Lambda function are disconnected.
The "zappa unschedule <stage>" command also disconnects the two services, is there a solution?
... | closed | 2021-02-20T13:24:47Z | 2024-04-13T19:36:53Z | https://github.com/zappa/Zappa/issues/939 | [
"no-activity",
"auto-closed"
] | jneves | 9 |
flairNLP/flair | nlp | 2,941 | How to use FastText embeddings pre-trained on custom corpus | Hi,
I have pre-trained FastText embeddings on my custom corpus. So I now have .bin and .txt file corresponding to fasttext model and pre-trained vectors.
Any suggestions on how should I use these custom embeddings for training a NER model?
Thanks in advance!
Nitesh | closed | 2022-09-17T14:48:47Z | 2023-02-02T08:01:56Z | https://github.com/flairNLP/flair/issues/2941 | [
"question",
"wontfix"
] | NiteshMethani | 1 |
pyg-team/pytorch_geometric | deep-learning | 9,583 | MessagePassing bugs when processing bipartite graph | ### 🐛 Describe the bug
I find a weird bug of `MessagePassing` module when processing bipartite graph.
## Run code snippet in Google Colab notebook
Here is my code:
```python
import torch
import torch.nn as nn
from torch_geometric.datasets import AmazonBook
from torch_geometric.nn.conv import MessagePassing... | open | 2024-08-08T08:59:48Z | 2024-08-08T09:04:28Z | https://github.com/pyg-team/pytorch_geometric/issues/9583 | [
"bug"
] | liulizhi1996 | 1 |
TarrySingh/Artificial-Intelligence-Deep-Learning-Machine-Learning-Tutorials | pandas | 4 | Try Fashion-MNIST on capsnet | Could you please test and post the result on Fashion-MNIST? https://github.com/zalandoresearch/fashion-mnist
It shares the same size & format as mnist, should be straightforward to integrate. | open | 2017-11-06T20:49:08Z | 2017-11-06T22:18:43Z | https://github.com/TarrySingh/Artificial-Intelligence-Deep-Learning-Machine-Learning-Tutorials/issues/4 | [] | hanxiao | 1 |
ansible/awx | django | 15,597 | make docker-compose-build fails with conflicting dependencies | ### Please confirm the following
- [X] I agree to follow this project's [code of conduct](https://docs.ansible.com/ansible/latest/community/code_of_conduct.html).
- [X] I have checked the [current issues](https://github.com/ansible/awx/issues) for duplicates.
- [X] I understand that AWX is open source software provide... | closed | 2024-10-23T13:50:32Z | 2024-11-08T13:31:05Z | https://github.com/ansible/awx/issues/15597 | [
"type:bug",
"needs_triage",
"community"
] | jean-christophe-manciot | 3 |
chainer/chainer | numpy | 8,531 | cudaErrorIllegalAddress when using ChainerX with ChainerMN | When I ran a training of https://github.com/msakai/chainer-formulanet/tree/4389aa09801c739c35a9ae2ceadd18fdbc74d5a5 using ChainerX and ChainerMN, I encountered `chainerx.ChainerxError: cudaErrorIllegalAddress:an illegal memory access `.
I prepared dataset as follows
```
$ wget http://cl-informatik.uibk.ac.at/cek... | closed | 2020-01-08T05:08:45Z | 2020-05-13T08:35:36Z | https://github.com/chainer/chainer/issues/8531 | [
"cat:bug",
"stale",
"prio:high"
] | msakai | 2 |
facebookresearch/fairseq | pytorch | 4,963 | how do I freeze certain parameters on fairseq when training ? |
I want to train a NMT model (transformer) based on a pretrained model, but I need to freeze some parameters of pretraind model when training ,How do I make some changes on code?
| open | 2023-01-30T05:38:13Z | 2023-03-02T05:59:17Z | https://github.com/facebookresearch/fairseq/issues/4963 | [
"question",
"needs triage"
] | sheoguo | 3 |
fastapi/sqlmodel | sqlalchemy | 342 | Is it possible to instantiate a SQLModel object with relationships from a `dict` type? | ### First Check
- [X] I added a very descriptive title to this issue.
- [X] I used the GitHub search to find a similar issue and didn't find it.
- [X] I searched the SQLModel documentation, with the integrated search.
- [X] I already searched in Google "How to X in SQLModel" and didn't find any information.
- [X... | open | 2022-05-17T04:29:36Z | 2022-09-07T16:18:27Z | https://github.com/fastapi/sqlmodel/issues/342 | [
"question"
] | JLHasson | 5 |
smiley/steamapi | rest-api | 9 | APIInterface: Retrieve all available APIs programmatically with "GetSupportedAPIList" instead of counting on the user/developer | Right now, the master branch only supports the Singleton-based `APIConnection` to call the API, and the user needs to know ahead the _entire_ API path to call it.
This isn't too friendly because you still need to open the API documentation to know what's what, and that isn't in line with SteamAPI's original goal: fast... | closed | 2014-05-27T17:05:35Z | 2016-12-21T16:56:31Z | https://github.com/smiley/steamapi/issues/9 | [
"enhancement"
] | smiley | 2 |
igorbenav/fastcrud | pydantic | 184 | UUID can not be used as primary ID - url paths fail parsing | **Describe the bug or question**
UUID can not be used as primary ID - URL paths fails parsing.
fetch_all works
**To Reproduce**
Create a model using UUId for primary key
```python
id = Column(UUID, primary_key=True, server_default=text("uuid_generate_v4()"))
```
**Description**
This is the error when try... | closed | 2024-12-14T17:40:39Z | 2024-12-23T09:14:14Z | https://github.com/igorbenav/fastcrud/issues/184 | [
"bug"
] | acmeguy | 0 |
qwj/python-proxy | asyncio | 54 | add network throttling feature | Would you be interested in adding a plugin that does network throttling ?
That is:
- limit the bandtwidth
- add delays
I am using this to mimic network conditions to test browser page loads. I've implemented it using a simple port forwarder + socks5 server ar https://github.com/tarekziade/tinap
But your pro... | closed | 2019-09-18T07:15:40Z | 2019-10-06T15:37:37Z | https://github.com/qwj/python-proxy/issues/54 | [] | tarekziade | 1 |
skypilot-org/skypilot | data-science | 5,020 | [GCP] GCS storage no longer works with owner role | I have an API server deployed with a GCP credentials that has project owner role, it cannot longer use GCS file_mounts as before:
cluster.yaml:
```yaml
resources:
cloud: kubernetes
cpus: 2+
file_mounts:
/my_data:
name: $NEW_BUCKET
store: gcs
setup: |
echo "From FUSE" > /my_data/test.txt
run: |
ca... | open | 2025-03-24T06:12:49Z | 2025-03-24T17:59:31Z | https://github.com/skypilot-org/skypilot/issues/5020 | [] | aylei | 3 |
gevent/gevent | asyncio | 2,054 | 3.13: Monkey patching broken: '_MainThread' object has no attribute '_tstate_lock': monkey.py, line 826, in patch_thread | Found in vivo testing `geventmp`: https://github.com/karellen/geventmp/actions/runs/10378049652/job/29958033565#step:4:602
```
File /home/runner/work/geventmp/geventmp/target/reports/integrationtests/monkey_mp_tests:
File /home/runner/work/geventmp/geventmp/target/reports/integrationtests/monkey_mp_tests.err:
... | closed | 2024-09-10T20:49:57Z | 2024-10-10T05:51:28Z | https://github.com/gevent/gevent/issues/2054 | [] | arcivanov | 5 |
CPJKU/madmom | numpy | 407 | 'music tempo estimation' is the same as 'music classification'? | Hello.
Recently,I do some research on music classification .I wan't to know that 'music tempo estimation' is the same as 'music classification'? | closed | 2019-01-08T11:54:41Z | 2019-01-08T13:06:10Z | https://github.com/CPJKU/madmom/issues/407 | [] | THtanghuan | 1 |
luispedro/mahotas | numpy | 109 | different shape has the same Zernike moments value | 

as picture shows the i have two different shapes (one is part of the other), but it's ... | open | 2019-12-01T14:52:40Z | 2019-12-03T06:25:01Z | https://github.com/luispedro/mahotas/issues/109 | [] | mashuai191 | 4 |
jonaswinkler/paperless-ng | django | 415 | Consumer status on the dashboard | Add ability to see the status of the document consumer per document on the dashboard
* with progress bars
* with error messages when consumption fails
* with success messages and buttons / links to open documents when consumption finished
*This will not work with Apache `mod_wsgi`*, since this change requires m... | closed | 2021-01-23T12:43:01Z | 2021-02-06T22:27:01Z | https://github.com/jonaswinkler/paperless-ng/issues/415 | [
"feature request",
"fixed in next release"
] | jonaswinkler | 33 |
ultralytics/yolov5 | machine-learning | 12,925 | Multi-GPU train | ### Search before asking
- [X] I have searched the YOLOv5 [issues](https://github.com/ultralytics/yolov5/issues) and [discussions](https://github.com/ultralytics/yolov5/discussions) and found no similar questions.
### Question
First of all, thank you for your always kind and detailed answers!
I'm trying to train... | closed | 2024-04-15T15:31:10Z | 2024-05-26T00:23:56Z | https://github.com/ultralytics/yolov5/issues/12925 | [
"question",
"Stale"
] | Cho-Hong-Seok | 2 |
opengeos/leafmap | jupyter | 424 | In leafmap.tms_to_geotiff(), add JP2000 and ECW formats; also option of coordinate system for output raster. | <!-- Please search existing issues to avoid creating duplicates. -->
### Description
Describe the feature (e.g., new functions/tutorials) you would like to propose.
Tell us what can be achieved with this new feature and what's the expected outcome.
### Source code
```
Paste your source code here if have s... | closed | 2023-04-21T09:31:31Z | 2023-04-22T04:31:38Z | https://github.com/opengeos/leafmap/issues/424 | [
"Feature Request"
] | ravishbapna | 1 |
junyanz/pytorch-CycleGAN-and-pix2pix | pytorch | 1,170 | Can pause training? | Could I pause the training whit ctrl + c? Is the next time it will keep going on where I stop? | closed | 2020-10-23T13:13:02Z | 2022-08-19T06:30:28Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/1170 | [] | darrenleeleelee1 | 1 |
ymcui/Chinese-LLaMA-Alpaca | nlp | 519 | 让模型基于私有知识回答问题应该怎样做? |
我想让模型基于我的私有数据回答问题。请问应该是怎样的流程?
1. 指令精调
2. 预训练+指令精调
3. 直接外部向量库
应该是哪种最合适。私有数据大多是一些 markdown 文档。 | closed | 2023-06-06T08:32:11Z | 2023-06-06T09:48:32Z | https://github.com/ymcui/Chinese-LLaMA-Alpaca/issues/519 | [] | mayi203 | 4 |
vitalik/django-ninja | django | 1,283 | [Question] Unable to cache paginated queryset `PicklingError` | Hellooo 👋
I'm having an issue with caching a paginated queryset that uses `prefetch_related` or `select_related`. Initially, I was using `@paginate` from Django Ninja, however, I was not able to cache it properly as the `count` query would always be requested since it happens outside my API view. _(Please let me k... | closed | 2024-08-27T11:02:46Z | 2024-08-27T14:36:13Z | https://github.com/vitalik/django-ninja/issues/1283 | [] | Tragio | 4 |
axnsan12/drf-yasg | rest-api | 193 | Internal server error when calling schemaView - Python3.6 regex issue | **Traceback:**
```
Log file created on 2018-08-29T14:59:17.623254
29-08-2018:14:59:21,302 ERROR [exception.py:118] Internal Server Error: /
Traceback (most recent call last):
File "/usr/lib/python3.6/site-packages/django/core/handlers/exception.py", line 35, in inner
response = get_response(request)
F... | closed | 2018-08-29T16:48:00Z | 2018-09-10T05:23:14Z | https://github.com/axnsan12/drf-yasg/issues/193 | [
"bug"
] | arvindnrbt | 2 |
babysor/MockingBird | pytorch | 80 | 合成失败 | 你好 我使用sishell3数据集来进行合成 ,使用的是你提供的预训练模型出现如下错误。请问如何修改呢‘?
Traceback (most recent call last):
File "G:\tj\anaconda\envs\gpu2\lib\tarfile.py", line 187, in nti
n = int(s.strip() or "0", 8)
ValueError: invalid literal for int() with base 8: 'build_te'
During handling of the above exception, another exception occu... | closed | 2021-09-10T03:21:27Z | 2023-02-18T14:29:19Z | https://github.com/babysor/MockingBird/issues/80 | [] | ajunbudou | 5 |
pytorch/pytorch | machine-learning | 149,746 | enabled dynamic rblock scaling on H100 | ### 🐛 Describe the bug
Apply https://github.com/pytorch/pytorch/pull/109275 to h100.
### Error logs
_No response_
### Versions
.
cc @chauhang @penguinwu @voznesenskym @EikanWang @jgong5 @Guobing-Chen @XiaobingSuper @zhuhaozhe @blzheng @wenzhe-nrv @jiayisunx @ipiszy @chenyang78 @kadeng @muchulee8 @amjames @aakhun... | open | 2025-03-21T17:34:07Z | 2025-03-21T17:34:21Z | https://github.com/pytorch/pytorch/issues/149746 | [
"triaged",
"oncall: pt2",
"module: inductor"
] | shunting314 | 0 |
AUTOMATIC1111/stable-diffusion-webui | pytorch | 15,827 | [Bug]: Torch is not able to use GPU | ### Checklist
- [ ] The issue exists after disabling all extensions
- [X] The issue exists on a clean installation of webui
- [ ] The issue is caused by an extension, but I believe it is caused by a bug in the webui
- [X] The issue exists in the current version of the webui
- [ ] The issue has not been reported ... | open | 2024-05-17T21:49:51Z | 2024-08-26T11:59:02Z | https://github.com/AUTOMATIC1111/stable-diffusion-webui/issues/15827 | [
"bug-report"
] | gabikreal1 | 4 |
ymcui/Chinese-LLaMA-Alpaca | nlp | 173 | 扩充后的词表,总共有多少条? | 扩充后的词表,总共有多少条? | closed | 2023-04-18T05:34:50Z | 2023-05-13T22:02:24Z | https://github.com/ymcui/Chinese-LLaMA-Alpaca/issues/173 | [
"stale"
] | mellivoraPKU | 3 |
gunthercox/ChatterBot | machine-learning | 1,547 | Concurrent connections | Since create_conversation is removed now (in 1.0 alpha), how to create concurrent conversation? | closed | 2019-01-05T13:53:54Z | 2019-11-08T14:23:06Z | https://github.com/gunthercox/ChatterBot/issues/1547 | [
"answered"
] | kulkarniniraj | 3 |
pyppeteer/pyppeteer | automation | 63 | Page goto returns None Even in Headmode | Hi,
For some URLs, the goto() does not fail, but still returns None. But when we process it later or after a no of retries, it returns correct response.
For example url:
https://www.vitals.com/dentists/Dr_John_C_Paris.html
I have used pyppeteer2 as well as pyppeteer with Python 3.6
Here is a minimal ex... | closed | 2020-03-13T09:25:49Z | 2020-03-14T15:42:19Z | https://github.com/pyppeteer/pyppeteer/issues/63 | [
"duplicate"
] | VishnuAtDevopStation | 4 |
pytorch/pytorch | deep-learning | 149,521 | DISABLED test_lazy_module4 (__main__.NNModuleTests) | Platforms: linux, rocm
This test was disabled because it is failing in CI. See [recent examples](https://hud.pytorch.org/flakytest?name=test_lazy_module4&suite=NNModuleTests&limit=100) and the most recent trunk [workflow logs](https://github.com/pytorch/pytorch/runs/39028613778).
Over the past 3 hours, it has been de... | open | 2025-03-19T15:43:18Z | 2025-03-19T15:43:22Z | https://github.com/pytorch/pytorch/issues/149521 | [
"triaged",
"module: flaky-tests",
"skipped",
"oncall: pt2",
"module: dynamo"
] | pytorch-bot[bot] | 1 |
feder-cr/Jobs_Applier_AI_Agent_AIHawk | automation | 563 | [FEATURE]: Answer 0 years of work experiece unless user writes higher in answers.json | ### Feature summary
When asked about years of experience, the bot should put 0 by default and then remember that answer in answers.json.
### Feature description
When asked about years of experience, the bot should put 0 by default and then remember that answer in `answers.json`. After a couple hours of job applying... | closed | 2024-10-18T22:36:07Z | 2024-10-26T21:52:03Z | https://github.com/feder-cr/Jobs_Applier_AI_Agent_AIHawk/issues/563 | [
"enhancement"
] | sloganking | 2 |
huggingface/pytorch-image-models | pytorch | 1,305 | Can you add "An Improved One millisecond Mobile Backbone" (MobileOne) | As above | closed | 2022-06-14T12:17:37Z | 2023-08-30T05:52:27Z | https://github.com/huggingface/pytorch-image-models/issues/1305 | [
"enhancement"
] | ghoshaw | 7 |
airtai/faststream | asyncio | 1,375 | Bug: Deserialization of list[Model[T]] not working in v5 | **Describe the bug**
I just upgraded to v5 and all of my subscribers that consume from a redis list broke. I use a Pydantic model with a generic, kind of like this:
```python
T = typing.TypeVar('T', bound=BaseModel | dict)
class Event(BaseModel, typing.Generic[T]):
uid: str
data: T
```
I now for a... | closed | 2024-04-16T22:50:50Z | 2024-04-17T15:22:55Z | https://github.com/airtai/faststream/issues/1375 | [
"bug"
] | chrisgoddard | 3 |
kizniche/Mycodo | automation | 506 | Global Unit/Conversion System | Changes with version 7.0 that will break current functionality (upgrade will fail, need to recreate database).
1. Full unit conversion system (select what unit to use for each sensor measurement) | closed | 2018-07-19T22:51:30Z | 2018-07-30T22:37:29Z | https://github.com/kizniche/Mycodo/issues/506 | [
"enhancement"
] | kizniche | 10 |
bmoscon/cryptofeed | asyncio | 106 | raise UnsupportedTradingPair(f'{pair} is not supported on {exchange}') | demo.py throw this error | closed | 2019-06-20T15:34:08Z | 2019-06-20T17:47:25Z | https://github.com/bmoscon/cryptofeed/issues/106 | [] | javy-kong | 0 |
tqdm/tqdm | pandas | 1,287 | Blank lines of nested progress bar in VSCode + ipynb | - [x] I have marked all applicable categories:
+ [ ] exception-raising bug
+ [x] visual output bug
- [x] I have visited the [source website], and in particular
read the [known issues]
- [x] I have searched through the [issue tracker] for duplicates
- [x] I have mentioned version numbers, operating syste... | closed | 2022-01-10T00:29:22Z | 2022-03-26T19:20:41Z | https://github.com/tqdm/tqdm/issues/1287 | [
"invalid ⛔",
"p2-bug-warning ⚠",
"submodule-notebook 📓"
] | Joilence | 4 |
marcomusy/vedo | numpy | 516 | Customized hotkeys | Hello,
This might be a vtk question, but I'm wondering if vedo can create customized hotkeys that overwrite the default hotkeys.
For example, can I set a new keypress p to prevent performing a pick up mode.
Thanks for your time! | closed | 2021-11-07T03:14:44Z | 2021-11-08T04:36:51Z | https://github.com/marcomusy/vedo/issues/516 | [] | Tai-Hsien | 5 |
seleniumbase/SeleniumBase | web-scraping | 2,209 | `driver.uc_click(selector)` needs a JS backup option in case of `ElementClickInterceptedException` | #### `driver.uc_click(selector)` needs a JS backup option in case of `ElementClickInterceptedException`
--------
There are some cases where `driver.uc_click(selector)` (a UC-Mode-only method) runs into an `ElementClickInterceptedException`. A backup option should be put in to use `driver.js_click(selector)` in th... | closed | 2023-10-26T00:17:49Z | 2023-10-27T07:53:07Z | https://github.com/seleniumbase/SeleniumBase/issues/2209 | [
"enhancement",
"UC Mode / CDP Mode"
] | mdmintz | 1 |
cchen156/Learning-to-See-in-the-Dark | tensorflow | 61 | why the shape of input_full is {1,1424,2128,4} but output is {1,2848,4256,3}?? | the fcn network is end to end and their have four maxpool and four deconv, i think it should output same shape, but why the output shape is {1,2848,4256,3}?
<img width="618" alt="default" src="https://user-images.githubusercontent.com/6647857/47829438-76b88c00-ddc2-11e8-8300-1c2f5c9da196.png">
| open | 2018-11-01T02:41:05Z | 2018-11-01T03:50:23Z | https://github.com/cchen156/Learning-to-See-in-the-Dark/issues/61 | [] | zkeenly | 1 |
viewflow/viewflow | django | 53 | Unify start.activate and view.next | closed | 2014-06-30T11:11:24Z | 2014-06-30T12:37:50Z | https://github.com/viewflow/viewflow/issues/53 | [
"dev/flow"
] | kmmbvnr | 1 | |
flasgger/flasgger | api | 7 | Handling multiple http methods and routes for a single function. | How does flasgger handle multiple http methods in a single route? It seems that there is no way to have two different sets of documentation for view function that has a GET and POST. Also I have view functions that have multiple routes such as /events and events/:id. How can I produce two separate definition objects?
| closed | 2015-11-30T20:03:38Z | 2016-01-11T17:35:07Z | https://github.com/flasgger/flasgger/issues/7 | [] | GGross5213 | 2 |
pyppeteer/pyppeteer | automation | 155 | Add support for downloading/using ARM Chromium binaries (Raspberry Pi, ...) | The previous repo already had issues for this:
https://github.com/miyakogi/pyppeteer/issues/115, https://github.com/miyakogi/pyppeteer/issues/284
Puppeteer also has an issue open for this:
https://github.com/puppeteer/puppeteer/issues/550 | open | 2020-07-30T09:16:40Z | 2021-08-25T02:45:54Z | https://github.com/pyppeteer/pyppeteer/issues/155 | [
"help wanted",
"priority-low"
] | thp | 4 |
hankcs/HanLP | nlp | 1,001 | 新词发现在300mb的语料上报内存不够 | <!--
注意事项和版本号必填,否则不回复。若希望尽快得到回复,请按模板认真填写,谢谢合作。
-->
## 注意事项
请确认下列注意事项:
* 我已仔细阅读下列文档,都没有找到答案:
- [首页文档](https://github.com/hankcs/HanLP)
- [wiki](https://github.com/hankcs/HanLP/wiki)
- [常见问题](https://github.com/hankcs/HanLP/wiki/FAQ)
* 我已经通过[Google](https://www.google.com/#newwindow=1&q=HanLP)和[issue区检... | closed | 2018-10-18T04:48:11Z | 2020-01-01T10:56:19Z | https://github.com/hankcs/HanLP/issues/1001 | [
"ignored"
] | SefaZeng | 2 |
AUTOMATIC1111/stable-diffusion-webui | deep-learning | 16,696 | [Bug]: Unable to create venv, The system cannot find the path specified. on error code 9009 | ### Checklist
- [ ] The issue exists after disabling all extensions
- [X] The issue exists on a clean installation of webui
- [ ] The issue is caused by an extension, but I believe it is caused by a bug in the webui
- [X] The issue exists in the current version of the webui
- [ ] The issue has not been reported before... | open | 2024-11-29T21:23:46Z | 2024-11-29T21:23:46Z | https://github.com/AUTOMATIC1111/stable-diffusion-webui/issues/16696 | [
"bug-report"
] | arisutendou-key | 0 |
pydata/pandas-datareader | pandas | 149 | Eurostat: Not working for a number of data series | Hi guys,
I've been trying to get data out of Eurostat, however, I have not had much luck with data series other than the one given in the docs [here](http://pandas-datareader.readthedocs.org/en/latest/remote_data.html#remote-data-eurostat).
So if I try to get the HICP data, I get the following error. Does anyone have... | closed | 2015-12-17T22:47:45Z | 2016-06-28T00:07:32Z | https://github.com/pydata/pandas-datareader/issues/149 | [] | esvhd | 4 |
yuka-friends/Windrecorder | streamlit | 83 | feat: 记录前台进程名,以在搜索时作为线索呈现 | PRD WIP | closed | 2023-12-29T11:33:57Z | 2024-02-09T16:18:19Z | https://github.com/yuka-friends/Windrecorder/issues/83 | [
"enhancement",
"P2"
] | Antonoko | 0 |
matplotlib/matplotlib | data-visualization | 28,944 | [Bug]: calling title before making polar plot | ### Bug summary
Hi, sorry to bother if it is not an issue at all.
Setting title first and then making polar plot messes up the plot and it makes the plot in usual cartesian plane
### Code for reproduction
```Python
import matplotlib.pyplot as plt
theta = [0, 1, 2, 3, 4, 5, 6]
r = [0, 1, 0.5, 1, 0.5, 1, 0]
pl... | closed | 2024-10-07T10:59:43Z | 2024-10-29T21:13:41Z | https://github.com/matplotlib/matplotlib/issues/28944 | [
"Documentation",
"Community support"
] | exekerey | 1 |
tqdm/tqdm | jupyter | 915 | If too many files are opened inside a tqdm loop, it swallows the useful error message | - [X] I have marked all applicable categories:
+ [X] exception-raising bug
+ [ ] visual output bug
+ [ ] documentation request (i.e. "X is missing from the documentation." If instead I want to ask "how to use X?" I understand [StackOverflow#tqdm] is more appropriate)
+ [ ] new feature request
- [X]... | open | 2020-03-11T17:06:21Z | 2020-03-12T17:03:10Z | https://github.com/tqdm/tqdm/issues/915 | [] | benhannel | 1 |
pytorch/vision | machine-learning | 8,816 | Python 3.13 build is failing on windows with "No such file or directory" | ### 🐛 Describe the bug
https://github.com/pytorch/vision/actions/runs/12361066769/job/34499347726?pr=8815
```
Emitting ninja build file C:\actions-runner\_work\vision\vision\pytorch\vision\build\temp.win-amd64-cpython-313\Release\build.ninja...
error: [Errno 2] No such file or directory: 'C:\\actions-runner\\_wo... | closed | 2024-12-16T21:57:34Z | 2024-12-17T03:00:47Z | https://github.com/pytorch/vision/issues/8816 | [] | atalman | 0 |
python-gino/gino | asyncio | 776 | Setting variables on connection | Greetings,
I have a use case where I need to set the variable for each session or connection.
and I am able to accomplish it using the asyncpg directly
```python
import asyncpg
con = await asyncpg.connect('postgresql://tenants@localhost:5433/internal?application_name=app_name')
r = await con.fetchrow("SELECT cu... | open | 2021-03-29T22:22:19Z | 2021-05-30T12:38:54Z | https://github.com/python-gino/gino/issues/776 | [
"question"
] | mpdevilleres | 3 |
keras-team/autokeras | tensorflow | 1,369 | Partly Pre-trained model | Hello,
I have been trying to use AutoKeras for my project. However, I have a problem that I do not know how to solve. The model I would like to train is an encoder-decoder. However, I would like to pre-train the encoder part, freeze its weights, and then train the decoder section. Is it possible to do it in AutoKeras?... | closed | 2020-10-07T07:42:37Z | 2020-10-15T09:57:38Z | https://github.com/keras-team/autokeras/issues/1369 | [] | mshahriarish | 1 |
LibrePhotos/librephotos | django | 1,087 | feeback on new caption model: screen refresh needed | When caption "generate" is pressed, "generate" becomes grey for a while, then goes back to blue. Nevertheless caption field is still blank.
Text may appear after a browser refresh request. | closed | 2023-12-02T12:47:46Z | 2024-03-29T15:47:07Z | https://github.com/LibrePhotos/librephotos/issues/1087 | [
"bug"
] | loulou91 | 2 |
ageitgey/face_recognition | machine-learning | 1,510 | t colanb | * face_recognition version:
* Python version:
* Operating System:
### Description
Describe what you were trying to get done.
Tell us what happened, what went wrong, and what you expected to happen.
IMPORTANT: If your issue is related to a specific picture, include it so others can reproduce the issue.
### ... | open | 2023-05-25T22:16:06Z | 2023-05-25T22:16:06Z | https://github.com/ageitgey/face_recognition/issues/1510 | [] | bxck75 | 0 |
huggingface/diffusers | deep-learning | 11,005 | pipeline_wan_i2v.py: minor discrepancy between arg default and docstring | ### Describe the bug
https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/wan/pipeline_wan_i2v.py
Line 447 (arg default):
```output_type: Optional[str] = "np",```
Line 496 (docstring):
```output_type (`str`, *optional*, defaults to `"pil"`):```
### Reproduction
n/a
### Logs
```shell
```
#... | open | 2025-03-07T16:37:48Z | 2025-03-11T17:45:09Z | https://github.com/huggingface/diffusers/issues/11005 | [
"bug"
] | rolux | 1 |
MagicStack/asyncpg | asyncio | 1,155 | Timeout configuration for multi-host config | <!--
Thank you for reporting an issue/feature request.
If this is a feature request, please disregard this template. If this is
a bug report, please answer to the questions below.
It will be much easier for us to fix the issue if a test case that reproduces
the problem is provided, with clear instructions on ... | open | 2024-05-18T18:44:16Z | 2024-10-28T17:38:11Z | https://github.com/MagicStack/asyncpg/issues/1155 | [] | inikolaev | 1 |
StackStorm/st2 | automation | 6,177 | Timeout support for Orquesta tasks | I have found missing the implementation of timeout logic for the Orquesta tasks.
It would be really nice to have something like this:
```yaml
...
tasks:
my_task:
action: mypack.myaction
retry:
delay: 10
count: 3
timeout: 120
next:
- when: <% timedout() %>
d... | open | 2024-04-05T09:07:27Z | 2024-06-14T15:07:16Z | https://github.com/StackStorm/st2/issues/6177 | [] | jesvilnie | 2 |
kubeflow/katib | scikit-learn | 1,604 | [Documentation] Add XGBoostJob and Argo Workflows to supported Katib Worker types | /kind feature
After this PR: https://github.com/kubeflow/katib/pull/1603 we should add `XGBoostJob` to the supported Katib Workers: https://www.kubeflow.org/docs/components/katib/overview/#worker-job.
| closed | 2021-08-02T21:06:46Z | 2021-08-05T21:15:42Z | https://github.com/kubeflow/katib/issues/1604 | [
"kind/feature"
] | andreyvelich | 1 |
autogluon/autogluon | data-science | 3,879 | [BUG] Installing autogluon.multimodal fails with AssertionError | **Bug Report Checklist**
<!-- Please ensure at least one of the following to help the developers troubleshoot the problem: -->
- [ ] I provided code that demonstrates a minimal reproducible example. <!-- Ideal, especially via source install -->
- [ ] I confirmed bug exists on the latest mainline of AutoGluon via s... | closed | 2024-01-23T23:16:33Z | 2024-06-28T22:20:36Z | https://github.com/autogluon/autogluon/issues/3879 | [
"bug: unconfirmed",
"Needs Triage",
"module: multimodal"
] | fuomag9 | 3 |
ageitgey/face_recognition | python | 817 | Error installing face recognition models | * face_recognition version:1.2.2
* Python version:3.5
* Operating System:Raspbian Stretch
### Description
I get this error when i try to install face_recognition using pip.

... | open | 2019-05-11T06:27:07Z | 2019-07-02T17:28:43Z | https://github.com/ageitgey/face_recognition/issues/817 | [] | abhaykrishnan | 1 |
falconry/falcon | api | 1,726 | No way | He took the code beginning of 2017, not 7 years ago. Don’t be a dick as the source code was stolen at that point and implemented on this. | closed | 2020-05-29T14:40:17Z | 2020-05-29T17:50:41Z | https://github.com/falconry/falcon/issues/1726 | [
"duplicate"
] | dmproia | 7 |
geex-arts/django-jet | django | 158 | Unable to login to admin | TypeError at /admin/
argument of type 'ValuesListQuerySet' is not iterable
Error during template rendering in virtualenv/local/lib/python2.7/site-packages/jet/templates/admin/base.html, error at line 176
 0.96.10 on Linux Mint 21.3 Cinnamon.
I made a script: "keyboard.send_key(Key.DOWN)", assigned a Window Filter (window class scummvm.scummvm) and a Hotkey ("s").
It sends both, first Key.DOWN, then "s".
_Originally posted by @SymbolicFrank in https://github.com/autokey/auto... | open | 2024-08-01T17:32:14Z | 2024-08-03T13:47:15Z | https://github.com/autokey/autokey/issues/953 | [
"user support"
] | SymbolicFrank | 5 |
deezer/spleeter | deep-learning | 745 | spleeter++ c++ version------>error | `/data/spleeter_cmake/spleeter/application/main.cpp:5:10: fatal error: spleeter/argument_parser/argument_parser.h: No such file or directory
/data/spleeter_cmake/spleeter/spleeter/audio/ffmpeg_audio_adapter.cpp:6:10: fatal error: spleeter/audio/ffmpeg_audio_adapter.h: No such file or directory
/data/spleeter_cmake/sp... | closed | 2022-04-01T02:48:16Z | 2022-04-02T05:42:57Z | https://github.com/deezer/spleeter/issues/745 | [
"bug",
"invalid"
] | KangChou | 3 |
healthchecks/healthchecks | django | 1,136 | [Contribution] Support CockroachDB as Database Engine | I've been experimenting with CockroachDB and thought it could be a valuable addition as a database option for our app. It's compatible with PostgreSQL, so integrating it should be straightforward.
CockroachDB's distributed architecture ensures high availability, meaning our app wouldn't rely on a single database that... | closed | 2025-03-23T21:30:26Z | 2025-03-23T22:19:15Z | https://github.com/healthchecks/healthchecks/issues/1136 | [] | adyavanapalli | 2 |
amidaware/tacticalrmm | django | 912 | History doesn't sort correctly - ignores year | History is out of order, wonder if this is a problem in other tabs too?
See
| closed | 2022-01-02T22:30:53Z | 2022-03-17T03:59:15Z | https://github.com/amidaware/tacticalrmm/issues/912 | [
"bug"
] | silversword411 | 0 |
hack4impact/flask-base | flask | 195 | Installing on Windows? Unable to get redis installation | Everytime I start a project I try to figure out if it will work in a Windows environment. Without finely reading the installation I didn't notice that redis doesn't contain installation instructions for Windows.
Looking through the rest of the innertubes it seems that there are some workarounds but are imperfect. Th... | closed | 2019-10-20T16:50:27Z | 2019-10-23T11:53:24Z | https://github.com/hack4impact/flask-base/issues/195 | [] | ripgith | 2 |
pydantic/logfire | fastapi | 169 | Test with older versions of pydantic | In https://github.com/pydantic/logfire/pull/163 we added code for pydantic v1, and in https://github.com/pydantic/logfire/pull/160/ we added code for v2.4. We should have automated testing for this. | open | 2024-05-13T11:27:01Z | 2024-11-04T20:30:11Z | https://github.com/pydantic/logfire/issues/169 | [
"Testing",
"P3"
] | alexmojaki | 1 |
vaexio/vaex | data-science | 1,661 | [BUG-REPORT] Cannot add virtual column that is output of different dataframe | Thank you for reaching out and helping us improve Vaex!
**Description**
If I have 2 dataframes, `df1` and `df2` and I want the output of an expression of `df1` to be applied to `df2`, I currently cannot.
```
import vaex
import numpy as np
ids = list(range(100))
data1 = {
'a': np.random.random(100),
... | closed | 2021-10-21T00:10:04Z | 2021-10-21T13:50:32Z | https://github.com/vaexio/vaex/issues/1661 | [] | Ben-Epstein | 3 |
albumentations-team/albumentations | machine-learning | 1,745 | [Performance] Move add + multiply to albucore | Used in BrightnessContrast | closed | 2024-05-23T20:13:07Z | 2024-06-05T01:28:41Z | https://github.com/albumentations-team/albumentations/issues/1745 | [
"Speed Improvements",
"Tech debt"
] | ternaus | 1 |
iusztinpaul/energy-forecasting | streamlit | 15 | Error while running training-pipeline because it is not being able to find libomp.dylib | First of all, great work Paul!
I am running on Apple M1.
I was able to run the feature-pipeline without any issues. However when I run,
python -m training_pipeline.hyperparameter_tuning
as part of training-pipeline, I get the following error:
OSError: dlopen(/Users/vatulparakh/Library/Caches/pypoetry/virtualenvs... | closed | 2023-08-06T14:12:21Z | 2023-08-21T14:08:59Z | https://github.com/iusztinpaul/energy-forecasting/issues/15 | [] | VATUL123 | 7 |
fastapi/sqlmodel | pydantic | 394 | ImportError with opencensus-ext-sqlalchemy: cannot import name 'create_mock_engine' from 'sqlalchemy.engine' | ### First Check
- [X] I added a very descriptive title to this issue.
- [X] I used the GitHub search to find a similar issue and didn't find it.
- [X] I searched the SQLModel documentation, with the integrated search.
- [X] I already searched in Google "How to X in SQLModel" and didn't find any information.
- [X... | closed | 2022-08-03T08:58:26Z | 2022-08-09T16:40:46Z | https://github.com/fastapi/sqlmodel/issues/394 | [
"question"
] | martin-greentrax | 2 |
unionai-oss/pandera | pandas | 1,721 | Arrow String checks not compatible ('re.Pattern' object has no attribute 'startswith') | **Describe the bug**
A clear and concise description of what the bug is.
- [x] I have checked that this issue has not already been reported.
- [x] I have confirmed this bug exists on the latest version of pandera.
- [ ] (optional) I have confirmed this bug exists on the main branch of pandera.
**Note**: Please... | closed | 2024-06-29T14:49:17Z | 2024-07-04T19:49:08Z | https://github.com/unionai-oss/pandera/issues/1721 | [
"bug"
] | dan9401 | 3 |
serengil/deepface | deep-learning | 1,090 | Question: basemodel DbLib.py | Consider [this line](https://github.com/serengil/deepface/blob/dea697c6ec5b89375cdbc376aa680a10f4231c42/deepface/basemodels/Dlib.py#L67) in DbLib.py
```python
self.layers = [DlibMetaData()]
```
What exactly is this for ? (member layers is not accessed anywhere) | closed | 2024-03-10T14:46:32Z | 2024-03-10T14:59:28Z | https://github.com/serengil/deepface/issues/1090 | [
"enhancement"
] | AndreaLanfranchi | 2 |
cchen156/Learning-to-See-in-the-Dark | tensorflow | 1 | How about training with 8-bit jpg image? | I just tried to train Sony dataset after converting the raw data into jpg image and found the result quite terrible. So are there any tricks when training 8bit data?
P.S.:
The channel number of input is 12, which results from packing each channel of rgb into four. | closed | 2018-05-11T09:58:12Z | 2018-05-14T09:37:07Z | https://github.com/cchen156/Learning-to-See-in-the-Dark/issues/1 | [] | ArsenLuca | 5 |
NVlabs/neuralangelo | computer-vision | 171 | colmap: error while loading shared libraries: libcudart.so.11.0: cannot open shared object file: No such file or directory | I'm trying to use colab, but images folder is not generated because of this error | open | 2023-12-15T19:20:58Z | 2024-01-09T21:22:23Z | https://github.com/NVlabs/neuralangelo/issues/171 | [] | TafnesBarbosa | 1 |
unit8co/darts | data-science | 2,569 | [BUG] optimization is too slow AWS EC2 instances | **Describe the bug**
first of all, I love the library and **thank you** for open sourcing and maintaining it.
Issue:
I am optimizing a forecasting model with Optuna and the individual trials finish in about 2 mins on M3 Max Macbook pro ( Number of Cores: 14 (10 performance and 4 efficiency)) for a wide variety of... | open | 2024-10-23T15:36:00Z | 2024-10-25T17:33:26Z | https://github.com/unit8co/darts/issues/2569 | [
"bug",
"triage"
] | raamana | 3 |
microsoft/nni | machine-learning | 5,574 | Infinite "collect_gpu_info" and gpu not found | **Describe the issue**:
During the Hello NAS tutorial for v3.0rc1, when i launch the experiment as described a number of issues arise:
1. Even though i edit `exp.config.trial_gpu_number = 1` and `exp.config.training_service.use_active_gpu = True`, the logger prints "no gpu found, edit exp.config.trial_gpu_number.
... | open | 2023-05-23T09:28:02Z | 2024-02-15T14:47:14Z | https://github.com/microsoft/nni/issues/5574 | [] | chachus | 10 |
roboflow/supervision | computer-vision | 751 | `PolygonZone` 2.0 | ### Search before asking
- [X] I have searched the Supervision [issues](https://github.com/roboflow/supervision/issues) and found no similar feature requests.
### Description
TODO
### Use case
TODO
### Additional
- do not require `resolution_wh`
- offers current and accumulated count
- delivery... | closed | 2024-01-18T20:44:46Z | 2024-01-26T13:53:18Z | https://github.com/roboflow/supervision/issues/751 | [
"enhancement",
"Q1.2024",
"planning"
] | SkalskiP | 0 |
aiogram/aiogram | asyncio | 1,530 | Migration docs for Dispatcher's update processing | Issue #1528 helped to identify another direction that we forgot to describe in the migration guide from version 2 to version 3 | closed | 2024-06-30T09:57:53Z | 2024-07-06T17:33:02Z | https://github.com/aiogram/aiogram/issues/1530 | [
"docs",
"3.x"
] | Olegt0rr | 0 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.