
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
deepset-ai/haystack | nlp | 8,025 | Add default "else" branch to the conditional router | When adding a conditional router with many branching options, it would be good to have an easy way to define a default "catch-all" branch in case the other conditions are not met. In other words, would it be possible to reproduce the following logic with a conditional router:
```
if [condition 1]: branch 1
if [conditi... | closed | 2024-07-15T08:48:39Z | 2024-09-16T07:35:00Z | https://github.com/deepset-ai/haystack/issues/8025 | [
"type:documentation",
"P3"
] | mrm1001 | 2 |
Lightning-AI/pytorch-lightning | deep-learning | 20,128 | training=False when use a pretrained model like BERT | ### Bug description
I use bert model from transformers for text classification, I found that the whole model's training=True and the bert model's training=False in training_step(), I want to know why and thanks for any kind help. Here is my code:
`class TestModel(pl.LightningModule):
def __init__(self,bert_confi... | closed | 2024-07-25T03:05:06Z | 2024-08-04T19:28:27Z | https://github.com/Lightning-AI/pytorch-lightning/issues/20128 | [
"bug",
"docs"
] | huangfu170 | 3 |
faif/python-patterns | python | 377 | No return value expected | https://github.com/faif/python-patterns/blob/5f47b07dbf2867b0b35866301573439b4e8e37ae/patterns/creational/prototype.py#L32-L38
According to type hint None type should be returned but obj of type `Prototype` is returned. | closed | 2021-07-05T06:31:17Z | 2021-07-06T22:00:05Z | https://github.com/faif/python-patterns/issues/377 | [
"bug"
] | g-paras | 1 |
dpgaspar/Flask-AppBuilder | flask | 1,603 | User self-registration fails if belonging to multiple LDAP groups mapping to same role | ### Environment
Running airflow 2.0.1-python3.8 in docker-compose w/image extended to use flask-appbuilder 3.2.0.
docker-compose version 1.27.4, build unknown
Docker version 19.03.13, build 4484c46d9d
Python 3.8.7
Flask-Appbuilder version: 3.2.0
pip freeze output:
adal==1.2.6
aiohttp==3.7.3
alembic==1.5.4
... | closed | 2021-04-07T19:16:04Z | 2021-07-12T17:54:02Z | https://github.com/dpgaspar/Flask-AppBuilder/issues/1603 | [
"stale"
] | fredthomsen | 2 |
tensorlayer/TensorLayer | tensorflow | 296 | set name automatically? | Currently, I must specify the names of each layer, i.e, when I want to use two dense layer, I have to name them 'dense1' and 'dense2'.
But in tensorflow.contrib.layers, it is ok to have two dense layers without specify their names.
Can it be done in tensorlayer? | closed | 2018-02-03T16:50:20Z | 2018-02-14T03:27:56Z | https://github.com/tensorlayer/TensorLayer/issues/296 | [] | youkaichao | 1 |
labmlai/annotated_deep_learning_paper_implementations | pytorch | 254 | connection timed out | https://github.com/labmlai/annotated_deep_learning_paper_implementations/blob/999f2036a5a7c54403352211b5d1cc0df42b83f6/labml_nn/neox/checkpoint.py#L22
It seems the above url is no longer working. | open | 2024-05-22T15:04:06Z | 2024-05-22T15:04:06Z | https://github.com/labmlai/annotated_deep_learning_paper_implementations/issues/254 | [] | cxw-droid | 0 |
deepfakes/faceswap | machine-learning | 535 | Get error in extract (mtcnn) after upgrade display card. | After upgrade to RTX 2070, I get following error in extract (mtcnn)
The Others (dlib) work.
2018-11-14 01:15:51.906117: E C:\tf_jenkins\workspace\rel-win\M\windows-gpu\PY\36\tensorflow\stream_executor\cuda\cuda_blas.cc:636] failed to run cuBLAS routine cublasSgemm_v2: CUBLAS_STATUS_EXECUTION_FAILED0%| | 0/... | closed | 2018-11-13T17:26:21Z | 2019-01-08T14:00:48Z | https://github.com/deepfakes/faceswap/issues/535 | [] | g0147 | 8 |
d2l-ai/d2l-en | tensorflow | 2,494 | French spelling to fix in chapter_attention-mechanisms-and-transformers/index.md | In file "chapter_attention-mechanisms-and-transformers/index.md"
> ...translating the sentence “my feet hurt” to “j’ai mal au pieds”
the french sentence should be
> ...translating the sentence “my feet hurt” to “j’ai mal aux pieds”
using "aux" which is the plural form of "au" as "pieds" is plural.
| open | 2023-05-17T17:00:12Z | 2023-05-17T17:00:12Z | https://github.com/d2l-ai/d2l-en/issues/2494 | [] | Serge-45 | 0 |
Lightning-AI/pytorch-lightning | machine-learning | 20,534 | DeepSpeed Stage 3 in lightning leads to Nan and Inf values in the model parameters. | ### Bug description
I try to use lightning with DeepSpeed stage 3 to train a model under the precision "16-mixed". However, I find that the model parameters includes Nan and Inf values at the first step. When I change it to DDP, this issue does not exist.
I initialize my trainer as:
```
trainer = Trainer(
... | open | 2025-01-07T08:24:38Z | 2025-01-13T22:18:47Z | https://github.com/Lightning-AI/pytorch-lightning/issues/20534 | [
"bug",
"repro needed",
"ver: 2.5.x"
] | LittleFlyingSheep | 2 |
horovod/horovod | tensorflow | 3,547 | Importing Horovod before establishing MySQL connection leads to segfault | ### Environment:
This issue is replicable on the official horovod docker [container](https://hub.docker.com/r/horovod/horovod).
1. Framework: TensorFlow
2. Framework version: 2.5.0
3. Horovod version: 0.24.3
4. MPI version: 3.00
5. CUDA version: 11.2
6. NCCL version: 2.8.4-1
7. Python version: 3.8.10
8. OS and... | open | 2022-05-16T20:31:40Z | 2022-10-24T05:56:58Z | https://github.com/horovod/horovod/issues/3547 | [
"bug"
] | AllenHW | 1 |
KevinMusgrave/pytorch-metric-learning | computer-vision | 62 | Fix key verification bug in CascadedEmbeddings | The loss functions have to take the form "metric_loss_[0-9]+$". Some loss functions require an optimizer, but it's not possible to pass in an optimizer, because the regex is looking for "metric_loss_[0-9]+$_optimizer".
The error is:
```
AssertionError: optimizers keys must be one of trunk_optimizer, embedder_optim... | closed | 2020-04-18T08:07:52Z | 2020-05-03T12:18:28Z | https://github.com/KevinMusgrave/pytorch-metric-learning/issues/62 | [
"bug",
"fixed in dev branch"
] | KevinMusgrave | 1 |
PeterL1n/BackgroundMattingV2 | computer-vision | 107 | 可以加微信吗?作者求加入啊 | 
| open | 2021-05-26T08:57:11Z | 2023-10-10T15:38:19Z | https://github.com/PeterL1n/BackgroundMattingV2/issues/107 | [] | zhanghonglishanzai | 4 |
newpanjing/simpleui | django | 421 | 首页的快捷操作链接建议按点击量降序或时间倒序排序,同时可以设定显示数量 | **你希望增加什么功能?**
** what features do you wish to add? * *
1.
2.
3.
**你希望哪些方面得到优化?**
1.首页的快捷操作链接建议按点击量降序或时间倒序排序,同时可以设定显示数量
2.
3.
**留下你的联系方式,以便与你取得联系**
** what would you like to see optimized? * *
QQ:xxxxx
E-mail:xxx@xxx.com
| open | 2022-02-10T05:53:06Z | 2022-02-10T06:02:37Z | https://github.com/newpanjing/simpleui/issues/421 | [
"enhancement"
] | byte1byte | 0 |
fohrloop/dash-uploader | dash | 79 | Getting 404 http error under the Flask server | Hi, I'm deploying a dash application in a Flask server and I get a 404 http error when using the dash-uploader. Do you know the reason for this ?
Your help will be very appreciated. | closed | 2022-03-03T22:29:10Z | 2022-03-04T09:34:09Z | https://github.com/fohrloop/dash-uploader/issues/79 | [] | BoudjemaaAKHAM | 0 |
paperless-ngx/paperless-ngx | machine-learning | 8,433 | [BUG] Docker compose webserver container not using USERMAP_UID when writing to media | ### Description
It seems the `webserver` docker container does not use the mapped `USERMAP_UID` and `USERMAP_GID` when writing to `media`, `consume` (e.g. creating the folder on initial build), and the likes.
- When the `webserver` container is initializing directories (`media`, `consume`, etc) on `docker compose ... | closed | 2024-12-05T22:43:38Z | 2024-12-05T22:46:04Z | https://github.com/paperless-ngx/paperless-ngx/issues/8433 | [
"not a bug"
] | benlinton | 0 |
public-apis/public-apis | api | 3,395 | https://excuser.herokuapp.com/ no longer valid | Just noticed the following URL is no longer valid. | closed | 2022-12-27T00:25:02Z | 2023-08-14T00:34:36Z | https://github.com/public-apis/public-apis/issues/3395 | [
"enhancement"
] | elliotth30 | 2 |
idealo/imagededup | computer-vision | 199 | No module named 'imagededup.evaluation' | ```
import imagededup
from imagededup.utils import plot_duplicates
from imagededup.methods.hashing import PHash
from imagededup.handlers import search
import imagededup.evaluation
```
```
---------------------------------------------------------------------------
ModuleNotFoundError Trace... | open | 2023-07-26T07:59:18Z | 2023-08-01T08:23:59Z | https://github.com/idealo/imagededup/issues/199 | [] | papayalove | 3 |
waditu/tushare | pandas | 1,034 | 项目的readme文件里change logs日期有误 | 写成了1018年
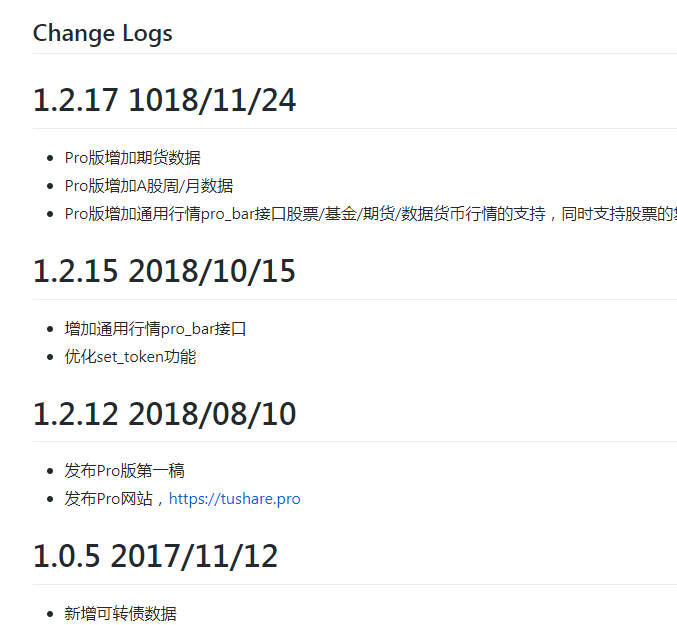
这算bug吗?
[https://tushare.pro/register?reg=265422](url)
| closed | 2019-05-10T08:53:40Z | 2019-06-24T10:54:51Z | https://github.com/waditu/tushare/issues/1034 | [] | EthanHsiung | 0 |
PokeAPI/pokeapi | graphql | 1,112 | Pokémon's highest and lowest stats. | Pretty much what the title says, I would like to be able to fetch this information. Do we have this information in some database, or do we need to gather it from scratch? I could maybe help out a bit, if necessary. | closed | 2024-07-11T13:21:04Z | 2024-07-12T13:58:46Z | https://github.com/PokeAPI/pokeapi/issues/1112 | [] | Renen12 | 4 |
plotly/dash-table | dash | 757 | Anyone has been able to use the pattern match id for the datatable? | The latest Dash supports a pattern match id to work with the dynamic component loading.
`id={'type': 'datatable', 'index': '234234'}`
However it does not seem to work with dash table for now. Any pointers?
Thanks. | closed | 2020-04-20T19:55:45Z | 2020-04-20T22:49:08Z | https://github.com/plotly/dash-table/issues/757 | [] | xumiao | 2 |
comfyanonymous/ComfyUI | pytorch | 6,343 | Help : Cant run comfyui | ### Your question
I can't use comfyui to run flux 1.D
As a newbie, I can't solve this problem.
I have the following log:
> F:\ComfyUI_windows_portable>.\python_embeded\python.exe -s ComfyUI\main.py --windows-standalone-build
> Adding extra search path checkpoints path/to/stable-diffusion-webui/models/Stable-di... | closed | 2025-01-04T08:28:53Z | 2025-01-07T01:59:07Z | https://github.com/comfyanonymous/ComfyUI/issues/6343 | [
"User Support"
] | ChaChrist25 | 11 |
CTFd/CTFd | flask | 2,522 | Users cant solve challenge after changing to user mode | **Environment**:
- CTFd Version/Commit: 3.7.0
- Operating System: Ubuntu 22.04.3 LTS
- Web Browser and Version: Bug is occurs in Newest Chrome, Chromium and Firefox. Not tested more.
**What happened?**
Some of our users was not able to submit correct flag to solve the challenge. This occurred for after we swap... | closed | 2024-04-10T17:50:49Z | 2024-05-15T17:48:13Z | https://github.com/CTFd/CTFd/issues/2522 | [] | HaraldMR | 3 |
Avaiga/taipy | automation | 2,217 | [🐛 BUG] Reading a data node changes the display of a table | ### What went wrong? 🤔
When running https://github.com/Avaiga/demo-sap with 4.0.1.dev1, creating a new scenario will change the display of the input data node table from this:

To this:
 bias for a Linear layer into a single tensor... | open | 2025-03-19T10:26:39Z | 2025-03-21T14:10:38Z | https://github.com/pytorch/pytorch/issues/149500 | [
"oncall: quantization",
"enhancement"
] | nikhil-arm | 2 |
ansible/awx | automation | 15,573 | Okta SAML integration and Group mapping | ### Please confirm the following
- [X] I agree to follow this project's [code of conduct](https://docs.ansible.com/ansible/latest/community/code_of_conduct.html).
- [X] I have checked the [current issues](https://github.com/ansible/awx/issues) for duplicates.
- [X] I understand that AWX is open source software provide... | open | 2024-10-03T15:56:51Z | 2024-11-13T00:56:38Z | https://github.com/ansible/awx/issues/15573 | [
"type:bug",
"component:ui",
"needs_triage",
"community"
] | dvdoron | 1 |
lucidrains/vit-pytorch | computer-vision | 5 | Is there pre-trained weight? | Hi,
ViT seems to perform better with large dataset pre-trained.
Will pre-trained weights provided in the future?
Thanks. | closed | 2020-10-13T07:08:39Z | 2020-10-13T17:23:54Z | https://github.com/lucidrains/vit-pytorch/issues/5 | [] | b02202050 | 1 |
huggingface/datasets | computer-vision | 6,594 | IterableDataset sharding logic needs improvement | ### Describe the bug
The sharding of IterableDatasets with respect to distributed and dataloader worker processes appears problematic with significant performance traps and inconsistencies wrt to distributed train processes vs worker processes.
Splitting across num_workers (per train process loader processes) and... | open | 2024-01-15T22:22:36Z | 2024-10-15T06:27:13Z | https://github.com/huggingface/datasets/issues/6594 | [] | rwightman | 1 |
davidsandberg/facenet | tensorflow | 808 | The extracted feature is not the same when run validate code twice | Hi, David,
Thanks a lot for sharing this repo, I notice that when extract the feature on lfw, the feature is not the same on when I run the code twice, could you please tell me how this happened? should I crop the image size as a certain size? | open | 2018-07-09T18:05:23Z | 2018-07-09T18:05:23Z | https://github.com/davidsandberg/facenet/issues/808 | [] | xingdi1990 | 0 |
kubeflow/katib | scikit-learn | 2,501 | [CI] ci job `Test Build For Component katib-ui` is flaky | ### What happened?
ERROR: failed to solve: process "/bin/sh -c npm config set fetch-retry-mintimeout 20000 && npm config set fetch-retry-maxtimeout 120000 && npm config get registry && npm config set registry https://registry.npmjs.org/ && npm config get https-proxy && npm config rm https-proxy && ... | closed | 2025-01-24T09:25:09Z | 2025-02-01T20:42:34Z | https://github.com/kubeflow/katib/issues/2501 | [
"help wanted",
"good first issue",
"kind/bug"
] | mahdikhashan | 5 |
tqdm/tqdm | pandas | 750 | Disable carriage return or simplified output when redirected to file. | Hello,
I'm using your TQDM in my processing scripts a lot, it gives me nice interactive feedback and I thank you!
I use TQDM in my python library methods which are used not only in jupyter notebooks, console scripts but also in my systemd service. But I have issue with carriage return (\r or ^M in Linux).
I chec... | open | 2019-05-27T09:42:21Z | 2024-06-25T15:55:13Z | https://github.com/tqdm/tqdm/issues/750 | [
"question/docs ‽",
"p4-enhancement-future 🧨"
] | jurajmichalak1 | 12 |
miguelgrinberg/python-socketio | asyncio | 942 | support statistics traffic | **Is your feature request related to a problem? Please describe.**
In my usage scenario, I need to count the traffic size of the transport layer in order to control the IO rate, but socketio cannot meet this requirement.
**Describe the solution you'd like**
I hope to add a variable of traffic statistics to the T... | closed | 2022-06-23T15:13:14Z | 2022-06-24T10:52:18Z | https://github.com/miguelgrinberg/python-socketio/issues/942 | [
"question"
] | b23r0 | 3 |
tflearn/tflearn | tensorflow | 794 | Saving LSTM cell internal structure | Hi all,
is it possible to save the gate values, cell state and hidden state over the course of the training?
I have tried adding a custom layer which will save them, however it fails to do so, usually with errors like
_You must feed a value for placeholder tensor 'InputData/X' with dtype float_
Thank you i... | closed | 2017-06-14T12:01:34Z | 2017-06-19T08:39:06Z | https://github.com/tflearn/tflearn/issues/794 | [] | yhalk | 2 |
jacobgil/pytorch-grad-cam | computer-vision | 213 | IndexError: too many indices for tensor of dimension 3 | `if __name__ == '__main__':
""" python vit_gradcam.py -image-path <path_to_image>
Example usage of using cam-methods on a VIT network.
"""
args = get_args()
argss = get_parser().parse_args()
cfg = setup_cfg(argss)
methods = \
{"gradcam": GradCAM,
"scorecam": Score... | closed | 2022-03-17T03:39:52Z | 2022-04-06T05:07:43Z | https://github.com/jacobgil/pytorch-grad-cam/issues/213 | [] | luoolu | 1 |
taverntesting/tavern | pytest | 504 | question: how to express that ordering doesn't matter? | I have a test:
```
- name: instance list
request:
url: http://localhost:10000/a1-p/policytypes/1006001/policies
method: GET
response:
status_code: 200
body: [qt1, qt2]
```
how do I express that `[qt1, qt2]` OR `[qt2,qt1]` is OK? Is there an "unordered_ok" or some equivale... | closed | 2020-01-02T18:57:11Z | 2021-06-20T13:45:51Z | https://github.com/taverntesting/tavern/issues/504 | [
"Type: Enhancement"
] | tommyjcarpenter | 5 |
alteryx/featuretools | data-science | 2,724 | Codecov reports are not being posted to pull requests | open | 2024-05-10T14:11:40Z | 2024-05-10T14:11:40Z | https://github.com/alteryx/featuretools/issues/2724 | [] | thehomebrewnerd | 0 | |
plotly/dash | plotly | 2,704 | dash_duo.server.stop() kills threads that it doesn't own - ones that were created after its inception | **Describe your context**
```
dash 2.14.1
dash-core-components 2.0.0
dash-html-components 2.0.0
dash-table 5.0.0
dash-testing-stub 0.0.2
```
**Describe the bug**
KillerThread kills all threads that were created since the server's inception. [This appears to be intended](https://g... | open | 2023-11-29T00:31:11Z | 2024-08-13T19:43:15Z | https://github.com/plotly/dash/issues/2704 | [
"bug",
"P3"
] | jake-bickle | 0 |
biolab/orange3 | pandas | 5,993 | Create Instance: Enable nan | <!--
Thanks for taking the time to submit a feature request!
For the best chance at our team considering your request, please answer the following questions to the best of your ability.
-->
**What's your use case?**
<!-- In other words, what's your pain point? -->
<!-- Is your request related to a problem, or ... | closed | 2022-05-25T11:27:04Z | 2022-06-10T10:33:30Z | https://github.com/biolab/orange3/issues/5993 | [
"meal"
] | ajdapretnar | 0 |
JaidedAI/EasyOCR | machine-learning | 530 | Question regarding training custom model | To the concerned,
* Just took a look at your training custom model section
* Reviewed the sample dataset and corresponding pth file. I see in your data set each jpg contained is one single word. I am not sure how to go about generating such a dataset in my case from P&ID engineering diagrams (printed not hand dr... | closed | 2021-08-30T15:27:44Z | 2021-10-06T08:52:41Z | https://github.com/JaidedAI/EasyOCR/issues/530 | [] | pankaja0285 | 2 |
microsoft/nni | machine-learning | 5,479 | how to run unittest ? | **Describe the issue**:
**Environment**:
- NNI version: 2.9
- Training service (local|remote|pai|aml|etc): local
- Client OS:
- Server OS (for remote mode only):
- Python version: 3.7
- PyTorch/TensorFlow version: TF2.9
- Is conda/virtualenv/venv used?: yes
- Is running in Docker?: yes
**Configu... | closed | 2023-03-27T02:03:04Z | 2023-04-07T03:04:17Z | https://github.com/microsoft/nni/issues/5479 | [] | south-ocean | 2 |
ageitgey/face_recognition | python | 1,294 | RuntimeError: Error while calling cudaOccupancyMaxPotentialBlockSize | I have **runtime cuda error** when I run any function from _face_recognition_ library.
I run on **AWS sagemaker**:
* **face_recognition version**: 1.2.3
* **Python version**: 3.6
### Full Error
`RuntimeError: Error while calling cudaOccupancyMaxPotentialBlockSize(&num_blocks,&num_threads,K) in file /tmp/pip-in... | open | 2021-03-23T14:28:14Z | 2021-03-23T14:28:41Z | https://github.com/ageitgey/face_recognition/issues/1294 | [] | mohamedabdallah1996 | 0 |
AirtestProject/Airtest | automation | 257 | touch图片,‘只运行选中代码’,识别不了图片 | **描述问题bug**
touch图片,‘只运行选中代码’,识别不了图片,运行结果如下图;但是按F5执行,却可以成功。
**相关截图**
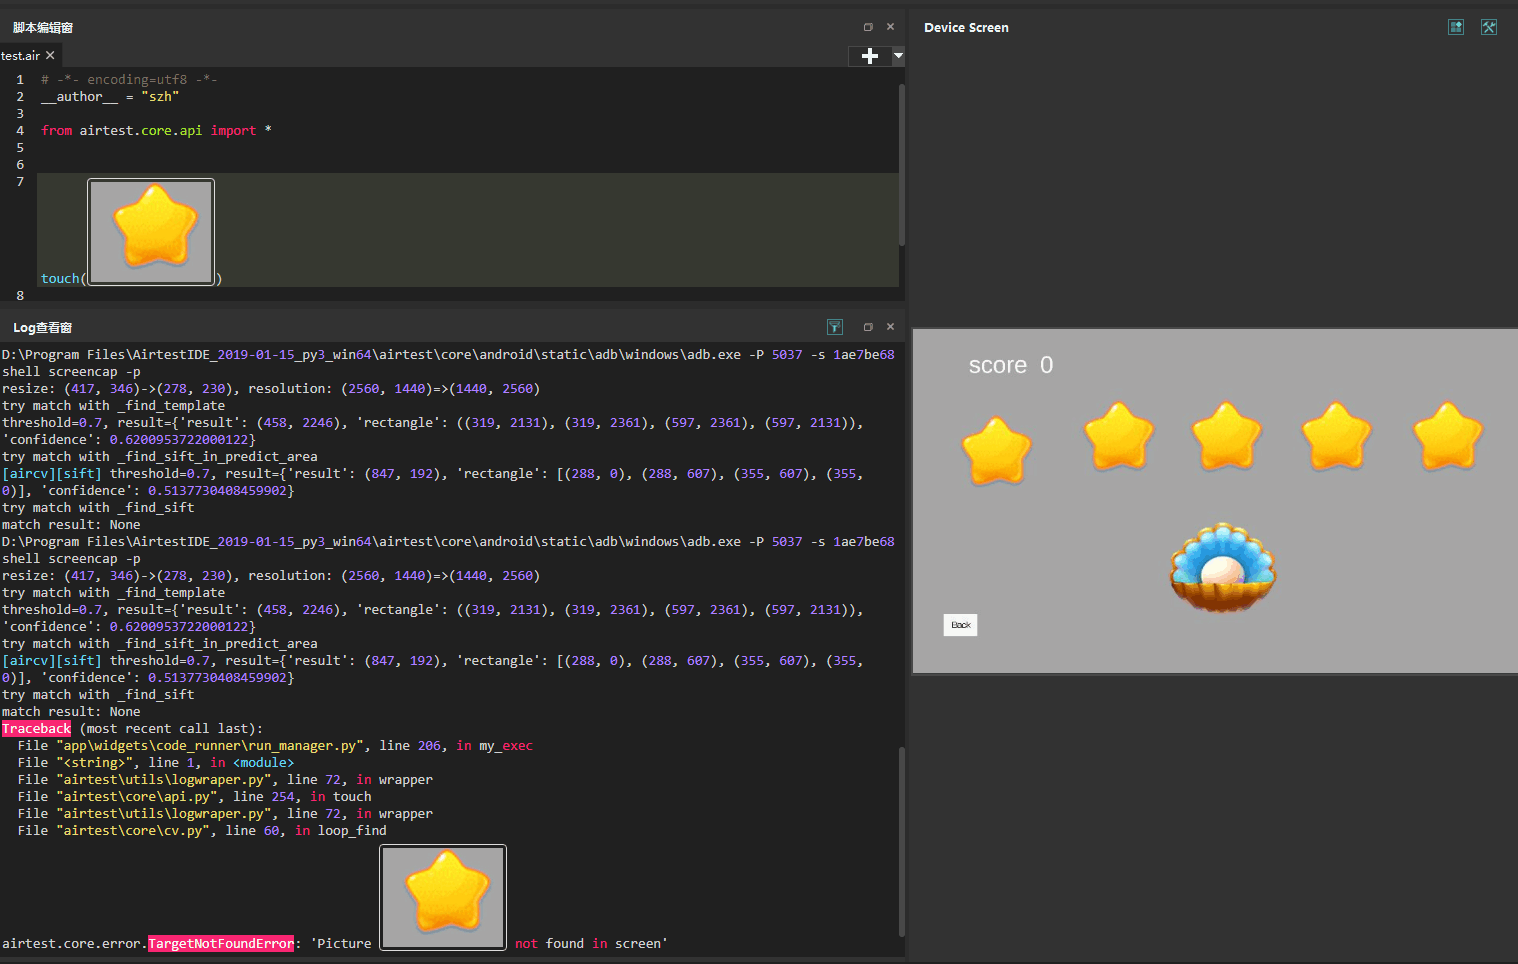
**复现步骤**
1. 插入一个touch图片语句
2. 右击选择‘只运行选中代码’
**预期效果**
单步执行成功。
我认为运行单行代码是调试的重要手段,应该予以重视。除非你们的用户都是用POCO。如果有用户大部分操... | closed | 2019-01-22T16:22:45Z | 2019-01-29T13:41:39Z | https://github.com/AirtestProject/Airtest/issues/257 | [
"compatibility",
"to be released"
] | songzhenhua | 3 |
hbldh/bleak | asyncio | 477 | Automatic reconnection when peripheral disconnects | * bleak version: 0.10.0
* Python version: 3.7.3
* Operating System: Windows 10
### Description
On Windows, a bleak client will automatically reconnect when the peripheral disconnects. This is undesirable behaviour in cases where it is required to completely terminate the connection with the host. For example, c... | closed | 2021-03-08T17:27:40Z | 2021-03-08T17:41:37Z | https://github.com/hbldh/bleak/issues/477 | [] | noonfom | 1 |
dgtlmoon/changedetection.io | web-scraping | 2,561 | [feature] 404 and non-200's should be watched by default ON | there is the option "treat non-200 replies as a change" should be ON by default
for example, people want to know when a product goes from 404 to back online | open | 2024-08-11T10:55:48Z | 2024-08-11T10:55:48Z | https://github.com/dgtlmoon/changedetection.io/issues/2561 | [
"enhancement"
] | dgtlmoon | 0 |
pywinauto/pywinauto | automation | 928 | drag_mouse_input code is likely to be partial/wrong | ## Expected Behavior
A correct drag&drop from a point A to a point B, with intermediate steps on the line [AB]
## Actual Behavior
It "flies" correctly from A to B, but the intermediate steps are inconsistent and do not simulate a human drag
## Steps to Reproduce the Problem
1. Do a simple : `app.drag_mouse... | closed | 2020-05-02T15:36:27Z | 2020-05-04T14:59:03Z | https://github.com/pywinauto/pywinauto/issues/928 | [
"duplicate"
] | r-jean-pierre | 2 |
jina-ai/clip-as-service | pytorch | 343 | How to get single word embeddings? | I have a list with individual tokens (like a vocab) that I want to extract the Bert embeddings for.
I used this command to run the Bert service:
` bert-serving-start -model_dir multi_cased_L-12_H-768_A-12/ -pooling_strategy=NONE -max_seq_len=4 -num_worker=3`
The crucial part, I assume, is the max_seq_len. If I ... | closed | 2019-05-07T14:15:01Z | 2019-05-25T15:53:18Z | https://github.com/jina-ai/clip-as-service/issues/343 | [] | Janinanu | 2 |
jina-ai/clip-as-service | pytorch | 451 | show_tokens=True参数无效,不会返回tokens 调用:embedding_temp = self.bc.encode(entity, show_tokens=True) | **Prerequisites**
> Please fill in by replacing `[ ]` with `[x]`.
* [ ] Are you running the latest `bert-as-service`?
* [ ] Did you follow [the installation](https://github.com/hanxiao/bert-as-service#install) and [the usage](https://github.com/hanxiao/bert-as-service#usage) instructions in `README.md`?
* [ ] D... | closed | 2019-09-23T03:10:33Z | 2019-10-09T03:00:46Z | https://github.com/jina-ai/clip-as-service/issues/451 | [] | renyuxiang | 1 |
darrenburns/posting | rest-api | 59 | Need env feature | I need a env feature to switch my base url or other params | closed | 2024-07-24T16:31:17Z | 2024-07-24T21:49:07Z | https://github.com/darrenburns/posting/issues/59 | [] | nishuzumi | 2 |
neuml/txtai | nlp | 351 | Update scoring algorithms | txtai's scoring algorithms are BM25, TF-IDF and SIF. Scoring methods are used with an embeddings instance when paired with a word vectors model. They are not used with sentence transformers models. Scoring models can be used directly.
The algorithms for these scoring methods should match the most common implementat... | closed | 2022-10-04T10:22:37Z | 2022-10-04T13:40:36Z | https://github.com/neuml/txtai/issues/351 | [] | davidmezzetti | 0 |
pydantic/logfire | fastapi | 194 | Don't configure automatically | As announced in https://pydanticlogfire.slack.com/archives/C06EDRBSAH3/p1716143149301069, the log/span/instrument methods shouldn't implicitly initialize config. This requires a few steps:
1. Make sure that all docs explicitly call `logfire.configure()` before anything else.
2. https://github.com/pydantic/logfire/i... | closed | 2024-05-19T19:38:10Z | 2024-05-31T13:09:30Z | https://github.com/pydantic/logfire/issues/194 | [] | alexmojaki | 1 |
plotly/dash | flask | 2,895 | Markdown does not update code component properly after callback update. | I have a dcc.Markdown that I want to update based on user input in a Textarea. Everything works correctly besides the code component, which when edited stops showing the correct colors (and upon further inspection does not assign the correct classes in the html code).
Expected:
The markdown should update the code c... | closed | 2024-06-20T08:20:39Z | 2024-09-03T19:47:31Z | https://github.com/plotly/dash/issues/2895 | [
"bug",
"P3"
] | athioak7 | 3 |
ndleah/python-mini-project | data-visualization | 286 | Test case for Caterpillar project | # Description
In this issue I want to create a test case to ensure that the try again function, is work correctly. The objective is to validate that this function is performed as expected
<!-- Please include a summary of the issue.-->
## Type of issue
- [ ] Feature (New Script)
- [ ] Bug
- [ ] Documentatio... | open | 2024-06-19T07:08:53Z | 2024-12-31T04:34:28Z | https://github.com/ndleah/python-mini-project/issues/286 | [] | Gabriela20103967 | 1 |
ultrafunkamsterdam/undetected-chromedriver | automation | 1,498 | Kasada.io detecting undetected-chromedriver | Kasada.io is detecting undetected chromedriver.
url: https://www.realestate.com.au/sold/list-1?source=refinement
Using Python 3.8 and undetected-chromedriver 3.5
It used to work before. I believe there has been some changes in the detection algorithm. Also nike.com uses Kasada but it seems to work fine for nik... | open | 2023-08-21T23:34:20Z | 2023-12-01T09:44:56Z | https://github.com/ultrafunkamsterdam/undetected-chromedriver/issues/1498 | [] | sagunsh | 9 |
sergree/matchering | numpy | 41 | Will we see a new update on matchering? | open | 2022-07-15T03:04:00Z | 2024-06-06T09:21:50Z | https://github.com/sergree/matchering/issues/41 | [
"question"
] | aircrushin | 1 | |
vllm-project/vllm | pytorch | 14,807 | [Bug]: CUDA_VISIBLE_DEVICES is not supported | ### Your current environment
<details>
<summary>The output of `python collect_env.py`</summary>
```text
Your output of `python collect_env.py` here
```
</details>
### 🐛 Describe the bug
It seems the executor will always select GPU 0,1,2,3... as the devices of ray workers. And this makes it impossible for user to... | open | 2025-03-14T08:25:11Z | 2025-03-22T02:42:25Z | https://github.com/vllm-project/vllm/issues/14807 | [
"bug",
"ray"
] | chenhongyu2048 | 3 |
ipython/ipython | jupyter | 14,422 | Different behavior when adding virtual environment | I tried addding a conda environment following this steps
1. conda create -n virtual_env
2. conda activate virtual_env
3. conda install pip
4. pip install ipykernel
With
5. ipython -m ipykernel install --user --prefix VIRTUAL_ENV_DIR --name virtual_env --display-name VIRTUAL_ENV
I got Value Error: Can't use ... | open | 2024-04-28T11:10:03Z | 2024-04-28T13:07:48Z | https://github.com/ipython/ipython/issues/14422 | [] | efakinpelu | 0 |
onnx/onnxmltools | scikit-learn | 419 | CoreML to ONNX: ValueError: Unsupported shape calculation for operator multiplyBroadcastable | Hi, I'm trying to convert EfficientNet model from CoreML back to ONNX (in order to validate correctness of onnx -> CoreML conversion)
```
# Load a Core ML model
coreml_model = coremltools.utils.load_spec(INPUT_PATH)
# Convert the Core ML model into ONNX
onnx_model = onnxmltools.convert_coreml(coreml_model, 'Exam... | open | 2020-08-25T07:40:43Z | 2021-01-06T17:23:29Z | https://github.com/onnx/onnxmltools/issues/419 | [
"coreml"
] | TomekPro | 1 |
huggingface/transformers | nlp | 36,509 | Can not use prompt tuning inference | ### System Info
transformers version: 4.48.0
Platform: Linux-4.15.0-76-generic-x86_64-with-glibc2.27
Python version: 3.9.0
Huggingface_hub version: 0.23.4
Safetensors version: 0.4.3
Accelerate version: 0.34.2
Accelerate config: - compute_environment: LOCAL_MACHINE
- distributed_type: DEEPSPEED
- mixed_precision: fp16
... | open | 2025-03-03T10:24:47Z | 2025-03-12T11:46:54Z | https://github.com/huggingface/transformers/issues/36509 | [
"bug"
] | aohenuo | 7 |
miguelgrinberg/Flask-SocketIO | flask | 1,077 | using global variables and multiple background threads asynchronous | Hello Congrats for this library @miguelgrinberg .
Here trying to adapt original https://github.com/miguelgrinberg/Flask-SocketIO/tree/master/example in app.py and trying to build two background processes in FlaskSocketio.
i) The Server generated 'iddle' that comes already with that code, which pings every 10 second... | closed | 2019-10-07T11:54:06Z | 2019-10-09T08:54:42Z | https://github.com/miguelgrinberg/Flask-SocketIO/issues/1077 | [
"question"
] | FrancisBases | 18 |
deezer/spleeter | deep-learning | 10 | Pip can't find spleeter | I can't install this at all with pip. it always says:
ERROR: Could not find a version that satisfies the requirement spleeter (from versions: none)
ERROR: No matching distribution found for spleeter
whenever I type:
pip install spleeter
Any ideas? This is annoying...
Also, if it means much: I'm using Wi... | closed | 2019-11-03T11:34:07Z | 2020-09-16T05:38:41Z | https://github.com/deezer/spleeter/issues/10 | [
"bug",
"distribution",
"windows",
"pip"
] | ghost | 8 |
healthchecks/healthchecks | django | 705 | "502 Bad Gateway" at /checks/<UUID>/log/ for new UUIDs | Hello,
I just created a new check/UUID, a few successful log entries are already in there.
Going to:
https://healthchecks.io/checks/<UUID>/details/
shows everything is fine.
However clicking on "show more" (the new filter interface) leads to a long running transaction that after 30 seconds times out ... | closed | 2022-09-19T15:54:46Z | 2022-09-20T08:11:47Z | https://github.com/healthchecks/healthchecks/issues/705 | [] | lukastribus | 3 |
numba/numba | numpy | 9,008 | Memory leak when passing string literal as an argument to a jitted function | As title says, when passing a literal string as an argument to a jitted function, it leaks memory. I'm using numba 0.56.4 and python 3.10.6
Here is a working example to reproduce it
```
#!/usr/bin/env python3
import numpy as np
from numba import njit,version_info
import psutil,os
print(version_info,end="\n\... | open | 2023-06-09T12:42:30Z | 2024-04-11T09:57:40Z | https://github.com/numba/numba/issues/9008 | [
"bug - memory leak"
] | tegonzalo | 3 |
gunthercox/ChatterBot | machine-learning | 1,627 | JSONDecodeError | from chatterbot import ChatBot
from chatterbot.trainers import ChatterBotCorpusTrainer
import os
import logging
logger = logging.getLogger()
logger.setLevel(logging.CRITICAL)
bot= ChatBot('Bot')
trainer = ChatterBotCorpusTrainer(bot)
corpus_path="C:/Users/Afrah/Desktop/Internship/CBot/chatterbot-corpus-mas... | closed | 2019-02-20T07:52:03Z | 2019-12-18T02:17:13Z | https://github.com/gunthercox/ChatterBot/issues/1627 | [] | AfrahAsif | 3 |
Yorko/mlcourse.ai | numpy | 375 | Assignment 1: Question 6 answer should be 1 of Olympics dataset. Because of men double medal. | closed | 2018-10-16T08:52:49Z | 2018-10-16T11:32:38Z | https://github.com/Yorko/mlcourse.ai/issues/375 | [
"invalid"
] | HammadZahidAli | 2 | |
huggingface/datasets | computer-vision | 6,637 | 'with_format' is extremely slow when used together with 'interleave_datasets' or 'shuffle' on IterableDatasets | ### Describe the bug
If you:
1. Interleave two iterable datasets together with the interleave_datasets function, or shuffle an iterable dataset
2. Set the output format to torch tensors with .with_format('torch')
Then iterating through the dataset becomes over 100x slower than it is if you don't apply the torch... | open | 2024-02-01T17:16:54Z | 2024-02-05T10:43:47Z | https://github.com/huggingface/datasets/issues/6637 | [] | tobycrisford | 1 |
mitmproxy/pdoc | api | 169 | pdoc master does not understand --html-out (makes weird folders) | Somewhere something regressed recently. When I invoke it like this:
```
pdoc --overwrite --html --html-dir build/apidocs sentry_sdk
```
It does not create a folder named `build/apidocs` but instead one `Namespace(all_submodules=False, external_links=False, filter=None, html=True, html_dir='build`:
```
$ ls ... | closed | 2018-09-07T21:20:17Z | 2018-09-13T12:57:10Z | https://github.com/mitmproxy/pdoc/issues/169 | [] | mitsuhiko | 1 |
qubvel-org/segmentation_models.pytorch | computer-vision | 285 | Remove skip connections | Hi,
Thank you for the great repo. Is it possible to remove skip connections or any model in this repo without skip connection?
Thank you | closed | 2020-11-26T11:33:01Z | 2022-02-27T01:54:13Z | https://github.com/qubvel-org/segmentation_models.pytorch/issues/285 | [
"Stale"
] | kargarisaac | 3 |
NullArray/AutoSploit | automation | 917 | Divided by zero exception293 | Error: Attempted to divide by zero.293 | closed | 2019-04-19T16:03:20Z | 2019-04-19T16:36:37Z | https://github.com/NullArray/AutoSploit/issues/917 | [] | AutosploitReporter | 0 |
explosion/spaCy | machine-learning | 13,222 | POS Tagging is Broken for Sliced Pipelines | <!-- NOTE: For questions or install related issues, please open a Discussion instead. -->
Hey everyone,
I'm trying to lemmatize a text which I cleaned earlier. The issue I had was due to runtime so I decided to cut down certain pipelines out since I wanted lemmas only. When I only enable lemmas I got some warnings ... | closed | 2024-01-06T23:35:39Z | 2024-01-08T15:38:59Z | https://github.com/explosion/spaCy/issues/13222 | [
"lang / en",
"models",
"feat / tagger"
] | lordsoffallen | 1 |
pytorch/pytorch | deep-learning | 148,973 | ConvTranspose1d on MKLDNN with BF32 yields wrong results on Intel Sapphire Rapids CPUs | ### 🐛 Describe the bug
I see test failures in `test_conv_deconv_*d_lower_precision_cpu_bfloat16` on systems with Intel Sapphire Rapids. They are consistent with the same diff so fully reproducible.
I reduced the test to a minimal example:
```
import copy
import torch
from torch.utils import mkldnn as mkldnn_utils
im... | closed | 2025-03-11T16:37:22Z | 2025-03-13T13:22:21Z | https://github.com/pytorch/pytorch/issues/148973 | [
"module: mkldnn",
"module: intel"
] | Flamefire | 6 |
junyanz/pytorch-CycleGAN-and-pix2pix | computer-vision | 1,554 | Pretrained model for colorizing | Hi, author
I am a newbie with GAN model. I see this repository and read README but there are no checkpoint for image colorization task.
Can you release it, please? | open | 2023-03-20T10:57:16Z | 2023-04-18T20:14:58Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/1554 | [] | viethoang303 | 2 |
2noise/ChatTTS | python | 633 | torchaudio.save报错 | 最新的代码中使用torchaudio.save(audioFile, torch.from_numpy(wavs[0]), 24000)时,在实体机上运行正常,但是在docker中运行的时候就会报错:
File "/data/ChatTTS/examples/web/infura.py", line 82, in customAudio
torchaudio.save(audioFile, torch.from_numpy(wavs[0]), 24000)
File "/root/anaconda3/lib/python3.10/site-packages/torchaudio/_backend/utils.py"... | closed | 2024-07-26T10:36:49Z | 2024-11-21T04:02:08Z | https://github.com/2noise/ChatTTS/issues/633 | [
"documentation",
"stale"
] | DExpress-dev | 7 |
marshmallow-code/flask-marshmallow | rest-api | 54 | How to use HyperLinkRelated when endpoint's arguments are > 1? | I am not sure if I use this correctly but my use case is that i have users(table) and subscribers(association table which maps user to another user etc..) so my endpoints are like this:
`/api/users/<int:id>/subscribers/` and
`/api/users/<int:id>/subscribers/<int:subscriber_id>`
Looking at the [code](https://github... | closed | 2016-12-13T00:11:18Z | 2018-10-15T16:38:16Z | https://github.com/marshmallow-code/flask-marshmallow/issues/54 | [] | ev-agelos | 3 |
activeloopai/deeplake | data-science | 2,630 | [BUG] | ### Severity
P0 - Critical breaking issue or missing functionality
### Current Behavior
hello ,
I am trying to deploy an app on google function and i have dependency issue that result from deeplake. I am using 3.7.1 version, and the dependency issues commes from ERROR: Cannot install -r requirements.txt (line 1... | closed | 2023-09-29T19:06:58Z | 2024-09-24T17:09:31Z | https://github.com/activeloopai/deeplake/issues/2630 | [
"bug"
] | kabsikabs | 2 |
cvat-ai/cvat | tensorflow | 9,249 | Clarification on Removal of Frame and Attributes in Event Payloads (PR #8616) and Alternatives | ## Context
I noticed that in Pull Request #8616 (<https://github.com/cvat-ai/cvat/pull/8616>), the payload for events such as `create`, `update`, and `delete` for `shapes`, `tags`, and `tracks` no longer includes the `frame` and `attributes` fields. This change impacts how I process event data in my workflow, as I prev... | open | 2025-03-24T12:23:23Z | 2025-03-24T12:23:23Z | https://github.com/cvat-ai/cvat/issues/9249 | [] | Snayyj | 0 |
trevorstephens/gplearn | scikit-learn | 81 | Problem regarding good practices | Hello,
Thank's for this amazing package !! I just discovered it yesterday and I want to use it for my problem.
My problem is a standard classification problem (0/1) with 180 variables both numeric and categorical (one-hot encoded). I created some features myself with field related knowledge (this is a credit pro... | closed | 2018-06-13T12:02:20Z | 2018-12-15T12:20:23Z | https://github.com/trevorstephens/gplearn/issues/81 | [] | Astrus1234 | 4 |
graphql-python/gql | graphql | 388 | Sending Graphql queries using RequestsHTTPTransport works, whereas AIOHTTPTransport doesn't work | **Describe the bug**
When I run a Graphql query using `AIOHTTPTransport` it results in a 503 error. When I run the same query using `RequestsHTTPTransport` I get no error.
```
import asyncio
from gql import Client, gql
from gql.transport.aiohttp import AIOHTTPTransport
from gql.transport.requests import Request... | closed | 2023-02-20T11:20:26Z | 2023-02-20T12:25:23Z | https://github.com/graphql-python/gql/issues/388 | [
"type: question or discussion"
] | HJA24 | 8 |
MaartenGr/BERTopic | nlp | 1,747 | Duplicate Topics Generated: Zero Shot Classification | Hello,
I was wondering if anyone has experienced duplicate topics being generated from the Zero Shot Topic List? I guess there are a couple of ways I can prevent this:
1. Decrease the threshold further
2. Merge the two manually
3. Adjust the clustering algorithm to create less clusters
4. Add the maximal ... | closed | 2024-01-12T21:11:29Z | 2024-02-02T18:43:14Z | https://github.com/MaartenGr/BERTopic/issues/1747 | [] | saikot-paul | 6 |
matplotlib/mplfinance | matplotlib | 492 | One Y axis on panel with multiple studies? | I am having trouble specifying one y axis for all studies on my sub panels. Is there a way to remove either the left or right y axis and fixing them to one?

I apologize if if I am out of the contributi... | closed | 2022-01-16T15:35:23Z | 2022-01-16T16:26:06Z | https://github.com/matplotlib/mplfinance/issues/492 | [
"question"
] | muraaby | 1 |
mlfoundations/open_clip | computer-vision | 648 | --lock-text does not work | --lock-text does not work for TextTransformer because there is not such method in this class.
Is this on purpose or is it going to be implemented? | open | 2023-09-29T13:47:33Z | 2024-02-29T12:14:24Z | https://github.com/mlfoundations/open_clip/issues/648 | [] | nikifori | 3 |
Buuntu/fastapi-react | fastapi | 18 | Add Prettier and Black to Github Actions | Should be run either as pre-commit hooks or on Github actions as a check (preferably both). | closed | 2020-05-21T05:43:52Z | 2020-07-29T03:19:47Z | https://github.com/Buuntu/fastapi-react/issues/18 | [] | Buuntu | 0 |
jupyter/nbviewer | jupyter | 286 | Pastebin notebook not able to be rendered: 400 error | When trying to open a notebook hosted on pastebin.com I get a 400 error.
If I copy the contents and move it into a gist it works, so the content itself is valid.
pastebin link: http://pastebin.com/raw.php?i=3tQF0kDq
| closed | 2014-05-11T17:20:30Z | 2014-05-13T19:59:14Z | https://github.com/jupyter/nbviewer/issues/286 | [] | bahostetterlewis | 2 |
oegedijk/explainerdashboard | plotly | 145 | How to add a custom HTML before dashboard appears? | I want to show a custom HTML login page (with Google Sign In) before I call `run` method from the `ExplainerDashboard`
For example:
`db = ExplainerDashboard(explainer, CustomDashboard, hide_header=True).run()`
When the code calls `run`, then it shows the dashboard.
I need to add a HTML page containing the Goog... | closed | 2021-09-11T22:45:01Z | 2021-12-23T15:28:51Z | https://github.com/oegedijk/explainerdashboard/issues/145 | [] | blakeex | 1 |
uriyyo/fastapi-pagination | fastapi | 731 | pagination on distinct column | I want to the get data of distinct records of paginated data, I'm following the fastapi pagination doc [here][1] .
In the below code snippet
```
from sqlalchemy import select
from fastapi_pagination.ext.sqlalchemy import paginate
@app.get('/users', response_model=Page[UserBase])
def get_users(db: Session = ... | closed | 2023-07-05T20:45:12Z | 2023-08-23T09:43:12Z | https://github.com/uriyyo/fastapi-pagination/issues/731 | [
"question"
] | kashi5 | 10 |
lanpa/tensorboardX | numpy | 57 | Nothing being shown pytorch3.0 | I am trying to run the demo.py code, but it seems no data is being sent to server.
Also, I can't see any thrown exceptions, so I am not sure where to begin debugging.
I am running pytorch3.0 and tensorboard 0.4.0rc3.
Any ideas?
| closed | 2017-12-13T11:56:15Z | 2017-12-13T12:28:41Z | https://github.com/lanpa/tensorboardX/issues/57 | [] | emanjavacas | 1 |
piskvorky/gensim | data-science | 3,334 | Model.Phrases - Specify what is considered a MWE component/word | #### Problem description
When using the Phrases model, words and punctuation are treated alike.
While the corpus can be cleaned previously, it will destroy the corpus structure that is useful for some tasks.
Just like the possibility to specify a list of connective words (ENGLISH_CONNECTOR_WORDS) it would be nice ... | open | 2022-04-25T17:58:12Z | 2022-04-29T21:16:37Z | https://github.com/piskvorky/gensim/issues/3334 | [] | ambs | 7 |
junyanz/pytorch-CycleGAN-and-pix2pix | computer-vision | 1,568 | WGAN produce very poor results | Hi
I am using Cyclegan for medical image translation however when I changed the WGAN, the results completely failed.
I have attached the original images and the generated results. I have trained for 400 epochs.
Anyone has any idea why this happens?
Fig 1 Real A
Fig 2 Real B
Fig 3 fake A from unet128+wgan
Fig ... | open | 2023-05-09T21:45:16Z | 2023-05-09T21:47:53Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/1568 | [] | xintian-99 | 0 |
mars-project/mars | scikit-learn | 2,771 | Add capability for getting slices directly | ## Motivation
Slicing arrays / dataframes is a common scenario in Mars. Currently, when executing expressions like `df["col"].sum()`, operands below need to be executed one by one:
1. `DataFrameGetItem(df, 'col')` and resulting column is stored, and
2. `DataFrameAggregate(df['col'], 'sum')` which takes column sl... | open | 2022-03-01T09:35:51Z | 2022-03-01T09:35:51Z | https://github.com/mars-project/mars/issues/2771 | [
"mod: serialization",
"mod: storage",
"mod: task service",
"needs discussions"
] | wjsi | 0 |
Yorko/mlcourse.ai | numpy | 705 | wrong import in "topic5_part3_feature_importance.ipynb" | I noticed a typo in the third part of the fifth topic of the open course.
[Тема 5. Часть 3.](https://github.com/Yorko/mlcourse.ai/blob/main/jupyter_russian/topic05_bagging_rf/topic5_part3_feature_importance.ipynb)
In the last string of first cell of codes wrong import of RandomForest -- > `from sklearn.ensemble.f... | closed | 2022-05-15T12:55:02Z | 2022-08-27T16:33:21Z | https://github.com/Yorko/mlcourse.ai/issues/705 | [] | artdaal | 0 |
d2l-ai/d2l-en | tensorflow | 2,559 | module 'd2l.torch' has no attribute 'count_corpus' | import math
import os
import random
import torch
from d2l import torch as d2l
import os
import matplotlib.pyplot as plt
os.environ["KMP_DUPLICATE_LIB_OK"]="TRUE"
#@save
d2l.DATA_HUB['ptb'] = (d2l.DATA_URL + 'ptb.zip',
'319d85e578af0cdc590547f26231e4e31cdf1e42')
#@save
def read_ptb... | open | 2023-09-29T06:10:56Z | 2024-09-12T14:43:04Z | https://github.com/d2l-ai/d2l-en/issues/2559 | [
"question"
] | wangze1219 | 4 |
scikit-optimize/scikit-optimize | scikit-learn | 555 | How is it possible to dealing with settings of optimization method in python such basin hopping (scipy) | I have some difficult with changeing settings of Scipy package for optimization I am trying to find global minmum by using scipy.optimize.basinhopping and using optimization method like (e.g. BFGS, Nelder-Mead simplex, Newton Conjugate Gradient, COBYLA or SLSQP) but i tried to change all settings like ( gtol , eps, fto... | closed | 2017-11-06T13:45:18Z | 2018-01-10T22:39:50Z | https://github.com/scikit-optimize/scikit-optimize/issues/555 | [] | azeezof | 1 |
snooppr/snoop | web-scraping | 38 | Downloading and Installing typing_extensions | How to install these modules i tried a lot but that's not working,I'm using Windows Subsystem for Linux(Kali Linux Rolling)
ERROR: ufonet 1.5 requires GeoIP>=1.3.2, which is not installed.
ERROR: ufonet 1.5 requires pycrypto>=2.6.1, which is not installed.
ERROR: clarifai 2.6.2 has requirement configparser<4,>=3.5... | closed | 2020-09-17T19:04:37Z | 2020-09-17T20:12:28Z | https://github.com/snooppr/snoop/issues/38 | [
"documentation"
] | Optane002 | 1 |
public-apis/public-apis | api | 3,699 | Apis | closed | 2023-11-06T20:19:15Z | 2023-11-06T21:03:17Z | https://github.com/public-apis/public-apis/issues/3699 | [] | SidneySM1 | 0 | |
ymcui/Chinese-LLaMA-Alpaca-2 | nlp | 303 | Chinese-Alpaca-2为何训练的时候用的是单轮prompt,推理的时候可以直接用多轮prompt? | ### 提交前必须检查以下项目
- [X] 请确保使用的是仓库最新代码(git pull),一些问题已被解决和修复。
- [X] 我已阅读[项目文档](https://github.com/ymcui/Chinese-LLaMA-Alpaca-2/wiki)和[FAQ章节](https://github.com/ymcui/Chinese-LLaMA-Alpaca-2/wiki/常见问题)并且已在Issue中对问题进行了搜索,没有找到相似问题和解决方案。
- [X] 第三方插件问题:例如[llama.cpp](https://github.com/ggerganov/llama.cpp)、[LangChain](https://g... | closed | 2023-09-21T02:17:36Z | 2023-09-22T01:24:14Z | https://github.com/ymcui/Chinese-LLaMA-Alpaca-2/issues/303 | [] | minmie | 6 |
microsoft/nni | data-science | 5,095 | output inconsistency for masked vs compressed model [structured pruning] | **Describe the issue**:
Model compression in NNI breaks numerical consistency when I use it for structured pruned model.
**Environment**:
- NNI version: 2.8
- Client OS: MacOS
**How to reproduce it?**:
```py3
import torch.nn as nn
from nni.compression.pytorch.pruning import FPGMPruner, L1NormPruner, Lev... | closed | 2022-08-29T17:42:31Z | 2022-09-09T03:11:34Z | https://github.com/microsoft/nni/issues/5095 | [
"bug",
"user raised",
"model compression"
] | SolomidHero | 2 |
ydataai/ydata-profiling | data-science | 1,330 | memory leak in histogram with 'auto' bins | ### Current Behaviour
I saw this pr had been merged https://github.com/ydataai/ydata-profiling/pull/1308
But I still got memory error:
```
---------------------------------------------------------------------------
MemoryError Traceback (most recent call last)
~\AppData\Local\... | open | 2023-05-18T06:08:44Z | 2023-05-22T08:26:05Z | https://github.com/ydataai/ydata-profiling/issues/1330 | [
"information requested ❔"
] | eromoe | 10 |
jumpserver/jumpserver | django | 14,601 | [Question] app.dd25a578.js:1 Uncaught SyntaxError: Unexpected token '<' 错做了一会儿控制界面后页面空白,请问是什么原因 | ### Product Version
v4.40
### Product Edition
- [X] Community Edition
- [ ] Enterprise Edition
- [ ] Enterprise Trial Edition
### Installation Method
- [X] Online Installation (One-click command installation)
- [ ] Offline Package Installation
- [ ] All-in-One
- [ ] 1Panel
- [ ] Kubernetes
- [ ] S... | closed | 2024-12-06T07:03:42Z | 2024-12-31T09:38:53Z | https://github.com/jumpserver/jumpserver/issues/14601 | [
"⏳ Pending feedback",
"🤔 Question"
] | Zhengyueewee2e | 3 |
SciTools/cartopy | matplotlib | 1,683 | patch.set_facecolor fails with Cartopy 0.18 and Matplotlib 3.3.3 | ### Description
<!-- Please provide a general introduction to the issue/proposal. -->
Hello, sometimes when using very high-resolution country layers I use `ax.patch.set_facecolor` instead of `ax.add_feature(cfeature.OCEAN)` so that there is no mismatch in the coast due to the difference in resolutions.
With `mat... | closed | 2020-11-26T01:17:40Z | 2020-11-27T20:00:20Z | https://github.com/SciTools/cartopy/issues/1683 | [] | marceloandrioni | 3 |
google-research/bert | tensorflow | 791 | Out of memory | when the bert model is loading, something bad occurs like this:
_tensorflow.python.framework.errors_impl.InternalError: CUDA runtime implicit initialization on GPU:0 failed. Status: out of memory_
but, 20G gpu memory is left. And running environment are following:
centos 7
tensorflow-gpu==1.11.0
cuda==9.0.176... | open | 2019-08-01T09:11:55Z | 2019-10-04T20:30:45Z | https://github.com/google-research/bert/issues/791 | [] | BinNong | 1 |
mars-project/mars | pandas | 2,670 | [BUG] Filtering failed when scaler is pd.Timestamp | <!--
Thank you for your contribution!
Please review https://github.com/mars-project/mars/blob/master/CONTRIBUTING.rst before opening an issue.
-->
**Describe the bug**
Filtering failed when scaler is pd.Timestamp.
**To Reproduce**
To help us reproducing this bug, please provide information below:
1. You... | closed | 2022-01-30T14:18:37Z | 2022-01-31T03:46:40Z | https://github.com/mars-project/mars/issues/2670 | [
"type: bug",
"mod: dataframe",
"task: medium"
] | qinxuye | 0 |
encode/apistar | api | 67 | Preloading components | For components that don't rely on the incoming request, we generally want to preload them into the state, so that we don't end up recreating them on every incoming request.
In particular this is true right now for our templates, where we're naively recreating the jinja environment on every incoming request. The inte... | closed | 2017-04-20T12:25:26Z | 2017-08-17T11:38:56Z | https://github.com/encode/apistar/issues/67 | [
"Cleanup"
] | tomchristie | 6 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.