
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
Johnserf-Seed/TikTokDownload | api | 641 | 安装 f2 遇到的问题 | **描述出现的错误**
Using cached pytest-7.4.2-py3-none-any.whl.metadata (7.9 kB)
Collecting pyyaml==6.0 (from f2)
Using cached PyYAML-6.0.tar.gz (124 kB)
Installing build dependencies ... done
Getting requirements to build wheel ... error
error: subprocess-exited-with-error
× Getting requirements to build... | open | 2024-01-11T02:27:19Z | 2025-01-05T13:40:01Z | https://github.com/Johnserf-Seed/TikTokDownload/issues/641 | [
"已确认(confirmed)",
"依赖更新(dependencies)"
] | ZaiKL | 8 |
aio-libs-abandoned/aioredis-py | asyncio | 1,385 | Add `nx`, `xx`, `gt` and `lt` to `.expire` | ### Is your feature request related to a problem?
Right now `redis.asyncio.Redis` and `aioredis` have different signatures for `.expire`.
When wirtting code that support both versions, one has to do something like this: https://github.com/wemake-services/asyncio-redis-rate-limit/blob/6079ee499e6e8f57719519806b1d6514e... | open | 2022-06-30T08:52:53Z | 2022-06-30T09:01:45Z | https://github.com/aio-libs-abandoned/aioredis-py/issues/1385 | [
"enhancement"
] | sobolevn | 1 |
Lightning-AI/pytorch-lightning | deep-learning | 20,205 | Allow passing custom reader/writer in _distributed_checkpoint_save and _distributed_checkpoint_load. | ### Description & Motivation
[distributed_checkpoint_save](https://github.com/Lightning-AI/pytorch-lightning/blob/master/src/lightning/fabric/strategies/fsdp.py#L861) for sharded dict initializes [torch.distributed.checkpoint.FileSystemWriter](https://github.com/Lightning-AI/pytorch-lightning/blob/master/src/lightning... | open | 2024-08-15T20:59:56Z | 2024-08-15T21:00:16Z | https://github.com/Lightning-AI/pytorch-lightning/issues/20205 | [
"feature",
"needs triage"
] | Yash9060 | 0 |
twopirllc/pandas-ta | pandas | 869 | RSI resulting in None value | **Which version are you running? The lastest version is on Github. Pip is for major releases.**
0.3.14b0
**Do you have _TA Lib_ also installed in your environment?**
TA-Lib 0.4.32
**Have you tried the _development_ version? Did it resolve the issue?**
No
**Describe the bug**
RSI resulting None value

./models/idefics/vision.py:468: hidden_states = self.pre_layrnorm(hidden_states)
./models/idefics... | closed | 2025-03-10T01:10:24Z | 2025-03-10T14:26:12Z | https://github.com/huggingface/transformers/issues/36623 | [] | jere357 | 1 |
cvat-ai/cvat | pytorch | 9,000 | How can I import two different annotations files to a single task? | I wanna import segmentations masks in the format "Segmentation Mask 1.1" but I also want to import bounding boxes in the COCO format. If i import one after the other, the second one overwrites the first one. | closed | 2025-01-27T18:25:49Z | 2025-01-28T09:09:11Z | https://github.com/cvat-ai/cvat/issues/9000 | [] | beatrizpinheiro | 1 |
xorbitsai/xorbits | numpy | 356 | BUG: fail to create a dataframe from an ndarray on GPU | ### Describe the bug
There is an error when creating a dataframe from an ndarray on GPU.
### To Reproduce
To help us to reproduce this bug, please provide information below:
1. Your Python version: `3.9.15`
2. The version of Xorbits you use: `master `
3. Versions of crucial packages, such as numpy, scipy and ... | closed | 2023-04-12T03:55:59Z | 2023-05-04T03:50:41Z | https://github.com/xorbitsai/xorbits/issues/356 | [
"bug",
"gpu"
] | UranusSeven | 0 |
seleniumbase/SeleniumBase | pytest | 2,179 | Refactor GUI Apps for improved Windows compatibility | ## Refactor GUI Apps for improved Windows compatibility
The Apps to refactor:
* [SeleniumBase Commander / GUI](https://github.com/seleniumbase/SeleniumBase/blob/master/help_docs/commander.md)
* [SeleniumBase Behave GUI](https://github.com/seleniumbase/SeleniumBase/blob/master/help_docs/behave_gui.md)
* [SeleniumB... | closed | 2023-10-11T20:00:05Z | 2023-10-12T17:48:19Z | https://github.com/seleniumbase/SeleniumBase/issues/2179 | [
"enhancement",
"SeleniumBase 4"
] | mdmintz | 1 |
ivy-llc/ivy | tensorflow | 28,248 | Fix Ivy Failing Test: paddle - elementwise.not_equal | closed | 2024-02-11T20:17:46Z | 2024-02-25T10:16:01Z | https://github.com/ivy-llc/ivy/issues/28248 | [
"Sub Task"
] | ksheroz | 0 | |
dask/dask | pandas | 11,830 | Infer schema does not work properly for categorical types with high cardinality values | Using categorical type with high cardinality values that do not fit into `int8` leads to error:
```
ValueError: Failed to convert partition to expected pyarrow schema:
`ArrowInvalid('Integer value 575 not in range: -128 to 127', 'Conversion failed for column ProductName with type category')`
```
It happens because... | open | 2025-03-17T17:46:08Z | 2025-03-17T17:53:11Z | https://github.com/dask/dask/issues/11830 | [
"needs triage"
] | dbalabka | 0 |
ultralytics/ultralytics | python | 19,262 | Volov8 My camera won't turn off (i think) | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
After testing the trained dataset on live video, I stop the relevant code. H... | closed | 2025-02-15T17:25:39Z | 2025-02-20T22:54:50Z | https://github.com/ultralytics/ultralytics/issues/19262 | [
"question",
"detect"
] | josephRed1 | 6 |
igorbenav/FastAPI-boilerplate | sqlalchemy | 43 | Enhance folder structure | Moving schemas inside the version folder could enhance the overall project organization. It might make the versioning more intuitive.
I believe middlewares should be in separate folder that's tell what it contain not like cache middleware its inside `app/core/cache.py`
Also exceptions file should be folder for each "... | closed | 2023-11-14T05:21:21Z | 2023-11-18T04:00:11Z | https://github.com/igorbenav/FastAPI-boilerplate/issues/43 | [
"enhancement"
] | YousefAldabbas | 3 |
recommenders-team/recommenders | machine-learning | 2,030 | [FEATURE] Add tests in SAR for remove seen feature | ### Description
<!--- Describe your expected feature in detail -->
### Expected behavior with the suggested feature
<!--- For example: -->
<!--- *Adding algorithm xxx will help people understand more about xxx use case scenarios. -->
### Other Comments
| open | 2023-10-27T09:48:13Z | 2023-10-27T09:48:13Z | https://github.com/recommenders-team/recommenders/issues/2030 | [
"enhancement"
] | miguelgfierro | 0 |
httpie/cli | python | 1,051 | brew install httpie will install python too instead of using my existing pyhton | **Checklist**
- [x] I've searched for similar issues.
- [x] I'm using the the latest version of HTTPie.
---
**What are the steps to reproduce the problem?**
1. MacOS 11.2.3 (Big Sur) has python 3.8 installed and most of my projects use python 3.8
2. I installed httpie using `brew install httpie` then brew... | closed | 2021-04-07T03:04:21Z | 2021-05-07T15:12:47Z | https://github.com/httpie/cli/issues/1051 | [] | qiulang | 10 |
KevinMusgrave/pytorch-metric-learning | computer-vision | 715 | Evaluating big datasets on GPU | Hi,
first of all, thanks for creating and maintaining the library.
I'm having issues with doing evaluation on my dataset (train 145K, val 15k, val2 15k). This is the part of code in regards to testing:
```
tester = testers.GlobalEmbeddingSpaceTester(
end_of_testing_hook=hooks.end_of_testing_hook,
data... | closed | 2024-09-09T08:19:03Z | 2024-09-12T17:15:35Z | https://github.com/KevinMusgrave/pytorch-metric-learning/issues/715 | [] | ir2718 | 3 |
allenai/allennlp | pytorch | 5,152 | Skip the train_step | I have an issue that I want to skip a training step and I really cannot filter these instances in DataLoader. I am just wondering if it is possible to skip this batch and carry on with the next one with the allennlp framework? | closed | 2021-04-24T17:08:21Z | 2021-05-10T16:10:10Z | https://github.com/allenai/allennlp/issues/5152 | [
"question",
"stale"
] | Aiah | 5 |
modoboa/modoboa | django | 3,307 | load_initial_data might fail te replace the frontend version | Starting 2.3.0.
Has to be linked with the shutils.rmtree. Deleting manually the frontend folder and starting load_initial_data fixes the issue.
| open | 2024-08-23T12:23:25Z | 2024-08-23T12:23:25Z | https://github.com/modoboa/modoboa/issues/3307 | [
"bug"
] | Spitfireap | 0 |
strawberry-graphql/strawberry-django | graphql | 703 | Shouldn't django-tree-queries be a dev-dependency? |
## Describe the Bug
I may be missing something, but it seems like `django-tree-queries` should be a dev dependency. I just upgraded to 0.55.1, and I don't see anything outside of `tests` using this dependency.
https://github.com/search?q=repo%3Astrawberry-graphql%2Fstrawberry-django%20tree_queries&type=code
`django... | closed | 2025-02-11T23:55:46Z | 2025-02-12T16:47:45Z | https://github.com/strawberry-graphql/strawberry-django/issues/703 | [
"bug"
] | pcraciunoiu | 2 |
huggingface/peft | pytorch | 1,700 | Error while loading PEFT lora model | Trained model using this lora config:
```
model.resize_token_embeddings(len(tokenizer))
Embedding(33004, 4096)
lora_alpha = 2048
lora_dropout = 0.3
lora_r = 1024
target_modules=[
# "up_proj",
"o_proj",
"v_proj",
"gate_proj",
"q_proj",
# "down_proj",
"k_proj"
]
modules_to_... | closed | 2024-04-30T20:36:17Z | 2024-05-02T09:29:53Z | https://github.com/huggingface/peft/issues/1700 | [] | Zuhashaik | 4 |
oegedijk/explainerdashboard | plotly | 290 | integration tests failing due dash_duo.get_logs() returning None | Our integration tests are failing both locally and in the CI due to dash_duo.get_logs() returning None instead of [].
Filed an issue with dash here: https://github.com/plotly/dash/issues/2712
In the meantime will switch off the integration tests in the CI. | open | 2023-12-17T12:27:56Z | 2023-12-19T20:11:18Z | https://github.com/oegedijk/explainerdashboard/issues/290 | [] | oegedijk | 1 |
ultrafunkamsterdam/undetected-chromedriver | automation | 1,218 | [ Profile Reuse - Session Bug ] Google Account Logging out every 24h | Hi !
So..
- I create a custom, whole new user data dir and a new profile.
- Login to my google accounts, so I can reuse my session cookies on some site
- get logged out of Google Account on top right corner of the browser, forcing me to relogin about every 12-24 hours.
Why is this happening ?
How can I... | closed | 2023-04-26T06:01:53Z | 2023-04-29T01:53:05Z | https://github.com/ultrafunkamsterdam/undetected-chromedriver/issues/1218 | [] | sdfgsdfgd | 1 |
pytorch/pytorch | python | 149,044 | [v.2.7.0] Release Tracker | We cut a [release branch](https://github.com/pytorch/pytorch/tree/release/2.7) for the 2.7.0 release.
Our plan from this point from this point is roughly:
* Phase 1 (until 3/31/25): work on finalizing the release branch
* Phase 2 (after 3/31/25): perform extended integration/stability/performance testing based on Rel... | open | 2025-03-12T14:43:25Z | 2025-03-21T23:31:30Z | https://github.com/pytorch/pytorch/issues/149044 | [
"module: ci",
"triaged",
"release tracker"
] | atalman | 30 |
writer/writer-framework | data-visualization | 509 | Ability to Filter file uploads based on mimetype | Issue: Currently the only method for filtering filetypes for the file upload component is custom implementation on the backend.
Suggested Solution: Having the ability to select the allowed filetypes in the component configuration will be a very useful feature. | open | 2024-08-06T12:42:50Z | 2024-08-26T08:20:19Z | https://github.com/writer/writer-framework/issues/509 | [
"enhancement"
] | yaseenali-writer | 0 |
jina-ai/serve | deep-learning | 5,241 | Bug: New type of logging hides info | As you can see, the new logging type hides important information from the user. A lot of output is cut off. It makes it much harder to debug.
<img width="460" alt="image" src="https://user-images.githubusercontent.com/11627845/193908102-25df61c5-c540-4cde-830b-6fddbf8f9bf3.png">
UAC
- [ ] all log out put should be... | closed | 2022-10-04T19:27:21Z | 2022-12-07T16:14:46Z | https://github.com/jina-ai/serve/issues/5241 | [
"type/bug"
] | florian-hoenicke | 3 |
sqlalchemy/alembic | sqlalchemy | 475 | autogenerate ignores 'collation' on Varchar/Str/Unicode columns | **Migrated issue, originally created by Rudolph Froger ([@rudolph](https://github.com/rudolph))**
When an explicit collation has been set then autogenerate doesn't use it when generating migrations for new models and/or changed columns.
| closed | 2018-01-11T13:08:09Z | 2022-05-26T14:31:30Z | https://github.com/sqlalchemy/alembic/issues/475 | [
"feature",
"autogenerate - detection",
"low priority"
] | sqlalchemy-bot | 2 |
quokkaproject/quokka | flask | 570 | cli: deploy pythonanywhere | DEploy static/live on pythonanywhere
https://github.com/rochacbruno/quokka_ng/issues/64 | closed | 2018-02-07T01:36:09Z | 2018-02-07T01:39:07Z | https://github.com/quokkaproject/quokka/issues/570 | [
"1.0.0",
"hacktoberfest"
] | rochacbruno | 0 |
tflearn/tflearn | tensorflow | 709 | tf.concat reordered arguments in tensorflow1.0 | I'm trying to use time_distributed layer, but I have an error:
```
tflearn/layers/core.py
645 except:
646 x = list(map(lambda t: tf.reshape(t, [-1, 1]+utils.get_incoming_shape(t)[1:]), x))
--> 647 return tf.concat(1, x)
```
It was because in tensorflow1.0 was changed concat function.
... | closed | 2017-04-12T20:10:36Z | 2017-04-13T21:34:24Z | https://github.com/tflearn/tflearn/issues/709 | [] | Ruslanmlnkv | 1 |
qubvel-org/segmentation_models.pytorch | computer-vision | 938 | My encoder-decoder shows asymmetrical architectures (using torchinfo package) | Using a ResNet-18 backbone (ResNetEncoder), I do not undestand why the decoder achieved using a UNet or FPN architecture is not symetrical ... I attach the summary of a UNetDecoder which only consists of 3M parameters, instead of the 11M related to the encoder. Where is the problem? How can I made the decoder completel... | open | 2024-10-08T12:11:14Z | 2024-10-09T19:29:03Z | https://github.com/qubvel-org/segmentation_models.pytorch/issues/938 | [] | bobetocalo | 1 |
jupyter-incubator/sparkmagic | jupyter | 652 | How to setup SparkR kernel and with LIVY? | I have install sparkRkernel as below as sparkkernel and pysparkkernel and configure the Livy with config.json
```
jupyter-kernelspec install $SPARK_MAGIC_PATH/sparkmagic/kernels/sparkkernel
jupyter-kernelspec install $SPARK_MAGIC_PATH/sparkmagic/kernels/pysparkkernel
jupyter-kernelspec install $SPARK_MA... | open | 2020-07-01T05:40:17Z | 2020-07-01T05:40:17Z | https://github.com/jupyter-incubator/sparkmagic/issues/652 | [] | koiralo | 0 |
huggingface/datasets | numpy | 7,215 | Iterable dataset map with explicit features causes slowdown for Sequence features | ### Describe the bug
When performing map, it's nice to be able to pass the new feature type, and indeed required by interleave and concatenate datasets.
However, this can cause a major slowdown for certain types of array features due to the features being re-encoded.
This is separate to the slowdown reported i... | open | 2024-10-10T22:08:20Z | 2024-10-10T22:10:32Z | https://github.com/huggingface/datasets/issues/7215 | [] | alex-hh | 0 |
zalandoresearch/fashion-mnist | computer-vision | 127 | BenchMark: Single CNN Layer | `The model is a single layer CNN (Conv2D) which takes input tensors of dimensions (image_height, image_width, image_channels) which is (28,28,1) which is the format of Fashion-MNIST dataset.
Layer 1 : Conv2D for convolution operation to extract features.
Layer 2 : MaxPooling2D to reduce dimension complexity and r... | closed | 2018-08-01T08:01:34Z | 2018-08-01T08:07:21Z | https://github.com/zalandoresearch/fashion-mnist/issues/127 | [] | yugkhanna | 1 |
aminalaee/sqladmin | asyncio | 210 | SqlAlchemy InvalidColumnReference error when listing entities that have a lazy="subquery" relationship | ### Checklist
- [X] The bug is reproducible against the latest release or `master`.
- [X] There are no similar issues or pull requests to fix it yet.
### Describe the bug
When going on /list the SELECT SQLAlchemy statement fails with the following error :

```
for DTensor + 1e-6, each rank adds 1e-6 to local tensor, instead of adding once
this was reported by others as well
### Versions
na
cc ... | open | 2025-03-21T21:47:57Z | 2025-03-24T14:13:14Z | https://github.com/pytorch/pytorch/issues/149768 | [
"oncall: distributed",
"module: fsdp"
] | weifengpy | 2 |
hankcs/HanLP | nlp | 1,108 | 如何ByteArray.createByteArray载入jar包内部的bin文件 | <!--
注意事项和版本号必填,否则不回复。若希望尽快得到回复,请按模板认真填写,谢谢合作。
-->
## 注意事项
请确认下列注意事项:
* 我已仔细阅读下列文档,都没有找到答案:
- [首页文档](https://github.com/hankcs/HanLP)
- [wiki](https://github.com/hankcs/HanLP/wiki)
- [常见问题](https://github.com/hankcs/HanLP/wiki/FAQ)
* 我已经通过[Google](https://www.google.com/#newwindow=1&q=HanLP)和[issue区检... | closed | 2019-03-05T08:31:55Z | 2019-03-12T09:18:40Z | https://github.com/hankcs/HanLP/issues/1108 | [
"question"
] | whaozl | 2 |
KaiyangZhou/deep-person-reid | computer-vision | 23 | Error when loading DenseNet model : Missing key(s) in state_dict | # 1.Error Description
I tried to perform test on the MARS dataset with the provided trained model `densenet121_xent_htri_mars.pth.tar`, using this command:
`python train_vid_model_xent_htri.py -d mars -a densenet121 --evaluate --resume saved-models/densenet121_xent_htri_mars.pth.tar --save-dir log/densenet121-xent-ht... | closed | 2018-06-06T14:23:23Z | 2018-06-22T14:46:15Z | https://github.com/KaiyangZhou/deep-person-reid/issues/23 | [] | ghost | 3 |
sanic-org/sanic | asyncio | 2,685 | Do not log body not consumed errors for http verbs that should not have a body | ### Is there an existing issue for this?
- [X] I have searched the existing issues
### Is your feature request related to a problem? Please describe.
We have clients outside our control that send GET requests with http body. We dont care about the body in those requests (in fact, they shouldn't be sending it at all)... | closed | 2023-02-15T16:21:19Z | 2024-04-01T13:49:09Z | https://github.com/sanic-org/sanic/issues/2685 | [
"feature request"
] | GabrielCappelli | 3 |
simple-login/app | flask | 1,372 | auto create alias rules don't say only lowercase letters are accepted | 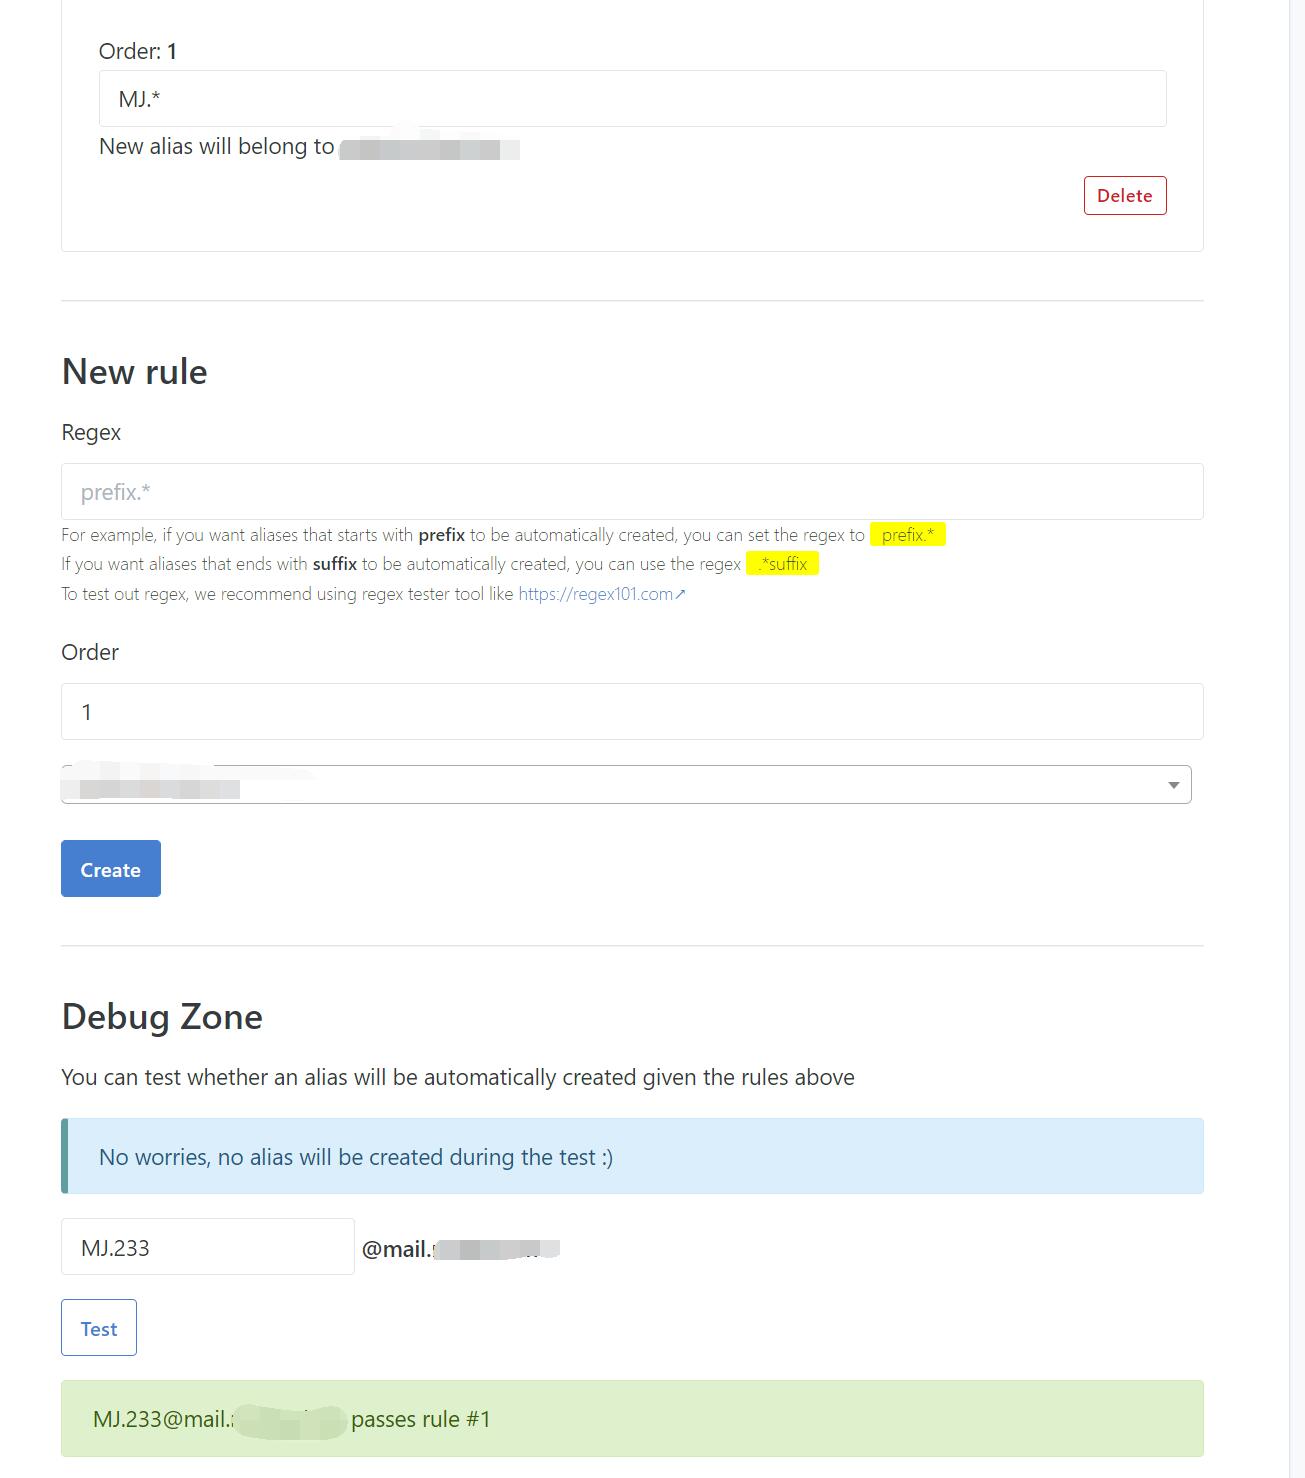
the debug zone also says it's accepted, but when I really use uppercase to create an alias. it doesn't work | open | 2022-10-25T22:18:12Z | 2022-10-30T17:55:00Z | https://github.com/simple-login/app/issues/1372 | [] | JasonMoriarty | 1 |
onnx/onnxmltools | scikit-learn | 369 | Issues converting dask XGB Models to ONNX | Hi @xadupre,
I'm having issues converting my dask XGB model to ONNX. The error I get is the following:
`ValueError: No proper operator name found for '<class 'xgboost.core.Booster'>'`.
I know you've released a patch mentioned in issue #349 ; however, we still are facing the issue. I've provided detailed code I... | open | 2020-02-06T19:39:29Z | 2020-04-15T10:56:54Z | https://github.com/onnx/onnxmltools/issues/369 | [] | ankit1200 | 1 |
pallets-eco/flask-wtf | flask | 538 | Setting WTF_CSRF_TIME_LIMIT to "None" is confusing | In #258, it is made "clear" that `WTF_CSRF_TIME_LIMIT` can be set to `None`. But this isn't entirely clear because what is `None` in the context of an environment variable?
Is it the absence of a value (presumably not, because then we get the default of 3600 seconds) - ?
Is it an empty string? I think a better va... | open | 2022-12-20T12:50:39Z | 2023-07-25T18:55:54Z | https://github.com/pallets-eco/flask-wtf/issues/538 | [
"csrf"
] | malthe | 0 |
miguelgrinberg/microblog | flask | 18 | ImportError: No module named migrate.versioning? | After pip install -r requirements.txt and python db_create.py, I still get the following? Which library is it taken from Flask-Migrate, Migrate?
```
from migrate.versioning import api
ImportError: No module named migrate.versioning
```
I did get:
```
ld: library not found for -lgcc_s.10.5
collect2: ld returned 1... | closed | 2015-09-28T18:52:40Z | 2017-12-10T20:19:01Z | https://github.com/miguelgrinberg/microblog/issues/18 | [
"question"
] | scheung38 | 19 |
jina-ai/clip-as-service | pytorch | 562 | No such file or directory | Hi:
i creat a folder named "tmp" and follow constructions to install and run,but got run:
"tensorflow.python.framework.errors_impl.NotFoundError: /chinese_L-12_H-768_A-12/bert_config.json; No such file or directory"
i think my folder routine is correct,so i dont know whats wrong | open | 2020-06-06T05:25:58Z | 2022-11-01T12:52:48Z | https://github.com/jina-ai/clip-as-service/issues/562 | [] | fangxiang00 | 1 |
cvat-ai/cvat | tensorflow | 8,896 | CANNOT Upload Annotations | ### Actions before raising this issue
- [X] I searched the existing issues and did not find anything similar.
- [X] I read/searched [the docs](https://docs.cvat.ai/docs/)
### Steps to Reproduce
1-Create a new project.
2- Add Raw labels
3-Submit & Open.
4-Create a new task under the project
5-Drag .png files
6-S... | closed | 2025-01-02T07:03:37Z | 2025-01-31T13:54:24Z | https://github.com/cvat-ai/cvat/issues/8896 | [
"bug",
"need info"
] | kotbiat | 1 |
slackapi/python-slack-sdk | asyncio | 763 | Random timeout errors when calling views_publish | ### Description
Recently started seeing random timeout errors while calling views_publish on webclient. Everything was fine until a few days ago.
I checked with the slack support team as I suspected something to do with the API, they were not able to replicate the same with the API and suggested that I raise the is... | closed | 2020-07-27T17:39:45Z | 2020-08-20T01:07:47Z | https://github.com/slackapi/python-slack-sdk/issues/763 | [
"Version: 2x",
"question",
"web-client",
"server-side-issue"
] | iamarora | 8 |
miguelgrinberg/Flask-SocketIO | flask | 1,330 | How can background tasks be assigned to a client? | What I need now is:
The front end sends a message to the server through an event, and the server parses the message, and then continuously pushes the required data to the client.
The current practice is to push data to the front end through background tasks, but all clients listening to this event will receive this... | closed | 2020-07-20T10:29:38Z | 2020-10-09T18:49:35Z | https://github.com/miguelgrinberg/Flask-SocketIO/issues/1330 | [
"question"
] | ShawnChen-dev | 3 |
plotly/dash-table | dash | 923 | Release v4.12.0 for Julia | closed | 2021-07-13T15:09:03Z | 2021-07-13T15:21:38Z | https://github.com/plotly/dash-table/issues/923 | [] | alexcjohnson | 2 | |
quantmind/pulsar | asyncio | 320 | The documentation website is down | I don't know if this is the right place to warn about this.

| open | 2020-09-03T08:51:11Z | 2020-09-03T08:51:11Z | https://github.com/quantmind/pulsar/issues/320 | [] | jruere | 0 |
cvat-ai/cvat | pytorch | 8,353 | Exporting review comments with annotations | Hello,
I want to save not only annotations but also their issues (comments that are made during review by clicking right mouse button and choosing "Open Issue") however I cannot find any export format that would do that.
Am I missing something, or it isn't implemented? If not, there are any possibilities to get such ... | closed | 2024-08-27T10:29:16Z | 2024-08-27T11:14:45Z | https://github.com/cvat-ai/cvat/issues/8353 | [] | DainiusGaidamaviciuss | 5 |
stanfordnlp/stanza | nlp | 870 | Stop Words | Is there a built in stop words classification for simplified chinese? thank you! | closed | 2021-11-04T03:32:02Z | 2021-11-09T22:39:21Z | https://github.com/stanfordnlp/stanza/issues/870 | [
"question"
] | nlp12 | 2 |
biolab/orange3 | scikit-learn | 6,217 | Deprecate: `max_features='auto' | ```test_scorer_feature (Orange.tests.test_random_forest.RandomForestTest) ... /home/runner/work/orange3/orange3/.tox/orange-released/lib/python3.8/site-packages/sklearn/ensemble/_forest.py:427: FutureWarning: `max_features='auto'` has been deprecated in 1.1 and will be removed in 1.3. To keep the past behaviour, explic... | closed | 2022-11-22T18:22:37Z | 2023-01-11T09:17:35Z | https://github.com/biolab/orange3/issues/6217 | [
"snack"
] | markotoplak | 1 |
jazzband/django-oauth-toolkit | django | 672 | Invalid grant_type refresh_token | Hi I am trying to get a refresh token with this endpoint 127.0.0.1:8000/o/token/ and the payload , I already try with json and x-www-form-urlencoded. The response is always 401 invalid grant type
{
"grant_type": "refresh_token",
"refresh_token":"xxxxxx",
"client_id":"xxxxx",
"client_secret":"xxxxxx"
} | closed | 2018-12-05T11:29:43Z | 2020-02-04T06:59:21Z | https://github.com/jazzband/django-oauth-toolkit/issues/672 | [] | tximpa91 | 4 |
microsoft/nni | machine-learning | 5,723 | Unsupported Layer nn.TransformerEncoderLayer | **Describe the bug**:
**Environment**:
- NNI version: 3.0
- Training service (local|remote|pai|aml|etc): local
- Python version: 3.10
- PyTorch version: 1.13
- Cpu or cuda version: Cuda/Cpu
**Reproduce the problem**
- How to reproduce: It seems like the class[`TransformerEncoderLayer`](https://pytorch... | open | 2023-12-12T21:56:24Z | 2023-12-12T21:57:13Z | https://github.com/microsoft/nni/issues/5723 | [] | saeedashrraf | 0 |
pytest-dev/pytest-django | pytest | 945 | enable_db_access_for_all_tests how to make it work for all databases in multi databases setup? | I tried with markers in different places in conftest - nothing helps.
If markers in individual test files that do use second db - everything work.
If there is no markers in test file that use only main db - everything works in this test file. | open | 2021-09-10T13:11:10Z | 2021-11-12T19:48:57Z | https://github.com/pytest-dev/pytest-django/issues/945 | [] | insspb | 1 |
stanfordnlp/stanza | nlp | 557 | add a feature to allow ssl verify = False. | Within our study environment , we cannot pull in models from github without enabling SSL_VERIFY=false. Because of this reason we are forced to download the models outside the notebook using unix commands like wget with --no-check-certificate and then copy it and configure it etc etc. It becomes difficult for the data ... | open | 2020-12-08T13:23:21Z | 2020-12-08T16:15:44Z | https://github.com/stanfordnlp/stanza/issues/557 | [
"enhancement"
] | niths4u | 1 |
yihong0618/running_page | data-visualization | 658 | Cloudflare 部署的是作者演示画面 | 我按教程操作
1、github repo
2、cloudflare 新建pages 关联到github repo
3、pages里 设置环境变量python3.8和构建命令 npm run build
4、构建,提示成功
5、打开page,显示的是作者的演示画面。
6、修改了sitemeta文件,cloudflare重新构建并显示了修改
重点:在github上修改了run_data_sync.yml ,github action执行后github画面更新为我的数据了;但是cloudflare构建后仍然是演示数据。重复多次构建,仍然是演示数据。
请问一下cloudflare这样部署是没办法和github数据同步吗?怎样... | closed | 2024-04-16T12:15:31Z | 2024-04-17T01:17:22Z | https://github.com/yihong0618/running_page/issues/658 | [] | gavenwan | 9 |
scrapy/scrapy | python | 5,936 | Docs involving Request.cookies are inaccurate | ### Description
The docs for a scrapy.Request have an example that no longer work. See docs [here](https://docs.scrapy.org/en/latest/topics/request-response.html).
In the section where it says:
> Example of a request that sends manually-defined cookies and ignores cookie storage:
> Request(
> url="http:... | closed | 2023-05-18T15:00:43Z | 2023-10-02T16:40:28Z | https://github.com/scrapy/scrapy/issues/5936 | [
"bug",
"docs"
] | plug-city | 3 |
sktime/pytorch-forecasting | pandas | 1,455 | MultivariateNormalDistributionLoss returns Negative Value | - PyTorch-Forecasting version: 1.0.0.post123+c2320fa
- PyTorch version: 2.0.0
- Python version: 3.10.13
- Operating System: Ubuntu 18.04
### Expected behavior
I ran the DeepAR and DeepVAR sample code at [https://pytorch-forecasting.readthedocs.io/en/stable/tutorials/deepar.html](url) with my own asset price da... | open | 2023-11-29T08:27:30Z | 2023-11-29T08:27:30Z | https://github.com/sktime/pytorch-forecasting/issues/1455 | [] | nonconvexopt | 0 |
inventree/InvenTree | django | 9,232 | Error after SQLITE3 to PGSQL Migration and Update Server | ### Please verify that this bug has NOT been raised before.
- [x] I checked and didn't find a similar issue
### Describe the bug*
Hello,
I have migrate my Inventree Instance from SQLITE3 to PGSQL and all seems OK.
I have running "apt upgrade" to update my OS and my Inventree instance.
When I reconnect, i have lo... | open | 2025-03-04T20:55:46Z | 2025-03-05T10:56:59Z | https://github.com/inventree/InvenTree/issues/9232 | [
"question",
"setup",
"documentation"
] | IT-META | 2 |
nteract/testbook | pytest | 55 | Accept notebook as str, file and nbformat.NotebookNode object | Currently, the `testbook` api only accepts a notebook path. We should extend it to also accept file objects and `nbformat.NotebookNode` objects.
@MSeal how do you suggest we go about this?
A particular use case where this would be feasible is when a notebook is obtained through a GET request. It would need to be... | closed | 2020-08-14T14:50:29Z | 2020-08-29T12:39:10Z | https://github.com/nteract/testbook/issues/55 | [
"GSoC-2020"
] | rohitsanj | 1 |
biolab/orange3 | pandas | 5,994 | Create Instances duplicates attribute names | **What's wrong?**
Variable "Source Id" is added even if the attribute with the same name already exists.
**How can we reproduce the problem?**
Put two Create Instances widgets one after another.
**What's your environment?**
N/A | closed | 2022-05-26T10:50:54Z | 2022-06-03T15:45:50Z | https://github.com/biolab/orange3/issues/5994 | [
"bug"
] | janezd | 0 |
matterport/Mask_RCNN | tensorflow | 2,277 | Stairs-like and cut-off predictions | I've been using matterport's Mask R-CNN to train on a custom dataset. However, there seem to be some parameters that i failed to correctly define because on practically all of the images, the bottom or top of the object's mask is cut off:
 {
id
}
}
```
### Expected Behavior
I expect the same result as this API call:
`/api/... | closed | 2024-10-06T01:01:28Z | 2025-03-10T19:37:16Z | https://github.com/netbox-community/netbox/issues/17681 | [
"type: bug",
"status: accepted",
"topic: GraphQL",
"severity: low",
"netbox"
] | kuon | 7 |
ShishirPatil/gorilla | api | 792 | 对于 API 托管Openai gpt4o模型生成和评估报错问题 | 目前用了openai gpt4o 的api key是正确的,用命令bfcl generate --model gpt-4o-2024-08-06-FC --test-category parallel --num-threads 1 报错如下;
{"id": "parallel_9", "result": "Error during inference: Error code: 401 - {'error': {'message': 'Incorrect API key provided: sk-l2PGB***************************************iY7Z. You can find your ... | closed | 2024-11-26T09:57:21Z | 2024-11-26T11:03:03Z | https://github.com/ShishirPatil/gorilla/issues/792 | [] | belief888 | 1 |
xinntao/Real-ESRGAN | pytorch | 425 | Can't install on conda | I can't install requirements on conda.
I tried for several hours, Each time something else causes issues.
The main issue is that I need a lower version of python for Numpy 1.20.
This starts a chain of headaches trying to figure out how to properly setup the environment on conda.
Is there a proper environment setup ... | open | 2022-08-30T23:08:35Z | 2022-08-31T11:19:24Z | https://github.com/xinntao/Real-ESRGAN/issues/425 | [] | smoran | 1 |
huggingface/datasets | deep-learning | 6,585 | losing DatasetInfo in Dataset.map when num_proc > 1 | ### Describe the bug
Hello and thanks for developing this package!
When I process a Dataset with the map function using multiple processors some set attributes of the DatasetInfo get lost and are None in the resulting Dataset.
### Steps to reproduce the bug
```python
from datasets import Dataset, DatasetInfo... | open | 2024-01-12T13:39:19Z | 2024-01-12T14:08:24Z | https://github.com/huggingface/datasets/issues/6585 | [] | JochenSiegWork | 2 |
AUTOMATIC1111/stable-diffusion-webui | pytorch | 15,669 | [Feature Request]: Implement AYS Sampler proposed by Nvidia | ### Is there an existing issue for this?
- [X] I have searched the existing issues and checked the recent builds/commits
### What would your feature do ?
Align Your Steps (AYS), a novel general framework for optimizing sampling schedules in diffusion models that
significantly boosts the quality of outputs, especial... | open | 2024-04-30T17:13:13Z | 2024-04-30T17:13:13Z | https://github.com/AUTOMATIC1111/stable-diffusion-webui/issues/15669 | [
"enhancement"
] | GongXinyuu | 0 |
man-group/notebooker | jupyter | 149 | Index page to group notebook results into folders | If notebooks are placed in folders, the folder structure is represented correctly in the 'Execute a Notebook' toolbar. However notebook results on the main index page are all flattened on one screen. This is becoming problematic in case of deployments with large number of notebooks.
Proposed solution: Implement folder... | closed | 2023-05-16T16:28:30Z | 2023-08-31T06:45:03Z | https://github.com/man-group/notebooker/issues/149 | [] | marcinapostoluk | 0 |
flasgger/flasgger | api | 252 | @swag_from("relative_path.yml") throws ImportError: No module named 'home' when using venv environments | EDIT: SCRATCH THAT. This was an unfortunate side effect of mixing up `-` and `_` in file names. Flasgger couldn't find the file, and then tried to import it as a module, which worked with importlib due to _ and - import rules. There's still a problem in using imp, but I just hit an unfortunate corner case, so I'm closi... | closed | 2018-10-11T10:31:09Z | 2018-10-12T06:33:00Z | https://github.com/flasgger/flasgger/issues/252 | [] | jkgeyti | 4 |
zihangdai/xlnet | nlp | 140 | Where could I find pre-trained base model? | open | 2019-07-08T22:10:48Z | 2019-07-15T02:09:34Z | https://github.com/zihangdai/xlnet/issues/140 | [] | Juyue | 3 | |
pytorch/pytorch | deep-learning | 149,225 | unexpected results when using torch.all_close API | ### 🐛 Describe the bug
The test_allclose_zero_toleranceshows unexpected behavior (expecting False, but torch.allclose returns True), showing that the implementation does not follow the documented and expected semantics.
```python
def test_allclose_zero_tolerance(self):
# Test with zero tolerance
... | closed | 2025-03-14T21:01:42Z | 2025-03-17T15:25:15Z | https://github.com/pytorch/pytorch/issues/149225 | [] | sjh0849 | 1 |
minimaxir/textgenrnn | tensorflow | 18 | TypeError: softmax() got an unexpected keyword argument 'axis' | Dear,
My environment as below:
Python 3.5.2 |Anaconda custom (64-bit)| (default, Jul 5 2016, 11:41:13) [MSC v.
1900 64 bit (AMD64)] on win32
I received below error when I issue textgenrnn():
>>> textgen = textgenrnn()
2018-04-27 09:39:11.639683: W C:\tf_jenkins\home\workspace\rel-win\M\windows\PY\
35\tens... | closed | 2018-04-27T01:42:22Z | 2018-04-28T03:53:58Z | https://github.com/minimaxir/textgenrnn/issues/18 | [] | awfssv | 2 |
streamlit/streamlit | streamlit | 10,160 | Expose OAuth errors during `st.login` | ### Checklist
- [X] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar feature requests.
- [X] I added a descriptive title and summary to this issue.
### Summary
We're soon launching native authentication in Streamlit (see #8518). One thing we left out for now is ... | open | 2025-01-10T23:32:58Z | 2025-01-10T23:33:46Z | https://github.com/streamlit/streamlit/issues/10160 | [
"type:enhancement",
"feature:st.user",
"feature:st.login"
] | jrieke | 1 |
wq/django-rest-pandas | rest-api | 32 | Use as a method in a ViewSet | Is it possibile to extend a standard DRF ViewSet with a method implementing a DRP PandasView? | closed | 2017-10-26T15:25:19Z | 2019-03-28T02:30:59Z | https://github.com/wq/django-rest-pandas/issues/32 | [] | donatogr | 4 |
pallets-eco/flask-sqlalchemy | sqlalchemy | 349 | _should_set_tablename is problematic | It runs at import time and ends up accessing _all_ attributes on the model classes.
My base model class has a class-level property like this:
```
@classproperty
@classmethod
def has_rows(cls):
"""Checks if the underlying table has any rows.
This is done in an efficient way and should preferred over
calli... | closed | 2015-11-17T12:48:33Z | 2020-12-05T21:18:08Z | https://github.com/pallets-eco/flask-sqlalchemy/issues/349 | [
"tablename"
] | ThiefMaster | 11 |
zama-ai/concrete-ml | scikit-learn | 82 | When I run the fhe_compatibility, the program is killed | qmodel = fhe_compatibility(quant_vgg, data)
print(
f"With {param_c10['dataset_name']}, the circuit has a maximum bit-width of "
f"{qmodel.fhe_circuit.graph.maximum_integer_bit_width()}-bits."
)
<img width="192" alt="1686310285723" src="https://github.com/zama-ai/concrete-ml/assets/127387074/cf6b835c-cb... | closed | 2023-06-09T11:32:18Z | 2023-06-22T06:11:00Z | https://github.com/zama-ai/concrete-ml/issues/82 | [] | maxwellgodv | 8 |
httpie/cli | python | 1,248 | Gracefully handle DNS failures | HTTPie for Web and Desktop prints useful suggestions when you are not connected to internet or the URL is invalid. Let's also have these on the CLI as well. | closed | 2021-12-22T15:29:28Z | 2021-12-29T09:08:58Z | https://github.com/httpie/cli/issues/1248 | [
"enhancement",
"new"
] | isidentical | 1 |
plotly/dash-component-boilerplate | dash | 94 | Convert an existing React component with a script? | Hi, thanks for dash and this component creation helper, great ideas both.
Right now, I just want to use someone else's React component (https://github.com/allenai/hierplane) in my dash app, but I can't find documentation for doing that. This repo is the closest I've gotten.
I saw once an issue about creating a ni... | open | 2019-11-06T21:33:54Z | 2023-01-13T19:26:06Z | https://github.com/plotly/dash-component-boilerplate/issues/94 | [] | interrogator | 5 |
voxel51/fiftyone | data-science | 5,295 | [BUG] Dynamic Filtering Float Field Sidebar Issue | ### Describe the problem
`fiftyone.core.fields.FloatField`s when added dynamically (eg. via an operator) fail to filter via the sidebar.

| open | 2024-12-18T19:25:39Z | 2024-12-19T17:25:43Z | https://github.com/voxel51/fiftyone/issues/5295 | [
"bug"
] | ritch | 3 |
junyanz/pytorch-CycleGAN-and-pix2pix | deep-learning | 1,268 | 256 pixel output, not 512, despite training on --load_size 512 | I've read the FAQ and training tips carefully. Nonetheless, my 512 height images are being output as 256 at test time. Why?
Train:
```
!python train.py --continue_train --gpu_ids 0 --dataroot ./datasets/joseph--name joseph --model pix2pix --preprocess crop --no_flip --load_size 512 --crop_size 256 --display_winsi... | open | 2021-04-05T11:40:24Z | 2022-02-15T20:59:40Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/1268 | [] | turian | 3 |
tensorflow/tensor2tensor | deep-learning | 1,173 | Translate English to Chinese with own data, but failed. | ### Description
I will to use my own set of data, but it is not working. Could anyone can help with this issue?
### Environment information
```
OS: CentOS
$ pip freeze | grep tensor
tensor2tensor==1.6.2
tensorboard==1.8.0
tensorflow-gpu==1.8.0
tensorflow-serving-api-python3==1.7.0
tensorflow-tensorboa... | closed | 2018-10-26T09:35:50Z | 2018-11-15T06:23:34Z | https://github.com/tensorflow/tensor2tensor/issues/1173 | [] | lowblung | 3 |
mars-project/mars | scikit-learn | 3,173 | What's about python version compatible? | It's able to install pymars on python3.7, but there is incompatible code, such as
https://github.com/mars-project/mars/blob/60e19c359f0f3a8b6717e8d683922fd4efba22fd/mars/deploy/oscar/ray.py#L429
I'm not sure if there is more incompatible case... | closed | 2022-06-28T05:42:01Z | 2022-08-03T05:29:22Z | https://github.com/mars-project/mars/issues/3173 | [] | cmsxbc | 5 |
arogozhnikov/einops | numpy | 153 | [Feature] Jax/Flax Layers, especially Einmix? | EinMix layer looks great but cannot be used with Jax since it's not a function. Would be great to have that EinMix layer in a Jax-based framework like Flax. | closed | 2021-12-05T19:18:54Z | 2022-10-03T06:47:15Z | https://github.com/arogozhnikov/einops/issues/153 | [
"feature suggestion"
] | lkhphuc | 7 |
jupyterlab/jupyter-ai | jupyter | 1,256 | Unify chat handler initialization | ### Problem
The `/ask`, `/generate`, and `/learn` default implementations are require an extra set of arguments in the constructor. This is impeding the development of #1249 by forcing the addition of complex logic to handle this case.
Specifically, the extra set of arguments required are:
- `error_logs_dir: str` (b... | closed | 2025-02-21T19:16:21Z | 2025-02-26T17:40:40Z | https://github.com/jupyterlab/jupyter-ai/issues/1256 | [
"enhancement"
] | dlqqq | 3 |
feder-cr/Jobs_Applier_AI_Agent_AIHawk | automation | 636 | [BUG]: It doesn't exclude senior positions even though only entry and associate in experienceLevel have been specified | ### Describe the bug
The program still applies to senior positions even though the only fields in the `experienceLevel` scope in the `config.yaml` file that has been set to `true` are `entry` and `associate`.
### Steps to reproduce
Just run the program with the following settings in the `experienceLevel` field... | closed | 2024-10-28T14:38:34Z | 2024-11-07T06:34:42Z | https://github.com/feder-cr/Jobs_Applier_AI_Agent_AIHawk/issues/636 | [
"bug"
] | Axedyson | 2 |
RomelTorres/alpha_vantage | pandas | 264 | Why can't I get data of S&P 500? | Hello, I'm new to coding.
I'm trying to get data of S&P 500 using alpha_vantage API,
but it somehow didn't work.
I tried IBM and Microsoft, and it all worked.
Does anyone know where the problem is?
![... | closed | 2020-10-18T13:36:41Z | 2020-11-10T14:29:56Z | https://github.com/RomelTorres/alpha_vantage/issues/264 | [] | TianliaoLiu | 3 |
skypilot-org/skypilot | data-science | 4,160 | [Performance] Move validation calls out of Resource.__init__ | <!-- Describe the bug report / feature request here -->
We are initiating the resource object multiple times which triggers non-trivial validation.
https://github.com/skypilot-org/skypilot/blob/master/sky/resources.py#L228-L234
<!-- If relevant, fill in versioning info to help us troubleshoot -->
_Version & C... | closed | 2024-10-24T01:14:43Z | 2024-12-19T09:31:25Z | https://github.com/skypilot-org/skypilot/issues/4160 | [
"P1"
] | yika-luo | 0 |
litestar-org/litestar | api | 3,937 | Bug: CI builds fail due to deprecated Github action | ### Description
The currently used Github upload action has been deprecated and should be upgraded.
### URL to code causing the issue
https://github.com/litestar-org/litestar/actions/runs/12687347653/job/35387778036?pr=3935#step:1:36
### MCVE
_No response_
### Steps to reproduce
_No response_
### Screenshot... | closed | 2025-01-09T17:51:53Z | 2025-01-10T02:47:26Z | https://github.com/litestar-org/litestar/issues/3937 | [
"Bug :bug:"
] | cofin | 1 |
apify/crawlee-python | web-scraping | 719 | Expose the `browser_options` to the PlaywrightCrawler | - In the same way as we do it for `headless` and `broser_type`.
- https://playwright.dev/python/docs/api/class-browsertype#browser-type-launch
- Also improve arg docs, add links to the PW docs | closed | 2024-11-21T11:23:09Z | 2024-11-25T10:55:10Z | https://github.com/apify/crawlee-python/issues/719 | [
"enhancement",
"t-tooling"
] | vdusek | 0 |
deepset-ai/haystack | machine-learning | 8,548 | Add a Recursive Chunking strategy | Use a set of predefined separators to split text recursively. The process follows these steps:
- It starts with a list of separator characters, typically ordered from most to least specific (e.g., ["\n\n", "\n", " ", ""]).
- The splitter attempts to divide the text using the first separator ("\n\n" in this case).
- I... | closed | 2024-11-15T09:48:48Z | 2025-01-10T16:28:55Z | https://github.com/deepset-ai/haystack/issues/8548 | [
"P2"
] | davidsbatista | 8 |
amidaware/tacticalrmm | django | 1,131 | Integrate TRMM with existing Meshcentral server | Currently we have deployed a meshcentral server with 9000+ customized meshagent. We need to integrate the same with TRRM server.can you suggest a solution to integrate the same
| closed | 2022-05-15T05:41:23Z | 2022-05-15T10:55:12Z | https://github.com/amidaware/tacticalrmm/issues/1131 | [] | VINISHVV | 0 |
ageitgey/face_recognition | machine-learning | 1,078 | ValueError: operands could not be broadcast together with shapes (1,2) (128,) | * face_recognition version:
* Python version:
* Operating System:
### Description
Describe what you were trying to get done.
Tell us what happened, what went wrong, and what you expected to happen.
IMPORTANT: If your issue is related to a specific picture, include it so others can reproduce the issue.
### ... | closed | 2020-03-03T12:17:25Z | 2020-03-24T17:32:55Z | https://github.com/ageitgey/face_recognition/issues/1078 | [] | panchami88 | 0 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.